Improving Language Understanding by Generative Pre-Training
Improving Language Understanding by Generative Pre-Training
通过生成式预训练改进语言理解
Alec Radford Karthik Narasimhan Tim Salimans Ilya Sutskever
OpenAI OpenAI OpenAI OpenAI
alec@openai.com karthikn@openai.com tim@openai.com ilyasu@openai.com
Abstract
摘要
Natural language understanding comprises a wide range of diverse tasks such as textual entailment, question answering, semantic similarity assessment, and document classification. Although large unlabeled text corpora are abundant, labeled data for learning these specific tasks is scarce, making it challenging for discriminatively trained models to perform adequately. We demonstrate that large gains on these tasks can be realized by generative pre-training of a language model on a diverse corpus of unlabeled text, followed by discriminative fine-tuning on each specific task. In contrast to previous approaches, we make use of task-aware input transformations during fine-tuning to achieve effective transfer while requiring minimal changes to the model architecture. We demonstrate the effectiveness of our approach on a wide range of benchmarks for natural language understanding. Our general task-agnostic model outperforms discriminatively trained models that use architectures specifically crafted for each task, significantly improving upon the state of the art in 9 out of the 12 tasks studied. For instance, we achieve absolute improvements of 8.9% on commonsense reasoning (Stories Cloze Test), 5.7% on question answering (RACE), and 1.5% on textual entailment (MultiNLI).
自然语言理解涵盖文本蕴含、问答、语义相似度评估与文档分类等多样任务。尽管大规模未标注文本语料很丰富,面向这些具体任务的标注数据却稀缺,使判别式训练的模型难以表现充分。我们证明:在多样未标注文本语料上对语言模型做生成式预训练,再在各具体任务上做判别式微调,可在这些任务上获得大幅提升。与先前方法不同,我们在微调时使用任务感知的输入变换,以在对模型架构改动最小的前提下实现有效迁移。我们在广泛的自然语言理解基准上验证了该方法。我们的通用、任务无关模型超过为各任务专门设计架构的判别式训练模型,在所研究的 12 项任务中有 9 项显著改进当时最优。例如,常识推理(Stories Cloze Test)绝对提升 8.9%,问答(RACE)提升 5.7%,文本蕴含(MultiNLI)提升 1.5%。
1 Introduction
1 引言
The ability to learn effectively from raw text is crucial to alleviating the dependence on supervised learning in natural language processing (NLP). Most deep learning methods require substantial amounts of manually labeled data, which restricts their applicability in many domains that suffer from a dearth of annotated resources [61]. In these situations, models that can leverage linguistic information from unlabeled data provide a valuable alternative to gathering more annotation, which can be time-consuming and expensive. Further, even in cases where considerable supervision is available, learning good representations in an unsupervised fashion can provide a significant performance boost. The most compelling evidence for this so far has been the extensive use of pretrained word embeddings [10, 39, 42] to improve performance on a range of NLP tasks [8, 11, 26, 45]. Leveraging more than word-level information from unlabeled text, however, is challenging for two main reasons. First, it is unclear what type of optimization objectives are most effective at learning text representations that are useful for transfer. Recent research has looked at various objectives such as language modeling [44], machine translation [38], and discourse coherence [22], with each method outperforming the others on different tasks.1 Second, there is no consensus on the most effective way to transfer these learned representations to the target task. Existing techniques involve a combination of making task-specific changes to the model architecture [43, 44], using intricate learning schemes [21] and adding auxiliary learning objectives [50]. These uncertainties have made it difficult to develop effective semi-supervised learning approaches for language processing. 1 https://gluebenchmark.com/leaderboard
能否有效从原始文本学习,对缓解自然语言处理(NLP)对监督学习的依赖至关重要。多数深度学习方法需要大量人工标注数据,这限制了它们在标注资源匮乏领域的适用性[61]。在这些情形下,能从未标注数据利用语言信息的模型,为继续搜集标注提供了有价值的替代——后者往往耗时昂贵。进一步地,即便监督充足,以无监督方式学到良好表征也能显著提升性能。迄今最有说服力的证据,是广泛使用预训练词嵌入[10, 39, 42]来改进一系列 NLP 任务[8, 11, 26, 45]。然而,从未标注文本中利用超过词级的信息仍有两大挑战。其一,何种优化目标最有效地学到利于迁移的文本表征仍不清楚。近期研究考察了语言建模[44]、机器翻译[38]、篇章连贯[22]等目标,各方法在不同任务上互有胜负。其二,把这些学到的表征迁移到目标任务的最有效方式尚无共识。现有技术往往组合任务特定的架构改动[43, 44]、复杂学习方案[21]与辅助学习目标[50]。这些不确定性使面向语言处理的有效半监督学习方法难以发展。1 https://gluebenchmark.com/leaderboard
In this paper, we explore a semi-supervised approach for language understanding tasks using a combination of unsupervised pre-training and supervised fine-tuning. Our goal is to learn a universal representation that transfers with little adaptation to a wide range of tasks. We assume access to a large corpus of unlabeled text and several datasets with manually annotated training examples (target tasks). Our setup does not require these target tasks to be in the same domain as the unlabeled corpus. We employ a two-stage training procedure. First, we use a language modeling objective on the unlabeled data to learn the initial parameters of a neural network model. Subsequently, we adapt these parameters to a target task using the corresponding supervised objective. For our model architecture, we use the Transformer [62], which has been shown to perform strongly on various tasks such as machine translation [62], document generation [34], and syntactic parsing [29]. This model choice provides us with a more structured memory for handling long-term dependencies in text, compared to alternatives like recurrent networks, resulting in robust transfer performance across diverse tasks. During transfer, we utilize task-specific input adaptations derived from traversal-style approaches [52], which process structured text input as a single contiguous sequence of tokens. As we demonstrate in our experiments, these adaptations enable us to fine-tune effectively with minimal changes to the architecture of the pre-trained model. We evaluate our approach on four types of language understanding tasks – natural language inference, question answering, semantic similarity, and text classification. Our general task-agnostic model outperforms discriminatively trained models that employ architectures specifically crafted for each task, significantly improving upon the state of the art in 9 out of the 12 tasks studied. For instance, we achieve absolute improvements of 8.9% on commonsense reasoning (Stories Cloze Test) [40], 5.7% on question answering (RACE) [30], 1.5% on textual entailment (MultiNLI) [66] and 5.5% on the recently introduced GLUE multi-task benchmark [64]. We also analyzed zero-shot behaviors of the pre-trained model on four different settings and demonstrate that it acquires useful linguistic knowledge for downstream tasks.
本文探索一种面向语言理解任务的半监督方法,结合无监督预训练与有监督微调。目标是学习一种只需很少适配即可迁移到广泛任务的通用表征。我们假定可访问大规模未标注文本语料,以及若干带人工标注训练样本的数据集(目标任务)。设定不要求这些目标任务与未标注语料同域。训练分两阶段:首先在未标注数据上用语言建模目标学习神经网络初始参数;随后用相应有监督目标把这些参数适配到目标任务。架构上我们使用 Transformer[62],它已在机器翻译[62]、文档生成[34]、句法分析[29]等任务上表现强劲。相对循环网络等替代方案,这一选择为我们处理文本长程依赖提供了更结构化的记忆,从而在多样任务上带来稳健迁移。迁移时,我们采用源自遍历式方法[52]的任务特定输入适配,把结构化文本输入处理为单一连续 token 序列。实验表明,这些适配使我们能在对预训练模型架构改动最小的情况下有效微调。我们在四类语言理解任务上评估:自然语言推理、问答、语义相似度与文本分类。我们的通用任务无关模型超过为各任务专门设计架构的判别式训练模型,在 12 项任务中有 9 项显著改进当时最优。例如,常识推理(Stories Cloze Test)[40]绝对提升 8.9%,问答(RACE)[30]提升 5.7%,文本蕴含(MultiNLI)[66]提升 1.5%,以及新近提出的 GLUE 多任务基准[64]提升 5.5%。我们还在四种设定下分析了预训练模型的零样本行为,表明它为下游任务习得了有用的语言知识。
2 Related Work
2 相关工作
Semi-supervised learning for NLP Our work broadly falls under the category of semi-supervised learning for natural language. This paradigm has attracted significant interest, with applications to tasks like sequence labeling [24, 33, 57] or text classification [41, 70]. The earliest approaches used unlabeled data to compute word-level or phrase-level statistics, which were then used as features in a supervised model [33]. Over the last few years, researchers have demonstrated the benefits of using word embeddings [11, 39, 42], which are trained on unlabeled corpora, to improve performance on a variety of tasks [8, 11, 26, 45]. These approaches, however, mainly transfer word-level information, whereas we aim to capture higher-level semantics. Recent approaches have investigated learning and utilizing more than word-level semantics from unlabeled data. Phrase-level or sentence-level embeddings, which can be trained using an unlabeled corpus, have been used to encode text into suitable vector representations for various target tasks [28, 32, 1, 36, 22, 12, 56, 31].
面向 NLP 的半监督学习 本工作大体属于自然语言半监督学习。该范式兴趣浓厚,应用于序列标注[24, 33, 57]或文本分类[41, 70]等任务。最早的方法用未标注数据计算词级或短语级统计,再作为有监督模型的特征[33]。近几年来,研究者展示了使用在未标注语料上训练的词嵌入[11, 39, 42]可改进多种任务[8, 11, 26, 45]。不过这些方法主要迁移词级信息,而我们旨在捕获更高层语义。近期方法研究从无标注数据学习并利用超过词级的语义。可用未标注语料训练的短语级或句子级嵌入,已被用来把文本编码为适合各目标任务的向量表征[28, 32, 1, 36, 22, 12, 56, 31]。
Unsupervised pre-training Unsupervised pre-training is a special case of semi-supervised learning where the goal is to find a good initialization point instead of modifying the supervised learning objective. Early works explored the use of the technique in image classification [20, 49, 63] and regression tasks [3]. Subsequent research [15] demonstrated that pre-training acts as a regularization scheme, enabling better generalization in deep neural networks. In recent work, the method has been used to help train deep neural networks on various tasks like image classification [69], speech recognition [68], entity disambiguation [17] and machine translation [48]. The closest line of work to ours involves pre-training a neural network using a language modeling objective and then fine-tuning it on a target task with supervision. Dai et al. [13] and Howard and Ruder [21] follow this method to improve text classification. However, although the pre-training phase helps capture some linguistic information, their usage of LSTM models restricts their prediction ability to a short range. In contrast, our choice of transformer networks allows us to capture longerrange linguistic structure, as demonstrated in our experiments. Further, we also demonstrate the effectiveness of our model on a wider range of tasks including natural language inference, paraphrase detection and story completion. Other approaches [43, 44, 38] use hidden representations from a
无监督预训练 无监督预训练是半监督学习的特例,目标是找到良好初始化点,而非修改有监督学习目标。早期工作探索其在图像分类[20, 49, 63]与回归任务[3]中的使用。后续研究[15]表明预训练充当正则,使深度网络更好泛化。近期该方法被用于帮助在图像分类[69]、语音识别[68]、实体消歧[17]与机器翻译[48]等任务上训练深度网络。与我们最接近的工作线是:用语言建模目标预训练神经网络,再在有监督目标任务上微调。Dai 等[13]以及 Howard 与 Ruder[21]沿此方法改进文本分类。不过,尽管预训练阶段有助于捕获部分语言信息,他们使用 LSTM 模型使其预测能力局限于短程。相比之下,我们选择 Transformer 网络以捕获更长程语言结构,实验亦予证明。进一步地,我们还在更广任务范围上展示有效性,包括自然语言推理、复述检测与故事补全。其他方法[43, 44, 38]使用来自
pre-trained language or machine translation model as auxiliary features while training a supervised model on the target task. This involves a substantial amount of new parameters for each separate target task, whereas we require minimal changes to our model architecture during transfer.
预训练语言或机器翻译模型的隐表征,作为在目标任务上训练有监督模型时的辅助特征。这会为每个独立目标任务引入大量新参数,而我们在迁移时对模型架构的改动最小。
Auxiliary training objectives Adding auxiliary unsupervised training objectives is an alternative form of semi-supervised learning. Early work by Collobert and Weston [10] used a wide variety of auxiliary NLP tasks such as POS tagging, chunking, named entity recognition, and language modeling to improve semantic role labeling. More recently, Rei [50] added an auxiliary language modeling objective to their target task objective and demonstrated performance gains on sequence labeling tasks. Our experiments also use an auxiliary objective, but as we show, unsupervised pre-training already learns several linguistic aspects relevant to target tasks.
辅助训练目标 加入辅助无监督训练目标是半监督学习的另一种形式。Collobert 与 Weston[10]早期工作使用词性标注、组块、命名实体识别与语言建模等多种辅助 NLP 任务来改进语义角色标注。最近,Rei[50]在目标任务目标上加入辅助语言建模目标,并在序列标注任务上展示性能增益。我们的实验也使用辅助目标,但如下所示,无监督预训练已经学到与目标任务相关的若干语言面向。
3 Framework
3 框架
Our training procedure consists of two stages. The first stage is learning a high-capacity language model on a large corpus of text. This is followed by a fine-tuning stage, where we adapt the model to a discriminative task with labeled data.
我们的训练流程分两阶段。第一阶段在大规模文本语料上学习高容量语言模型;随后是微调阶段,把模型适配到带标注数据的判别任务。
3.1 Unsupervised pre-training
3.1 无监督预训练
Given an unsupervised corpus of tokens U = {u1 , . . . , un }, we use a standard language modeling objective to maximize the following likelihood: X L1 (U) = log P (ui |ui−k , . . . , ui−1 ; Θ) (1) i where k is the size of the context window, and the conditional probability P is modeled using a neural network with parameters Θ. These parameters are trained using stochastic gradient descent [51]. In our experiments, we use a multi-layer Transformer decoder [34] for the language model, which is a variant of the transformer [62]. This model applies a multi-headed self-attention operation over the input context tokens followed by position-wise feedforward layers to produce an output distribution over target tokens: h0 = U We + Wp hl = transformer_block(hl−1 )∀i ∈ [1, n] (2) P (u) = softmax(hn WeT ) where U = (u−k , . . . , u−1 ) is the context vector of tokens, n is the number of layers, We is the token embedding matrix, and Wp is the position embedding matrix.
给定未标注 token 语料 ,我们使用标准语言建模目标最大化如下似然: (1),其中 为上下文窗口大小,条件概率 由参数为 的神经网络建模。这些参数用随机梯度下降训练[51]。实验中,我们用多层 Transformer 解码器[34]作语言模型,它是 transformer[62] 的一种变体。该模型对输入上下文 token 施加多头自注意力,再经按位置的前馈层,产生目标 token 上的输出分布:, (2),,其中 为上下文 token 向量, 为层数, 为 token 嵌入矩阵, 为位置嵌入矩阵。
3.2 Supervised fine-tuning
3.2 有监督微调
After training the model with the objective in Eq. 1, we adapt the parameters to the supervised target task. We assume a labeled dataset C, where each instance consists of a sequence of input tokens, x1 , . . . , xm , along with a label y. The inputs are passed through our pre-trained model to obtain the final transformer block’s activation hm l , which is then fed into an added linear output layer with parameters Wy to predict y: P (y|x1 , . . . , xm ) = softmax(hm l Wy ). (3) This gives us the following objective to maximize: X L2 (C) = log P (y|x1 , . . . , xm ). (4) (x,y)
在用式 1 的目标训练模型后,我们将参数适配到有监督目标任务。假定有标注数据集 ,每个实例由输入 token 序列 与标签 组成。输入经预训练模型得到最终 transformer 块的激活 ,再送入新增的、参数为 的线性输出层以预测 :。(3) 由此得到要最大化的目标:。(4)
We additionally found that including language modeling as an auxiliary objective to the fine-tuning helped learning by (a) improving generalization of the supervised model, and (b) accelerating convergence. This is in line with prior work [50, 43], who also observed improved performance with such an auxiliary objective. Specifically, we optimize the following objective (with weight λ): L3 (C) = L2 (C) + λ ∗ L1 (C) (5) Overall, the only extra parameters we require during fine-tuning are Wy , and embeddings for delimiter tokens (described below in Section 3.3).
我们还发现,把语言建模作为微调的辅助目标有助于学习:(a) 改进有监督模型的泛化,(b) 加速收敛。这与先前工作[50, 43]一致,他们也观察到此类辅助目标带来性能提升。具体地,我们优化如下目标(权重为 ): (5)。总体而言,微调时仅需额外的 ,以及分隔符 token 的嵌入(见第 3.3 节)。
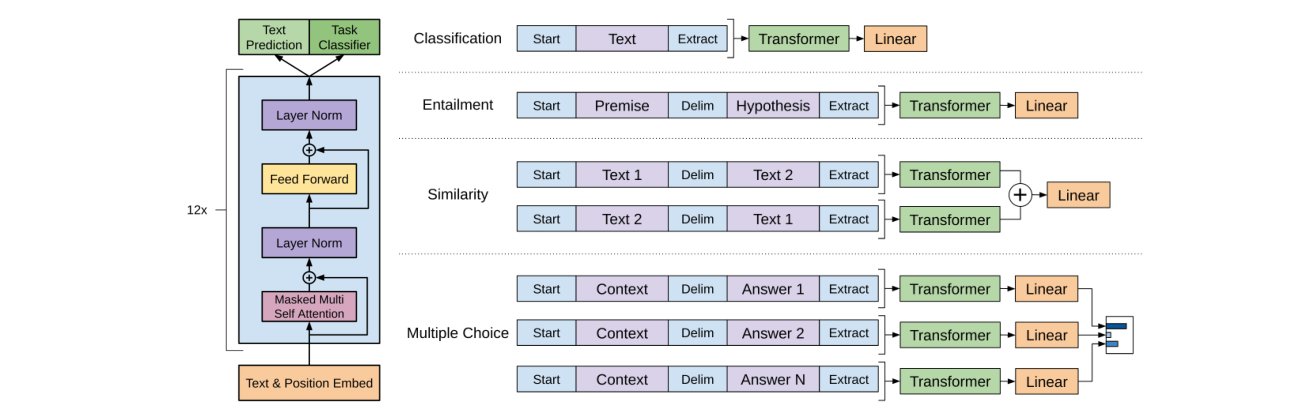
Figure 1: (left) Transformer architecture and training objectives used in this work. (right) Input transformations for fine-tuning on different tasks. We convert all structured inputs into token sequences to be processed by our pre-trained model, followed by a linear+softmax layer.
图 1:(左) 本工作使用的 Transformer 架构与训练目标。(右) 不同任务微调时的输入变换。我们把所有结构化输入转换为 token 序列,由预训练模型处理,再接线性+softmax 层。
3.3 Task-specific input transformations
3.3 任务特定的输入变换
For some tasks, like text classification, we can directly fine-tune our model as described above. Certain other tasks, like question answering or textual entailment, have structured inputs such as ordered sentence pairs, or triplets of document, question, and answers. Since our pre-trained model was trained on contiguous sequences of text, we require some modifications to apply it to these tasks. Previous work proposed learning task specific architectures on top of transferred representations [44]. Such an approach re-introduces a significant amount of task-specific customization and does not use transfer learning for these additional architectural components. Instead, we use a traversal-style approach [52], where we convert structured inputs into an ordered sequence that our pre-trained model can process. These input transformations allow us to avoid making extensive changes to the architecture across tasks. We provide a brief description of these input transformations below and Figure 1 provides a visual illustration. All transformations include adding randomly initialized start and end tokens (hsi, hei).
对某些任务(如文本分类),可直接按上文所述微调模型。另一些任务(如问答或文本蕴含)具有结构化输入,例如有序句对,或文档、问题与答案的三元组。由于预训练模型是在连续文本序列上训练的,应用到这些任务需要一些修改。先前工作提议在迁移表征之上学习任务特定架构[44]。这种方法会重新引入大量任务特定定制,且这些额外架构组件用不到迁移学习。相反,我们使用遍历式方法[52],把结构化输入转换为预训练模型可处理的有序序列。这些输入变换使我们避免跨任务对架构做大量改动。下面简要描述这些变换,图 1 给出示意。所有变换都加入随机初始化的起止 token(⟨s⟩、⟨e⟩)。
Textual entailment For entailment tasks, we concatenate the premise p and hypothesis h token sequences, with a delimiter token ($) in between.
文本蕴含 对蕴含任务,我们拼接前提 与假设 的 token 序列,中间加分隔符 token($)。
Similarity For similarity tasks, there is no inherent ordering of the two sentences being compared. To reflect this, we modify the input sequence to contain both possible sentence orderings (with a delimiter in between) and process each independently to produce two sequence representations hm l which are added element-wise before being fed into the linear output layer.
相似度 对相似度任务,被比较的两句没有固有顺序。为反映这一点,我们修改输入序列,使其包含两种可能的句子顺序(中间有分隔符),各自独立处理得到两个序列表征 ,逐元素相加后再送入线性输出层。
Question Answering and Commonsense Reasoning For these tasks, we are given a context document z, a question q, and a set of possible answers {ak }. We concatenate the document context and question with each possible answer, adding a delimiter token in between to get [z; q; $; ak ]. Each of these sequences are processed independently with our model and then normalized via a softmax layer to produce an output distribution over possible answers.
问答与常识推理 对这些任务,给定上下文文档 、问题 与一组可能答案 。我们把文档上下文与问题与每个可能答案拼接,中间加分隔符,得到 。各序列由模型独立处理,再经 softmax 层归一化,得到可能答案上的输出分布。
4 Experiments
4 实验
4.1 Setup
4.1 设定
Unsupervised pre-training We use the BooksCorpus dataset [71] for training the language model. It contains over 7,000 unique unpublished books from a variety of genres including Adventure, Fantasy, and Romance. Crucially, it contains long stretches of contiguous text, which allows the generative model to learn to condition on long-range information. An alternative dataset, the 1B Word Benchmark, which is used by a similar approach, ELMo [44], is approximately the same size
无监督预训练 我们用 BooksCorpus 数据集[71]训练语言模型。它包含来自冒险、奇幻、言情等多种体裁的 7000 余本未出版独特书籍。关键的是,它包含长段连续文本,使生成模型能学会以长程信息为条件。另一种数据集是 1B Word Benchmark,被类似方法 ELMo[44]使用,规模大致相当
Table 1: A list of the different tasks and datasets used in our experiments.
表 1:实验所用不同任务与数据集列表。
Task Datasets Natural language inference SNLI [5], MultiNLI [66], Question NLI [64], RTE [4], SciTail [25] Question Answering RACE [30], Story Cloze [40] Sentence similarity MSR Paraphrase Corpus [14], Quora Question Pairs [9], STS Benchmark [6] Classification Stanford Sentiment Treebank-2 [54], CoLA [65]
Task Datasets Natural language inference SNLI [5], MultiNLI [66], Question NLI [64], RTE [4], SciTail [25] Question Answering RACE [30], Story Cloze [40] Sentence similarity MSR Paraphrase Corpus [14], Quora Question Pairs [9], STS Benchmark [6] Classification Stanford Sentiment Treebank-2 [54], CoLA [65]
(任务与数据集一览。)
but is shuffled at a sentence level - destroying long-range structure. Our language model achieves a very low token level perplexity of 18.4 on this corpus.
但在句子级被打乱——破坏了长程结构。我们的语言模型在该语料上达到很低的 token 级困惑度 18.4。
Model specifications Our model largely follows the original transformer work [62]. We trained a 12-layer decoder-only transformer with masked self-attention heads (768 dimensional states and 12 attention heads). For the position-wise feed-forward networks, we used 3072 dimensional inner states. We used the Adam optimization scheme [27] with a max learning rate of 2.5e-4. The learning rate was increased linearly from zero over the first 2000 updates and annealed to 0 using a cosine schedule. We train for 100 epochs on minibatches of 64 randomly sampled, contiguous sequences of 512 tokens. Since layernorm [2] is used extensively throughout the model, a simple weight initialization of N (0, 0.02) was sufficient. We used a bytepair encoding (BPE) vocabulary with 40,000 merges [53] and residual, embedding, and attention dropouts with a rate of 0.1 for regularization. We also employed a modified version of L2 regularization proposed in [37], with w = 0.01 on all non bias or gain weights. For the activation function, we used the Gaussian Error Linear Unit (GELU) [18]. We used learned position embeddings instead of the sinusoidal version proposed in the original work. We use the ftfy library2 to clean the raw text in BooksCorpus, standardize some punctuation and whitespace, and use the spaCy tokenizer.3
模型规格 我们的模型大体遵循原始 transformer 工作[62]。我们训练了 12 层仅解码器 transformer,带掩码自注意力头(768 维状态、12 个注意力头)。按位置前馈网络使用 3072 维内部状态。优化使用 Adam[27],最大学习率 2.5e-4。学习率在前 2000 次更新从零线性升高,再按余弦日程退火到 0。在大小为 64、随机采样的连续 512 token 序列小批次上训练 100 个 epoch。由于模型中广泛使用 layernorm[2],简单的 权重初始化即足够。使用带 40,000 次合并的字节对编码(BPE)词表[53],并对残差、嵌入与注意力使用 0.1 的 dropout 正则。我们还采用[37]提出的改进 L2 正则,对所有非 bias/gain 权重取 。激活函数使用高斯误差线性单元(GELU)[18]。使用学习到的位置嵌入,而非原工作提出的正弦版本。用 ftfy 库清理 BooksCorpus 原始文本、标准化部分标点与空白,并用 spaCy 分词。
Fine-tuning details Unless specified, we reuse the hyperparameter settings from unsupervised pre-training. We add dropout to the classifier with a rate of 0.1. For most tasks, we use a learning rate of 6.25e-5 and a batchsize of 32. Our model finetunes quickly and 3 epochs of training was sufficient for most cases. We use a linear learning rate decay schedule with warmup over 0.2% of training. λ was set to 0.5.
微调细节 除非另行说明,我们复用无监督预训练的超参设定。给分类器加 0.1 的 dropout。多数任务使用学习率 6.25e-5、批次大小 32。模型微调很快,多数情形 3 个 epoch 即足够。使用带 0.2% 训练量预热的线性学习率衰减日程。 设为 0.5。
4.2 Supervised fine-tuning
4.2 有监督微调
We perform experiments on a variety of supervised tasks including natural language inference, question answering, semantic similarity, and text classification. Some of these tasks are available as part of the recently released GLUE multi-task benchmark [64], which we make use of. Figure 1 provides an overview of all the tasks and datasets.
我们在自然语言推理、问答、语义相似度与文本分类等多种有监督任务上做实验。其中部分任务可在新近发布的 GLUE 多任务基准[64]中获得,我们亦加以使用。图 1 概述了全部任务与数据集。
Natural Language Inference The task of natural language inference (NLI), also known as recognizing textual entailment, involves reading a pair of sentences and judging the relationship between them from one of entailment, contradiction or neutral. Although there has been a lot of recent interest [58, 35, 44], the task remains challenging due to the presence of a wide variety of phenomena like lexical entailment, coreference, and lexical and syntactic ambiguity. We evaluate on five datasets with diverse sources, including image captions (SNLI), transcribed speech, popular fiction, and government reports (MNLI), Wikipedia articles (QNLI), science exams (SciTail) or news articles (RTE). Table 2 details various results on the different NLI tasks for our model and previous state-of-the-art approaches. Our method significantly outperforms the baselines on four of the five datasets, achieving absolute improvements of upto 1.5% on MNLI, 5% on SciTail, 5.8% on QNLI and 0.6% on SNLI over the previous best results. This demonstrates our model’s ability to better reason over multiple sentences, and handle aspects of linguistic ambiguity. On RTE, one of the smaller datasets we evaluate on (2490 examples), we achieve an accuracy of 56%, which is below the 61.7% reported by a multi-task biLSTM model. Given the strong performance of our approach on larger NLI datasets, it is likely our model will benefit from multi-task training as well but we have not explored this currently. 2 https://ftfy.readthedocs.io/en/latest/ 3 https://spacy.io/
自然语言推理 自然语言推理(NLI)又称识别文本蕴含,需要阅读一对句子并判断其间关系属于蕴含、矛盾或中性。尽管近期兴趣很高[58, 35, 44],该任务仍因词汇蕴含、共指以及词汇与句法歧义等广泛现象而具有挑战性。我们在五个来源多样的数据集上评估,包括图像描述(SNLI)、转写语音、流行小说与政府报告(MNLI)、维基百科文章(QNLI)、科学考试(SciTail)或新闻文章(RTE)。表 2 详列我们的模型与先前最优方法在各 NLI 任务上的结果。我们的方法在五个数据集中的四个上显著超过基线,相对先前最佳结果在 MNLI 上绝对提升最多 1.5%,SciTail 上 5%,QNLI 上 5.8%,SNLI 上 0.6%。这表明模型能更好地跨多句推理,并处理语言歧义面向。在 RTE(我们评估的较小数据集之一,2490 例)上,我们达到 56% 准确率,低于多任务 biLSTM 模型报告的 61.7%。鉴于本方法在更大 NLI 数据集上的强表现,模型很可能也会受益于多任务训练,但我们目前尚未探索。
Table 2: Experimental results on natural language inference tasks, comparing our model with current state-of-the-art methods. 5x indicates an ensemble of 5 models. All datasets use accuracy as the evaluation metric.
表 2:自然语言推理任务实验结果,与当前最优方法比较。5x 表示 5 模型集成。所有数据集以准确率为评估指标。
Method MNLI-m MNLI-mm SNLI SciTail QNLI RTE ESIM + ELMo [44] (5x) - - 89.3 - - CAFE [58] (5x) 80.2 79.0 89.3 - - Stochastic Answer Network [35] (3x) 80.6 80.1 - - - CAFE [58] 78.7 77.9 88.5 83.3 GenSen [64] 71.4 71.3 - - 82.3 59.2 Multi-task BiLSTM + Attn [64] 72.2 72.1 - - 82.1 61.7 Finetuned Transformer LM (ours) 82.1 81.4 89.9 88.3 88.1 56.0
Table 3: Results on question answering and commonsense reasoning, comparing our model with current state-of-the-art methods.. 9x means an ensemble of 9 models.
表 3:问答与常识推理结果,与当前最优方法比较。9x 表示 9 模型集成。
Method Story Cloze RACE-m RACE-h RACE val-LS-skip [55] 76.5 - - Hidden Coherence Model [7] 77.6 - - Dynamic Fusion Net [67] (9x) - 55.6 49.4 51.2 BiAttention MRU [59] (9x) - 60.2 50.3 53.3 Finetuned Transformer LM (ours) 86.5 62.9 57.4 59.0
Question answering and commonsense reasoning Another task that requires aspects of single and multi-sentence reasoning is question answering. We use the recently released RACE dataset [30], consisting of English passages with associated questions from middle and high school exams. This corpus has been shown to contain more reasoning type questions that other datasets like CNN [19] or SQuaD [47], providing the perfect evaluation for our model which is trained to handle long-range contexts. In addition, we evaluate on the Story Cloze Test [40], which involves selecting the correct ending to multi-sentence stories from two options. On these tasks, our model again outperforms the previous best results by significant margins - up to 8.9% on Story Cloze, and 5.7% overall on RACE. This demonstrates the ability of our model to handle long-range contexts effectively.
问答与常识推理 另一需要单句与多句推理面向的任务是问答。我们使用新近发布的 RACE 数据集[30],由中学与高中考试中的英文篇章及配套问题组成。该语料被证明包含比 CNN[19] 或 SQuAD[47] 等数据集更多的推理型问题,为我们训练来处理长程上下文的模型提供了理想评估。此外,我们在 Story Cloze Test[40] 上评估,任务是从两个选项中为多句故事选择正确结尾。在这些任务上,我们的模型再次以显著幅度超过先前最佳结果——Story Cloze 上最多 8.9%,RACE 整体上 5.7%。这表明模型能有效处理长程上下文。
Semantic Similarity Semantic similarity (or paraphrase detection) tasks involve predicting whether two sentences are semantically equivalent or not. The challenges lie in recognizing rephrasing of concepts, understanding negation, and handling syntactic ambiguity. We use three datasets for this task – the Microsoft Paraphrase corpus (MRPC) [14] (collected from news sources), the Quora Question Pairs (QQP) dataset [9], and the Semantic Textual Similarity benchmark (STS-B) [6]. We obtain state-of-the-art results on two of the three semantic similarity tasks (Table 4) with a 1 point absolute gain on STS-B. The performance delta on QQP is significant, with a 4.2% absolute improvement over Single-task BiLSTM + ELMo + Attn.
Classification Finally, we also evaluate on two different text classification tasks. The Corpus of Linguistic Acceptability (CoLA) [65] contains expert judgements on whether a sentence is grammatical or not, and tests the innate linguistic bias of trained models. The Stanford Sentiment Treebank (SST-2) [54], on the other hand, is a standard binary classification task. Our model obtains an score of 45.4 on CoLA, which is an especially big jump over the previous best result of 35.0, showcasing the innate linguistic bias learned by our model. The model also achieves 91.3% accuracy on SST-2, which is competitive with the state-of-the-art results. We also achieve an overall score of 72.8 on the GLUE benchmark, which is significantly better than the previous best of 68.9.
分类 最后,我们还在两个不同的文本分类任务上评估。语言可接受性语料(CoLA)[65]包含专家对句子是否合乎语法的判断,检验训练模型的先天语言偏向。斯坦福情感树库(SST-2)[54]则是标准二分类任务。我们的模型在 CoLA 上得到 45.4 分,相对先前最佳 35.0 有尤其大的跃升,展示了模型学到的先天语言偏向。模型在 SST-2 上也达到 91.3% 准确率,与当时最优有竞争力。我们在 GLUE 基准上总体得分 72.8,显著优于先前最佳 68.9。
Table 4: Semantic similarity and classification results, comparing our model with current state-of-theart methods. All task evaluations in this table were done using the GLUE benchmark. (mc= Mathews correlation, acc=Accuracy, pc=Pearson correlation)
表 4:语义相似度与分类结果,与当前最优方法比较。本表所有任务评估均使用 GLUE 基准。(mc=Matthews 相关,acc=准确率,pc=Pearson 相关)
Method Classification Semantic Similarity GLUE CoLA SST2 MRPC STSB QQP (mc) (acc) (F1) (pc) (F1) Sparse byte mLSTM [16] - 93.2 - - - TF-KLD [23] - - 86.0 - - ECNU (mixed ensemble) [60] - - - 81.0 - Single-task BiLSTM + ELMo + Attn [64] 35.0 90.2 80.2 55.5 66.1 64.8 Multi-task BiLSTM + ELMo + Attn [64] 18.9 91.6 83.5 72.8 63.3 68.9 Finetuned Transformer LM (ours) 45.4 91.3 82.3 82.0 70.3 72.8
Overall, our approach achieves new state-of-the-art results in 9 out of the 12 datasets we evaluate on, outperforming ensembles in many cases. Our results also indicate that our approach works well across datasets of different sizes, from smaller datasets such as STS-B (≈5.7k training examples) – to the largest one – SNLI (≈550k training examples).
总体而言,我们的方法在所评估的 12 个数据集中有 9 个取得新的当时最优,许多情形下超过集成方法。结果还表明本方法适用于不同规模的数据集,从小数据集如 STS-B(约 5.7k 训练样本)到最大的 SNLI(约 550k 训练样本)。
5 Analysis
5 分析
Impact of number of layers transferred We observed the impact of transferring a variable number of layers from unsupervised pre-training to the supervised target task. Figure 2(left) illustrates the performance of our approach on MultiNLI and RACE as a function of the number of layers transferred. We observe the standard result that transferring embeddings improves performance and that each transformer layer provides further benefits up to 9% for full transfer on MultiNLI. This indicates that each layer in the pre-trained model contains useful functionality for solving target tasks.
迁移层数的影响 我们观察从无监督预训练向有监督目标任务迁移可变层数的影响。图 2(左)展示本方法在 MultiNLI 与 RACE 上随迁移层数变化的性能。我们观察到标准结果:迁移嵌入可提升性能,且每个 transformer 层都能进一步带来收益,在 MultiNLI 上完整迁移最多约 9%。这表明预训练模型的每一层都包含对解决目标任务有用的功能。
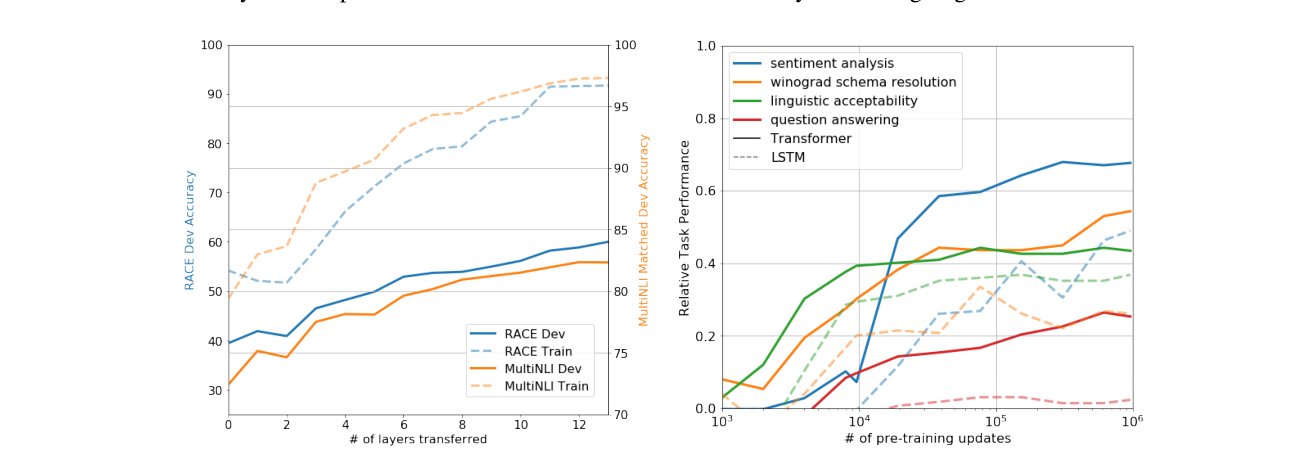
Figure 2: (left) Effect of transferring increasing number of layers from the pre-trained language model on RACE and MultiNLI. (right) Plot showing the evolution of zero-shot performance on different tasks as a function of LM pre-training updates. Performance per task is normalized between a random guess baseline and the current state-of-the-art with a single model.
图 2:(左) 从预训练语言模型迁移递增层数对 RACE 与 MultiNLI 的影响。(右) 不同任务零样本性能随 LM 预训练更新次数的演化。每任务性能在随机猜测基线与单模型当前最优之间归一化。
Zero-shot Behaviors We’d like to better understand why language model pre-training of transformers is effective. A hypothesis is that the underlying generative model learns to perform many of the tasks we evaluate on in order to improve its language modeling capability and that the more structured
零样本行为 我们希望更好理解为何对 transformer 做语言建模预训练有效。一个假说是:底层生成模型为改进语言建模能力而学会执行我们评估的许多任务,且更结构化的
Table 5: Analysis of various model ablations on different tasks. Avg. score is a unweighted average of all the results. (mc= Mathews correlation, acc=Accuracy, pc=Pearson correlation)
表 5:不同任务上各种模型消融分析。Avg. score 为所有结果的未加权平均。(mc=Matthews 相关,acc=准确率,pc=Pearson 相关)
Method Avg. Score CoLA SST2 MRPC STSB QQP MNLI QNLI RTE (mc) (acc) (F1) (pc) (F1) (acc) (acc) (acc) Transformer w/ aux LM (full) 74.7 45.4 91.3 82.3 82.0 70.3 81.8 88.1 56.0 Transformer w/o pre-training 59.9 18.9 84.0 79.4 30.9 65.5 75.7 71.2 53.8 Transformer w/o aux LM 75.0 47.9 92.0 84.9 83.2 69.8 81.1 86.9 54.4 LSTM w/ aux LM 69.1 30.3 90.5 83.2 71.8 68.1 73.7 81.1 54.6
attentional memory of the transformer assists in transfer compared to LSTMs. We designed a series of heuristic solutions that use the underlying generative model to perform tasks without supervised finetuning. We visualize the effectiveness of these heuristic solutions over the course of generative pre-training in Fig 2(right). We observe the performance of these heuristics is stable and steadily increases over training suggesting that generative pretraining supports the learning of a wide variety of task relevant functionality. We also observe the LSTM exhibits higher variance in its zero-shot performance suggesting that the inductive bias of the Transformer architecture assists in transfer. For CoLA (linguistic acceptability), examples are scored as the average token log-probability the generative model assigns and predictions are made by thresholding. For SST-2 (sentiment analysis), we append the token very to each example and restrict the language model’s output distribution to only the words positive and negative and guess the token it assigns higher probability to as the prediction. For RACE (question answering), we pick the answer the generative model assigns the highest average token log-probability when conditioned on the document and question. For DPRD [46] (winograd schemas), we replace the definite pronoun with the two possible referrents and predict the resolution that the generative model assigns higher average token log-probability to the rest of the sequence after the substitution.
注意力记忆相对 LSTM 更有助于迁移。我们设计了一系列启发式方案,用底层生成模型在不做有监督微调的情况下执行任务。图 2(右)可视化这些启发式方案在生成式预训练过程中的有效性。我们观察到这些启发式的性能稳定,并随训练稳步提升,表明生成式预训练支持学习广泛的任务相关功能。我们也观察到 LSTM 的零样本性能方差更高,表明 Transformer 架构的归纳偏置有助于迁移。对 CoLA(语言可接受性),样本按生成模型赋予的平均 token 对数概率打分,并通过阈值做预测。对 SST-2(情感分析),我们在每个样本后附加 token very,并把语言模型输出分布限制为仅含 positive 与 negative,选取其赋予更高概率的 token 作为预测。对 RACE(问答),我们选择生成模型赋予最高平均
Ablation studies We perform three different ablation studies (Table 5). First, we examine the performance of our method without the auxiliary LM objective during fine-tuning. We observe that the auxiliary objective helps on the NLI tasks and QQP. Overall, the trend suggests that larger datasets benefit from the auxiliary objective but smaller datasets do not. Second, we analyze the effect of the Transformer by comparing it with a single layer 2048 unit LSTM using the same framework. We observe a 5.6 average score drop when using the LSTM instead of the Transformer. The LSTM only outperforms the Transformer on one dataset – MRPC. Finally, we also compare with our transformer architecture directly trained on supervised target tasks, without pre-training. We observe that the lack of pre-training hurts performance across all the tasks, resulting in a 14.8% decrease compared to our full model.
消融研究 我们做三项消融(表 5)。第一,考察微调时去掉辅助 LM 目标的性能。我们观察到辅助目标在 NLI 任务与 QQP 上有帮助。总体趋势表明更大的数据集受益于辅助目标,而较小数据集则不然。第二,通过与使用同一框架的单层 2048 单元 LSTM 比较来分析 Transformer 的作用。用 LSTM 替代 Transformer 时平均分下降 5.6。LSTM 仅在一个数据集——MRPC——上超过 Transformer。最后,我们还与直接在有监督目标任务上训练、不做预训练的 transformer 架构比较。缺少预训练会伤害所有任务的性能,相对完整模型下降 14.8%。
6 Conclusion
6 结论
We introduced a framework for achieving strong natural language understanding with a single task-agnostic model through generative pre-training and discriminative fine-tuning. By pre-training on a diverse corpus with long stretches of contiguous text our model acquires significant world knowledge and ability to process long-range dependencies which are then successfully transferred to solving discriminative tasks such as question answering, semantic similarity assessment, entailment determination, and text classification, improving the state of the art on 9 of the 12 datasets we study. Using unsupervised (pre-)training to boost performance on discriminative tasks has long been an important goal of Machine Learning research. Our work suggests that achieving significant performance gains is indeed possible, and offers hints as to what models (Transformers) and data sets (text with long range dependencies) work best with this approach. We hope that this will help enable new research into unsupervised learning, for both natural language understanding and other domains, further improving our understanding of how and when unsupervised learning works.
我们提出通过生成式预训练与判别式微调、用单一任务无关模型实现强自然语言理解的框架。通过在包含长段连续文本的多样语料上预训练,模型获得显著的世界知识与处理长程依赖的能力,再成功迁移到问答、语义相似度评估、蕴含判定与文本分类等判别任务,在所研究的 12 个数据集中改进其中 9 个的当时最优。用无监督(预)训练提升判别任务性能长期是机器学习研究的重要目标。本工作表明取得显著性能增益确实可能,并提示何种模型(Transformer)与数据集(具有长程依赖的文本)最适合这一路径。我们希望这将推动面向自然语言理解及其他领域的无监督学习新研究,进一步加深我们对无监督学习何时、如何奏效的理解。
References
参考文献
[1] S. Arora, Y. Liang, and T. Ma. A simple but tough-to-beat baseline for sentence embeddings. 2016.
[2] J. L. Ba, J. R. Kiros, and G. E. Hinton. Layer normalization. arXiv preprint arXiv:1607.06450, 2016.
[3] Y. Bengio, P. Lamblin, D. Popovici, and H. Larochelle. Greedy layer-wise training of deep networks. In Advances in neural information processing systems, pages 153–160, 2007.
[4] L. Bentivogli, P. Clark, I. Dagan, and D. Giampiccolo. The fifth pascal recognizing textual entailment challenge. In TAC, 2009.
[5] S. R. Bowman, G. Angeli, C. Potts, and C. D. Manning. A large annotated corpus for learning natural language inference. EMNLP, 2015.
[6] D. Cer, M. Diab, E. Agirre, I. Lopez-Gazpio, and L. Specia. Semeval-2017 task 1: Semantic textual similarity-multilingual and cross-lingual focused evaluation. arXiv preprint arXiv:1708.00055, 2017.
[7] S. Chaturvedi, H. Peng, and D. Roth. Story comprehension for predicting what happens next. In Proceedings of the 2017 Conference on Empirical Methods in Natural Language Processing, pages 1603–1614, 2017.
[8] D. Chen and C. Manning. A fast and accurate dependency parser using neural networks. In Proceedings of the 2014 conference on empirical methods in natural language processing (EMNLP), pages 740–750, 2014.
[9] Z. Chen, H. Zhang, X. Zhang, and L. Zhao. Quora question pairs. https://data.quora.com/First-QuoraDataset-Release-Question-Pairs, 2018.
[10] R. Collobert and J. Weston. A unified architecture for natural language processing: Deep neural networks with multitask learning. In Proceedings of the 25th international conference on Machine learning, pages 160–167. ACM, 2008.
[11] R. Collobert, J. Weston, L. Bottou, M. Karlen, K. Kavukcuoglu, and P. Kuksa. Natural language processing (almost) from scratch. Journal of Machine Learning Research, 12(Aug):2493–2537, 2011.
[12] A. Conneau, D. Kiela, H. Schwenk, L. Barrault, and A. Bordes. Supervised learning of universal sentence representations from natural language inference data. EMNLP, 2017.
[13] A. M. Dai and Q. V. Le. Semi-supervised sequence learning. In Advances in Neural Information Processing Systems, pages 3079–3087, 2015.
[14] W. B. Dolan and C. Brockett. Automatically constructing a corpus of sentential paraphrases. In Proceedings of the Third International Workshop on Paraphrasing (IWP2005), 2005.
[15] D. Erhan, Y. Bengio, A. Courville, P.-A. Manzagol, P. Vincent, and S. Bengio. Why does unsupervised pre-training help deep learning? Journal of Machine Learning Research, 11(Feb):625–660, 2010.
[16] S. Gray, A. Radford, and K. P. Diederik. Gpu kernels for block-sparse weights. 2017.
[17] Z. He, S. Liu, M. Li, M. Zhou, L. Zhang, and H. Wang. Learning entity representation for entity disambiguation. In Proceedings of the 51st Annual Meeting of the Association for Computational Linguistics (Volume 2: Short Papers), volume 2, pages 30–34, 2013.
[18] D. Hendrycks and K. Gimpel. Bridging nonlinearities and stochastic regularizers with gaussian error linear units. arXiv preprint arXiv:1606.08415, 2016.
[19] K. M. Hermann, T. Kocisky, E. Grefenstette, L. Espeholt, W. Kay, M. Suleyman, and P. Blunsom. Teaching machines to read and comprehend. In Advances in Neural Information Processing Systems, pages 1693– 1701, 2015.
[20] G. E. Hinton, S. Osindero, and Y.-W. Teh. A fast learning algorithm for deep belief nets. Neural computation, 18(7):1527–1554, 2006.
[21] J. Howard and S. Ruder. Universal language model fine-tuning for text classification. Association for Computational Linguistics (ACL), 2018.
[22] Y. Jernite, S. R. Bowman, and D. Sontag. Discourse-based objectives for fast unsupervised sentence representation learning. arXiv preprint arXiv:1705.00557, 2017.
[23] Y. Ji and J. Eisenstein. Discriminative improvements to distributional sentence similarity. In Proceedings of the 2013 Conference on Empirical Methods in Natural Language Processing, pages 891–896, 2013.
[24] F. Jiao, S. Wang, C.-H. Lee, R. Greiner, and D. Schuurmans. Semi-supervised conditional random fields for improved sequence segmentation and labeling. In Proceedings of the 21st International Conference on Computational Linguistics and the 44th annual meeting of the Association for Computational Linguistics, pages 209–216. Association for Computational Linguistics, 2006.
[25] T. Khot, A. Sabharwal, and P. Clark. Scitail: A textual entailment dataset from science question answering. In Proceedings of AAAI, 2018.
[26] Y. Kim. Convolutional neural networks for sentence classification. EMNLP, 2014.
[27] D. P. Kingma and J. Ba. Adam: A method for stochastic optimization. arXiv preprint arXiv:1412.6980, 2014.
[28] R. Kiros, Y. Zhu, R. R. Salakhutdinov, R. Zemel, R. Urtasun, A. Torralba, and S. Fidler. Skip-thought vectors. In Advances in neural information processing systems, pages 3294–3302, 2015.
[29] N. Kitaev and D. Klein. Constituency parsing with a self-attentive encoder. ACL, 2018.
[30] G. Lai, Q. Xie, H. Liu, Y. Yang, and E. Hovy. Race: Large-scale reading comprehension dataset from examinations. EMNLP, 2017.
[31] G. Lample, L. Denoyer, and M. Ranzato. Unsupervised machine translation using monolingual corpora only. ICLR, 2018.
[32] Q. Le and T. Mikolov. Distributed representations of sentences and documents. In International Conference on Machine Learning, pages 1188–1196, 2014.
[33] P. Liang. Semi-supervised learning for natural language. PhD thesis, Massachusetts Institute of Technology, 2005.
[34] P. J. Liu, M. Saleh, E. Pot, B. Goodrich, R. Sepassi, L. Kaiser, and N. Shazeer. Generating wikipedia by summarizing long sequences. ICLR, 2018.
[35] X. Liu, K. Duh, and J. Gao. Stochastic answer networks for natural language inference. arXiv preprint arXiv:1804.07888, 2018.
[36] L. Logeswaran and H. Lee. An efficient framework for learning sentence representations. ICLR, 2018.
[37] I. Loshchilov and F. Hutter. Fixing weight decay regularization in adam. arXiv preprint arXiv:1711.05101, 2017.
[38] B. McCann, J. Bradbury, C. Xiong, and R. Socher. Learned in translation: Contextualized word vectors. In Advances in Neural Information Processing Systems, pages 6297–6308, 2017.
[39] T. Mikolov, I. Sutskever, K. Chen, G. S. Corrado, and J. Dean. Distributed representations of words and phrases and their compositionality. In Advances in neural information processing systems, pages 3111–3119, 2013.
[40] N. Mostafazadeh, M. Roth, A. Louis, N. Chambers, and J. Allen. Lsdsem 2017 shared task: The story cloze test. In Proceedings of the 2nd Workshop on Linking Models of Lexical, Sentential and Discourse-level Semantics, pages 46–51, 2017.
[41] K. Nigam, A. McCallum, and T. Mitchell. Semi-supervised text classification using em. Semi-Supervised Learning, pages 33–56, 2006.
[42] J. Pennington, R. Socher, and C. Manning. Glove: Global vectors for word representation. In Proceedings of the 2014 conference on empirical methods in natural language processing (EMNLP), pages 1532–1543, 2014.
[43] M. E. Peters, W. Ammar, C. Bhagavatula, and R. Power. Semi-supervised sequence tagging with bidirectional language models. ACL, 2017.
[44] M. E. Peters, M. Neumann, M. Iyyer, M. Gardner, C. Clark, K. Lee, and L. Zettlemoyer. Deep contextualized word representations. NAACL, 2018.
[45] Y. Qi, D. S. Sachan, M. Felix, S. J. Padmanabhan, and G. Neubig. When and why are pre-trained word embeddings useful for neural machine translation? NAACL, 2018.
[46] A. Rahman and V. Ng. Resolving complex cases of definite pronouns: the winograd schema challenge. In Proceedings of the 2012 Joint Conference on Empirical Methods in Natural Language Processing and Computational Natural Language Learning, pages 777–789. Association for Computational Linguistics, 2012.
[47] P. Rajpurkar, J. Zhang, K. Lopyrev, and P. Liang. Squad: 100,000+ questions for machine comprehension of text. EMNLP, 2016.
[48] P. Ramachandran, P. J. Liu, and Q. V. Le. Unsupervised pretraining for sequence to sequence learning. arXiv preprint arXiv:1611.02683, 2016.
[49] M. Ranzato, C. Poultney, S. Chopra, and Y. LeCun. Efficient learning of sparse representations with an energy-based model. In Advances in neural information processing systems, pages 1137–1144, 2007.
[50] M. Rei. Semi-supervised multitask learning for sequence labeling. ACL, 2017.
[51] H. Robbins and S. Monro. A stochastic approximation method. The annals of mathematical statistics, pages 400–407, 1951.
[52] T. Rocktäschel, E. Grefenstette, K. M. Hermann, T. Kočiskỳ, and P. Blunsom. Reasoning about entailment with neural attention. arXiv preprint arXiv:1509.06664, 2015.
[53] R. Sennrich, B. Haddow, and A. Birch. Neural machine translation of rare words with subword units. arXiv preprint arXiv:1508.07909, 2015.
[54] R. Socher, A. Perelygin, J. Wu, J. Chuang, C. D. Manning, A. Ng, and C. Potts. Recursive deep models for semantic compositionality over a sentiment treebank. In Proceedings of the 2013 conference on empirical methods in natural language processing, pages 1631–1642, 2013.
[55] S. Srinivasan, R. Arora, and M. Riedl. A simple and effective approach to the story cloze test. arXiv preprint arXiv:1803.05547, 2018.
[56] S. Subramanian, A. Trischler, Y. Bengio, and C. J. Pal. Learning general purpose distributed sentence representations via large scale multi-task learning. arXiv preprint arXiv:1804.00079, 2018.
[57] J. Suzuki and H. Isozaki. Semi-supervised sequential labeling and segmentation using giga-word scale unlabeled data. Proceedings of ACL-08: HLT, pages 665–673, 2008.
[58] Y. Tay, L. A. Tuan, and S. C. Hui. A compare-propagate architecture with alignment factorization for natural language inference. arXiv preprint arXiv:1801.00102, 2017.
[59] Y. Tay, L. A. Tuan, and S. C. Hui. Multi-range reasoning for machine comprehension. arXiv preprint arXiv:1803.09074, 2018.
[60] J. Tian, Z. Zhou, M. Lan, and Y. Wu. Ecnu at semeval-2017 task 1: Leverage kernel-based traditional nlp features and neural networks to build a universal model for multilingual and cross-lingual semantic textual similarity. In Proceedings of the 11th International Workshop on Semantic Evaluation (SemEval-2017), pages 191–197, 2017.
[61] Y. Tsvetkov. Opportunities and challenges in working with low-resource languages. CMU, 2017.
[62] A. Vaswani, N. Shazeer, N. Parmar, J. Uszkoreit, L. Jones, A. N. Gomez, Ł. Kaiser, and I. Polosukhin. Attention is all you need. In Advances in Neural Information Processing Systems, pages 6000–6010, 2017.
[63] P. Vincent, H. Larochelle, Y. Bengio, and P.-A. Manzagol. Extracting and composing robust features with denoising autoencoders. In Proceedings of the 25th international conference on Machine learning, pages 1096–1103. ACM, 2008.
[64] A. Wang, A. Singh, J. Michael, F. Hill, O. Levy, and S. R. Bowman. Glue: A multi-task benchmark and analysis platform for natural language understanding. arXiv preprint arXiv:1804.07461, 2018.
[65] A. Warstadt, A. Singh, and S. R. Bowman. Corpus of linguistic acceptability. http://nyu-mll.github.io/cola, 2018.
[66] A. Williams, N. Nangia, and S. R. Bowman. A broad-coverage challenge corpus for sentence understanding through inference. NAACL, 2018.
[67] Y. Xu, J. Liu, J. Gao, Y. Shen, and X. Liu. Towards human-level machine reading comprehension: Reasoning and inference with multiple strategies. arXiv preprint arXiv:1711.04964, 2017.
[68] D. Yu, L. Deng, and G. Dahl. Roles of pre-training and fine-tuning in context-dependent dbn-hmms for real-world speech recognition. In Proc. NIPS Workshop on Deep Learning and Unsupervised Feature Learning, 2010.
[69] R. Zhang, P. Isola, and A. A. Efros. Split-brain autoencoders: Unsupervised learning by cross-channel prediction. In CVPR, volume 1, page 6, 2017.
[70] X. Zhu. Semi-supervised learning literature survey. 2005.
[71] Y. Zhu, R. Kiros, R. Zemel, R. Salakhutdinov, R. Urtasun, A. Torralba, and S. Fidler. Aligning books and movies: Towards story-like visual explanations by watching movies and reading books. In Proceedings of the IEEE international conference on computer vision, pages 19–27, 2015.