Glow: Generative Flow with Invertible 1x1 Convolutions
Glow: Generative Flow with Invertible 11 Convolutions
Glow:带可逆 卷积的生成流
Diederik P. Kingma Prafulla DhariwalOpenAI, San Francisco Thanks: Equal contribution.
Abstract
摘要
Flow-based generative models (Dinh et al., 2014) are conceptually attractive due to tractability of the exact log-likelihood, tractability of exact latent-variable inference, and parallelizability of both training and synthesis. In this paper we propose Glow, a simple type of generative flow using an invertible convolution. Using our method we demonstrate a significant improvement in log-likelihood on standard benchmarks. Perhaps most strikingly, we demonstrate that a generative model optimized towards the plain log-likelihood objective is capable of efficient realistic-looking synthesis and manipulation of large images. The code for our model is available at https://github.com/openai/glow.
基于流的生成模型 (Dinh et al., 2014) 概念上有吸引力:精确对数似然可算、潜变量推断精确可算,且训练与合成都可并行。本文提出 Glow:一种使用可逆 卷积的简洁生成流。该方法在标准基准上显著改善对数似然;更醒目的是,仅优化普通对数似然目标的生成模型,也能高效地合成并操纵看起来真实的大图。代码见 https://github.com/openai/glow。
1 Introduction
1 引言
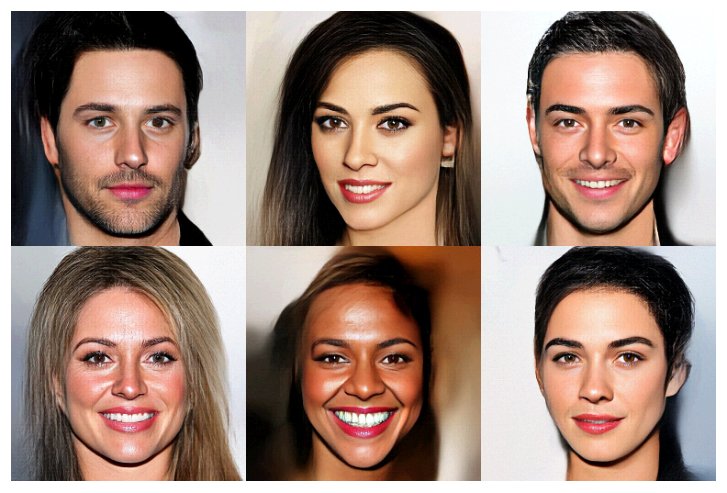
Figure 1: Synthetic celebrities sampled from our model; see Section 3 for architecture and method, and Section 5 for more results.
图 1:自我们模型采样的合成名人面孔;结构与方法见第 3 节,更多结果见第 5 节。
Two major unsolved problems in the field of machine learning are (1) data-efficiency: the ability to learn from few datapoints, like humans; and (2) generalization: robustness to changes of the task or its context. AI systems, for example, often do not work at all when given inputs that are different from their training distribution. A promise of generative models, a major branch of machine learning, is to overcome these limitations by: (1) learning realistic world models, potentially allowing agents to plan in a world model before actual interaction with the world, and (2) learning meaningful features of the input while requiring little or no human supervision or labeling. Since such features can be learned from large unlabeled datasets and are not necessarily task-specific, downstream solutions based on those features could potentially be more robust and more data efficient. In this paper we work towards this ultimate vision, in addition to intermediate applications, by aiming to improve upon the state-of-the-art of generative models.
机器学习中两大未解问题是:(1) 数据效率——像人一样从少量样本学习;(2) 泛化——对任务或其上下文变化保持稳健。例如,输入偏离训练分布时,许多 AI 系统会完全失效。生成模型作为机器学习的重要分支,承诺通过以下途径缓解这些限制:(1) 学习逼真的世界模型,使智能体可在与真实世界交互前先在世界模型中规划;(2) 在很少或无需人工标注下学习输入的有意义特征。这类特征可从大规模无标注数据学得、且不必绑定特定任务,基于它们的下游方案有望更稳健、更省数据。本文除中间应用外,也朝这一长远目标推进,着力改进生成模型的前沿水平。
Generative modeling is generally concerned with the extremely challenging task of modeling all dependencies within very high-dimensional input data, usually specified in the form of a full joint probability distribution. Since such joint models potentially capture all patterns that are present in the data, the applications of accurate generative models are near endless. Immediate applications are as diverse as speech synthesis, text analysis, semi-supervised learning and model-based control; see Section 4 for references.
生成建模通常要在极高维输入上刻画全部依赖,并以完整联合概率分布形式给出。一旦联合模型足够准确,应用近乎无穷;直接用途涵盖语音合成、文本分析、半监督学习与基于模型的控制等,参见第 4 节文献。
The discipline of generative modeling has experienced enormous leaps in capabilities in recent years, mostly with likelihood-based methods (Graves, 2013; Kingma and Welling, 2013; Kingma and Welling, 2018; Dinh et al., 2014; van den Oord et al., 2016a) and generative adversarial networks (GANs) (Goodfellow et al., 2014) (see Section 4). Likelihood-based methods can be divided into three categories:
近年来生成建模能力跃升,主要来自基于似然的方法 (Graves, 2013; Kingma and Welling, 2013; Kingma and Welling, 2018; Dinh et al., 2014; van den Oord et al., 2016a) 与生成对抗网络(GANs) (Goodfellow et al., 2014)(见第 4 节)。基于似然的方法大致分三类:
- Autoregressive models (Hochreiter and Schmidhuber, 1997; Graves, 2013; van den Oord et al., 2016a; van den Oord et al., 2016b; Van Den Oord et al., 2016). Those have the advantage of simplicity, but have as disadvantage that synthesis has limited parallelizability, since the computational length of synthesis is proportional to the dimensionality of the data; this is especially troublesome for large images or video.
- 自回归模型 (Hochreiter and Schmidhuber, 1997; Graves, 2013; van den Oord et al., 2016a; van den Oord et al., 2016b; Van Den Oord et al., 2016)。优点是简洁,缺点是合成并行性有限:合成计算长度与数据维数成正比,对大图或视频尤甚。
- Variational autoencoders (VAEs) (Kingma and Welling, 2013; Kingma and Welling, 2018), which optimize a lower bound on the log-likelihood of the data. Variational autoencoders have the advantage of parallelizability of training and synthesis, but can be comparatively challenging to optimize (Kingma et al., 2016).
- 变分自编码器(VAEs) (Kingma and Welling, 2013; Kingma and Welling, 2018),优化数据对数似然的下界。优点是训练与合成均可并行,但优化可能相对困难 (Kingma et al., 2016)。
- Flow-based generative models, first described in NICE (Dinh et al., 2014) and extended in RealNVP (Dinh et al., 2016). We explain the key ideas behind this class of model in the following sections.
- 基于流的生成模型,始见于 NICE (Dinh et al., 2014),并在 RealNVP (Dinh et al., 2016) 中扩展。后续章节解释该类模型的关键思想。
Flow-based generative models have so far gained little attention in the research community compared to GANs (Goodfellow et al., 2014) and VAEs (Kingma and Welling, 2013). Some of the merits of flow-based generative models include:
相对 GAN (Goodfellow et al., 2014) 与 VAE (Kingma and Welling, 2013),基于流的生成模型迄今较少受关注。其若干优点包括:
- • Exact latent-variable inference and log-likelihood evaluation. In VAEs, one is able to infer only approximately the value of the latent variables that correspond to a datapoint. GAN’s have no encoder at all to infer the latents. In reversible generative models, this can be done exactly without approximation. Not only does this lead to accurate inference, it also enables optimization of the exact log-likelihood of the data, instead of a lower bound of it.
- • 精确的潜变量推断与对数似然评估。VAE 只能近似推断与数据点对应的潜变量;GAN 根本没有编码器。可逆生成模型可精确完成、无需近似。这不仅带来准确推断,还能优化数据的精确对数似然,而非其下界。
- • Efficient inference and efficient synthesis. Autoregressive models, such as the PixelCNN (van den Oord et al., 2016b), are also reversible, however synthesis from such models is difficult to parallelize, and typically inefficient on parallel hardware. Flow-based generative models like Glow (and RealNVP) are efficient to parallelize for both inference and synthesis.
- • 高效推断与高效合成。PixelCNN (van den Oord et al., 2016b) 等自回归模型也可逆,但合成难以并行,在并行硬件上通常低效。Glow(及 RealNVP)这类基于流的模型在推断与合成上都能高效并行。
- • Useful latent space for downstream tasks. The hidden layers of autoregressive models have unknown marginal distributions, making it much more difficult to perform valid manipulation of data. In GANs, datapoints can usually not be directly represented in a latent space, as they have no encoder and might not have full support over the data distribution. (Grover et al., 2018). This is not the case for reversible generative models and VAEs, which allow for various applications such as interpolations between datapoints and meaningful modifications of existing datapoints.
- • 有利于下游任务的潜空间。自回归模型隐层边缘分布未知,难以对数据做合法操纵。GAN 通常无法把数据点直接映到潜空间——没有编码器,且未必覆盖数据分布的全支撑 (Grover et al., 2018)。可逆生成模型与 VAE 则不然,可做数据点插值及对已有样本的有意义修改。
- • Significant potential for memory savings. Computing gradients in reversible neural networks requires an amount of memory that is constant instead of linear in their depth, as explained in the RevNet paper (Gomez et al., 2017).
- • 显著的潜在省内存空间。可逆网络求梯度所需内存相对深度是常数而非线性,见 RevNet (Gomez et al., 2017)。
In this paper we propose a new a generative flow coined Glow, with various new elements as described in Section 3. In Section 5, we compare our model quantitatively with previous flows, and in Section 6, we study the qualitative aspects of our model on high-resolution datasets.
本文提出名为 Glow 的新生成流,第 3 节描述多项新要素;第 5 节定量对比先前流模型;第 6 节在高分辨率数据上考察定性表现。
2 Background: Flow-based Generative Models
2 背景:基于流的生成模型
Let be a high-dimensional random vector with unknown true distribution . We collect an i.i.d. dataset , and choose a model with parameters . In case of discrete data , the log-likelihood objective is then equivalent to minimizing:
设 为未知真分布 的高维随机向量。我们收集 i.i.d. 数据集 ,并选择带参数 的模型 。若 离散,对数似然目标等价于最小化:
In case of continuous data , we minimize the following:
若 为连续数据,则最小化:
where with , and where is determined by the discretization level of the data and is the dimensionality of . Both objectives (eqs. (1) and (2)) measure the expected compression cost in nats or bits; see (Dinh et al., 2016). Optimization is done through stochastic gradient descent using minibatches of data (Kingma and Ba, 2015).
其中 ,,, 由数据离散化水平决定, 为 的维数。目标(式 (1)(2))度量以 nat 或 bit 计的期望压缩代价;见 (Dinh et al., 2016)。优化用小批量随机梯度下降 (Kingma and Ba, 2015)。
In most flow-based generative models (Dinh et al., 2014; Dinh et al., 2016), the generative process is defined as:
在多数基于流的生成模型 (Dinh et al., 2014; Dinh et al., 2016) 中,生成过程定义为:
where is the latent variable and has a (typically simple) tractable density, such as a spherical multivariate Gaussian distribution: . The function is invertible, also called bijective, such that given a datapoint , latent-variable inference is done by . For brevity, we will omit subscript from and .
其中 为潜变量, 具有(通常简单的)易处理密度,例如球面多元高斯 。函数 可逆(双射),给定数据点 ,潜变量推断为 。为简洁,下文省略 、 的下标 。
We focus on functions where (and, likewise, ) is composed of a sequence of transformations: , such that the relationship between and can be written as:
我们关注 (以及 )由一串变换组成的情形:,于是 与 的关系可写为:
Such a sequence of invertible transformations is also called a (normalizing) flow (Rezende and Mohamed, 2015). Under the change of variables of eq. (4), the probability density function (pdf) of the model given a datapoint can be written as:
这样一串可逆变换也称(归一化)流 (Rezende and Mohamed, 2015)。在式 (4) 的变量替换下,给定数据点时模型的概率密度可写为:
where we define and for conciseness. The scalar value is the logarithm of the absolute value of the determinant of the Jacobian matrix , also called the log-determinant. This value is the change in log-density when going from to under transformation . While it may look intimidating, its value can be surprisingly simple to compute for certain choices of transformations, as previously explored in (Deco and Brauer, 1995; Dinh et al., 2014; Rezende and Mohamed, 2015; Kingma et al., 2016). The basic idea is to choose transformations whose Jacobian is a triangular matrix. For those transformations, the log-determinant is simple:
其中为简洁定义 、。标量 是雅可比矩阵行列式绝对值的对数,也称 log-determinant,表示在变换 下从 到 的对数密度变化。看似吓人,但对某些变换其值可以惊人地简单,见 (Deco and Brauer, 1995; Dinh et al., 2014; Rezende and Mohamed, 2015; Kingma et al., 2016)。基本思路是选择雅可比 为三角阵的变换;此时 log-determinant 为:
where takes the sum over all vector elements, takes the element-wise logarithm, and takes the diagonal of the Jacobian matrix.
其中 对全部向量元素求和, 逐元素取对数, 取雅可比对角元。
(a) One step of our flow.
(a) 我们流中的一步。
3 Proposed Generative Flow
3 所提生成流
We propose a new flow, building on the NICE and RealNVP flows proposed in (Dinh et al., 2014; Dinh et al., 2016). It consists of a series of steps of flow, combined in a multi-scale architecture; see Figure 2. Each step of flow consists of actnorm (Section 3.1) followed by an invertible convolution (Section 3.2), followed by a coupling layer (Section 3.3).
我们在 NICE 与 RealNVP 流 (Dinh et al., 2014; Dinh et al., 2016) 基础上提出新流:由多步流串接,并嵌入多尺度结构,见图 2。每步依次为 actnorm(第 3.1 节)、可逆 卷积(第 3.2 节)与耦合层(第 3.3 节)。
This flow is combined with a multi-scale architecture; due to space constraints we refer to (Dinh et al., 2016) for more details. This architecture has a depth of flow , and number of levels (Figure 2).
该流与多尺度结构结合;篇幅所限细节参见 (Dinh et al., 2016)。结构具有流深度 与层级数 (图 2)。
| Description | Function | Reverse Function | Log-determinant | |||||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Actnorm. See Section 3.1. | Actnorm. | See Section 3.1. | ||||||||||||||||
| Actnorm. | ||||||||||||||||||
| See Section 3.1. | ||||||||||||||||||
| Invertible convolution. . See Section 3.2. | Invertible convolution. | . | See Section 3.2. | or (see eq. (10)) | or | (see eq. (10)) | ||||||||||||
| Invertible convolution. | ||||||||||||||||||
| . | ||||||||||||||||||
| See Section 3.2. | ||||||||||||||||||
| or | ||||||||||||||||||
| (see eq. (10)) | ||||||||||||||||||
| Affine coupling layer. See Section 3.3 and (Dinh et al., 2014) | Affine coupling layer. | See Section 3.3 and | (Dinh et al., 2014) | |||||||||||||||
| Affine coupling layer. | ||||||||||||||||||
| See Section 3.3 and | ||||||||||||||||||
| (Dinh et al., 2014) | ||||||||||||||||||
| Actnorm. |
|---|
| See Section 3.1. |
| Invertible convolution. |
|---|
| . |
| See Section 3.2. |
| or |
| (see eq. (10)) |
| Affine coupling layer. |
|---|
| See Section 3.3 and |
| (Dinh et al., 2014) |
Table 1: The three main components of our proposed flow, their reverses, and their log-determinants. Here, signifies the input of the layer, and signifies its output. Both and are tensors of shape with spatial dimensions and channel dimension . With we denote spatial indices into tensors and . The function is a nonlinear mapping, such as a (shallow) convolutional neural network like in ResNets (He et al., 2016) and RealNVP (Dinh et al., 2016).
| Description | Function | Reverse Function | Log-determinant | |||||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Actnorm. See Section 3.1. | Actnorm. | See Section 3.1. | ||||||||||||||||
| Actnorm. | ||||||||||||||||||
| See Section 3.1. | ||||||||||||||||||
| Invertible convolution. . See Section 3.2. | Invertible convolution. | . | See Section 3.2. | or (see eq. (10)) | or | (see eq. (10)) | ||||||||||||
| Invertible convolution. | ||||||||||||||||||
| . | ||||||||||||||||||
| See Section 3.2. | ||||||||||||||||||
| or | ||||||||||||||||||
| (see eq. (10)) | ||||||||||||||||||
| Affine coupling layer. See Section 3.3 and (Dinh et al., 2014) | Affine coupling layer. | See Section 3.3 and | (Dinh et al., 2014) | |||||||||||||||
| Affine coupling layer. | ||||||||||||||||||
| See Section 3.3 and | ||||||||||||||||||
| (Dinh et al., 2014) | ||||||||||||||||||
| Actnorm. |
|---|
| See Section 3.1. |
| Invertible convolution. |
|---|
| . |
| See Section 3.2. |
| or |
| (see eq. (10)) |
| Affine coupling layer. |
|---|
| See Section 3.3 and |
| (Dinh et al., 2014) |
表 1:所提流的三个主要组件、其逆变换与 log-determinant。 其中 为层输入, 为输出;二者形状均为 ,空间维 、通道维 。 表示空间下标。 为非线性映射,例如 ResNets (He et al., 2016) 与 RealNVP (Dinh et al., 2016) 中的浅层卷积网络。
3.1 Actnorm: scale and bias layer with data dependent initialization
3.1 Actnorm:带数据相关初始化的缩放与偏置层
In Dinh et al., 2016, the authors propose the use of batch normalization (Ioffe and Szegedy, 2015) to alleviate the problems encountered when training deep models. However, since the variance of activations noise added by batch normalization is inversely proportional to minibatch size per GPU or other processing unit (PU), performance is known to degrade for small per-PU minibatch size. For large images, due to memory constraints, we learn with minibatch size 1 per PU. We propose an actnorm layer (for activation normalizaton), that performs an affine transformation of the activations using a scale and bias parameter per channel, similar to batch normalization. These parameters are initialized such that the post-actnorm activations per-channel have zero mean and unit variance given an initial minibatch of data. This is a form of data dependent initialization (Salimans and Kingma, 2016). After initialization, the scale and bias are treated as regular trainable parameters that are independent of the data.
Dinh et al., 2016 提出用批归一化 (Ioffe and Szegedy, 2015) 缓解深度模型训练问题。但批归一化引入的激活噪声方差与每 GPU/处理单元(PU)的小批量大小成反比,每 PU 小批量很小时表现会下降。大图受显存限制时,我们每 PU 以 minibatch size 1 学习。为此提出 actnorm(activation normalization)层:对每通道用缩放与偏置做仿射变换,类似批归一化。参数初始化使给定初始小批量时,actnorm 后每通道激活零均值、单位方差,属于数据相关初始化 (Salimans and Kingma, 2016)。初始化后,缩放与偏置当作普通可训练参数,不再依赖数据。
3.2 Invertible convolution
3.2 可逆 卷积
(Dinh et al., 2014; Dinh et al., 2016) proposed a flow containing the equivalent of a permutation that reverses the ordering of the channels. We propose to replace this fixed permutation with a (learned) invertible convolution, where the weight matrix is initialized as a random rotation matrix. Note that a convolution with equal number of input and output channels is a generalization of a permutation operation.
(Dinh et al., 2014; Dinh et al., 2016) 提出的流包含等价于通道顺序反转的置换。我们建议用(可学习的)可逆 卷积替换该固定置换,权重矩阵初始化为随机旋转矩阵。输入输出通道数相等的 卷积是置换运算的推广。
The log-determinant of an invertible convolution of a tensor with weight matrix is straightforward to compute:
对 张量 与 权重 ,可逆 卷积的 log-determinant 容易计算:
The cost of computing or differentiating is , which is often comparable to the cost computing which is . We initialize the weights as a random rotation matrix, having a log-determinant of 0; after one SGD step these values start to diverge from 0.
计算或微分 的代价为 ,往往与计算 的 相当。我们将 初始化为随机旋转矩阵,其 log-determinant 为 0;一步 SGD 后这些值开始偏离 0。
LU Decomposition.
This cost of computing can be reduced from to by parameterizing directly in its LU decomposition:
LU 分解
通过直接用 LU 分解参数化 ,可将计算 的代价从 降到 :
where is a permutation matrix, is a lower triangular matrix with ones on the diagonal, is an upper triangular matrix with zeros on the diagonal, and is a vector. The log-determinant is then simply:
其中 为置换矩阵, 为对角为 1 的下三角阵, 为对角为 0 的上三角阵, 为向量。于是 log-determinant 就是:
The difference in computational cost will become significant for large , although for the networks in our experiments we did not measure a large difference in wallclock computation time.
当 很大时计算代价差异会显著;但对我们实验中的网络,墙钟时间差异并不大。
In this parameterization, we initialize the parameters by first sampling a random rotation matrix , then computing the corresponding value of (which remains fixed) and the corresponding initial values of and and (which are optimized).
该参数化下,先采样随机旋转矩阵 ,再计算对应的 (固定)以及 、、 的初值(可优化)。
3.3 Affine Coupling Layers
3.3 仿射耦合层
A powerful reversible transformation where the forward function, the reverse function and the log-determinant are computationally efficient, is the affine coupling layer introduced in (Dinh et al., 2014; Dinh et al., 2016). See Table 1. An additive coupling layer is a special case with and a log-determinant of 0.
前向、反向与 log-determinant 都计算高效的有力可逆变换,是 (Dinh et al., 2014; Dinh et al., 2016) 引入的仿射耦合层,见表 1。加性耦合是 且 log-determinant 为 0 的特例。
Zero initialization.
We initialize the last convolution of each with zeros, such that each affine coupling layer initially performs an identity function; we found that this helps training very deep networks.
零初始化
我们将每个 的最后一层卷积初始化为零,使每个仿射耦合层起初等价于恒等映射;我们发现这对训练很深的网络有帮助。
Split and concatenation.
As in (Dinh et al., 2014), the function splits the input tensor into two halves along the channel dimension, while the operation performs the corresponding reverse operation: concatenation into a single tensor. In (Dinh et al., 2016), another type of split was introduced: along the spatial dimensions using a checkerboard pattern. In this work we only perform splits along the channel dimension, simplifying the overall architecture.
分割与拼接
与 (Dinh et al., 2014) 一样, 沿通道维把输入张量 一分为二, 做对应的逆操作:拼回单一张量。(Dinh et al., 2016) 还引入沿空间维按棋盘格分割的方式。本文只沿通道维分割,以简化整体结构。
Permutation.
Each step of flow above should be preceded by some kind of permutation of the variables that ensures that after sufficient steps of flow, each dimensions can affect every other dimension. The type of permutation specifically done in (Dinh et al., 2014; Dinh et al., 2016) is equivalent to simply reversing the ordering of the channels (features) before performing an additive coupling layer. An alternative is to perform a (fixed) random permutation. Our invertible 1x1 convolution is a generalization of such permutations. In experiments we compare these three choices.
置换
上述每步流之前,应先对变量做某种置换,确保足够多步之后每一维都能影响其他维。(Dinh et al., 2014; Dinh et al., 2016) 中的置换等价于在加性耦合前反转通道(特征)顺序。另一种选择是(固定)随机置换。可逆 1×1 卷积是这类置换的推广。实验中我们对比这三种选择。
4 Related Work
4 相关工作
This work builds upon the ideas and flows proposed in (Dinh et al., 2014) (NICE) and (Dinh et al., 2016) (RealNVP); comparisons with this work are made throughout this paper. In (Papamakarios et al., 2017) (MAF), the authors propose a generative flow based on IAF (Kingma et al., 2016); however, since synthesis from MAF is non-parallelizable and therefore inefficient, we omit it from comparisons. Synthesis from autoregressive (AR) models (Hochreiter and Schmidhuber, 1997; Graves, 2013; van den Oord et al., 2016a; van den Oord et al., 2016b; Van Den Oord et al., 2016) is similarly non-parallelizable. Synthesis of high-dimensional data typically takes multiple orders of magnitude longer with AR models; see (Kingma et al., 2016; Oord et al., 2017) for evidence. Sampling images with our largest models takes less than one second on current hardware. [^1]
本文建立在 (Dinh et al., 2014)(NICE)与 (Dinh et al., 2016)(RealNVP)提出的思想与流之上;文中多处与之对比。(Papamakarios et al., 2017)(MAF)基于 IAF (Kingma et al., 2016) 提出生成流;但 MAF 合成不可并行、效率低,故不纳入对比。自回归(AR)模型 (Hochreiter and Schmidhuber, 1997; Graves, 2013; van den Oord et al., 2016a; van den Oord et al., 2016b; Van Den Oord et al., 2016) 的合成同样难以并行。合成高维数据时 AR 模型通常慢几个数量级;证据见 (Kingma et al., 2016; Oord et al., 2017)。用我们最大模型采样 图像,在现有硬件上不到一秒。[^1]
GANs (Goodfellow et al., 2014) are arguably best known for their ability to synthesize large and realistic images (Karras et al., 2017), in contrast with likelihood-based methods. Downsides of GANs are their general lack of latent-space encoders, their general lack of full support over the data (Grover et al., 2018), their difficulty of optimization, and their difficulty of assessing overfitting and generalization.
GAN (Goodfellow et al., 2014) 以能合成大幅真实图像著称 (Karras et al., 2017),与基于似然的方法形成对照。其短板包括通常缺少潜空间编码器、对数据常无全支撑 (Grover et al., 2018)、优化困难,以及难评估过拟合与泛化。
5 Quantitative Experiments
5 定量实验
We begin our experiments by comparing how our new flow compares against RealNVP (Dinh et al., 2016). We then apply our model on other standard datasets and compare log-likelihoods against previous generative models. See the appendix for optimization details. In our experiments, we let each have three convolutional layers, where the two hidden layers have ReLU activation functions and 512 channels. The first and last convolutions are , while the center convolution is , since both its input and output have a large number of channels, in contrast with the first and last convolution.
实验首先对比新流与 RealNVP (Dinh et al., 2016),再在其他标准数据集上比较对数似然。优化细节见附录。实验中每个 含三层卷积:两层隐层用 ReLU、512 通道;首尾卷积为 ,中间为 ,因其输入输出通道都很多。
(a) Additive coupling.
(a) 加性耦合。
Gains using invertible Convolution.
We choose the architecture described in Section 3, and consider three variations for the permutation of the channel variables - a reversing operation as described in the RealNVP, a fixed random permutation, and our invertible convolution. We compare for models with only additive coupling layers, and models with affine coupling. As described earlier, we initialize all models with a data-dependent initialization which normalizes the activations of each layer. All models were trained with and . The model with convolution has a negligible larger amount of parameters.
可逆 卷积带来的增益
采用第 3 节结构,对通道变量置换考虑三种变体:RealNVP 中的反转、固定随机置换,以及可逆 卷积。分别在仅加性耦合与仿射耦合下比较。如前所述,全部模型用数据相关初始化归一化各层激活。均取 、。带 卷积的模型参数量仅多约 ,可忽略。
We compare the average negative log-likelihood (bits per dimension) on the CIFAR-10 (Krizhevsky, 2009) dataset, keeping all training conditions constant and averaging across three random seeds. The results are in Figure 3. As we see, for both additive and affine couplings, the invertible convolution achieves a lower negative log likelihood and converges faster. The affine coupling models also converge faster than the additive coupling models. We noted that the increase in wallclock time for the invertible convolution model was only , thus the operation is computationally efficient as well.
在 CIFAR-10 (Krizhevsky, 2009) 上比较平均负对数似然(bits per dimension),训练条件保持不变,并对三个随机种子取平均。结果见图 3。可见无论加性还是仿射耦合,可逆 卷积都能得到更低的负对数似然并更快收敛;仿射耦合也比加性耦合收敛更快。我们测得可逆 卷积带来的墙钟时间增幅仅约 ,计算上仍然高效。
Comparison with RealNVP on standard benchmarks.
Besides the permutation operation, the RealNVP architecture has other differences such as the spatial coupling layers. In order to verify that our proposed architecture is overall competitive with the RealNVP architecture, we compare our models on various natural images datasets. In particular, we compare on CIFAR-10, ImageNet (Russakovsky et al., 2015) and LSUN (Yu et al., 2015) datasets. We follow the same preprocessing as in (Dinh et al., 2016). For Imagenet, we use the and downsampled version of ImageNet (Oord et al., 2016), and for LSUN we downsample to and take random crops of . We also include the bits/dimension for our model trained on CelebA HQ used in our qualitative experiments.[^2] As we see in Table 2, our model achieves a significant improvement on all the datasets.
在标准基准上与 RealNVP 对比
除置换外,RealNVP 还有空间耦合层等差异。为验证整体结构仍具竞争力,我们在多种自然图像数据集上比较,包括 CIFAR-10、ImageNet (Russakovsky et al., 2015) 与 LSUN (Yu et al., 2015),预处理同 (Dinh et al., 2016)。ImageNet 使用 与 下采样版 (Oord et al., 2016);LSUN 下采样到 再随机裁 。我们也给出定性实验所用 CelebA HQ 上的 bits/dimension。[^2] 如表 2,我们的模型在全部数据集上均有显著提升。
| Model | CIFAR-10 | ImageNet 32x32 | ImageNet 64x64 | LSUN (bedroom) | LSUN (tower) | LSUN (church outdoor) |
|---|---|---|---|---|---|---|
| RealNVP | 2.72 | 2.81 | 3.08 | |||
| Glow |
Table 2: Best results in bits per dimension of our model compared to RealNVP.
| 模型 | CIFAR-10 | ImageNet 32x32 | ImageNet 64x64 | LSUN (bedroom) | LSUN (tower) | LSUN (church outdoor) |
|---|---|---|---|---|---|---|
| RealNVP | 2.72 | 2.81 | 3.08 | |||
| Glow |
表 2:相对 RealNVP,我们模型在 bits per dimension 上的最佳结果。
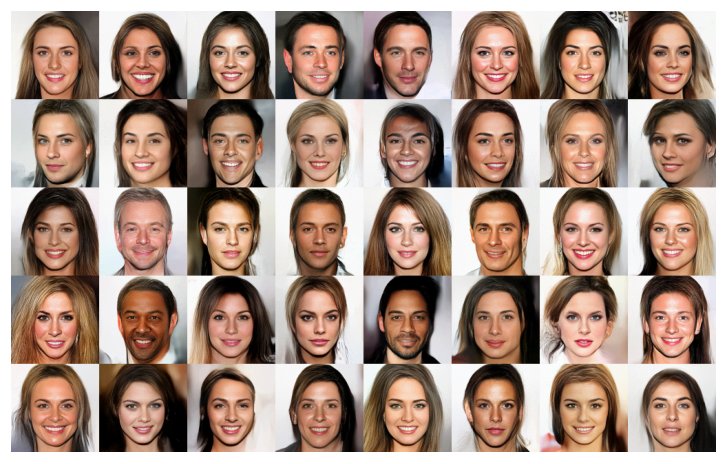
Figure 4: Random samples from the model, with temperature
图 4:模型随机样本,温度
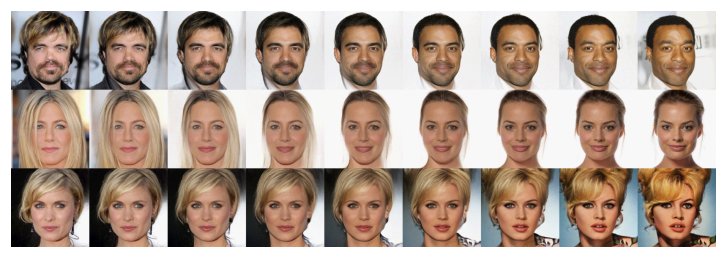
Figure 5: Linear interpolation in latent space between real images
图 5:真实图像之间的潜空间线性插值
6 Qualitative Experiments
6 定性实验
We now study the qualitative aspects of the model on high-resolution datasets. We choose the CelebA-HQ dataset (Karras et al., 2017), which consists of high resolution images from the CelebA dataset, and train the same architecture as above but now for images at a resolution of , and . To improve visual quality at the cost of slight decrease in color fidelity, we train our models on -bit images. We aim to study if our model can scale to high resolutions, produce realistic samples, and produce a meaningful latent space. Due to device memory constraints, at these resolutions we work with minibatch size 1 per PU, and use gradient checkpointing (Salimans and Bulatov, 2017). In the future, we could use a constant amount of memory independent of depth by utilizing the reversibility of the model (Gomez et al., 2017).
接着在高分辨率数据上考察定性表现。选用 CelebA-HQ (Karras et al., 2017),含来自 CelebA 的 30000 张高分辨率图像;结构同上,分辨率 ,,。为略降色彩保真换取更好观感,我们在 5-bit 图像上训练。目标是检验模型能否扩展到高分辨率、产生逼真样本,并得到有意义的潜空间。受设备显存限制,该分辨率下每 PU minibatch size 为 1,并使用梯度检查点 (Salimans and Bulatov, 2017)。未来可利用模型可逆性,使内存相对深度为常数 (Gomez et al., 2017)。
Consistent with earlier work on likelihood-based generative models (Parmar et al., 2018), we found that sampling from a reduced-temperature model often results in higher-quality samples. When sampling with temperature , we sample from the distribution . In case of additive coupling layers, this can be achieved simply by multiplying the standard deviation of by a factor of .
与早期基于似然的生成模型工作 (Parmar et al., 2018) 一致,我们发现从降温度模型采样往往质量更高。温度为 时,从 采样。对加性耦合,只需把 的标准差乘以 。
Synthesis and Interpolation.
Figure 4 shows the random samples obtained from our model. The images are extremely high quality for a non-autoregressive likelihood based model. To see how well we can interpolate, we take a pair of real images, encode them with the encoder, and linearly interpolate between the latents to obtain samples. The results in Figure 5 show that the image manifold of the generator distribution is extremely smooth and almost all intermediate samples look like realistic faces.
合成与插值
图 4 给出随机样本:对非自回归、基于似然的模型而言质量极高。为检验插值,取一对真实图像,经编码器得到潜变量并线性插值再解码。图 5 显示生成分布的图像流形极为平滑,几乎所有中间样本都像真实面孔。
Semantic Manipulation.
(a) Smiling
语义操纵
(a) 微笑
We now consider modifying attributes of an image. To do so, we use the labels in the CelebA dataset. Each image has a binary label corresponding to presence or absence of attributes like smiling, blond hair, young, etc. This gives us binary labels for each attribute. We then calculate the average latent vector for images with the attribute and for images without, and then use the difference as a direction for manipulating. Note that this is a relatively small amount of supervision, and is done after the model is trained (no labels were used while training), making it extremely easy to do for a variety of different target attributes. The results are shown in Figure 6.
接着考虑修改图像属性。利用 CelebA 标签:每张图对微笑、金发、年轻等属性有二值标注,于是每个属性有 30000 个二值标签。分别计算有该属性与无该属性图像的平均潜向量 、,以其差 作为操纵方向。监督量相对较小,且在模型训练之后进行(训练未用标签),因此很容易迁移到多种目标属性。结果见图 6。
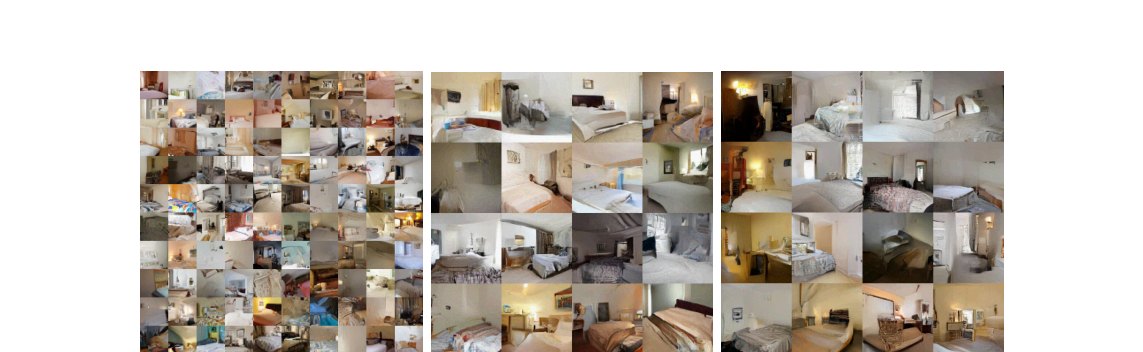
Figure 7: Samples from model trained on 5-bit LSUN bedrooms, at temperature 0.875. Resolutions 64, 96 and 128 respectively [^3]
图 7:在 5-bit LSUN bedrooms 上训练的模型样本,温度 0.875。分辨率分别为 64、96 与 128[^3]
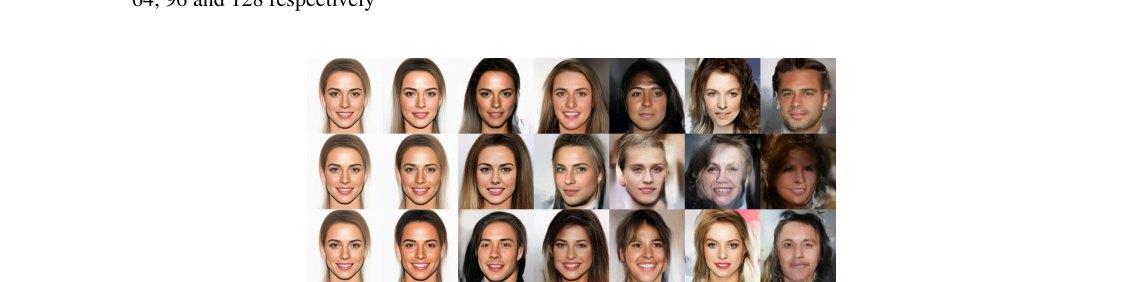
Figure 8: Effect of change of temperature. From left to right, samples obtained at temperatures
图 8:温度变化的影响。从左到右,温度依次为
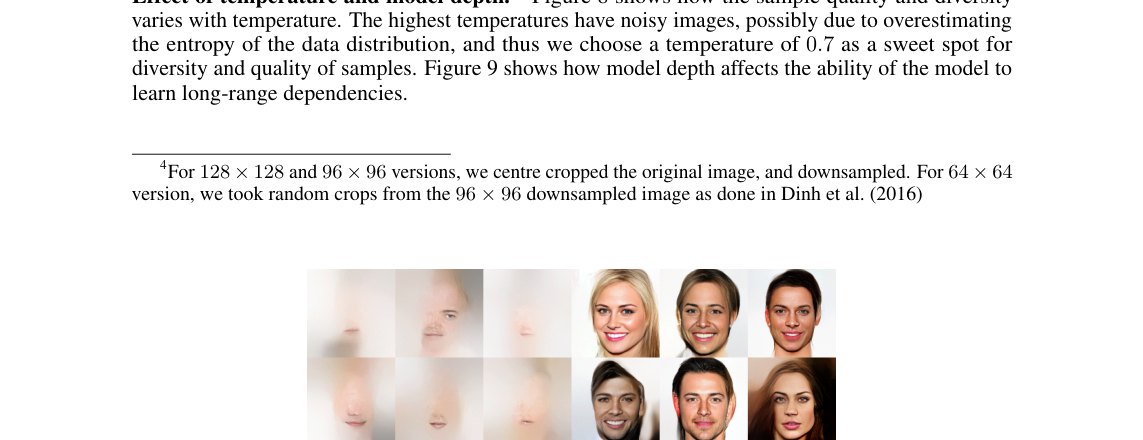
Figure 9: Samples from shallow model on left vs deep model on right. Shallow model has levels, while deep model has levels
图 9:左为浅模型、右为深模型样本。浅模型 级,深模型 级
Effect of temperature and model depth.
Figure 8 shows how the sample quality and diversity varies with temperature. The highest temperatures have noisy images, possibly due to overestimating the entropy of the data distribution, and thus we choose a temperature of as a sweet spot for diversity and quality of samples. Figure 9 shows how model depth affects the ability of the model to learn long-range dependencies.
温度与模型深度的影响
图 8 展示样本质量与多样性如何随温度变化。最高温度图像偏噪,可能因高估数据分布熵;我们取温度 作为多样性与质量的折中。图 9 则说明模型深度如何影响学习长程依赖的能力。
7 Conclusion
7 结论
We propose a new type of flow, coined Glow, and demonstrate improved quantitative performance in terms of log-likelihood on standard image modeling benchmarks. In addition, we demonstrate that when trained on high-resolution faces, our model is able to synthesize realistic images. Our model is, to the best of our knowledge, the first likelihood-based model in the literature that can efficiently synthesize high-resolution natural images.
我们提出名为 Glow 的新流,在标准图像建模基准上以对数似然衡量取得更好定量表现;并在高分辨率人脸上展示能合成逼真图像。据我们所知,这是文献中首个能高效合成高分辨率自然图像的基于似然的模型。
References
参考文献
Deco and Brauer, (1995) Deco, G. and Brauer, W. (1995). Higher order statistical decorrelation without information loss. Advances in Neural Information Processing Systems , pages 247–254.
Dinh et al., (2014) Dinh, L., Krueger, D., and Bengio, Y. (2014). Nice: non-linear independent components estimation. arXiv preprint arXiv:1410.8516 .
Dinh et al., (2016) Dinh, L., Sohl-Dickstein, J., and Bengio, S. (2016). Density estimation using Real NVP. arXiv preprint arXiv:1605.08803 .
Gomez et al., (2017) Gomez, A. N., Ren, M., Urtasun, R., and Grosse, R. B. (2017). The reversible residual network: Backpropagation without storing activations. In Advances in Neural Information Processing Systems , pages 2211–2221.
Goodfellow et al., (2014) Goodfellow, I., Pouget-Abadie, J., Mirza, M., Xu, B., Warde-Farley, D., Ozair, S., Courville, A., and Bengio, Y. (2014). Generative adversarial nets. In Advances in Neural Information Processing Systems , pages 2672–2680.
Graves, (2013) Graves, A. (2013). Generating sequences with recurrent neural networks. arXiv preprint arXiv:1308.0850 .
Grover et al., (2018) Grover, A., Dhar, M., and Ermon, S. (2018). Flow-gan: Combining maximum likelihood and adversarial learning in generative models. In AAAI Conference on Artificial Intelligence .
He et al., (2016) He, K., Zhang, X., Ren, S., and Sun, J. (2016). Identity mappings in deep residual networks. arXiv preprint arXiv:1603.05027 .
Hochreiter and Schmidhuber, (1997) Hochreiter, S. and Schmidhuber, J. (1997). Long Short-Term Memory. Neural computation , 9(8):1735–1780.
Ioffe and Szegedy, (2015) Ioffe, S. and Szegedy, C. (2015). Batch normalization: Accelerating deep network training by reducing internal covariate shift. arXiv preprint arXiv:1502.03167 .
Karras et al., (2017) Karras, T., Aila, T., Laine, S., and Lehtinen, J. (2017). Progressive growing of gans for improved quality, stability, and variation. arXiv preprint arXiv:1710.10196 .
Kingma and Ba, (2015) Kingma, D. and Ba, J. (2015). Adam: A method for stochastic optimization. Proceedings of the International Conference on Learning Representations 2015 .
Kingma et al., (2016) Kingma, D. P., Salimans, T., Jozefowicz, R., Chen, X., Sutskever, I., and Welling, M. (2016). Improved variational inference with inverse autoregressive flow. In Advances in Neural Information Processing Systems , pages 4743–4751.
Kingma and Welling, (2013) Kingma, D. P. and Welling, M. (2013). Auto-encoding variational Bayes. Proceedings of the 2nd International Conference on Learning Representations .
Kingma and Welling, (2018) Kingma, D. P. and Welling, M. (2018). Variational autoencoders. Under Review .
Krizhevsky, (2009) Krizhevsky, A. (2009). Learning multiple layers of features from tiny images.
Oord et al., (2016) Oord, A. v. d., Kalchbrenner, N., and Kavukcuoglu, K. (2016). Pixel recurrent neural networks. arXiv preprint arXiv:1601.06759 .
Oord et al., (2017) Oord, A. v. d., Li, Y., Babuschkin, I., Simonyan, K., Vinyals, O., Kavukcuoglu, K., Driessche, G. v. d., Lockhart, E., Cobo, L. C., Stimberg, F., et al. (2017). Parallel wavenet: Fast high-fidelity speech synthesis. arXiv preprint arXiv:1711.10433 .
Papamakarios et al., (2017) Papamakarios, G., Murray, I., and Pavlakou, T. (2017). Masked autoregressive flow for density estimation. In Advances in Neural Information Processing Systems , pages 2335–2344.
Parmar et al., (2018) Parmar, N., Vaswani, A., Uszkoreit, J., Kaiser, Ł., Shazeer, N., and Ku, A. (2018). Image transformer. arXiv preprint arXiv:1802.05751 .
Rezende and Mohamed, (2015) Rezende, D. and Mohamed, S. (2015). Variational inference with normalizing flows. In Proceedings of The 32nd International Conference on Machine Learning , pages 1530–1538.
Russakovsky et al., (2015) Russakovsky, O., Deng, J., Su, H., Krause, J., Satheesh, S., Ma, S., Huang, Z., Karpathy, A., Khosla, A., Bernstein, M., et al. (2015). Imagenet large scale visual recognition challenge. International Journal of Computer Vision , 115(3):211–252.
Salimans and Bulatov, (2017) Salimans, T. and Bulatov, Y. (2017). Gradient checkpointing. https://github.com/openai/gradient-checkpointing .
Salimans and Kingma, (2016) Salimans, T. and Kingma, D. P. (2016). Weight normalization: A simple reparameterization to accelerate training of deep neural networks. arXiv preprint arXiv:1602.07868 .
Van Den Oord et al., (2016) Van Den Oord, A., Dieleman, S., Zen, H., Simonyan, K., Vinyals, O., Graves, A., Kalchbrenner, N., Senior, A., and Kavukcuoglu, K. (2016). Wavenet: A generative model for raw audio. arXiv preprint arXiv:1609.03499 .
(26) van den Oord, A., Kalchbrenner, N., and Kavukcuoglu, K. (2016a). Pixel recurrent neural networks. arXiv preprint arXiv:1601.06759 .
(27) van den Oord, A., Kalchbrenner, N., Vinyals, O., Espeholt, L., Graves, A., and Kavukcuoglu, K. (2016b). Conditional image generation with PixelCNN decoders. arXiv preprint arXiv:1606.05328 .
Yu et al., (2015) Yu, F., Zhang, Y., Song, S., Seff, A., and Xiao, J. (2015). Lsun: Construction of a large-scale image dataset using deep learning with humans in the loop. arXiv preprint arXiv:1506.03365 .
Appendix A Additional quantitative results
附录 A 额外定量结果
See Table 3.
见表 3。
| Dataset | Glow |
|---|---|
| CIFAR-10, 3232, 5-bit | 1.67 |
| ImageNet, 3232, 5-bit | 1.99 |
| ImageNet, 6464, 5-bit | 1.76 |
| CelebA HQ, 256256, 5-bit | 1.03 |
Table 3: Quantiative results in bits per dimension on the test set.
| 数据集 | Glow |
|---|---|
| CIFAR-10, 3232, 5-bit | 1.67 |
| ImageNet, 3232, 5-bit | 1.99 |
| ImageNet, 6464, 5-bit | 1.76 |
| CelebA HQ, 256256, 5-bit | 1.03 |
表 3:测试集上以 bits per dimension 计的定量结果。
Appendix B Simple python implementation of the invertible convolution
附录 B 可逆 卷积的简单 Python 实现
Invertible 1x1 conv
def invertible_1x1_conv(z, logdet, forward=True):
Shape
h,w,c = z.shape[1:]
Sample a random orthogonal matrix to initialise weights
w_init = np.linalg.qr(np.random.randn(c,c))[0]
w = tf.get_variable("W", initializer=w_init)
Compute log determinant
dlogdet = h * w * tf.log(abs(tf.matrix_determinant(w)))
if forward:
Forward computation
_w = tf.reshape(w, [1,1,c,c])
z = tf.nn.conv2d(z, _w, [1,1,1,1], ’SAME’)
logdet += dlogdet
return z, logdet
else:
Reverse computation
_w = tf.matrix_inverse(w)
_w = tf.reshape(_w, [1,1,c,c])
z = tf.nn.conv2d(z, _w, [1,1,1,1], ’SAME’)
logdet -= dlogdet
return z, logdet
Appendix C Optimization details
附录 C 优化细节
We use the Adam optimizer (Kingma and Ba, 2015) with and default and . In out quantitative experiments (Section 5, Table 2) we used the following hyperparameters (Table 4).
我们使用 Adam 优化器 (Kingma and Ba, 2015),,、 取默认。定量实验(第 5 节、表 2)超参见表 4。
| Dataset | Minibatch Size | Levels (L) | Depth per level (K) | Coupling |
|---|---|---|---|---|
| CIFAR-10 | 512 | 3 | 32 | Affine |
| ImageNet, 3232 | 512 | 3 | 48 | Affine |
| ImageNet, 6464 | 128 | 4 | 48 | Affine |
| LSUN, 6464 | 128 | 4 | 48 | Affine |
Table 4: Hyperparameters for results in Section 5, Table 2
| 数据集 | 小批量大小 | 层级数 (L) | 每级深度 (K) | 耦合 |
|---|---|---|---|---|
| CIFAR-10 | 512 | 3 | 32 | Affine |
| ImageNet, 3232 | 512 | 3 | 48 | Affine |
| ImageNet, 6464 | 128 | 4 | 48 | Affine |
| LSUN, 6464 | 128 | 4 | 48 | Affine |
表 4:第 5 节、表 2 结果所用超参
In our qualitative experiments (Section 6), we used the following hyperparameters (Table 5)
定性实验(第 6 节)使用下列超参(表 5)。
| Dataset | Minibatch Size | Levels (L) | Depth per level (K) | Coupling |
|---|---|---|---|---|
| LSUN, 6464, 5-bit | 128 | 4 | 48 | Additive |
| LSUN, 9696, 5-bit | 320 | 5 | 64 | Additive |
| LSUN, 128128, 5-bit | 160 | 5 | 64 | Additive |
| CelebA HQ, 256256, 5-bit | 40 | 6 | 32 | Additive |
Table 5: Hyperparameters for results in Section 6
| 数据集 | 小批量大小 | 层级数 (L) | 每级深度 (K) | 耦合 |
|---|---|---|---|---|
| LSUN, 6464, 5-bit | 128 | 4 | 48 | Additive |
| LSUN, 9696, 5-bit | 320 | 5 | 64 | Additive |
| LSUN, 128128, 5-bit | 160 | 5 | 64 | Additive |
| CelebA HQ, 256256, 5-bit | 40 | 6 | 32 | Additive |
表 5:第 6 节结果所用超参
Appendix D Extra samples from qualitative experiments
附录 D 定性实验的额外样本
For the class conditional CIFAR-10 and 3232 ImageNet samples, we used the same hyperparameters as the quantitative experiments, but with a class dependent prior at the top-most level. We also added a classification loss to predict the class label from the second last layer of the encoder, with a weight of . The results are in Figure 10.
对类别条件的 CIFAR-10 与 ImageNet 样本,超参与定量实验相同,但最顶层使用类别相关先验。我们还在编码器倒数第二层上加分类损失以预测类别标签,权重 。结果见图 10。
(a) Class conditional CIFAR-10 samples
(a) 类别条件 CIFAR-10 样本
Appendix E Extra samples from the quantitative experiments
附录 E 定量实验的额外样本
For direct comparison with other work, datasets are preprocessed exactly as in Dinh et al., 2016. Results are in Figure 11 and Figure 12.
为与其他工作直接对比,数据预处理与 Dinh et al., 2016 完全一致。结果见图 11 与图 12。
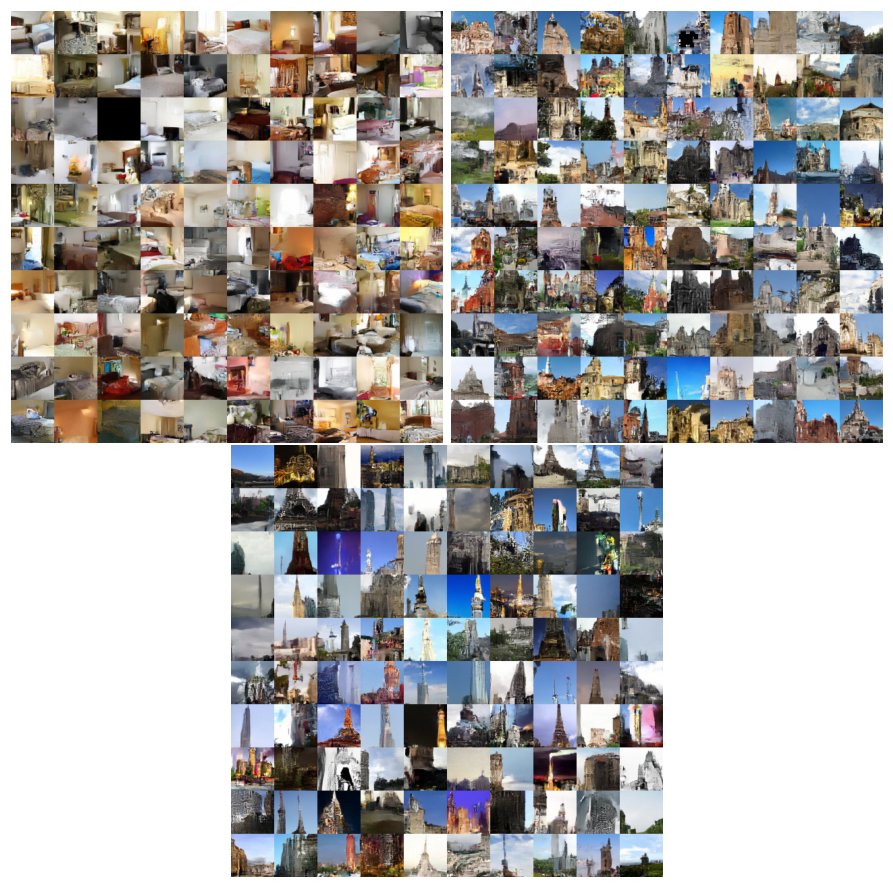
Figure 11: Samples from 8-bit, LSUN bedrooms, church and towers respectively. Temperature 1.0
图 11:8-bit、 的 LSUN bedrooms、church 与 towers 样本。温度 1.0
Figure 12: Samples from an unconditional model with affine coupling layers trained on the CIFAR-10 dataset with temperature 1.0.
图 12:在 CIFAR-10 上、用仿射耦合层训练的无条件模型样本,温度 1.0。