How Powerful are Graph Neural Networks?
How Powerful are Graph Neural Networks?
图神经网络究竟有多强?
Keyulu Xu Thanks: Equal contribution. Thanks: Work partially performed while in Tokyo, visiting Prof. Ken-ichi Kawarabayashi. Affiliation: MIT Email: keyulu@mit.edu Weihua Hu 1 1 footnotemark: 1 Thanks: Work partially performed while at RIKEN AIP and University of Tokyo. Affiliation: Stanford University Email: weihuahu@stanford.edu Jure Leskovec Affiliation: Stanford University Email: jure@cs.stanford.edu Stefanie Jegelka Affiliation: MIT Email: stefje@mit.edu
Abstract
摘要
Graph Neural Networks (GNNs) are an effective framework for representation learning of graphs. GNNs follow a neighborhood aggregation scheme, where the representation vector of a node is computed by recursively aggregating and transforming representation vectors of its neighboring nodes. Many GNN variants have been proposed and have achieved state-of-the-art results on both node and graph classification tasks. However, despite GNNs revolutionizing graph representation learning, there is limited understanding of their representational properties and limitations. Here, we present a theoretical framework for analyzing the expressive power of GNNs to capture different graph structures. Our results characterize the discriminative power of popular GNN variants, such as Graph Convolutional Networks and GraphSAGE, and show that they cannot learn to distinguish certain simple graph structures. We then develop a simple architecture that is provably the most expressive among the class of GNNs and is as powerful as the Weisfeiler-Lehman graph isomorphism test. We empirically validate our theoretical findings on a number of graph classification benchmarks, and demonstrate that our model achieves state-of-the-art performance.
图神经网络(GNN)是图表示学习的有效框架。GNN 采用邻域聚合:节点表示向量通过递归聚合并变换其邻居的表示得到。已有许多 GNN 变体在节点与图分类上达到当时最优。尽管 GNN 深刻改变了图表示学习,对其表示性质与局限的理解仍有限。本文提出理论框架,分析 GNN 捕捉不同图结构的表达能力。结果刻画了图卷积网络、GraphSAGE 等流行变体的判别力,并表明它们无法学会区分某些简单图结构。随后我们给出一种简单结构,可证明在 GNN 类中表达能力最强,并与 Weisfeiler-Lehman 图同构检验同等有力。我们在多个图分类基准上验证理论,并展示该模型达到当时最优表现。
1 Introduction
1 引言
Learning with graph structured data, such as molecules, social, biological, and financial networks, requires effective representation of their graph structure (Hamilton et al. 2017b). Recently, there has been a surge of interest in Graph Neural Network (GNN) approaches for representation learning of graphs (Li et al. 2016; Hamilton et al. 2017a; Kipf & Welling 2017; Velickovic et al. 2018; Xu et al. 2018). GNNs broadly follow a recursive neighborhood aggregation (or message passing) scheme, where each node aggregates feature vectors of its neighbors to compute its new feature vector (Xu et al. 2018; Gilmer et al. 2017). After iterations of aggregation, a node is represented by its transformed feature vector, which captures the structural information within the node’s -hop neighborhood. The representation of an entire graph can then be obtained through pooling (Ying et al. 2018), for example, by summing the representation vectors of all nodes in the graph.
在分子、社交、生物与金融网络等图结构数据上学习,需要有效表示其图结构(Hamilton et al. 2017b)。近年图神经网络(GNN)表示学习迅速升温(Li et al. 2016;Hamilton et al. 2017a;Kipf & Welling 2017;Velickovic et al. 2018;Xu et al. 2018)。GNN 大体遵循递归邻域聚合(或消息传递):每个节点聚合邻居特征向量以计算新特征(Xu et al. 2018;Gilmer et al. 2017)。聚合 轮后,节点由其变换后的特征向量表示,刻画其 跳邻域内的结构信息。整图表示可通过池化得到(Ying et al. 2018),例如对所有节点表示求和。
Many GNN variants with different neighborhood aggregation and graph-level pooling schemes have been proposed (Scarselli et al. 2009b; Battaglia et al. 2016; Defferrard et al. 2016; Duvenaud et al. 2015; Hamilton et al. 2017a; Kearnes et al. 2016; Kipf & Welling 2017; Li et al. 2016; Velickovic et al. 2018; Santoro et al. 2017; Xu et al. 2018; Santoro et al. 2018; Verma & Zhang 2018; Ying et al. 2018; Zhang et al. 2018). Empirically, these GNNs have achieved state-of-the-art performance in many tasks such as node classification, link prediction, and graph classification. However, the design of new GNNs is mostly based on empirical intuition, heuristics, and experimental trial-and-error. There is little theoretical understanding of the properties and limitations of GNNs, and formal analysis of GNNs’ representational capacity is limited.
已有大量带不同邻域聚合与图级池化方案的 GNN 变体(Scarselli et al. 2009b;Battaglia et al. 2016;Defferrard et al. 2016;Duvenaud et al. 2015;Hamilton et al. 2017a;Kearnes et al. 2016;Kipf & Welling 2017;Li et al. 2016;Velickovic et al. 2018;Santoro et al. 2017;Xu et al. 2018;Santoro et al. 2018;Verma & Zhang 2018;Ying et al. 2018;Zhang et al. 2018)。经验上它们在节点分类、链接预测与图分类等任务上表现优异。但新 GNN 的设计多靠直觉、启发式与试错,对其性质与局限的理论理解很少,对表示能力的形式分析也有限。
Here, we present a theoretical framework for analyzing the representational power of GNNs. We formally characterize how expressive different GNN variants are in learning to represent and distinguish between different graph structures. Our framework is inspired by the close connection between GNNs and the Weisfeiler-Lehman (WL) graph isomorphism test (Weisfeiler & Lehman 1968), a powerful test known to distinguish a broad class of graphs (Babai & Kucera 1979). Similar to GNNs, the WL test iteratively updates a given node’s feature vector by aggregating feature vectors of its network neighbors. What makes the WL test so powerful is its injective aggregation update that maps different node neighborhoods to different feature vectors. Our key insight is that a GNN can have as large discriminative power as the WL test if the GNN’s aggregation scheme is highly expressive and can model injective functions.
本文提出分析 GNN 表示能力的理论框架,形式刻画不同变体在学习表示并区分图结构上的表达力。框架受 GNN 与 Weisfeiler-Lehman(WL)图同构检验(Weisfeiler & Lehman 1968)密切联系启发——该检验能区分一大类图(Babai & Kucera 1979)。与 GNN 类似,WL 通过聚合网络邻居的特征向量迭代更新节点特征;其强大之处在于注入式聚合更新,把不同节点邻域映到不同特征向量。关键洞见是:若 GNN 的聚合方案足够富有表达力、能建模注入函数,则其判别力可与 WL 检验相当。
To mathematically formalize the above insight, our framework first represents the set of feature vectors of a given node’s neighbors as a multiset, i.e., a set with possibly repeating elements. Then, the neighbor aggregation in GNNs can be thought of as an aggregation function over the multiset. Hence, to have strong representational power, a GNN must be able to aggregate different multisets into different representations. We rigorously study several variants of multiset functions and theoretically characterize their discriminative power, i.e., how well different aggregation functions can distinguish different multisets. The more discriminative the multiset function is, the more powerful the representational power of the underlying GNN.
为把上述洞见数学化,框架先把某节点邻居的特征向量集合视为多重集(可有重复元素的集合)。于是 GNN 的邻居聚合可看作多重集上的聚合函数。要有强表示能力,GNN 必须能把不同多重集聚合成不同表示。我们严格研究若干多重集函数变体,理论刻画其判别力,即不同聚合函数区分不同多重集的能力。多重集函数越具判别力,底层 GNN 的表示能力越强。
Our main results are summarized as follows:
主要结果概括如下:
- We show that GNNs are at most as powerful as the WL test in distinguishing graph structures.
- 我们证明:在区分图结构上,GNN 至多与 WL 检验同样有力。
- We establish conditions on the neighbor aggregation and graph readout functions under which the resulting GNN is as powerful as the WL test.
- 我们给出邻居聚合与图读出函数的条件,使所得 GNN 与 WL 检验同等有力。
- We identify graph structures that cannot be distinguished by popular GNN variants, such as GCN (Kipf & Welling 2017) and GraphSAGE (Hamilton et al. 2017a), and we precisely characterize the kinds of graph structures such GNN-based models can capture.
- 我们指出 GCN(Kipf & Welling 2017)、GraphSAGE(Hamilton et al. 2017a)等流行变体无法区分的图结构,并精确刻画这类 GNN 能捕捉的结构种类。
- We develop a simple neural architecture, Graph Isomorphism Network (GIN), and show that its discriminative/representational power is equal to the power of the WL test.
- 我们提出简单结构 图同构网络(GIN),并证明其判别/表示能力与 WL 检验相等。
We validate our theory via experiments on graph classification datasets, where the expressive power of GNNs is crucial to capture graph structures. In particular, we compare the performance of GNNs with various aggregation functions. Our results confirm that the most powerful GNN by our theory, i.e., Graph Isomorphism Network (GIN), also empirically has high representational power as it almost perfectly fits the training data, whereas the less powerful GNN variants often severely underfit the training data. In addition, the representationally more powerful GNNs outperform the others by test set accuracy and achieve state-of-the-art performance on many graph classification benchmarks.
我们在图分类数据集上验证理论——此处 GNN 的表达力对捕捉图结构至关重要。特别地,比较不同聚合函数的 GNN:结果确认按理论最强的图同构网络(GIN)经验上也有高表示能力,几乎完美拟合训练数据;较弱变体则常严重欠拟合。此外,表示更强的 GNN 在测试准确率上优于其他,并在多个图分类基准上达到当时最优。
2 Preliminaries
2 预备知识
We begin by summarizing some of the most common GNN models and, along the way, introduce our notation. Let denote a graph with node feature vectors for . There are two tasks of interest: (1) Node classification, where each node has an associated label and the goal is to learn a representation vector of such that ’s label can be predicted as ; (2) Graph classification, where, given a set of graphs and their labels , we aim to learn a representation vector that helps predict the label of an entire graph, .
先概括若干常见 GNN 模型并引入记号。设 为图,节点特征为 ()。关注两类任务:(1) 节点分类:每个 有标签 ,目标是学习表示 使 ;(2) 图分类:给定图集 与标签 ,学习整图表示 ,使 。
Graph Neural Networks. GNNs use the graph structure and node features to learn a representation vector of a node, , or the entire graph, . Modern GNNs follow a neighborhood aggregation strategy, where we iteratively update the representation of a node by aggregating representations of its neighbors. After iterations of aggregation, a node’s representation captures the structural information within its -hop network neighborhood. Formally, the -th layer of a GNN is
图神经网络。 GNN 利用图结构与节点特征 学习节点表示 或整图表示 。现代 GNN 采用邻域聚合:迭代地通过聚合邻居表示来更新节点表示。 轮后,节点表示捕捉其 跳邻域的结构信息。形式上,GNN 第 层为
where is the feature vector of node at the -th iteration/layer. We initialize , and is a set of nodes adjacent to . The choice of AGGREGATE and COMBINE in GNNs is crucial. A number of architectures for AGGREGATE have been proposed. In the pooling variant of GraphSAGE (Hamilton et al. 2017a), AGGREGATE has been formulated as
其中 为第 轮/层节点 的特征向量。初始化 , 为 的邻接节点集。AGGREGATE 与 COMBINE 的选择至关重要。已有多种 AGGREGATE 结构;在 GraphSAGE 的池化变体(Hamilton et al. 2017a)中,AGGREGATE 写为
where is a learnable matrix, and MAX represents an element-wise max-pooling. The COMBINE step could be a concatenation followed by a linear mapping as in GraphSAGE. In Graph Convolutional Networks (GCN) (Kipf & Welling 2017), the element-wise mean pooling is used instead, and the AGGREGATE and COMBINE steps are integrated as follows:
其中 可学习,MAX 为逐元素最大池化。COMBINE 可以是拼接后再线性映射 ,如 GraphSAGE。图卷积网络(GCN,Kipf & Welling 2017)改用逐元素均值池化,并把 AGGREGATE 与 COMBINE 合写为:
Many other GNNs can be represented similarly to Eq. 2.1 (Xu et al. 2018; Gilmer et al. 2017).
许多其他 GNN 也可类似写成式 2.1(Xu et al. 2018;Gilmer et al. 2017)。
For node classification, the node representation of the final iteration is used for prediction. For graph classification, the READOUT function aggregates node features from the final iteration to obtain the entire graph’s representation :
节点分类使用最后一轮的节点表示 做预测。图分类则用 READOUT 聚合最后一轮节点特征,得到整图表示 :
READOUT can be a simple permutation invariant function such as summation or a more sophisticated graph-level pooling function (Ying et al. 2018; Zhang et al. 2018).
READOUT 可以是求和等简单置换不变函数,或更复杂的图级池化(Ying et al. 2018;Zhang et al. 2018)。
Weisfeiler-Lehman test. The graph isomorphism problem asks whether two graphs are topologically identical. This is a challenging problem: no polynomial-time algorithm is known for it yet (Garey 1979; Garey & Johnson 2002; Babai 2016). Apart from some corner cases (Cai et al. 1992), the Weisfeiler-Lehman (WL) test of graph isomorphism (Weisfeiler & Lehman 1968) is an effective and computationally efficient test that distinguishes a broad class of graphs (Babai & Kucera 1979). Its 1-dimensional form, “naïve vertex refinement”, is analogous to neighbor aggregation in GNNs. The WL test iteratively (1) aggregates the labels of nodes and their neighborhoods, and (2) hashes the aggregated labels into unique new labels. The algorithm decides that two graphs are non-isomorphic if at some iteration the labels of the nodes between the two graphs differ.
Weisfeiler-Lehman 检验。 图同构问题问两图在拓扑上是否相同,颇具挑战:尚无已知的多项式时间算法(Garey 1979;Garey & Johnson 2002;Babai 2016)。除若干边例外(Cai et al. 1992),Weisfeiler-Lehman(WL)图同构检验(Weisfeiler & Lehman 1968)能高效区分一大类图(Babai & Kucera 1979)。其一维形式“朴素顶点细化”类似于 GNN 的邻居聚合:WL 迭代地 (1) 聚合节点及其邻域的标签,(2) 把聚合标签散列成唯一新标签;若某轮两图节点标签集合不同,则判定非同构。
Based on the WL test, Shervashidze et al. 2011 proposed the WL subtree kernel that measures the similarity between graphs. The kernel uses the counts of node labels at different iterations of the WL test as the feature vector of a graph. Intuitively, a node’s label at the -th iteration of WL test represents a subtree structure of height rooted at the node (Figure 1). Thus, the graph features considered by the WL subtree kernel are essentially counts of different rooted subtrees in the graph.
基于 WL,Shervashidze et al. 2011 提出 WL 子树核度量图相似度:以 WL 各轮节点标签计数作为图特征向量。直观上,第 轮节点标签表示以该节点为根、高度为 的子树结构(图 1)。因而 WL 子树核考虑的图特征本质上是图中不同有根子树的计数。
3 Theoretical framework: overview
3 理论框架概览
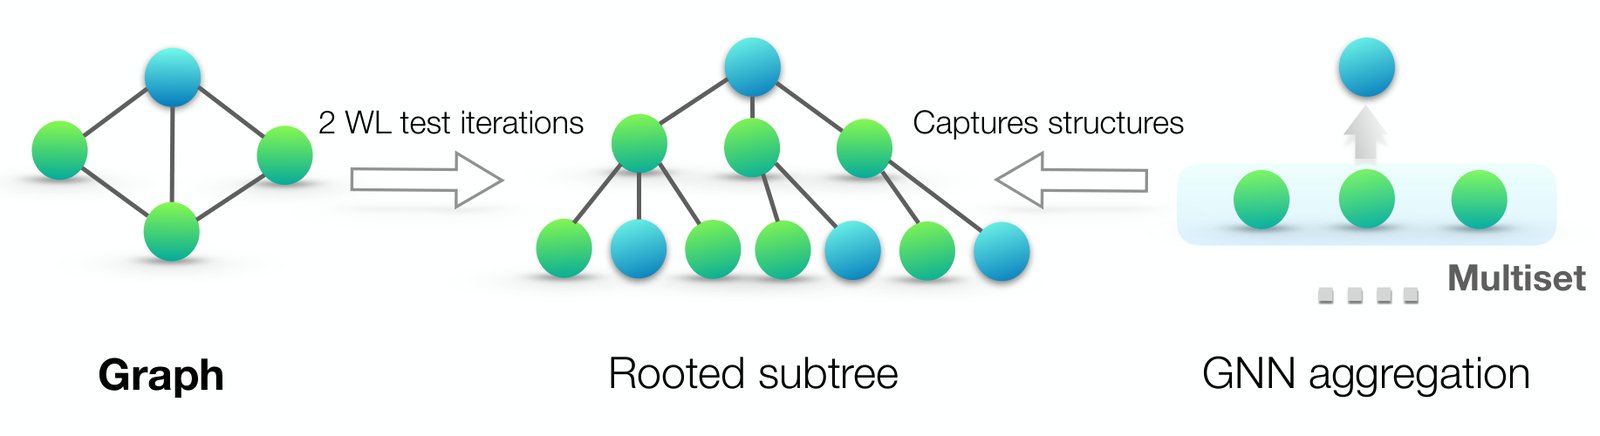
Figure 1: An overview of our theoretical framework. Middle panel: rooted subtree structures (at the blue node) that the WL test uses to distinguish different graphs. Right panel: if a GNN’s aggregation function captures the full multiset of node neighbors, the GNN can capture the rooted subtrees in a recursive manner and be as powerful as the WL test.
图 1:理论框架概览。 中图:WL 检验用来区分不同图的有根子树结构(蓝色节点处)。右图:若 GNN 的聚合函数能捕捉邻居节点的完整多重集,则可递归捕捉有根子树,并与 WL 检验同等有力。
We start with an overview of our framework for analyzing the expressive power of GNNs. Figure 1 illustrates our idea. A GNN recursively updates each node’s feature vector to capture the network structure and features of other nodes around it, i.e., its rooted subtree structures (Figure 1). Throughout the paper, we assume node input features are from a countable universe. For finite graphs, node feature vectors at deeper layers of any fixed model are also from a countable universe. For notational simplicity, we can assign each feature vector a unique label in . Then, feature vectors of a set of neighboring nodes form a multiset (Figure 1): the same element can appear multiple times since different nodes can have identical feature vectors.
先概述分析 GNN 表达能力的框架。图 1 示意我们的想法:GNN 递归更新每个节点的特征向量,以捕捉其周围网络结构与其他节点特征,即有根子树结构(图 1)。全文假设节点输入特征来自可数全域;对有限图,任意固定模型更深一层的节点特征也来自可数全域。为记号简便,可为每个特征向量在 中赋唯一标签。于是一组邻居节点的特征向量构成多重集(图 1):同一元素可多次出现,因为不同节点可有相同特征。
Definition 1(Multiset).
A multiset is a generalized concept of a set that allows multiple instances for its elements. More formally, a multiset is a 2-tuple where is the underlying set of that is formed from its distinct elements, and gives the multiplicity of the elements.
定义 1(多重集)。
多重集是允许元素重复出现的集合推广。形式地,多重集是二元组 ,其中 是由不同元素构成的底层集合, 给出元素的重数。
To study the representational power of a GNN, we analyze when a GNN maps two nodes to the same location in the embedding space. Intuitively, a maximally powerful GNN maps two nodes to the same location only if they have identical subtree structures with identical features on the corresponding nodes. Since subtree structures are defined recursively via node neighborhoods (Figure 1), we can reduce our analysis to the question whether a GNN maps two neighborhoods (i.e., two multisets) to the same embedding or representation. A maximally powerful GNN would never map two different neighborhoods, i.e., multisets of feature vectors, to the same representation. This means its aggregation scheme must be injective. Thus, we abstract a GNN’s aggregation scheme as a class of functions over multisets that their neural networks can represent, and analyze whether they are able to represent injective multiset functions.
为研究 GNN 的表示能力,我们分析何时两个节点被映到嵌入空间同一位置。直观上,最强 GNN 仅当两节点具有相同子树结构且对应节点特征相同时,才映到同一位置。由于子树结构经由节点邻域递归定义(图 1),分析可归结为:GNN 是否把两个邻域(即两个多重集)映到同一嵌入。最强 GNN 绝不会把两个不同邻域(特征向量多重集)映到同一表示,因而其聚合方案必须注入。于是我们把 GNN 聚合抽象为神经网络可表示的一类多重集函数,并分析它们能否表示注入的多重集函数。
Next, we use this reasoning to develop a maximally powerful GNN. In Section 5, we study popular GNN variants and see that their aggregation schemes are inherently not injective and thus less powerful, but that they can capture other interesting properties of graphs.
接下来据此构造最强 GNN。第 5 节研究流行变体,会看到其聚合本质不注入因而更弱,但仍能捕捉图的其他有趣性质。
4 Building powerful graph neural networks
4 构建强有力的图神经网络
First, we characterize the maximum representational capacity of a general class of GNN-based models. Ideally, a maximally powerful GNN could distinguish different graph structures by mapping them to different representations in the embedding space. This ability to map any two different graphs to different embeddings, however, implies solving the challenging graph isomorphism problem. That is, we want isomorphic graphs to be mapped to the same representation and non-isomorphic ones to different representations. In our analysis, we characterize the representational capacity of GNNs via a slightly weaker criterion: a powerful heuristic called Weisfeiler-Lehman (WL) graph isomorphism test, that is known to work well in general, with a few exceptions, e.g., regular graphs (Cai et al. 1992; Douglas 2011; Evdokimov & Ponomarenko 1999).
首先刻画一类通用 GNN 模型的最大表示能力。理想情况下,最强 GNN 应能把不同图结构映到嵌入空间中的不同表示。但“任意两不同图映到不同嵌入”意味着解决困难的图同构问题:同构图应同表示,非同构图应不同表示。分析中我们用稍弱、但通常很管用的启发式——Weisfeiler-Lehman(WL)图同构检验——来刻画表示能力;该检验总体表现好,但对正则图等有例外(Cai et al. 1992;Douglas 2011;Evdokimov & Ponomarenko 1999)。
Lemma 2.
Let and be any two non-isomorphic graphs. If a graph neural network maps and to different embeddings, the Weisfeiler-Lehman graph isomorphism test also decides and are not isomorphic.
引理 2。
设 、 为任意两非同构图。若图神经网络 把 、 映到不同嵌入,则 Weisfeiler-Lehman 图同构检验也会判定二者非同构。
Proofs of all Lemmas and Theorems can be found in the Appendix. Hence, any aggregation-based GNN is at most as powerful as the WL test in distinguishing different graphs. A natural follow-up question is whether there exist GNNs that are, in principle, as powerful as the WL test? Our answer, in Theorem 3, is yes: if the neighbor aggregation and graph-level readout functions are injective, then the resulting GNN is as powerful as the WL test.
全部引理与定理的证明见附录。因此,任何基于聚合的 GNN 在区分不同图上至多与 WL 检验同等有力。自然的后续问题是:是否存在原则上与 WL 同等有力的 GNN?定理 3 给出肯定答案:若邻居聚合与图级读出函数均为注入,则所得 GNN 与 WL 检验同等有力。
Theorem 3.
Let be a GNN. With a sufficient number of GNN layers, maps any graphs and that the Weisfeiler-Lehman test of isomorphism decides as non-isomorphic, to different embeddings if the following conditions hold:
定理 3。
设 为 GNN。在层数足够时, 把 Weisfeiler-Lehman 同构检验判定为非同构的任意图 、 映到不同嵌入,若满足:
- a) aggregates and updates node features iteratively with where the functions, which operates on multisets, andare injective.
- a) 按 迭代聚合并更新节点特征,其中作用在多重集上的以及均为注入。
- b) ’s graph-level readout, which operates on the multiset of node features, is injective.
- b) 的图级读出作用在节点特征多重集上,且为注入。
We prove Theorem 3 in the appendix. For countable sets, injectiveness well characterizes whether a function preserves the distinctness of inputs. Uncountable sets, where node features are continuous, need some further considerations. In addition, it would be interesting to characterize how close together the learned features lie in a function’s image. We leave these questions for future work, and focus on the case where input node features are from a countable set (that can be a subset of an uncountable set such as ).
定理 3 的证明见附录。对可数集,注入性很好刻画函数是否保持输入的可区分性。特征连续的不可数集还需额外考虑;此外,刻画学到的特征在像中有多“挤”也很有趣。这些问题留待未来,本文聚焦输入节点特征来自可数集(可为 等不可数集的子集)的情形。
Lemma 4.
Assume the input feature space is countable. Let be the function parameterized by a GNN’s -th layer for , where is defined on multisets of bounded size. The range of , i.e., the space of node hidden features , is also countable for all .
引理 4。
假设输入特征空间 可数。设 为 GNN 第 层所参数化的函数(),其中 定义在有界大小的多重集 上。则对所有 , 的值域(即节点隐特征 的空间)也可数。
Here, it is also worth discussing an important benefit of GNNs beyond distinguishing different graphs, that is, capturing similarity of graph structures. Note that node feature vectors in the WL test are essentially one-hot encodings and thus cannot capture the similarity between subtrees. In contrast, a GNN satisfying the criteria in Theorem 3 generalizes the WL test by learning to embed the subtrees to low-dimensional space. This enables GNNs to not only discriminate different structures, but also to learn to map similar graph structures to similar embeddings and capture dependencies between graph structures. Capturing structural similarity of the node labels is shown to be helpful for generalization particularly when the co-occurrence of subtrees is sparse across different graphs or there are noisy edges and node features (Yanardag & Vishwanathan 2015).
这里也值得讨论 GNN 相对“仅区分不同图”的另一重要收益:捕捉图结构相似度。WL 检验中的节点特征本质上是 one-hot,无法刻画子树相似度。满足定理 3 条件的 GNN 则通过学习把子树嵌入低维空间来推广 WL:既能判别不同结构,也能把相似图结构映到相近嵌入并捕捉结构依赖。当不同图上子树共现稀疏,或边与节点特征有噪声时,捕捉节点标签的结构相似度有助于泛化(Yanardag & Vishwanathan 2015)。
4.1 Graph Isomorphism Network (GIN)
4.1 图同构网络(GIN)
Having developed conditions for a maximally powerful GNN, we next develop a simple architecture, Graph Isomorphism Network (GIN), that provably satisfies the conditions in Theorem 3. This model generalizes the WL test and hence achieves maximum discriminative power among GNNs.
在给出最强 GNN 的条件后,我们构造简单结构 图同构网络(GIN),可证明满足定理 3。该模型推广 WL 检验,从而在 GNN 中达到最大判别力。
To model injective multiset functions for the neighbor aggregation, we develop a theory of “deep multisets”, i.e., parameterizing universal multiset functions with neural networks. Our next lemma states that sum aggregators can represent injective, in fact, universal functions over multisets.
为给邻居聚合建模注入多重集函数,我们发展“深度多重集”理论,即用神经网络参数化通用多重集函数。下一条引理指出:求和聚合器可以表示注入的——事实上是通用的——多重集函数。
Lemma 5.
Assume is countable. There exists a function so that is unique for each multiset of bounded size. Moreover, any multiset function can be decomposed as for some function .
引理 5。
假设 可数。存在函数 ,使 对有界大小的每个多重集 都唯一。并且,任意多重集函数 可分解为 (对某个 )。
We prove Lemma 5 in the appendix. The proof extends the setting in (Zaheer et al. 2017) from sets to multisets. An important distinction between deep multisets and sets is that certain popular injective set functions, such as the mean aggregator, are not injective multiset functions. With the mechanism for modeling universal multiset functions in Lemma 5 as a building block, we can conceive aggregation schemes that can represent universal functions over a node and the multiset of its neighbors, and thus will satisfy the injectiveness condition (a) in Theorem 3. Our next corollary provides a simple and concrete formulation among many such aggregation schemes.
引理 5 证明见附录;证明把 Zaheer et al. 2017 的集合设定扩展到多重集。深度多重集与集合的重要区别是:某些流行的注入集合函数(如均值聚合)并不是注入的多重集函数。以引理 5 的通用多重集机制为构件,可设想能表示“节点及其邻居多重集”上通用函数的聚合方案,从而满足定理 3 的注入条件 (a)。下一条推论给出众多此类方案中一个简单具体的形式。
Corollary 6.
Assume is countable. There exists a function so that for infinitely many choices of , including all irrational numbers, is unique for each pair , where and is a multiset of bounded size. Moreover, any function over such pairs can be decomposed as for some function .
推论 6。
假设 可数。存在函数 ,使得对无穷多 (包括全部无理数), 对每个对 唯一,其中 , 为有界大小多重集。并且,任意定义在此类对上的函数 可分解为 (对某个 )。
We can use multi-layer perceptrons (MLPs) to model and learn and in Corollary 6, thanks to the universal approximation theorem (Hornik et al. 1989; Hornik 1991). In practice, we model with one MLP, because MLPs can represent the composition of functions. In the first iteration, we do not need MLPs before summation if input features are one-hot encodings as their summation alone is injective. We can make a learnable parameter or a fixed scalar. Then, GIN updates node representations as
由通用逼近定理(Hornik et al. 1989;Hornik 1991),可用多层感知机(MLP)建模并学习推论 6 中的 与 。实践中用一个 MLP 建模 ,因为 MLP 能表示函数复合。第一轮若输入特征为 one-hot,求和本身已注入,求和前不必再接 MLP。 可设为可学习参数或固定标量。于是 GIN 更新节点表示为
Generally, there may exist many other powerful GNNs. GIN is one such example among many maximally powerful GNNs, while being simple.
一般而言可能存在许多其他强 GNN;GIN 是其中满足最强条件且形式简单的一例。
4.2 Graph-level readout of GIN
4.2 GIN 的图级读出
Node embeddings learned by GIN can be directly used for tasks like node classification and link prediction. For graph classification tasks we propose the following “readout” function that, given embeddings of individual nodes, produces the embedding of the entire graph.
GIN 学到的节点嵌入可直接用于节点分类、链接预测等。对图分类,我们提出如下“读出”:由各节点嵌入得到整图嵌入。
An important aspect of the graph-level readout is that node representations, corresponding to subtree structures, get more refined and global as the number of iterations increases. A sufficient number of iterations is key to achieving good discriminative power. Yet, features from earlier iterations may sometimes generalize better. To consider all structural information, we use information from all depths/iterations of the model. We achieve this by an architecture similar to Jumping Knowledge Networks (Xu et al. 2018), where we replace Eq. 2.4 with graph representations concatenated across all iterations/layers of GIN:
图级读出的要点是:对应子树结构的节点表示随迭代加深而更精细、更全局。足够轮数是获得良好判别力的关键;但较早轮次的特征有时泛化更好。为纳入全部结构信息,我们使用模型所有深度/轮次的信息,采用类似 Jumping Knowledge Networks(Xu et al. 2018)的结构,把式 2.4 换成跨 GIN 所有轮次/层 拼接的图表示:
By Theorem 3 and Corollary 6, if GIN replaces READOUT in Eq. 4.2 with summing all node features from the same iterations (we do not need an extra MLP before summation for the same reason as in Eq. 4.1), it provably generalizes the WL test and the WL subtree kernel.
由定理 3 与推论 6,若把式 4.2 中的 READOUT 换成对同一轮所有节点特征求和(与式 4.1 同理,求和前不必再加 MLP),则 GIN 可证明推广了 WL 检验与 WL 子树核。
5 Less powerful but still interesting GNNs
5 较弱但仍有意思的 GNN
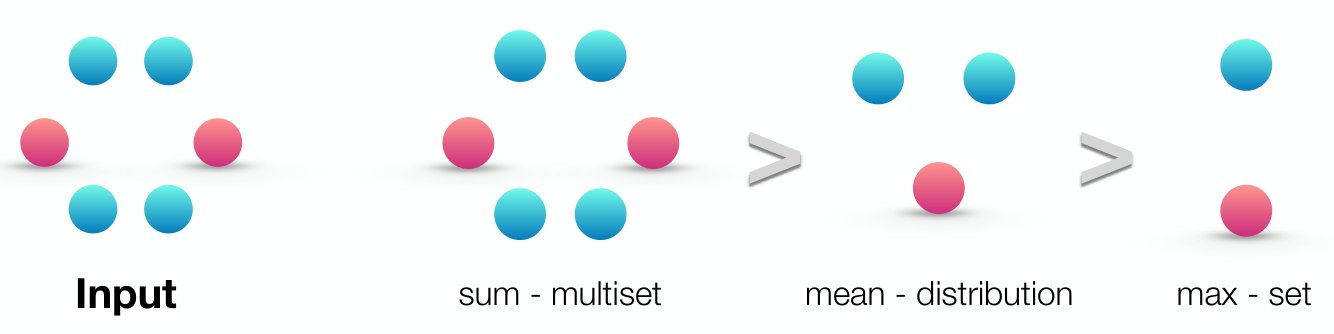
Figure 2: Ranking by expressive power for sum, mean and max aggregators over a multiset. Left panel shows the input multiset, i.e., the network neighborhood to be aggregated. The next three panels illustrate the aspects of the multiset a given aggregator is able to capture: sum captures the full multiset, mean captures the proportion/distribution of elements of a given type, and the max aggregator ignores multiplicities (reduces the multiset to a simple set).
图 2:对多重集上 sum、mean、max 聚合器按表达能力排序。 左图为输入多重集(待聚合的网络邻域)。随后三图分别示意各聚合器能捕捉的多重集侧面:sum 捕捉完整多重集,mean 捕捉某类元素的比例/分布,max 忽略重数(把多重集压成普通集合)。
(a) Mean and Max both fail
(a) 均值与最大值均失败
Next, we study GNNs that do not satisfy the conditions in Theorem 3, including GCN (Kipf & Welling 2017) and GraphSAGE (Hamilton et al. 2017a). We conduct ablation studies on two aspects of the aggregator in Eq. 4.1: (1) 1-layer perceptrons instead of MLPs and (2) mean or max-pooling instead of the sum. We will see that these GNN variants get confused by surprisingly simple graphs and are less powerful than the WL test. Nonetheless, models with mean aggregators like GCN perform well for node classification tasks. To better understand this, we precisely characterize what different GNN variants can and cannot capture about a graph and discuss the implications for learning with graphs.
接着研究不满足定理 3 条件的 GNN,包括 GCN(Kipf & Welling 2017)与 GraphSAGE(Hamilton et al. 2017a)。对式 4.1 聚合器做两方面消融:(1) 用 1 层感知机代替 MLP;(2) 用均值或最大池化代替求和。会看到这些变体会被出奇简单的图迷惑,弱于 WL 检验。尽管如此,带均值聚合的模型(如 GCN)在节点分类上表现好。为更好理解,我们精确刻画不同变体能/不能捕捉图的哪些方面,并讨论对图学习的含义。
5.1 1-layer perceptrons are not sufficient
5.1 一层感知机不够
The function in Lemma 5 helps map distinct multisets to unique embeddings. It can be parameterized by an MLP by the universal approximation theorem (Hornik 1991). Nonetheless, many existing GNNs instead use a 1-layer perceptron (Duvenaud et al. 2015; Kipf & Welling 2017; Zhang et al. 2018), a linear mapping followed by a non-linear activation function such as a ReLU. Such 1-layer mappings are examples of Generalized Linear Models (Nelder & Wedderburn 1972). Therefore, we are interested in understanding whether 1-layer perceptrons are enough for graph learning. Lemma 7 suggests that there are indeed network neighborhoods (multisets) that models with 1-layer perceptrons can never distinguish.
引理 5 中的函数 帮助把不同多重集映到唯一嵌入;由通用逼近定理(Hornik 1991)可用 MLP 参数化。但许多已有 GNN 改用 1 层感知机 (Duvenaud et al. 2015;Kipf & Welling 2017;Zhang et al. 2018),即线性映射加 ReLU 等非线性。这类 1 层映射是广义线性模型的例子(Nelder & Wedderburn 1972)。因此我们关心:图学习是否一层感知机就够?引理 7 表明:确实存在带一层感知机的模型永远无法区分的网络邻域(多重集)。
Lemma 7.
There exist finite multisets so that for any linear mapping ,
引理 7。
存在有限多重集 ,使得对任意线性映射 ,有
The main idea of the proof for Lemma 7 is that 1-layer perceptrons can behave much like linear mappings, so the GNN layers degenerate into simply summing over neighborhood features. Our proof builds on the fact that the bias term is lacking in the linear mapping. With the bias term and sufficiently large output dimensionality, 1-layer perceptrons might be able to distinguish different multisets. Nonetheless, unlike models using MLPs, the 1-layer perceptron (even with the bias term) is not a universal approximator of multiset functions. Consequently, even if GNNs with 1-layer perceptrons can embed different graphs to different locations to some degree, such embeddings may not adequately capture structural similarity, and can be difficult for simple classifiers, e.g., linear classifiers, to fit. In Section 7, we will empirically see that GNNs with -layer perceptrons, when applied to graph classification, sometimes severely underfit training data and often perform worse than GNNs with MLPs in terms of test accuracy.
引理 7 证明的核心是:1 层感知机可表现得酷似线性映射,从而使 GNN 层退化成对邻域特征简单求和。证明利用了线性映射缺少偏置项这一点。若有偏置且输出维足够大,1 层感知机或许能区分不同多重集;但即便有偏置,它也不是多重集函数的通用逼近器,这与使用 MLP 的模型不同。因此,即使带 1 层感知机的 GNN 能在一定程度上把不同图映到不同位置,这类嵌入也可能不足以刻画结构相似度,且难以被线性分类器等简单分类器拟合。第 7 节将经验看到:用于图分类时,带 1 层感知机的 GNN 有时严重欠拟合训练数据,测试准确率也常弱于带 MLP 的 GNN。
5.2 Structures that confuse mean and max-pooling
5.2 迷惑均值与最大池化的结构
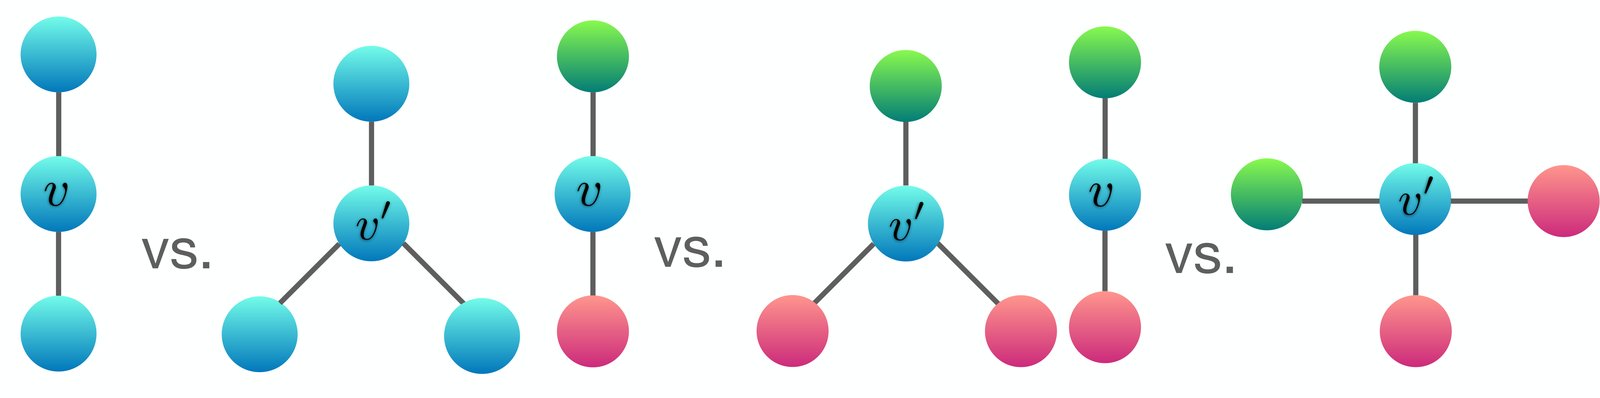
What happens if we replace the sum in with mean or max-pooling as in GCN and GraphSAGE? Mean and max-pooling aggregators are still well-defined multiset functions because they are permutation invariant. But, they are not injective. Figure 2 ranks the three aggregators by their representational power, and Figure 3 illustrates pairs of structures that the mean and max-pooling aggregators fail to distinguish. Here, node colors denote different node features, and we assume the GNNs aggregate neighbors first before combining them with the central node labeled as and .
若把 中的求和换成 GCN、GraphSAGE 中的均值或最大池化会怎样?均值与最大池化仍是良定的多重集函数(置换不变),但不是注入。图 2 按表示能力给三种聚合器排序;图 3 给出均值与最大池化无法区分的结构对。节点颜色表示不同节点特征;并假设 GNN 先聚合邻居,再与中心节点(标为 、)结合。
In Figure 3(a), every node has the same feature and is the same across all nodes (for any function ). When performing neighborhood aggregation, the mean or maximum over remains and, by induction, we always obtain the same node representation everywhere. Thus, in this case mean and max-pooling aggregators fail to capture any structural information. In contrast, the sum aggregator distinguishes the structures because and give different values. The same argument can be applied to any unlabeled graph. If node degrees instead of a constant value is used as node input features, in principle, mean can recover sum, but max-pooling cannot.
在图 3(a) 中,每个节点特征都是 ,对任意 有相同的 。邻域聚合时,对 取均值或最大仍是 ,归纳可知处处得到相同节点表示。于是均值与最大池化捕捉不到任何结构信息。相反,求和聚合可以区分,因为 与 不同。同一论证适用于任意无标签图。若用节点度数而非常数作输入特征,均值原则上可恢复求和,但最大池化不行。
Fig. 3(a) suggests that mean and max have trouble distinguishing graphs with nodes that have repeating features. Let ( for red, for green) denote node features transformed by . Fig. 3(b) shows that maximum over the neighborhood of the blue nodes and yields and , which collapse to the same representation (even though the corresponding graph structures are different). Thus, max-pooling fails to distinguish them. In contrast, the sum aggregator still works because and are in general not equivalent. Similarly, in Fig. 3(c), both mean and max fail as .
图 3(a) 表明:当节点特征重复时,均值与最大值难以区分图。设 ( 红、 绿)为经 变换后的节点特征。图 3(b) 显示:蓝节点 与 邻域上的最大值分别是 与 ,会塌成同一表示(尽管图结构不同),故最大池化失败。求和仍有效,因为 与 一般不等价。类似地,图 3(c) 中均值与最大值都失败,因 。
5.3 Mean learns distributions
5.3 均值学习分布
To characterize the class of multisets that the mean aggregator can distinguish, consider the example and , where and have the same set of distinct elements, but contains copies of each element of . Any mean aggregator maps and to the same embedding, because it simply takes averages over individual element features. Thus, the mean captures the distribution (proportions) of elements in a multiset, but not the exact multiset.
为刻画均值聚合器能区分的多重集类,考虑 与 :二者有相同的不同元素集合,但 含 每个元素的 份拷贝。任何均值聚合器把 、 映到同一嵌入,因为它只对元素特征取平均。因此均值捕捉多重集中元素的分布(比例),而非精确多重集。
Corollary 8.
Assume is countable. There exists a function so that for , if and only if multisets and have the same distribution. That is, assuming , we have and for some .
推论 8。
假设 可数。存在函数 ,使得对 , 当且仅当多重集 、 有相同分布。亦即,在 时,有 、(某个 )。
The mean aggregator may perform well if, for the task, the statistical and distributional information in the graph is more important than the exact structure. Moreover, when node features are diverse and rarely repeat, the mean aggregator is as powerful as the sum aggregator. This may explain why, despite the limitations identified in Section 5.2, GNNs with mean aggregators are effective for node classification tasks, such as classifying article subjects and community detection, where node features are rich and the distribution of the neighborhood features provides a strong signal for the task.
若任务更看重图中的统计与分布信息而非精确结构,均值聚合可能表现好。此外,当节点特征多样、很少重复时,均值与求和同等有力。这或可解释:尽管有第 5.2 节的局限,带均值聚合的 GNN 在节点分类(如文章主题分类、社区发现)上仍然有效——节点特征丰富,邻域特征分布对任务信号很强。
5.4 Max-pooling learns sets with distinct elements
5.4 最大池化学习不同元素构成的集合
The examples in Figure 3 illustrate that max-pooling considers multiple nodes with the same feature as only one node (i.e., treats a multiset as a set). Max-pooling captures neither the exact structure nor the distribution. However, it may be suitable for tasks where it is important to identify representative elements or the “skeleton”, rather than to distinguish the exact structure or distribution. Qi et al. 2017 empirically show that the max-pooling aggregator learns to identify the skeleton of a 3D point cloud and that it is robust to noise and outliers. For completeness, the next corollary shows that the max-pooling aggregator captures the underlying set of a multiset.
图 3 的例子说明:最大池化把多个同特征节点视为一个节点(即把多重集当集合)。它既不捕捉精确结构,也不捕捉分布。但对需要识别代表性元素或“骨架”、而非区分精确结构/分布的任务,它可能合适。Qi et al. 2017 经验表明,最大池化聚合能学会识别 3D 点云骨架,并对噪声与离群点稳健。为完整起见,下一条推论说明最大池化捕捉多重集的底层集合。
Corollary 9.
Assume is countable. Then there exists a function so that for , if and only if and have the same underlying set.
推论 9。
假设 可数。则存在函数 ,使得对 , 当且仅当 、 有相同底层集合。
5.5 Remarks on other aggregators
5.5 对其余聚合器的备注
There are other non-standard neighbor aggregation schemes that we do not cover, e.g., weighted average via attention (Velickovic et al. 2018) and LSTM pooling (Hamilton et al. 2017a; Murphy et al. 2018). We emphasize that our theoretical framework is general enough to characterize the representaional power of any aggregation-based GNNs. In the future, it would be interesting to apply our framework to analyze and understand other aggregation schemes.
还有本文未覆盖的非标准邻居聚合,例如经注意力的加权平均(Velickovic et al. 2018)与 LSTM 池化(Hamilton et al. 2017a;Murphy et al. 2018)。需要强调:本理论框架足够一般,可刻画任意基于聚合的 GNN 的表示能力。未来有趣的是用它分析并理解其他聚合方案。
6 Other related work
6 其他相关工作
Despite the empirical success of GNNs, there has been relatively little work that mathematically studies their properties. An exception to this is the work of Scarselli et al. 2009a who shows that the perhaps earliest GNN model (Scarselli et al. 2009b) can approximate measurable functions in probability. Lei et al. 2017 show that their proposed architecture lies in the RKHS of graph kernels, but do not study explicitly which graphs it can distinguish. Each of these works focuses on a specific architecture and do not easily generalize to multple architectures. In contrast, our results above provide a general framework for analyzing and characterizing the expressive power of a broad class of GNNs. Recently, many GNN-based architectures have been proposed, including sum aggregation and MLP encoding (Battaglia et al. 2016; Scarselli et al. 2009b; Duvenaud et al. 2015), and most without theoretical derivation. In contrast to many prior GNN architectures, our Graph Isomorphism Network (GIN) is theoretically motivated, simple yet powerful.
尽管 GNN 经验成功,对其性质的数学研究相对较少。例外包括 Scarselli et al. 2009a:表明或许最早的 GNN 模型(Scarselli et al. 2009b)能在概率意义下逼近可测函数;Lei et al. 2017 表明其结构落在图核的 RKHS 中,但未显式研究能区分哪些图。这些工作多针对特定结构,不易推广到多种结构。相比之下,上文结果为分析一大类 GNN 的表达能力提供了一般框架。近年还提出许多 GNN 结构,包括求和聚合与 MLP 编码(Battaglia et al. 2016;Scarselli et al. 2009b;Duvenaud et al. 2015),多数缺少理论推导。与许多先前结构不同,图同构网络(GIN)有理论动机,简单却有力。
7 Experiments
7 实验
We evaluate and compare the training and test performance of GIN and less powerful GNN variants.[^1] Training set performance allows us to compare different GNN models based on their representational power and test set performance quantifies generalization ability.
我们评测并比较 GIN 与较弱 GNN 变体的训练与测试表现。[^1] 训练集表现用来按表示能力比较不同 GNN;测试集表现量化泛化。
Datasets. We use 9 graph classification benchmarks: 4 bioinformatics datasets (MUTAG, PTC, NCI1, PROTEINS) and 5 social network datasets (COLLAB, IMDB-BINARY, IMDB-MULTI, REDDIT-BINARY and REDDIT-MULTI5K) (Yanardag & Vishwanathan 2015). Importantly, our goal here is not to allow the models to rely on the input node features but mainly learn from the network structure. Thus, in the bioinformatic graphs, the nodes have categorical input features but in the social networks, they have no features. For social networks we create node features as follows: for the REDDIT datasets, we set all node feature vectors to be the same (thus, features here are uninformative); for the other social graphs, we use one-hot encodings of node degrees. Dataset statistics are summarized in Table 1, and more details of the data can be found in Appendix I.
数据集。 使用 9 个图分类基准:4 个生物信息数据集(MUTAG、PTC、NCI1、PROTEINS)与 5 个社交网络数据集(COLLAB、IMDB-BINARY、IMDB-MULTI、REDDIT-BINARY、REDDIT-MULTI5K)(Yanardag & Vishwanathan 2015)。此处目标不是让模型依赖输入节点特征,而主要从图结构学习。因此生物信息图的节点有类别输入特征,社交网络则无特征。社交网络按如下造特征:REDDIT 上所有节点特征相同(因而无信息);其余社交图用节点度数的 one-hot。数据统计见表 1,细节见附录 I。
Models and configurations. We evaluate GINs (Eqs. 4.1 and 4.2) and the less powerful GNN variants. Under the GIN framework, we consider two variants: (1) a GIN that learns in Eq. 4.1 by gradient descent, which we call GIN-, and (2) a simpler (slightly less powerful)[^2] GIN, where in Eq. 4.1 is fixed to 0, which we call GIN-0. As we will see, GIN-0 shows strong empirical performance: not only does GIN-0 fit training data equally well as GIN-, it also demonstrates good generalization, slightly but consistently outperforming GIN- in terms of test accuracy. For the less powerful GNN variants, we consider architectures that replace the sum in the GIN-0 aggregation with mean or max-pooling[^3], or replace MLPs with 1-layer perceptrons, i.e., a linear mapping followed by ReLU. In Figure 4 and Table 1, a model is named by the aggregator/perceptron it uses. Here mean–1-layer and max–1-layer correspond to GCN and GraphSAGE, respectively, up to minor architecture modifications. We apply the same graph-level readout (READOUT in Eq. 4.2) for GINs and all the GNN variants, specifically, sum readout on bioinformatics datasets and mean readout on social datasets due to better test performance.
模型与配置。 评测 GIN(式 4.1、4.2)与较弱变体。在 GIN 框架下考虑两种:(1) 用梯度下降学习式 4.1 中 的 GIN-;(2) 将 固定为 0 的更简单(略弱)[^2] GIN-0。后文可见 GIN-0 经验很强:拟合训练不逊于 GIN-,测试准确率还略高且更稳。较弱变体包括:把 GIN-0 聚合中的求和换成均值或最大池化[^3],或把 MLP 换成 1 层感知机(线性映射加 ReLU)。图 4 与表 1 中模型按所用聚合/感知机命名;mean–1-layer 与 max–1-layer 分别近似对应 GCN 与 GraphSAGE(有少量结构差别)。GIN 与全部变体使用相同图级读出(式 4.2 的 READOUT):生物信息集用求和读出,社交集用均值读出(测试更好)。
Following (Yanardag & Vishwanathan 2015; Niepert et al. 2016), we perform 10-fold cross-validation with LIB-SVM (Chang & Lin 2011). We report the average and standard deviation of validation accuracies across the 10 folds within the cross-validation. For all configurations, 5 GNN layers (including the input layer) are applied, and all MLPs have layers. Batch normalization (Ioffe & Szegedy 2015) is applied on every hidden layer. We use the Adam optimizer (Kingma & Ba 2015) with initial learning rate and decay the learning rate by every 50 epochs. The hyper-parameters we tune for each dataset are: (1) the number of hidden units for bioinformatics graphs and for social graphs; (2) the batch size ; (3) the dropout ratio after the dense layer (Srivastava et al. 2014); (4) the number of epochs, i.e., a single epoch with the best cross-validation accuracy averaged over the 10 folds was selected. Note that due to the small dataset sizes, an alternative setting, where hyper-parameter selection is done using a validation set, is extremely unstable, e.g., for MUTAG, the validation set only contains 18 data points. We also report the training accuracy of different GNNs, where all the hyper-parameters were fixed across the datasets: 5 GNN layers (including the input layer), hidden units of size 64, minibatch of size 128, and 0.5 dropout ratio. For comparison, the training accuracy of the WL subtree kernel is reported, where we set the number of iterations to 4, which is comparable to the 5 GNN layers.
沿用 Yanardag & Vishwanathan 2015、Niepert et al. 2016,用 LIB-SVM(Chang & Lin 2011)做 10 折交叉验证,报告 10 折验证准确率的均值与标准差。所有配置使用 5 层 GNN(含输入层),MLP 均为 2 层;每隐层加 BatchNorm(Ioffe & Szegedy 2015)。优化器用 Adam(Kingma & Ba 2015),初始学习率 ,每 50 个 epoch 衰减 。各数据集调参:(1) 隐单元数,生物信息 ,社交为 ;(2) 批大小 ;(3) 全连接层后 dropout (Srivastava et al. 2014);(4) epoch 数,取 10 折平均交叉验证准确率最高的单个 epoch。因数据规模小,用独立验证集选参极不稳定(如 MUTAG 验证仅 18 条)。另报训练准确率:超参跨集合固定为 5 层、隐单元 64、minibatch 128、dropout 0.5。对照还报 WL 子树核的训练准确率,迭代设为 4,与 5 层 GNN 可比。
Baselines. We compare the GNNs above with a number of state-of-the-art baselines for graph classification: (1) the WL subtree kernel (Shervashidze et al. 2011), where -SVM (Chang & Lin 2011) was used as a classifier; the hyper-parameters we tune are of the SVM and the number of WL iterations ; (2) state-of-the-art deep learning architectures, i.e., Diffusion-convolutional neural networks (DCNN) (Atwood & Towsley 2016), PATCHY-SAN (Niepert et al. 2016) and Deep Graph CNN (DGCNN) (Zhang et al. 2018); (3) Anonymous Walk Embeddings (AWL) (Ivanov & Burnaev 2018). For the deep learning methods and AWL, we report the accuracies reported in the original papers.
基线。 与若干图分类 SotA 对照:(1) WL 子树核(Shervashidze et al. 2011)+ -SVM,调 与 WL 迭代数 ;(2) 深度结构:DCNN(Atwood & Towsley 2016)、PATCHY-SAN(Niepert et al. 2016)、DGCNN(Zhang et al. 2018);(3) Anonymous Walk Embeddings(AWL,Ivanov & Burnaev 2018)。深度方法与 AWL 直接引用原论文准确率。
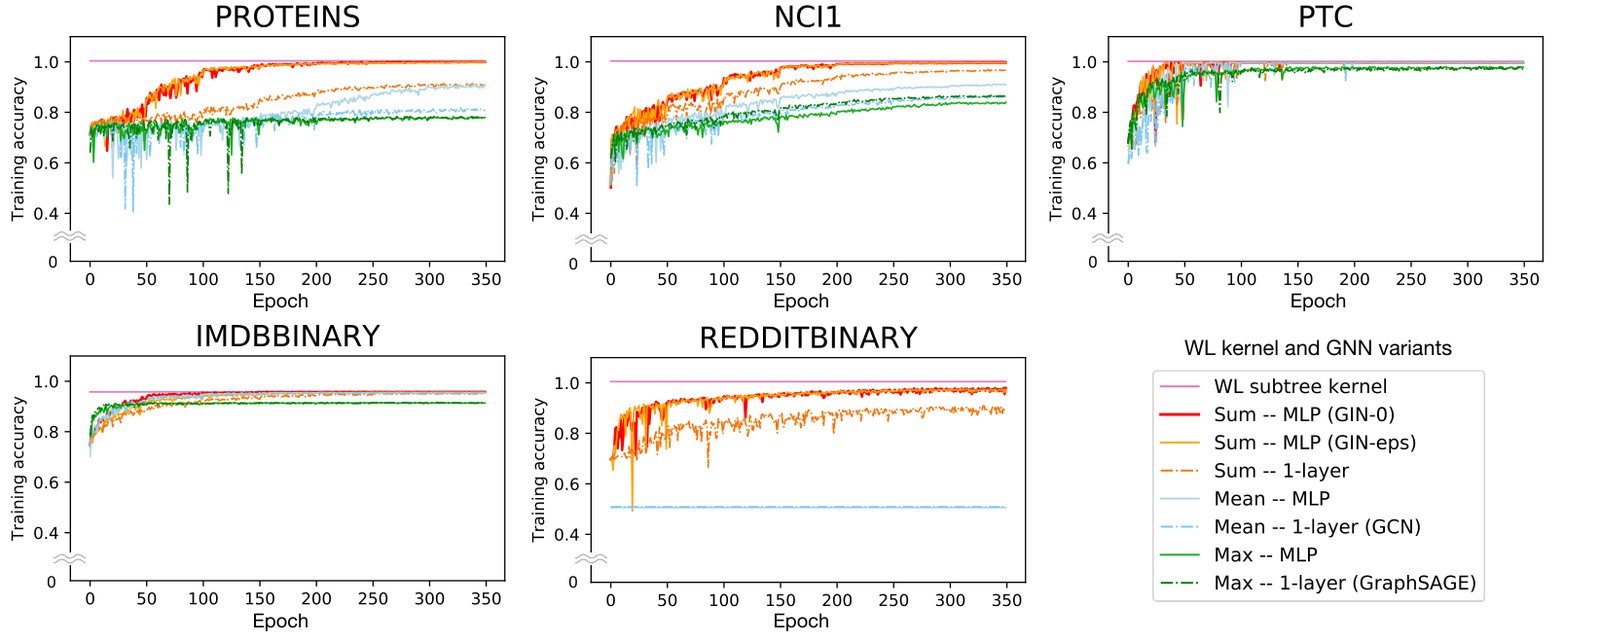
Figure 4: Training set performance of GINs, less powerful GNN variants, and the WL subtree kernel.
图 4:GIN、较弱 GNN 变体与 WL 子树核的训练集表现。
Datasets IMDB-B IMDB-M RDT-B RDT-M5K COLLAB MUTAG PROTEINS PTC NCI1 Datasets # graphs 1000 1500 2000 5000 5000 188 1113 344 4110 # classes 2 3 2 5 3 2 2 2 2 Avg # nodes 19.8 13.0 429.6 508.5 74.5 17.9 39.1 25.5 29.8 Baselines WL subtree 73.8 3.9 50.9 3.8 81.0 3.1 52.5 2.1 78.9 1.9 90.4 5.7 75.0 3.1 59.9 4.3 86.0 1.8 ∗ DCNN 49.1 33.5 – – 52.1 67.0 61.3 56.6 62.6 PatchySan 71.0 2.2 45.2 2.8 86.3 1.6 49.1 0.7 72.6 2.2 92.6 4.2 ∗ 75.9 2.8 60.0 4.8 78.6 1.9 DGCNN 70.0 47.8 – – 73.7 85.8 75.5 58.6 74.4 AWL 74.5 5.9 51.5 3.6 87.9 2.5 54.7 2.9 73.9 1.9 87.9 9.8 – – – GNN variants Sum–MLP (GIN-0) 75.1 5.1 52.3 2.8 92.4 2.5 57.5 1.5 80.2 1.9 89.4 5.6 76.2 2.8 64.6 7.0 82.7 1.7 Sum–MLP (GIN-) 74.3 5.1 52.1 3.6 92.2 2.3 57.0 1.7 80.1 1.9 89.0 6.0 75.9 3.8 63.7 8.2 82.7 1.6 Sum–1-Layer 74.1 5.0 52.2 2.4 90.0 2.7 55.1 1.6 80.6 1.9 90.0 8.8 76.2 2.6 63.1 5.7 82.0 1.5 Mean–MLP 73.7 3.7 52.3 3.1 50.0 0.0 20.0 0.0 79.2 2.3 83.5 6.3 75.5 3.4 66.6 6.9 80.9 1.8 Mean–1-Layer (GCN) 74.0 3.4 51.9 3.8 50.0 0.0 20.0 0.0 79.0 1.8 85.6 5.8 76.0 3.2 64.2 4.3 80.2 2.0 Max–MLP 73.2 5.8 51.1 3.6 – – – 84.0 6.1 76.0 3.2 64.6 10.2 77.8 1.3 Max–1-Layer (GraphSAGE) 72.3 5.3 50.9 2.2 – – – 85.1 7.6 75.9 3.2 63.9 7.7 77.7 1.5
Datasets
Baselines
GNN variants
Table 1: Test set classification accuracies (%). The best-performing GNNs are highlighted with boldface. On datasets where GINs’ accuracy is not strictly the highest among GNN variants, we see that GINs are still comparable to the best GNN because a paired t-test at significance level 10% does not distinguish GINs from the best; thus, GINs are also highlighted with boldface. If a baseline performs significantly better than all GNNs, we highlight it with boldface and asterisk.
| 数据集 | IMDB-B | IMDB-M | RDT-B | RDT-M5K | COLLAB | MUTAG | PROTEINS | PTC | NCI1 |
|---|---|---|---|---|---|---|---|---|---|
| # graphs | 1000 | 1500 | 2000 | 5000 | 5000 | 188 | 1113 | 344 | 4110 |
| # classes | 2 | 3 | 2 | 5 | 3 | 2 | 2 | 2 | 2 |
| Avg # nodes | 19.8 | 13.0 | 429.6 | 508.5 | 74.5 | 17.9 | 39.1 | 25.5 | 29.8 |
| 基线 | |||||||||
| WL subtree | 73.8 3.9 | 50.9 3.8 | 81.0 3.1 | 52.5 2.1 | 78.9 1.9 | 90.4 5.7 | 75.0 3.1 | 59.9 4.3 | 86.0 1.8 ∗ |
| DCNN | 49.1 | 33.5 | – | – | 52.1 | 67.0 | 61.3 | 56.6 | 62.6 |
| PatchySan | 71.0 2.2 | 45.2 2.8 | 86.3 1.6 | 49.1 0.7 | 72.6 2.2 | 92.6 4.2 ∗ | 75.9 2.8 | 60.0 4.8 | 78.6 1.9 |
| DGCNN | 70.0 | 47.8 | – | – | 73.7 | 85.8 | 75.5 | 58.6 | 74.4 |
| AWL | 74.5 5.9 | 51.5 3.6 | 87.9 2.5 | 54.7 2.9 | 73.9 1.9 | 87.9 9.8 | – | – | – |
| GNN 变体 | |||||||||
| Sum–MLP (GIN-0) | 75.1 5.1 | 52.3 2.8 | 92.4 2.5 | 57.5 1.5 | 80.2 1.9 | 89.4 5.6 | 76.2 2.8 | 64.6 7.0 | 82.7 1.7 |
| Sum–MLP (GIN-) | 74.3 5.1 | 52.1 3.6 | 92.2 2.3 | 57.0 1.7 | 80.1 1.9 | 89.0 6.0 | 75.9 3.8 | 63.7 8.2 | 82.7 1.6 |
| Sum–1-Layer | 74.1 5.0 | 52.2 2.4 | 90.0 2.7 | 55.1 1.6 | 80.6 1.9 | 90.0 8.8 | 76.2 2.6 | 63.1 5.7 | 82.0 1.5 |
| Mean–MLP | 73.7 3.7 | 52.3 3.1 | 50.0 0.0 | 20.0 0.0 | 79.2 2.3 | 83.5 6.3 | 75.5 3.4 | 66.6 6.9 | 80.9 1.8 |
| Mean–1-Layer (GCN) | 74.0 3.4 | 51.9 3.8 | 50.0 0.0 | 20.0 0.0 | 79.0 1.8 | 85.6 5.8 | 76.0 3.2 | 64.2 4.3 | 80.2 2.0 |
| Max–MLP | 73.2 5.8 | 51.1 3.6 | – | – | – | 84.0 6.1 | 76.0 3.2 | 64.6 10.2 | 77.8 1.3 |
| Max–1-Layer (GraphSAGE) | 72.3 5.3 | 50.9 2.2 | – | – | – | 85.1 7.6 | 75.9 3.2 | 63.9 7.7 | 77.7 1.5 |
表 1:测试集分类准确率(%)。 表现最好的 GNN 加粗。若 GIN 并非严格最高,但在 10% 显著性的配对 t 检验下与最佳 GNN 无区别,亦加粗。若某基线显著优于全部 GNN,则加粗并标星号。
7.1 Results
7.1 结果
Training set performance. We validate our theoretical analysis of the representational power of GNNs by comparing their training accuracies. Models with higher representational power should have higher training set accuracy. Figure 4 shows training curves of GINs and less powerful GNN variants with the same hyper-parameter settings. First, both the theoretically most powerful GNN, i.e. GIN- and GIN-0, are able to almost perfectly fit all the training sets. In our experiments, explicit learning of in GIN- yields no gain in fitting training data compared to fixing to 0 as in GIN-0. In comparison, the GNN variants using mean/max pooling or 1-layer perceptrons severely underfit on many datasets. In particular, the training accuracy patterns align with our ranking by the models’ representational power: GNN variants with MLPs tend to have higher training accuracies than those with 1-layer perceptrons, and GNNs with sum aggregators tend to fit the training sets better than those with mean and max-pooling aggregators.
训练集表现。 通过比较训练准确率验证关于 GNN 表示能力的理论分析:表示能力更强的模型应有更高训练准确率。图 4 在相同超参下给出 GIN 与较弱变体的训练曲线。首先,理论上最强的 GIN- 与 GIN-0 几乎能完美拟合全部训练集;显式学习 相对固定为 0 并无额外拟合收益。相比之下,使用均值/最大池化或 1 层感知机的变体在多个数据集上严重欠拟合。训练准确率排序与按表示能力的理论排序一致:带 MLP 的变体往往高于 1 层感知机;带求和聚合的往往比均值、最大池化更好拟合。
On our datasets, training accuracies of the GNNs never exceed those of the WL subtree kernel. This is expected because GNNs generally have lower discriminative power than the WL test. For example, on IMDBBINARY, none of the models can perfectly fit the training set, and the GNNs achieve at most the same training accuracy as the WL kernel. This pattern aligns with our result that the WL test provides an upper bound for the representational capacity of the aggregation-based GNNs. However, the WL kernel is not able to learn how to combine node features, which might be quite informative for a given prediction task as we will see next.
在我们的数据上,GNN 训练准确率从未超过 WL 子树核。这符合预期:GNN 的判别力一般低于 WL 检验。例如在 IMDB-BINARY 上,没有模型能完美拟合,GNN 至多达到与 WL 核相同的训练准确率。这与“WL 检验给出基于聚合的 GNN 表示能力上界”一致。但 WL 核无法学习如何组合节点特征,而这对预测任务可能很有信息量,如下文所示。
Test set performance. Next, we compare test accuracies. Although our theoretical results do not directly speak about the generalization ability of GNNs, it is reasonable to expect that GNNs with strong expressive power can accurately capture graph structures of interest and thus generalize well. Table 1 compares test accuracies of GINs (Sum–MLP), other GNN variants, as well as the state-of-the-art baselines.
测试集表现。 理论结果并不直接谈论泛化,但可合理预期:表达力强的 GNN 更能准确捕捉感兴趣的图结构,从而泛化更好。表 1 比较 GIN(Sum–MLP)、其他变体与 SotA 基线的测试准确率。
First, GINs, especially GIN-0, outperform (or achieve comparable performance as) the less powerful GNN variants on all the 9 datasets, achieving state-of-the-art performance. GINs shine on the social network datasets, which contain a relatively large number of training graphs. For the Reddit datasets, all nodes share the same scalar as node feature. Here, GINs and sum-aggregation GNNs accurately capture the graph structure and significantly outperform other models. Mean-aggregation GNNs, however, fail to capture any structures of the unlabeled graphs (as predicted in Section 5.2) and do not perform better than random guessing. Even if node degrees are provided as input features, mean-based GNNs perform much worse than sum-based GNNs (the accuracy of the GNN with mean–MLP aggregation is 71.24.6% on REDDIT-BINARY and 41.32.1% on REDDIT-MULTI5K). Comparing GINs (GIN-0 and GIN-), we observe that GIN-0 slightly but consistently outperforms GIN-. Since both models fit training data equally well, the better generalization of GIN-0 may be explained by its simplicity compared to GIN-.
首先,GIN(尤其 GIN-0)在全部 9 个数据集上优于或可比于较弱变体,达到当时最优。社交网络数据训练图较多,GIN 尤为突出。REDDIT 上所有节点共用同一标量特征时,GIN 与求和聚合 GNN 能准确捕捉结构并显著超过其他模型;均值聚合则无法捕捉无标签图的任何结构(与第 5.2 节一致),表现不优于随机猜测。即便提供节点度数作输入,均值类 GNN 仍远弱于求和类(mean–MLP 在 REDDIT-BINARY 约 71.24.6%,在 REDDIT-MULTI5K 约 41.32.1%)。比较 GIN-0 与 GIN-,前者略高且更稳;二者拟合训练相当,更好泛化或可用结构更简单解释。
8 Conclusion
8 结论
In this paper, we developed theoretical foundations for reasoning about the expressive power of GNNs, and proved tight bounds on the representational capacity of popular GNN variants. We also designed a provably maximally powerful GNN under the neighborhood aggregation framework. An interesting direction for future work is to go beyond neighborhood aggregation (or message passing) in order to pursue possibly even more powerful architectures for learning with graphs. To complete the picture, it would also be interesting to understand and improve the generalization properties of GNNs as well as better understand their optimization landscape.
本文为推理 GNN 表达能力建立理论基础,并对流行变体的表示能力给出紧界;同时在邻域聚合框架下设计了可证明最强的 GNN。未来有趣方向是超越邻域聚合(或消息传递),追求可能更强的图学习结构。为补全图景,理解并改进 GNN 的泛化与优化景观同样重要。
Acknowledgments
This research was supported by NSF CAREER award 1553284, a DARPA D3M award and DARPA DSO’s Lagrange program under grant FA86501827838. This research was also supported in part by NSF, ARO MURI, Boeing, Huawei, Stanford Data Science Initiative, and Chan Zuckerberg Biohub. Weihua Hu was supported by Funai Overseas Scholarship. We thank Prof. Ken-ichi Kawarabayashi and Prof. Masashi Sugiyama for supporting this research with computing resources and providing great advice. We thank Tomohiro Sonobe and Kento Nozawa for managing servers. We thank Rex Ying and William Hamilton for helpful feedback. We thank Simon S. Du, Yasuo Tabei, Chengtao Li, and Jingling Li for helpful discussions and positive comments.
致谢
本工作获 NSF CAREER award 1553284、DARPA D3M 以及 DARPA DSO Lagrange 项目(FA86501827838)支持;亦获 NSF、ARO MURI、Boeing、Huawei、Stanford Data Science Initiative 与 Chan Zuckerberg Biohub 部分支持。Weihua Hu 获 Funai Overseas Scholarship 资助。感谢 Ken-ichi Kawarabayashi 与 Masashi Sugiyama 教授提供算力与建议;感谢 Tomohiro Sonobe 与 Kento Nozawa 维护服务器;感谢 Rex Ying、William Hamilton 的反馈,以及 Simon S. Du、Yasuo Tabei、Chengtao Li、Jingling Li 的讨论与鼓励。
References
参考文献
Atwood & Towsley (2016) James Atwood and Don Towsley. Diffusion-convolutional neural networks. In Advances in Neural Information Processing Systems (NIPS) , pp. 1993–2001, 2016.
Babai (2016) László Babai. Graph isomorphism in quasipolynomial time. In Proceedings of the forty-eighth annual ACM symposium on Theory of Computing , pp. 684–697. ACM, 2016.
Babai & Kucera (1979) László Babai and Ludik Kucera. Canonical labelling of graphs in linear average time. In Foundations of Computer Science, 1979., 20th Annual Symposium on , pp. 39–46. IEEE, 1979.
Battaglia et al. (2016) Peter Battaglia, Razvan Pascanu, Matthew Lai, Danilo Jimenez Rezende, et al. Interaction networks for learning about objects, relations and physics. In Advances in Neural Information Processing Systems (NIPS) , pp. 4502–4510, 2016.
Cai et al. (1992) Jin-Yi Cai, Martin Fürer, and Neil Immerman. An optimal lower bound on the number of variables for graph identification. Combinatorica , 12(4):389–410, 1992.
Chang & Lin (2011) Chih-Chung Chang and Chih-Jen Lin. Libsvm: a library for support vector machines. ACM transactions on intelligent systems and technology (TIST) , 2(3):27, 2011.
Defferrard et al. (2016) Michaël Defferrard, Xavier Bresson, and Pierre Vandergheynst. Convolutional neural networks on graphs with fast localized spectral filtering. In Advances in Neural Information Processing Systems (NIPS) , pp. 3844–3852, 2016.
Douglas (2011) Brendan L Douglas. The weisfeiler-lehman method and graph isomorphism testing. arXiv preprint arXiv:1101.5211 , 2011.
Duvenaud et al. (2015) David K Duvenaud, Dougal Maclaurin, Jorge Iparraguirre, Rafael Bombarell, Timothy Hirzel, Alán Aspuru-Guzik, and Ryan P Adams. Convolutional networks on graphs for learning molecular fingerprints. pp. 2224–2232, 2015.
Evdokimov & Ponomarenko (1999) Sergei Evdokimov and Ilia Ponomarenko. Isomorphism of coloured graphs with slowly increasing multiplicity of jordan blocks. Combinatorica , 19(3):321–333, 1999.
Garey (1979) Michael R Garey. A guide to the theory of np-completeness. Computers and intractability , 1979.
Garey & Johnson (2002) Michael R Garey and David S Johnson. Computers and intractability , volume 29. wh freeman New York, 2002.
Gilmer et al. (2017) Justin Gilmer, Samuel S Schoenholz, Patrick F Riley, Oriol Vinyals, and George E Dahl. Neural message passing for quantum chemistry. In International Conference on Machine Learning (ICML) , pp. 1273–1272, 2017.
Hamilton et al. (2017a) William L Hamilton, Rex Ying, and Jure Leskovec. Inductive representation learning on large graphs. In Advances in Neural Information Processing Systems (NIPS) , pp. 1025–1035, 2017a.
Hamilton et al. (2017b) William L Hamilton, Rex Ying, and Jure Leskovec. Representation learning on graphs: Methods and applications. IEEE Data Engineering Bulletin , 40(3):52–74, 2017b.
Hornik (1991) Kurt Hornik. Approximation capabilities of multilayer feedforward networks. Neural networks , 4(2):251–257, 1991.
Hornik et al. (1989) Kurt Hornik, Maxwell Stinchcombe, and Halbert White. Multilayer feedforward networks are universal approximators. Neural networks , 2(5):359–366, 1989.
Ioffe & Szegedy (2015) Sergey Ioffe and Christian Szegedy. Batch normalization: Accelerating deep network training by reducing internal covariate shift. In International Conference on Machine Learning (ICML) , pp. 448–456, 2015.
Ivanov & Burnaev (2018) Sergey Ivanov and Evgeny Burnaev. Anonymous walk embeddings. In International Conference on Machine Learning (ICML) , pp. 2191–2200, 2018.
Kearnes et al. (2016) Steven Kearnes, Kevin McCloskey, Marc Berndl, Vijay Pande, and Patrick Riley. Molecular graph convolutions: moving beyond fingerprints. Journal of computer-aided molecular design , 30(8):595–608, 2016.
Kingma & Ba (2015) Diederik P Kingma and Jimmy Ba. Adam: A method for stochastic optimization. In International Conference on Learning Representations (ICLR) , 2015.
Kipf & Welling (2017) Thomas N Kipf and Max Welling. Semi-supervised classification with graph convolutional networks. In International Conference on Learning Representations (ICLR) , 2017.
Lei et al. (2017) Tao Lei, Wengong Jin, Regina Barzilay, and Tommi Jaakkola. Deriving neural architectures from sequence and graph kernels. pp. 2024–2033, 2017.
Li et al. (2016) Yujia Li, Daniel Tarlow, Marc Brockschmidt, and Richard Zemel. Gated graph sequence neural networks. In International Conference on Learning Representations (ICLR) , 2016.
Murphy et al. (2018) Ryan L Murphy, Balasubramaniam Srinivasan, Vinayak Rao, and Bruno Ribeiro. Janossy pooling: Learning deep permutation-invariant functions for variable-size inputs. arXiv preprint arXiv:1811.01900 , 2018.
Nelder & Wedderburn (1972) J. A. Nelder and R. W. M. Wedderburn. Generalized linear models. Journal of the Royal Statistical Society, Series A, General , 135:370–384, 1972.
Niepert et al. (2016) Mathias Niepert, Mohamed Ahmed, and Konstantin Kutzkov. Learning convolutional neural networks for graphs. In International Conference on Machine Learning (ICML) , pp. 2014–2023, 2016.
Qi et al. (2017) Charles R Qi, Hao Su, Kaichun Mo, and Leonidas J Guibas. Pointnet: Deep learning on point sets for 3d classification and segmentation. Proc. Computer Vision and Pattern Recognition (CVPR), IEEE , 1(2):4, 2017.
Santoro et al. (2017) Adam Santoro, David Raposo, David G Barrett, Mateusz Malinowski, Razvan Pascanu, Peter Battaglia, and Timothy Lillicrap. A simple neural network module for relational reasoning. In Advances in neural information processing systems , pp. 4967–4976, 2017.
Santoro et al. (2018) Adam Santoro, Felix Hill, David Barrett, Ari Morcos, and Timothy Lillicrap. Measuring abstract reasoning in neural networks. In International Conference on Machine Learning , pp. 4477–4486, 2018.
Scarselli et al. (2009a) Franco Scarselli, Marco Gori, Ah Chung Tsoi, Markus Hagenbuchner, and Gabriele Monfardini. Computational capabilities of graph neural networks. IEEE Transactions on Neural Networks , 20(1):81–102, 2009a.
Scarselli et al. (2009b) Franco Scarselli, Marco Gori, Ah Chung Tsoi, Markus Hagenbuchner, and Gabriele Monfardini. The graph neural network model. IEEE Transactions on Neural Networks , 20(1):61–80, 2009b.
Shervashidze et al. (2011) Nino Shervashidze, Pascal Schweitzer, Erik Jan van Leeuwen, Kurt Mehlhorn, and Karsten M Borgwardt. Weisfeiler-lehman graph kernels. Journal of Machine Learning Research , 12(Sep):2539–2561, 2011.
Srivastava et al. (2014) Nitish Srivastava, Geoffrey Hinton, Alex Krizhevsky, Ilya Sutskever, and Ruslan Salakhutdinov. Dropout: a simple way to prevent neural networks from overfitting. The Journal of Machine Learning Research , 15(1):1929–1958, 2014.
Velickovic et al. (2018) Petar Velickovic, Guillem Cucurull, Arantxa Casanova, Adriana Romero, Pietro Lio, and Yoshua Bengio. Graph attention networks. In International Conference on Learning Representations (ICLR) , 2018.
Verma & Zhang (2018) Saurabh Verma and Zhi-Li Zhang. Graph capsule convolutional neural networks. arXiv preprint arXiv:1805.08090 , 2018.
Weisfeiler & Lehman (1968) Boris Weisfeiler and AA Lehman. A reduction of a graph to a canonical form and an algebra arising during this reduction. Nauchno-Technicheskaya Informatsia , 2(9):12–16, 1968.
Xu et al. (2018) Keyulu Xu, Chengtao Li, Yonglong Tian, Tomohiro Sonobe, Ken-ichi Kawarabayashi, and Stefanie Jegelka. Representation learning on graphs with jumping knowledge networks. In International Conference on Machine Learning (ICML) , pp. 5453–5462, 2018.
Yanardag & Vishwanathan (2015) Pinar Yanardag and SVN Vishwanathan. Deep graph kernels. In Proceedings of the 21th ACM SIGKDD International Conference on Knowledge Discovery and Data Mining , pp. 1365–1374. ACM, 2015.
Ying et al. (2018) Rex Ying, Jiaxuan You, Christopher Morris, Xiang Ren, William L Hamilton, and Jure Leskovec. Hierarchical graph representation learning with differentiable pooling. In Advances in Neural Information Processing Systems (NIPS) , 2018.
Zaheer et al. (2017) Manzil Zaheer, Satwik Kottur, Siamak Ravanbakhsh, Barnabas Poczos, Ruslan R Salakhutdinov, and Alexander J Smola. Deep sets. In Advances in Neural Information Processing Systems , pp. 3391–3401, 2017.
Zhang et al. (2018) Muhan Zhang, Zhicheng Cui, Marion Neumann, and Yixin Chen. An end-to-end deep learning architecture for graph classification. In AAAI Conference on Artificial Intelligence , pp. 4438–4445, 2018.
Appendix A Proof for Lemma 2
附录 A 引理 2 的证明
Proof.
Suppose after iterations, a graph neural network has but the WL test cannot decide and are non-isomorphic. It follows that from iteration to in the WL test, and always have the same collection of node labels. In particular, because and have the same WL node labels for iteration and for any , and have the same collection, i.e. multiset, of WL node labels as well as the same collection of node neighborhoods . Otherwise, the WL test would have obtained different collections of node labels at iteration for and as different multisets get unique new labels.
证明。
假设经过 轮后,图神经网络 有 ,但 WL 检验无法判定 、 非同构。则 WL 从第 0 轮到第 轮, 与 始终有相同的节点标签集合。特别地,对任意 ,因第 与第 轮 WL 节点标签集合相同, 与 有相同的 WL 节点标签多重集 ,以及相同的节点邻域集合 。否则 WL 会在第 轮因不同多重集得到不同的新标签集合。
The WL test always relabels different multisets of neighboring nodes into different new labels. We show that on the same graph or , if WL node labels , we always have GNN node features for any iteration . This apparently holds for because WL and GNN starts with the same node features. Suppose this holds for iteration , if for any , , then it must be the case that
WL 检验总是把不同的邻居多重集重新标成不同新标签。我们证明:在同一图 或 上,若 ,则对任意轮次 都有 GNN 节点特征 。 显然成立,因为 WL 与 GNN 从相同节点特征起步。假设第 轮成立,则若对任意 有 ,必有
By our assumption on iteration , we must have
由第 轮假设,必有
In the aggregation process of the GNN, the same AGGREGATE and COMBINE are applied. The same input, i.e. neighborhood features, generates the same output. Thus, . By induction, if WL node labels , we always have GNN node features for any iteration . This creates a valid mapping such that for any . It follows from and have the same multiset of WL neighborhood labels that and also have the same collection of GNN neighborhood features
GNN 聚合中使用相同的 AGGREGATE 与 COMBINE,相同输入(邻域特征)产生相同输出,故 。归纳可知:若 ,则对任意 有 。由此得到合法映射 ,使对任意 有 。由 、 有相同的 WL 邻域标签多重集,它们也有相同的 GNN 邻域特征集合
Thus, are the same. In particular, we have the same collection of GNN node features for and . Because the graph level readout function is permutation invariant with respect to the collection of node features, . Hence we have reached a contradiction. ∎
因而 相同。特别地,、 有相同的 GNN 节点特征集合 。图级读出对节点特征集合置换不变,故 ,矛盾。∎
Appendix B Proof for Theorem 3
附录 B 定理 3 的证明
Proof.
Let be a graph neural network where the condition holds. Let , be any graphs which the WL test decides as non-isomorphic at iteration . Because the graph-level readout function is injective, i.e., it maps distinct multiset of node features into unique embeddings, it sufficies to show that ’s neighborhood aggregation process, with sufficient iterations, embeds and into different multisets of node features. Let us assume updates node representations as
证明。
设 为满足条件的图神经网络。设 、 为 WL 在第 轮判定为非同构的任意图。因图级读出注入(把不同节点特征多重集映到唯一嵌入),只需证明:在足够轮次下, 的邻域聚合把 、 嵌入为不同的节点特征多重集。设 按
with injective funtions and . The WL test applies a predetermined injective hash function to update the WL node labels :
更新,其中 、 注入。WL 用预定注入散列 更新标签 :
We will show, by induction, that for any iteration , there always exists an injective function such that . This apparently holds for because the initial node features are the same for WL and GNN for all . So could be the identity function for . Suppose this holds for iteration , we show that it also holds for . Substituting with gives us
我们用归纳证明:对任意轮次 ,总存在注入 使 。 显然,因初始特征相同 , 可取恒等。假设第 轮成立,则第 轮把 换成 得
Since the composition of injective functions is injective, there exists some injective function so that
注入函数的复合仍注入,故存在注入 使
Then we have
于是
is injective because the composition of injective functions is injective. Hence for any iteration , there always exists an injective function such that . At the -th iteration, the WL test decides that and are non-isomorphic, that is the multisets are different for and . The graph neural network ’s node embeddings must also be different for and because of the injectivity of .
因复合而注入。故对任意 都存在注入 使 。第 轮 WL 判定 、 非同构,即多重集 不同;由 的注入性, 的节点嵌入 对两图也不同。
∎
Appendix C Proof for Lemma 4
附录 C 引理 4 的证明
Proof.
Before proving our lemma, we first show a well-known result that we will later reduce our problem to: is countable for every , i.e. finite Cartesian product of countable sets is countable. We observe that it suffices to show is countable, because the proof then follows clearly from induction. To show is countable, we construct a bijection from to as
证明。
证明引理前,先给出稍后会归约到的熟知结论:对每个 , 可数,即有限个可数集的笛卡尔积可数。只需证明 可数,再归纳即可。构造双射 如下
Now we go back to proving our lemma. If we can show that the range of any function defined on multisets of bounded size from a countable set is also countable, then the lemma holds for any by induction. Thus, our goal is to show that the range of such is countable. First, it is clear that the mapping from to is injective because is a well-defined function. It follows that it suffices to show the set of all multisets is countable.
回到引理。若能证明:定义在可数集上、有界大小多重集上的任意函数 ,其值域也可数,则对任意 由归纳成立。故目标是证明此类 的值域可数。首先, 到 的映射因 良定而注入,从而只需证明所有多重集 构成的集合可数。
Since the union of two countable sets is countable, the following set is also countable.
两可数集之并可数,故下列集合 也可数:
where is a dummy element that is not in . It follows from the result we showed above, i.e., is countable for every , that is countable for every . It remains to show there exists an injective mapping from the set of multisets in to for some .
其中 为哑元。由上文, 对每个 可数,故 对每个 可数。余下只需证明存在从 中多重集集合到某个 的注入。
We construct an injective mapping from the set of multisets to for some as follows. Because is countable, there exists a mapping from to natural numbers. We can sort the elements by as , where . Because the multisets are of bounded size, there exists so that for all . We can then define as
构造注入 :因 可数,存在 。将 按 排序为 ()。多重集大小有界,存在 使所有 。定义
where the coordinates are filled with the dummy element . It is clear that is injective because for any multisets and of bounded size, only if is equivalent to . Hence it follows that the range of is countable as desired.
后 个坐标填哑元 。 显然注入:对有界大小多重集 、, 仅当 与 等价。故 的值域可数。
∎
Appendix D Proof for Lemma 5
附录 D 引理 5 的证明
Proof.
We first prove that there exists a mapping so that is unique for each multiset of bounded size. Because is countable, there exists a mapping from to natural numbers. Because the cardinality of multisets is bounded, there exists a number so that for all . Then an example of such is . This can be viewed as a more compressed form of an one-hot vector or -digit presentation. Thus, is an injective function of multisets.
证明。
先证存在映射 ,使对有界大小的每个多重集 , 唯一。因 可数,存在 ;因基数有界,存在 使所有 。一例是 ,可视为更压缩的 one-hot 或 进制表示。于是 为多重集上的注入函数。
is permutation invariant so it is a well-defined multiset function. For any multiset function , we can construct such by letting . Note that such is well-defined because is injective.
置换不变,因而是良定的多重集函数。对任意多重集函数 ,可令 构造 ;因 注入,该 良定。
∎
Appendix E Proof of Corollary 6
附录 E 推论 6 的证明
Proof.
Following the proof of Lemma 5, we consider , where and are the same as defined in Appendix D. Let . Our goal is show that for any with and , holds, if is an irrational number. We prove by contradiction. For any , suppose there exists such that but holds. Let us consider the following two cases: (1) but , and (2) . For the first case, implies . It follows from Lemma 5 that the equality will not hold, because with , implies . Thus, we reach a contradiction. For the second case, we can similarly rewrite as
证明。
沿用引理 5 的证明,取 ( 与 同附录 D)。令 。目标是证明:对任意 (,),当 为无理数时 。用反证。对任意 ,假设存在 使 相等。分两种情形:(1) 但 ;(2) 。情形 (1) 由 得 ,与引理 5 及 矛盾。情形 (2) 可改写为
Because is an irrational number and is a non-zero rational number, L.H.S. of Eq. E.1 is irrational. On the other hand, R.H.S. of Eq. E.1, the sum of a finite number of rational numbers, is rational. Hence the equality in Eq. E.1 cannot hold, and we have reached a contradiction.
因 无理且 为非零有理数,式 E.1 左边无理;右边为有限个有理数之和,有理。等式不能成立,矛盾。
For any function over the pairs , we can construct such for the desired decomposition by letting . Note that such is well-defined because is injective. ∎
对任意定义在对 上的函数 ,可令 得到所需分解;因 注入, 良定。∎
Appendix F Proof for Lemma 7
附录 F 引理 7 的证明
Proof.
Let us consider the example and , i.e. two different multisets of positive numbers that sum up to the same value. We will be using the homogeneity of ReLU.
证明。
取例子 与 ,即两个不同但元素之和相同的正数多重集。证明将用到 ReLU 的齐次性。
Let be an arbitrary linear transform that maps into . It is clear that, at the same coordinates, are either positive or negative for all because all in and are positive. It follows that ReLU are either positive or at the same coordinate for all in . For the coordinates where ReLU are , we have . For the coordinates where are positive, linearity still holds. It follows from linearity that
设 为把 映到 的任意线性变换。因 、 中所有 为正,同一坐标上 同号(全正或全负)。故对所有 ,ReLU 在同一坐标上要么同为正,要么同为 0。在为 0 的坐标上,。在 为正的坐标上线性仍成立,故
where could be or . Because , we have the following as desired.
其中 可为 或 。因 ,即得所欲:
∎
Appendix G Proof for Corollary 8
附录 G 推论 8 的证明
Proof.
Suppose multisets and have the same distribution, without loss of generality, let us assume and for some , i.e. and have the same underlying set and the multiplicity of each element in is times of that in . Then we have and . Thus,
证明。
设多重集 、 有相同分布;不失一般性令 、(某个 ),即底层集合相同且 中每个元素重数是 的 倍。则 且 。于是
Now we show that there exists a function so that is unique for distributionally equivalent . Because is countable, there exists a mapping from to natural numbers. Because the cardinality of multisets is bounded, there exists a number so that for all . Then an example of such is . ∎
再证存在 使 对分布等价的 唯一。因 可数,存在 ;因基数有界,存在 使所有 。一例是 。∎
Appendix H Proof for Corollary 9
附录 H 推论 9 的证明
Proof.
Suppose multisets and have the same underlying set , then we have
证明。
设多重集 、 有相同底层集合 ,则
Now we show that there exists a mapping so that is unique for s with the same underlying set. Because is countable, there exists a mapping from to natural numbers. Then an example of such is defined as for and otherwise, where is the -th coordinate of . Such an essentially maps a multiset to its one-hot embedding. ∎
再证存在映射 使 对有相同底层集合的 唯一。因 可数,存在 。一例 定义为: 时 ,否则为 0。这样的 本质上把多重集映到其 one-hot 嵌入。∎
Appendix I Details of datasets
附录 I 数据集细节
We give detailed descriptions of datasets used in our experiments. Further details can be found in (Yanardag & Vishwanathan 2015).
下面详细描述实验所用数据集;更多细节见 Yanardag & Vishwanathan 2015。
Social networks datasets.
IMDB-BINARY and IMDB-MULTI are movie collaboration datasets. Each graph corresponds to an ego-network for each actor/actress, where nodes correspond to actors/actresses and an edge is drawn betwen two actors/actresses if they appear in the same movie. Each graph is derived from a pre-specified genre of movies, and the task is to classify the genre graph it is derived from. REDDIT-BINARY and REDDIT-MULTI5K are balanced datasets where each graph corresponds to an online discussion thread and nodes correspond to users. An edge was drawn between two nodes if at least one of them responded to another’s comment. The task is to classify each graph to a community or a subreddit it belongs to. COLLAB is a scientific collaboration dataset, derived from 3 public collaboration datasets, namely, High Energy Physics, Condensed Matter Physics and Astro Physics. Each graph corresponds to an ego-network of different researchers from each field. The task is to classify each graph to a field the corresponding researcher belongs to.
社交网络数据集。
IMDB-BINARY 与 IMDB-MULTI 为电影合作数据集。每个图对应一位演员/女演员的 ego-network:节点为演员,若两人出现在同一部电影中则连边。图来自预先指定的电影类型,任务是分类该图所属类型。REDDIT-BINARY 与 REDDIT-MULTI5K 为平衡数据集:每个图对应一个在线讨论串,节点为用户;若至少一方回复了另一方的评论则连边。任务是把每个图分到所属社区或子版块。COLLAB 为科学合作数据集,来自高能物理、凝聚态物理与天体物理三个公开合作数据集;每个图对应各领域研究者的 ego-network,任务是分类研究者所属领域。
Bioinformatics datasets.
MUTAG is a dataset of 188 mutagenic aromatic and heteroaromatic nitro compounds with 7 discrete labels. PROTEINS is a dataset where nodes are secondary structure elements (SSEs) and there is an edge between two nodes if they are neighbors in the amino-acid sequence or in 3D space. It has 3 discrete labels, representing helix, sheet or turn. PTC is a dataset of 344 chemical compounds that reports the carcinogenicity for male and female rats and it has 19 discrete labels. NCI1 is a dataset made publicly available by the National Cancer Institute (NCI) and is a subset of balanced datasets of chemical compounds screened for ability to suppress or inhibit the growth of a panel of human tumor cell lines, having 37 discrete labels.
生物信息数据集。
MUTAG 含 188 个致突变芳香与杂芳硝基化合物,7 个离散标签。PROTEINS 中节点为二级结构元件(SSE),若在氨基酸序列或三维空间中相邻则连边,含 3 个离散标签(螺旋、折叠或转角)。PTC 含 344 个化合物,报告对雌雄大鼠的致癌性,19 个离散标签。NCI1 由国家癌症研究所公开,是筛查抑制人类肿瘤细胞系生长能力的平衡化合物子集,37 个离散标签。