High-Dimensional Continuous Control Using Generalized Advantage Estimation
High-Dimensional Continuous Control Using Generalized Advantage Estimation
用广义优势估计实现高维连续控制
John Schulman Philipp Moritz Sergey Levine Michael I. Jordan Pieter Abbeel Affiliation: Department of Electrical Engineering and Computer Science Affiliation: University of California, Berkeley Email: {joschu,pcmoritz,levine,jordan,pabbeel}@eecs.berkeley.edu
Abstract
摘要
Policy gradient methods are an appealing approach in reinforcement learning because they directly optimize the cumulative reward and can straightforwardly be used with nonlinear function approximators such as neural networks. The two main challenges are the large number of samples typically required, and the difficulty of obtaining stable and steady improvement despite the nonstationarity of the incoming data. We address the first challenge by using value functions to substantially reduce the variance of policy gradient estimates at the cost of some bias, with an exponentially-weighted estimator of the advantage function that is analogous to TD(). We address the second challenge by using trust region optimization procedure for both the policy and the value function, which are represented by neural networks.
策略梯度方法在强化学习中很有吸引力,因为它们直接优化累积回报,并且可以很自然地与神经网络这类非线性函数逼近器一起使用。两个主要困难是:通常需要大量样本,以及在输入数据非平稳的情况下,难以获得稳定而持续的改进。针对第一点,我们用价值函数在引入一定偏差的代价下显著降低策略梯度估计的方差,并采用一种与 TD() 类似的、对优势函数做指数加权的估计器。针对第二点,我们对策略和价值函数都使用信赖域优化,二者均用神经网络表示。
Our approach yields strong empirical results on highly challenging 3D locomotion tasks, learning running gaits for bipedal and quadrupedal simulated robots, and learning a policy for getting the biped to stand up from starting out lying on the ground. In contrast to a body of prior work that uses hand-crafted policy representations, our neural network policies map directly from raw kinematics to joint torques. Our algorithm is fully model-free, and the amount of simulated experience required for the learning tasks on 3D bipeds corresponds to 1-2 weeks of real time.
我们的方法在极具挑战性的三维运动任务上取得了很强的经验结果:为双足和四足仿真机器人学到了奔跑步态,并为从仰卧起始姿态站起来的双足机器人学到了策略。与许多依赖手工设计策略表示的已有工作不同,我们的神经网络策略直接把原始运动学量映射到关节力矩。算法完全是无模型的;在三维双足任务上所需的仿真经验,大约相当于现实时间的一到两周。
1 Introduction
1 引言
The typical problem formulation in reinforcement learning is to maximize the expected total reward of a policy. A key source of difficulty is the long time delay between actions and their positive or negative effect on rewards; this issue is called the credit assignment problem in the reinforcement learning literature (Minsky, 1961; Sutton & Barto, 1998), and the distal reward problem in the behavioral literature (Hull, 1943). Value functions offer an elegant solution to the credit assignment problem—they allow us to estimate the goodness of an action before the delayed reward arrives. Reinforcement learning algorithms make use of value functions in a variety of different ways; this paper considers algorithms that optimize a parameterized policy and use value functions to help estimate how the policy should be improved.
强化学习里典型的问题设定,是最大化策略的期望总回报。一个主要难点在于动作与其带来的正负回报之间往往有很长的时间延迟;强化学习文献称之为信用分配问题(Minsky, 1961; Sutton & Barto, 1998),行为学文献则称之为远端奖赏问题(Hull, 1943)。价值函数为信用分配提供了一种优雅的解决办法——它让我们在延迟回报到来之前,就能估计某个动作的好坏。强化学习算法以多种方式使用价值函数;本文考虑的是这样一类算法:它们优化参数化策略,并用价值函数来帮助估计策略应当如何改进。
When using a parameterized stochastic policy, it is possible to obtain an unbiased estimate of the gradient of the expected total returns (Williams, 1992; Sutton et al., 1999; Baxter & Bartlett, 2000); these noisy gradient estimates can be used in a stochastic gradient ascent algorithm. Unfortunately, the variance of the gradient estimator scales unfavorably with the time horizon, since the effect of an action is confounded with the effects of past and future actions. Another class of policy gradient algorithms, called actor-critic methods, use a value function rather than the empirical returns, obtaining an estimator with lower variance at the cost of introducing bias (Konda & Tsitsiklis, 2003; Hafner & Riedmiller, 2011). But while high variance necessitates using more samples, bias is more pernicious—even with an unlimited number of samples, bias can cause the algorithm to fail to converge, or to converge to a poor solution that is not even a local optimum.
当使用参数化的随机策略时,可以获得期望总回报梯度的无偏估计(Williams, 1992; Sutton et al., 1999; Baxter & Bartlett, 2000);这些带噪声的梯度估计可用于随机梯度上升。可惜,梯度估计器的方差会随时间视界不利地增大,因为一个动作的效果会与过去和未来动作的效果纠缠在一起。另一类称为演员–评论家的策略梯度算法用价值函数代替经验回报,以引入偏差为代价得到方差更低的估计器(Konda & Tsitsiklis, 2003; Hafner & Riedmiller, 2011)。高方差只是要求用更多样本,偏差则更为棘手——即便样本无限,偏差也可能使算法无法收敛,或收敛到甚至不是局部最优的较差解。
We propose a family of policy gradient estimators that significantly reduce variance while maintaining a tolerable level of bias. We call this estimation scheme, parameterized by and , the generalized advantage estimator (GAE). Related methods have been proposed in the context of online actor-critic methods (Kimura & Kobayashi, 1998; Wawrzyński, 2009). We provide a more general analysis, which is applicable in both the online and batch settings, and discuss an interpretation of our method as an instance of reward shaping (Ng et al., 1999), where the approximate value function is used to shape the reward.
我们提出一类能显著降低方差、同时把偏差控制在可容忍水平的策略梯度估计器。这一由 和 参数化的估计方案,称为广义优势估计(generalized advantage estimator, GAE)。在在线演员–评论家方法中已有相关做法(Kimura & Kobayashi, 1998; Wawrzyński, 2009)。我们给出更一般的分析,同时适用于在线和批量设定,并把该方法解释为奖励塑形(reward shaping)(Ng et al., 1999)的一个实例:用近似价值函数来塑形奖励。
We present experimental results on a number of highly challenging 3D locomotion tasks, where we show that our approach can learn complex gaits using high-dimensional, general purpose neural network function approximators for both the policy and the value function, each with over parameters. The policies perform torque-level control of simulated 3D robots with up to 33 state dimensions and 10 actuators.
我们在若干极具挑战性的三维运动任务上给出实验结果,表明该方法可以用高维、通用的神经网络函数逼近器同时表示策略和价值函数(各自参数都超过 ),并学到复杂步态。这些策略对最多有 33 维状态和 10 个执行器的仿真三维机器人做力矩级控制。
The contributions of this paper are summarized as follows:
本文贡献可概括如下:
- We provide justification and intuition for an effective variance reduction scheme for policy gradients, which we call generalized advantage estimation (GAE). While the formula has been proposed in prior work (Kimura & Kobayashi, 1998; Wawrzyński, 2009), our analysis is novel and enables GAE to be applied with a more general set of algorithms, including the batch trust-region algorithm we use for our experiments.
- 我们为一套有效的策略梯度方差削减方案提供了理由和直观解释,并称之为广义优势估计(GAE)。公式本身已在先前工作中出现(Kimura & Kobayashi, 1998; Wawrzyński, 2009),但我们的分析是新的,使 GAE 能与更广泛的算法一起使用,包括实验中采用的批量信赖域算法。
- We propose the use of a trust region optimization method for the value function, which we find is a robust and efficient way to train neural network value functions with thousands of parameters.
- 我们提出用信赖域方法优化价值函数,发现这是训练带有数千参数的神经网络价值函数的一种稳健而高效的方式。
- By combining (1) and (2) above, we obtain an algorithm that empirically is effective at learning neural network policies for challenging control tasks. The results extend the state of the art in using reinforcement learning for high-dimensional continuous control. Videos are available at https://sites.google.com/site/gaepapersupp.
- 把上述(1)和(2)结合起来,我们得到一套在经验上能够为困难控制任务学习神经网络策略的算法。这些结果推进了用强化学习做高维连续控制的现有水平。视频见 https://sites.google.com/site/gaepapersupp。
2 Preliminaries
2 预备知识
We consider an undiscounted formulation of the policy optimization problem. The initial state is sampled from distribution . A trajectory is generated by sampling actions according to the policy and sampling the states according to the dynamics , until a terminal (absorbing) state is reached. A reward is received at each timestep. The goal is to maximize the expected total reward , which is assumed to be finite for all policies. Note that we are not using a discount as part of the problem specification; it will appear below as an algorithm parameter that adjusts a bias-variance tradeoff. But the discounted problem (maximizing ) can be handled as an instance of the undiscounted problem in which we absorb the discount factor into the reward function, making it time-dependent.
我们考虑无折扣形式的策略优化问题。初始状态 从分布 中采样。轨迹 由按策略采样动作 、并按动力学采样状态 生成,直到到达终止(吸收)状态。每个时间步收到奖励 。目标是最大化期望总奖励 ,并假定它对所有策略都有限。注意,折扣并不是问题本身的一部分;它将作为算法参数出现,用来调节偏差–方差权衡。不过,折扣问题(最大化 )可以看作无折扣问题的一个特例:把折扣因子吸收进奖励函数,使其依赖于时间。
Policy gradient methods maximize the expected total reward by repeatedly estimating the gradient . There are several different related expressions for the policy gradient, which have the form
策略梯度方法通过反复估计梯度 来最大化期望总奖励。策略梯度有若干相关表达式,形式均为
where may be one of the following:
其中 可以是下面之一:
- : total reward of the trajectory.
- :整条轨迹的总奖励。
- : reward following action .
- :动作 之后的奖励。
- : baselined version of previous formula.
- :上一式减去基线后的形式。
- : state-action value function.
- :状态–动作价值函数。
- : advantage function.
- :优势函数。
- : TD residual.
- :TD 残差。
The latter formulas use the definitions
后面几式用到如下定义
$$\displaystyle V^{\pi}(s_{t}) \ \displaystyle\vcentcolon=\mathbb{E}{\begin{subarray}{c}s{t+1:\infty},\
a_{t:\infty}\end{subarray}}\left[\sum_{l=0}^{\infty}r_{t+l}\right]\hskip 36.135ptQ^{\pi}(s_{t},a_{t})\vcentcolon=\mathbb{E}{\begin{subarray}{c}s{t+1:\infty},\
a_{t+1:\infty}\end{subarray}}\left[\sum_{l=0}^{\infty}r_{t+l}\right] \ \displaystyle A^{\pi}(s_{t},a_{t}) \ \displaystyle\vcentcolon=Q^{\pi}(s_{t},a_{t})-V^{\pi}(s_{t}),\quad\text{(Advantage function)}. \tag{2}$$
Here, the subscript of enumerates the variables being integrated over, where states and actions are sampled sequentially from the dynamics model and policy , respectively. The colon notation refers to the inclusive range . These formulas are well known and straightforward to obtain; they follow directly from Proposition 1, which will be stated shortly.
这里 的下标列出被积分的变量,状态和动作分别依次从动力学模型 和策略 中采样。冒号记法 表示闭区间 。这些公式广为人知,也不难得到;它们直接由稍后陈述的命题 1 推出。
The choice yields almost the lowest possible variance, though in practice, the advantage function is not known and must be estimated. This statement can be intuitively justified by the following interpretation of the policy gradient: that a step in the policy gradient direction should increase the probability of better-than-average actions and decrease the probability of worse-than-average actions. The advantage function, by it’s definition , measures whether or not the action is better or worse than the policy’s default behavior. Hence, we should choose to be the advantage function , so that the gradient term points in the direction of increased if and only if . See Greensmith et al. (2004) for a more rigorous analysis of the variance of policy gradient estimators and the effect of using a baseline.
取 几乎能得到最低的方差,但实践中优势函数未知,必须估计。这一点可以用对策略梯度的如下直观解释来说明:沿策略梯度方向走一步,应当提高优于平均的动作的概率,并降低差于平均的动作的概率。由定义 ,优势函数衡量的正是该动作是否好于策略的默认行为。因此应取 为优势函数 ,从而使梯度项 当且仅当 时指向增大 的方向。关于策略梯度估计器方差以及使用基线的影响,更严格的分析见 Greensmith et al.(2004)。
We will introduce a parameter that allows us to reduce variance by downweighting rewards corresponding to delayed effects, at the cost of introducing bias. This parameter corresponds to the discount factor used in discounted formulations of MDPs, but we treat it as a variance reduction parameter in an undiscounted problem; this technique was analyzed theoretically by Marbach & Tsitsiklis (2003); Kakade (2001b); Thomas (2014). The discounted value functions are given by:
我们将引入参数 ,通过降低与延迟效应相对应的奖励权重来减小方差,代价是引入偏差。该参数对应于折扣 MDP 表述中的折扣因子,但在无折扣问题中我们把它当作方差削减参数;Marbach & Tsitsiklis(2003)、Kakade(2001b)、Thomas(2014)曾从理论上分析过这一技巧。折扣价值函数定义为:
$$\displaystyle V^{\pi,\gamma}(s_{t}) \ \displaystyle\vcentcolon=\mathbb{E}{\begin{subarray}{c}s{t+1:\infty},\
a_{t:\infty}\end{subarray}}\left[\sum_{l=0}^{\infty}\gamma^{l}r_{t+l}\right]\hskip 36.135ptQ^{\pi,\gamma}(s_{t},a_{t})\vcentcolon=\mathbb{E}{\begin{subarray}{c}s{t+1:\infty},\
a_{t+1:\infty}\end{subarray}}\left[\sum_{l=0}^{\infty}\gamma^{l}r_{t+l}\right] \ \displaystyle A^{\pi,\gamma}(s_{t},a_{t}) \ \displaystyle\vcentcolon=Q^{\pi,\gamma}(s_{t},a_{t})-V^{\pi,\gamma}(s_{t}). \tag{4}$$
The discounted approximation to the policy gradient is defined as follows:
对策略梯度的折扣近似定义如下:
$$\displaystyle g^{\gamma} \ \displaystyle\vcentcolon=\mathbb{E}{\begin{subarray}{c}s{0:\infty}\
a_{0:\infty}\end{subarray}}\left[\sum_{t=0}^{\infty}A^{\pi,\gamma}(s_{t},a_{t})\nabla_{\theta}\log\pi_{\theta}(a_{t}>|>s_{t})\right]. \tag{6}$$
The following section discusses how to obtain biased (but not too biased) estimators for , giving us noisy estimates of the discounted policy gradient in Equation 6.
下一节讨论如何得到 的有偏(但偏差不过大)估计,从而得到方程 6 中折扣策略梯度的带噪声估计。
Before proceeding, we will introduce the notion of a -just estimator of the advantage function, which is an estimator that does not introduce bias when we use it in place of (which is not known and must be estimated) in Equation 6 to estimate .[^1] Consider an advantage estimator , which may in general be a function of the entire trajectory.
[^1]: Note, that we have already introduced bias by using in place of ; here we are concerned with obtaining an unbiased estimate of , which is a biased estimate of the policy gradient of the undiscounted MDP.
在继续之前,我们引入优势函数的 -正当(-just)估计器这一概念:若在方程 6 中用它代替未知、因而必须估计的 来估计 ,则不会额外引入偏差。[^1] 考虑优势估计器 ,一般说来它可以是整条轨迹的函数。
[^1]: 需要注意,用 代替 已经引入了偏差;这里关心的是得到 的无偏估计,而 本身已是无折扣 MDP 策略梯度的有偏估计。
Definition 1.
The estimator is -just if
定义 1。
称估计器 是 -正当的,如果
$$\displaystyle\mathbb{E}{\begin{subarray}{c}s{0:\infty}\
a_{0:\infty}\end{subarray}}\left[\hat{A}{t}(s{0:\infty},a_{0:\infty})\nabla_{\theta}\log\pi_{\theta}(a_{t}>|>s_{t})\right]=\mathbb{E}{\begin{subarray}{c}s{0:\infty}\
a_{0:\infty}\end{subarray}}\left[A^{\pi,\gamma}(s_{t},a_{t})\nabla_{\theta}\log\pi_{\theta}(a_{t}>|>s_{t})\right]. \tag{7}$$
It follows immediately that if is -just for all , then
由此立即得到:若 对所有 都是 -正当的,则
$$\displaystyle\mathbb{E}{\begin{subarray}{c}s{0:\infty}\
a_{0:\infty}\end{subarray}}\left[\sum_{t=0}^{\infty}\hat{A}{t}(s{0:\infty},a_{0:\infty})\nabla_{\theta}\log\pi_{\theta}(a_{t}>|>s_{t})\right]=g^{\gamma} \tag{8}$$
One sufficient condition for to be -just is that decomposes as the difference between two functions and , where can depend on any trajectory variables but gives an unbiased estimator of the -discounted -function, and is an arbitrary function of the states and actions sampled before .
为 -正当的一个充分条件是:它可分解为两个函数 与 之差,其中 可以依赖任意轨迹变量,但是 -折扣 函数的无偏估计,而 则是在 之前采样的状态和动作的任意函数。
Proposition 1.
Suppose that can be written in the form such that for all , . Then is -just.
命题 1。
设 可写成 的形式,并且对所有 都有 。则 是 -正当的。
The proof is provided in Appendix B. It is easy to verify that the following expressions are -just advantage estimators for :
证明见附录 B。不难验证,下列表达式都是 的 -正当优势估计器:
- •
- •
- •
- • .
- • 。
3 Advantage function estimation
3 优势函数估计
This section will be concerned with producing an accurate estimate of the discounted advantage function , which will then be used to construct a policy gradient estimator of the following form:
本节关心的是如何准确估计折扣优势函数 ,记为 ,再用它构造如下形式的策略梯度估计器:
where indexes over a batch of episodes.
其中 遍历一批回合。
Let be an approximate value function. Define , i.e., the TD residual of with discount (Sutton & Barto, 1998). Note that can be considered as an estimate of the advantage of the action . In fact, if we have the correct value function , then it is a -just advantage estimator, and in fact, an unbiased estimator of :
设 是近似价值函数。定义 ,即 在折扣 下的 TD 残差(Sutton & Barto, 1998)。注意 可视为对动作 优势的一种估计。事实上,若价值函数恰好正确,即 ,则它是 -正当的优势估计器,并且还是 的无偏估计:
However, this estimator is only -just for , otherwise it will yield biased policy gradient estimates.
不过,该估计器只有在 时才是 -正当的,否则会得到有偏的策略梯度估计。
Next, let us consider taking the sum of of these terms, which we will denote by
接下来考虑把 个这样的 项加起来,记为
These equations result from a telescoping sum, and we see that involves a -step estimate of the returns, minus a baseline term . Analogously to the case of , we can consider to be an estimator of the advantage function, which is only -just when . However, note that the bias generally becomes smaller as , since the term becomes more heavily discounted, and the term does not affect the bias. Taking , we get
这些等式来自望远镜求和。可以看到, 包含对回报的 步估计,再减去基线项 。与 的情形类似,可以把 看作优势函数的估计器,它同样只在 时才是 -正当的。不过请注意,随着 ,偏差通常会变小,因为 被更重地折扣,而 并不影响偏差。取 ,得到
which is simply the empirical returns minus the value function baseline.
这不过是经验回报减去价值函数基线。
The generalized advantage estimator is defined as the exponentially-weighted average of these -step estimators:
广义优势估计器 定义为这些 步估计器的指数加权平均:
From Equation 16, we see that the advantage estimator has a remarkably simple formula involving a discounted sum of Bellman residual terms. Section 4 discusses an interpretation of this formula as the returns in an MDP with a modified reward function. The construction we used above is closely analogous to the one used to define TD() (Sutton & Barto, 1998), however TD() is an estimator of the value function, whereas here we are estimating the advantage function.
由方程 16 可见,该优势估计器有一个相当简洁的公式,即贝尔曼残差项的折扣和。第 4 节把这一公式解释为在修改了奖励函数的 MDP 中的回报。上面的构造与定义 TD()(Sutton & Barto, 1998)时所用的构造非常类似,不过 TD() 估计的是价值函数,而这里估计的是优势函数。
There are two notable special cases of this formula, obtained by setting and .
令 和 ,可以得到这一公式的两个值得注意的特例。
is -just regardless of the accuracy of , but it has high variance due to the sum of terms. is -just for and otherwise induces bias, but it typically has much lower variance. The generalized advantage estimator for makes a compromise between bias and variance, controlled by parameter .
不论 是否准确都是 -正当的,但由于要对多项求和,方差较高。 只在 时是 -正当的,否则会引入偏差,但通常方差低得多。当 时,广义优势估计器在偏差与方差之间折中,由参数 控制。
We’ve described an advantage estimator with two separate parameters and , both of which contribute to the bias-variance tradeoff when using an approximate value function. However, they serve different purposes and work best with different ranges of values. most importantly determines the scale of the value function , which does not depend on . Taking introduces bias into the policy gradient estimate, regardless of the value function’s accuracy. On the other hand, introduces bias only when the value function is inaccurate. Empirically, we find that the best value of is much lower than the best value of , likely because introduces far less bias than for a reasonably accurate value function.
到这里,我们描述了一个带有两个独立参数 和 的优势估计器,二者在使用近似价值函数时都会参与偏差–方差权衡,但用途不同,最佳取值范围也不一样。 最重要的作用是决定价值函数 的尺度,而这一尺度与 无关。取 会给策略梯度估计引入偏差,无论价值函数多么准确。相比之下, 只在价值函数不准确时才引入偏差。经验上,我们发现 的最佳值远低于 的最佳值,这很可能是因为在价值函数相当准确时, 引入的偏差远小于 。
Using the generalized advantage estimator, we can construct a biased estimator of , the discounted policy gradient from Equation 6:
利用广义优势估计器,可以构造方程 6 中折扣策略梯度 的有偏估计:
where equality holds when .
当 时等号成立。
4 Interpretation as Reward Shaping
4 作为奖励塑形的解释
In this section, we discuss how one can interpret as an extra discount factor applied after performing a reward shaping transformation on the MDP. We also introduce the notion of a response function to help understand the bias introduced by and .
本节讨论如何把 解释为:先对 MDP 做一次奖励塑形变换,再额外施加的一个折扣因子。我们还引入响应函数的概念,以帮助理解 和 所引入的偏差。
Reward shaping (Ng et al., 1999) refers to the following transformation of the reward function of an MDP: let be an arbitrary scalar-valued function on state space, and define the transformed reward function by
奖励塑形(Ng et al., 1999)指对 MDP 奖励函数做如下变换:设 是状态空间上任意的标量函数,并定义变换后的奖励函数 为
which in turn defines a transformed MDP. This transformation leaves the discounted advantage function unchanged for any policy . To see this, consider the discounted sum of rewards of a trajectory starting with state :
这一变换进而定义了一个新的 MDP。它对任意策略 ,都保持折扣优势函数 不变。为看清这一点,考虑从状态 出发的一条轨迹的折扣奖励和:
Letting be the value and advantage functions of the transformed MDP, one obtains from the definitions of these quantities that
记 为变换后 MDP 的价值和优势函数,由这些量的定义可得
Note that if happens to be the state-value function from the original MDP, then the transformed MDP has the interesting property that is zero at every state.
注意,若 恰好是原 MDP 的状态价值函数 ,则变换后的 MDP 有一个有趣的性质:在每个状态上 都为零。
Note that (Ng et al., 1999) showed that the reward shaping transformation leaves the policy gradient and optimal policy unchanged when our objective is to maximize the discounted sum of rewards . In contrast, this paper is concerned with maximizing the undiscounted sum of rewards, where the discount is used as a variance-reduction parameter.
还要注意,Ng et al.(1999)证明的是:当我们的目标是最大化折扣奖励和 时,奖励塑形变换不改变策略梯度和最优策略。相比之下,本文关心的是最大化无折扣奖励和,折扣 只是作为方差削减参数来使用。
Having reviewed the idea of reward shaping, let us consider how we could use it to get a policy gradient estimate. The most natural approach is to construct policy gradient estimators that use discounted sums of shaped rewards . However, Equation 21 shows that we obtain the discounted sum of the original MDP’s rewards minus a baseline term. Next, let’s consider using a “steeper” discount , where . It’s easy to see that the shaped reward equals the Bellman residual term , introduced in Section 3, where we set . Letting , we see that
回顾了奖励塑形之后,再看如何用它来估计策略梯度。最自然的做法是构造使用塑形奖励 的折扣和的策略梯度估计器。但方程 21 表明,这样得到的是原 MDP 奖励 的折扣和再减去一个基线项。接下来考虑使用更“陡”的折扣 ,其中 。不难看出,取 时,塑形奖励 正好等于第 3 节引入的贝尔曼残差项 。令 ,我们有
Hence, by considering the -discounted sum of shaped rewards, we exactly obtain the generalized advantage estimators from Section 3. As shown previously, gives an unbiased estimate of , whereas gives a biased estimate.
因此,考虑塑形奖励的 -折扣和,恰好得到第 3 节中的广义优势估计器。如前所述, 给出 的无偏估计,而 给出有偏估计。
To further analyze the effect of this shaping transformation and parameters and , it will be useful to introduce the notion of a response function , which we define as follows:
为进一步分析这一塑形变换以及参数 和 的作用,引入如下定义的响应函数 会很有用:
Note that , hence the response function decomposes the advantage function across timesteps. The response function lets us quantify the temporal credit assignment problem: long range dependencies between actions and rewards correspond to nonzero values of the response function for .
注意 ,因此响应函数把优势函数按时间步分解开来。响应函数让我们能量化时间信用分配问题:动作与奖励之间的长程依赖,对应于 时响应函数的非零值。
Next, let us revisit the discount factor and the approximation we are making by using rather than . The discounted policy gradient estimator from Equation 6 has a sum of terms of the form
接下来再看折扣因子 ,以及用 代替 所做的近似。方程 6 中的折扣策略梯度估计器包含如下形式的项
Using a discount corresponds to dropping the terms with . Thus, the error introduced by this approximation will be small if rapidly decays as increases, i.e., if the effect of an action on rewards is “forgotten” after timesteps.
使用 的折扣,相当于丢掉 的那些项。因此,若 随 增大而迅速衰减,也就是说一个动作对奖励的影响在大约 步之后就被“遗忘”,则这一近似引入的误差会很小。
If the reward function were obtained using , we would have for , i.e., the response function would only be nonzero at . Therefore, this shaping transformation would turn temporally extended response into an immediate response. Given that completely reduces the temporal spread of the response function, we can hope that a good approximation partially reduces it. This observation suggests an interpretation of Equation 16: reshape the rewards using to shrink the temporal extent of the response function, and then introduce a “steeper” discount to cut off the noise arising from long delays, i.e., ignore terms where .
若奖励函数 是用 得到的,则会有 (对 ),即响应函数只在 时非零。因此,这一塑形变换会把时间上延展的响应变成即时响应。既然 能完全压缩响应函数的时间跨度,我们也可以希望一个好的近似 能部分地做到这一点。这一观察提示了对方程 16 的一种解释:先用 重塑奖励以缩小响应函数的时间范围,再引入更“陡”的折扣 来截断长延迟带来的噪声,也就是忽略那些 的项 。
5 Value Function Estimation
5 价值函数估计
A variety of different methods can be used to estimate the value function (see, e.g., Bertsekas (2012)). When using a nonlinear function approximator to represent the value function, the simplest approach is to solve a nonlinear regression problem:
估计价值函数可用多种方法(例如参见 Bertsekas, 2012)。当用非线性函数逼近器表示价值函数时,最简单的做法是求解一个非线性回归问题:
where is the discounted sum of rewards, and indexes over all timesteps in a batch of trajectories. This is sometimes called the Monte Carlo or TD() approach for estimating the value function (Sutton & Barto, 1998).[^2]
[^2]: Another natural choice is to compute target values with an estimator based on the TD() backup (Bertsekas, 2012; Sutton & Barto, 1998), mirroring the expression we use for policy gradient estimation: . While we experimented with this choice, we did not notice a difference in performance from the estimator in Equation 28.
其中 是折扣奖励和, 遍历一批轨迹中的所有时间步。这有时称为估计价值函数的蒙特卡洛或 TD() 方法(Sutton & Barto, 1998)。[^2]
[^2]: 另一个自然的选择是用基于 TD() 备份的估计器来计算目标值(Bertsekas, 2012; Sutton & Barto, 1998),形式与我们用于策略梯度估计的表达式相对应:。我们试验过这一选择,但并未发现它与方程 28 中 的估计器在性能上有明显差别。
For the experiments in this work, we used a trust region method to optimize the value function in each iteration of a batch optimization procedure. The trust region helps us to avoid overfitting to the most recent batch of data. To formulate the trust region problem, we first compute , where is the parameter vector before optimization. Then we solve the following constrained optimization problem:
在本工作的实验中,我们在批量优化的每次迭代里用信赖域方法优化价值函数。信赖域有助于避免对最近一批数据过拟合。为表述信赖域问题,我们先计算 ,其中 是优化前的参数向量。然后求解如下约束优化问题:
This constraint is equivalent to constraining the average KL divergence between the previous value function and the new value function to be smaller than , where the value function is taken to parameterize a conditional Gaussian distribution with mean and variance .
这一约束等价于把新旧价值函数之间的平均 KL 散度限制在小于 ,这里把价值函数理解为均值 、方差 的条件高斯分布的参数。
We compute an approximate solution to the trust region problem using the conjugate gradient algorithm (Wright & Nocedal, 1999). Specifically, we are solving the quadratic program
我们用共轭梯度算法(Wright & Nocedal, 1999)求信赖域问题的近似解。具体地说,是在求解二次规划
where is the gradient of the objective, and , where . Note that is the “Gauss-Newton” approximation of the Hessian of the objective, and it is (up to a factor) the Fisher information matrix when interpreting the value function as a conditional probability distribution. Using matrix-vector products to implement the conjugate gradient algorithm, we compute a step direction . Then we rescale such that and take . This procedure is analogous to the procedure we use for updating the policy, which is described further in Section 6 and based on Schulman et al. (2015).
其中 是目标函数的梯度,,而 。注意 是目标函数 Hessian 的“高斯–牛顿”近似,并且在把价值函数解释为条件概率分布时,(相差一个 因子)它就是 Fisher 信息矩阵。我们用矩阵–向量乘积 来实现共轭梯度算法,算出步方向 。然后将 缩放为 ,使得 ,并取 。这一流程与我们更新策略所用的流程类似,详见第 6 节,并基于 Schulman et al.(2015)。
6 Experiments
6 实验
We designed a set of experiments to investigate the following questions:
我们设计了一组实验来考察下列问题:
- What is the empirical effect of varying and when optimizing episodic total reward using generalized advantage estimation?
- 在用广义优势估计优化回合总奖励时,改变 和 的经验效果如何?
- Can generalized advantage estimation, along with trust region algorithms for policy and value function optimization, be used to optimize large neural network policies for challenging control problems?
- 广义优势估计,再加上用于策略和价值函数优化的信赖域算法,能否用来为困难的控制问题优化大型神经网络策略?
6.1 Policy Optimization Algorithm
6.1 策略优化算法
While generalized advantage estimation can be used along with a variety of different policy gradient methods, for these experiments, we performed the policy updates using trust region policy optimization (TRPO) (Schulman et al., 2015). TRPO updates the policy by approximately solving the following constrained optimization problem each iteration:
尽管广义优势估计可以与多种策略梯度方法一起使用,在这些实验中我们用信赖域策略优化(TRPO)(Schulman et al., 2015)来做策略更新。TRPO 在每次迭代中通过近似求解如下约束优化问题来更新策略:
As described in (Schulman et al., 2015), we approximately solve this problem by linearizing the objective and quadraticizing the constraint, which yields a step in the direction , where is the average Fisher information matrix, and is a policy gradient estimate. This policy update yields the same step direction as the natural policy gradient (Kakade, 2001a) and natural actor-critic (Peters & Schaal, 2008), however it uses a different stepsize determination scheme and numerical procedure for computing the step.
如 Schulman et al.(2015)所述,我们通过把目标函数线性化、把约束二次化来近似求解该问题,得到沿 方向的一步,其中 是平均 Fisher 信息矩阵, 是策略梯度估计。这一策略更新给出的步方向与自然策略梯度(Kakade, 2001a)和自然演员–评论家(Peters & Schaal, 2008)相同,但步长确定方案以及计算该步的数值程序不同。
Since prior work (Schulman et al., 2015) compared TRPO to a variety of different policy optimization algorithms, we will not repeat these comparisons; rather, we will focus on varying the parameters of policy gradient estimator while keeping the underlying algorithm fixed.
由于先前工作(Schulman et al., 2015)已将 TRPO 与多种策略优化算法做过比较,这里不再重复那些比较;我们把注意力放在固定底层算法、只改变策略梯度估计器的 参数上。
For completeness, the whole algorithm for iteratively updating policy and value function is given below:
为完整起见,下面给出迭代更新策略和价值函数的整套算法:
Initialize policy parameter and value function parameter .
for = 0, 1, 2, … do
Simulate current policy until timesteps are obtained.
Compute at all timesteps , using .
Compute at all timesteps.
Compute with TRPO update, Equation 31.
Compute with Equation 30.
end for
初始化策略参数 和价值函数参数 。
for = 0, 1, 2, … do
用当前策略 仿真,直到得到 个时间步。
对所有时间步 ,用 计算 。
对所有时间步计算 。
用方程 31 的 TRPO 更新计算 。
用方程 30 计算 。
end for
Note that the policy update is performed using the value function for advantage estimation, not . Additional bias would have been introduced if we updated the value function first. To see this, consider the extreme case where we overfit the value function, and the Bellman residual becomes zero at all timesteps—the policy gradient estimate would be zero.
注意,策略更新 使用的是价值函数 来估计优势,而不是 。若先更新价值函数,会引入额外偏差。极端情形下,若把价值函数过拟合到使贝尔曼残差 在所有时间步都为零,策略梯度估计就会变成零。
6.2 Experimental Setup
6.2 实验设置
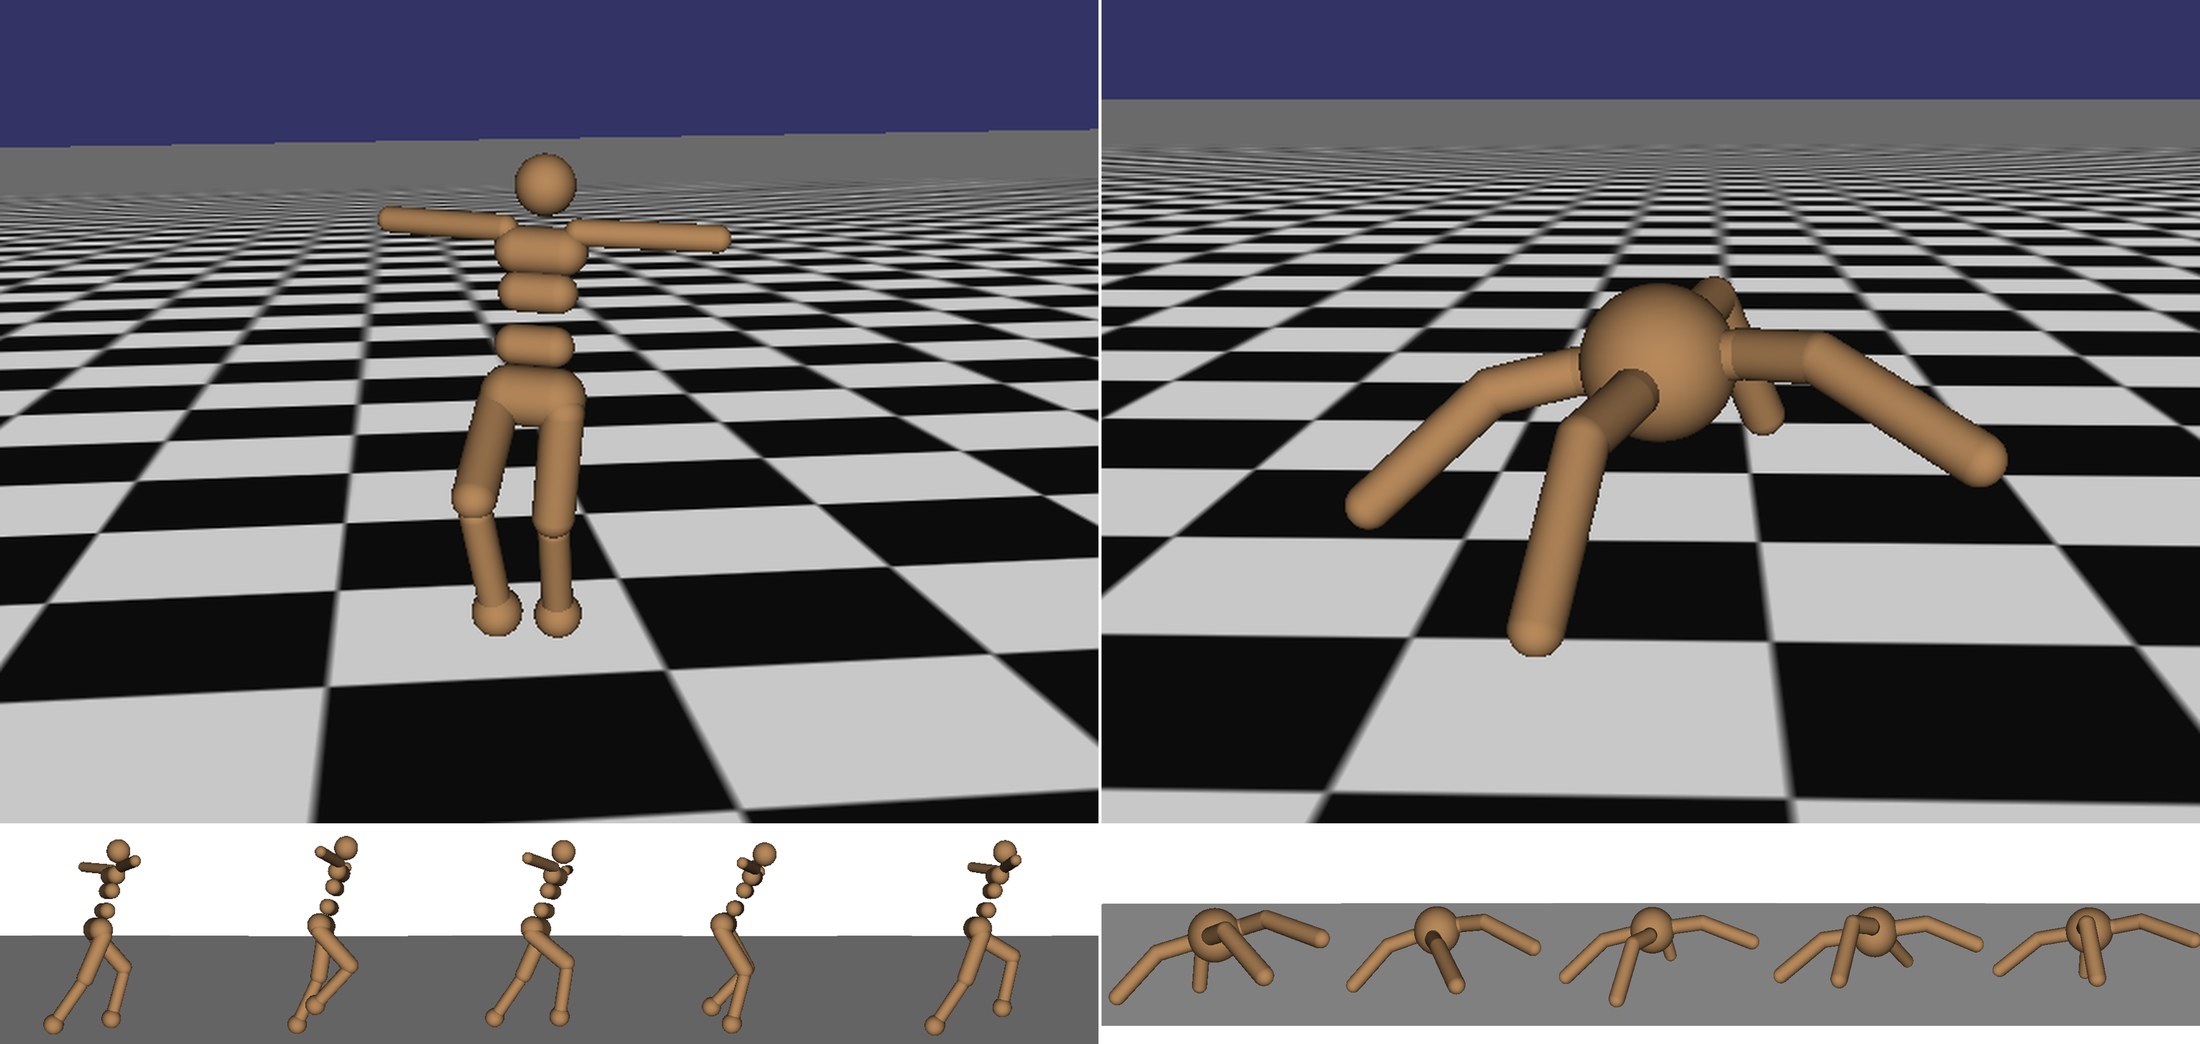
Figure 1: Top figures: robot models used for 3D locomotion. Bottom figures: a sequence of frames from the learned gaits. Videos are available at https://sites.google.com/site/gaepapersupp.
图 1:上图为用于三维运动的机器人模型。下图为学到的步态的一组帧。视频见 https://sites.google.com/site/gaepapersupp。
We evaluated our approach on the classic cart-pole balancing problem, as well as several challenging 3D locomotion tasks: (1) bipedal locomotion; (2) quadrupedal locomotion; (3) dynamically standing up, for the biped, which starts off laying on its back. The models are shown in Figure 1.
我们在经典的倒立摆(cart-pole)平衡问题上,以及若干具有挑战性的三维运动任务上评估了该方法:(1)双足行走;(2)四足行走;(3)动态站起,即双足机器人从仰卧在地开始。模型见图 1。
6.2.1 Architecture
We used the same neural network architecture for all of the 3D robot tasks, which was a feedforward network with three hidden layers, with , and tanh units respectively. The same architecture was used for the policy and value function. The final output layer had linear activation. The value function estimator used the same architecture, but with only one scalar output. For the simpler cart-pole task, we used a linear policy, and a neural network with one 20-unit hidden layer as the value function.
6.2.1 架构
所有三维机器人任务都使用同一套神经网络架构:三层隐层的前馈网络,分别有 、 和 个 tanh 单元。策略和价值函数使用相同架构。最后的输出层为线性激活。价值函数估计器架构相同,但只有一个标量输出。对较简单的倒立摆任务,我们使用线性策略,价值函数则是带一个 20 单元隐层的神经网络。
6.2.2 Task details
For the cart-pole balancing task, we collected 20 trajectories per batch, with a maximum length of 1000 timesteps, using the physical parameters from Barto et al. (1983).
6.2.2 任务细节
对倒立摆平衡任务,每批采集 20 条轨迹,最大长度为 1000 个时间步,物理参数取自 Barto et al.(1983)。
The simulated robot tasks were simulated using the MuJoCo physics engine (Todorov et al., 2012). The humanoid model has 33 state dimensions and 10 actuated degrees of freedom, while the quadruped model has 29 state dimensions and 8 actuated degrees of freedom. The initial state for these tasks consisted of a uniform distribution centered on a reference configuration. We used 50000 timesteps per batch for bipedal locomotion, and 200000 timesteps per batch for quadrupedal locomotion and bipedal standing. Each episode was terminated after timesteps if the robot had not reached a terminal state beforehand. The timestep was seconds.
仿真机器人任务用 MuJoCo 物理引擎(Todorov et al., 2012)进行仿真。人形模型有 33 维状态和 10 个驱动自由度,四足模型有 29 维状态和 8 个驱动自由度。这些任务的初始状态是以某个参考构型为中心的均匀分布。双足行走每批使用 50000 个时间步,四足行走和双足站起每批使用 200000 个时间步。若机器人此前未到达终止状态,每个回合在 个时间步后终止。时间步长为 秒。
The reward functions are provided in the table below.
奖励函数见下表。
| Task | Reward |
|---|---|
| 3D biped locomotion | |
| Quadruped locomotion | |
| Biped getting up |
| 任务 | 奖励 |
|---|---|
| 三维双足行走 | |
| 四足行走 | |
| 双足起身 |
Here, , , , .
其中,,,,。
In the locomotion tasks, the episode is terminated if the center of mass of the actor falls below a predefined height: for the biped, and for the quadruped. The constant offset in the reward function encourages longer episodes; otherwise the quadratic reward terms might lead lead to a policy that ends the episodes as quickly as possible.
在运动任务中,若主体质心落到预先设定的高度以下,回合即终止:双足为 ,四足为 。奖励函数中的常数偏置鼓励更长的回合;否则二次奖励项可能导致策略尽快结束回合。
6.3 Experimental Results
6.3 实验结果
All results are presented in terms of the cost, which is defined as negative reward and is minimized. Videos of the learned policies are available at https://sites.google.com/site/gaepapersupp. In plots, “No VF” means that we used a time-dependent baseline that did not depend on the state, rather than an estimate of the state value function. The time-dependent baseline was computed by averaging the return at each timestep over the trajectories in the batch.
所有结果都以代价表示,代价定义为负奖励,并被最小化。学到的策略视频见 https://sites.google.com/site/gaepapersupp。图中的 “No VF” 表示我们使用了不依赖于状态的、随时间变化的基线,而不是对状态价值函数的估计。该时变基线是把该批次轨迹在每个时间步的回报取平均得到的。
6.3.1 Cart-pole
The results are averaged across experiments with different random seeds. Results are shown in Figure 2, and indicate that the best results are obtained at intermediate values of the parameters: and .
6.3.1 倒立摆
结果对 次使用不同随机种子的实验取平均。结果见图 2,表明在参数取中间值时效果最好:,。
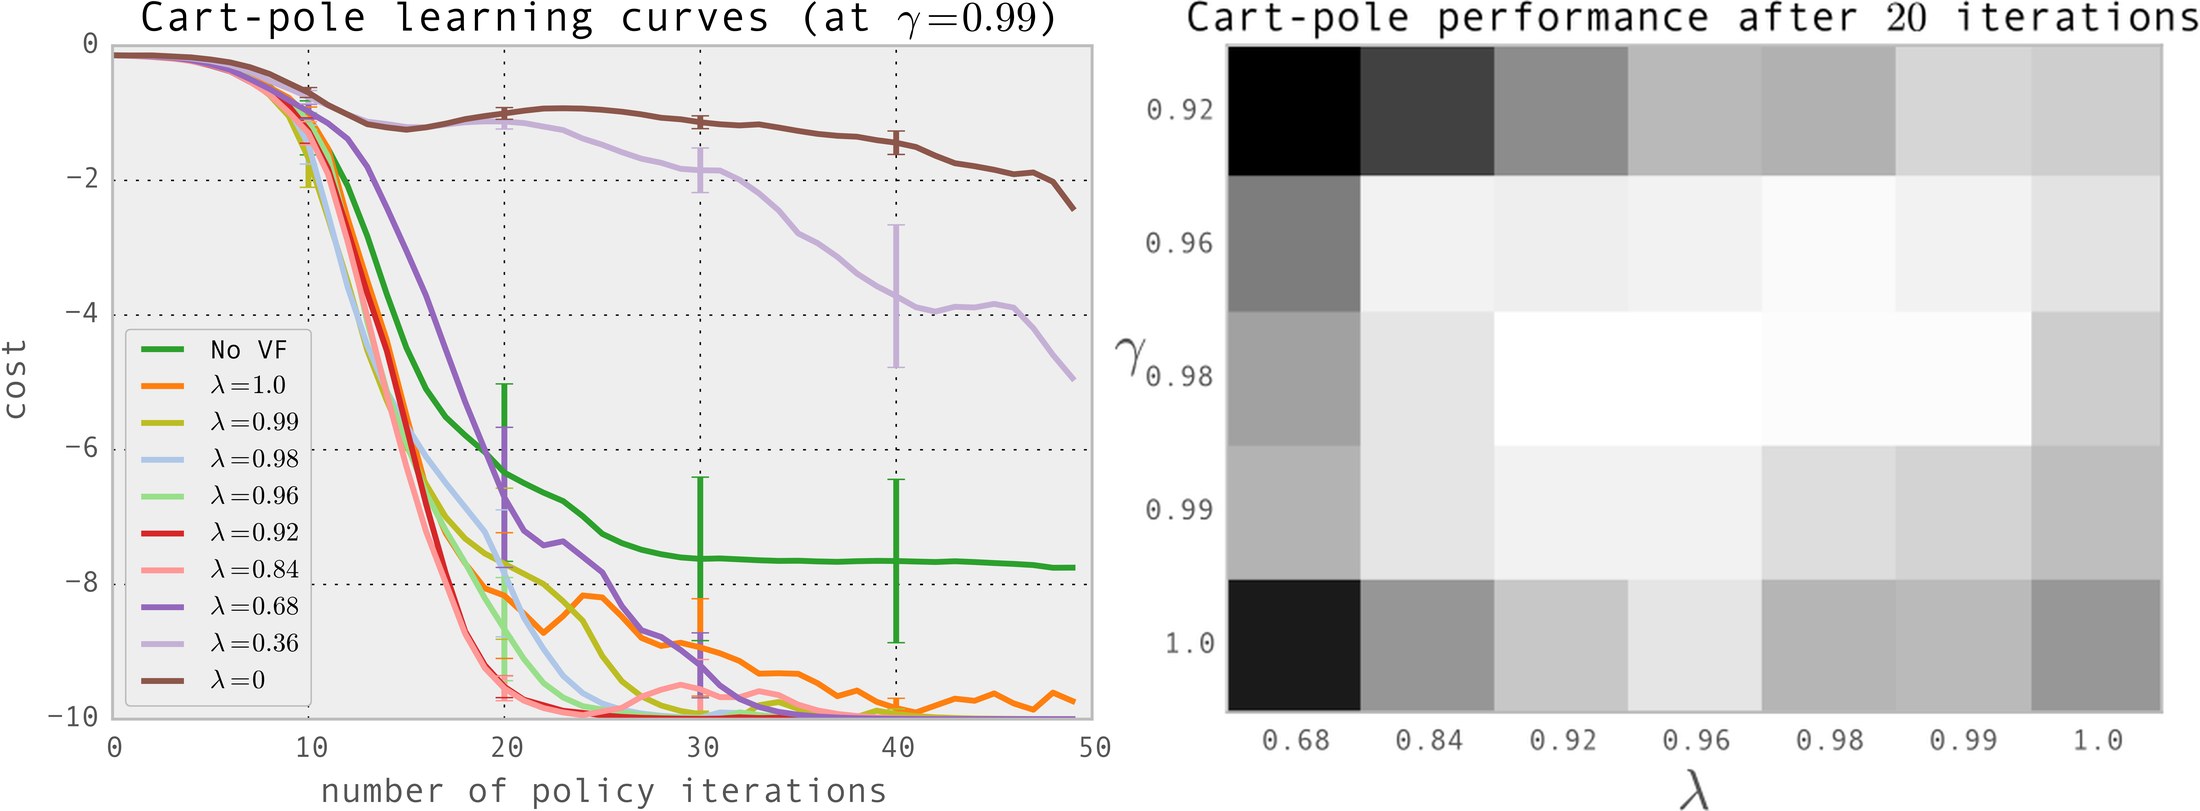
Figure 2: Left: learning curves for cart-pole task, using generalized advantage estimation with varying values of at . The fastest policy improvement is obtain by intermediate values of in the range . Right: performance after 20 iterations of policy optimization, as and are varied. White means higher reward. The best results are obtained at intermediate values of both.
图 2:左图为倒立摆任务的学习曲线,使用广义优势估计,在 下改变 。策略改进最快的是 取区间 中的中间值。右图为策略优化 20 次迭代后的性能,随 和 变化。白色表示奖励更高。二者都取中间值时结果最好。
6.3.2 3D bipedal locomotion
Each trial took about 2 hours to run on a 16-core machine, where the simulation rollouts were parallelized, as were the function, gradient, and matrix-vector-product evaluations used when optimizing the policy and value function. Here, the results are averaged across trials with different random seeds. The best performance is again obtained using intermediate values of . The result after 1000 iterations is a fast, smooth, and stable gait that is effectively completely stable. We can compute how much “real time” was used for this learning process: . Hence, it is plausible that this algorithm could be run on a real robot, or multiple real robots learning in parallel, if there were a way to reset the state of the robot and ensure that it doesn’t damage itself.
6.3.2 三维双足行走
每次试验在 16 核机器上大约运行 2 小时,仿真滚动以及优化策略和价值函数时用到的函数、梯度和矩阵–向量乘积计算都做了并行。这里的结果对 次不同随机种子的试验取平均。最佳性能再次出现在中间取值:,。1000 次迭代之后得到的是快速、平滑且稳定的步态,实际上已经完全稳定。可以计算这一学习过程用了多少“现实时间”:。因此,如果有办法重置机器人状态并保证它不会损坏自己,该算法在真实机器人上运行,或在多台真实机器人上并行学习,都是说得通的。
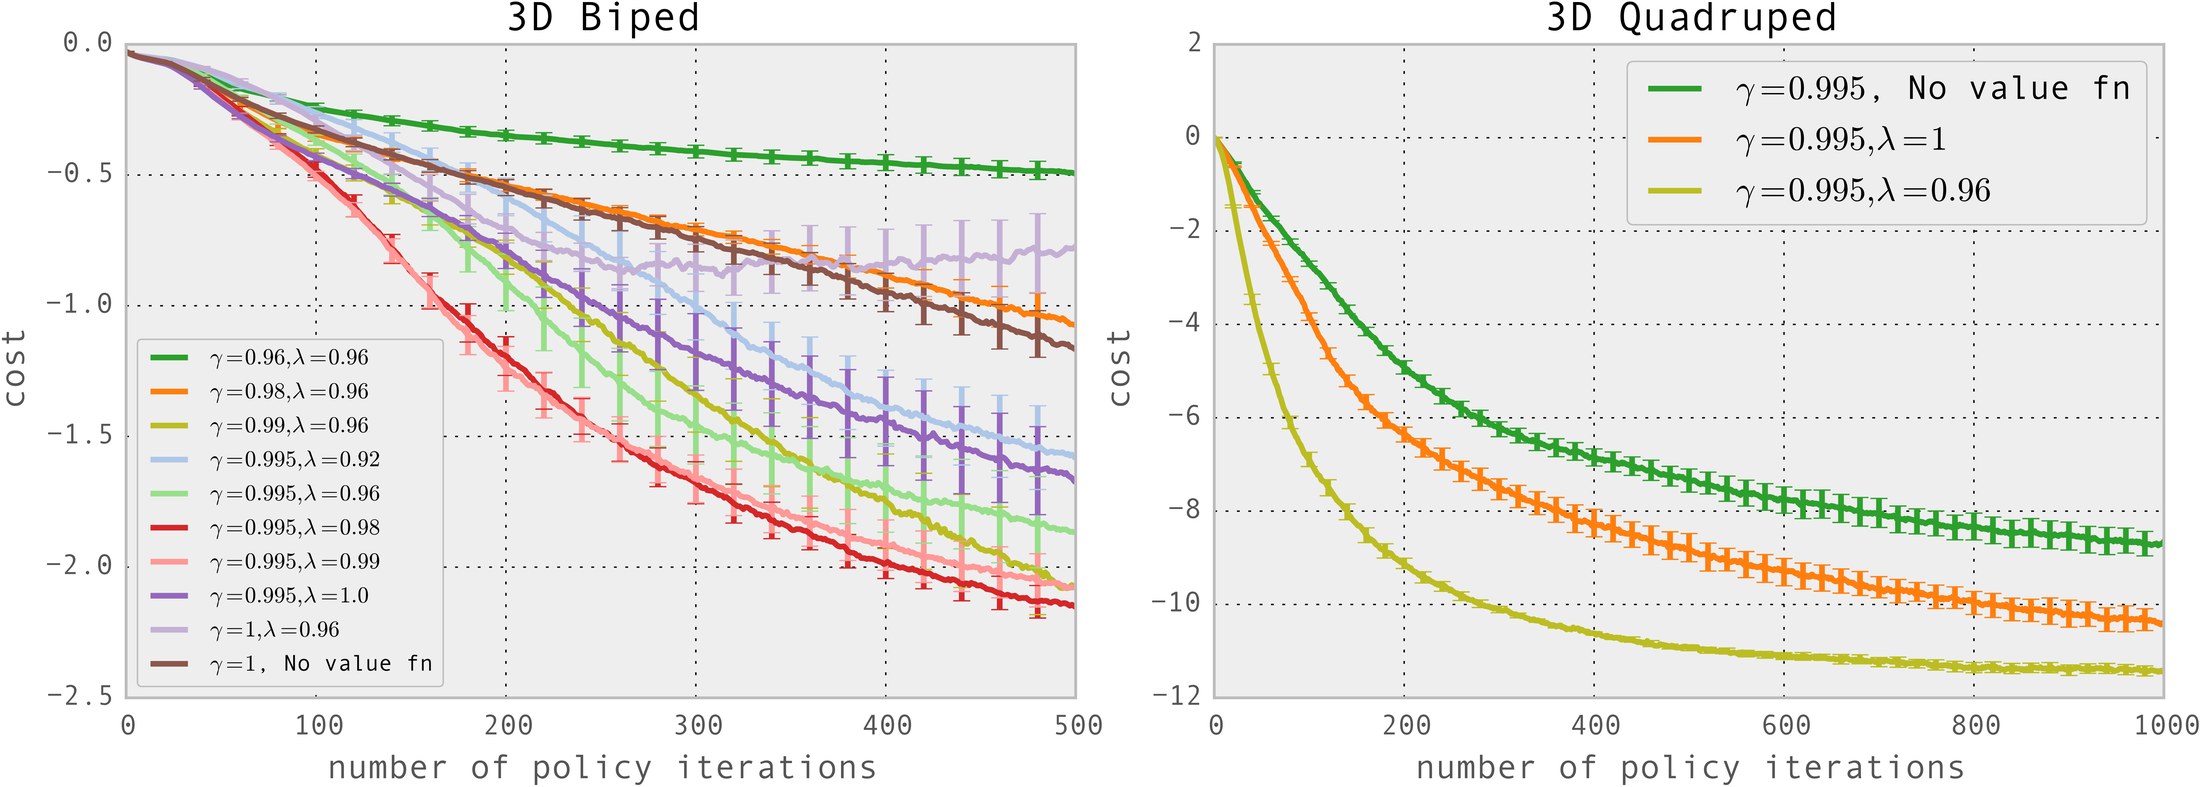
Figure 3: Left: Learning curves for 3D bipedal locomotion, averaged across nine runs of the algorithm. Right: learning curves for 3D quadrupedal locomotion, averaged across five runs.
图 3:左图为三维双足行走的学习曲线,对算法的九次运行取平均。右图为三维四足行走的学习曲线,对五次运行取平均。
6.3.3 Other 3D robot tasks
The other two motor behaviors considered are quadrupedal locomotion and getting up off the ground for the 3D biped. Again, we performed 5 trials per experimental condition, with different random seeds (and initializations). The experiments took about 4 hours per trial on a 32-core machine. We performed a more limited comparison on these domains (due to the substantial computational resources required to run these experiments), fixing but varying , as well as an experimental condition with no value function. For quadrupedal locomotion, the best results are obtained using a value function with Figure 3. For 3D standing, the value function always helped, but the results are roughly the same for and .
6.3.3 其他三维机器人任务
另外两种运动行为是四足行走,以及三维双足从地面站起。我们同样在每种实验条件下做了 5 次试验,使用不同的随机种子(以及初始化)。每次试验在 32 核机器上大约需要 4 小时。由于这些实验需要大量计算资源,我们在这些领域只做了较有限的比较:固定 ,改变 ,并加上不使用价值函数的实验条件。对四足行走,最好的结果是使用价值函数且 ,见图 3。对三维站起,价值函数始终有帮助,但 与 的结果大致相同。
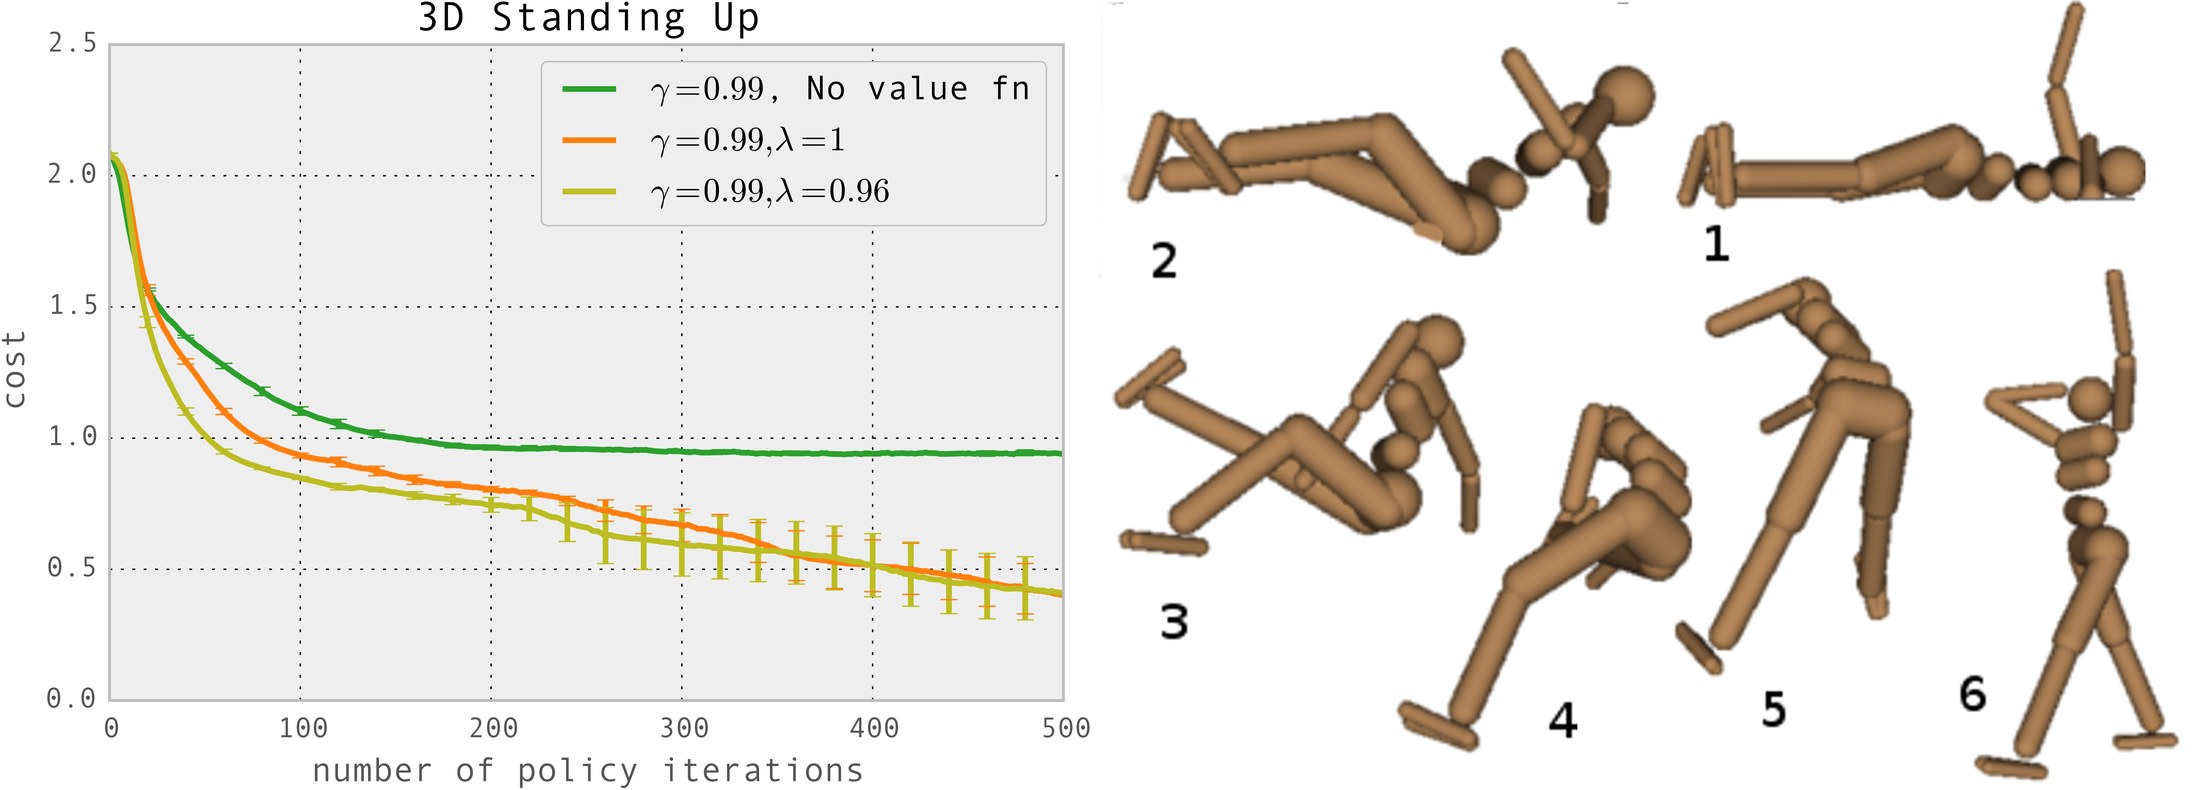
Figure 4: (a) Learning curve from quadrupedal walking, (b) learning curve for 3D standing up, (c) clips from 3D standing up.
图 4:(a)四足行走的学习曲线,(b)三维站起的学习曲线,(c)三维站起的若干片段。
7 Discussion
7 讨论
Policy gradient methods provide a way to reduce reinforcement learning to stochastic gradient descent, by providing unbiased gradient estimates. However, so far their success at solving difficult control problems has been limited, largely due to their high sample complexity. We have argued that the key to variance reduction is to obtain good estimates of the advantage function.
策略梯度方法通过提供无偏的梯度估计,把强化学习化约为随机梯度下降。但到目前为止,它们在解决困难控制问题上的成功仍然有限,很大程度上是因为样本复杂度很高。我们主张,降低方差的关键在于得到好的优势函数估计。
We have provided an intuitive but informal analysis of the problem of advantage function estimation, and justified the generalized advantage estimator, which has two parameters which adjust the bias-variance tradeoff. We described how to combine this idea with trust region policy optimization and a trust region algorithm that optimizes a value function, both represented by neural networks. Combining these techniques, we are able to learn to solve difficult control tasks that have previously been out of reach for generic reinforcement learning methods.
我们对优势函数估计问题给出了一种直观但非正式的分析,并为广义优势估计器提供了理由;该估计器有两个参数 来调节偏差–方差权衡。我们描述了如何把这一想法与信赖域策略优化、以及用信赖域算法优化价值函数结合起来,二者都用神经网络表示。把这些技术组合起来,我们能够学会解决此前对通用强化学习方法来说尚不可及的困难控制任务。
Our main experimental validation of generalized advantage estimation is in the domain of simulated robotic locomotion. As shown in our experiments, choosing an appropriate intermediate value of in the range usually results in the best performance. A possible topic for future work is how to adjust the estimator parameters in an adaptive or automatic way.
我们对广义优势估计的主要实验验证是在仿真机器人运动领域。如实验所示,把 选在 这一适当的中间范围,通常能得到最好的性能。一个可能的后续课题是如何以自适应或自动的方式调整估计器参数 。
One question that merits future investigation is the relationship between value function estimation error and policy gradient estimation error. If this relationship were known, we could choose an error metric for value function fitting that is well-matched to the quantity of interest, which is typically the accuracy of the policy gradient estimation. Some candidates for such an error metric might include the Bellman error or projected Bellman error, as described in Bhatnagar et al. (2009).
一个值得今后研究的问题,是价值函数估计误差与策略梯度估计误差之间的关系。如果这一关系已知,我们就可以为价值函数拟合选择一种与真正关心的量——通常是策略梯度估计的准确性——相匹配的误差度量。这样的误差度量的候选包括贝尔曼误差或投影贝尔曼误差,如 Bhatnagar et al.(2009)所述。
Another enticing possibility is to use a shared function approximation architecture for the policy and the value function, while optimizing the policy using generalized advantage estimation. While formulating this problem in a way that is suitable for numerical optimization and provides convergence guarantees remains an open question, such an approach could allow the value function and policy representations to share useful features of the input, resulting in even faster learning.
另一个诱人的可能,是为策略和价值函数使用共享的函数逼近架构,同时用广义优势估计来优化策略。如何把这一问题表述成适于数值优化、并提供收敛保证的形式,仍然是一个开放问题;但这种方法可以让价值函数和策略表示共享有用的输入特征,从而学得更快。
In concurrent work, researchers have been developing policy gradient methods that involve differentiation with respect to the continuous-valued action (Lillicrap et al., 2015; Heess et al., 2015). While we found empirically that the one-step return () leads to excessive bias and poor performance, these papers show that such methods can work when tuned appropriately. However, note that those papers consider control problems with substantially lower-dimensional state and action spaces than the ones considered here. A comparison between both classes of approach would be useful for future work.
在并行开展的工作中,研究者正在发展对连续值动作求导的策略梯度方法(Lillicrap et al., 2015; Heess et al., 2015)。我们在经验上发现一步回报()会带来过大的偏差和较差的性能,而这些论文表明,只要调参得当,这类方法也可以奏效。不过需要注意,那些论文考虑的控制问题,其状态和动作空间的维度明显低于本文。对这两类方法做比较,将是有用的后续工作。
Acknowledgements
致谢
We thank Emo Todorov for providing the simulator as well as insightful discussions, and we thank Greg Wayne, Yuval Tassa, Dave Silver, Carlos Florensa Campo, and Greg Brockman for insightful discussions. This research was funded in part by the Office of Naval Research through a Young Investigator Award and under grant number N00014-11-1-0688, DARPA through a Young Faculty Award, by the Army Research Office through the MAST program.
感谢 Emo Todorov 提供仿真器并给予富有洞见的讨论,并感谢 Greg Wayne、Yuval Tassa、Dave Silver、Carlos Florensa Campo 和 Greg Brockman 的深入讨论。本研究部分资助来自美国海军研究办公室青年研究者奖及基金号 N00014-11-1-0688,DARPA 青年教师奖,以及陆军研究办公室通过 MAST 项目提供的支持。
Appendix A Frequently Asked Questions
附录 A 常见问题
A.1 What’s the Relationship with Compatible Features?
A.1 与相容特征有什么关系?
Compatible features are often mentioned in relation to policy gradient algorithms that make use of a value function, and the idea was proposed in the paper On Actor-Critic Methods by Konda & Tsitsiklis (2003). These authors pointed out that due to the limited representation power of the policy, the policy gradient only depends on a certain subspace of the space of advantage functions. This subspace is spanned by the compatible features , where . This theory of compatible features provides no guidance on how to exploit the temporal structure of the problem to obtain better estimates of the advantage function, making it mostly orthogonal to the ideas in this paper.
相容特征常被提及,与使用价值函数的策略梯度算法有关,这一想法由 Konda & Tsitsiklis(2003)在论文 On Actor-Critic Methods 中提出。这些作者指出,由于策略的表示能力有限,策略梯度只依赖于优势函数空间中的某个子空间。该子空间由相容特征 张成,其中 。相容特征理论并不指导我们如何利用问题的时间结构来更好地估计优势函数,因而与本文的想法大体是正交的。
The idea of compatible features motivates an elegant method for computing the natural policy gradient (Kakade, 2001a; Peters & Schaal, 2008). Given an empirical estimate of the advantage function at each timestep, we can project it onto the subspace of compatible features by solving the following least squares problem:
相容特征的想法启发了一种计算自然策略梯度的优美方法(Kakade, 2001a; Peters & Schaal, 2008)。给定每个时间步优势函数的经验估计 ,可以通过求解如下最小二乘问题,把它投影到相容特征子空间上:
If is -just, the least squares solution is the natural policy gradient (Kakade, 2001a). Note that any estimator of the advantage function can be substituted into this formula, including the ones we derive in this paper. For our experiments, we also compute natural policy gradient steps, but we use the more computationally efficient numerical procedure from Schulman et al. (2015), as discussed in Section 6.
若 是 -正当的,则最小二乘解就是自然策略梯度(Kakade, 2001a)。注意,任何优势函数估计器都可以代入这一公式,包括本文导出的那些。在我们的实验中也计算了自然策略梯度步,但使用的是 Schulman et al.(2015)中计算效率更高的数值程序,见第 6 节的讨论。
A.2 Why Don’t You Just Use a -Function?
A.2 为什么不直接使用 函数?
Previous actor critic methods, e.g. in Konda & Tsitsiklis (2003), use a -function to obtain potentially low-variance policy gradient estimates. Recent papers, including Heess et al. (2015); Lillicrap et al. (2015), have shown that a neural network -function approximator can used effectively in a policy gradient method. However, there are several advantages to using a state-value function in the manner of this paper. First, the state-value function has a lower-dimensional input and is thus easier to learn than a state-action value function. Second, the method of this paper allows us to smoothly interpolate between the high-bias estimator () and the low-bias estimator (). On the other hand, using a parameterized -function only allows us to use a high-bias estimator. We have found that the bias is prohibitively large when using a one-step estimate of the returns, i.e., the estimator, . We expect that similar difficulty would be encountered when using an advantage estimator involving a parameterized -function, . There is an interesting space of possible algorithms that would use a parameterized -function and attempt to reduce bias, however, an exploration of these possibilities is beyond the scope of this work.
先前的演员–评论家方法,例如 Konda & Tsitsiklis(2003),用 函数来获得可能低方差的策略梯度估计。包括 Heess et al.(2015)、Lillicrap et al.(2015)在内的近期论文表明,神经网络 函数逼近器可以有效用于策略梯度方法。但按本文方式使用状态价值函数有若干优点。第一,状态价值函数的输入维度更低,因而比状态–动作价值函数更容易学习。第二,本文的方法可以在高偏差估计器()和低偏差估计器()之间平滑插值。相反,使用参数化 函数只允许我们采用高偏差估计器。我们发现,使用回报的一步估计,即 估计器 时,偏差大会到难以接受。我们预期,在使用涉及参数化 函数的优势估计器 时,也会遇到类似困难。还存在一类有趣的可能算法:使用参数化 函数并试图降低偏差,但探索这些可能已超出本文范围。
Appendix B Proofs
附录 B 证明
Proof of Proposition 1: First we can split the expectation into terms involving and ,
命题 1 的证明:首先可以把期望拆成涉及 和 的两项,
We’ll consider the terms with and in turn.
我们依次考虑含 和含 的项。
Next,
接下来,
References
参考文献
Barto et al. (1983) Barto, Andrew G, Sutton, Richard S, and Anderson, Charles W. Neuronlike adaptive elements that can solve difficult learning control problems. Systems, Man and Cybernetics, IEEE Transactions on , (5):834–846, 1983.
Baxter & Bartlett (2000) Baxter, Jonathan and Bartlett, Peter L. Reinforcement learning in POMDPs via direct gradient ascent. In ICML , pp. 41–48, 2000.
Bertsekas (2012) Bertsekas, Dimitri P. Dynamic programming and optimal control , volume 2. Athena Scientific, 2012.
Bhatnagar et al. (2009) Bhatnagar, Shalabh, Precup, Doina, Silver, David, Sutton, Richard S, Maei, Hamid R, and Szepesvári, Csaba. Convergent temporal-difference learning with arbitrary smooth function approximation. In Advances in Neural Information Processing Systems , pp. 1204–1212, 2009.
Greensmith et al. (2004) Greensmith, Evan, Bartlett, Peter L, and Baxter, Jonathan. Variance reduction techniques for gradient estimates in reinforcement learning. The Journal of Machine Learning Research , 5:1471–1530, 2004.
Hafner & Riedmiller (2011) Hafner, Roland and Riedmiller, Martin. Reinforcement learning in feedback control. Machine learning , 84(1-2):137–169, 2011.
Heess et al. (2015) Heess, Nicolas, Wayne, Greg, Silver, David, Lillicrap, Timothy, Tassa, Yuval, and Erez, Tom. Learning continuous control policies by stochastic value gradients. arXiv preprint arXiv:1510.09142 , 2015.
Hull (1943) Hull, Clark. Principles of behavior. 1943.
Kakade (2001a) Kakade, Sham. A natural policy gradient. In NIPS , volume 14, pp. 1531–1538, 2001a.
Kakade (2001b) Kakade, Sham. Optimizing average reward using discounted rewards. In Computational Learning Theory , pp. 605–615. Springer, 2001b.
Kimura & Kobayashi (1998) Kimura, Hajime and Kobayashi, Shigenobu. An analysis of actor/critic algorithms using eligibility traces: Reinforcement learning with imperfect value function. In ICML , pp. 278–286, 1998.
Konda & Tsitsiklis (2003) Konda, Vijay R and Tsitsiklis, John N. On actor-critic algorithms. SIAM journal on Control and Optimization , 42(4):1143–1166, 2003.
Lillicrap et al. (2015) Lillicrap, Timothy P, Hunt, Jonathan J, Pritzel, Alexander, Heess, Nicolas, Erez, Tom, Tassa, Yuval, Silver, David, and Wierstra, Daan. Continuous control with deep reinforcement learning. arXiv preprint arXiv:1509.02971 , 2015.
Marbach & Tsitsiklis (2003) Marbach, Peter and Tsitsiklis, John N. Approximate gradient methods in policy-space optimization of markov reward processes. Discrete Event Dynamic Systems , 13(1-2):111–148, 2003.
Minsky (1961) Minsky, Marvin. Steps toward artificial intelligence. Proceedings of the IRE , 49(1):8–30, 1961.
Ng et al. (1999) Ng, Andrew Y, Harada, Daishi, and Russell, Stuart. Policy invariance under reward transformations: Theory and application to reward shaping. In ICML , volume 99, pp. 278–287, 1999.
Peters & Schaal (2008) Peters, Jan and Schaal, Stefan. Natural actor-critic. Neurocomputing , 71(7):1180–1190, 2008.
Schulman et al. (2015) Schulman, John, Levine, Sergey, Moritz, Philipp, Jordan, Michael I, and Abbeel, Pieter. Trust region policy optimization. arXiv preprint arXiv:1502.05477 , 2015.
Sutton & Barto (1998) Sutton, Richard S and Barto, Andrew G. Introduction to reinforcement learning . MIT Press, 1998.
Sutton et al. (1999) Sutton, Richard S, McAllester, David A, Singh, Satinder P, and Mansour, Yishay. Policy gradient methods for reinforcement learning with function approximation. In NIPS , volume 99, pp. 1057–1063. Citeseer, 1999.
Thomas (2014) Thomas, Philip. Bias in natural actor-critic algorithms. In Proceedings of The 31st International Conference on Machine Learning , pp. 441–448, 2014.
Todorov et al. (2012) Todorov, Emanuel, Erez, Tom, and Tassa, Yuval. Mujoco: A physics engine for model-based control. In Intelligent Robots and Systems (IROS), 2012 IEEE/RSJ International Conference on , pp. 5026–5033. IEEE, 2012.
Wawrzyński (2009) Wawrzyński, Paweł. Real-time reinforcement learning by sequential actor–critics and experience replay. Neural Networks , 22(10):1484–1497, 2009.
Williams (1992) Williams, Ronald J. Simple statistical gradient-following algorithms for connectionist reinforcement learning. Machine learning , 8(3-4):229–256, 1992.
Wright & Nocedal (1999) Wright, Stephen J and Nocedal, Jorge. Numerical optimization . Springer New York, 1999.