Semi-Supervised Classification with Graph Convolutional Networks
Semi-Supervised Classification with Graph Convolutional Networks
用图卷积网络做半监督分类
Thomas N. Kipf Affiliation: University of Amsterdam Email: T.N.Kipf@uva.nl Max Welling Affiliation: University of Amsterdam Affiliation: Canadian Institute for Advanced Research (CIFAR) Email: M.Welling@uva.nl
Abstract
摘要
We present a scalable approach for semi-supervised learning on graph-structured data that is based on an efficient variant of convolutional neural networks which operate directly on graphs. We motivate the choice of our convolutional architecture via a localized first-order approximation of spectral graph convolutions. Our model scales linearly in the number of graph edges and learns hidden layer representations that encode both local graph structure and features of nodes. In a number of experiments on citation networks and on a knowledge graph dataset we demonstrate that our approach outperforms related methods by a significant margin.
我们提出一种可扩展的图结构数据半监督学习方法,其核心是一种直接在图上运算的高效卷积神经网络变体。我们用谱图卷积的局部一阶近似来说明该卷积架构的选择。模型复杂度相对图边数线性增长,并学习同时编码局部图结构与节点特征的隐层表示。在多个引用网络与一个知识图谱数据集上的实验表明,该方法显著优于相关方法。
1 Introduction
1 引言
We consider the problem of classifying nodes (such as documents) in a graph (such as a citation network), where labels are only available for a small subset of nodes. This problem can be framed as graph-based semi-supervised learning, where label information is smoothed over the graph via some form of explicit graph-based regularization (Zhu et al. 2003; Zhou et al. 2004; Belkin et al. 2006; Weston et al. 2012), e.g. by using a graph Laplacian regularization term in the loss function:
我们考虑在图(例如引用网络)上对节点(例如文档)分类的问题,其中只有少量节点带有标签。这一问题可表述为基于图的半监督学习:标签信息通过某种显式的基于图的正则化在图上平滑(Zhu et al. 2003;Zhou et al. 2004;Belkin et al. 2006;Weston et al. 2012),例如在损失函数中加入图拉普拉斯正则项:
Here, denotes the supervised loss w.r.t. the labeled part of the graph, can be a neural network-like differentiable function, is a weighing factor and is a matrix of node feature vectors . denotes the unnormalized graph Laplacian of an undirected graph with nodes , edges , an adjacency matrix (binary or weighted) and a degree matrix . The formulation of Eq. 1 relies on the assumption that connected nodes in the graph are likely to share the same label. This assumption, however, might restrict modeling capacity, as graph edges need not necessarily encode node similarity, but could contain additional information.
这里, 表示相对图中已标注部分的监督损失, 可以是类似神经网络的可微函数, 是权重系数, 是由节点特征向量 组成的矩阵。 表示无向图 的未归一化图拉普拉斯,其中有 个节点 、边 、邻接矩阵 (二值或加权)以及度矩阵 。式 1 的形式依赖于「相连节点更可能共享同一标签」这一假设。但这一假设可能限制建模能力,因为图边并不一定只编码节点相似性,还可能携带额外信息。
In this work, we encode the graph structure directly using a neural network model and train on a supervised target for all nodes with labels, thereby avoiding explicit graph-based regularization in the loss function. Conditioning on the adjacency matrix of the graph will allow the model to distribute gradient information from the supervised loss and will enable it to learn representations of nodes both with and without labels.
在本工作中,我们用神经网络模型 直接编码图结构,并在所有带标签节点上相对监督目标 训练,从而避免在损失函数中显式加入基于图的正则。把 条件于图的邻接矩阵,使模型能够把监督损失 的梯度信息沿图传播,并同时学习有标签与无标签节点的表示。
Our contributions are two-fold. Firstly, we introduce a simple and well-behaved layer-wise propagation rule for neural network models which operate directly on graphs and show how it can be motivated from a first-order approximation of spectral graph convolutions (Hammond et al. 2011). Secondly, we demonstrate how this form of a graph-based neural network model can be used for fast and scalable semi-supervised classification of nodes in a graph. Experiments on a number of datasets demonstrate that our model compares favorably both in classification accuracy and efficiency (measured in wall-clock time) against state-of-the-art methods for semi-supervised learning.
我们的贡献有两方面。其一,我们为直接在图上运算的神经网络引入一条简单且性态良好的逐层传播规则,并说明它可由谱图卷积的一阶近似推导而来(Hammond et al. 2011)。其二,我们展示这类基于图的神经网络如何用于快速、可扩展的节点半监督分类。多个数据集上的实验表明,在分类精度与效率(墙钟时间)上,我们的模型相对当时的半监督学习先进方法都具有竞争力。
2 Fast Approximate Convolutions on Graphs
2 图上的快速近似卷积
In this section, we provide theoretical motivation for a specific graph-based neural network model that we will use in the rest of this paper. We consider a multi-layer Graph Convolutional Network (GCN) with the following layer-wise propagation rule:
本节为后文将使用的特定图神经网络模型 提供理论动机。我们考虑多层图卷积网络(GCN),其逐层传播规则为:
Here, is the adjacency matrix of the undirected graph with added self-connections. is the identity matrix, and is a layer-specific trainable weight matrix. denotes an activation function, such as the . is the matrix of activations in the layer; . In the following, we show that the form of this propagation rule can be motivated[^1] via a first-order approximation of localized spectral filters on graphs (Hammond et al. 2011; Defferrard et al. 2016).
这里, 是加入自环后的无向图 邻接矩阵。 是单位矩阵,, 是第 层可训练权重矩阵。 表示激活函数,例如 。 是第 层激活矩阵;。下文将说明,该传播规则形式可由图上局部谱滤波器的一阶近似推导而来[^1](Hammond et al. 2011;Defferrard et al. 2016)。
2.1 Spectral Graph Convolutions
2.1 谱图卷积
We consider spectral convolutions on graphs defined as the multiplication of a signal (a scalar for every node) with a filter parameterized by in the Fourier domain, i.e.:
我们把图上的谱卷积定义为:信号 (每个节点一个标量)与滤波器 (由 参数化)在傅里叶域中的乘法,即:
where is the matrix of eigenvectors of the normalized graph Laplacian , with a diagonal matrix of its eigenvalues and being the graph Fourier transform of . We can understand as a function of the eigenvalues of , i.e. . Evaluating Eq. 3 is computationally expensive, as multiplication with the eigenvector matrix is . Furthermore, computing the eigendecomposition of in the first place might be prohibitively expensive for large graphs. To circumvent this problem, it was suggested in Hammond et al. 2011 that can be well-approximated by a truncated expansion in terms of Chebyshev polynomials up to order:
其中 是归一化图拉普拉斯 的特征向量矩阵, 为其特征值对角矩阵, 是 的图傅里叶变换。可以把 理解为 特征值的函数,即 。计算式 3 代价很高,因为与特征向量矩阵 相乘是 。此外,对大图预先计算 的特征分解也可能不可接受。为绕过这一问题,Hammond et al. 2011 建议用截断的切比雪夫多项式 展开(到第 阶)来良好近似 :
with a rescaled . denotes the largest eigenvalue of . is now a vector of Chebyshev coefficients. The Chebyshev polynomials are recursively defined as , with and . The reader is referred to Hammond et al. 2011 for an in-depth discussion of this approximation.
其中经重缩放的 。 表示 的最大特征值。 现在是切比雪夫系数向量。切比雪夫多项式递推定义为 ,且 、。更深入讨论见 Hammond et al. 2011。
Going back to our definition of a convolution of a signal with a filter , we now have:
回到信号 与滤波器 的卷积定义,我们现在有:
with ; as can easily be verified by noticing that . Note that this expression is now -localized since it is a -order polynomial in the Laplacian, i.e. it depends only on nodes that are at maximum steps away from the central node (-order neighborhood). The complexity of evaluating Eq. 5 is , i.e. linear in the number of edges. Defferrard et al. 2016 use this -localized convolution to define a convolutional neural network on graphs.
其中 ;注意到 即可验证。注意该表达式现在是 -局部的,因为它是拉普拉斯的 阶多项式,即只依赖于距中心节点至多 步的节点(第 阶邻域)。计算式 5 的复杂度是 ,即相对边数线性。Defferrard et al. 2016 用这种 -局部卷积定义图上的卷积神经网络。
2.2 Layer-Wise Linear Model
2.2 逐层线性模型
A neural network model based on graph convolutions can therefore be built by stacking multiple convolutional layers of the form of Eq. 5, each layer followed by a point-wise non-linearity. Now, imagine we limited the layer-wise convolution operation to (see Eq. 5), i.e. a function that is linear w.r.t. and therefore a linear function on the graph Laplacian spectrum.
因此,可以堆叠多个形如式 5 的卷积层(每层后接逐点非线性)来构建基于图卷积的神经网络。现在设想把逐层卷积限制为 (见式 5),即相对 线性、从而在图拉普拉斯谱上也线性的函数。
In this way, we can still recover a rich class of convolutional filter functions by stacking multiple such layers, but we are not limited to the explicit parameterization given by, e.g., the Chebyshev polynomials. We intuitively expect that such a model can alleviate the problem of overfitting on local neighborhood structures for graphs with very wide node degree distributions, such as social networks, citation networks, knowledge graphs and many other real-world graph datasets. Additionally, for a fixed computational budget, this layer-wise linear formulation allows us to build deeper models, a practice that is known to improve modeling capacity on a number of domains (He et al. 2016).
这样,通过堆叠多层仍可恢复丰富的卷积滤波函数类,但不再受限于例如切比雪夫多项式给出的显式参数化。我们直觉上期望:对节点度分布很宽的图(如社交网络、引用网络、知识图谱及许多其他真实图数据),这类模型能缓解对局部邻域结构过拟合的问题。此外,在固定计算预算下,这种逐层线性形式允许构建更深的模型——在多个领域中,加深已被证明能提升建模能力(He et al. 2016)。
In this linear formulation of a GCN we further approximate , as we can expect that neural network parameters will adapt to this change in scale during training. Under these approximations Eq. 5 simplifies to:
在这一线性 GCN 形式中,我们进一步近似 ,因为可以期望神经网络参数在训练中适应这一尺度变化。在这些近似下,式 5 简化为:
with two free parameters and . The filter parameters can be shared over the whole graph. Successive application of filters of this form then effectively convolve the -order neighborhood of a node, where is the number of successive filtering operations or convolutional layers in the neural network model.
其中有两个自由参数 与 。滤波参数可在整张图上共享。连续施加这种形式的滤波器,实际上就是对节点的第 阶邻域做卷积,这里 是相继滤波次数,也即神经网络中的卷积层数。
In practice, it can be beneficial to constrain the number of parameters further to address overfitting and to minimize the number of operations (such as matrix multiplications) per layer. This leaves us with the following expression:
实践中,进一步约束参数数量有助于应对过拟合,并减少每层运算(如矩阵乘法)次数。于是得到:
with a single parameter . Note that now has eigenvalues in the range . Repeated application of this operator can therefore lead to numerical instabilities and exploding/vanishing gradients when used in a deep neural network model. To alleviate this problem, we introduce the following renormalization trick: , with and .
其中只有单个参数 。注意 的特征值现在落在 。在深度神经网络中反复施加该算子可能导致数值不稳定以及梯度爆炸/消失。为缓解这一问题,我们引入如下重归一化技巧:,其中 ,。
We can generalize this definition to a signal with input channels (i.e. a -dimensional feature vector for every node) and filters or feature maps as follows:
可以把该定义推广到具有 个输入通道的信号 (即每个节点一个 维特征向量)以及 个滤波器或特征图的情形:
where is now a matrix of filter parameters and is the convolved signal matrix. This filtering operation has complexity , as can be efficiently implemented as a product of a sparse matrix with a dense matrix.
其中 是滤波参数矩阵, 是卷积后的信号矩阵。该滤波运算复杂度为 ,因为 可高效实现为稀疏矩阵与稠密矩阵的乘积。
3 Semi-Supervised Node Classification
3 半监督节点分类
Having introduced a simple, yet flexible model for efficient information propagation on graphs, we can return to the problem of semi-supervised node classification. As outlined in the introduction, we can relax certain assumptions typically made in graph-based semi-supervised learning by conditioning our model both on the data and on the adjacency matrix of the underlying graph structure. We expect this setting to be especially powerful in scenarios where the adjacency matrix contains information not present in the data , such as citation links between documents in a citation network or relations in a knowledge graph. The overall model, a multi-layer GCN for semi-supervised learning, is schematically depicted in Figure 1.
在引入用于图上高效信息传播的简单而灵活的模型 之后,我们回到半监督节点分类问题。如引言所述,通过把模型 同时条件于数据 与底层图结构的邻接矩阵 ,可以放宽基于图的半监督学习中常见的某些假设。我们期望:当邻接矩阵含有数据 中不存在的信息时——例如引用网络中文档间的引用链接,或知识图谱中的关系——这一设定尤其有力。用于半监督学习的多层 GCN 整体模型示意如图 1。
(a) Graph Convolutional Network
(a) 图卷积网络
3.1 Example
3.1 示例
In the following, we consider a two-layer GCN for semi-supervised node classification on a graph with a symmetric adjacency matrix (binary or weighted). We first calculate in a pre-processing step. Our forward model then takes the simple form:
下面考虑在对称邻接矩阵 (二值或加权)的图上做半监督节点分类的两层 GCN。我们先在预处理步骤中计算 。前向模型于是取简单形式:
Here, is an input-to-hidden weight matrix for a hidden layer with feature maps. is a hidden-to-output weight matrix. The softmax activation function, defined as with , is applied row-wise. For semi-supervised multi-class classification, we then evaluate the cross-entropy error over all labeled examples:
这里, 是输入到隐层的权重矩阵,隐层有 个特征图。 是隐层到输出的权重矩阵。softmax 激活定义为 ,其中 ,并按行施加。对半监督多类分类,我们在所有已标注样本上计算交叉熵误差:
where is the set of node indices that have labels.
其中 是带标签的节点下标集合。
The neural network weights and are trained using gradient descent. In this work, we perform batch gradient descent using the full dataset for every training iteration, which is a viable option as long as datasets fit in memory. Using a sparse representation for , memory requirement is , i.e. linear in the number of edges. Stochasticity in the training process is introduced via dropout (Srivastava et al. 2014). We leave memory-efficient extensions with mini-batch stochastic gradient descent for future work.
神经网络权重 与 用梯度下降训练。本工作对每次训练迭代使用全数据集做批量梯度下降;只要数据能装入内存,这是可行的。对 使用稀疏表示时,内存需求为 ,即相对边数线性。训练过程中的随机性由 dropout 引入(Srivastava et al. 2014)。带小批量随机梯度下降的内存高效扩展留作未来工作。
3.2 Implementation
3.2 实现
In practice, we make use of TensorFlow (Abadi et al. 2015) for an efficient GPU-based implementation[^2] of Eq. 9 using sparse-dense matrix multiplications. The computational complexity of evaluating Eq. 9 is then , i.e. linear in the number of graph edges.
实践中,我们用 TensorFlow(Abadi et al. 2015)基于稀疏-稠密矩阵乘法高效实现式 9 的 GPU 版本[^2]。计算式 9 的复杂度于是为 ,即相对图边数线性。
4 Related Work
4 相关工作
Our model draws inspiration both from the field of graph-based semi-supervised learning and from recent work on neural networks that operate on graphs. In what follows, we provide a brief overview on related work in both fields.
我们的模型同时受到基于图的半监督学习与近期在图上运算的神经网络两方面启发。下文对这两个领域的相关工作作简要综述。
4.1 Graph-Based Semi-Supervised Learning
4.1 基于图的半监督学习
A large number of approaches for semi-supervised learning using graph representations have been proposed in recent years, most of which fall into two broad categories: methods that use some form of explicit graph Laplacian regularization and graph embedding-based approaches. Prominent examples for graph Laplacian regularization include label propagation (Zhu et al. 2003), manifold regularization (Belkin et al. 2006) and deep semi-supervised embedding (Weston et al. 2012).
近年来提出了大量利用图表示的半监督学习方法,大多可归为两大类:使用某种显式图拉普拉斯正则的方法,以及基于图嵌入的方法。图拉普拉斯正则的代表包括标签传播(Zhu et al. 2003)、流形正则(Belkin et al. 2006)与深度半监督嵌入(Weston et al. 2012)。
Recently, attention has shifted to models that learn graph embeddings with methods inspired by the skip-gram model (Mikolov et al. 2013). DeepWalk (Perozzi et al. 2014) learns embeddings via the prediction of the local neighborhood of nodes, sampled from random walks on the graph. LINE (Tang et al. 2015) and node2vec (Grover & Leskovec 2016) extend DeepWalk with more sophisticated random walk or breadth-first search schemes. For all these methods, however, a multi-step pipeline including random walk generation and semi-supervised training is required where each step has to be optimized separately. Planetoid (Yang et al. 2016) alleviates this by injecting label information in the process of learning embeddings.
近来注意力转向受 skip-gram 模型启发、学习图嵌入的方法(Mikolov et al. 2013)。DeepWalk(Perozzi et al. 2014)通过对从图上随机游走采样得到的节点局部邻域做预测来学习嵌入。LINE(Tang et al. 2015)与 node2vec(Grover & Leskovec 2016)用更精细的随机游走或广度优先搜索方案扩展 DeepWalk。然而,这些方法都需要包含随机游走生成与半监督训练的多步流水线,且每一步须分别优化。Planetoid(Yang et al. 2016)通过在学习嵌入过程中注入标签信息来缓解这一问题。
4.2 Neural Networks on Graphs
4.2 图上的神经网络
Neural networks that operate on graphs have previously been introduced in Gori et al. 2005; Scarselli et al. 2009 as a form of recurrent neural network. Their framework requires the repeated application of contraction maps as propagation functions until node representations reach a stable fixed point. This restriction was later alleviated in Li et al. 2016 by introducing modern practices for recurrent neural network training to the original graph neural network framework. Duvenaud et al. 2015 introduced a convolution-like propagation rule on graphs and methods for graph-level classification. Their approach requires to learn node degree-specific weight matrices which does not scale to large graphs with wide node degree distributions. Our model instead uses a single weight matrix per layer and deals with varying node degrees through an appropriate normalization of the adjacency matrix (see Section 3.1).
在图上运算的神经网络更早由 Gori et al. 2005;Scarselli et al. 2009 以循环神经网络形式引入。其框架要求反复施加压缩映射作为传播函数,直到节点表示达到稳定不动点。这一限制后来被 Li et al. 2016 缓解——他们把现代循环神经网络训练实践引入原始图神经网络框架。Duvenaud et al. 2015 引入了图上类似卷积的传播规则以及图级分类方法。他们的方法需要为每个节点度学习特定权重矩阵,难以扩展到节点度分布很宽的大图。我们的模型则每层只用一个权重矩阵,并通过适当归一化邻接矩阵来处理变化的节点度(见第 3.1 节)。
A related approach to node classification with a graph-based neural network was recently introduced in Atwood & Towsley 2016. They report complexity, limiting the range of possible applications. In a different yet related model, Niepert et al. 2016 convert graphs locally into sequences that are fed into a conventional 1D convolutional neural network, which requires the definition of a node ordering in a pre-processing step.
Atwood & Towsley 2016 最近引入了一种相关的、用基于图的神经网络做节点分类的方法。他们报告复杂度为 ,限制了可能的应用范围。在另一个相关但不同的模型中,Niepert et al. 2016 把图局部转换成序列,再送入常规的一维卷积神经网络,这要求在预处理步骤中定义节点次序。
Our method is based on spectral graph convolutional neural networks, introduced in Bruna et al. 2014 and later extended by Defferrard et al. 2016 with fast localized convolutions. In contrast to these works, we consider here the task of transductive node classification within networks of significantly larger scale. We show that in this setting, a number of simplifications (see Section 2.2) can be introduced to the original frameworks of Bruna et al. 2014 and Defferrard et al. 2016 that improve scalability and classification performance in large-scale networks.
我们的方法基于谱图卷积神经网络,由 Bruna et al. 2014 引入,后由 Defferrard et al. 2016 用快速局部卷积扩展。与这些工作不同,我们在此考虑规模显著更大的网络中的直推式节点分类任务。我们表明,在这一设定下,可对 Bruna et al. 2014 与 Defferrard et al. 2016 的原始框架引入若干简化(见第 2.2 节),从而在大规模网络中提升可扩展性与分类性能。
5 Experiments
5 实验
We test our model in a number of experiments: semi-supervised document classification in citation networks, semi-supervised entity classification in a bipartite graph extracted from a knowledge graph, an evaluation of various graph propagation models and a run-time analysis on random graphs.
我们在多项实验中测试模型:引用网络上的半监督文档分类、从知识图谱抽取的二部图上的半监督实体分类、多种图传播模型的评估,以及随机图上的运行时间分析。
5.1 Datasets
5.1 数据集
We closely follow the experimental setup in Yang et al. 2016. Dataset statistics are summarized in Table 1. In the citation network datasets—Citeseer, Cora and Pubmed (Sen et al. 2008)—nodes are documents and edges are citation links. Label rate denotes the number of labeled nodes that are used for training divided by the total number of nodes in each dataset. NELL (Carlson et al. 2010; Yang et al. 2016) is a bipartite graph dataset extracted from a knowledge graph with 55,864 relation nodes and 9,891 entity nodes.
我们紧密遵循 Yang et al. 2016 的实验设定。数据集统计见表 1。在引用网络数据集——Citeseer、Cora 与 Pubmed(Sen et al. 2008)——中,节点是文档,边是引用链接。标签率表示用于训练的已标注节点数除以各数据集节点总数。NELL(Carlson et al. 2010;Yang et al. 2016)是从知识图谱抽取的二部图数据集,含 55,864 个关系节点与 9,891 个实体节点。
| Dataset | Type | Nodes | Edges | Classes | Features | Label rate |
|---|---|---|---|---|---|---|
| Citeseer | Citation network | 3,327 | 4,732 | 3,703 | ||
| Cora | Citation network | 2,708 | 5,429 | 1,433 | ||
| Pubmed | Citation network | 19,717 | 44,338 | 500 | ||
| NELL | Knowledge graph | 65,755 | 266,144 | 5,414 |
Table 1: Dataset statistics, as reported in Yang et al. 2016.
| 数据集 | 类型 | 节点 | 边 | 类别 | 特征 | 标签率 |
|---|---|---|---|---|---|---|
| Citeseer | 引用网络 | 3,327 | 4,732 | 3,703 | ||
| Cora | 引用网络 | 2,708 | 5,429 | 1,433 | ||
| Pubmed | 引用网络 | 19,717 | 44,338 | 500 | ||
| NELL | 知识图谱 | 65,755 | 266,144 | 5,414 |
表 1:数据集统计,引自 Yang et al. 2016。
Citation networks
We consider three citation network datasets: Citeseer, Cora and Pubmed (Sen et al. 2008). The datasets contain sparse bag-of-words feature vectors for each document and a list of citation links between documents. We treat the citation links as (undirected) edges and construct a binary, symmetric adjacency matrix . Each document has a class label. For training, we only use 20 labels per class, but all feature vectors.
引用网络
我们考虑三个引用网络数据集:Citeseer、Cora 与 Pubmed(Sen et al. 2008)。数据集为每篇文档提供稀疏词袋特征向量,以及文档间引用链接列表。我们把引用链接视为(无向)边,并构造二值对称邻接矩阵 。每篇文档有一个类别标签。训练时每类仅用 20 个标签,但使用全部特征向量。
NELL
NELL is a dataset extracted from the knowledge graph introduced in (Carlson et al. 2010). A knowledge graph is a set of entities connected with directed, labeled edges (relations). We follow the pre-processing scheme as described in Yang et al. 2016. We assign separate relation nodes and for each entity pair as and . Entity nodes are described by sparse feature vectors. We extend the number of features in NELL by assigning a unique one-hot representation for every relation node, effectively resulting in a 61,278-dim sparse feature vector per node. The semi-supervised task here considers the extreme case of only a single labeled example per class in the training set. We construct a binary, symmetric adjacency matrix from this graph by setting entries , if one or more edges are present between nodes and .
NELL
NELL 是从 Carlson et al. 2010 引入的知识图谱中抽取的数据集。知识图谱是一组由有向、带标签的边(关系)连接的实体。我们遵循 Yang et al. 2016 所述预处理方案。对每个实体对 ,分别指定关系节点 与 ,对应 与 。实体节点由稀疏特征向量描述。我们为每个关系节点分配唯一 one-hot 表示,从而扩展 NELL 的特征数,最终每个节点得到 61,278 维稀疏特征向量。此处的半监督任务考虑训练集每类只有一个已标注样本的极端情形。我们由此图构造二值对称邻接矩阵:若节点 与 之间存在一条或多条边,则令 。
Random graphs
We simulate random graph datasets of various sizes for experiments where we measure training time per epoch. For a dataset with nodes we create a random graph assigning edges uniformly at random. We take the identity matrix as input feature matrix , thereby implicitly taking a featureless approach where the model is only informed about the identity of each node, specified by a unique one-hot vector. We add dummy labels for every node.
随机图
我们模拟不同规模的随机图数据集,用于测量每轮训练时间。对含 个节点的数据集,我们均匀随机分配 条边。以单位矩阵 作为输入特征矩阵 ,从而隐式采用无特征设定:模型只获知每个节点的身份,由唯一 one-hot 向量指定。我们为每个节点添加虚拟标签 。
5.2 Experimental Set-Up
5.2 实验设置
Unless otherwise noted, we train a two-layer GCN as described in Section 3.1 and evaluate prediction accuracy on a test set of 1,000 labeled examples. We provide additional experiments using deeper models with up to 10 layers in Appendix B. We choose the same dataset splits as in Yang et al. 2016 with an additional validation set of 500 labeled examples for hyperparameter optimization (dropout rate for all layers, L2 regularization factor for the first GCN layer and number of hidden units). We do not use the validation set labels for training.
除非另有说明,我们按第 3.1 节训练两层 GCN,并在含 1,000 个已标注样本的测试集上评估预测精度。附录 B 给出了最多 10 层的更深模型的额外实验。数据集划分与 Yang et al. 2016 相同,并额外使用含 500 个已标注样本的验证集做超参数优化(各层 dropout 率、第一层 GCN 的 L2 正则系数与隐单元数)。验证集标签不用于训练。
For the citation network datasets, we optimize hyperparameters on Cora only and use the same set of parameters for Citeseer and Pubmed. We train all models for a maximum of 200 epochs (training iterations) using Adam (Kingma & Ba 2015) with a learning rate of and early stopping with a window size of , i.e. we stop training if the validation loss does not decrease for 10 consecutive epochs. We initialize weights using the initialization described in Glorot & Bengio 2010 and accordingly (row-)normalize input feature vectors. On the random graph datasets, we use a hidden layer size of 32 units and omit regularization (i.e. neither dropout nor L2 regularization).
对引用网络数据集,我们仅在 Cora 上优化超参数,并对 Citeseer 与 Pubmed 使用同一组参数。所有模型最多训练 200 个 epoch(训练迭代),使用 Adam(Kingma & Ba 2015),学习率 ,早停窗口大小为 ,即若验证损失连续 10 个 epoch 不下降则停止训练。权重按 Glorot & Bengio 2010 所述初始化,并对输入特征向量做(行)归一化。在随机图数据集上,隐层大小为 32,且省略正则(即既不用 dropout 也不用 L2 正则)。
5.3 Baselines
5.3 基线
We compare against the same baseline methods as in Yang et al. 2016, i.e. label propagation (LP) (Zhu et al. 2003), semi-supervised embedding (SemiEmb) (Weston et al. 2012), manifold regularization (ManiReg) (Belkin et al. 2006) and skip-gram based graph embeddings (DeepWalk) (Perozzi et al. 2014). We omit TSVM (Joachims 1999), as it does not scale to the large number of classes in one of our datasets.
我们与 Yang et al. 2016 相同的基线方法比较,即标签传播(LP)(Zhu et al. 2003)、半监督嵌入(SemiEmb)(Weston et al. 2012)、流形正则(ManiReg)(Belkin et al. 2006)以及基于 skip-gram 的图嵌入(DeepWalk)(Perozzi et al. 2014)。我们省略 TSVM(Joachims 1999),因为它无法扩展到我们某个数据集中的大量类别。
We further compare against the iterative classification algorithm (ICA) proposed in Lu & Getoor 2003 in conjunction with two logistic regression classifiers, one for local node features alone and one for relational classification using local features and an aggregation operator as described in Sen et al. 2008. We first train the local classifier using all labeled training set nodes and use it to bootstrap class labels of unlabeled nodes for relational classifier training. We run iterative classification (relational classifier) with a random node ordering for 10 iterations on all unlabeled nodes (bootstrapped using the local classifier). L2 regularization parameter and aggregation operator (count vs. prop, see Sen et al. 2008) are chosen based on validation set performance for each dataset separately.
我们进一步与 Lu & Getoor 2003 提出的迭代分类算法(ICA)比较,并配合两个逻辑回归分类器:一个仅用局部节点特征,另一个用局部特征与聚合算子做关系分类(如 Sen et al. 2008 所述)。我们先用全部已标注训练节点训练局部分类器,再用它引导未标注节点的类别标签,以供关系分类器训练。我们在全部未标注节点上(由局部分类器引导)按随机节点次序运行迭代分类(关系分类器)10 次。L2 正则参数与聚合算子(count 对 prop,见 Sen et al. 2008)按各数据集验证集表现分别选定。
Lastly, we compare against Planetoid (Yang et al. 2016), where we always choose their best-performing model variant (transductive vs. inductive) as a baseline.
最后,我们与 Planetoid(Yang et al. 2016)比较,始终取其表现最好的模型变体(直推式对归纳式)作为基线。
6 Results
6 结果
6.1 Semi-Supervised Node Classification
6.1 半监督节点分类
Results are summarized in Table 2. Reported numbers denote classification accuracy in percent. For ICA, we report the mean accuracy of 100 runs with random node orderings. Results for all other baseline methods are taken from the Planetoid paper (Yang et al. 2016). Planetoid* denotes the best model for the respective dataset out of the variants presented in their paper.
结果汇总于表 2。报告数字为分类精度(百分比)。对 ICA,我们报告 100 次随机节点次序运行的平均精度。其余基线方法结果取自 Planetoid 论文(Yang et al. 2016)。Planetoid* 表示其论文中各变体在相应数据集上最好的模型。
| Method | Citeseer | Cora | Pubmed | NELL |
|---|---|---|---|---|
| ManiReg [3] | ||||
| SemiEmb [28] | ||||
| LP [32] | ||||
| DeepWalk [22] | ||||
| ICA [18] | ||||
| Planetoid* [29] | (26s) | (13s) | (25s) | (185s) |
| GCN (this paper) | (7s) | (4s) | (38s) | (48s) |
| GCN (rand. splits) |
Table 2: Summary of results in terms of classification accuracy (in percent).
| 方法 | Citeseer | Cora | Pubmed | NELL |
|---|---|---|---|---|
| ManiReg [3] | ||||
| SemiEmb [28] | ||||
| LP [32] | ||||
| DeepWalk [22] | ||||
| ICA [18] | ||||
| Planetoid* [29] | (26s) | (13s) | (25s) | (185s) |
| GCN(本文) | (7s) | (4s) | (38s) | (48s) |
| GCN(随机划分) |
表 2:分类精度(百分比)结果汇总。
We further report wall-clock training time in seconds until convergence (in brackets) for our method (incl. evaluation of validation error) and for Planetoid. For the latter, we used an implementation provided by the authors[^3] and trained on the same hardware (with GPU) as our GCN model. We trained and tested our model on the same dataset splits as in Yang et al. 2016 and report mean accuracy of 100 runs with random weight initializations. We used the following sets of hyperparameters for Citeseer, Cora and Pubmed: 0.5 (dropout rate), (L2 regularization) and (number of hidden units); and for NELL: 0.1 (dropout rate), (L2 regularization) and (number of hidden units).
我们还报告收敛前的墙钟训练时间(秒,括号内):对我们的方法(含验证误差计算)以及对 Planetoid。后者使用作者提供的实现[^3],并在与我们 GCN 模型相同的硬件(含 GPU)上训练。我们在与 Yang et al. 2016 相同的数据集划分上训练与测试,并报告 100 次随机权重初始化的平均精度。对 Citeseer、Cora 与 Pubmed 使用如下超参数:0.5(dropout 率)、(L2 正则)与 (隐单元数);对 NELL:0.1(dropout 率)、(L2 正则)与 (隐单元数)。
In addition, we report performance of our model on 10 randomly drawn dataset splits of the same size as in Yang et al. 2016, denoted by GCN (rand. splits). Here, we report mean and standard error of prediction accuracy on the test set split in percent.
此外,我们在与 Yang et al. 2016 相同规模的 10 次随机数据集划分上报告模型表现,记为 GCN(随机划分)。这里报告测试集划分上预测精度的均值与标准误差(百分比)。
6.2 Evaluation of Propagation Model
6.2 传播模型评估
We compare different variants of our proposed per-layer propagation model on the citation network datasets. We follow the experimental set-up described in the previous section. Results are summarized in Table 3. The propagation model of our original GCN model is denoted by renormalization trick (in bold). In all other cases, the propagation model of both neural network layers is replaced with the model specified under propagation model. Reported numbers denote mean classification accuracy for 100 repeated runs with random weight matrix initializations. In case of multiple variables per layer, we impose L2 regularization on all weight matrices of the first layer.
我们在引用网络数据集上比较所提出的逐层传播模型的不同变体。实验设定遵循上一节。结果汇总于表 3。原始 GCN 模型的传播模型记为重归一化技巧(加粗)。在其余情形中,两个神经网络层的传播模型都替换为传播模型栏所指定的模型。报告数字为 100 次随机权重矩阵初始化重复运行的平均分类精度。若每层有多个变量 ,则对第一层所有权重矩阵施加 L2 正则。
| Description | Propagation model | Citeseer | Cora | Pubmed | |
|---|---|---|---|---|---|
| Chebyshev filter (Eq. 5) | |||||
| -order model (Eq. 6) | |||||
| Single parameter (Eq. 7) | |||||
| Renormalization trick (Eq. 8) | |||||
| -order term only | |||||
| Multi-layer perceptron |
Table 3: Comparison of propagation models.
| 描述 | 传播模型 | Citeseer | Cora | Pubmed | |
|---|---|---|---|---|---|
| 切比雪夫滤波(式 5) | |||||
| 一阶模型(式 6) | |||||
| 单参数(式 7) | |||||
| 重归一化技巧(式 8) | |||||
| 仅一阶项 | |||||
| 多层感知机 |
表 3:传播模型比较。
6.3 Training Time per Epoch
6.3 每轮训练时间
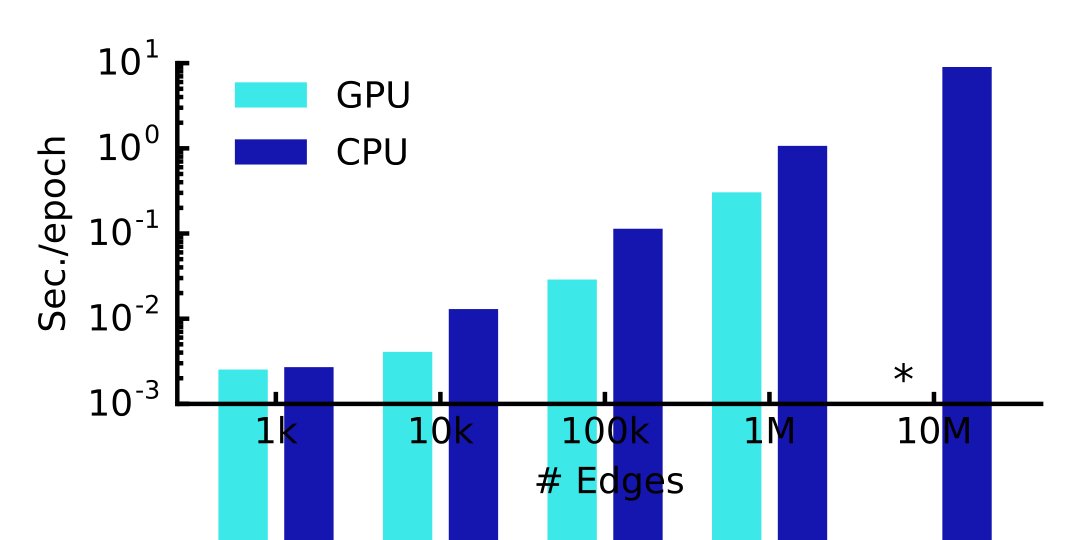
Figure 2: Wall-clock time per epoch for random graphs. (*) indicates out-of-memory error.
图 2:随机图上每轮墙钟时间。(*) 表示内存不足错误。
Here, we report results for the mean training time per epoch (forward pass, cross-entropy calculation, backward pass) for 100 epochs on simulated random graphs, measured in seconds wall-clock time. See Section 5.1 for a detailed description of the random graph dataset used in these experiments. We compare results on a GPU and on a CPU-only implementation[^4] in TensorFlow (Abadi et al. 2015). Figure 2 summarizes the results.
这里我们报告在模拟随机图上 100 个 epoch 的平均每轮训练时间(前向传播、交叉熵计算、反向传播),以墙钟秒计。所用随机图数据集的详细描述见第 5.1 节。我们比较 TensorFlow(Abadi et al. 2015)在 GPU 与仅 CPU 实现[^4]上的结果。图 2 汇总了结果。
7 Discussion
7 讨论
7.1 Semi-Supervised Model
7.1 半监督模型
In the experiments demonstrated here, our method for semi-supervised node classification outperforms recent related methods by a significant margin. Methods based on graph-Laplacian regularization (Zhu et al. 2003; Belkin et al. 2006; Weston et al. 2012) are most likely limited due to their assumption that edges encode mere similarity of nodes. Skip-gram based methods on the other hand are limited by the fact that they are based on a multi-step pipeline which is difficult to optimize. Our proposed model can overcome both limitations, while still comparing favorably in terms of efficiency (measured in wall-clock time) to related methods. Propagation of feature information from neighboring nodes in every layer improves classification performance in comparison to methods like ICA (Lu & Getoor 2003), where only label information is aggregated.
在此展示的实验中,我们的半监督节点分类方法显著优于近期相关方法。基于图拉普拉斯正则的方法(Zhu et al. 2003;Belkin et al. 2006;Weston et al. 2012)很可能受限于其假设——边仅编码节点相似性。另一方面,基于 skip-gram 的方法受限于其多步流水线难以联合优化。所提模型可同时克服这两点限制,同时在效率(墙钟时间)上仍具竞争力。每层从邻域节点传播特征信息,相对仅聚合标签信息的方法如 ICA(Lu & Getoor 2003),能提升分类表现。
We have further demonstrated that the proposed renormalized propagation model (Eq. 8) offers both improved efficiency (fewer parameters and operations, such as multiplication or addition) and better predictive performance on a number of datasets compared to a naïve -order model (Eq. 6) or higher-order graph convolutional models using Chebyshev polynomials (Eq. 5).
我们进一步表明,所提重归一化传播模型(式 8)相对朴素一阶模型(式 6)或使用切比雪夫多项式的高阶图卷积模型(式 5),在多个数据集上既更高效(更少参数与运算,如乘法或加法),预测表现也更好。
7.2 Limitations and Future Work
7.2 局限与未来工作
Here, we describe several limitations of our current model and outline how these might be overcome in future work.
这里描述当前模型的若干局限,并概述未来工作中可能的克服方式。
Memory requirement
In the current setup with full-batch gradient descent, memory requirement grows linearly in the size of the dataset. We have shown that for large graphs that do not fit in GPU memory, training on CPU can still be a viable option. Mini-batch stochastic gradient descent can alleviate this issue. The procedure of generating mini-batches, however, should take into account the number of layers in the GCN model, as the -order neighborhood for a GCN with layers has to be stored in memory for an exact procedure. For very large and densely connected graph datasets, further approximations might be necessary.
内存需求
在当前全批量梯度下降设定下,内存需求随数据集规模线性增长。我们已表明:对装不进 GPU 内存的大图,在 CPU 上训练仍可行。小批量随机梯度下降可缓解这一问题。但生成小批量的过程应考虑 GCN 模型的层数,因为对 层 GCN,精确过程需要把第 阶邻域存入内存。对非常大且稠密连接的图数据,可能还需要进一步近似。
Directed edges and edge features
Our framework currently does not naturally support edge features and is limited to undirected graphs (weighted or unweighted). Results on NELL however show that it is possible to handle both directed edges and edge features by representing the original directed graph as an undirected bipartite graph with additional nodes that represent edges in the original graph (see Section 5.1 for details).
有向边与边特征
我们的框架目前不能自然支持边特征,且限于无向图(加权或未加权)。但 NELL 上的结果表明:通过把原始有向图表示为带额外节点的无向二部图——这些额外节点表示原图中的边——可以同时处理有向边与边特征(细节见第 5.1 节)。
Limiting assumptions
Through the approximations introduced in Section 2, we implicitly assume locality (dependence on the -order neighborhood for a GCN with layers) and equal importance of self-connections vs. edges to neighboring nodes. For some datasets, however, it might be beneficial to introduce a trade-off parameter in the definition of :
限制性假设
通过第 2 节引入的近似,我们隐式假定局部性(对 层 GCN 依赖于第 阶邻域)以及自环与到邻域节点的边同等重要。但对某些数据集,在 的定义中引入折中参数 可能有益:
This parameter now plays a similar role as the trade-off parameter between supervised and unsupervised loss in the typical semi-supervised setting (see Eq. 1). Here, however, it can be learned via gradient descent.
该参数现在扮演与典型半监督设定中监督损失与无监督损失之间折中参数类似的角色(见式 1)。但在这里,它可通过梯度下降学习。
8 Conclusion
8 结论
We have introduced a novel approach for semi-supervised classification on graph-structured data. Our GCN model uses an efficient layer-wise propagation rule that is based on a first-order approximation of spectral convolutions on graphs. Experiments on a number of network datasets suggest that the proposed GCN model is capable of encoding both graph structure and node features in a way useful for semi-supervised classification. In this setting, our model outperforms several recently proposed methods by a significant margin, while being computationally efficient.
我们为图结构数据上的半监督分类引入了一种新方法。我们的 GCN 模型使用基于图上谱卷积一阶近似的高效逐层传播规则。多个网络数据集上的实验表明,所提 GCN 模型能够以对半监督分类有用的方式同时编码图结构与节点特征。在这一设定下,我们的模型显著优于若干近期方法,同时计算高效。
Acknowledgments
We would like to thank Christos Louizos, Taco Cohen, Joan Bruna, Zhilin Yang, Dave Herman, Pramod Sinha and Abdul-Saboor Sheikh for helpful discussions. This research was funded by SAP.
致谢
感谢 Christos Louizos、Taco Cohen、Joan Bruna、Zhilin Yang、Dave Herman、Pramod Sinha 与 Abdul-Saboor Sheikh 的有益讨论。本研究由 SAP 资助。
References
参考文献
Abadi et al. (2015) Martín Abadi et al. TensorFlow: Large-scale machine learning on heterogeneous systems, 2015.
Atwood & Towsley (2016) James Atwood and Don Towsley. Diffusion-convolutional neural networks. In Advances in neural information processing systems (NIPS) , 2016.
Belkin et al. (2006) Mikhail Belkin, Partha Niyogi, and Vikas Sindhwani. Manifold regularization: A geometric framework for learning from labeled and unlabeled examples. Journal of machine learning research (JMLR) , 7(Nov):2399–2434, 2006.
Brandes et al. (2008) Ulrik Brandes, Daniel Delling, Marco Gaertler, Robert Gorke, Martin Hoefer, Zoran Nikoloski, and Dorothea Wagner. On modularity clustering. IEEE Transactions on Knowledge and Data Engineering , 20(2):172–188, 2008.
Bruna et al. (2014) Joan Bruna, Wojciech Zaremba, Arthur Szlam, and Yann LeCun. Spectral networks and locally connected networks on graphs. In International Conference on Learning Representations (ICLR) , 2014.
Carlson et al. (2010) Andrew Carlson, Justin Betteridge, Bryan Kisiel, Burr Settles, Estevam R. Hruschka Jr, and Tom M. Mitchell. Toward an architecture for never-ending language learning. In AAAI , volume 5, pp. 3, 2010.
Defferrard et al. (2016) Michaël Defferrard, Xavier Bresson, and Pierre Vandergheynst. Convolutional neural networks on graphs with fast localized spectral filtering. In Advances in neural information processing systems (NIPS) , 2016.
Douglas (2011) Brendan L. Douglas. The Weisfeiler-Lehman method and graph isomorphism testing. arXiv preprint arXiv:1101.5211 , 2011.
Duvenaud et al. (2015) David K. Duvenaud, Dougal Maclaurin, Jorge Iparraguirre, Rafael Bombarell, Timothy Hirzel, Alán Aspuru-Guzik, and Ryan P. Adams. Convolutional networks on graphs for learning molecular fingerprints. In Advances in neural information processing systems (NIPS) , pp. 2224–2232, 2015.
Glorot & Bengio (2010) Xavier Glorot and Yoshua Bengio. Understanding the difficulty of training deep feedforward neural networks. In AISTATS , volume 9, pp. 249–256, 2010.
Gori et al. (2005) Marco Gori, Gabriele Monfardini, and Franco Scarselli. A new model for learning in graph domains. In Proceedings. 2005 IEEE International Joint Conference on Neural Networks. , volume 2, pp. 729–734. IEEE, 2005.
Grover & Leskovec (2016) Aditya Grover and Jure Leskovec. node2vec: Scalable feature learning for networks. In Proceedings of the 22nd ACM SIGKDD International Conference on Knowledge Discovery and Data Mining . ACM, 2016.
Hammond et al. (2011) David K. Hammond, Pierre Vandergheynst, and Rémi Gribonval. Wavelets on graphs via spectral graph theory. Applied and Computational Harmonic Analysis , 30(2):129–150, 2011.
He et al. (2016) Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. Deep residual learning for image recognition. In IEEE Conference on Computer Vision and Pattern Recognition (CVPR) , 2016.
Joachims (1999) Thorsten Joachims. Transductive inference for text classification using support vector machines. In International Conference on Machine Learning (ICML) , volume 99, pp. 200–209, 1999.
Kingma & Ba (2015) Diederik P. Kingma and Jimmy Lei Ba. Adam: A method for stochastic optimization. In International Conference on Learning Representations (ICLR) , 2015.
Li et al. (2016) Yujia Li, Daniel Tarlow, Marc Brockschmidt, and Richard Zemel. Gated graph sequence neural networks. In International Conference on Learning Representations (ICLR) , 2016.
Lu & Getoor (2003) Qing Lu and Lise Getoor. Link-based classification. In International Conference on Machine Learning (ICML) , volume 3, pp. 496–503, 2003.
Maaten & Hinton (2008) Laurens van der Maaten and Geoffrey Hinton. Visualizing data using t-sne. Journal of Machine Learning Research (JMLR) , 9(Nov):2579–2605, 2008.
Mikolov et al. (2013) Tomas Mikolov, Ilya Sutskever, Kai Chen, Greg S. Corrado, and Jeff Dean. Distributed representations of words and phrases and their compositionality. In Advances in neural information processing systems (NIPS) , pp. 3111–3119, 2013.
Niepert et al. (2016) Mathias Niepert, Mohamed Ahmed, and Konstantin Kutzkov. Learning convolutional neural networks for graphs. In International Conference on Machine Learning (ICML) , 2016.
Perozzi et al. (2014) Bryan Perozzi, Rami Al-Rfou, and Steven Skiena. Deepwalk: Online learning of social representations. In Proceedings of the 20th ACM SIGKDD international conference on Knowledge discovery and data mining , pp. 701–710. ACM, 2014.
Scarselli et al. (2009) Franco Scarselli, Marco Gori, Ah Chung Tsoi, Markus Hagenbuchner, and Gabriele Monfardini. The graph neural network model. IEEE Transactions on Neural Networks , 20(1):61–80, 2009.
Sen et al. (2008) Prithviraj Sen, Galileo Namata, Mustafa Bilgic, Lise Getoor, Brian Galligher, and Tina Eliassi-Rad. Collective classification in network data. AI magazine , 29(3):93, 2008.
Srivastava et al. (2014) Nitish Srivastava, Geoffrey E. Hinton, Alex Krizhevsky, Ilya Sutskever, and Ruslan Salakhutdinov. Dropout: a simple way to prevent neural networks from overfitting. Journal of Machine Learning Research (JMLR) , 15(1):1929–1958, 2014.
Tang et al. (2015) Jian Tang, Meng Qu, Mingzhe Wang, Ming Zhang, Jun Yan, and Qiaozhu Mei. Line: Large-scale information network embedding. In Proceedings of the 24th International Conference on World Wide Web , pp. 1067–1077. ACM, 2015.
Weisfeiler & Lehmann (1968) Boris Weisfeiler and A. A. Lehmann. A reduction of a graph to a canonical form and an algebra arising during this reduction. Nauchno-Technicheskaya Informatsia , 2(9):12–16, 1968.
Weston et al. (2012) Jason Weston, Frédéric Ratle, Hossein Mobahi, and Ronan Collobert. Deep learning via semi-supervised embedding. In Neural Networks: Tricks of the Trade , pp. 639–655. Springer, 2012.
Yang et al. (2016) Zhilin Yang, William Cohen, and Ruslan Salakhutdinov. Revisiting semi-supervised learning with graph embeddings. In International Conference on Machine Learning (ICML) , 2016.
Zachary (1977) Wayne W. Zachary. An information flow model for conflict and fission in small groups. Journal of anthropological research , pp. 452–473, 1977.
Zhou et al. (2004) Dengyong Zhou, Olivier Bousquet, Thomas Navin Lal, Jason Weston, and Bernhard Schölkopf. Learning with local and global consistency. In Advances in neural information processing systems (NIPS) , volume 16, pp. 321–328, 2004.
Zhu et al. (2003) Xiaojin Zhu, Zoubin Ghahramani, and John Lafferty. Semi-supervised learning using gaussian fields and harmonic functions. In International Conference on Machine Learning (ICML) , volume 3, pp. 912–919, 2003.
Appendix A Relation to Weisfeiler-Lehman Algorithm
附录 A 与 Weisfeiler-Lehman 算法的关系
A neural network model for graph-structured data should ideally be able to learn representations of nodes in a graph, taking both the graph structure and feature description of nodes into account. A well-studied framework for the unique assignment of node labels given a graph and (optionally) discrete initial node labels is provided by the 1-dim Weisfeiler-Lehman (WL-1) algorithm (Weisfeiler & Lehmann 1968):
理想的图结构数据神经网络模型应能学习图中节点的表示,同时考虑图结构与节点的特征描述。给定图以及(可选的)离散初始节点标签、为节点唯一分配标签的成熟框架,由一维 Weisfeiler-Lehman(WL-1)算法提供(Weisfeiler & Lehmann 1968):
Input: Initial node coloring
Output: Final node coloring
t 0;
repeat
for do
;
;
until stable node coloring is reached;
Algorithm 1 WL-1 algorithm (Weisfeiler & Lehmann 1968)
输入: 初始节点着色
输出: 最终节点着色
t 0;
repeat
for do
;
;
until 达到稳定节点着色;
算法 1 WL-1 算法(Weisfeiler & Lehmann 1968)
Here, denotes the coloring (label assignment) of node (at iteration ) and is its set of neighboring node indices (irrespective of whether the graph includes self-connections for every node or not). is a hash function. For an in-depth mathematical discussion of the WL-1 algorithm see, e.g., Douglas 2011.
这里, 表示节点 (在第 次迭代)的着色(标签分配), 是其邻域节点下标集合(无论图是否为每个节点包含自环)。 是哈希函数。WL-1 算法的深入数学讨论见例如 Douglas 2011。
We can replace the hash function in Algorithm 1 with a neural network layer-like differentiable function with trainable parameters as follows:
我们可以把算法 1 中的哈希函数替换为带可训练参数的、类似神经网络层的可微函数,如下:
where is an appropriately chosen normalization constant for the edge . Further, we can take now to be a vector of activations of node in the neural network layer. is a layer-specific weight matrix and denotes a differentiable, non-linear activation function.
其中 是边 上适当选取的归一化常数。进一步,现在可以把 取为节点 在第 层神经网络中的激活向量。 是层特定权重矩阵, 表示可微非线性激活函数。
By choosing , where denotes the degree of node , we recover the propagation rule of our Graph Convolutional Network (GCN) model in vector form (see Eq. 2)[^5].
取 ,其中 表示节点 的度,即可恢复图卷积网络(GCN)模型的向量形式传播规则(见式 2)[^5]。
This—loosely speaking—allows us to interpret our GCN model as a differentiable and parameterized generalization of the 1-dim Weisfeiler-Lehman algorithm on graphs.
粗略地说,这使我们能把 GCN 模型解释为图上一维 Weisfeiler-Lehman 算法的可微、参数化推广。
A.1 Node Embeddings with Random Weights
A.1 随机权重下的节点嵌入
From the analogy with the Weisfeiler-Lehman algorithm, we can understand that even an untrained GCN model with random weights can serve as a powerful feature extractor for nodes in a graph. As an example, consider the following 3-layer GCN model:
由与 Weisfeiler-Lehman 算法的类比可知,即使是权重随机、未经训练的 GCN 模型,也能作为图中节点的强大特征提取器。例如,考虑如下 3 层 GCN 模型:
with weight matrices initialized at random using the initialization described in Glorot & Bengio 2010. , and are defined as in Section 3.1.
其中权重矩阵 按 Glorot & Bengio 2010 所述随机初始化。、 与 的定义同第 3.1 节。
We apply this model on Zachary’s karate club network (Zachary 1977). This graph contains 34 nodes, connected by 154 (undirected and unweighted) edges. Every node is labeled by one of four classes, obtained via modularity-based clustering (Brandes et al. 2008). See Figure 3(a) for an illustration.
我们把该模型应用于 Zachary 的空手道俱乐部网络(Zachary 1977)。该图含 34 个节点,由 154 条(无向、未加权)边连接。每个节点被标为四个类别之一,类别由基于模块度的聚类得到(Brandes et al. 2008)。示意图见图 3(a)。
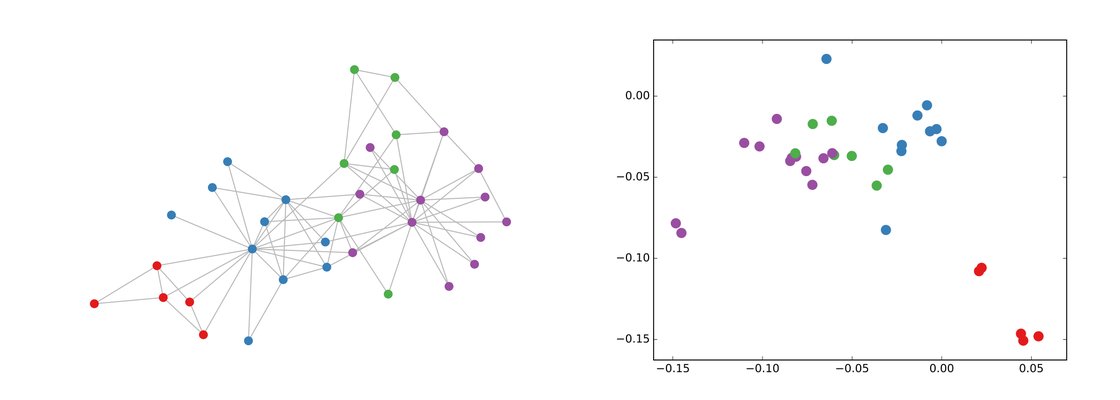
(a) Karate club network
(a) 空手道俱乐部网络
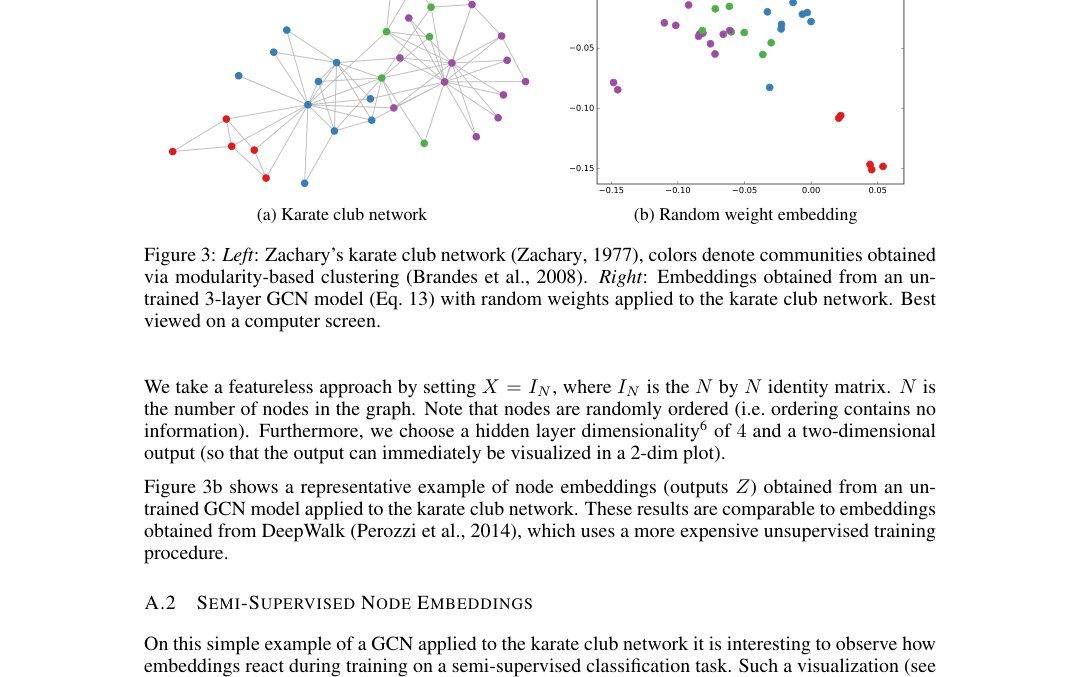
We take a featureless approach by setting , where is the by identity matrix. is the number of nodes in the graph. Note that nodes are randomly ordered (i.e. ordering contains no information). Furthermore, we choose a hidden layer dimensionality[^6] of and a two-dimensional output (so that the output can immediately be visualized in a 2-dim plot).
我们取无特征设定 ,其中 是 单位矩阵。 是图中节点数。注意节点次序是随机的(即次序不含信息)。此外,我们取隐层维数[^6]为 ,输出为二维(以便输出可直接在二维图中可视化)。
Figure 3(b) shows a representative example of node embeddings (outputs ) obtained from an untrained GCN model applied to the karate club network. These results are comparable to embeddings obtained from DeepWalk (Perozzi et al. 2014), which uses a more expensive unsupervised training procedure.
图 3(b) 展示了把未经训练的 GCN 模型应用于空手道俱乐部网络得到的节点嵌入(输出 )的一个代表性例子。这些结果可与 DeepWalk(Perozzi et al. 2014)得到的嵌入相比——后者使用更昂贵的无监督训练过程。
A.2 Semi-Supervised Node Embeddings
A.2 半监督节点嵌入
On this simple example of a GCN applied to the karate club network it is interesting to observe how embeddings react during training on a semi-supervised classification task. Such a visualization (see Figure 4) provides insights into how the GCN model can make use of the graph structure (and of features extracted from the graph structure at later layers) to learn embeddings that are useful for a classification task.
在这一把 GCN 应用于空手道俱乐部网络的简单例子上,观察半监督分类任务训练过程中嵌入如何变化很有意思。这种可视化(见图 4)有助于理解 GCN 模型如何利用图结构(以及后续层从图结构提取的特征)来学习对分类任务有用的嵌入。
We consider the following semi-supervised learning setup: we add a softmax layer on top of our model (Eq. 13) and train using only a single labeled example per class (i.e. a total number of 4 labeled nodes). We train for 300 training iterations using Adam (Kingma & Ba 2015) with a learning rate of on a cross-entropy loss.
我们考虑如下半监督学习设定:在模型(式 13)顶部加 softmax 层,每类仅用一个已标注样本训练(即共 4 个已标注节点)。我们用 Adam(Kingma & Ba 2015)、学习率 、交叉熵损失训练 300 次迭代。
Figure 4 shows the evolution of node embeddings over a number of training iterations. The model succeeds in linearly separating the communities based on minimal supervision and the graph structure alone. A video of the full training process can be found on our website[^7].
图 4 展示了若干训练迭代上节点嵌入的演化。模型仅凭极少监督与图结构本身,就成功把各社区线性分开。完整训练过程视频见我们的网站[^7]。
(a) Iteration 25
(a) 第 25 次迭代
Appendix B Experiments on Model Depth
附录 B 模型深度实验
In these experiments, we investigate the influence of model depth (number of layers) on classification performance. We report results on a 5-fold cross-validation experiment on the Cora, Citeseer and Pubmed datasets (Sen et al. 2008) using all labels. In addition to the standard GCN model (Eq. 2), we report results on a model variant where we use residual connections (He et al. 2016) between hidden layers to facilitate training of deeper models by enabling the model to carry over information from the previous layer’s input:
这些实验考察模型深度(层数)对分类表现的影响。我们在 Cora、Citeseer 与 Pubmed 数据集(Sen et al. 2008)上用全部标签做 5 折交叉验证并报告结果。除标准 GCN 模型(式 2)外,我们还报告一种变体:在隐层之间使用残差连接(He et al. 2016),以便通过让模型携带前一层输入的信息来便于训练更深模型:
On each cross-validation split, we train for 400 epochs (without early stopping) using the Adam optimizer (Kingma & Ba 2015) with a learning rate of . Other hyperparameters are chosen as follows: 0.5 (dropout rate, first and last layer), (L2 regularization, first layer), 16 (number of units for each hidden layer) and 0.01 (learning rate). Results are summarized in Figure 5.
在每个交叉验证划分上,我们用 Adam 优化器(Kingma & Ba 2015)、学习率 训练 400 个 epoch(不早停)。其他超参数如下:0.5(dropout 率,第一层与最后一层)、(L2 正则,第一层)、16(每个隐层单元数)与 0.01(学习率)。结果汇总于图 5。
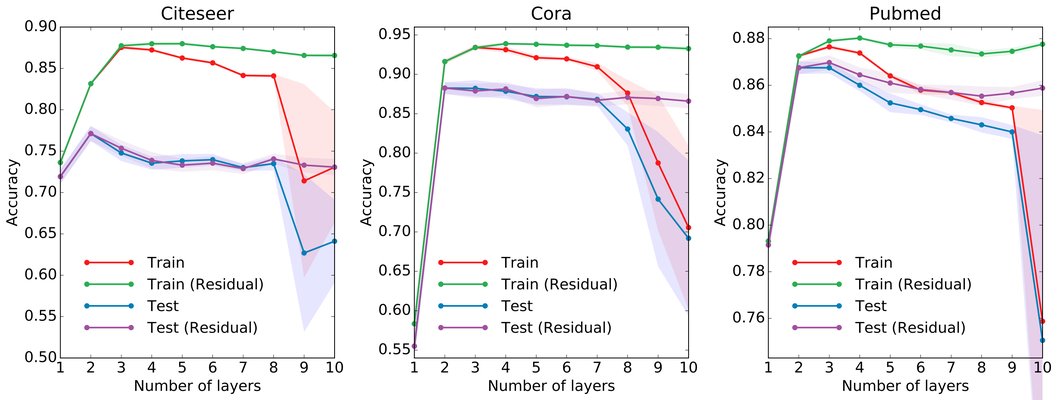
Figure 5: Influence of model depth (number of layers) on classification performance. Markers denote mean classification accuracy (training vs. testing) for 5-fold cross-validation. Shaded areas denote standard error. We show results both for a standard GCN model (dashed lines) and a model with added residual connections (He et al. 2016) between hidden layers (solid lines).
图 5:模型深度(层数)对分类表现的影响。标记表示 5 折交叉验证的平均分类精度(训练对测试)。阴影区域表示标准误差。我们同时展示标准 GCN 模型(虚线)以及在隐层之间加入残差连接(He et al. 2016)的模型(实线)的结果。
For the datasets considered here, best results are obtained with a 2- or 3-layer model. We observe that for models deeper than 7 layers, training without the use of residual connections can become difficult, as the effective context size for each node increases by the size of its -order neighborhood (for a model with layers) with each additional layer. Furthermore, overfitting can become an issue as the number of parameters increases with model depth.
对这里考虑的数据集,最好结果来自 2 层或 3 层模型。我们观察到:层数超过 7 时,若不使用残差连接,训练可能变得困难,因为对 层模型,每个节点的有效上下文大小会随每增加一层而按第 阶邻域扩大。此外,随模型加深参数增多,过拟合也可能成为问题。