Gated Attention for Large Language Models: Non-linearity, Sparsity, and Attention-Sink-Free
Gated Attention for Large Language Models: Non-linearity, Sparsity, and Attention-Sink-Free
大语言模型中的门控注意力:非线性、稀疏性与无注意力汇聚
Abstract
摘要
Gating mechanisms have been widely utilized, from early models like LSTMs (Hochreiter & Schmidhuber, 1997) and Highway Networks (Srivastava et al., 2015) to recent state space models (Gu & Dao, 2023), linear attention (Hua et al., 2022), and also softmax attention (Lin et al., 2025). Yet, existing literature rarely examines the specific effects of gating. In this work, we conduct comprehensive experiments to systematically investigate gating-augmented softmax attention variants. Specifically, we perform a comprehensive comparison over 30 variants of 15B Mixture-of-Experts (MoE) models and 1.7B dense models trained on a 3.5 trillion token dataset. Our central finding is that a simple modification—applying a head-specific sigmoid gate after the Scaled Dot-Product Attention (SDPA)—consistently improves performance. This modification also enhances training stability, tolerates larger learning rates, and improves scaling properties. By comparing various gating positions and computational variants, we attribute this effectiveness to two key factors: (1) introducing non-linearity upon the low-rank mapping in the softmax attention, and (2) applying query-dependent sparse gating scores to modulate the SDPA output. Notably, we find this sparse gating mechanism mitigates ‘attention sink’ and enhances long-context extrapolation performance, and we also release related codes and models to facilitate future research.
门控机制(gating mechanism)用途很广,从早期的 LSTM(Hochreiter & Schmidhuber, 1997)和高速公路网络(Highway Networks,Srivastava et al., 2015),到近来的状态空间模型(Gu & Dao, 2023)、线性注意力(Hua et al., 2022)以及 softmax 注意力(Lin et al., 2025)都在用。但现有文献很少考察门控本身究竟起了什么作用。本文通过大量实验,系统研究加入门控的各种 softmax 注意力变体。具体来说,我们在 3.5 万亿词元的数据集上训练了 15B 混合专家(Mixture-of-Experts, MoE)模型和 1.7B 稠密模型,对 30 多种变体做了全面比较。核心发现是一个简单的改动:*在缩放点积注意力(Scaled Dot-Product Attention, SDPA)之后加一个各头独立的 sigmoid 门,能稳定地提升性能。*这一改动还增强了训练稳定性,能承受更大的学习率,并改善扩展特性。通过比较不同的门控位置和计算方式,我们把它的效果归结为两个因素:(1)在 softmax 注意力的低秩映射上引入非线性;(2)用依赖查询(query)的稀疏门控分数调制 SDPA 输出。我们还发现,这种稀疏门控缓解了“注意力汇聚”(attention sink),并提升了长上下文外推性能。我们同时公开了相关代码和模型,以便后续研究。
1 Introduction
1 引言
Gating mechanism is well-established in neural networks. Early architectures, such as LSTMs (Hochreiter & Schmidhuber, 1997), Highway Networks (Srivastava et al., 2015) and GRUs (Dey & Salem, 2017), pioneer the use of gating to control information flow across time steps or layers and improve gradient propagation. This principle persists in modern architectures. Recent sequence modeling works, including state-space models (Gu & Dao, 2023; Dao & Gu, 2024) and attention mechanisms (Hua et al., 2022; Sun et al., 2023; Qin et al., 2024a; Yang et al., 2024b; Lin et al., 2025) commonly apply gating, often to modulate the outputs of token-mixer components. Despite its widespread adoption and empirical success, the function and impact of gating mechanisms remain insufficiently explored beyond their initial intuition.
门控机制在神经网络中早已成熟。LSTM(Hochreiter & Schmidhuber, 1997)、高速公路网络(Srivastava et al., 2015)和 GRU(Dey & Salem, 2017)等早期架构率先用门控控制信息在时间步或层之间的流动,改善梯度传播。这一原则延续到了现代架构中。近来的序列建模工作,包括状态空间模型(Gu & Dao, 2023; Dao & Gu, 2024)和注意力机制(Hua et al., 2022; Sun et al., 2023; Qin et al., 2024a; Yang et al., 2024b; Lin et al., 2025),普遍使用门控,通常用来调制词元混合(token-mixer)组件的输出。尽管门控被广泛采用、实践效果也好,人们对它的作用和影响的理解,大多仍停留在最初的直觉上。
Insufficient understanding hinders assessing gating’s true contribution, especially when confounded with other architectural factors. For instance, while Switch Heads (Csordas et al., 2024a; Csordas et al., 2024b) introduces a sigmoid gating to select top-K attention head experts, our experiments reveal an interesting finding (Appendix A.1): substantial performance gains persist even when reduced to a single expert, where the gate simply modulates the value output. This strongly suggests the gating itself provides significant intrinsic value, separate from the routing mechanism. Similarly, in Native Sparse Attention (NSA) (Yuan et al., 2025), while overall performance improvements are demonstrated, they do not disentangle the contributions of its gating mechanism from the effects of the sparse attention design itself. These considerations underscore the need to rigorously disentangle the effects of gating from other architectural components.
理解不足,就难以评估门控的真实贡献,尤其是当它和其他架构因素混在一起的时候。例如,Switch Heads(Csordas et al., 2024a; Csordas et al., 2024b)引入 sigmoid 门控来选择 top-K 个注意力头专家,而我们的实验发现了一个有意思的现象(附录 A.1):即使专家数减到一个、门只是在调制值(value)的输出,性能仍有大幅提升。这强烈说明门控本身就有很大的价值,与路由机制无关。同样,原生稀疏注意力(Native Sparse Attention, NSA)(Yuan et al., 2025)虽然展示了整体性能提升,但没有把门控机制的贡献和稀疏注意力设计本身的作用区分开。这些情况说明,有必要严格地把门控的作用从其他架构组件中剥离出来。
In this work, we investigate gating mechanisms in the standard softmax attention (Vaswani, 2017) (Sec.2.2). Specifically, we introduce gating at distinct positions (Fig. 1): after the query (), key (), and value projections (); following the Scaled Dot Product Attention (SDPA) outputs (); and after the final dense output layer (). Our exploration covers gating variants including elementwise and headwise, head-specific and head-shared, as well as additive and multiplicative forms. We find that: (i) applying SDPA output head-specific gating () yields the most significant performance improvements (e.g., up to 0.2 PPL reduction and 2 points on MMLU); (ii) the SDPA output gating also improves training stability, nearly eliminating loss spikes, enabling larger learning rates and enhancing model scalability.
本文研究标准 softmax 注意力(Vaswani, 2017)中的门控机制(第 2.2 节)。具体来说,我们在不同位置引入门控(图 1):查询投影之后()、键投影之后()、值投影之后();缩放点积注意力(SDPA)输出之后();以及最后的稠密输出层之后()。考察的门控变体包括逐元素(elementwise)与按头(headwise)、各头独立(head-specific)与跨头共享(head-shared),以及加性与乘性等形式。我们发现:(i) 在 SDPA 输出上加各头独立的门控()带来的性能提升最大(例如 PPL 最多降低 0.2,MMLU 提高 2 分);(ii) SDPA 输出门控还改善了训练稳定性,几乎消除了损失尖峰(loss spike),使模型能用更大的学习率,扩展性也更好。
We identify two primary factors contributing to the efficacy of gating: (i) Non-Linearity. The two consecutive linear layers - the value () and dense () projections - can be rewritten into one low-rank linear projection. Therefore, introducing non-linearity through gating at positions or can increase the expressiveness of this low-rank linear transformation (Sec. 4.1). (ii) Sparsity. Although non-linear gating variants consistently enhance performance, we observe that their gains vary. Our analysis further reveals that the pronounced sparsity of the gating scores is another crucial factor, introducing input-dependent sparsity to SDPA outputs (Sec. 4.2). Moreover, sparse gating eliminates the attention sink (Xiao et al., 2023): the initial tokens disproportionately dominate attention scores (Fig. 2, Sec. 4.3). Previous work (Xiao et al., 2023; Sun et al., 2024; Gu et al., 2024) explains attention sinks as an accumulation of redundant attention due to non-negative softmax normalization. Empirically, we verify that when query-dependent sparse gating is applied at the SDPA output, both our dense and MoE models (trained on 3.5T tokens) exhibit no attention sink. Furthermore, these models demonstrate superior performance in length generalization, achieving a gain of over 10 points on RULER (Hsieh et al., 2024)(Sec.4.4).
我们找出了门控起作用的两个主要因素:(i) 非线性。值投影()和稠密投影()这两个连续的线性层可以合写成一个低秩线性投影。因此,在 或 处用门控引入非线性,可以增强这一低秩线性变换的表达能力(第 4.1 节)。(ii) 稀疏性。非线性门控变体虽然都能提升性能,但提升幅度各不相同。进一步分析表明,门控分数的显著稀疏性是另一个关键因素,它给 SDPA 输出引入了依赖输入的稀疏性(第 4.2 节)。此外,稀疏门控消除了注意力汇聚(attention sink,Xiao et al., 2023),即开头几个词元不成比例地占据注意力分数的现象(图 2,第 4.3 节)。以往工作(Xiao et al., 2023; Sun et al., 2024; Gu et al., 2024)把注意力汇聚解释为:softmax 归一化要求非负,冗余的注意力因此累积下来。我们在实验中验证,当在 SDPA 输出上施加依赖查询的稀疏门控时,我们的稠密模型和 MoE 模型(都在 3.5T 词元上训练)都不再出现注意力汇聚。而且这些模型的长度泛化能力更强,在 RULER(Hsieh et al., 2024)上提升了 10 分以上(第 4.4 节)。
In summary, our work highlights the impact of gating in standard attention layers on the performance and behaviors of models. By evaluating gating variants, we uncover their ability to introduce non-linearity and sparsity, and eliminate attention sinks. These findings deepen our understanding of the mechanisms of gated attention. We will open-source our attention-sink-free models to advance future research.
总之,本文揭示了标准注意力层中的门控对模型性能和行为的影响。通过评估各种门控变体,我们发现它们能引入非线性和稀疏性,并消除注意力汇聚。这些发现加深了我们对门控注意力机制的理解。我们将开源这些没有注意力汇聚的模型,推动后续研究。
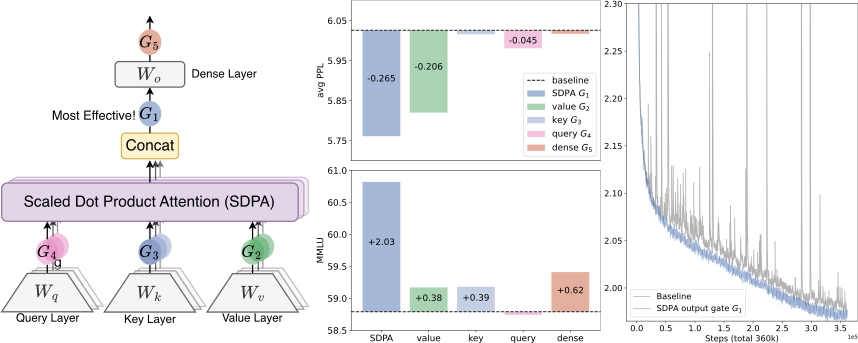
Figure 1: Left: Investigated positions for applying gating operations.; Middle: Performance comparison (Test PPL and MMLU) of 15B MoE models with gating applied at various positions. Gating after SDPA () yields the best overall results. Gating after the Value layer () also demonstrates notable improvements, particularly in PPL. Right: Training loss comparison (smoothed, 0.9 coeff.) over 3.5T tokens between baseline and SDPA-gated 1.7B dense models under identical hyperparameters. Gating results in lower final loss and substantially enhanced training stability, mitigating loss spikes. This stability allows for potentially higher learning rates and facilitates better scaling.
图 1:左:本文考察的门控施加位置。中:在不同位置施加门控的 15B MoE 模型的性能对比(测试 PPL 和 MMLU)。在 SDPA 之后加门控()整体效果最好。在值层之后加门控()也有明显提升,PPL 上尤其如此。右:在相同超参数下,基线与 SDPA 门控的 1.7B 稠密模型在 3.5T 词元上的训练损失对比(平滑系数 0.9)。门控带来更低的最终损失,训练稳定性大幅提高,损失尖峰得到缓解。这种稳定性使模型有可能使用更高的学习率,也更便于扩展。
2 Gated-Attention Layer
2 门控注意力层
2.1 Preliminary: Multi-Head Softmax Attention
2.1 预备知识:多头 softmax 注意力
Given an input , where is the sequence length and is the model dimension, the computation of transformer’s attention layer (Vaswani, 2017) could be divided into four stages.
给定输入 ,其中 是序列长度, 是模型维度,Transformer 注意力层(Vaswani, 2017)的计算可以分为四个阶段。
QKV Linear Projections:
The input is linearly transformed into queries , keys , and values using learned weight matrices and :
QKV 线性投影:
输入 经可学习的权重矩阵 线性变换,得到查询 、键 和值 ,且 :
Scaled Product Dot-Product Attention (SDPA):
computes attention scores between queries and keys, followed by a softmax normalization. The output is a weighted sum of the values:
缩放点积注意力(SDPA):
计算查询与键之间的注意力分数,再做 softmax 归一化。输出是值的加权和:
where represents the scaled dot-product similarity matrix, and ensures the attention weights are no-negative and sum to 1 across each row.
其中 是缩放后的点积相似度矩阵, 保证每一行的注意力权重非负且和为 1。
Multi-Head Concatenation:
In multi-head attention, the above process is repeated in parallel for heads, with each head having its projection matrices . All heads’ outputs are concatenated:
多头拼接:
在多头注意力中,上述过程在 个头上并行重复,每个头有自己的投影矩阵 。所有头的输出拼接起来:
where .
其中 。
Final Output Layer:
The concatenated SDPA output is passed through an output layer :
最终输出层:
拼接后的 SDPA 输出经过输出层 :
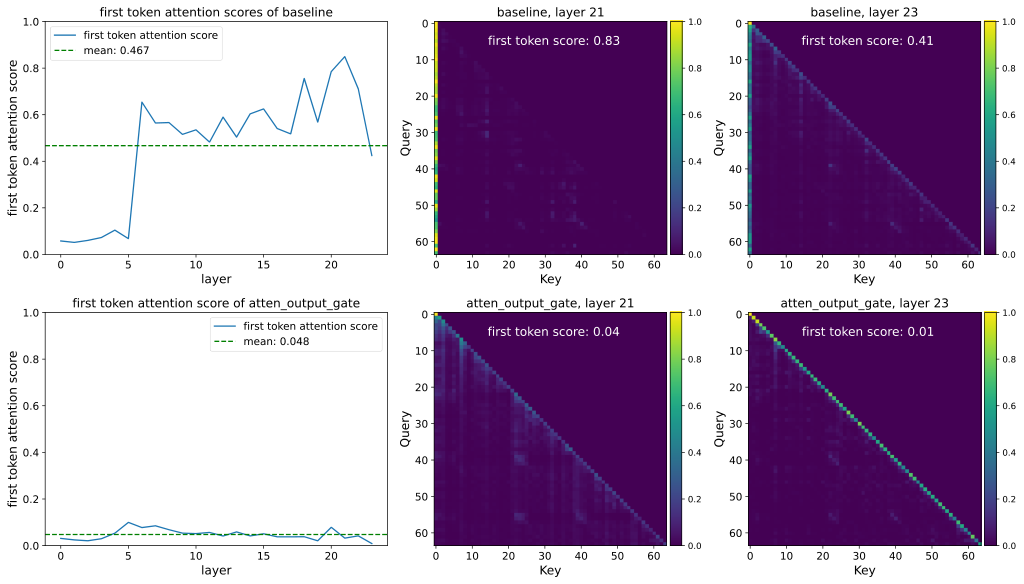
Figure 2: Left: Proportion of attention allocated to the initial token per layer (test perplexity dataset). The baseline model suffers from a significant attention sink, with an average of 46.7% of attention scores across layers directed towards the first token. Introducing a gate effectively alleviates this, reducing the proportion to 4.8%. Right: Average attention map weights for each head. Layer 21 in the baseline model demonstrates a strong attention sink (83% on the first token), which is substantially reduced by the gate (4%). In the final output layer, the gate amplifies the existing tendency for the model to attend to individual tokens within the sequence.
图 2:左:每一层分配给首个词元的注意力比例(测试困惑度数据集)。基线模型存在严重的注意力汇聚,各层平均有 46.7% 的注意力分数指向第一个词元。引入门控后,这一比例有效降到 4.8%。右:每个头的平均注意力图权重。基线模型第 21 层表现出很强的注意力汇聚(83% 落在第一个词元上),加门控后大幅降到 4%。在最后的输出层,门控放大了模型原有的倾向,即关注序列中的个别词元。
2.2 Augmenting Attention Layer with Gating Mechanisms
2.2 用门控机制增强注意力层
The gating mechanism is formalized as:
门控机制形式化为:
where is the input to be modulated, is another input used to compute the gating scores[^1], refers to the learnable parameters of gate, is an activation function (e.g., sigmoid), and is the gated output. The gating score, , effectively acts as a dynamic filter, controlling the information flow from by selectively preserving or erasing its features.
其中 是被调制的输入, 是用来计算门控分数的另一个输入[^1], 是门的可学习参数, 是激活函数(例如 sigmoid), 是门控后的输出。门控分数 相当于一个动态滤波器,通过有选择地保留或抹去 的特征来控制从 流出的信息。
[^1] We adopt the hidden states after pre-normalization as .
[^1] 我们取前置归一化之后的隐藏状态作为 。
In this work, we comprehensively investigate several variants of gating mechanisms within the attention layers. Our exploration focuses on five key aspects: (1) Positions. We study the effect of applying gating at different positions, as illustrated in Fig. 1(left): (a) after the projections (Equ. 1), corresponding to positions in Fig. 1(left); (b) following the SDPA (Equ. 3) outputs (). (c) after the final concatenated multi-head attention outputs (Equ. 4, ). (2) Granularity. We consider two levels of granularity for the gating score: (a) Headwise: A single scalar gating score modulates the entire output of an attention head. (b) Elementwise: Gating scores are vectors with the same dimensionality as , enabling fine-grained, per-dimension modulation. (3) Head Specific or Shared. Given the multi-head nature of attention, we further consider: (a) Head-Specific: each attention head has its specific gating scores, enabling independent modulation for each head. (b) Head-Shared: and gating scores are shared across heads. (4) Multiplicative or additive. For applying gating score to , we consider (a) Multiplicative Gating: The gated output is computed as: . (b) Additive Gating: (5) Activation Function. We mainly consider two common activation functions: SiLU (Shazeer, 2020) and sigmoid. We only use SiLU for additive gating due to its unbounded output range, and sigmoid only gives scores in . Additionally, to further dissect the mechanisms underlying gating’s effectiveness, we also consider Identity Mapping or RMSNorm (Zhang & Sennrich, 2019) (detailed in Sec 4.1).
本文全面考察注意力层内门控机制的几种变体,重点关注五个方面:(1) 位置。我们研究在不同位置施加门控的效果,如图 1(左)所示:(a) 在 投影之后(式 1),对应图 1(左)中的位置 ;(b) 在 SDPA 输出之后(式 3,);(c) 在最终拼接的多头注意力输出之后(式 4,)。(2) 粒度。门控分数考虑两种粒度:(a) 按头:用一个标量门控分数调制一个注意力头的全部输出。(b) 逐元素:门控分数是与 同维的向量,可以对每个维度做细粒度调制。(3) 各头独立或跨头共享。考虑到注意力的多头结构,我们进一步考虑:(a) 各头独立:每个注意力头有自己的门控分数,各头可以独立调制。(b) 跨头共享: 和门控分数在各头之间共享。(4) 乘性或加性。把门控分数作用到 上时,我们考虑 (a) 乘性门控:门控输出 按 计算。(b) 加性门控: (5) 激活函数。我们主要考虑两种常见激活函数:SiLU(Shazeer, 2020)和 sigmoid。由于 SiLU 的输出范围无界,我们只在加性门控中使用它;sigmoid 只给出 内的分数。此外,为了进一步拆解门控起作用的机制,我们还考虑了恒等映射或 RMSNorm(Zhang & Sennrich, 2019)(详见第 4.1 节)。
Unless otherwise specified, we employ head-specific, multiplicative gating utilizing the sigmoid activation function ().
除非另有说明,我们都采用各头独立、使用 sigmoid 激活函数()的乘性门控。
3 Experiments
3 实验
3.1 Experimental Setups
3.1 实验设置
Model Architecture and Training Settings
We conduct experiments on both MoE models (15B total parameters with 2.54B activated, 15A2B) and dense models (1.7B total parameters). The 15A2B MoE models utilize 128 total experts with top-8 softmax gating, fine-grained experts (Dai et al., 2024), global-batch LBL (Qiu et al., 2025), and z-loss (Zoph et al., 2022). We adopt group query attention (GQA) (Ainslie et al., 2023) for the attention part. We train the models on subsets of a 3.5T high-quality tokens, encompassing multilingual, math, and general knowledge content. The context sequence length is set to 4096. More detailed configurations, such as learning rate and batch size (bsz), will be introduced in each part. Other hyperparameters follow the default values of the AdamW optimizer. Since the parameters and flops introduced by the gating are small, the wall-time latency introduced by gating is less than 2%.
模型架构与训练设置
我们在 MoE 模型(总参数 15B,激活 2.54B,记作 15A2B)和稠密模型(总参数 1.7B)上做实验。15A2B MoE 模型共有 128 个专家,采用 top-8 softmax 门控、细粒度专家(Dai et al., 2024)、全局批次负载均衡损失(global-batch LBL,Qiu et al., 2025)和 z-loss(Zoph et al., 2022)。注意力部分采用分组查询注意力(group query attention, GQA)(Ainslie et al., 2023)。我们用一个 3.5T 高质量词元数据集的子集训练模型,内容涵盖多语言、数学和通用知识。上下文序列长度设为 4096。学习率和批大小(bsz)等更详细的配置会在各部分分别介绍。其余超参数沿用 AdamW 优化器的默认值。由于门控引入的参数量和计算量都很小,门控带来的实际运行延迟不到 2%。
Evaluation
We test the few-shots results on popular benchmarks, including Hellaswag (Zellers et al., 2019) for English, MMLU (Hendrycks et al., 2020) for general knowledge, GSM8k (Cobbe et al., 2021) for math reasoning, HumanEval (Chen et al., 2021) for coding, C-eval (Huang et al., 2024) and CMMLU (Li et al., 2023) for Chinese proficiency. We also report the perplexity (PPL) of language modeling on diverse held-out test sets, including domains like English, Chinese, Code, Math, Law, and Literature.
评测
我们在常用基准上测试少样本结果,包括英语的 Hellaswag(Zellers et al., 2019)、通用知识的 MMLU(Hendrycks et al., 2020)、数学推理的 GSM8k(Cobbe et al., 2021)、编程的 HumanEval(Chen et al., 2021),以及考察中文能力的 C-eval(Huang et al., 2024)和 CMMLU(Li et al., 2023)。我们还报告了在多个留出测试集上的语言建模困惑度(PPL),领域包括英语、中文、代码、数学、法律和文学。
| Method | Act Func | Score Shape | Added Param | Avg PPL | Hellaswag | MMLU | GSM8k | C-eval |
|---|---|---|---|---|---|---|---|---|
| Reference Baselines (Baseline uses . All methods use .) | ||||||||
| (1) Baseline | - | - | 0 | 6.026 | 73.07 | 58.79 | 52.92 | 60.26 |
| (2) | - | - | 50 | 5.979 | 73.51 | 59.78 | 52.16 | 62.26 |
| (3) | - | - | 201 | 5.953 | 73.59 | 58.45 | 53.30 | 59.67 |
| (4) Add 4 Experts | - | - | 400 | 5.964 | 73.19 | 58.84 | 52.54 | 63.19 |
| Gating Position Variants | ||||||||
| (5) SDPA Elementwise | sigmoid | 201 | 5.761 | 74.64 | 60.82 | 55.27 | 62.20 | |
| (6) v Elementwise | sigmoid | 25 | 5.820 | 74.38 | 59.17 | 53.97 | 61.00 | |
| (7) k Elementwise | sigmoid | 25 | 6.016 | 72.88 | 59.18 | 50.49 | 61.74 | |
| (8) q Elementwise | sigmoid | 201 | 5.981 | 73.01 | 58.74 | 53.97 | 62.14 | |
| (9) Dense Output | sigmoid | 100 | 6.017 | 73.32 | 59.41 | 50.87 | 59.43 | |
| Gating Granularity Variants | ||||||||
| (10) SDPA Headwise | sigmoid | 1.6 | 5.792 | 74.50 | 60.05 | 54.44 | 62.61 | |
| (11) v Headwise | sigmoid | 0.2 | 5.808 | 74.38 | 59.32 | 53.53 | 62.61 | |
| Head-Specific v.s. Head-Shared Gating | ||||||||
| (12) SDPA Head-Shared | sigmoid | 201 | 5.801 | 74.34 | 60.06 | 53.15 | 61.01 | |
| (13) v Head-Shared | sigmoid | 25 | 5.867 | 74.10 | 59.02 | 53.03 | 60.61 | |
| Multiplicative v.s. Additive | ||||||||
| (14) SDPA Additive | SiLU | 201 | 5.821 | 74.81 | 60.06 | 53.30 | 60.98 | |
| Activation Variants | ||||||||
| (15) SDPA Elementwise | SiLU | 201 | 5.822 | 74.22 | 60.49 | 54.59 | 62.34 |
Table 1: Gating variant performance and results. We train the 15A2B MoE models on 400B tokens. is the head dim, is the model’s hidden dim, and is the number of tokens. refers to the number of query heads, refers to the number of key-value heads. ‘Act Func’ is the activation function in Eq 5. ‘Score Shape’ is the gating score shape for an input . ‘added param’ indicates added parameters (Million).
| 方法 | 激活函数 | 分数形状 | 新增参数 | 平均 PPL | Hellaswag | MMLU | GSM8k | C-eval |
|---|---|---|---|---|---|---|---|---|
| 参考基线(基线使用 ,所有方法均使用 。) | ||||||||
| (1) 基线 | - | - | 0 | 6.026 | 73.07 | 58.79 | 52.92 | 60.26 |
| (2) | - | - | 50 | 5.979 | 73.51 | 59.78 | 52.16 | 62.26 |
| (3) | - | - | 201 | 5.953 | 73.59 | 58.45 | 53.30 | 59.67 |
| (4) 增加 4 个专家 | - | - | 400 | 5.964 | 73.19 | 58.84 | 52.54 | 63.19 |
| 门控位置变体 | ||||||||
| (5) SDPA 逐元素 | sigmoid | 201 | 5.761 | 74.64 | 60.82 | 55.27 | 62.20 | |
| (6) v 逐元素 | sigmoid | 25 | 5.820 | 74.38 | 59.17 | 53.97 | 61.00 | |
| (7) k 逐元素 | sigmoid | 25 | 6.016 | 72.88 | 59.18 | 50.49 | 61.74 | |
| (8) q 逐元素 | sigmoid | 201 | 5.981 | 73.01 | 58.74 | 53.97 | 62.14 | |
| (9) 稠密输出 | sigmoid | 100 | 6.017 | 73.32 | 59.41 | 50.87 | 59.43 | |
| 门控粒度变体 | ||||||||
| (10) SDPA 按头 | sigmoid | 1.6 | 5.792 | 74.50 | 60.05 | 54.44 | 62.61 | |
| (11) v 按头 | sigmoid | 0.2 | 5.808 | 74.38 | 59.32 | 53.53 | 62.61 | |
| 各头独立与跨头共享门控 | ||||||||
| (12) SDPA 跨头共享 | sigmoid | 201 | 5.801 | 74.34 | 60.06 | 53.15 | 61.01 | |
| (13) v 跨头共享 | sigmoid | 25 | 5.867 | 74.10 | 59.02 | 53.03 | 60.61 | |
| 乘性与加性 | ||||||||
| (14) SDPA 加性 | SiLU | 201 | 5.821 | 74.81 | 60.06 | 53.30 | 60.98 | |
| 激活函数变体 | ||||||||
| (15) SDPA 逐元素 | SiLU | 201 | 5.822 | 74.22 | 60.49 | 54.59 | 62.34 |
表 1:各门控变体的性能结果。我们在 400B 词元上训练 15A2B MoE 模型。 是头维度, 是模型隐藏维度, 是词元数。 指查询头数, 指键值头数。“激活函数”指式 5 中的激活函数。“分数形状”指输入为 时门控分数的形状。“新增参数”指增加的参数量(单位:百万)。
3.2 Main Results
3.2 主要结果
3.2.1 Gated Attention for MoE models
We first compare the results of different gated attention layers on the training-efficient MoE-15A2B models. All models use a scheduler that warms up to a maximum LR of 2e-3 in 1k steps and decays using cosine to 3e-5. We use a global bsz of 1024, comprising 100k optimization steps. The results are summarized in Tab. 1. To provide a fair comparison, we supplement the vanilla MoE baseline (row 1) with parameter expansion methods, including increasing the number of key-value heads (row 2), increasing the number of query heads (row 3), and increasing both the total and activated number of experts (row 4). These methods introduce a comparable or greater number of parameters than the gating mechanisms.
3.2.1 MoE 模型中的门控注意力
我们先在训练效率较高的 MoE-15A2B 模型上比较不同的门控注意力层。所有模型使用同一学习率调度:在 1k 步内预热到最大学习率 2e-3,再按余弦衰减到 3e-5。全局批大小为 1024,共 10 万个优化步。结果汇总在表 1 中。为了公平比较,我们在普通 MoE 基线(第 1 行)之外补充了几种扩充参数的方法,包括增加键值头数(第 2 行)、增加查询头数(第 3 行),以及同时增加专家总数和激活专家数(第 4 行)。这些方法引入的参数量与门控机制相当甚至更多。
From Tab. 1, we observe: (i) SDPA and value output gating are effective. Inserting gates at the output of SDPA () or the value map () is the most effective, achieving lower PPL and better overall benchmark performance than other variants. We will further investigate why gating at these two positions is effective in Sec 4.2. (ii) Head-Specific Gating Matters. Applying headwise gating at and introduces very few additional parameters (less than 2M for the MoE-15A2B model) but still delivers substantial improvements (rows 10 and 11). When sharing gating scores across different attention heads (we average over the query head dimension to obtain an score from the original ), the benchmark improvements are smaller than those achieved by headwise gating (row 12 v.s. 10, 13 v.s. 11). This underscores the importance of applying distinct gating scores for different attention heads. (iii) Multiplicative Gating is Preferred. Additive SDPA output gating underperforms the multiplicative one, although it shows improvements over the baselines. (iv) Sigmoid Activation is Better. Replacing the activation function in the most effective gating configuration (row 5) with SiLU (row 15) leads to less improvement.
从表 1 可以看到:(i) SDPA 输出门控和值输出门控有效。在 SDPA 输出()或值映射输出()处插入门最有效,PPL 比其他变体更低,基准整体表现也更好。我们将在第 4.2 节进一步研究为什么这两个位置的门控有效。(ii) 各头独立的门控很重要。在 和 处加按头门控只增加极少的参数(MoE-15A2B 模型上不到 2M),却仍带来大幅提升(第 10、11 行)。如果让不同注意力头共享门控分数(我们沿查询头维度 取平均,把原本 的分数变成 ),基准上的提升就小于按头门控(第 12 行对第 10 行,第 13 行对第 11 行)。这说明给不同注意力头施加不同的门控分数很重要。(iii) 乘性门控更好。加性 SDPA 输出门控虽然比基线有提升,但不如乘性门控。(iv) sigmoid 激活更好。把最有效配置(第 5 行)中的激活函数换成 SiLU(第 15 行),提升会变小。
Overall, adding gating at the value layer () and SDPA output () reduces PPL by more than 0.2, outperforming various parameter-expanding baselines. However, gating at achieves better PPL and benchmark results. As long as different heads receive distinct gating scores, the granularity of gating and the choice of activation function have relatively minor impacts. We will further analyze the reasons behind these observations in Analysis (Sec 4.2).
总体上,在值层()和 SDPA 输出()处加门控能把 PPL 降低 0.2 以上,优于各种扩充参数的基线。不过 处的门控在 PPL 和基准结果上都更好。只要不同的头得到各自的门控分数,门控粒度和激活函数的选择影响就相对较小。我们将在分析部分(第 4.2 节)进一步讨论这些现象的原因。
3.2.2 Gated Attention for Dense Models.
We also conduct experiments on dense models following (Yang et al., 2024a) to validate SDPA output sigmoid gating. When using gating, we reduce the width of FFN to maintain the parameter size. Most experiments use optimized hyperparameters for the baseline. For instance, for the 1.7B model trained on 400B tokens, we use a maximum LR of 4e-3 and a bsz of 1024. For training on 3.5T tokens, we increase the maximum LR to 4.5e-3 and the bsz to 2048. Prior work has established that while increased network depth, large learning rates, and large batch sizes can significantly improve model performance (McCandlish et al., 2018; Wang et al., 2022; D’Angelo et al., 2024) and distributed training efficiency, they often introduce training instabilities (Wang et al., 2022; Zeng et al., 2022; Takase et al., 2023). We observe that applying gating mechanisms demonstrably reduces the occurrence of loss spikes during training (Chowdhery et al., 2023; Takase et al., 2023), suggesting a promising role for gating in enhancing training stability. Motivated by this finding, we introduce another experimental setting characterized by an increased number of layers, a higher maximum learning rate, and a larger batch size to further probe gating’s stabilizing effects.
3.2.2 稠密模型中的门控注意力
我们还参照 Yang et al.(2024a)在稠密模型上做实验,验证 SDPA 输出 sigmoid 门控的效果。使用门控时,我们缩小 FFN 的宽度,使参数量保持不变。大部分实验使用为基线调优过的超参数。例如,在 400B 词元上训练的 1.7B 模型,最大学习率为 4e-3,批大小为 1024。在 3.5T 词元上训练时,最大学习率提高到 4.5e-3,批大小提高到 2048。已有工作表明,更深的网络、更大的学习率和更大的批大小能显著提升模型性能(McCandlish et al., 2018; Wang et al., 2022; D’Angelo et al., 2024)和分布式训练效率,但往往会带来训练不稳定(Wang et al., 2022; Zeng et al., 2022; Takase et al., 2023)。我们观察到,使用门控机制明显减少了训练中的损失尖峰(Chowdhery et al., 2023; Takase et al., 2023),这表明门控有望增强训练稳定性。受此启发,我们另设了一组实验,增加层数、提高最大学习率、加大批大小,进一步考察门控的稳定作用。
| Method | Max LR | Avg PPL | HumanEval | MMLU | GSM8k | Hellaswag | C-eval | CMMLU |
|---|---|---|---|---|---|---|---|---|
| 28 Layer, 1.7B Parameters, 400B Tokens, Batch Size=1024 | ||||||||
| (1) Baseline | 7.499 | 28.66 | 50.21 | 27.82 | 64.94 | 49.15 | 49.52 | |
| (2) SDPA Elementwise | 7.404 | 29.27 | 51.15 | 28.28 | 65.48 | 50.72 | 50.72 | |
| 28 Layer, 1.7B Parameters, 3.5T Tokens, Batch Size=2048 | ||||||||
| (3) Baseline | 6.180 | 34.15 | 59.10 | 69.07 | 68.02 | 68.19 | 64.95 | |
| (4) SDPA Elementwise | 6.130 | 37.80 | 59.61 | 70.20 | 68.84 | 68.52 | 65.76 | |
| 48 Layer, 1.7B Parameters, 400B Tokens, Batch Size=1024 | ||||||||
| (5) Baseline | 7.421 | 28.05 | 52.04 | 32.98 | 65.96 | 51.11 | 51.86 | |
| (6) Baseline | 9.195 | 21.34 | 44.28 | 15.24 | 57.00 | 43.11 | 42.63 | |
| (7) Baseline+Sandwich Norm | 7.407 | 30.49 | 52.07 | 32.90 | 66.00 | 52.04 | 51.72 | |
| (8) SDPA Elementwise | 7.288 | 31.71 | 52.44 | 32.37 | 66.28 | 52.06 | 52.29 | |
| (9) SDPA Headwise | 7.370 | 31.10 | 53.83 | 34.12 | 65.59 | 55.07 | 52.38 | |
| (10) SDPA Elementwise | 7.325 | 31.10 | 54.47 | 36.62 | 66.40 | 53.91 | 53.80 | |
| 48 Layer, 1.7B Parameters, 1T Tokens, Batch Size=4096 | ||||||||
| (11) Baseline | 7.363 | 29.88 | 54.44 | 32.22 | 65.43 | 53.72 | 53.37 | |
| (12) Baseline | - | - | - | - | - | - | - | |
| (13) SDPA Elementwise | 7.101 | 34.15 | 55.70 | 36.69 | 67.17 | 54.51 | 54.68 | |
| (14) SDPA Elementwise | 7.078 | 31.71 | 56.47 | 39.73 | 67.38 | 55.52 | 55.77 |
Table 2: Performance of different methods with varying learning rates, batch sizes, and model configurations. ‘SDPA’ refers to the sigmoid gating after SDPA in Eq 3, and ‘sandwitch norm’ (Ding et al., 2021) indicates normalizing attention/ffn outputs before adding them to the residual. When using gating, we reduce the FFN’s width so that all methods have the same number of parameters. ‘-’ means the model diverges during training.
| 方法 | 最大学习率 | 平均 PPL | HumanEval | MMLU | GSM8k | Hellaswag | C-eval | CMMLU |
|---|---|---|---|---|---|---|---|---|
| 28 层,1.7B 参数,400B 词元,批大小 = 1024 | ||||||||
| (1) 基线 | 7.499 | 28.66 | 50.21 | 27.82 | 64.94 | 49.15 | 49.52 | |
| (2) SDPA 逐元素 | 7.404 | 29.27 | 51.15 | 28.28 | 65.48 | 50.72 | 50.72 | |
| 28 层,1.7B 参数,3.5T 词元,批大小 = 2048 | ||||||||
| (3) 基线 | 6.180 | 34.15 | 59.10 | 69.07 | 68.02 | 68.19 | 64.95 | |
| (4) SDPA 逐元素 | 6.130 | 37.80 | 59.61 | 70.20 | 68.84 | 68.52 | 65.76 | |
| 48 层,1.7B 参数,400B 词元,批大小 = 1024 | ||||||||
| (5) 基线 | 7.421 | 28.05 | 52.04 | 32.98 | 65.96 | 51.11 | 51.86 | |
| (6) 基线 | 9.195 | 21.34 | 44.28 | 15.24 | 57.00 | 43.11 | 42.63 | |
| (7) 基线 + 三明治归一化 | 7.407 | 30.49 | 52.07 | 32.90 | 66.00 | 52.04 | 51.72 | |
| (8) SDPA 逐元素 | 7.288 | 31.71 | 52.44 | 32.37 | 66.28 | 52.06 | 52.29 | |
| (9) SDPA 按头 | 7.370 | 31.10 | 53.83 | 34.12 | 65.59 | 55.07 | 52.38 | |
| (10) SDPA 逐元素 | 7.325 | 31.10 | 54.47 | 36.62 | 66.40 | 53.91 | 53.80 | |
| 48 层,1.7B 参数,1T 词元,批大小 = 4096 | ||||||||
| (11) 基线 | 7.363 | 29.88 | 54.44 | 32.22 | 65.43 | 53.72 | 53.37 | |
| (12) 基线 | - | - | - | - | - | - | - | |
| (13) SDPA 逐元素 | 7.101 | 34.15 | 55.70 | 36.69 | 67.17 | 54.51 | 54.68 | |
| (14) SDPA 逐元素 | 7.078 | 31.71 | 56.47 | 39.73 | 67.38 | 55.52 | 55.77 |
表 2:不同方法在不同学习率、批大小和模型配置下的性能。“SDPA”指式 3 中 SDPA 之后的 sigmoid 门控,“三明治归一化”(sandwich norm,Ding et al., 2021)指注意力和 FFN 的输出在加入残差之前先做归一化。使用门控时,我们缩小 FFN 的宽度,使所有方法的参数量相同。“-”表示模型在训练中发散。
Tab. 2 reveals that: (i) Gating is effective across various settings Across various model configurations (row 1 v.s. 2, 5 v.s. 8), training data (row 3 v.s. 4), and hyperparameters (row 11 v.s. 13), applying SDPA output gating consistently yields benefits. (ii) Gating improves stability and facilitates scaling. Under the 3.5T token setting, gating improves training stability, largely reducing the loss spike (Fig. 1, right). When increasing the maximum LR, baselines encounter convergence issues (row 6, 12). While adding sandwich norm (Ding et al., 2021) restores convergence, the improvement is negligible. In contrast, increasing the maximum LR in models with gating results in a noticeable improvement.
表 2 显示:(i) 门控在各种设置下都有效。在不同的模型配置(第 1 行对第 2 行,第 5 行对第 8 行)、训练数据(第 3 行对第 4 行)和超参数(第 11 行对第 13 行)下,SDPA 输出门控都稳定地带来收益。(ii) 门控提高稳定性,有利于扩展。在 3.5T 词元设置下,门控提高了训练稳定性,大幅减少了损失尖峰(图 1 右)。提高最大学习率时,基线出现收敛问题(第 6、12 行)。加入三明治归一化(Ding et al., 2021)虽然能恢复收敛,但提升可以忽略。相比之下,带门控的模型提高最大学习率后有明显提升。
In summary, we identify SDPA element-wise gating as the most effective method to augment the attention mechanism. Applying this method to dense transformers further demonstrates that the gate enables stable training with larger batch sizes and learning rates, resulting in improved performance.
总之,我们认定 SDPA 逐元素门控是增强注意力机制最有效的方法。把它用到稠密 Transformer 上进一步表明,门控使模型能在更大的批大小和学习率下稳定训练,从而提升性能。
4 Analysis: Non-Linearity, Sparsity, and Attention-Sink-Free
4 分析:非线性、稀疏性与无注意力汇聚
In this section, we conduct a series of experiments to explore why such a simple gating mechanism can yield significant improvements in performance and training stability. Here are the takeaways according to our analysis: (1) Gating operations enhancing non-linearity consistently lead to performance gains (Sec 4.1); (2) The most effective SDPA elementwise gate introduces strong input-dependent sparsity to the SDPA outputs (Sec 4.2), which then helps to eliminate the ‘attention sink’ phenomenon.
本节通过一系列实验,探究为什么如此简单的门控机制能显著提升性能和训练稳定性。分析的要点如下:(1)增强非线性的门控操作都能带来性能提升(第 4.1 节);(2)最有效的 SDPA 逐元素门 给 SDPA 输出引入了很强的、依赖输入的稀疏性(第 4.2 节),这又有助于消除“注意力汇聚”现象。
4.1 Non-linearity Improves the Expressiveness of Low-Rank Mapping in Attention
4.1 非线性增强了注意力中低秩映射的表达能力
| Method | Activation Function | Avg PPL | Hellaswag | MMLU | GSM8k | C-eval |
|---|---|---|---|---|---|---|
| (1) Baseline | - | 6.026 | 73.07 | 58.79 | 52.92 | 60.26 |
| (2) SDPA Elementwise Gate | Sigmoid | 5.761 | 74.64 | 60.82 | 55.27 | 62.20 |
| (3) v Elementwise Gate | Sigmoid | 5.820 | 74.38 | 59.17 | 53.97 | 61.00 |
| (4) SDPA Additive Gate | SiLU | 5.821 | 74.81 | 60.06 | 53.30 | 60.98 |
| (5) SDPA GroupNorm | RMSNorm | 5.847 | 74.10 | 60.15 | 53.75 | 61.14 |
| (6) SDPA SiLU | SiLU | 5.975 | 73.34 | 59.55 | 53.19 | 60.90 |
| (7) SDPA Additive Gate | Identity | 5.882 | 74.17 | 59.20 | 52.77 | 59.86 |
Table 3: Performance of different (non)-linearity augmentations.
| 方法 | 激活函数 | 平均 PPL | Hellaswag | MMLU | GSM8k | C-eval |
|---|---|---|---|---|---|---|
| (1) 基线 | - | 6.026 | 73.07 | 58.79 | 52.92 | 60.26 |
| (2) SDPA 逐元素门控 | Sigmoid | 5.761 | 74.64 | 60.82 | 55.27 | 62.20 |
| (3) v 逐元素门控 | Sigmoid | 5.820 | 74.38 | 59.17 | 53.97 | 61.00 |
| (4) SDPA 加性门控 | SiLU | 5.821 | 74.81 | 60.06 | 53.30 | 60.98 |
| (5) SDPA 组归一化 | RMSNorm | 5.847 | 74.10 | 60.15 | 53.75 | 61.14 |
| (6) SDPA SiLU | SiLU | 5.975 | 73.34 | 59.55 | 53.19 | 60.90 |
| (7) SDPA 加性门控 | 恒等 | 5.882 | 74.17 | 59.20 | 52.77 | 59.86 |
表 3:不同(非)线性增强方式的性能。
Inspired by prior works that utilize group norm for the SDPA output (Sun et al., 2023; Ye et al., 2024), with the same setting in Sec. 3.2.1, we apply RMSNorm (Zhang & Sennrich, 2019) independently to the output of each attention head before concatenation. As shown in Tab. 3 row 5, applying RMSNorm, which introduces almost no additional parameters, also leads to a significant reduction in PPL.
一些已有工作对 SDPA 输出使用组归一化(Sun et al., 2023; Ye et al., 2024)。受此启发,我们沿用第 3.2.1 节的设置,在拼接之前对每个注意力头的输出分别施加 RMSNorm(Zhang & Sennrich, 2019)。如表 3 第 5 行所示,RMSNorm 几乎不引入额外参数,同样能显著降低 PPL。
In multi-head attention, the output of the -th token, corresponding to the -th head, can be expressed as:
在多头注意力中,第 个词元在第 个头上的输出可以写成:
where is the parameters of the output layer corresponding to the -th head[^2]. Here, denotes the attention score of the -th token attending to the -th token in the -th head, is the input to the attention for token , and represents the value output of token in the -th head. From Equ. 6, we can merge into one low-rank linear mapping applied over all as . With GQA, is shared among heads within the same group, further diminishing the expressiveness.
其中 是输出层 中对应第 个头的参数[^2]。 表示第 个头中第 个词元对第 个词元的注意力分数, 是词元 的注意力输入, 是词元 在第 个头上的值输出。由式 6 可知,由于 ,可以把 合并成一个作用于所有 的低秩线性映射。使用 GQA 时,同一组内的各头共享 ,表达能力进一步减弱。
[^2] Note that concatenating outputs from different heads and then multiplying with is equivalent to multiplying each head’s output with its corresponding before concatenation
[^2] 注意,先把各头的输出拼接再乘以 ,等价于在拼接之前把每个头的输出乘以对应的 。
Given that adding non-linearity between two linear mappings can improve their expensiveness (Montufar et al., 2014), we have two modifications to mitigate the low-rank problem:
在两个线性映射之间加入非线性可以提高它们的表达能力(Montufar et al., 2014),据此我们有两种缓解低秩问题的改法:
Notably, adding gating at the (Tab. 3 row 3) position corresponds to the first modification (Equ. 7), while adding gating (row 4) or group normalization (row 5) at the position corresponds to the second (Equ. 8). This also explains why adding gating or normalization at the position after has no effect (Tab. 1 row 9) — it does not address the lack of non-linearity between and .
在 位置加门控(表 3 第 3 行)对应第一种改法(式 7),在 位置加门控(第 4 行)或组归一化(第 5 行)对应第二种(式 8)。这也解释了为什么在 之后的 位置加门控或归一化没有效果(表 1 第 9 行):它没有解决 与 之间缺少非线性的问题。
For additive gating at , the output of gating passes through SiLU (Tab. 3 row 4), also introducing some non-linearity, which explains the observed performance gains, albeit smaller than those achieved by multiplicative gating. Based on these insights, we conduct two additional experiments: (i) Adding SiLU only at the position without introducing additional parameters (Tab. 3 row 6). Notice this simple modification also leads to a modest reduction in PPL, but most benchmark scores remain unchanged. (ii) Removing SiLU from additive gating, such that the output of after gating is directly added at the position (Tab. 3 row 7). This further diminishes the gains of addictive gating.
对于 处的加性门控,门控输出要经过 SiLU(表 3 第 4 行),同样引入了一定的非线性,这解释了观察到的性能提升,只是提升小于乘性门控。基于这些认识,我们又做了两个实验:(i) 只在 位置加 SiLU,不引入额外参数(表 3 第 6 行)。这一简单改动也让 PPL 小幅下降,但大部分基准分数没有变化。(ii) 去掉加性门控中的 SiLU,使 经门控后的输出直接加到 位置(表 3 第 7 行)。这进一步削弱了加性门控的收益。
In summary, the enhanced performance associated with effective gating variants is likely attributable to the introduction of non-linearity between and . Although applying gating at positions and can can both introduce this non-linearity, these applications yield differing performance gains. This observed difference motivates us to further analyze the impacts of gating at these two positions.
总之,有效的门控变体之所以提升性能,很可能是因为在 和 之间引入了非线性。在 和 位置加门控虽然都能引入这种非线性,带来的性能提升却不同。这一差异促使我们进一步分析这两个位置的门控各有什么影响。
4.2 Gating Introduces Input-Dependent Sparsity
4.2 门控引入依赖输入的稀疏性
We analyze the gating scores (Tab. 1, ‘Gate Score’ column) of models with gating applied at the value () and SDPA output () positions, evaluated on the test language modeling data. The mean gating scores for all layers are presented in Table 4, with the score distributions visualized in Fig. 3 (layer-wise scores in Appendix A.2). Key observations include:
我们在语言建模测试数据上,分析在值()和 SDPA 输出()位置加门控的模型的门控分数(表 1“门控分数”列)。表 4 给出所有层的平均门控分数,图 3 展示分数分布(逐层分数见附录 A.2)。主要观察如下:
(i) Effective Gating Scores are Sparse. SDPA output gatings (Element/head-wise) exhibit the lowest mean gating scores. Furthermore, the SDPA output gating score distribution shows a high concentration near 0, indicating substantial sparsity, consistent with its superior performance. (ii) Head-Specific Sparsity Matters. Enforcing shared gating scores across attention heads increases the overall gating scores and diminishes performance gains. Observations (i) and (ii) underscore the importance of head-specific gating, aligning with previous research demonstrating that individual attention heads capture distinct aspects of the input (Voita et al., 2019; Wang et al., 2021; Olsson et al., 2022; Wang et al., 2023).
(i) 有效的门控分数是稀疏的。SDPA 输出门控(逐元素和按头)的平均门控分数最低。此外,SDPA 输出门控分数的分布高度集中在 0 附近,说明稀疏性很强,这与它最好的性能相符。(ii) 各头独立的稀疏性很重要。强制各注意力头共享门控分数,会使整体门控分数升高,性能提升减小。观察 (i) 和 (ii) 说明了各头独立门控的重要性,这与以往研究的结论一致:不同的注意力头捕捉输入的不同方面(Voita et al., 2019; Wang et al., 2021; Olsson et al., 2022; Wang et al., 2023)。
| Method | Act-Func | Gate Score | M-Act | F-Attn | PPL | Hellaswag | MMLU | GSM8k |
|---|---|---|---|---|---|---|---|---|
| (1) Baseline | - | - | 1053 | 0.467 | 6.026 | 73.07 | 58.79 | 52.92 |
| (2) SDPA Elementwise Gate | Sigmoid | 0.116 | 94 | 0.048 | 5.761 | 74.64 | 60.82 | 55.27 |
| (3) SDPA Headwise Gate | Sigmoid | 0.172 | 98 | 0.073 | 5.792 | 74.50 | 60.05 | 54.44 |
| (4) SDPA Elementwise Head-shared Gate | Sigmoid | 0.271 | 286 | 0.301 | 5.801 | 74.34 | 60.06 | 53.15 |
| (5) v Elementwise Gate | Sigmoid | 0.221 | 125 | 0.297 | 5.820 | 74.38 | 59.17 | 51.33 |
| (6) SDPA Input Independent Gate | Sigmoid | 0.335 | 471 | 0.364 | 5.917 | 73.64 | 59.02 | 52.40 |
| (7) SDPA Elementwise Gate | NS-sigmoid | 0.653 | 892 | 0.451 | 5.900 | 74.05 | 60.05 | 52.75 |
Table 4: Performance of different gating methods with varying activation functions and average gate scores. ‘Act-Func’ refers to the activation function used for computing the gating scores, while ‘M-Act’ denotes the rounded maximum activation values of the hidden states output by each layer of the model. Additionally, ‘F-Attn’ represents the attention score of the first token, with higher values indicating more pronounced ‘attention sink’.
| 方法 | 激活函数 | 门控分数 | M-Act | F-Attn | PPL | Hellaswag | MMLU | GSM8k |
|---|---|---|---|---|---|---|---|---|
| (1) 基线 | - | - | 1053 | 0.467 | 6.026 | 73.07 | 58.79 | 52.92 |
| (2) SDPA 逐元素门控 | Sigmoid | 0.116 | 94 | 0.048 | 5.761 | 74.64 | 60.82 | 55.27 |
| (3) SDPA 按头门控 | Sigmoid | 0.172 | 98 | 0.073 | 5.792 | 74.50 | 60.05 | 54.44 |
| (4) SDPA 逐元素跨头共享门控 | Sigmoid | 0.271 | 286 | 0.301 | 5.801 | 74.34 | 60.06 | 53.15 |
| (5) v 逐元素门控 | Sigmoid | 0.221 | 125 | 0.297 | 5.820 | 74.38 | 59.17 | 51.33 |
| (6) SDPA 输入无关门控 | Sigmoid | 0.335 | 471 | 0.364 | 5.917 | 73.64 | 59.02 | 52.40 |
| (7) SDPA 逐元素门控 | NS-sigmoid | 0.653 | 892 | 0.451 | 5.900 | 74.05 | 60.05 | 52.75 |
表 4:使用不同激活函数的门控方法的性能及平均门控分数。“激活函数”指计算门控分数所用的激活函数,“M-Act”指模型每层输出隐藏状态的最大激活值(取整)。“F-Attn”指首个词元得到的注意力分数,数值越高,“注意力汇聚”越明显。
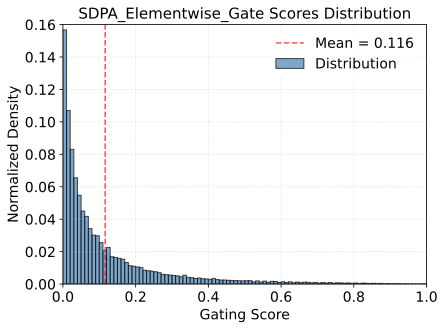
Figure 3: Gating score means and distributions for SDPA elementwise (Left), value Elementwise (Middle), and SDPA elementwise with head-shared gating (Right). Most gating scores are less than 0.5, indicating that the gating scores are sparse. Among them, the SDPA output gating score exhibits the strongest sparsity.
图 3:SDPA 逐元素门控(左)、值逐元素门控(中)和跨头共享的 SDPA 逐元素门控(右)的门控分数均值与分布。大部分门控分数小于 0.5,说明门控分数是稀疏的。其中 SDPA 输出门控分数的稀疏性最强。
(iii) Query-Dependency Matters. The scores for value gating () are higher than those for SDPA output gating (), and the performance is inferior. This suggests that gating score sparsity is more effective when query-dependent rather than determined by the key and value. Specifically, SDPA output gating scores are derived from the hidden states corresponding to the current query (e.g. the Non-Linearity-Map in Eq 8 depends on ), whereas value gating scores are derived from hidden states associated with past keys and values (e.g. the Non-Linearity-Map in Eq 7 depends on each ). This implies that gating score sparsity may filter out irrelevant contextual information for the query. To further validate the importance of query-dependency, we introduce input-independent gating by zero-initializing learnable parameters (), applying a sigmoid function, and multiplying it with the SDPA output. As shown in row (6), input-independent gating improves upon the baseline, likely due to the introduction of non-linearity. Moreover, the high gating scores reinforce that effective sparsity should be input-dependent.
(iii) 依赖查询很重要。值门控()的分数高于 SDPA 输出门控(),性能也更差。这说明门控分数的稀疏性由查询决定时,比由键和值决定时更有效。具体来说,SDPA 输出门控分数来自当前查询对应的隐藏状态(例如式 8 中的 Non-Linearity-Map 取决于 ),而值门控分数来自过去的键和值对应的隐藏状态(例如式 7 中的 Non-Linearity-Map 取决于每个 )。这意味着门控分数的稀疏性可能替查询过滤掉了无关的上下文信息。为了进一步验证依赖查询的重要性,我们引入了与输入无关的门控:把一组可学习参数()初始化为零,经过 sigmoid 函数后与 SDPA 输出相乘。如第 (6) 行所示,输入无关的门控比基线有所改进,这很可能是因为引入了非线性。同时,它的门控分数较高,进一步说明有效的稀疏性应当依赖输入。
(iv) Less Sparse Gating is Worse. To further validate the importance of gating score sparsity, we reduce sparsity from the gating formulation. Specifically, we replace the sigmoid function with a modified Non-Sparse (NS) version:
(iv) 稀疏性越弱,门控越差。为了进一步验证门控分数稀疏性的重要性,我们在门控公式中削弱稀疏性。具体做法是把 sigmoid 函数换成一个修改后的非稀疏(Non-Sparse, NS)版本:
which constrains the gating scores between [0.5, 1.0]. This ensures introducing non-linearity while removing gating score sparsity. As shown in Tab. 4 row (7), the gains of NS-sigmoid gating are inferior to those of SDPA output sigmoid gating. In Appendix A.2, we provide a more detailed discussion on how sparse gating scores affect the sparsity (the proportion of values below the threshold) in SDPA hidden states. We will discuss the impact of different sparsity levels on model behavior, including reducing the ‘attention sink’, in the next section.
它把门控分数限制在 [0.5, 1.0] 之间。这样既保留了非线性,又去掉了门控分数的稀疏性。如表 4 第 (7) 行所示,NS-sigmoid 门控的收益不如 SDPA 输出 sigmoid 门控。附录 A.2 更详细地讨论了稀疏的门控分数如何影响 SDPA 隐藏状态的稀疏度(低于阈值的值所占比例)。下一节将讨论不同稀疏程度对模型行为的影响,包括减轻“注意力汇聚”。
4.3 SDPA Output Gating Reduces Attention-Sink
4.3 SDPA 输出门控减轻注意力汇聚
Based on the observation that gating introduces sparsity to the SDPA output in an input-dependent manner, we hypothesized that this mechanism can filter out context irrelevant to the current query token, thereby mitigating the attention sink (Xiao et al., 2023; Sun et al., 2024). To verify this, we analyze the distribution of attention scores (averaged over all heads) and the proportion of attention scores allocated to the first token (Fig. 2, Tab. 4, ‘F-Attn’ column). Inspired by the discussion about massive activation in hidden states and attention sinks (Sun et al., 2024), we also compute the mean of the maximum hidden state activations across layers, as shown in the ‘M-Act’ column of Tab. 4. More detailed layer-wise results are provided in the Appendix A.3.
既然门控以依赖输入的方式给 SDPA 输出引入稀疏性,我们推测这一机制能过滤掉与当前查询词元无关的上下文,从而减轻注意力汇聚(Xiao et al., 2023; Sun et al., 2024)。为了验证这一点,我们分析了注意力分数的分布(所有头的平均)以及分配给首个词元的注意力比例(图 2,表 4“F-Attn”列)。Sun et al.(2024)讨论过隐藏状态中的巨量激活(massive activation)与注意力汇聚的关系,受此启发,我们还计算了各层隐藏状态最大激活的均值,见表 4“M-Act”列。更详细的逐层结果见附录 A.3。
We can observe: (i) Head-wise and element-wise query-dependent sigmoid gating at the SDPA output () largely reduces the attention score allocated to the first token and decreases massive activations. (ii) Enforcing shared gating scores across heads or applying gating only after the value projection () decreases massive activations, but does not reduce attention scores to the first token. This reinforces the importance of head-specific gating and suggests that massive activations are not a prerequisite for attention sinks. (iii) Reducing the input-dependence of gating (row 6) or using NS-sigmoid to reduce sparsity (row 7) intensifies both massive activations and attention sink.
可以看到:(i) 在 SDPA 输出()上施加按头和逐元素、依赖查询的 sigmoid 门控,大幅减少了分配给首个词元的注意力分数,也降低了巨量激活。(ii) 强制各头共享门控分数,或只在值投影之后()加门控,能降低巨量激活,但不能减少首个词元得到的注意力分数。这进一步说明了各头独立门控的重要性,也表明巨量激活并不是注意力汇聚的前提。(iii) 削弱门控对输入的依赖(第 6 行)或用 NS-sigmoid 削弱稀疏性(第 7 行),都会加剧巨量激活和注意力汇聚。
Collectively, these observations indicate that input-dependent, head-specific gating of the SDPA output introduces significant sparsity, thereby mitigating the attention sink. Furthermore, sparsity in the SDPA outputs reduces massive activations within the model, with increased sparsity leading to smaller activations. This may explain the improved training stability with gating: by reducing massive activations, the model is less susceptible to numerical errors during BF16 training (Budzinskiy et al., 2025). We also observe that massive activations originate primarily from early layers (e.g., layer 5), where the FFN outputs large values, consistent with (Yona et al., 2025). Once added to the residual stream, these activations are propagated through subsequent layers via the pre-norm mechanism. This aligns with the effectiveness of sandwich normalization (Ding et al., 2021) in enhancing training stability (Table 2, row 7): applying LayerNorm to the FFN output prevents these large activations from entering the residual stream.
综合来看,这些观察表明,*对 SDPA 输出施加依赖输入、各头独立的门控,会引入显著的稀疏性,从而减轻注意力汇聚。*此外,SDPA 输出的稀疏性降低了模型内部的巨量激活,稀疏性越强,激活越小。*这或许能解释门控为什么改善了训练稳定性:巨量激活减少后,模型在 BF16 训练中更不容易受数值误差影响(Budzinskiy et al., 2025)。*我们还观察到,巨量激活主要源于靠前的层(例如第 5 层),那里的 FFN 输出很大的值,这与 Yona et al.(2025)的发现一致。这些激活一旦加入残差流,就会经由前置归一化(pre-norm)机制传到后续各层。这也与三明治归一化(Ding et al., 2021)提升训练稳定性的效果吻合(表 2 第 7 行):对 FFN 输出施加 LayerNorm,可以阻止这些大激活进入残差流。
4.4 SDPA Output Gating Facilitates Context Length Extension
4.4 SDPA 输出门控有利于扩展上下文长度
| Method | 4k | 8k | 16k | 32k | 64k | 128k |
|---|---|---|---|---|---|---|
| Baseline | 88.89 | 85.88 | 83.15 | 79.50 | - | - |
| SDPA-Gate | 90.56 | 87.11 | 84.61 | 79.77 | - | - |
| YaRN Extended | ||||||
| Baseline | 82.90(-6.0) | 71.52(-14.4) | 61.23(-21.9) | 37.94(-41.56) | 37.51 | 31.65 |
| SDPA-Gate | 88.13(-2.4) | 80.01(-7.1) | 76.74(-7.87) | 72.88(-6.89) | 66.60 | 58.82 |
Table 5: Performance of different methods across varying sequence lengths. ‘YaRN Extended’ indicates the expanded context length variant. ‘(values)’ indicate the performance declines after extending the context length.
| 方法 | 4k | 8k | 16k | 32k | 64k | 128k |
|---|---|---|---|---|---|---|
| 基线 | 88.89 | 85.88 | 83.15 | 79.50 | - | - |
| SDPA 门控 | 90.56 | 87.11 | 84.61 | 79.77 | - | - |
| YaRN 扩展 | ||||||
| 基线 | 82.90(-6.0) | 71.52(-14.4) | 61.23(-21.9) | 37.94(-41.56) | 37.51 | 31.65 |
| SDPA 门控 | 88.13(-2.4) | 80.01(-7.1) | 76.74(-7.87) | 72.88(-6.89) | 66.60 | 58.82 |
表 5:不同方法在不同序列长度上的性能。“YaRN 扩展”指扩展了上下文长度的变体。括号中的数值表示扩展上下文长度后的性能下降。
Based on the attention-sink-free pattern, we evaluate the SDPA gating’s effect in the long-context setting. Specifically, we extend the context length for the models trained on 3.5T tokens. We increase the RoPE (Su et al., 2024) base from 10k to 1M and continue training on data with a sequence length of 32k for an additional 80B tokens. This gives us models with a context length of 32k. Subsequently, we use YaRN (Peng et al., 2023) to extend the context length to 128k. We evaluate models on the RULER benchmark (Hsieh et al., 2024) and summarize results in Tab. 5. We observe the following: (i) Under the 32k setting, models with gating slightly outperform the baseline. This suggests that within the training length, the attention sink phenomenon may not hurt the model’s long-context performance. (ii) When the context length is extended to 128k using YaRN, both the baseline and gated models experience a decline within the original 32k range. This observation is consistent with previous works on extending context length by modifying RoPE (Chen et al., 2023; Peng et al., 2023; Dong et al., 2025). Even though the decline is less pronounced for models with gating. (iii) At context lengths of 64k and 128k, the gated attention models outperform the baseline signifantly. From these observations, we hypothesize that adding gating helps the model adapt to the context-length extension. A possible explanation is that baseline models rely on attention sinks to adjust the distribution of attention scores. Dong et al. (2025) derives the effects of changing the RoPE based on the attention and hidden state distributions. When techniques like YaRN are applied to modify the RoPE base, the attention sink pattern may struggle to adapt in a training-free manner, leading to a noticeable drop in performance. In contrast, models with gating primarily rely on input-dependent gating scores to control information flow, making them more robust to such changes.
既然门控模型没有注意力汇聚,我们进一步评估 SDPA 门控在长上下文场景下的效果。具体来说,我们对在 3.5T 词元上训练的模型扩展上下文长度:把 RoPE(Su et al., 2024)的基数从 10k 提高到 1M,并在序列长度为 32k 的数据上继续训练 80B 词元,得到上下文长度为 32k 的模型。随后用 YaRN(Peng et al., 2023)把上下文长度扩展到 128k。我们在 RULER 基准(Hsieh et al., 2024)上评测模型,结果汇总在表 5 中。观察如下:(i) 在 32k 设置下,带门控的模型略优于基线。这说明在训练长度以内,注意力汇聚现象可能不会损害模型的长上下文性能。(ii) 用 YaRN 把上下文长度扩展到 128k 后,基线和门控模型在原有 32k 范围内的表现都有所下降。这与以往通过修改 RoPE 扩展上下文长度的工作(Chen et al., 2023; Peng et al., 2023; Dong et al., 2025)观察一致,只是门控模型下降得没那么多。(iii) 在 64k 和 128k 的上下文长度上,门控注意力模型明显优于基线。据此我们推测,加入门控有助于模型适应上下文长度扩展。一种可能的解释是,基线模型依靠注意力汇聚来调整注意力分数的分布。Dong et al.(2025)根据注意力和隐藏状态的分布,推导了改变 RoPE 的影响。用 YaRN 等技术修改 RoPE 基数时,注意力汇聚模式可能难以在不训练的情况下适应,因而性能明显下降。相比之下,带门控的模型主要依靠依赖输入的门控分数控制信息流,对这类变化更稳健。
5 Related Works
5 相关工作
5.1 Gating in Neural Networks
5.1 神经网络中的门控
Gating mechanisms have been widely adopted in neural networks. Early works such as LSTMs (Hochreiter & Schmidhuber, 1997) and GRUs (Dey & Salem, 2017) introduce gates to regulate information flow across time steps, addressing gradient vanishing/exploding issues by selectively retaining or discarding information. Highway Networks (Srivastava et al., 2015) extend this concept to feedforward networks, enabling the successful training of very deep architectures. SwiGLU (Shazeer, 2020) introduce gating mechanisms into transformer FFN layers, enhancing their expressive power and becoming a standard component in many open-source LLMs (Grattafiori et al., 2024; Yang et al., 2024a).
门控机制在神经网络中应用广泛。LSTM(Hochreiter & Schmidhuber, 1997)和 GRU(Dey & Salem, 2017)等早期工作引入门来调节信息在时间步之间的流动,通过有选择地保留或丢弃信息,解决梯度消失和梯度爆炸问题。高速公路网络(Srivastava et al., 2015)把这一思想推广到前馈网络,使非常深的架构得以训练成功。SwiGLU(Shazeer, 2020)把门控机制引入 Transformer 的 FFN 层,增强了其表达能力,已成为许多开源大语言模型的标准组件(Grattafiori et al., 2024; Yang et al., 2024a)。
Several works on state-space models (Gu & Dao, 2023; Dao & Gu, 2024) and Linear Attention, such as FLASH (Hua et al., 2022), RetNet (Sun et al., 2023), Lightning Attention (Qin et al., 2024a; Qin et al., 2024b; Li et al., 2025), and Gated Delta Networks (Yang et al., 2024b), also incorporate gating modules to controlinformation of token-mixer modules. Forgetting Transformer (Lin et al., 2025) applies gating mechanisms to the output of softmax attention, observing significant performance improvements. Although these works demonstrate the effectiveness of gating, a comprehensive understanding of its precise mechanisms and the reasons behind its effectiveness still needs exploration. This could contribute to a broader appreciation of gating’s importance beyond RNNs and facilitate designs that better leverage gating’s unique advantages. For example, while Switch Heads (Csordas et al., 2024b; Csordas et al., 2024a), NSA (Yuan et al., 2025), and MoSA (Piękos et al., 2025) employ sigmoid-based gating (Csordas et al., 2023) for selection, further investigation into isolating gating’s specific contribution could offer valuable insights. Comparisons with baselines incorporating similar gating mechanisms in standard transformers could offer a more refined perspective on the effectiveness of their proposed selection mechanisms. The work most closely related to ours is Quantizable Transformers (Bondarenko et al., 2023), which also finds that applying gating in softmax attention alleviates extreme attention concentration and outliers in hidden states in encoder models like BERT and ViT. While this work primarily leverages gating to eliminate outliers for model quantization, we provide a detailed analysis of various gating variants, uncovering their benefits through enhanced non-linearity and sparsity, as well as improved training stability. Building on these insights, we scale up gated attention models, demonstrating gating’s broad applicability and impact.
一些状态空间模型(Gu & Dao, 2023; Dao & Gu, 2024)和线性注意力工作,如 FLASH(Hua et al., 2022)、RetNet(Sun et al., 2023)、Lightning Attention(Qin et al., 2024a; Qin et al., 2024b; Li et al., 2025)和门控 Delta 网络(Gated Delta Networks,Yang et al., 2024b),也加入了门控模块来控制词元混合模块的信息。遗忘 Transformer(Forgetting Transformer,Lin et al., 2025)对 softmax 注意力的输出施加门控,观察到显著的性能提升。这些工作虽然证明了门控的有效性,但对其确切机制和起效原因仍缺乏全面理解。弄清这些,有助于人们认识到门控在 RNN 之外的重要性,也有助于设计出更能发挥门控独特优势的结构。例如,Switch Heads(Csordas et al., 2024b; Csordas et al., 2024a)、NSA(Yuan et al., 2025)和 MoSA(Piękos et al., 2025)都用基于 sigmoid 的门控(Csordas et al., 2023)做选择,进一步单独考察门控本身的贡献可能会带来有价值的认识。与在标准 Transformer 中加入类似门控机制的基线做比较,可以更准确地评估它们所提选择机制的效果。与我们最相近的工作是可量化 Transformer(Quantizable Transformers,Bondarenko et al., 2023),它也发现在 BERT、ViT 等编码器模型的 softmax 注意力中加门控,可以缓解注意力的极端集中和隐藏状态中的离群值。这项工作主要用门控消除离群值以便模型量化,而我们详细分析了各种门控变体,揭示了它们通过增强非线性和稀疏性带来的好处,以及对训练稳定性的改善。在此基础上,我们扩大了门控注意力模型的规模,展示了门控的广泛适用性和影响。
5.2 Attention Sink
5.2 注意力汇聚
Xiao et al. (2023) formally identifies the ‘attention sink’ phenomenon, in which specific tokens receive large attention scores. Similarly, Darcet et al. (2023) finds in the vision transformer, some redundant tokens act as ‘registers’ to store attention scores. Later, Sun et al. (2024) shows that excessive attention scores are also assigned to tokens associated with massive activation values. However, our work reveals that applying gating at the output of value projection eliminates massive activations, yet attention sinks persist, indicating that massive activations are not a necessary condition for attention sinks. Similarly, Gu et al. (2024) characterizes attention sinks as non-informative ‘key biases’ that store redundant attention scores, arguing that softmax’s inherent normalization dependency drives this behavior. Experimental attempts to modify softmax attention, such as replacing softmax with unnormalized sigmoid attention (Ramapuram et al., 2024; Gu et al., 2024), adding softmax attention gate or clip (Bondarenko et al., 2023), and modifying softmax computation (Zuhri et al., 2025) and denominator (Miller, 2023), show promise in mitigating attention sinks. Our work demonstrates that sparse gating after SDPA eliminates attention sinks in both dense (1B-parameter) and MoE (15B-parameter) models, even when trained on 3.5T tokens. Furthermore, we uncover the potential of eliminating attention sinks to benefit context-length extension.
Xiao et al.(2023)正式提出了“注意力汇聚”现象,即某些特定词元得到很大的注意力分数。类似地,Darcet et al.(2023)发现视觉 Transformer 中一些冗余词元充当“寄存器”(register),用来存放注意力分数。之后,Sun et al.(2024)指出,与巨量激活值相关的词元也会被分配过多的注意力分数。然而我们的工作表明,在值投影的输出上加门控可以消除巨量激活,注意力汇聚却依然存在,说明巨量激活不是注意力汇聚的必要条件。同样,Gu et al.(2024)把注意力汇聚刻画为存放冗余注意力分数的、不携带信息的“键偏置”(key bias),认为是 softmax 固有的归一化依赖导致了这种行为。修改 softmax 注意力的实验尝试,例如用未归一化的 sigmoid 注意力替代 softmax(Ramapuram et al., 2024; Gu et al., 2024)、加入 softmax 注意力门或截断(Bondarenko et al., 2023)、修改 softmax 的计算方式(Zuhri et al., 2025)及分母(Miller, 2023),都显示出缓解注意力汇聚的潜力。我们的工作表明,SDPA 之后的稀疏门控在稠密模型(1B 参数)和 MoE 模型(15B 参数)中都消除了注意力汇聚,即使模型在 3.5T 词元上训练也是如此。此外,我们还揭示了消除注意力汇聚对扩展上下文长度的潜在好处。
6 Conclusion
6 结论
This work systematically investigates the role of gating mechanisms in the standard softmax attention, revealing their significant impact on performance, training stability, and attention dynamics. Through extensive experimental comparisons over 30 variants of 15B MoE and 1.7B dense models trained on up to 3.5T tokens, we demonstrate that applying a sigmoid gate after scaled dot-product attention yields the most substantial improvements. This simple mechanism enhances non-linearity, introduces input-dependent sparsity, and eliminates inefficiencies like the ‘attention sink’ phenomenon. Additionally, gating facilitates context length extension, allowing models to generalize effectively to longer sequences without retraining. We also release the first attention-sink-free models. We believe these empirical validations will pave the way for engineering the next generation of advanced foundation models.
本文系统研究了门控机制在标准 softmax 注意力中的作用,揭示了它对性能、训练稳定性和注意力动态的显著影响。通过对 30 多种变体(15B MoE 模型和 1.7B 稠密模型,训练数据最多 3.5T 词元)的大量实验比较,我们证明在缩放点积注意力之后加 sigmoid 门带来的提升最大。这一简单机制增强了非线性,引入了依赖输入的稀疏性,并消除了“注意力汇聚”这类低效现象。此外,门控有利于扩展上下文长度,使模型无需重新训练就能较好地泛化到更长的序列。我们还发布了首批没有注意力汇聚的模型。我们相信,这些实证结果将为构建下一代先进基础模型铺平道路。
Limitations
局限
Our work primarily focuses on analyzing the reasons and impacts of attention gating through a series of ablation studies. However, we acknowledge several limitations. The broader implications of non-linearity on the dynamics of attention and the overall training process remain under-explored. Although we observe that eliminating attention sinks improves performance in long-context extension scenarios, we do not provide a rigorous theoretical explanation for how attention sinks influence the model’s ability to generalize to longer sequences.
本文主要通过一系列消融研究,分析注意力门控起作用的原因和影响。我们也承认存在几项局限。非线性对注意力动态和整个训练过程的更广泛影响仍有待探索。我们虽然观察到消除注意力汇聚能提升长上下文扩展场景下的性能,但没有给出严格的理论解释,说明注意力汇聚如何影响模型泛化到更长序列的能力。
References
参考文献
Ainslie et al. (2023) Joshua Ainslie, James Lee-Thorp, Michiel De Jong, Yury Zemlyanskiy, Federico Lebrón, and Sumit Sanghai. Gqa: Training generalized multi-query transformer models from multi-head checkpoints. arXiv preprint arXiv:2305.13245 , 2023.
Bondarenko et al. (2023) Yelysei Bondarenko, Markus Nagel, and Tijmen Blankevoort. Quantizable transformers: Removing outliers by helping attention heads do nothing. Advances in Neural Information Processing Systems , 36:75067–75096, 2023.
Budzinskiy et al. (2025) Stanislav Budzinskiy, Wenyi Fang, Longbin Zeng, and Philipp Petersen. Numerical error analysis of large language models. arXiv preprint arXiv:2503.10251 , 2025.
Chen et al. (2021) Mark Chen, Jerry Tworek, Heewoo Jun, Qiming Yuan, Henrique Ponde de Oliveira Pinto, Jared Kaplan, Harri Edwards, Yuri Burda, Nicholas Joseph, Greg Brockman, Alex Ray, Raul Puri, Gretchen Krueger, Michael Petrov, Heidy Khlaaf, Girish Sastry, Pamela Mishkin, Brooke Chan, Scott Gray, Nick Ryder, Mikhail Pavlov, Alethea Power, Lukasz Kaiser, Mohammad Bavarian, Clemens Winter, Philippe Tillet, Felipe Petroski Such, Dave Cummings, Matthias Plappert, Fotios Chantzis, Elizabeth Barnes, Ariel Herbert-Voss, William Hebgen Guss, Alex Nichol, Alex Paino, Nikolas Tezak, Jie Tang, Igor Babuschkin, Suchir Balaji, Shantanu Jain, William Saunders, Christopher Hesse, Andrew N. Carr, Jan Leike, Josh Achiam, Vedant Misra, Evan Morikawa, Alec Radford, Matthew Knight, Miles Brundage, Mira Murati, Katie Mayer, Peter Welinder, Bob McGrew, Dario Amodei, Sam McCandlish, Ilya Sutskever, and Wojciech Zaremba. Evaluating large language models trained on code, 2021.
Chen et al. (2023) Shouyuan Chen, Sherman Wong, Liangjian Chen, and Yuandong Tian. Extending context window of large language models via positional interpolation, 2023. URL https://arxiv.org/abs/2306.15595 .
Chowdhery et al. (2023) Aakanksha Chowdhery, Sharan Narang, Jacob Devlin, Maarten Bosma, Gaurav Mishra, Adam Roberts, Paul Barham, Hyung Won Chung, Charles Sutton, Sebastian Gehrmann, et al. Palm: Scaling language modeling with pathways. Journal of Machine Learning Research , 24(240):1–113, 2023.
Cobbe et al. (2021) Karl Cobbe, Vineet Kosaraju, Mohammad Bavarian, Mark Chen, Heewoo Jun, Lukasz Kaiser, Matthias Plappert, Jerry Tworek, Jacob Hilton, Reiichiro Nakano, et al. Training verifiers to solve math word problems. arXiv preprint arXiv:2110.14168 , 2021.
Csordas et al. (2023) Robert Csordas, Kazuki Irie, and Jurgen Schmidhuber. Approximating two-layer feedforward networks for efficient transformers. arXiv preprint arXiv:2310.10837 , 2023.
Csordas et al. (2024a) Robert Csordas, Kazuki Irie, Jurgen Schmidhuber, Christopher Potts, and Christopher D Manning. Moeut: Mixture-of-experts universal transformers. arXiv preprint arXiv:2405.16039 , 2024a.
Csordas et al. (2024b) Robert Csordas, Piotr Piekos, Kazuki Irie, and Jurgen Schmidhuber. Switchhead: Accelerating transformers with mixture-of-experts attention. Advances in Neural Information Processing Systems , 37:74411–74438, 2024b.
Dai et al. (2024) Damai Dai, Chengqi Deng, Chenggang Zhao, RX Xu, Huazuo Gao, Deli Chen, Jiashi Li, Wangding Zeng, Xingkai Yu, Y Wu, et al. Deepseekmoe: Towards ultimate expert specialization in mixture-of-experts language models. arXiv preprint arXiv:2401.06066 , 2024.
D’Angelo et al. (2024) Francesco D’Angelo, Maksym Andriushchenko, Aditya Vardhan Varre, and Nicolas Flammarion. Why do we need weight decay in modern deep learning? Advances in Neural Information Processing Systems , 37:23191–23223, 2024.
Dao & Gu (2024) Tri Dao and Albert Gu. Transformers are ssms: Generalized models and efficient algorithms through structured state space duality. In Forty-first International Conference on Machine Learning, ICML 2024, Vienna, Austria, July 21-27, 2024 . OpenReview.net, 2024. URL https://openreview.net/forum?id=ztn8FCR1td .
Darcet et al. (2023) Timothée Darcet, Maxime Oquab, Julien Mairal, and Piotr Bojanowski. Vision transformers need registers. arXiv preprint arXiv:2309.16588 , 2023.
Dey & Salem (2017) Rahul Dey and Fathi M Salem. Gate-variants of gated recurrent unit (gru) neural networks. In 2017 IEEE 60th international midwest symposium on circuits and systems (MWSCAS) , pp. 1597–1600. IEEE, 2017.
Ding et al. (2021) Ming Ding, Zhuoyi Yang, Wenyi Hong, Wendi Zheng, Chang Zhou, Da Yin, Junyang Lin, Xu Zou, Zhou Shao, Hongxia Yang, and Jie Tang. Cogview: Mastering text-to-image generation via transformers, 2021.
Dong et al. (2025) Zican Dong, Junyi Li, Jinhao Jiang, Mingyu Xu, Wayne Xin Zhao, Bingning Wang, and Weipeng Chen. Longred: Mitigating short-text degradation of long-context large language models via restoration distillation. ArXiv , abs/2502.07365, 2025. URL https://arxiv.org/abs/2502.07365 .
Grattafiori et al. (2024) Aaron Grattafiori, Abhimanyu Dubey, Abhinav Jauhri, Abhinav Pandey, Abhishek Kadian, Ahmad Al-Dahle, Aiesha Letman, Akhil Mathur, Alan Schelten, Alex Vaughan, et al. The llama 3 herd of models. arXiv preprint arXiv:2407.21783 , 2024.
Gu & Dao (2023) Albert Gu and Tri Dao. Mamba: Linear-time sequence modeling with selective state spaces. arXiv preprint arXiv:2312.00752 , 2023.
Gu et al. (2024) Xiangming Gu, Tianyu Pang, Chao Du, Qian Liu, Fengzhuo Zhang, Cunxiao Du, Ye Wang, and Min Lin. When attention sink emerges in language models: An empirical view. arXiv preprint arXiv:2410.10781 , 2024.
Hendrycks et al. (2020) Dan Hendrycks, Collin Burns, Steven Basart, Andy Zou, Mantas Mazeika, Dawn Song, and Jacob Steinhardt. Measuring massive multitask language understanding. arXiv preprint arXiv:2009.03300 , 2020.
Hochreiter & Schmidhuber (1997) Sepp Hochreiter and Jürgen Schmidhuber. Long short-term memory. Neural computation , 9(8):1735–1780, 1997.
Hsieh et al. (2024) Cheng-Ping Hsieh, Simeng Sun, Samuel Kriman, Shantanu Acharya, Dima Rekesh, Fei Jia, Yang Zhang, and Boris Ginsburg. Ruler: What’s the real context size of your long-context language models? arXiv preprint arXiv:2404.06654 , 2024.
Hua et al. (2022) Weizhe Hua, Zihang Dai, Hanxiao Liu, and Quoc V. Le. Transformer quality in linear time. In International Conference on Machine Learning, ICML 2022, 17-23 July 2022, Baltimore, Maryland, USA , volume 162 of Proceedings of Machine Learning Research , pp. 9099–9117. PMLR, 2022. URL https://proceedings.mlr.press/v162/hua22a.html .
Huang et al. (2024) Yuzhen Huang, Yuzhuo Bai, Zhihao Zhu, Junlei Zhang, Jinghan Zhang, Tangjun Su, Junteng Liu, Chuancheng Lv, Yikai Zhang, Yao Fu, et al. C-eval: A multi-level multi-discipline chinese evaluation suite for foundation models. Advances in Neural Information Processing Systems , 36, 2024.
Li et al. (2025) Aonian Li, Bangwei Gong, Bo Yang, Boji Shan, Chang Liu, Cheng Zhu, Chunhao Zhang, Congchao Guo, Da Chen, Dong Li, et al. Minimax-01: Scaling foundation models with lightning attention. arXiv preprint arXiv:2501.08313 , 2025.
Li et al. (2023) Haonan Li, Yixuan Zhang, Fajri Koto, Yifei Yang, Hai Zhao, Yeyun Gong, Nan Duan, and Timothy Baldwin. Cmmlu: Measuring massive multitask language understanding in chinese, 2023.
Lin et al. (2025) Zhixuan Lin, Evgenii Nikishin, Xu Owen He, and Aaron Courville. Forgetting transformer: Softmax attention with a forget gate. arXiv preprint arXiv:2503.02130 , 2025.
McCandlish et al. (2018) Sam McCandlish, Jared Kaplan, Dario Amodei, and OpenAI Dota Team. An empirical model of large-batch training. arXiv preprint arXiv:1812.06162 , 2018.
Miller (2023) Evan Miller. Attention is off by one, 2023. URL https://www.evanmiller.org/attention-is-off-by-one.html .
Montufar et al. (2014) Guido Montufar, Razvan Pascanu, Kyunghyun Cho, and Yoshua Bengio. On the number of linear regions of deep neural networks, 2014. URL https://arxiv.org/abs/1402.1869 .
Olsson et al. (2022) Catherine Olsson, Nelson Elhage, Neel Nanda, Nicholas Joseph, Nova DasSarma, Tom Henighan, Ben Mann, Amanda Askell, Yuntao Bai, Anna Chen, et al. In-context learning and induction heads. arXiv preprint arXiv:2209.11895 , 2022.
Peng et al. (2023) Bowen Peng, Jeffrey Quesnelle, Honglu Fan, and Enrico Shippole. Yarn: Efficient context window extension of large language models. arXiv preprint arXiv:2309.00071 , 2023.
Piękos et al. (2025) Piotr Piękos, Róbert Csordás, and Jürgen Schmidhuber. Mixture of sparse attention: Content-based learnable sparse attention via expert-choice routing, 2025. URL https://arxiv.org/abs/2505.00315 .
Qin et al. (2024a) Zhen Qin, Weigao Sun, Dong Li, Xuyang Shen, Weixuan Sun, and Yiran Zhong. Lightning attention-2: A free lunch for handling unlimited sequence lengths in large language models. arXiv preprint arXiv:2401.04658 , 2024a.
Qin et al. (2024b) Zhen Qin, Weigao Sun, Dong Li, Xuyang Shen, Weixuan Sun, and Yiran Zhong. Various lengths, constant speed: Efficient language modeling with lightning attention. arXiv preprint arXiv:2405.17381 , 2024b.
Qiu et al. (2025) Zihan Qiu, Zeyu Huang, Bo Zheng, Kaiyue Wen, Zekun Wang, Rui Men, Ivan Titov, Dayiheng Liu, Jingren Zhou, and Junyang Lin. Demons in the detail: On implementing load balancing loss for training specialized mixture-of-expert models, 2025. URL https://arxiv.org/abs/2501.11873 .
Ramapuram et al. (2024) Jason Ramapuram, Federico Danieli, Eeshan Dhekane, Floris Weers, Dan Busbridge, Pierre Ablin, Tatiana Likhomanenko, Jagrit Digani, Zijin Gu, Amitis Shidani, et al. Theory, analysis, and best practices for sigmoid self-attention. arXiv preprint arXiv:2409.04431 , 2024.
Shazeer (2020) Noam Shazeer. Glu variants improve transformer. arXiv preprint arXiv:2002.05202 , 2020.
Srivastava et al. (2015) Rupesh Kumar Srivastava, Klaus Greff, and Jürgen Schmidhuber. Highway networks. arXiv preprint arXiv:1505.00387 , 2015.
Su et al. (2024) Jianlin Su, Murtadha Ahmed, Yu Lu, Shengfeng Pan, Wen Bo, and Yunfeng Liu. Roformer: Enhanced transformer with rotary position embedding. Neurocomputing , 568:127063, 2024.
Sun et al. (2024) Mingjie Sun, Xinlei Chen, J Zico Kolter, and Zhuang Liu. Massive activations in large language models. arXiv preprint arXiv:2402.17762 , 2024.
Sun et al. (2023) Yutao Sun, Li Dong, Shaohan Huang, Shuming Ma, Yuqing Xia, Jilong Xue, Jianyong Wang, and Furu Wei. Retentive network: A successor to transformer for large language models, 2023. URL https://arxiv.org/abs/2307.08621 .
Takase et al. (2023) Sho Takase, Shun Kiyono, Sosuke Kobayashi, and Jun Suzuki. Spike no more: Stabilizing the pre-training of large language models. arXiv preprint arXiv:2312.16903 , 2023.
Vaswani (2017) A Vaswani. Attention is all you need. Advances in Neural Information Processing Systems , 2017.
Voita et al. (2019) Elena Voita, David Talbot, Fedor Moiseev, Rico Sennrich, and Ivan Titov. Analyzing multi-head self-attention: Specialized heads do the heavy lifting, the rest can be pruned. arXiv preprint arXiv:1905.09418 , 2019.
Wang et al. (2021) Hanrui Wang, Zhekai Zhang, and Song Han. Spatten: Efficient sparse attention architecture with cascade token and head pruning. In 2021 IEEE International Symposium on High-Performance Computer Architecture (HPCA) , pp. 97–110. IEEE, 2021.
Wang et al. (2022) Hongyu Wang, Shuming Ma, Li Dong, Shaohan Huang, Dongdong Zhang, and Furu Wei. Deepnet: Scaling transformers to 1,000 layers, 2022. URL https://arxiv.org/abs/2203.00555 .
Wang et al. (2023) Zekun Wang, Jingchang Chen, Wangchunshu Zhou, Haichao Zhu, Jiafeng Liang, Liping Shan, Ming Liu, Dongliang Xu, Qing Yang, and Bing Qin. Smarttrim: Adaptive tokens and attention pruning for efficient vision-language models. arXiv preprint arXiv:2305.15033 , 2023.
Xiao et al. (2023) Guangxuan Xiao, Yuandong Tian, Beidi Chen, Song Han, and Mike Lewis. Efficient streaming language models with attention sinks. arXiv preprint arXiv:2309.17453 , 2023.
Yang et al. (2024a) An Yang, Baosong Yang, Beichen Zhang, Binyuan Hui, Bo Zheng, Bowen Yu, Chengyuan Li, Dayiheng Liu, Fei Huang, Haoran Wei, et al. Qwen2. 5 technical report. arXiv preprint arXiv:2412.15115 , 2024a.
Yang et al. (2024b) Songlin Yang, Jan Kautz, and Ali Hatamizadeh. Gated delta networks: Improving mamba2 with delta rule. arXiv preprint arXiv:2412.06464 , 2024b.
Ye et al. (2024) Tianzhu Ye, Li Dong, Yuqing Xia, Yutao Sun, Yi Zhu, Gao Huang, and Furu Wei. Differential transformer. arXiv preprint arXiv:2410.05258 , 2024.
Yona et al. (2025) Itay Yona, Ilia Shumailov, Jamie Hayes, Federico Barbero, and Yossi Gandelsman. Interpreting the repeated token phenomenon in large language models. arXiv preprint arXiv:2503.08908 , 2025.
Yuan et al. (2025) Jingyang Yuan, Huazuo Gao, Damai Dai, Junyu Luo, Liang Zhao, Zhengyan Zhang, Zhenda Xie, YX Wei, Lean Wang, Zhiping Xiao, et al. Native sparse attention: Hardware-aligned and natively trainable sparse attention. arXiv preprint arXiv:2502.11089 , 2025.
Zellers et al. (2019) Rowan Zellers, Ari Holtzman, Yonatan Bisk, Ali Farhadi, and Yejin Choi. Hellaswag: Can a machine really finish your sentence? arXiv preprint arXiv:1905.07830 , 2019.
Zeng et al. (2022) Aohan Zeng, Xiao Liu, Zhengxiao Du, Zihan Wang, Hanyu Lai, Ming Ding, Zhuoyi Yang, Yifan Xu, Wendi Zheng, Xiao Xia, et al. Glm-130b: An open bilingual pre-trained model. arXiv preprint arXiv:2210.02414 , 2022.
Zhang & Sennrich (2019) Biao Zhang and Rico Sennrich. Root mean square layer normalization. Advances in Neural Information Processing Systems , 32, 2019.
Zoph et al. (2022) Barret Zoph, Irwan Bello, Sameer Kumar, Nan Du, Yanping Huang, Jeff Dean, Noam Shazeer, and William Fedus. St-moe: Designing stable and transferable sparse expert models. arXiv preprint arXiv:2202.08906 , 2022.
Zuhri et al. (2025) Zayd M. K. Zuhri, Erland Hilman Fuadi, and Alham Fikri Aji. Softpick: No attention sink, no massive activations with rectified softmax, 2025. URL https://arxiv.org/abs/2504.20966 .
Appendix A Supplement Experiments
附录 A 补充实验
A.1 Switch Head Baselines
A.1 Switch Head 基线
In this section, we present detailed experiments related to Switch Heads. The Switch Head paper demonstrates that introducing sparse activation in attention—where each token selects the top-k experts from a pool of key/value/output experts via learnable sigmoid routing—enables the model to achieve comparable results to the baseline. This suggests that, within the Switch Head framework, both expert parameters and activated parameters are beneficial, with more being better under the same total parameter budget.
本节给出与 Switch Heads 相关的详细实验。Switch Head 论文表明,在注意力中引入稀疏激活(每个词元通过可学习的 sigmoid 路由,从一组键/值/输出专家中选出 top-k 个专家),模型就能达到与基线相当的结果。这意味着在 Switch Head 框架内,专家参数和激活参数都有益,在总参数预算相同时越多越好。
| Method | Added Param (M) | PPL | MMLU | GSM8k | Hellaswag | C-eval |
|---|---|---|---|---|---|---|
| (1) Baseline (q32, kv4) | - | 6.026 | 58.79 | 52.92 | 73.07 | 60.26 |
| (2) Switch kv, 8top8 | 38 | 5.847 | 59.17 | 52.54 | 73.32 | 61.01 |
| (3) Switch kv, 4top4 | 13 | 5.935 | 58.14 | 53.27 | 73.75 | 59.67 |
| (4) Switch v, 4top4 | 13 | 5.820 | 59.02 | 52.77 | 73.34 | 61.74 |
| (5) Switch v, 8top2 | 25 | 5.870 | 59.10 | 53.53 | 74.17 | 62.34 |
| (6) Switch v, 1top1 | 3 | 5.808 | 59.32 | 53.53 | 74.38 | 62.61 |
Table 6: Performance of different switch head methods with varying parameter additions and configurations. ‘switch kv’ and ‘switch v’ refer to introducing selective computing in key-value and value components, respectively. ‘Switch kv, 8top8’ means there are 8 key and value map experts, and each token select top8 experts. Notice ‘Switch v, 1top1’ is equivalent to v Headwise Gate in Tab. 1 row (11).
| 方法 | 新增参数(M) | PPL | MMLU | GSM8k | Hellaswag | C-eval |
|---|---|---|---|---|---|---|
| (1) 基线(q32, kv4) | - | 6.026 | 58.79 | 52.92 | 73.07 | 60.26 |
| (2) Switch kv, 8top8 | 38 | 5.847 | 59.17 | 52.54 | 73.32 | 61.01 |
| (3) Switch kv, 4top4 | 13 | 5.935 | 58.14 | 53.27 | 73.75 | 59.67 |
| (4) Switch v, 4top4 | 13 | 5.820 | 59.02 | 52.77 | 73.34 | 61.74 |
| (5) Switch v, 8top2 | 25 | 5.870 | 59.10 | 53.53 | 74.17 | 62.34 |
| (6) Switch v, 1top1 | 3 | 5.808 | 59.32 | 53.53 | 74.38 | 62.61 |
表 6:不同 Switch Head 方法在不同参数增量和配置下的性能。“switch kv”和“switch v”分别指在键值部分和值部分引入选择性计算。“Switch kv, 8top8”表示有 8 个键映射和值映射专家,每个词元选择 top8 个专家。注意“Switch v, 1top1”等价于表 1 第 (11) 行的 v 按头门控。
Looking at the results in Tab. 6, we observe an interesting trend: while increasing the number of activated kv experts (with the same expert parameter settings) appears to offer some improvement in PPL (row 4 vs. 5), the gains in overall benchmark performance are less pronounced. Notably, the best results for both benchmark scores and PPL were achieved by ‘Switch v 1top1’ (row 6), which, as mentioned earlier, is analogous to applying sigmoid gating directly to the output of the value layer. These findings raise an intriguing question about the primary driver of the performance improvements observed in these experiments. It suggests that the introduction of gating itself plays a significant role in the effectiveness of this approach.
从表 6 的结果中可以看到一个有意思的趋势:增加激活的 kv 专家数(专家参数设置相同)似乎能让 PPL 有所改善(第 4 行对第 5 行),但基准整体表现的提升不那么明显。基准分数和 PPL 的最好结果都出自“Switch v 1top1”(第 6 行),如前所述,它相当于直接对值层输出施加 sigmoid 门控。这些发现引出一个耐人寻味的问题:这些实验中的性能提升,主要动力究竟是什么?结果表明,引入门控本身对这一方法的效果起了很大作用。
A.2 More Discussion on Sparse Gating Score
A.2 关于稀疏门控分数的更多讨论
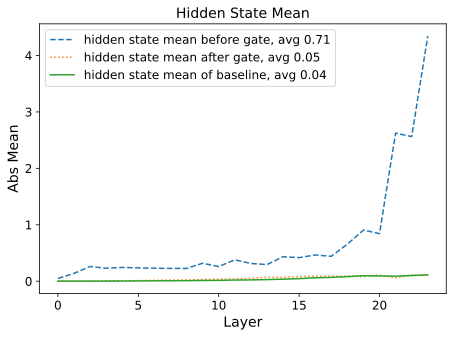
Figure 4: Mean absolute values before and after gating. The baseline and post-gating values are similar.
图 4:门控前后的平均绝对值。基线与门控后的数值相近。
In this section, we analyze the impact of gating score sparsity on attention output. First, we examine the mean values of SDPA output before and after applying gating to the hidden states. Specifically, we calculated the mean absolute values of and before and after at each layer, as shown in Fig. 4. We also included results from a baseline without gating for comparison. The results indicate that: (1) after gating, the mean value of hidden states decreased from 0.71 to 0.05, corresponding to the generally small gating scores; (2) the gated hidden states closely resemble the baseline, suggesting that gating might serve a similar function as attention sink in filtering out irrelevant information.
本节分析门控分数的稀疏性对注意力输出的影响。首先,我们考察对隐藏状态施加门控前后 SDPA 输出的均值。具体来说,我们计算每一层 前后 和 的平均绝对值,如图 4 所示,并附上不带门控的基线结果作对比。结果表明:(1)门控后隐藏状态的均值从 0.71 降到 0.05,与普遍较小的门控分数相对应;(2)门控后的隐藏状态与基线非常接近,说明门控可能与注意力汇聚一样,起到过滤无关信息的作用。
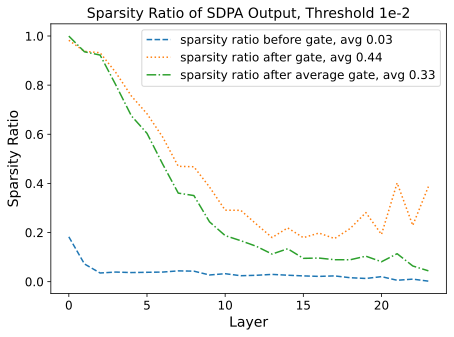
Figure 5: Proportion of SDPA output values below threshold after gating (Left: 1e-2, Right: 1e-3). We also include sparsity measurements obtained by multiplying the average gating score with pre-gating hidden states.
图 5:门控后 SDPA 输出值低于阈值的比例(左:1e-2,右:1e-3)。图中还给出了用平均门控分数乘以门控前隐藏状态所得的稀疏度。
We further analyze the proportion of hidden states below certain thresholds before and after gating, as shown in Fig 5. The results reveal that: (1) after gating, the sparsity in hidden states significantly increases across different thresholds. Since the mean gating scores are already small, multiplying hidden states by a small number naturally pushes some values below the threshold. Therefore, (2) we further multiply the pre-gating hidden states by the average gating score and observed that the increase in sparsity is smaller than with original gating. This suggests that sparse gating scores enhance sparsity in hidden states.
我们进一步分析门控前后隐藏状态低于一定阈值的比例,如图 5 所示。结果显示:(1)门控后,在不同阈值下隐藏状态的稀疏度都显著提高。由于平均门控分数本来就小,隐藏状态乘以一个小数自然会把一部分值压到阈值以下。因此,(2)我们又用平均门控分数乘以门控前的隐藏状态,发现稀疏度的增幅小于原始门控。这说明稀疏的门控分数增强了隐藏状态的稀疏性。
A.3 Layerwise Massive Activations and Attention Sinks
A.3 逐层的巨量激活与注意力汇聚
In this section, we compare and analyze the presence of massive activations and attention sinks (the attention score of the first token) within the model. From the results, we observe the following:
本节比较分析模型内部巨量激活和注意力汇聚(首个词元的注意力分数)的情况。从结果中可以观察到:
For the baseline (row 1), the output of the 6th layer’s FFN contains massive activations, which are subsequently added to the residual stream, causing large activations to persist in the residuals of subsequent layers. Correspondingly, significant attention sink phenomena emerge starting from the 6th layer. After applying gating to the SDPA output (row 2), the outputs of the earlier layers in the network remain relatively small overall, with massive activations growing gradually as the layer depth increases. Notably, no significant attention sink phenomenon is observed in any layer of the network.
对于基线(第 1 行),第 6 层 FFN 的输出含有巨量激活,这些激活随后加入残差流,使后续各层的残差中持续存在大激活。相应地,从第 6 层开始出现明显的注意力汇聚现象。对 SDPA 输出施加门控后(第 2 行),网络靠前各层的输出整体保持较小,巨量激活随层数加深逐渐增大。网络的任何一层都没有观察到明显的注意力汇聚现象。
When gating is applied only at the value layer (row 3), the model exhibits massive activations similar to row 2. However, a certain degree of attention sink phenomenon persists. This indicates that massive activations are not a necessary condition for the emergence of attention sinks. When enforcing shared gating scores across different heads (row 4) or modifying the activation function of gating to suppress sparsity (row 5), the sparsity introduced by gating is reduced. In these cases, both massive activations and attention sinks become comparable to those observed in the baseline.
只在值层施加门控时(第 3 行),模型的巨量激活与第 2 行相近,但仍存在一定程度的注意力汇聚。这说明巨量激活不是注意力汇聚出现的必要条件。强制不同头共享门控分数(第 4 行),或修改门控的激活函数以抑制稀疏性(第 5 行),都会削弱门控引入的稀疏性。在这些情况下,巨量激活和注意力汇聚都与基线相当。
These observations suggest that introducing sufficient sparsity within the attention mechanism may help mitigate the occurrence of massive activations. However, further investigation is needed to fully understand the interplay between sparsity, massive activations, and attention sinks, particularly in the context of scaling to deeper and larger models.
这些观察表明,在注意力机制中引入足够的稀疏性,可能有助于减少巨量激活的出现。不过,要充分理解稀疏性、巨量激活和注意力汇聚三者之间的相互作用,尤其是在扩展到更深、更大的模型时,还需要进一步研究。
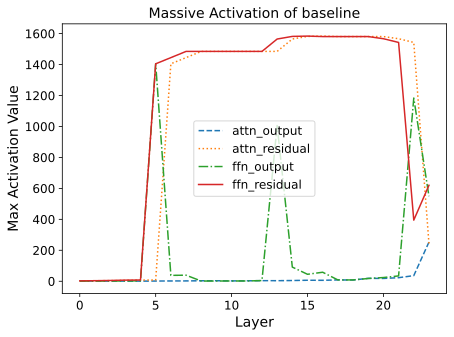
Figure 6: Comparison of massive activations and attention sink phenomena across different gating configurations. Row 1 (Baseline): Significant massive activations and attention sinks emerge after the 6th layer. Row 2 (SDPA Gating): Reduced activations and no attention sinks observed. Row 3 (Value Layer Gating): Similar activations to Row 2 but with residual attention sinks. Rows 4–5 (Reduced Sparsity via cross-head share and NS-sigmoid): Massive activations and attention sinks resemble the baseline.
图 6:不同门控配置下巨量激活和注意力汇聚现象的比较。第 1 行(基线):第 6 层之后出现明显的巨量激活和注意力汇聚。第 2 行(SDPA 门控):激活减小,未观察到注意力汇聚。第 3 行(值层门控):激活与第 2 行相近,但仍有残余的注意力汇聚。第 4–5 行(通过跨头共享和 NS-sigmoid 削弱稀疏性):巨量激活和注意力汇聚与基线相似。
A.4 More Layerwise Gating Scores
A.4 更多逐层门控分数
In this section, we analyze the distribution of gating scores under two additional constraints while using SDPA output gating as the baseline (row 1, elementwise/headwise): (1) enforcing the same gating score across different heads (row 2, left), and (2) restricting the minimum value of the gating scores (row 2, right). When enforcing shared gating scores across different heads, the gating scores for most layers increase. This indicates that different heads require different sparsity, highlighting the importance of head-specific gating mechanisms.
本节以 SDPA 输出门控为基准(第 1 行,逐元素/按头),分析另外两种约束下门控分数的分布:(1)强制不同头使用相同的门控分数(第 2 行左);(2)限制门控分数的最小值(第 2 行右)。强制各头共享门控分数时,大多数层的门控分数都升高了。这说明不同的头需要不同的稀疏度,各头独立的门控机制因此很重要。
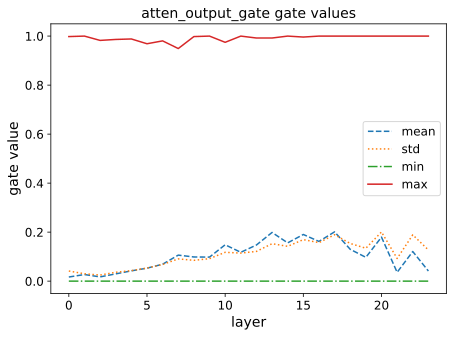
Figure 7: Distribution of gating scores under different constraints for SDPA output gating variants.
图 7:SDPA 输出门控变体在不同约束下的门控分数分布。
A.5 Other Attempt to Stabilize Training
A.5 稳定训练的其他尝试
We observe that both the addition of sandwich normalization (Ding et al., 2021) and gating mechanisms eliminate massive activations while improving training stability. This prompts us to explore whether simpler methods could prevent large activations within residuals. Specifically, we introduce a clipping operation to constrain the outputs of attention and FFN layers before they enter the residual connection, limiting their values to the range (-clip, clip). However, we find that regardless of whether the clip value was set to 300 or 100, the model still encounters convergence issues at a learning rate of 8e-3. This suggests that the instability in pre-norm model training is not solely due to large activations within residuals. It is likely that any layer producing large outputs can lead to stability problems, indicating the need for further investigation into the root causes of training instability.
我们观察到,加入三明治归一化(Ding et al., 2021)和加入门控机制都能消除巨量激活,同时提高训练稳定性。这促使我们探索能否用更简单的方法阻止残差中出现大激活。具体来说,我们引入截断操作,在注意力层和 FFN 层的输出进入残差连接之前,把它们的值限制在 (-clip, clip) 范围内。然而我们发现,无论截断值设为 300 还是 100,模型在学习率为 8e-3 时仍会出现收敛问题。这说明前置归一化模型训练的不稳定并不只是残差中的大激活造成的。很可能任何产生大输出的层都会导致稳定性问题,训练不稳定的根本原因还需要进一步研究。