Graph Attention Networks
Graph Attention Networks
图注意力网络
Petar Veličković † † thanks: Work performed while the author was at the Montréal Institute of Learning Algorithms. Affiliation: Department of Computer Science and Technology Affiliation: University of Cambridge Email: petar.velickovic@cst.cam.ac.uk Guillem Cucurull * Affiliation: Centre de Visió per Computador, UAB Email: gcucurull@gmail.com Arantxa Casanova * Affiliation: Centre de Visió per Computador, UAB Email: ar.casanova.8@gmail.com Adriana Romero Affiliation: Montréal Institute for Learning Algorithms Email: adriana.romero.soriano@umontreal.ca Pietro Liò Affiliation: Department of Computer Science and Technology Affiliation: University of Cambridge Email: pietro.lio@cst.cam.ac.uk Yoshua Bengio Affiliation: Montréal Institute for Learning Algorithms Email: yoshua.umontreal@gmail.com
Abstract
摘要
We present graph attention networks (GATs), novel neural network architectures that operate on graph-structured data, leveraging masked self-attentional layers to address the shortcomings of prior methods based on graph convolutions or their approximations. By stacking layers in which nodes are able to attend over their neighborhoods’ features, we enable (implicitly) specifying different weights to different nodes in a neighborhood, without requiring any kind of costly matrix operation (such as inversion) or depending on knowing the graph structure upfront. In this way, we address several key challenges of spectral-based graph neural networks simultaneously, and make our model readily applicable to inductive as well as transductive problems. Our GAT models have achieved or matched state-of-the-art results across four established transductive and inductive graph benchmarks: the Cora, Citeseer and Pubmed citation network datasets, as well as a protein-protein interaction dataset (wherein test graphs remain unseen during training).
我们提出图注意力网络(GAT):一类面向图结构数据的神经网络,借助带掩码的自注意力层,补足此前基于图卷积或其近似的方法的不足。通过堆叠若干层,使每个节点能对邻域特征做注意力聚合,从而(隐式地)为邻域内不同节点赋予不同权重,既不需要昂贵的矩阵运算(如求逆),也不依赖事先知道整张图的结构。由此,我们同时应对了谱方法图神经网络的若干关键挑战,并使模型可直接用于归纳式与直推式问题。在四个成熟的直推/归纳图基准上——Cora、Citeseer、Pubmed 引文网络,以及测试图在训练中完全未见的蛋白质–蛋白质相互作用数据集——我们的 GAT 达到或持平了当时最优结果。
1 Introduction
1 引言
Convolutional Neural Networks (CNNs) have been successfully applied to tackle problems such as image classification (He et al., 2016), semantic segmentation (Jégou et al., 2017) or machine translation (Gehring et al., 2016), where the underlying data representation has a grid-like structure. These architectures efficiently reuse their local filters, with learnable parameters, by applying them to all the input positions.
卷积神经网络(CNN)已成功用于图像分类(He et al., 2016)、语义分割(Jégou et al., 2017)与机器翻译(Gehring et al., 2016)等任务;这些任务的底层数据表示呈网格状结构。此类架构以可学习参数的局部滤波器高效复用,并在所有输入位置上施加同一组滤波器。
However, many interesting tasks involve data that can not be represented in a grid-like structure and that instead lies in an irregular domain. This is the case of 3D meshes, social networks, telecommunication networks, biological networks or brain connectomes. Such data can usually be represented in the form of graphs.
然而,许多有价值的任务所涉数据无法用网格结构表示,而落在不规则域上:例如三维网格、社交网络、电信网络、生物网络或脑连接组。这类数据通常可表示成图。
There have been several attempts in the literature to extend neural networks to deal with arbitrarily structured graphs. Early work used recursive neural networks to process data represented in graph domains as directed acyclic graphs (Frasconi et al., 1998; Sperduti & Starita, 1997). Graph Neural Networks (GNNs) were introduced in Gori et al. (2005) and Scarselli et al. (2009) as a generalization of recursive neural networks that can directly deal with a more general class of graphs, e.g. cyclic, directed and undirected graphs. GNNs consist of an iterative process, which propagates the node states until equilibrium; followed by a neural network, which produces an output for each node based on its state. This idea was adopted and improved by Li et al. (2016), which propose to use gated recurrent units (Cho et al., 2014) in the propagation step.
文献中已有若干尝试,把神经网络推广到任意结构的图。早期工作用递归神经网络处理有向无环图形式的图域数据(Frasconi et al., 1998;Sperduti & Starita, 1997)。图神经网络(GNN)由 Gori et al.(2005)与 Scarselli et al.(2009)提出,作为递归网络的推广,可直接处理更一般的图类,例如含环、有向与无向图。GNN 先迭代传播节点状态直至平衡,再用神经网络按各节点状态产生输出。Li et al.(2016)采纳并改进了这一思路,在传播步中引入门控循环单元(Cho et al., 2014)。
Nevertheless, there is an increasing interest in generalizing convolutions to the graph domain. Advances in this direction are often categorized as spectral approaches and non-spectral approaches.
与此同时,把卷积推广到图域的兴趣持续上升。这一方向的进展常被划分为谱方法与非谱方法。
On one hand, spectral approaches work with a spectral representation of the graphs and have been successfully applied in the context of node classification. In Bruna et al. (2014), the convolution operation is defined in the Fourier domain by computing the eigendecomposition of the graph Laplacian, resulting in potentially intense computations and non-spatially localized filters. These issues were addressed by subsequent works. Henaff et al. (2015) introduced a parameterization of the spectral filters with smooth coefficients in order to make them spatially localized. Later, Defferrard et al. (2016) proposed to approximate the filters by means of a Chebyshev expansion of the graph Laplacian, removing the need to compute the eigenvectors of the Laplacian and yielding spatially localized filters. Finally, Kipf & Welling (2017) simplified the previous method by restricting the filters to operate in a 1-step neighborhood around each node. However, in all of the aforementioned spectral approaches, the learned filters depend on the Laplacian eigenbasis, which depends on the graph structure. Thus, a model trained on a specific structure can not be directly applied to a graph with a different structure.
一方面,谱方法在图的谱表示上工作,并已成功用于节点分类。Bruna et al.(2014)在傅里叶域通过图拉普拉斯的特征分解定义卷积,计算可能很重,且滤波器未必空间局部化。后续工作缓解了这些问题:Henaff et al.(2015)用光滑系数参数化谱滤波器以增强空间局部性;随后 Defferrard et al.(2016)用图拉普拉斯的切比雪夫展开近似滤波器,免去特征分解并得到空间局部滤波器;最终 Kipf & Welling(2017)进一步简化,把滤波器限制在每个节点的一阶邻域。然而,上述谱方法所学滤波器都依赖拉普拉斯特征基,而特征基又依赖图结构,因此在某一结构上训练的模型无法直接用到结构不同的图上。
On the other hand, we have non-spectral approaches (Duvenaud et al., 2015; Atwood & Towsley, 2016; Hamilton et al., 2017), which define convolutions directly on the graph, operating on groups of spatially close neighbors. One of the challenges of these approaches is to define an operator which works with different sized neighborhoods and maintains the weight sharing property of CNNs. In some cases, this requires learning a specific weight matrix for each node degree (Duvenaud et al., 2015), using the powers of a transition matrix to define the neighborhood while learning weights for each input channel and neighborhood degree (Atwood & Towsley, 2016), or extracting and normalizing neighborhoods containing a fixed number of nodes (Niepert et al., 2016). Monti et al. (2016) presented mixture model CNNs (MoNet), a spatial approach which provides a unified generalization of CNN architectures to graphs. More recently, Hamilton et al. (2017) introduced GraphSAGE, a method for computing node representations in an inductive manner. This technique operates by sampling a fixed-size neighborhood of each node, and then performing a specific aggregator over it (such as the mean over all the sampled neighbors’ feature vectors, or the result of feeding them through a recurrent neural network). This approach has yielded impressive performance across several large-scale inductive benchmarks.
另一方面,非谱方法(Duvenaud et al., 2015;Atwood & Towsley, 2016;Hamilton et al., 2017)直接在图上定义卷积,作用于空间邻近的节点组。挑战之一是定义能处理不同大小邻域、又保持 CNN 权重共享性质的算子。有时需要为每种节点度数学习单独的权重矩阵(Duvenaud et al., 2015),用转移矩阵的幂定义邻域并为每个输入通道与邻域阶数学习权重(Atwood & Towsley, 2016),或抽取并归一化固定节点数的邻域(Niepert et al., 2016)。Monti et al.(2016)提出混合模型 CNN(MoNet),以空间方式统一推广 CNN 到图。更近的 Hamilton et al.(2017)提出 GraphSAGE,以归纳方式计算节点表示:对每个节点采样固定大小邻域,再对其施加特定聚合器(例如对采样邻居特征向量取均值,或经循环网络处理)。该方法在若干大规模归纳基准上表现突出。
Attention mechanisms have become almost a de facto standard in many sequence-based tasks (Bahdanau et al., 2015; Gehring et al., 2016). One of the benefits of attention mechanisms is that they allow for dealing with variable sized inputs, focusing on the most relevant parts of the input to make decisions. When an attention mechanism is used to compute a representation of a single sequence, it is commonly referred to as self-attention or intra-attention. Together with Recurrent Neural Networks (RNNs) or convolutions, self-attention has proven to be useful for tasks such as machine reading (Cheng et al., 2016) and learning sentence representations (Lin et al., 2017). However, Vaswani et al. (2017) showed that not only self-attention can improve a method based on RNNs or convolutions, but also that it is sufficient for constructing a powerful model obtaining state-of-the-art performance on the machine translation task.
注意力机制几乎已成为许多序列任务的事实标准(Bahdanau et al., 2015;Gehring et al., 2016)。其好处之一是能处理可变长度输入,并聚焦输入中最相关的部分再做决策。当注意力用于计算单一序列的表示时,常称为自注意力或内部注意力。与循环神经网络(RNN)或卷积结合时,自注意力已在机器阅读(Cheng et al., 2016)与句子表示学习(Lin et al., 2017)等任务上证明有用。而 Vaswani et al.(2017)进一步表明:自注意力不仅能改进基于 RNN 或卷积的方法,本身就足以构建在机器翻译上达到当时最优的强大模型。
Inspired by this recent work, we introduce an attention-based architecture to perform node classification of graph-structured data. The idea is to compute the hidden representations of each node in the graph, by attending over its neighbors, following a self-attention strategy. The attention architecture has several interesting properties: (1) the operation is efficient, since it is parallelizable across node-neighbor pairs; (2) it can be applied to graph nodes having different degrees by specifying arbitrary weights to the neighbors; and (3) the model is directly applicable to inductive learning problems, including tasks where the model has to generalize to completely unseen graphs. We validate the proposed approach on four challenging benchmarks: Cora, Citeseer and Pubmed citation networks as well as an inductive protein-protein interaction dataset, achieving or matching state-of-the-art results that highlight the potential of attention-based models when dealing with arbitrarily structured graphs.
受此启发,我们引入一种基于注意力的架构,对图结构数据做节点分类:按自注意力策略,让每个节点对邻居做注意力聚合,以计算其隐表示。该注意力架构有若干有趣性质:(1)运算高效,可在节点–邻居对上并行;(2)可为度数不同的节点指定任意邻居权重;(3)可直接用于归纳学习,包括必须泛化到完全未见过的图的任务。我们在四个有挑战性的基准上验证:Cora、Citeseer、Pubmed 引文网络以及归纳式蛋白质–蛋白质相互作用数据集,达到或持平当时最优结果,凸显注意力模型处理任意结构图的潜力。
It is worth noting that, as Kipf & Welling (2017) and Atwood & Towsley (2016), our work can also be reformulated as a particular instance of MoNet (Monti et al., 2016). Moreover, our approach of sharing a neural network computation across edges is reminiscent of the formulation of relational networks (Santoro et al., 2017) and VAIN (Hoshen, 2017), wherein relations between objects or agents are aggregated pair-wise, by employing a shared mechanism. Similarly, our proposed attention model can be connected to the works by Duan et al. (2017) and Denil et al. (2017), which use a neighborhood attention operation to compute attention coefficients between different objects in an environment. Other related approaches include locally linear embedding (LLE) (Roweis & Saul, 2000) and memory networks (Weston et al., 2014). LLE selects a fixed number of neighbors around each data point, and learns a weight coefficient for each neighbor to reconstruct each point as a weighted sum of its neighbors. A second optimization step extracts the point’s feature embedding. Memory networks also share some connections with our work, in particular, if we interpret the neighborhood of a node as the memory, which is used to compute the node features by attending over its values, and then is updated by storing the new features in the same position.
值得一提的是,与 Kipf & Welling(2017)及 Atwood & Towsley(2016)类似,我们的工作也可重述为 MoNet(Monti et al., 2016)的特例。此外,跨边共享神经网络计算的做法,与关系网络(Santoro et al., 2017)和 VAIN(Hoshen, 2017)的表述相近:对象或智能体之间的关系按对聚合,并共用一套机制。我们的注意力模型也可与 Duan et al.(2017)、Denil et al.(2017)联系起来——他们用邻域注意力在环境中不同对象间计算注意力系数。其他相关思路还包括局部线性嵌入(LLE)(Roweis & Saul, 2000)与记忆网络(Weston et al., 2014)。LLE 在每个数据点周围选取固定数目邻居,为每个邻居学习权重系数,把该点重建为邻居的加权和,再经第二步优化得到特征嵌入。若把节点邻域视为记忆,通过对其取值做注意力来计算节点特征、再把新特征写回同一位置,则记忆网络与本文也有相通之处。
2 GAT architecture
2 GAT 架构
In this section, we will present the building block layer used to construct arbitrary graph attention networks (through stacking this layer), and directly outline its theoretical and practical benefits and limitations compared to prior work in the domain of neural graph processing.
本节给出构建任意图注意力网络所用的基本层(通过堆叠该层实现),并直接对照此前神经图处理工作,概述其理论与实践上的收益与局限。
2.1 Graph attentional layer
2.1 图注意力层
We will start by describing a single graph attentional layer, as the sole layer utilized throughout all of the GAT architectures used in our experiments. The particular attentional setup utilized by us closely follows the work of Bahdanau et al. (2015)—but the framework is agnostic to the particular choice of attention mechanism.
我们首先描述单个图注意力层——实验中所有 GAT 架构都只用这一层作为基本构件。我们采用的注意力设定紧密遵循 Bahdanau et al.(2015),但框架本身对具体注意力机制的选择无关。
The input to our layer is a set of node features, , where is the number of nodes, and is the number of features in each node. The layer produces a new set of node features (of potentially different cardinality ), , as its output.
层的输入是一组节点特征 ,其中 为节点数, 为每个节点的特征维数。层输出一组新的节点特征(维数可为不同的 ):。
In order to obtain sufficient expressive power to transform the input features into higher-level features, at least one learnable linear transformation is required. To that end, as an initial step, a shared linear transformation, parametrized by a weight matrix, , is applied to every node. We then perform self-attention on the nodes—a shared attentional mechanism computes attention coefficients
为使输入特征具备足够表达力以变换到更高层特征,至少需要一次可学习的线性变换。因此,作为第一步,对每个节点施加由权重矩阵 参数化的共享线性变换。随后在节点上做自注意力——共享注意力机制 计算注意力系数
that indicate the importance of node ’s features to node . In its most general formulation, the model allows every node to attend on every other node, dropping all structural information. We inject the graph structure into the mechanism by performing masked attention—we only compute for nodes , where is some neighborhood of node in the graph. In all our experiments, these will be exactly the first-order neighbors of (including ). To make coefficients easily comparable across different nodes, we normalize them across all choices of using the softmax function:
用以刻画节点 的特征对节点 的重要性。在最一般的形式下,模型允许每个节点关注所有其他节点,从而丢掉全部结构信息。我们通过掩码注意力把图结构注入机制:仅对 的节点计算 ,其中 是图中节点 的某个邻域。实验中该邻域恰为 的一阶邻居(含 自身)。为使不同节点间的系数可比较,我们用 softmax 在所有 的选择上归一化:
In our experiments, the attention mechanism is a single-layer feedforward neural network, parametrized by a weight vector , and applying the LeakyReLU nonlinearity (with negative input slope ). Fully expanded out, the coefficients computed by the attention mechanism (illustrated by Figure 1 (left)) may then be expressed as:
实验中,注意力机制 是单层前馈网络,由权重向量 参数化,并施加 LeakyReLU 非线性(负输入斜率为 )。完全展开后,注意力机制(见图 1 左)算出的系数可写为:
where represents transposition and is the concatenation operation.
其中 表示转置, 为拼接运算。
Once obtained, the normalized attention coefficients are used to compute a linear combination of the features corresponding to them, to serve as the final output features for every node (after potentially applying a nonlinearity, ):
得到归一化注意力系数后,用它们对相应特征做线性组合,作为每个节点的最终输出特征(之后可再施加非线性 ):
To stabilize the learning process of self-attention, we have found extending our mechanism to employ multi-head attention to be beneficial, similarly to Vaswani et al. (2017). Specifically, independent attention mechanisms execute the transformation of Equation 4, and then their features are concatenated, resulting in the following output feature representation:
为稳定自注意力的学习过程,我们发现把机制扩展为多头注意力有益,做法类似 Vaswani et al.(2017)。具体地, 个独立注意力机制各自执行式 4 的变换,再将其特征拼接,得到如下输出特征表示:
where represents concatenation, are normalized attention coefficients computed by the -th attention mechanism (), and is the corresponding input linear transformation’s weight matrix. Note that, in this setting, the final returned output, , will consist of features (rather than ) for each node.
其中 表示拼接, 是第 个注意力机制()算出的归一化系数, 是对应输入线性变换的权重矩阵。注意在此设定下,最终返回的 对每个节点含 维特征(而非 )。
Specially, if we perform multi-head attention on the final (prediction) layer of the network, concatenation is no longer sensible—instead, we employ averaging, and delay applying the final nonlinearity (usually a softmax or logistic sigmoid for classification problems) until then:
特别地,若在网络最后(预测)层做多头注意力,拼接不再合适——我们改为取平均,并把最终非线性(分类问题中通常为 softmax 或 logistic sigmoid)推迟到平均之后:
The aggregation process of a multi-head graph attentional layer is illustrated by Figure 1 (right).
多头图注意力层的聚合过程见图 1(右)。
Figure 1: Left: The attention mechanism employed by our model, parametrized by a weight vector , applying a LeakyReLU activation. Right: An illustration of multi-head attention (with heads) by node 1 on its neighborhood. Different arrow styles and colors denote independent attention computations. The aggregated features from each head are concatenated or averaged to obtain .
图 1:左: 模型所用注意力机制 ,由权重向量 参数化,并施加 LeakyReLU 激活。右: 节点 1 对其邻域的多头注意力示意( 头)。不同箭头样式与颜色表示独立的注意力计算。各头聚合特征经拼接或平均得到 。
2.2 Comparisons to related work
2.2 与相关工作的比较
The graph attentional layer described in subsection 2.1 directly addresses several issues that were present in prior approaches to modelling graph-structured data with neural networks:
2.1 节描述的图注意力层直接应对了此前用神经网络建模图结构数据时的若干问题:
- • Computationally, it is highly efficient: the operation of the self-attentional layer can be parallelized across all edges, and the computation of output features can be parallelized across all nodes. No eigendecompositions or similar costly matrix operations are required. The time complexity of a single GAT attention head computing features may be expressed as , where is the number of input features, and and are the numbers of nodes and edges in the graph, respectively. This complexity is on par with the baseline methods such as Graph Convolutional Networks (GCNs) (Kipf & Welling, 2017). Applying multi-head attention multiplies the storage and parameter requirements by a factor of , while the individual heads’ computations are fully independent and can be parallelized.
- • As opposed to GCNs, our model allows for (implicitly) assigning different importances to nodes of a same neighborhood, enabling a leap in model capacity. Furthermore, analyzing the learned attentional weights may lead to benefits in interpretability, as was the case in the machine translation domain (e.g. the qualitative analysis of Bahdanau et al. (2015)).
- • The attention mechanism is applied in a shared manner to all edges in the graph, and therefore it does not depend on upfront access to the global graph structure or (features of) all of its nodes (a limitation of many prior techniques). This has several desirable implications: – The graph is not required to be undirected (we may simply leave out computing if edge is not present). – It makes our technique directly applicable to inductive learning—including tasks where the model is evaluated on graphs that are completely unseen during training.
- • The recently published inductive method of Hamilton et al. (2017) samples a fixed-size neighborhood of each node, in order to keep its computational footprint consistent; this does not allow it access to the entirety of the neighborhood while performing inference. Moreover, this technique achieved some of its strongest results when an LSTM (Hochreiter & Schmidhuber, 1997)-based neighborhood aggregator is used. This assumes the existence of a consistent sequential node ordering across neighborhoods, and the authors have rectified it by consistently feeding randomly-ordered sequences to the LSTM. Our technique does not suffer from either of these issues—it works with the entirety of the neighborhood (at the expense of a variable computational footprint, which is still on-par with methods like the GCN), and does not assume any ordering within it.
- • As mentioned in Section 1, GAT can be reformulated as a particular instance of MoNet (Monti et al., 2016). More specifically, setting the pseudo-coordinate function to be , where represent (potentially MLP-transformed) features of node and is concatenation; and the weight function to be (with the softmax performed over the entire neighborhood of a node) would make MoNet’s patch operator similar to ours. Nevertheless, one should note that, in comparison to previously considered MoNet instances, our model uses node features for similarity computations, rather than the node’s structural properties (which would assume knowing the graph structure upfront).
- • 计算上高度高效:自注意力层可在所有边上并行,输出特征可在所有节点上并行。不需要特征分解或类似昂贵的矩阵运算。单个 GAT 注意力头计算 维特征的时间复杂度可写为 ,其中 为输入特征维,、 分别为图中节点数与边数。该复杂度与图卷积网络(GCN)(Kipf & Welling, 2017)等基线相当。采用多头注意力会使存储与参数需求乘以 ,但各头计算完全独立、可并行。
- • 相对 GCN,我们的模型可(隐式地)为同一邻域内的节点赋予不同重要性,从而提升模型容量。此外,分析学到的注意力权重或可带来可解释性收益,一如机器翻译领域(例如 Bahdanau et al.(2015)的定性分析)。
- • 注意力机制以共享方式施加于图中所有边,因此不依赖事先获得全局图结构或全部节点(特征)——这是许多先前技术的限制。由此带来若干合意含义:– 图不必是无向的(若边 不存在,只需跳过计算 )。– 技术可直接用于归纳学习——包括在训练中完全未见的图上评估的任务。
- • Hamilton et al.(2017)近期发表的归纳方法对每个节点采样固定大小邻域以保持计算足迹一致,推理时因而无法访问完整邻域。此外,该方法在部分最强结果中使用基于 LSTM(Hochreiter & Schmidhuber, 1997)的邻域聚合器,这假定邻域间存在一致的节点序列顺序;作者通过始终向 LSTM 喂入随机打乱的序列加以修正。我们的技术不受这两点困扰——它使用完整邻域(代价是可变的计算足迹,仍与 GCN 等方法相当),且不假定邻域内有任何顺序。
- • 如第 1 节所述,GAT 可重述为 MoNet(Monti et al., 2016)的特例。更具体地,令伪坐标函数为 ,其中 表示节点 的(可能经 MLP 变换的)特征, 为拼接;权重函数为 (softmax 在整个邻域上执行),则 MoNet 的 patch 算子与我们的相近。不过相对此前考虑的 MoNet 实例,我们的模型用节点特征做相似度计算,而非节点的结构属性(后者会假定事先知道图结构)。
We were able to produce a version of the GAT layer that leverages sparse matrix operations, reducing the storage complexity to linear in the number of nodes and edges and enabling the execution of GAT models on larger graph datasets. However, the tensor manipulation framework we used only supports sparse matrix multiplication for rank-2 tensors, which limits the batching capabilities of the layer as it is currently implemented (especially for datasets with multiple graphs). Appropriately addressing this constraint is an important direction for future work. Depending on the regularity of the graph structure in place, GPUs may not be able to offer major performance benefits compared to CPUs in these sparse scenarios. It should also be noted that the size of the “receptive field” of our model is upper-bounded by the depth of the network (similarly as for GCN and similar models). Techniques such as skip connections (He et al., 2016) could be readily applied for appropriately extending the depth, however. Lastly, parallelization across all the graph edges, especially in a distributed manner, may involve a lot of redundant computation, as the neighborhoods will often highly overlap in graphs of interest.
我们做出了利用稀疏矩阵运算的 GAT 层版本,把存储复杂度降到与节点数、边数成线性,从而能在更大图数据集上运行 GAT。但所用张量框架仅支持秩为 2 的稀疏矩阵乘法,限制了当前实现的批处理能力(尤其对含多图的数据集)。恰当解决这一约束是未来工作的重要方向。视图结构规则程度而定,稀疏场景下 GPU 相对 CPU 未必有明显性能优势。还应指出,我们模型的「感受野」大小以上界受网络深度约束(与 GCN 及类似模型相同);跳跃连接(He et al., 2016)等技术可直接用于适当加深网络。最后,尤其在分布式设定下,跨所有图边并行可能带来大量冗余计算,因为感兴趣的图中邻域往往高度重叠。
3 Evaluation
3 评估
We have performed comparative evaluation of GAT models against a wide variety of strong baselines and previous approaches, on four established graph-based benchmark tasks (transductive as well as inductive), achieving or matching state-of-the-art performance across all of them. This section summarizes our experimental setup, results, and a brief qualitative analysis of a GAT model’s extracted feature representations.
我们在四个成熟的图基准任务(含直推与归纳)上,把 GAT 与多种强基线及先前方法做了对比评估,在全部任务上达到或持平当时最优表现。本节概述实验设定、结果,以及对 GAT 提取特征表示的简要定性分析。
| Cora | Citeseer | Pubmed | PPI | |
|---|---|---|---|---|
| Task | Transductive | Transductive | Transductive | Inductive |
| # Nodes | 2708 (1 graph) | 3327 (1 graph) | 19717 (1 graph) | 56944 (24 graphs) |
| # Edges | 5429 | 4732 | 44338 | 818716 |
| # Features/Node | 1433 | 3703 | 500 | 50 |
| # Classes | 7 | 6 | 3 | 121 (multilabel) |
| # Training Nodes | 140 | 120 | 60 | 44906 (20 graphs) |
| # Validation Nodes | 500 | 500 | 500 | 6514 (2 graphs) |
| # Test Nodes | 1000 | 1000 | 1000 | 5524 (2 graphs) |
Table 1: Summary of the datasets used in our experiments.
| Cora | Citeseer | Pubmed | PPI | |
|---|---|---|---|---|
| 任务 | 直推 | 直推 | 直推 | 归纳 |
| 节点数 | 2708(1 图) | 3327(1 图) | 19717(1 图) | 56944(24 图) |
| 边数 | 5429 | 4732 | 44338 | 818716 |
| 每节点特征数 | 1433 | 3703 | 500 | 50 |
| 类别数 | 7 | 6 | 3 | 121(多标签) |
| 训练节点数 | 140 | 120 | 60 | 44906(20 图) |
| 验证节点数 | 500 | 500 | 500 | 6514(2 图) |
| 测试节点数 | 1000 | 1000 | 1000 | 5524(2 图) |
表 1:实验所用数据集概览。
3.1 Datasets
3.1 数据集
Transductive learning
We utilize three standard citation network benchmark datasets—Cora, Citeseer and Pubmed (Sen et al., 2008)—and closely follow the transductive experimental setup of Yang et al. (2016). In all of these datasets, nodes correspond to documents and edges to (undirected) citations. Node features correspond to elements of a bag-of-words representation of a document. Each node has a class label. We allow for only 20 nodes per class to be used for training—however, honoring the transductive setup, the training algorithm has access to all of the nodes’ feature vectors. The predictive power of the trained models is evaluated on 1000 test nodes, and we use 500 additional nodes for validation purposes (the same ones as used by Kipf & Welling (2017)). The Cora dataset contains 2708 nodes, 5429 edges, 7 classes and 1433 features per node. The Citeseer dataset contains 3327 nodes, 4732 edges, 6 classes and 3703 features per node. The Pubmed dataset contains 19717 nodes, 44338 edges, 3 classes and 500 features per node.
直推学习
我们使用三个标准引文网络基准——Cora、Citeseer 与 Pubmed(Sen et al., 2008)——并紧随 Yang et al.(2016)的直推实验设定。这些数据集中,节点对应文档,边对应(无向)引用;节点特征是文档的词袋表示元素;每个节点有一个类别标签。每类仅允许 20 个节点用于训练——但遵从直推设定,训练算法可访问所有节点的特征向量。在 1000 个测试节点上评估预测力,另用 500 个节点做验证(与 Kipf & Welling(2017)所用相同)。Cora 含 2708 节点、5429 边、7 类、每节点 1433 维特征;Citeseer 含 3327 节点、4732 边、6 类、每节点 3703 维特征;Pubmed 含 19717 节点、44338 边、3 类、每节点 500 维特征。
Inductive learning
We make use of a protein-protein interaction (PPI) dataset that consists of graphs corresponding to different human tissues (Zitnik & Leskovec, 2017). The dataset contains 20 graphs for training, 2 for validation and 2 for testing. Critically, testing graphs remain completely unobserved during training. To construct the graphs, we used the preprocessed data provided by Hamilton et al. (2017). The average number of nodes per graph is 2372. Each node has 50 features that are composed of positional gene sets, motif gene sets and immunological signatures. There are 121 labels for each node set from gene ontology, collected from the Molecular Signatures Database (Subramanian et al., 2005), and a node can possess several labels simultaneously.
归纳学习
我们使用蛋白质–蛋白质相互作用(PPI)数据集,其图对应不同人体组织(Zitnik & Leskovec, 2017)。数据集含 20 张训练图、2 张验证图与 2 张测试图。关键在于:测试图在训练期间完全不可见。构图使用 Hamilton et al.(2017)提供的预处理数据。每图平均约 2372 个节点;每个节点有 50 维特征,由位置基因集、基序基因集与免疫签名组成。每个节点集合有来自基因本体的 121 个标签(取自 Molecular Signatures Database,Subramanian et al., 2005),一个节点可同时拥有多个标签。
An overview of the interesting characteristics of the datasets is given in Table 1.
数据集的主要特征概览见表 1。
3.2 State-of-the-art methods
3.2 当时最优方法
Transductive learning
For transductive learning tasks, we compare against the same strong baselines and state-of-the-art approaches as specified in Kipf & Welling (2017). This includes label propagation (LP) (Zhu et al., 2003), semi-supervised embedding (SemiEmb) (Weston et al., 2012), manifold regularization (ManiReg) (Belkin et al., 2006), skip-gram based graph embeddings (DeepWalk) (Perozzi et al., 2014), the iterative classification algorithm (ICA) (Lu & Getoor, 2003) and Planetoid (Yang et al., 2016). We also directly compare our model against GCNs (Kipf & Welling, 2017), as well as graph convolutional models utilising higher-order Chebyshev filters (Defferrard et al., 2016), and the MoNet model presented in Monti et al. (2016).
直推学习
对直推任务,我们对照 Kipf & Welling(2017)所列的同一组强基线与当时最优方法,包括标签传播(LP)(Zhu et al., 2003)、半监督嵌入(SemiEmb)(Weston et al., 2012)、流形正则(ManiReg)(Belkin et al., 2006)、基于 skip-gram 的图嵌入(DeepWalk)(Perozzi et al., 2014)、迭代分类算法(ICA)(Lu & Getoor, 2003)以及 Planetoid(Yang et al., 2016)。我们也直接与 GCN(Kipf & Welling, 2017)、使用高阶切比雪夫滤波器的图卷积模型(Defferrard et al., 2016)以及 Monti et al.(2016)的 MoNet 对比。
Inductive learning
For the inductive learning task, we compare against the four different supervised GraphSAGE inductive methods presented in Hamilton et al. (2017). These provide a variety of approaches to aggregating features within a sampled neighborhood: GraphSAGE-GCN (which extends a graph convolution-style operation to the inductive setting), GraphSAGE-mean (taking the elementwise mean value of feature vectors), GraphSAGE-LSTM (aggregating by feeding the neighborhood features into an LSTM) and GraphSAGE-pool (taking the elementwise maximization operation of feature vectors transformed by a shared nonlinear multilayer perceptron). The other transductive approaches are either completely inappropriate in an inductive setting or assume that nodes are incrementally added to a single graph, making them unusable for the setup where test graphs are completely unseen during training (such as the PPI dataset).
归纳学习
对归纳任务,我们对照 Hamilton et al.(2017)提出的四种有监督 GraphSAGE 归纳方法。它们在采样邻域内聚合特征的方式各异:GraphSAGE-GCN(把类图卷积运算推广到归纳设定)、GraphSAGE-mean(对特征向量逐元素取均值)、GraphSAGE-LSTM(把邻域特征送入 LSTM 聚合)以及 GraphSAGE-pool(对经共享非线性多层感知机变换后的特征向量逐元素取最大)。其他直推方法要么完全不适于归纳设定,要么假定节点逐步加入单张图,因而无法用于测试图在训练中完全未见的设定(如 PPI 数据集)。
Additionally, for both tasks we provide the performance of a per-node shared multilayer perceptron (MLP) classifier (that does not incorporate graph structure at all).
此外,对两类任务我们都给出按节点共享的多层感知机(MLP)分类器表现(完全不利用图结构)。
3.3 Experimental setup
3.3 实验设定
Transductive learning
For the transductive learning tasks, we apply a two-layer GAT model. Its architectural hyperparameters have been optimized on the Cora dataset and are then reused for Citeseer. The first layer consists of attention heads computing features each (for a total of 64 features), followed by an exponential linear unit (ELU) (Clevert et al., 2016) nonlinearity. The second layer is used for classification: a single attention head that computes features (where is the number of classes), followed by a softmax activation. For coping with the small training set sizes, regularization is liberally applied within the model. During training, we apply regularization with . Furthermore, dropout (Srivastava et al., 2014) with is applied to both layers’ inputs, as well as to the normalized attention coefficients (critically, this means that at each training iteration, each node is exposed to a stochastically sampled neighborhood). Similarly as observed by Monti et al. (2016), we found that Pubmed’s training set size (60 examples) required slight changes to the GAT architecture: we have applied output attention heads (instead of one), and strengthened the regularization to . Otherwise, the architecture matches the one used for Cora and Citeseer.
直推学习
对直推任务,我们使用两层 GAT。架构超参在 Cora 上优化后复用于 Citeseer。第一层含 个注意力头,每头计算 维特征(合计 64 维),后接指数线性单元(ELU)(Clevert et al., 2016)非线性。第二层用于分类:单个注意力头计算 维特征( 为类别数),后接 softmax。为应对训练集约小,模型中较充分地施加正则:训练时用 的 正则;并对两层的输入以及归一化注意力系数施加 的 dropout(Srivastava et al., 2014)(关键在于:每次训练迭代中,每个节点看到的是随机采样的邻域)。与 Monti et al.(2016)的观察类似,我们发现 Pubmed 的训练集规模(60 例)需要对 GAT 架构略作调整:输出注意力头改为 (而非 1),并把 加强到 ;其余与 Cora、Citeseer 所用架构一致。
Inductive learning
For the inductive learning task, we apply a three-layer GAT model. Both of the first two layers consist of attention heads computing features (for a total of 1024 features), followed by an ELU nonlinearity. The final layer is used for (multi-label) classification: attention heads computing 121 features each, that are averaged and followed by a logistic sigmoid activation. The training sets for this task are sufficiently large and we found no need to apply regularization or dropout—we have, however, successfully employed skip connections (He et al., 2016) across the intermediate attentional layer. We utilize a batch size of 2 graphs during training. To strictly evaluate the benefits of applying an attention mechanism in this setting (i.e. comparing with a near GCN-equivalent model), we also provide the results when a constant attention mechanism, , is used, with the same architecture—this will assign the same weight to every neighbor.
归纳学习
对归纳任务,我们使用三层 GAT。前两层各含 个注意力头,每头计算 维特征(合计 1024 维),后接 ELU。最后一层用于(多标签)分类: 个注意力头各算 121 维特征,取平均后接 logistic sigmoid。该任务训练集足够大,我们未使用 正则或 dropout——但在中间注意力层成功加入了跳跃连接(He et al., 2016)。训练批大小为 2 张图。为严格评估注意力机制在此设定下的收益(即与近乎等价于 GCN 的模型对比),我们还报告在同一架构下使用常数注意力机制 的结果——这会对每个邻居赋予相同权重。
Both models are initialized using Glorot initialization (Glorot & Bengio, 2010) and trained to minimize cross-entropy on the training nodes using the Adam SGD optimizer (Kingma & Ba, 2014) with an initial learning rate of 0.01 for Pubmed, and 0.005 for all other datasets. In both cases we use an early stopping strategy on both the cross-entropy loss and accuracy (transductive) or micro-F1 (inductive) score on the validation nodes, with a patience of 100 epochs[^1].
两个模型均用 Glorot 初始化(Glorot & Bengio, 2010),并以 Adam SGD 优化器(Kingma & Ba, 2014)在训练节点上最小化交叉熵;Pubmed 初始学习率为 0.01,其余数据集为 0.005。两种情形下,我们都对验证节点上的交叉熵损失与准确率(直推)或 micro-F1(归纳)采用早停,耐心为 100 个 epoch[^1]。
| Transductive | |||
|---|---|---|---|
| Method | Cora | Citeseer | Pubmed |
| MLP | 55.1% | 46.5% | 71.4% |
| ManiReg (Belkin et al., 2006) | 59.5% | 60.1% | 70.7% |
| SemiEmb (Weston et al., 2012) | 59.0% | 59.6% | 71.7% |
| LP (Zhu et al., 2003) | 68.0% | 45.3% | 63.0% |
| DeepWalk (Perozzi et al., 2014) | 67.2% | 43.2% | 65.3% |
| ICA (Lu & Getoor, 2003) | 75.1% | 69.1% | 73.9% |
| Planetoid (Yang et al., 2016) | 75.7% | 64.7% | 77.2% |
| Chebyshev (Defferrard et al., 2016) | 81.2% | 69.8% | 74.4% |
| GCN (Kipf & Welling, 2017) | 81.5% | 70.3% | 79.0% |
| MoNet (Monti et al., 2016) | 81.7 0.5% | — | 78.8 0.3% |
| GCN-64∗ | 81.4 0.5% | 70.9 0.5% | 79.0 0.3% |
| GAT (ours) | 83.0 0.7% | 72.5 0.7% | 79.0 0.3% |
Table 2: Summary of results in terms of classification accuracies, for Cora, Citeseer and Pubmed. GCN-64∗ corresponds to the best GCN result computing 64 hidden features (using ReLU or ELU).
| 直推 | |||
|---|---|---|---|
| 方法 | Cora | Citeseer | Pubmed |
| MLP | 55.1% | 46.5% | 71.4% |
| ManiReg (Belkin et al., 2006) | 59.5% | 60.1% | 70.7% |
| SemiEmb (Weston et al., 2012) | 59.0% | 59.6% | 71.7% |
| LP (Zhu et al., 2003) | 68.0% | 45.3% | 63.0% |
| DeepWalk (Perozzi et al., 2014) | 67.2% | 43.2% | 65.3% |
| ICA (Lu & Getoor, 2003) | 75.1% | 69.1% | 73.9% |
| Planetoid (Yang et al., 2016) | 75.7% | 64.7% | 77.2% |
| Chebyshev (Defferrard et al., 2016) | 81.2% | 69.8% | 74.4% |
| GCN (Kipf & Welling, 2017) | 81.5% | 70.3% | 79.0% |
| MoNet (Monti et al., 2016) | 81.7 0.5% | — | 78.8 0.3% |
| GCN-64∗ | 81.4 0.5% | 70.9 0.5% | 79.0 0.3% |
| GAT (ours) | 83.0 0.7% | 72.5 0.7% | 79.0 0.3% |
表 2:Cora、Citeseer、Pubmed 上的分类准确率汇总。GCN-64∗ 为计算 64 维隐特征的最佳 GCN 结果(ReLU 或 ELU)。
| Inductive | |
|---|---|
| Method | PPI |
| Random | 0.396 |
| MLP | 0.422 |
| GraphSAGE-GCN (Hamilton et al., 2017) | 0.500 |
| GraphSAGE-mean (Hamilton et al., 2017) | 0.598 |
| GraphSAGE-LSTM (Hamilton et al., 2017) | 0.612 |
| GraphSAGE-pool (Hamilton et al., 2017) | 0.600 |
| GraphSAGE∗ | 0.768 |
| Const-GAT (ours) | 0.934 0.006 |
| GAT (ours) | 0.973 0.002 |
Table 3: Summary of results in terms of micro-averaged F1 scores, for the PPI dataset. GraphSAGE∗ corresponds to the best GraphSAGE result we were able to obtain by just modifying its architecture. Const-GAT corresponds to a model with the same architecture as GAT, but with a constant attention mechanism (assigning same importance to each neighbor; GCN-like inductive operator).
| 归纳 | |
|---|---|
| 方法 | PPI |
| Random | 0.396 |
| MLP | 0.422 |
| GraphSAGE-GCN (Hamilton et al., 2017) | 0.500 |
| GraphSAGE-mean (Hamilton et al., 2017) | 0.598 |
| GraphSAGE-LSTM (Hamilton et al., 2017) | 0.612 |
| GraphSAGE-pool (Hamilton et al., 2017) | 0.600 |
| GraphSAGE∗ | 0.768 |
| Const-GAT (ours) | 0.934 0.006 |
| GAT (ours) | 0.973 0.002 |
表 3:PPI 数据集上的 micro 平均 F1 汇总。GraphSAGE∗ 为我们仅改架构所能得到的最佳 GraphSAGE 结果。Const-GAT 与 GAT 架构相同,但使用常数注意力机制(对每个邻居赋予相同重要性;类 GCN 的归纳算子)。
3.4 Results
3.4 结果
The results of our comparative evaluation experiments are summarized in Tables 2 and 3.
对比评估实验的结果汇总于表 2 与表 3。
For the transductive tasks, we report the mean classification accuracy (with standard deviation) on the test nodes of our method after 100 runs, and reuse the metrics already reported in Kipf & Welling (2017) and Monti et al. (2016) for state-of-the-art techniques. Specifically, for the Chebyshev filter-based approach (Defferrard et al., 2016), we provide the maximum reported performance for filters of orders and . In order to fairly assess the benefits of the attention mechanism, we further evaluate a GCN model that computes 64 hidden features, attempting both the ReLU and ELU activation, and reporting (as GCN-64∗) the better result after 100 runs (which was the ReLU in all three cases).
对直推任务,我们报告方法在测试节点上经 100 次运行后的平均分类准确率(含标准差),并复用 Kipf & Welling(2017)与 Monti et al.(2016)已报告的当时最优方法指标。具体地,对基于切比雪夫滤波器的方法(Defferrard et al., 2016),我们给出阶数 与 滤波器中报告的最高表现。为公平评估注意力机制的收益,我们还评估计算 64 维隐特征的 GCN,分别尝试 ReLU 与 ELU,并报告(记为 GCN-64∗)100 次运行后的较好结果(三种情形下均为 ReLU)。
For the inductive task, we report the micro-averaged F1 score on the nodes of the two unseen test graphs, averaged after 10 runs, and reuse the metrics already reported in Hamilton et al. (2017) for the other techniques. Specifically, as our setup is supervised, we compare against the supervised GraphSAGE approaches. To evaluate the benefits of aggregating across the entire neighborhood, we further provide (as GraphSAGE∗) the best result we were able to achieve with GraphSAGE by just modifying its architecture (this was with a three-layer GraphSAGE-LSTM with [512, 512, 726] features computed in each layer and 128 features used for aggregating neighborhoods). Finally, we report the 10-run result of our constant attention GAT model (as Const-GAT), to fairly evaluate the benefits of the attention mechanism against a GCN-like aggregation scheme (with the same architecture).
对归纳任务,我们报告两张未见测试图节点上的 micro 平均 F1,经 10 次运行取平均,并复用 Hamilton et al.(2017)已报告的其他方法指标。由于我们的设定是有监督的,对照有监督 GraphSAGE 方法。为评估在完整邻域上聚合的收益,我们另给出(记为 GraphSAGE∗)仅改架构所能得到的最佳 GraphSAGE 结果(三层 GraphSAGE-LSTM,各层特征为 [512, 512, 726],邻域聚合用 128 维特征)。最后,我们报告常数注意力 GAT(记为 Const-GAT)的 10 次运行结果,以公平对照注意力机制相对类 GCN 聚合方案(同架构)的收益。
Our results successfully demonstrate state-of-the-art performance being achieved or matched across all four datasets—in concordance with our expectations, as per the discussion in Section 2.2. More specifically, we are able to improve upon GCNs by a margin of 1.5% and 1.6% on Cora and Citeseer, respectively, suggesting that assigning different weights to nodes of a same neighborhood may be beneficial. It is worth noting the improvements achieved on the PPI dataset: Our GAT model improves by 20.5% w.r.t. the best GraphSAGE result we were able to obtain, demonstrating that our model has the potential to be applied in inductive settings, and that larger predictive power can be leveraged by observing the entire neighborhood. Furthermore, it improves by 3.9% w.r.t. Const-GAT (the identical architecture with constant attention mechanism), once again directly demonstrating the significance of being able to assign different weights to different neighbors.
结果成功表明:在全部四个数据集上达到或持平当时最优——与第 2.2 节讨论中的预期一致。更具体地,相对 GCN,我们在 Cora 与 Citeseer 上分别提升 1.5% 与 1.6%,提示为同一邻域内节点赋予不同权重可能有益。PPI 上的提升尤值注意:相对我们所能得到的最佳 GraphSAGE 结果,GAT 提升 20.5%,表明模型有潜力用于归纳设定,且观察完整邻域可带来更大预测力。相对 Const-GAT(同架构但常数注意力)再提升 3.9%,再次直接表明能为不同邻居赋予不同权重的重要性。
The effectiveness of the learned feature representations may also be investigated qualitatively—and for this purpose we provide a visualization of the t-SNE (Maaten & Hinton, 2008)-transformed feature representations extracted by the first layer of a GAT model pre-trained on the Cora dataset (Figure 2). The representation exhibits discernible clustering in the projected 2D space. Note that these clusters correspond to the seven labels of the dataset, verifying the model’s discriminative power across the seven topic classes of Cora. Additionally, we visualize the relative strengths of the normalized attention coefficients (averaged across all eight attention heads). Properly interpreting these coefficients (as performed by e.g. Bahdanau et al. (2015)) will require further domain knowledge about the dataset under study, and is left for future work.
学到的特征表示有效性也可定性考察——为此我们给出在 Cora 上预训练的 GAT 第一层特征经 t-SNE(Maaten & Hinton, 2008)变换后的可视化(图 2)。投影到二维空间后可见清晰聚类;这些簇对应数据集的七个标签,印证模型对 Cora 七个主题类的判别力。我们还可视化归一化注意力系数的相对强度(对全部八个注意力头取平均)。恰当解释这些系数(如 Bahdanau et al.(2015)所做)需要对该数据集更多领域知识,留待未来工作。
4 Conclusions
4 结论
We have presented graph attention networks (GATs), novel convolution-style neural networks that operate on graph-structured data, leveraging masked self-attentional layers. The graph attentional layer utilized throughout these networks is computationally efficient (does not require costly matrix operations, and is parallelizable across all nodes in the graph), allows for (implicitly) assigning different importances to different nodes within a neighborhood while dealing with different sized neighborhoods, and does not depend on knowing the entire graph structure upfront—thus addressing many of the theoretical issues with previous spectral-based approaches. Our models leveraging attention have successfully achieved or matched state-of-the-art performance across four well-established node classification benchmarks, both transductive and inductive (especially, with completely unseen graphs used for testing).
我们提出了图注意力网络(GAT):一类在图结构数据上运行的卷积风格神经网络,借助带掩码的自注意力层。贯穿这些网络的图注意力层计算高效(不需要昂贵矩阵运算,且可在图中所有节点上并行),可(隐式地)为邻域内不同节点赋予不同重要性并处理不同大小的邻域,且不依赖事先知道整张图结构——从而应对了此前谱方法的许多理论问题。借助注意力的模型在四个成熟的节点分类基准上达到或持平当时最优,涵盖直推与归纳(尤其是测试使用完全未见的图)。
There are several potential improvements and extensions to graph attention networks that could be addressed as future work, such as overcoming the practical problems described in subsection 2.2 to be able to handle larger batch sizes. A particularly interesting research direction would be taking advantage of the attention mechanism to perform a thorough analysis on the model interpretability. Moreover, extending the method to perform graph classification instead of node classification would also be relevant from the application perspective. Finally, extending the model to incorporate edge features (possibly indicating relationship among nodes) would allow us to tackle a larger variety of problems.
图注意力网络仍有若干可改进与扩展之处,可作为未来工作:例如克服 2.2 节所述实践问题以支持更大批大小。一个特别有趣的方向是利用注意力机制对模型可解释性做深入分析。把方法从节点分类扩展到图分类,从应用角度看也相关。最后,若纳入边特征(可能指示节点间关系),将能应对更广的一类问题。
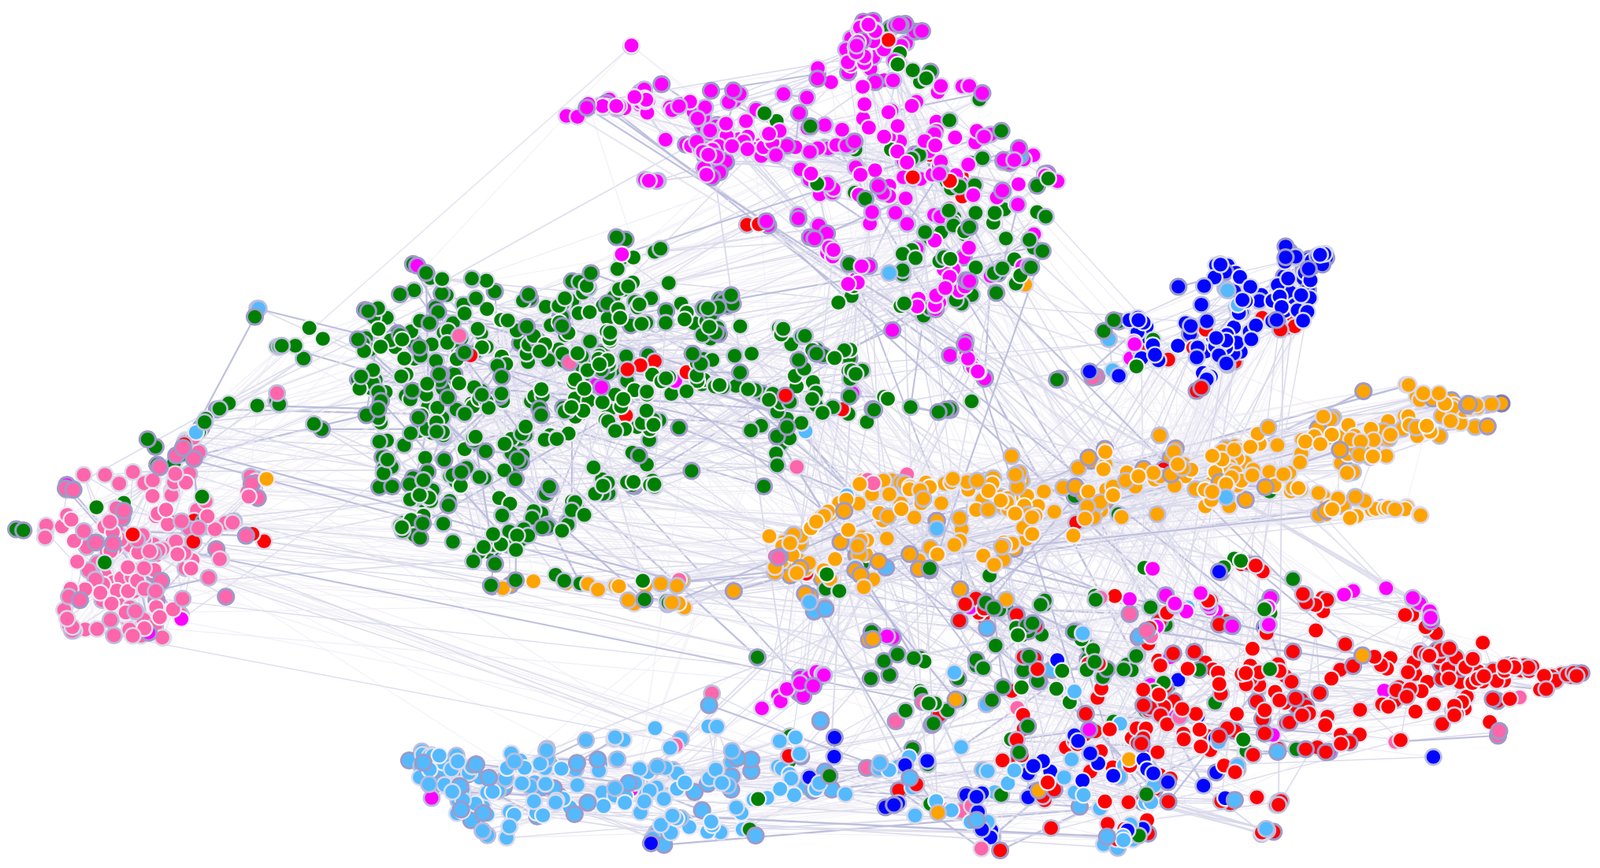
Figure 2: A t-SNE plot of the computed feature representations of a pre-trained GAT model’s first hidden layer on the Cora dataset. Node colors denote classes. Edge thickness indicates aggregated normalized attention coefficients between nodes and , across all eight attention heads .
图 2:在 Cora 上预训练的 GAT 第一隐层特征表示的 t-SNE 图。节点颜色表示类别。边粗细表示节点 与 之间、对全部八个注意力头聚合后的归一化注意力系数 。
Acknowledgements
The authors would like to thank the developers of TensorFlow (Abadi et al., 2015). PV and PL have received funding from the European Union’s Horizon 2020 research and innovation programme PROPAG-AGEING under grant agreement No 634821. We further acknowledge the support of the following agencies for research funding and computing support: CIFAR, Canada Research Chairs, Compute Canada and Calcul Québec, as well as NVIDIA for the generous GPU support. Special thanks to: Benjamin Day and Fabian Jansen for kindly pointing out issues in a previous iteration of the paper; Michał Drożdżal for useful discussions, feedback and support; and Gaétan Marceau for reviewing the paper prior to submission.
致谢
作者感谢 TensorFlow(Abadi et al., 2015)的开发者。PV 与 PL 获得欧盟 Horizon 2020 研究与创新计划 PROPAG-AGEING(资助协议 No 634821)资助。我们亦感谢下列机构在科研资助与计算支持上的帮助:CIFAR、Canada Research Chairs、Compute Canada 与 Calcul Québec,以及 NVIDIA 慷慨的 GPU 支持。特别感谢:Benjamin Day 与 Fabian Jansen 指出论文前一版本中的问题;Michał Drożdżal 提供有益讨论、反馈与支持;Gaétan Marceau 在投稿前审阅论文。
References
参考文献
Abadi et al. (2015) Martín Abadi, Ashish Agarwal, Paul Barham, Eugene Brevdo, Zhifeng Chen, Craig Citro, Greg S. Corrado, Andy Davis, Jeffrey Dean, Matthieu Devin, Sanjay Ghemawat, Ian Goodfellow, Andrew Harp, Geoffrey Irving, Michael Isard, Yangqing Jia, Rafal Jozefowicz, Lukasz Kaiser, Manjunath Kudlur, Josh Levenberg, Dan Mané, Rajat Monga, Sherry Moore, Derek Murray, Chris Olah, Mike Schuster, Jonathon Shlens, Benoit Steiner, Ilya Sutskever, Kunal Talwar, Paul Tucker, Vincent Vanhoucke, Vijay Vasudevan, Fernanda Viégas, Oriol Vinyals, Pete Warden, Martin Wattenberg, Martin Wicke, Yuan Yu, and Xiaoqiang Zheng. TensorFlow: Large-scale machine learning on heterogeneous systems, 2015. URL https://www.tensorflow.org/ . Software available from tensorflow.org.
Atwood & Towsley (2016) James Atwood and Don Towsley. Diffusion-convolutional neural networks. In Advances in Neural Information Processing Systems , pp. 1993–2001, 2016.
Bahdanau et al. (2015) Dzmitry Bahdanau, Kyunghyun Cho, and Yoshua Bengio. Neural machine translation by jointly learning to align and translate. International Conference on Learning Representations (ICLR) , 2015.
Belkin et al. (2006) Mikhail Belkin, Partha Niyogi, and Vikas Sindhwani. Manifold regularization: A geometric framework for learning from labeled and unlabeled examples. Journal of machine learning research , 7(Nov):2399–2434, 2006.
Bruna et al. (2014) Joan Bruna, Wojciech Zaremba, Arthur Szlam, and Yann LeCun. Spectral networks and locally connected networks on graphs. International Conference on Learning Representations (ICLR) , 2014.
Cheng et al. (2016) Jianpeng Cheng, Li Dong, and Mirella Lapata. Long short-term memory-networks for machine reading. arXiv preprint arXiv:1601.06733 , 2016.
Cho et al. (2014) Kyunghyun Cho, Bart Van Merriënboer, Caglar Gulcehre, Dzmitry Bahdanau, Fethi Bougares, Holger Schwenk, and Yoshua Bengio. Learning phrase representations using rnn encoder-decoder for statistical machine translation. arXiv preprint arXiv:1406.1078 , 2014.
Clevert et al. (2016) Djork-Arné Clevert, Thomas Unterthiner, and Sepp Hochreiter. Fast and accurate deep network learning by exponential linear units (elus). International Conference on Learning Representations (ICLR) , 2016.
Defferrard et al. (2016) Michaël Defferrard, Xavier Bresson, and Pierre Vandergheynst. Convolutional neural networks on graphs with fast localized spectral filtering. In Advances in Neural Information Processing Systems , pp. 3844–3852, 2016.
Denil et al. (2017) Misha Denil, Sergio Gómez Colmenarejo, Serkan Cabi, David Saxton, and Nando de Freitas. Programmable agents. arXiv preprint arXiv:1706.06383 , 2017.
Duan et al. (2017) Yan Duan, Marcin Andrychowicz, Bradly Stadie, Jonathan Ho, Jonas Schneider, Ilya Sutskever, Pieter Abbeel, and Wojciech Zaremba. One-shot imitation learning. arXiv preprint arXiv:1703.07326 , 2017.
Duvenaud et al. (2015) David K Duvenaud, Dougal Maclaurin, Jorge Iparraguirre, Rafael Bombarell, Timothy Hirzel, Alán Aspuru-Guzik, and Ryan P Adams. Convolutional networks on graphs for learning molecular fingerprints. In Advances in neural information processing systems , pp. 2224–2232, 2015.
Frasconi et al. (1998) Paolo Frasconi, Marco Gori, and Alessandro Sperduti. A general framework for adaptive processing of data structures. IEEE transactions on Neural Networks , 9(5):768–786, 1998.
Gehring et al. (2016) Jonas Gehring, Michael Auli, David Grangier, and Yann N. Dauphin. A convolutional encoder model for neural machine translation. CoRR , abs/1611.02344, 2016. URL http://arxiv.org/abs/1611.02344 .
Glorot & Bengio (2010) Xavier Glorot and Yoshua Bengio. Understanding the difficulty of training deep feedforward neural networks. In Proceedings of the Thirteenth International Conference on Artificial Intelligence and Statistics , pp. 249–256, 2010.
Gori et al. (2005) Marco Gori, Gabriele Monfardini, and Franco Scarselli. A new model for learning in graph domains. In IEEE International Joint Conference on Neural Networks , pp. 729–734, 2005.
Hamilton et al. (2017) William L Hamilton, Rex Ying, and Jure Leskovec. Inductive representation learning on large graphs. Neural Information Processing Systems (NIPS) , 2017.
He et al. (2016) Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. Deep residual learning for image recognition. In Proceedings of the IEEE conference on computer vision and pattern recognition , pp. 770–778, 2016.
Henaff et al. (2015) Mikael Henaff, Joan Bruna, and Yann LeCun. Deep convolutional networks on graph-structured data. arXiv preprint arXiv:1506.05163 , 2015.
Hochreiter & Schmidhuber (1997) Sepp Hochreiter and Jürgen Schmidhuber. Long short-term memory. Neural computation , 9(8):1735–1780, 1997.
Hoshen (2017) Yedid Hoshen. Vain: Attentional multi-agent predictive modeling. In I. Guyon, U. V. Luxburg, S. Bengio, H. Wallach, R. Fergus, S. Vishwanathan, and R. Garnett (eds.), Advances in Neural Information Processing Systems 30 , pp. 2698–2708. Curran Associates, Inc., 2017. URL http://papers.nips.cc/paper/6863-vain-attentional-multi-agent-predictive-modeling.pdf .
Jégou et al. (2017) Simon Jégou, Michal Drozdzal, David Vázquez, Adriana Romero, and Yoshua Bengio. The one hundred layers tiramisu: Fully convolutional densenets for semantic segmentation. In Workshop on Computer Vision in Vehicle Technology CVPRW , 2017.
Kingma & Ba (2014) Diederik Kingma and Jimmy Ba. Adam: A method for stochastic optimization. arXiv preprint arXiv:1412.6980 , 2014.
Kipf & Welling (2017) Thomas N Kipf and Max Welling. Semi-supervised classification with graph convolutional networks. International Conference on Learning Representations (ICLR) , 2017.
Li et al. (2016) Yujia Li, Daniel Tarlow, Marc Brockschmidt, and Richard Zemel. Gated graph sequence neural networks. International Conference on Learning Representations (ICLR) , 2016.
Lin et al. (2017) Zhouhan Lin, Minwei Feng, Cicero Nogueira dos Santos, Mo Yu, Bing Xiang, Bowen Zhou, and Yoshua Bengio. A structured self-attentive sentence embedding. arXiv preprint arXiv:1703.03130 , 2017.
Lu & Getoor (2003) Qing Lu and Lise Getoor. Link-based classification. In Proceedings of the 20th International Conference on Machine Learning (ICML-03) , pp. 496–503, 2003.
Maaten & Hinton (2008) Laurens van der Maaten and Geoffrey Hinton. Visualizing data using t-sne. Journal of Machine Learning Research , 9(Nov):2579–2605, 2008.
Monti et al. (2016) Federico Monti, Davide Boscaini, Jonathan Masci, Emanuele Rodolà, Jan Svoboda, and Michael M Bronstein. Geometric deep learning on graphs and manifolds using mixture model cnns. arXiv preprint arXiv:1611.08402 , 2016.
Niepert et al. (2016) Mathias Niepert, Mohamed Ahmed, and Konstantin Kutzkov. Learning convolutional neural networks for graphs. In Proceedings of The 33rd International Conference on Machine Learning , volume 48, pp. 2014–2023, 2016.
Perozzi et al. (2014) Bryan Perozzi, Rami Al-Rfou, and Steven Skiena. Deepwalk: Online learning of social representations. In Proceedings of the 20th ACM SIGKDD international conference on Knowledge discovery and data mining , pp. 701–710. ACM, 2014.
Roweis & Saul (2000) Sam T. Roweis and Lawrence K. Saul. Nonlinear dimensionality reduction by locally linear embedding. Science , 290:2323–2326, 2000.
Santoro et al. (2017) Adam Santoro, David Raposo, David GT Barrett, Mateusz Malinowski, Razvan Pascanu, Peter Battaglia, and Timothy Lillicrap. A simple neural network module for relational reasoning. arXiv preprint arXiv:1706.01427 , 2017.
Scarselli et al. (2009) Franco Scarselli, Marco Gori, Ah Chung Tsoi, Markus Hagenbuchner, and Gabriele Monfardini. The graph neural network model. IEEE Transactions on Neural Networks , 20(1):61–80, 2009.
Sen et al. (2008) Prithviraj Sen, Galileo Namata, Mustafa Bilgic, Lise Getoor, Brian Galligher, and Tina Eliassi-Rad. Collective classification in network data. AI magazine , 29(3):93, 2008.
Sperduti & Starita (1997) A. Sperduti and A. Starita. Supervised neural networks for the classification of structures. Trans. Neur. Netw. , 8(3):714–735, May 1997. ISSN 1045-9227. doi: 10.1109/72.572108 .
Srivastava et al. (2014) Nitish Srivastava, Geoffrey E Hinton, Alex Krizhevsky, Ilya Sutskever, and Ruslan Salakhutdinov. Dropout: a simple way to prevent neural networks from overfitting. Journal of machine learning research , 15(1):1929–1958, 2014.
Subramanian et al. (2005) Aravind Subramanian, Pablo Tamayo, Vamsi K Mootha, Sayan Mukherjee, Benjamin L Ebert, Michael A Gillette, Amanda Paulovich, Scott L Pomeroy, Todd R Golub, Eric S Lander, et al. Gene set enrichment analysis: a knowledge-based approach for interpreting genome-wide expression profiles. Proceedings of the National Academy of Sciences , 102(43):15545–15550, 2005.
Vaswani et al. (2017) Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Lukasz Kaiser, and Illia Polosukhin. Attention is all you need. arXiv preprint arXiv:1706.03762 , 2017.
Weston et al. (2012) Jason Weston, Frédéric Ratle, Hossein Mobahi, and Ronan Collobert. Deep learning via semi-supervised embedding. In Neural Networks: Tricks of the Trade , pp. 639–655. Springer, 2012.
Weston et al. (2014) Jason Weston, Sumit Chopra, and Antoine Bordes. Memory networks. CoRR , abs/1410.3916, 2014. URL http://arxiv.org/abs/1410.3916 .
Yang et al. (2016) Zhilin Yang, William Cohen, and Ruslan Salakhudinov. Revisiting semi-supervised learning with graph embeddings. In International Conference on Machine Learning , pp. 40–48, 2016.
Zhu et al. (2003) Xiaojin Zhu, Zoubin Ghahramani, and John D Lafferty. Semi-supervised learning using gaussian fields and harmonic functions. In Proceedings of the 20th International conference on Machine learning (ICML-03) , pp. 912–919, 2003.
Zitnik & Leskovec (2017) Marinka Zitnik and Jure Leskovec. Predicting multicellular function through multi-layer tissue networks. Bioinformatics , 33(14):i190–i198, 2017.