Fourier Neural Operator for Parametric Partial Differential Equations
Fourier Neural Operator for Parametric Partial Differential Equations
Published as a conference paper at ICLR 2021
发表为 ICLR 2021 会议论文
Abstract
摘要
The classical development of neural networks has primarily focused on learning mappings between finite-dimensional Euclidean spaces. Recently, this has been generalized to neural operators that learn mappings between function spaces. For partial differential equations (PDEs), neural operators directly learn the mapping from any functional parametric dependence to the solution. Thus, they learn an entire family of PDEs, in contrast to classical methods which solve one instance of the equation. In this work, we formulate a new neural operator by parameterizing the integral kernel directly in Fourier space, allowing for an expressive and efficient architecture. We perform experiments on Burgers’ equation, Darcy flow, and Navier-Stokes equation. The Fourier neural operator is the first ML-based method to successfully model turbulent flows with zero-shot super-resolution. It is up to three orders of magnitude faster compared to traditional PDE solvers. Additionally, it achieves superior accuracy compared to previous learning-based solvers under fixed resolution.
神经网络的经典发展,主要关注学习有限维欧几里得空间之间的映射。近来,这一路线被推广到神经算子,用来学习函数空间之间的映射。对偏微分方程(PDE)而言,神经算子直接学习从任意函数型参数依赖到解的映射。因此,它们学到的是一整族 PDE,而传统方法只解方程的某一个实例。本文通过把积分核直接在傅里叶空间里参数化,构造了一种新的神经算子,从而得到表达力强且高效的结构。我们在 Burgers 方程、Darcy 流和 Navier-Stokes 方程上做了实验。傅里叶神经算子是第一种能以零样本超分辨率成功建模湍流的机器学习方法。与传统 PDE 求解器相比,它最多可快三个数量级。在固定分辨率下,它也比此前基于学习的求解器更准确。
1 Introduction
1 引言
Many problems in science and engineering involve solving complex partial differential equation (PDE) systems repeatedly for different values of some parameters. Examples arise in molecular dynamics, micro-mechanics, and turbulent flows. Often such systems require fine discretization in order to capture the phenomenon being modeled. As a consequence, traditional numerical solvers are slow and sometimes inefficient. For example, when designing materials such as airfoils, one needs to solve the associated inverse problem where thousands of evaluations of the forward model are needed. A fast method can make such problems feasible.
科学与工程中的许多问题,都需要针对不同的参数取值,反复求解复杂的偏微分方程(PDE)系统。例子出现在分子动力学、微力学和湍流中。这类系统往往需要很细的离散,才能抓住所要建模的现象。于是传统数值求解器又慢,有时也效率不高。例如在设计翼型一类材料时,需要求解相应的反问题,前向模型往往要被调用上千次。如果有一种更快的方法,这类问题才变得可行。
Conventional solvers vs. Data-driven methods.
传统求解器与数据驱动方法
Traditional solvers such as finite element methods (FEM) and finite difference methods (FDM) solve the equation by discretizing the space. Therefore, they impose a trade-off on the resolution: coarse grids are fast but less accurate; fine grids are accurate but slow. Complex PDE systems, as described above, usually require a very fine discretization, and therefore very challenging and time-consuming for traditional solvers. On the other hand, data-driven methods can directly learn the trajectory of the family of equations from the data. As a result, the learning-based method can be orders of magnitude faster than the conventional solvers.
有限元方法(FEM)、有限差分方法(FDM)这类传统求解器,是通过对空间做离散来解方程的。因此分辨率上存在折中:粗网格快但不准,细网格准但慢。上面这类复杂 PDE 系统通常需要非常细的离散,对传统求解器来说既困难又耗时。另一方面,数据驱动方法可以直接从数据里学习整族方程的轨迹。于是基于学习的方法可以比传统求解器快上若干个数量级。
Machine learning methods may hold the key to revolutionizing scientific disciplines by providing fast solvers that approximate or enhance traditional ones (Raissi et al., 2019; Jiang et al., 2020; Greenfeld et al., 2019; Kochkov et al., 2021). However, classical neural networks map between finite-dimensional spaces and can therefore only learn solutions tied to a specific discretization. This is often a limitation for practical applications and therefore the development of mesh-invariant neural networks is required. We first outline two mainstream neural network-based approaches for PDEs – the finite-dimensional operators and Neural-FEM.
机器学习方法有可能通过提供逼近或增强传统求解器的快速算法,为科学领域带来变革(Raissi et al., 2019; Jiang et al., 2020; Greenfeld et al., 2019; Kochkov et al., 2021)。然而,经典神经网络映射的是有限维空间,因此只能学到绑定在特定离散上的解。这在实际应用中常常构成限制,因而需要发展与网格无关的神经网络。我们先概述两类主流的、基于神经网络的 PDE 方法:有限维算子,以及 Neural-FEM。
Finite-dimensional operators.
有限维算子
These approaches parameterize the solution operator as a deep convolutional neural network between finite-dimensional Euclidean spaces Guo et al. (2016); Zhu & Zabaras (2018); Adler & Oktem (2017); Bhatnagar et al. (2019); Khoo et al. (2017). Such approaches are, by definition, mesh-dependent and will need modifications and tuning for different resolutions and discretizations in order to achieve consistent error (if at all possible). Furthermore, these approaches are limited to the discretization size and geometry of the training data and hence, it is not possible to query solutions at new points in the domain. In contrast, we show, for our method, both invariance of the error to grid resolution, and the ability to transfer the solution between meshes.
这类方法把解算子参数化成有限维欧几里得空间之间的深度卷积网络(Guo et al., 2016; Zhu & Zabaras, 2018; Adler & Oktem, 2017; Bhatnagar et al., 2019; Khoo et al., 2017)。它们在定义上就依赖网格,要在不同分辨率和离散上保持一致的误差(如果做得到的话),就需要改结构和调参。此外,这类方法受限于训练数据的离散尺度和几何,因而无法在区域中的新点上查询解。相比之下,我们表明,本文方法的误差对网格分辨率保持不变,并且能在不同网格之间迁移解。
Neural-FEM.
Neural-FEM
The second approach directly parameterizes the solution function as a neural network (E & Yu, 2018; Raissi et al., 2019; Bar & Sochen, 2019; Smith et al., 2020; Pan & Duraisamy, 2020). This approach is designed to model one specific instance of the PDE, not the solution operator. It is mesh-independent and accurate, but for any given new instance of the functional parameter/coefficient, it requires training a new neural network. The approach closely resembles classical methods such as finite elements, replacing the linear span of a finite set of local basis functions with the space of neural networks. The Neural-FEM approach suffers from the same computational issue as classical methods: the optimization problem needs to be solved for every new instance. Furthermore, the approach is limited to a setting in which the underlying PDE is known.
第二种做法是直接把解函数本身参数化成神经网络(E & Yu, 2018; Raissi et al., 2019; Bar & Sochen, 2019; Smith et al., 2020; Pan & Duraisamy, 2020)。它的目标是建模 PDE 的某一个具体实例,而不是解算子。这种方法与网格无关,也可以很准,可每遇到一个新的函数型参数或系数,都要重新训练一个网络。它很像有限元一类经典方法,只不过把有限个局部基函数的线性张成,换成了神经网络所在的函数空间。Neural-FEM 因而也有和经典方法一样的计算问题:每个新实例都要再解一次优化。此外,这一路线还局限于底层 PDE 已知的情形。
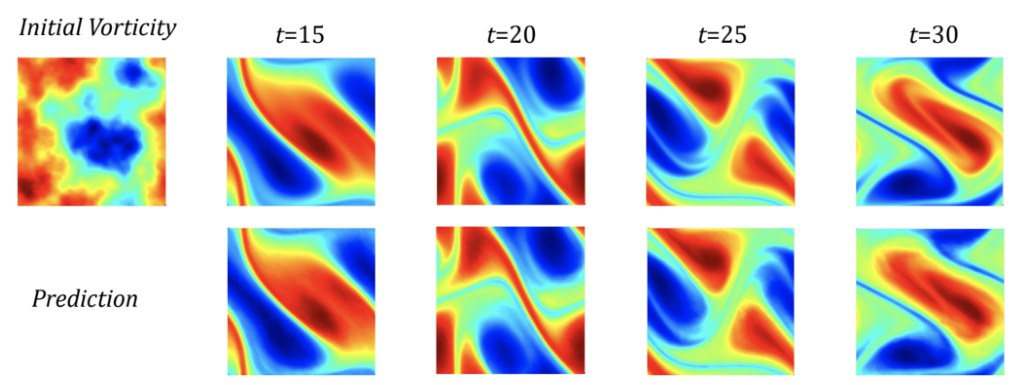
Figure 1: top: The architecture of the Fourier layer; bottom: Example flow from Navier-Stokes.
Zero-shot super-resolution: Navier-Stokes Equation with viscosity ; Ground truth on top and prediction on bottom; trained on dataset; evaluated on (see Section 5.4).
图 1:上:傅里叶层的结构;下:来自 Navier-Stokes 的示例流程。
零样本超分辨率:黏度为 的 Navier-Stokes 方程;上为真实值,下为预测;在 的数据集上训练,在 上评估(见第 5.4 节)。
Neural Operators.
神经算子
Recently, a new line of work proposed learning mesh-free, infinite-dimensional operators with neural networks (Lu et al., 2019; Bhattacharya et al., 2020; Nelsen & Stuart, 2020; Li et al., 2020b; Li et al., 2020a; Patel et al., 2021). The neural operator remedies the mesh-dependent nature of the finite-dimensional operator methods discussed above by producing a single set of network parameters that may be used with different discretizations. It has the ability to transfer solutions between meshes. Furthermore, the neural operator needs to be trained only once. Obtaining a solution for a new instance of the parameter requires only a forward pass of the network, alleviating the major computational issues incurred in Neural-FEM methods. Lastly, the neural operator requires no knowledge of the underlying PDE, only data. Thus far, neural operators have not yielded efficient numerical algorithms that can parallel the success of convolutional or recurrent neural networks in the finite-dimensional setting due to the cost of evaluating integral operators. Through the fast Fourier transform, our work alleviates this issue.
近来有一批新工作提出,用神经网络学习与网格无关的无限维算子(Lu et al., 2019; Bhattacharya et al., 2020; Nelsen & Stuart, 2020; Li et al., 2020b; Li et al., 2020a; Patel et al., 2021)。神经算子给出一套可在不同离散上共用的网络参数,从而克服了上文有限维算子方法对网格的依赖。它还能在不同网格之间迁移解。此外,神经算子只需训练一次。对新的参数实例求一次解,只需要网络做一次前向计算,从而缓解了 Neural-FEM 方法中主要的计算负担。最后,神经算子不必知道底层 PDE,只需数据。迄今为止,由于积分算子求值代价高,神经算子还没有给出能与有限维设定里卷积或循环网络相媲美的高效数值算法。借助快速傅里叶变换,本文缓解了这一问题。
Fourier Transform.
傅里叶变换
The Fourier transform is frequently used in spectral methods for solving differential equations, since differentiation is equivalent to multiplication in the Fourier domain. Fourier transforms have also played an important role in the development of deep learning. In theory, they appear in the proof of the universal approximation theorem (Hornik et al., 1989) and, empirically, they have been used to speed up convolutional neural networks (Mathieu et al., 2013). Neural network architectures involving the Fourier transform or the use of sinusoidal activation functions have also been proposed and studied (Bengio et al., 2007; Mingo et al., 2004; Sitzmann et al., 2020). Recently, some spectral methods for PDEs have been extended to neural networks (Fan et al., 2019a; Fan et al., 2019b; Kashinath et al., 2020). We build on these works by proposing a neural operator architecture defined directly in Fourier space with quasi-linear time complexity and state-of-the-art approximation capabilities.
傅里叶变换在用谱方法求解微分方程时很常见,因为微分在傅里叶域里等价于乘法。傅里叶变换在深度学习的发展中也扮演过重要角色。理论上,它出现在通用逼近定理的证明里(Hornik et al., 1989);经验上,它也被用来加速卷积网络(Mathieu et al., 2013)。把傅里叶变换或正弦激活写进网络结构的工作也已有人提出并研究(Bengio et al., 2007; Mingo et al., 2004; Sitzmann et al., 2020)。近来,一些面向 PDE 的谱方法也被推广到了神经网络(Fan et al., 2019a; Fan et al., 2019b; Kashinath et al., 2020)。我们在这些工作之上,提出一种直接在傅里叶空间定义的神经算子结构,具有准线性时间复杂度,以及当时最好的逼近能力。
Our Contributions.
本文贡献
We introduce the Fourier neural operator, a novel deep learning architecture able to learn mappings between infinite-dimensional spaces of functions; the integral operator is restricted to a convolution, and instantiated through a linear transformation in the Fourier domain.
我们提出傅里叶神经算子,这是一种能够学习无限维函数空间之间映射的新深度学习结构:积分算子被限制为卷积,并在傅里叶域里用一个线性变换来实现。
- The Fourier neural operator is the first work that learns the resolution-invariant solution operator for the family of Navier-Stokes equation in the turbulent regime, where previous graph-based neural operators do not converge.
- 傅里叶神经算子是第一项为湍流区段的 Navier-Stokes 方程族学到分辨率不变解算子的工作,此前基于图的神经算子在这一区段不能收敛。
- By construction, the method shares the same learned network parameters irrespective of the discretization used on the input and output spaces. It can do zero-shot super-resolution: trained on a lower resolution directly evaluated on a higher resolution, as shown in Figure 1.
- 按构造,无论输入、输出空间采用何种离散,该方法都共用同一套学到的网络参数。它可以做零样本超分辨率:在较低分辨率上训练,直接在更高分辨率上评估,如图 1 所示。
- The proposed method consistently outperforms all existing deep learning methods even when fixing the resolution to be . It achieves error rates that are lower on Burgers’ Equation, lower on Darcy Flow, and lower on Navier Stokes (turbulent regime with viscosity ). When learning the mapping for the entire time series, the method achieves error with viscosity and error with viscosity .
- 即便把分辨率固定在 ,所提方法也始终优于现有的各种深度学习方法。相对误差在 Burgers 方程上低 ,在 Darcy 流上低 ,在 Navier-Stokes(黏度 的湍流区段)上低 。在学习整条时间序列的映射时,黏度 时误差小于 ,黏度 时误差为 。
- On a grid, the Fourier neural operator has an inference time of only s compared to the of the pseudo-spectral method used to solve Navier-Stokes. Despite its tremendous speed advantage, the method does not suffer from accuracy degradation when used in downstream applications such as solving the Bayesian inverse problem, as shown in Figure 6.
- 在 的网格上,傅里叶神经算子的推断时间只有 秒,而用于求解 Navier-Stokes 的伪谱方法是 秒。尽管速度优势很大,把它用到贝叶斯反问题一类下游任务时,精度也没有下降,如图 6 所示。
We observed that the proposed framework can approximate complex operators raising in PDEs that are highly non-linear, with high frequency modes and slow energy decay. The power of neural operators comes from combining linear, global integral operators (via the Fourier transform) and non-linear, local activation functions. Similar to the way standard neural networks approximate highly non-linear functions by combining linear multiplications with non-linear activations, the proposed neural operators can approximate highly non-linear operators.
我们观察到,所提框架能够逼近 PDE 中出现的复杂算子,这些算子高度非线性,含有高频模态,能量衰减也较慢。神经算子的能力,来自把线性的全局积分算子(通过傅里叶变换)与非线性的局部激活函数结合起来。正如标准神经网络用线性乘法加上非线性激活来逼近高度非线性的函数,所提的神经算子也能逼近高度非线性的算子。
2 Learning Operators
2 学习算子
Our methodology learns a mapping between two infinite dimensional spaces from a finite collection of observed input-output pairs. Let be a bounded, open set and and be separable Banach spaces of function taking values in and respectively. Furthermore let be a (typically) non-linear map. We study maps which arise as the solution operators of parametric PDEs – see Section 5 for examples. Suppose we have observations where is an i.i.d. sequence from the probability measure supported on and is possibly corrupted with noise. We aim to build an approximation of by constructing a parametric map
我们的方法从有限个观测到的输入–输出对出发,学习两个无限维空间之间的映射。设 是有界开集, 和 分别是取值在 和 中的可分 Banach 函数空间。再设 是一个(通常)非线性的映射。我们研究的 来自参数型 PDE 的解算子,例子见第 5 节。假设有观测 ,其中 是支撑在 上的概率测度 的独立同分布序列,且 ,其中可能带有噪声。我们希望通过构造一个参数化映射来逼近
for some finite-dimensional parameter space by choosing so that . This is a natural framework for learning in infinite-dimensions as one could define a cost functional and seek a minimizer of the problem
对某个有限维参数空间 ,选取 ,使得 。这是无限维学习的自然框架,因为可以定义代价泛函 ,并寻求下述问题的极小化元
which directly parallels the classical finite-dimensional setting (Vapnik, 1998). Showing the existence of minimizers, in the infinite-dimensional setting, remains a challenging open problem. We will approach this problem in the test-train setting by using a data-driven empirical approximation to the cost used to determine and to test the accuracy of the approximation. Because we conceptualize our methodology in the infinite-dimensional setting, all finite-dimensional approximations share a common set of parameters which are consistent in infinite dimensions. A table of notation is shown in Appendix 3.
这与经典的有限维设定直接平行(Vapnik, 1998)。在无限维设定下证明极小化元的存在性,仍然是一个具有挑战性的未解决问题。我们将在训练–测试设定下处理这一问题,用数据驱动的经验近似来确定 ,并检验逼近的精度。由于我们把方法建立在无限维设定中,所有有限维逼近都共用一套在无限维中保持一致的参数。符号表见附录 3。
Learning the Operator.
学习算子
Approximating the operator is a different and typically much more challenging task than finding the solution of a PDE for a single instance of the parameter . Most existing methods, ranging from classical finite elements, finite differences, and finite volumes to modern machine learning approaches such as physics-informed neural networks (PINNs) (Raissi et al., 2019) aim at the latter and can therefore be computationally expensive. This makes them impractical for applications where a solution to the PDE is required for many different instances of the parameter. On the other hand, our approach directly approximates the operator and is therefore much cheaper and faster, offering tremendous computational savings when compared to traditional solvers. For an example application to Bayesian inverse problems, see Section 5.5.
逼近算子 ,与针对参数 的单个取值去求 PDE 的解 ,是不同的任务,通常也困难得多。从经典的有限元、有限差分和有限体积,到物理信息神经网络(PINNs)(Raissi et al., 2019)这类较新的机器学习方法,大多数现有方法都针对后者,因而计算上可能很贵。若应用中需要针对许多不同的参数取值反复求解 PDE,这些方法就不实用。相比之下,我们的方法直接逼近算子,因而便宜得多、也快得多,与传统求解器相比能节省大量计算。把它用到贝叶斯反问题的一个例子,见第 5.5 节。
Discretization.
离散化
Since our data and are, in general, functions, to work with them numerically, we assume access only to point-wise evaluations. Let be a -point discretization of the domain and assume we have observations , , for a finite collection of input-output pairs indexed by . To be discretization-invariant, the neural operator can produce an answer for any , potentially . Such a property is highly desirable as it allows a transfer of solutions between different grid geometries and discretizations.
由于数据 和 一般是函数,要在数值上处理它们,我们假定只能得到逐点取值。设 是区域 的一个 点离散,并假定对有限个以 标记的输入–输出对,有观测 ,。为了做到对离散不变,神经算子需要能对任意 给出 ,即使 。这一性质非常有用,因为它允许在不同的网格几何和离散之间迁移解。
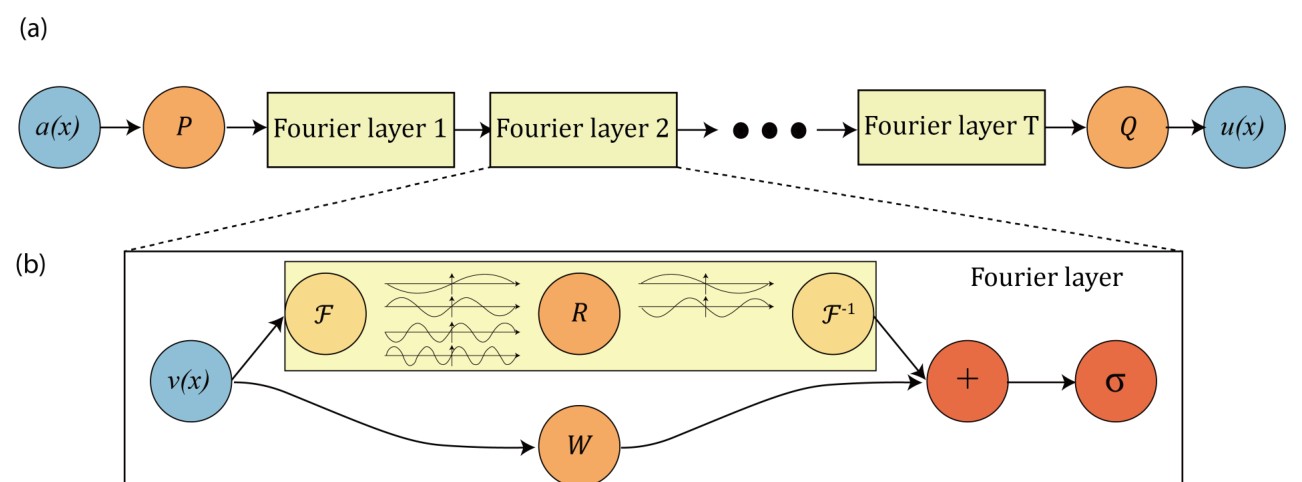
Figure 2: top: The architecture of the neural operators; bottom: Fourier layer.
(a) The full architecture of neural operator: start from input . 1. Lift to a higher dimension channel space by a neural network . 2. Apply four layers of integral operators and activation functions. 3. Project back to the target dimension by a neural network . Output . (b) Fourier layers: Start from input . On top: apply the Fourier transform ; a linear transform on the lower Fourier modes and filters out the higher modes; then apply the inverse Fourier transform . On the bottom: apply a local linear transform .
图 2:上:神经算子的结构;下:傅里叶层。
(a) 神经算子的完整结构:从输入 出发。1. 用神经网络 抬到更高维的通道空间。2. 施加四层积分算子和激活函数。3. 用神经网络 投影回目标维数。输出 。(b) 傅里叶层:从输入 出发。上方:做傅里叶变换 ;对较低的傅里叶模态做线性变换 ,并滤掉较高模态;再做逆傅里叶变换 。下方:施加局部线性变换 。
3 Neural Operator
3 神经算子
The neural operator, proposed in (Li et al., 2020b), is formulated as an iterative architecture where for is a sequence of functions each taking values in . As shown in Figure 2 (a), the input is first lifted to a higher dimensional representation by the local transformation which is usually parameterized by a shallow fully-connected neural network. Then we apply several iterations of updates (defined below). The output is the projection of by the local transformation . In each iteration, the update is defined as the composition of a non-local integral operator and a local, nonlinear activation function .
在(Li et al., 2020b)中提出的神经算子,被写成迭代结构 ,其中 ()是一列取值在 中的函数。如图 2(a) 所示,输入 先由局部变换 抬到更高维的表示 , 通常参数化成浅层全连接网络。随后施加若干次更新 (定义见下)。输出 是用局部变换 对 做的投影。在每一次迭代中,更新 定义为非局部积分算子 与局部非线性激活函数 的复合。
Definition 1 (Iterative updates)
定义 1(迭代更新)
Define the update to the representation by
将表示的更新 定义为
where maps to bounded linear operators on and is parameterized by , is a linear transformation, and is a non-linear activation function whose action is defined component-wise.
其中 映到 上的有界线性算子,并由 参数化, 是线性变换, 是按分量作用的非线性激活函数。
We choose to be a kernel integral transformation parameterized by a neural network.
我们把 取成由神经网络参数化的核积分变换。
Definition 2 (Kernel integral operator )
定义 2(核积分算子 )
Define the kernel integral operator mapping in (2) by
将 (2) 中的核积分算子映射定义为
where is a neural network parameterized by .
其中 是由 参数化的神经网络。
Here plays the role of a kernel function which we learn from data. Together definitions 1 and 2 constitute a generalization of neural networks to infinite-dimensional spaces as first proposed in Li et al. (2020b). Notice even the integral operator is linear, the neural operator can learn highly non-linear operators by composing linear integral operators with non-linear activation functions, analogous to standard neural networks.
这里 扮演从数据中学习的核函数的角色。定义 1 与定义 2 合在一起,构成了 Li et al.(2020b)首先提出的、把神经网络推广到无限维空间的框架。注意到,即便积分算子是线性的,神经算子仍可通过把线性积分算子与非线性激活函数复合,来学习高度非线性的算子,这与标准神经网络类似。
If we remove the dependence on the function and impose , we obtain that (3) is a convolution operator, which is a natural choice from the perspective of fundamental solutions. We exploit this fact in the following section by parameterizing directly in Fourier space and using the Fast Fourier Transform (FFT) to efficiently compute (3). This leads to a fast architecture that obtains state-of-the-art results for PDE problems.
若去掉对函数 的依赖,并施加 ,则 (3) 成为一个卷积算子,从基本解的角度看,这是很自然的选择。下一节我们将利用这一点,直接在傅里叶空间里参数化 ,并用快速傅里叶变换(FFT)高效计算 (3)。由此得到一种快速结构,并在 PDE 问题上取得当时最好的结果。
4 Fourier Neural Operator
4 傅里叶神经算子
We propose replacing the kernel integral operator in (3), by a convolution operator defined in Fourier space. Let denote the Fourier transform of a function and its inverse then
我们建议把 (3) 中的核积分算子,换成在傅里叶空间定义的卷积算子。记 为函数 的傅里叶变换, 为其逆,则
for where is the imaginary unit. By letting in (3) and applying the convolution theorem, we find that
对 成立,其中 是虚数单位。在 (3) 中令 ,并应用卷积定理,得到
We, therefore, propose to directly parameterize in Fourier space.
因此,我们建议直接在傅里叶空间里参数化 。
Definition 3 (Fourier integral operator )
定义 3(傅里叶积分算子 )
Define the Fourier integral operator
定义傅里叶积分算子
where is the Fourier transform of a periodic function parameterized by . An illustration is given in Figure 2 (b).
其中 是周期函数 的傅里叶变换,该函数由 参数化。示意图见图 2(b)。
For frequency mode , we have and . Notice that since we assume is periodic, it admits a Fourier series expansion, so we may work with the discrete modes . We pick a finite-dimensional parameterization by truncating the Fourier series at a maximal number of modes We thus parameterize directly as complex-valued -tensor comprising a collection of truncated Fourier modes and therefore drop from our notation. Since is real-valued, we impose conjugate symmetry. We note that the set is not the canonical choice for the low frequency modes of . Indeed, the low frequency modes are usually defined by placing an upper-bound on the -norm of . We choose as above since it allows for an efficient implementation.
对频率模态 ,有 以及 。由于假定 是周期的,它有傅里叶级数展开,因而可以在离散模态 上工作。我们通过在最大模态数 处截断傅里叶级数,来取一种有限维参数化。于是把 直接参数化成由一组截断傅里叶模态组成的复值 张量,并因此在记号中略去 。由于 是实值的,我们施加共轭对称。需要说明, 并不是 低频模态的典范取法。低频模态通常是对 的 范数加一个上界来定义的。我们按上面的方式选取 ,是因为它便于高效实现。
The discrete case and the FFT.
离散情形与 FFT
Assuming the domain is discretized with points, we have that and . Since we convolve with a function which only has Fourier modes, we may simply truncate the higher modes to obtain . Multiplication by the weight tensor is then
假定区域 被离散成 个点,则 ,。由于我们是在与一个只有 个傅里叶模态的函数做卷积,只需截掉较高模态,得到 。再与权重张量 相乘,即为
When the discretization is uniform with resolution , can be replaced by the Fast Fourier Transform. For , , and , the FFT and its inverse are defined as
当离散是分辨率为 的均匀网格时, 可以换成快速傅里叶变换。对 ,,以及 ,FFT 及其逆 定义为
for . In this case, the set of truncated modes becomes
对 成立。此时,被截断的模态集合成为
When implemented, is treated as a -tensor and the above definition of corresponds to the “corners” of , which allows for a straight-forward parallel implementation of (5) via matrix-vector multiplication. In practice, we have found that choosing which yields parameters per channel to be sufficient for all the tasks that we consider.
实现时, 被当作 张量,上面 的定义对应 的“边角”,从而可以借助矩阵–向量乘法,直接并行实现 (5)。实践中我们发现,取 ,也就是每个通道 个参数,对我们考虑的全部任务都已经足够。
Parameterizations of .
的参数化
In general, can be defined to depend on to parallel (3). Indeed, we can define as a parametric function that maps to the values of the appropriate Fourier modes. We have experimented with linear as well as neural network parameterizations of . We find that the linear parameterization has a similar performance to the previously described direct parameterization, while neural networks have worse performance. This is likely due to the discrete structure of the space . Our experiments in this work focus on the direct parameterization presented above.
一般地,也可以让 依赖于 ,以与 (3) 平行。确实可以把 定义成把 映到相应傅里叶模态取值的参数函数。我们试验过 的线性参数化和神经网络参数化。线性参数化与前面所述的直接参数化表现相近,神经网络则更差。这很可能与空间 的离散结构有关。本文实验集中在上面给出的直接参数化。
Invariance to discretization.
对离散化的不变性
The Fourier layers are discretization-invariant because they can learn from and evaluate functions which are discretized in an arbitrary way. Since parameters are learned directly in Fourier space, resolving the functions in physical space simply amounts to projecting on the basis which are well-defined everywhere on . This allows us to achieve zero-shot super-resolution as shown in Section 5.4. Furthermore, our architecture has a consistent error at any resolution of the inputs and outputs. On the other hand, notice that, in Figure 3, the standard CNN methods we compare against have an error that grows with the resolution.
傅里叶层对离散是不变的,因为它们可以从任意方式离散的函数中学习,并在这些函数上做评估。由于参数直接在傅里叶空间里学习,要在物理空间中还原函数,只需向处处在 上有定义的基 做投影。这使得我们可以实现第 5.4 节所示的零样本超分辨率。此外,无论输入、输出取何种分辨率,这一结构的误差都保持一致。另一方面,从图 3 可以看出,我们比较的标准 CNN 方法,误差会随分辨率上升。
Quasi-linear complexity.
准线性复杂度
The weight tensor contains modes, so the inner multiplication has complexity . Therefore, the majority of the computational cost lies in computing the Fourier transform and its inverse. General Fourier transforms have complexity , however, since we truncate the series the complexity is in fact , while the FFT has complexity . Generally, we have found using FFTs to be very efficient. However a uniform discretization is required.
权重张量 只含 个模态,因而内部乘法的复杂度是 。于是主要计算量在求傅里叶变换 及其逆。一般的傅里叶变换复杂度是 ,但由于我们截断了级数,复杂度实际上是 ,而 FFT 的复杂度是 。总体而言,我们发现使用 FFT 非常高效。不过这要求离散是均匀的。
5 Numerical experiments
5 数值实验
In this section, we compare the proposed Fourier neural operator with multiple finite-dimensional architectures as well as operator-based approximation methods on the 1-d Burgers’ equation, the 2-d Darcy Flow problem, and 2-d Navier-Stokes equation. The data generation processes are discussed in Appendices A.3.1, A.3.2, and A.3.3 respectively. We do not compare against traditional solvers (FEM/FDM) or neural-FEM type methods since our goal is to produce an efficient operator approximation that can be used for downstream applications. We demonstrate one such application to the Bayesian inverse problem in Section 5.5.
本节把所提的傅里叶神经算子,与多种有限维结构以及基于算子的逼近方法,在一维 Burgers 方程、二维 Darcy 流问题和二维 Navier-Stokes 方程上进行比较。数据生成过程分别见附录 A.3.1、A.3.2 和 A.3.3。我们不与传统求解器(FEM/FDM)或 Neural-FEM 一类方法比较,因为目标是得到可用于下游应用的高效算子逼近。第 5.5 节给出了把它用到贝叶斯反问题的一个例子。
We construct our Fourier neural operator by stacking four Fourier integral operator layers as specified in (2) and (4) with the ReLU activation as well as batch normalization. Unless otherwise specified, we use training instances and testing instances. We use Adam optimizer to train for epochs with an initial learning rate of that is halved every epochs. We set for the 1-d problem and for the 2-d problems. Lower resolution data are downsampled from higher resolution. All the computation is carried on a single Nvidia V100 GPU with 16GB memory.
我们把按 (2) 和 (4) 给出的四个傅里叶积分算子层叠在一起,配以 ReLU 激活和批归一化,来构造傅里叶神经算子。除非另有说明,训练实例取 ,测试实例取 。优化器用 Adam,训练 个周期,初始学习率为 ,每 个周期减半。一维问题取 ,二维问题取 。较低分辨率的数据由较高分辨率下采样得到。全部计算在一块 16GB 显存的 Nvidia V100 GPU 上完成。
Remark on Resolution.
关于分辨率的说明
Traditional PDE solvers such as FEM and FDM approximate a single function and therefore their error to the continuum decreases as the resolution is increased. On the other hand, operator approximation is independent of the ways its data is discretized as long as all relevant information is resolved. Resolution-invariant operators have consistent error rates among different resolutions as shown in Figure 3. Further, resolution-invariant operators can do zero-shot super-resolution, as shown in Section 5.4.
FEM、FDM 这类传统 PDE 求解器逼近的是单个函数,因而它们相对连续极限的误差会随分辨率提高而下降。另一方面,只要相关信息都被分辨出来,算子逼近就与数据的离散方式无关。分辨率不变的算子在不同分辨率上有一致的误差率,如图 3 所示。此外,分辨率不变的算子还可以做零样本超分辨率,见第 5.4 节。
Benchmarks for time-independent problems (Burgers and Darcy):
与时间无关问题的基准(Burgers 与 Darcy)
NN: a simple point-wise feedforward neural network. RBM: the classical Reduced Basis Method (using a POD basis) (DeVore, 2014). FCN: a the-state-of-the-art neural network architecture based on Fully Convolution Networks (Zhu & Zabaras, 2018). PCANN: an operator method using PCA as an autoencoder on both the input and output data and interpolating the latent spaces with a neural network (Bhattacharya et al., 2020). GNO: the original graph neural operator (Li et al., 2020b). MGNO: the multipole graph neural operator (Li et al., 2020a). LNO: a neural operator method based on the low-rank decomposition of the kernel , similar to the unstacked DeepONet proposed in (Lu et al., 2019). FNO: the newly purposed Fourier neural operator.
NN:一种逐点的简单前馈神经网络。RBM:经典的约化基方法(使用 POD 基)(DeVore, 2014)。FCN:一种基于全卷积网络的当时最先进神经网络结构(Zhu & Zabaras, 2018)。PCANN:一种算子方法,用 PCA 作为输入和输出数据的自编码器,再用神经网络在潜空间中插值(Bhattacharya et al., 2020)。GNO:最初的图神经算子(Li et al., 2020b)。MGNO:多极图神经算子(Li et al., 2020a)。LNO:基于核的低秩分解 的神经算子方法,类似于(Lu et al., 2019)提出的未堆叠 DeepONet。FNO:本文新提出的傅里叶神经算子。
Benchmarks for time-dependent problems (Navier-Stokes):
与时间有关问题的基准(Navier-Stokes)
ResNet: layers of 2-d convolution with residual connections (He et al., 2016). U-Net: A popular choice for image-to-image regression tasks consisting of four blocks with 2-d convolutions and deconvolutions (Ronneberger et al., 2015). TF-Net: A network designed for learning turbulent flows based on a combination of spatial and temporal convolutions (Wang et al., 2020). FNO-2d: 2-d Fourier neural operator with a RNN structure in time. FNO-3d: 3-d Fourier neural operator that directly convolves in space-time.
ResNet:18 层带残差连接的二维卷积(He et al., 2016)。U-Net:图像到图像回归任务中的常用选择,由四个带二维卷积和反卷积的块组成(Ronneberger et al., 2015)。TF-Net:一种为学习湍流设计的网络,结合了空间卷积与时间卷积(Wang et al., 2020)。FNO-2d:在时间上采用 RNN 结构的二维傅里叶神经算子。FNO-3d:直接在时空中做卷积的三维傅里叶神经算子。
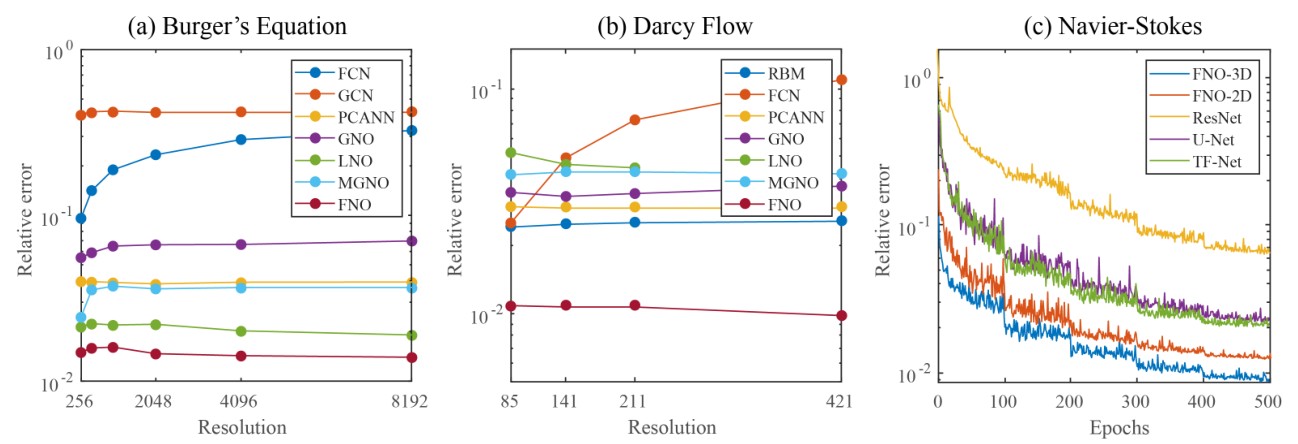
Figure 3: Benchmark on Burger’s equation, Darcy Flow, and Navier-Stokes
Left: benchmarks on Burgers equation; Mid: benchmarks on Darcy Flow for different resolutions; Right: the learning curves on Navier-Stokes with different benchmarks. Train and test on the same resolution. For acronyms, see Section 5; details in Tables 1, 3, 4.
图 3:Burgers 方程、Darcy 流和 Navier-Stokes 上的基准
左:Burgers 方程上的基准;中:不同分辨率下 Darcy 流的基准;右:黏度 的 Navier-Stokes 在不同基准方法上的学习曲线。训练和测试使用同一分辨率。缩写见第 5 节;细节见表 1、表 3、表 4。
5.1 Burgers’ Equation
5.1 Burgers 方程
The 1-d Burgers’ equation is a non-linear PDE with various applications including modeling the one dimensional flow of a viscous fluid. It takes the form
一维 Burgers 方程是一种非线性 PDE,应用包括对黏性流体一维流动的建模。它的形式为
$$\displaystyle\begin{split}\partial_{t}u(x,t)+\partial_{x}(u^{2}(x,t)/2)&=\nu\partial_{xx}u(x,t),\qquad x\in(0,1),t\in(0,1]\
u(x,0)&=u_{0}(x),\qquad\qquad>>x\in(0,1)\end{split} \tag{6}$$
with periodic boundary conditions where is the initial condition and is the viscosity coefficient. We aim to learn the operator mapping the initial condition to the solution at time one, defined by for any .
并带有周期边界条件,其中 是初值, 是黏度系数。我们希望学习把初值映到时刻 1 的解的算子 ,由 定义,对任意 成立。
The results of our experiments are shown in Figure 3 (a) and Table 3 (Appendix A.3.1). Our proposed method obtains the lowest relative error compared to any of the benchmarks. Further, the error is invariant with the resolution, while the error of convolution neural network based methods (FCN) grows with the resolution. Compared to other neural operator methods such as GNO and MGNO that use Nyström sampling in physical space, the Fourier neural operator is both more accurate and more computationally efficient.
实验结果见图 3(a) 和表 3(附录 A.3.1)。与所有基准方法相比,所提方法得到了最低的相对误差。而且误差对分辨率保持不变,而基于卷积网络的方法(FCN)的误差会随分辨率上升。与在物理空间使用 Nyström 抽样的 GNO、MGNO 等其他神经算子方法相比,傅里叶神经算子既更准确,计算上也更高效。
5.2 Darcy Flow
5.2 Darcy 流
We consider the steady-state of the 2-d Darcy Flow equation on the unit box which is the second order, linear, elliptic PDE
我们考虑单位方体上二维 Darcy 流方程的稳态,它是如下二阶线性椭圆型 PDE
$$\displaystyle\begin{split}-\nabla\cdot(a(x)\nabla u(x))&=f(x)\qquad x\in(0,1)^{2}\
u(x)&=0\qquad\quad>>x\in\partial(0,1)^{2}\end{split} \tag{7}$$
with a Dirichlet boundary where is the diffusion coefficient and is the forcing function. This PDE has numerous applications including modeling the pressure of subsurface flow, the deformation of linearly elastic materials, and the electric potential in conductive materials. We are interested in learning the operator mapping the diffusion coefficient to the solution, defined by . Note that although the PDE is linear, the operator is not.
并带有 Dirichlet 边界,其中 是扩散系数, 是强迫项。这个 PDE 有许多应用,包括地下渗流压力、线性弹性材料的变形,以及导电材料中的电势。我们希望学习把扩散系数映到解的算子 ,由 定义。需要注意,尽管 PDE 本身是线性的,算子 却不是。
The results of our experiments are shown in Figure 3 (b) and Table 4 (Appendix A.3.2). The proposed Fourier neural operator obtains nearly one order of magnitude lower relative error compared to any benchmarks. We again observe the invariance of the error with respect to the resolution.
实验结果见图 3(b) 和表 4(附录 A.3.2)。所提的傅里叶神经算子得到的相对误差,比任何基准方法都低了接近一个数量级。我们再次看到误差对分辨率保持不变。
5.3 Navier-Stokes Equation
5.3 Navier-Stokes 方程
We consider the 2-d Navier-Stokes equation for a viscous, incompressible fluid in vorticity form on the unit torus:
我们考虑单位环面上黏性不可压流体的二维 Navier-Stokes 方程的涡量形式:
$$\displaystyle\begin{split}\partial_{t}w(x,t)+u(x,t)\cdot\nabla w(x,t)&=\nu\Delta w(x,t)+f(x),\qquad x\in(0,1)^{2},t\in(0,T]\
\nabla\cdot u(x,t)&=0,\qquad\qquad\qquad\qquad\quad x\in(0,1)^{2},t\in[0,T]\
w(x,0)&=w_{0}(x),\qquad\qquad\qquad\quad x\in(0,1)^{2}\end{split} \tag{8}$$
where for any is the velocity field, is the vorticity, is the initial vorticity, is the viscosity coefficient, and is the forcing function. We are interested in learning the operator mapping the vorticity up to time 10 to the vorticity up to some later time , defined by . Given the vorticity it is easy to derive the velocity. While vorticity is harder to model compared to velocity, it provides more information. By formulating the problem on vorticity, the neural network models mimic the pseudo-spectral method. We experiment with the viscosities , decreasing the final time as the dynamic becomes chaotic. Since the baseline methods are not resolution-invariant, we fix the resolution to be for both training and testing.
其中对任意 , 是速度场, 是涡量, 是初始涡量, 是黏度系数, 是强迫项。我们希望学习把直到时刻 10 的涡量映到某个更晚时刻 的涡量的算子 ,由 定义。有了涡量,速度很容易导出。虽然涡量比速度更难建模,它提供的信息也更多。把问题写在涡量上,神经网络模型便与伪谱方法类似。我们试验了黏度 ,并随着动力学变得更混沌而缩短终端时间 。由于基准方法对分辨率并不不变,训练和测试都把分辨率固定为 。
Table 1: Benchmarks on Navier Stokes (fixing resolution for both training and testing)
| Parameters | Time | |||||
|---|---|---|---|---|---|---|
| Config | per | |||||
| epoch | ||||||
| FNO-3D | ||||||
| FNO-2D | ||||||
| U-Net | ||||||
| TF-Net | ||||||
| ResNet |
表 1:Navier-Stokes 上的基准(训练和测试都固定分辨率为 )
| 参数量 | 时间 | |||||
|---|---|---|---|---|---|---|
| 配置 | 每 | |||||
| 周期 | ||||||
| FNO-3D | ||||||
| FNO-2D | ||||||
| U-Net | ||||||
| TF-Net | ||||||
| ResNet |
As shown in Table 1, the FNO-3D has the best performance when there is sufficient data ( and ). For the configurations where the amount of data is insufficient ( and ), all methods have error with FNO-2D achieving the lowest. Note that we only present results for spatial resolution since all benchmarks we compare against are designed for this resolution. Increasing it degrades their performance while FNO achieves the same errors.
如表 1 所示,在数据充足时( 以及 ),FNO-3D 表现最好。在数据不足的配置里( 以及 ),所有方法的误差都大于 ,其中以 FNO-2D 最低。需要说明,我们只给出空间分辨率 的结果,因为用来比较的所有基准方法都是为这一分辨率设计的。提高分辨率会损害它们的表现,而 FNO 仍得到同样的误差。
2D and 3D Convolutions.
二维与三维卷积
FNO-2D, U-Net, TF-Net, and ResNet all do 2D-convolution in the spatial domain and recurrently propagate in the time domain (2D+RNN). The operator maps the solution at the previous time steps to the next time step (2D functions to 2D functions). On the other hand, FNO-3D performs convolution in space-time. It maps the initial time steps directly to the full trajectory (3D functions to 3D functions). The 2D+RNN structure can propagate the solution to any arbitrary time in increments of a fixed interval length , while the Conv3D structure is fixed to the interval but can transfer the solution to an arbitrary time-discretization. We find the 3-d method to be more expressive and easier to train compared to its RNN-structured counterpart.
FNO-2D、U-Net、TF-Net 和 ResNet 都在空间域做二维卷积,并在时间域循环推进(2D+RNN)。算子把前 个时间步的解映到下一个时间步(二维函数到二维函数)。另一方面,FNO-3D 在时空中做卷积。它把初始时间步直接映到完整轨迹(三维函数到三维函数)。2D+RNN 结构可以按固定间隔 把解推进到任意时刻 ,而 Conv3D 结构固定在区间 上,但可以把解转到任意的时间离散。我们发现,与带 RNN 结构的对应方法相比,三维方法表达力更强,也更容易训练。
5.4 Zero-shot super-resolution.
5.4 零样本超分辨率
The neural operator is mesh-invariant, so it can be trained on a lower resolution and evaluated at a higher resolution, without seeing any higher resolution data (zero-shot super-resolution). Figure 1 shows an example where we train the FNO-3D model on resolution data in the setting above with () and transfer to resolution, demonstrating super-resolution in space-time. Fourier neural operator is the only model among the benchmarks (FNO-2D, U-Net, TF-Net, and ResNet) that can do zero-shot super-resolution. And surprisingly, it can do super-resolution not only in the spatial domain but also in the temporal domain.
神经算子与网格无关,因而可以在较低分辨率上训练,再在更高分辨率上评估,而不必见过任何更高分辨率的数据(零样本超分辨率)。图 1 给出一个例子:我们在上述设定下用()的 分辨率数据训练 FNO-3D 模型,再迁移到 分辨率,展示了时空上的超分辨率。在各基准方法(FNO-2D、U-Net、TF-Net 和 ResNet)中,只有傅里叶神经算子能做零样本超分辨率。而且出人意料的是,它不仅可以在空间域上做超分辨率,也可以在时间域上做。
5.5 Bayesian Inverse Problem
5.5 贝叶斯反问题
In this experiment, we use a function space Markov chain Monte Carlo (MCMC) method (Cotter et al., 2013) to draw samples from the posterior distribution of the initial vorticity in Navier-Stokes given sparse, noisy observations at time . We compare the Fourier neural operator acting as a surrogate model with the traditional solvers used to generate our train-test data (both run on GPU). We generate 25,000 samples from the posterior (with a 5,000 sample burn-in period), requiring 30,000 evaluations of the forward operator.
在这一实验中,我们使用函数空间上的马尔可夫链蒙特卡洛(MCMC)方法(Cotter et al., 2013),从 Navier-Stokes 初始涡量的后验分布中抽样,条件是时刻 上稀疏且带噪声的观测。我们把作为代理模型的傅里叶神经算子,与用来生成训练–测试数据的传统求解器相比较(二者都在 GPU 上运行)。我们从后验中生成 25,000 个样本(其中 5,000 个为预热期),因而需要对前向算子评估 30,000 次。
As shown in Figure 6 (Appendix A.5), FNO and the traditional solver recover almost the same posterior mean which, when pushed forward, recovers well the late-time dynamic of Navier Stokes. In sharp contrast, FNO takes to evaluate a single instance while the traditional solver, after being optimized to use the largest possible internal time-step which does not lead to blow-up, takes . This amounts to minutes for the MCMC using FNO and over hours for the traditional solver. Even if we account for data generation and training time (offline steps) which take hours, using FNO is still faster! Once trained, FNO can be used to quickly perform multiple MCMC runs for different initial conditions and observations, while the traditional solver will take hours for every instance. Furthermore, since FNO is differentiable, it can easily be applied to PDE-constrained optimization problems without the need for the adjoint method.
如图 6(附录 A.5)所示,FNO 与传统求解器恢复出几乎相同的后验均值,把它向前推进后,也能很好地恢复 Navier-Stokes 后期的动力学。与之形成鲜明对比的是,FNO 评估单个实例只需 秒,而传统求解器在被优化到使用尚不导致爆破的最大内部时间步之后,仍需 秒。这意味着用 FNO 做 MCMC 只要 分钟,传统求解器则要超过 小时。即便把耗时 小时的数据生成和训练(离线步骤)也算进去,使用 FNO 仍然更快。一旦训练完成,FNO 可以迅速针对不同的初值和观测做多次 MCMC;而传统求解器每个实例都要再花 小时。此外,由于 FNO 可微,它可以方便地用于带 PDE 约束的优化问题,而不必再求伴随。
Spectral analysis.
谱分析
Due to the way we parameterize , the function output by (4) has at most Fourier modes per channel. This, however, does not mean that the Fourier neural operator can only approximate functions up to modes. Indeed, the activation functions which occur between integral operators and the final decoder network recover the high frequency modes. As an example, consider a solution to the Navier-Stokes equation with viscosity . Truncating this function at Fourier modes yields an error around while our Fourier neural operator learns the parametric dependence and produces approximations to an error of with only parameterized modes.
由于我们对 的参数化方式,(4) 输出的函数在每个通道上最多有 个傅里叶模态。但这并不意味着傅里叶神经算子只能逼近不超过 个模态的函数。事实上,积分算子之间的激活函数,以及最后的解码网络 ,会把高频模态恢复出来。作为一个例子,考虑黏度 的 Navier-Stokes 方程的一个解。把这个函数截断到 个傅里叶模态,误差大约是 ;而我们的傅里叶神经算子在只参数化 个模态的情况下,就能学会参数依赖,并把逼近误差做到 。
Non-periodic boundary condition.
非周期边界条件
Traditional Fourier methods work only with periodic boundary conditions. However, the Fourier neural operator does not have this limitation. This is due to the linear transform (the bias term) which keeps the track of non-periodic boundary. As an example, the Darcy Flow and the time domain of Navier-Stokes have non-periodic boundary conditions, and the Fourier neural operator still learns the solution operator with excellent accuracy.
传统傅里叶方法只适用于周期边界条件。但傅里叶神经算子没有这一限制。这要归功于线性变换 (偏置项),它能够跟踪非周期边界。例如,Darcy 流以及 Navier-Stokes 的时间方向都具有非周期边界条件,傅里叶神经算子仍然能以很高的精度学会解算子。
6 Discussion and Conclusion
6 讨论与结论
Requirements on Data. Data-driven methods rely on the quality and quantity of data. To learn Navier-Stokes equation with viscosity , we need to generate training pairs with the numerical solver. However, for more challenging PDEs, generating a few training samples can be already very expensive. A future direction is to combine neural operators with numerical solvers to levitate the requirements on data. Recurrent structure. The neural operator has an iterative structure that can naturally be formulated as a recurrent network where all layers share the same parameters without sacrificing performance. (We did not impose this restriction in the experiments.) Computer vision. Operator learning is not restricted to PDEs. Images can naturally be viewed as real-valued functions on 2-d domains and videos simply add a temporal structure. Our approach is therefore a natural choice for problems in computer vision where invariance to discretization crucial is important (Chi et al., 2020).
对数据的要求。数据驱动方法依赖于数据的质量和数量。要学习黏度 的 Navier-Stokes 方程,我们需要用数值求解器生成 对训练样本 。但对更困难的 PDE,哪怕只生成少量训练样本,也可能已经非常昂贵。一个未来方向,是把神经算子与数值求解器结合起来,以减轻对数据的需求。循环结构。神经算子具有迭代结构,可以自然地写成循环网络,让所有层共用同一套参数,而不牺牲性能。(实验中我们没有施加这一限制。)计算机视觉。算子学习并不局限于 PDE。图像可以自然地看成二维区域上的实值函数,视频则再加上时间结构。因此,在离散不变性至关重要的计算机视觉问题中,我们的方法也是一种自然的选择(Chi et al., 2020)。
Acknowledgements
致谢
The authors want to thank Ray Wang and Rose Yu for meaningful discussions. Z. Li gratefully acknowledges the financial support from the Kortschak Scholars Program. A. Anandkumar is supported in part by Bren endowed chair, LwLL grants, Beyond Limits, Raytheon, Microsoft, Google, Adobe faculty fellowships, and DE Logi grant. K. Bhattacharya, N. B. Kovachki, B. Liu, and A. M. Stuart gratefully acknowledge the financial support of the Army Research Laboratory through the Cooperative Agreement Number W911NF-12-0022. Research was sponsored by the Army Research Laboratory and was accomplished under Cooperative Agreement Number W911NF-12-2-0022. The views and conclusions contained in this document are those of the authors and should not be interpreted as representing the official policies, either expressed or implied, of the Army Research Laboratory or the U.S. Government. The U.S. Government is authorized to reproduce and distribute reprints for Government purposes notwithstanding any copyright notation herein.
作者感谢 Ray Wang 和 Rose Yu 的有益讨论。Z. Li 感谢 Kortschak Scholars Program 的资助。A. Anandkumar 的部分支持来自 Bren 讲席、LwLL 资助、Beyond Limits、Raytheon、Microsoft、Google、Adobe 教师奖学金,以及 DE Logi 资助。K. Bhattacharya、N. B. Kovachki、B. Liu 和 A. M. Stuart 感谢陆军研究实验室通过合作协议 W911NF-12-0022 提供的资助。本研究由陆军研究实验室赞助,并在合作协议 W911NF-12-2-0022 下完成。本文所含观点和结论属于作者,不应被理解为代表陆军研究实验室或美国政府的官方政策,不论明示或暗示。美国政府获准为政府目的复制和分发重印本,不受本文任何版权声明限制。
References
参考文献
Adler & Oktem (2017) Jonas Adler and Ozan Oktem. Solving ill-posed inverse problems using iterative deep neural networks. Inverse Problems , nov 2017. doi: 10.1088/1361-6420/aa9581 . URL https://doi.org/10.1088%2F1361-6420%2Faa9581 .
Bar & Sochen (2019) Leah Bar and Nir Sochen. Unsupervised deep learning algorithm for pde-based forward and inverse problems. arXiv preprint arXiv:1904.05417 , 2019.
Bengio et al. (2007) Yoshua Bengio, Yann LeCun, et al. Scaling learning algorithms towards ai. Large-scale kernel machines , 34(5):1–41, 2007.
Bhatnagar et al. (2019) Saakaar Bhatnagar, Yaser Afshar, Shaowu Pan, Karthik Duraisamy, and Shailendra Kaushik. Prediction of aerodynamic flow fields using convolutional neural networks. Computational Mechanics , pp. 1–21, 2019.
Bhattacharya et al. (2020) Kaushik Bhattacharya, Nikola B. Kovachki, and Andrew M. Stuart. Model reduction and neural networks for parametric pde(s). preprint , 2020.
Chi et al. (2020) Lu Chi, Borui Jiang, and Yadong Mu. Fast fourier convolution. Advances in Neural Information Processing Systems , 33, 2020.
Cotter et al. (2013) S. L. Cotter, G. O. Roberts, A. M. Stuart, and D. White. Mcmc methods for functions: Modifying old algorithms to make them faster. Statistical Science , 28(3):424–446, Aug 2013. ISSN 0883-4237. doi: 10.1214/13-sts421 . URL http://dx.doi.org/10.1214/13-STS421 .
DeVore (2014) Ronald A. DeVore. Chapter 3: The Theoretical Foundation of Reduced Basis Methods . 2014. doi: 10.1137/1.9781611974829.ch3 . URL https://epubs.siam.org/doi/abs/10.1137/1.9781611974829.ch3 .
E & Yu (2018) Weinan E and Bing Yu. The deep ritz method: A deep learning-based numerical algorithm for solving variational problems. Communications in Mathematics and Statistics , 3 2018. ISSN 2194-6701. doi: 10.1007/s40304-018-0127-z .
Fan et al. (2019a) Yuwei Fan, Cindy Orozco Bohorquez, and Lexing Ying. Bcr-net: A neural network based on the nonstandard wavelet form. Journal of Computational Physics , 384:1–15, 2019a.
Fan et al. (2019b) Yuwei Fan, Lin Lin, Lexing Ying, and Leonardo Zepeda-Núnez. A multiscale neural network based on hierarchical matrices. Multiscale Modeling & Simulation , 17(4):1189–1213, 2019b.
Greenfeld et al. (2019) Daniel Greenfeld, Meirav Galun, Ronen Basri, Irad Yavneh, and Ron Kimmel. Learning to optimize multigrid pde solvers. In International Conference on Machine Learning , pp. 2415–2423. PMLR, 2019.
Guo et al. (2016) Xiaoxiao Guo, Wei Li, and Francesco Iorio. Convolutional neural networks for steady flow approximation. In Proceedings of the 22nd ACM SIGKDD International Conference on Knowledge Discovery and Data Mining , 2016.
He et al. (2016) Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. Deep residual learning for image recognition. In Proceedings of the IEEE conference on computer vision and pattern recognition , pp. 770–778, 2016.
Hornik et al. (1989) Kurt Hornik, Maxwell Stinchcombe, Halbert White, et al. Multilayer feedforward networks are universal approximators. Neural networks , 2(5):359–366, 1989.
Jiang et al. (2020) Chiyu Max Jiang, Soheil Esmaeilzadeh, Kamyar Azizzadenesheli, Karthik Kashinath, Mustafa Mustafa, Hamdi A Tchelepi, Philip Marcus, Anima Anandkumar, et al. Meshfreeflownet: A physics-constrained deep continuous space-time super-resolution framework. arXiv preprint arXiv:2005.01463 , 2020.
Kashinath et al. (2020) Karthik Kashinath, Philip Marcus, et al. Enforcing physical constraints in cnns through differentiable pde layer. In ICLR 2020 Workshop on Integration of Deep Neural Models and Differential Equations , 2020.
Khoo et al. (2017) Yuehaw Khoo, Jianfeng Lu, and Lexing Ying. Solving parametric PDE problems with artificial neural networks. arXiv preprint arXiv:1707.03351 , 2017.
Kochkov et al. (2021) Dmitrii Kochkov, Jamie A Smith, Ayya Alieva, Qing Wang, Michael P Brenner, and Stephan Hoyer. Machine learning accelerated computational fluid dynamics. arXiv preprint arXiv:2102.01010 , 2021.
Li et al. (2020a) Zongyi Li, Nikola Kovachki, Kamyar Azizzadenesheli, Burigede Liu, Kaushik Bhattacharya, Andrew Stuart, and Anima Anandkumar. Multipole graph neural operator for parametric partial differential equations, 2020a.
Li et al. (2020b) Zongyi Li, Nikola Kovachki, Kamyar Azizzadenesheli, Burigede Liu, Kaushik Bhattacharya, Andrew Stuart, and Anima Anandkumar. Neural operator: Graph kernel network for partial differential equations. arXiv preprint arXiv:2003.03485 , 2020b.
Lu et al. (2019) Lu Lu, Pengzhan Jin, and George Em Karniadakis. Deeponet: Learning nonlinear operators for identifying differential equations based on the universal approximation theorem of operators. arXiv preprint arXiv:1910.03193 , 2019.
Mathieu et al. (2013) Michael Mathieu, Mikael Henaff, and Yann LeCun. Fast training of convolutional networks through ffts, 2013.
Mingo et al. (2004) Luis Mingo, Levon Aslanyan, Juan Castellanos, Miguel Diaz, and Vladimir Riazanov. Fourier neural networks: An approach with sinusoidal activation functions. 2004.
Nelsen & Stuart (2020) NH Nelsen and AM Stuart. The random feature model for input-output maps between banach spaces. arXiv preprint arXiv:2005.10224 , 2020.
Pan & Duraisamy (2020) Shaowu Pan and Karthik Duraisamy. Physics-informed probabilistic learning of linear embeddings of nonlinear dynamics with guaranteed stability. SIAM Journal on Applied Dynamical Systems , 19(1):480–509, 2020.
Patel et al. (2021) Ravi G Patel, Nathaniel A Trask, Mitchell A Wood, and Eric C Cyr. A physics-informed operator regression framework for extracting data-driven continuum models. Computer Methods in Applied Mechanics and Engineering , 373:113500, 2021.
Raissi et al. (2019) Maziar Raissi, Paris Perdikaris, and George E Karniadakis. Physics-informed neural networks: A deep learning framework for solving forward and inverse problems involving nonlinear partial differential equations. Journal of Computational Physics , 378:686–707, 2019.
Ronneberger et al. (2015) Olaf Ronneberger, Philipp Fischer, and Thomas Brox. U-net: Convolutional networks for biomedical image segmentation. In International Conference on Medical image computing and computer-assisted intervention , pp. 234–241. Springer, 2015.
Sitzmann et al. (2020) Vincent Sitzmann, Julien NP Martel, Alexander W Bergman, David B Lindell, and Gordon Wetzstein. Implicit neural representations with periodic activation functions. arXiv preprint arXiv:2006.09661 , 2020.
Smith et al. (2020) Jonathan D Smith, Kamyar Azizzadenesheli, and Zachary E Ross. Eikonet: Solving the eikonal equation with deep neural networks. arXiv preprint arXiv:2004.00361 , 2020.
Vapnik (1998) Vladimir N. Vapnik. Statistical Learning Theory . Wiley-Interscience, 1998.
Wang et al. (2020) Rui Wang, Karthik Kashinath, Mustafa Mustafa, Adrian Albert, and Rose Yu. Towards physics-informed deep learning for turbulent flow prediction. In Proceedings of the 26th ACM SIGKDD International Conference on Knowledge Discovery & Data Mining , pp. 1457–1466, 2020.
Zhu & Zabaras (2018) Yinhao Zhu and Nicholas Zabaras. Bayesian deep convolutional encoder–decoder networks for surrogate modeling and uncertainty quantification. Journal of Computational Physics , 2018. ISSN 0021-9991. doi: https://doi.org/10.1016/j.jcp.2018.04.018 . URL http://www.sciencedirect.com/science/article/pii/S0021999118302341 .
Appendix A Appendix
附录 A
A.1 Table of notations
A.1 符号表
A table of notations is given in Table 2.
符号表见表 2。
Table 2: table of notations
| Notation | Meaning |
|---|---|
| Operator learning | |
| The spatial domain for the PDE | |
| Points in the the spatial domain | |
| The input coefficient functions | |
| The target solution functions | |
| The discretization of | |
| The operator mapping the coefficients to the solutions | |
| A probability measure where sampled from. | |
| Neural operator | |
| The neural network representation of | |
| Dimension of the input . | |
| Dimension of the output . | |
| The dimension of the representation | |
| The kernel maps to a matrix | |
| The parameters of the kernel network | |
| The time steps (layers) | |
| The activation function | |
| Fourier operator | |
| Fourier transformation and its inverse. | |
| The linear transformation applied on the lower Fourier modes. | |
| The linear transformation (bias term) applied on the spatial domain. | |
| Fourier modes / wave numbers. | |
| The max Fourier modes used in the Fourier layer. | |
| Hyperparameters | |
| The number of training pairs. | |
| The size of the discretization. | |
| The resolution of the discretization . | |
| The viscosity. | |
| The time interval for time-dependent equation. |
表 2:符号表
| 符号 | 含义 |
|---|---|
| 算子学习 | |
| PDE 的空间区域 | |
| 空间区域中的点 | |
| 输入系数函数 | |
| 目标解函数 | |
| 的离散 | |
| 把系数映到解的算子 | |
| 从中抽样的概率测度 | |
| 神经算子 | |
| 的神经网络表示 | |
| 输入 的维数 | |
| 输出 的维数 | |
| 表示 的维数 | |
| 把 映到 矩阵的核 | |
| 核网络 的参数 | |
| 时间步(层) | |
| 激活函数 | |
| 傅里叶算子 | |
| 傅里叶变换及其逆 | |
| 作用在较低傅里叶模态上的线性变换 | |
| 作用在空间域上的线性变换(偏置项) | |
| 傅里叶模态 / 波数 | |
| 傅里叶层中使用的最大傅里叶模态 | |
| 超参数 | |
| 训练对的数目 | |
| 离散的规模 | |
| 离散的分辨率() | |
| 黏度 | |
| 含时方程的时间区间 |
A.2 Spectral Analysis
A.2 谱分析
The spectral decay of the Navier Stokes equation data is shown in Figure 4. The spectrum decay has a slope , matching the energy spectrum in the turbulence region. And we notice the energy spectrum does not decay along with time.
Navier-Stokes 方程数据的谱衰减如图 4 所示。谱的衰减斜率为 ,与湍流区的能谱相符。我们还注意到,能谱并不随时间衰减。
We also present the spectral decay in term of the truncation defined in 4 as shown in Figure5. We note all equations (Burgers, Darcy, and Navier-Stokes with ) exhibit high frequency modes. Even we truncate at in the Fourier layer, the Fourier neural operator can recover the high frequency modes.
我们还给出了按第 4 节所定义的截断 来看的谱衰减,如图 5 所示。我们注意到,所有方程(Burgers、Darcy,以及 的 Navier-Stokes)都表现出高频模态。即便在傅里叶层里截断到 ,傅里叶神经算子仍能恢复高频模态。
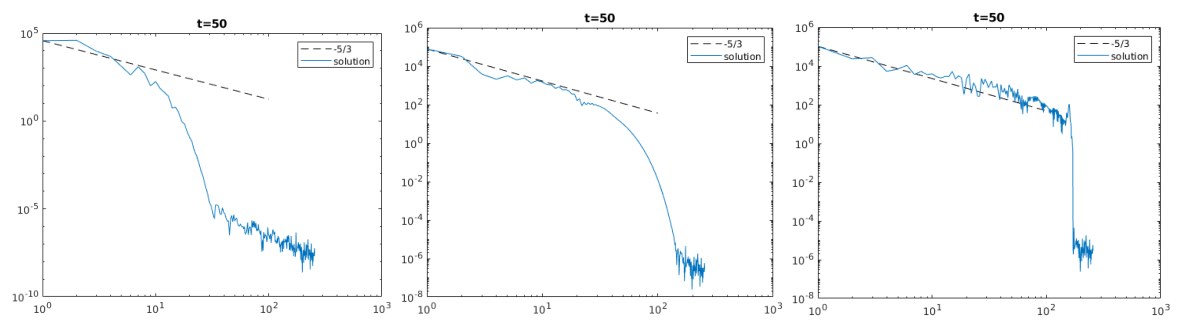
Figure 4: Spectral Decay of Navier-Stokes equations
The spectral decay of the Navier-stokes equation data we used in section 5.3. The y-axis is the spectrum; the x-axis is the wavenumber .
图 4:Navier-Stokes 方程的谱衰减
第 5.3 节所用 Navier-Stokes 方程数据的谱衰减。纵轴是谱,横轴是波数 。
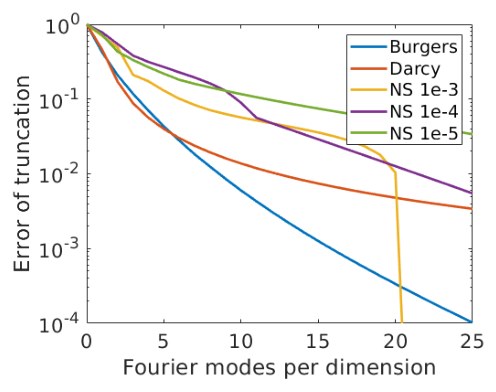
Figure 5: Spectral Decay in term of
The error of truncation in one single Fourier layer without applying the linear transform . The y-axis is the normalized truncation error; the x-axis is the truncation mode .
图 5:按 来看的谱衰减
在单个傅里叶层中、尚未施加线性变换 时的截断误差。纵轴是归一化截断误差,横轴是截断模态 。
A.3 Data generation
A.3 数据生成
In this section, we provide the details of data generator for the three equation we used in Section 5.
本节给出第 5 节所用三个方程的数据生成细节。
A.3.1 Burgers Equation
A.3.1 Burgers 方程
Recall the 1-d Burger’s equation on the unit torus:
回顾单位环面上的一维 Burgers 方程:
$$\displaystyle\begin{split}\partial_{t}u(x,t)+\partial_{x}(u^{2}(x,t)/2)&=\nu\partial_{xx}u(x,t),\qquad x\in(0,1),t\in(0,1]\
u(x,0)&=u_{0}(x),\qquad\qquad>x\in(0,1).\end{split}$$
The initial condition is generated according to where with periodic boundary conditions. We set the viscosity to and solve the equation using a split step method where the heat equation part is solved exactly in Fourier space then the non-linear part is advanced, again in Fourier space, using a very fine forward Euler method. We solve on a spatial mesh with resolution and use this dataset to subsample other resolutions.
初值 按 生成,其中 ,并带周期边界条件。黏度取 ,方程用分裂步进法求解:热方程部分在傅里叶空间中精确求解,非线性部分同样在傅里叶空间中,用非常细的前向 Euler 法推进。我们在分辨率 的空间网格上求解,并用这一数据集下采样得到其他分辨率。
A.3.2 Darcy Flow
A.3.2 Darcy 流
The 2-d Darcy Flow is a second-order linear elliptic equation of the form
二维 Darcy 流是如下形式的二阶线性椭圆方程
$$\displaystyle\begin{split}-\nabla\cdot(a(x)\nabla u(x))&=f(x)\qquad x\in(0,1)^{2}\
u(x)&=0\qquad\quad>>x\in\partial(0,1)^{2}.\end{split}$$
The coefficients are generated according to where with zero Neumann boundary conditions on the Laplacian. The mapping takes the value on the positive part of the real line and on the negative and the push-forward is defined pointwise. The forcing is kept fixed . Such constructions are prototypical models for many physical systems such as permeability in subsurface flows and material microstructures in elasticity. Solutions are obtained by using a second-order finite difference scheme on a grid. Different resolutions are downsampled from this dataset.
系数 按 生成,其中 ,并在拉普拉斯算子上取零 Neumann 边界条件。映射 在正半实轴上取值为 ,在负半实轴上取值为 ,推进是逐点定义的。强迫项保持固定 。这类构造是许多物理系统的原型模型,例如地下渗流中的渗透率,以及弹性中的材料微结构。解 用二阶有限差分格式在 网格上求得。不同分辨率由这一数据集下采样得到。
A.3.3 Navier-Stokes Equation
A.3.3 Navier-Stokes 方程
Recall the 2-d Navier-Stokes equation for a viscous, incompressible fluid in vorticity form on the unit torus:
回顾单位环面上黏性不可压流体的二维 Navier-Stokes 方程的涡量形式:
$$\displaystyle\begin{split}\partial_{t}w(x,t)+u(x,t)\cdot\nabla w(x,t)&=\nu\Delta w(x,t)+f(x),\qquad x\in(0,1)^{2},t\in(0,T]\
\nabla\cdot u(x,t)&=0,\qquad\qquad\qquad\qquad\quad x\in(0,1)^{2},t\in[0,T]\
w(x,0)&=w_{0}(x),\qquad\qquad\qquad\quad x\in(0,1)^{2}.\end{split}$$
The initial condition is generated according to where with periodic boundary conditions. The forcing is kept fixed . The equation is solved using the stream-function formulation with a pseudospectral method. First a Poisson equation is solved in Fourier space to find the velocity field. Then the vorticity is differentiated and the non-linear term is computed is physical space after which it is dealiased. Time is advanced with a Crank–Nicolson update where the non-linear term does not enter the implicit part. All data are generated on a grid and are downsampled to . We use a time-step of for the Crank–Nicolson scheme in the data-generated process where we record the solution every time units. The step is increased to when used in MCMC for the Bayesian inverse problem.
初值 按 生成,其中 ,并带周期边界条件。强迫项保持固定 。方程在流函数形式下用伪谱方法求解。首先在傅里叶空间中解一个泊松方程以得到速度场。然后对涡量求导,并在物理空间中计算非线性项,随后做去混叠。时间用 Crank–Nicolson 格式推进,非线性项不进入隐式部分。全部数据在 网格上生成,再下采样到 。在数据生成过程中,Crank–Nicolson 格式的时间步取 ,每隔 个时间单位记录一次解。在贝叶斯反问题的 MCMC 中,时间步加大到 。
A.4 Results of Burgers’ equation and Darcy Flow
A.4 Burgers 方程与 Darcy 流的结果
The details error rate on Burgers’ equation and Darcy Flow are listed in Table 3 and Table 4.
Burgers 方程和 Darcy 流上的详细误差率列于表 3 和表 4。
Table 3: Benchmarks on 1-d Burgers’ equation
| Networks | ||||||
|---|---|---|---|---|---|---|
| NN | ||||||
| GCN | ||||||
| FCN | ||||||
| PCANN | ||||||
| GNO | ||||||
| LNO | ||||||
| MGNO | ||||||
| FNO | 0.0149 | 0.0158 | 0.0160 | 0.0146 | 0.0142 | 0.0139 |
表 3:一维 Burgers 方程上的基准
| 网络 | ||||||
|---|---|---|---|---|---|---|
| NN | ||||||
| GCN | ||||||
| FCN | ||||||
| PCANN | ||||||
| GNO | ||||||
| LNO | ||||||
| MGNO | ||||||
| FNO | 0.0149 | 0.0158 | 0.0160 | 0.0146 | 0.0142 | 0.0139 |
Table 4: Benchmarks on 2-d Darcy Flow
| Networks | ||||
|---|---|---|---|---|
| NN | ||||
| FCN | ||||
| PCANN | ||||
| RBM | ||||
| GNO | ||||
| LNO | ||||
| MGNO | ||||
| FNO | 0.0108 | 0.0109 | 0.0109 | 0.0098 |
表 4:二维 Darcy 流上的基准
| 网络 | ||||
|---|---|---|---|---|
| NN | ||||
| FCN | ||||
| PCANN | ||||
| RBM | ||||
| GNO | ||||
| LNO | ||||
| MGNO | ||||
| FNO | 0.0108 | 0.0109 | 0.0109 | 0.0098 |
A.5 Bayesian Inverse Problem
A.5 贝叶斯反问题
Results of the Bayesian inverse problem for the Navier-Stokes equation are shown in Figure 6. It can be seen that the result using Fourier neural operator as a surrogate is as good as the result of the traditional solver.
Navier-Stokes 方程贝叶斯反问题的结果如图 6 所示。可以看出,用傅里叶神经算子作为代理模型得到的结果,与传统求解器相当。
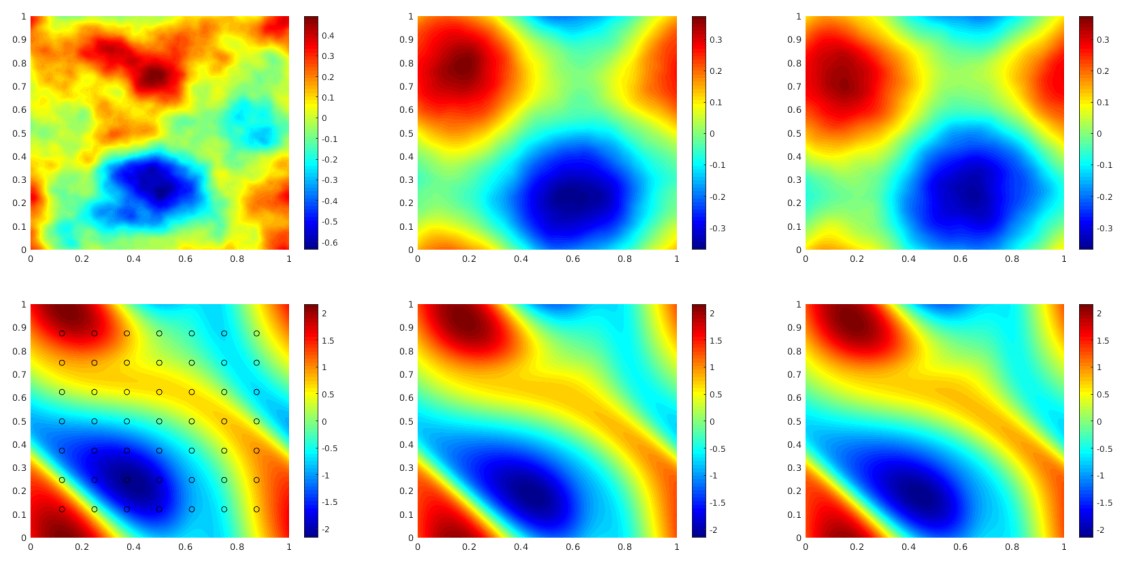
Figure 6: Results of the Bayesian inverse problem for the Navier-Stokes equation.
The top left panel shows the true initial vorticity while bottom left panel shows the true observed vorticity at with black dots indicating the locations of the observation points placed on a grid. The top middle panel shows the posterior mean of the initial vorticity given the noisy observations estimated with MCMC using the traditional solver, while the top right panel shows the same thing but using FNO as a surrogate model. The bottom middle and right panels show the vorticity at when the respective approximate posterior means are used as initial conditions.
图 6:Navier-Stokes 方程贝叶斯反问题的结果。
左上图给出真实的初始涡量,左下图给出时刻 的真实观测涡量,黑点标出布置在 网格上的观测点位置。中上图给出在带噪声观测条件下、用传统求解器经 MCMC 估计的初始涡量后验均值,右上图给出同样的事情,但用 FNO 作为代理模型。中下图和右下图给出把相应的近似后验均值当作初值时,时刻 的涡量。