Fully Convolutional Networks for Semantic Segmentation
Fully Convolutional Networks for Semantic Segmentation
面向语义分割的全卷积网络
Jonathan Long † † thanks: Authors contributed equally Evan Shelhamer 1 1 footnotemark: 1 Trevor Darrell Affiliation: UC Berkeley Email: {jonlong,shelhamer,trevor}@cs.berkeley.edu
Abstract
摘要
Convolutional networks are powerful visual models that yield hierarchies of features. We show that convolutional networks by themselves, trained end-to-end, pixels-to-pixels, exceed the state-of-the-art in semantic segmentation. Our key insight is to build “fully convolutional” networks that take input of arbitrary size and produce correspondingly-sized output with efficient inference and learning. We define and detail the space of fully convolutional networks, explain their application to spatially dense prediction tasks, and draw connections to prior models. We adapt contemporary classification networks (AlexNet [19], the VGG net [31], and GoogLeNet [32]) into fully convolutional networks and transfer their learned representations by fine-tuning [4] to the segmentation task. We then define a novel architecture that combines semantic information from a deep, coarse layer with appearance information from a shallow, fine layer to produce accurate and detailed segmentations. Our fully convolutional network achieves state-of-the-art segmentation of PASCAL VOC (20% relative improvement to 62.2% mean IU on 2012), NYUDv2, and SIFT Flow, while inference takes less than one fifth of a second for a typical image.
卷积网络是能产生特征层次的强大视觉模型。我们表明:卷积网络本身,经端到端、像素到像素的训练,即可在语义分割上超过当时最优。关键认识是构建「全卷积」网络:接受任意尺寸输入,并以高效的推理与学习产出对应尺寸的输出。我们界定并细述全卷积网络的空间,说明其如何用于空间稠密预测,并与既有模型建立联系。我们把当代分类网络(AlexNet [19]、VGG [31]、GoogLeNet [32])改造成全卷积网络,并通过微调 [4] 把已学表征迁移到分割任务。随后定义一种新结构:把深层、粗糙层的语义信息与浅层、精细层的外观信息结合起来,以得到准确且细致的分割。我们的全卷积网络在 PASCAL VOC(相对提升 20%,2012 年 mean IU 达 62.2%)、NYUDv2 与 SIFT Flow 上达到当时最优,典型图像推理不到五分之一秒。
1 Introduction
1 引言
Convolutional networks are driving advances in recognition. Convnets are not only improving for whole-image classification [19, 31, 32], but also making progress on local tasks with structured output. These include advances in bounding box object detection [29, 12, 17], part and keypoint prediction [39, 24], and local correspondence [24, 9].
卷积网络正在推动识别进步。它们不仅在整图分类上持续提升 [19, 31, 32],也在带结构化输出的局部任务上取得进展,包括边界框目标检测 [29, 12, 17]、部件与关键点预测 [39, 24],以及局部对应 [24, 9]。
The natural next step in the progression from coarse to fine inference is to make a prediction at every pixel. Prior approaches have used convnets for semantic segmentation [27, 2, 8, 28, 16, 14, 11], in which each pixel is labeled with the class of its enclosing object or region, but with shortcomings that this work addresses.
从粗到细推断的自然下一步,是对每个像素做预测。先前已有用卷积网络做语义分割的工作 [27, 2, 8, 28, 16, 14, 11]——为每个像素标上所属物体或区域的类别——但存在本文要解决的不足。
We show that a fully convolutional network (FCN), trained end-to-end, pixels-to-pixels on semantic segmentation exceeds the state-of-the-art without further machinery. To our knowledge, this is the first work to train FCNs end-to-end (1) for pixelwise prediction and (2) from supervised pre-training. Fully convolutional versions of existing networks predict dense outputs from arbitrary-sized inputs. Both learning and inference are performed whole-image-at-a-time by dense feedforward computation and backpropagation. In-network upsampling layers enable pixelwise prediction and learning in nets with subsampled pooling.
我们表明:在语义分割上端到端、像素到像素训练的全卷积网络(FCN),无需额外机关即可超过当时最优。据我们所知,这是首个(1)为像素级预测、(2)从有监督预训练出发、端到端训练 FCN 的工作。既有网络的全卷积版本可从任意尺寸输入预测稠密输出。学习与推理都以整图为单位,通过稠密前馈计算与反向传播完成。网络内上采样层使带有下采样池化的网络也能做像素级预测与学习。
This method is efficient, both asymptotically and absolutely, and precludes the need for the complications in other works. Patchwise training is common [27, 2, 8, 28, 11], but lacks the efficiency of fully convolutional training. Our approach does not make use of pre- and post-processing complications, including superpixels [8, 16], proposals [16, 14], or post-hoc refinement by random fields or local classifiers [8, 16]. Our model transfers recent success in classification [19, 31, 32] to dense prediction by reinterpreting classification nets as fully convolutional and fine-tuning from their learned representations. In contrast, previous works have applied small convnets without supervised pre-training [8, 28, 27].
该方法在渐近意义与绝对意义上都高效,从而不必再依赖其他工作中的复杂手段。按块(patch)训练很常见 [27, 2, 8, 28, 11],但缺少全卷积训练的效率。我们的方法不用超像素 [8, 16]、提议框 [16, 14],也不用随机场或局部分类器做事后精修 [8, 16]。通过把分类网重新解释为全卷积并从其已学表征微调,我们把近期分类上的成功 [19, 31, 32] 迁移到稠密预测。相较之下,先前工作多用小卷积网且无有监督预训练 [8, 28, 27]。
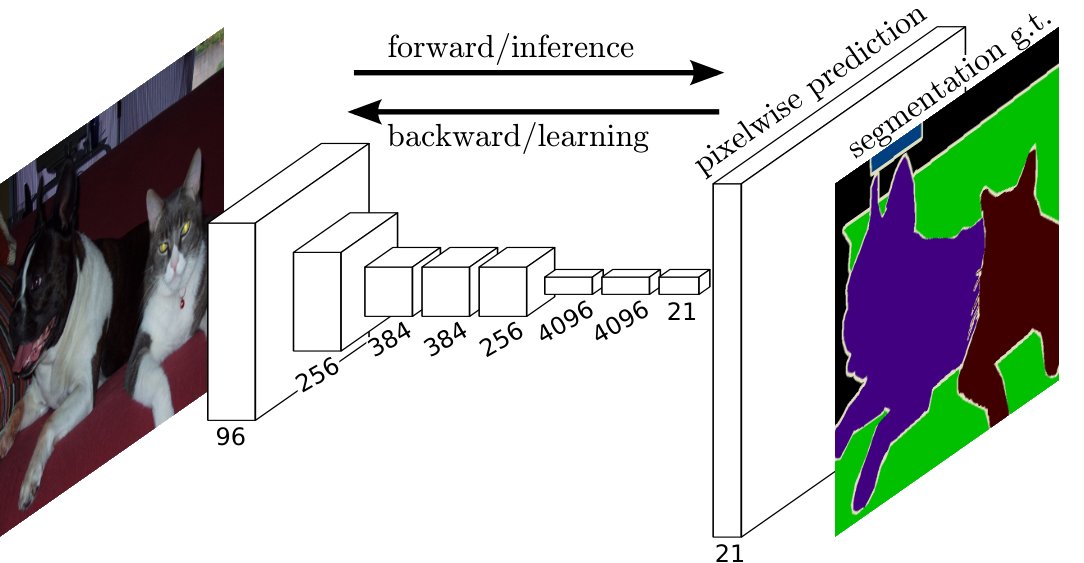
Figure 1: Fully convolutional networks can efficiently learn to make dense predictions for per-pixel tasks like semantic segmentation.
图 1:全卷积网络能高效学习为语义分割一类逐像素任务做稠密预测。
Semantic segmentation faces an inherent tension between semantics and location: global information resolves what while local information resolves where. Deep feature hierarchies jointly encode location and semantics in a local-to-global pyramid. We define a novel “skip” architecture to combine deep, coarse, semantic information and shallow, fine, appearance information in Section 4.2 (see Figure 3).
语义分割面临语义与位置之间固有的张力:全局信息回答「是什么」,局部信息回答「在哪里」。深层特征层次在由局部到全局的金字塔中联合编码位置与语义。我们在第 4.2 节定义一种新颖的「跳跃」结构,用以结合深层、粗糙的语义信息与浅层、精细的外观信息(见图 3)。
In the next section, we review related work on deep classification nets, FCNs, and recent approaches to semantic segmentation using convnets. The following sections explain FCN design and dense prediction tradeoffs, introduce our architecture with in-network upsampling and multi-layer combinations, and describe our experimental framework. Finally, we demonstrate state-of-the-art results on PASCAL VOC 2011-2, NYUDv2, and SIFT Flow.
下一节回顾深度分类网、FCN,以及用卷积网做语义分割的近期方法。随后各节说明 FCN 设计与稠密预测权衡,介绍带网络内上采样与多层融合的结构,并描述实验框架。最后在 PASCAL VOC 2011–2、NYUDv2 与 SIFT Flow 上展示当时最优结果。
2 Related work
2 相关工作
Our approach draws on recent successes of deep nets for image classification [19, 31, 32] and transfer learning [4, 38]. Transfer was first demonstrated on various visual recognition tasks [4, 38], then on detection, and on both instance and semantic segmentation in hybrid proposal-classifier models [12, 16, 14]. We now re-architect and fine-tune classification nets to direct, dense prediction of semantic segmentation. We chart the space of FCNs and situate prior models, both historical and recent, in this framework.
我们的方法依托深度网络在图像分类 [19, 31, 32] 与迁移学习 [4, 38] 上的近期成功。迁移先在各类视觉识别任务上得到验证 [4, 38],再扩展到检测,以及混合「提议–分类器」模型中的实例与语义分割 [12, 16, 14]。我们现在重新设计并微调分类网,直接做语义分割的稠密预测。我们梳理 FCN 的空间,并把历史与近期的先前模型置于这一框架中。
Fully convolutional networks To our knowledge, the idea of extending a convnet to arbitrary-sized inputs first appeared in Matan et al. [25], which extended the classic LeNet [21] to recognize strings of digits. Because their net was limited to one-dimensional input strings, Matan et al. used Viterbi decoding to obtain their outputs. Wolf and Platt [37] expand convnet outputs to 2-dimensional maps of detection scores for the four corners of postal address blocks. Both of these historical works do inference and learning fully convolutionally for detection. Ning et al. [27] define a convnet for coarse multiclass segmentation of C. elegans tissues with fully convolutional inference.
全卷积网络 据我们所知,把卷积网扩展到任意尺寸输入的想法最早出现在 Matan et al. [25],他们把经典 LeNet [21] 扩展到识别数字串。因其网络限于一维输入串,Matan et al. 用 Viterbi 解码得到输出。Wolf 与 Platt [37] 把卷积网输出扩展为二维检测分数图,用于邮政地址块的四角。这两项早期工作都为检测做全卷积推理与学习。Ning et al. [27] 定义了用于秀丽隐杆线虫组织粗多类分割的卷积网,并做全卷积推理。
Fully convolutional computation has also been exploited in the present era of many-layered nets. Sliding window detection by Sermanet et al. [29], semantic segmentation by Pinheiro and Collobert [28], and image restoration by Eigen et al. [5] do fully convolutional inference. Fully convolutional training is rare, but used effectively by Tompson et al. [35] to learn an end-to-end part detector and spatial model for pose estimation, although they do not exposit on or analyze this method.
在多层网络盛行的当代,全卷积计算同样被利用。Sermanet et al. [29] 的滑动窗口检测、Pinheiro 与 Collobert [28] 的语义分割,以及 Eigen et al. [5] 的图像复原,都做全卷积推理。全卷积训练仍少见,但 Tompson et al. [35] 有效地用它端到端学习姿态估计的部件检测器与空间模型,不过他们并未阐释或分析该方法。
Alternatively, He et al. [17] discard the non-convolutional portion of classification nets to make a feature extractor. They combine proposals and spatial pyramid pooling to yield a localized, fixed-length feature for classification. While fast and effective, this hybrid model cannot be learned end-to-end.
另一条路是 He et al. [17]:丢掉分类网的非卷积部分做成特征提取器,再结合提议与空间金字塔池化,得到用于分类的局部化定长特征。这一混合模型虽快且有效,但不能端到端学习。
Dense prediction with convnets Several recent works have applied convnets to dense prediction problems, including semantic segmentation by Ning et al. [27], Farabet et al. [8], and Pinheiro and Collobert [28]; boundary prediction for electron microscopy by Ciresan et al. [2] and for natural images by a hybrid neural net/nearest neighbor model by Ganin and Lempitsky [11]; and image restoration and depth estimation by Eigen et al. [5, 6]. Common elements of these approaches include
用卷积网做稠密预测 若干近期工作把卷积网用于稠密预测,包括 Ning et al. [27]、Farabet et al. [8]、Pinheiro 与 Collobert [28] 的语义分割;Ciresan et al. [2] 的电镜边界预测,以及 Ganin 与 Lempitsky [11] 用混合神经网/最近邻模型做自然图像边界;还有 Eigen et al. [5, 6] 的图像复原与深度估计。这些方法的常见要素包括
- • small models restricting capacity and receptive fields;
- • 容量与感受野受限的小模型;
- • patchwise training [27, 2, 8, 28, 11];
- • 按块训练 [27, 2, 8, 28, 11];
- • post-processing by superpixel projection, random field regularization, filtering, or local classification [8, 2, 11];
- • 用超像素投影、随机场正则、滤波或局部分类做后处理 [8, 2, 11];
- • input shifting and output interlacing for dense output [28, 11] as introduced by OverFeat [29];
- • 为得到稠密输出而做的输入平移与输出交织 [28, 11](由 OverFeat [29] 引入);
- • multi-scale pyramid processing [8, 28, 11];
- • 多尺度金字塔处理 [8, 28, 11];
- • saturating nonlinearities [8, 5, 28]; and
- • 饱和的 非线性 [8, 5, 28];以及
- • ensembles [2, 11],
- • 集成 [2, 11],
whereas our method does without this machinery. However, we do study patchwise training 3.4 and “shift-and-stitch” dense output 3.2 from the perspective of FCNs. We also discuss in-network upsampling 3.3, of which the fully connected prediction by Eigen et al. [6] is a special case.
而我们的方法不依赖这些机关。不过,我们仍从 FCN 视角研究按块训练(3.4)与「平移–交织」稠密输出(3.2)。我们也讨论网络内上采样(3.3),Eigen et al. [6] 的全连接预测是其上采样的一个特例。
Unlike these existing methods, we adapt and extend deep classification architectures, using image classification as supervised pre-training, and fine-tune fully convolutionally to learn simply and efficiently from whole image inputs and whole image ground thruths.
与这些既有方法不同,我们改造并扩展深度分类结构,以图像分类为有监督预训练,再全卷积地微调,从而简单地、高效地从整图输入与整图真值学习。
Hariharan et al. [16] and Gupta et al. [14] likewise adapt deep classification nets to semantic segmentation, but do so in hybrid proposal-classifier models. These approaches fine-tune an R-CNN system [12] by sampling bounding boxes and/or region proposals for detection, semantic segmentation, and instance segmentation. Neither method is learned end-to-end.
Hariharan et al. [16] 与 Gupta et al. [14] 同样把深度分类网用于语义分割,但是在混合「提议–分类器」模型中:通过采样边界框和/或区域提议,微调 R-CNN 系统 [12],以做检测、语义分割与实例分割。两种方法都不是端到端学习。
They achieve state-of-the-art results on PASCAL VOC segmentation and NYUDv2 segmentation respectively, so we directly compare our standalone, end-to-end FCN to their semantic segmentation results in Section 5.
它们分别在 PASCAL VOC 分割与 NYUDv2 分割上达到当时最优,因此我们在第 5 节把独立的端到端 FCN 与其语义分割结果直接对比。
3 Fully convolutional networks
3 全卷积网络
Each layer of data in a convnet is a three-dimensional array of size , where and are spatial dimensions, and is the feature or channel dimension. The first layer is the image, with pixel size , and color channels. Locations in higher layers correspond to the locations in the image they are path-connected to, which are called their receptive fields.
卷积网中每一层数据是尺寸为 的三维数组,其中 与 为空间维, 为特征或通道维。第一层是图像,像素大小为 , 为颜色通道。更高层中的位置对应它们在图像中有路径相连的位置,称为其感受野。
Convnets are built on translation invariance. Their basic components (convolution, pooling, and activation functions) operate on local input regions, and depend only on relative spatial coordinates. Writing for the data vector at location in a particular layer, and for the following layer, these functions compute outputs by
卷积网建立在平移不变性之上。其基本组件(卷积、池化与激活函数)作用于局部输入区域,且只依赖相对空间坐标。记某一层位置 处的数据向量为 ,下一层为 ,这些函数按下式计算输出
where is called the kernel size, is the stride or subsampling factor, and determines the layer type: a matrix multiplication for convolution or average pooling, a spatial max for max pooling, or an elementwise nonlinearity for an activation function, and so on for other types of layers.
其中 称为核大小, 为步长或下采样因子, 决定层类型:卷积或平均池化为矩阵乘法,最大池化为空间取最大,激活函数为逐元素非线性,其他层类型依此类推。
This functional form is maintained under composition, with kernel size and stride obeying the transformation rule
这一函数形式在复合下保持,核大小与步长服从变换规则
While a general deep net computes a general nonlinear function, a net with only layers of this form computes a nonlinear filter, which we call a deep filter or fully convolutional network. An FCN naturally operates on an input of any size, and produces an output of corresponding (possibly resampled) spatial dimensions.
一般深度网络计算一般非线性函数;而仅由这类层构成的网络计算的是非线性滤波器,我们称之为深度滤波器或全卷积网络。FCN 天然可作用于任意尺寸输入,并产生对应(可能经重采样)空间尺寸的输出。
A real-valued loss function composed with an FCN defines a task. If the loss function is a sum over the spatial dimensions of the final layer, , its gradient will be a sum over the gradients of each of its spatial components. Thus stochastic gradient descent on computed on whole images will be the same as stochastic gradient descent on , taking all of the final layer receptive fields as a minibatch.
与 FCN 复合的实值损失函数定义一项任务。若损失函数是对最终层空间维的求和,,则其梯度是各空间分量梯度之和。因此,在整图上对 做随机梯度下降,等价于把最终层全部感受野当作一个 minibatch,对 做随机梯度下降。
When these receptive fields overlap significantly, both feedforward computation and backpropagation are much more efficient when computed layer-by-layer over an entire image instead of independently patch-by-patch.
当这些感受野显著重叠时,相对按块独立计算,按层对整图做前馈与反向传播都高效得多。
We next explain how to convert classification nets into fully convolutional nets that produce coarse output maps. For pixelwise prediction, we need to connect these coarse outputs back to the pixels. Section 3.2 describes a trick that OverFeat [29] introduced for this purpose. We gain insight into this trick by reinterpreting it as an equivalent network modification. As an efficient, effective alternative, we introduce deconvolution layers for upsampling in Section 3.3. In Section 3.4 we consider training by patchwise sampling, and give evidence in Section 4.3 that our whole image training is faster and equally effective.
下面先说明如何把分类网转换成产出粗糙输出图的全卷积网。为做像素级预测,还需把这些粗糙输出连回像素。第 3.2 节描述 OverFeat [29] 为此引入的技巧;我们将其重新解释为等价的网络改动以获得洞见。作为高效、有效的替代,第 3.3 节引入用于上采样的反卷积层。第 3.4 节考虑按块采样训练,并在第 4.3 节给出证据:整图训练更快且同样有效。
3.1 Adapting classifiers for dense prediction
3.1 把分类器改造成稠密预测
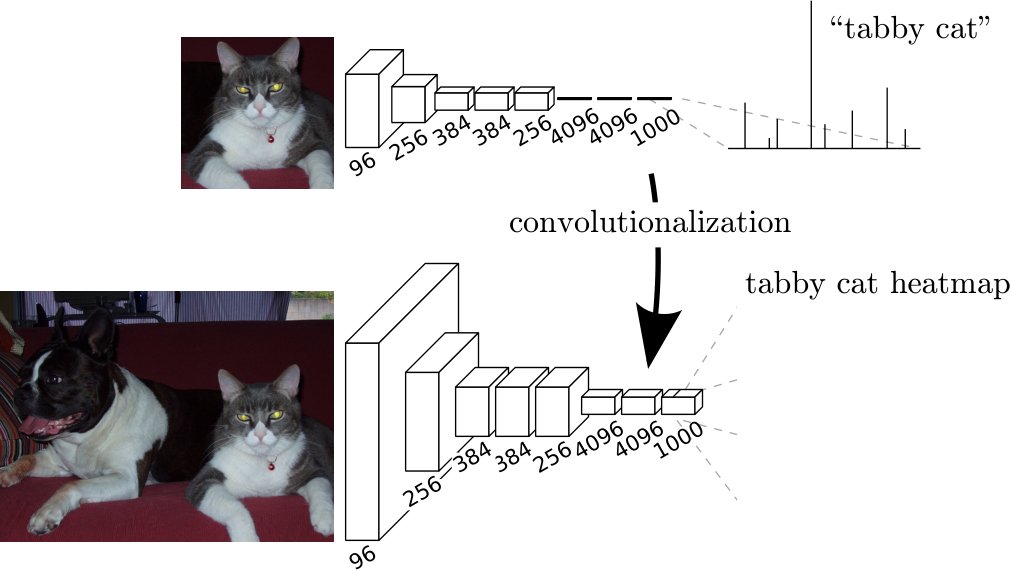
Figure 2: Transforming fully connected layers into convolution layers enables a classification net to output a heatmap. Adding layers and a spatial loss (as in Figure 1) produces an efficient machine for end-to-end dense learning.
图 2:把全连接层变成卷积层,使分类网能输出热图。再添加层与空间损失(如图 1),即得到用于端到端稠密学习的高效机器。
Typical recognition nets, including LeNet [21], AlexNet [19], and its deeper successors [31, 32], ostensibly take fixed-sized inputs and produce nonspatial outputs. The fully connected layers of these nets have fixed dimensions and throw away spatial coordinates. However, these fully connected layers can also be viewed as convolutions with kernels that cover their entire input regions. Doing so casts them into fully convolutional networks that take input of any size and output classification maps. This transformation is illustrated in Figure 2. (By contrast, nonconvolutional nets, such as the one by Le et al. [20], lack this capability.)
典型识别网络,包括 LeNet [21]、AlexNet [19] 及其更深后继 [31, 32],表面上接受固定尺寸输入并产生非空间输出。这些网络的全连接层维度固定,并丢掉空间坐标。不过,全连接层也可看成核覆盖整个输入区域的卷积。如此一来,它们就变成可接受任意尺寸输入并输出分类图的全卷积网络。这一变换见图 2。(相较之下,Le et al. [20] 一类非卷积网不具备该能力。)
Furthermore, while the resulting maps are equivalent to the evaluation of the original net on particular input patches, the computation is highly amortized over the overlapping regions of those patches. For example, while AlexNet takes ms (on a typical GPU) to produce the classification scores of a image, the fully convolutional version takes ms to produce a grid of outputs from a image, which is more than times faster than the naïve approach[^1].
此外,所得图虽等价于原网在特定输入块上的求值,但计算在这些块的重叠区域上被高度摊销。例如,AlexNet 对 图像产生分类分数约需 ms(典型 GPU),而其全卷积版本对 图像产生 输出网格约需 ms,比朴素做法快 5 倍以上。[^1]
The spatial output maps of these convolutionalized models make them a natural choice for dense problems like semantic segmentation. With ground truth available at every output cell, both the forward and backward passes are straightforward, and both take advantage of the inherent computational efficiency (and aggressive optimization) of convolution.
这些「卷积化」模型的空间输出图,使它们成为语义分割一类稠密问题的自然选择。在每个输出单元都有真值时,前向与反向都直接,且都能利用卷积固有的计算效率(以及激进的优化)。
The corresponding backward times for the AlexNet example are ms for a single image and ms for a fully convolutional output map, resulting in a speedup similar to that of the forward pass. This dense backpropagation is illustrated in Figure 1.
上述 AlexNet 例子的对应反向时间:单图 ms,全卷积 输出图 ms,加速比与前向相近。这一稠密反向传播见图 1。
While our reinterpretation of classification nets as fully convolutional yields output maps for inputs of any size, the output dimensions are typically reduced by subsampling. The classification nets subsample to keep filters small and computational requirements reasonable. This coarsens the output of a fully convolutional version of these nets, reducing it from the size of the input by a factor equal to the pixel stride of the receptive fields of the output units.
虽把分类网重新解释为全卷积后,任意尺寸输入都能得到输出图,但输出尺寸通常因下采样而缩小。分类网做下采样是为了保持滤波器小、计算量合理。这使这些网络的全卷积版本输出变粗,相对输入缩小的倍数等于输出单元感受野的像素步长。
3.2 Shift-and-stitch is filter rarefaction
3.2 平移–交织即滤波器稀疏化
Input shifting and output interlacing is a trick that yields dense predictions from coarse outputs without interpolation, introduced by OverFeat [29]. If the outputs are downsampled by a factor of , the input is shifted (by left and top padding) pixels to the right and pixels down, once for every value of . These inputs are each run through the convnet, and the outputs are interlaced so that the predictions correspond to the pixels at the centers of their receptive fields.
输入平移与输出交织是由 OverFeat [29] 引入的技巧:无需插值即可从粗糙输出得到稠密预测。若输出被下采样因子 ,则对输入做左、上填充,向右平移 像素、向下平移 像素,对 的每个取值各做一次。这 个输入分别过卷积网,再把输出交织,使预测对应其感受野中心处的像素。
Changing only the filters and layer strides of a convnet can produce the same output as this shift-and-stitch trick. Consider a layer (convolution or pooling) with input stride , and a following convolution layer with filter weights (eliding the feature dimensions, irrelevant here). Setting the lower layer’s input stride to upsamples its output by a factor of , just like shift-and-stitch. However, convolving the original filter with the upsampled output does not produce the same result as the trick, because the original filter only sees a reduced portion of its (now upsampled) input. To reproduce the trick, rarefy the filter by enlarging it as
仅改变卷积网的滤波器与层步长,即可得到与该平移–交织技巧相同的输出。考虑输入步长为 的一层(卷积或池化),以及随后滤波器权重为 的卷积层(此处略去无关的特征维)。把下层输入步长设为 ,会使其输出上采样 倍,一如平移–交织。但用原滤波器与上采样输出卷积,并不能复现该技巧,因为原滤波器只看到(现已上采样的)输入的缩减部分。要复现该技巧,需按下式放大滤波器以使其稀疏化
$f^{\prime}_{ij}=\left\{\begin{tabular}[]{ll}f_{i/s,j/s}&ifsij$;\
&otherwise,\end{tabular}\right.$$
(with and zero-based). Reproducing the full net output of the trick involves repeating this filter enlargement layer-by-layer until all subsampling is removed.
(、 从零起计)。要复现技巧下的完整网络输出,需逐层重复这一滤波器放大,直到去掉所有下采样。
Simply decreasing subsampling within a net is a tradeoff: the filters see finer information, but have smaller receptive fields and take longer to compute. We have seen that the shift-and-stitch trick is another kind of tradeoff: the output is made denser without decreasing the receptive field sizes of the filters, but the filters are prohibited from accessing information at a finer scale than their original design.
单纯减小网络内下采样是一种权衡:滤波器看到更细信息,但感受野变小、计算更慢。我们已经看到,平移–交织是另一种权衡:输出变密且不减小滤波器感受野,但滤波器被禁止访问细于原设计尺度的信息。
Although we have done preliminary experiments with shift-and-stitch, we do not use it in our model. We find learning through upsampling, as described in the next section, to be more effective and efficient, especially when combined with the skip layer fusion described later on.
我们虽对平移–交织做过初步实验,但最终模型未采用。我们发现,按下节所述通过上采样来学习,尤其与后文跳跃层融合结合时,更有效也更高效。
3.3 Upsampling is backwards strided convolution
3.3 上采样即反向跨步卷积
Another way to connect coarse outputs to dense pixels is interpolation. For instance, simple bilinear interpolation computes each output from the nearest four inputs by a linear map that depends only on the relative positions of the input and output cells.
把粗糙输出连回稠密像素的另一条路是插值。例如,简单双线性插值用仅依赖输入与输出单元相对位置的线性映射,由最近的四个输入计算每个输出 。
In a sense, upsampling with factor is convolution with a fractional input stride of . So long as is integral, a natural way to upsample is therefore backwards convolution (sometimes called deconvolution) with an output stride of . Such an operation is trivial to implement, since it simply reverses the forward and backward passes of convolution. Thus upsampling is performed in-network for end-to-end learning by backpropagation from the pixelwise loss.
在某种意义上,因子为 的上采样是输入步长为 的分数卷积。只要 为整数,一种自然的上采样方式就是输出步长为 的反向卷积(有时称反卷积)。该运算实现很直接:只需对调卷积的前向与反向。于是上采样在网络内完成,可从像素级损失反向传播做端到端学习。
Note that the deconvolution filter in such a layer need not be fixed (e.g., to bilinear upsampling), but can be learned. A stack of deconvolution layers and activation functions can even learn a nonlinear upsampling.
注意:这类层中的反卷积滤波器不必固定(例如固定为双线性上采样),而可以学习。一叠反卷积层与激活函数甚至能学到非线性上采样。
In our experiments, we find that in-network upsampling is fast and effective for learning dense prediction. Our best segmentation architecture uses these layers to learn to upsample for refined prediction in Section 4.2.
实验中我们发现,网络内上采样对学习稠密预测又快又有效。我们最佳的分割结构在第 4.2 节用这些层学习上采样以精修预测。
3.4 Patchwise training is loss sampling
3.4 按块训练即损失采样
In stochastic optimization, gradient computation is driven by the training distribution. Both patchwise training and fully-convolutional training can be made to produce any distribution, although their relative computational efficiency depends on overlap and minibatch size. Whole image fully convolutional training is identical to patchwise training where each batch consists of all the receptive fields of the units below the loss for an image (or collection of images). While this is more efficient than uniform sampling of patches, it reduces the number of possible batches. However, random selection of patches within an image may be recovered simply. Restricting the loss to a randomly sampled subset of its spatial terms (or, equivalently applying a DropConnect mask [36] between the output and the loss) excludes patches from the gradient computation.
在随机优化中,梯度计算由训练分布驱动。按块训练与全卷积训练都能产生任意分布,但其相对计算效率取决于重叠程度与 minibatch 大小。整图全卷积训练等价于按块训练,且每个 batch 由损失下方各单元对一幅(或一组)图像的全部感受野组成。这比均匀采样图像块更高效,但减少了可能的 batch 种数。不过,仍可简单恢复图像内的随机选块:把损失限制到其空间项的随机子集(或等价地,在输出与损失之间施加 DropConnect 掩码 [36]),即可把某些块排除在梯度计算之外。
If the kept patches still have significant overlap, fully convolutional computation will still speed up training. If gradients are accumulated over multiple backward passes, batches can include patches from several images.[^2]
若保留的块仍有显著重叠,全卷积计算仍会加速训练。若在多次反向中累积梯度,batch 可包含来自多幅图像的块。[^2]
Sampling in patchwise training can correct class imbalance [27, 8, 2] and mitigate the spatial correlation of dense patches [28, 16]. In fully convolutional training, class balance can also be achieved by weighting the loss, and loss sampling can be used to address spatial correlation.
按块训练中的采样可纠正类别不平衡 [27, 8, 2],并缓解稠密块的空间相关 [28, 16]。在全卷积训练中,也可通过对损失加权实现类别平衡,并用损失采样应对空间相关。
We explore training with sampling in Section 4.3, and do not find that it yields faster or better convergence for dense prediction. Whole image training is effective and efficient.
我们在第 4.3 节探索带采样的训练,发现它对稠密预测并未带来更快或更好的收敛。整图训练有效且高效。
4 Segmentation Architecture
4 分割结构
We cast ILSVRC classifiers into FCNs and augment them for dense prediction with in-network upsampling and a pixelwise loss. We train for segmentation by fine-tuning. Next, we build a novel skip architecture that combines coarse, semantic and local, appearance information to refine prediction.
我们把 ILSVRC 分类器改造成 FCN,并加上网络内上采样与像素级损失以做稠密预测;通过微调训练分割。随后构建一种新颖的跳跃结构,融合粗糙语义信息与局部外观信息以精修预测。
For this investigation, we train and validate on the PASCAL VOC 2011 segmentation challenge [7]. We train with a per-pixel multinomial logistic loss and validate with the standard metric of mean pixel intersection over union, with the mean taken over all classes, including background. The training ignores pixels that are masked out (as ambiguous or difficult) in the ground truth.
本研究所用训练与验证集为 PASCAL VOC 2011 分割挑战 [7]。训练使用逐像素多项式逻辑损失,验证使用标准指标:各类(含背景)平均的像素交并比(mean IU)。训练忽略真值中被掩掉(模糊或困难)的像素。
4.1 From classifier to dense FCN
4.1 从分类器到稠密 FCN
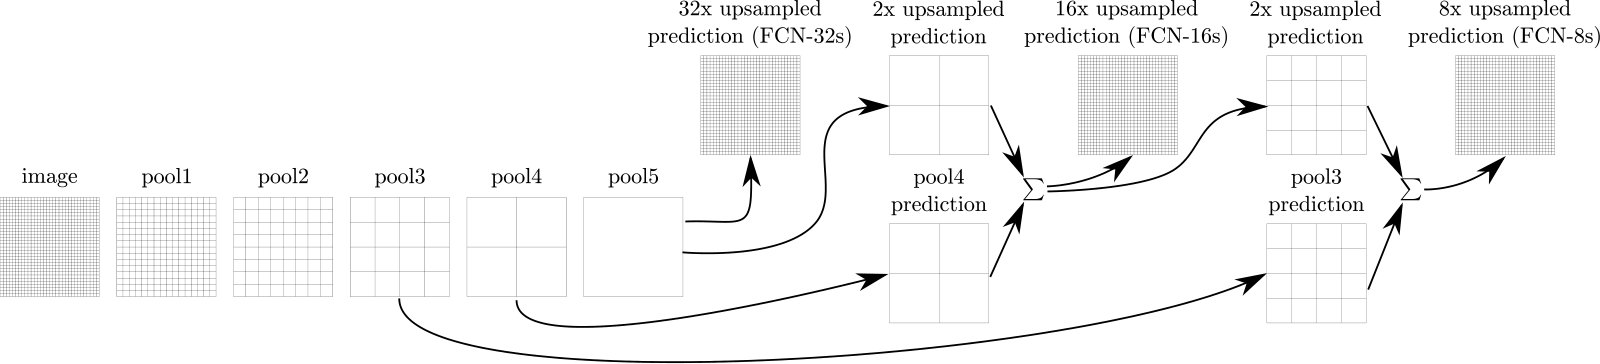
Figure 3: Our DAG nets learn to combine coarse, high layer information with fine, low layer information. Layers are shown as grids that reveal relative spatial coarseness. Only pooling and prediction layers are shown; intermediate convolution layers (including our converted fully connected layers) are omitted. Solid line (FCN-32s): Our single-stream net, described in Section 4.1, upsamples stride 32 predictions back to pixels in a single step. Dashed line (FCN-16s): Combining predictions from both the final layer and the pool4 layer, at stride 16, lets our net predict finer details, while retaining high-level semantic information. Dotted line (FCN-8s): Additional predictions from pool3, at stride 8, provide further precision.
图 3:我们的 DAG 网络学习把高层粗糙信息与低层精细信息结合起来。层画成网格以显示相对空间粗细。仅画出池化与预测层;中间卷积层(含我们转换后的全连接层)省略。实线(FCN-32s):第 4.1 节所述单流网络,一步把步长 32 的预测上采样回像素。虚线(FCN-16s):融合最终层与 pool4(步长 16)的预测,使网络在保留高层语义的同时预测更细细节。点线(FCN-8s):再加入 pool3(步长 8)的预测,提供更高精度。
We begin by convolutionalizing proven classification architectures as in Section 3. We consider the AlexNet[^3] architecture [19] that won ILSVRC12, as well as the VGG nets [31] and the GoogLeNet[^4] [32] which did exceptionally well in ILSVRC14. We pick the VGG 16-layer net[^5], which we found to be equivalent to the 19-layer net on this task. For GoogLeNet, we use only the final loss layer, and improve performance by discarding the final average pooling layer. We decapitate each net by discarding the final classifier layer, and convert all fully connected layers to convolutions. We append a convolution with channel dimension to predict scores for each of the PASCAL classes (including background) at each of the coarse output locations, followed by a deconvolution layer to bilinearly upsample the coarse outputs to pixel-dense outputs as described in Section 3.3. Table 1 compares the preliminary validation results along with the basic characteristics of each net. We report the best results achieved after convergence at a fixed learning rate (at least 175 epochs).
我们按第 3 节把已验证的分类结构卷积化。考虑赢得 ILSVRC12 的 AlexNet[^3] [19],以及在 ILSVRC14 表现突出的 VGG [31] 与 GoogLeNet[^4] [32]。我们选用 VGG 16 层网[^5],发现其在本任务上与 19 层网相当。对 GoogLeNet,我们只用最终损失层,并丢掉最终平均池化以提升表现。去掉各网最终分类层,把全部全连接层转为卷积;再接通道维为 的 卷积,在每个粗糙输出位置为 PASCAL 各类(含背景)打分;最后用反卷积层把粗糙输出双线性上采样到像素稠密输出(见第 3.3 节)。表 1 比较初步验证结果及各网基本特征。我们报告固定学习率收敛后的最佳结果(至少 175 个 epoch)。
Fine-tuning from classification to segmentation gave reasonable predictions for each net. Even the worst model achieved of state-of-the-art performance. The segmentation-equippped VGG net (FCN-VGG16) already appears to be state-of-the-art at 56.0 mean IU on val, compared to 52.6 on test [16]. Training on extra data raises performance to 59.4 mean IU on a subset of val[^7]. Training details are given in Section 4.3.
从分类微调到分割后,各网都能给出合理预测。即使最差模型也达到当时最优约 的表现。配备分割头的 VGG(FCN-VGG16)在验证集上 mean IU 已达 56.0,看起来已是当时最优(测试集上先前为 52.6 [16])。用额外数据训练后,在验证子集上可到 59.4 mean IU。[^7] 训练细节见第 4.3 节。
Despite similar classification accuracy, our implementation of GoogLeNet did not match this segmentation result.
尽管分类精度相近,我们实现的 GoogLeNet 未能达到同等分割结果。
| FCN-AlexNet | FCN-VGG16 | FCN-GoogLeNet[^4] | |
|---|---|---|---|
| mean IU | 39.8 | 56.0 | 42.5 |
| forward time | 50 ms | 210 ms | 59 ms |
| conv. layers | 8 | 16 | 22 |
| parameters | 57M | 134M | 6M |
| rf size | 355 | 404 | 907 |
| max stride | 32 | 32 | 32 |
Table 1: We adapt and extend three classification convnets to segmentation. We compare performance by mean intersection over union on the validation set of PASCAL VOC 2011 and by inference time (averaged over 20 trials for a input on an NVIDIA Tesla K40c). We detail the architecture of the adapted nets as regards dense prediction: number of parameter layers, receptive field size of output units, and the coarsest stride within the net. (These numbers give the best performance obtained at a fixed learning rate, not best performance possible.)
| FCN-AlexNet | FCN-VGG16 | FCN-GoogLeNet[^4] | |
|---|---|---|---|
| mean IU | 39.8 | 56.0 | 42.5 |
| 前向时间 | 50 ms | 210 ms | 59 ms |
| 卷积层数 | 8 | 16 | 22 |
| 参数量 | 57M | 134M | 6M |
| 感受野大小 | 355 | 404 | 907 |
| 最大步长 | 32 | 32 | 32 |
表 1:我们改造并扩展三种分类卷积网用于分割。在 PASCAL VOC 2011 验证集上以 mean IU 比较性能,并以推理时间比较( 输入在 NVIDIA Tesla K40c 上平均 20 次)。我们详列改造后网络与稠密预测相关的结构:参数层数、输出单元感受野大小,以及网内最粗步长。(这些数字为固定学习率下的最佳表现,未必是可能达到的最佳。)
4.2 Combining what and where
4.2 融合「是什么」与「在哪里」
We define a new fully convolutional net (FCN) for segmentation that combines layers of the feature hierarchy and refines the spatial precision of the output. See Figure 3.
我们为分割定义一种新的全卷积网(FCN),融合特征层次各层并精修输出的空间精度。见图 3。
While fully convolutionalized classifiers can be fine-tuned to segmentation as shown in 4.1, and even score highly on the standard metric, their output is dissatisfyingly coarse (see Figure 4). The 32 pixel stride at the final prediction layer limits the scale of detail in the upsampled output.
虽如 4.1 所示,全卷积化的分类器可微调到分割,甚至在标准指标上得分很高,但其输出粗糙得令人不满(见图 4)。最终预测层 32 像素的步长限制了上采样输出中细节的尺度。
We address this by adding links that combine the final prediction layer with lower layers with finer strides. This turns a line topology into a DAG, with edges that skip ahead from lower layers to higher ones (Figure 3). As they see fewer pixels, the finer scale predictions should need fewer layers, so it makes sense to make them from shallower net outputs. Combining fine layers and coarse layers lets the model make local predictions that respect global structure. By analogy to the multiscale local jet of Florack et al. [10], we call our nonlinear local feature hierarchy the deep jet.
我们的做法是:加入把最终预测层与更细步长的较低层结合起来的连接。这把线状拓扑变成 DAG,边从较低层跳到较高层(图 3)。因所见像素更少,更细尺度的预测应需要更少层,故从较浅网络输出做这些预测是合理的。融合细层与粗层,使模型能在尊重全局结构的同时做局部预测。类比 Florack et al. [10] 的多尺度局部 jet,我们把这一非线性局部特征层次称为深度 jet。
We first divide the output stride in half by predicting from a 16 pixel stride layer. We add a convolution layer on top of pool4 to produce additional class predictions. We fuse this output with the predictions computed on top of conv7 (convolutionalized fc7) at stride 32 by adding a upsampling layer and summing[^6] both predictions. (See Figure 3). We initialize the upsampling to bilinear interpolation, but allow the parameters to be learned as described in Section 3.3. Finally, the stride 16 predictions are upsampled back to the image. We call this net FCN-16s. FCN-16s is learned end-to-end, initialized with the parameters of the last, coarser net, which we now call FCN-32s. The new parameters acting on pool4 are zero-initialized so that the net starts with unmodified predictions. The learning rate is decreased by a factor of 100.
我们先从步长 16 像素的层做预测,把输出步长减半:在 pool4 上加 卷积以产生额外类别预测;再加 上采样层,与 conv7(卷积化后的 fc7)上步长 32 的预测相加融合[^6](见图 3)。 上采样初始化为双线性插值,但允许按第 3.3 节学习参数。最后把步长 16 的预测上采样回图像。我们称该网为 FCN-16s。FCN-16s 端到端学习,用上一较粗网(现称 FCN-32s)的参数初始化;作用在 pool4 上的新参数零初始化,使网络一开始保持未改动的预测。学习率降低 100 倍。
Learning this skip net improves performance on the validation set by 3.0 mean IU to 62.4. Figure 4 shows improvement in the fine structure of the output. We compared this fusion with learning only from the pool4 layer (which resulted in poor performance), and simply decreasing the learning rate without adding the extra link (which results in an insignificant performance improvement, without improving the quality of the output).
学习该跳跃网使验证集表现提升 3.0 mean IU,达到 62.4。图 4 显示输出细结构的改善。我们对比了:只从 pool4 层学习(表现很差),以及不加额外连接、只降低学习率(提升可忽略,且不改善输出质量)。
We continue in this fashion by fusing predictions from pool3 with a upsampling of predictions fused from pool4 and conv7, building the net FCN-8s. We obtain a minor additional improvement to 62.7 mean IU, and find a slight improvement in the smoothness and detail of our output. At this point our fusion improvements have met diminishing returns, both with respect to the IU metric which emphasizes large-scale correctness, and also in terms of the improvement visible e.g. in Figure 4, so we do not continue fusing even lower layers.
我们继续把 pool3 的预测与由 pool4、conv7 融合后再 上采样的预测融合,建成 FCN-8s。mean IU 再小幅升至 62.7,输出平滑度与细节略有改善。至此,融合带来的提升已进入收益递减:无论强调大尺度正确性的 IU 指标,还是如图 4 可见的改善,都不再明显,故不再继续融合更低层。
| FCN-32s | FCN-16s | FCN-8s | Ground truth |
|---|---|---|---|
Figure 4: Refining fully convolutional nets by fusing information from layers with different strides improves segmentation detail. The first three images show the output from our 32, 16, and 8 pixel stride nets (see Figure 3).
| FCN-32s | FCN-16s | FCN-8s | 真值 |
|---|---|---|---|
图 4:通过融合不同步长层的信息精修全卷积网,可改善分割细节。前三幅图分别来自步长 32、16、8 像素的网络输出(见图 3)。
| pixel acc. | mean acc. | mean IU | f.w. IU | |
|---|---|---|---|---|
| FCN-32s-fixed | 83.0 | 59.7 | 45.4 | 72.0 |
| FCN-32s | 89.1 | 73.3 | 59.4 | 81.4 |
| FCN-16s | 90.0 | 75.7 | 62.4 | 83.0 |
| FCN-8s | 90.3 | 75.9 | 62.7 | 83.2 |
Table 2: Comparison of skip FCNs on a subset of PASCAL VOC2011 validation[^7]. Learning is end-to-end, except for FCN-32s-fixed, where only the last layer is fine-tuned. Note that FCN-32s is FCN-VGG16, renamed to highlight stride.
| pixel acc. | mean acc. | mean IU | f.w. IU | |
|---|---|---|---|---|
| FCN-32s-fixed | 83.0 | 59.7 | 45.4 | 72.0 |
| FCN-32s | 89.1 | 73.3 | 59.4 | 81.4 |
| FCN-16s | 90.0 | 75.7 | 62.4 | 83.0 |
| FCN-8s | 90.3 | 75.9 | 62.7 | 83.2 |
表 2:PASCAL VOC2011 验证子集[^7] 上跳跃 FCN 的对比。除 FCN-32s-fixed(仅微调最后一层)外均为端到端学习。注意 FCN-32s 即 FCN-VGG16,改名以突出步长。
Refinement by other means Decreasing the stride of pooling layers is the most straightforward way to obtain finer predictions. However, doing so is problematic for our VGG16-based net. Setting the pool5 layer to have stride 1 requires our convolutionalized fc6 to have a kernel size of in order to maintain its receptive field size. In addition to their computational cost, we had difficulty learning such large filters. We made an attempt to re-architect the layers above pool5 with smaller filters, but were not successful in achieving comparable performance; one possible explanation is that the initialization from ImageNet-trained weights in the upper layers is important.
用其他手段精修 减小池化层步长是获得更细预测最直接的办法,但对我们基于 VGG16 的网络有问题:把 pool5 步长设为 1,则卷积化后的 fc6 需用 核以保持感受野。除计算代价外,我们很难学会如此大的滤波器。我们曾尝试用更小滤波器重构 pool5 以上各层,但未能达到可比表现;一种可能解释是:上层来自 ImageNet 训练权重的初始化很重要。
Another way to obtain finer predictions is to use the shift-and-stitch trick described in Section 3.2. In limited experiments, we found the cost to improvement ratio from this method to be worse than layer fusion.
获得更细预测的另一条路是第 3.2 节的平移–交织技巧。在有限实验中,我们发现该方法的「代价/提升」比不如层融合。
4.3 Experimental framework
4.3 实验框架
Optimization We train by SGD with momentum. We use a minibatch size of 20 images and fixed learning rates of , , and for FCN-AlexNet, FCN-VGG16, and FCN-GoogLeNet, respectively, chosen by line search. We use momentum , weight decay of or , and doubled the learning rate for biases, although we found training to be insensitive to these parameters (but sensitive to the learning rate). We zero-initialize the class scoring convolution layer, finding random initialization to yield neither better performance nor faster convergence. Dropout was included where used in the original classifier nets.
优化 我们用带动量的 SGD 训练。minibatch 为 20 幅图像;FCN-AlexNet、FCN-VGG16、FCN-GoogLeNet 的固定学习率经线搜索分别取 、、。动量 0.9,权重衰减 或 ,偏置学习率加倍;我们发现训练对这些参数不敏感(但对学习率敏感)。类别打分卷积层零初始化;随机初始化既不带来更好表现,也不加快收敛。原分类网中使用的 dropout 予以保留。
Fine-tuning We fine-tune all layers by back-propagation through the whole net. Fine-tuning the output classifier alone yields only 70% of the full fine-tuning performance as compared in Table 2. Training from scratch is not feasible considering the time required to learn the base classification nets. (Note that the VGG net is trained in stages, while we initialize from the full 16-layer version.) Fine-tuning takes three days on a single GPU for the coarse FCN-32s version, and about one day each to upgrade to the FCN-16s and FCN-8s versions.
微调 我们通过整网反向传播微调所有层。如表 2 对比,只微调输出分类器仅能达到完整微调约 70% 的表现。从零训练不可行,因为学基础分类网本身就很耗时。(注意 VGG 是分阶段训练的,而我们从完整 16 层版本初始化。)粗糙版 FCN-32s 在单 GPU 上微调约三天,升级到 FCN-16s 与 FCN-8s 各约一天。
Patch Sampling As explained in Section 3.4, our full image training effectively batches each image into a regular grid of large, overlapping patches. By contrast, prior work randomly samples patches over a full dataset [27, 2, 8, 28, 11], potentially resulting in higher variance batches that may accelerate convergence [22]. We study this tradeoff by spatially sampling the loss in the manner described earlier, making an independent choice to ignore each final layer cell with some probability . To avoid changing the effective batch size, we simultaneously increase the number of images per batch by a factor . Note that due to the efficiency of convolution, this form of rejection sampling is still faster than patchwise training for large enough values of (e.g., at least for according to the numbers in Section 3.1). Figure 5 shows the effect of this form of sampling on convergence. We find that sampling does not have a significant effect on convergence rate compared to whole image training, but takes significantly more time due to the larger number of images that need to be considered per batch. We therefore choose unsampled, whole image training in our other experiments.
块采样 如第 3.4 节所释,我们的整图训练等价于把每幅图像批成规则网格上的大块重叠图块。相较之下,先前工作在整个数据集上随机采样图块 [27, 2, 8, 28, 11],可能得到方差更高的 batch,从而加速收敛 [22]。我们按前文所述对损失做空间采样来研究这一权衡:以概率 独立忽略每个最终层单元。为避免有效 batch 大小变化,同时把每 batch 图像数增大 倍。注意由于卷积高效,只要 足够大(例如按第 3.1 节数字,),这种拒绝采样仍快于按块训练。图 5 显示该采样对收敛的影响。我们发现:相对整图训练,采样对收敛速度无显著影响,却因每 batch 需考虑更多图像而明显更慢。因此其他实验均采用不采样的整图训练。
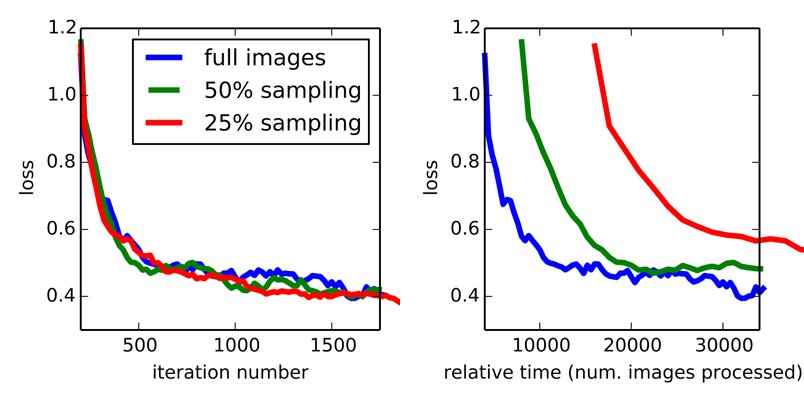
Figure 5: Training on whole images is just as effective as sampling patches, but results in faster (wall time) convergence by making more efficient use of data. Left shows the effect of sampling on convergence rate for a fixed expected batch size, while right plots the same by relative wall time.
图 5:整图训练与采样图块同样有效,但因数据利用更充分,挂钟时间上收敛更快。左图为固定期望 batch 大小下采样对收敛速率的影响;右图按相对挂钟时间绘制同一结果。
Class Balancing Fully convolutional training can balance classes by weighting or sampling the loss. Although our labels are mildly unbalanced (about are background), we find class balancing unnecessary.
类别平衡 全卷积训练可通过加权或采样损失来平衡类别。尽管标签轻度不平衡(约 为背景),我们发现不必做类别平衡。
Dense Prediction The scores are upsampled to the input dimensions by deconvolution layers within the net. Final layer deconvolutional filters are fixed to bilinear interpolation, while intermediate upsampling layers are initialized to bilinear upsampling, and then learned. Shift-and-stitch (Section 3.2), or the filter rarefaction equivalent, are not used.
稠密预测 分数由网内反卷积层上采样到输入尺寸。最终层反卷积滤波器固定为双线性插值;中间上采样层初始化为双线性上采样后再学习。不使用平移–交织(第 3.2 节)或其滤波器稀疏化等价形式。
Augmentation We tried augmenting the training data by randomly mirroring and “jittering” the images by translating them up to 32 pixels (the coarsest scale of prediction) in each direction. This yielded no noticeable improvement.
增强 我们尝试过随机镜像,以及在各方向最多平移 32 像素(最粗预测尺度)的「抖动」。未观察到明显提升。
More Training Data The PASCAL VOC 2011 segmentation challenge training set, which we used for Table 1, labels 1112 images. Hariharan et al. [15] have collected labels for a much larger set of 8498 PASCAL training images, which was used to train the previous state-of-the-art system, SDS [16]. This training data improves the FCN-VGG16 validation score[^7] by 3.4 points to 59.4 mean IU.
更多训练数据 表 1 所用的 PASCAL VOC 2011 分割训练集约标注 1112 幅图像。Hariharan et al. [15] 为更大的 8498 幅 PASCAL 训练图像收集了标注,先前最优系统 SDS [16] 即用该数据训练。这些训练数据使 FCN-VGG16 验证分数[^7] 提升 3.4 点,达到 59.4 mean IU。
Implementation All models are trained and tested with Caffe [18] on a single NVIDIA Tesla K40c. The models and code will be released open-source on publication.
实现 全部模型在单块 NVIDIA Tesla K40c 上用 Caffe [18] 训练与测试。模型与代码将于发表时开源。
5 Results
5 结果
We test our FCN on semantic segmentation and scene parsing, exploring PASCAL VOC, NYUDv2, and SIFT Flow. Although these tasks have historically distinguished between objects and regions, we treat both uniformly as pixel prediction. We evaluate our FCN skip architecture[^8] on each of these datasets, and then extend it to multi-modal input for NYUDv2 and multi-task prediction for the semantic and geometric labels of SIFT Flow.
我们在语义分割与场景解析上测试 FCN,探索 PASCAL VOC、NYUDv2 与 SIFT Flow。虽这些任务历史上区分物体与区域,我们统一当作像素预测。我们在各数据集上评估 FCN 跳跃结构[^8],再扩展到 NYUDv2 的多模态输入,以及 SIFT Flow 上语义与几何标签的多任务预测。
Metrics We report four metrics from common semantic segmentation and scene parsing evaluations that are variations on pixel accuracy and region intersection over union (IU). Let be the number of pixels of class predicted to belong to class , where there are different classes, and let be the total number of pixels of class . We compute:
指标 我们报告语义分割与场景解析常用的四项指标,它们是像素精度与区域交并比(IU)的变体。令 为类别 的像素被预测为类别 的数量,共有 类,并令 为类别 的像素总数。我们计算:
- • pixel accuracy:
- • 像素精度:
- • mean accuraccy:
- • 平均精度:
- • mean IU:
- • mean IU:
- • frequency weighted IU:
- • 频率加权 IU:
PASCAL VOC Table 3 gives the performance of our FCN-8s on the test sets of PASCAL VOC 2011 and 2012, and compares it to the previous state-of-the-art, SDS [16], and the well-known R-CNN [12]. We achieve the best results on mean IU[^9] by a relative margin of 20%. Inference time is reduced (convnet only, ignoring proposals and refinement) or (overall).
PASCAL VOC 表 3 给出 FCN-8s 在 PASCAL VOC 2011 与 2012 测试集上的表现,并与先前最优 SDS [16] 及著名的 R-CNN [12] 对比。我们在 mean IU[^9] 上相对领先 20%。推理时间降至 (仅卷积网,不计提议与精修)或 (整体)。
| mean IU | mean IU | inference | |
|---|---|---|---|
| VOC2011 test | VOC2012 test | time | |
| R-CNN [12] | 47.9 | - | - |
| SDS [16] | 52.6 | 51.6 | 50 s |
| FCN-8s | 62.7 | 62.2 | 175 ms |
Table 3: Our fully convolutional net gives a 20% relative improvement over the state-of-the-art on the PASCAL VOC 2011 and 2012 test sets, and reduces inference time.
| mean IU | mean IU | 推理 | |
|---|---|---|---|
| VOC2011 test | VOC2012 test | 时间 | |
| R-CNN [12] | 47.9 | - | - |
| SDS [16] | 52.6 | 51.6 | 50 s |
| FCN-8s | 62.7 | 62.2 | 175 ms |
表 3:我们的全卷积网在 PASCAL VOC 2011 与 2012 测试集上相对当时最优有 20% 相对提升,并缩短推理时间。
NYUDv2 [30] is an RGB-D dataset collected using the Microsoft Kinect. It has 1449 RGB-D images, with pixelwise labels that have been coalesced into a 40 class semantic segmentation task by Gupta et al. [13]. We report results on the standard split of 795 training images and 654 testing images. (Note: all model selection is performed on PASCAL 2011 val.) Table 4 gives the performance of our model in several variations. First we train our unmodified coarse model (FCN-32s) on RGB images. To add depth information, we train on a model upgraded to take four-channel RGB-D input (early fusion). This provides little benefit, perhaps due to the difficultly of propagating meaningful gradients all the way through the model. Following the success of Gupta et al. [14], we try the three-dimensional HHA encoding of depth, training nets on just this information, as well as a “late fusion” of RGB and HHA where the predictions from both nets are summed at the final layer, and the resulting two-stream net is learned end-to-end. Finally we upgrade this late fusion net to a 16-stride version.
NYUDv2 [30] 是用 Microsoft Kinect 采集的 RGB-D 数据集,含 1449 幅 RGB-D 图像;Gupta et al. [13] 把像素标签合并为 40 类语义分割任务。我们在标准划分(795 训练、654 测试)上报告结果。(注意:全部模型选择在 PASCAL 2011 val 上进行。)表 4 给出若干变体的表现。先在 RGB 上训练未改动的粗糙模型(FCN-32s)。为加入深度,训练接受四通道 RGB-D 输入的模型(早期融合);收益很小,可能因有意义的梯度难以一路回传到模型深处。沿 Gupta et al. [14] 的成功,我们尝试深度的三维 HHA 编码:只在该信息上训练,以及 RGB 与 HHA 的「晚期融合」——两网预测在最终层相加,得到的双流网端到端学习。最后把该晚期融合网升级为 16 步长版本。
SIFT Flow is a dataset of 2,688 images with pixel labels for 33 semantic categories (“bridge”, “mountain”, “sun”), as well as three geometric categories (“horizontal”, “vertical”, and “sky”). An FCN can naturally learn a joint representation that simultaneously predicts both types of labels. We learn a two-headed version of FCN-16s with semantic and geometric prediction layers and losses. The learned model performs as well on both tasks as two independently trained models, while learning and inference are essentially as fast as each independent model by itself. The results in Table 5, computed on the standard split into 2,488 training and 200 test images,[^10] show state-of-the-art performance on both tasks.
SIFT Flow 含 2,688 幅图像,像素标签包括 33 个语义类(「桥」「山」「太阳」)以及三个几何类(「水平」「竖直」「天空」)。FCN 可自然学习同时预测两类标签的联合表征。我们学习带语义与几何预测层及损失的双头 FCN-16s。学到的模型在两项任务上的表现不亚于两个独立训练的模型,而学习与推理速度几乎与单个独立模型相当。表 5 在标准划分(2,488 训练、200 测试)[^10] 上的结果显示两项任务均为当时最优。
| pixel acc. | mean acc. | mean IU | f.w. IU | |
|---|---|---|---|---|
| Gupta et al. [14] | 60.3 | - | 28.6 | 47.0 |
| FCN-32s RGB | 60.0 | 42.2 | 29.2 | 43.9 |
| FCN-32s RGBD | 61.5 | 42.4 | 30.5 | 45.5 |
| FCN-32s HHA | 57.1 | 35.2 | 24.2 | 40.4 |
| FCN-32s RGB-HHA | 64.3 | 44.9 | 32.8 | 48.0 |
| FCN-16s RGB-HHA | 65.4 | 46.1 | 34.0 | 49.5 |
Table 4: Results on NYUDv2. RGBD is early-fusion of the RGB and depth channels at the input. HHA is the depth embedding of [14] as horizontal disparity, height above ground, and the angle of the local surface normal with the inferred gravity direction. RGB-HHA is the jointly trained late fusion model that sums RGB and HHA predictions.
| pixel acc. | mean acc. | mean IU | f.w. IU | |
|---|---|---|---|---|
| Gupta et al. [14] | 60.3 | - | 28.6 | 47.0 |
| FCN-32s RGB | 60.0 | 42.2 | 29.2 | 43.9 |
| FCN-32s RGBD | 61.5 | 42.4 | 30.5 | 45.5 |
| FCN-32s HHA | 57.1 | 35.2 | 24.2 | 40.4 |
| FCN-32s RGB-HHA | 64.3 | 44.9 | 32.8 | 48.0 |
| FCN-16s RGB-HHA | 65.4 | 46.1 | 34.0 | 49.5 |
表 4:NYUDv2 结果。RGBD 为在输入处对 RGB 与深度通道的早期融合。HHA 为 [14] 的深度嵌入:水平视差、离地高度,以及局部表面法向与推断重力方向的夹角。RGB-HHA 为联合训练的晚期融合模型,把 RGB 与 HHA 预测相加。
| pixel acc. | mean acc. | mean IU | f.w. IU | geom. acc. | |
|---|---|---|---|---|---|
| Liu et al. [23] | 76.7 | - | - | - | - |
| Tighe et al. [33] | - | - | - | - | 90.8 |
| Tighe et al. [34] 1 | 75.6 | 41.1 | - | - | - |
| Tighe et al. [34] 2 | 78.6 | 39.2 | - | - | - |
| Farabet et al. [8] 1 | 72.3 | 50.8 | - | - | - |
| Farabet et al. [8] 2 | 78.5 | 29.6 | - | - | - |
| Pinheiro et al. [28] | 77.7 | 29.8 | - | - | - |
| FCN-16s | 85.2 | 51.7 | 39.5 | 76.1 | 94.3 |
Table 5: Results on SIFT Flow[^10] with class segmentation (center) and geometric segmentation (right). Tighe [33] is a non-parametric transfer method. Tighe 1 is an exemplar SVM while 2 is SVM + MRF. Farabet is a multi-scale convnet trained on class-balanced samples (1) or natural frequency samples (2). Pinheiro is a multi-scale, recurrent convnet, denoted rCNN3 . The metric for geometry is pixel accuracy.
| pixel acc. | mean acc. | mean IU | f.w. IU | geom. acc. | |
|---|---|---|---|---|---|
| Liu et al. [23] | 76.7 | - | - | - | - |
| Tighe et al. [33] | - | - | - | - | 90.8 |
| Tighe et al. [34] 1 | 75.6 | 41.1 | - | - | - |
| Tighe et al. [34] 2 | 78.6 | 39.2 | - | - | - |
| Farabet et al. [8] 1 | 72.3 | 50.8 | - | - | - |
| Farabet et al. [8] 2 | 78.5 | 29.6 | - | - | - |
| Pinheiro et al. [28] | 77.7 | 29.8 | - | - | - |
| FCN-16s | 85.2 | 51.7 | 39.5 | 76.1 | 94.3 |
表 5:SIFT Flow[^10] 上的类别分割(中)与几何分割(右)结果。Tighe [33] 为非参数迁移方法。Tighe 1 为 exemplar SVM,2 为 SVM + MRF。Farabet 为在类别平衡样本(1)或自然频率样本(2)上训练的多尺度卷积网。Pinheiro 为多尺度循环卷积网,记为 rCNN3 。几何任务指标为像素精度。
| FCN-8s | SDS [16] | Ground Truth | Image |
|---|---|---|---|
Figure 6: Fully convolutional segmentation nets produce state-of-the-art performance on PASCAL. The left column shows the output of our highest performing net, FCN-8s. The second shows the segmentations produced by the previous state-of-the-art system by Hariharan et al. [16]. Notice the fine structures recovered (first row), ability to separate closely interacting objects (second row), and robustness to occluders (third row). The fourth row shows a failure case: the net sees lifejackets in a boat as people.
| FCN-8s | SDS [16] | 真值 | 图像 |
|---|---|---|---|
图 6:全卷积分割网在 PASCAL 上达到当时最优。左列为我们表现最好的网络 FCN-8s 的输出;第二列为 Hariharan et al. [16] 先前最优系统的分割。注意恢复的细结构(第一行)、分离紧邻物体的能力(第二行),以及对遮挡的稳健性(第三行)。第四行为失败例:网络把船上的救生衣看成了人。
6 Conclusion
6 结论
Fully convolutional networks are a rich class of models, of which modern classification convnets are a special case. Recognizing this, extending these classification nets to segmentation, and improving the architecture with multi-resolution layer combinations dramatically improves the state-of-the-art, while simultaneously simplifying and speeding up learning and inference.
全卷积网络是一类丰富的模型,当代分类卷积网是其特例。认识到这一点,把这些分类网扩展到分割,并用多分辨率层组合改进结构,显著提升了当时最优水平,同时简化并加速了学习与推理。
Acknowledgements This work was supported in part by DARPA’s MSEE and SMISC programs, NSF awards IIS-1427425, IIS-1212798, IIS-1116411, and the NSF GRFP, Toyota, and the Berkeley Vision and Learning Center. We gratefully acknowledge NVIDIA for GPU donation. We thank Bharath Hariharan and Saurabh Gupta for their advice and dataset tools. We thank Sergio Guadarrama for reproducing GoogLeNet in Caffe. We thank Jitendra Malik for his helpful comments. Thanks to Wei Liu for pointing out an issue wth our SIFT Flow mean IU computation and an error in our frequency weighted mean IU formula.
致谢 本工作部分得到 DARPA 的 MSEE 与 SMISC 项目、NSF 资助 IIS-1427425、IIS-1212798、IIS-1116411 以及 NSF GRFP、丰田,与 Berkeley Vision and Learning Center 的支持。感谢 NVIDIA 捐赠 GPU。感谢 Bharath Hariharan 与 Saurabh Gupta 的建议与数据集工具。感谢 Sergio Guadarrama 在 Caffe 中复现 GoogLeNet。感谢 Jitendra Malik 的有益评论。感谢 Wei Liu 指出我们 SIFT Flow mean IU 计算中的问题,以及频率加权 mean IU 公式中的错误。
Appendix A Upper Bounds on IU
附录 A IU 上界
In this paper, we have achieved good performance on the mean IU segmentation metric even with coarse semantic prediction. To better understand this metric and the limits of this approach with respect to it, we compute approximate upper bounds on performance with prediction at various scales. We do this by downsampling ground truth images and then upsampling them again to simulate the best results obtainable with a particular downsampling factor. The following table gives the mean IU on a subset of PASCAL 2011 val for various downsampling factors.
本文即便在粗糙语义预测下,也在 mean IU 分割指标上取得了不错表现。为更好理解该指标以及本方法相对它的极限,我们计算不同尺度预测下表现的近似上界:先下采样真值图像再上采样回来,以模拟给定下采样因子下可达到的最佳结果。下表给出 PASCAL 2011 val 子集上各下采样因子的 mean IU。
Pixel-perfect prediction is clearly not necessary to achieve mean IU well above state-of-the-art, and, conversely, mean IU is a not a good measure of fine-scale accuracy.
像素完美的预测显然不是把 mean IU 推到远超当时最优所必需的;反过来,mean IU 也不是衡量细尺度精度的好指标。
Appendix B More Results
附录 B 更多结果
We further evaluate our FCN for semantic segmentation.
我们进一步评估 FCN 的语义分割。
PASCAL-Context [26] provides whole scene annotations of PASCAL VOC 2010. While there are over 400 distinct classes, we follow the 59 class task defined by [26] that picks the most frequent classes. We train and evaluate on the training and val sets respectively. In Table 6, we compare to the joint object + stuff variation of Convolutional Feature Masking [3] which is the previous state-of-the-art on this task. FCN-8s scores 35.1 mean IU for an 11% relative improvement.
PASCAL-Context [26] 为 PASCAL VOC 2010 提供整景标注。虽有逾 400 个不同类,我们遵循 [26] 定义的 59 类任务(取最频繁类)。分别在训练集与验证集上训练与评估。表 6 与该任务先前最优——Convolutional Feature Masking [3] 的联合物体+stuff 变体——对比。FCN-8s 得到 35.1 mean IU,相对提升 11%。
| 59 class | pixel acc. | mean acc. | mean IU | f.w. IU |
|---|---|---|---|---|
| O2P | - | - | 18.1 | - |
| CFM | - | - | 31.5 | - |
| FCN-32s | 63.8 | 42.7 | 31.8 | 48.3 |
| FCN-16s | 65.7 | 46.2 | 34.8 | 50.7 |
| FCN-8s | 65.9 | 46.5 | 35.1 | 51.0 |
| 33 class | ||||
| O2P | - | - | 29.2 | - |
| CFM | - | - | 46.1 | - |
| FCN-32s | 69.8 | 65.1 | 50.4 | 54.9 |
| FCN-16s | 71.8 | 68.0 | 53.4 | 57.5 |
| FCN-8s | 71.8 | 67.6 | 53.5 | 57.7 |
Table 6: Results on PASCAL-Context. CFM is the best result of [3] by convolutional feature masking and segment pursuit with the VGG net. O2P is the second order pooling method [1] as reported in the errata of [26]. The 59 class task includes the 59 most frequent classes while the 33 class task consists of an easier subset identified by [26].
| 59 class | pixel acc. | mean acc. | mean IU | f.w. IU |
|---|---|---|---|---|
| O2P | - | - | 18.1 | - |
| CFM | - | - | 31.5 | - |
| FCN-32s | 63.8 | 42.7 | 31.8 | 48.3 |
| FCN-16s | 65.7 | 46.2 | 34.8 | 50.7 |
| FCN-8s | 65.9 | 46.5 | 35.1 | 51.0 |
| 33 class | ||||
| O2P | - | - | 29.2 | - |
| CFM | - | - | 46.1 | - |
| FCN-32s | 69.8 | 65.1 | 50.4 | 54.9 |
| FCN-16s | 71.8 | 68.0 | 53.4 | 57.5 |
| FCN-8s | 71.8 | 67.6 | 53.5 | 57.7 |
表 6:PASCAL-Context 结果。CFM 为 [3] 用卷积特征掩码与片段追逐、配合 VGG 网的最佳结果。O2P 为二阶池化方法 [1],取自 [26] 的勘误。59 类任务含最频繁的 59 类;33 类任务为 [26] 给出的较易子集。
Changelog
变更记录
The arXiv version of this paper is kept up-to-date with corrections and additional relevant material. The following gives a brief history of changes.
本文 arXiv 版本会持续更新勘误与相关补充材料。以下简要记录变更历史。
v2 Add Appendix A giving upper bounds on mean IU and Appendix B with PASCAL-Context results. Correct PASCAL validation numbers (previously, some val images were included in train), SIFT Flow mean IU (which used an inappropriately strict metric), and an error in the frequency weighted mean IU formula. Add link to models and update timing numbers to reflect improved implementation (which is publicly available).
v2 新增附录 A(mean IU 上界)与附录 B(PASCAL-Context 结果)。更正 PASCAL 验证数字(此前部分 val 图像被计入 train)、SIFT Flow mean IU(先前用了过严的度量),以及频率加权 mean IU 公式中的错误。加入模型链接,并更新计时数字以反映改进后的实现(已公开)。
References
参考文献
[1] J. Carreira, R. Caseiro, J. Batista, and C. Sminchisescu. Semantic segmentation with second-order pooling. In ECCV , 2012.
[2] D. C. Ciresan, A. Giusti, L. M. Gambardella, and J. Schmidhuber. Deep neural networks segment neuronal membranes in electron microscopy images. In NIPS , pages 2852–2860, 2012.
[3] J. Dai, K. He, and J. Sun. Convolutional feature masking for joint object and stuff segmentation. arXiv preprint arXiv:1412.1283 , 2014.
[4] J. Donahue, Y. Jia, O. Vinyals, J. Hoffman, N. Zhang, E. Tzeng, and T. Darrell. DeCAF: A deep convolutional activation feature for generic visual recognition. In ICML , 2014.
[5] D. Eigen, D. Krishnan, and R. Fergus. Restoring an image taken through a window covered with dirt or rain. In Computer Vision (ICCV), 2013 IEEE International Conference on , pages 633–640. IEEE, 2013.
[6] D. Eigen, C. Puhrsch, and R. Fergus. Depth map prediction from a single image using a multi-scale deep network. arXiv preprint arXiv:1406.2283 , 2014.
[7] M. Everingham, L. Van Gool, C. K. I. Williams, J. Winn, and A. Zisserman. The PASCAL Visual Object Classes Challenge 2011 (VOC2011) Results. http://www.pascal-network.org/challenges/VOC/voc2011/workshop/index.html.
[8] C. Farabet, C. Couprie, L. Najman, and Y. LeCun. Learning hierarchical features for scene labeling. Pattern Analysis and Machine Intelligence, IEEE Transactions on , 2013.
[9] P. Fischer, A. Dosovitskiy, and T. Brox. Descriptor matching with convolutional neural networks: a comparison to SIFT. CoRR , abs/1405.5769, 2014.
[10] L. Florack, B. T. H. Romeny, M. Viergever, and J. Koenderink. The gaussian scale-space paradigm and the multiscale local jet. International Journal of Computer Vision , 18(1):61–75, 1996.
[11] Y. Ganin and V. Lempitsky. N 4 -fields: Neural network nearest neighbor fields for image transforms. In ACCV , 2014.
[12] R. Girshick, J. Donahue, T. Darrell, and J. Malik. Rich feature hierarchies for accurate object detection and semantic segmentation. In Computer Vision and Pattern Recognition , 2014.
[13] S. Gupta, P. Arbelaez, and J. Malik. Perceptual organization and recognition of indoor scenes from RGB-D images. In CVPR , 2013.
[14] S. Gupta, R. Girshick, P. Arbelaez, and J. Malik. Learning rich features from RGB-D images for object detection and segmentation. In ECCV . Springer, 2014.
[15] B. Hariharan, P. Arbelaez, L. Bourdev, S. Maji, and J. Malik. Semantic contours from inverse detectors. In International Conference on Computer Vision (ICCV) , 2011.
[16] B. Hariharan, P. Arbeláez, R. Girshick, and J. Malik. Simultaneous detection and segmentation. In European Conference on Computer Vision (ECCV) , 2014.
[17] K. He, X. Zhang, S. Ren, and J. Sun. Spatial pyramid pooling in deep convolutional networks for visual recognition. In ECCV , 2014.
[18] Y. Jia, E. Shelhamer, J. Donahue, S. Karayev, J. Long, R. Girshick, S. Guadarrama, and T. Darrell. Caffe: Convolutional architecture for fast feature embedding. arXiv preprint arXiv:1408.5093 , 2014.
[19] A. Krizhevsky, I. Sutskever, and G. E. Hinton. Imagenet classification with deep convolutional neural networks. In NIPS , 2012.
[20] Q. V. Le, R. Monga, M. Devin, K. Chen, G. S. Corrado, J. Dean, and A. Y. Ng. Building high-level features using large scale unsupervised learning. In ICML , 2012.
[21] Y. LeCun, B. Boser, J. Denker, D. Henderson, R. E. Howard, W. Hubbard, and L. D. Jackel. Backpropagation applied to hand-written zip code recognition. In Neural Computation , 1989.
[22] Y. A. LeCun, L. Bottou, G. B. Orr, and K.-R. Müller. Efficient backprop. In Neural networks: Tricks of the trade , pages 9–48. Springer, 1998.
[23] C. Liu, J. Yuen, and A. Torralba. Sift flow: Dense correspondence across scenes and its applications. Pattern Analysis and Machine Intelligence, IEEE Transactions on , 33(5):978–994, 2011.
[24] J. Long, N. Zhang, and T. Darrell. Do convnets learn correspondence? In NIPS , 2014.
[25] O. Matan, C. J. Burges, Y. LeCun, and J. S. Denker. Multi-digit recognition using a space displacement neural network. In NIPS , pages 488–495. Citeseer, 1991.
[26] R. Mottaghi, X. Chen, X. Liu, N.-G. Cho, S.-W. Lee, S. Fidler, R. Urtasun, and A. Yuille. The role of context for object detection and semantic segmentation in the wild. In Computer Vision and Pattern Recognition (CVPR), 2014 IEEE Conference on , pages 891–898. IEEE, 2014.
[27] F. Ning, D. Delhomme, Y. LeCun, F. Piano, L. Bottou, and P. E. Barbano. Toward automatic phenotyping of developing embryos from videos. Image Processing, IEEE Transactions on , 14(9):1360–1371, 2005.
[28] P. H. Pinheiro and R. Collobert. Recurrent convolutional neural networks for scene labeling. In ICML , 2014.
[29] P. Sermanet, D. Eigen, X. Zhang, M. Mathieu, R. Fergus, and Y. LeCun. Overfeat: Integrated recognition, localization and detection using convolutional networks. In ICLR , 2014.
[30] N. Silberman, D. Hoiem, P. Kohli, and R. Fergus. Indoor segmentation and support inference from rgbd images. In ECCV , 2012.
[31] K. Simonyan and A. Zisserman. Very deep convolutional networks for large-scale image recognition. CoRR , abs/1409.1556, 2014.
[32] C. Szegedy, W. Liu, Y. Jia, P. Sermanet, S. Reed, D. Anguelov, D. Erhan, V. Vanhoucke, and A. Rabinovich. Going deeper with convolutions. CoRR , abs/1409.4842, 2014.
[33] J. Tighe and S. Lazebnik. Superparsing: scalable nonparametric image parsing with superpixels. In ECCV , pages 352–365. Springer, 2010.
[34] J. Tighe and S. Lazebnik. Finding things: Image parsing with regions and per-exemplar detectors. In CVPR , 2013.
[35] J. Tompson, A. Jain, Y. LeCun, and C. Bregler. Joint training of a convolutional network and a graphical model for human pose estimation. CoRR , abs/1406.2984, 2014.
[36] L. Wan, M. Zeiler, S. Zhang, Y. L. Cun, and R. Fergus. Regularization of neural networks using dropconnect. In Proceedings of the 30th International Conference on Machine Learning (ICML-13) , pages 1058–1066, 2013.
[37] R. Wolf and J. C. Platt. Postal address block location using a convolutional locator network. Advances in Neural Information Processing Systems , pages 745–745, 1994.
[38] M. D. Zeiler and R. Fergus. Visualizing and understanding convolutional networks. In Computer Vision–ECCV 2014 , pages 818–833. Springer, 2014.
[39] N. Zhang, J. Donahue, R. Girshick, and T. Darrell. Part-based r-cnns for fine-grained category detection. In Computer Vision–ECCV 2014 , pages 834–849. Springer, 2014.