Faster R-CNN: Towards Real-Time Object Detection with Region Proposal Networks
Faster R-CNN: Towards Real-Time Object Detection with Region Proposal Networks
Faster R-CNN:面向实时目标检测的区域提议网络(Faster R-CNN: Towards Real-Time Object Detection with Region Proposal Networks)
Shaoqing Ren Kaiming He Ross Girshick and Jian Sun Thanks: S. Ren is with University of Science and Technology of China, Hefei, China. This work was done when S. Ren was an intern at Microsoft Research. Email: sqren@mail.ustc.edu.cn K.˜He and J.˜Sun are with Visual Computing Group, Microsoft Research. E-mail: {kahe,jiansun}@microsoft.com R.˜Girshick is with Facebook AI Research. The majority of this work was done when R. Girshick was with Microsoft Research. E-mail: rbg@fb.com
任少卿 何恺明 Ross Girshick 孙剑
致谢:任少卿就职于中国科学技术大学(合肥);本工作完成于其在微软研究院实习期间。邮箱:sqren@mail.ustc.edu.cn。何恺明与孙剑就职于微软研究院视觉计算组,邮箱:{kahe,jiansun}@microsoft.com。Ross Girshick 就职于 Facebook AI Research;本工作大部分完成于其在微软研究院期间。邮箱:rbg@fb.com
Abstract
摘要
State-of-the-art object detection networks depend on region proposal algorithms to hypothesize object locations. Advances like SPPnet [1] and Fast R-CNN [2] have reduced the running time of these detection networks, exposing region proposal computation as a bottleneck. In this work, we introduce a Region Proposal Network (RPN) that shares full-image convolutional features with the detection network, thus enabling nearly cost-free region proposals. An RPN is a fully convolutional network that simultaneously predicts object bounds and objectness scores at each position. The RPN is trained end-to-end to generate high-quality region proposals, which are used by Fast R-CNN for detection. We further merge RPN and Fast R-CNN into a single network by sharing their convolutional features—using the recently popular terminology of neural networks with “attention” mechanisms, the RPN component tells the unified network where to look. For the very deep VGG-16 model [3], our detection system has a frame rate of 5fps (including all steps) on a GPU, while achieving state-of-the-art object detection accuracy on PASCAL VOC 2007, 2012, and MS COCO datasets with only 300 proposals per image. In ILSVRC and COCO 2015 competitions, Faster R-CNN and RPN are the foundations of the 1st-place winning entries in several tracks. Code has been made publicly available.
当时最先进的目标检测网络依赖区域提议算法来假设物体位置。SPPnet [1] 与 Fast R-CNN [2] 等进展缩短了检测网络本身的运行时间,使区域提议计算成为瓶颈。本文引入与检测网络共享整图卷积特征的区域提议网络(RPN),从而使区域提议几乎零成本。RPN 是全卷积网络,在每个位置同时预测物体边界与 objectness 分数;端到端训练后生成高质量提议,供 Fast R-CNN 做检测。我们进一步通过共享卷积特征,把 RPN 与 Fast R-CNN 合并为单一网络——借用神经网络“注意力”机制的说法,RPN 告诉统一网络该看哪里。对非常深的 VGG-16 模型 [3],本检测系统在 GPU 上达到 5 fps(含全部步骤),并在 PASCAL VOC 2007、2012 与 MS COCO 上仅用每图 300 个提议即取得当时领先的检测精度。在 ILSVRC 与 COCO 2015 竞赛中,Faster R-CNN 与 RPN 是若干检测、定位、分割赛道第一名条目的基础。代码已公开。
I Introduction
I 引言
Index Terms:
Recent advances in object detection are driven by the success of region proposal methods (e.g., [4]) and region-based convolutional neural networks (R-CNNs) [5]. Although region-based CNNs were computationally expensive as originally developed in [5], their cost has been drastically reduced thanks to sharing convolutions across proposals [1, 2]. The latest incarnation, Fast R-CNN [2], achieves near real-time rates using very deep networks [3], when ignoring the time spent on region proposals. Now, proposals are the test-time computational bottleneck in state-of-the-art detection systems.
- 索引术语:
最近在物体检测方面的进步是由区域提议方法(,,[4])和基于区域的卷积神经网络(R-CNNs)[5]的成功推动的. 尽管以区域为基础的CNN在计算上像[5]年最初开发的那样昂贵,但由于在提案[1,2]之间共享,其成本已经大幅降低. 最新化身Fast R-CNN[2],使用非常深的网络实现近实时速率[3],忽略了在区域提议上花费的时间. 现在,建议是测试时间计算在最先进的检测系统中的瓶颈.
Region proposal methods typically rely on inexpensive features and economical inference schemes. Selective Search [4], one of the most popular methods, greedily merges superpixels based on engineered low-level features. Yet when compared to efficient detection networks [2], Selective Search is an order of magnitude slower, at 2 seconds per image in a CPU implementation. EdgeBoxes [6] currently provides the best tradeoff between proposal quality and speed, at 0.2 seconds per image. Nevertheless, the region proposal step still consumes as much running time as the detection network.
区域提议方法通常依赖廉价的特征和经济的推理方案。 选择性搜索[4],最流行的方法之一,贪婪地将基于工程低级特性的超像素融合在一起. 然而,与高效的检测网络相比[2],选择性搜索是一个较慢的量级顺序,在CPU执行中每个图像2秒. EdgeBoxes [6] 目前为提案质量和速度提供了最佳的权衡,每个图像0.2秒. 尽管如此,区域提议步骤仍与检测网络一样耗时。
One may note that fast region-based CNNs take advantage of GPUs, while the region proposal methods used in research are implemented on the CPU, making such runtime comparisons inequitable. An obvious way to accelerate proposal computation is to re-implement it for the GPU. This may be an effective engineering solution, but re-implementation ignores the down-stream detection network and therefore misses important opportunities for sharing computation.
人们可能注意到,快速的区域CNN利用了GPU,而用于研究的区域提议方法则在CPU上实施,使得这种运行时间比较不公平. 加快提案计算的一个明显方法是重新实施GPU. 这可能是有效的工程解决方案,但重新实施忽略了下游检测网络,因此错过了共享计算的重要机会.
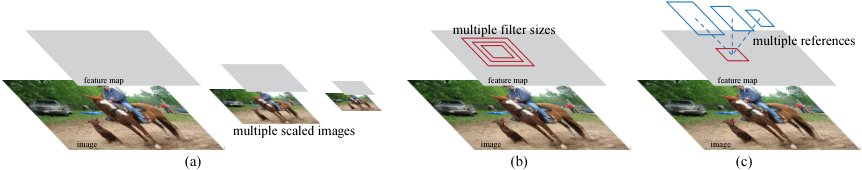
Fig. 1: Different schemes for addressing multiple scales and sizes. (a) Pyramids of images and feature maps are built, and the classifier is run at all scales. (b) Pyramids of filters with multiple scales/sizes are run on the feature map. (c) We use pyramids of reference boxes in the regression functions.
费格。 1: 处理多种规模和规模的不同方案。 (a) 构筑图像和专题地图的金字塔,分类器在所有尺度上运行。 (b) 特性图上运行有多个大小的滤波器的金字塔。 (c) 我们在回归函数中使用了参考框的金字塔.
In this paper, we show that an algorithmic change—computing proposals with a deep convolutional neural network—leads to an elegant and effective solution where proposal computation is nearly cost-free given the detection network’s computation. To this end, we introduce novel Region Proposal Networks (RPNs) that share convolutional layers with state-of-the-art object detection networks [1, 2]. By sharing convolutions at test-time, the marginal cost for computing proposals is small (e.g., 10ms per image).
在本文中,我们表明,一种算法变化——用深刻的神经网络来计算建议——导致了一种优雅而有效的解决方案,根据检测网络的计算,建议计算几乎是免费的。 为此,我们引入了小说"Region Proposition Networks*(RPNs)",与最先进的物体检测网络共享进化层[1,2]. 通过在测试时分享演化,计算建议时的边际成本是很小的(如**,每个图像10ms).
Our observation is that the convolutional feature maps used by region-based detectors, like Fast R-CNN, can also be used for generating region proposals. On top of these convolutional features, we construct an RPN by adding a few additional convolutional layers that simultaneously regress region bounds and objectness scores at each location on a regular grid. The RPN is thus a kind of fully convolutional network (FCN) [7] and can be trained end-to-end specifically for the task for generating detection proposals.
我们的观察是,以区域为基础的探测器所使用的卷积特征图,如Fast R-CNN,也可以用来产生区域提议. 在这些卷积特征之外,我们通过增加几个额外的卷积层来构建RPN,这些层同时在正常网格上的每个位置递减区域界限和对象分数. 因此,RPN是一种完全革命性的网络[7],可以专门为生成检测建议的任务而接受端到端的培训.
RPNs are designed to efficiently predict region proposals with a wide range of scales and aspect ratios. In contrast to prevalent methods [8, 9, 1, 2] that use pyramids of images (Figure 1, a) or pyramids of filters (Figure 1, b), we introduce novel “anchor” boxes that serve as references at multiple scales and aspect ratios. Our scheme can be thought of as a pyramid of regression references (Figure 1, c), which avoids enumerating images or filters of multiple scales or aspect ratios. This model performs well when trained and tested using single-scale images and thus benefits running speed.
区域规划网旨在高效预测各种尺度和方面比率的区域提议。 与使用图像金字塔(图1,a)或过滤器金字塔(图1,b)的常用方法[8,9,1,2]形成对照的是,我们引入了新颖的“锁定”框,作为多个尺度和方方面面比率的参考。 我们的方案可以被认为是一个回归参照金字塔(图1,c),它避免列举多个尺度或侧面比的图像或过滤器. 这个模型在使用单比例图像进行训练和测试时表现良好,从而有利于运行速度。
To unify RPNs with Fast R-CNN [2] object detection networks, we propose a training scheme that alternates between fine-tuning for the region proposal task and then fine-tuning for object detection, while keeping the proposals fixed. This scheme converges quickly and produces a unified network with convolutional features that are shared between both tasks.[^1]
为了将RPN与快速R-CNN[2]对象检测网络统一起来,我们提出一个培训计划,在对区域提议任务进行微调和然后对对象检测进行微调之间取而代之,同时使提案保持固定. 这个方案很快地汇合起来,并产生了一个具有两个任务共享的卷积特征的统一网络。 [^1]
We comprehensively evaluate our method on the PASCAL VOC detection benchmarks [11] where RPNs with Fast R-CNNs produce detection accuracy better than the strong baseline of Selective Search with Fast R-CNNs. Meanwhile, our method waives nearly all computational burdens of Selective Search at test-time—the effective running time for proposals is just 10 milliseconds. Using the expensive very deep models of [3], our detection method still has a frame rate of 5fps (including all steps) on a GPU, and thus is a practical object detection system in terms of both speed and accuracy. We also report results on the MS COCO dataset [12] and investigate the improvements on PASCAL VOC using the COCO data. Code has been made publicly available at https://github.com/shaoqingren/faster_rcnn (in MATLAB) and https://github.com/rbgirshick/py-faster-rcnn (in Python).
我们全面评价我们在PASCAL VOC检测基准上的方法[11],其中具有快速R-CNN的RPN的检测精度比带有快速R-CNN的选择性搜索的强基线更好。 与此同时,我们的方法免除了测试时选择搜索的几乎所有计算负担——提案的有效运行时间只有10毫秒。 使用[3]的昂贵非常深的模型,我们的检测方法在GPU上仍然有5fps(包括所有步骤)的帧速率,因此在速度和准确性上都是实用的对象检测系统. 我们还报告MS COCO数据集的结果[12],并利用COCO数据调查PASCAL VOC的改进情况。 已在https://github.com/shaoqingren/faster rcnn(MATLAB)和https://github.com/rbgirshick/py-faster-rcnn(Python)上公布代码。
A preliminary version of this manuscript was published previously [10]. Since then, the frameworks of RPN and Faster R-CNN have been adopted and generalized to other methods, such as 3D object detection [13], part-based detection [14], instance segmentation [15], and image captioning [16]. Our fast and effective object detection system has also been built in commercial systems such as at Pinterests [17], with user engagement improvements reported.
这份手稿的初步版本之前已经出版[10]. 此后,RPN和S更快R-CNN的框架被采用并被推广到其他方法,如3D对象检测[13],部分基检测[14],实例分割[15],图像字幕[16]. 我们的快速有效的物体检测系统也在Pinterests[17]等商业系统中建立,并报告了用户参与方面的改进。
In ILSVRC and COCO 2015 competitions, Faster R-CNN and RPN are the basis of several 1st-place entries [18] in the tracks of ImageNet detection, ImageNet localization, COCO detection, and COCO segmentation. RPNs completely learn to propose regions from data, and thus can easily benefit from deeper and more expressive features (such as the 101-layer residual nets adopted in [18]). Faster R-CNN and RPN are also used by several other leading entries in these competitions[^2]. These results suggest that our method is not only a cost-efficient solution for practical usage, but also an effective way of improving object detection accuracy.
在ILSVRC和COCO 2015比赛中,更快的R-CNN和RPN是ImageNet检测,ImageNet本地化,COCO检测和COCO分区化的轨道中数个第1位条目[18]的基础. 区域网络完全学习从数据中建议区域,因此可以很容易地从更深和更具表现性的特点(例如[18]采用的101层残网)中受益。 更快的R-CNN和RPN也被用于这些比赛中的其他几个领先条目[^2]. 这些结果表明,我们的方法不仅是实际使用的成本-效益高的解决办法,也是提高物体检测准确性的有效方法。
II Related Work
II 相关工作
Object Proposals. There is a large literature on object proposal methods. Comprehensive surveys and comparisons of object proposal methods can be found in [19, 20, 21]. Widely used object proposal methods include those based on grouping super-pixels (e.g., Selective Search [4], CPMC [22], MCG [23]) and those based on sliding windows (e.g., objectness in windows [24], EdgeBoxes [6]). Object proposal methods were adopted as external modules independent of the detectors (e.g., Selective Search [4] object detectors, R-CNN [5], and Fast R-CNN [2]).
** 反对提案。 ** 有关物体建议方法的文献很多。 在[19、20、21]中可找到对物体建议方法的全面调查和比较。 广泛使用的对象建议方法包括基于组合超像素(,,选择性搜索[4],CPMC [22],MCG [23])和基于滑动窗口(,,窗口中的对象性[24],边框[6])的方法. 采用物体建议方法作为独立于探测器的外部模块(如,选择性搜索[4]物体检测器,R-CNN[5],以及Fast R-CNN[2]).
Deep Networks for Object Detection. The R-CNN method [5] trains CNNs end-to-end to classify the proposal regions into object categories or background. R-CNN mainly plays as a classifier, and it does not predict object bounds (except for refining by bounding box regression). Its accuracy depends on the performance of the region proposal module (see comparisons in [20]). Several papers have proposed ways of using deep networks for predicting object bounding boxes [25, 9, 26, 27]. In the OverFeat method [9], a fully-connected layer is trained to predict the box coordinates for the localization task that assumes a single object. The fully-connected layer is then turned into a convolutional layer for detecting multiple class-specific objects. The MultiBox methods [26, 27] generate region proposals from a network whose last fully-connected layer simultaneously predicts multiple class-agnostic boxes, generalizing the “single-box” fashion of OverFeat. These class-agnostic boxes are used as proposals for R-CNN [5]. The MultiBox proposal network is applied on a single image crop or multiple large image crops (e.g., 224224), in contrast to our fully convolutional scheme. MultiBox does not share features between the proposal and detection networks. We discuss OverFeat and MultiBox in more depth later in context with our method. Concurrent with our work, the DeepMask method [28] is developed for learning segmentation proposals.
** 深入的物体检测网络。 ** R-CNN方法[5]对CNN进行端对端训练,将建议区域分类为对象类别或背景. R-CNN主要作为分类器演奏,它不预测对象界限(除了通过边框回归进行精炼). 其准确性取决于区域提议单元的绩效(见[20]中的比较)。 一些文件提出了利用深层网络预测物体边框的方法[25、9、26、27]。 在OverFeat方法[9]中,一个完全连接的层被训练出来,以预测为假设单个对象的本地化任务的框坐标. 完全连接的地层随后变成一个卷积层,用于探测多个类特有物体. MultiBox方法[26,27]从一个网络生成区域提议,其最后一个完全连接的层同时预测多个类不可知框,概括了OverFeat的"单盒"时尚. 这些类不可知箱被用作R-CNN的建议[5]. 多Box建议网络被应用在一个单一的图像作物或多个大型图像作物上(如*,224224),与我们完全的革命计划形成对比. MultiBox在建议和检测网络之间并不共享特征. 我们稍后将结合我们的方法更深入地讨论OverFeat和MultiBox。 与我们的工作同时,DeepMask方法[28]是为学习分门别类的建议而开发的.
Shared computation of convolutions [9, 1, 29, 7, 2] has been attracting increasing attention for efficient, yet accurate, visual recognition. The OverFeat paper [9] computes convolutional features from an image pyramid for classification, localization, and detection. Adaptively-sized pooling (SPP) [1] on shared convolutional feature maps is developed for efficient region-based object detection [1, 30] and semantic segmentation [29]. Fast R-CNN [2] enables end-to-end detector training on shared convolutional features and shows compelling accuracy and speed.
共同计算演化[9, 1, 29, 7, 2]越来越引起人们的注意,以便有效但准确的视觉识别. OverFeat纸[9]从图像金字塔中计算出进化特征,用于分类,本地化,检测. 用于高效的区域对象检测[1,30]和语义分区[29]的共享卷积特征图上的适应性大小集合(SPP)[1]. Fast R-CNN [2] 实现了对端到端的探测器进行共享的演化特性培训,并显示出令人信服的精度和速度.
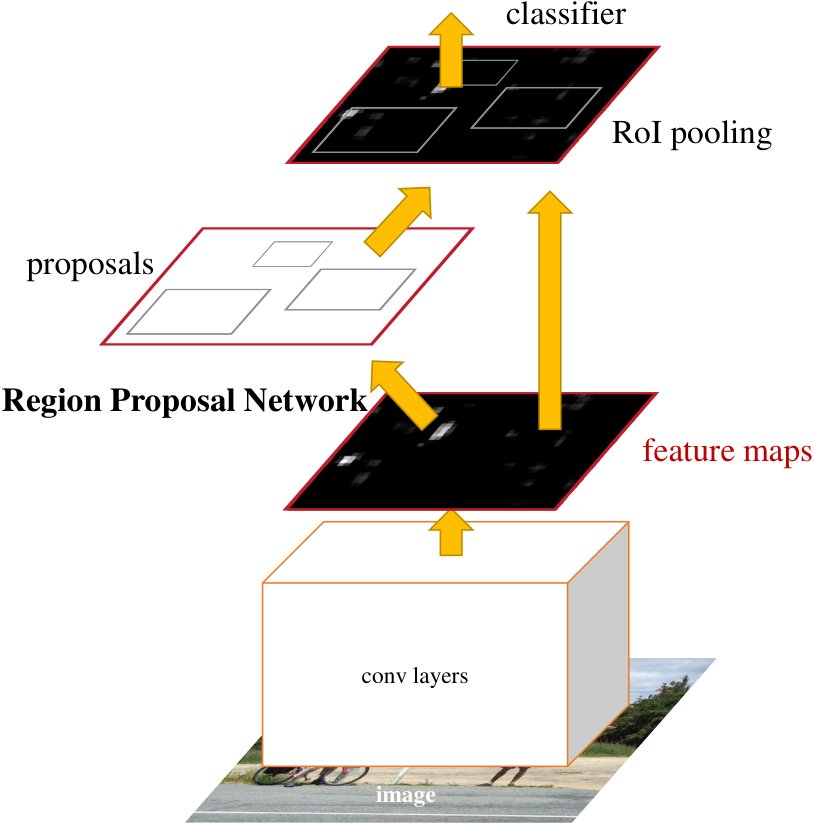
Fig. 2: Faster R-CNN is a single, unified network for object detection. The RPN module serves as the ‘attention’ of this unified network.
费格。 2:更快的R-CNN是用于物体检测的单一,统一的网络. RPN模块是这一统一网络的 " 注意 " 。
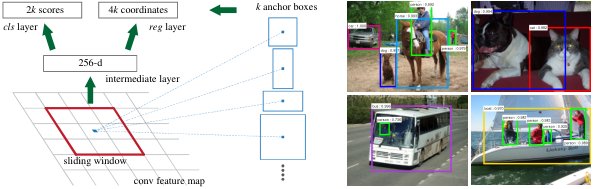
Fig. 3: Left: Region Proposal Network (RPN). Right: Example detections using RPN proposals on PASCAL VOC 2007 test. Our method detects objects in a wide range of scales and aspect ratios.
图3:**左:区域提议网(RPN)。 右:使用RPN建议进行PASCAL VOC 2007测试的示例检测. 我们的方法检测物体的尺度和方方面面比率各不相同。 **
III Faster R-CNN
Our object detection system, called Faster R-CNN, is composed of two modules. The first module is a deep fully convolutional network that proposes regions, and the second module is the Fast R-CNN detector [2] that uses the proposed regions. The entire system is a single, unified network for object detection (Figure 2). Using the recently popular terminology of neural networks with ‘attention’ [31] mechanisms, the RPN module tells the Fast R-CNN module where to look. In Section III-A we introduce the designs and properties of the network for region proposal. In Section III-B we develop algorithms for training both modules with features shared.
我们的物体检测系统称为更快R-CNN,由两个模块组成. 第一个模块是提出区域的深层全卷积网络,第二个模块是使用拟议区域的快速R-CNN探测器[2]. 整个系统是一个单一,统一的物体检测网络(图2). RPN模块使用最近流行的神经网络术语, 在第三节A部分,我们介绍了区域提议网络的设计和特性。 在第三节B部分,我们开发了两种具有共同特点的培训算法。
III-A Region Proposal Networks
III-A 区域提议网络(Region Proposal Networks)
A Region Proposal Network (RPN) takes an image (of any size) as input and outputs a set of rectangular object proposals, each with an objectness score.[^3] We model this process with a fully convolutional network [7], which we describe in this section. Because our ultimate goal is to share computation with a Fast R-CNN object detection network [2], we assume that both nets share a common set of convolutional layers. In our experiments, we investigate the Zeiler and Fergus model [32] (ZF), which has 5 shareable convolutional layers and the Simonyan and Zisserman model [3] (VGG-16), which has 13 shareable convolutional layers.
To generate region proposals, we slide a small network over the convolutional feature map output by the last shared convolutional layer. This small network takes as input an spatial window of the input convolutional feature map. Each sliding window is mapped to a lower-dimensional feature (256-d for ZF and 512-d for VGG, with ReLU [33] following). This feature is fed into two sibling fully-connected layers—a box-regression layer (reg) and a box-classification layer (cls). We use in this paper, noting that the effective receptive field on the input image is large (171 and 228 pixels for ZF and VGG, respectively). This mini-network is illustrated at a single position in Figure 3 (left). Note that because the mini-network operates in a sliding-window fashion, the fully-connected layers are shared across all spatial locations. This architecture is naturally implemented with an convolutional layer followed by two sibling convolutional layers (for reg and cls, respectively).
为了产生区域提议,我们把一个小网络 滑过最后一层共享的地貌图输出 这个小的网络将输入卷积特征图的空间窗口作为输入. 每个滑动窗口被映射到一个下维特性(ZF为256-d,VGG为512-d,ReLU[33]后面). 这一特性被输入两个完全连接的兄弟姐妹层——一个箱递回层(reg)和一个箱分类层(cls)。 我们在本文中使用,指出输入图像上的有效可接受字段很大(ZF和VGG分别为171和228像素). 这种小型网络在图3(左)中以单一位置显示。 请注意,由于迷你网络以滑动窗口的方式运作,全连接的层层在所有空间位置共享.سيل This XX XX XX XX XX XX XX XX XX XX XX XX XX implemented implemented XX implemented implemented
III-A1 Anchors
At each sliding-window location, we simultaneously predict multiple region proposals, where the number of maximum possible proposals for each location is denoted as . So the reg layer has outputs encoding the coordinates of boxes, and the cls layer outputs scores that estimate probability of object or not object for each proposal[^4]. The proposals are parameterized relative to reference boxes, which we call anchors. An anchor is centered at the sliding window in question, and is associated with a scale and aspect ratio (Figure 3, left). By default we use 3 scales and 3 aspect ratios, yielding anchors at each sliding position. For a convolutional feature map of a size (typically 2,400), there are anchors in total.
III-A1 锚框(Anchors)
Translation-Invariant Anchors
** 翻译 -- -- 不定式锚框**
An important property of our approach is that it is translation invariant, both in terms of the anchors and the functions that compute proposals relative to the anchors. If one translates an object in an image, the proposal should translate and the same function should be able to predict the proposal in either location. This translation-invariant property is guaranteed by our method[^5]. As a comparison, the MultiBox method [27] uses k-means to generate 800 anchors, which are not translation invariant. So MultiBox does not guarantee that the same proposal is generated if an object is translated.
我们做法的一个重要财产是,无论是就锚点还是相对于锚点计算提案的功能而言,它都是 " 翻译的 " 。 如果用图像翻译一个对象,提案应当翻译,同一功能应当能够在任一地点预测提案。 这个翻译不变化的属性由我们的方法[^5]保证. 作为比较,MultiBox方法[27]使用k-means生成800个锚,这些锚是not翻译的无变体. 因此,MultiBox并不能保证如果一个对象被翻译出来,会生成同样的建议.
The translation-invariant property also reduces the model size. MultiBox has a -dimensional fully-connected output layer, whereas our method has a -dimensional convolutional output layer in the case of anchors. As a result, our output layer has parameters ( for VGG-16), two orders of magnitude fewer than MultiBox’s output layer that has parameters ( for GoogleNet [34] in MultiBox [27]). If considering the feature projection layers, our proposal layers still have an order of magnitude fewer parameters than MultiBox[^6]. We expect our method to have less risk of overfitting on small datasets, like PASCAL VOC.
翻译不变量属性也减少了模型大小. MultiBox具有 - 维度全连接输出层,而我们的方法则具有 - 维度演化输出层,以锚为例. 因此,我们的输出层有参数( for VGG-16),比MultiBox的输出层少两个数量级(参数为GoogleNet[34] in MultiBox [27]). 如果考虑特征投影层,我们的提案层的参数仍比MultiBox[^6]少一个数量级。 我们期望我们的方法能够减少小数据集过拟合的风险,比如PASCAL VOC.
Multi-Scale Anchors as Regression References
** 作为递归参考的多级基准**
Our design of anchors presents a novel scheme for addressing multiple scales (and aspect ratios). As shown in Figure 1, there have been two popular ways for multi-scale predictions. The first way is based on image/feature pyramids, e.g., in DPM [8] and CNN-based methods [9, 1, 2]. The images are resized at multiple scales, and feature maps (HOG [8] or deep convolutional features [9, 1, 2]) are computed for each scale (Figure 1(a)). This way is often useful but is time-consuming. The second way is to use sliding windows of multiple scales (and/or aspect ratios) on the feature maps. For example, in DPM [8], models of different aspect ratios are trained separately using different filter sizes (such as 57 and 75). If this way is used to address multiple scales, it can be thought of as a “pyramid of filters” (Figure 1(b)). The second way is usually adopted jointly with the first way [8].
我们的锚的设计提出了处理多重尺度(和方方面面比率)的新办法。 如图1所示,多尺度预测有两种流行方式. 第一种方式是基于图像/地貌金字塔,如,在DPM[8]和基于CNN的方法[9,1,2]. 图像按多个尺度调整大小,并计算每个尺度的特征图(HOG [8] 或深卷积特征[9, 1, 2])(图1(a))。 这种方式往往有用,但很费时。 第二种方法是在特征图上使用多个比例(和/或尺寸比)的滑动窗口. 例如拣读DPM[8]中,不同方面比率的模型分别使用不同的滤波器大小(如57和75)进行训练. 如果用这种方法处理多个尺度,可以认为是"滤波器的金字塔"(图1(b)). 第二种方式通常与第一种方式共同采用[8].
As a comparison, our anchor-based method is built on a pyramid of anchors, which is more cost-efficient. Our method classifies and regresses bounding boxes with reference to anchor boxes of multiple scales and aspect ratios. It only relies on images and feature maps of a single scale, and uses filters (sliding windows on the feature map) of a single size. We show by experiments the effects of this scheme for addressing multiple scales and sizes (Table VIII).
作为比较,我们的锚框法建立在一个"锚框金字塔"上,它更具有成本效益. 我们的方法参照多个尺度和方格比率的锚盒,对捆绑框进行分类和递减。 它只依靠单一尺度的图像和 引言图,使用单一尺寸的过滤器(特征图上的滑动窗口). 我们通过实验显示这一计划对处理多种规模和规模的影响(表八)。
Because of this multi-scale design based on anchors, we can simply use the convolutional features computed on a single-scale image, as is also done by the Fast R-CNN detector [2]. The design of multi-scale anchors is a key component for sharing features without extra cost for addressing scales.
由于这种基于锚的多尺度设计,我们可以简单地使用在单尺度图像上计算出的卷积特征,快R-CNN探测器也这样做[2]. 多尺度锚地的设计是共享特性的关键组成部分,而不涉及处理尺度的额外费用。
III-A2 Loss Function
For training RPNs, we assign a binary class label (of being an object or not) to each anchor. We assign a positive label to two kinds of anchors: (i) the anchor/anchors with the highest Intersection-over-Union (IoU) overlap with a ground-truth box, or (ii) an anchor that has an IoU overlap higher than 0.7 with any ground-truth box. Note that a single ground-truth box may assign positive labels to multiple anchors. Usually the second condition is sufficient to determine the positive samples; but we still adopt the first condition for the reason that in some rare cases the second condition may find no positive sample. We assign a negative label to a non-positive anchor if its IoU ratio is lower than 0.3 for all ground-truth boxes. Anchors that are neither positive nor negative do not contribute to the training objective.
III-A2 损失函数
With these definitions, we minimize an objective function following the multi-task loss in Fast R-CNN [2]. Our loss function for an image is defined as:
有了这些定义,在Fast R-CNN的多任务损失之后,我们将一个目标函数最小化[2]. 我们的图像丢失函数被定义为:
Here, is the index of an anchor in a mini-batch and is the predicted probability of anchor being an object. The ground-truth label is 1 if the anchor is positive, and is 0 if the anchor is negative. is a vector representing the 4 parameterized coordinates of the predicted bounding box, and is that of the ground-truth box associated with a positive anchor. The classification loss is log loss over two classes (object vs. not object). For the regression loss, we use where is the robust loss function (smooth L1) defined in [2]. The term means the regression loss is activated only for positive anchors () and is disabled otherwise (). The outputs of the cls and reg layers consist of and respectively.
在这里等同于是迷你批量中锚框的指数,是锚框成为物体的预测概率. 地真标签为1,如果锚是正的,如果锚是负的,则为0. 是一个矢量,代表了预测的边框的4个参数化坐标,是一个与正锚相连的地真盒的矢量. 的分类损失是两个类别(对象vs.不是对象)的日志损失。 对于回归损失,我们使用,其中是[2]定义的稳健损失函数(smooth L1)。 一词是指回归损失仅对正锚()激活,否则被禁用(). cls和reg层的产出分别由和组成.
The two terms are normalized by and and weighted by a balancing parameter . In our current implementation (as in the released code), the term in Eqn.(1) is normalized by the mini-batch size (i.e., ) and the term is normalized by the number of anchor locations (i.e., ). By default we set , and thus both cls and reg terms are roughly equally weighted. We show by experiments that the results are insensitive to the values of in a wide range (Table IX). We also note that the normalization as above is not required and could be simplified.
这两个术语由和规范化,并以一个平衡参数加权. 在我们目前的执行中(如已发布的代码),Eqn.(1)中的术语按小批量大小(即为)实现正常化,术语按锚点数(即为,)实现正常化. 默认情况下,我们设定了,因此,cls和reg*两个术语的加权率大致相同。 我们通过实验表明,结果对的数值不敏感(表九)。 我们还注意到,上述正常化没有必要,可以简化。
For bounding box regression, we adopt the parameterizations of the 4 coordinates following [5]:
对于边框回归,我们采用以下4个坐标的参数化[5]:
where , , , and denote the box’s center coordinates and its width and height. Variables , , and are for the predicted box, anchor box, and ground-truth box respectively (likewise for ). This can be thought of as bounding-box regression from an anchor box to a nearby ground-truth box.
其中、、和表示箱的中心坐标及其宽度和高度。 、和分别用于预测箱、锚盒和真值箱(如)。 这可以被认为是从锚盒到附近的地面真相盒的边框回归.
Nevertheless, our method achieves bounding-box regression by a different manner from previous RoI-based (Region of Interest) methods [1, 2]. In [1, 2], bounding-box regression is performed on features pooled from arbitrarily sized RoIs, and the regression weights are shared by all region sizes. In our formulation, the features used for regression are of the same spatial size () on the feature maps. To account for varying sizes, a set of bounding-box regressors are learned. Each regressor is responsible for one scale and one aspect ratio, and the regressors do not share weights. As such, it is still possible to predict boxes of various sizes even though the features are of a fixed size/scale, thanks to the design of anchors.
尽管如此,我们的方法还是以不同于以往基于RoI(利息登记)的方法[1,2]的方式实现了边框回归. [1, 2包括通过“任意”大小 RoIs 集合的特性进行边框回归,回归权重由所有区域大小* 分摊。 在我们的表述中,用于回归的特征是特征图上的相同空间大小(). 为说明大小不同,学习了一套 边框式退缩器。 每个递减器负责一个尺度和一个方面的比例,而递减器负责不共享权重. 因此,由于锚的设计,尽管特征是固定的大小/尺度,仍然可以预测各种大小的盒子.
III-A3 Training RPNs
The RPN can be trained end-to-end by back-propagation and stochastic gradient descent (SGD) [35]. We follow the “image-centric” sampling strategy from [2] to train this network. Each mini-batch arises from a single image that contains many positive and negative example anchors. It is possible to optimize for the loss functions of all anchors, but this will bias towards negative samples as they are dominate. Instead, we randomly sample 256 anchors in an image to compute the loss function of a mini-batch, where the sampled positive and negative anchors have a ratio of up to 1:1. If there are fewer than 128 positive samples in an image, we pad the mini-batch with negative ones.
III-A3 训练 RPN
We randomly initialize all new layers by drawing weights from a zero-mean Gaussian distribution with standard deviation 0.01. All other layers (i.e., the shared convolutional layers) are initialized by pre-training a model for ImageNet classification [36], as is standard practice [5]. We tune all layers of the ZF net, and conv3 and up for the VGG net to conserve memory [2]. We use a learning rate of 0.001 for 60k mini-batches, and 0.0001 for the next 20k mini-batches on the PASCAL VOC dataset. We use a momentum of 0.9 and a weight decay of 0.0005 [37]. Our implementation uses Caffe [38].
我们通过从零度的高斯分布中抽取权重,以标准偏差0.01来随机初始化所有新层. 所有其他的层(即,共享的卷积层)都通过预训练ImageNet分类模型初始化[36],与标准做法[5]一样. 我们调整 ZF 网的所有层, 和 conv3和上为 VGG 网保存内存 [2]. 在PASCAL VOC数据集上,我们使用0.001的学习率为60千个小炮管,0.0001的下20千个小炮管。 我们使用0.9的动力,0.0005的重量衰减[37]. 我们的执行使用咖啡[38]。
III-B Sharing Features for RPN and Fast R-CNN
III-B RPN 与 Fast R-CNN 的特征共享
Thus far we have described how to train a network for region proposal generation, without considering the region-based object detection CNN that will utilize these proposals. For the detection network, we adopt Fast R-CNN [2]. Next we describe algorithms that learn a unified network composed of RPN and Fast R-CNN with shared convolutional layers (Figure 2).
迄今为止,我们已经描述了如何培训一个区域提议生成网络,而不考虑利用这些提案的基于区域的物体检测CNN。 对于检测网络,我们采用快速R-CNN[2]. 接下来我们描述学习由 RPN 和 Fast R-CNN 组成的具有共享卷积层的统一网络的算法(图2).
| anchor | , 2:1 | , 1:1 | , 1:2 | , 2:1 | , 1:1 | , 1:2 | , 2:1 | , 1:1 | , 1:2 |
|---|---|---|---|---|---|---|---|---|---|
| proposal | 188111 | 113114 | 7092 | 416229 | 261284 | 174332 | 768437 | 499501 | 355715 |
TABLE I: the learned average proposal size for each anchor using the ZF net (numbers for ).
| 锁定 | , 2:1 | , 1:1 | , 1:2 | , 2:1 | , 1:1 | , 1:2 | , 2:1 | , 1:1 | , 1:2 |
|---|---|---|---|---|---|---|---|---|---|
| 建议 | 188111 | 113114 | 7092 | 416229 | 261284 | 174332 | 768437 | 499501 | 355715 |
表一:使用ZF净值( 数字)计算每个锚点的平均建议规模。
Both RPN and Fast R-CNN, trained independently, will modify their convolutional layers in different ways. We therefore need to develop a technique that allows for sharing convolutional layers between the two networks, rather than learning two separate networks. We discuss three ways for training networks with features shared:
独立训练的RPN和Fast R-CNN都会以不同的方式修改其革命层. 因此,我们需要开发一种技术,允许在两个网络之间共享卷积层,而不是学习两个独立的网络. 我们讨论了三种培训网络方式,其特点如下:
(i) Alternating training. In this solution, we first train RPN, and use the proposals to train Fast R-CNN. The network tuned by Fast R-CNN is then used to initialize RPN, and this process is iterated. This is the solution that is used in all experiments in this paper.
(一) 替代培训。 在这个解决方案中,我们首先培训RPN,并利用建议来培训Fast R-CNN. 由Fast R-CNN调制的网络随后被用来初始化RPN,这个过程被反复使用. 这是本文所有实验中使用的解决方案.
(ii) Approximate joint training. In this solution, the RPN and Fast R-CNN networks are merged into one network during training as in Figure 2. In each SGD iteration, the forward pass generates region proposals which are treated just like fixed, pre-computed proposals when training a Fast R-CNN detector. The backward propagation takes place as usual, where for the shared layers the backward propagated signals from both the RPN loss and the Fast R-CNN loss are combined. This solution is easy to implement. But this solution ignores the derivative w.r.t. the proposal boxes’ coordinates that are also network responses, so is approximate. In our experiments, we have empirically found this solver produces close results, yet reduces the training time by about 25-50% comparing with alternating training. This solver is included in our released Python code.
(二) * 近期联合培训*。 在这一解决方案中,RPN网络和快速R-CNN网络在培训期间合并为一个网络,如图2所示. 在每一 SGD 迭代中,前传生成的区域提议,在培训快速R-CNN探测器时,这些提案被处理得就像固定的、预先计算的提案一样。 落后的传播照常进行,对于共享层来说,RPN损失和快速R-CNN损失的后向传播信号是合并在一起的。 这一解决办法易于实施。 但这个解决方案忽略了衍生W.r.t.的建议框的坐标,这些坐标也是网络响应,因此是大致的. 在我们的实验中,我们从经验中发现这个解答器产生近似的结果,然而与交替训练相比,将训练时间减少了大约25-50%. 这个解答器包含在我们发布的Python代码中.
(iii) Non-approximate joint training. As discussed above, the bounding boxes predicted by RPN are also functions of the input. The RoI pooling layer [2] in Fast R-CNN accepts the convolutional features and also the predicted bounding boxes as input, so a theoretically valid backpropagation solver should also involve gradients w.r.t. the box coordinates. These gradients are ignored in the above approximate joint training. In a non-approximate joint training solution, we need an RoI pooling layer that is differentiable w.r.t. the box coordinates. This is a nontrivial problem and a solution can be given by an “RoI warping” layer as developed in [15], which is beyond the scope of this paper.
- 非近似联合培训*。 如上所述,RPN预测的边框也是输入的功能. Ro 上述大约联合培训忽略了这些梯度。 在一个非近似联合训练的解决方案中,我们需要一个 RoI 集合层,它是不同的w.r.t. 这是一个非三角问题,可以通过[15]中开发的“RoI warping”层给出解决办法,这超出了本文件的范围。
4-Step Alternating Training. In this paper, we adopt a pragmatic 4-step training algorithm to learn shared features via alternating optimization. In the first step, we train the RPN as described in Section III-A3. This network is initialized with an ImageNet-pre-trained model and fine-tuned end-to-end for the region proposal task. In the second step, we train a separate detection network by Fast R-CNN using the proposals generated by the step-1 RPN. This detection network is also initialized by the ImageNet-pre-trained model. At this point the two networks do not share convolutional layers. In the third step, we use the detector network to initialize RPN training, but we fix the shared convolutional layers and only fine-tune the layers unique to RPN. Now the two networks share convolutional layers. Finally, keeping the shared convolutional layers fixed, we fine-tune the unique layers of Fast R-CNN. As such, both networks share the same convolutional layers and form a unified network. A similar alternating training can be run for more iterations, but we have observed negligible improvements.
4-分阶段替代培训。 在本文中,我们采用了实用的四步训练算法,通过交替优化来学习共同的特征. 第一步,我们如第三节A3所述,培训RPN。 该网络已经初始化,采用了ImageNet经过预先培训的模型,并对区域提议任务的端到端进行了微调。 第二步,我们利用步骤-1RPN产生的建议,通过Fast R-CNN训练一个单独的检测网络. 这个检测网络也由ImageNet预训练模型初始化. 此时两个网络并不共享革命层. 在第三步中,我们利用探测器网络来初始化RPN训练,但我们固定了共享的卷积层,只微调了RPN特有的层. 现在两个网络共享革命层. 最后,保持共享的革命层固定,我们微调了快速R-CNN的独特层. 因此,两个网络都共享同样的革命层,并形成统一的网络. 类似的交替培训可以用于更多的迭代,但我们看到的改进微不足道。
| train-time region proposals | test-time region proposals | |||
|---|---|---|---|---|
| method | # boxes | method | # proposals | mAP (%) |
| SS | 2000 | SS | 2000 | 58.7 |
| EB | 2000 | EB | 2000 | 58.6 |
| RPN+ZF, shared | 2000 | RPN+ZF, shared | 300 | 59.9 |
| ablation experiments follow below | ||||
| RPN+ZF, unshared | 2000 | RPN+ZF, unshared | 300 | 58.7 |
| SS | 2000 | RPN+ZF | 100 | 55.1 |
| SS | 2000 | RPN+ZF | 300 | 56.8 |
| SS | 2000 | RPN+ZF | 1000 | 56.3 |
| SS | 2000 | RPN+ZF (no NMS) | 6000 | 55.2 |
| SS | 2000 | RPN+ZF (no cls) | 100 | 44.6 |
| SS | 2000 | RPN+ZF (no cls) | 300 | 51.4 |
| SS | 2000 | RPN+ZF (no cls) | 1000 | 55.8 |
| SS | 2000 | RPN+ZF (no reg) | 300 | 52.1 |
| SS | 2000 | RPN+ZF (no reg) | 1000 | 51.3 |
| SS | 2000 | RPN+VGG | 300 | 59.2 |
TABLE II: Detection results on PASCAL VOC 2007 test set (trained on VOC 2007 trainval). The detectors are Fast R-CNN with ZF, but using various proposal methods for training and testing.
| ** 训练时间区域提议** | ** 试验期区域提议** | |||
|---|---|---|---|---|
| 方法 | # 纸箱 | 方法 | # 建议 | mAP (%) |
| SS | 2000 | SS | 2000 | 58.7 |
| 电子邮件 | 2000 | 电子邮件 | 2000 | 58.6 |
| RPN+ZF, 共享 | 2000 | RPN+ZF, 共享 | 300 | 59.9 国家 |
| 以下是模拟实验 | ||||
| RPN+ZF, 未分摊 | 2000 | RPN+ZF, 未分摊 | 300 | 58.7 |
| SS | 2000 | RPN+ZF 常规运算 | 100 | 55.1 |
| SS | 2000 | RPN+ZF 常规运算 | 300 | 56.8 |
| SS | 2000 | RPN+ZF 常规运算 | 1000 | 56.3 |
| SS | 2000 | RPN+ZF(无国家监测系统) | 6000 | 55.2 |
| SS | 2000 | RPN+ZF(无 *cls *) | 100 | 44.6 |
| SS | 2000 | RPN+ZF(无 *cls *) | 300 | 51.4 |
| SS | 2000 | RPN+ZF(无 *cls *) | 1000 | 55.8 |
| SS | 2000 | RPN+ZF(无 reg) | 300 | 52.1 |
| SS | 2000 | RPN+ZF(无 reg) | 1000 | 51.3 |
| SS | 2000 | RPN+VGG 组合 | 300 | 59.2 |
表二:PASCAL VOC 2007测试集的检测结果(在VOC 2007列车val上培训). 探测器是带有ZF的快速R-CNN,但使用各种建议方法进行训练和测试.
III-C Implementation Details
III-C 实现细节
We train and test both region proposal and object detection networks on images of a single scale [1, 2]. We re-scale the images such that their shorter side is pixels [2]. Multi-scale feature extraction (using an image pyramid) may improve accuracy but does not exhibit a good speed-accuracy trade-off [2]. On the re-scaled images, the total stride for both ZF and VGG nets on the last convolutional layer is 16 pixels, and thus is 10 pixels on a typical PASCAL image before resizing (500375). Even such a large stride provides good results, though accuracy may be further improved with a smaller stride.
我们在单一比例的图像[1、2]上培训和测试区域提议和物体检测网络。 我们调整了图像的尺寸,使其短的一面是像素[2]. 多尺度特征提取(使用图像金字塔)可能提高精度,但不会显示良好的速度精确度权衡[2]. 在重新缩放的图像上,ZF和VGG网在最后一个卷积层上的总步态为16像素,因此在重新缩放之前是典型的PASCAL图像上的 10像素( 500375). 即使这样大的步子也提供了良好的效果,但用较小的步子可以进一步提高准确性。
For anchors, we use 3 scales with box areas of , , and pixels, and 3 aspect ratios of 1:1, 1:2, and 2:1. These hyper-parameters are not carefully chosen for a particular dataset, and we provide ablation experiments on their effects in the next section. As discussed, our solution does not need an image pyramid or filter pyramid to predict regions of multiple scales, saving considerable running time. Figure 3 (right) shows the capability of our method for a wide range of scales and aspect ratios. Table I shows the learned average proposal size for each anchor using the ZF net. We note that our algorithm allows predictions that are larger than the underlying receptive field. Such predictions are not impossible—one may still roughly infer the extent of an object if only the middle of the object is visible.
对于锚,我们使用3个比例尺,框区为,,和像素,3个尺寸比为1:1,1:2和2:1. 这些超参数不是** 精心选择用于特定的数据集,我们在下一节中提供其效应的减速实验. 正如所讨论的,我们的解决方案不需要一个图像金字塔或过滤金字塔来预测多个尺度的区域,从而节省大量运行时间。 图3(右)显示我们的方法在各种尺度和方面比率方面的能力。 表一用ZF网显示每个锚点的平均建议规模。 我们注意到,我们的算法允许比基本接受领域更大的预测。 这种预测并非不可能——如果只看到物体的中间,人们仍然可以大致推断物体的范围。
The anchor boxes that cross image boundaries need to be handled with care. During training, we ignore all cross-boundary anchors so they do not contribute to the loss. For a typical image, there will be roughly 20000 () anchors in total. With the cross-boundary anchors ignored, there are about 6000 anchors per image for training. If the boundary-crossing outliers are not ignored in training, they introduce large, difficult to correct error terms in the objective, and training does not converge. During testing, however, we still apply the fully convolutional RPN to the entire image. This may generate cross-boundary proposal boxes, which we clip to the image boundary.
跨越图像边界的锚盒需要小心处理。 在训练期间,我们忽略了所有跨界锚,以免造成损失。 对于一个典型的图像,总共会有大约20000()锚. 由于跨界锚框被忽略,每个图像约有6000个锚框用于训练. 如果在训练中不忽略跨越边界的外围者,它们引入了大型,难以校正目标中的误差术语,而训练并不趋同. 然而,在测试期间,我们仍然对整个图像应用了全演化的RPN. 这可能会产生跨边界的建议框,我们将其剪切到图像边界。
Some RPN proposals highly overlap with each other. To reduce redundancy, we adopt non-maximum suppression (NMS) on the proposal regions based on their cls scores. We fix the IoU threshold for NMS at 0.7, which leaves us about 2000 proposal regions per image. As we will show, NMS does not harm the ultimate detection accuracy, but substantially reduces the number of proposals. After NMS, we use the top- ranked proposal regions for detection. In the following, we train Fast R-CNN using 2000 RPN proposals, but evaluate different numbers of proposals at test-time.
一些RPN建议彼此高度重叠. 为了减少冗余,我们根据建议区域的cl分数,对提议区域采用非最大压制。 我们把国家监测系统的IoU阈值定在0.7,这使我们每个图像约有2000个提案区域。 正如我们将显示的那样,核监测系统不会损害最终检测的准确性,而是会大大减少提案的数量。 在NMS之后,我们使用最高的 -排名建议区域进行检测. 在下面,我们利用2000年RPN提案来训练快速R-CNN,但在试验时评价不同数目的提案.
IV Experiments
IV 实验
IV-A Experiments on PASCAL VOC
IV-A PASCAL VOC 上的实验
We comprehensively evaluate our method on the PASCAL VOC 2007 detection benchmark [11]. This dataset consists of about 5k trainval images and 5k test images over 20 object categories. We also provide results on the PASCAL VOC 2012 benchmark for a few models. For the ImageNet pre-trained network, we use the “fast” version of ZF net [32] that has 5 convolutional layers and 3 fully-connected layers, and the public VGG-16 model[^7] [3] that has 13 convolutional layers and 3 fully-connected layers. We primarily evaluate detection mean Average Precision (mAP), because this is the actual metric for object detection (rather than focusing on object proposal proxy metrics).
我们对2007年PASCAL VOC检测基准的方法进行全面评价[11]。 这个数据集包含约5k列车val图像和超过20个对象类别的5k测试图像. 我们还为几个模型提供了PASCAL VOC 2012基准结果。 对于ImageNet预先训练的网络,我们使用ZF网的"快速"版本[32],该版本有5个卷积层和3个全连接层,公共VGG-16模式[^7][3],该版本有13个卷积层和3个全连接层. 我们主要评价检测是指平均精度(mAP),因为这是物体检测的实际度量衡(而不是专注于物体建议代用度量).
Table II (top) shows Fast R-CNN results when trained and tested using various region proposal methods. These results use the ZF net. For Selective Search (SS) [4], we generate about 2000 proposals by the “fast” mode. For EdgeBoxes (EB) [6], we generate the proposals by the default EB setting tuned for 0.7 IoU. SS has an mAP of 58.7% and EB has an mAP of 58.6% under the Fast R-CNN framework. RPN with Fast R-CNN achieves competitive results, with an mAP of 59.9% while using up to 300 proposals[^8]. Using RPN yields a much faster detection system than using either SS or EB because of shared convolutional computations; the fewer proposals also reduce the region-wise fully-connected layers’ cost (Table V).
表二(上)显示使用各种区域提议方法培训和测试的快速R-CNN结果。 这些结果使用ZF网. 对于选择性搜索(SS)[4],我们按“快速”模式提出大约2000项建议。 对于EdgeBoxes(EB)[6],我们通过默认的EB设定调制0.7 IoU来生成提案. SS的mAP为58.7%,EB的mAP为58.6%在Fast R-CNN框架下. 配有快速R-CNN的RPN实现竞争结果,mAP为59.9%,同时使用*最多300个建议书[^8]. 使用 RPN 的检测系统比使用SS 或 EB 的检测系统要快得多,因为共享的演化计算;提案越少,也降低了区域全连接层的成本(表五).
| method | # proposals | data | mAP (%) |
|---|---|---|---|
| SS | 2000 | 07 | 66.9*†* |
| SS | 2000 | 07+12 | 70.0 |
| RPN+VGG, unshared | 300 | 07 | 68.5 |
| RPN+VGG, shared | 300 | 07 | 69.9 |
| RPN+VGG, shared | 300 | 07+12 | 73.2 |
| RPN+VGG, shared | 300 | COCO+07+12 | 78.8 |
TABLE III: Detection results on PASCAL VOC 2007 test set. The detector is Fast R-CNN and VGG-16. Training data: “07”: VOC 2007 trainval, “07+12”: union set of VOC 2007 trainval and VOC 2012 trainval. For RPN, the train-time proposals for Fast R-CNN are 2000. †: this number was reported in [2]; using the repository provided by this paper, this result is higher (68.1).
| 方法 | # 建议 | 数据 | mAP (%) |
|---|---|---|---|
| SS | 2000 | 07 | 66.9是否可以确定: |
| SS | 2000 | 07+12 | 70.0 |
| RPN+VGG, 未分摊 | 300 | 07 | 68.5 |
| RPN+VGG, 共享 | 300 | 07 | 69.9 |
| RPN+VGG, 共享 | 300 | 07+12 | ** 第73.2段** |
| RPN+VGG, 共享 | 300 | COCO+07+12 (中文(简体) ). | 页:1 |
表三:PASCAL VOC 2007测试集的检测结果。 探测器为Fast R-CNN和VGG-16. 训练数据:"07":VOC 2007列车val,"07+12":联盟系列VOC 2007列车val和VOC 2012列车val. 对RPN来说,ýR-CNN的火车时间建议是2000年。 †:这一数字在[2]中报告;使用本文提供的存储器,这一结果更高(68.1)。
| method | # proposals | data | mAP (%) |
|---|---|---|---|
| SS | 2000 | 12 | 65.7 |
| SS | 2000 | 07++12 | 68.4 |
| RPN+VGG, shared*†* | 300 | 12 | 67.0 |
| RPN+VGG, shared*‡* | 300 | 07++12 | 70.4 |
| RPN+VGG, shared§ | 300 | COCO+07++12 | 75.9 |
TABLE IV: Detection results on PASCAL VOC 2012 test set. The detector is Fast R-CNN and VGG-16. Training data: “07”: VOC 2007 trainval, “07++12”: union set of VOC 2007 trainval+test and VOC 2012 trainval. For RPN, the train-time proposals for Fast R-CNN are 2000. †: http://host.robots.ox.ac.uk:8080/anonymous/HZJTQA.html. ‡: http://host.robots.ox.ac.uk:8080/anonymous/YNPLXB.html. §: http://host.robots.ox.ac.uk:8080/anonymous/XEDH10.html.
| 方法 | # 建议 | 数据 | mAP (%) |
|---|---|---|---|
| SS | 2000 | 12 | 65.7 |
| SS | 2000 | 07++12 | 68.4 |
| RPN+VGG, 共享QQ | 300 | 12 | 67.0 |
| RPN芸+VGG, 共享 QQ | 300 | 07++12 | ** 第70.4段** |
| RPN+VGG, 共享§ | 300 | COCO+07++12 导弹 | 页:1 |
表四:PASCAL VOC 2012测试集的检测结果。 探测器为Fast R-CNN和VGG-16. 训练数据:"07":VOC 2007列车val,"07++12":工会集 VOC 2007列车val+测试和VOC 2012列车val. 对RPN来说,快速R-CNN的火车时间建议是2000年. http://host.robots.ox.ac.uk:8080/anonymous/HZJTQA.html. ‡:http://host.robots.ox.ac.uk:8080/anonymous/YNPLXB.html. §: http://host.robots.ox.ac.uk:8080/anonymous/XEDH10.html.
| model | system | conv | proposal | region-wise | total | rate |
|---|---|---|---|---|---|---|
| VGG | SS + Fast R-CNN | 146 | 1510 | 174 | 1830 | 0.5 fps |
| VGG | RPN + Fast R-CNN | 141 | 10 | 47 | 198 | 5 fps |
| ZF | RPN + Fast R-CNN | 31 | 3 | 25 | 59 | 17 fps |
TABLE V: Timing (ms) on a K40 GPU, except SS proposal is evaluated in a CPU. “Region-wise” includes NMS, pooling, fully-connected, and softmax layers. See our released code for the profiling of running time.
| 模型 | 系统 | 弯曲 | 建议 | 区域 | 共计 | .1 费率 |
|---|---|---|---|---|---|---|
| VGG 游戏 | SS + 快速 R- CNN | 146 | 1510 | 174 | 1830 | 0.5小时 |
| VGG 游戏 | RPN + 快车R-CNN | 141 | 页:1 | 47 | 页:1 | **5英尺处 |
| 津巴布韦语Name | RPN + 快车R-CNN | 31 | 页:1 | 25 | 页:1 | ** 17英尺处** |
表格五:** K40 GPU上的图示(ms),除了党卫军的提议在CPU中进行评价. “视理”包括NMS、集合、完全连接和软磁层。 关于运行时间的剖析,见我们发布的代码。 **
Ablation Experiments on RPN. To investigate the behavior of RPNs as a proposal method, we conducted several ablation studies. First, we show the effect of sharing convolutional layers between the RPN and Fast R-CNN detection network. To do this, we stop after the second step in the 4-step training process. Using separate networks reduces the result slightly to 58.7% (RPN+ZF, unshared, Table II). We observe that this is because in the third step when the detector-tuned features are used to fine-tune the RPN, the proposal quality is improved.
** RPN上的扩张实验。 ** 为了调查RPNs作为一种提议方法的行为,我们进行了几项消化研究. 首先,我们显示RPN和Fast R-CNN检测网络之间共享卷积层的效果. 为了做到这一点,我们在四步训练进程的第二步之后就停止了。 使用单独的网络将结果略降至58.7%(RPN+ZF,未分摊,表二)。 我们观察到,这是因为在第三步使用探测器调制特性来微调RPN时,提案的质量得到了提高.
Next, we disentangle the RPN’s influence on training the Fast R-CNN detection network. For this purpose, we train a Fast R-CNN model by using the 2000 SS proposals and ZF net. We fix this detector and evaluate the detection mAP by changing the proposal regions used at test-time. In these ablation experiments, the RPN does not share features with the detector.
接下来我们解开RPN对训练快速R-CNN检测网络的影响. 为此,我们利用2000年党卫军提案和ZF网来训练一种快速R-CNN模式. 我们通过改变试验时使用的提案区域来修复这个探测器并评估探测仪。 在这些衰减实验中,RPN不与探测器共享特征.
Replacing SS with 300 RPN proposals at test-time leads to an mAP of 56.8%. The loss in mAP is because of the inconsistency between the training/testing proposals. This result serves as the baseline for the following comparisons.
以300 RPN提议取代SS在测试时,导致mAP为56.8%. MAP的损失是由于培训/测试建议不一致。 这一结果可作为以下比较的基准。
Somewhat surprisingly, the RPN still leads to a competitive result (55.1%) when using the top-ranked 100 proposals at test-time, indicating that the top-ranked RPN proposals are accurate. On the other extreme, using the top-ranked 6000 RPN proposals (without NMS) has a comparable mAP (55.2%), suggesting NMS does not harm the detection mAP and may reduce false alarms.
令人惊讶的是,RPN在测试时间使用排名最高的100个建议书时仍然会导致竞争结果(55.1%),这表明排名最高的RPN建议书准确无误. 另一方面,使用排名最高的6000RPN建议(不含NMS)具有可比较的mAP(55.2%),说明NMS不会损害检测mAP,可能减少假警报.
Next, we separately investigate the roles of RPN’s cls and reg outputs by turning off either of them at test-time. When the cls layer is removed at test-time (thus no NMS/ranking is used), we randomly sample proposals from the unscored regions. The mAP is nearly unchanged with (55.8%), but degrades considerably to 44.6% when . This shows that the cls scores account for the accuracy of the highest ranked proposals.
接下来,我们单独调查RPN的cl和reg产出的作用,在测试时关闭其中任一产出。 当cls层在测试时被移除(因此没有使用NMS/级别)时,我们随机抽取来自无分数区域的提案. 与(55.8%)相比,mAP几乎没有变化,但在 时大幅下降至44.6%. 这表明cls分数是排名最高的建议书的准确性.
On the other hand, when the reg layer is removed at test-time (so the proposals become anchor boxes), the mAP drops to 52.1%. This suggests that the high-quality proposals are mainly due to the regressed box bounds. The anchor boxes, though having multiple scales and aspect ratios, are not sufficient for accurate detection.
另一方面,当reg层在测试时被移除(因此建议成为锚箱)时,mAP下降到52.1%. 这表明,高质量提案主要是由于框框界限倒退所致。 锚盒虽然具有多个尺度和侧面比率,但不足以准确检测。
We also evaluate the effects of more powerful networks on the proposal quality of RPN alone. We use VGG-16 to train the RPN, and still use the above detector of SS+ZF. The mAP improves from 56.8% (using RPN+ZF) to 59.2% (using RPN+VGG). This is a promising result, because it suggests that the proposal quality of RPN+VGG is better than that of RPN+ZF. Because proposals of RPN+ZF are competitive with SS (both are 58.7% when consistently used for training and testing), we may expect RPN+VGG to be better than SS. The following experiments justify this hypothesis.
我们还评价较强大的网络仅对RPN提案质量的影响。 我们使用VGG-16来训练RPN,仍然使用上面的SS+ZF探测器. mAP从56.8%(使用RPN+ZF)提高到59.2%(使用RPN+VGG). 这是一个很有希望的结果,因为它表明RPN+VGG的建议书质量优于RPN+ZF. 因为RPN+ZF的提议与SS竞争(在持续用于培训和测试时均为58.7%),我们可能会期望RPN+VGG优于SS. 以下实验证明这一假设是合理的.
| method | # box | data | mAP | areo | bike | bird | boat | bottle | bus | car | cat | chair | cow | table | dog | horse | mbike | person | plant | sheep | sofa | train | tv |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| SS | 2000 | 07 | 66.9 | 74.5 | 78.3 | 69.2 | 53.2 | 36.6 | 77.3 | 78.2 | 82.0 | 40.7 | 72.7 | 67.9 | 79.6 | 79.2 | 73.0 | 69.0 | 30.1 | 65.4 | 70.2 | 75.8 | 65.8 |
| SS | 2000 | 07+12 | 70.0 | 77.0 | 78.1 | 69.3 | 59.4 | 38.3 | 81.6 | 78.6 | 86.7 | 42.8 | 78.8 | 68.9 | 84.7 | 82.0 | 76.6 | 69.9 | 31.8 | 70.1 | 74.8 | 80.4 | 70.4 |
| RPN∗ | 300 | 07 | 68.5 | 74.1 | 77.2 | 67.7 | 53.9 | 51.0 | 75.1 | 79.2 | 78.9 | 50.7 | 78.0 | 61.1 | 79.1 | 81.9 | 72.2 | 75.9 | 37.2 | 71.4 | 62.5 | 77.4 | 66.4 |
| RPN | 300 | 07 | 69.9 | 70.0 | 80.6 | 70.1 | 57.3 | 49.9 | 78.2 | 80.4 | 82.0 | 52.2 | 75.3 | 67.2 | 80.3 | 79.8 | 75.0 | 76.3 | 39.1 | 68.3 | 67.3 | 81.1 | 67.6 |
| RPN | 300 | 07+12 | 73.2 | 76.5 | 79.0 | 70.9 | 65.5 | 52.1 | 83.1 | 84.7 | 86.4 | 52.0 | 81.9 | 65.7 | 84.8 | 84.6 | 77.5 | 76.7 | 38.8 | 73.6 | 73.9 | 83.0 | 72.6 |
| RPN | 300 | COCO+07+12 | 78.8 | 84.3 | 82.0 | 77.7 | 68.9 | 65.7 | 88.1 | 88.4 | 88.9 | 63.6 | 86.3 | 70.8 | 85.9 | 87.6 | 80.1 | 82.3 | 53.6 | 80.4 | 75.8 | 86.6 | 78.9 |
TABLE VI: Results on PASCAL VOC 2007 test set with Fast R-CNN detectors and VGG-16. For RPN, the train-time proposals for Fast R-CNN are 2000. RPN∗ denotes the unsharing feature version.
| 方法 | # box | 数据 | mAP | 状态 | 自行车 | 鸟 | boat | 瓶装 | 公共汽车 | car | cat | 椅子 | 黄牛 | 页:1 | 狗头 | 马 | 摩托车 | 座谈会 | 工厂 | 绵羊 | 沙发 | 火车 | 将按照 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| SS | 2000 | 07 | 66.9 | 74.5 | 78.3 | 69.2 | 53.2 | 36.6 | 77.3 | 78.2 | 82.0 | 40.7 | 72.7 | 67.9 | 79.6 | 79.2 | 73.0 | 69.0 | 30.1 | 65.4 | 70.2 | 75.8 | 65.8 |
| SS | 2000 | 07+12 | 70.0 | 77.0 | 78.1 | 69.3 | 59.4 | 38.3 | 81.6 | 78.6 | 86.7 | 42.8 | 78.8 | 68.9 | 84.7 | 82.0 | 76.6 | 69.9 | 31.8 | 70.1 | 74.8 | 80.4 | 70.4 |
| 卢旺达* | 300 | 07 | 68.5 | 74.1 | 77.2 | 67.7 | 53.9 | 51.0 | 75.1 | 79.2 | 78.9 | 50.7 | 78.0 | 61.1 | 79.1 | 81.9 | 72.2 | 75.9 | 37.2 | 71.4 | 62.5 | 77.4 | 66.4 |
| RPN 红调 | 300 | 07 | 69.9 | 70.0 | 80.6 | 70.1 | 57.3 | 49.9 | 78.2 | 80.4 | 82.0 | 52.2 | 75.3 | 67.2 | 80.3 | 79.8 | 75.0 | 76.3 | 39.1 | 68.3 | 67.3 | 81.1 | 67.6 |
| RPN 红调 | 300 | 07+12 | 73.2 | 76.5 | 79.0 | 70.9 | 65.5 | 52.1 | 83.1 | 84.7 | 86.4 | 52.0 | 81.9 | 65.7 | 84.8 | 84.6 | 77.5 | 76.7 | 38.8 | 73.6 | 73.9 | 83.0 | 72.6 |
| RPN 红调 | 300 | 共 3 倍, 共 3 倍 | 页:1 | 页:1 | ** ** 82.0 ** | 页:1 | 页:1 | ** 65.7 ** | ** 88.1 ** | ** 88.4** (单位:千美元) | * ** 88.9 ** | 页:1 | 页:1 | ** 第70.8段** | 页:1 | 我们要打个招呼。 | 页:1 | 之间关系 | ** 53.6** 经常预算: | 页:1 | 页:1 | 页:1 | ** ** 78.9 ** |
表六:使用快速R-CNN探测器和VGG-16进行2007年PASCAL VOC测试的结果。 对RPN来说,快速R-CNN的火车时间建议是2000年. RPN* 表示未共享特性版本.
| method | # box | data | mAP | areo | bike | bird | boat | bottle | bus | car | cat | chair | cow | table | dog | horse | mbike | person | plant | sheep | sofa | train | tv |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| SS | 2000 | 12 | 65.7 | 80.3 | 74.7 | 66.9 | 46.9 | 37.7 | 73.9 | 68.6 | 87.7 | 41.7 | 71.1 | 51.1 | 86.0 | 77.8 | 79.8 | 69.8 | 32.1 | 65.5 | 63.8 | 76.4 | 61.7 |
| SS | 2000 | 07++12 | 68.4 | 82.3 | 78.4 | 70.8 | 52.3 | 38.7 | 77.8 | 71.6 | 89.3 | 44.2 | 73.0 | 55.0 | 87.5 | 80.5 | 80.8 | 72.0 | 35.1 | 68.3 | 65.7 | 80.4 | 64.2 |
| RPN | 300 | 12 | 67.0 | 82.3 | 76.4 | 71.0 | 48.4 | 45.2 | 72.1 | 72.3 | 87.3 | 42.2 | 73.7 | 50.0 | 86.8 | 78.7 | 78.4 | 77.4 | 34.5 | 70.1 | 57.1 | 77.1 | 58.9 |
| RPN | 300 | 07++12 | 70.4 | 84.9 | 79.8 | 74.3 | 53.9 | 49.8 | 77.5 | 75.9 | 88.5 | 45.6 | 77.1 | 55.3 | 86.9 | 81.7 | 80.9 | 79.6 | 40.1 | 72.6 | 60.9 | 81.2 | 61.5 |
| RPN | 300 | COCO+07++12 | 75.9 | 87.4 | 83.6 | 76.8 | 62.9 | 59.6 | 81.9 | 82.0 | 91.3 | 54.9 | 82.6 | 59.0 | 89.0 | 85.5 | 84.7 | 84.1 | 52.2 | 78.9 | 65.5 | 85.4 | 70.2 |
TABLE VII: Results on PASCAL VOC 2012 test set with Fast R-CNN detectors and VGG-16. For RPN, the train-time proposals for Fast R-CNN are 2000.
| 方法 | # box | 数据 | mAP | 状态 | 自行车 | 鸟 | boat | 瓶装 | 公共汽车 | car | cat | 椅子 | 黄牛 | 页:1 | ồ虫 | 马 | 摩托车 | 人员 | 工厂 | 向他们提供 | 还好沙发 | 火车 | 电视 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| SS | 2000 | 12 | 65.7 | 80.3 | 74.7 | 66.9 | 46.9 | 37.7 | 73.9 | 68.6 | 87.7 | 41.7 | 71.1 | 51.1 | 86.0 | 77.8 | 79.8 | 69.8 | 32.1 | 65.5 | 63.8 | 76.4 | 61.7 |
| SS | 2000 | 07++12 | 68.4 | 82.3 | 78.4 | 70.8 | 52.3 | 38.7 | 77.8 | 71.6 | 89.3 | 44.2 | 73.0 | 55.0 | 页:1 | 80.5 | 80.8 | 72.0 | 35.1 | 68.3 | ** 65.7 ** | 80.4 | 64.2 |
| RPN 红调 | 300 | 12 | 67.0 | 82.3 | 76.4 | 71.0 | 48.4 | 45.2 | 72.1 | 72.3 | 87.3 | 42.2 | 73.7 | 50.0 | 86.8 | 78.7 | 78.4 | 77.4 | 34.5 | 70.1 | 57.1 | 77.1 | 58.9 |
| RPN 红调 | 300 | 07++12 | 70.4 | 84.9 | 79.8 | 74.3 | 53.9 | 49.8 | 77.5 | 75.9 | 88.5 | 45.6 | 77.1 | 55.3 | 86.9 | 81.7 | 80.9 | 79.6 | 40.1 | 72.6 | 60.9 | 81.2 | 61.5 |
| RPN 红调 | 300 | COCO+07++12 导弹 | 页:1 | 页:1 | 页:1 | 页:1 | 页:1 | 页:1 | 页:1 | ** ** 82.0 ** | 91.3 经常预算: | 页:1 | ** 82.6 ** 以千美元计。 | ** 599.0** (单位:千美元) | 页:1 | ** 85.5%** | ** 84.7 ** | ** 8 4 6 6 6 7 6 7 | **52.2 ** | ** ** 78.9 ** | 65.5 | ** 85.4** (单位:千美元) | 除此以外,还存在下列情况: |
表七:使用快速R-CNN探测器和VGG-16进行PASAL VOC 2012测试的结果. 对RPN来说,快速R-CNN的火车时间建议是2000年.
Performance of VGG-16. Table III shows the results of VGG-16 for both proposal and detection. Using RPN+VGG, the result is 68.5% for unshared features, slightly higher than the SS baseline. As shown above, this is because the proposals generated by RPN+VGG are more accurate than SS. Unlike SS that is pre-defined, the RPN is actively trained and benefits from better networks. For the feature-shared variant, the result is 69.9%—better than the strong SS baseline, yet with nearly cost-free proposals. We further train the RPN and detection network on the union set of PASCAL VOC 2007 trainval and 2012 trainval. The mAP is 73.2%. Figure 5 shows some results on the PASCAL VOC 2007 test set. On the PASCAL VOC 2012 test set (Table IV), our method has an mAP of 70.4% trained on the union set of VOC 2007 trainval+test and VOC 2012 trainval. Table VI and Table VII show the detailed numbers.
** VGG-16的绩效。 ** 表三显示VGG-16提案和检测结果。 使用RPN+VGG,结果对未共享特性为68.5%,略高于SS基线. 如上所示,这是因为RPN+VGG产生的建议比SS更准确. 与预定义的SS不同,RPN受到积极的训练,并从更好的网络中获益. 就特征共享的变体而言,结果比严格的党卫军基准要好69.9*%,但几乎是免费的。 我们进一步培训RPN和检测网络在PASCAL VOC 2007列车和2012列车的联盟系列。 mAP为73.2%. 图5显示了2007年PASCAL VOC测试集的一些结果。 在PASCAL VOC 2012虔诚测试集(表四)上,我们的方法有**70.4%**的mAP,培训内容为VOC 2007列车+测试和VOC 2012列车val的结合集. 表六和表七列出了详细数字。
In Table V we summarize the running time of the entire object detection system. SS takes 1-2 seconds depending on content (on average about 1.5s), and Fast R-CNN with VGG-16 takes 320ms on 2000 SS proposals (or 223ms if using SVD on fully-connected layers [2]). Our system with VGG-16 takes in total 198ms for both proposal and detection. With the convolutional features shared, the RPN alone only takes 10ms computing the additional layers. Our region-wise computation is also lower, thanks to fewer proposals (300 per image). Our system has a frame-rate of 17 fps with the ZF net.
在表五中,我们总结了整个物体检测系统的运行时间。 党卫军根据内容需要1-2秒(平均约1.5秒),而带有VGG-16的快速R-CNN在2000年党卫军建议书上需要320ms(或者如果在全连通层上使用SVD[2]). 我们与VGG-16的系统总共需要198ms 用于建议和检测。 由于共享的卷积特征,单RPN只需要10ms计算额外的层. 由于提议减少(每幅图像300),我们区域的计算也较低。 我们的系统有17英尺的帧率 与ZF网。
| settings | anchor scales | aspect ratios | mAP (%) |
|---|---|---|---|
| 1 scale, 1 ratio | 1:1 | 65.8 | |
| 1:1 | 66.7 | ||
| 1 scale, 3 ratios | {2:1, 1:1, 1:2} | 68.8 | |
| {2:1, 1:1, 1:2} | 67.9 | ||
| 3 scales, 1 ratio | 1:1 | 69.8 | |
| 3 scales, 3 ratios | {2:1, 1:1, 1:2} | 69.9 |
TABLE VIII: Detection results of Faster R-CNN on PASCAL VOC 2007 test set using different settings of anchors. The network is VGG-16. The training data is VOC 2007 trainval. The default setting of using 3 scales and 3 aspect ratios (69.9%) is the same as that in Table III.
| 设置 | 锁定天平 | 纵横比 | mAP (%) |
|---|---|---|---|
| 1级,1级比率 | 1:1 (中文(简体) ). | 65.8 | |
| 1:1 (中文(简体) ). | 66.7 | ||
| 1个比额表,3个比率 | {2: 1,的目的是1: 1,1: 2} | 68.8 | |
| {2: 1,的目的是1: 1,1: 2} | 67.9 | ||
| 3个比额表,1个比率 | 1:1 (中文(简体) ). | ** 第69.8段** | |
| 3个比额表、3个比率 | {2: 1, 1: 1, 1: 2} (中文(简体) ). | 页:1 |
表八:使用不同的锚框设置对2007年PASCAL VOC测试集进行快速R-CNN检测结果。 网络为VGG-16. 培训数据为VOC 2007 trainval. 采用3个比例和3个方面比率(69.9%)的默认设定与表三相同。
| 0.1 | 1 | 10 | 100 | |
|---|---|---|---|---|
| mAP (%) | 67.2 | 68.9 | 69.9 | 69.1 |
TABLE IX: Detection results of Faster R-CNN on PASCAL VOC 2007 test set using different values of in Equation (1). The network is VGG-16. The training data is VOC 2007 trainval. The default setting of using (69.9%) is the same as that in Table III.
| 0.1 | 1 | 10 | 100 | |
|---|---|---|---|---|
| mAP (%) | 67.2 | 68.9 | 69.9 | 69.1 |
表九闺门:在PASCAL VOC 2007测试集上使用** **的异值的检测结果(1)。 网络为VGG-16. 培训数据为VOC 2007 trainval. 使用(69.9%)的默认设置与表三中的设置相同.
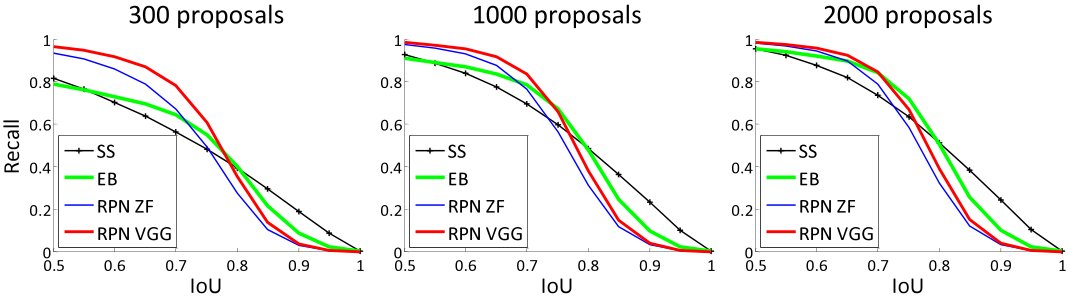
Fig. 4: Recall vs. IoU overlap ratio on the PASCAL VOC 2007 test set.
图4:回顾vs. IoU在PASCAL VOC 2007测试集上的重叠比.
| proposals | detector | mAP (%) | ||
|---|---|---|---|---|
| Two-Stage | RPN + ZF, unshared | 300 | Fast R-CNN + ZF, 1 scale | 58.7 |
| One-Stage | dense, 3 scales, 3 aspect ratios | 20000 | Fast R-CNN + ZF, 1 scale | 53.8 |
| One-Stage | dense, 3 scales, 3 aspect ratios | 20000 | Fast R-CNN + ZF, 5 scales | 53.9 |
TABLE X: One-Stage Detection vs. Two-Stage Proposal + Detection. Detection results are on the PASCAL VOC 2007 test set using the ZF model and Fast R-CNN. RPN uses unshared features.
| 建议 | 探测器 | mAP (%) | ||
|---|---|---|---|---|
| 双层 | RPN + ZF, 未分摊 | 300 | 快速 R-CNN + ZF, 1 级 | 58.7 |
| 单层 | 密度、3个尺度、3个方面比率 | 20000 | 快速 R-CNN + ZF, 1 级 | 53.8 |
| 单层 | 密度、3个尺度、3个方面比率 | 20000 | 快速 R-CNN + ZF, 5 级 | 53.9 |
表十:** 单阶检测 *vs *. 双阶建议+检测. 检测结果在使用ZF模型和快速R-CNN的PASCAL VOC 2007测试集上. RPN使用未共享的特性。 **
Sensitivities to Hyper-parameters. In Table VIII we investigate the settings of anchors. By default we use 3 scales and 3 aspect ratios (69.9% mAP in Table VIII). If using just one anchor at each position, the mAP drops by a considerable margin of 3-4%. The mAP is higher if using 3 scales (with 1 aspect ratio) or 3 aspect ratios (with 1 scale), demonstrating that using anchors of multiple sizes as the regression references is an effective solution. Using just 3 scales with 1 aspect ratio (69.8%) is as good as using 3 scales with 3 aspect ratios on this dataset, suggesting that scales and aspect ratios are not disentangled dimensions for the detection accuracy. But we still adopt these two dimensions in our designs to keep our system flexible.
** 对超参数的敏感性。 ** 在表八中,我们调查锚的设置。 默认情况下,我们使用3个尺度和3个方面的比例(表八中69.9%的mAP)。 如果每个位置只使用一个锚,mAP会下降相当的3%-4%. 如果使用3个尺度(带有1个侧面比)或3个尺寸比(带有1个尺度),mAP会更高,表明使用多尺寸锚作为回归参考是一个有效的解决方案. 使用只有3个比分,1个比分(69.8%),与使用3个比分,3个比分在本数据集中一样好,说明比分和比分对于检测精度来说并不是分散的比分. 但是,我们仍然在设计中采纳这两个方面,以保持我们的系统的灵活性.
In Table IX we compare different values of in Equation (1). By default we use which makes the two terms in Equation (1) roughly equally weighted after normalization. Table IX shows that our result is impacted just marginally (by ) when is within a scale of about two orders of magnitude (1 to 100). This demonstrates that the result is insensitive to in a wide range.
在表九中,我们比较了方程式(1)中的的不同值。 默认情况下,我们使用,使方程式(1)中的两个术语在正常化后大致相等加权。 表九显示,当在大约两个数量级(1至100个)范围内时,我们的结果只是受到轻微的影响(由)。 这表明,这一结果对有广泛的不敏感。
Analysis of Recall-to-IoU. Next we compute the recall of proposals at different IoU ratios with ground-truth boxes. It is noteworthy that the Recall-to-IoU metric is just loosely [19, 20, 21] related to the ultimate detection accuracy. It is more appropriate to use this metric to diagnose the proposal method than to evaluate it.
** 对《召回规则》的分析。 ** 接下来,我们用地面-事实资料框计算不同IoU比率的提案的召回。 值得注意的是,“召回”至“IoU”的度量标准只是与最终检测准确性有关的“低度”[19、20、21]。 使用这一衡量标准来分析建议方法比评价建议方法更为恰当。
In Figure 4, we show the results of using 300, 1000, and 2000 proposals. We compare with SS and EB, and the proposals are the top- ranked ones based on the confidence generated by these methods. The plots show that the RPN method behaves gracefully when the number of proposals drops from 2000 to 300. This explains why the RPN has a good ultimate detection mAP when using as few as 300 proposals. As we analyzed before, this property is mainly attributed to the cls term of the RPN. The recall of SS and EB drops more quickly than RPN when the proposals are fewer.
在图4中,我们显示了使用300、1000和2000年提案的结果。 我们与SS和EB比较,提案是根据这些方法产生的信心排名最高的-提案. 这些图案表明,当提案数目从2000年下降到300个时,RPN方法表现优雅。 这解释了为什么RPN在使用多达300个提案时有一个良好的最终检测mAP. 正如我们之前分析的那样,这种财产主要归结于RPN的cls名词. 党卫军和EB的召回比RPN在提案较少的时候下降得更快.
One-Stage Detection vs. Two-Stage Proposal + Detection. The OverFeat paper [9] proposes a detection method that uses regressors and classifiers on sliding windows over convolutional feature maps. OverFeat is a one-stage, class-specific detection pipeline, and ours is a two-stage cascade consisting of class-agnostic proposals and class-specific detections. In OverFeat, the region-wise features come from a sliding window of one aspect ratio over a scale pyramid. These features are used to simultaneously determine the location and category of objects. In RPN, the features are from square (33) sliding windows and predict proposals relative to anchors with different scales and aspect ratios. Though both methods use sliding windows, the region proposal task is only the first stage of Faster R-CNN—the downstream Fast R-CNN detector attends to the proposals to refine them. In the second stage of our cascade, the region-wise features are adaptively pooled [1, 2] from proposal boxes that more faithfully cover the features of the regions. We believe these features lead to more accurate detections.
** OverFeat 纸张[9] 提出了一种检测方法,在滑动的窗口上使用折叠器和分类器来覆盖卷积特征图。 OverFeat是一个单级,级特异性检测管道,我们的是一个双级级级,由级-不可知性建议和级特异性检测组成. 在OverFeat中,区域特点来自规模金字塔上一个侧面比的滑动窗口。 这些特征用于同时确定物体的位置和类别. 在RPN中,这些特性来自正方形(33)滑动窗口,并预测相对于具有不同尺度和侧面比的锚点的建议. 虽然这两种方法都使用滑动窗口,但区域提议任务只是快速R-CNN的第一阶段,即下游快速R-CNN探测器* 注意完善这些窗口的提案。 在我们的级联的第二阶段,区域特点从提案框中适应性地集合[1、2],更忠实地涵盖各区域的特点。 我们认为这些特征导致了更准确的检测.
To compare the one-stage and two-stage systems, we emulate the OverFeat system (and thus also circumvent other differences of implementation details) by one-stage Fast R-CNN. In this system, the “proposals” are dense sliding windows of 3 scales (128, 256, 512) and 3 aspect ratios (1:1, 1:2, 2:1). Fast R-CNN is trained to predict class-specific scores and regress box locations from these sliding windows. Because the OverFeat system adopts an image pyramid, we also evaluate using convolutional features extracted from 5 scales. We use those 5 scales as in [1, 2].
为了比较一个阶段和两个阶段的系统,我们用一个阶段 * 快速R-CNN 来模拟 OverFeat 系统(从而避免实现细节上的其他差异)。 在这个系统中,“建议”是密集的滑动窗口,有3个比例(128、256、512)和3个侧面比例(1:1、1:2、2:1)。 Fast R-CNN接受过从这些滑动窗口预测特定类分数和递归框位置的训练. 因为OverFeat系统采用了一个图像金字塔,我们也利用从5个尺度提取的卷积特征来评价. 我们使用这5个秤像[1、2]。
Table X compares the two-stage system and two variants of the one-stage system. Using the ZF model, the one-stage system has an mAP of 53.9%. This is lower than the two-stage system (58.7%) by 4.8%. This experiment justifies the effectiveness of cascaded region proposals and object detection. Similar observations are reported in [2, 39], where replacing SS region proposals with sliding windows leads to 6% degradation in both papers. We also note that the one-stage system is slower as it has considerably more proposals to process.
表X比较了两阶段制和两阶段制的变体. 采用ZF模式,单级系统拥有53.9%的mAP. 这比两级系统(58.7%)低4.8%。 这一试验证明级联区域提议和物体检测的有效性是合理的。 在[2,39]中也报告了类似的观测结果,在这两份文件中,用滑动窗口取代党卫军区域提议会导致退化6%。 我们还注意到,单阶段系统的速度较慢,因为它有相当多的处理建议。
| COCO val | COCO test-dev | |||||
|---|---|---|---|---|---|---|
| method | proposals | training data | mAP@.5 | mAP@[.5, .95] | mAP@.5 | mAP@[.5, .95] |
| Fast R-CNN [2] | SS, 2000 | COCO train | - | - | 35.9 | 19.7 |
| Fast R-CNN [impl. in this paper] | SS, 2000 | COCO train | 38.6 | 18.9 | 39.3 | 19.3 |
| Faster R-CNN | RPN, 300 | COCO train | 41.5 | 21.2 | 42.1 | 21.5 |
| Faster R-CNN | RPN, 300 | COCO trainval | - | - | 42.7 | 21.9 |
TABLE XI: Object detection results (%) on the MS COCO dataset. The model is VGG-16.
| COCO 华尔 | 几句说句 | |||||
|---|---|---|---|---|---|---|
| 方法 | 建议 | 培训数据 | mAP@.5 移动 | mAP@[5.95] (中文(简体) ). | mAP@.5 移动 | mAP@[5.95] (中文(简体) ). |
| 快R-CNN [2] (中文(简体) ). | SS, 2000 | COCO列车 | - | - | 35.9 | 19.7 |
| Fast R-CNN [本文中的简 | SS, 2000 | COCO列车 | 38.6 | 18.9 | 39.3 | 19.3 |
| . | 计生网,300 | COCO列车 | 41.5 | 21.2 | 42.1 | 21.5 |
| 更快 原来是R-CNN | 计生网,300 | COCO 列车 | - | - | ** 42.7 ** | 页:1 |
表十一:MS COCO数据集的物体检测结果(%). 该型号为VGG-16.
IV-B Experiments on MS COCO
IV-B MS COCO 上的实验
We present more results on the Microsoft COCO object detection dataset [12]. This dataset involves 80 object categories. We experiment with the 80k images on the training set, 40k images on the validation set, and 20k images on the test-dev set. We evaluate the mAP averaged for IoU (COCO’s standard metric, simply denoted as mAP@[.5, .95]) and mAP@0.5 (PASCAL VOC’s metric).
我们在微软COCO对象检测数据集上给出了更多结果[12]. 本数据集涉及80个对象类别. 我们在训练集上试验了80k图像,在验证集上试验了40k图像,在测试-dev集上试验了20k图像. 我们评价IoU (COCO标准度量,仅指mAP@[5..95])和mAP@0.5(PASCAL VOC的度量)的平均mAP。
There are a few minor changes of our system made for this dataset. We train our models on an 8-GPU implementation, and the effective mini-batch size becomes 8 for RPN (1 per GPU) and 16 for Fast R-CNN (2 per GPU). The RPN step and Fast R-CNN step are both trained for 240k iterations with a learning rate of 0.003 and then for 80k iterations with 0.0003. We modify the learning rates (starting with 0.003 instead of 0.001) because the mini-batch size is changed. For the anchors, we use 3 aspect ratios and 4 scales (adding ), mainly motivated by handling small objects on this dataset. In addition, in our Fast R-CNN step, the negative samples are defined as those with a maximum IoU with ground truth in the interval of , instead of used in [1, 2]. We note that in the SPPnet system [1], the negative samples in are used for network fine-tuning, but the negative samples in are still visited in the SVM step with hard-negative mining. But the Fast R-CNN system [2] abandons the SVM step, so the negative samples in are never visited. Including these samples improves mAP@0.5 on the COCO dataset for both Fast R-CNN and Faster R-CNN systems (but the impact is negligible on PASCAL VOC).
我们的系统为这个数据集做了一些小的改变。 我们用8GPU执行来训练我们的模型,有效的小批量大小变为RPN的8(每GPU1)和快速R-CNN的16(每GPU2). RPN步骤和快速R-CNN步骤都为240k的迭代训练,学习率为0.003,然后为80k的迭代训练为0.0003. 我们修改学习率(从0.003开始,而不是从0.001开始),因为小批量大小有所改变。 对于锚,我们使用3个侧面比和4个秤(添加),主要动机是处理本数据集中的小对象. 此外,在我们快速R-CNN步骤中,阴性样品被定义为在的间隔中具有地面真伪的最大IOU,而不是在[1,2]中使用的. 我们注意到,在SPPnet系统[1]中,中的阴性样品被用于网络微调,但中的阴性样品仍然在SVM步骤中以硬阴性开采进行访问. 但快速R-CNN系统[2]放弃了SVM步骤,因此中的负样品从未被访问. 包括这些样本,改进了快速R-CNN和更快R-CNN系统COCO数据集上的mAP@0.5(但对PASCAL VOC的影响可忽略不计)。
The rest of the implementation details are the same as on PASCAL VOC. In particular, we keep using 300 proposals and single-scale () testing. The testing time is still about 200ms per image on the COCO dataset.
其余的实现细节与PASCAL VOC相同。 特别是,我们继续使用300项提案和单一规模()测试。 COCO数据集上每张图像的测试时间仍然约为200ms.
In Table XI we first report the results of the Fast R-CNN system [2] using the implementation in this paper. Our Fast R-CNN baseline has 39.3% mAP@0.5 on the test-dev set, higher than that reported in [2]. We conjecture that the reason for this gap is mainly due to the definition of the negative samples and also the changes of the mini-batch sizes. We also note that the mAP@[.5, .95] is just comparable.
在表十一中,我们首先利用本文件中的执行情况报告快速R-CNN系统的结果[2]。 我们的快速R-CNN基线在测试-dev集上为39.3%mAP@0.5,高于[2]中的报告. 我们推测,造成这一差距的原因主要是对负标本的定义以及小批量尺寸的变化. 我们还注意到,mAP@[5..95]只是可比较的。
Next we evaluate our Faster R-CNN system. Using the COCO training set to train, Faster R-CNN has 42.1% mAP@0.5 and 21.5% mAP@[.5, .95] on the COCO test-dev set. This is 2.8% higher for mAP@0.5 and 2.2% higher for mAP@[.5, .95] than the Fast R-CNN counterpart under the same protocol (Table XI). This indicates that RPN performs excellent for improving the localization accuracy at higher IoU thresholds. Using the COCO trainval set to train, Faster R-CNN has 42.7% mAP@0.5 and 21.9% mAP@[.5, .95] on the COCO test-dev set. Figure 6 shows some results on the MS COCO test-dev set.
接下来我们评价我们的快速R-CNN系统. 使用COCO训练集进行训练,更快的R-CNN在COCO测试-dev集上拥有42.1%的mAP@0.5和21.5%的mAP@[5..95]. 这比MAP@0.5高2.8%,而MAP@[5..95]比同一协议下的快速R-CNN对应方高2.2%(表十一)。 这表明RPN在提高IoU阈值的定位精度方面表现优异. 使用COCO列车集进行列车,快速R-CNN在COCO测试-dev集上拥有42.7%的mAP@0.5和21.9%的mAP@[5..95]. 图6显示了MS COCO测试-dev集的一些结果.
Faster R-CNN in ILSVRC & COCO 2015 competitions We have demonstrated that Faster R-CNN benefits more from better features, thanks to the fact that the RPN completely learns to propose regions by neural networks. This observation is still valid even when one increases the depth substantially to over 100 layers [18]. Only by replacing VGG-16 with a 101-layer residual net (ResNet-101) [18], the Faster R-CNN system increases the mAP from 41.5%/21.2% (VGG-16) to 48.4%/27.2% (ResNet-101) on the COCO val set. With other improvements orthogonal to Faster R-CNN, He et al. [18] obtained a single-model result of 55.7%/34.9% and an ensemble result of 59.0%/37.4% on the COCO test-dev set, which won the 1st place in the COCO 2015 object detection competition. The same system [18] also won the 1st place in the ILSVRC 2015 object detection competition, surpassing the second place by absolute 8.5%. RPN is also a building block of the 1st-place winning entries in ILSVRC 2015 localization and COCO 2015 segmentation competitions, for which the details are available in [18] and [15] respectively.
** 在ILSVRC & COCO 2015比赛中较快的R-CNN** 我们已经表明,由于RPN完全学会通过神经网络提出区域提议,更快的R-CNN从更好的特征中获益更多. 即使将深度大幅提高到100多层[18],这一观察仍然有效。 只有用101层的剩余网(ResNet-101)[18]来取代VGG-16,更快的R-CNN系统才能将COCO val集的mAP从41.5%/21.2%(VGG-16)增加到48.4%/27.2%(ResNet-101). 随着其他的改进正统到更快的R-CNN,He *et al. [18]在COCO测试-dev集上获得了55.7%/34.9%的单型结果和59.0%/37.4%的综艺结果,后者在COCO2015对象检测比赛中获得了第1名. 同一系统[18]在ILSVRC2015天体探测比赛中也获得了第1名,以绝对8.5%的成绩超过了第二名. RPN也是ILSVRC2015本地化和COCO2015分区化比赛中第1位获胜条目的构件,其细节分别见于[18]和[15].
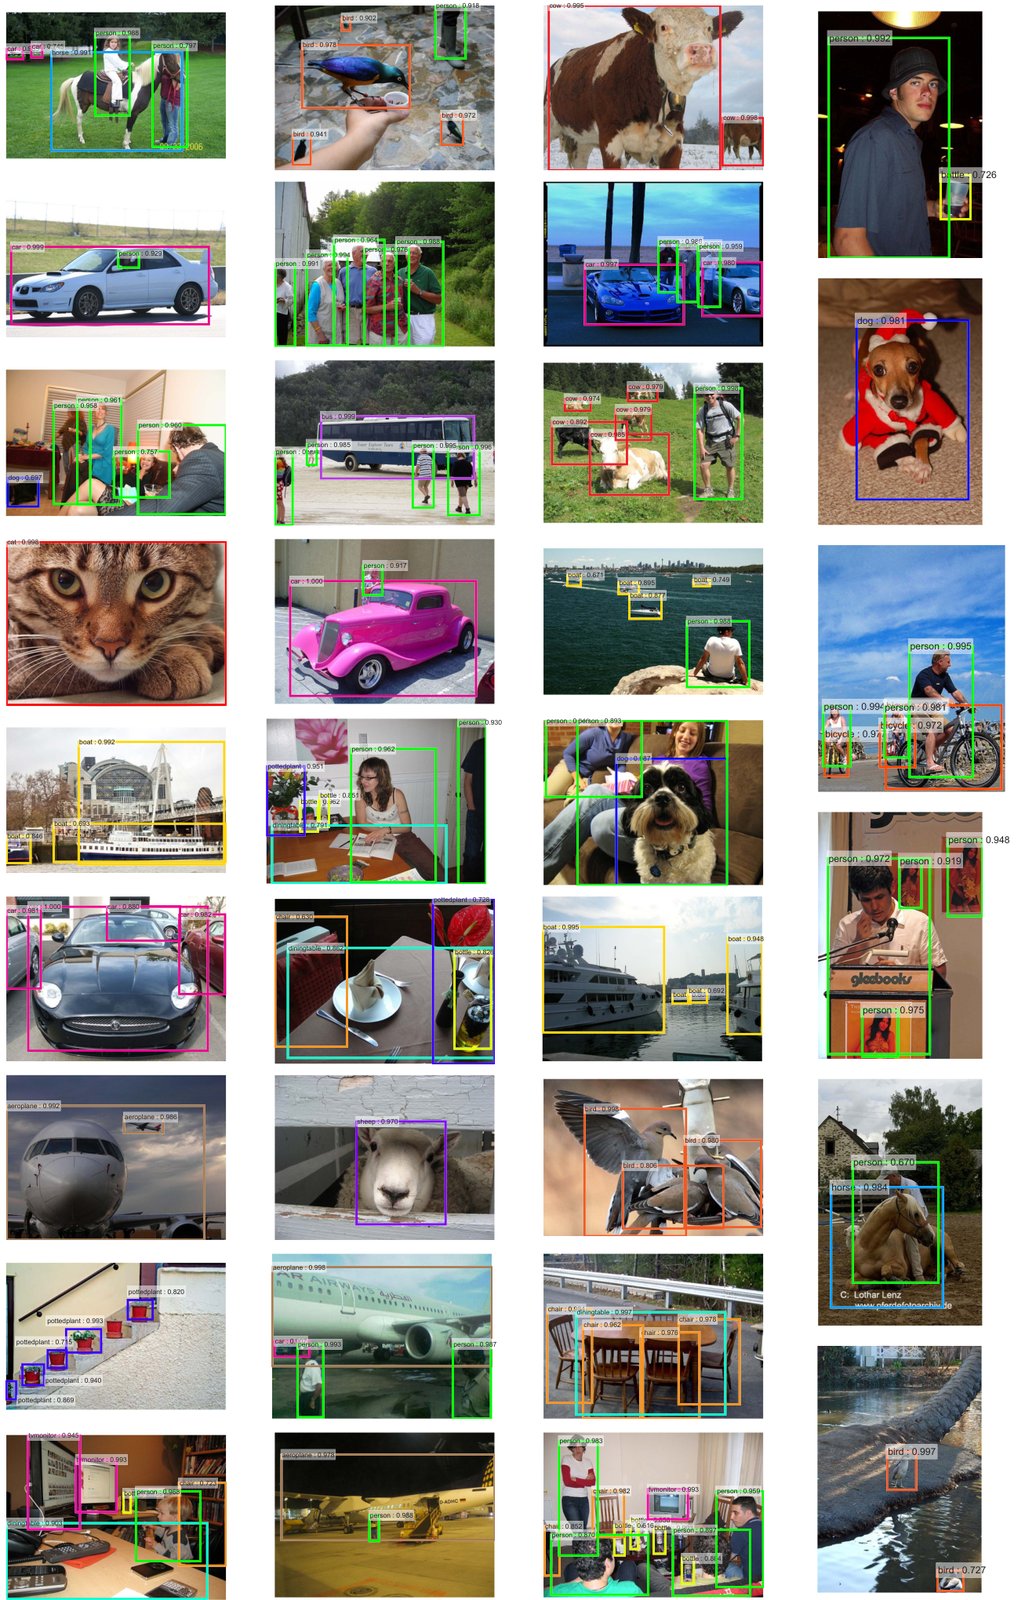
Fig. 5: Selected examples of object detection results on the PASCAL VOC 2007 test set using the Faster R-CNN system. The model is VGG-16 and the training data is 07+12 trainval (73.2% mAP on the 2007 test set). Our method detects objects of a wide range of scales and aspect ratios. Each output box is associated with a category label and a softmax score in . A score threshold of 0.6 is used to display these images. The running time for obtaining these results is 198ms per image, including all steps.
费格。 5: PASCAL VOC 2007测试集上使用更快R-CNN系统的物体检测结果选例. 该型号为VGG-16,训练数据为07+12列车val(2007年测试集上为73.2%mAP). 我们的方法探测到各种尺度和方格比的物体。 每个输出框与一个类别标签和中的软max分数相关. 使用0.6的分数阈值来显示这些图像. 获得这些结果的运行时间是198ms每个图像,包括所有步骤。
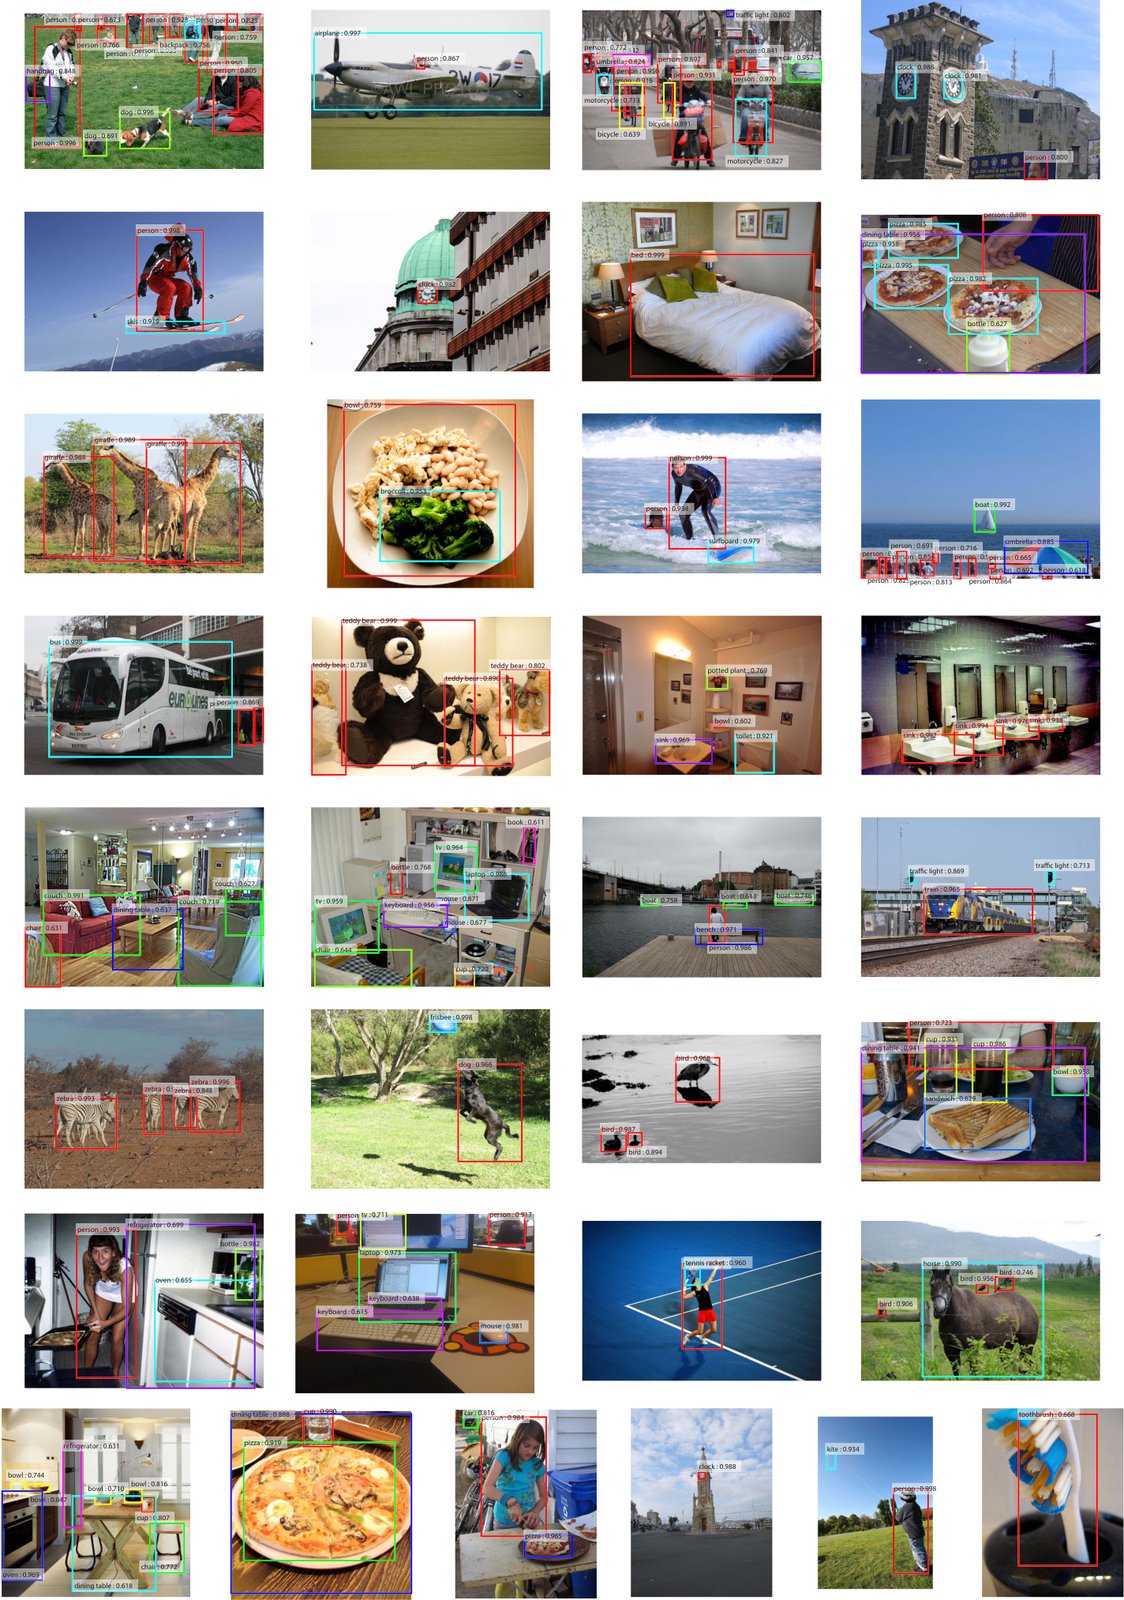
Fig. 6: Selected examples of object detection results on the MS COCO test-dev set using the Faster R-CNN system. The model is VGG-16 and the training data is COCO trainval (42.7% mAP@0.5 on the test-dev set). Each output box is associated with a category label and a softmax score in . A score threshold of 0.6 is used to display these images. For each image, one color represents one object category in that image.
费格。 6:使用更快的R-CNN系统在MS COCO测试-dev集上检测对象结果的一些实例. 该型号为VGG-16,培训数据为COCO列车(42.这方面的工作率为mAP@0.5于测试-dev集). 每个输出框与一个类别标签和中的软max分数相关. 使用0.6的分数阈值来显示这些图像. 对于每个图像,一个颜色代表该图像中的一个对象类别.
IV-C From MS COCO to PASCAL VOC
IV-C 从 MS COCO 到 PASCAL VOC
| training data | 2007 test | 2012 test |
|---|---|---|
| VOC07 | 69.9 | 67.0 |
| VOC07+12 | 73.2 | - |
| VOC07++12 | - | 70.4 |
| COCO (no VOC) | 76.1 | 73.0 |
| COCO+VOC07+12 | 78.8 | - |
| COCO+VOC07++12 | - | 75.9 |
TABLE XII: Detection mAP (%) of Faster R-CNN on PASCAL VOC 2007 test set and 2012 test set using different training data. The model is VGG-16. “COCO” denotes that the COCO trainval set is used for training. See also Table VI and Table VII.
| 培训数据 | 2007年测试 | 2012年测试 |
|---|---|---|
| VOC07 请检查url=值 (帮助). | 69.9 | 67.0 |
| VOC07+12 (韩语). | 73.2 | - |
| VOC07++12 维基月球 | - | 70.4 |
| COCO( 无VOC) | 76.1 | 73.0 |
| CO 麦加VOC07+12 | 页:1 | - |
| COCO+VOC07++12 (韩语). | - | 页:1 |
表十二:使用不同培训数据在PASCAL VOC 2007测试集和2012测试集上检测更快R-CNN的mAP(%). 该型号为VGG-16. “COCO”表示COCO列车组用于培训. 另见表六和表七。
Large-scale data is of crucial importance for improving deep neural networks. Next, we investigate how the MS COCO dataset can help with the detection performance on PASCAL VOC.
大规模数据对于改善深层神经网络至关重要。 接下来,我们调查MS COCO数据集如何帮助PASCAL VOC上的检测性能.
As a simple baseline, we directly evaluate the COCO detection model on the PASCAL VOC dataset, without fine-tuning on any PASCAL VOC data. This evaluation is possible because the categories on COCO are a superset of those on PASCAL VOC. The categories that are exclusive on COCO are ignored in this experiment, and the softmax layer is performed only on the 20 categories plus background. The mAP under this setting is 76.1% on the PASCAL VOC 2007 test set (Table XII). This result is better than that trained on VOC07+12 (73.2%) by a good margin, even though the PASCAL VOC data are not exploited.
作为简单的基线,我们直接评价PASCAL VOC数据集上的COCO检测模型,* 不对任何PASCAL VOC数据进行微调*. 这一评价之所以可能,是因为COCO上的类别是PASCAL VOC上的一类。 本实验中忽略了COCO独占的类别,软马克斯层只在20个类别加背景上进行. 该设置下的mAP在PASCAL VOC 2007测试集(表十二)上为76.1%. 这一结果比VOC07+12(73.2%)培训的结果要好,尽管PASCAL VOC数据没有被利用。
Then we fine-tune the COCO detection model on the VOC dataset. In this experiment, the COCO model is in place of the ImageNet-pre-trained model (that is used to initialize the network weights), and the Faster R-CNN system is fine-tuned as described in Section III-B. Doing so leads to 78.8% mAP on the PASCAL VOC 2007 test set. The extra data from the COCO set increases the mAP by 5.6%. Table VI shows that the model trained on COCO+VOC has the best AP for every individual category on PASCAL VOC 2007. Similar improvements are observed on the PASCAL VOC 2012 test set (Table XII and Table VII). We note that the test-time speed of obtaining these strong results is still about 200ms per image.
然后微调VOC数据集上的COCO检测模型. 在这个秃鹰实验中,COCO模型取代ễار البر الدير الدي الدي العري الدي العدي الدي الدي الدي العي الدي الدي العي الدي الدي الدي الدي الري الرارار الماري الدي الدارار الداري الداري ارار ار اري ال اري ال ال اريدي ال ال اري ال ال ال ال ال ال ال ال ال ال ال ال ال ال ال اري ال ال ال ا ا 这样一来,2007年PASAL VOC测试集的mAP就达到了78.8%. COCO集的额外数据使mAP增加了5.6%. 表六显示,经过COCO+VOC培训的模型对2007年PASCAL VOC的每个个人类别都有最好的AP. 在PASCAL VOC 2012测试集(表十二和表七)中也观察到类似的改进。 我们注意到,获得这些强效结果的试验时间速度仍然大约为每个图像200ms。
V Conclusion
V 结论
We have presented RPNs for efficient and accurate region proposal generation. By sharing convolutional features with the down-stream detection network, the region proposal step is nearly cost-free. Our method enables a unified, deep-learning-based object detection system to run at near real-time frame rates. The learned RPN also improves region proposal quality and thus the overall object detection accuracy.
我们提出了区域方案网络,以便有效和准确地提出区域提议。 通过与下游检测网络共享卷积特征,区域提议步骤几乎是免费的. 我们的方法使得一个统一、深度学习的物体检测系统能够以接近实时帧率运行。 所学的RPN还提高了区域提议书的质量,从而提高了整体对象检测的准确性.
References
参考文献
(1) K. He, X. Zhang, S. Ren, and J. Sun, “Spatial pyramid pooling in deep convolutional networks for visual recognition,” in European Conference on Computer Vision (ECCV) , 2014.
(2) R. Girshick, “Fast R-CNN,” in IEEE International Conference on Computer Vision (ICCV) , 2015.
(3) K. Simonyan and A. Zisserman, “Very deep convolutional networks for large-scale image recognition,” in International Conference on Learning Representations (ICLR) , 2015.
(4) J. R. Uijlings, K. E. van de Sande, T. Gevers, and A. W. Smeulders, “Selective search for object recognition,” International Journal of Computer Vision (IJCV) , 2013.
(5) R. Girshick, J. Donahue, T. Darrell, and J. Malik, “Rich feature hierarchies for accurate object detection and semantic segmentation,” in IEEE Conference on Computer Vision and Pattern Recognition (CVPR) , 2014.
(6) C. L. Zitnick and P. Dollár, “Edge boxes: Locating object proposals from edges,” in European Conference on Computer Vision (ECCV) , 2014.
(7) J. Long, E. Shelhamer, and T. Darrell, “Fully convolutional networks for semantic segmentation,” in IEEE Conference on Computer Vision and Pattern Recognition (CVPR) , 2015.
(8) P. F. Felzenszwalb, R. B. Girshick, D. McAllester, and D. Ramanan, “Object detection with discriminatively trained part-based models,” IEEE Transactions on Pattern Analysis and Machine Intelligence (TPAMI) , 2010.
(9) P. Sermanet, D. Eigen, X. Zhang, M. Mathieu, R. Fergus, and Y. LeCun, “Overfeat: Integrated recognition, localization and detection using convolutional networks,” in International Conference on Learning Representations (ICLR) , 2014.
(10) S. Ren, K. He, R. Girshick, and J. Sun, “Faster R-CNN: Towards real-time object detection with region proposal networks,” in Neural Information Processing Systems (NIPS) , 2015.
(11) M. Everingham, L. Van Gool, C. K. I. Williams, J. Winn, and A. Zisserman, “The PASCAL Visual Object Classes Challenge 2007 (VOC2007) Results,” 2007.
(12) T.-Y. Lin, M. Maire, S. Belongie, J. Hays, P. Perona, D. Ramanan, P. Dollár, and C. L. Zitnick, “Microsoft COCO: Common Objects in Context,” in European Conference on Computer Vision (ECCV) , 2014.
(13) S. Song and J. Xiao, “Deep sliding shapes for amodal 3d object detection in rgb-d images,” arXiv:1511.02300 , 2015.
(14) J. Zhu, X. Chen, and A. L. Yuille, “DeePM: A deep part-based model for object detection and semantic part localization,” arXiv:1511.07131 , 2015.
(15) J. Dai, K. He, and J. Sun, “Instance-aware semantic segmentation via multi-task network cascades,” arXiv:1512.04412 , 2015.
(16) J. Johnson, A. Karpathy, and L. Fei-Fei, “Densecap: Fully convolutional localization networks for dense captioning,” arXiv:1511.07571 , 2015.
(17) D. Kislyuk, Y. Liu, D. Liu, E. Tzeng, and Y. Jing, “Human curation and convnets: Powering item-to-item recommendations on pinterest,” arXiv:1511.04003 , 2015.
(18) K. He, X. Zhang, S. Ren, and J. Sun, “Deep residual learning for image recognition,” arXiv:1512.03385 , 2015.
(19) J. Hosang, R. Benenson, and B. Schiele, “How good are detection proposals, really?” in British Machine Vision Conference (BMVC) , 2014.
(20) J. Hosang, R. Benenson, P. Dollár, and B. Schiele, “What makes for effective detection proposals?” IEEE Transactions on Pattern Analysis and Machine Intelligence (TPAMI) , 2015.
(21) N. Chavali, H. Agrawal, A. Mahendru, and D. Batra, “Object-Proposal Evaluation Protocol is ’Gameable’,” arXiv: 1505.05836 , 2015.
(22) J. Carreira and C. Sminchisescu, “CPMC: Automatic object segmentation using constrained parametric min-cuts,” IEEE Transactions on Pattern Analysis and Machine Intelligence (TPAMI) , 2012.
(23) P. Arbeláez, J. Pont-Tuset, J. T. Barron, F. Marques, and J. Malik, “Multiscale combinatorial grouping,” in IEEE Conference on Computer Vision and Pattern Recognition (CVPR) , 2014.
(24) B. Alexe, T. Deselaers, and V. Ferrari, “Measuring the objectness of image windows,” IEEE Transactions on Pattern Analysis and Machine Intelligence (TPAMI) , 2012.
(25) C. Szegedy, A. Toshev, and D. Erhan, “Deep neural networks for object detection,” in Neural Information Processing Systems (NIPS) , 2013.
(26) D. Erhan, C. Szegedy, A. Toshev, and D. Anguelov, “Scalable object detection using deep neural networks,” in IEEE Conference on Computer Vision and Pattern Recognition (CVPR) , 2014.
(27) C. Szegedy, S. Reed, D. Erhan, and D. Anguelov, “Scalable, high-quality object detection,” arXiv:1412.1441 (v1) , 2015.
(28) P. O. Pinheiro, R. Collobert, and P. Dollar, “Learning to segment object candidates,” in Neural Information Processing Systems (NIPS) , 2015.
(29) J. Dai, K. He, and J. Sun, “Convolutional feature masking for joint object and stuff segmentation,” in IEEE Conference on Computer Vision and Pattern Recognition (CVPR) , 2015.
(30) S. Ren, K. He, R. Girshick, X. Zhang, and J. Sun, “Object detection networks on convolutional feature maps,” arXiv:1504.06066 , 2015.
(31) J. K. Chorowski, D. Bahdanau, D. Serdyuk, K. Cho, and Y. Bengio, “Attention-based models for speech recognition,” in Neural Information Processing Systems (NIPS) , 2015.
(32) M. D. Zeiler and R. Fergus, “Visualizing and understanding convolutional neural networks,” in European Conference on Computer Vision (ECCV) , 2014.
(33) V. Nair and G. E. Hinton, “Rectified linear units improve restricted boltzmann machines,” in International Conference on Machine Learning (ICML) , 2010.
(34) C. Szegedy, W. Liu, Y. Jia, P. Sermanet, S. Reed, D. Anguelov, D. Erhan, and A. Rabinovich, “Going deeper with convolutions,” in IEEE Conference on Computer Vision and Pattern Recognition (CVPR) , 2015.
(35) Y. LeCun, B. Boser, J. S. Denker, D. Henderson, R. E. Howard, W. Hubbard, and L. D. Jackel, “Backpropagation applied to handwritten zip code recognition,” Neural computation , 1989.
(36) O. Russakovsky, J. Deng, H. Su, J. Krause, S. Satheesh, S. Ma, Z. Huang, A. Karpathy, A. Khosla, M. Bernstein, A. C. Berg, and L. Fei-Fei, “ImageNet Large Scale Visual Recognition Challenge,” in International Journal of Computer Vision (IJCV) , 2015.
(37) A. Krizhevsky, I. Sutskever, and G. Hinton, “Imagenet classification with deep convolutional neural networks,” in Neural Information Processing Systems (NIPS) , 2012.
(38) Y. Jia, E. Shelhamer, J. Donahue, S. Karayev, J. Long, R. Girshick, S. Guadarrama, and T. Darrell, “Caffe: Convolutional architecture for fast feature embedding,” arXiv:1408.5093 , 2014.
(39) K. Lenc and A. Vedaldi, “R-CNN minus R,” in British Machine Vision Conference (BMVC) , 2015.