FaceNet: A Unified Embedding for Face Recognition and Clustering
FaceNet: A Unified Embedding for Face Recognition and Clustering
FaceNet:用于人脸识别与聚类的统一嵌入
Abstract
摘要
Despite significant recent advances in the field of face recognition [10, 14, 15, 17], implementing face verification and recognition efficiently at scale presents serious challenges to current approaches. In this paper we present a system, called FaceNet, that directly learns a mapping from face images to a compact Euclidean space where distances directly correspond to a measure of face similarity. Once this space has been produced, tasks such as face recognition, verification and clustering can be easily implemented using standard techniques with FaceNet embeddings as feature vectors.
尽管人脸识别近年已有显著进展 [10, 14, 15, 17],但要在大规模场景下高效完成验证与识别,现有方法仍面临严峻挑战。本文提出名为 FaceNet 的系统:直接学习从人脸图像到紧凑欧氏空间的映射,使该空间中的距离本身就对应人脸相似度。得到这一空间之后,识别、验证和聚类都可以把 FaceNet 嵌入当作特征向量,用标准方法直接实现。
Our method uses a deep convolutional network trained to directly optimize the embedding itself, rather than an intermediate bottleneck layer as in previous deep learning approaches. To train, we use triplets of roughly aligned matching / non-matching face patches generated using a novel online triplet mining method. The benefit of our approach is much greater representational efficiency: we achieve state-of-the-art face recognition performance using only 128-bytes per face.
我们的方法用深度卷积网络直接优化嵌入本身,而不是像以往深度学习方法那样优化中间瓶颈层。训练时,我们用大致对齐的匹配 / 非匹配人脸块组成三元组,并由一种新的在线三元组挖掘方法生成。这样做的好处是表征效率高得多:每人脸只需 128 字节,就能达到当时最先进的人脸识别性能。
On the widely used Labeled Faces in the Wild (LFW) dataset, our system achieves a new record accuracy of 99.63%. On YouTube Faces DB it achieves 95.12%. Our system cuts the error rate in comparison to the best published result [15] by 30% on both datasets.
在广泛使用的 Labeled Faces in the Wild(LFW)数据集上,本系统取得了 99.63% 的新纪录准确率;在 YouTube Faces DB 上达到 95.12%。与当时最好的已发表结果 [15] 相比,两个数据集上的误差都降低了 30%。
1. Introduction
1. 引言
In this paper we present a unified system for face verification (is this the same person), recognition (who is this person) and clustering (find common people among these faces). Our method is based on learning a Euclidean embedding per image using a deep convolutional network. The network is trained such that the squared L2 distances in the embedding space directly correspond to face similarity: faces of the same person have small distances and faces of distinct people have large distances.
本文提出一套统一的系统,同时覆盖人脸验证(是不是同一个人)、识别(这是谁)和聚类(在这些脸里找出相同的人)。方法是用深度卷积网络为每张图像学习一个欧氏嵌入。网络的训练目标是:嵌入空间中的平方 L2 距离直接对应人脸相似度——同一人的脸距离小,不同人的脸距离大。
Once this embedding has been produced, then the aforementioned tasks become straight-forward: face verification simply involves thresholding the distance between the two embeddings; recognition becomes a k-NN classification problem; and clustering can be achieved using off-the-shelf techniques such as k-means or agglomerative clustering.
一旦得到这种嵌入,上述任务就变得直接:验证只需对两个嵌入的距离设阈值;识别变成 k 近邻分类;聚类则可用现成的 k-means 或层次聚类。
Previous face recognition approaches based on deep networks use a classification layer [15, 17] trained over a set of known face identities and then take an intermediate bottleneck layer as a representation used to generalize recognition beyond the set of identities used in training. The downsides of this approach are its indirectness and its inefficiency: one has to hope that the bottleneck representation generalizes well to new faces; and by using a bottleneck layer the representation size per face is usually very large (1000s of dimensions). Some recent work [15] has reduced this dimensionality using PCA, but this is a linear transformation that can be easily learnt in one layer of the network.
以往基于深度网络的人脸识别方法,先在一组已知身份上训练分类层 [15, 17],再取中间瓶颈层作为表征,希望它能泛化到训练时未见过的人。这条路的缺点是既间接又低效:只能指望瓶颈表征对新手脸仍然有效;而且用瓶颈层时,每人脸的表征维数通常很大(上千维)。近期工作 [15] 用 PCA 降过维,但那只是线性变换,完全可以在网络里用一层学到。
In contrast to these approaches, FaceNet directly trains its output to be a compact 128-D embedding using a triplet-based loss function based on LMNN [19]. Our triplets consist of two matching face thumbnails and a non-matching face thumbnail and the loss aims to separate the positive pair from the negative by a distance margin. The thumbnails are tight crops of the face area, no 2D or 3D alignment, other than scale and translation is performed.
与这些做法不同,FaceNet 直接把输出训成紧凑的 128 维嵌入,损失是基于 LMNN [19] 的三元组损失。每个三元组包含两张匹配的人脸缩略图和一张不匹配的缩略图,损失的目标是让正样本对与负样本之间隔开一段距离间隔。缩略图是人脸区域的紧裁,除尺度和平移外,不做二维或三维对齐。
Choosing which triplets to use turns out to be very important for achieving good performance and, inspired by curriculum learning [1], we present a novel online negative exemplar mining strategy which ensures consistently increasing difficulty of triplets as the network trains. To improve clustering accuracy, we also explore hard-positive mining techniques which encourage spherical clusters for the embeddings of a single person.
选哪些三元组,对最终性能非常关键。受课程学习 [1] 启发,我们提出一种新的在线负样本挖掘策略,让三元组的难度随着训练持续增加。为提高聚类准确率,我们还探索了难正样本挖掘,促使同一人的嵌入形成更接近球形的簇。
As an illustration of the incredible variability that our method can handle see Figure 1. Shown are image pairs from PIE [13] that previously were considered to be very difficult for face verification systems.
图 1 说明了本方法能够应对的巨大变化:图中是来自 PIE [13] 的图像对,以往被认为对人脸验证系统非常困难。
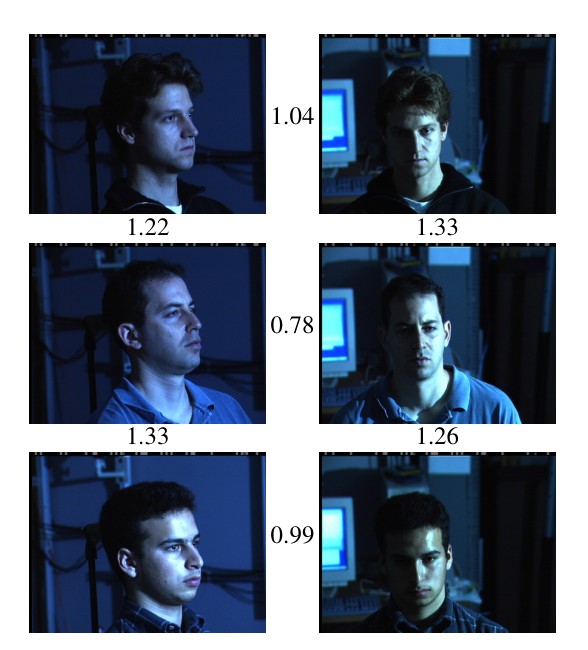
Figure 1. Illumination and Pose invariance. Pose and illumination have been a long standing problem in face recognition. This figure shows the output distances of FaceNet between pairs of faces of the same and a different person in different pose and illumination combinations. A distance of 0.0 means the faces are identical, 4.0 corresponds to the opposite spectrum, two different identities. You can see that a threshold of 1.1 would classify every pair correctly.
图 1. 光照与姿态不变性。姿态和光照一直是人脸识别里的老难题。本图给出 FaceNet 对同一人以及不同人、在不同姿态与光照组合下的输出距离。距离 0.0 表示两张脸完全相同,4.0 则位于另一端,对应两个不同身份。可以看出,阈值取 1.1 就能把每一对都分对。
An overview of the rest of the paper is as follows: in section 2 we review the literature in this area; section 3.1 defines the triplet loss and section 3.2 describes our novel triplet selection and training procedure; in section 3.3 we describe the model architecture used. Finally in section 4 and 5 we present some quantitative results of our embeddings and also qualitatively explore some clustering results.
后文安排如下:第 2 节回顾相关文献;第 3.1 节给出三元组损失的定义,第 3.2 节介绍我们的三元组选择与训练流程;第 3.3 节描述所用模型结构。最后在第 4、5 节给出嵌入的定量结果,并定性讨论一些聚类结果。
2. Related Work
2. 相关工作
Similarly to other recent works which employ deep networks [15, 17], our approach is a purely data driven method which learns its representation directly from the pixels of the face. Rather than using engineered features, we use a large dataset of labelled faces to attain the appropriate invariances to pose, illumination, and other variational conditions.
与其他使用深度网络的近期工作 [15, 17] 类似,我们的方法完全由数据驱动,直接从人脸像素学习表征。我们不用人工设计的特征,而是依靠大规模带标注人脸数据,来获得对姿态、光照及其他变化的适当不变性。
In this paper we explore two different deep network architectures that have been recently used to great success in the computer vision community. Both are deep convolutional networks [8, 11]. The first architecture is based on the Zeiler&Fergus [22] model which consists of multiple interleaved layers of convolutions, non-linear activations, local response normalizations, and max pooling layers. We additionally add several 1×1×d convolution layers inspired by the work of [9]. The second architecture is based on the Inception model of Szegedy et al. which was recently used as the winning approach for ImageNet 2014 [16]. These networks use mixed layers that run several different convolutional and pooling layers in parallel and concatenate their responses. We have found that these models can reduce the number of parameters by up to 20 times and have the potential to reduce the number of FLOPS required for comparable performance.
本文考察了计算机视觉界近期取得很大成功的两种深度网络结构,二者都是深度卷积网络 [8, 11]。第一种基于 Zeiler & Fergus [22] 模型,由卷积、非线性激活、局部响应归一化和最大池化多层交错组成。我们还依照 [9] 的思路,额外加入若干 1×1×d 卷积层。第二种基于 Szegedy 等人的 Inception 模型,也就是 ImageNet 2014 的获胜方案 [16]。这类网络用混合层并行运行多种卷积和池化,再把响应拼接起来。我们发现,这些模型最多可以把参数量降到原来的约二十分之一,并有潜力在相近性能下减少所需的浮点运算次数。
There is a vast corpus of face verification and recognition works. Reviewing it is out of the scope of this paper so we will only briefly discuss the most relevant recent work.
人脸验证与识别的文献非常多,全面综述超出本文范围,我们只简要讨论最相关的近期工作。
The works of [15, 17, 23] all employ a complex system of multiple stages, that combines the output of a deep convolutional network with PCA for dimensionality reduction and an SVM for classification.
[15, 17, 23] 这些工作都采用多阶段的复杂系统,把深度卷积网络的输出与用于降维的 PCA 和用于分类的 SVM 组合在一起。
Zhenyao et al. [23] employ a deep network to “warp” faces into a canonical frontal view and then learn CNN that classifies each face as belonging to a known identity. For face verification, PCA on the network output in conjunction with an ensemble of SVMs is used.
Zhenyao 等人 [23] 用深度网络把人脸“扭曲”到标准正面视角,再学习一个 CNN,把每张脸分到已知身份上。做人脸验证时,他们对网络输出做 PCA,再与一组 SVM 一起使用。
Taigman et al. [17] propose a multi-stage approach that aligns faces to a general 3D shape model. A multi-class network is trained to perform the face recognition task on over four thousand identities. The authors also experimented with a so called Siamese network where they directly optimize the L1-distance between two face features. Their best performance on LFW (97.35%) stems from an ensemble of three networks using different alignments and color channels. The predicted distances (non-linear SVM predictions based on the χ2 kernel) of those networks are combined using a non-linear SVM.
Taigman 等人 [17] 提出一种多阶段方法,把人脸对齐到通用三维形状模型上,并训练一个多类网络,在四千多个身份上做识别。作者还试验了所谓的孪生网络,直接优化两个人脸特征之间的 L1 距离。他们在 LFW 上的最好结果(97.35%)来自三个网络的集成,分别使用不同的对齐方式和颜色通道。这些网络给出的预测距离(基于 χ2 核的非线性 SVM 预测)再用一个非线性 SVM 加以组合。
Sun et al. [14, 15] propose a compact and therefore relatively cheap to compute network. They use an ensemble of 25 of these network, each operating on a different face patch. For their final performance on LFW (99.47% [15]) the authors combine 50 responses (regular and flipped). Both PCA and a Joint Bayesian model [2] that effectively correspond to a linear transform in the embedding space are employed. Their method does not require explicit 2D/3D alignment. The networks are trained by using a combination of classification and verification loss. The verification loss is similar to the triplet loss we employ [12, 19], in that it minimizes the L2-distance between faces of the same identity and enforces a margin between the distance of faces of different identities. The main difference is that only pairs of images are compared, whereas the triplet loss encourages a relative distance constraint.
Sun 等人 [14, 15] 提出一种紧凑、因而计算相对便宜的网络。他们把 25 个这样的网络集成起来,每个作用于不同的人脸块。最终在 LFW 上的结果(99.47% [15])来自 50 路响应的组合(原图与翻转)。他们同时使用了 PCA 和联合贝叶斯模型 [2],二者在嵌入空间中实际上都相当于线性变换。该方法不需要显式的二维或三维对齐。网络用分类损失和验证损失的组合来训练。其中的验证损失与我们采用的三元组损失 [12, 19] 相似:它缩小同一身份人脸的 L2 距离,并在不同身份的距离之间强制间隔。主要差别在于,他们只比较图像对,而三元组损失鼓励的是相对距离约束。
A similar loss to the one used here was explored in Wang et al. [18] for ranking images by semantic and visual similarity.
Wang 等人 [18] 也曾探索过与本文类似的损失,用于按语义和视觉相似度对图像排序。
3. Method
3. 方法
FaceNet uses a deep convolutional network. We discuss two different core architectures: The Zeiler&Fergus [22] style networks and the recent Inception [16] type networks. The details of these networks are described in section 3.3.
FaceNet 使用深度卷积网络。我们讨论两种核心结构:Zeiler & Fergus [22] 风格的网络,以及较新的 Inception [16] 类型网络。细节见第 3.3 节。
Given the model details, and treating it as a black box (see Figure 2), the most important part of our approach lies in the end-to-end learning of the whole system. To this end we employ the triplet loss that directly reflects what we want to achieve in face verification, recognition and clustering. Namely, we strive for an embedding , from an image into a feature space , such that the squared distance between all faces, independent of imaging conditions, of the same identity is small, whereas the squared distance between a pair of face images from different identities is large.
把模型细节当作黑箱(见图 2)来看,我们方法中最重要的部分,是对整套系统做端到端学习。为此我们采用三元组损失,它直接对应人脸验证、识别和聚类想要达成的目标。具体地说,我们希望得到嵌入 ,把图像 映射到特征空间 ,使得同一身份的所有人脸——不依赖于成像条件——平方距离都小,而不同身份的人脸图像对平方距离都大。
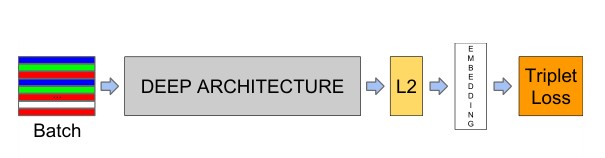
Figure 2. Model structure. Our network consists of a batch input layer and a deep CNN followed by L2 normalization, which results in the face embedding. This is followed by the triplet loss during training.
图 2. 模型结构。网络由批次输入层和深度 CNN 组成,再接 L2 归一化,得到人脸嵌入。训练时在此之后接三元组损失。
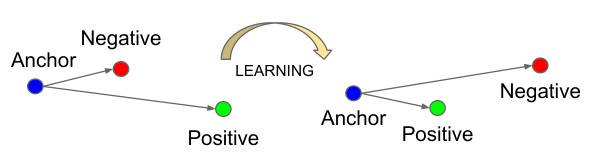
Figure 3. The Triplet Loss minimizes the distance between an anchor and a positive, both of which have the same identity, and maximizes the distance between the anchor and a negative of a different identity.
图 3. 三元组损失缩小锚点与同一身份正样本之间的距离,并拉大锚点与不同身份负样本之间的距离。
Although we did not a do direct comparison to other losses, e.g. the one using pairs of positives and negatives, as used in [14] Eq. (2), we believe that the triplet loss is more suitable for face verification. The motivation is that the loss from [14] encourages all faces of one identity to be “projected” onto a single point in the embedding space. The triplet loss, however, tries to enforce a margin between each pair of faces from one person to all other faces. This allows the faces for one identity to live on a manifold, while still enforcing the distance and thus discriminability to other identities.
我们并没有与其他损失做直接比较,例如 [14] 式 (2) 中那种使用正负样本对的损失,但我们认为三元组损失更适合人脸验证。原因是 [14] 的损失会鼓励把同一身份的所有脸“投影”到嵌入空间中的一个点;而三元组损失则试图在某个人的每一对脸与所有其他脸之间强制间隔。这样,同一身份的脸可以落在一个流形上,同时仍然保持与其他身份的距离,从而可分。
The following section describes this triplet loss and how it can be learned efficiently at scale.
下一节描述这一三元组损失,以及如何在大规模下高效学习它。
3.1. Triplet Loss
3.1. 三元组损失
The embedding is represented by . It embeds an image into a -dimensional Euclidean space. Additionally, we constrain this embedding to live on the -dimensional hypersphere, i.e. . This loss is motivated in [19] in the context of nearest-neighbor classification. Here we want to ensure that an image (anchor) of a specific person is closer to all other images (positive) of the same person than it is to any image (negative) of any other person. This is visualized in Figure 3.
嵌入记为 ,把图像 映射到 维欧氏空间。此外,我们约束嵌入落在 维超球面上,即 。这一损失在 [19] 中是从最近邻分类的角度提出的。在这里,我们希望某个人的图像 (锚点)到同一人所有其他图像 (正样本)的距离,都小于它到任何其他人的任何图像 (负样本)的距离。如图 3 所示。
Thus we want,
因此我们希望:
where is a margin that is enforced between positive and negative pairs. is the set of all possible triplets in the training set and has cardinality .
其中 是在正样本对与负样本对之间强制的间隔。 是训练集中所有可能三元组的集合,其基数为 。
The loss that is being minimized is then
于是要最小化的损失为
Generating all possible triplets would result in many triplets that are easily satisfied (i.e. fulfill the constraint in Eq. (1)). These triplets would not contribute to the training and result in slower convergence, as they would still be passed through the network. It is crucial to select hard triplets, that are active and can therefore contribute to improving the model. The following section talks about the different approaches we use for the triplet selection.
如果生成所有可能的三元组,其中会有许多很容易就被满足(即已经符合式 (1) 的约束)。这些三元组对训练没有贡献,却仍要过一遍网络,从而导致收敛变慢。关键是选出仍然活跃、因而能够改进模型的困难三元组。下一节讨论我们用于三元组选择的不同做法。
3.2. Triplet Selection
3.2. 三元组选择
In order to ensure fast convergence it is crucial to select triplets that violate the triplet constraint in Eq. (1). This means that, given , we want to select an (hard positive) such that and similarly (hard negative) such that .
为了保证快速收敛,必须选出违反式 (1) 中三元组约束的样本。也就是说,给定 ,我们希望选出 (难正样本),使得 ;类似地,选出 (难负样本),使得 。
It is infeasible to compute the argmin and argmax across the whole training set. Additionally, it might lead to poor training, as mislabelled and poorly imaged faces would dominate the hard positives and negatives. There are two obvious choices that avoid this issue:
在整个训练集上计算 argmin 和 argmax 并不可行。此外,这还可能导致训练变差,因为标错的脸和成像很差的脸会主导难正样本和难负样本。有两种显而易见的做法可以避开这个问题:
- Generate triplets offline every steps, using the most recent network checkpoint and computing the argmin and argmax on a subset of the data.
- 每 步离线生成三元组,使用最近的网络检查点,并在数据的一个子集上计算 argmin 和 argmax。
- Generate triplets online. This can be done by selecting the hard positive/negative exemplars from within a mini-batch.
- 在线生成三元组。做法是在一个小批量内部选择难正 / 难负样本。
Here, we focus on the online generation and use large mini-batches in the order of a few thousand exemplars and only compute the argmin and argmax within a mini-batch.
这里我们侧重在线生成,并使用大约数千个样本的大批次,只在小批量内部计算 argmin 和 argmax。
To have a meaningful representation of the anchor-positive distances, it needs to be ensured that a minimal number of exemplars of any one identity is present in each mini-batch. In our experiments we sample the training data such that around 40 faces are selected per identity per mini-batch. Additionally, randomly sampled negative faces are added to each mini-batch.
为了让锚点–正样本距离有意义,必须保证每个小批量里任一身份都至少有若干样本。实验中我们这样抽样:每个小批量里每个身份大约选 40 张脸,并再向每个小批量加入随机抽取的负样本脸。
Instead of picking the hardest positive, we use all anchor-positive pairs in a mini-batch while still selecting the hard negatives. We don't have a side-by-side comparison of hard anchor-positive pairs versus all anchor-positive pairs within a mini-batch, but we found in practice that the all anchor-positive method was more stable and converged slightly faster at the beginning of training.
我们并不只挑最难的正样本,而是使用小批量中所有锚点–正样本对,同时仍选择难负样本。我们没有在小批量内对“只使用困难锚点–正样本对”和“使用全部锚点–正样本对”做并排比较,但实践中发现,使用全部锚点–正样本对的方法更稳定,并且在训练初期收敛稍快。
We also explored the offline generation of triplets in conjunction with the online generation and it may allow the use of smaller batch sizes, but the experiments were inconclusive.
我们也探索过把离线生成与在线生成结合起来,这或许允许使用更小的批量,但实验结果并不确定。
Selecting the hardest negatives can in practice lead to bad local minima early on in training, specifically it can result in a collapsed model (i.e. ). In order to mitigate this, it helps to select such that
在训练早期选择最难的负样本,实践中可能导致糟糕的局部极小,具体来说,模型可能塌缩(即 )。为缓解这一点,选择满足下式的 会有帮助
We call these negative exemplars semi-hard, as they are further away from the anchor than the positive exemplar, but still hard because the squared distance is close to the anchor-positive distance. Those negatives lie inside the margin .
我们称这些负样本为半难样本:它们比正样本离锚点更远,但仍然困难,因为平方距离接近锚点–正样本距离。这些负样本落在间隔 之内。
As mentioned before, correct triplet selection is crucial for fast convergence. On the one hand we would like to use small mini-batches as these tend to improve convergence during Stochastic Gradient Descent (SGD) [20]. On the other hand, implementation details make batches of tens to hundreds of exemplars more efficient. The main constraint with regards to the batch size, however, is the way we select hard relevant triplets from within the mini-batches. In most experiments we use a batch size of around 1,800 exemplars.
如前所述,正确选择三元组对快速收敛至关重要。一方面,我们希望使用较小的小批量,因为这往往能改善随机梯度下降(SGD)[20] 的收敛;另一方面,实现细节又使数十到数百个样本的批量更高效。不过,批量大小的主要约束,还是我们如何从批次内部选出相关的困难三元组。大多数实验中,我们使用大约 1,800 个样本的批量。
3.3. Deep Convolutional Networks
3.3. 深度卷积网络
In all our experiments we train the CNN using Stochastic Gradient Descent (SGD) with standard backprop [8, 11] and AdaGrad [5]. In most experiments we start with a learning rate of 0.05 which we lower to finalize the model. The models are initialized from random, similar to [16], and trained on a CPU cluster for 1,000 to 2,000 hours. The decrease in the loss (and increase in accuracy) slows down drastically after 500h of training, but additional training can still significantly improve performance. The margin is set to 0.2.
所有实验中,我们都用标准反向传播 [8, 11] 配合随机梯度下降(SGD)以及 AdaGrad [5] 来训练 CNN。多数实验从学习率 0.05 开始,并在收尾时将其降低。模型按与 [16] 类似的方式随机初始化,在 CPU 集群上训练 1,000 到 2,000 小时。训练 500 小时之后,损失下降(以及准确率上升)会明显变慢,但继续训练仍能显著提高性能。间隔 设为 0.2。
We used two types of architectures and explore their trade-offs in more detail in the experimental section. Their practical differences lie in the difference of parameters and FLOPS. The best model may be different depending on the application. E.g. a model running in a datacenter can have many parameters and require a large number of FLOPS, whereas a model running on a mobile phone needs to have few parameters, so that it can fit into memory. All our models use rectified linear units as the non-linear activation function.
我们使用了两类结构,并在实验部分更细致地考察它们的取舍。实际差别主要在参数量和浮点运算次数。最佳模型可能随应用而不同。例如,跑在数据中心的模型可以有很多参数、需要大量浮点运算;跑在手机上的模型则必须参数很少,才能放进内存。我们所有模型都用整流线性单元作为非线性激活函数。
The first category, shown in Table 1, adds convolutional layers, as suggested in [9], between the standard convolutional layers of the Zeiler&Fergus [22] architecture and results in a model 22 layers deep. It has a total of 140 million parameters and requires around 1.6 billion FLOPS per image.
第一类如表 1 所示:在 Zeiler & Fergus [22] 结构的标准卷积层之间,按 [9] 的建议加入 卷积层,得到 22 层深的模型。它一共约有 1.4 亿参数,每张图大约需要 16 亿次浮点运算。
| layer | size-in | size-out | kernel | param | FLPS |
|---|---|---|---|---|---|
| conv1 | 220×220×3 | 110×110×64 | 7×7×3, 2 | 9K | 115M |
| pool1 | 110×110×64 | 55×55×64 | 3×3×64, 2 | 0 | |
| rnorm1 | 55×55×64 | 55×55×64 | 0 | ||
| conv2a | 55×55×64 | 55×55×64 | 1×1×64, 1 | 4K | 13M |
| conv2 | 55×55×64 | 55×55×192 | 3×3×64, 1 | 111K | 335M |
| rnorm2 | 55×55×192 | 55×55×192 | 0 | ||
| pool2 | 55×55×192 | 28×28×192 | 3×3×192, 2 | 0 | |
| conv3a | 28×28×192 | 28×28×192 | 1×1×192, 1 | 37K | 29M |
| conv3 | 28×28×192 | 28×28×384 | 3×3×192, 1 | 664K | 521M |
| pool3 | 28×28×384 | 14×14×384 | 3×3×384, 2 | 0 | |
| conv4a | 14×14×384 | 14×14×384 | 1×1×384, 1 | 148K | 29M |
| conv4 | 14×14×384 | 14×14×256 | 3×3×384, 1 | 885K | 173M |
| conv5a | 14×14×256 | 14×14×256 | 1×1×256, 1 | 66K | 13M |
| conv5 | 14×14×256 | 14×14×256 | 3×3×256, 1 | 590K | 116M |
| conv6a | 14×14×256 | 14×14×256 | 1×1×256, 1 | 66K | 13M |
| conv6 | 14×14×256 | 14×14×256 | 3×3×256, 1 | 590K | 116M |
| pool4 | 14×14×256 | 7×7×256 | 3×3×256, 2 | 0 | |
| concat | 7×7×256 | 7×7×256 | 0 | ||
| fc1 | 7×7×256 | 1×32×128 | maxout p=2 | 103M | 103M |
| fc2 | 1×32×128 | 1×32×128 | maxout p=2 | 34M | 34M |
| fc7128 | 1×32×128 | 1×1×128 | 524K | 0.5M | |
| L2 | 1×1×128 | 1×1×128 | 0 | ||
| total | 140M | 1.6B |
Table 1. NN1. This table show the structure of our Zeiler&Fergus [22] based model with 1×1 convolutions inspired by [9]. The input and output sizes are described in rows × cols × #filters. The kernel is specified as rows × cols, stride and the maxout [6] pooling size as p = 2.
| layer | size-in | size-out | kernel | param | FLPS |
|---|---|---|---|---|---|
| conv1 | 220×220×3 | 110×110×64 | 7×7×3, 2 | 9K | 115M |
| pool1 | 110×110×64 | 55×55×64 | 3×3×64, 2 | 0 | |
| rnorm1 | 55×55×64 | 55×55×64 | 0 | ||
| conv2a | 55×55×64 | 55×55×64 | 1×1×64, 1 | 4K | 13M |
| conv2 | 55×55×64 | 55×55×192 | 3×3×64, 1 | 111K | 335M |
| rnorm2 | 55×55×192 | 55×55×192 | 0 | ||
| pool2 | 55×55×192 | 28×28×192 | 3×3×192, 2 | 0 | |
| conv3a | 28×28×192 | 28×28×192 | 1×1×192, 1 | 37K | 29M |
| conv3 | 28×28×192 | 28×28×384 | 3×3×192, 1 | 664K | 521M |
| pool3 | 28×28×384 | 14×14×384 | 3×3×384, 2 | 0 | |
| conv4a | 14×14×384 | 14×14×384 | 1×1×384, 1 | 148K | 29M |
| conv4 | 14×14×384 | 14×14×256 | 3×3×384, 1 | 885K | 173M |
| conv5a | 14×14×256 | 14×14×256 | 1×1×256, 1 | 66K | 13M |
| conv5 | 14×14×256 | 14×14×256 | 3×3×256, 1 | 590K | 116M |
| conv6a | 14×14×256 | 14×14×256 | 1×1×256, 1 | 66K | 13M |
| conv6 | 14×14×256 | 14×14×256 | 3×3×256, 1 | 590K | 116M |
| pool4 | 14×14×256 | 7×7×256 | 3×3×256, 2 | 0 | |
| concat | 7×7×256 | 7×7×256 | 0 | ||
| fc1 | 7×7×256 | 1×32×128 | maxout p=2 | 103M | 103M |
| fc2 | 1×32×128 | 1×32×128 | maxout p=2 | 34M | 34M |
| fc7128 | 1×32×128 | 1×1×128 | 524K | 0.5M | |
| L2 | 1×1×128 | 1×1×128 | 0 | ||
| total | 140M | 1.6B |
表 1. NN1。本表给出我们基于 Zeiler & Fergus [22]、并加入受 [9] 启发的 1×1 卷积的模型结构。输入和输出尺寸按 行 × 列 × 滤波器数 描述。卷积核写成 行 × 列、步长,maxout [6] 的池化大小为 p = 2。
The second category we use is based on GoogLeNet style Inception models [16]. These models have 20× fewer parameters (around 6.6M–7.5M) and up to 5× fewer FLOPS (between 500M–1.6B). Some of these models are dramatically reduced in size (both depth and number of filters), so that they can be run on a mobile phone. One, NNS1, has 26M parameters and only requires 220M FLOPS per image. The other, NNS2, has 4.3M parameters and 20M FLOPS. Table 2 describes NN2 our largest network in detail. NN3 is identical in architecture but has a reduced input size of 160×160. NN4 has an input size of only 96×96, thereby drastically reducing the CPU requirements (285M FLOPS vs 1.6B for NN2). In addition to the reduced input size it does not use 5×5 convolutions in the higher layers as the receptive field is already too small by then. Generally we found that the 5×5 convolutions can be removed throughout with only a minor drop in accuracy. Figure 4 compares all our models.
我们使用的第二类基于 GoogLeNet 风格的 Inception 模型 [16]。这些模型的参数量少约 20 倍(大约 6.6M–7.5M),浮点运算最多可少 5 倍(在 500M–1.6B 之间)。其中一些在深度和滤波器数量上都大幅缩小,以便在手机上运行。NNS1 有 2600 万参数,每张图只需 2.2 亿次浮点运算;NNS2 有 430 万参数、2000 万次浮点运算。表 2 详细描述了我们最大的网络 NN2。NN3 结构相同,但输入缩小为 160×160。NN4 的输入只有 96×96,从而大幅降低 CPU 需求(2.85 亿次浮点运算,而 NN2 为 16 亿次)。除了缩小输入,它在更高层也不再使用 5×5 卷积,因为那时感受野已经太小。总体而言,我们发现全程去掉 5×5 卷积只会带来很小的精度下降。图 4 比较了我们所有模型。
| type | output size | depth | #1×1 | #3×3 reduce | #3×3 | #5×5 reduce | #5×5 | pool proj (p) | params | FLOPS |
|---|---|---|---|---|---|---|---|---|---|---|
| conv1 (7×7×3, 2) | 112×112×64 | 1 | 9K | 119M | ||||||
| max pool + norm | 56×56×64 | 0 | m 3×3, 2 | |||||||
| inception (2) | 56×56×192 | 2 | 64 | 192 | 115K | 360M | ||||
| norm + max pool | 28×28×192 | 0 | m 3×3, 2 | |||||||
| inception (3a) | 28×28×256 | 2 | 64 | 96 | 128 | 16 | 32 | m, 32p | 164K | 128M |
| inception (3b) | 28×28×320 | 2 | 64 | 96 | 128 | 32 | 64 | L2, 64p | 228K | 179M |
| inception (3c) | 14×14×640 | 2 | 0 | 128 | 256,2 | 32 | 64,2 | m 3×3,2 | 398K | 108M |
| inception (4a) | 14×14×640 | 2 | 256 | 96 | 192 | 32 | 64 | L2, 128p | 545K | 107M |
| inception (4b) | 14×14×640 | 2 | 224 | 112 | 224 | 32 | 64 | L2, 128p | 595K | 117M |
| inception (4c) | 14×14×640 | 2 | 192 | 128 | 256 | 32 | 64 | L2, 128p | 654K | 128M |
| inception (4d) | 14×14×640 | 2 | 160 | 144 | 288 | 32 | 64 | L2, 128p | 722K | 142M |
| inception (4e) | 7×7×1024 | 2 | 0 | 160 | 256,2 | 64 | 128,2 | m 3×3,2 | 717K | 56M |
| inception (5a) | 7×7×1024 | 2 | 384 | 192 | 384 | 48 | 128 | L2, 128p | 1.6M | 78M |
| inception (5b) | 7×7×1024 | 2 | 384 | 192 | 384 | 48 | 128 | m, 128p | 1.6M | 78M |
| avg pool | 1×1×1024 | 0 | ||||||||
| fully conn | 1×1×128 | 1 | 131K | 0.1M | ||||||
| L2 normalization | 1×1×128 | 0 | ||||||||
| total | 7.5M | 1.6B |
Table 2. NN2. Details of the NN2 Inception incarnation. This model is almost identical to the one described in [16]. The two major differences are the use of L2 pooling instead of max pooling (m), where specified. The pooling is always 3×3 (aside from the final average pooling) and in parallel to the convolutional modules inside each Inception module. If there is a dimensionality reduction after the pooling it is denoted with p. 1×1, 3×3, and 5×5 pooling are then concatenated to get the final output.
| type | output size | depth | #1×1 | #3×3 reduce | #3×3 | #5×5 reduce | #5×5 | pool proj (p) | params | FLOPS |
|---|---|---|---|---|---|---|---|---|---|---|
| conv1 (7×7×3, 2) | 112×112×64 | 1 | 9K | 119M | ||||||
| max pool + norm | 56×56×64 | 0 | m 3×3, 2 | |||||||
| inception (2) | 56×56×192 | 2 | 64 | 192 | 115K | 360M | ||||
| norm + max pool | 28×28×192 | 0 | m 3×3, 2 | |||||||
| inception (3a) | 28×28×256 | 2 | 64 | 96 | 128 | 16 | 32 | m, 32p | 164K | 128M |
| inception (3b) | 28×28×320 | 2 | 64 | 96 | 128 | 32 | 64 | L2, 64p | 228K | 179M |
| inception (3c) | 14×14×640 | 2 | 0 | 128 | 256,2 | 32 | 64,2 | m 3×3,2 | 398K | 108M |
| inception (4a) | 14×14×640 | 2 | 256 | 96 | 192 | 32 | 64 | L2, 128p | 545K | 107M |
| inception (4b) | 14×14×640 | 2 | 224 | 112 | 224 | 32 | 64 | L2, 128p | 595K | 117M |
| inception (4c) | 14×14×640 | 2 | 192 | 128 | 256 | 32 | 64 | L2, 128p | 654K | 128M |
| inception (4d) | 14×14×640 | 2 | 160 | 144 | 288 | 32 | 64 | L2, 128p | 722K | 142M |
| inception (4e) | 7×7×1024 | 2 | 0 | 160 | 256,2 | 64 | 128,2 | m 3×3,2 | 717K | 56M |
| inception (5a) | 7×7×1024 | 2 | 384 | 192 | 384 | 48 | 128 | L2, 128p | 1.6M | 78M |
| inception (5b) | 7×7×1024 | 2 | 384 | 192 | 384 | 48 | 128 | m, 128p | 1.6M | 78M |
| avg pool | 1×1×1024 | 0 | ||||||||
| fully conn | 1×1×128 | 1 | 131K | 0.1M | ||||||
| L2 normalization | 1×1×128 | 0 | ||||||||
| total | 7.5M | 1.6B |
表 2. NN2。NN2 这一 Inception 实现的细节。该模型与 [16] 中描述的几乎相同。两个主要差别是:在标明之处用 L2 池化代替最大池化(m)。池化始终为 3×3(最后的平均池化除外),并在每个 Inception 模块内部与卷积支路并行。若池化之后还有降维,则用 p 标出。随后将 1×1、3×3 和 5×5 与池化拼接,得到最终输出。
4. Datasets and Evaluation
4. 数据集与评测
We evaluate our method on four datasets and with the exception of Labelled Faces in the Wild and YouTube Faces we evaluate our method on the face verification task. I.e. given a pair of two face images a squared distance threshold is used to determine the classification of same and different. All faces pairs of the same identity are denoted with , whereas all pairs of different identities are denoted with .
我们在四个数据集上评测本方法;除 Labeled Faces in the Wild 和 YouTube Faces 外,评测任务都是人脸验证。也就是说,给定两张人脸图像,用平方 距离阈值 来判定“相同”还是“不同”。同一身份的所有人脸对 记为 ,不同身份的所有对记为 。
We define the set of all true accepts as
我们把所有正确接受的集合定义为
These are the face pairs that were correctly classified as same at threshold . Similarly
即在阈值 下被正确判为相同的人脸对 。类似地
is the set of all pairs that was incorrectly classified as same (false accept).
是所有被错误判为相同的配对集合(错误接受)。
The validation rate and the false accept rate for a given face distance are then defined as
对给定的人脸距离 ,验证率 和错误接受率 定义为
4.1. Hold-out Test Set
4.1. 留出测试集
We keep a hold out set of around one million images, that has the same distribution as our training set, but disjoint identities. For evaluation we split it into five disjoint sets of 200k images each. The FAR and VAL rate are then computed on 100k × 100k image pairs. Standard error is reported across the five splits.
我们保留大约一百万张图像作为留出集,其分布与训练集相同,但身份互不相交。评测时把它分成五个互不相交的子集,各 20 万张图像。然后在 10 万 × 10 万的图像对上计算 FAR 和 VAL。标准误差在五个划分上报告。
4.2. Personal Photos
4.2. 私人照片
This is a test set with similar distribution to our training set, but has been manually verified to have very clean labels. It consists of three personal photo collections with a total of around 12k images. We compute the FAR and VAL rate across all 12k squared pairs of images.
这是一个与训练集分布相近、但经过人工核验、标签非常干净的测试集。它由三个私人相册组成,大约共 1.2 万张图像。我们在全部约 1.2 万张图像的成对组合上计算 FAR 和 VAL。
4.3. Academic Datasets
4.3. 学术数据集
Labeled Faces in the Wild (LFW) is the de-facto academic test set for face verification [7]. We follow the standard protocol for unrestricted, labeled outside data and report the mean classification accuracy as well as the standard error of the mean.
Labeled Faces in the Wild(LFW)是人脸验证事实上的学术测试集 [7]。我们遵循无限制、可使用外部标注数据的标准协议,报告平均分类准确率以及均值的标准误差。
Youtube Faces DB [21] is a new dataset that has gained popularity in the face recognition community [17, 15]. The setup is similar to LFW, but instead of verifying pairs of images, pairs of videos are used.
YouTube Faces DB [21] 是一个人脸识别社区中日益常用的新数据集 [17, 15]。设置与 LFW 类似,但验证的是视频对,而不是图像对。
5. Experiments
5. 实验
If not mentioned otherwise we use between 100M-200M training face thumbnails consisting of about 8M different identities. A face detector is run on each image and a tight bounding box around each face is generated. These face thumbnails are resized to the input size of the respective network. Input sizes range from 96×96 pixels to 224×224 pixels in our experiments.
若无特别说明,我们使用 1 亿到 2 亿张训练用人脸缩略图,大约包含 800 万个不同身份。对每张图像运行人脸检测器,并生成紧贴人脸的边界框。这些缩略图再被缩放到相应网络的输入尺寸。实验中输入尺寸从 96×96 到 224×224 像素不等。
5.1. Computation Accuracy Trade-off
5.1. 计算量与准确率的权衡
Before diving into the details of more specific experiments let's discuss the trade-off of accuracy versus number of FLOPS that a particular model requires. Figure 4 shows the FLOPS on the x-axis and the accuracy at 0.001 false accept rate (FAR) on our user labelled test-data set from section 4.2. It is interesting to see the strong correlation between the computation a model requires and the accuracy it achieves. The figure highlights the five models (NN1, NN2, NN3, NNS1, NNS2) that we discuss in more detail in our experiments.
在进入更具体的实验细节之前,先讨论准确率与特定模型所需浮点运算次数之间的权衡。图 4 的横轴是浮点运算次数,纵轴是第 4.2 节用户标注测试集上错误接受率为 0.001 时的准确率。可以看到,模型所需计算量与它所达到的准确率之间有很强的相关性。图中标出了我们在实验中重点讨论的五个模型(NN1、NN2、NN3、NNS1、NNS2)。
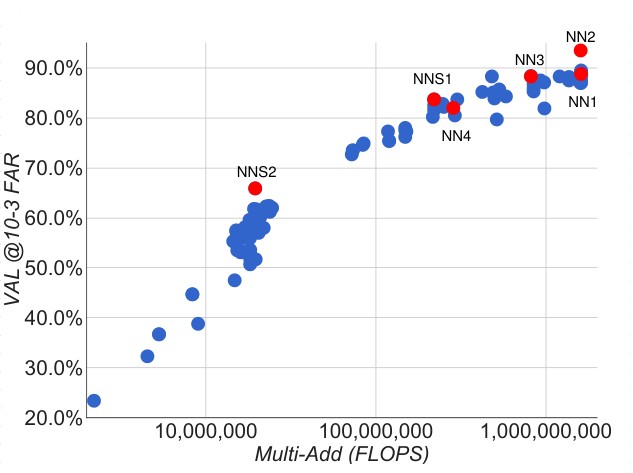
Figure 4. FLOPS vs. Accuracy trade-off. Shown is the trade-off between FLOPS and accuracy for a wide range of different model sizes and architectures. Highlighted are the four models that we focus on in our experiments.
图 4. 浮点运算次数与准确率的权衡。图中展示了多种模型尺寸和结构下,浮点运算次数与准确率之间的权衡。我们在实验中重点讨论的四个模型被标出。
| architecture | VAL |
|---|---|
| NN1 (Zeiler&Fergus 220×220) | 87.9% ± 1.9 |
| NN2 (Inception 224×224) | 89.4% ± 1.6 |
| NN3 (Inception 160×160) | 88.3% ± 1.7 |
| NN4 (Inception 96×96) | 82.0% ± 2.3 |
| NNS1 (mini Inception 165×165) | 82.4% ± 2.4 |
| NNS2 (tiny Inception 140×116) | 51.9% ± 2.9 |
Table 3. Network Architectures. This table compares the performance of our model architectures on the hold out test set (see section 4.1). Reported is the mean validation rate VAL at 10E-3 false accept rate. Also shown is the standard error of the mean across the five test splits.
| architecture | VAL |
|---|---|
| NN1 (Zeiler&Fergus 220×220) | 87.9% ± 1.9 |
| NN2 (Inception 224×224) | 89.4% ± 1.6 |
| NN3 (Inception 160×160) | 88.3% ± 1.7 |
| NN4 (Inception 96×96) | 82.0% ± 2.3 |
| NNS1 (mini Inception 165×165) | 82.4% ± 2.4 |
| NNS2 (tiny Inception 140×116) | 51.9% ± 2.9 |
表 3. 网络结构。本表比较各模型结构在留出测试集上的表现(见第 4.1 节)。报告的是错误接受率为 10E-3 时的平均验证率 VAL,并给出五个测试划分上均值的标准误差。
We also looked into the accuracy trade-off with regards to the number of model parameters. However, the picture is not as clear in that case. For example, the Inception based model NN2 achieves a comparable performance to NN1, but only has a 20th of the parameters. The number of FLOPS is comparable, though. Obviously at some point the performance is expected to decrease, if the number of parameters is reduced further. Other model architectures may allow further reductions without loss of accuracy, just like Inception [16] did in this case.
我们也考察了准确率与模型参数量之间的权衡,但这时关系就不那么清楚了。例如,基于 Inception 的 NN2 与 NN1 性能相当,参数却只有后者的二十分之一,浮点运算次数则大致相当。显然,参数再继续减少,性能终将下降。其他结构或许还能在不损失精度的前提下进一步压缩,就像 Inception [16] 在这里所做的那样。
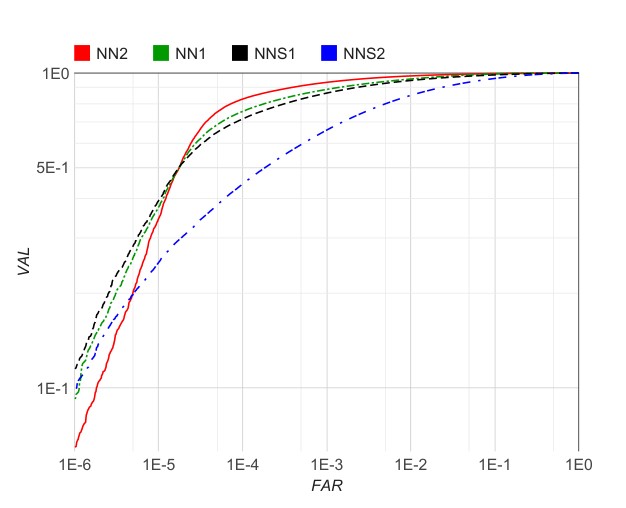
Figure 5. Network Architectures. This plot shows the complete ROC for the four different models on our personal photos test set from section 4.2. The sharp drop at 10E-4 FAR can be explained by noise in the groundtruth labels. The models in order of performance are: NN2: 224×224 input Inception based model; NN1: Zeiler&Fergus based network with 1×1 convolutions; NNS1: small Inception style model with only 220M FLOPS; NNS2: tiny Inception model with only 20M FLOPS.
图 5. 网络结构。本图给出四个不同模型在第 4.2 节私人照片测试集上的完整 ROC。在 10E-4 的 FAR 处出现陡降,可以用真值标签中的噪声来解释。按性能排序,这些模型分别是:NN2:输入 224×224 的 Inception 模型;NN1:带 1×1 卷积的 Zeiler & Fergus 网络;NNS1:只有 2.2 亿次浮点运算的小型 Inception 风格模型;NNS2:只有 2000 万次浮点运算的微型 Inception 模型。
5.2. Effect of CNN Model
5.2. CNN 模型的影响
We now discuss the performance of our four selected models in more detail. On the one hand we have our traditional Zeiler&Fergus based architecture with 1×1 convolutions [22, 9] (see Table 1). On the other hand we have Inception [16] based models that dramatically reduce the model size. Overall, in the final performance the top models of both architectures perform comparably. However, some of our Inception based models, such as NN3, still achieve good performance while significantly reducing both the FLOPS and the model size.
下面更细致地讨论我们选出的四个模型的表现。一方面是传统的、带 1×1 卷积的 Zeiler & Fergus 结构 [22, 9](见表 1);另一方面是大幅缩小模型体积的 Inception [16] 模型。总体而言,两类结构中最好的模型最终性能相当。不过,我们一些基于 Inception 的模型,例如 NN3,仍能在显著减少浮点运算和模型体积的同时保持良好性能。
The detailed evaluation on our personal photos test set is shown in Figure 5. While the largest model achieves a dramatic improvement in accuracy compared to the tiny NNS2, the latter can be run 30ms / image on a mobile phone and is still accurate enough to be used in face clustering. The sharp drop in the ROC for FAR indicates noisy labels in the test data groundtruth. At extremely low false accept rates a single mislabeled image can have a significant impact on the curve.
在私人照片测试集上的详细评测见图 5。最大模型相比微型的 NNS2 在准确率上有大幅提升,但后者可以在手机上以每张图 30 毫秒运行,精度仍足以用于人脸聚类。ROC 在 FAR 处的陡降,表明测试数据真值中存在噪声标签。在极低的错误接受率下,哪怕一张标错的图像也会对曲线产生显著影响。
5.3. Sensitivity to Image Quality
5.3. 对图像质量的敏感性
Table 4 shows the robustness of our model across a wide range of image sizes. The network is surprisingly robust with respect to JPEG compression and performs very well down to a JPEG quality of 20. The performance drop is very small for face thumbnails down to a size of 120×120 pixels and even at 80×80 pixels it shows acceptable performance. This is notable, because the network was trained on 220×220 input images. Training with lower resolution faces could improve this range further.
表 4 展示了模型在很大范围的图像尺寸上的稳健性。网络对 JPEG 压缩出奇地稳健,直到 JPEG 质量为 20 时表现仍然很好。人脸缩略图小到 120×120 像素时,性能下降很小;即便到 80×80 像素,表现也还可以接受。这一点值得注意,因为网络是在 220×220 的输入上训练的。若用更低分辨率的人脸来训练,这一范围还有望进一步拓宽。
| jpeg q | val-rate | #pixels | val-rate | |
|---|---|---|---|---|
| 10 | 67.3% | 1,600 | 37.8% | |
| 20 | 81.4% | 6,400 | 79.5% | |
| 30 | 83.9% | 14,400 | 84.5% | |
| 50 | 85.5% | 25,600 | 85.7% | |
| 70 | 86.1% | 65,536 | 86.4% | |
| 90 | 86.5% |
Table 4. Image Quality. The table on the left shows the effect on the validation rate at 10E-3 precision with varying JPEG quality. The one on the right shows how the image size in pixels effects the validation rate at 10E-3 precision. This experiment was done with NN1 on the first split of our test hold-out dataset.
| jpeg q | val-rate | #pixels | val-rate | |
|---|---|---|---|---|
| 10 | 67.3% | 1,600 | 37.8% | |
| 20 | 81.4% | 6,400 | 79.5% | |
| 30 | 83.9% | 14,400 | 84.5% | |
| 50 | 85.5% | 25,600 | 85.7% | |
| 70 | 86.1% | 65,536 | 86.4% | |
| 90 | 86.5% |
表 4. 图像质量。左表给出 JPEG 质量变化时、在 10E-3 精度下验证率的变化;右表给出以像素计的图像大小如何影响 10E-3 精度下的验证率。该实验用 NN1 在测试留出集的第一个划分上进行。
5.4. Embedding Dimensionality
5.4. 嵌入维数
We explored various embedding dimensionalities and selected 128 for all experiments other than the comparison reported in Table 5. One would expect the larger embeddings to perform at least as good as the smaller ones, however, it is possible that they require more training to achieve the same accuracy. That said, the differences in the performance reported in Table 5 are statistically insignificant.
我们探索了多种嵌入维数,除表 5 中的比较外,所有实验都选用 128 维。按理说更大的嵌入至少不应差于较小的嵌入,但它们也可能需要更多训练才能达到同样的精度。不过,表 5 中报告的性能差异在统计上并不显著。
| #dims | VAL |
|---|---|
| 64 | 86.8% ± 1.7 |
| 128 | 87.9% ± 1.9 |
| 256 | 87.7% ± 1.9 |
| 512 | 85.6% ± 2.0 |
Table 5. Embedding Dimensionality. This Table compares the effect of the embedding dimensionality of our model NN1 on our hold-out set from section 4.1. In addition to the VAL at 10E-3 we also show the standard error of the mean computed across five splits.
| #dims | VAL |
|---|---|
| 64 | 86.8% ± 1.7 |
| 128 | 87.9% ± 1.9 |
| 256 | 87.7% ± 1.9 |
| 512 | 85.6% ± 2.0 |
表 5. 嵌入维数。本表比较模型 NN1 的嵌入维数在第 4.1 节留出集上的影响。除 10E-3 处的 VAL 外,我们还给出在五个划分上计算的均值标准误差。
It should be noted, that during training a 128 dimensional float vector is used, but it can be quantized to 128-bytes without loss of accuracy. Thus each face is compactly represented by a 128 dimensional byte vector, which is ideal for large scale clustering and recognition. Smaller embeddings are possible at a minor loss of accuracy and could be employed on mobile devices.
需要说明的是,训练时使用的是 128 维浮点向量,但可以在不损失精度的情况下量化为 128 字节。于是每张脸都能用一个 128 维的字节向量紧凑表示,非常适合大规模聚类和识别。更小的嵌入也是可能的,精度只会略有下降,可用于移动设备。
5.5. Amount of Training Data
5.5. 训练数据量
Table 6 shows the impact of large amounts of training data. Due to time constraints this evaluation was run on a smaller model; the effect may be even larger on larger models. It is clear that using tens of millions of exemplars results in a clear boost of accuracy on our personal photo test set from section 4.2. Compared to only millions of images the relative reduction in error is 60%. Using another order of magnitude more images (hundreds of millions) still gives a small boost, but the improvement tapers off.
表 6 展示了大规模训练数据的影响。受时间限制,这一评测是在较小模型上做的;在更大模型上效果可能更明显。可以清楚地看到,使用数千万样本会在第 4.2 节的私人照片测试集上带来明显的准确率提升。与只用数百万张图像相比,误差相对降低了 60%。再增加一个数量级(数亿张图像)仍有小幅提升,但收益开始变小。
| #training images | VAL |
|---|---|
| 2,600,000 | 76.3% |
| 26,000,000 | 85.1% |
| 52,000,000 | 85.1% |
| 260,000,000 | 86.2% |
Table 6. Training Data Size. This table compares the performance after 700h of training for a smaller model with 96×96 pixel inputs. The model architecture is similar to NN2, but without the 5×5 convolutions in the Inception modules.
| #training images | VAL |
|---|---|
| 2,600,000 | 76.3% |
| 26,000,000 | 85.1% |
| 52,000,000 | 85.1% |
| 260,000,000 | 86.2% |
表 6. 训练数据规模。本表比较一个输入为 96×96 像素的较小模型在训练 700 小时后的表现。模型结构与 NN2 类似,但 Inception 模块中没有 5×5 卷积。
5.6. Performance on LFW
5.6. 在 LFW 上的表现
We evaluate our model on LFW using the standard protocol for unrestricted, labeled outside data. Nine training splits are used to select the -distance threshold. Classification (same or different) is then performed on the tenth test split. The selected optimal threshold is 1.242 for all test splits except split eighth (1.256).
我们按无限制、可使用外部标注数据的标准协议在 LFW 上评测模型。用九个训练划分来选择 距离阈值,再在第十个测试划分上做分类(相同或不同)。除第八个划分(1.256)外,各测试划分选出的最优阈值都是 1.242。
Our model is evaluated in two modes:
模型按两种方式评测:
- Fixed center crop of the LFW provided thumbnail.
- 对 LFW 提供的缩略图做固定中心裁剪。
- A proprietary face detector (similar to Picasa [3]) is run on the provided LFW thumbnails. If it fails to align the face (this happens for two images), the LFW alignment is used.
- 在 LFW 提供的缩略图上运行自研人脸检测器(类似于 Picasa [3])。若对齐失败(有两张图像出现这种情况),则使用 LFW 的对齐结果。
Figure 6 gives an overview of all failure cases. It shows false accepts on the top as well as false rejects at the bottom. We achieve a classification accuracy of 98.87%±0.15 when using the fixed center crop described in (1) and the record breaking 99.63%±0.09 standard error of the mean when using the extra face alignment (2). This reduces the error reported for DeepFace in [17] by more than a factor of 7 and the previous state-of-the-art reported for DeepId2+ in [15] by 30%. This is the performance of model NN1, but even the much smaller NN3 achieves performance that is not statistically significantly different.
图 6 给出了全部失败案例的概览:上方是错误接受,下方是错误拒绝。使用 (1) 中的固定中心裁剪时,分类准确率为 98.87%±0.15;再使用额外的人脸对齐 (2) 时,达到破纪录的 99.63%±0.09(均值的标准误差)。这把 [17] 中 DeepFace 报告的误差缩小了七倍以上,也比 [15] 中 DeepId2+ 当时的最好结果再降 30%。这是模型 NN1 的表现,但小得多的 NN3 也能达到在统计上并无显著差异的性能。
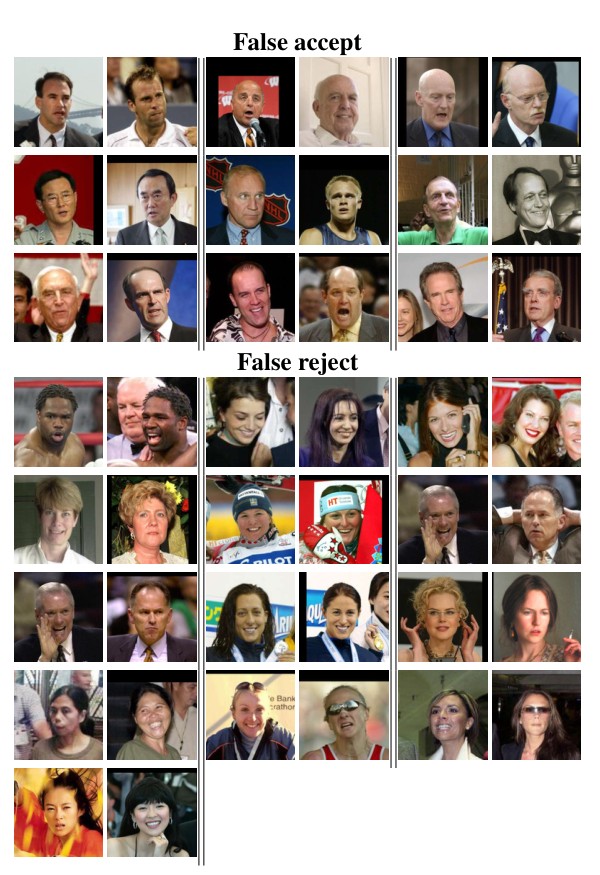
Figure 6. LFW errors. This shows all pairs of images that were incorrectly classified on LFW.
图 6. LFW 上的错误。图中给出在 LFW 上被错误分类的全部图像对。
5.7. Performance on Youtube Faces DB
5.7. 在 YouTube Faces DB 上的表现
We use the average similarity of all pairs of the first one hundred frames that our face detector detects in each video. This gives us a classification accuracy of 95.12%±0.39. Using the first one thousand frames results in 95.18%. Compared to [17] 91.4% who also evaluate one hundred frames per video we reduce the error rate by almost half. DeepId2+ [15] achieved 93.2% and our method reduces this error by 30%, comparable to our improvement on LFW.
我们对每段视频中检测器找到的前一百帧,计算所有帧对的平均相似度,得到 95.12%±0.39 的分类准确率。若改用前一千帧,则为 95.18%。[17] 同样按每段视频一百帧评测,结果为 91.4%,我们把误差率几乎降低了一半。DeepId2+ [15] 达到 93.2%,我们的方法把这一误差降低了 30%,与在 LFW 上的提升相当。
5.8. Face Clustering
5.8. 人脸聚类
Our compact embedding lends itself to be used in order to cluster a users personal photos into groups of people with the same identity. The constraints in assignment imposed by clustering faces, compared to the pure verification task, lead to truly amazing results. Figure 7 shows one cluster in a users personal photo collection, generated using agglomerative clustering. It is a clear showcase of the incredible invariance to occlusion, lighting, pose and even age.
这种紧凑嵌入很适合把用户的私人照片按同一身份聚成若干组。与纯粹的验证任务相比,聚类在分配上施加的约束带来了相当惊人的结果。图 7 展示了用层次聚类在某个用户私人相册中得到的一个簇。它可以清楚地看出,模型对遮挡、光照、姿态甚至年龄具有很强的不变性。
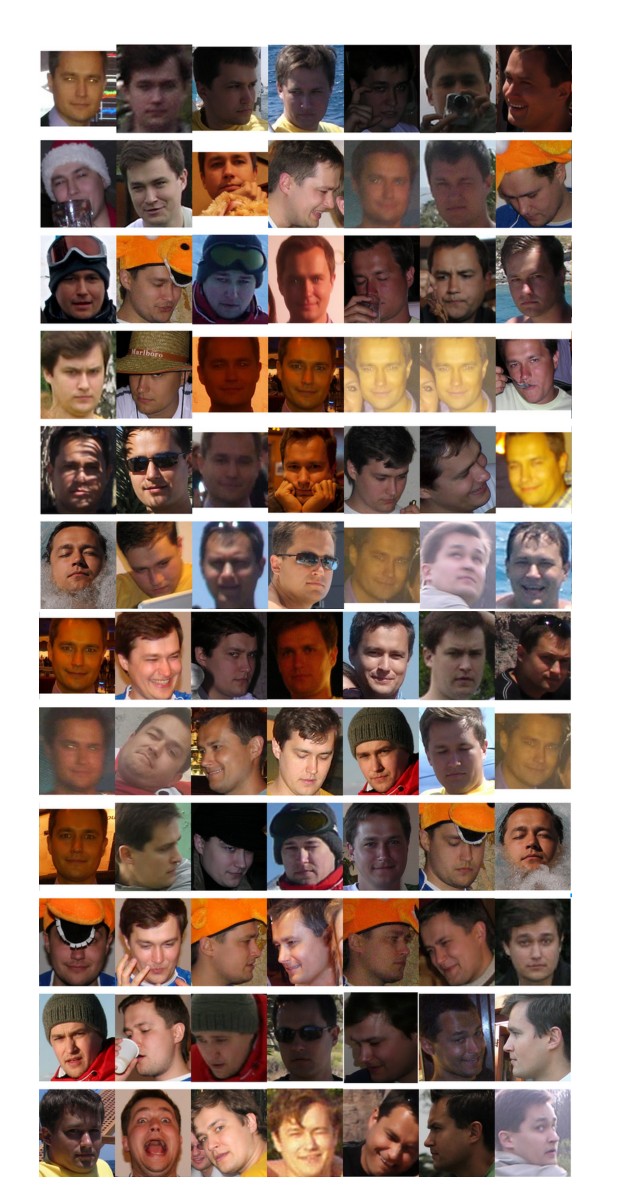
Figure 7. Face Clustering. Shown is an exemplar cluster for one user. All these images in the users personal photo collection were clustered together.
图 7. 人脸聚类。图中是某个用户的一个示例簇。该用户私人相册中的这些图像被聚到了一起。
6. Summary
6. 小结
We provide a method to directly learn an embedding into an Euclidean space for face verification. This sets it apart from other methods [15, 17] who use the CNN bottleneck layer, or require additional post-processing such as concatenation of multiple models and PCA, as well as SVM classification. Our end-to-end training both simplifies the setup and shows that directly optimizing a loss relevant to the task at hand improves performance.
我们给出一种直接学习欧氏空间嵌入、用于人脸验证的方法。这使它有别于其他使用 CNN 瓶颈层的方法 [15, 17],也不需要把多个模型拼接后再做 PCA,以及再用 SVM 分类这类后处理。端到端训练既简化了流程,也表明直接优化与当前任务相关的损失能够提高性能。
Another strength of our model is that it only requires minimal alignment (tight crop around the face area). [17], for example, performs a complex 3D alignment. We also experimented with a similarity transform alignment and notice that this can actually improve performance slightly. It is not clear if it is worth the extra complexity.
本模型的另一个优点是只需最少的对齐(在人脸区域做紧裁)。例如 [17] 要做复杂的三维对齐。我们也试验过相似变换对齐,并注意到这其实还能略微提高性能。不过,这点收益是否值得增加复杂度,并不清楚。
Future work will focus on better understanding of the error cases, further improving the model, and also reducing model size and reducing CPU requirements. We will also look into ways of improving the currently extremely long training times, e.g. variations of our curriculum learning with smaller batch sizes and offline as well as online positive and negative mining.
未来工作将侧重于更好地理解错误案例、继续改进模型,以及缩小模型体积、降低 CPU 需求。我们也会寻找缩短目前极长训练时间的办法,例如在更小批量上调整课程学习,并把离线与在线的正、负样本挖掘结合起来。
Acknowledgments
致谢
We would like to thank Johannes Steffens for his discussions and great insights on face recognition and Christian Szegedy for providing new network architectures like [16] and discussing network design choices. Also we are indebted to the DistBelief [4] team for their support especially to Rajat Monga for help in setting up efficient training schemes.
我们感谢 Johannes Steffens 就人脸识别所做的讨论和深刻见解,以及 Christian Szegedy 提供如 [16] 这样的新网络结构并一起讨论网络设计选择。我们也感谢 DistBelief [4] 团队的支持,尤其是 Rajat Monga 帮助建立高效的训练方案。
Also our work would not have been possible without the support of Chuck Rosenberg, Hartwig Adam, and Simon Han.
同样,没有 Chuck Rosenberg、Hartwig Adam 和 Simon Han 的支持,这项工作也不可能完成。
References
参考文献
[1] Y. Bengio, J. Louradour, R. Collobert, and J. Weston. Curriculum learning. In Proc. of ICML, New York, NY, USA, 2009. 2
[2] D. Chen, X. Cao, L. Wang, F. Wen, and J. Sun. Bayesian face revisited: A joint formulation. In Proc. ECCV, 2012. 2
[3] D. Chen, S. Ren, Y. Wei, X. Cao, and J. Sun. Joint cascade face detection and alignment. In Proc. ECCV, 2014. 8
[4] J. Dean, G. Corrado, R. Monga, K. Chen, M. Devin, M. Mao, M. Ranzato, A. Senior, P. Tucker, K. Yang, Q. V. Le, and A. Y. Ng. Large scale distributed deep networks. In P. Bartlett, F. Pereira, C. Burges, L. Bottou, and K. Weinberger, editors, NIPS, pages 1232–1240. 2012. 9
[5] J. Duchi, E. Hazan, and Y. Singer. Adaptive subgradient methods for online learning and stochastic optimization. J. Mach. Learn. Res., 12:2121–2159, July 2011. 4
[6] I. J. Goodfellow, D. Warde-farley, M. Mirza, A. Courville, and Y. Bengio. Maxout networks. In In ICML, 2013. 4
[7] G. B. Huang, M. Ramesh, T. Berg, and E. Learned-Miller. Labeled faces in the wild: A database for studying face recognition in unconstrained environments. Technical Report 07-49, University of Massachusetts, Amherst, October 2007. 5
[8] Y. LeCun, B. Boser, J. S. Denker, D. Henderson, R. E. Howard, W. Hubbard, and L. D. Jackel. Backpropagation applied to handwritten zip code recognition. Neural Computation, 1(4):541–551, Dec. 1989. 2, 4
[9] M. Lin, Q. Chen, and S. Yan. Network in network. CoRR, abs/1312.4400, 2013. 2, 4, 6
[10] C. Lu and X. Tang. Surpassing human-level face verification performance on LFW with gaussianface. CoRR, abs/1404.3840, 2014. 1
[11] D. E. Rumelhart, G. E. Hinton, and R. J. Williams. Learning representations by back-propagating errors. Nature, 1986. 2, 4
[12] M. Schultz and T. Joachims. Learning a distance metric from relative comparisons. In S. Thrun, L. Saul, and B. Schölkopf, editors, NIPS, pages 41–48. MIT Press, 2004. 2
[13] T. Sim, S. Baker, and M. Bsat. The CMU pose, illumination, and expression (PIE) database. In In Proc. FG, 2002. 2
[14] Y. Sun, X. Wang, and X. Tang. Deep learning face representation by joint identification-verification. CoRR, abs/1406.4773, 2014. 1, 2, 3
[15] Y. Sun, X. Wang, and X. Tang. Deeply learned face representations are sparse, selective, and robust. CoRR, abs/1412.1265, 2014. 1, 2, 5, 8
[16] C. Szegedy, W. Liu, Y. Jia, P. Sermanet, S. Reed, D. Anguelov, D. Erhan, V. Vanhoucke, and A. Rabinovich. Going deeper with convolutions. CoRR, abs/1409.4842, 2014. 2, 4, 5, 6, 9
[17] Y. Taigman, M. Yang, M. Ranzato, and L. Wolf. Deepface: Closing the gap to human-level performance in face verification. In IEEE Conf. on CVPR, 2014. 1, 2, 5, 8
[18] J. Wang, Y. Song, T. Leung, C. Rosenberg, J. Wang, J. Philbin, B. Chen, and Y. Wu. Learning fine-grained image similarity with deep ranking. CoRR, abs/1404.4661, 2014. 2
[19] K. Q. Weinberger, J. Blitzer, and L. K. Saul. Distance metric learning for large margin nearest neighbor classification. In NIPS. MIT Press, 2006. 2, 3
[20] D. R. Wilson and T. R. Martinez. The general inefficiency of batch training for gradient descent learning. Neural Networks, 16(10):1429–1451, 2003. 4
[21] L. Wolf, T. Hassner, and I. Maoz. Face recognition in unconstrained videos with matched background similarity. In IEEE Conf. on CVPR, 2011. 5
[22] M. D. Zeiler and R. Fergus. Visualizing and understanding convolutional networks. CoRR, abs/1311.2901, 2013. 2, 4, 6
[23] Z. Zhu, P. Luo, X. Wang, and X. Tang. Recover canonical-view faces in the wild with deep neural networks. CoRR, abs/1404.3543, 2014. 2