End-to-End Training of Deep Visuomotor Policies
End-to-End Training of Deep Visuomotor Policies
深度视觉运动策略的端到端训练(End-to-End Training of Deep Visuomotor Policies)
Abstract
摘要
Policy search methods can allow robots to learn control policies for a wide range of tasks, but practical applications of policy search often require hand-engineered components for perception, state estimation, and low-level control. In this paper, we aim to answer the following question: does training the perception and control systems jointly end-to-end provide better performance than training each component separately? To this end, we develop a method that can be used to learn policies that map raw image observations directly to torques at the robot’s motors. The policies are represented by deep convolutional neural networks (CNNs) with 92,000 parameters, and are trained using a guided policy search method, which transforms policy search into supervised learning, with supervision provided by a simple trajectory-centric reinforcement learning method. We evaluate our method on a range of real-world manipulation tasks that require close coordination between vision and control, such as screwing a cap onto a bottle, and present simulated comparisons to a range of prior policy search methods.
策略搜索方法可以让机器人为广泛任务学习控制策略,但实际应用中策略搜索往往仍需要为感知、状态估计与底层控制手写组件。本文旨在回答:把感知与控制系统联合端到端训练,是否比分开训练各组件表现更好?为此,我们提出一种方法,可学习把原始图像观测直接映射到机器人电机力矩的策略。策略由约 92,000 参数的深度卷积神经网络(CNN)表示,并用引导策略搜索训练——该方法把策略搜索转化为监督学习,监督来自简单的轨迹中心强化学习。我们在一系列需要视觉与控制紧密配合的真实世界操作任务上评估(例如把瓶盖旋到瓶子上),并给出与多种先前策略搜索方法的仿真比较。
1 Introduction
1 引言
keywords
关键词
Robots can perform impressive tasks under human control, including surgery (Lanfranco et al. 2004) and household chores (Wyrobek et al. 2008). However, designing the perception and control software for autonomous operation remains a major challenge, even for basic tasks. Policy search methods hold the promise of allowing robots to automatically learn new behaviors through experience (Kober et al. 2010b; Deisenroth et al. 2011; Kalakrishnan et al. 2011; Deisenroth et al. 2013). However, policies learned using such methods often rely on a number of hand-engineered components for perception and control, so as to present the policy with a more manageable and low-dimensional representation of observations and actions. The vision system in particular can be complex and prone to errors, and it is typically not improved during policy training, nor adapted to the goal of the task.
机器人可以在人类控制下完成令人印象深刻的任务,包括手术(Lanfranco 等,2004)与家务(Wyrobek 等,2008)。然而,即便对基本任务,为自主运行设计感知与控制软件仍是重大挑战。策略搜索方法有望让机器人通过经验自动学习新行为(Kober 等,2010b;Deisenroth 等,2011;Kalakrishnan 等,2011;Deisenroth 等,2013)。但用这些方法学到的策略往往仍依赖若干手写的感知与控制组件,以便向策略提供更易处理、更低维的观测与动作表示。视觉系统尤其复杂且易出错,在策略训练期间通常既不改进,也不针对任务目标适配。
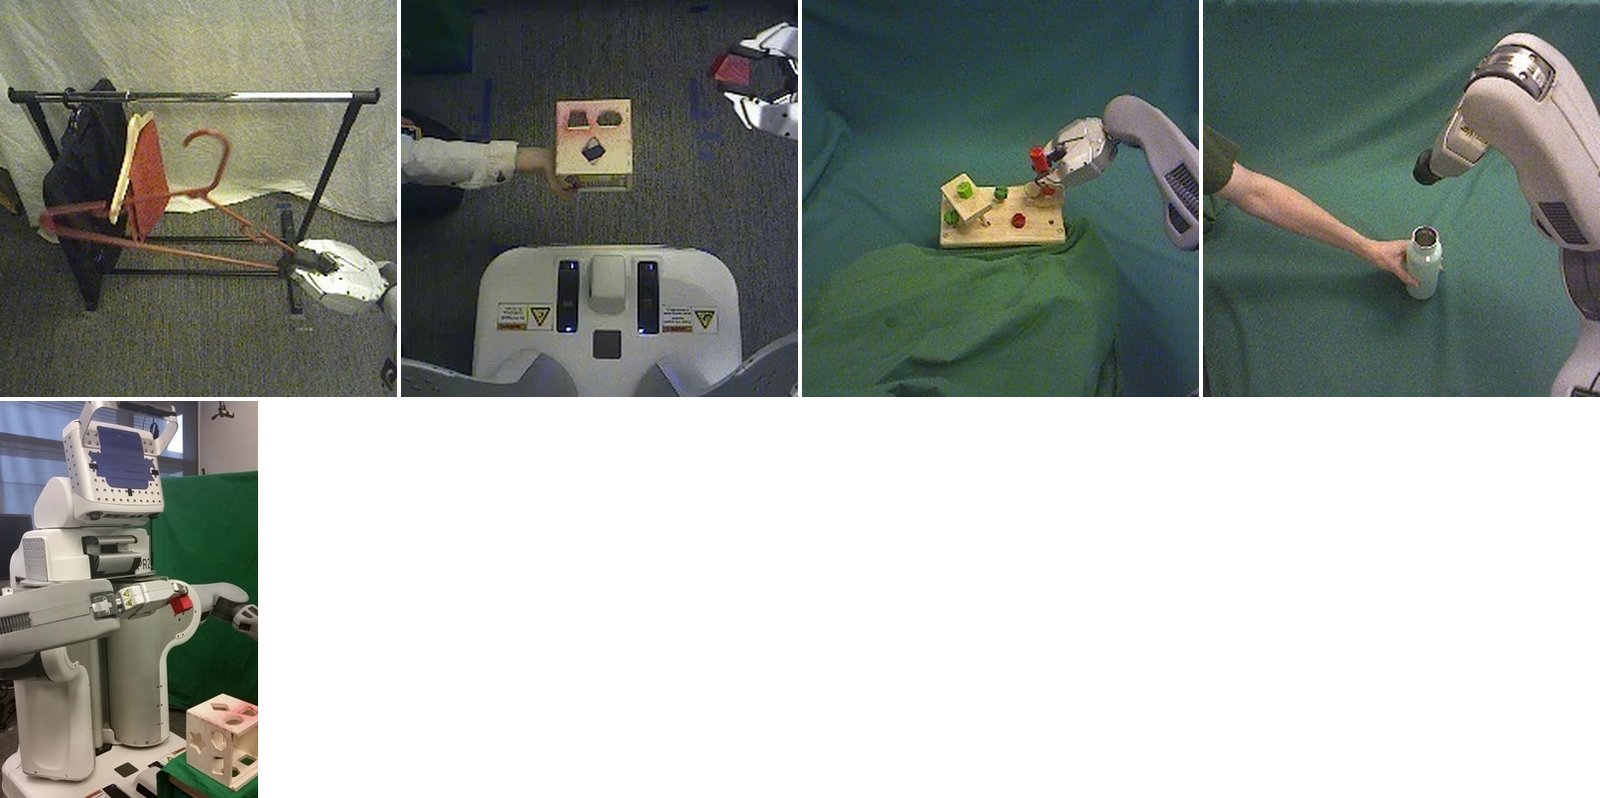
Figure 1: Our method learns visuomotor policies that directly use camera image observations (left) to set motor torques on a PR2 robot (right).
图 1:我们的方法学习视觉运动策略,直接用相机图像观测(左)在 PR2 机器人(右)上设定电机力矩。
In this article, we aim to answer the following question: can we acquire more effective policies for sensorimotor control if the perception system is trained jointly with the control policy, rather than separately? In order to represent a policy that performs both perception and control, we use deep neural networks. Deep neural network representations have recently seen widespread success in a variety of domains, such as computer vision and speech recognition, and even playing video games. However, using deep neural networks for real-world sensorimotor policies, such as robotic controllers that map image pixels and joint angles to motor torques, presents a number of unique challenges. Successful applications of deep neural networks typically rely on large amounts of data and direct supervision of the output, neither of which is available in robotic control. Real-world robot interaction data is scarce, and task completion is defined at a high level by means of a cost function, which means that the learning algorithm must determine on its own which action to take at each point. From the control perspective, a further complication is that observations from the robot’s sensors do not provide us with the full state of the system. Instead, important state information, such as the positions of task-relevant objects, must be inferred from inputs such as camera images.
本文旨在回答:若感知系统与控制策略联合训练而非分开训练,能否获得更有效的感觉运动控制策略?为表示同时做感知与控制的策略,我们使用深度神经网络。深度网络近来在计算机视觉、语音识别乃至电子游戏等领域取得广泛成功。然而,把深度网络用于真实世界的感觉运动策略——例如把图像像素与关节角映射到电机力矩的机器人控制器——带来若干独特挑战。深度网络的成功应用通常依赖大量数据与对输出的直接监督,这两者在机器人控制中都不具备。真实机器人交互数据稀缺,任务完成由高层代价函数定义,学习算法须自行决定每一步动作。从控制角度看,另一困难是观测可能无法提供系统完整状态的全部信息。
We address these challenges by developing a guided policy search algorithm for sensorimotor deep learning, as well as a novel CNN architecture designed for robotic control. Guided policy search converts policy search into supervised learning, by iteratively constructing the training data using an efficient model-free trajectory optimization procedure. We show that this can be formalized as an instance of Bregman ADMM (BADMM) (Wang and Banerjee 2014), which can be used to show that the algorithm converges to a locally optimal solution. In our method, the full state of the system is observable at training time, but not at test time. For most tasks, providing the full state simply requires positioning objects in one of several known positions for each trial during training. At test time, the learned CNN policy can handle novel, unknown configurations, and no longer requires full state information. Since the policy is optimized with supervised learning, we can use standard methods like stochastic gradient descent for training. Our CNNs have 92,000 parameters and 7 layers, including a novel spatial feature point transformation that provides accurate spatial reasoning and reduces overfitting. This allows us to train our policies with relatively modest amounts of data and only tens of minutes of real-world interaction time.
我们通过为感觉运动深度学习开发引导策略搜索算法,以及面向机器人控制的新型 CNN 架构来应对这些挑战。引导策略搜索把策略搜索转化为监督学习:用高效的免模型轨迹优化迭代构造训练数据。我们证明这可形式化为 Bregman ADMM(BADMM)(Wang and Banerjee,2014)的实例,并据此说明算法收敛到局部最优。在我们的方法中,系统完整状态在训练时可知,测试时不可知。对多数任务,提供完整状态只需目标物体的位姿,可用第二只机械臂在训练时持有目标物体来获得。
We evaluate our method by learning policies for inserting a block into a shape sorting cube, screwing a cap onto a bottle, fitting the claw of a toy hammer under a nail with various grasps, and placing a coat hanger on a rack with a PR2 robot (see Figure 1). These tasks require localization, visual tracking, and handling complex contact dynamics. Our results demonstrate improvements in consistency and generalization from training visuomotor policies end-to-end, when compared to training the vision and control components separately. We also present simulated comparisons that show that guided policy search outperforms a number of prior methods when training high-dimensional neural network policies. Some of the material in this article has previously appeared in two conference papers (Levine and Abbeel 2014; Levine et al. 2015), which we extend to introduce visual input into the policy.
我们通过学习以下策略来评估方法:把积木插入形状分类盒、把瓶盖旋到瓶子上、以多种抓取把玩具锤的爪对准钉子下方,以及用 PR2 把衣架挂到架子上(见图 1)。这些任务需要定位、视觉跟踪并处理复杂接触动力学。结果表明,与分别训练视觉与控制组件相比,端到端训练视觉运动策略在一致性与泛化上有提升。我们也给出仿真比较,显示在训练高维神经网络策略时,引导策略搜索优于若干先前方法。
2 Related Work
2 相关工作
Reinforcement learning and policy search methods (Gullapalli 1990; Williams 1992) have been applied in robotics for playing games such as table tennis (Kober et al. 2010b), object manipulation (Gullapalli 1995; Peters and Schaal 2008; Kober et al. 2010a; Deisenroth et al. 2011; Kalakrishnan et al. 2011), locomotion (Benbrahim and Franklin 1997; Kohl and Stone 2004; Tedrake et al. 2004; Geng et al. 2006; Endo et al. 2008), and flight (Ng et al. 2004). Several recent papers provide surveys of policy search in robotics (Deisenroth et al. 2013; Kober et al. 2013). Such methods are typically applied to one component of the robot control pipeline, which often sits on top of a hand-designed controller, such as a PD controller, and accepts processed input, for example from an existing vision pipeline (Kalakrishnan et al. 2011). Our method learns policies that map visual input and joint encoder readings directly to the torques at the robot’s joints. By learning the entire mapping from perception to control, the perception layers can be adapted to optimize task performance, and the motor control layers can be adapted to imperfect perception.
强化学习与策略搜索方法(Gullapalli,1990;Williams,1992)已广泛用于机器人控制(Peters 与 Schaal,2008;Kober 等,2013;Deisenroth 等,2013)。许多最成功的方法仍依赖手写特征或低维状态表示。尽管如此,已有若干工作探索从视觉等原始感觉输入学习策略。早期工作常在仿真中学习,或依赖预先计算的视觉特征。近期深度强化学习在游戏与仿真中取得显著成功,但样本复杂度通常使真实机器人上的直接应用变得困难。
We represent our policies with convolutional neural networks (CNNs). CNNs have a long history in computer vision and deep learning (Fukushima 1980; LeCun et al. 1989; Schmidhuber 2015), and have recently gained prominence due to excellent results on a number of vision benchmarks (Ciresan et al. 2011; Krizhevsky et al. 2012; Ciresan et al. 2012; Girshick et al. 2014a; Tompson et al. 2014; LeCun et al. 2015; He et al. 2015). Most applications of CNNs focus on classification, where locational information is discarded by means of successive pooling layers to provide for invariance (Lee et al. 2009). Applications to localization typically either use a sliding window (Girshick et al. 2014a) or object proposals (Endres and Hoiem 2010; Uijlings et al. 2013; Girshick et al. 2014b) to localize the object, reducing the task to classification, perform regression to a heatmap of manually labeled keypoints (Tompson et al. 2014), requiring precise knowledge of the object position in the image and camera calibration, or use 3D models to localize previously scanned objects (Pepik et al. 2012; Savarese and Fei-Fei 2007). Many prior robotic applications of CNNs do not directly consider control, but employ CNNs for the perception component of a larger robotic system (Hadsell et al. 2009; Sung et al. 2015; Lenz et al. 2015b; Pinto and Gupta 2015). We use a novel CNN architecture for our policies that automatically learn feature points that capture spatial information about the scene, without any supervision beyond the information from the robot’s encoders and camera.
我们用卷积神经网络(CNN)表示策略。CNN 在计算机视觉中有悠久历史,并构成许多当前最佳视觉系统的骨干。将 CNN 用于控制提出独特要求:策略必须产生精确的空间动作,而非仅类别标签,且必须从相对较少的真实机器人数据中学习。
Applications of deep learning in robotic control have been less prevalent in recent years than in visual recognition. Backpropagation through the dynamics and the image formation process is typically impractical, since they are often non-differentiable, and such long-range backpropagation can lead to extreme numerical instability, since the linearization of a suboptimal policy is likely to be unstable. This issue has also been observed in the related context of recurrent neural networks (Hochreiter et al. 2001; Pascanu and Bengio 2012). The high dimensionality of the network also makes reinforcement learning difficult (Deisenroth et al. 2013). Pioneering early work on neural network control used small, simple networks (Pomerleau 1989; Hunt et al. 1992; Bekey and Goldberg 1992; Lewis et al. 1998; Bakker et al. 2003; Mayer et al. 2006), and has largely been supplanted by methods that use carefully designed policies that can be learned efficiently with reinforcement learning (Kober et al. 2013). More recent work on sensorimotor deep learning has tackled simple task-space motions (Lenz et al. 2015a; Lampe and Riedmiller 2013) and used unsupervised learning to obtain low-dimensional state spaces from images (Lange et al. 2012). Such methods have been demonstrated on tasks with a low-dimensional underlying structure: Lenz et al. 2015a controls the end-effector in 2D space, while Lange et al. 2012 controls a 2-dimensional slot car with 1-dimensional actions. Our experiments include full torque control of 7-DoF robotic arms interacting with objects, with 30-40 state dimensions. In simple synthetic environments, control from images has been addressed with image features (Jodogne and Piater 2007), nonparametric methods (van Hoof et al. 2015), and unsupervised state-space learning (Böhmer et al. 2013; Jonschkowski and Brock 2014). CNNs have also been trained to play video games with Q-learning, Monte Carlo tree search, and stochastic search (Mnih et al. 2013; Koutník et al. 2013; Guo et al. 2014), and have been applied to simple simulated control tasks (Watter et al. 2015; Lillicrap et al. 2015). However, such methods have only been demonstrated on synthetic domains that lack the visual complexity of the real world, and require an impractical number of samples for real-world robotic learning. Our method is sample efficient, requiring only minutes of interaction time. To the best of our knowledge, this is the first method that can train deep visuomotor policies for complex, high-dimensional manipulation skills with direct torque control.
深度学习在机器人控制中的应用近年来相对较少,尽管早期神经控制器工作可追溯到几十年前。若干近期方法在仿真中学习视觉运动策略,或用人类示范。与这些方法相比,我们的算法直接在真实机器人上从力矩级控制学习,并用引导策略搜索降低样本复杂度。
Learning visuomotor policies on a real robot requires handling complex observations and high dimensional policy representations. We tackle these challenges using guided policy search. In guided policy search, the policy is optimized using supervised learning, which scales gracefully with the dimensionality of the policy. The training set for supervised learning can be constructed using trajectory optimization under known dynamics (Levine and Koltun 2013a; Levine and Koltun 2013b; Levine and Koltun 2014; Mordatch and Todorov 2014) and trajectory-centric reinforcement learning methods that operate under unknown dynamics (Levine and Abbeel 2014; Levine et al. 2015), which is the approach taken in this work. In both cases, the supervision is adapted to the policy, to ensure that the final policy can reproduce the training data. The use of supervised learning in the inner loop of iterative policy search has also been proposed in the context of imitation learning (Ross et al. 2011; Ross et al. 2013). However, such methods typically do not address the question of how the supervision should be adapted to the policy.
在真实机器人上学习视觉运动策略需要处理复杂观测与高维动作。若干工作结合视觉伺服与学习,或用位姿估计作为中间表示。我们的目标是去掉对手写中间表示的依赖,联合训练感知与控制。
The goal of our approach is also similar to visual servoing, which performs feedback control on feature points in a camera image (Espiau et al. 1992; Mohta et al. 2014; Wilson et al. 1996). However, our visuomotor policies are entirely learned from real-world data, and do not require feature points or feedback controllers to be specified by hand. This allows our method much more flexibility in choosing how to use the visual signal. Our approach also does not require any sort of camera calibration, in contrast to many visual servoing methods (though not all – see e.g. Jägersand et al. 1997; Yoshimi and Allen 1994).
我们的目标也与视觉伺服相近,后者根据图像特征误差做反馈控制。经典视觉伺服通常需要手选特征与已知几何。学习型方法可减轻部分负担,但端到端从像素到力矩仍少见。我们的工作表明,借助合适的策略搜索与网络架构,这种端到端训练在真实硬件上可行。
3 Background and Overview
3 背景与概述
In this section, we define the visuomotor policy learning problem and present an overview of our approach. The core component of our approach is a guided policy search algorithm that separates the problem of learning visuomotor policies into separate supervised learning and trajectory learning phases, each of which is easier than optimizing the policy directly. We also discuss a policy architecture suitable for end-to-end learning of vision and control, and a training setup that allows our method to be applied to real robotic platforms.
本节定义视觉运动策略学习问题,并概述我们的方法。后续各节给出算法细节、网络架构与实验结果。
3.1 Definitions and Problem Formulation
3.1 定义与问题形式化
In policy search, the goal is to learn a policy that allows an agent to choose actions in response to observations to control a dynamical system, such as a robot. The policy comes from some parametric class parameterized by , which could be, for example, the weights of a neural network. The system is defined by states , actions , and observations . For example, might include the joint angles of the robot, the positions of objects in the world, and their time derivatives, might consist of motor torque commands, and might include an image from the robot’s onboard camera. In this paper, we address finite horizon episodic tasks with . The states evolve in time according to the system dynamics , and the observations are, in general, a stochastic consequence of the states, according to . Neither the dynamics nor the observation distribution are assumed to be known in general. For notational convenience, we will use to denote the distribution over actions under the policy conditioned on the state. However, since the policy is conditioned on the observation , this distribution is in fact given by . The dynamics and together induce a distribution over trajectories :
在策略搜索中,目标是学习策略 ,它根据观测 选择动作 。系统动力学为 ,观测模型为 。轨迹分布可写成
The goal of a task is given by a cost function , and the objective in policy search is to minimize the expectation , which we will abbreviate as . A summary of the notation used in the paper is provided in Table 1.
任务目标由代价函数 给出,策略搜索最小化期望总代价。在我们的设定中,训练时可获得完整状态 (含目标物体位姿),而测试时策略只接收观测 (图像与本体感觉)。
| symbol | definition | example/details |
|---|---|---|
| Markovian system state at time step | joint angles, end-effector pose, object positions, and their velocities; dimensionality: 14 to 32 | |
| control or action at time step | joint motor torque commands; dimensionality: 7 (for the PR2 robot) | |
| observation at time step | RGB camera image, joint encoder readings & velocities, end-effector pose; dimensionality: around 200,000 | |
| trajectory: | notational shorthand for a sequence of states and actions | |
| cost function that defines the goal of the task | distance between an object in the gripper and the target | |
| unknown system dynamics | physics that govern the robot and any objects it interacts with | |
| unknown observation distribution | stochastic process that produces camera images from system state | |
| learned nonlinear global policy parameterized by weights | convolutional neural network, such as the one in Figure 2 | |
| notational shorthand for observation-based policy conditioned on state | ||
| learned local time-varying linear-Gaussian controller for initial state | time-varying linear-Gaussian controller has form | |
| trajectory distribution for : | notational shorthand for trajectory distribution induced by a policy |
Table 1: Summary of the notation frequently used in this article.
| 符号 | 定义 | 示例/细节 |
|---|---|---|
| 马尔可夫状态 | 关节角、速度、末端执行器位姿、目标物体位姿 | |
| 动作 | 关节力矩 | |
| 观测 | RGB 图像与关节配置 | |
| 策略 | 将观测映射到力矩的 CNN | |
| 代价 | 到目标点的距离、力矩惩罚等 |
3.2 Approach Summary
3.2 方法概要
Our methods consists of two main components, which are illustrated in Figure 3. The first is a supervised learning algorithm that trains policies of the form , where both and are general nonlinear functions. In our implementation, is a deep convolutional neural network, while is an observation-independent learned covariance, though other representations are possible. The second component is a trajectory-centric reinforcement learning (RL) algorithm that generates guiding distributions that provide the supervision used to train the policy. These two components form a policy search algorithm that can be used to learn complex robotic tasks using only a high-level cost function . During training, only samples from the guiding distributions are generated by running rollouts on the physical system, which avoids the need to execute partially trained neural network policies on physical hardware.
我们的方法由两个主要组件组成,如图 3 所示。第一是监督学习算法,训练形式为 的策略,其中 与 均为一般非线性函数。实现中 是深度卷积网络, 是与观测无关的可学习协方差,当然也可采用其他表示。第二是轨迹中心的强化学习(RL)算法,生成导引分布,为训练策略提供监督。两组件共同构成策略搜索算法,仅用高层代价函数即可学习复杂机器人任务。训练期间只在物理系统上执行来自导引分布的样本,从而避免在硬件上运行部分训练的神经网络策略。
Supervised learning will not, in general, produce a policy with good long-horizon performance, since a small mistake on the part of the policy will place the system into states that are outside the distribution in the training data, causing compounding errors. To avoid this issue, the training data must come from the policy’s own state distribution (Ross et al. 2011). We achieve this by alternating between trajectory-centric RL and supervised learning. The RL stage adapts to the current policy , providing supervision at states that are iteratively brought closer to the states visited by the policy. This is formalized as a variant of the BADMM algorithm (Wang and Banerjee 2014) for constrained optimization, which can be used to show that, at convergence, the policy and the guiding distributions will exhibit the same behavior. This algorithm is derived in Section 4. The guiding distributions are substantially easier to optimize than learning the policy parameters directly (e.g., using model-free reinforcement learning), because they use the full state of the system , while the policy only uses the observations. This means that the method requires the full state to be known during training, but not at test time. This makes it possible to efficiently learn complex visuomotor policies, but imposes additional assumptions on the observability of during training that we discuss in Section 4.
一般而言,监督学习不会产生具有良好长时程表现的策略,因为训练分布未必覆盖策略实际访问的状态。引导策略搜索通过交替优化导引分布与策略来解决这一点,并约束二者保持接近,从而把策略搜索变成带约束的监督学习问题。
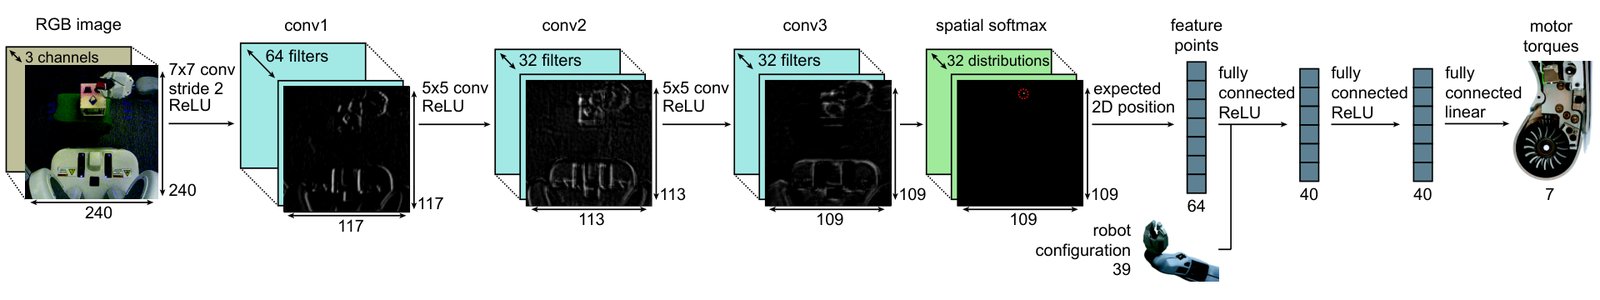
Figure 2: Visuomotor policy architecture. The network contains three convolutional layers, followed by a spatial softmax and an expected position layer that converts pixel-wise features to feature points, which are better suited for spatial computations. The points are concatenated with the robot configuration, then passed through three fully connected layers to produce the torques.
图 2:视觉运动策略架构。网络含三个卷积层,后接空间 Softmax 与期望算子以产生特征点,再与机器人配置一并送入全连接层以输出力矩。
When learning visuomotor tasks, the policy is represented by a novel convolutional neural network (CNN) architecture, which we describe in Section 5.2. CNNs have enjoyed considerable success in computer vision (LeCun et al. 2015), but the most popular architectures rely on large datasets and focus on semantic tasks such as classification, often intentionally discarding spatial information. Our architecture, illustrated in Figure 2, uses a fixed transformation from the last convolutional layer to a set of spatial feature points, which form a concise representation of the visual scene suitable for feedback control. Our network has 7 layers and around 92,000 parameters, which presents a major challenge for standard policy search methods (Deisenroth et al. 2013).
学习视觉运动任务时,策略 必须从图像推断任务相关信息(如目标位置),同时生成稳定控制。这要求感知与控制表示兼容,并在有限真实数据下泛化。
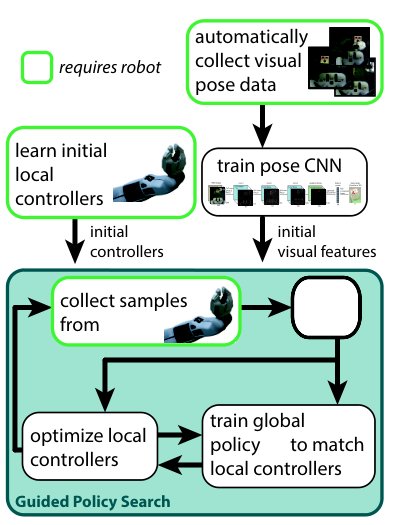
Figure 3: Diagram of our approach, including the main guided policy search phase and initialization phases.
图 3:方法示意图,包括主引导策略搜索阶段与用于加快收敛的初始化。
To reduce the amount of experience needed to train visuomotor policies, we also introduce a pretraining scheme that allows us to train effective policies with a relatively small number of iterations. The pretraining steps are illustrated in Figure 3. The intuition behind our pretraining is that, although we ultimately seek to obtain sensorimotor policies that combine both vision and control, low-level aspects of vision can be initialized independently. To that end, we pretrain the convolutional layers of our network by predicting elements of that are not provided in the observation , such as the positions of objects in the scene. We also initially train the guiding trajectory distributions independently of the convolutional network until the trajectories achieve a basic level of competence at the task, and then switch to full guided policy search with end-to-end training of . In our implementation, we also initialize the first layer filters from the model of Szegedy et al. 2014, which is trained on ImageNet (Deng et al. 2009) classification. The initialization and pretraining scheme is described in Section 5.2.
为减少训练视觉运动策略所需的经验量,我们还引入位姿预测预训练与完全观测轨迹预训练,为端到端阶段提供良好初始化。
4 Guided Policy Search with BADMM
4 基于 BADMM 的引导策略搜索
Guided policy search transforms policy search into a supervised learning problem, where the training set is generated by a simple trajectory-centric RL algorithm. This algorithm optimizes linear-Gaussian controllers , and is described in Section 4.2. We refer to the trajectory distribution induced by as . Each succeeds from different initial states. For example, in the task of placing a cap on a bottle, these initial states correspond to different positions of the bottle. By training on trajectories for multiple bottle positions, the final CNN policy can succeed from all initial states, and can generalize to other states from the same distribution.
引导策略搜索把策略搜索转化为监督学习问题,训练集由简单的轨迹中心 RL 算法生成。该算法优化线性-高斯控制器 ,见第 4.2 节。我们把由 诱导的轨迹分布记为 。每个 从不同初始状态取得成功。例如在把瓶盖放到瓶子上的任务中,这些初始状态对应瓶子的不同位置。通过在多个瓶子位置的轨迹上训练,最终 CNN 策略可从所有初始状态成功,并泛化到同分布的其他状态。
The final policy learned with guided policy search is only provided with observations of the full state , and the dynamics are assumed to be unknown. A diagram of this method, which corresponds to an expanded version of the guided policy search box in Figure 3, is shown on the right. In the outer loop, we draw sample trajectories for each initial state on the physical system by running the corresponding controller . The samples are used to fit the dynamics that are used to improve , and serve as training data for the policy. The inner loop alternates between optimizing each and optimizing the policy to match these trajectory distributions. The policy is trained to predict the actions along each trajectory from the observations , rather than the full state . This allows the policy to directly use raw observations at test time. This alternating optimization can be framed as an instance of the BADMM algorithm (Wang and Banerjee 2014), which converges to a solution where the trajectory distributions and the policy have the same state distribution. This allows greedy supervised training of the policy to produce a policy with good long-horizon performance.
用引导策略搜索学到的最终策略 只获得完整状态 的观测 ,并假定动力学未知。该方法示意图(图 3 中引导策略搜索框的展开)见右。外层循环中,在物理系统上运行对应控制器 ,为每个初始状态采集样本轨迹 。样本用于拟合改进 所需的动力学 ,并作为策略的训练数据。内层循环交替优化每个 与使策略匹配这些轨迹分布。策略被训练成根据观测 而非完整状态 预测各轨迹上的动作,从而使策略在测试时能直接使用原始观测。该交替优化可形式化为 BADMM 算法的实例。
4.1 Algorithm Derivation
4.1 算法推导
Policy search methods minimize the expected cost , where is a trajectory, and is the cost of an episode. In the fully observed case, the expectation is taken under . The final policy is conditioned on the observations , but can be recovered as . We will present the derivation in this section for , but we do not require knowledge of in the final algorithm. As discussed in Section 4.3, the integral will be evaluated with samples from the real system, which include both and . We begin by rewriting the expected cost minimization as a constrained problem:
策略搜索方法最小化期望代价 ,其中 为轨迹, 为回合代价。在完全观测情形下,期望在 下计算。最终策略 条件于观测 ,但可把 恢复为 。本节推导针对 ,但最终算法不需要知道 。如第 4.3 节所述,该积分用真实系统样本评估,样本同时包含 与 。我们首先把期望代价最小化改写为带约束的形式。
where we will refer to as a guiding distribution. This formulation is equivalent to the original problem, since the constraint forces the two distributions to be identical. However, if we approximate the initial state distribution with samples , we can choose to be a class of distributions that is much easier to optimize than , as we will show later. This will allow us to use simple local learning methods for , without needing to train the complex neural network policy directly with reinforcement learning, which would require a prohibitive amount of experience on real physical systems.
其中我们把 称为导引分布。该形式与原问题等价,因为约束迫使两分布相同。然而,若用样本 近似初始状态分布 ,可以选择比 容易优化得多的分布类作为 ,后文将说明。这将允许我们对 使用简单的局部学习方法,而无需直接用强化学习训练复杂的神经网络策略 ——后者在真实物理系统上需要禁止数量的经验。
The constrained problem can be solved by a dual descent method, which alternates between minimizing the Lagrangian with respect to the primal variables, and incrementing the Lagrange multipliers by their subgradient. Minimization of the Lagrangian with respect to and is done in alternating fashion: minimizing with respect to corresponds to supervised learning (making match ), and minimizing with respect to consists of one or more trajectory optimization problems. The dual descent method we use is based on BADMM (Wang and Banerjee 2014), a variant of ADMM (Boyd et al. 2011) that augments the Lagrangian with a Bregman divergence between the constrained variables. We use the KL-divergence as the Bregman constraint, which is particularly convenient for working with probability distributions. We will also modify the constraint by multiplying both sides by , to get . This constraint is equivalent, but has the convenient property that we can express the Lagrangian in terms of expectations. The BADMM augmented Lagrangians for and are therefore given by
约束问题可用对偶下降法求解:交替关于原变量最小化拉格朗日函数,并按次梯度递增拉格朗日乘子。关于 与 的拉格朗日最小化交替进行:对 最小化对应监督学习(使 匹配 ),对 最小化由一个或多个轨迹优化问题组成。我们使用的对偶下降基于 BADMM(Wang and Banerjee,2014),它是 ADMM(Boyd 等,2011)的变体,用约束变量之间的 Bregman 散度增强拉格朗日。我们用 KL 散度作为 Bregman 约束,这对处理概率分布特别方便。我们还将约束 两边乘以 ,得到 。该约束等价,但在表示上更方便。
where is the Lagrange multiplier for state and action at time , and are are expectations of the KL-divergences:
其中 是时刻 状态 与动作 的拉格朗日乘子, 与 是 KL 散度的期望:
Dual descent with alternating primal minimization is then described by the following steps:
带交替原问题最小化的对偶下降由以下步骤描述:
This procedure is an instance of BADMM, and therefore inherits its convergence guarantees. Note that we drop terms that are independent of the optimization variables on each line. The parameter is a step size. As with most augmented Lagrangian methods, the weight is set heuristically, as described in Appendix A.1.
该流程是 BADMM 的实例,因而继承其收敛保证。注意每行我们丢掉与优化变量无关的项。参数 是步长。与多数增强拉格朗日方法一样,权重 启发式设定,见附录 A.1。
The dynamics only affect the optimization with respect to . In order to make this optimization efficient, we choose to be a mixture of Gaussians , one for each initial state sample . This makes the action conditionals and the dynamics linear-Gaussian, as discussed in Section 4.2. This is a reasonable choice when the system is deterministic, or the noise is Gaussian or small, and we found that this approach is sufficiently tolerant to noise for use on real physical systems. Our choice of also assumes that the policy is conditionally Gaussian. This is also reasonable, since the mean and covariance of can be any nonlinear function of the observations , which themselves are a function of the unobserved state . In Section 4.2, we show how these assumptions enable each to be optimized very efficiently. We will refer to as guiding distributions, since they serve to focus the policy on good, low-cost behaviors.
动力学只影响关于 的优化。为使该优化高效,我们选择 为 个高斯 的混合,每个对应一个初始状态样本 。这使得动作条件 与动力学 为线性-高斯,见第 4.2 节。当系统确定性、或噪声为高斯或较小时,这是合理选择;我们发现该方法对噪声的容忍足以用于真实物理系统。对 的选择也假定策略 为条件高斯。这也合理,因为其均值与协方差可以是观测 的任意非线性函数,而观测本身又是未观测状态 的函数。第 4.2 节说明这些假定如何使每个 能被非常高效地优化。我们称 为导引分布,因为它们把策略聚焦到良好行为上。
Aside from learning , we must choose a tractable way to represent the infinite set of constraints . One approximate approach proposed in prior work is to replace the exact constraints with expectations of features (Peters et al. 2010). When the features consist of linear, quadratic, or higher order monomial functions of the random variable, this can be viewed as a constraint on the moments of the distributions. If we only use the first moment, we get a constraint on the expected action: . If the stochasticity in the dynamics is low, as we assumed previously, the optimal solution for each will have low entropy, making this first moment constraint a reasonable approximation. The KL-divergence terms in the augmented Lagrangians will still serve to softly enforce agreement between the higher moments. While this simplification is quite drastic, we found that it was more stable in practice than including higher moments, likely because these higher moments are harder to estimate accurately with a limited number of samples. The alternating optimization is now given by
除学习 外,还必须选择可处理的方式表示无穷约束集 。先前工作提出的一种近似是用特征期望代替精确约束(Peters 等,2010)。当特征由随机变量的线性、二次或更高阶单项式组成时,可视为对分布矩的约束。若只用一阶矩,得到期望动作约束:。若动力学随机性较低(如前假定),每个 的最优解熵较低,使该一阶矩约束成为合理近似。增强拉格朗日中的 KL 项仍会软性地强制更高阶矩一致。尽管这一简化相当剧烈,我们发现它在实践中比包含二阶矩更稳定。
where is the Lagrange multiplier on the expected action at time . In the rest of the paper, we will use and to denote the two augmented Lagrangians in Equations (2) and (3), respectively. In the next two sections, we will describe how can be optimized with respect to under unknown dynamics, and how can be optimized for complex, high-dimensional policies. Implementation details of the BADMM optimization are presented in Appendix A.1.
其中 是时刻 期望动作上的拉格朗日乘子。后文用 与 分别表示式 (2) 与 (3) 中的两个增强拉格朗日。下面两节说明如何在未知动力学下关于 优化 ,以及如何对复杂高维策略优化 。BADMM 优化的实现细节见附录 A.1。
4.2 Trajectory Optimization under Unknown Dynamics
4.2 未知动力学下的轨迹优化
Since the Lagrangian in the previous section factorizes over the mixture elements in , we describe the trajectory optimization method for a single Gaussian . When there are multiple mixture elements, this procedure is applied in parallel to each . Since is Gaussian, the conditionals and , which correspond to the dynamics and the controller, are time-varying linear-Gaussian, and given by
由于上一节拉格朗日 在混合 的各成分上因子分解,我们描述单个高斯 的轨迹优化方法。有多个混合成分时,该流程对每个 并行应用。由于 为高斯,条件分布 与 (对应动力学与控制器)为时变线性-高斯,并由下式给出
This type of controller can be learned efficiently with a small number of real-world samples, making it a good choice for optimizing the guiding distributions. Since a different set of time-varying linear-Gaussian dynamics is fitted for each initial state, this dynamics representation can model any continuous deterministic system that can be locally linearized. Stochastic dynamics can violate the local linearity assumption in principle, but we found that in practice this representation was well suited for a wide variety of noisy real-world tasks.
这类控制器可用少量真实世界样本高效学习,适合优化导引分布。由于为每个初始状态拟合不同的时变线性-高斯动力学,该动力学表示可建模任何可局部线性化的连续确定性系统。随机动力学原则上可能违反局部线性假定,但实践中我们发现该表示适合多种带噪声的真实世界任务。
The dynamics are determined by the environment. If they are known, can be optimized with a variant of the iterative linear-quadratic-Gaussian regulator (iLQG) (Li and Todorov 2004; Levine and Koltun 2013a), which is a variant of DDP (Jacobson and Mayne 1970). In the case of unknown dynamics, we can fit to sample trajectories sampled from the trajectory distribution at the previous iteration, denoted . If is too different from , these samples will not give a good estimate of , and the optimization will diverge. To avoid this, we can bound the change from to in terms of their KL-divergence by a step size , producing the following constrained problem:
动力学由环境决定。若已知,可用迭代线性二次高斯调节器(iLQG)的变体(Li and Todorov,2004;Levine and Koltun,2013a)优化 ,iLQG 是 DDP(Jacobson and Mayne,1970)的变体。在未知动力学时,可用上一迭代轨迹分布(记为 )采得的样本轨迹拟合 。若 与 相差过大,这些样本不能很好估计动力学,优化会发散。为避免这一点,可用 KL 散度约束从 到 的变化。
This type of policy update has previously been proposed by several authors in the context of policy search (Bagnell and Schneider 2003; Peters and Schaal 2008; Peters et al. 2010; Levine and Abbeel 2014). In the case when is Gaussian, this problem can be solved efficiently using dual gradient descent, while the dynamics are fitted to samples gathered by running the previous controller on the robot. Fitting a global Gaussian mixture model to tuples and using it as a prior for fitting the dynamics serves to greatly reduce the sample complexity. We describe the dynamics fitting procedure in detail in Appendix A.3.
这类策略更新此前已有若干作者在策略搜索语境中提出(Bagnell and Schneider,2003;Peters and Schaal,2008;Peters 等,2010;Levine and Abbeel,2014)。当 为高斯时,可用对偶梯度下降高效求解;动力学 拟合到在机器人上运行上一控制器 得到的样本。对元组 拟合全局高斯混合模型并用作拟合动力学的先验,可大幅降低样本复杂度。动力学拟合流程见附录。
Note that the trajectory optimization cost function also depends on the policy , while we only have access to . In order to compute a local quadratic expansion of the KL-divergence term inside for iLQG, we also estimate a linearization of the mean of the conditionally Gaussian policy with respect to the state , using the same procedure that we use to linearize the dynamics. The data for this estimation consists of tuples , which we can obtain because both the states and the observations are available for all of the samples evaluated on the real physical system.
注意轨迹优化代价 也依赖于策略 ,而我们只有 。为对 内 KL 项 做局部二次展开以用于 iLQG,我们还估计条件高斯策略均值关于状态 的线性化,使用与线性化动力学相同的流程。该估计的数据由元组构成,含状态与策略在对应观测下的期望动作。
This constrained optimization is performed in the “inner loop” of the optimization described in the previous section, and the KL-divergence constraint imposes a step size on the trajectory update. The overall algorithm then becomes an instance of generalized BADMM (Wang and Banerjee 2014). Note that the augmented Lagrangian consists of an expectation under of a quantity that is independent of . We can locally approximate this quantity with a quadratic by using a quadratic expansion of , and fitting a linear-Gaussian to with the same method we used for the dynamics. We can then solve the primal optimization in the dual gradient descent procedure with a standard LQR backward pass. This is significantly simpler and much faster than the forward-backward dynamic programming procedure employed in previous work (Levine and Abbeel 2014; Levine and Koltun 2014). This improvement is enabled by the use of BADMM, which allows us to always formulate the KL-divergence term in the Lagrangian with the distribution being optimized as the first argument. Since the KL-divergence is convex in its first argument, this makes the corresponding optimization significantly easier. The details of this LQR-based dual gradient descent algorithm are derived in Appendix A.4.
该约束优化在上一节所述优化的“内层循环”中执行,KL 约束 对轨迹更新施加步长。整体算法于是成为广义 BADMM 的实例(Wang and Banerjee,2014)。注意增强拉格朗日 由 下某个与 无关的量的期望组成。我们可用 的二次展开,并用与动力学相同的方法对 拟合线性-高斯,从而局部把该量近似为二次,再在对偶下降中求解原问题。
We can further improve the efficiency of the method by allowing samples from multiple trajectories to be used to fit a shared dynamics , while the controllers are allowed to vary. This makes sense when the initial states of these trajectories are similar, and they therefore visit similar regions. This allows us to draw just a single sample from each at each iteration, allowing us to handle many more initial states.
还可通过允许来自多条轨迹 的样本拟合共享动力学 ,同时允许控制器 不同,进一步提高效率。当这些轨迹初始状态相近因而访问相似区域时,这是合理的。这使我们每次迭代只需从每个 采一个样本,从而能处理更多初始状态。
4.3 Supervised Policy Optimization
4.3 有监督的策略优化
Since the policy parameters participate only in the constraints of the optimization problem in Equation (1), optimizing the policy corresponds to minimizing the KL-divergence between the policy and trajectory distribution, as well as the expectation of . For a conditional Gaussian policy of the form , the objective is
由于策略参数 只参与式 (1) 优化问题的约束,优化策略对应于最小化策略与轨迹分布之间的 KL 散度,以及 的期望。对形式为 的条件高斯策略,目标为
where is the mean of and is the covariance, and the expectation is evaluated using samples from each with corresponding observations . The observations are sampled from by recording camera images on the real system. Since the input to and is not the state , but only an observation , we can train the policy to directly use raw observations. Note that is simply a weighted quadratic loss on the difference between the policy mean and the mean action of the trajectory distribution, offset by the Lagrange multiplier. The weighting is the precision matrix of the conditional in the trajectory distribution, which is equal to the curvature of its cost-to-go function (Levine and Koltun 2013a). This has an intuitive interpretation: penalizes deviation from the trajectory distribution, with a penalty that is locally proportional to its cost-to-go. At convergence, when the policy takes the same actions as , their Q-functions are equal, and the supervised policy objective becomes equivalent to the policy iteration objective (Levine and Koltun 2014)
其中 是 的均值, 是协方差,期望用各 的样本及对应观测 评估。观测通过在真实系统上记录相机图像从 采样。由于 与 的输入不是状态 而只是观测 ,我们可以训练策略直接使用原始观测。注意 本质上是策略均值与轨迹分布均值动作之差(再偏移拉格朗日乘子)上的加权二次损失。
In this work, we optimize with respect to using stochastic gradient descent (SGD), a standard method for neural network training. The covariance of the Gaussian policy does not depend on the observation in our implementation, though adding this dependence would be straightforward. Since training complex neural networks requires a substantial number of samples, we found it beneficial to include sampled observations from previous iterations into the policy optimization, evaluating the action at their corresponding states using the current trajectory distributions. Since these samples come from the wrong state distribution, we use importance sampling and weight them according to the ratio of their probability under the current distribution and the one they were sampled from, which is straightforward to evaluate under the estimated linear-Gaussian dynamics (Levine and Koltun 2013b).
本文用随机梯度下降(SGD)关于 优化 ,这是神经网络训练的标准方法。实现中高斯策略的协方差不依赖于观测,但加入该依赖是直接的。由于训练复杂网络需要大量样本,我们发现把先前迭代的采样观测纳入策略优化有益:用当前轨迹分布在其对应状态上评估动作 。由于这些样本来自错误的状态分布,我们使用重要性采样,按其在当前与先前轨迹分布下的概率比加权。
4.4 Comparison with Prior Guided Policy Search Methods
4.4 与先前引导策略搜索方法的比较
We presented a guided policy search method where the policy is trained on observations, while the trajectories are trained on the full state. The BADMM formulation of guided policy search is new to this work, though several prior guided policy search methods based on constrained optimization have been proposed. Levine and Koltun 2014 proposed a formulation similar to Equation (1), but with a constraint on the KL-divergence between and . This results in a more complex, non-convex forward-backward trajectory optimization phase. Since the BADMM formulation solves a convex problem during the trajectory optimization phase, it is substantially faster and easier to implement and use, especially when the number of trajectories is large.
我们提出一种引导策略搜索方法:策略在观测上训练,轨迹在完整状态上训练。引导策略搜索的 BADMM 形式化是本文新内容,尽管已有若干基于约束优化的先前引导策略搜索方法。Levine 与 Koltun(2014)提出类似式 (1) 的形式,但对 与 之间的 KL 散度施加约束。这导致更复杂、非凸的前向-后向轨迹优化阶段。由于 BADMM 形式化在轨迹优化阶段求解凸问题,它显著更快、更易实现与使用,尤其当轨迹数 很大时。
The use of ADMM for guided policy search was also proposed by Mordatch and Todorov 2014 for deterministic policies under known dynamics. This approach requires known, deterministic dynamics and trains deterministic policies. Furthermore, because this approach uses a simple quadratic augmented Lagrangian term, it further requires penalty terms on the gradient of the policy to account for local feedback. Our approach enforces this feedback behavior due to the higher moments included in the KL-divergence term, but does not require computing the second derivative of the policy.
Mordatch 与 Todorov(2014)也曾为已知动力学下的确定性策略提出用 ADMM 做引导策略搜索。该方法需要已知、确定性动力学并训练确定性策略。此外,因其使用简单二次增强拉格朗日项,还需要在策略梯度上加惩罚项以刻画局部反馈。我们的方法由于 KL 项包含更高阶矩而强制这种反馈行为,但不需要计算策略的二阶导数。
5 End-to-End Visuomotor Policies
5 端到端视觉运动策略
Guided policy search allows us to optimize complex, high-dimensional policies with raw observations, such as when the input to the policy consists of images from a robot’s onboard camera. However, leveraging this capability to directly learn policies for visuomotor control requires designing a policy representation that is both data-efficient and capable of learning complex control strategies directly from raw visual inputs. In this section, we describe a deep convolutional neural network (CNN) model that is uniquely suited to this task. Our approach combines a novel spatial soft-argmax layer with a pretraining procedure that provides for flexibility and data-efficiency.
引导策略搜索使我们能优化带原始观测的复杂高维策略,例如策略输入为机器人机载相机图像时。然而,要利用这一能力直接学习视觉运动控制策略,需要设计既样本高效、又能直接从原始视觉输入学习复杂控制策略的策略表示。本节描述特别适合该任务的深度卷积网络(CNN)模型。我们的方法结合新颖的空间 soft-argmax 层与提供灵活性与数据效率的预训练流程。
5.1 Visuomotor Policy Architecture
5.1 视觉运动策略架构
Our visuomotor policy runs at 20 Hz on the robot, mapping monocular RGB images and the robot configurations to joint torques on a 7 DoF arm. The configuration includes the angles of the joints and the pose of the end-effector (defined by 3 points in the space of the end-effector), as well as their velocities, but does not include the position of the target object or goal, which must be determined from the image. CNNs often use pooling to discard the locational information that is necessary to determine positions, since it is an irrelevant distractor for tasks such as object classification (Lee et al. 2009). Because locational information is important for control, our policy does not use pooling. Additionally, CNNs built for spatial tasks such as human pose estimation often also rely on the availability of location labels in image-space, such as hand-labeled keypoints (Tompson et al. 2014). We propose a novel CNN architecture capable of estimating spatial information from an image without direct supervision in image space. Our pose estimation experiments, discussed in Section 5.2, show that this network can learn useful visual features using only 3D position information provided by the robot, and no camera calibration. Further training the network with guided policy search to directly output motor torques causes it to acquire task-specific visual features. Our experiments in Section 6.4 show that this improves performance beyond the level achieved with features trained only for pose estimation.
我们的视觉运动策略在机器人上以 20 Hz 运行,把单目 RGB 图像与机器人配置映射到 7 自由度臂的关节力矩。配置包括关节角、末端执行器位姿(由末端执行器空间中的 3 个点定义)及其速度,但不包含目标物体或目标位置——后者必须从图像确定。CNN 常使用池化丢弃确定位置所需的定位信息,因为对物体分类等任务而言它是无关干扰(Lee 等,2009)。由于定位信息对控制很重要,我们的策略不使用池化。此外,面向人体姿态估计等空间任务的 CNN 往往还依赖图像空间中的位置标注,如手标关键点(Tompson 等,2014)。我们提出一种新型 CNN 架构,能在没有图像空间直接监督的情况下从图像估计空间信息。第 5.2 节的位姿估计实验表明,该网络仅用机器人运动学提供的 3D 位置信息即可学到有用视觉特征。
Our network architecture is shown in Figure 2. The visual processing layers of the network consist of three convolutional layers, each of which learns a bank of filters that are applied to patches centered on every pixel of its input. These filters form a hierarchy of local image features. Each convolutional layer is followed by a rectifying nonlinearity of the form for each channel and each pixel coordinate . The third convolutional layer contains response maps with resolution . These response maps are passed through a spatial softmax function of the form . Each output channel of the softmax is a probability distribution over the location of a feature in the image. To convert from this distribution to a coordinate representation , the network calculates the expected image position of each feature, yielding a 2D coordinate for each channel: and , where is the image-space position of the point in the response map. Since this is a linear operation, it corresponds to a fixed, sparse fully connected layer with weights and . The combination of the spatial softmax and expectation operator implement a kind of soft-argmax. The spatial feature points are concatenated with the robot’s configuration and fed into two fully connected layers, each with 40 rectified units, followed by linear connections to the torques. The full network contains about 92,000 parameters, of which 86,000 are in the convolutional layers.
网络架构见图 2。视觉处理层由三个卷积层组成,每层学习一组在每个像素为中心的图像块上应用的滤波器,形成局部图像特征的层次。每个卷积层后接形式为 的整流非线性。第三卷积层含 张分辨率为 的响应图。这些响应图通过形式为 的空间 Softmax。Softmax 的每个输出通道是图像中某特征位置的概率分布。为把该分布转为坐标表示 ,网络计算每个特征的期望图像位置,从而为每个通道得到二维坐标:,,其中 是响应图中点 的图像空间位置。
The spatial softmax and the expected position computation serve to convert pixel-wise representations in the convolutional layers to spatial coordinate representations, which can be manipulated by the fully connected layers into 3D positions or motor torques. The softmax also provides lateral inhibition, which suppresses low, erroneous activations, only keeping strong activations that are more likely to be accurate. This makes our policy more robust to distractors, providing generalization to novel visual variation. We compare our architecture with more standard alternatives in Section 6.3 and evaluate robustness to visual distractors in Section 6.4. However, the proposed architecture is also in some sense more specialized for visuomotor control, in contrast to more general standard convolutional networks. For example, not all perception tasks require information that can be coherently summarized by a set of spatial locations.
空间 Softmax 与期望位置计算把卷积层中的逐像素表示转换为空间坐标表示,再由全连接层操作成 3D 位置或电机力矩。Softmax 还提供侧抑制,压制低且错误的激活,只保留更可能准确的强激活。这使策略对干扰物更稳健,从而泛化到新的视觉变化。我们在第 6.3 节与更标准替代架构比较,并在第 6.4 节评估对视觉干扰物的稳健性。不过,所提架构在某种意义上也更专门服务于视觉运动控制,而不同于更通用的标准卷积网络。例如,并非所有感知任务都需要能由一组空间位置连贯概括的信息。
5.2 Visuomotor Policy Training
5.2 视觉运动策略训练
The guided policy search trajectory optimization phase uses the full state of the system, though the final policy only uses the observations. This type of instrumented training is a natural choice for many robotics tasks, where the robot is trained under controlled conditions, but must then act intelligently in uncontrolled, real-world situations. In our tasks, the unobserved variables are the pose of a target object (e.g. the bottle on which a cap must be placed). During training, this target object is typically held in the robot’s left gripper, while the robot’s right arm performs the task, as shown to the right. This allows the robot to move the target through a range of known positions. The final visuomotor policy does not receive this position as input, but must instead use the camera images. Due to the modest amount of training data, distractors that are correlated with task-relevant variables can hamper generalization. For this reason, the left arm is covered with cloth to prevent the policy from associating its appearance with the object’s position.
引导策略搜索的轨迹优化阶段使用系统完整状态,而最终策略只用观测。这种“仪器化训练”对许多机器人任务是自然选择:机器人在受控条件下训练,然后须在不受控的真实情境中智能行动。在我们的任务中,未观测变量是目标物体的位姿(例如须放上瓶盖的瓶子)。训练时该目标物体通常由机器人左夹爪持有,右臂执行任务,如右图所示。这使机器人能把目标移过一系列已知位置。最终视觉运动策略不接收该位置作为输入,而必须使用相机图像。由于训练数据量适中,与任务相关变量相关的干扰物会妨碍泛化。因此左臂用布遮盖,防止策略把它的外观与物体位置关联。
While we can train the visuomotor policy entirely from scratch, the algorithm would spend a large number of iterations learning basic visual features and arm motions that can more efficiently be learned by themselves, before being incorporated into the policy. To speed up learning, we initialize both the vision layers in the policy and the trajectory distributions for guided policy search by leveraging the fully observed training setup. To initialize the vision layers, the robot moves the target object through a range of random positions, recording camera images and the object’s pose, which is computed automatically from the pose of the gripper. This dataset is used to train a pose regression CNN, which consists of the same vision layers as the policy, followed by a fully connected layer that outputs the 3D points that define the target. Since the training set is still small (we use 1000 images collected from random arm motions), we initialize the filters in the first layer with weights from the model of Szegedy et al. 2014, which is trained on ImageNet (Deng et al. 2009) classification. After training on pose regression, the weights in the convolutional layers are transferred to the policy CNN. This enables the robot to learn the appearance of the objects prior to learning the behavior.
虽然可以从头训练视觉运动策略,算法会花费大量迭代学习基本视觉特征与手臂运动——这些本可先单独更高效地学会再并入策略。为加速学习,我们利用完全观测的训练设置,同时初始化策略中的视觉层与引导策略搜索的轨迹分布。为初始化视觉层,机器人把目标物体移过一系列随机位置,记录相机图像与物体位姿(由夹爪位姿自动计算)。该数据集用于训练位姿回归 CNN:与策略相同的视觉层,后接输出定义目标的 3D 点的全连接层。由于训练集仍较小(我们用随机手臂运动采集的 1000 张图像),第一层滤波器用 Szegedy 等(2014)在 ImageNet(Deng 等,2009)分类上训练的模型权重初始化。位姿回归训练后,卷积层权重迁移到策略。
To initialize the linear-Gaussian controllers for each of the initial states, we take 15 iterations of guided policy search without optimizing the visuomotor policy. This allows for much faster training in the early iterations, when the trajectories are not yet successful, and optimizing the full visuomotor policy is unnecessarily time consuming. Since we still want the trajectories to arrive at compatible strategies for each target position, we replace the visuomotor policy during these iterations with a small network that receives the full state, which consisted of two layers with 40 rectified linear hidden units in our experiments. This network serves only to constrain the trajectories and avoid divergent behaviors from emerging for similar initial states, which would make subsequent policy learning difficult.
为初始化各初始状态的线性-高斯控制器,我们先做 15 次不优化视觉运动策略的引导策略搜索迭代。这使早期迭代(轨迹尚未成功、优化完整视觉运动策略不必要地耗时时)训练快得多。由于仍希望各目标位置的轨迹到达相容策略,这些迭代中用接收完整状态的小网络替换视觉运动策略;实验中该网络为两层、每层 40 个整流线性隐单元。该网络只用于约束轨迹,避免对相似初始状态出现发散行为,否则后续策略学习会变难。
After initialization, we train the full visuomotor policy with guided policy search. During the supervised policy optimization phase, the fully connected motor control layers are first optimized by themselves, since they are not initialized with pretraining. This can be done very quickly because these layers are small. Then, the entire network is further optimized end-to-end. We found that first training the upper layers before end-to-end optimization prevented the convolutional layers from forgetting useful features learning during pretraining, when the error signal due to the untrained upper layers is very large. The entire pretraining scheme is summarized in the diagram on the right. Note that the trajectories can be pretrained in parallel with the vision layer pretraining, which does not require access to the physical system. Furthermore, the entire initialization procedure does not use any additional information that is not already available from the robot.
初始化后,用引导策略搜索训练完整视觉运动策略。在有监督策略优化阶段,先单独优化全连接电机控制层,因为它们未经预训练初始化;这些层很小,可很快完成。然后整网进一步端到端优化。我们发现先训练上层再端到端优化,可防止卷积层在未训练上层误差信号很大时忘记预训练学到的有用特征。整个预训练方案概括见右图。注意轨迹可与视觉层预训练并行(后者不需要接触物理系统)。此外,整个初始化流程不使用机器人上本不可得的额外信息。
6 Experimental Evaluation
6 实验评估
In this section, we present a series of experiments aimed at evaluating our approach and answering the following questions:
本节给出一系列实验,旨在评估我们的方法并回答下列问题:
- How does the guided policy search algorithm compare to other policy search methods for training complex, high-dimensional policies, such as neural networks?
- Does our trajectory optimization algorithm work on a real robotic platform with unknown dynamics, for a range of different tasks?
- How does our spatial softmax architecture compare to other, more standard convolutional neural network architectures?
- Does training the perception and control systems in a visuomotor policy jointly end-to-end provide better performance than training each component separately?
- 引导策略搜索算法与其他策略搜索方法相比,在训练神经网络等复杂高维策略时表现如何?
- 我们的轨迹优化算法能否在动力学未知的真实机器人平台上,对一系列不同任务奏效?
- 我们的空间 Softmax 架构与其他更标准的卷积网络架构相比如何?
- 在视觉运动策略中联合端到端训练感知与控制系统,是否比分开训练各组件表现更好?
Evaluating a wide range of policy search algorithms on a real robot would be extremely time consuming, particularly for methods that require a large number of samples. We therefore answer question (1) by using a physical simulator and simpler policies that do not use vision. This also allows us to test the generality of guided policy search on tasks that include manipulation, walking, and swimming. To answer question (2), we present a wide range of experiments on a PR2 robot. These experiments allow us to evaluate the sample efficiency of our trajectory optimization algorithm. To address question (3), we compare a range of different policy architectures on the task of localizing a target object (the cube in the shape sorting cube task). Since localizing the target object is a prerequisite for completing the shape sorting cube task, this serves as a good proxy for evaluating different architectures. Finally, we answer the last and most important question (4) by training visuomotor policies for hanging a coat hanger on a clothes rack, inserting a block into a shape sorting cube, fitting the claw of a toy hammer under a nail with various grasps, and screwing on a bottle cap. These tasks are illustrated in Figure 8.
在真实机器人上评估大量策略搜索算法会极其耗时,尤其对需要大量样本的方法。因此我们用物理仿真与不使用视觉的较简单策略回答问题 (1)。这也让我们能在包含操作、行走与游泳的任务上测试引导策略搜索的一般性。为回答问题 (2),我们在 PR2 上给出大量实验,以评估轨迹优化算法的样本效率。为回答问题 (3),我们在定位目标物体的任务上比较一系列不同策略架构。为回答问题 (4),我们在完整视觉运动策略上比较端到端训练与分模块训练。
6.1 Simulated Comparisons to Prior Policy Search Methods
6.1 与先前策略搜索方法的仿真比较
In this section, we compare our method against prior policy search techniques on a range of simulated robotic control tasks. These results previously appeared in our conference paper that introduced the trajectory optimization procedure with local linear models (Levine and Abbeel 2014). In these tasks, the state consists of the joint angles and velocities of each robot, and the actions consist of the torques at each joint. The neural network policies used one hidden layer and soft rectifier nonlinearities of the form . Since these policies use the state as input, they only have a few hundred parameters, far fewer than our visuomotor policies. However, even this number of parameters can pose a major challenge for prior policy search methods (Deisenroth et al. 2013).
本节在一系列仿真机器人控制任务上把我们的方法与先前策略搜索技术比较。这些结果此前出现在引入带局部线性模型的轨迹优化流程的会议论文中(Levine and Abbeel,2014)。这些任务中,状态 由各机器人关节角与速度组成,动作 为各关节力矩。神经网络策略使用一个隐层与形式为 的软整流非线性。由于这些策略以状态为输入,参数只有几百个,远少于我们的视觉运动策略。
Experimental tasks.
实验任务。
We simulated 2D and 3D peg insertion, octopus arm control, and planar swimming and walking. The difficulty in the peg insertion tasks stems from the need to align the peg with the slot and the complex contacts between the peg and the walls, which result in discontinuous dynamics. Octopus arm control involves moving the tip of a flexible arm to a goal position (Engel et al. 2005). The challenge in this task stems from its high dimensionality: the arm has degrees of freedom, corresponding to state dimensions. The swimming task requires controlling a three-link snake, and the walking task requires a seven-link biped to maintain a target velocity. The challenge in these tasks comes from underactuation. Details of the simulation and cost for each task are in Appendix B.1.
我们仿真了 2D 与 3D 插钉、章鱼臂控制以及平面游泳与行走。插钉任务的困难来自需要对齐钉与槽,以及钉与壁之间导致动力学不连续的复杂接触。章鱼臂控制要求把柔性臂尖端移到目标位置(Engel 等,2005),挑战来自高维: 自由度对应 维状态。游泳任务控制三连杆蛇形机器人,行走任务要求七连杆双足保持目标速度。
Prior methods.
先前方法。
We compare to REPS (Peters et al. 2010), reward-weighted regression (RWR) (Peters and Schaal 2007; Kober and Peters 2009), the cross-entropy method (CEM) (Rubinstein and Kroese 2004), and PILCO (Deisenroth and Rasmussen 2011). We also use iLQG (Li and Todorov 2004) with a known model as a baseline, shown as a black horizontal line in all plots. REPS is a model-free method that, like our approach, enforces a KL-divergence constraint between the new and old policy. We compare to a variant of REPS that also fits linear dynamics to generate 500 pseudo-samples (Lioutikov et al. 2014), which we label “REPS (20 + 500).” RWR is an EM algorithm that fits the policy to previous samples weighted by the exponential of their reward, and CEM fits the policy to the best samples in each batch. With Gaussian trajectories, CEM and RWR only differ in the weights. These methods represent a class of RL algorithms that fit the policy to weighted samples, including PoWER and PI2 (Kober and Peters 2009; Theodorou et al. 2010; Stulp and Sigaud 2012). PILCO is a model-based method that uses a Gaussian process to learn a global dynamics model that is used to optimize the policy. We used the open-source implementation of PILCO provided by the authors. Both REPS and PILCO require solving large nonlinear optimizations at each iteration, while our method does not. Our method used rollouts with the Gaussian mixture model prior, and without. Due to its computational cost, PILCO was provided with rollouts per iteration, while other prior methods used and . For all prior methods with free hyperparameters (such as the fraction of elites for CEM), we performed hyperparameter sweeps and chose the most successful settings for the comparison.
我们与 REPS(Peters 等,2010)、奖励加权回归(RWR)(Peters and Schaal,2007;Kober and Peters,2009)、交叉熵方法(CEM)(Rubinstein and Kroese,2004)以及 PILCO(Deisenroth and Rasmussen,2011)比较。也用已知模型的 iLQG(Li and Todorov,2004)作为基线,在所有图中以黑色水平线表示。
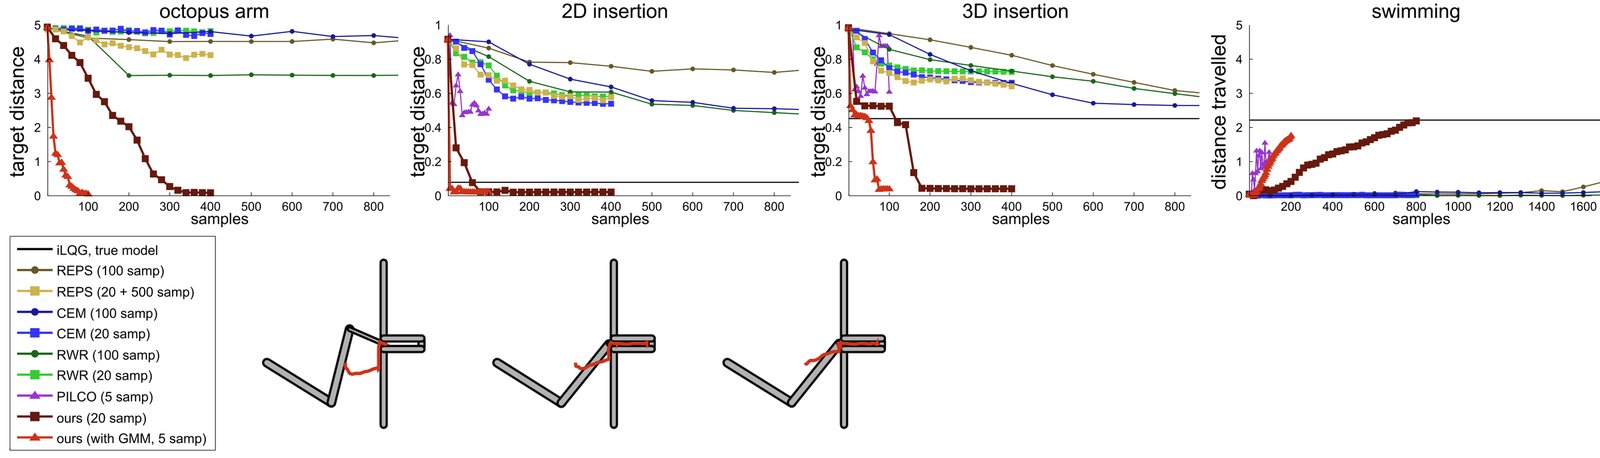
Figure 4: Results for learning linear-Gaussian controllers for 2D and 3D insertion, octopus arm, and swimming. Our approach uses fewer samples and finds better solutions than prior methods, and the GMM further reduces the required sample count. Images in the lower-right show the last time step for each system at several iterations of our method, with red lines indicating end effector trajectories.
图 4:学习 2D/3D 插入、章鱼臂与游泳的线性-高斯控制器的结果。我们的方法用更少样本找到比先前方法更好的解,GMM 进一步降低所需样本数。右下图像显示若干迭代中各系统最后时间步,红线为末端执行器轨迹。
Gaussian trajectory distributions.
高斯轨迹分布。
In the first set of comparisons, we evaluate only the trajectory optimization procedure for training linear-Gaussian controllers under unknown dynamics to determine its sample-efficiency and applicability to complex, high-dimensional problems. The results of this comparison for the peg insertion, octopus arm, and swimming tasks appears in Figure 4. The horizontal axis shows the total number of samples, and the vertical axis shows the minimum distance between the end of the peg and the bottom of the slot, the distance to the target for the octopus arm, or the total distance travelled by the swimmer. Since the peg is units long, distances above this amount correspond to controllers that cannot perform an insertion. Our method learned much more effective controllers with fewer samples, especially when using the Gaussian mixture model prior. On 3D insertion, it outperformed the iLQG baseline, which used a known model. Contact discontinuities cause problems for derivative-based methods like iLQG, as well as methods like PILCO that learn a smooth global dynamics model. We use a time-varying local model, which preserves more detail, and fitting the model to samples has a smoothing effect that mitigates discontinuity issues. Prior policy search methods could servo to the hole, but were unable to insert the peg. On the octopus arm, our method succeeded despite the high dimensionality of the state and action spaces.[^1] Our method also successfully learned a swimming gait, while prior model-free methods could not initiate forward motion. PILCO also learned an effective gait due to the smooth dynamics of this task, but its GP-based optimization required orders of magnitude more computation time than our method, taking about 50 minutes per iteration. In the case of prior model-free methods, the high dimensionality of the time-varying linear-Gaussian controllers likely caused considerable difficulty (Deisenroth et al. 2013), while our approach exploits the structure of linear-Gaussian controllers for efficient learning.
第一组比较只评估在未知动力学下训练线性-高斯控制器的轨迹优化流程,以确定其样本效率与对复杂高维问题的适用性。插钉、章鱼臂与游泳任务的结果见图 4。横轴为总样本数,纵轴为钉端到槽底最小距离、章鱼臂到目标距离或游泳者总行程。由于钉长 单位,高于此的距离表示未插入。我们的方法用更少样本达到更好性能;用 GMM 先验拟合动力学可进一步减少样本。
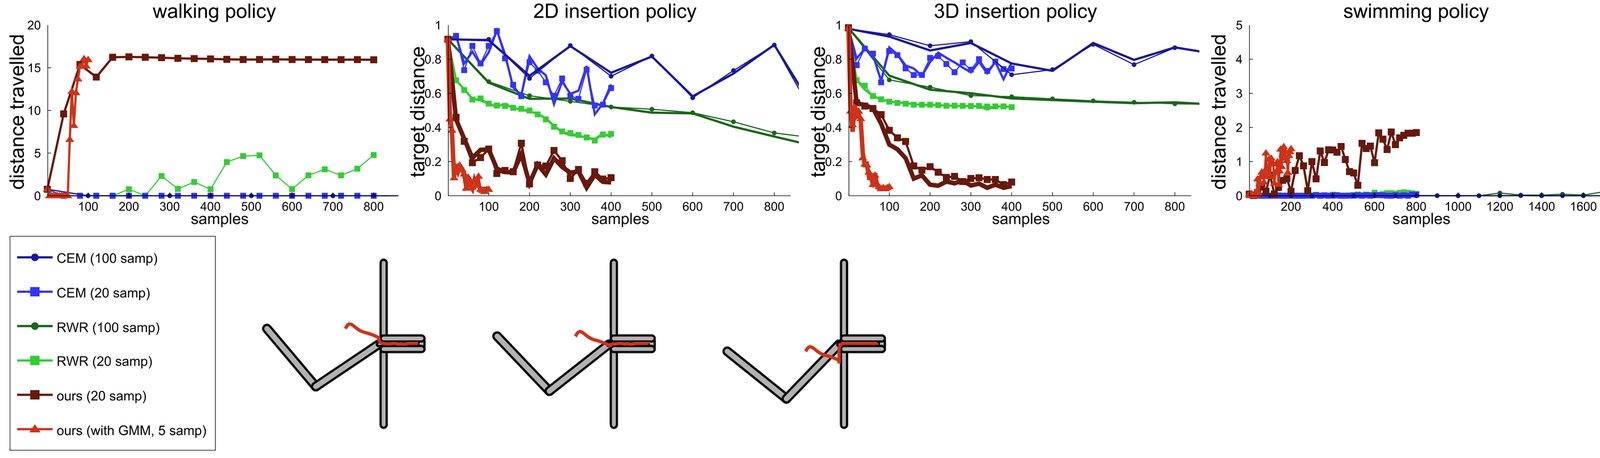
Figure 5: Comparison on neural network policies. For insertion, the policy was trained to search for an unknown slot position on four slot positions (shown above). Generalization to new positions is graphed with dashed lines. Note how the end effector (red) follows the surface to find the slot, and how the swimming gait is smoother due to the stationary policy.
图 5:神经网络策略上的比较。对插入任务,策略在四个槽位置上训练以搜索未知槽位置(上图)。虚线为对新位置的泛化。注意末端执行器(红)沿表面滑动寻找槽,以及由于平稳策略游泳步态更平滑。
Neural network policies.
神经网络策略。
In the second set of comparisons, shown in Figure 5, we compare guided policy search to RWR and CEM[^2] on the challenging task of training high-dimensional neural network policies for the peg insertion and locomotion tasks. The variant of guided policy search used in this comparison differs somewhat from the version described in Section 4, in that it used a simpler dual gradient descent formulation, rather than BADMM. In practice, we found the performance of these methods to be very similar, though the BADMM variant was substantially faster and easier to implement.
第二组比较见图 5,在插钉与运动任务上把引导策略搜索与 RWR、CEM 比较,训练高维神经网络策略。该比较中使用的引导策略搜索变体与第 4 节所述略有不同:使用更简单的对偶梯度下降形式而非 BADMM。实践中我们发现性能相似,但 BADMM 形式化更易扩展到视觉运动设定。
On swimming, our method achieved similar performance to the linear-Gaussian case, but since the neural network policy was stationary, the resulting gait was much smoother. Previous methods could only solve this task with samples per iteration, with RWR eventually obtaining a distance of 0.5m after 4000 samples, and CEM reaching 2.1m after 3000. Our method was able to reach such distances with many fewer samples. Following prior work (Levine and Koltun 2013a), the walker trajectory was initialized from a demonstration, which was stabilized with simple linear feedback. The RWR and CEM policies were initialized with samples from this controller to provide a fair comparison. The graph shows the average distance travelled on rollouts that did not fall, and shows that only our method was able to learn walking policies that succeeded consistently.
在游泳任务上,我们的方法达到与线性-高斯情形相似的性能,但由于神经网络策略是平稳的,所得步态平滑得多。先前方法每次迭代需要 个样本才能解决该任务:RWR 在 4000 个样本后达到 0.5 m,CEM 在 3000 个样本后达到 2.1 m。我们的方法用少得多的样本即可达到类似距离。按先前工作(Levine and Koltun,2013a),行走者轨迹用开环轨迹初始化。
On peg insertion, the neural network was trained to insert the peg without precise knowledge of the position of the hole, resulting in a partially observed problem. The holes were placed in a region of radius 0.2 units in 2D and 0.1 units in 3D. The policies were trained on four different hole positions, and then tested on four new hole positions to evaluate generalization. The hole position was not provided to the neural network, and the policies therefore had to search for the hole, with only joint angles and velocities as input. Only our method could acquire a successful strategy to locate both the training and test holes, although RWR was eventually able to insert the peg into one of the four holes in 2D.
在插钉任务上,神经网络在不精确知道孔位置的情况下训练插入,形成部分可观测问题。孔放置在 2D 半径 0.2、3D 半径 0.1 的区域内。策略在四个不同孔位置上训练,再在四个新孔位置上测试以评估泛化。孔位置不提供给神经网络,因此策略必须搜索孔,只能依靠接触动力学。
These comparisons show that training even medium-sized neural network policies for continuous control tasks with a limited number of samples is very difficult for many prior policy search algorithms. Indeed, it is generally known that model-free policy search methods struggle with policies that have over 100 parameters (Deisenroth et al. 2013). In subsequent sections, we will evaluate our method on real robotic tasks, showing that it can scale from these simulated tasks all the way up to end-to-end learning of visuomotor control.
这些比较表明,在有限样本下为连续控制任务训练即便中等规模的神经网络策略,对许多先前策略搜索算法都非常困难。事实上,一般认为免模型策略搜索方法难以处理超过 100 个参数的策略(Deisenroth 等,2013)。后续各节将在真实机器人任务上评估我们的方法,表明它能从这些仿真任务一直扩展到端到端视觉运动策略。
6.2 Learning Linear-Gaussian Controllers on a PR2 Robot
6.2 在 PR2 机器人上学习线性-高斯控制器
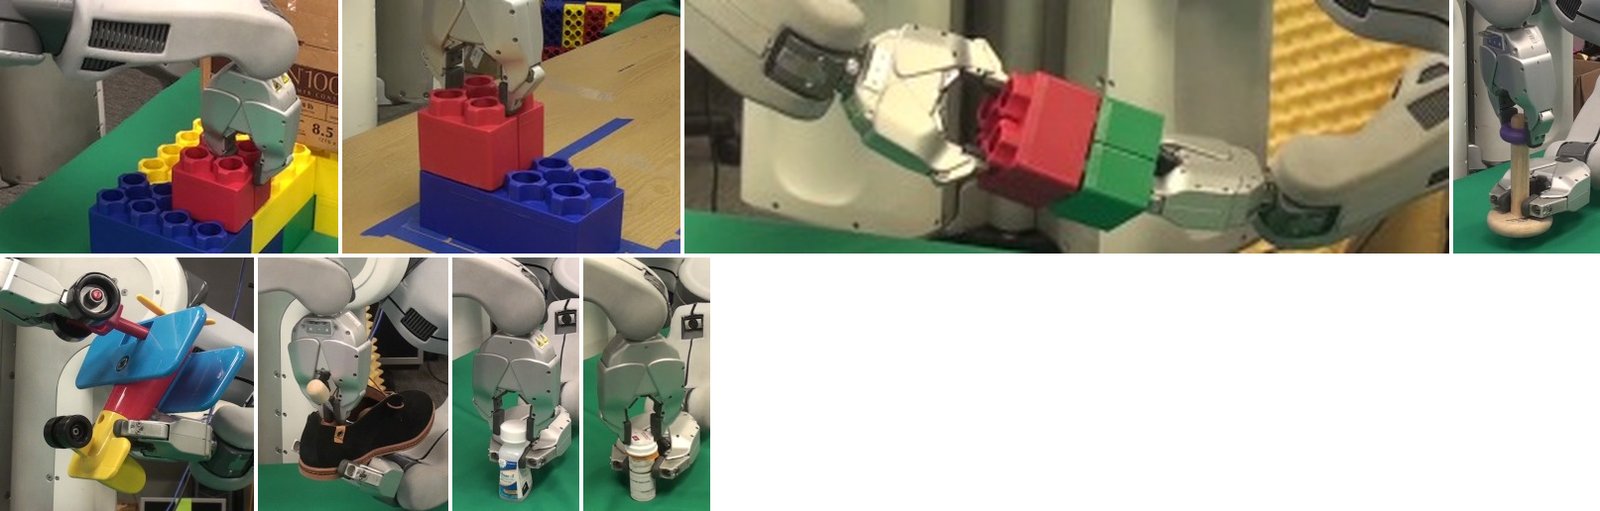
Figure 6: Tasks for linear-Gaussian controller evaluation: (a) stacking lego blocks on a fixed base, (b) onto a free-standing block, (c) held in both gripper; (d) threading wooden rings onto a peg; (e) attaching the wheels to a toy airplane; (f) inserting a shoe tree into a shoe; (g,h) screwing caps onto pill bottles and (i) onto a water bottle.
图 6:线性-高斯控制器评估任务:(a) 在固定底座上堆叠乐高;(b) 堆到独立块上;(c) 双手夹持;(d) 把木环穿到钉子上;(e) 给玩具飞机装轮;(f) 把鞋撑插入鞋内;(g,h) 把盖旋到药瓶上;(i) 旋到水瓶上。
In this section, we demonstrate the range of manipulation tasks that can be learned using our trajectory optimization algorithm on a real PR2 robot. These experiments previously appeared in our conference paper on guided policy search (Levine et al. 2015). Since performing trajectory optimization is a prerequisite for guided policy search to learn effective visuomotor policies, it is important to evaluate that our trajectory optimization can learn a wide variety of robotic manipulation tasks under unknown dynamics. The tasks in these experiments are shown in Figure 6, while Figure 7 shows the learning curves for each task. For all robotic experiments in this article, the tasks were learned entirely from scratch,
本节展示在真实 PR2 上用我们的轨迹优化算法可学到的操作任务范围。这些实验此前出现在关于引导策略搜索的会议论文中(Levine 等,2015)。由于轨迹优化是引导策略搜索学到有效视觉运动策略的前提,评估该轨迹优化能否在未知动力学下学习多种机器人操作任务很重要。
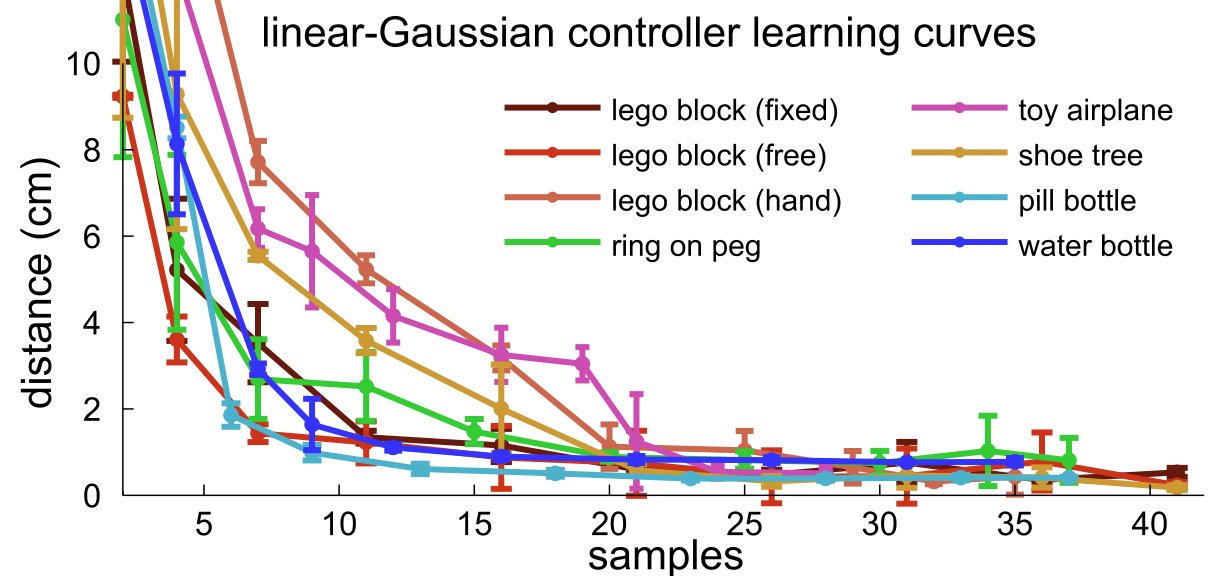
Figure 7: Distance to target point during training of linear-Gaussian controllers. The actual target may differ due to perturbations. Error bars indicate one standard deviation.
图 7:训练线性-高斯控制器期间到目标点的距离。由于扰动,实际目标可能不同。误差棒表示一个标准差。
with the initialization of the controllers described in Appendix B.2. The number of samples required to learn each controller is around 20-25, substantially lower than many prior policy search methods in the literature (Peters and Schaal 2008; Kober et al. 2010b; Theodorou et al. 2010; Deisenroth et al. 2013). Total learning time was about ten minutes for each task, of which only 3-4 minutes involved system interaction. The rest of the time was spent resetting the robot to the initial state and on computation.
控制器 的初始化见附录 B.2。学习每个控制器约需 20–25 个样本,明显低于文献中许多先前策略搜索方法(Peters and Schaal,2008;Kober 等,2010b;Theodorou 等,2010;Deisenroth 等,2013)。每项任务总学习时间约十分钟,其中只有 3–4 分钟涉及系统交互,其余用于把机器人重置到初始状态与计算。
The linear-Gaussian controllers are optimized for a specific condition – e.g., a specific position of the target lego block. To evaluate their robustness to errors in the specified target position, we conducted experiments on the lego block and ring tasks where the target object (the lower block and the peg) was perturbed at each trial during training, and then tested with various perturbations. For each task, controllers were trained with Gaussian perturbations with standard deviations of , , and cm in the position of the target object, and each controller was tested with perturbations of radius , , , and cm. Note that with a radius of cm, the peg would be placed about one ring-width away from the expected position. The results are shown in Table 2. All controllers were robust to perturbations of cm, and would often succeed at cm. Robustness increased slightly when more noise was injected during training, but even controllers trained without noise exhibited considerable robustness, since the linear-Gaussian controllers themselves add noise during sampling. We also evaluated a kinematic baseline for each perturbation level, which planned a straight path from a point 5 cm above the target to the expected (unperturbed) target location. This baseline was only able to place the lego block in the absence of perturbations. The rounded top of the peg provided an easier condition for the baseline, with occasional successes at higher perturbation levels. Our controllers outperformed the baseline by a wide margin.
线性-高斯控制器针对特定条件优化——例如目标乐高块的特定位置。为评估对指定目标位置误差的稳健性,我们在乐高块与环任务上做实验:训练时每次试验扰动目标物体(下方块与钉子),再用各种扰动测试。对每项任务,用标准差为 、 与 cm 的高斯扰动训练控制器,并在 – cm 扰动下测试。结果见表 2:训练时加入扰动显著提升对更大测试扰动的稳健性;运动学开环基线几乎不能承受扰动。
All of the robotic experiments discussed in this section may be viewed in the corresponding supplementary video, available online: http://rll.berkeley.edu/icra2015gps. A video illustration of the visuomotor policies, discussed in the following sections, is also available: http://sites.google.com/site/visuomotorpolicy.
| test perturbation | |||||||||
|---|---|---|---|---|---|---|---|---|---|
| lego block | ring on peg | ||||||||
| 0 cm | 1 cm | 2 cm | 3 cm | 0 cm | 1 cm | 2 cm | 3 cm | ||
| training perturb. | 0 cm | 5/5 | 5/5 | 3/5 | 2/5 | 5/5 | 5/5 | 0/5 | 0/5 |
| 1 cm | 5/5 | 5/5 | 3/5 | 2/5 | 5/5 | 5/5 | 3/5 | 0/5 | |
| 2 cm | 5/5 | 5/5 | 5/5 | 3/5 | 5/5 | 5/5 | 3/5 | 0/5 | |
| kinematic baseline | 5/5 | 0/5 | 0/5 | 0/5 | 5/5 | 3/5 | 0/5 | 0/5 |
Table 2: Success rates of linear-Gaussian controllers under target object perturbation.
| 测试扰动 | |||||||||
|---|---|---|---|---|---|---|---|---|---|
| 乐高块 | 环穿钉 | ||||||||
| 0 cm | 1 cm | 2 cm | 3 cm | 0 cm | 1 cm | 2 cm | 3 cm | ||
| 训练扰动 | 0 cm | 5/5 | 5/5 | 3/5 | 2/5 | 5/5 | 5/5 | 0/5 | 0/5 |
| 1 cm | 5/5 | 5/5 | 3/5 | 2/5 | 5/5 | 5/5 | 3/5 | 0/5 | |
| 2 cm | 5/5 | 5/5 | 5/5 | 3/5 | 5/5 | 5/5 | 3/5 | 0/5 | |
| 运动学基线 | 5/5 | 0/5 | 0/5 | 0/5 | 5/5 | 3/5 | 0/5 | 0/5 |
表 2:目标物体扰动下线性-高斯控制器的成功率。
6.3 Spatial Softmax CNN Architecture Evaluation
6.3 空间 Softmax CNN 架构评估
In this section, we evaluate the neural network architecture that we propose in Section 5.1 in comparison to more standard convolutional networks. To isolate the architectures from other confounding factors, we measure their accuracy on the pose estimation pretraining task described in Section 5.2. This is a reasonable proxy for evaluating how well the network can overcome two major challenges in visuomotor learning: the ability to handle relatively small datasets without overfitting, and the capability to learn tasks that are inherently spatial. We compare to a network where the expectation operator after the softmax is replaced with a learned fully connected layer, as is standard in the literature, a network where both the softmax and the expectation operators are replaced with a fully connected layer, and a version of this network that also uses max pooling with stride at the first two layers. These alternative architectures have many more parameters, since the fully connected layer takes the entire bank of response maps from the third convolutional layer as input. Pooling helps to reduce the number of parameters, but not to the same degree as the spatial softmax and expectation operators in our architecture.
本节把第 5.1 节提出的神经网络架构与更标准的卷积网络比较。为隔离架构与其他混淆因素,我们在第 5.2 节所述位姿估计预训练任务上测量精度。这是评估网络能否克服视觉运动学习两大挑战的合理代理:在相对小的数据集上不过拟合,以及学习固有空间性的任务。我们与把 Softmax 后期望算子换成可学习全连接层的网络比较,后者在文献中更常见。
The results in Table 3 indicate that using the softmax and expectation operators improves pose estimation accuracy substantially. Our network is able to outperform the more standard architectures because it is forced by the softmax and expectation operators to learn feature points, which provide a concise representation suitable for spatial inference. Since most of the parameters in this architecture are in the convolutional layers, which benefit from extensive weight sharing, overfitting is also greatly reduced. By removing pooling, our network also maintains higher resolution in the convolutional layers, improving spatial accuracy. Although we did attempt to regularize the larger standard architectures with higher weight decay and dropout, we did not observe a significant improvement on this dataset. We also did not extensively optimize the parameters of this network, such as filter size and number of channels, and investigating these design decisions further would be valuable to investigate in future work.
表 3 结果表明,使用 Softmax 与期望算子显著提升位姿估计精度。我们的网络能超过更标准架构,因为它被 Softmax 与期望算子强制学习特征点,提供适合空间推断的简洁表示。该架构多数参数在受益于大量权值共享的卷积层中,过拟合也大大降低。去掉池化后,卷积层保持更高分辨率,提升空间精度。我们也尝试正则更大的标准架构,但仍明显差于特征点网络。
| network architecture | test error (cm) |
|---|---|
| softmax + feature points (ours) | 1.30 0.73 |
| softmax + fully connected layer | 2.59 1.19 |
| fully connected layer | 4.75 2.29 |
| max-pooling + fully connected | 3.71 1.73 |
Table 3: Average pose estimation accuracy and standard deviation with various architectures, measured as average Euclidean error for the three target points in 3D, with ground truth determined by forward kinematics from the left arm.
| 网络架构 | 测试误差 (cm) |
|---|---|
| Softmax + 特征点(本文) | 1.30 0.73 |
| Softmax + 全连接层 | 2.59 1.19 |
| 全连接层 | 4.75 2.29 |
| 最大池化 + 全连接 | 3.71 1.73 |
表 3:多种架构的平均位姿估计精度与标准差,以三个目标点在 3D 中的平均欧氏误差衡量,真值由左臂正运动学确定。
6.4 Deep Visuomotor Policy Evaluation
6.4 深度视觉运动策略评估
In this section, we present an evaluation of our full visuomotor policy training algorithm on a PR2 robot. The aim of this evaluation is to answer the following question: does training the perception and control systems in a visuomotor policy jointly end-to-end provide better performance than training each component separately?
本节在 PR2 机器人上评估完整视觉运动策略训练算法。评估旨在回答:在视觉运动策略中联合端到端训练感知与控制系统,是否比分开训练各组件表现更好?
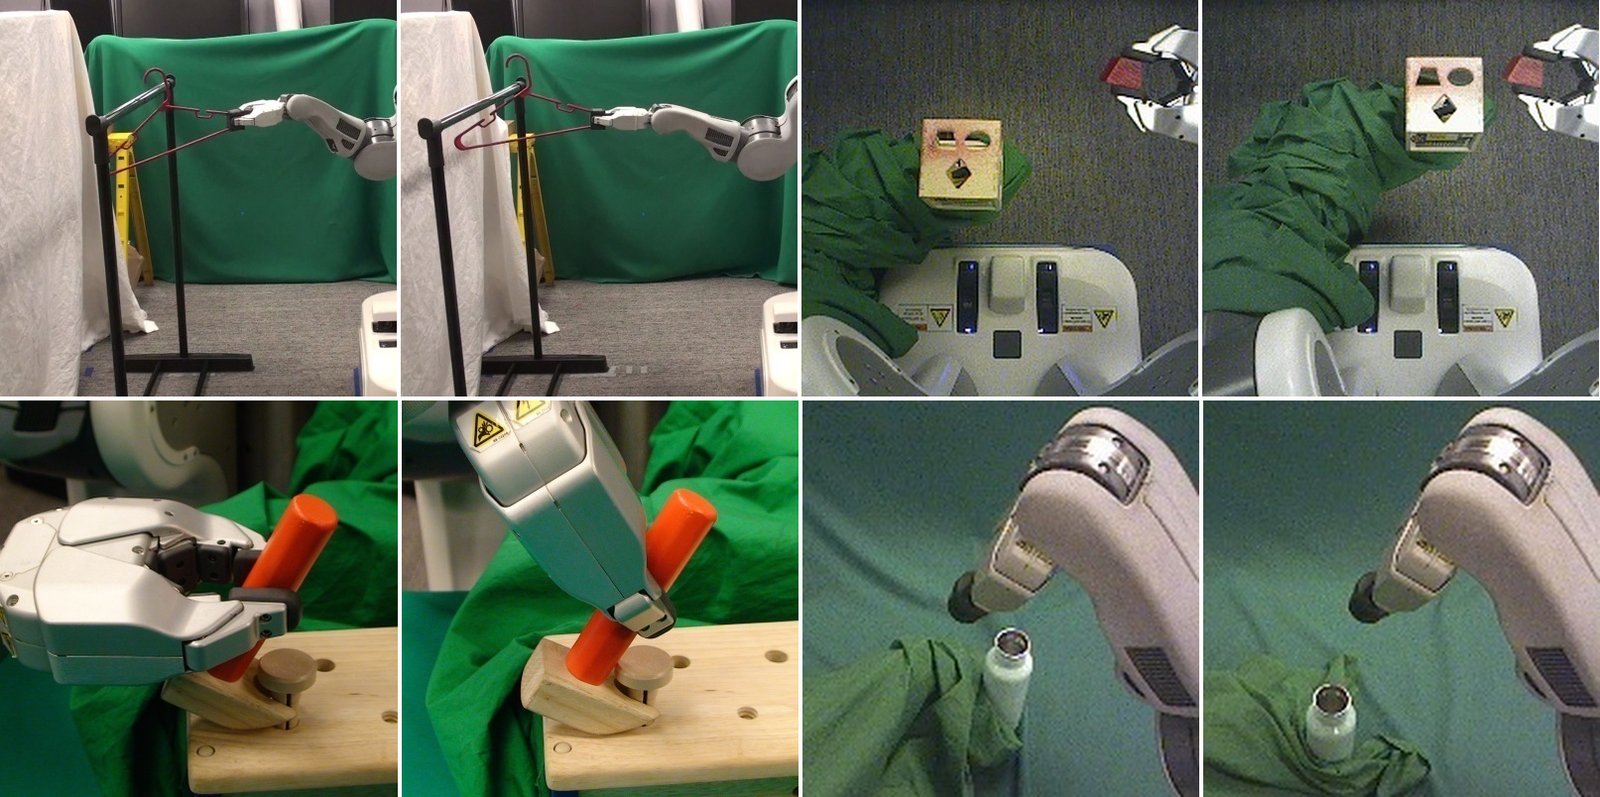
Figure 8: Illustration of the tasks in our visuomotor policy experiments, showing the variation in the position of the target for the hanger, cube, and bottle tasks, as well as two of the three grasps for the hammer, which also included variation in position (not shown).
图 8:视觉运动策略实验中的任务示意,显示衣架、积木与瓶子任务中目标位置的变化,以及锤子的三种抓取中的两种(锤子任务也有位置变化,图中未标)。
Experimental tasks.
实验任务。
We trained policies for hanging a coat hanger on a clothes rack, inserting a block into a shape sorting cube, fitting the claw of a toy hammer under a nail with various grasps, and screwing on a bottle cap. The cost function for these tasks encourages low distance between three points on the end-effector and corresponding target points, low torques, and, for the bottle task, spinning the wrist. The equations for these cost functions and the details of each task are presented in Appendix B.2. The tasks are illustrated in Figure 8. Each task involved variation of 10-20 cm in each direction in the position of the target object (the rack, shape sorting cube, nail, and bottle). In addition, the coat hanger and hammer tasks were trained with two and three grasps, respectively. The current angle of the grasp was not provided to the policy, but had to be inferred from observing the robot’s gripper in the camera images. All tasks used the same policy architecture and model parameters.
我们训练了把衣架挂到晾衣架、把积木插入形状分类盒、以多种抓取把玩具锤爪对准钉子下方、以及旋紧瓶盖的策略。这些任务的代价函数鼓励末端执行器上三点到对应目标点的距离小、力矩小,瓶盖任务还鼓励手腕旋转。代价函数公式与各任务细节见附录 B.2。任务示意见图 8。每项任务中目标物体(架子、分类盒、钉子与瓶子)位置在各方向有约 10–20 cm 变化。
Experimental conditions.
实验条件。
We evaluated the visuomotor policies in three conditions: (1) the training target positions and grasps, (2) new target positions not seen during training and, for the hammer, new grasps (spatial test), and (3) training positions with visual distractors (visual test). A selection of these experiments is shown in the supplementary video.[^3] For the visual test, the shape sorting cube was placed on a table rather than held in the gripper, the coat hanger was placed on a rack with clothes, and the bottle and hammer tasks were done in the presence of clutter. Illustrations of this test are shown in Figure 9.
我们在三种条件下评估视觉运动策略:(1) 训练时的目标位置与抓取;(2) 训练未见的新目标位置,锤子还有新抓取(空间测试);(3) 训练位置但有视觉干扰物(视觉测试)。部分实验见补充视频。视觉测试中,形状分类盒放在桌上而非夹爪中,衣架挂在有衣物的架子上,瓶子与锤子任务在杂乱场景中完成。测试示意见图 9。
Comparison.
比较。
The success rates for each test are shown in Figure 9. We compared to two baselines, both of which train the vision layers in advance for pose prediction, instead of training the entire policy end-to-end. The features baseline discards the last layer of the pose predictor and uses the feature points, resulting in the same architecture as our policy, while the prediction baseline feeds the predicted pose into the control layers. The pose prediction baseline is analogous to a standard modular approach to policy learning, where the vision system is first trained to localize the target, and the policy is trained on top of it. This variant achieves poor performance. As discussed in Section 6.3, the pose estimate is accurate to about 1 cm. However, unlike the tasks in Section 6.2, where robust controllers could succeed even with inaccurate perception, many of these tasks have tolerances of just a few millimeters. In fact, the pose prediction baseline is only successful on the coat hanger, which requires comparatively little accuracy. Millimeter accuracy is difficult to achieve even with calibrated cameras and checkerboards. Indeed, prior work has reported that the PR2 can maintain a camera to end effector accuracy of about 2 cm during open loop motion (Meeussen et al. 2010). This suggests that the failure of this baseline is not atypical, and that our visuomotor policies are learning visual features and control strategies that improve the robot’s accuracy. When provided with pose estimation features, the policy has more freedom in how it uses the visual information, and achieves somewhat higher success rates. However, full end-to-end training performs significantly better, achieving high accuracy even on the challenging bottle task, and successfully adapting to the variety of grasps on the hammer task. This suggests that, although the vision layer pretraining is clearly beneficial for reducing computation time, it is not sufficient by itself for discovering good features for visuomotor policies.
各测试成功率见图 9。我们与两个基线比较,二者都预先训练视觉层做位姿预测,而非端到端训练整策略。特征基线丢掉位姿预测器最后一层并使用特征点,得到与我们策略相同的架构;预测基线把预测位姿送入控制层。位姿预测基线类似于策略学习的标准模块化做法:先训练视觉系统定位目标,再在其上训练策略。该变体表现较差。如第 6.3 节所述,位姿估计误差对控制很敏感,模块化流水线会把感知误差直接传给控制器。端到端训练可适配特征以服务控制。特征基线好于预测基线,但仍不及完整端到端训练。
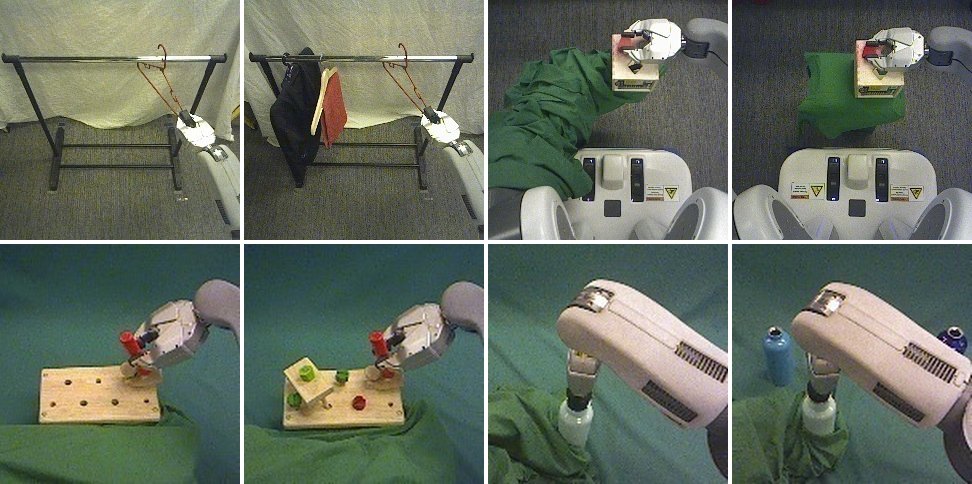
Figure 9: Training and visual test scenes as seen by the policy (left), and experimental results (right). The hammer and bottle images were cropped for visualization only.
图 9:策略所见的训练与视觉测试场景(左),以及实验结果(右)。锤子与瓶子图像仅为人眼观看而裁剪。
Visual distractors.
视觉干扰物。
The policies exhibit moderate tolerance to distractors that are visually separated from the target object. This is enabled in part by the spatial softmax, which has a lateral inhibition effect that suppresses non-maximal activations. Since distractors are unlikely to activate each feature as much as the true object, their activations are therefore suppressed. However, as expected, the learned policies tend to perform poorly under drastic changes to the backdrop, or when the distractors are adjacent to or occluding the manipulated objects, as shown in the supplementary video. A standard solution to this issue to expose the policy to a greater variety of visual situations during training. This issue could also be mitigated by artificially augmenting the image samples with synthetic transformations, as discussed in prior work in computer vision (Simard et al. 2003), or even incorporating ideas from transfer and semi-supervised learning.
策略对与目标物体视觉上分离的干扰物表现出中等容忍。这部分得益于空间 Softmax 的侧抑制,压制非最大激活。干扰物不太可能像真实物体那样强烈激活每个特征,因而其激活被抑制。但如预期,当背景剧变,或干扰物紧邻/遮挡被操作物体时,学到的策略往往表现较差,见补充视频。标准解决办法是让策略接触更多样的视觉情境。
6.5 Features Learned with End-to-End Training
6.5 端到端训练学到的特征
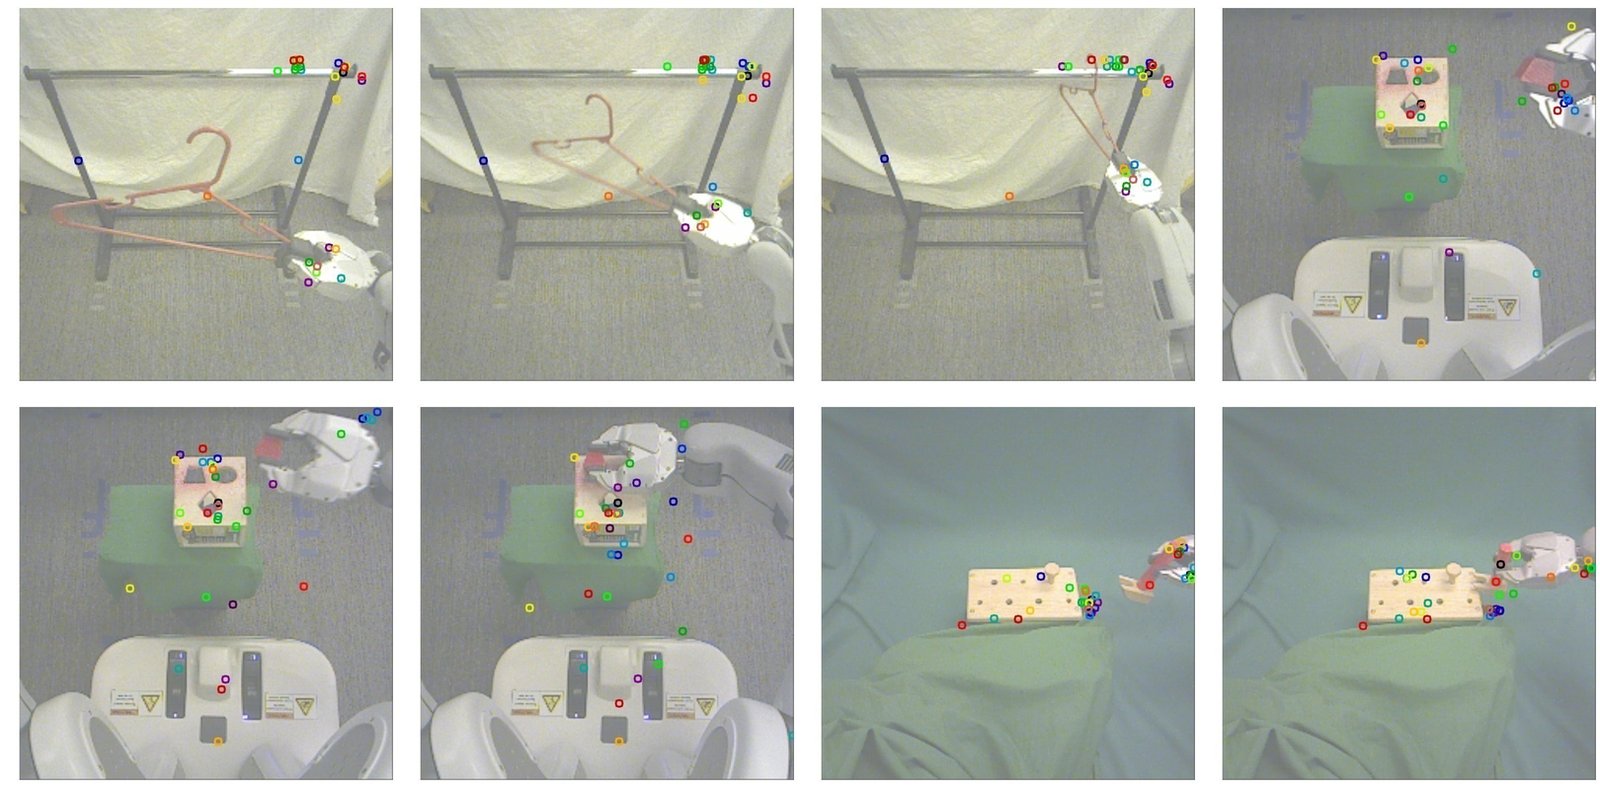
Figure 10: Feature points tracked by the policy during task execution for each of the four tasks. Each feature point is displayed in a different random color, with consistent coloring across images. The policy finds features on the target object and the robot gripper and arm. In the bottle cap task, note that the policy correctly ignores the distractor bottle in the background, even though it was not present during training.
图 10:各任务执行期间策略跟踪的特征点。每个特征点用不同随机颜色显示,跨图像颜色一致。策略在目标物体与机器人夹爪/手臂上找到特征。瓶盖任务中,策略正确忽略背景中的干扰瓶,即便训练时并不存在。
The visual processing layers of our architecture automatically learn features points using the spatial softmax and expectation operators. These feature points encapsulate all of the visual information received by the motor layers of the policy. In Figure 10, we show the features points discovered by our visuomotor policy through guided policy search. Each policy learns features on the target object and the robot manipulator, both clearly relevant to task execution. The policy tends to pick out robust, distinctive features on the objects, such as the left pole of the clothes rack, the left corners of the shape-sorting cube and the bottom-left corner of the toy tool bench. In the bottle task, the end-to-end trained policy outputs points on both sides of the bottle, including one on the cap, while the pose prediction network only finds points on the right edge of the bottle.
我们架构的视觉处理层通过空间 Softmax 与期望算子自动学习特征点。这些特征点封装了策略电机层收到的全部视觉信息。图 10 显示通过引导策略搜索发现的视觉运动策略特征点。每个策略都在目标物体与机器人操作器上学习特征,二者都明显与任务执行相关。策略倾向于挑选物体上稳健、有区分度的特征,如晾衣架左杆、形状分类盒左角、玩具工具台左下角。
In Figure 11, we compare the feature points learned through guided policy search to those learned by a CNN trained for pose prediction. After end-to-end training, the policy acquired a distinctly different set of feature points compared to the pose prediction CNN used for initialization. The end-to-end trained model finds more feature points on task-relevant objects and fewer points on background objects. This suggests that the policy improves its performance by acquiring goal-driven visual features that differ from those learned for object localization.
图 11 比较引导策略搜索学到的特征点与为位姿预测训练的 CNN 学到的特征点。端到端训练后,策略获得与初始化用位姿预测 CNN 明显不同的特征点集。端到端模型在任务相关物体上找到更多特征点,在背景物体上更少。这表明策略通过获得不同于物体定位所学的目标驱动视觉特征来提升表现。
The feature point representation is very simple, since it assumes that the learned features are present at all times, and only one instance of each feature is ever present in the image. While this is a drastic simplification, both the pose predictor and the policy still achieve good results. A more flexible architecture that still learns a concise feature point representation could further improve policy performance. We hope to explore this in future work.
特征点表示非常简单,因为它假定所学特征始终存在,且图像中每种特征只有一个实例。尽管这是剧烈简化,位姿预测器与策略仍取得良好结果。更灵活但仍学习简洁特征点表示的架构或可进一步提升策略表现。我们希望在未来工作中探索这一点。
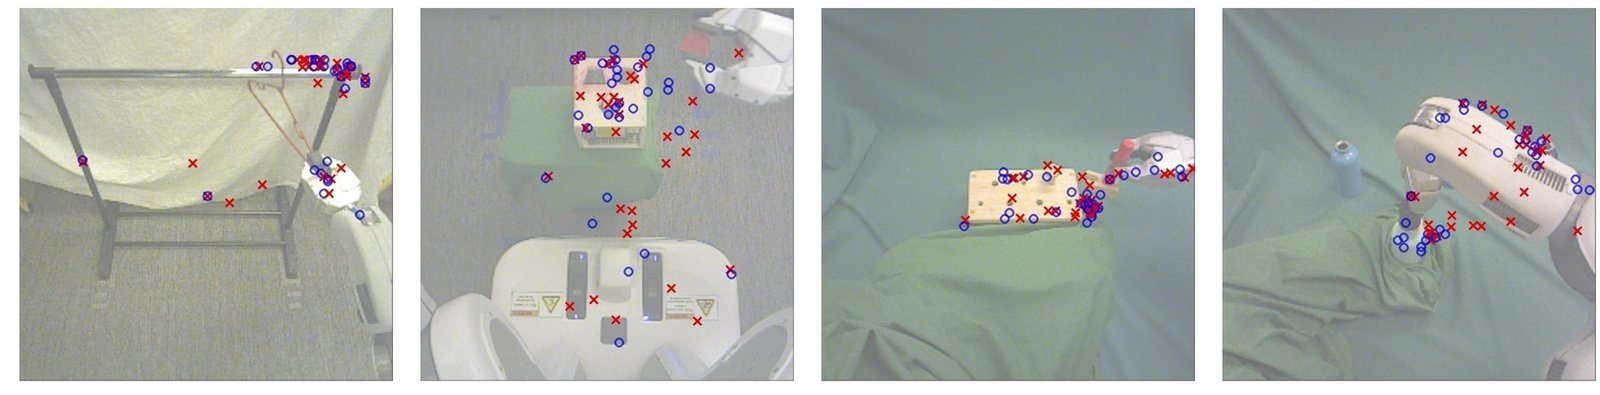
Figure 11: Feature points learned for each task. For each input image, the feature points produced by the policy are shown in blue, while the feature points of the pose prediction network are shown in red. The end-to-end trained policy tends to discover more feature points on the target object and the robot arm than the pose prediction network.
图 11:各任务学到的特征点。对每张输入图像,策略产生的特征点为蓝色,位姿预测网络的特征点为红色。端到端训练的策略往往比位姿预测网络在目标物体与机器人手臂上发现更多特征点。
6.6 Computational Performance and Sample Efficiency
6.6 计算性能与样本效率
We used the Caffe deep learning library (Jia et al. 2014) for CNN training. Each visuomotor policy required a total of 3-4 hours of training time: 20-30 minutes for the pose prediction data collection on the robot, 40-60 minutes for the fully observed trajectory pretraining on the robot and offline pose pretraining (which can be done in parallel), and between 1.5 and 2.5 hours for end-to-end training with guided policy search. The coat hanger task required two iterations of guided policy search, the shape sorting cube and the hammer required three, and the bottle task required four. Only about 15 minutes of the training time consisted of executing trials on the robot. Since training was dominated by computation, we expect significant speedup from a more efficient implementation. The number of samples for training each policy is shown in Table 4. Each trial was five seconds in length, and the numbers do not include the time needed to collect about 1000 images for pretraining the visual processing layers of the policy.
我们用 Caffe 深度学习库(Jia 等,2014)做 CNN 训练。每个视觉运动策略总共需要 3–4 小时训练:机器人上采集位姿预测数据 20–30 分钟,机器人上完全观测轨迹预训练与离线位姿预训练 40–60 分钟(可并行),引导策略搜索端到端训练 1.5–2.5 小时。衣架任务需 2 轮引导策略搜索,形状分类盒与锤子需 3 轮,瓶盖需 4 轮。训练时间中只有约 15 分钟是在机器人上执行试验。
| number of trials | |||
|---|---|---|---|
| task | trajectory pretraining | end-to-end training | total |
| coat hanger | 120 | 36 | 156 |
| shape cube | 90 | 81 | 171 |
| toy hammer | 150 | 90 | 240 |
| bottle cap | 180 | 108 | 288 |
Table 4: Total number of trials used for learning each visuomotor policy.
| 试验次数 | |||
|---|---|---|---|
| 任务 | 轨迹预训练 | 端到端训练 | 合计 |
| 衣架 | 120 | 36 | 156 |
| 形状盒 | 90 | 81 | 171 |
| 玩具锤 | 150 | 90 | 240 |
| 瓶盖 | 180 | 108 | 288 |
表 4:学习各视觉运动策略所用的总试验次数。
7 Discussion and Future Work
7 讨论与未来工作
In this paper, we presented a method for learning robotic control policies that use raw input from a monocular camera. These policies are represented by a novel convolutional neural network architecture, and can be trained end-to-end using our guided policy search algorithm, which decomposes the policy search problem in a trajectory optimization phase that uses full state information and a supervised learning phase that only uses the observations. This decomposition allows us to leverage state-of-the-art tools from supervised learning, making it straightforward to optimize extremely high-dimensional policies. Our experimental results show that our method can execute complex manipulation skills, and that end-to-end training produces significant improvements in policy performance compared to using fixed vision layers trained for pose prediction.
本文提出一种学习使用单目相机原始输入的机器人控制策略的方法。这些策略由新颖的卷积网络架构表示,可用我们的引导策略搜索算法端到端训练:轨迹优化阶段使用完整状态信息,监督学习阶段只使用观测。这种分解使我们能利用监督学习的先进工具,使优化极高维策略变得直接。实验结果表明,该方法能实现需要视觉与控制紧密协调的复杂操作技能。
Although we demonstrate moderate generalization over variations in the scene, our current method does not generalize to dramatically different settings, especially when visual distractors occlude the manipulated object or break up its silhouette in ways that differ from the training. The success of CNNs on exceedingly challenging vision tasks suggests that this class of models is capable of learning invariance to irrelevant distractor features (LeCun et al. 2015), and in principle this issue can be addressed by training the policy in a variety of environments, though this poses certain logistical challenges. More practical alternatives that could be explored in future work include simultaneously training the policy on multiple robots, each of which is located in a different environment, developing more sophisticated regularization and pretraining techniques to avoid overfitting, and introducing artificial data augmentation to encourage the policy to be invariant to irrelevant clutter. However, even without these improvements, our method has numerous applications in, for example, an industrial setting where the robot must repeatedly and efficiently perform a task that requires visual feedback under moderate variation in background and clutter conditions.
与分模块训练视觉与控制相比,端到端训练提升了一致性与泛化,并学到更任务相关的视觉特征。空间 Softmax 特征点架构在小数据与空间精度要求下优于更标准的 CNN。样本效率方面,结合轨迹中心强化学习与监督学习,使真实 PR2 上用几百次试验即可训练约 9 万参数的策略。
Our method takes advantage of a known, fully observed state space during training. This is both a weakness and a strength. It allows us to train linear-Gaussian controllers for guided policy search using a very small number of samples, far more efficiently than standard policy search methods. However, the requirement to observe the full state during training limits the tasks to which the method can be applied. In many cases, this limitation is minor, and the only “instrumentation” required at training is to position the objects in the scene at consistent positions. However, tasks that require, for example, manipulating freely moving objects require more extensive instrumentation, such as motion capture. A promising direction for addressing this limitation is to combine our method with unsupervised state-space learning, as proposed in several recent works, including our own (Lange et al. 2012; Watter et al. 2015; Finn et al. 2015).
未来方向包括更灵活的视觉表示、更多样的任务与干扰物、以及减少对训练时完整状态仪器化的依赖。把类似思想扩展到更大技能集与更少人工仪器的设定,是迈向实用通用视觉运动技能的重要一步。
In future work, we hope to explore more complex policy architectures, such as recurrent policies that can deal with extensive occlusions by keeping a memory of past observations. We also hope to extend our method to a wider range of tasks that can benefit from visual input, as well as a variety of other rich sensory modalities, including haptic input from pressure sensors and auditory input. With a wider range of sensory modalities, end-to-end training of sensorimotor policies will become increasingly important: while it is often straightforward to imagine how vision might help to localize the position of an object in the scene, it is much less apparent how sound can be integrated into robotic control. A learned sensorimotor policy would be able to naturally integrate a wide range of modalities and utilize them to directly aid in control.
在今后的工作中,我们希望探索更复杂的策略架构,例如通过对过去观察的记忆,能够处理广泛排斥问题的经常性策略。 我们还希望将我们的方法扩大到能够从视觉输入中受益的更广泛的任务,以及各种其他丰富的感官模式,包括压力传感器和听觉输入的随机输入。 随着各种感官模式的扩大,对感官策略的端到端训练将变得日益重要:虽然通常可以直截了当地想象视觉如何帮助一个物体在现场的位置定位,但声音如何融入机器人控制却远没有那么明显. 一项有知识的感应器政策将能够自然地综合各种方式并利用它们直接协助控制。
Acknowledgements
致谢
This research was funded in part by DARPA through a Young Faculty Award, the Army Research Office through the MAST program, NSF awards IIS-1427425 and IIS-1212798, the Berkeley Vision and Learning Center, and a Berkeley EECS Department Fellowship.
感谢支持本工作的资助方与提供反馈的同事。部分结果此前出现在相关会议论文中。
Appendix A Guided Policy Search Algorithm Details
附录 A 引导策略搜索算法细节
In this appendix, we describe a number of implementation details of our BADMM-based guided policy search algorithm and our linear-Gaussian controller optimization method.
在本附录中,我们描述了我们基于BADMM的引导策略搜索算法和我们的线性-高斯式控制器优化方法的一些实施细节.
A.1 BADMM Dual Variables and Weight Adjustment
A.1 BADMM 对偶变量与权重调整
Recall that the inner loop alternating optimization is given by
回顾内环交替优化由
We use a step size of in all of our experiments, which we found to be more stable than . The weights are initialized to and incremented based on the following schedule: at every iteration, we compute the average KL-divergence between and at each time step, as well as its standard deviation over time steps. The weights corresponding to time steps where the KL-divergence is higher than the average are increased by a factor of 2, and the weights corresponding to time steps where the KL-divergence is two standard deviations or more below the average are decreased by a factor of 2. The rationale behind this schedule is to adjust the KL-divergence penalty to keep the policy and trajectory in agreement by roughly the same amount at all time steps. Increasing too quickly can lead to the policy and trajectory becoming “locked” together, which makes it difficult for the trajectory to decrease its cost, while leaving it too low requires more iterations for convergence. We found this schedule to work well across all tasks, both during trajectory pretraining and while training the visuomotor policy.
我们在所有实验中使用了的阶梯尺寸, 我们发现它比更稳定。 的权重初始化为,并基于以下时间表进行递增: 在每次迭代时,我们计算每一步和之间的平均KL潜水量,以及其随时间阶次的标准差. 与KL潜水量高于平均值的时间级对应的权重 乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘2乘以2乘以2乘以2乘1乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘以3乘以2乘以2乘以2乘以2乘以2乘以1乘以2乘以2乘以2乘以2乘以2乘以2乘以2乘 这一时间表的理由是调整KL-潜水处罚,使政策和轨道在任何时候都大致相同。 增加的速度太快,可导致政策和轨迹“密不可分”,从而使轨迹难以降低成本,而使其太低则需要更多的迭代才能趋同。 我们发现,这一时间表在轨迹预训期间和在训练机动车政策期间,在所有任务中运作良好。
To update the dual variables , we evaluate the expectations over by using the latest batch of sampled trajectories. For each state along these sampled trajectories, we evaluate the expectations over under and , which correspond simply to the means of these conditional Gaussian distributions, in closed form.
为了更新的双重变量,我们利用最新的一批抽样轨迹来评估对的预期值。 在MATTOKEN4和MATTOKEN5中, 我们评估了对MATTOKEN3的预期, 仅与这些有条件的高斯分布方式相对应,
A.2 Policy Variance Optimization
A.2 策略方差优化
As discussed in Section 4, the variance of the Gaussian policy does not depend on the observation, though this dependence would be straightforward to add. Analyzing the objective , we can write out only the terms that depend on :
如 像第4节所讨论的那样,高斯政策的差异并不取决于观察,尽管这种依赖性可以直截了当地补充。 分析目标,
Differentiating and setting the derivative to zero, we obtain the following equation for :
区分并设定衍生物为零,我们获得的如下方程:
where the expectation under is omitted, since does not depend on .
,因为MATTOKEN1并不取决于MATTOKEN2。
A.3 Dynamics Fitting
A.3 动力学拟合
Optimizing the linear-Gaussian controllers that induce the trajectory distributions requires fitting the system dynamics at each iteration to samples generated on the physical system from the previous controller . In this section, we describe how these dynamics are fitted. As in Section 4, we drop the subscript , since the dynamics are fitted the same way for all of the trajectory distributions.
优化诱导轨迹分布的线性-广西控制器,需要在每个周期将系统动力学配置到前一位控制器在物理系统中生成的样品上. 在本节中,我们描述了这些动态是如何适应的。 如同第4节,我们放弃下标的, 因为动力学对所有的轨迹分布都是一样的。
The linear-Gaussian dynamics are defined as , and the data that we obtain from the robot can be viewed as tuples . A simple way to fit these linear-Gaussian dynamics is to use linear regression to determine , , and , and fit based on the errors. However, the sample complexity of linear regression scales with the dimensionality of . For a high-dimensional robotic system, we might need an impractically large number of samples at each iteration to obtain a good fit. However, we can observe that the dynamics at nearby time steps are strongly correlated, and we can dramatically reduce the sample complexity of the dynamics fitting by bringing in information from other time steps, and even prior iterations. We will bring in this information by fitting a global model to all of the transitions for all and all tuples from several prior iterations (we use three prior iterations in our implementation), and then use this model as a prior for fitting the dynamics at each time step. Note that this global model does not itself need to be a good forward dynamics model – it just needs to serve as a good prior to reduce the sample complexity of linear regression.
线性-高斯动力学被定义为,我们从机器人获得的数据可以看作是Tuples . 符合这些线性-高斯动力学的一个简单方法是使用线性回归来确定,,和,并根据错误来适应. 然而,线性回归尺度的样本复杂性与的维度. 对于一个高维的机器人系统, 我们可能需要一个不切实际的大量样本 在每一个迭代,以获得一个很好的合身。 然而,我们可以看到,附近的时间步骤的动态是密切相关的,我们可以通过从其他时间步骤中,甚至从以前的迭代中,带来信息来大幅降低动态的样本复杂性。 我们将将这一,为所有,所有,所有,所有,所有, 都, , , , , , 请注意,这个全球模型本身不需要是一个良好的前向动态模型 — — 它只需要在降低线性回归的样本复杂性之前起到良好的作用.
To make it more convenient to incorporate a data-driven prior, we will first reformulate this linear regression fit and view it as fitting a Gaussian model to the dataset at each time step , and then conditioning this Gaussian to obtain . While this is equivalent to linear regression, it allows us to easily incorporate a normal-inverse-Wishart prior on this Gaussian in order to bring in prior information. Let be the empirical covariance of our dataset, and let be the empirical mean. The normal-inverse-Wishart prior is defined by prior parameters , , , and . Under this prior, the maximum a posteriori estimates for the covariance and mean are given by
为了更方便地加入一个数据驱动的前置程序,我们将首先重新制定这个线性回归方式,并将它视为在每一步的数据集上配上一个高斯模型,然后对这个高斯进行调节以获得。 虽然这相当于线性回归,但是它允许我们在这个高斯人之前很容易地包含一个正常的反向维夏特,以便引入先前的信息. 让成为我们数据集的经验共性, 让成为经验的刻薄。 通常反向维沙之前由以前的参数、、和定义。 在此前的这一下,对共变的和平均值0的最大后期估计由下列单位给出:
Having obtained and , we can obtain an estimate of the dynamics by conditioning the distribution on , which produces linear-Gaussian dynamics . The parameters of the normal-inverse-Wishart prior are obtained from the global model of the dynamics which, as described previously, is fitted to all available tuples .
在获得和之后,我们可以通过在上调节分布的来获得对的动力学的估计,而上产生线性-高斯动力学. 通常反向维沙之前的参数来自全球动力学模型,如前所述,该模型适用于所有可用的Tuple 。
The simplest prior can be obtained by fitting a Gaussian distribution to vectors . If the mean and covariance of this data are given by and , the prior is given by and , while and should be set to the number of data points in the datasets. In practice, settings and to tends to produce better results, since the prior is fitted to many more samples than are available for linear regression at each time step. While this prior is simple, we can obtain a better prior by employing a nonlinear model.
最简单的前置方式是将高斯分布配给向量。 如果这些数据的平均值和一致性由和给出,则前一个数据由和给出,而和应设定为数据集的数据点数. 在实践中,MATTOKEN7和MATTOKEN8至MATTOKEN9的设置往往产生更好的结果,因为前一个设置比每个步骤的线性回归可用样本多得多。 虽然这之前很简单,但我们可以通过使用非线性模型获得更好的前置.
The particular global model we use in this work is a Gaussian mixture model over vectors . Systems of articulated rigid bodies undergoing contact dynamics, such as robots interacting with their environment, can be coarsely modeled as having piecewise linear dynamics. The Gaussian mixture model provides a good approximation for such piecewise linear systems, with each mixture element corresponding to a different linear mode (Khansari-Zadeh and Billard 2010). Under this model, the state transition tuple is assumed to come from a distribution that depends on some hidden state , which corresponds to the mixture element identity. In practice, this hidden state might correspond to the type of contact profile experienced by a robotic arm at step . The prior for the dynamics fit at time step is then obtained by inferring the hidden state distribution for the transition dataset , and using the mean and covariance of the corresponding mixture elements (weighted by their probabilities) to obtain and . The prior parameters can then be obtained as described above.
我们使用的特殊全球模型是高斯混合模型, 正在经历接触动态的清晰刚性体的系统,如机器人与环境相互作用,可以粗略地模拟为具有片面线性动态。 高斯混合模型为这种片状线性系统提供了良好的近似,每个混合物元素对应不同的线性模式(Khansari-Zadeh和Billard,2010年). 在这个模型下,状态过渡的Tuple被假定来自一个取决于某些隐藏状态的分布,即,它与混合物元素特性相对应. 在实践中,这种隐藏状态可能与机器人臂在步骤中经历的接触特征类型相对应. 然后通过推断过渡数据集的隐藏状态分布,并利用相应的混合物元素(按其概率加权)的平均值和共性,获得和,从而获得时间步骤MATOKEN3的动力学的前身。 然后可以如上所述获得先前的参数。
In our experiments, we set the number of mixture elements for the Gaussian mixture model prior such that there were at least 40 samples per mixture element, or 20 total mixture elements, whichever was lower. In general, we did not find the performance of the method to be sensitive to this parameter, though overfitting did tend to occur in the early iterations when the number of samples is low, if the number of mixtures was too high.
在我们的实验中,我们先确定高斯混合模型的混合物元素数量,这样每个混合物元素至少有40个样本,或者20个混合物元素总量,以较低者为准。 一般来说,我们并不认为该方法的性能对这个参数敏感,尽管在样品数量低时,如果混合物数量太高,在早期迭代时往往会出现过量适应.
A.4 Trajectory Optimization
A.4 轨迹优化
In this section, we show how the LQR backward pass can be used to optimize the constrained objective in Section 4.2. The constrained trajectory optimization problem is given by
在本节中,我们展示了如何利用LQR后传来优化第4.2节限制的目标. 限制的轨道优化问题由
The augmented Lagrangian consists of an entropy term and an expectation under of a quantity that is independent of . We can locally approximate this quantity with a quadratic by using a quadratic expansion of , and fitting a linear Gaussian to with the same method we used for the dynamics. We can then solve the primal optimization in the dual gradient descent procedure with a standard LQR backward pass. As discussed in Section 4, can be written as the expectation of some function that is independent of , such that . Specifically,
增量的Lagrangian 包括一个肽类和下对独立于的数量的预期值。 我们可以通过使用的四面体膨胀, 并用我们用于动力学的相同方法将线性高斯琴与相匹配, 从而在本地以四面体来估计这个数量。 然后用标准的LQR后传解决双梯度降程程序中的原始优化. 如第4节所述,可以作为独立于的某些函数的预期值写成,如。 具体来说,
Writing the Lagrangian of the constrained optimization, we have
写作Lagrangeian 限制优化,我们已经
where is the Lagrange multiplier. Note that is the Lagrangian of the constrained trajectory optimization, which is not related to the augmented Lagrangian . Grouping the terms in the expectation and omitting constants, we can rewrite the minimization of the Lagrangian with respect to the primal variables as
其中是拉格兰格乘数。 请注意,是受限轨迹优化的拉格朗格人,这与拉格朗格人的增强无关。 将预期中的术语分组并省略常数,我们可以将拉格朗日变量最小化改写为:
Let . The above optimization corresponds to minimizing . This type of maximum entropy problem can be solved using the LQR algorithm, and the solution is given by
让马斯托肯0。 以上优化对应最小化 。 使用 LQR 算法可以解决这类最大的 en问题,解决方案由
where and are the feedback and open loop terms of the optimal linear feedback controller corresponding to the cost and the dynamics , and is the quadratic term in the Q-function at time step . All of these terms can be obtained from a standard LQR backward pass (Li and Todorov 2004), which we summarize below.
其中MATHToken0和MATHToken1是最佳线性反馈控制器的反馈和开放循环条件,与成本MATHToken2和动态MATHToken3相对应,而MATHToken4则是Q函数中时间步骤MATHToken5的四元. 所有这些术语都可以从标准的LQR后传(Li and Todorov 2004)中获取,下文对此作总结.
Recall that the estimated linear-Gaussian dynamics have the form . The quadratic cost approximation has the form
记得估计的线性-高斯动力学有的形态. 四进制成本近似有形式
where subscripts denote derivatives, e.g. is the gradient of with respect to , while is the Hessian.[^4] Under this model of the dynamics and cost function, the optimal controller can be computed by recursively computing the quadratic -function and value function, starting with the last time step. These functions are given by
其中下标表示衍生物,例如是相对于的梯度,而是黑森人. [^4] 在这个动力学和成本函数的模型下,最优化的控制器可以通过递归计算四极 - 函数和值函数来计算,从最后一个时间步骤开始. 这些职能由
We can express them with the following recurrence, which is computed starting at the last time step and moving backward through time:
我们可以用以下的重现来表达它们,从的最后一个步骤开始计算,然后向后移动:
and the optimal control law is then given by , where and . If, instead of simply minimizing the expected cost, we instead wish to optimize the maximum entropy objective in Equation (4), the optimal controller is instead linear-Gaussian, with the solution given by , as shown in prior work (Levine and Koltun 2013a).
然后,最佳控制法由给出,其中和. 如果与其简单地将预期成本降到最低,不如在方程式(4)中优化最大均匀目标,则最佳控制器反而是线性-高斯语,由给出溶液,如前作(Levine and Koltun 2013a)所示.
Appendix B Experimental Setup Details
附录 B 实验设置细节
In this appendix, we present a detailed summary of the experimental setup for our simulated and real-world experiments.
在本附录中,我们详细概述了我们模拟和现实世界实验的实验设置。
B.1 Simulated Experiment Details
B.1 仿真实验细节
All of the simulated experiments used the MuJoCo simulation package (Todorov et al. 2012), with simulated frictional contacts and torque motors at the joints used for actuation. Although no control or state noise was added during simulation, noise was injected naturally by the linear-Gaussian controllers. The linear-Gaussian controllers were initialized to stay near the initial state using linear feedback based on a proportional-derivative control law for all tasks, except for the octopus arm, where was initialized to be zero mean with a fixed spherical covariance, and the walker, which was initialized to track a demonstration trajectory with proportional-derivative feedback. The walker was the only task that used a demonstration, as described previously. We describe the details of each system below.
所有模拟实验都使用了MujoCo模拟包(Todorov等人,2012年),在用于激活的关节处有模拟摩擦接触和扭矩电动机. 虽然在模拟过程中没有添加控制或状态噪声,但噪声是由线性-高斯式控制器自然注入的. 线性-高斯语控制器被初始化以在初始状态附近停留,根据比例-衍生控制法对所有任务进行线性反馈,除了章鱼臂被初始化的与固定球面共变为零平均值,行人被初始化以跟踪具有比例-衍生反馈的演示轨迹. 如前所述,行尸是唯一使用示威的任务。 我们介绍以下每个系统的细节。
Peg insertion:
Peg 插入 :
The 2D peg insertion task has 6 state dimensions (joint angles and angular velocities) and 2 action dimensions. The 3D version of the task has 12 state dimensions, since the arm has 3 degrees of freedom at the shoulder, 1 at the elbow, and 2 at the wrist. Trials were 8 seconds in length and simulated at 100 Hz, resulting in 800 time steps per rollout. The cost function is given by
2D配位插入任务有6个状态维度(联合角和角速度)和2个动作维度. 3D版本的任务有12个状态维度,因为手臂肩部有3度的自由度,肘部有1度,腕部有2度. 试验时间为8秒,模拟时间为100赫兹,导致每次推出800个时间步. 成本函数由
where is the position of the end effector for state , is the desired end effector position at the bottom of the slot, and the norm is given by , which corresponds to the sum of an and soft norm. We use this norm to encourage the peg to precisely reach the target position at the bottom of the hole, but to also receive a larger penalty when far away. The task also works well in 2D with a simple penalty, though we found that the 3D version of the task takes longer to insert the peg all the way into the hole without the -like square root term. The weights were set to and . Initial states were chosen by moving the shoulder of the arm relative to the hole, with four equally spaced starting states in a 20 cm region for the 2D arm, and four random starting states in a 10 cm radius for the 3D arm.
其中是状态的终端效应器位置,是槽底的所期望的终端效应器位置,规范由给出,相当于一个和软规范的总和. 我们利用这个规范来鼓励挂钩者精确地到达洞底的目标位置,但是在远处也会得到更大的惩罚. 任务在2D中同样用简单的惩罚效果良好,尽管我们发现3D版本的任务需要更长的时间才能将插在洞中,而不使用——类似平方根名词. 重量设定为和0. 初始状态通过将臂的肩部相对孔移动来选择,在2D臂的20厘米区域有四个等距起始状态,在3D臂的10厘米半径内有四个随机起始状态.
Octopus arm:
奥克托普斯手臂:
The octopus arm consists of six four-sided chambers. Each edge of each chamber is a simulated muscle, and actions correspond to contracting or relaxing the muscle. The state space consists of the positions and velocities of the chamber vertices. The midpoint of one edge of the first chamber is fixed, resulting in a total of degrees of freedom: the 2D positions of the unconstrained points, and the orientation of the first edge. Including velocities, the total dimensionality of the state space is . The cost function depends on the activation of the muscles and distance between the tip of the arm and the target point, in the same way as for peg insertion. The weights are set to and .
章鱼臂由6个四面室组成. 每个室的每个边缘都是模拟肌肉,动作对应收缩或放松肌肉. 状态空间由室顶的位置和速度组成. 第一舱一个边缘的中点是固定的,导致总自由度为:无约束点的2D位置,以及第一舱边缘的方向. 包括速度, 状态空间的总维度是 。 成本功能取决于肌肉的激活和手臂尖端与目标点之间的距离,其方式与插入钉子相同. 重量设定为和。
Swimmer:
游泳运动员:
The swimmer consists of 3 links and 5 degrees of freedom, including the global position and orientation which, together with the velocities, produces a 10 dimensional state space. The swimmer has 2 action dimensions corresponding to the torques between joints. The simulation applied drag on each link of the swimmer to roughly simulate a fluid, allowing it to propel itself. The rollouts were 20 seconds in length at 20 Hz, resulting in 400 time steps per rollout. The cost function for the swimmer is given by
游泳者包括3个链接和5度自由,包括全球位置和方向,与速度一起产生10维状态空间. 游泳者有2个动作维度,对应关节之间的扭矩. 模拟应用在游泳者的每个环节上拖动,大致模拟一个流体,使其能自行推进. 推出时间在20赫兹时长度为20秒,导致每次推出时间步数达到400步. 游泳运动员的成本函数由
where is the horizontal velocity, , and the weights were and .
其中为水平速度,,重量为和.
Walker:
华克:
The bipedal walker consists of a torso and two legs, each with three links, for a total of 9 degrees of freedom and 18 dimensions, with velocity, and 6 action dimensions. The simulation ran for 5 seconds at 100 Hz, for a total of 500 time steps. The cost function is given by
双人行走器由一个躯干和两条腿组成,每条腿有三条连接,共9度自由度和18维,速度快,6个动作维. 模拟以100赫兹的速度运行了5秒,共计500步时间. 成本函数由
where is again the horizontal velocity, is the vertical position of the root, , , and the weights were set to , , and .
其中再次是水平速度,是根的垂直位置,,,重量被设定为,,和.
B.2 Robotic Experiment Details
B.2 机器人实验细节
All of the robotic experiments were conducted on a PR2 robot. The robot was controlled at 20 Hz via direct effort control,[^5] and camera images were recorded using the RGB camera on a PrimeSense Carmine sensor. The images were downsampled to . The learned policies controlled one 7 DoF arm of the robot, while the other arm was used to move objects in the scene to automatically vary the initial conditions. The camera was kept fixed in each experiment. Each episode was seconds in length. For each task, the cost function required placing the object held in the gripper at a particular location (which might require, for example, to insert a shape into a shape sorting cube). The cost was given by the following equation:
所有机器人实验都是在一个PR2机器人上进行的. 该机器人通过直接努力控制在20赫兹得到控制,[^5] 并使用RGB相机在PrimeSense Carmine传感器上录制相机图像. 图像被取样到。 学习到的策略控制了机器人的一个7 DoF臂,而另一个臂则用于在现场移动物体,以自动改变初始条件. 相机在每次实验中都被固定. 每集的长度均为秒. 对于每一项任务,成本函数需要将被夹住的物体放置在特定位置(例如可能需要将形状插入形状排序立方体). 费用按以下公式计算:
where is the distance between three points in the space of the end-effector and their target positions,[^6], and the weights are set to , , and . The quadratic term encourages moving the end-effector toward the target when it is far, while the logarithm term encourages placing it precisely at the target location, as discussed in prior work (Levine et al. 2015). The bottle cap task used an additional cost term consisting of a quadratic penalty on the difference between the wrist angular velocity and a target velocity.
其中是末端效应器空间中三个点与其目标位置之间的距离,[^6],重量设定为,,和。 四重词鼓励在远处将最终效应器移向目标,而对数词则鼓励将其精确地放在目标位置,如先前的工作(Levine等人,2015年)所讨论的那样。 瓶盖任务使用了附加成本术语,包括对手腕角速度与目标速度之差的四重罚.
For all of the tasks, we initialized all of the linear-Gaussian controllers to stay near the initial state , with a diagonal noise covariance. The covariance of the noise was chosen to be proportional to a diagonal approximation of the inverse effective mass at each joint, as provided by the manufacturer of the PR2 robot, and the feedback controller was constructed using LQR, with an approximate linear model obtained from the same diagonal inverse mass matrix. The role of this initial controller was primarily to avoid dangerous actions during the first iteration. We discuss the particular setup for each experiment below:
在所有这些任务中,我们初始化了所有线性-高斯式控制器 以停留在初始状态 附近,并带有对角噪声共变. 噪声的共变量被选为与每个关节反向有效质量的对角近似量成正比,由PR2机器人制造商提供,反馈控制器使用LQR构建,从同一个对角反向质量矩阵中获得的大致线性模型. 这个初始控制器的作用主要是在第一次重复时避免危险行动. 我们讨论以下每个试验的具体设置:
Coat hanger:
本段尚未翻译。
The coat hanger task required the robot to hang a coat hanger on a clothes rack. The coat hanger was grasped at one of two angles, about apart, and the rack was positioned at three different distances from the robot during training, with differences of about between each position. The rack was moved manually between these positions during training. A trial was considered successful if, when the coat hanger was released, it remained hanging on the rack rather than dropping to the ground.
衣架任务要求机器人将衣架挂在衣架上. 衣架在两个角度中的一个被抓住,相距大约为,在训练期间,吊架的位置与机器人处于三个不同的距离上,每个位置之间的大约为. 在训练期间,这些职位之间的架子是人工移动的。 如果在释放衣架时仍悬挂在架子上而不是倒在地上,审判被认为是成功的。
Shape sorting cube:
XQ 形状排序立方体:
The shape sorting cube task required the robot to insert a red trapezoid into a trapezoidal hole on a shape sorting cube. During training, the cube was positioned at nine different positions, situated at the corners, edges, and middle of a rectangular region in size. During training, the shape sorting cube was moved through the training positions by using the left arm. A trial was considered successful if the bottom face of the trapezoid was completely inside the shape sorting cube, such that if the robot were to release the trapezoid, it would fall inside the cube.
形状分拣立方体的任务要求机器人在形状分拣立方体上将红色的夹层插入夹层孔. 在训练期间,立方体被定位在9个不同的位置上,位于角落、边缘和长方形区域的中间。 在训练期间,形状分拣立方体通过使用左臂通过训练位置移动. 如果tapezoid的底面完全在形状分拣立方体内,那么一次试验被认为是成功的,这样如果机器人释放tapezoid,它就会掉在立方体内.
Toy hammer:
玩具锤:
The hammer task required the robot to insert the claw of a toy hammer underneath a toy plastic nail, placing the claw around the base of the nail. The hammer was grasped at one of three angles, each apart, for a total variation of degrees, and the nail was positioned at five positions, at the corners and center of a rectangular region in size. During training, the toy tool bench containing the nail was moved using the left arm. A trial was considered successful if the tip of the claw of the hammer was at least under the centerline of the nail.
锤子任务要求机器人在玩具塑料钉下方插入玩具锤子的爪子,将爪子置于钉子底部. 锤子在三个角度中的一个被抓住,每个相隔,总变化度为度,钉子位于5个位置,在矩形区域的角和中心大小. 训练期间,使用左臂移动了装有指甲的玩具工具凳. 如果锤子的爪尖至少位于钉子的中线之下,那么审判被认为是成功的.
Bottle cap:
瓶盖:
The bottle cap task required the robot to screw a cap onto a bottle at various positions. The bottle was located at nine different positions, situated at the corners, edges, and middle of a rectangular region in size, and the left arm was used to move the bottle through the training positions. A trial was considered successful if, after completion, the cap could not be removed from bottle simply by pulling vertically.
瓶盖任务要求机器人在各种位置上将瓶盖螺钉在瓶上. 瓶子位于9个不同位置,分别位于角,边缘和长方形区域中部,左臂通过训练位置移动瓶子. 如果完成后无法仅通过垂直拉取瓶盖,则试验被认为是成功的。
References
参考文献
Bagnell and Schneider (2003) J. A. Bagnell and J. Schneider. Covariant policy search. In International Joint Conference on Artificial Intelligence (IJCAI) , 2003.
Bakker et al. (2003) B. Bakker, V. Zhumatiy, G. Gruener, and J. Schmidhuber. A robot that reinforcement-learns to identify and memorize important previous observations. In International Conference on Intelligent Robots and Systems (IROS) , 2003.
Bekey and Goldberg (1992) G. Bekey and K. Goldberg. Neural Networks in Robotics . Springer US, 1992.
Benbrahim and Franklin (1997) H. Benbrahim and J. A. Franklin. Biped dynamic walking using reinforcement learning. Robotics and Autonomous Systems , 22:283–302, 1997.
Böhmer et al. (2013) W. Böhmer, S. Grünewälder, Y. Shen, M. Musial, and K. Obermayer. Construction of approximation spaces for reinforcement learning. Journal of Machine Learning Research , 14(1):2067–2118, January 2013.
Boyd et al. (2011) S. Boyd, N. Parikh, E. Chu, B. Peleato, and J. Eckstein. Distributed optimization and statistical learning via the alternating direction method of multipliers. Foundations and Trends in Machine Learning , 3(1):1122, 2011.
Ciresan et al. (2011) D. Ciresan, U. Meier, J. Masci, L. Gambardella, and J. Schmidhuber. Flexible, high performance convolutional neural networks for image classification. In International Joint Conference on Artificial Intelligence (IJCAI) , 2011.
Ciresan et al. (2012) D. Ciresan, U. Meier, and J. Schmidhuber. Multi-column deep neural networks for image classification. In Computer Vision and Pattern Recognition (CVPR) , 2012.
Deisenroth and Rasmussen (2011) M. Deisenroth and C. Rasmussen. PILCO: a model-based and data-efficient approach to policy search. In International Conference on Machine Learning (ICML) , 2011.
Deisenroth et al. (2011) M. Deisenroth, C. Rasmussen, and D. Fox. Learning to control a low-cost manipulator using data-efficient reinforcement learning. In Robotics: Science and Systems (RSS) , 2011.
Deisenroth et al. (2013) M. Deisenroth, G. Neumann, and J. Peters. A survey on policy search for robotics. Foundations and Trends in Robotics , 2(1-2):1–142, 2013.
Deng et al. (2009) J. Deng, W. Dong, R. Socher, L. Li, K. Li, and L. Fei-Fei. ImageNet: A large-scale hierarchical image database. In Computer Vision and Pattern Recognition (CVPR) , 2009.
Endo et al. (2008) G. Endo, J. Morimoto, T. Matsubara, J. Nakanishi, and G. Cheng. Learning CPG-based biped locomotion with a policy gradient method: Application to a humanoid robot. International Journal of Robotic Research , 27(2):213–228, 2008.
Endres and Hoiem (2010) I. Endres and D. Hoiem. Category independent object proposals. In European Conference on Computer Vision (ECCV) . 2010.
Engel et al. (2005) Y. Engel, P. Szabó, and D. Volkinshtein. Learning to control an octopus arm with Gaussian process temporal difference methods. In Advances in Neural Information Processing Systems (NIPS) , 2005.
Espiau et al. (1992) B. Espiau, F. Chaumette, and P. Rives. A new approach to visual servoing in robotics. IEEE Transactions on Robotics and Automation , 8(3), 1992.
Finn et al. (2015) C. Finn, X. Tan, Y. Duan, T. Darrell, S. Levine, and P. Abbeel. Learning visual feature spaces for robotic manipulation with deep spatial autoencoders. arXiv preprint arXiv:1509.06113 , 2015.
Fukushima (1980) K. Fukushima. Neocognitron: A self-organizing neural network model for a mechanism of pattern recognition unaffected by shift in position. Biological Cybernetics , 36:193–202, 1980.
Geng et al. (2006) T. Geng, B. Porr, and F. Wörgötter. Fast biped walking with a reflexive controller and realtime policy searching. In Advances in Neural Information Processing Systems (NIPS) , 2006.
Girshick et al. (2014a) R. Girshick, J. Donahue, T. Darrell, and J. Malik. Rich feature hierarchies for accurate object detection and semantic segmentation. In Conference on Computer Vision and Pattern Recognition (CVPR) , 2014a.
Girshick et al. (2014b) R. Girshick, J. Donahue, T. Darrell, and J. Malik. Rich feature hierarchies for accurate object detection and semantic segmentation. In IEEE Conference on Computer Vision and Pattern Recognition (CVPR) , 2014b.
Gullapalli (1990) V. Gullapalli. A stochastic reinforcement learning algorithm for learning real-valued functions. Neural Networks , 3(6):671–692, 1990.
Gullapalli (1995) V. Gullapalli. Skillful control under uncertainty via direct reinforcement learning. Reinforcement Learning and Robotics , 15(4):237–246, 1995.
Guo et al. (2014) X. Guo, S. Singh, H. Lee, R. L. Lewis, and X. Wang. Deep learning for real-time Atari game play using offline Monte-Carlo tree search planning. In Advances in Neural Information Processing Systems (NIPS) , 2014.
Hadsell et al. (2009) R. Hadsell, P. Sermanet, J. B. A. Erkan, and M. Scoffier. Learning long-range vision for autonomous off-road driving. Journal of Field Robotics , pages 120–144, 2009.
He et al. (2015) K. He, X. Zhang, S. Ren, and J. Sun. Deep residual learning for image recognition. arXiv preprint arXiv:1512.03385 , 2015.
Hochreiter et al. (2001) S. Hochreiter, Y. Bengio, P. Frasconi, and J. Schmidhuber. Gradient flow in recurrent nets: the difficulty of learning long-term dependencies. In A Field Guide to Dynamic Recurrent Neural Networks . IEEE Press, 2001.
Hunt et al. (1992) K. J. Hunt, D. Sbarbaro, R. Żbikowski, and P. J. Gawthrop. Neural networks for control systems: A survey. Automatica , 28(6):1083–1112, November 1992.
Jacobson and Mayne (1970) D. Jacobson and D. Mayne. Differential Dynamic Programming . Elsevier, 1970.
Jägersand et al. (1997) M. Jägersand, O. Fuentes, and R. C. Nelson. Experimental evaluation of uncalibrated visual servoing for precision manipulation. In International Conference on Robotics and Automation (ICRA) , 1997.
Jia et al. (2014) Y. Jia, E. Shelhamer, J. Donahue, S. Karayev, J. Long, R. Girshick, S. Guadarrama, and T. Darrell. Caffe: Convolutional architecture for fast feature embedding. arXiv preprint arXiv:1408.5093 , 2014.
Jodogne and Piater (2007) S. Jodogne and J. H. Piater. Closed-loop learning of visual control policies. Journal of Artificial Intelligence Research , 28:349–391, 2007.
Jonschkowski and Brock (2014) R. Jonschkowski and O. Brock. State representation learning in robotics: Using prior knowledge about physical interaction. In Proceedings of Robotics: Science and Systems , 2014.
Kalakrishnan et al. (2011) M. Kalakrishnan, L. Righetti, P. Pastor, and S. Schaal. Learning force control policies for compliant manipulation. In International Conference on Intelligent Robots and Systems (IROS) , 2011.
Khansari-Zadeh and Billard (2010) S. M. Khansari-Zadeh and A. Billard. BM: An iterative algorithm to learn stable non-linear dynamical systems with Gaussian mixture models. In International Conference on Robotics and Automation (ICRA) , 2010.
Kober and Peters (2009) J. Kober and J. Peters. Learning motor primitives for robotics. In International Conference on Robotics and Automation (ICRA) , 2009.
Kober et al. (2010a) J. Kober, K. Muelling, O. Kroemer, C.H. Lampert, B. Schoelkopf, and J. Peters. Movement templates for learning of hitting and batting. In International Conference on Robotics and Automation (ICRA) , 2010a.
Kober et al. (2010b) J. Kober, E. Oztop, and J. Peters. Reinforcement learning to adjust robot movements to new situations. In Robotics: Science and Systems (RSS) , 2010b.
Kober et al. (2013) J. Kober, J. A. Bagnell, and J. Peters. Reinforcement learning in robotics: A survey. International Journal of Robotic Research , 32(11):1238–1274, 2013.
Kohl and Stone (2004) N. Kohl and P. Stone. Policy gradient reinforcement learning for fast quadrupedal locomotion. In International Conference on Robotics and Automation (IROS) , 2004.
Koutník et al. (2013) J. Koutník, G. Cuccu, J. Schmidhuber, and F. Gomez. Evolving large-scale neural networks for vision-based reinforcement learning. In Conference on Genetic and Evolutionary Computation , GECCO ’13, 2013.
Krizhevsky et al. (2012) A. Krizhevsky, I. Sutskever, and G. Hinton. ImageNet classification with deep convolutional neural networks. In Advances in Neural Information Processing Systems (NIPS) . 2012.
Lampe and Riedmiller (2013) T. Lampe and M. Riedmiller. Acquiring visual servoing reaching and grasping skills using neural reinforcement learning. In International Joint Conference on Neural Networks (IJCNN) , 2013.
Lanfranco et al. (2004) A. Lanfranco, A. Castellanos, J. Desai, and W. Meyers. Robotic surgery: a current perspective. Annals of surgery , 239(1):14, 2004.
Lange et al. (2012) S. Lange, M. Riedmiller, and A. Voigtlaender. Autonomous reinforcement learning on raw visual input data in a real world application. In International Joint Conference on Neural Networks , 2012.
LeCun et al. (1989) Y. LeCun, B. Boser, J. S. Denker, D. Henderson, R. E. Howard, W. Hubbard, and L. D. Jackel. Handwritten digit recognition with a back-propagation network. In Advances in Neural Information Processing Systems (NIPS) , 1989.
LeCun et al. (2015) Y. LeCun, Y. Bengio, and G. Hinton. Deep learning. Nature , 521:436–444, May 2015.
Lee et al. (2009) H. Lee, R. Grosse, R. Ranganath, and A. Y. Ng. Convolutional deep belief networks for scalable unsupervised learning of hierarchical representations. In International Conference on Machine Learning (ICML) , 2009.
Lenz et al. (2015a) Ian Lenz, Ross Knepper, and Ashutosh Saxena. DeepMPC: Learning deep latent features for model predictive control. In RSS , 2015a.
Lenz et al. (2015b) Ian Lenz, Honglak Lee, and Ashutosh Saxena. Deep learning for detecting robotic grasps. IJRR , 2015b.
Levine and Abbeel (2014) S. Levine and P. Abbeel. Learning neural network policies with guided policy search under unknown dynamics. In Advances in Neural Information Processing Systems (NIPS) , 2014.
Levine and Koltun (2013a) S. Levine and V. Koltun. Guided policy search. In International Conference on Machine Learning (ICML) , 2013a.
Levine and Koltun (2013b) S. Levine and V. Koltun. Variational policy search via trajectory optimization. In Advances in Neural Information Processing Systems (NIPS) , 2013b.
Levine and Koltun (2014) S. Levine and V. Koltun. Learning complex neural network policies with trajectory optimization. In International Conference on Machine Learning (ICML) , 2014.
Levine et al. (2015) S. Levine, N. Wagener, and P. Abbeel. Learning contact-rich manipulation skills with guided policy search. In International Conference on Robotics and Automation (ICRA) , 2015.
Lewis et al. (1998) F. L. Lewis, A. Yesildirak, and S. Jagannathan. Neural Network Control of Robot Manipulators and Nonlinear Systems . Taylor & Francis, Inc., 1998.
Li and Todorov (2004) W. Li and E. Todorov. Iterative linear quadratic regulator design for nonlinear biological movement systems. In ICINCO (1) , pages 222–229, 2004.
Lillicrap et al. (2015) T. Lillicrap, J. Hunt, A. Pritzel, N. Heess, T. Erez, Y. Tassa, D. Silver, and D. Wierstra. Continuous control with deep reinforcement learning. arXiv preprint arXiv:1509.02971 , 2015.
Lioutikov et al. (2014) R. Lioutikov, A. Paraschos, G. Neumann, and J. Peters. Sample-based information-theoretic stochastic optimal control. In International Conference on Robotics and Automation , 2014.
Mayer et al. (2006) H. Mayer, F. Gomez, D. Wierstra, I. Nagy, A. Knoll, and J. Schmidhuber. A system for robotic heart surgery that learns to tie knots using recurrent neural networks. In International Conference on Intelligent Robots and Systems (IROS) , 2006.
Meeussen et al. (2010) W. Meeussen, M. Wise, S. Glaser, S. Chitta, C. McGann, P. Mihelich, E. Marder-Eppstein, M. Muja, Victor Eruhimov, T. Foote, J. Hsu, R.B. Rusu, B. Marthi, G. Bradski, K. Konolige, B. Gerkey, and E. Berger. Autonomous door opening and plugging in with a personal robot. In International Conference on Robotics and Automation (ICRA) , 2010.
Mnih et al. (2013) V. Mnih, K. Kavukcuoglu, D. Silver, A. Graves, I. Antonoglou, D. Wierstra, and M. Riedmiller. Playing Atari with deep reinforcement learning. NIPS ’13 Workshop on Deep Learning , 2013.
Mohta et al. (2014) K. Mohta, V. Kumar, and K. Daniilidis. Vision based control of a quadrotor for perching on planes and lines. In International Conference on Robotics and Automation (ICRA) , 2014.
Mordatch and Todorov (2014) I. Mordatch and E. Todorov. Combining the benefits of function approximation and trajectory optimization. In Robotics: Science and Systems (RSS) , 2014.
Ng et al. (2004) A. Y. Ng, H. J. Kim, M. I. Jordan, and S. Sastry. Inverted autonomous helicopter flight via reinforcement learning. In International Symposium on Experimental Robotics , 2004.
Pascanu and Bengio (2012) R. Pascanu and Y. Bengio. On the difficulty of training recurrent neural networks. Technical Report arXiv:1211.5063, Universite de Montreal, 2012.
Pepik et al. (2012) B. Pepik, M. Stark, P. Gehler, and B. Schiele. Teaching 3D geometry to deformable part models. In Computer Vision and Pattern Recognition (CVPR) , 2012.
Peters and Schaal (2007) J. Peters and S. Schaal. Applying the episodic natural actor-critic architecture to motor primitive learning. In European Symposium on Artificial Neural Networks (ESANN) , 2007.
Peters and Schaal (2008) J. Peters and S. Schaal. Reinforcement learning of motor skills with policy gradients. Neural Networks , 21(4):682–697, 2008.
Peters et al. (2010) J. Peters, K. Mülling, and Y. Altün. Relative entropy policy search. In AAAI Conference on Artificial Intelligence , 2010.
Pinto and Gupta (2015) Lerrel Pinto and Abhinav Gupta. Supersizing self-supervision: Learning to grasp from 50k tries and 700 robot hours. CoRR , abs/1509.06825, 2015.
Pomerleau (1989) D. Pomerleau. ALVINN: an autonomous land vehicle in a neural network. In Advances in Neural Information Processing Systems (NIPS) , 1989.
Ross et al. (2011) S. Ross, G. Gordon, and A. Bagnell. A reduction of imitation learning and structured prediction to no-regret online learning. Journal of Machine Learning Research , 15:627–635, 2011.
Ross et al. (2013) S. Ross, N. Melik-Barkhudarov, K. Shaurya Shankar, A. Wendel, D. Dey, J. A. Bagnell, and M. Hebert. Learning monocular reactive UAV control in cluttered natural environments. In International Conference on Robotics and Automation (ICRA) , 2013.
Rubinstein and Kroese (2004) R. Rubinstein and D. Kroese. The Cross-Entropy Method: A Unified Approach to Combinatorial Optimization, Monte-Carlo Simulation and Machine Learning . Springer, 2004.
Savarese and Fei-Fei (2007) S. Savarese and L. Fei-Fei. 3D generic object categorization, localization and pose estimation. In International Conference on Computer Vision (ICCV) , 2007.
Schmidhuber (2015) J. Schmidhuber. Deep learning in neural networks: An overview. Neural Networks , 61:85–117, 2015.
Simard et al. (2003) P. Y. Simard, D. Steinkraus, and J. C. Platt. Best practices for convolutional neural networks applied to visual document analysis. In Seventh International Conference on Document Analysis and Recognition , 2003.
Stulp and Sigaud (2012) F. Stulp and O. Sigaud. Path integral policy improvement with covariance matrix adaptation. In International Conference on Machine Learning (ICML) , 2012.
Sung et al. (2015) Jaeyong Sung, Seok Hyun Jin, and Ashutosh Saxena. Robobarista: Object part based transfer of manipulation trajectories from crowd-sourcing in 3d pointclouds. CoRR , abs/1504.03071, 2015.
Szegedy et al. (2014) C. Szegedy, W. Liu, Y. Jia, P. Sermanet, S. Reed, D. Anguelov, D. Erhan, V. Vanhoucke, and A. Rabinovich. Going deeper with convolutions. arXiv preprint arXiv:1409.4842 , 2014.
Tedrake et al. (2004) R. Tedrake, T. Zhang, and H. Seung. Stochastic policy gradient reinforcement learning on a simple 3d biped. In International Conference on Intelligent Robots and Systems (IROS) , 2004.
Theodorou et al. (2010) E. Theodorou, J. Buchli, and S. Schaal. Reinforcement learning of motor skills in high dimensions. In International Conference on Robotics and Automation (ICRA) , 2010.
Todorov et al. (2012) E. Todorov, T. Erez, and Y. Tassa. MuJoCo: A physics engine for model-based control. In IEEE/RSJ International Conference on Intelligent Robots and Systems , 2012.
Tompson et al. (2014) J. J. Tompson, A. Jain, Y. LeCun, and C. Bregler. Joint training of a convolutional network and a graphical model for human pose estimation. In Advances in Neural Information Processing Systems (NIPS) , 2014.
Uijlings et al. (2013) J. Uijlings, K. van de Sande, T. Gevers, and A. Smeulders. Selective search for object recognition. International Journal of Computer Vision , 2013.
van Hoof et al. (2015) H. van Hoof, J. Peters, and G. Neumann. Learning of non-parametric control policies with high-dimensional state features. In International Conference on Artificial Intelligence and Statistics , 2015.
Wang and Banerjee (2014) H. Wang and A. Banerjee. Bregman alternating direction method of multipliers. In Advances in Neural Information Processing Systems (NIPS) . 2014.
Watter et al. (2015) M. Watter, J. Springenberg, J. Boedecker, and M. Riedmiller. Embed to control: A locally linear latent dynamics model for control from raw images. In Advanced in Neural Information Processing Systems (NIPS) , 2015.
Williams (1992) R. Williams. Simple statistical gradient-following algorithms for connectionist reinforcement learning. Machine Learning , 8(3-4):229–256, May 1992.
Wilson et al. (1996) W. J. Wilson, C. W. Williams Hulls, and G. S. Bell. Relative end-effector control using cartesian position based visual servoing. IEEE Transactions on Robotics and Automation , 12(5), 1996.
Wyrobek et al. (2008) K.A. Wyrobek, E.H. Berger, HF M. Van der Loos, and K. Salisbury. Towards a personal robotics development platform: Rationale and design of an intrinsically safe personal robot. In International Conference on Robotics and Automation (ICRA) , 2008.
Yoshimi and Allen (1994) B. H. Yoshimi and P. K. Allen. Active, uncalibrated visual servoing. In International Conference on Robotics and Automation (ICRA) , 1994.