E(n) Equivariant Graph Neural Networks
E(n) Equivariant Graph Neural Networks
E(n) 等变图神经网络
Victor Garcia Satorras Affiliation: UvA-Bosch Delta Lab, University of Amsterdam, Netherlands Correspondence to: v.garciasatorras@uva.nl Emiel Hoogeboom Affiliation: UvA-Bosch Delta Lab, University of Amsterdam, Netherlands Correspondence to: e.hoogeboom@uva.nl Max Welling Affiliation: UvA-Bosch Delta Lab, University of Amsterdam, Netherlands Correspondence to: m.welling@uva.nl
Abstract
摘要
This paper introduces a new model to learn graph neural networks equivariant to rotations, translations, reflections and permutations called -Equivariant Graph Neural Networks (EGNNs). In contrast with existing methods, our work does not require computationally expensive higher-order representations in intermediate layers while it still achieves competitive or better performance. In addition, whereas existing methods are limited to equivariance on dimensional spaces, our model is easily scaled to higher-dimensional spaces. We demonstrate the effectiveness of our method on dynamical systems modelling, representation learning in graph autoencoders and predicting molecular properties.
本文提出一种对旋转、平移、反射与置换等变的图神经网络新模型,称为 -等变图神经网络(EGNN)。与已有方法不同,本工作在中间层不需要计算昂贵的高阶表示,仍能达到有竞争力或更好的表现。此外,已有方法多限于三维空间上的等变性,而本模型可轻松扩展到更高维空间。我们在动力系统建模、图自编码器中的表示学习以及分子性质预测上验证了方法的有效性。
Keywords:
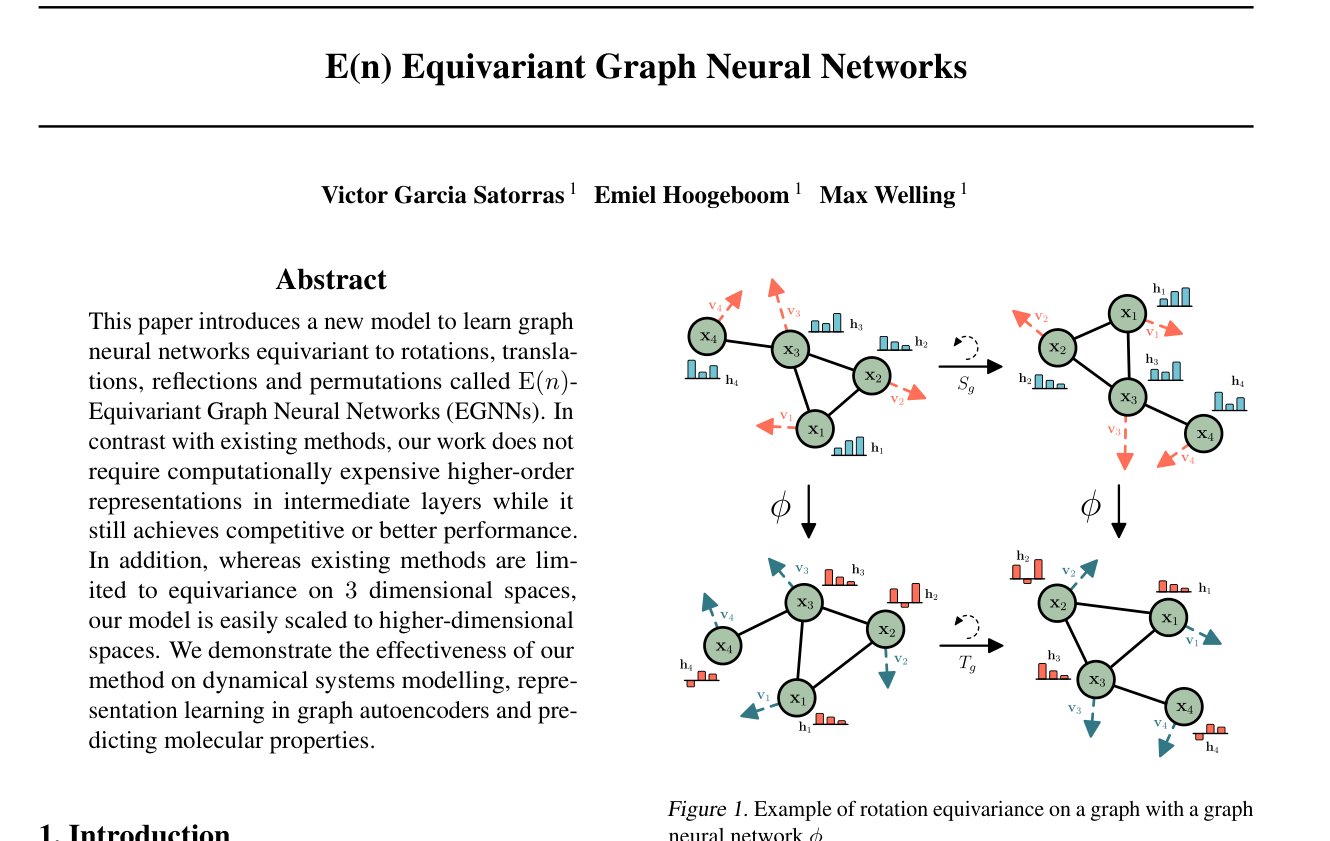
Figure 1: Example of rotation equivariance on a graph with a graph neural network
关键词:
图 1:图神经网络 在图上的旋转等变示例
1 Introduction
1 引言
Although deep learning has largely replaced hand-crafted features, many advances are critically dependent on inductive biases in deep neural networks. An effective method to restrict neural networks to relevant functions is to exploit the symmetry of problems by enforcing equivariance with respect to transformations from a certain symmetry group. Notable examples are translation equivariance in Convolutional Neural Networks and permutation equivariance in Graph Neural Networks (Bruna et al. 2013; Defferrard et al. 2016; Kipf & Welling 2016a).
尽管深度学习已在很大程度上取代了手工特征,许多进展仍关键地依赖深度网络中的归纳偏置。限制网络只表达相关函数的一种有效做法,是利用问题的对称性,强制对某对称群的变换保持等变。典型例子包括卷积神经网络中的平移等变,以及图神经网络中的置换等变(Bruna et al. 2013;Defferrard et al. 2016;Kipf & Welling 2016a)。
Many problems exhibit 3D translation and rotation symmetries. Some examples are point clouds (Uy et al. 2019), 3D molecular structures (Ramakrishnan et al. 2014) or N-body particle simulations (Kipf et al. 2018). The group corresponding to these symmetries is named the Euclidean group: SE(3) or when reflections are included E(3). It is often desired that predictions on these tasks are either equivariant or invariant with respect to E(3) transformations.
许多问题具有三维平移与旋转对称性。例如点云(Uy et al. 2019)、三维分子结构(Ramakrishnan et al. 2014)或 N 体粒子模拟(Kipf et al. 2018)。对应的对称群称为欧几里得群:SE(3);若再包含反射则为 E(3)。在这些任务上,人们常希望预测对 E(3) 变换保持等变或不变。
Recently, various forms and methods to achieve E(3) or SE(3) equivariance have been proposed (Thomas et al. 2018; Fuchs et al. 2020; Finzi et al. 2020; Köhler et al. 2020). Many of these works achieve innovations in studying types of higher-order representations for intermediate network layers. However, the transformations for these higher-order representations require coefficients or approximations that can be expensive to compute. Additionally, in practice for many types of data the inputs and outputs are restricted to scalar values (for instance temperature or energy, referred to as type- in literature) and 3d vectors (for instance velocity or momentum, referred to as type- in literature).
近来已有多种实现 E(3) 或 SE(3) 等变的形式与方法(Thomas et al. 2018;Fuchs et al. 2020;Finzi et al. 2020;Köhler et al. 2020)。不少工作通过研究中间层的高阶表示类型取得进展。然而,这些高阶表示的变换需要系数或近似,计算可能昂贵。此外,实践中许多数据的输入输出仅限于标量(如温度或能量,文献中称 type-0)与三维向量(如速度或动量,称 type-1)。
In this work we present a new architecture that is translation, rotation and reflection equivariant (), and permutation equivariant with respect to an input set of points. Our model is simpler than previous methods in that it does not require the spherical harmonics as in (Thomas et al. 2018; Fuchs et al. 2020) while it can still achieve competitive or better results. In addition, equivariance in our model is not limited to the 3-dimensional space and can be scaled to larger dimensional spaces without a significant increase in computation.
本文提出一种对平移、旋转与反射等变(),并对输入点集置换等变的新结构。相对先前方法,模型更简单:不需要像 Thomas et al. 2018、Fuchs et al. 2020 那样使用球谐函数,仍能达到有竞争力或更好的结果。此外,等变性不限于三维,可扩展到更高维空间而不显著增加计算量。
We evaluate our method in modelling dynamical systems, representation learning in graph autoencoders and predicting molecular properties in the QM9 dataset. Our method reports the best or very competitive performance in all three experiments.
我们在动力系统建模、图自编码器表示学习以及 QM9 分子性质预测上评测本方法。三项实验中均报告了最佳或极具竞争力的表现。
2 Background
2 背景
In this section we introduce the relevant materials on equivariance and graph neural networks which will later complement the definition of our method.
本节介绍等变与图神经网络的相关材料,后文定义方法时会用到。
2.1 Equivariance
2.1 等变性
Let be a set of transformations on for the abstract group . We say a function is equivariant to if there exists an equivalent transformation on its output space such that:
设 为抽象群 在 上的一组变换。称函数 对 等变,若在输出空间存在等价变换 ,使得:
As a practical example, let be a non-linear function, an input set of point clouds embedded in a -dimensional space, the transformed set of point clouds, a translation on the input set and an equivalent translation on the output set . If our transformation is translation equivariant, translating the input set and then applying the function on it, will deliver the same result as first running the function and then applying an equivalent translation to the output such that Equation 1 is fulfilled and . In this work we explore the following three types of equivariance on a set of particles :
作为实际例子,设 为非线性函数, 为嵌入在 维空间中的 个点云构成的输入集合, 为变换后的点云集合, 为输入上的平移 , 为输出上的等价平移 。若变换 对平移等变,则先平移输入再作用 ,应与先算 再对输出做等价平移 得到相同结果,从而满足方程 1:。本文在粒子集合 上考察下列三类等变:
- Translation equivariance. Translating the input by results in an equivalent translation of the output. Let be shorthand for . Then
- 平移等变。输入平移 导致输出同等平移。以 简记 ,则有 。
- Rotation (and reflection) equivariance. For any orthogonal matrix , let be shorthand for . Then rotating the input results in an equivalent rotation of the output .
- 旋转(与反射)等变。对任意正交矩阵 ,以 简记 。旋转输入导致输出同等旋转:。
- Permutation equivariance. Permuting the input results in the same permutation of the output where is a permutation on the row indexes.
- 置换等变。置换输入导致输出同样置换:,其中 作用在行下标上。
Note that velocities are unaffected by translations, but they transform equivalently under rotation (2) and permutation (3). Our method introduced in Section 3 will satisfy the three above mentioned equivariant constraints.
注意速度 不受平移影响,但在旋转(2)与置换(3)下同样变换。第 3 节引入的方法将满足上述三条等变约束。
2.2 Graph Neural Networks
2.2 图神经网络
Graph Neural Networks are permutation equivariant networks that operate on graph structured data (Bruna et al. 2013; Defferrard et al. 2016; Kipf & Welling 2016a). Given a graph with nodes and edges we define a graph convolutional layer following notation from (Gilmer et al. 2017) as:
图神经网络是在图结构数据上运作的置换等变网络(Bruna et al. 2013;Defferrard et al. 2016;Kipf & Welling 2016a)。给定图 ,节点 ,边 ,我们按 Gilmer et al. 2017 的记号定义一层图卷积为:
Where is the nf-dimensional embedding of node at layer . are the edge attributes. represents the set of neighbors of node . Finally, and are the edge and node operations respectively which are commonly approximated by Multilayer Perceptrons (MLPs).
其中 是节点 在第 层的 nf 维嵌入, 为边属性, 为节点 的邻居集合。 与 分别为边与节点运算,通常用多层感知机(MLP)近似。
3 Equivariant Graph Neural Networks
3 等变图神经网络
In this section we present Equivariant Graph Neural Networks (EGNNs). Following the notation from background Section 2.2, we consider a graph with nodes and edges . In addition to the feature node embeddings we now also consider a -dimensional coordinate associated with each of the graph nodes. Our model will preserve equivariance to rotations and translations on these set of coordinates and it will also preserve equivariance to permutations on the set of nodes in the same fashion as GNNs.
本节给出等变图神经网络(EGNN)。沿用背景 2.2 的记号,考虑图 ,节点 ,边 。除特征节点嵌入 外,现为每个图节点关联 维坐标 。模型将对这组坐标 保持旋转与平移等变,并对节点集 保持与 GNN 相同的置换等变。
Our Equivariant Graph Convolutional Layer (EGCL) takes as input the set of node embeddings , coordinate embeddings and edge information and outputs a transformation on and . Concisely: . The equations that define this layer are the following:
等变图卷积层(EGCL)的输入为节点嵌入集合 、坐标嵌入 与边信息 ,输出对 与 的变换。简记:。定义该层的方程如下:
Notice the main differences between the above proposed method and the original Graph Neural Network from equation 2 are found in equations 3 and 4. In equation 3 we now input the relative squared distance between two coordinates into the edge operation . The embeddings , , and the edge attributes are also provided as input to the edge operation as in the GNN case. In our case the edge attributes will incorporate the edge values , but they can also include additional edge information.
注意,上述方法与方程 2 中原始图神经网络的主要差别出现在方程 3 与 4。方程 3 把两坐标相对平方距离 送入边运算 。嵌入 、 与边属性 也与 GNN 一样作为边运算输入。本文中边属性取边值 ,也可纳入额外边信息。
In Equation 4 we update the position of each particle as a vector field in a radial direction. In other words, the position of each particle is updated by the weighted sum of all relative differences . The weights of this sum are provided as the output of the function that takes as input the edge embedding from the previous edge operation and outputs a scalar value. is chosen to be , which divides the sum by its number of elements. This equation is the main difference of our model compared to standard GNNs and it is the reason why equivariances 1, 2 are preserved (proof in Appendix A). Despite its simplicity, this equivariant operation is very flexible since the embedding can carry information from the whole graph and not only from the given edge .
方程 4 沿径向向量场更新每个粒子位置 :即用所有相对差 的加权和对 做更新。权重由函数 给出,该函数以前一步边嵌入 为输入并输出标量。 取 ,即按元素个数做平均。该方程是本模型相对标准 GNN 的主要差别,也是等变性质 1、2 得以保持的原因(证明见附录 A)。尽管形式简单,这一等变运算很灵活:嵌入 可携带整图信息,而不限于边 本身。
Finally, equations 5 and 6 follow the same updates than standard GNNs. Equation 5 is the aggregation step, in this work we choose to aggregate messages from all other nodes , but we could limit the message exchange to a given neighborhood if desired in both equations 5 and 4. Equation 6 performs the node operation which takes as input the aggregated messages , the node emedding and outputs the updated node embedding .
最后,方程 5 与 6 与标准 GNN 的更新一致。方程 5 为聚合步:本文选择对所有其他节点 聚合消息,但也可在方程 5 与 4 中把消息交换限制到给定邻域 。方程 6 执行节点运算 :输入聚合消息 与节点嵌入 ,输出更新后的 。
3.1 Analysis on E(n) equivariance
3.1 对 E(n) 等变性的分析
In this section we analyze the equivariance properties of our model for symmetries (i.e. properties 1 and 2 stated in section 2.1). In other words, our model should be translation equivariant on for any translation vector and it should also be rotation and reflection equivariant on for any orthogonal matrix . More formally our model satisfies:
本节分析模型对 对称(即 2.1 节性质 1 与 2)的等变性质。换言之,模型应对任意平移向量 在 上平移等变,并对任意正交矩阵 在 上旋转与反射等变。形式地,模型满足:
We provide a formal proof of this in Appendix A. Intuitively, let’s consider a feature which is already invariant, then we can see that the resultant edge embedding from Equation 3 will also be invariant, because in addition to , it only depends on squared distances , which are invariant. Next, Equation 4 computes by a weighted sum of differences which is added to , this transforms as a type-1 vector and preserves equivariance (see Appendix A). Finally the last two equations 5 and 6 that generate the next layer node-embeddings remain invariant since they only depend on and which, as we saw above, are invariant. Therefore the output is invariant and is equivariant to . Inductively, a composition of s will also be equivariant.
形式证明见附录 A。直观上,若 已对 不变,则方程 3 得到的边嵌入 也对 不变:除 外,它只依赖平方距离 ,而平方距离对 不变。接着,方程 4 用相对差 的加权和计算 并加到 上,这按 type-1 向量变换并保持等变(见附录 A)。最后生成下一层节点嵌入 的方程 5、6 只依赖 与 ,如前所述二者均对 不变,故输出 对 不变,而 对 保持 等变。归纳地,若干 EGCL 的复合也等变。
3.2 Extending EGNNs for vector type representations
3.2 扩展 EGNN 以表示向量型量
In this section we propose a slight modification to the presented method such that we explicitly keep track of the particle’s momentum. In some scenarios this can be useful not only to obtain an estimate of the particle’s velocity at every layer but also to provide an initial velocity value in those cases where it is not 0. We can include momentum to our proposed method by just replacing Equation 4 of our model with the following equation:
本节对前述方法做一轻微修改,显式跟踪粒子动量。在某些场景中,这不但可在每层得到粒子速度估计,也可在初始速度非零时提供初值。只需把模型方程 4 换成下式即可纳入动量:
Note that this extends the EGCL layer as . The only difference is that now we broke down the coordinate update (eq. 4) in two steps, first we compute the velocity and then we use this velocity to update the position . The initial velocity is scaled by a new function that maps the node embedding to a scalar value. Notice that if the initial velocity is set to zero (), both equations 4 and 7 become exactly the same. We proof the equivariance of this variant of the model in Appendix B.1. This variant is used in experiment 5.1 where we provide the initial velocity of the system, and predict a relative position change.
注意这把 EGCL 扩展为 。唯一差别是把坐标更新(方程 4)拆成两步:先算速度 ,再用该速度更新位置 。初始速度 由新函数 缩放,该函数把节点嵌入 映到标量。若初始速度为零(),则方程 4 与 7 完全相同。该变体的等变证明见附录 B.1。实验 5.1 使用该变体:提供系统初始速度,并预测相对位置变化。
| GNN | Radial Field | TFN | Schnet | EGNN | |
|---|---|---|---|---|---|
| Edge | $\mathbf{m}{ij}=\phi{\text{rf}}(\ | \mathbf{r}_{ij}^{l}\ | )\mathbf{r}_{ij}^{l}$ | ||
| Agg. | |||||
| Node | |||||
| Non-equivariant | -Equivariant | -Equivariant | -Invariant | -Equivariant |
Table 1: Comparison over different works from the literature under the message passing framework notation. We created this table with the aim to provide a clear and simple way to compare over these different methods. The names from left to right are: Graph Neural Networks (Gilmer et al. 2017); Radial Field from Equivariant Flows (Köhler et al. 2019); Tensor Field Networks (Thomas et al. 2018); Schnet (Schütt et al. 2017b); and our Equivariant Graph Neural Network. The difference between two points is written .
| GNN | Radial Field | TFN | Schnet | EGNN | |
|---|---|---|---|---|---|
| Edge | |||||
| Agg. | |||||
| Node | |||||
| 非等变 | -等变 | -等变 | -不变 | -等变 |
表 1:在消息传递框架记号下对比若干文献方法。制表旨在提供清晰、简单的对照。从左到右依次为:图神经网络(Gilmer et al. 2017);等变流中的 Radial Field(Köhler et al. 2019);Tensor Field Networks(Thomas et al. 2018);Schnet(Schütt et al. 2017b);以及本文的等变图神经网络。两点之差记为 。
3.3 Inferring the edges
3.3 推断边
Given a point cloud or a set of nodes, we may not always be provided with an adjacency matrix. In those cases we can assume a fully connected graph where all nodes exchange messages with each other as done in Equation 5. This fully connected approach may not scale well to large point clouds where we may want to locally limit the exchange of messages to a neighborhood to avoid an overflow of information.
给定点云或节点集合时,未必总有邻接矩阵。此时可假定全连接图,使所有节点彼此交换消息 ,如方程 5。全连接做法对大型点云可能扩展性不佳:为避免信息过载,往往希望把消息交换 限制在局部邻域 。
Similarly to (Serviansky et al. 2020; Kipf et al. 2018), we present a simple solution to infer the relations/edges of the graph in our model, even when they are not explicitly provided. Given a set of neighbors for each node , we can re-write the aggregation operation from our model (eq. 5) in the following way:
与 Serviansky et al. 2020、Kipf et al. 2018 类似,我们给出在边未显式给出时推断图关系/边的简单做法。对每个节点 给定邻居集 ,可将模型聚合(方程 5)改写为:
Where takes value if there is an edge between nodes and otherwise. Now we can choose to approximate the relations with the following function , where resembles a linear layer followed by a sigmoid function that takes as input the current edge embedding and outputs a soft estimation of its edge value. This modification does not change the properties of the model since we are only operating on the messages which are already invariant.
其中若节点 之间有边则 取 1,否则取 0。现可用函数 近似关系 ,其中 形如线性层加 sigmoid,以当前边嵌入为输入并输出边值的软估计。该修改不改变模型的 性质:我们只在已对 不变的消息 上运算。
4 Related Work
4 相关工作
Group equivariant neural networks have demonstrated their effectiveness in a wide variety of tasks (Cohen & Welling 2016; Cohen & Welling 2017; Weiler & Cesa 2019; Rezende et al. 2019; Romero & Cordonnier 2021). Recently, various forms and methods to achieve E(3) or SE(3) equivariance have been proposed. Thomas et al. 2018; Fuchs et al. 2020 utilize the spherical harmonics to compute a basis for the transformations, which allows transformations between higher-order representations. A downside to this method is that the spherical harmonics need to be recomputed which can be expensive. Currently, an extension of this method to arbitrary dimensions is unknown. Finzi et al. 2020 parametrize transformations by mapping kernels on the Lie Algebra. For this method the neural network outputs are in certain situations stochastic, which may be undesirable. Horie et al. 2020 proposes a set of isometric invariant and equivairant transformations for Graph Neural Networks. Köhler et al. 2019; Köhler et al. 2020 propose an equivariant network to model 3D point clouds, but the method is only defined for positional data on the nodes without any feature dimensions.
群等变神经网络已在多种任务上展现效力(Cohen & Welling 2016;Cohen & Welling 2017;Weiler & Cesa 2019;Rezende et al. 2019;Romero & Cordonnier 2021)。近来已有多种实现 E(3) 或 SE(3) 等变的形式与方法。Thomas et al. 2018;Fuchs et al. 2020 用球谐函数计算变换基,从而支持高阶表示之间的变换;缺点是球谐需反复计算,开销较大,且目前尚不知如何扩展到任意维。Finzi et al. 2020 通过在李代数上映射核来参数化变换;在某些情形下网络输出带随机性,可能并不理想。Horie et al. 2020 为图神经网络提出一组等距不变与等变变换。Köhler et al. 2019;Köhler et al. 2020 提出 等变网络以建模三维点云,但方法仅定义在节点位置数据上,没有特征维。
Another related line of research concerns message passing algorithms on molecular data. (Gilmer et al. 2017) presented a message passing setting (or Graph Neural Network) for quantum chemistry, this method is permutation equivariant but not translation or rotation equivariant. (Kondor et al. 2018) extends the equivariance of GNNs such that each neuron transforms in a specific way under permutations, but this extension only affects its permutation group and not translations or rotations in a geometric space. Further works (Schütt et al. 2017b; Schütt et al. 2017a) build invariant message passing networks by inputting the relative distances between points. Klicpera et al. 2020b; Klicpera et al. 2020a in addition to relative distances it includes a modified message passing scheme analogous to Belief Propagation that considers angles and directional information equivariant to rotations. It also uses Bessel functions and spherical harmonics to construct and orthogonal basis. Anderson et al. 2019; Miller et al. 2020 include equivariance in its intermediate layers for modelling the behavior and properties of molecular data. Our method is also framed as a message passing framework but in contrast to these methods it achieves equivariance.
另一条相关线索是分子数据上的消息传递。(Gilmer et al. 2017)提出面向量子化学的消息传递设定(即图神经网络),该方法对置换等变,但对平移或旋转不等变。(Kondor et al. 2018)把 GNN 的等变扩展到每个神经元在置换下按特定方式变换,但扩展只作用于置换群,而不作用于几何空间中的平移或旋转。后续工作(Schütt et al. 2017b;Schütt et al. 2017a)通过输入点间相对距离构建 不变的消息传递网络。Klicpera et al. 2020b;Klicpera et al. 2020a 在相对距离之外引入类似信念传播的消息传递,纳入对旋转等变的角度与方向信息,并用贝塞尔函数与球谐构造正交基。Anderson et al. 2019;Miller et al. 2020 在中间层纳入 等变以建模分子行为与性质。本方法同样置于消息传递框架,但与这些方法不同,它实现 等变。
Relationship with existing methods
与已有方法的关系
In Table 1 the EGNN equations are detailed together with some of its closest methods from the literature under the message passing notation from (Gilmer et al. 2017). This table aims to provide a simple way to compare these different algorithms. It is structured in three main rows that describe i) the edge ii) aggregation and iii) node update operations. The GNN algorithm is the same as the previously introduced in Section 2.1. Our EGNN algorithm is also equivalent to the description in Section 3 but notation has been modified to match the (edge, aggregation, node) format. In all equations . Notice that except the EGNN, all algorithms have the same aggregation operation and the main differences arise from the edge operation. The algorithm that we call ”Radial Field” is the equivariant update from (Köhler et al. 2019). This method is equivariant, however its main limitation is that it only operates on and it doesn’t propagate node features among nodes. In the method is modelled as an MLP. Tensor Field Networks (TFN) (Thomas et al. 2018) instead propagate the node embeddings but it uses spherical harmonics to compute its learnable weight kernel which preserves equivariance but is expensive to compute an limited to the 3 dimensional space. The SE(3) Transformer (Fuchs et al. 2020) (not included in this table), can be interpreted as an extension of TFN with attention. Schnet (Schütt et al. 2017b) can be interpreted as an invariant Graph Neural Network where receives as input relative distances and outputs a continuous filter convolution that multiplies the neighbor embeddings . Our EGNN differs from these other methods in terms that it performs two different updates in each of the table rows, one related to the embeddings and another related to the coordinates , these two variables exchange information in the edge operation. In summary the EGNN can retain the flexibility of GNNs while remaining equivariant as the Radial Field algorithm and without the need to compute expensive operations (i.e. spherical harmonics).
表 1 在 Gilmer et al. 2017 的消息传递记号下,把 EGNN 方程与若干最接近的文献方法并列,便于对照。表按三行组织,分别描述 (i) 边、(ii) 聚合与 (iii) 节点更新。GNN 算法即 2.1 节已介绍者。EGNN 亦与第 3 节描述等价,记号改写为(边、聚合、节点)格式。所有方程中 。注意除 EGNN 外,各算法的聚合运算相同,主要差别来自边运算。我们称为「Radial Field」的算法是 Köhler et al. 2019 的 等变更新:虽对 等变,但主要局限是只在 上运作,不在节点间传播节点特征 ;其中 用 MLP 建模。Tensor Field Networks(TFN,Thomas et al. 2018)则传播节点嵌入 ,但用球谐计算可学习权重核 ,保持 等变,计算昂贵且限于三维。SE(3) Transformer(Fuchs et al. 2020,未列入此表)可视为带注意力的 TFN 扩展。Schnet(Schütt et al. 2017b)可视为 不变的图神经网络: 以相对距离为输入,输出连续滤波卷积并与邻居嵌入 相乘。EGNN 与这些方法的差别在于:表中每一行都做两类更新——一类关乎嵌入 ,一类关乎坐标 ——二者在边运算中交换信息。总之,EGNN 可保留 GNN 的灵活性,同时像 Radial Field 那样保持 等变,又无需计算球谐等昂贵运算。
5 Experiments
5 实验
5.1 Modelling a dynamical system — N-body system
5.1 建模动力系统——N 体系统
In a dynamical system a function defines the time dependence of a point or set of points in a geometrical space. Modelling these complex dynamics is crucial in a variety of applications such as control systems (Chua et al. 2018), model based dynamics in reinforcement learning (Nagabandi et al. 2018), and physical systems simulations (Grzeszczuk et al. 1998; Watters et al. 2017). In this experiment we forecast the positions for a set of particles which are modelled by simple interaction rules, yet can exhibit complex dynamics.
在动力系统中,一个函数定义几何空间中一点或一组点的时间依赖。建模这类复杂动力学对控制系统(Chua et al. 2018)、强化学习中的基于模型动力学(Nagabandi et al. 2018)以及物理系统模拟(Grzeszczuk et al. 1998;Watters et al. 2017)等应用至关重要。本实验预测一组粒子的位置:交互规则简单,却可展现复杂动力学。
Similarly to (Fuchs et al. 2020), we extended the Charged Particles N-body experiment from (Kipf et al. 2018) to a 3 dimensional space. The system consists of 5 particles that carry a positive or negative charge and have a position and a velocity associated in 3-dimensional space. The system is controlled by physic rules: particles are attracted or repelled depending on their charges. This is an equivariant task since rotations and translations on the input set of particles result in the same transformations throughout the entire trajectory.
与 Fuchs et al. 2020 类似,我们把 Kipf et al. 2018 的带电粒子 N 体实验扩展到三维。系统由 5 个带正或负电荷的粒子组成,各自在三维空间中有位置与速度。物理规则控制吸引或排斥。该任务是等变的:对输入粒子集做旋转与平移,会在整条轨迹上导致相同变换。
Dataset: We sampled 3.000 trajectories for training, 2.000 for validation and 2.000 for testing. Each trajectory has a duration of 1.000 timesteps. For each trajectory we are provided with the initial particle positions , their initial velocities and their respective charges . The task is to estimate the positions of the five particles after 1.000 timesteps. We optimize the averaged Mean Squared Error of the estimated position with the ground truth one.
数据集: 采样 3,000 条训练轨迹、2,000 条验证、2,000 条测试。每条轨迹时长 1,000 个时间步。对每条轨迹给定初始粒子位置 、初始速度 以及电荷 。任务是估计 1,000 步后五个粒子的位置。我们优化估计位置相对真值的平均均方误差。
Implementation details: In this experiment we used the extension of our model that includes velocity from section 3.2. We input the position as the first layer coordinates of our model and the velocity as the initial velocity in Equation 7, the norms are also provided as features to through a linear mapping. The charges are input as edge attributes . The model outputs the last layer coordinates as the estimated positions. We compare our method to its non equivariant Graph Neural Network (GNN) cousin, and the equivariant methods: Radial Field (Köhler et al. 2019), Tensor Field Networks and the SE(3) Transformer. All algorithms are composed of 4 layers and have been trained under the same conditions, batch size 100, 10.000 epochs, Adam optimizer, the learning rate was tuned independently for each model. We used 64 features for the hidden layers in the Radial Field, the GNN and our EGNN. As non-linearity we used the Swish activation function (Ramachandran et al. 2017). For TFN and the SE(3) Transformer we swept over different number of vector types and features and chose those that provided the best performance. Further implementation details are provided in Appendix C.1. A Linear model that simply considers the motion equation is also included as a baseline. We also provide the average forward pass time in seconds for each of the models for a batch of 100 samples in a GTX 1080 Ti GPU.
实现细节: 本实验使用第 3.2 节含速度的模型扩展。把位置 作为模型第一层坐标 ,把速度 作为方程 7 的初始速度;范数 也经线性映射作为特征送入 。电荷作为边属性 。模型输出最后一层坐标 作为估计位置。对比非等变的图神经网络(GNN)近亲,以及等变方法:Radial Field(Köhler et al. 2019)、Tensor Field Networks 与 SE(3) Transformer。所有算法均为 4 层,训练条件相同:batch size 100、10,000 epoch、Adam 优化器,学习率各自调优。Radial Field、GNN 与 EGNN 隐层用 64 维特征;非线性用 Swish(Ramachandran et al. 2017)。对 TFN 与 SE(3) Transformer 扫过不同向量类型数与特征数并取最优。更多细节见附录 C.1。另以仅用运动方程 的线性模型为基线。我们还给出各模型在 GTX 1080 Ti 上、batch 100 的平均前向时间(秒)。
| Method | MSE | Forward time (s) |
|---|---|---|
| Linear | 0.0819 | .0001 |
| SE(3) Transformer | 0.0244 | .1346 |
| Tensor Field Network | 0.0155 | .0343 |
| Graph Neural Network | 0.0107 | .0032 |
| Radial Field | 0.0104 | .0039 |
| EGNN | 0.0071 | .0062 |
Table 2: Mean Squared Error for the future position estimation in the N-body system experiment, and forward time in seconds for a batch size of 100 samples running in a GTX 1080Ti GPU.
| Method | MSE | Forward time (s) |
|---|---|---|
| Linear | 0.0819 | .0001 |
| SE(3) Transformer | 0.0244 | .1346 |
| Tensor Field Network | 0.0155 | .0343 |
| Graph Neural Network | 0.0107 | .0032 |
| Radial Field | 0.0104 | .0039 |
| EGNN | 0.0071 | .0062 |
表 2:N 体系统实验中未来位置估计的均方误差,以及在 GTX 1080Ti 上 batch size 为 100 时的前向时间(秒)。
Results As shown in Table 2 our model significantly outperforms the other equivariant and non-equivariant alternatives while still being efficient in terms of running time. It reduces the error with respect to the second best performing method by a . In addition it doesn’t require the computation of spherical harmonics which makes it more time efficient than Tensor Field Networks and the SE(3) Transformer.
结果。 如表 2 所示,本模型显著优于其他等变与非等变方案,同时前向仍较高效;相对第二名误差降低约 。此外无需计算球谐,因而比 Tensor Field Networks 与 SE(3) Transformer 更省时。
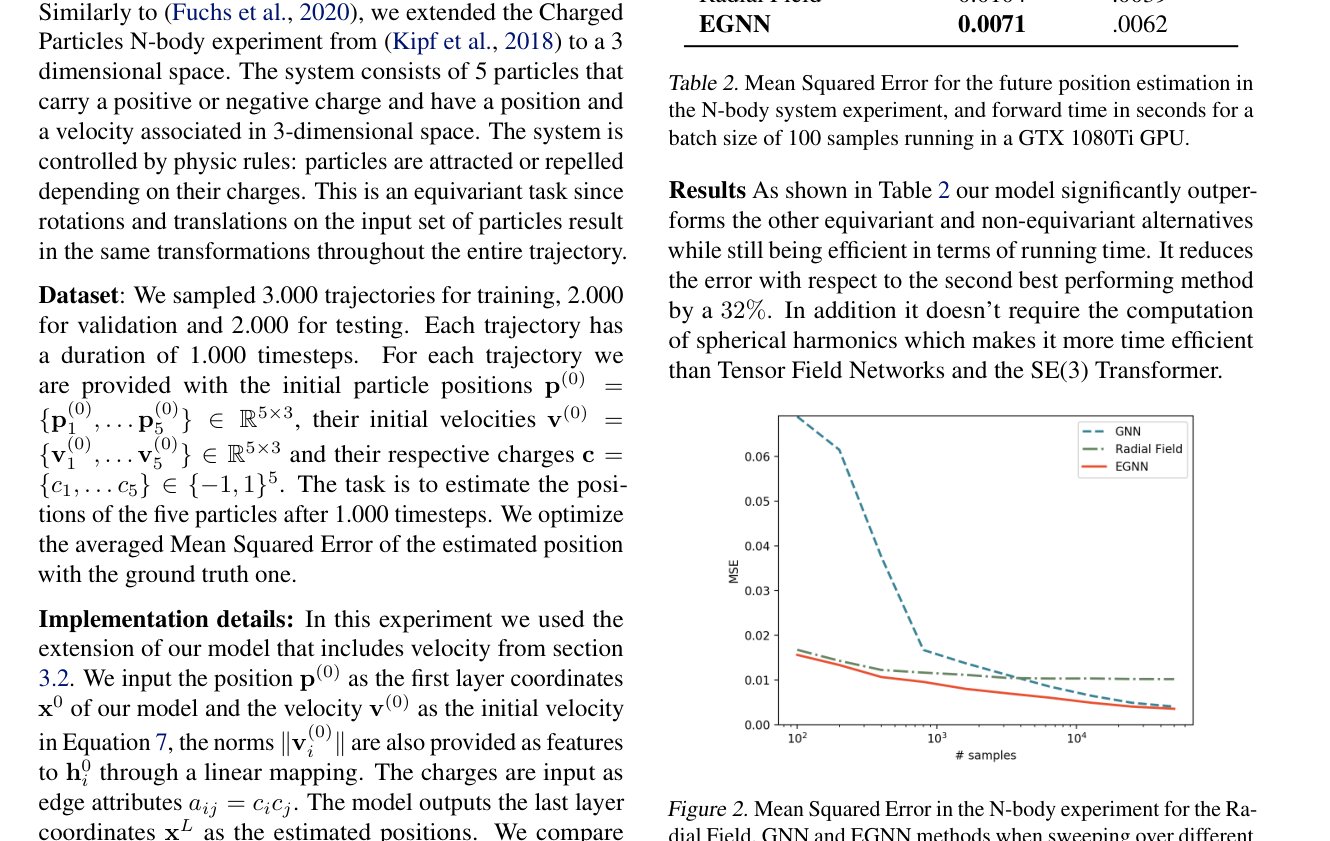
Figure 2: Mean Squared Error in the N-body experiment for the Radial Field, GNN and EGNN methods when sweeping over different amounts of training data.
图 2:在不同训练样本量下,Radial Field、GNN 与 EGNN 在 N 体实验中的均方误差。
Analysis for different number of training samples: We want to analyze the performance of our EGNN in the small and large data regime. In the following, we report on a similar experiment as above, but instead of using 3.000 training samples we generated a new training partition of 50.000 samples and we sweep over different amounts of data from 100 to 50.000 samples. We compare the performances of our EGNN vs its non-equivariant GNN counterpart and the Radial Field algorithm. Results are presented in Figure 2. Our method outperforms both Radial Field and GNNs in the small and large data regimes. This shows the EGNN is more data efficient than GNNs since it doesn’t require to generalize over rotations and translations of the data while it ensembles the flexibility of GNNs in the larger data regime. Due to its high model bias, the Radial Field algorithm performs well when data is scarce but it is unable to learn the subtleties of the dataset as we increase the training size. In summary, our EGNN benefits from both the high bias of methods and the flexibility of GNNs.
对不同训练样本量的分析: 我们希望分析 EGNN 在小数据与大数据体制下的表现。以下报告与上文类似的实验,但不用 3,000 个训练样本,而是生成 50,000 样本的新训练划分,并在 100 到 50,000 之间扫样本量。对比 EGNN、其非等变 GNN 对照以及 Radial Field。结果见图 2。无论小数据还是大数据体制,本方法都优于 Radial Field 与 GNN。这说明 EGNN 比 GNN 更省数据:不必对数据的旋转与平移再做泛化;在大数据体制下又保留了 GNN 的灵活性。Radial Field 因模型偏置强,数据稀缺时表现不错,但随训练量增大难以学到数据细微结构。总之,EGNN 同时受益于 方法的高偏置与 GNN 的灵活性。
5.2 Graph Autoencoder
5.2 图自编码器
A Graph Autoencoder can learn unsupervised representations of graphs in a continuous latent space (Kipf & Welling 2016b; Simonovsky & Komodakis 2018). In this experiment section we use our EGNN to build an Equivariant Graph Autoencoder. We will explain how Graph Autoencoders can benefit from equivariance and we will show how our method outperforms standard GNN autoencoders in the provided datasets. This problem is particularly interesting since the embedding space can be scaled to larger dimensions and is not limited to a 3 dimensional Euclidean space.
图自编码器可在连续潜空间中学习图的无监督表示(Kipf & Welling 2016b;Simonovsky & Komodakis 2018)。本节用 EGNN 构建等变图自编码器,说明图自编码器如何从等变中受益,并展示本方法在给定数据集上优于标准 GNN 自编码器。该问题尤其有趣:嵌入空间可扩展到更高维,不限于三维欧几里得空间。
Similarly to the work of (Kipf & Welling 2016b) further extended by section 3.3 in (Liu et al. 2019), our graph auto-encoder embeds a graph into a set of latent nodes , where is the number of nodes and the embedding size per node. Notice this may reduce the memory complexity to store the graphs from to where may depend on for a certain approximation error tolerance. This differs from the variational autoencoder proposed in (Simonovsky & Komodakis 2018) which embeds the graph in a single vector , which causes the reconstruction to be computationally very expensive since the nodes of the decoded graph have to be matched again to the ground truth. In addition to the introduced graph generation and representation learning methods, it is worth it mentioning that in the context of graph compression other methods (Candès & Recht 2009) can be used.
与 Kipf & Welling 2016b 以及 Liu et al. 2019 第 3.3 节的扩展类似,图自编码器 把图 嵌入为一组潜节点 ,其中 为节点数, 为每节点嵌入维。注意这可能把存图的内存复杂度从 降到 ,其中 可随某近似误差容忍度依赖 。这与 Simonovsky & Komodakis 2018 的变分自编码器不同:后者把图嵌入单个向量 ,重建时解码图的节点需再与真值匹配,计算非常昂贵。除上述图生成与表示学习方法外,图压缩语境下也可使用 Candès & Recht 2009 等方法。
More specifically, we will compare our Equivariant Graph Auto-Encoder in the task presented in (Liu et al. 2019) where a graph with node features and adjacency matrix is embedded into a latent space . Following (Kipf & Welling 2016b; Liu et al. 2019), we are only interested in reconstructing the adjacency matrix since the datasets we will work with do not contain node features. The decoder proposed by (Liu et al. 2019) takes as input the embedding space and outputs the reconstructed adjacency matrix , this decoder function is defined as follows:
更具体地,我们在 Liu et al. 2019 提出的任务上对比等变图自编码器:图 带节点特征 与邻接矩阵 ,嵌入到潜空间 。沿用 Kipf & Welling 2016b;Liu et al. 2019,我们只关心重建邻接矩阵 ,因为所用数据集不含节点特征。Liu et al. 2019 提出的解码器 以嵌入空间 为输入,输出重建邻接 ,定义为:
Where and are its only learnable parameters and is the decoder edge function applied to every pair of node embeddings. It reflects that edge probabilities will depend on the relative distances among node embeddings. The training loss is defined as the binary cross entropy between the estimated and the ground truth edges .
其中 与 是仅有的可学习参数, 为作用于每对节点嵌入的解码边函数。它表明边概率将依赖节点嵌入间的相对距离。训练损失定义为估计边与真值边之间的二元交叉熵 。
The symmetry problem: The above stated autoencoder may seem straightforward to implement at first sight but in some cases there is a strong limitation regarding the symmetry of the graph. Graph Neural Networks are convolutions on the edges and nodes of a graph, i.e. the same function is applied to all edges and to all nodes. In some graphs (e.g. those defined only by its adjacency matrix) we may not have input features in the nodes, and for that reason the difference among nodes relies only on their edges or neighborhood topology. Therefore, if the neighborhood of two nodes is exactly the same, their encoded embeddings will be the same too. A clear example of this is a cycle graph (an example of a 4 nodes cycle graph is provided in Figure 3). When running a Graph Neural Network encoder on a node featureless cycle graph, we will obtain the exact same embedding for each of the nodes, which makes it impossible to reconstruct the edges of the original graph from the node embeddings. The cycle graph is a severe example where all nodes have the exact same neighborhood topology but these symmetries can be present in different ways for other graphs with different edge distributions or even when including node features if these are not unique.
对称性问题: 上述自编码器初看似乎容易实现,但在某些情形下图的对称性会带来强限制。图神经网络是在边与节点上的卷积,即同一函数作用于所有边与所有节点。某些图(例如仅由邻接矩阵定义者)可能没有节点输入特征,节点之间的差别只依赖边或邻域拓扑。因此,若两节点邻域完全相同,其编码嵌入也会相同。清晰例子是环图(图 3 给出 4 节点环图示例)。在无节点特征的环图上跑图神经网络编码器,每个节点会得到完全相同的嵌入,从而无法从节点嵌入重建原图的边。环图是所有节点邻域拓扑完全相同的极端情形;其他边分布的图,乃至节点特征不唯一时,也可能以不同方式出现这类对称。
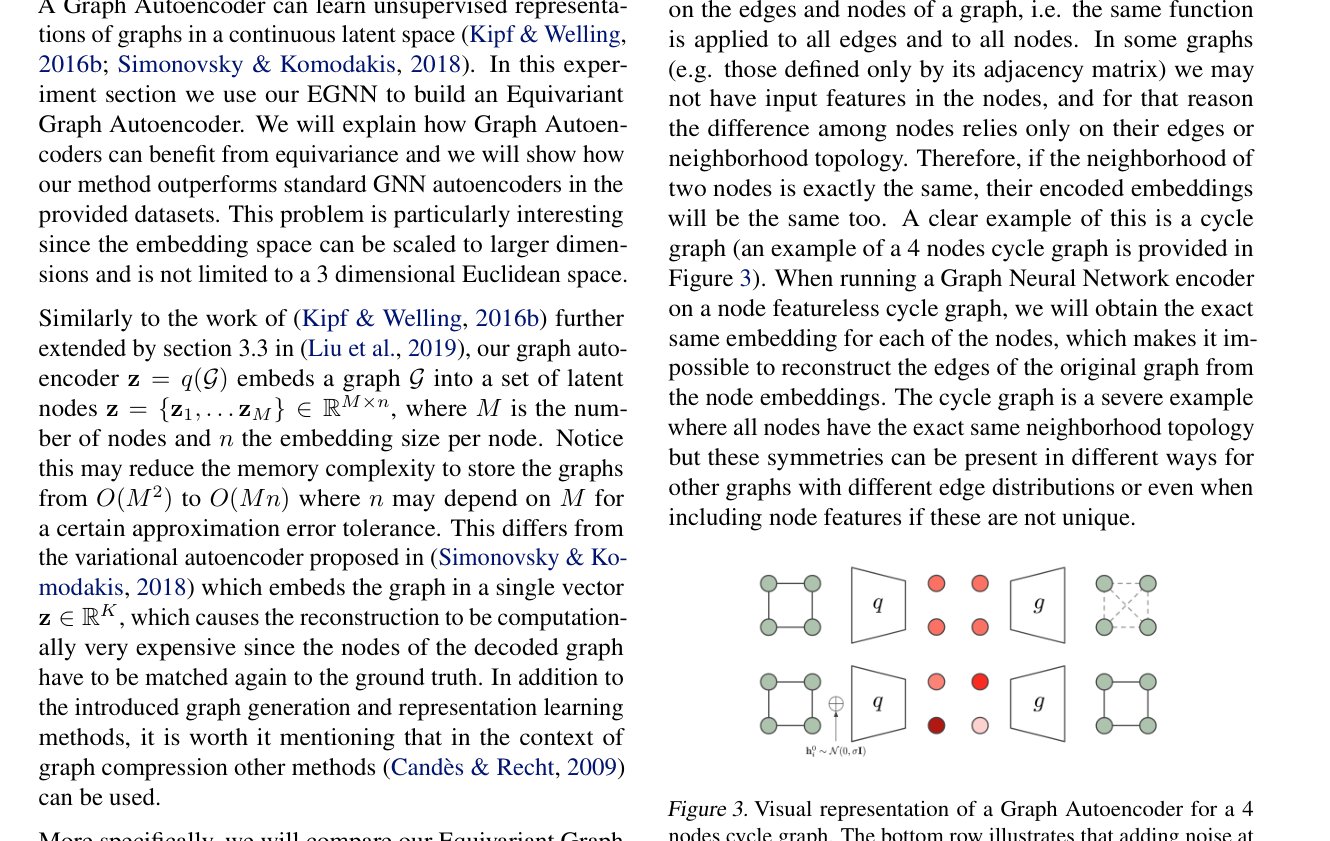
Figure 3: Visual representation of a Graph Autoencoder for a 4 nodes cycle graph. The bottom row illustrates that adding noise at the input graph breaks the symmetry of the embedding allowing the reconstruction of the adjacency matrix.
图 3:4 节点环图上图自编码器的示意。底行说明:在输入图加噪声可打破嵌入对称,从而能重建邻接矩阵。
| Community Small | Erdos&Renyi | |||||
|---|---|---|---|---|---|---|
| Encoder | BCE | % Error | F1 | BCE | % Error | F1 |
| Baseline | - | 31.79 | .0000 | - | 25.13 | 0.000 |
| GNN | 6.75 | 1.29 | 0.980 | 14.15 | 4.62 | 0.907 |
| Noise-GNN | 3.32 | 0.44 | 0.993 | 4.56 | 1.25 | 0.975 |
| Radial Field | 9.22 | 1.19 | 0.981 | 6.78 | 1.63 | 0.968 |
| EGNN | 2.14 | 0.06 | 0.999 | 1.65 | 0.11 | 0.998 |
Figure 4: In the Table at the left we report the Binary Cross Entropy, % Error and F1 scores for the test partition on the Graph Autoencoding experiment in the Community Small and Erdos&Renyi datasets. In the Figure at the right, we report the F1 score when overfitting a training partition of 100 samples in the Erdos&Renyi dataset for different values of sparsity . The GNN is not able to successfully auto-encode sparse graphs (small values) for the Erdos&Renyi dataset even when training and testing on the same small subset.
| Community Small | Erdos&Renyi | |||||
|---|---|---|---|---|---|---|
| Encoder | BCE | % Error | F1 | BCE | % Error | F1 |
| Baseline | - | 31.79 | .0000 | - | 25.13 | 0.000 |
| GNN | 6.75 | 1.29 | 0.980 | 14.15 | 4.62 | 0.907 |
| Noise-GNN | 3.32 | 0.44 | 0.993 | 4.56 | 1.25 | 0.975 |
| Radial Field | 9.22 | 1.19 | 0.981 | 6.78 | 1.63 | 0.968 |
| EGNN | 2.14 | 0.06 | 0.999 | 1.65 | 0.11 | 0.998 |
图 4:左表报告 Community Small 与 Erdos&Renyi 数据集上图自编码实验测试集的二元交叉熵、% Error 与 F1。右图报告在 Erdos&Renyi 上对 100 个训练样本过拟合时、不同稀疏度 下的 F1。即便在同一小子集上训练与测试,GNN 仍无法成功自编码稀疏图( 很小)。
An ad-hoc method to break the symmetry of the graph is introduced by (Liu et al. 2019). This method introduces noise sampled from a Gaussian distribution into the input node features of the graph . This noise allows different representations for all node embeddings and as a result the graph can be decoded again, but it comes with a drawback, the network has to generalize over the new introduced noise distribution. Our Equivariant Graph Autoencoder will remain translation and rotation equivariant to this sampled noise which we find makes the generalization much easier. Another way of looking at this is considering the sampled noise makes the node representations go from structural to positional (Srinivasan & Ribeiro 2019) where equivariance may be beneficial. In our case we will simply input this noise as the input coordinates of our EGNN which will output an equivariant transformation of them , this output will be used as the embedding of the graph (i.e. ) which is the input to the decoder from Equation 9.
Liu et al. 2019 引入一种打破图对称的临时做法:向图的输入节点特征加入高斯噪声 。噪声使各节点嵌入可区分,从而图可再被解码;代价是网络必须对引入的噪声分布做泛化。等变图自编码器对该采样噪声保持平移与旋转等变,我们发现这使泛化容易得多。另一视角是:采样噪声使节点表示从结构转向位置(Srinivasan & Ribeiro 2019),此时 等变可能有益。本文直接把噪声作为 EGNN 的输入坐标 ,输出对其等变变换 ,用作图嵌入(即 )并送入方程 9 的解码器。
Dataset: We generated community-small graphs (You et al. 2018; Liu et al. 2019) by running the original code from (You et al. 2018). These graphs contain nodes. We also generated a second dataset using the Erdos&Renyi generative model (Bollobás & Béla 2001) sampling random graphs with an initial number of nodes and edge probability . We sampled graphs for training, for validation and for test for both datasets. Each graph is defined as and adjacency matrix .
数据集: 用 You et al. 2018 的原始代码生成 community-small 图(You et al. 2018;Liu et al. 2019),节点数 。第二套数据用 Erdos&Renyi 生成模型(Bollobás & Béla 2001),初始节点 、边概率 。两套数据各采样 5,000 训练、500 验证、500 测试。每张图定义为邻接矩阵 。
Implementation details: Our Equivariant Graph Auto-Encoder is composed of an EGNN encoder followed by the decoder from Equation 9. The graph edges are input as edge attributes in Equation 3. The noise used to break the symmetry is input as the coordinates in the first layer and is initialized as ones since we are working with featureless graphs. As mentioned before, the encoder outputs an equivariant transformation on the coordinates which is the graph embedding and input to the decoder . We use dimensions for the embedding space. We compare the EGNN to its GNN cousin, we also compare to Noise-GNN which is an adaptation of our GNN to match the setting from (Liu et al. 2019), and we also include the Radial Field algorithm as an additional baseline. All four models have 4 layers, 64 features for the hidden layers, the Swish activation function as a non-linearity and they were all trained for 100 epochs using the Adam optimizer and learning rate . More details are provided in Appendix C.2. Since the number of nodes is larger than the number of layers, the receptive field of a GNN may not comprise the whole graph which can make the comparison unfair with our EGNN. To avoid this limitation, all models exchange messages among all nodes and the edge information is provided as edge attributes in all of them.
实现细节: 等变图自编码器由 EGNN 编码器与方程 9 的解码器组成。图边 作为方程 3 中的边属性 。打破对称的噪声作为第一层坐标 ; 初始化为全一,因为处理的是无特征图。如前所述,编码器对坐标输出等变变换,即图嵌入,并作为解码器输入 。嵌入空间取 。对比 EGNN 与其 GNN 近亲,以及适配 Liu et al. 2019 设定的 Noise-GNN,并加入 Radial Field 基线。四个模型均为 4 层、隐层 64 维特征、Swish 非线性,Adam、学习率 训练 100 epoch。更多细节见附录 C.2。由于节点数大于层数,GNN 感受野可能无法覆盖整图,与 EGNN 对比可能不公。为避免此限制,所有模型在全部节点间交换消息,并以边属性 提供边信息。
Results: In the table from Figure 4 we report the Binary Cross Entropy loss between the estimated and ground truth edges, the % Error which is defined as the percentage of wrong predicted edges with respect to the total amount of potential edges, and the F1 score of the edge classification, all numbers refer to the test partition. We also include a ”Baseline” that predicts all edges as missing . The standard GNN seems to suffer from the symmetry problem and provides the worst performance. When introducing noise (Noise-GNN), both the loss and the error decrease showing that it is actually useful to add noise to the input nodes. Finally, our EGNN remains equivariant to this noise distribution and provides the best reconstruction with a error in the Erdos&Renyi dataset and close to optimal in the Community Small dataset. A further analysis of the reconstruction error for different embedding sizes is reported in Appendix D.1.
结果: 图 4 左表报告估计边与真值边的二元交叉熵、% Error(错误预测边数相对潜在边总数的百分比)以及边分类 F1,均为测试集。另含「Baseline」:预测所有边缺失 。标准 GNN 似乎受对称性问题困扰,表现最差。引入噪声(Noise-GNN)后损失与误差均下降,说明向输入节点加噪确实有用。最终,EGNN 对该噪声分布保持 等变,重建最佳:Erdos&Renyi 上误差 ,Community Small 上接近最优的 。不同嵌入维 下的重建误差进一步分析见附录 D.1。
| Task | ZPVE | |||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Units | bohr3 | meV | meV | meV | D | cal/mol K | meV | meV | bohr3 | meV | meV | meV |
| NMP | .092 | 69 | 43 | 38 | .030 | .040 | 19 | 17 | .180 | 20 | 20 | 1.50 |
| Schnet | .235 | 63 | 41 | 34 | .033 | .033 | 14 | 14 | .073 | 19 | 14 | 1.70 |
| Cormorant | .085 | 61 | 34 | 38 | .038 | .026 | 20 | 21 | .961 | 21 | 22 | 2.03 |
| L1Net | .088 | 68 | 46 | 35 | .043 | .031 | 14 | 14 | .354 | 14 | 13 | 1.56 |
| LieConv | .084 | 49 | 30 | 25 | .032 | .038 | 22 | 24 | .800 | 19 | 19 | 2.28 |
| DimeNet++* | .044 | 33 | 25 | 20 | .030 | .023 | 8 | 7 | .331 | 6 | 6 | 1.21 |
| TFN | .223 | 58 | 40 | 38 | .064 | .101 | - | - | - | - | - | - |
| SE(3)-Tr. | .142 | 53 | 35 | 33 | .051 | .054 | - | - | - | - | - | - |
| EGNN | .071 | 48 | 29 | 25 | .029 | .031 | 12 | 12 | .106 | 12 | 11 | 1.55 |
Table 3: Mean Absolute Error for the molecular property prediction benchmark in QM9 dataset. *DimeNet++ uses slightly different train/val/test partitions than the other papers listed here.
| Task | ZPVE | |||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Units | bohr3 | meV | meV | meV | D | cal/mol K | meV | meV | bohr3 | meV | meV | meV |
| NMP | .092 | 69 | 43 | 38 | .030 | .040 | 19 | 17 | .180 | 20 | 20 | 1.50 |
| Schnet | .235 | 63 | 41 | 34 | .033 | .033 | 14 | 14 | .073 | 19 | 14 | 1.70 |
| Cormorant | .085 | 61 | 34 | 38 | .038 | .026 | 20 | 21 | .961 | 21 | 22 | 2.03 |
| L1Net | .088 | 68 | 46 | 35 | .043 | .031 | 14 | 14 | .354 | 14 | 13 | 1.56 |
| LieConv | .084 | 49 | 30 | 25 | .032 | .038 | 22 | 24 | .800 | 19 | 19 | 2.28 |
| DimeNet++* | .044 | 33 | 25 | 20 | .030 | .023 | 8 | 7 | .331 | 6 | 6 | 1.21 |
| TFN | .223 | 58 | 40 | 38 | .064 | .101 | - | - | - | - | - | - |
| SE(3)-Tr. | .142 | 53 | 35 | 33 | .051 | .054 | - | - | - | - | - | - |
| EGNN | .071 | 48 | 29 | 25 | .029 | .031 | 12 | 12 | .106 | 12 | 11 | 1.55 |
表 3:QM9 分子性质预测基准上的平均绝对误差。*DimeNet++ 使用的训练/验证/测试划分与表中其他论文略有不同。
Overfitting the training set: We explained the symmetry problem and we showed the EGNN outperforms other methods in the given datasets. Although we observed that adding noise to the GNN improves the results, it is difficult to exactly measure the impact of the symmetry limitation in these results independent from other factors such as generalization from the training to the test set. In this section we conduct an experiment where we train the different models in a subset of 100 Erdos&Renyi graphs and embedding size with the aim to overfit the data. We evaluate the methods on the training data. In this experiment the GNN is unable to fit the training data properly while the EGNN can achieve perfect reconstruction and Noise-GNN close to perfect. We sweep over different sparsity values from to since the symmetry limitation is more present in very sparse or very dense graphs. We report the F1 scores of this experiment in the right plot of Figure 4.
对训练集过拟合: 我们解释了对称性问题,并展示 EGNN 在给定数据集上优于其他方法。虽观察到给 GNN 加噪可改进结果,但很难把对称限制的影响与训练到测试的泛化等因素完全分开度量。本节在 100 张 Erdos&Renyi 图的子集上、嵌入维 训练各模型,目标是过拟合数据,并在训练数据上评估。该实验中 GNN 无法很好拟合训练数据,而 EGNN 可完美重建,Noise-GNN 接近完美。我们扫过 从 到 的稀疏度,因为极稀疏或极稠密图上对称限制更明显。图 4 右图报告该实验的 F1。
In this experiment we showed that equivariance improves performance when embedding graphs in a continuous space as a set of nodes in dimension . Even though this is a simple reconstruction task, we think this can be a useful step towards generating graphs or molecules where often graphs (i.e. edges) are decoded as pairwise distances or similarities between nodes e.g. (Kipf & Welling 2016b; Liu et al. 2019; Grover et al. 2019), and these metrics (e.g. eq. 9) are invariant. Additionally this experiment also showed that our method can successfully perform in a equivariant task for higher dimensional spaces where .
本实验表明:把图嵌入为 维连续空间中的一组节点时, 等变可提升表现。即便这是简单重建任务,我们认为这对生成图或分子仍有用——图(即边)常被解码为节点间成对距离或相似度,例如 Kipf & Welling 2016b;Liu et al. 2019;Grover et al. 2019,而这些度量(如方程 9)对 不变。此外,实验也表明本方法可在 的更高维空间成功完成 等变任务。
5.3 Molecular data — QM9
5.3 分子数据——QM9
The QM9 dataset (Ramakrishnan et al. 2014) has become a standard in machine learning as a chemical property prediction task. The QM9 dataset consists of small molecules represented as a set of atoms (up to 29 atoms per molecule), each atom having a 3D position associated and a five dimensional one-hot node embedding that describe the atom type (H, C, N, O, F). The dataset labels are a variety of chemical properties for each of the molecules which are estimated through regression. These properties are invariant to translations, rotations and reflections on the atom positions. Therefore those models that are E(3) invariant are highly suitable for this task.
QM9 数据集(Ramakrishnan et al. 2014)已成为机器学习中化学性质预测的标准任务。QM9 由小分子组成,每个分子是一组原子(至多 29 个),每个原子有三维位置以及描述原子类型(H、C、N、O、F)的五维 one-hot 节点嵌入。标签是各分子的多种化学性质,通过回归估计。这些性质对原子位置的平移、旋转与反射不变,因此 E(3) 不变模型非常适合该任务。
We imported the dataset partitions from (Anderson et al. 2019), 100K molecules for training, 18K for validation and 13K for testing. A variety of 12 chemical properties were estimated per molecule. We optimized and report the Mean Absolute Error between predictions and ground truth.
我们采用 Anderson et al. 2019 的数据划分:100K 训练、18K 验证、13K 测试。每个分子估计 12 种化学性质。优化并报告预测与真值之间的平均绝对误差。
Implementation details: Our EGNN receives as input the 3D coordinate locations of each atom which are provided as in Equation 3 and an embedding of the atom properties which is provided as input node features . Since this is an invariant task and also positions are static, there is no need to update the particle’s position by running Equation 4 as we did in previous experiments. Consequently, we tried both manners and we didn’t notice any improvement by updating . When not updating the particle’s position (i.e. skipping Equation 4), our model becomes invariant, which is analogous to a standard GNN where all relative squared norms between pairs of points are inputted to the edge operation (eq. 3). Additionally, since we are not provided with an adjacency matrix and molecules can scale up to 29 nodes, we use the extension of our model from Section 3.3 that infers a soft estimation of the edges. Our EGNN network consists of 7 layers, 128 features per hidden layer and the Swish activation function as a non-linearity. A sum-pooling operation preceded and followed by two layers MLPs maps all the node embeddings from the output of the EGNN to the estimated property value. Further implementation details are reported in Appendix. C. We compare to NMP (Gilmer et al. 2017), Schnet (Schütt et al. 2017b), Cormorant (Anderson et al. 2019), L1Net (Miller et al. 2020), LieConv (Finzi et al. 2020), DimeNet++ (Klicpera et al. 2020a), TFN (Thomas et al. 2018) and SE(3)-Tr. (Fuchs et al. 2020).
实现细节: EGNN 以每个原子的三维坐标位置作为方程 3 中的 ,以原子属性嵌入作为输入节点特征 。这是不变任务,且 位置静态,无需像前几项实验那样用方程 4 更新粒子位置 。我们两种都试过,更新 未见提升。不更新粒子位置(跳过方程 4)时,模型变为 不变,等价于标准 GNN 但把所有点对相对平方范数 送入边运算(方程 3)。此外,未提供邻接矩阵且分子可至 29 节点,我们使用第 3.3 节推断边的软估计扩展。EGNN 为 7 层、隐层 128 维、Swish 非线性。sum-pooling 前后各接两层 MLP,把 EGNN 输出的全部节点嵌入 映到估计性质值。更多细节见附录 C。对比 NMP(Gilmer et al. 2017)、Schnet(Schütt et al. 2017b)、Cormorant(Anderson et al. 2019)、L1Net(Miller et al. 2020)、LieConv(Finzi et al. 2020)、DimeNet++(Klicpera et al. 2020a)、TFN(Thomas et al. 2018)与 SE(3)-Tr.(Fuchs et al. 2020)。
Results are presented in Table 3. Our method reports very competitive results in all property prediction tasks while remaining relatively simple, i.e. not introducing higher order representations, angles or spherical harmonics. Perhaps, surprisingly, we outperform other equivariant networks that consider higher order representations while in this task, we are only using type-0 representations (i.e. relative distances) to define the geometry of the molecules. In Appendix E we prove that when only positional information is given (i.e. no velocity or higher order type features), then the geometry is completely defined by the norms in-between points up to -transformations, in other words, if two collections of points separated by transformations are considered to be identical, then the relative norms between points is a unique identifier of the collection.
结果 见表 3。本方法在各项性质预测上均报告极具竞争力的结果,同时相对简单:不引入高阶表示、角度或球谐。或许出人意料的是,我们优于其他考虑高阶表示的等变网络;而在本任务中,我们仅用 type-0 表示(即相对距离)定义分子几何。附录 E 证明:当只给定位置信息(无速度或更高阶类型特征)时,几何完全由点间范数在 变换意义下唯一确定——换言之,若两团点经 变换后视为同一,则点间相对范数是该团点的唯一标识。
6 Conclusions
6 结论
Equivariant graph neural networks are receiving increasing interest from the natural and medical sciences as they represent a new tool for analyzing molecules and their properties. In this work, we presented a new equivariant deep architecture for graphs that is computationally efficient, easy to implement, and significantly improves over the current state-of-the-art on a wide range of tasks. We believe these properties make it ideally suited to make a direct impact on topics such as drug discovery, protein folding and the design of new materials, as well as applications in 3D computer vision.
等变图神经网络正日益受到自然科学与医学关注,成为分析分子及其性质的新工具。本文提出一种新的图上 等变深度结构:计算高效、易于实现,并在广泛任务上显著改进当前前沿。我们相信这些性质使其特别适合直接影响药物发现、蛋白质折叠与新材料设计,以及三维计算机视觉等应用。
Acknowledgements
致谢
We would like to thank Patrick Forré for his support to formalize the invariance features identification proof.
感谢 Patrick Forré 协助形式化不变特征识别证明。
References
参考文献
Anderson et al. (2019) Anderson, B., Hy, T.-S., and Kondor, R. Cormorant: Covariant molecular neural networks. arXiv preprint arXiv:1906.04015 , 2019.
Bollobás & Béla (2001) Bollobás, B. and Béla, B. Random graphs . Number 73. Cambridge university press, 2001.
Bruna et al. (2013) Bruna, J., Zaremba, W., Szlam, A., and LeCun, Y. Spectral networks and locally connected networks on graphs. arXiv preprint arXiv:1312.6203 , 2013.
Candès & Recht (2009) Candès, E. J. and Recht, B. Exact matrix completion via convex optimization. Foundations of Computational mathematics , 9(6):717–772, 2009.
Chua et al. (2018) Chua, K., Calandra, R., McAllister, R., and Levine, S. Deep reinforcement learning in a handful of trials using probabilistic dynamics models. arXiv preprint arXiv:1805.12114 , 2018.
Cohen & Welling (2016) Cohen, T. and Welling, M. Group equivariant convolutional networks. In Balcan, M. and Weinberger, K. Q. (eds.), Proceedings of the 33nd International Conference on Machine Learning, ICML , 2016.
Cohen & Welling (2017) Cohen, T. S. and Welling, M. Steerable cnns. In 5th International Conference on Learning Representations, ICLR , 2017.
Defferrard et al. (2016) Defferrard, M., Bresson, X., and Vandergheynst, P. Convolutional neural networks on graphs with fast localized spectral filtering. In Advances in neural information processing systems , pp. 3844–3852, 2016.
Finzi et al. (2020) Finzi, M., Stanton, S., Izmailov, P., and Wilson, A. G. Generalizing convolutional neural networks for equivariance to lie groups on arbitrary continuous data. arXiv preprint arXiv:2002.12880 , 2020.
Fuchs et al. (2020) Fuchs, F., Worrall, D., Fischer, V., and Welling, M. Se (3)-transformers: 3d roto-translation equivariant attention networks. Advances in Neural Information Processing Systems , 33, 2020.
Gilmer et al. (2017) Gilmer, J., Schoenholz, S. S., Riley, P. F., Vinyals, O., and Dahl, G. E. Neural message passing for quantum chemistry. arXiv preprint arXiv:1704.01212 , 2017.
Grover et al. (2019) Grover, A., Zweig, A., and Ermon, S. Graphite: Iterative generative modeling of graphs. In International conference on machine learning , pp. 2434–2444. PMLR, 2019.
Grzeszczuk et al. (1998) Grzeszczuk, R., Terzopoulos, D., and Hinton, G. Neuroanimator: Fast neural network emulation and control of physics-based models. In Proceedings of the 25th annual conference on Computer graphics and interactive techniques , pp. 9–20, 1998.
Horie et al. (2020) Horie, M., Morita, N., Hishinuma, T., Ihara, Y., and Mitsume, N. Isometric transformation invariant and equivariant graph convolutional networks. arXiv preprint arXiv:2005.06316 , 2020.
Kipf et al. (2018) Kipf, T., Fetaya, E., Wang, K.-C., Welling, M., and Zemel, R. Neural relational inference for interacting systems. arXiv preprint arXiv:1802.04687 , 2018.
Kipf & Welling (2016a) Kipf, T. N. and Welling, M. Semi-supervised classification with graph convolutional networks. arXiv preprint arXiv:1609.02907 , 2016a.
Kipf & Welling (2016b) Kipf, T. N. and Welling, M. Variational graph auto-encoders. arXiv preprint arXiv:1611.07308 , 2016b.
Klicpera et al. (2020a) Klicpera, J., Giri, S., Margraf, J. T., and Günnemann, S. Fast and uncertainty-aware directional message passing for non-equilibrium molecules. arXiv preprint arXiv:2011.14115 , 2020a.
Klicpera et al. (2020b) Klicpera, J., Groß, J., and Günnemann, S. Directional message passing for molecular graphs. arXiv preprint arXiv:2003.03123 , 2020b.
Köhler et al. (2019) Köhler, J., Klein, L., and Noé, F. Equivariant flows: sampling configurations for multi-body systems with symmetric energies. CoRR , abs/1910.00753, 2019.
Köhler et al. (2020) Köhler, J., Klein, L., and Noé, F. Equivariant flows: exact likelihood generative learning for symmetric densities. arXiv preprint arXiv:2006.02425 , 2020.
Kondor et al. (2018) Kondor, R., Son, H. T., Pan, H., Anderson, B., and Trivedi, S. Covariant compositional networks for learning graphs. arXiv preprint arXiv:1801.02144 , 2018.
Liu et al. (2019) Liu, J., Kumar, A., Ba, J., Kiros, J., and Swersky, K. Graph normalizing flows. In Advances in Neural Information Processing Systems , pp. 13578–13588, 2019.
Miller et al. (2020) Miller, B. K., Geiger, M., Smidt, T. E., and Noé, F. Relevance of rotationally equivariant convolutions for predicting molecular properties. arXiv preprint arXiv:2008.08461 , 2020.
Nagabandi et al. (2018) Nagabandi, A., Kahn, G., Fearing, R. S., and Levine, S. Neural network dynamics for model-based deep reinforcement learning with model-free fine-tuning. In 2018 IEEE International Conference on Robotics and Automation (ICRA) , pp. 7559–7566. IEEE, 2018.
Ramachandran et al. (2017) Ramachandran, P., Zoph, B., and Le, Q. V. Searching for activation functions. arXiv preprint arXiv:1710.05941 , 2017.
Ramakrishnan et al. (2014) Ramakrishnan, R., Dral, P. O., Rupp, M., and Von Lilienfeld, O. A. Quantum chemistry structures and properties of 134 kilo molecules. Scientific data , 1(1):1–7, 2014.
Rezende et al. (2019) Rezende, D. J., Racanière, S., Higgins, I., and Toth, P. Equivariant hamiltonian flows. CoRR , abs/1909.13739, 2019.
Romero & Cordonnier (2021) Romero, D. W. and Cordonnier, J.-B. Group equivariant stand-alone self-attention for vision. In International Conference on Learning Representations , 2021. URL https://openreview.net/forum?id=JkfYjnOEo6M .
Schütt et al. (2017a) Schütt, K. T., Arbabzadah, F., Chmiela, S., Müller, K. R., and Tkatchenko, A. Quantum-chemical insights from deep tensor neural networks. Nature communications , 8(1):1–8, 2017a.
Schütt et al. (2017b) Schütt, K. T., Kindermans, P.-J., Sauceda, H. E., Chmiela, S., Tkatchenko, A., and Müller, K.-R. Schnet: A continuous-filter convolutional neural network for modeling quantum interactions. arXiv preprint arXiv:1706.08566 , 2017b.
Serviansky et al. (2020) Serviansky, H., Segol, N., Shlomi, J., Cranmer, K., Gross, E., Maron, H., and Lipman, Y. Set2graph: Learning graphs from sets. Advances in Neural Information Processing Systems , 33, 2020.
Simonovsky & Komodakis (2018) Simonovsky, M. and Komodakis, N. Graphvae: Towards generation of small graphs using variational autoencoders. In International Conference on Artificial Neural Networks , pp. 412–422. Springer, 2018.
Srinivasan & Ribeiro (2019) Srinivasan, B. and Ribeiro, B. On the equivalence between positional node embeddings and structural graph representations. arXiv preprint arXiv:1910.00452 , 2019.
Thomas et al. (2018) Thomas, N., Smidt, T., Kearnes, S., Yang, L., Li, L., Kohlhoff, K., and Riley, P. Tensor field networks: Rotation-and translation-equivariant neural networks for 3d point clouds. arXiv preprint arXiv:1802.08219 , 2018.
Uy et al. (2019) Uy, M. A., Pham, Q.-H., Hua, B.-S., Nguyen, T., and Yeung, S.-K. Revisiting point cloud classification: A new benchmark dataset and classification model on real-world data. In Proceedings of the IEEE International Conference on Computer Vision , pp. 1588–1597, 2019.
Watters et al. (2017) Watters, N., Zoran, D., Weber, T., Battaglia, P., Pascanu, R., and Tacchetti, A. Visual interaction networks: Learning a physics simulator from video. Advances in neural information processing systems , 30:4539–4547, 2017.
Weiler & Cesa (2019) Weiler, M. and Cesa, G. General e(2)-equivariant steerable cnns. In Wallach, H. M., Larochelle, H., Beygelzimer, A., d’Alché-Buc, F., Fox, E. B., and Garnett, R. (eds.), Advances in Neural Information Processing Systems 32: Annual Conference on Neural Information Processing Systems , 2019.
You et al. (2018) You, J., Ying, R., Ren, X., Hamilton, W. L., and Leskovec, J. Graphrnn: Generating realistic graphs with deep auto-regressive models. arXiv preprint arXiv:1802.08773 , 2018.
Appendix A Equivariance Proof
附录 A 等变证明
In this section we prove that our model is translation equivariant on for any translation vector and it is rotation and reflection equivariant on for any orthogonal matrix . More formally, we will prove the model satisfies:
本节证明:模型对任意平移向量 在 上平移等变,并对任意正交矩阵 在 上旋转与反射等变。形式地,将证明模型满足:
We will analyze how a translation and rotation of the input coordinates propagates through our model. We start assuming is invariant to transformations on , in other words, we do not encode any information about the absolute position or orientation of into . Then, the output of Equation 3 will be invariant too since the distance between two particles is invariant to translations , and it is invariant to rotations and reflections such that the edge operation becomes invariant:
我们分析输入坐标的平移与旋转如何在模型中传播。首先假定 对 上的 变换不变,即不把 的绝对位置或朝向信息编码进 。则方程 3 的输出 也不变:两粒子距离对平移不变 ,对旋转与反射也不变 ,从而使边运算不变:
The second equation of our model (eq. 4) that updates the coordinates is equivariant. Following, we prove its equivariance by showing that an transformation of the input leads to the same transformation of the output. Notice is already invariant as proven above. We want to show:
模型的第二个方程(方程 4)更新坐标 ,对 等变。下面通过「输入做 变换则输出做同一变换」证明其等变。注意如上所证 已不变。我们要证明:
Derivation.
推导。
Therefore, we have proven that rotating and translating results in the same rotation and translation on at the output of Equation 4.
因此已证明:旋转并平移 会在方程 4 的输出上导致 的同一旋转与平移。
Furthermore equations 5 and 6 only depend on and which as saw at the beginning of this proof, are invariant, therefore the output of Equation 6 will be invariant too. Thus concluding that a transformation on will result in the same transformation on while will remain invariant to it such that is satisfied.
此外,方程 5 与 6 只依赖 与 ;如本证明开头所述,二者对 不变,故方程 6 的输出 也不变。从而对 做变换 会在 上导致同一变换,而 对其不变,即满足 。
Appendix B Re-formulation for velocity type inputs
附录 B 速度型输入的重述
In this section we write down the EGNN transformation layer that can take in velocity input and output channels. We also prove it remains equivariant.
本节写出可接收速度输入与输出通道的 EGNN 变换层 ,并证明其仍对 等变。
B.1 Equivariance proof for velocity type inputs
B.1 速度型输入的等变证明
In this subsection we prove that the velocity types input formulation of our model is also equivariant on . More formally, for any translation vector and for any orthogonal matrix , the model should satisfy:
本小节证明模型的速度型输入表述对 亦 等变。形式地,对任意平移向量 与任意正交矩阵 ,模型应满足:
In Appendix A we already proved the equivariance of our EGNN (Section 3) when not including vector type inputs. In its velocity type inputs variant we only replaced its coordinate updates (eq. 4) by Equation 7 that includes velocity. Since this is the only modification we will only prove that Equation 7 re-written below is equivariant.
附录 A 已证明不含向量型输入时 EGNN(第 3 节)的等变。速度型变体只是把坐标更新(方程 4)换成含速度的方程 7。因这是唯一改动,我们只证明下面重写的方程 7 等变。
First, we prove the first line preserves equivariance, that is we want to show:
首先证明第一行保持等变,即要证明:
Derivation.
推导。
Finally, it is straightforward to show the second equation is also equivariant, that is we want to show
最后,第二式的等变亦直接:。
Derivation.
推导。
Concluding we showed that an transformation on the input set of points results in the same transformation on the output set of points such that is satisfied.
综上,对输入点集做 变换会在输出点集上导致同一变换,从而满足 。
Appendix C Implementation details
附录 C 实现细节
In this Appendix section we describe the implementation details of the experiments. First, we describe those parts of our model that are the same across all experiments. Our EGNN model from Section 3 contains the following three main learnable functions.
本附录描述各实验的实现细节。先说明所有实验中相同的模型部分。第 3 节的 EGNN 含下列三个主要可学习函数。
- • The edge function (eq. 3) is a two layers MLP with two Swish non-linearities: Input {LinearLayer() Swish() LinearLayer() Swish() } Output.
- • 边函数 (方程 3)为两层 MLP,带两个 Swish 非线性:Input {LinearLayer() Swish() LinearLayer() Swish() } Output。
- • The coordinate function (eq. 4) consists of a two layers MLP with one non-linearity: {LinearLayer() Swish() LinearLayer() } Output
- • 坐标函数 (方程 4)为两层 MLP,带一个非线性: {LinearLayer() Swish() LinearLayer() } Output。
- • The node function (eq. 6) consists of a two layers MLP with one non-linearity and a residual connection: [, ] {LinearLayer() Swish() LinearLayer() Addition() }
- • 节点函数 (方程 6)为两层 MLP,带一个非线性与残差连接:[, ] {LinearLayer() Swish() LinearLayer() Addition() } 。
These functions are used in our EGNN across all experiments. Notice the GNN (eq. 2) also contains and edge operation and a node operation and respectively. We use the same functions described above for both the GNN and the EGNN such that comparisons are as fair as possible.
这些函数在所有实验的 EGNN 中通用。注意 GNN(方程 2)也含边运算与节点运算 、。我们对 GNN 与 EGNN 使用上述同一套函数,以使对比尽可能公平。
C.1 Implementation details for Dynamical Systems
C.1 动力系统实验的实现细节
Dataset
数据集
In the dynamical systems experiment we used a modification of the Charged Particle’s N-body (N=5) system from (Kipf et al. 2018). Similarly to (Fuchs et al. 2020), we extended it from 2 to 3 dimensions customizing the original code from (https://github.com/ethanfetaya/NRI) and we removed the virtual boxes that bound the particle’s positions. The sampled dataset consists of 3.000 training trajectories, 2.000 for validation and 2.000 for testing. Each trajectory has a duration of 1.000 timesteps. To move away from the transient phase, we actually generated trajectories of 5.000 time steps and sliced them from timestep to timestep (1.000 time steps into the future) such that the initial conditions are more realistic than the Gaussian Noise initialization from which they are initialized.
动力系统实验使用对 Kipf et al. 2018 带电粒子 N 体(N=5)系统的修改。与 Fuchs et al. 2020 类似,我们基于原代码(https://github.com/ethanfetaya/NRI)从二维扩展到三维,并去掉限制粒子位置的虚拟盒子。采样数据含 3,000 条训练轨迹、2,000 验证、2,000 测试;每条时长 1,000 步。为离开瞬态,实际生成 5,000 步轨迹,再从第 3,000 步切到第 4,000 步(前瞻 1,000 步),使初始条件比高斯噪声初始化更接近现实。
In our second experiment, we sweep from 100 to 50.000 training samples, for this we just created a new training partition following the same procedure as before but now generating 50.000 trajectories instead. The validation and test partition remain the same from last experiment.
第二项实验从 100 扫到 50,000 训练样本:按相同流程新建训练划分,生成 50,000 条轨迹;验证与测试划分与上一实验相同。
Models
模型
All models are composed of 4 layers, the details for each model are the following.
所有模型均为 4 层,细节如下。
- • EGNN: For the EGNN we use its variation that considers vector type inputs from Section 3.2. This variation adds the function to the model which is composed of two linear layers with one non-linearity: Input {LinearLayer() Swish() LinearLayer() } Output. Functions , and that define our EGNN are the same than for all experiments and are described at the beginning of this Appendix C.
- • EGNN: 使用第 3.2 节考虑向量型输入的变体。该变体向模型加入函数 :两层线性层加一个非线性:Input {LinearLayer() Swish() LinearLayer() } Output。定义 EGNN 的 、、 与所有实验相同,见本附录 C 开头。
- • GNN: The GNN is also composed of 4 layers, its learnable functions edge operation and node operation from Equation 2 are exactly the same as and from our EGNN introduced in Appendix C. We chose the same functions for both models to ensure a fair comparison. In the GNN case, the initial position and velocity from the particles is passed through a linear layer and inputted into the GNN first layer . The particle’s charges are inputted as edge attributes . The output of the GNN is passed through a two layers MLP that maps it to the estimated position.
- • GNN: 亦为 4 层;方程 2 中可学习的边运算 与节点运算 与附录 C 引入的 EGNN 中 、 完全相同,以保证公平对比。GNN 情形下,粒子初始位置 与速度 经线性层后作为 GNN 第一层 ;电荷作为边属性 。GNN 输出 再经两层 MLP 映到估计位置。
- • Radial Field: The Radial Field algorithm is described in the Related Work 4, its only parameters are contained in its edge operation which in our case is a two layers MLP with two non linearities Input {LinearLayer() Swish() LinearLayer() Tanh } Output. Notice we introduced a Tanh at the end of the MLP which fixes some instability issues that were causing this model to diverge in the dynamical system experiment. We also augmented the Radial Field algorithm with the vector type inputs modifications introduced in Section 3.2. In addition to the norms between pairs of points, also takes as input the particle charges .
- • Radial Field: 算法见相关工作第 4 节;仅有参数在边运算 中,本文取两层 MLP 加两个非线性:Input {LinearLayer() Swish() LinearLayer() Tanh } Output。末尾 Tanh 用于修复动力系统实验中导致发散的不稳定。我们还按第 3.2 节为 Radial Field 加入向量型输入修改。除点对范数外, 也接收粒子电荷 。
- • Tensor Field Network: We used the Pytorch implementation from https://github.com/FabianFuchsML/se3-transformer-public. We swept over different hyper paramters, degree {2, 3, 4}, number of features {12, 24, 32, 64, 128}. We got the best performance in our dataset for degree 2 and number of features 32. We used the Relu activation layer instead of the Swish for this model since it provided better performance.
- • Tensor Field Network: 使用 https://github.com/FabianFuchsML/se3-transformer-public 的 Pytorch 实现。扫过 degree {2, 3, 4}、特征数 {12, 24, 32, 64, 128}。本数据上最佳为 degree 2、特征数 32。该模型用 Relu 而非 Swish,因表现更好。
- • SE(3) Transformers: For the SE(3)-Transformer we used code from https://github.com/FabianFuchsML/se3-transformer-public. Notice this implementation has only been validated in the QM9 dataset but it is the only available implementation of this model. We swept over different hyperparamters degree {1, 2, 3, 4}, number of features 16, 32, 64 and divergence {1, 2}, along with the learning rate. We obtained the best performance for degree 3, number of features 64 and divergence 1. As in Tensor Field Networks we obtained better results by using the Relu activation layer instead of the Swish.
- • SE(3) Transformers: 代码来自 https://github.com/FabianFuchsML/se3-transformer-public。注意该实现仅在 QM9 上验证过,但是该模型唯一可用实现。扫过 degree {1, 2, 3, 4}、特征数 {16, 32, 64}、divergence {1, 2} 以及学习率。最佳为 degree 3、特征数 64、divergence 1。与 TFN 一样,用 Relu 优于 Swish。
Other implementation details
其他实现细节
In Table 2 all models were trained for 10.000 epochs, batch size 100, Adam optimizer, the learning rate was fixed and independently chosen for each model. All models are 4 layers deep and the number of training samples was set to 3.000.
表 2 中所有模型训练 10,000 epoch,batch size 100,Adam,学习率固定且各模型独立选取。均为 4 层,训练样本数 3,000。
C.2 Implementation details for Graph Autoneoders
C.2 图自编码器的实现细节
Dataset
数据集
In this experiment we worked with Community Small (You et al. 2018) and Erdos&Renyi (Bollobás & Béla 2001) generated datasets.
本实验使用 Community Small(You et al. 2018)与 Erdos&Renyi(Bollobás & Béla 2001)生成数据。
- • Community Small: We used the original code from (You et al. 2018) (https://github.com/JiaxuanYou/graph-generation) to generate a Community Small dataset. We sampled 5.000 training graphs, 500 for validation and 500 for testing.
- • Community Small:使用 You et al. 2018 原代码(https://github.com/JiaxuanYou/graph-generation)生成,采样 5,000 训练、500 验证、500 测试。
- • Erdos&Renyi is one of the most famous graph generative algorithms. We used the ”gnp_random_graph(, )” function from (https://networkx.org/) that generates random graphs when povided with the number of nodes and the edge probability following the Erdos&Renyi model. Again we generated 5.000 graphs for training, 500 for validation and 500 for testing. We set the edge probability (or sparsity value) to and the number of nodes ranging from 7 to 16 deterministically uniformly distributed. Notice that edges are generated stochastically with probability , therefore, there is a chance that some nodes are left disconnected from the graph, ”gnp_random_graph(, )” function discards these disconnected nodes such that even if we generate graphs setting parameters to and the generated graphs may have less number of nodes.
- • Erdos&Renyi 是最著名的图生成算法之一。我们使用 networkx 的
gnp_random_graph($M$, $p$)(https://networkx.org/),在给定节点数 与边概率 时按 Erdos&Renyi 模型生成随机图。同样生成 5,000 训练、500 验证、500 测试。边概率(或稀疏度)设为 ,节点数 在 7 到 16 均匀分布。注意边以概率 随机生成,因此部分节点可能与图断开;gnp_random_graph会丢弃断开节点,故即便参数设为 、,生成图的节点数也可能更少。
Finally, in the graph autoencoding experiment we also overfitted in a small partition of 100 samples (Figure 4) for the Erdos&Renyi graphs described above. We reported results for different values ranging from to . For each value we generated a partition of 100 graphs with initial number of nodes between using the Erdos&Renyi generative model.
最后,图自编码实验还在上述 Erdos&Renyi 图的 100 样本小划分上过拟合(图 4),并报告 从 到 的结果。对每个 用 Erdos&Renyi 生成 100 张图,初始节点数 。
Models
模型
All models consist of 4 layers, 64 features for the hidden layers and the Swish activation function as a non linearity. The EGNN is defined as explained in Section 3 without any additional modules (i.e. no velocity type features or inferring edges). The functions , and are defined at the beginning of this Appendix C. The GNN (eq. 2) mimics the EGNN in terms that it uses the same and than the EGNN for its edge and node updates. The Noise-GNN is exactly the same as the GNN but inputting noise into the features. Finally the Radial Field was defined in the Related Related work Section 4 which edge’s operation consists of a two layers MLP: Input { Linear() Swish() Linear() } Output.
所有模型为 4 层、隐层 64 维、Swish 非线性。EGNN 按第 3 节定义,无额外模块(无速度型特征、不推断边)。、、 见本附录 C 开头。GNN(方程 2)在边与节点更新上使用与 EGNN 相同的 、。Noise-GNN 与 GNN 完全相同,只是向 特征输入噪声。Radial Field 见相关工作第 4 节,其边运算 为两层 MLP:Input { Linear() Swish() Linear() } Output。
Other implementation details
其他实现细节
All experiments have been trained with learning rate , batch size 1, Adam optimizer, weight decay , 100 training epochs for the 5.000 samples sized datasets performing early stopping for the minimum Binary Cross Entropy loss in the validation partition. The overfitting experiments were trained for 10.000 epochs on the 100 samples subsets.
所有实验学习率 、batch size 1、Adam、weight decay ;5,000 样本规模数据集训练 100 epoch,按验证集二元交叉熵最小做早停。过拟合实验在 100 样本子集上训练 10,000 epoch。
C.3 Implementation details for QM9
C.3 QM9 的实现细节
For QM9 (Ramakrishnan et al. 2014) we used the dataset partitions from (Anderson et al. 2019). We imported the dataloader from his code repository (https://github.com/risilab/cormorant) which includes his data-preprocessing. Additionally all properties have been normalized by substracting the mean and dividing by the Mean Absolute Deviation.
QM9(Ramakrishnan et al. 2014)采用 Anderson et al. 2019 的数据划分,从其代码仓库(https://github.com/risilab/cormorant)导入 dataloader(含其数据预处理)。此外,所有性质均减去均值并除以平均绝对偏差做归一化。
Our EGNN consists of 7 layers. Functions and are defined at the beginning of this Appendix C. Additionally, we use the module presented in Section 3.3 that infers the edges . This function is defined as a linear layer followed by a sigmoid: Input {Linear() sigmoid()} Output. Finally, the output of our EGNN is forwarded through a two layers MLP that acts node-wise, a sum pooling operation and another two layers MLP that maps the averaged embedding to the predicted property value, more formally: {Linear() Swish() Linear() Sum-Pooling() Linear() Swish() Linear} Property. The number of hidden features for all model hidden layers is 128.
EGNN 为 7 层。、 见本附录 C 开头。另用第 3.3 节的 推断边:线性层加 sigmoid:Input {Linear() sigmoid()} Output。EGNN 输出 再经两层按节点作用的 MLP、sum pooling,以及另一两层 MLP 映到预测性质值,形式为: {Linear() Swish() Linear() Sum-Pooling() Linear() Swish() Linear} Property。所有隐层特征维为 128。
We trained each property individually for a total of 1.000 epochs, we used Adam optimizer, batch size 96, weight decay , and cosine decay for the learning rate starting at at a lr= except for the Homo, Lumo and Gap properties where its initial value was set to .
每个性质单独训练共 1,000 epoch;Adam、batch size 96、weight decay ;学习率余弦衰减,起始 lr=,但 Homo、Lumo 与 Gap 起始为 。
Appendix D Further experiments
附录 D 进一步实验
D.1 Graph Autoencoder
D.1 图自编码器
In this section we present an extension of the Graph Autoencoder experiment 5.2. In Table 4 we report the approximation error of the reconstructed graphs as the embedding dimensionality is reduced in the Community Small and Erdos&Renyi datasets for the GNN, Noise-GNN and EGNN models. For small embedding sizes () all methods perform poorly, but as the embedding size grows our EGNN significantly outperforms the others.
本节扩展图自编码器实验 5.2。表 4 报告在 Community Small 与 Erdos&Renyi 上,嵌入维 时 GNN、Noise-GNN 与 EGNN 的重建近似误差。小嵌入维()时各方法都较差;随着嵌入维增大,EGNN 显著优于其他方法。
| Community Small | Erdos&Renyi | |||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| n=4 | n=6 | n=8 | n=4 | n=6 | n=8 | |||||||
| % Err. | F1 | % Err. | F1 | % Err. | F1 | % Err. | F1 | % Err. | F1 | % Err. | F1 | |
| GNN | 1.45 | 0.977 | 1.29 | 0.9800 | 1.29 | 0.980 | 7.92 | 0.844 | 5.22 | 0.894 | 4.62 | 0.907 |
| Noise-GNN | 1.94 | 0.970 | 0.44 | 0.9931 | 0.44 | 0.993 | 3.80 | 0.925 | 2.66 | 0.947 | 1.25 | 0.975 |
| EGNN | 2.19 | 0.966 | 0.42 | 0.9934 | 0.06 | 0.999 | 3.09 | 0.939 | 0.58 | 0.988 | 0.11 | 0.998 |
Table 4: Analysis of the % of wrong edges and F1 score for different embedding sizes {2, 4, 8 } for the GNN, Noise-GNN and EGNN in Community Small and Erdos&Renyi datasets.
| Community Small | Erdos&Renyi | |||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| n=4 | n=6 | n=8 | n=4 | n=6 | n=8 | |||||||
| % Err. | F1 | % Err. | F1 | % Err. | F1 | % Err. | F1 | % Err. | F1 | % Err. | F1 | |
| GNN | 1.45 | 0.977 | 1.29 | 0.9800 | 1.29 | 0.980 | 7.92 | 0.844 | 5.22 | 0.894 | 4.62 | 0.907 |
| Noise-GNN | 1.94 | 0.970 | 0.44 | 0.9931 | 0.44 | 0.993 | 3.80 | 0.925 | 2.66 | 0.947 | 1.25 | 0.975 |
| EGNN | 2.19 | 0.966 | 0.42 | 0.9934 | 0.06 | 0.999 | 3.09 | 0.939 | 0.58 | 0.988 | 0.11 | 0.998 |
表 4:Community Small 与 Erdos&Renyi 上,GNN、Noise-GNN 与 EGNN 在不同嵌入维 的错误边百分比与 F1。
Appendix E Sometimes invariant features are all you need.
附录 E 有时不变特征就够了
Perhaps surprisingly we find our EGNNs outperform other equivariant networks that consider higher-order representations. In this section we prove that when only positional information is given (i.e. no velocity-type features) then the geometry is completely defined by the invariant distance norms in-between points, without loss of relevant information. As a consequence, it is not necessary to consider higher-order representation types of the relative distances, not even the relative differences as vectors. To be precise, note that these invariant features still need to be permutation equivariant, they are only invariant.
或许出人意料,我们发现 EGNN 优于其他考虑高阶表示的等变网络。本节证明:当只给定位置信息(无速度型特征)时,几何完全由点间不变距离范数定义,不损失相关信息。因此不必考虑相对距离的高阶表示类型,甚至不必把相对差当作向量。精确地说,这些不变特征仍需对置换等变,它们只对 不变。
To be specific, we want to show that for a collection of points the norm of in-between distances are a unique identifier of the geometry, where collections separated by an transformations are considered to be identical. We want to show invariance of the norms under transformations and uniqueness: two point collections are identical (up to transform) when they have the same distance norms.
具体地,我们要证明:对点集 ,点间距离范数 是几何的唯一标识——经 变换分离的集合视为相同。我们要证明范数在 下的不变性,以及唯一性:两团点在具有相同距离范数时(至多差一个 变换)相同。
Invariance. Let be a collection of points where and the distances are . We want to show that all are unaffected by transformations.
不变性。 设 为 个点,, 距离为 。要证明所有 不受 变换影响。
Proof. Consider an arbitrary transformation where is orthogonal and is a translation. Then for all :
证明。 考虑任意 变换 ,其中 正交, 为平移。则对所有 :
This proves that the distances are invariant under transforms.
这就证明 距离在 变换下不变。
Uniqueness. Let and be two collection of points each where all in-between distance norms are identical, meaning . We want to show that for some orthogonal and translation , for all .
唯一性。 设 与 各为 个点的集合,且所有点间距离范数相同,即 。要证明存在正交 与平移 ,使对所有 有 。
Proof. Subtract from all and from all , so and . As proven above, since translation is an transformation the distance norms are unaffected and:
证明。 从所有 减去 ,从所有 减去 ,得 ,。如上所证,平移是 变换,距离范数不受影响,且:
So without loss of generality, we may assume that . As a direct consequence . Now writing out the square:
因此不妨假定 。直接推论 。展开平方:
And since , it follows that or equivalently written as dot product . Notice that this already shows that angles between pairs of points are the same.
又因 ,可得 ,或写成内积 。注意这已说明点对之间的角度相同。
At this moment, it might already be intuïtive that the collections of points are indeed identical. To finalize the proof formally we will construct a linear map for which we will show that (1) it maps every to and (2) that it is orthogonal. First note that from the angle equality it follows immediately that for every linear combination:
至此或许已可直观感到两团点确实相同。为正式完成证明,我们构造线性映射 ,并证明 (1) 它把每个 映到 ,(2) 它正交。首先由角度相等立即得到:对任意线性组合:
Let be the linear span of (so is the linear subspace of all linear combinations of ). Let be a basis of , where . Recall that one can define a linear map by choosing a basis, and then define for each basis vector where it maps to. Define a linear map from to by the transformation from the basis to for . Now pick any point and write it in its basis . We want to show or alternatively . Note that . Then:
设 为 的线性张成(即 一切线性组合构成的线性子空间)。设 为 的一组基,。回忆:可通过选定基并为每个基向量指定像来定义线性映射。定义从 到 的线性映射 ,把基 映到 ,。任取一点 ,在基下写成 。要证明 ,或等价地 。注意 。于是:
Thus showing that for all , proving (1). Finally we want to show that is orthogonal, when restricted to . This follows since:
从而对所有 有 ,证明了 (1)。最后要证明限制在 上时 正交。这由下式得出:
for the basis elements . This implies that is orthogonal (at least when restricted to ). Finally can be extended via an orthogonal complement of to the whole space. This concludes the proof for (2) and shows that is indeed orthogonal.
对基元 成立。这意味着(至少限制在 上) 正交。最后可通过 的正交补把 扩展到全空间。这就完成了 (2) 的证明,并表明 确实正交。