End-to-End Object Detection with Transformers
End-to-End Object Detection with Transformers
Nicolas Carion Thanks: Equal contribution Affiliation: Facebook AI Francisco Massa * Gabriel Synnaeve Nicolas Usunier Alexander Kirillov Sergey Zagoruyko
Abstract
We present a new method that views object detection as a direct set prediction problem. Our approach streamlines the detection pipeline, effectively removing the need for many hand-designed components like a non-maximum suppression procedure or anchor generation that explicitly encode our prior knowledge about the task. The main ingredients of the new framework, called DEtection TRansformer or DETR, are a set-based global loss that forces unique predictions via bipartite matching, and a transformer encoder-decoder architecture. Given a fixed small set of learned object queries, DETR reasons about the relations of the objects and the global image context to directly output the final set of predictions in parallel. The new model is conceptually simple and does not require a specialized library, unlike many other modern detectors. DETR demonstrates accuracy and run-time performance on par with the well-established and highly-optimized Faster R-CNN baseline on the challenging COCO object detection dataset. Moreover, DETR can be easily generalized to produce panoptic segmentation in a unified manner. We show that it significantly outperforms competitive baselines. Training code and pretrained models are available at https://github.com/facebookresearch/detr.
我们提出一种把目标检测视为直接集合预测问题的新方法。该方法精简检测流水线,有效去掉许多显式编码任务先验的手工组件,例如非极大值抑制与锚框生成。新框架称为 DEtection TRansformer(DETR),其核心要素是:通过二分图匹配迫使预测唯一的集合式全局损失,以及 Transformer 编码器–解码器架构。给定一组固定、少量的可学习 object query,DETR 对物体之间关系与全局图像上下文进行推理,并行直接输出最终预测集合。新模型概念上简单,也不需要专用库,这与许多现代检测器不同。在具有挑战性的 COCO 目标检测数据集上,DETR 的精度与运行时表现可与高度优化、久经验证的 Faster R-CNN 基线相媲美。此外,DETR 能以统一方式轻松推广到全景分割,并显著超过有竞争力的基线。训练代码与预训练模型见 https://github.com/facebookresearch/detr 。
1 Introduction
The goal of object detection is to predict a set of bounding boxes and category labels for each object of interest. Modern detectors address this set prediction task in an indirect way, by defining surrogate regression and classification problems on a large set of proposals [37, 5], anchors [23], or window centers [53, 46]. Their performances are significantly influenced by postprocessing steps to collapse near-duplicate predictions, by the design of the anchor sets and by the heuristics that assign target boxes to anchors [52]. To simplify these pipelines, we propose a direct set prediction approach to bypass the surrogate tasks. This end-to-end philosophy has led to significant advances in complex structured prediction tasks such as machine translation or speech recognition, but not yet in object detection: previous attempts [43, 16, 4, 39] either add other forms of prior knowledge, or have not proven to be competitive with strong baselines on challenging benchmarks. This paper aims to bridge this gap.
目标检测的目标是为每个感兴趣物体预测一组边界框与类别标签。现代检测器以间接方式处理这一集合预测任务:在大量 proposal [37, 5]、锚框 [23] 或窗口中心 [53, 46] 上定义代理回归与分类问题。其表现显著受后处理(合并近重复预测)、锚框集合设计,以及把目标框赋给锚框的启发式规则 [52] 影响。为简化这些流水线,我们提出直接集合预测方法以绕过代理任务。这种端到端思路已在机器翻译、语音识别等复杂结构化预测中带来显著进展,但在目标检测中尚未如此:既往尝试 [43, 16, 4, 39] 要么加入其他形式的先验,要么尚未在挑战性基准上证明能与强基线竞争。本文旨在弥合这一差距。
We streamline the training pipeline by viewing object detection as a direct set prediction problem. We adopt an encoder-decoder architecture based on transformers [47], a popular architecture for sequence prediction. The self-attention mechanisms of transformers, which explicitly model all pairwise interactions between elements in a sequence, make these architectures particularly suitable for specific constraints of set prediction such as removing duplicate predictions.
我们把目标检测视为直接集合预测问题,从而精简训练流水线。采用基于 Transformer [47] 的编码器–解码器架构——一种流行的序列预测架构。Transformer 的自注意力显式建模序列中所有元素两两交互,因此特别适合集合预测的特定约束,例如去除重复预测。
Our DEtection TRansformer (DETR, see Figure 1) predicts all objects at once, and is trained end-to-end with a set loss function which performs bipartite matching between predicted and ground-truth objects. DETR simplifies the detection pipeline by dropping multiple hand-designed components that encode prior knowledge, like spatial anchors or non-maximal suppression. Unlike most existing detection methods, DETR doesn’t require any customized layers, and thus can be reproduced easily in any framework that contains standard CNN and transformer classes.[^1].
我们的 DEtection TRansformer(DETR,见图 1)一次性预测所有物体,并用在预测与真值物体之间做二分图匹配的集合损失端到端训练。DETR 通过去掉空间锚框、非极大值抑制等编码先验知识的手工组件来简化检测流水线。与多数现有检测方法不同,DETR 不需要任何定制层,因此可在任何包含标准 CNN 与 Transformer 类的框架中轻易复现。[^1]
Compared to most previous work on direct set prediction, the main features of DETR are the conjunction of the bipartite matching loss and transformers with (non-autoregressive) parallel decoding [29, 12, 10, 8]. In contrast, previous work focused on autoregressive decoding with RNNs [43, 41, 30, 36, 42]. Our matching loss function uniquely assigns a prediction to a ground truth object, and is invariant to a permutation of predicted objects, so we can emit them in parallel.
相对多数先前的直接集合预测工作,DETR 的主要特点是二分图匹配损失与带(非自回归)并行解码的 Transformer 的结合 [29, 12, 10, 8]。相比之下,先前工作聚焦于用 RNN 做自回归解码 [43, 41, 30, 36, 42]。我们的匹配损失把每个预测唯一赋给一个真值物体,并对预测排列不变,因此可并行发出预测。
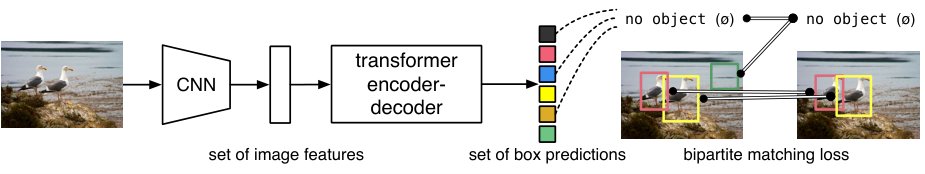
Figure 1: DETR directly predicts (in parallel) the final set of detections by combining a common CNN with a transformer architecture. During training, bipartite matching uniquely assigns predictions with ground truth boxes. Prediction with no match should yield a “no object” () class prediction.
图 1:DETR 通过把常见 CNN 与 Transformer 架构结合,直接(并行)预测最终检测集合。训练时,二分图匹配把预测唯一赋给真值框。无匹配的预测应输出“无物体”()类别。
We evaluate DETR on one of the most popular object detection datasets, COCO [24], against a very competitive Faster R-CNN baseline [37]. Faster R-CNN has undergone many design iterations and its performance was greatly improved since the original publication. Our experiments show that our new model achieves comparable performances. More precisely, DETR demonstrates significantly better performance on large objects, a result likely enabled by the non-local computations of the transformer. It obtains, however, lower performances on small objects. We expect that future work will improve this aspect in the same way the development of FPN [22] did for Faster R-CNN.
我们在最流行的目标检测数据集之一 COCO [24] 上,对照极具竞争力的 Faster R-CNN 基线 [37] 评估 DETR。Faster R-CNN 经历过多次设计迭代,相对原始论文表现已大幅提升。实验表明我们的新模型达到可比表现。更具体地,DETR 在大物体上显著更好——这很可能得益于 Transformer 的非局部计算;但在小物体上表现较低。我们预期未来工作会像 FPN [22] 对 Faster R-CNN 那样改进这一方面。
Training settings for DETR differ from standard object detectors in multiple ways. The new model requires extra-long training schedule and benefits from auxiliary decoding losses in the transformer. We thoroughly explore what components are crucial for the demonstrated performance.
DETR 的训练设定在多方面不同于标准目标检测器。新模型需要特别长的训练日程,并受益于 Transformer 中的辅助解码损失。我们系统探索哪些组件对所示表现至关重要。
The design ethos of DETR easily extend to more complex tasks. In our experiments, we show that a simple segmentation head trained on top of a pre-trained DETR outperfoms competitive baselines on Panoptic Segmentation [19], a challenging pixel-level recognition task that has recently gained popularity.
DETR 的设计理念易于扩展到更复杂任务。实验中我们表明:在预训练 DETR 之上训练一个简单的分割头,即可在近来流行的像素级识别任务——全景分割 [19] 上超过有竞争力的基线。
2 Related work
Our work build on prior work in several domains: bipartite matching losses for set prediction, encoder-decoder architectures based on the transformer, parallel decoding, and object detection methods.
本工作建立在若干领域的先前工作之上:用于集合预测的二分图匹配损失、基于 Transformer 的编码器–解码器架构、并行解码,以及目标检测方法。
2.1 Set Prediction
There is no canonical deep learning model to directly predict sets. The basic set prediction task is multilabel classification (see e.g., [40, 33] for references in the context of computer vision) for which the baseline approach, one-vs-rest, does not apply to problems such as detection where there is an underlying structure between elements (i.e., near-identical boxes). The first difficulty in these tasks is to avoid near-duplicates. Most current detectors use postprocessings such as non-maximal suppression to address this issue, but direct set prediction are postprocessing-free. They need global inference schemes that model interactions between all predicted elements to avoid redundancy. For constant-size set prediction, dense fully connected networks [9] are sufficient but costly. A general approach is to use auto-regressive sequence models such as recurrent neural networks [48]. In all cases, the loss function should be invariant by a permutation of the predictions. The usual solution is to design a loss based on the Hungarian algorithm [20], to find a bipartite matching between ground-truth and prediction. This enforces permutation-invariance, and guarantees that each target element has a unique match. We follow the bipartite matching loss approach. In contrast to most prior work however, we step away from autoregressive models and use transformers with parallel decoding, which we describe below.
目前没有标准的深度学习模型可直接预测集合。最基础的集合预测任务是多标签分类(计算机视觉语境见如 [40, 33]),其基线方法 one-vs-rest 不适用于检测这类元素之间存在底层结构(即近乎相同的框)的问题。这些任务的第一难点是避免近重复。多数当前检测器用非极大值抑制等后处理应对,但直接集合预测是无后处理的。它们需要能建模所有预测元素交互的全局推理方案以避免冗余。对固定大小集合预测,稠密全连接网络 [9] 足够但代价高。一般做法是使用自回归序列模型如 RNN [48]。无论何种情况,损失函数应对预测排列不变。常见解法是基于匈牙利算法 [20] 设计损失,在真值与预测之间找二分图匹配。这强制排列不变,并保证每个目标元素有唯一匹配。我们遵循二分图匹配损失路线。但与多数先前工作不同,我们离开自回归模型,改用并行解码的 Transformer,如下所述。
2.2 Transformers and Parallel Decoding
Transformers were introduced by Vaswani et al. [47] as a new attention-based building block for machine translation. Attention mechanisms [2] are neural network layers that aggregate information from the entire input sequence. Transformers introduced self-attention layers, which, similarly to Non-Local Neural Networks [49], scan through each element of a sequence and update it by aggregating information from the whole sequence. One of the main advantages of attention-based models is their global computations and perfect memory, which makes them more suitable than RNNs on long sequences. Transformers are now replacing RNNs in many problems in natural language processing, speech processing and computer vision [8, 27, 45, 34, 31].
Transformer 由 Vaswani et al. [47] 作为机器翻译的新注意力构建块提出。注意力机制 [2] 是从整个输入序列聚合信息的神经网络层。Transformer 引入自注意力层:与 Non-Local Neural Networks [49] 类似,它扫描序列每个元素,并通过聚合整段序列信息来更新该元素。基于注意力模型的主要优势之一是全局计算与完美记忆,使其在长序列上比 RNN 更合适。Transformer 正取代 RNN,出现在自然语言处理、语音处理与计算机视觉的许多问题中 [8, 27, 45, 34, 31]。
Transformers were first used in auto-regressive models, following early sequence-to-sequence models [44], generating output tokens one by one. However, the prohibitive inference cost (proportional to output length, and hard to batch) lead to the development of parallel sequence generation, in the domains of audio [29], machine translation [12, 10], word representation learning [8], and more recently speech recognition [6]. We also combine transformers and parallel decoding for their suitable trade-off between computational cost and the ability to perform the global computations required for set prediction.
Transformer 起初用于自回归模型,跟随早期序列到序列模型 [44],逐个生成输出 token。但推理代价过高(与输出长度成正比,且难以批处理)推动了并行序列生成的发展,涵盖音频 [29]、机器翻译 [12, 10]、词表征学习 [8],以及近来的语音识别 [6]。我们也把 Transformer 与并行解码结合,以在计算代价与集合预测所需全局计算能力之间取得合适折中。
2.3 Object detection
Most modern object detection methods make predictions relative to some initial guesses. Two-stage detectors [37, 5] predict boxes w.r.t. proposals, whereas single-stage methods make predictions w.r.t. anchors [23] or a grid of possible object centers [53, 46]. Recent work [52] demonstrate that the final performance of these systems heavily depends on the exact way these initial guesses are set. In our model we are able to remove this hand-crafted process and streamline the detection process by directly predicting the set of detections with absolute box prediction w.r.t. the input image rather than an anchor.
多数现代目标检测方法相对某些初始猜测做预测。两阶段检测器 [37, 5] 相对 proposal 预测框,而单阶段方法相对锚框 [23] 或可能的物体中心网格 [53, 46] 做预测。近期工作 [52] 表明这些系统的最终表现严重依赖初始猜测的精确设定方式。在我们的模型中,我们能够去掉这一手工过程,通过对输入图像做绝对框预测、直接预测检测集合,从而精简检测流程,而非相对锚框。
Set-based loss.
Several object detectors [9, 25, 35] used the bipartite matching loss. However, in these early deep learning models, the relation between different prediction was modeled with convolutional or fully-connected layers only and a hand-designed NMS post-processing can improve their performance. More recent detectors [37, 23, 53] use non-unique assignment rules between ground truth and predictions together with an NMS.
Set-based loss.
若干目标检测器 [9, 25, 35] 使用过二分图匹配损失。但在这些早期深度学习模型中,不同预测之间的关系仅由卷积或全连接层建模,手工设计的 NMS 后处理仍可提升表现。更新近的检测器 [37, 23, 53] 在真值与预测之间使用非唯一赋值规则,并配合 NMS。
Learnable NMS methods [16, 4] and relation networks [17] explicitly model relations between different predictions with attention. Using direct set losses, they do not require any post-processing steps. However, these methods employ additional hand-crafted context features like proposal box coordinates to model relations between detections efficiently, while we look for solutions that reduce the prior knowledge encoded in the model.
可学习 NMS 方法 [16, 4] 与关系网络 [17] 用注意力显式建模不同预测之间的关系。使用直接集合损失时,它们不需要任何后处理步骤。但这些方法还依赖 proposal 框坐标等额外手工上下文特征来高效建模检测之间关系,而我们寻找减少模型中编码先验知识的方案。
Recurrent detectors.
Closest to our approach are end-to-end set predictions for object detection [43] and instance segmentation [41, 30, 36, 42]. Similarly to us, they use bipartite-matching losses with encoder-decoder architectures based on CNN activations to directly produce a set of bounding boxes. These approaches, however, were only evaluated on small datasets and not against modern baselines. In particular, they are based on autoregressive models (more precisely RNNs), so they do not leverage the recent transformers with parallel decoding.
Recurrent detectors.
与我们最接近的是目标检测 [43] 与实例分割 [41, 30, 36, 42] 的端到端集合预测。与我们类似,它们用基于 CNN 激活的编码器–解码器架构配合二分图匹配损失,直接产生边界框集合。但这些方法只在小数据集上评估,且未与现代基线对照。尤其是它们基于自回归模型(更精确地说是 RNN),因而未利用近来带并行解码的 Transformer。
3 The DETR model
Two ingredients are essential for direct set predictions in detection: (1) a set prediction loss that forces unique matching between predicted and ground truth boxes; (2) an architecture that predicts (in a single pass) a set of objects and models their relation. We describe our architecture in detail in Figure 2.
检测中的直接集合预测有两个要素至关重要:(1) 迫使预测框与真值框唯一匹配的集合预测损失;(2) 能(单次前向)预测物体集合并建模其关系的架构。我们在图 2 中详细描述架构。
3.1 Object detection set prediction loss
DETR infers a fixed-size set of predictions, in a single pass through the decoder, where is set to be significantly larger than the typical number of objects in an image. One of the main difficulties of training is to score predicted objects (class, position, size) with respect to the ground truth. Our loss produces an optimal bipartite matching between predicted and ground truth objects, and then optimize object-specific (bounding box) losses.
DETR 经解码器单次前向推断固定大小为 的预测集合,其中 设为显著大于图像中典型物体数。训练的主要难点之一是相对真值对预测物体(类别、位置、尺寸)打分。我们的损失在预测与真值物体之间产生最优二分图匹配,再优化物体特定的(边界框)损失。
Let us denote by the ground truth set of objects, and the set of predictions. Assuming is larger than the number of objects in the image, we consider also as a set of size padded with (no object). To find a bipartite matching between these two sets we search for a permutation of elements with the lowest cost:
记 为真值物体集合, 为 个预测的集合。假定 大于图像中物体数,我们也把 视为大小为 、用 (无物体)填充的集合。为在这两个集合之间找二分图匹配,我们搜索代价最低的 元排列 :
where is a pair-wise matching cost between ground truth and a prediction with index . This optimal assignment is computed efficiently with the Hungarian algorithm, following prior work (e.g. [43]).
其中 是真值 与下标 的预测之间的成对匹配代价。该最优赋值用匈牙利算法高效计算,遵循先前工作(e.g. [43])。
The matching cost takes into account both the class prediction and the similarity of predicted and ground truth boxes. Each element of the ground truth set can be seen as a where is the target class label (which may be ) and is a vector that defines ground truth box center coordinates and its height and width relative to the image size. For the prediction with index we define probability of class as and the predicted box as . With these notations we define as .
匹配代价同时考虑类别预测,以及预测框与真值框的相似性。真值集合中每个元素 可看作 ,其中 是目标类别标签(可能为 ), 是定义真值框中心坐标及其相对图像尺寸的高与宽的向量。对下标 的预测,我们定义类别 的概率为 ,预测框为 。在此记号下,把 定义为 。
This procedure of finding matching plays the same role as the heuristic assignment rules used to match proposal [37] or anchors [22] to ground truth objects in modern detectors. The main difference is that we need to find one-to-one matching for direct set prediction without duplicates.
这一找匹配的过程扮演与现代检测器中把 proposal [37] 或锚框 [22] 匹配到真值物体的启发式赋值规则相同的角色。主要差别是:对无重复的直接集合预测,我们需要找到一对一匹配。
The second step is to compute the loss function, the Hungarian loss for all pairs matched in the previous step. We define the loss similarly to the losses of common object detectors, i.e. a linear combination of a negative log-likelihood for class prediction and a box loss defined later:
第二步是计算损失函数,即对上一步所有匹配对的 Hungarian loss。我们把损失定义得与常见目标检测器类似,即 类别预测负对数似然与后文定义的框损失的线性组合:
where is the optimal assignment computed in the first step (1). In practice, we down-weight the log-probability term when by a factor to account for class imbalance. This is analogous to how Faster R-CNN training procedure balances positive/negative proposals by subsampling [37]. Notice that the matching cost between an object and doesn’t depend on the prediction, which means that in that case the cost is a constant. In the matching cost we use probabilities instead of log-probabilities. This makes the class prediction term commensurable to (described below), and we observed better empirical performances.
其中 是第一步 (1) 算出的最优赋值。实践中,当 时我们把对数概率项降权 10 倍以应对类别不平衡。这类似于 Faster R-CNN 训练通过子采样平衡正/负 proposal 的做法 [37]。注意物体与 之间的匹配代价不依赖预测,亦即该情形下代价为常数。在匹配代价中我们使用概率 而非对数概率。这使类别预测项与 (下文描述)可通约,并且我们观察到更好的经验表现。
Bounding box loss.
The second part of the matching cost and the Hungarian loss is that scores the bounding boxes. Unlike many detectors that do box predictions as a w.r.t. some initial guesses, we make box predictions directly. While such approach simplify the implementation it poses an issue with relative scaling of the loss. The most commonly-used loss will have different scales for small and large boxes even if their relative errors are similar. To mitigate this issue we use a linear combination of the loss and the generalized IoU loss [38] that is scale-invariant. Overall, our box loss is defined as where are hyperparameters. These two losses are normalized by the number of objects inside the batch.
Bounding box loss.
匹配代价与 Hungarian loss 的第二部分是对边界框打分的 。与许多把框预测为相对某些初始猜测的 的检测器不同,我们直接做框预测。这一做法简化实现,但带来损失相对缩放的问题。最常用的 损失即便相对误差相近,对小框与大框也会有不同尺度。为缓解该问题,我们使用 损失与尺度不变的广义 IoU 损失 [38] 的线性组合。总体而言,我们的框损失 定义为 ,其中 为超参。这两项损失按 batch 内物体数归一化。
3.2 DETR architecture
The overall DETR architecture is surprisingly simple and depicted in Figure 2. It contains three main components, which we describe below: a CNN backbone to extract a compact feature representation, an encoder-decoder transformer, and a simple feed forward network (FFN) that makes the final detection prediction.
整体 DETR 架构出人意料地简单,如图 2 所示。它包含三个主要组件(下文描述):提取紧凑特征表示的 CNN 骨干、编码器–解码器 Transformer,以及做出最终检测预测的简单前馈网络(FFN)。
Unlike many modern detectors, DETR can be implemented in any deep learning framework that provides a common CNN backbone and a transformer architecture implementation with just a few hundred lines. Inference code for DETR can be implemented in less than 50 lines in PyTorch [32]. We hope that the simplicity of our method will attract new researchers to the detection community.
与许多现代检测器不同,DETR 可在任何提供常见 CNN 骨干与 Transformer 架构实现的深度学习框架中,用区区数百行实现。DETR 的推理代码在 PyTorch [32] 中可少于 50 行实现。我们希望方法的简洁性能吸引新研究者进入检测社区。
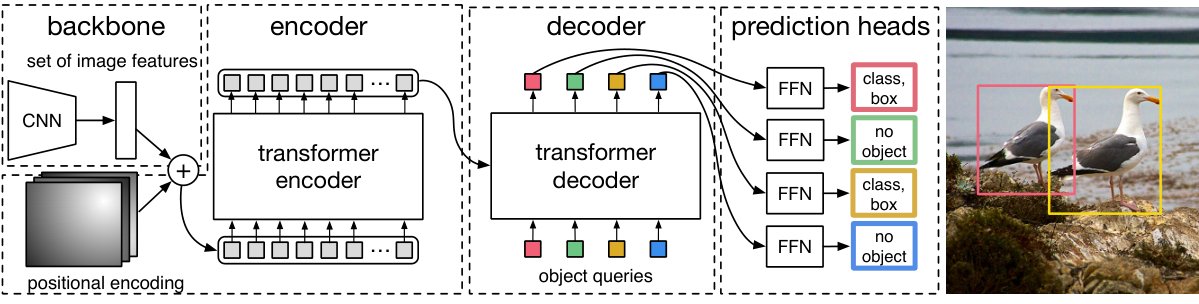
Figure 2: DETR uses a conventional CNN backbone to learn a 2D representation of an input image. The model flattens it and supplements it with a positional encoding before passing it into a transformer encoder. A transformer decoder then takes as input a small fixed number of learned positional embeddings, which we call object queries, and additionally attends to the encoder output. We pass each output embedding of the decoder to a shared feed forward network (FFN) that predicts either a detection (class and bounding box) or a “no object” class.
图 2:DETR 用常规 CNN 骨干学习输入图像的 2D 表示。模型将其展平并补充位置编码后送入 Transformer 编码器。Transformer 解码器则以少量固定的可学习位置嵌入(我们称为 object queries)为输入,并额外对编码器输出做注意力。我们把解码器每个输出嵌入送入共享前馈网络(FFN),预测检测(类别与边界框)或“无物体”类。
Backbone.
Starting from the initial image (with color channels[^2]), a conventional CNN backbone generates a lower-resolution activation map . Typical values we use are and .
Backbone.
从初始图像 (含 3 个颜色通道[^2])出发,常规 CNN 骨干生成较低分辨率激活图 。我们常用的典型值为 ,。
Transformer encoder.
First, a 1x1 convolution reduces the channel dimension of the high-level activation map from to a smaller dimension . creating a new feature map . The encoder expects a sequence as input, hence we collapse the spatial dimensions of into one dimension, resulting in a feature map. Each encoder layer has a standard architecture and consists of a multi-head self-attention module and a feed forward network (FFN). Since the transformer architecture is permutation-invariant, we supplement it with fixed positional encodings [31, 3] that are added to the input of each attention layer. We defer to the supplementary material the detailed definition of the architecture, which follows the one described in [47].
Transformer encoder.
首先,1×1 卷积把高层激活图 的通道维从 降到更小的维 ,得到新特征图 。编码器期望序列输入,因此我们把 的空间维折叠为一维,得到 特征图。每个编码器层为标准架构,由多头自注意力模块与前馈网络(FFN)组成。由于 Transformer 架构对排列不变,我们补充固定位置编码 [31, 3],加到每个注意力层的输入上。架构的详细定义留到补充材料,其遵循 [47] 所述。
Transformer decoder.
The decoder follows the standard architecture of the transformer, transforming embeddings of size using multi-headed self- and encoder-decoder attention mechanisms. The difference with the original transformer is that our model decodes the objects in parallel at each decoder layer, while Vaswani et al. [47] use an autoregressive model that predicts the output sequence one element at a time. We refer the reader unfamiliar with the concepts to the supplementary material. Since the decoder is also permutation-invariant, the input embeddings must be different to produce different results. These input embeddings are learnt positional encodings that we refer to as object queries, and similarly to the encoder, we add them to the input of each attention layer. The object queries are transformed into an output embedding by the decoder. They are then independently decoded into box coordinates and class labels by a feed forward network (described in the next subsection), resulting final predictions. Using self- and encoder-decoder attention over these embeddings, the model globally reasons about all objects together using pair-wise relations between them, while being able to use the whole image as context.
Transformer decoder.
解码器遵循 Transformer 的标准架构,用多头自注意力与编码器–解码器注意力机制变换 个大小为 的嵌入。与原始 Transformer 的差别在于:我们的模型在每一解码器层并行解码这 个物体,而 Vaswani et al. [47] 使用自回归模型一次预测输出序列的一个元素。不熟悉这些概念的读者可参阅补充材料。由于解码器也对排列不变, 个输入嵌入必须不同才能产生不同结果。这些输入嵌入是可学习的位置编码,我们称为 object queries;与编码器类似,我们把它们加到每个注意力层的输入上。解码器把 个 object query 变换为输出嵌入,再由前馈网络(下一小节描述)独立解码为框坐标与类别标签,得到 个最终预测。通过对这些嵌入做自注意力与编码器–解码器注意力,模型利用物体两两关系全局地一起推理所有物体,同时能以整幅图像为上下文。
Prediction feed-forward networks (FFNs).
The final prediction is computed by a 3-layer perceptron with ReLU activation function and hidden dimension , and a linear projection layer. The FFN predicts the normalized center coordinates, height and width of the box w.r.t. the input image, and the linear layer predicts the class label using a softmax function. Since we predict a fixed-size set of bounding boxes, where is usually much larger than the actual number of objects of interest in an image, an additional special class label is used to represent that no object is detected within a slot. This class plays a similar role to the “background” class in the standard object detection approaches.
Prediction feed-forward networks (FFNs).
最终预测由带 ReLU 激活、隐维为 的 3 层感知机与一个线性投影层计算。FFN 预测相对输入图像归一化的中心坐标、高与宽;线性层用 softmax 预测类别标签。由于我们预测固定大小为 的边界框集合,而 通常远大于图像中实际感兴趣物体数,额外使用特殊类别标签 表示某槽位未检测到物体。该类扮演与标准目标检测方法中“背景”类类似的角色。
Auxiliary decoding losses.
We found helpful to use auxiliary losses [1] in decoder during training, especially to help the model output the correct number of objects of each class. We add prediction FFNs and Hungarian loss after each decoder layer. All predictions FFNs share their parameters. We use an additional shared layer-norm to normalize the input to the prediction FFNs from different decoder layers.
Auxiliary decoding losses.
我们发现在训练时于解码器中使用辅助损失 [1] 有帮助,尤其有助于模型输出各类别正确的物体数量。我们在每个解码器层后加入预测 FFN 与 Hungarian loss。所有预测 FFN 共享参数。我们还使用额外的共享 layer-norm,对不同解码器层送入预测 FFN 的输入做归一化。
4 Experiments
We show that DETR achieves competitive results compared to Faster R-CNN in quantitative evaluation on COCO. Then, we provide a detailed ablation study of the architecture and loss, with insights and qualitative results. Finally, to show that DETR is a versatile and extensible model, we present results on panoptic segmentation, training only a small extension on a fixed DETR model. We provide code and pretrained models to reproduce our experiments at https://github.com/facebookresearch/detr.
我们表明 DETR 在 COCO 定量评估上相对 Faster R-CNN 达到有竞争力的结果。随后给出架构与损失的详细消融,并附见解与定性结果。最后,为展示 DETR 是通用且可扩展的模型,我们给出全景分割结果:仅在固定 DETR 模型上训练一个小扩展。复现实验的代码与预训练模型见 https://github.com/facebookresearch/detr 。
Dataset.
We perform experiments on COCO 2017 detection and panoptic segmentation datasets [24, 18], containing 118k training images and 5k validation images. Each image is annotated with bounding boxes and panoptic segmentation. There are 7 instances per image on average, up to 63 instances in a single image in training set, ranging from small to large on the same images. If not specified, we report AP as bbox AP, the integral metric over multiple thresholds. For comparison with Faster R-CNN we report validation AP at the last training epoch, for ablations we report median over validation results from the last 10 epochs.
Dataset.
我们在 COCO 2017 检测与全景分割数据集 [24, 18] 上实验,含 118k 训练图像与 5k 验证图像。每张图标注有边界框与全景分割。平均每图 7 个实例,训练集单图最多 63 个,同一图像上从小到大都有。若无特别说明,我们报告的 AP 为 bbox AP,即多阈值上的积分指标。与 Faster R-CNN 比较时报告最后训练 epoch 的验证 AP;消融则报告最后 10 个 epoch 验证结果的中位数。
Technical details.
We train DETR with AdamW [26] setting the initial transformer’s learning rate to , the backbone’s to , and weight decay to . All transformer weights are initialized with Xavier init [11], and the backbone is with ImageNet-pretrained ResNet model [15] from torchvision with frozen batchnorm layers. We report results with two different backbones: a ResNet-50 and a ResNet-101. The corresponding models are called respectively DETR and DETR-R101. Following [21], we also increase the feature resolution by adding a dilation to the last stage of the backbone and removing a stride from the first convolution of this stage. The corresponding models are called respectively DETR-DC5 and DETR-DC5-R101 (dilated C5 stage). This modification increases the resolution by a factor of two, thus improving performance for small objects, at the cost of a 16x higher cost in the self-attentions of the encoder, leading to an overall 2x increase in computational cost. A full comparison of FLOPs of these models and Faster R-CNN is given in Table 1.
Technical details.
我们用 AdamW [26] 训练 DETR,Transformer 初始学习率设为 ,骨干为 ,权重衰减为 。所有 Transformer 权重用 Xavier 初始化 [11],骨干为 torchvision 中 ImageNet 预训练的 ResNet [15],并冻结 batchnorm 层。我们报告两种骨干的结果:ResNet-50 与 ResNet-101,对应模型分别称为 DETR 与 DETR-R101。遵循 [21],我们还通过对骨干最后阶段加膨胀、并去掉该阶段第一个卷积的步幅来提高特征分辨率。对应模型分别称为 DETR-DC5 与 DETR-DC5-R101(膨胀的 C5 阶段)。该修改使分辨率提高两倍,从而改善小物体表现,但编码器自注意力代价提高 16 倍,总体计算代价约提高 2 倍。这些模型与 Faster R-CNN 的 FLOPs 完整比较见表 1。
We use scale augmentation, resizing the input images such that the shortest side is at least 480 and at most 800 pixels while the longest at most 1333 [50]. To help learning global relationships through the self-attention of the encoder, we also apply random crop augmentations during training, improving the performance by approximately 1 AP. Specifically, a train image is cropped with probability 0.5 to a random rectangular patch which is then resized again to 800-1333. The transformer is trained with default dropout of 0.1. At inference time, some slots predict empty class. To optimize for AP, we override the prediction of these slots with the second highest scoring class, using the corresponding confidence. This improves AP by 2 points compared to filtering out empty slots. Other training hyperparameters can be found in section 0.A.4. For our ablation experiments we use training schedule of 300 epochs with a learning rate drop by a factor of 10 after 200 epochs, where a single epoch is a pass over all training images once. Training the baseline model for 300 epochs on 16 V100 GPUs takes 3 days, with 4 images per GPU (hence a total batch size of 64). For the longer schedule used to compare with Faster R-CNN we train for 500 epochs with learning rate drop after 400 epochs. This schedule adds 1.5 AP compared to the shorter schedule.
我们使用尺度增强:把输入图像最短边缩放到至少 480、至多 800 像素,同时最长边至多 1333 [50]。为帮助通过编码器自注意力学习全局关系,训练时还施加随机裁剪增强,约提升 1 AP。具体地,训练图像以 0.5 概率裁成随机矩形块,再重新缩放到 800–1333。Transformer 使用默认 0.1 dropout。推理时部分槽位预测空类。为优化 AP,我们用次高分类别覆盖这些槽位的预测,并使用对应置信度。相对过滤空槽,这提升约 2 个 AP 点。其他训练超参见第 0.A.4 节。消融实验使用 300 epoch 训练日程,200 epoch 后学习率降 10 倍;一个 epoch 为遍历全部训练图像一次。在 16 块 V100 上训练基线模型 300 epoch 约需 3 天,每 GPU 4 张图(总 batch 64)。与 Faster R-CNN 比较时使用更长日程:500 epoch,400 epoch 后降学习率。该日程相对短日程再加 1.5 AP。
4.1 Comparison with Faster R-CNN
| Model | GFLOPS/FPS | #params | AP | AP50 | AP75 | APS | APM | APL |
|---|---|---|---|---|---|---|---|---|
| Faster RCNN-DC5 | 320/16 | 166M | 39.0 | 60.5 | 42.3 | 21.4 | 43.5 | 52.5 |
| Faster RCNN-FPN | 180/26 | 42M | 40.2 | 61.0 | 43.8 | 24.2 | 43.5 | 52.0 |
| Faster RCNN-R101-FPN | 246/20 | 60M | 42.0 | 62.5 | 45.9 | 25.2 | 45.6 | 54.6 |
| Faster RCNN-DC5+ | 320/16 | 166M | 41.1 | 61.4 | 44.3 | 22.9 | 45.9 | 55.0 |
| Faster RCNN-FPN+ | 180/26 | 42M | 42.0 | 62.1 | 45.5 | 26.6 | 45.4 | 53.4 |
| Faster RCNN-R101-FPN+ | 246/20 | 60M | 44.0 | 63.9 | 47.8 | 27.2 | 48.1 | 56.0 |
| DETR | 86/28 | 41M | 42.0 | 62.4 | 44.2 | 20.5 | 45.8 | 61.1 |
| DETR-DC5 | 187/12 | 41M | 43.3 | 63.1 | 45.9 | 22.5 | 47.3 | 61.1 |
| DETR-R101 | 152/20 | 60M | 43.5 | 63.8 | 46.4 | 21.9 | 48.0 | 61.8 |
| DETR-DC5-R101 | 253/10 | 60M | 44.9 | 64.7 | 47.7 | 23.7 | 49.5 | 62.3 |
Table 1: Comparison with Faster R-CNN with a ResNet-50 and ResNet-101 backbones on the COCO validation set. The top section shows results for Faster R-CNN models in Detectron2 [50], the middle section shows results for Faster R-CNN models with GIoU [38], random crops train-time augmentation, and the long 9x training schedule. DETR models achieve comparable results to heavily tuned Faster R-CNN baselines, having lower APS but greatly improved APL. We use torchscript Faster R-CNN and DETR models to measure FLOPS and FPS. Results without R101 in the name correspond to ResNet-50.
| Model | GFLOPS/FPS | #params | AP | AP50 | AP75 | APS | APM | APL |
|---|---|---|---|---|---|---|---|---|
| Faster RCNN-DC5 | 320/16 | 166M | 39.0 | 60.5 | 42.3 | 21.4 | 43.5 | 52.5 |
| Faster RCNN-FPN | 180/26 | 42M | 40.2 | 61.0 | 43.8 | 24.2 | 43.5 | 52.0 |
| Faster RCNN-R101-FPN | 246/20 | 60M | 42.0 | 62.5 | 45.9 | 25.2 | 45.6 | 54.6 |
| Faster RCNN-DC5+ | 320/16 | 166M | 41.1 | 61.4 | 44.3 | 22.9 | 45.9 | 55.0 |
| Faster RCNN-FPN+ | 180/26 | 42M | 42.0 | 62.1 | 45.5 | 26.6 | 45.4 | 53.4 |
| Faster RCNN-R101-FPN+ | 246/20 | 60M | 44.0 | 63.9 | 47.8 | 27.2 | 48.1 | 56.0 |
| DETR | 86/28 | 41M | 42.0 | 62.4 | 44.2 | 20.5 | 45.8 | 61.1 |
| DETR-DC5 | 187/12 | 41M | 43.3 | 63.1 | 45.9 | 22.5 | 47.3 | 61.1 |
| DETR-R101 | 152/20 | 60M | 43.5 | 63.8 | 46.4 | 21.9 | 48.0 | 61.8 |
| DETR-DC5-R101 | 253/10 | 60M | 44.9 | 64.7 | 47.7 | 23.7 | 49.5 | 62.3 |
表 1:在 COCO 验证集上与使用 ResNet-50 / ResNet-101 骨干的 Faster R-CNN 比较。上段为 Detectron2 [50] 中 Faster R-CNN 结果;中段为加入 GIoU [38]、随机裁剪训练增强与长 9x 训练日程的 Faster R-CNN;DETR 与高度调优的 Faster R-CNN 基线结果可比,APS 较低但 APL 大幅提升。用 torchscript 的 Faster R-CNN 与 DETR 测 FLOPS 与 FPS。名称中无 R101 的对应 ResNet-50。
Transformers are typically trained with Adam or Adagrad optimizers with very long training schedules and dropout, and this is true for DETR as well. Faster R-CNN, however, is trained with SGD with minimal data augmentation and we are not aware of successful applications of Adam or dropout. Despite these differences we attempt to make a Faster R-CNN baseline stronger. To align it with DETR, we add generalized IoU [38] to the box loss, the same random crop augmentation and long training known to improve results [13]. Results are presented in Table 1. In the top section we show Faster R-CNN results from Detectron2 Model Zoo [50] for models trained with the 3x schedule. In the middle section we show results (with a “+”) for the same models but trained with the 9x schedule (109 epochs) and the described enhancements, which in total adds 1-2 AP. In the last section of Table 1 we show the results for multiple DETR models. To be comparable in the number of parameters we choose a model with 6 transformer and 6 decoder layers of width 256 with 8 attention heads. Like Faster R-CNN with FPN this model has 41.3M parameters, out of which 23.5M are in ResNet-50, and 17.8M are in the transformer. Even though both Faster R-CNN and DETR are still likely to further improve with longer training, we can conclude that DETR can be competitive with Faster R-CNN with the same number of parameters, achieving 42 AP on the COCO val subset. The way DETR achieves this is by improving APL (+7.8), however note that the model is still lagging behind in APS (-5.5). DETR-DC5 with the same number of parameters and similar FLOP count has higher AP, but is still significantly behind in APS too. Faster R-CNN and DETR with ResNet-101 backbone show comparable results as well.
Transformer 通常用 Adam 或 Adagrad、很长训练日程与 dropout 训练,DETR 亦然。而 Faster R-CNN 用 SGD、最小数据增强训练,我们也不知道 Adam 或 dropout 的成功应用。尽管有这些差异,我们仍尝试加强 Faster R-CNN 基线。为与 DETR 对齐,我们在框损失中加入广义 IoU [38]、相同的随机裁剪增强,以及已知能改善结果的长训练 [13]。结果见表 1。上段给出 Detectron2 Model Zoo [50] 中以 3x 日程训练的 Faster R-CNN。中段给出同模型但以 9x 日程(109 epoch)与上述增强训练的结果(标“+”),合计提升 1–2 AP。表 1 最后一段给出多种 DETR 结果。为在参数量上可比,我们选择 6 层编码器、6 层解码器、宽度 256、8 注意力头的模型。与带 FPN 的 Faster R-CNN 一样,该模型有 41.3M 参数,其中 23.5M 在 ResNet-50,17.8M 在 Transformer。即便 Faster R-CNN 与 DETR 都很可能随更长训练继续提升,我们仍可结论:在相同参数量下 DETR 可与 Faster R-CNN 竞争,在 COCO val 子集上达到 42 AP。DETR 达成这一点主要靠提升 APL(+7.8),但请注意模型在 APS 上仍落后(-5.5)。参数量相同、FLOP 相近的 DETR-DC5 有更高 AP,但在 APS 上仍显著落后。ResNet-101 骨干的 Faster R-CNN 与 DETR 结果同样可比。
4.2 Ablations
Attention mechanisms in the transformer decoder are the key components which model relations between feature representations of different detections. In our ablation analysis, we explore how other components of our architecture and loss influence the final performance. For the study we choose ResNet-50-based DETR model with 6 encoder, 6 decoder layers and width 256. The model has 41.3M parameters, achieves 40.6 and 42.0 AP on short and long schedules respectively, and runs at 28 FPS, similarly to Faster R-CNN-FPN with the same backbone.
Transformer 解码器中的注意力机制是建模不同检测特征表示之间关系的关键组件。消融分析中,我们探索架构与损失的其他组件如何影响最终表现。研究选用基于 ResNet-50 的 DETR:6 编码器层、6 解码器层、宽度 256。模型有 41.3M 参数,短/长日程分别达到 40.6 与 42.0 AP,运行约 28 FPS,与同骨干 Faster R-CNN-FPN 相近。
Number of encoder layers.
We evaluate the importance of global image-level self-attention by changing the number of encoder layers (Table 2). Without encoder layers, overall AP drops by 3.9 points, with a more significant drop of 6.0 AP on large objects. We hypothesize that, by using global scene reasoning, the encoder is important for disentangling objects. In Figure 3, we visualize the attention maps of the last encoder layer of a trained model, focusing on a few points in the image. The encoder seems to separate instances already, which likely simplifies object extraction and localization for the decoder.
Number of encoder layers.
我们通过改变编码器层数评估全局图像级自注意力的重要性(表 2)。无编码器层时,总体 AP 下降 3.9 点,大物体上下降更显著达 6.0 AP。我们假设:借助全局场景推理,编码器对解耦物体很重要。图 3 可视化训练模型最后一层编码器注意力图,聚焦图像中若干点。编码器似乎已能分离实例,这很可能简化解码器的物体提取与定位。
| #layers | GFLOPS/FPS | #params | AP | AP50 | APS | APM | APL |
|---|---|---|---|---|---|---|---|
| 0 | 76/28 | 33.4M | 36.7 | 57.4 | 16.8 | 39.6 | 54.2 |
| 3 | 81/25 | 37.4M | 40.1 | 60.6 | 18.5 | 43.8 | 58.6 |
| 6 | 86/23 | 41.3M | 40.6 | 61.6 | 19.9 | 44.3 | 60.2 |
| 12 | 95/20 | 49.2M | 41.6 | 62.1 | 19.8 | 44.9 | 61.9 |
Table 2: Effect of encoder size. Each row corresponds to a model with varied number of encoder layers and fixed number of decoder layers. Performance gradually improves with more encoder layers.
| #layers | GFLOPS/FPS | #params | AP | AP50 | APS | APM | APL |
|---|---|---|---|---|---|---|---|
| 0 | 76/28 | 33.4M | 36.7 | 57.4 | 16.8 | 39.6 | 54.2 |
| 3 | 81/25 | 37.4M | 40.1 | 60.6 | 18.5 | 43.8 | 58.6 |
| 6 | 86/23 | 41.3M | 40.6 | 61.6 | 19.9 | 44.3 | 60.2 |
| 12 | 95/20 | 49.2M | 41.6 | 62.1 | 19.8 | 44.9 | 61.9 |
表 2:编码器规模的影响。每行对应编码器层数变化、解码器层数固定的模型。表现随编码器层数增加逐渐提升。
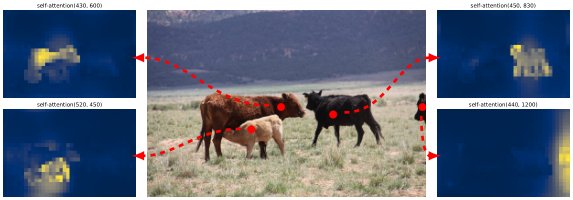
Figure 3: Encoder self-attention for a set of reference points. The encoder is able to separate individual instances. Predictions are made with baseline DETR model on a validation set image.
图 3:若干参考点上的编码器自注意力。编码器能够分离个体实例。预测由基线 DETR 模型在验证集图像上做出。
Number of decoder layers.
Figure 4: AP and AP50 performance after each decoder layer. A single long schedule baseline model is evaluated. DETR does not need NMS by design, which is validated by this figure. NMS lowers AP in the final layers, removing TP predictions, but improves AP in the first decoder layers, removing double predictions, as there is no communication in the first layer, and slightly improves AP50.
Number of decoder layers.
图 4:每个解码器层后的 AP 与 AP50 表现。评估单个长日程基线模型。DETR 设计上不需要 NMS,本图加以验证。NMS 在最后几层降低 AP(去掉 TP 预测),但在最初几层解码器提升 AP(去掉双重预测——因为第一层尚无通信),并略提升 AP50。
We apply auxiliary losses after each decoding layer (see Section 3.2), hence, the prediction FFNs are trained by design to predict objects out of the outputs of every decoder layer. We analyze the importance of each decoder layer by evaluating the objects that would be predicted at each stage of the decoding (Fig. 5). Both AP and AP50 improve after every layer, totalling into a very significant +8.2/9.5 AP improvement between the first and the last layer. With its set-based loss, DETR does not need NMS by design. To verify this we run a standard NMS procedure with default parameters [50] for the outputs after each decoder. NMS improves performance for the predictions from the first decoder. This can be explained by the fact that a single decoding layer of the transformer is not able to compute any cross-correlations between the output elements, and thus it is prone to making multiple predictions for the same object. In the second and subsequent layers, the self-attention mechanism over the activations allows the model to inhibit duplicate predictions. We observe that the improvement brought by NMS diminishes as depth increases. At the last layers, we observe a small loss in AP as NMS incorrectly removes true positive predictions.
我们在每个解码层后施加辅助损失(见第 3.2 节),因此预测 FFN 在设计上就被训练为从每一解码层输出预测物体。我们通过分析解码各阶段将预测的物体来衡量每层重要性(图 5)。AP 与 AP50 在每一层后都提升,第一层到最后一层合计非常显著的 +8.2/9.5 AP 提升。借助集合损失,DETR 设计上不需要 NMS。为验证这一点,我们对每个解码器后的输出运行默认参数的标准 NMS 流程 [50]。NMS 改善第一层解码器的预测表现,可解释为:单层 Transformer 解码无法计算输出元素之间的交叉相关,因而容易对同一物体做多次预测。从第二层起,对激活的自注意力使模型能抑制重复预测。我们观察到 NMS 带来的提升随深度增加而减弱。在最后几层,NMS 因错误去掉真阳性预测而导致 AP 略有损失。
Similarly to visualizing encoder attention, we visualize decoder attentions in Fig. 6, coloring attention maps for each predicted object in different colors. We observe that decoder attention is fairly local, meaning that it mostly attends to object extremities such as heads or legs. We hypothesise that after the encoder has separated instances via global attention, the decoder only needs to attend to the extremities to extract the class and object boundaries.
与可视化编码器注意力类似,我们在图 6 可视化解码器注意力,用不同颜色为每个预测物体的注意力图上色。我们观察到解码器注意力相当局部,即主要关注头或腿等物体极端部位。我们假设:编码器已通过全局注意力分离实例后,解码器只需关注极端部位即可提取类别与物体边界。
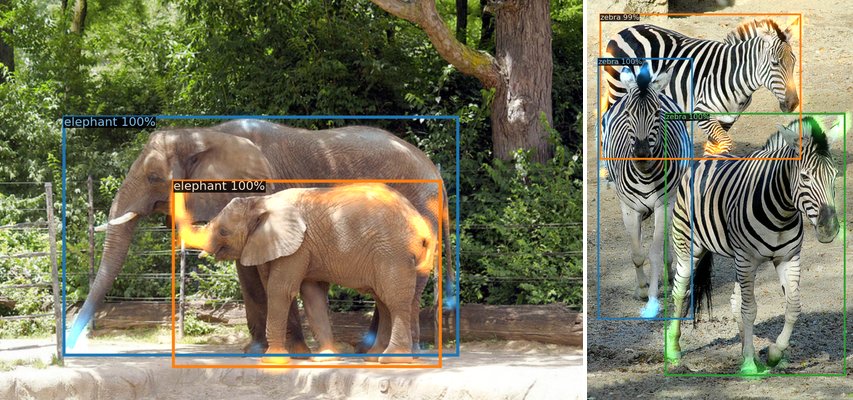
Figure 6: Visualizing decoder attention for every predicted object (images from COCO val set). Predictions are made with DETR-DC5 model. Attention scores are coded with different colors for different objects. Decoder typically attends to object extremities, such as legs and heads. Best viewed in color.
图 6:为每个预测物体可视化解码器注意力(图像来自 COCO val 集)。预测由 DETR-DC5 模型做出。不同物体的注意力分数用不同颜色编码。解码器通常关注腿、头等物体极端部位。建议彩色查看。
Importance of FFN.
FFN inside tranformers can be seen as convolutional layers, making encoder similar to attention augmented convolutional networks [3]. We attempt to remove it completely leaving only attention in the transformer layers. By reducing the number of network parameters from 41.3M to 28.7M, leaving only 10.8M in the transformer, performance drops by 2.3 AP, we thus conclude that FFN are important for achieving good results.
Importance of FFN.
Transformer 内部的 FFN 可视为 卷积层,使编码器类似于注意力增强卷积网络 [3]。我们尝试完全去掉它,只在 Transformer 层中保留注意力。网络参数从 41.3M 减到 28.7M(Transformer 中仅剩 10.8M),表现下降 2.3 AP,因此我们结论 FFN 对取得好结果很重要。
Importance of positional encodings.
There are two kinds of positional encodings in our model: spatial positional encodings and output positional encodings (object queries). We experiment with various combinations of fixed and learned encodings, results can be found in table 3. Output positional encodings are required and cannot be removed, so we experiment with either passing them once at decoder input or adding to queries at every decoder attention layer. In the first experiment we completely remove spatial positional encodings and pass output positional encodings at input and, interestingly, the model still achieves more than 32 AP, losing 7.8 AP to the baseline. Then, we pass fixed sine spatial positional encodings and the output encodings at input once, as in the original transformer [47], and find that this leads to 1.4 AP drop compared to passing the positional encodings directly in attention. Learned spatial encodings passed to the attentions give similar results. Surprisingly, we find that not passing any spatial encodings in the encoder only leads to a minor AP drop of 1.3 AP. When we pass the encodings to the attentions, they are shared across all layers, and the output encodings (object queries) are always learned.
Importance of positional encodings.
模型中有两类位置编码:空间位置编码与输出位置编码(object queries)。我们试验固定与可学习编码的多种组合,结果见表 3。输出位置编码是必需的、不能去掉,因此我们试验:只在解码器输入处传一次,或在每个解码器注意力层加到 query 上。第一项实验完全去掉空间位置编码,并在输入处传输出位置编码;有趣的是模型仍超过 32 AP,相对基线损失 7.8 AP。随后我们传固定正弦空间位置编码,并像原始 Transformer [47] 那样在输入处传一次输出编码,发现相对直接在注意力中传位置编码下降 1.4 AP。传给注意力的可学习空间编码给出相近结果。令人惊讶的是,编码器中不传任何空间编码仅导致 1.3 AP 的轻微下降。当把编码传给注意力时,它们在所有层共享;输出编码(object queries)始终可学习。
| spatial pos. enc. | output pos. enc. | |||||
|---|---|---|---|---|---|---|
| encoder | decoder | decoder | AP | AP50 | ||
| none | none | learned at input | 32.8 | -7.8 | 55.2 | -6.5 |
| sine at input | sine at input | learned at input | 39.2 | -1.4 | 60.0 | -1.6 |
| learned at attn. | learned at attn. | learned at attn. | 39.6 | -1.0 | 60.7 | -0.9 |
| none | sine at attn. | learned at attn. | 39.3 | -1.3 | 60.3 | -1.4 |
| sine at attn. | sine at attn. | learned at attn. | 40.6 | - | 61.6 | - |
Table 3: Results for different positional encodings compared to the baseline (last row), which has fixed sine pos. encodings passed at every attention layer in both the encoder and the decoder. Learned embeddings are shared between all layers. Not using spatial positional encodings leads to a significant drop in AP. Interestingly, passing them in decoder only leads to a minor AP drop. All these models use learned output positional encodings.
| spatial pos. enc. | output pos. enc. | |||||
|---|---|---|---|---|---|---|
| encoder | decoder | decoder | AP | AP50 | ||
| none | none | learned at input | 32.8 | -7.8 | 55.2 | -6.5 |
| sine at input | sine at input | learned at input | 39.2 | -1.4 | 60.0 | -1.6 |
| learned at attn. | learned at attn. | learned at attn. | 39.6 | -1.0 | 60.7 | -0.9 |
| none | sine at attn. | learned at attn. | 39.3 | -1.3 | 60.3 | -1.4 |
| sine at attn. | sine at attn. | learned at attn. | 40.6 | - | 61.6 | - |
表 3:不同位置编码相对基线(末行)的结果;基线在编码器与解码器每个注意力层传入固定正弦位置编码。可学习嵌入在所有层共享。不使用空间位置编码会导致 AP 显著下降。有趣的是,仅在解码器传入只造成轻微 AP 下降。所有这些模型都使用可学习输出位置编码。
Given these ablations, we conclude that transformer components: the global self-attention in encoder, FFN, multiple decoder layers, and positional encodings, all significantly contribute to the final object detection performance.
基于这些消融,我们结论:Transformer 组件——编码器中的全局自注意力、FFN、多层解码器以及位置编码——都对最终目标检测表现有显著贡献。
Loss ablations.
To evaluate the importance of different components of the matching cost and the loss, we train several models turning them on and off. There are three components to the loss: classification loss, bounding box distance loss, and GIoU [38] loss. The classification loss is essential for training and cannot be turned off, so we train a model without bounding box distance loss, and a model without the GIoU loss, and compare with baseline, trained with all three losses. Results are presented in table 4.
Loss ablations.
为评估匹配代价与损失不同组件的重要性,我们训练若干开关它们的模型。损失有三个组件:分类损失、 边界框距离损失,以及 GIoU [38] 损失。分类损失对训练必不可少、不能关掉,因此我们训练无边界框距离损失的模型与无 GIoU 损失的模型,并与三者皆用的基线比较。结果见表 4。
| class | GIoU | AP | AP50 | APS | APM | APL | |||
|---|---|---|---|---|---|---|---|---|---|
| ✓ | ✓ | 35.8 | -4.8 | 57.3 | -4.4 | 13.7 | 39.8 | 57.9 | |
| ✓ | ✓ | 39.9 | -0.7 | 61.6 | 0 | 19.9 | 43.2 | 57.9 | |
| ✓ | ✓ | ✓ | 40.6 | - | 61.6 | - | 19.9 | 44.3 | 60.2 |
Table 4: Effect of loss components on AP. We train two models turning off loss, and GIoU loss, and observe that gives poor results on its own, but when combined with GIoU improves APM and APL. Our baseline (last row) combines both losses.
| class | GIoU | AP | AP50 | APS | APM | APL | |||
|---|---|---|---|---|---|---|---|---|---|
| ✓ | ✓ | 35.8 | -4.8 | 57.3 | -4.4 | 13.7 | 39.8 | 57.9 | |
| ✓ | ✓ | 39.9 | -0.7 | 61.6 | 0 | 19.9 | 43.2 | 57.9 | |
| ✓ | ✓ | ✓ | 40.6 | - | 61.6 | - | 19.9 | 44.3 | 60.2 |
表 4:损失组件对 AP 的影响。我们训练关掉 损失与关掉 GIoU 损失的两个模型,观察到单独 结果较差,但与 GIoU 结合可提升 APM 与 APL。我们的基线(末行)结合两种损失。
GIoU loss on its own accounts for most of the model performance, losing only 0.7 AP to the baseline with combined losses. Using without GIoU shows poor results. We only studied simple ablations of different losses (using the same weighting every time), but other means of combining them may achieve different results.
单独的 GIoU 损失承担模型表现的大部分,相对结合损失的基线仅损失 0.7 AP。不用 GIoU、只用 结果较差。我们只研究了不同损失的简单消融(每次使用相同加权),但其他组合方式可能得到不同结果。
4.3 Analysis
Decoder output slot analysis
Figure 7: Visualization of all box predictions on all images from COCO 2017 val set for 20 out of total prediction slots in DETR decoder. Each box prediction is represented as a point with the coordinates of its center in the 1-by-1 square normalized by each image size. The points are color-coded so that green color corresponds to small boxes, red to large horizontal boxes and blue to large vertical boxes. We observe that each slot learns to specialize on certain areas and box sizes with several operating modes. We note that almost all slots have a mode of predicting large image-wide boxes that are common in COCO dataset.
Decoder output slot analysis
图 7:对 DETR 解码器全部 个预测槽位中的 20 个,可视化其在 COCO 2017 val 集全部图像上的所有框预测。每个框预测表示为其在按各图像尺寸归一化的 1×1 正方形中的中心坐标点。点用颜色编码:绿色对应小框,红色对应大水平框,蓝色对应大竖直框。我们观察到每个槽位学到在某些区域与框尺寸上特化,并有若干工作模式。我们注意到几乎所有槽位都有预测 COCO 中常见的大范围整图框的模式。
In Fig. 7 we visualize the boxes predicted by different slots for all images in COCO 2017 val set. DETR learns different specialization for each query slot. We observe that each slot has several modes of operation focusing on different areas and box sizes. In particular, all slots have the mode for predicting image-wide boxes (visible as the red dots aligned in the middle of the plot). We hypothesize that this is related to the distribution of objects in COCO.
在图 7 中,我们可视化 DETR 不同槽位对 COCO 2017 val 集全部图像预测的框。DETR 为每个 query 槽位学到不同特化。我们观察到每个槽位有若干工作模式,聚焦不同区域与框尺寸。尤其是,所有槽位都有预测整图范围框的模式(可见为图中部对齐的红点)。我们假设这与 COCO 中物体分布有关。
Generalization to unseen numbers of instances.
Some classes in COCO are not well represented with many instances of the same class in the same image. For example, there is no image with more than 13 giraffes in the training set. We create a synthetic image[^3] to verify the generalization ability of DETR (see Figure 5). Our model is able to find all 24 giraffes on the image which is clearly out of distribution. This experiment confirms that there is no strong class-specialization in each object query.
Generalization to unseen numbers of instances.
COCO 中某些类别在同图出现大量同类别实例的情况代表性不足。例如训练集中没有超过 13 只长颈鹿的图像。我们创建一张合成图像[^3] 以验证 DETR 的泛化能力(见图 5)。我们的模型能找到图中全部 24 只长颈鹿,这明显超出分布。该实验确认:各个 object query 中不存在强烈的类别特化。
4.4 DETR for panoptic segmentation
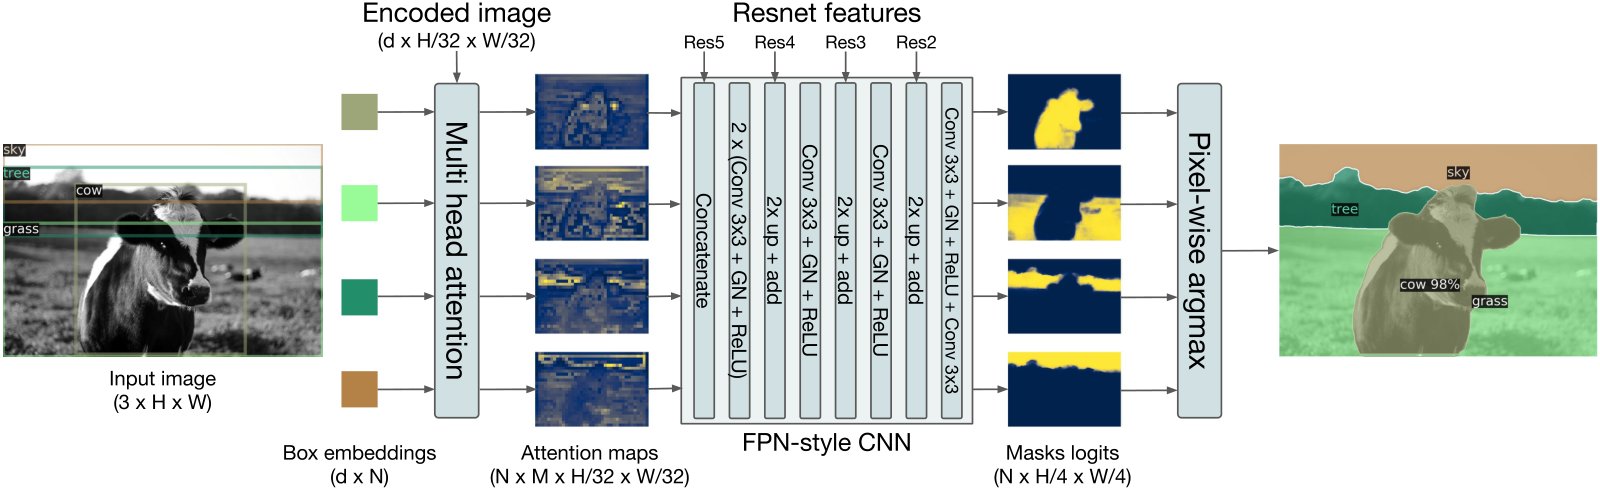
Figure 8: Illustration of the panoptic head. A binary mask is generated in parallel for each detected object, then the masks are merged using pixel-wise argmax.
图 8:全景头示意。为每个检测到的物体并行生成二值掩码,再用逐像素 argmax 合并掩码。
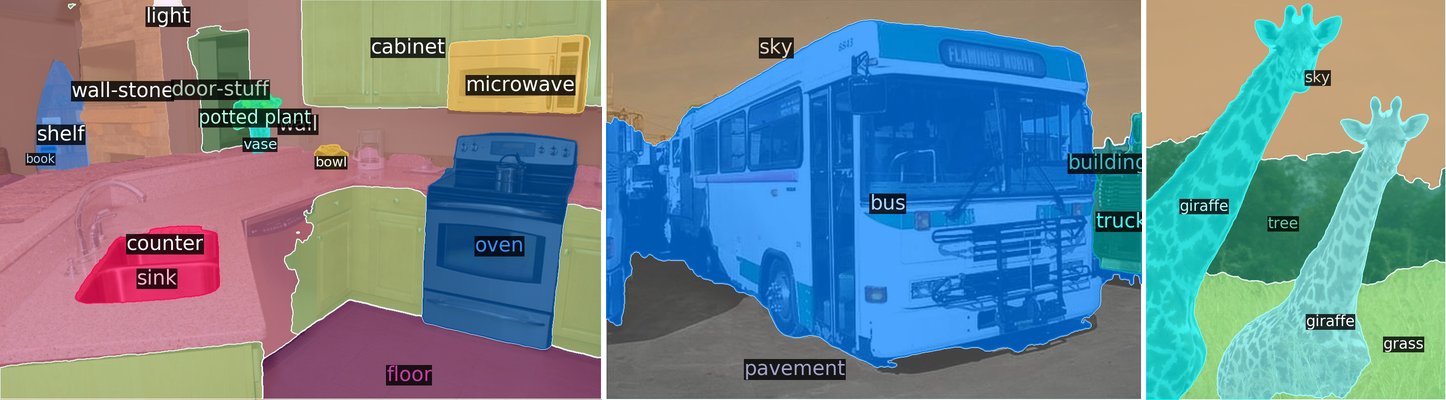
Figure 9: Qualitative results for panoptic segmentation generated by DETR-R101. DETR produces aligned mask predictions in a unified manner for things and stuff.
图 9:DETR-R101 生成的全景分割定性结果。DETR 以统一方式为 things 与 stuff 产生对齐的掩码预测。
Panoptic segmentation [19] has recently attracted a lot of attention from the computer vision community. Similarly to the extension of Faster R-CNN [37] to Mask R-CNN [14], DETR can be naturally extended by adding a mask head on top of the decoder outputs. In this section we demonstrate that such a head can be used to produce panoptic segmentation [19] by treating stuff and thing classes in a unified way. We perform our experiments on the panoptic annotations of the COCO dataset that has 53 stuff categories in addition to 80 things categories.
全景分割 [19] 近来受到计算机视觉社区大量关注。类似于把 Faster R-CNN [37] 扩展到 Mask R-CNN [14],DETR 可通过在解码器输出之上加掩码头自然扩展。本节我们表明:通过以统一方式对待 stuff 与 thing 类,这样的头可用于产生全景分割 [19]。我们在 COCO 数据集的全景标注上实验,除 80 个 things 类别外还有 53 个 stuff 类别。
We train DETR to predict boxes around both stuff and things classes on COCO, using the same recipe. Predicting boxes is required for the training to be possible, since the Hungarian matching is computed using distances between boxes. We also add a mask head which predicts a binary mask for each of the predicted boxes, see Figure 8. It takes as input the output of transformer decoder for each object and computes multi-head (with heads) attention scores of this embedding over the output of the encoder, generating attention heatmaps per object in a small resolution. To make the final prediction and increase the resolution, an FPN-like architecture is used. We describe the architecture in more details in the supplement. The final resolution of the masks has stride 4 and each mask is supervised independently using the DICE/F-1 loss [28] and Focal loss [23].
我们用相同配方训练 DETR,对 COCO 上的 stuff 与 things 类都预测框。预测框对训练是必需的,因为匈牙利匹配用框之间的距离计算。我们还加入为每个预测框预测二值掩码的掩码头,见图 8。它以每个物体的 Transformer 解码器输出为输入,计算该嵌入在编码器输出上的多头( 头)注意力分数,从而以较低分辨率为每个物体生成 张注意力热图。为做最终预测并提高分辨率,使用类似 FPN 的架构。架构细节见补充材料。掩码最终分辨率为 stride 4,每个掩码用 DICE/F-1 损失 [28] 与 Focal 损失 [23] 独立监督。
The mask head can be trained either jointly, or in a two steps process, where we train DETR for boxes only, then freeze all the weights and train only the mask head for 25 epochs. Experimentally, these two approaches give similar results, we report results using the latter method since it results in a shorter total wall-clock time training.
掩码头既可联合训练,也可两步训练:先只为框训练 DETR,再冻结全部权重、只训练掩码头 25 个 epoch。实验上两种做法结果相近;我们报告后者,因其总墙钟训练时间更短。
To predict the final panoptic segmentation we simply use an argmax over the mask scores at each pixel, and assign the corresponding categories to the resulting masks. This procedure guarantees that the final masks have no overlaps and, therefore, DETR does not require a heuristic [19] that is often used to align different masks.
为预测最终全景分割,我们仅对每个像素上的掩码分数取 argmax,并把对应类别赋给所得掩码。该流程保证最终掩码无重叠,因此 DETR 不需要常用于对齐不同掩码的启发式 [19]。
Training details.
We train DETR, DETR-DC5 and DETR-R101 models following the recipe for bounding box detection to predict boxes around stuff and things classes in COCO dataset. The new mask head is trained for 25 epochs (see supplementary for details). During inference we first filter out the detection with a confidence below 85%, then compute the per-pixel argmax to determine in which mask each pixel belongs. We then collapse different mask predictions of the same stuff category in one, and filter the empty ones (less than 4 pixels).
Training details.
我们按边界框检测配方训练 DETR、DETR-DC5 与 DETR-R101,以在 COCO 上为 stuff 与 things 类预测框。新掩码头训练 25 个 epoch(细节见补充材料)。推理时先过滤置信度低于 85% 的检测,再计算逐像素 argmax 以确定每个像素属于哪个掩码。随后把同一 stuff 类别的不同掩码预测折叠为一个,并过滤空掩码(少于 4 像素)。
| Model | Backbone | PQ | SQ | RQ | AP | ||||||
|---|---|---|---|---|---|---|---|---|---|---|---|
| PanopticFPN++ | R50 | 42.4 | 79.3 | 51.6 | 49.2 | 82.4 | 58.8 | 32.3 | 74.8 | 40.6 | 37.7 |
| UPSnet | R50 | 42.5 | 78.0 | 52.5 | 48.6 | 79.4 | 59.6 | 33.4 | 75.9 | 41.7 | 34.3 |
| UPSnet-M | R50 | 43.0 | 79.1 | 52.8 | 48.9 | 79.7 | 59.7 | 34.1 | 78.2 | 42.3 | 34.3 |
| PanopticFPN++ | R101 | 44.1 | 79.5 | 53.3 | 51.0 | 83.2 | 60.6 | 33.6 | 74.0 | 42.1 | 39.7 |
| DETR | R50 | 43.4 | 79.3 | 53.8 | 48.2 | 79.8 | 59.5 | 36.3 | 78.5 | 45.3 | 31.1 |
| DETR-DC5 | R50 | 44.6 | 79.8 | 55.0 | 49.4 | 80.5 | 60.6 | 37.3 | 78.7 | 46.5 | 31.9 |
| DETR-R101 | R101 | 45.1 | 79.9 | 55.5 | 50.5 | 80.9 | 61.7 | 37.0 | 78.5 | 46.0 | 33.0 |
Table 5: Comparison with the state-of-the-art methods UPSNet [51] and Panoptic FPN [18] on the COCO val dataset We retrained PanopticFPN with the same data-augmentation as DETR, on a 18x schedule for fair comparison. UPSNet uses the 1x schedule, UPSNet-M is the version with multiscale test-time augmentations.
| Model | Backbone | PQ | SQ | RQ | AP | ||||||
|---|---|---|---|---|---|---|---|---|---|---|---|
| PanopticFPN++ | R50 | 42.4 | 79.3 | 51.6 | 49.2 | 82.4 | 58.8 | 32.3 | 74.8 | 40.6 | 37.7 |
| UPSnet | R50 | 42.5 | 78.0 | 52.5 | 48.6 | 79.4 | 59.6 | 33.4 | 75.9 | 41.7 | 34.3 |
| UPSnet-M | R50 | 43.0 | 79.1 | 52.8 | 48.9 | 79.7 | 59.7 | 34.1 | 78.2 | 42.3 | 34.3 |
| PanopticFPN++ | R101 | 44.1 | 79.5 | 53.3 | 51.0 | 83.2 | 60.6 | 33.6 | 74.0 | 42.1 | 39.7 |
| DETR | R50 | 43.4 | 79.3 | 53.8 | 48.2 | 79.8 | 59.5 | 36.3 | 78.5 | 45.3 | 31.1 |
| DETR-DC5 | R50 | 44.6 | 79.8 | 55.0 | 49.4 | 80.5 | 60.6 | 37.3 | 78.7 | 46.5 | 31.9 |
| DETR-R101 | R101 | 45.1 | 79.9 | 55.5 | 50.5 | 80.9 | 61.7 | 37.0 | 78.5 | 46.0 | 33.0 |
表 5:在 COCO val 上与当时领先方法 UPSNet [51] 和 Panoptic FPN [18] 比较。我们用与 DETR 相同的数据增强、18x 日程重训 PanopticFPN 以便公平比较。UPSNet 使用 1x 日程;UPSNet-M 为带多尺度测试时增强的版本。
Main results.
Qualitative results are shown in Figure 9. In table 5 we compare our unified panoptic segmenation approach with several established methods that treat things and stuff differently. We report the Panoptic Quality (PQ) and the break-down on things () and stuff (). We also report the mask AP (computed on the things classes), before any panoptic post-treatment (in our case, before taking the pixel-wise argmax). We show that DETR outperforms published results on COCO-val 2017, as well as our strong PanopticFPN baseline (trained with same data-augmentation as DETR, for fair comparison). The result break-down shows that DETR is especially dominant on stuff classes, and we hypothesize that the global reasoning allowed by the encoder attention is the key element to this result. For things class, despite a severe deficit of up to 8 mAP compared to the baselines on the mask AP computation, DETR obtains competitive . We also evaluated our method on the test set of the COCO dataset, and obtained 46 PQ. We hope that our approach will inspire the exploration of fully unified models for panoptic segmentation in future work.
Main results.
定性结果见图 9。表 5 中我们把统一全景分割方法与若干对 things 与 stuff 区别对待的既有方法比较。我们报告全景质量(PQ)以及在 things()与 stuff()上的分解。我们也报告任何全景后处理之前(我们的情形是逐像素 argmax 之前)在 things 类上计算的掩码 AP。结果表明 DETR 超过 COCO-val 2017 上已发表结果,以及我们强的 PanopticFPN 基线(用与 DETR 相同数据增强训练以便公平比较)。结果分解显示 DETR 在 stuff 类上尤其占优;我们假设编码器注意力带来的全局推理是该结果的关键。对 things 类,尽管在掩码 AP 计算上相对基线最多落后 8 mAP,DETR 仍获得有竞争力的 。我们也在 COCO 测试集上评估,得到 46 PQ。希望我们的方法能启发未来工作探索全景分割的完全统一模型。
5 Conclusion
We presented DETR, a new design for object detection systems based on transformers and bipartite matching loss for direct set prediction. The approach achieves comparable results to an optimized Faster R-CNN baseline on the challenging COCO dataset. DETR is straightforward to implement and has a flexible architecture that is easily extensible to panoptic segmentation, with competitive results. In addition, it achieves significantly better performance on large objects than Faster R-CNN, likely thanks to the processing of global information performed by the self-attention.
我们提出 DETR:一种基于 Transformer 与二分图匹配损失、面向直接集合预测的目标检测系统设计。该方法在具有挑战性的 COCO 数据集上达到与优化后 Faster R-CNN 基线可比的结果。DETR 实现直接,架构灵活,易于扩展到全景分割并取得有竞争力的结果。此外,它在大物体上显著优于 Faster R-CNN,这很可能得益于自注意力所做的全局信息处理。
This new design for detectors also comes with new challenges, in particular regarding training, optimization and performances on small objects. Current detectors required several years of improvements to cope with similar issues, and we expect future work to successfully address them for DETR.
这一新检测器设计也带来新挑战,尤其在训练、优化与小物体表现方面。当前检测器用了数年改进才应对类似问题,我们预期未来工作能成功为 DETR 解决这些问题。
6 Acknowledgements
We thank Sainbayar Sukhbaatar, Piotr Bojanowski, Natalia Neverova, David Lopez-Paz, Guillaume Lample, Danielle Rothermel, Kaiming He, Ross Girshick, Xinlei Chen and the whole Facebook AI Research Paris team for discussions and advices without which this work would not be possible.
References
[1] Al-Rfou, R., Choe, D., Constant, N., Guo, M., Jones, L.: Character-level language modeling with deeper self-attention. In: AAAI Conference on Artificial Intelligence (2019)
[2] Bahdanau, D., Cho, K., Bengio, Y.: Neural machine translation by jointly learning to align and translate. In: ICLR (2015)
[3] Bello, I., Zoph, B., Vaswani, A., Shlens, J., Le, Q.V.: Attention augmented convolutional networks. In: ICCV (2019)
[4] Bodla, N., Singh, B., Chellappa, R., Davis, L.S.: Soft-NMS — improving object detection with one line of code. In: ICCV (2017)
[5] Cai, Z., Vasconcelos, N.: Cascade R-CNN: High quality object detection and instance segmentation. PAMI (2019)
[6] Chan, W., Saharia, C., Hinton, G., Norouzi, M., Jaitly, N.: Imputer: Sequence modelling via imputation and dynamic programming. arXiv:2002.08926 (2020)
[7] Cordonnier, J.B., Loukas, A., Jaggi, M.: On the relationship between self-attention and convolutional layers. In: ICLR (2020)
[8] Devlin, J., Chang, M.W., Lee, K., Toutanova, K.: BERT: Pre-training of deep bidirectional transformers for language understanding. In: NAACL-HLT (2019)
[9] Erhan, D., Szegedy, C., Toshev, A., Anguelov, D.: Scalable object detection using deep neural networks. In: CVPR (2014)
[10] Ghazvininejad, M., Levy, O., Liu, Y., Zettlemoyer, L.: Mask-predict: Parallel decoding of conditional masked language models. arXiv:1904.09324 (2019)
[11] Glorot, X., Bengio, Y.: Understanding the difficulty of training deep feedforward neural networks. In: AISTATS (2010)
[12] Gu, J., Bradbury, J., Xiong, C., Li, V.O., Socher, R.: Non-autoregressive neural machine translation. In: ICLR (2018)
[13] He, K., Girshick, R., Dollár, P.: Rethinking imagenet pre-training. In: ICCV (2019)
[14] He, K., Gkioxari, G., Dollár, P., Girshick, R.B.: Mask R-CNN. In: ICCV (2017)
[15] He, K., Zhang, X., Ren, S., Sun, J.: Deep residual learning for image recognition. In: CVPR (2016)
[16] Hosang, J.H., Benenson, R., Schiele, B.: Learning non-maximum suppression. In: CVPR (2017)
[17] Hu, H., Gu, J., Zhang, Z., Dai, J., Wei, Y.: Relation networks for object detection. In: CVPR (2018)
[18] Kirillov, A., Girshick, R., He, K., Dollár, P.: Panoptic feature pyramid networks. In: CVPR (2019)
[19] Kirillov, A., He, K., Girshick, R., Rother, C., Dollar, P.: Panoptic segmentation. In: CVPR (2019)
[20] Kuhn, H.W.: The hungarian method for the assignment problem (1955)
[21] Li, Y., Qi, H., Dai, J., Ji, X., Wei, Y.: Fully convolutional instance-aware semantic segmentation. In: CVPR (2017)
[22] Lin, T.Y., Dollár, P., Girshick, R., He, K., Hariharan, B., Belongie, S.: Feature pyramid networks for object detection. In: CVPR (2017)
[23] Lin, T.Y., Goyal, P., Girshick, R.B., He, K., Dollár, P.: Focal loss for dense object detection. In: ICCV (2017)
[24] Lin, T.Y., Maire, M., Belongie, S., Hays, J., Perona, P., Ramanan, D., Dollár, P., Zitnick, C.L.: Microsoft COCO: Common objects in context. In: ECCV (2014)
[25] Liu, W., Anguelov, D., Erhan, D., Szegedy, C., Reed, S.E., Fu, C.Y., Berg, A.C.: Ssd: Single shot multibox detector. In: ECCV (2016)
[26] Loshchilov, I., Hutter, F.: Decoupled weight decay regularization. In: ICLR (2017)
[27] Lüscher, C., Beck, E., Irie, K., Kitza, M., Michel, W., Zeyer, A., Schlüter, R., Ney, H.: Rwth asr systems for librispeech: Hybrid vs attention - w/o data augmentation. arXiv:1905.03072 (2019)
[28] Milletari, F., Navab, N., Ahmadi, S.A.: V-net: Fully convolutional neural networks for volumetric medical image segmentation. In: 3DV (2016)
[29] Oord, A.v.d., Li, Y., Babuschkin, I., Simonyan, K., Vinyals, O., Kavukcuoglu, K., Driessche, G.v.d., Lockhart, E., Cobo, L.C., Stimberg, F., et al.: Parallel wavenet: Fast high-fidelity speech synthesis. arXiv:1711.10433 (2017)
[30] Park, E., Berg, A.C.: Learning to decompose for object detection and instance segmentation. arXiv:1511.06449 (2015)
[31] Parmar, N., Vaswani, A., Uszkoreit, J., Kaiser, L., Shazeer, N., Ku, A., Tran, D.: Image transformer. In: ICML (2018)
[32] Paszke, A., Gross, S., Massa, F., Lerer, A., Bradbury, J., Chanan, G., Killeen, T., Lin, Z., Gimelshein, N., Antiga, L., Desmaison, A., Kopf, A., Yang, E., DeVito, Z., Raison, M., Tejani, A., Chilamkurthy, S., Steiner, B., Fang, L., Bai, J., Chintala, S.: Pytorch: An imperative style, high-performance deep learning library. In: NeurIPS (2019)
[33] Pineda, L., Salvador, A., Drozdzal, M., Romero, A.: Elucidating image-to-set prediction: An analysis of models, losses and datasets. arXiv:1904.05709 (2019)
[34] Radford, A., Wu, J., Child, R., Luan, D., Amodei, D., Sutskever, I.: Language models are unsupervised multitask learners (2019)
[35] Redmon, J., Divvala, S., Girshick, R., Farhadi, A.: You only look once: Unified, real-time object detection. In: CVPR (2016)
[36] Ren, M., Zemel, R.S.: End-to-end instance segmentation with recurrent attention. In: CVPR (2017)
[37] Ren, S., He, K., Girshick, R.B., Sun, J.: Faster R-CNN: Towards real-time object detection with region proposal networks. PAMI (2015)
[38] Rezatofighi, H., Tsoi, N., Gwak, J., Sadeghian, A., Reid, I., Savarese, S.: Generalized intersection over union. In: CVPR (2019)
[39] Rezatofighi, S.H., Kaskman, R., Motlagh, F.T., Shi, Q., Cremers, D., Leal-Taixé, L., Reid, I.: Deep perm-set net: Learn to predict sets with unknown permutation and cardinality using deep neural networks. arXiv:1805.00613 (2018)
[40] Rezatofighi, S.H., Milan, A., Abbasnejad, E., Dick, A., Reid, I., Kaskman, R., Cremers, D., Leal-Taixé, l.: Deepsetnet: Predicting sets with deep neural networks. In: ICCV (2017)
[41] Romera-Paredes, B., Torr, P.H.S.: Recurrent instance segmentation. In: ECCV (2015)
[42] Salvador, A., Bellver, M., Baradad, M., Marqués, F., Torres, J., Giró, X.: Recurrent neural networks for semantic instance segmentation. arXiv:1712.00617 (2017)
[43] Stewart, R.J., Andriluka, M., Ng, A.Y.: End-to-end people detection in crowded scenes. In: CVPR (2015)
[44] Sutskever, I., Vinyals, O., Le, Q.V.: Sequence to sequence learning with neural networks. In: NeurIPS (2014)
[45] Synnaeve, G., Xu, Q., Kahn, J., Grave, E., Likhomanenko, T., Pratap, V., Sriram, A., Liptchinsky, V., Collobert, R.: End-to-end ASR: from supervised to semi-supervised learning with modern architectures. arXiv:1911.08460 (2019)
[46] Tian, Z., Shen, C., Chen, H., He, T.: FCOS: Fully convolutional one-stage object detection. In: ICCV (2019)
[47] Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A.N., Kaiser, L., Polosukhin, I.: Attention is all you need. In: NeurIPS (2017)
[48] Vinyals, O., Bengio, S., Kudlur, M.: Order matters: Sequence to sequence for sets. In: ICLR (2016)
[49] Wang, X., Girshick, R.B., Gupta, A., He, K.: Non-local neural networks. In: CVPR (2018)
[50] Wu, Y., Kirillov, A., Massa, F., Lo, W.Y., Girshick, R.: Detectron2. https://github.com/facebookresearch/detectron2 (2019)
[51] Xiong, Y., Liao, R., Zhao, H., Hu, R., Bai, M., Yumer, E., Urtasun, R.: Upsnet: A unified panoptic segmentation network. In: CVPR (2019)
[52] Zhang, S., Chi, C., Yao, Y., Lei, Z., Li, S.Z.: Bridging the gap between anchor-based and anchor-free detection via adaptive training sample selection. arXiv:1912.02424 (2019)
[53] Zhou, X., Wang, D., Krähenbühl, P.: Objects as points. arXiv:1904.07850 (2019)
Appendix 0.A Appendix
0.A.1 Preliminaries: Multi-head attention layers
Since our model is based on the Transformer architecture, we remind here the general form of attention mechanisms we use for exhaustivity. The attention mechanism follows [47], except for the details of positional encodings (see Equation 8) that follows [7].
由于我们的模型基于 Transformer 架构,这里为完整性回顾所用注意力机制的一般形式。注意力机制遵循 [47],但位置编码细节(见公式 8)遵循 [7]。
Multi-head
The general form of multi-head attention with heads of dimension is a function with the following signature (using , and giving matrix/tensors sizes in underbrace)
Multi-head
带 个维数为 的头的 多头注意力 一般形式是具有如下签名的函数(使用 ,并在花括号下给出矩阵/张量尺寸)
where is the query sequence of length , is the key-value sequence of length (with the same number of channels for simplicity of exposition), is the weight tensor to compute the so-called query, key and value embeddings, and is a projection matrix. The output is the same size as the query sequence. To fix the vocabulary before giving details, multi-head *self-*attention (mh-s-attn) is the special case , i.e.
其中 是长度为 的 query 序列, 是长度为 的 key-value 序列(为表述简便,通道数同为 ), 是计算所谓 query、key、value 嵌入的权重张量, 是投影矩阵。输出与 query 序列同尺寸。在给出细节前固定术语:多头 自注意力(mh-s-attn)是 的特例,即
The multi-head attention is simply the concatenation of single attention heads followed by a projection with . The common practice [47] is to use residual connections, dropout and layer normalization. In other words, denoting and the concatenation of attention heads, we have
多头注意力就是把 个单注意力头拼接后再用 投影。常见做法 [47] 是使用残差连接、dropout 与层归一化。换言之,记 , 为注意力头的拼接,则有
where [;] denotes concatenation on the channel axis.
其中 [;] 表示在通道轴上拼接。
Single head
An attention head with weight tensor , denoted by , depends on additional positional encoding and . It starts by computing so-called query, key and value embeddings after adding the query and key positional encodings [7]:
Single head
带权重张量 的注意力头,记为 ,还依赖额外位置编码 与 。它在加入 query 与 key 的位置编码后开始计算所谓的 query、key、value 嵌入 [7]:
where is the concatenation of . The attention weights are then computed based on the softmax of dot products between queries and keys, so that each element of the query sequence attends to all elements of the key-value sequence ( is a query index and a key-value index):
其中 是 的拼接。注意力权重 随即基于 query 与 key 点积的 softmax 计算,使 query 序列每个元素关注 key-value 序列全部元素( 为 query 下标, 为 key-value 下标):
In our case, the positional encodings may be learnt or fixed, but are shared across all attention layers for a given query/key-value sequence, so we do not explicitly write them as parameters of the attention. We give more details on their exact value when describing the encoder and the decoder. The final output is the aggregation of values weighted by attention weights: The -th row is given by .
在我们的情形中,位置编码可以是可学习或固定的,但对给定 query/key-value 序列在所有注意力层共享,因此我们不把它们显式写成注意力的参数。描述编码器与解码器时会给出其精确取值的更多细节。最终输出是按注意力权重加权的 value 聚合:第 行由 给出。
Feed-forward network (FFN) layers
The original transformer alternates multi-head attention and so-called FFN layers [47], which are effectively multilayer 1x1 convolutions, which have input and output channels in our case. The FFN we consider is composed of two-layers of 1x1 convolutions with ReLU activations. There is also a residual connection/dropout/layernorm after the two layers, similarly to equation 6.
Feed-forward network (FFN) layers
原始 Transformer 交替多头注意力与所谓的 FFN 层 [47],它们实际上是多层 1×1 卷积,在我们的情形中输入输出通道为 。我们考虑的 FFN 由两层带 ReLU 激活的 1×1 卷积组成。两层之后同样有残差连接/dropout/layernorm,类似于公式 6。
0.A.2 Losses
For completeness, we present in detail the losses used in our approach. All losses are normalized by the number of objects inside the batch. Extra care must be taken for distributed training: since each GPU receives a sub-batch, it is not sufficient to normalize by the number of objects in the local batch, since in general the sub-batches are not balanced across GPUs. Instead, it is important to normalize by the total number of objects in all sub-batches.
为完整性,我们详细给出方法所用损失。所有损失按 batch 内物体数归一化。分布式训练需格外小心:由于每个 GPU 收到子 batch,仅按本地 batch 物体数归一化不够,因为子 batch 一般在 GPU 间不平衡。相反,重要的是按所有子 batch 中物体总数归一化。
Box loss
Similarly to [41, 36], we use a soft version of Intersection over Union in our loss, together with a loss on :
Box loss
与 [41, 36] 类似,我们在损失中使用软版交并比,并配合对 的 损失:
where are hyperparameters and is the generalized IoU [38]:
其中 为超参, 为广义 IoU [38]:
means “area”, and the union and intersection of box coordinates are used as shorthands for the boxes themselves. The areas of unions or intersections are computed by of the linear functions of and , which makes the loss sufficiently well-behaved for stochastic gradients. means the largest box containing (the areas involving are also computed based on of linear functions of the box coordinates).
表示“面积”,框坐标的并与交用作框本身的简写。并或交的面积由 与 线性函数的 计算,使损失对随机梯度足够良好。 表示包含 的最大框(涉及 的面积同样基于框坐标线性函数的 计算)。
DICE/F-1 loss [28]
The DICE coefficient is closely related to the Intersection over Union. If we denote by the raw mask logits prediction of the model, and the binary target mask, the loss is defined as:
DICE/F-1 loss [28]
DICE 系数与交并比密切相关。记 为模型的原始掩码 logit 预测, 为二值目标掩码,损失定义为:
where is the sigmoid function. This loss is normalized by the number of objects.
其中 为 sigmoid 函数。该损失按物体数归一化。
0.A.3 Detailed architecture
The detailed description of the transformer used in DETR, with positional encodings passed at every attention layer, is given in Fig. 10. Image features from the CNN backbone are passed through the transformer encoder, together with spatial positional encoding that are added to queries and keys at every multi-head self-attention layer. Then, the decoder receives queries (initially set to zero), output positional encoding (object queries), and encoder memory, and produces the final set of predicted class labels and bounding boxes through multiple multi-head self-attention and decoder-encoder attention. The first self-attention layer in the first decoder layer can be skipped.
DETR 所用 Transformer 的详细描述(位置编码在每个注意力层传入)见图 10。来自 CNN 骨干的图像特征与空间位置编码一起送入 Transformer 编码器;空间位置编码在每个多头自注意力层加到 query 与 key 上。随后,解码器接收 query(初始为零)、输出位置编码(object queries)与编码器 memory,并通过多层多头自注意力与解码器–编码器注意力产生最终的类别标签与边界框预测集合。第一解码器层中的第一个自注意力层可以跳过。
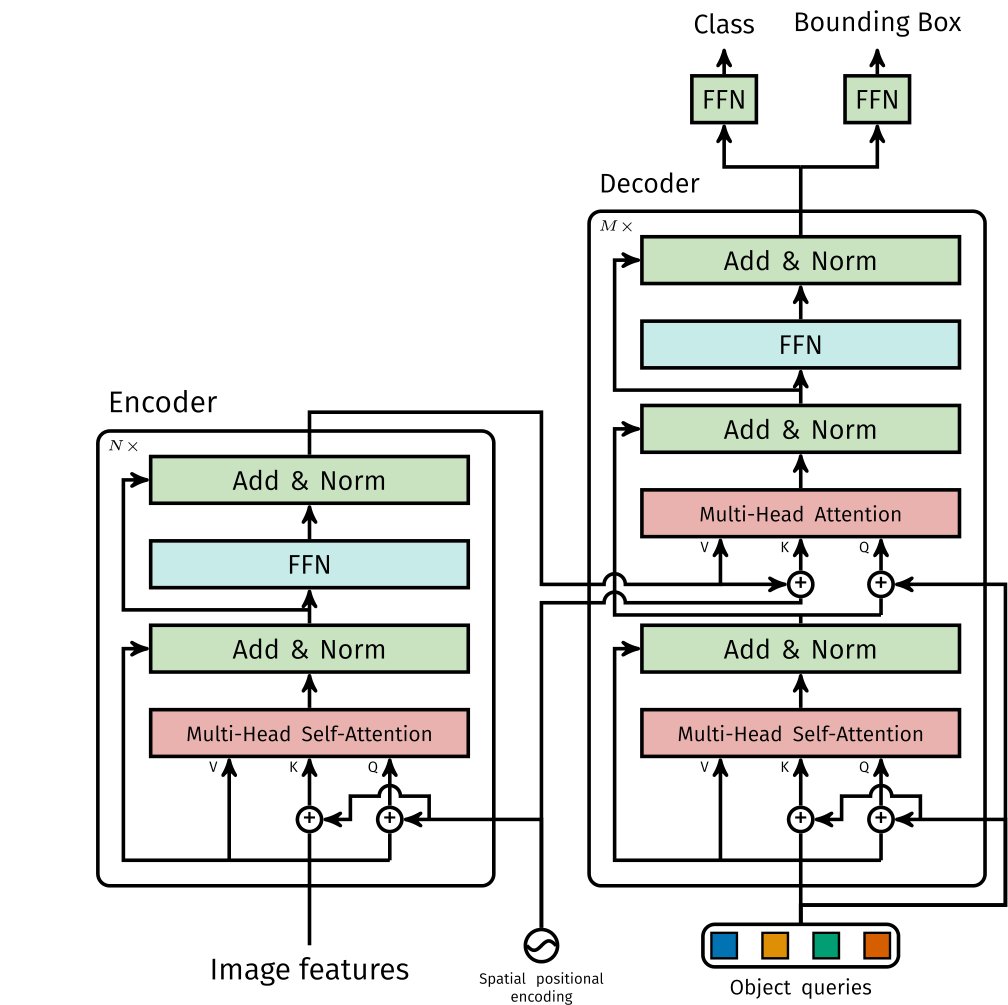
Figure 10: Architecture of DETR’s transformer. Please, see Section 0.A.3 for details.
图 10:DETR 的 Transformer 架构。细节见第 0.A.3 节。
Computational complexity
Every self-attention in the encoder has complexity : is the cost of computing a single query/key/value embeddings (and ), while is the cost of computing the attention weights for one head. Other computations are negligible. In the decoder, each self-attention is in , and cross-attention between encoder and decoder is in , which is much lower than the encoder since in practice.
Computational complexity
编码器中每个自注意力复杂度为 : 是计算单个 query/key/value 嵌入的代价(且 ),而 是为一个头计算注意力权重的代价。其他计算可忽略。在解码器中,每个自注意力为 ,编码器与解码器之间的交叉注意力为 ,由于实践中 ,这远低于编码器。
FLOPS computation
Given that the FLOPS for Faster R-CNN depends on the number of proposals in the image, we report the average number of FLOPS for the first 100 images in the COCO 2017 validation set. We compute the FLOPS with the tool flop_count_operators from Detectron2 [50]. We use it without modifications for Detectron2 models, and extend it to take batch matrix multiply (bmm) into account for DETR models.
FLOPS computation
鉴于 Faster R-CNN 的 FLOPS 依赖图像中 proposal 数量,我们报告 COCO 2017 验证集前 100 张图像的平均 FLOPS。用 Detectron2 [50] 的 flop_count_operators 工具计算。对 Detectron2 模型不做修改;对 DETR 模型扩展该工具以计入批矩阵乘(bmm)。
0.A.4 Training hyperparameters
We train DETR using AdamW [26] with improved weight decay handling, set to . We also apply gradient clipping, with a maximal gradient norm of . The backbone and the transformers are treated slightly differently, we now discuss the details for both.
我们用改进权重衰减处理的 AdamW [26] 训练 DETR,权重衰减设为 。还施加梯度裁剪,最大梯度范数为 。骨干与 Transformer 的处理略有不同,下文分别讨论细节。
Backbone
ImageNet pretrained backbone ResNet-50 is imported from Torchvision, discarding the last classification layer. Backbone batch normalization weights and statistics are frozen during training, following widely adopted practice in object detection. We fine-tune the backbone using learning rate of . We observe that having the backbone learning rate roughly an order of magnitude smaller than the rest of the network is important to stabilize training, especially in the first few epochs.
Backbone
从 Torchvision 导入 ImageNet 预训练的 ResNet-50 骨干,去掉最后分类层。训练时冻结骨干 batch normalization 权重与统计量,遵循目标检测中广泛采用的做法。我们以 学习率微调骨干。观察到骨干学习率大致比网络其余部分低一个数量级对稳定训练很重要,尤其在最初几个 epoch。
Transformer
We train the transformer with a learning rate of . Additive dropout of is applied after every multi-head attention and FFN before layer normalization. The weights are randomly initialized with Xavier initialization.
Transformer
我们以 学习率训练 Transformer。在每个多头注意力与 FFN 之后、层归一化之前施加 0.1 的加性 dropout。权重用 Xavier 初始化随机初始化。
Losses
We use linear combination of and GIoU losses for bounding box regression with and weights respectively. All models were trained with decoder query slots.
Losses
边界框回归使用 与 GIoU 损失的线性组合,权重分别为 与 。所有模型以 个解码器 query 槽位训练。
Baseline
Our enhanced Faster-RCNN+ baselines use GIoU [38] loss along with the standard loss for bounding box regression. We performed a grid search to find the best weights for the losses and the final models use only GIoU loss with weights and for box and proposal regression tasks respectively. For the baselines we adopt the same data augmentation as used in DETR and train it with 9 schedule (approximately 109 epochs). All other settings are identical to the same models in the Detectron2 model zoo [50].
Baseline
我们增强的 Faster-RCNN+ 基线在边界框回归上同时使用 GIoU [38] 损失与标准 损失。我们做网格搜索找最佳损失权重,最终模型只使用 GIoU 损失,框与 proposal 回归任务权重分别为 20 与 1。对基线我们采用与 DETR 相同的数据增强,并以 9 日程训练(约 109 epoch)。所有其他设定与 Detectron2 model zoo [50] 中同名模型相同。
Spatial positional encoding
Encoder activations are associated with corresponding spatial positions of image features. In our model we use a fixed absolute encoding to represent these spatial positions. We adopt a generalization of the original Transformer [47] encoding to the 2D case [31]. Specifically, for both spatial coordinates of each embedding we independently use sine and cosine functions with different frequencies. We then concatenate them to get the final channel positional encoding.
Spatial positional encoding
编码器激活与图像特征对应的空间位置相关联。在我们的模型中,用固定绝对编码表示这些空间位置。我们采用把原始 Transformer [47] 编码推广到 2D 情形的做法 [31]。具体地,对每个嵌入的两个空间坐标,各自独立使用频率不同的 个正弦与余弦函数,再拼接得到最终 通道位置编码。
0.A.5 Additional results
Some extra qualitative results for the panoptic prediction of the DETR-R101 model are shown in Fig.11.
DETR-R101 模型全景预测的一些额外定性结果见图 11。
(a) Failure case with overlapping objects. PanopticFPN misses one plane entirely, while DETR fails to accurately segment 3 of them.
(a) 重叠物体的失败案例。PanopticFPN 完全漏掉一架飞机,而 DETR 未能准确分割其中 3 架。
Increasing the number of instances
Figure 12: Analysis of the number of instances of various classes missed by DETR depending on how many are present in the image. We report the mean and the standard deviation. As the number of instances gets close to 100, DETR starts saturating and misses more and more objects
Increasing the number of instances
图 12:按图像中某类实例数量,分析 DETR 漏检各类实例数。报告均值与标准差。当实例数接近 100 时,DETR 开始饱和并漏检越来越多物体。
By design, DETR cannot predict more objects than it has query slots, i.e. 100 in our experiments. In this section, we analyze the behavior of DETR when approaching this limit. We select a canonical square image of a given class, repeat it on a grid, and compute the percentage of instances that are missed by the model. To test the model with less than 100 instances, we randomly mask some of the cells. This ensures that the absolute size of the objects is the same no matter how many are visible. To account for the randomness in the masking, we repeat the experiment 100 times with different masks. The results are shown in Fig.12. The behavior is similar across classes, and while the model detects all instances when up to 50 are visible, it then starts saturating and misses more and more instances. Notably, when the image contains all 100 instances, the model only detects 30 on average, which is less than if the image contains only 50 instances that are all detected. The counter-intuitive behavior of the model is likely because the images and the detections are far from the training distribution.
按设计,DETR 不能预测超过其 query 槽位数的物体,我们实验中为 100。本节分析接近该上限时 DETR 的行为。我们选取给定类别的标准正方形图像,在 网格上重复,并计算模型漏检实例的百分比。为测试少于 100 个实例,我们随机掩蔽部分格子。这确保无论可见多少个,物体的绝对尺寸相同。为计入掩蔽随机性,用不同掩码重复实验 100 次。结果见图 12。跨类别行为相似:可见最多约 50 个时模型检测到全部实例,随后开始饱和并漏检越来越多。值得注意的是,当图像含全部 100 个实例时,模型平均只检测到 30 个,少于仅含 50 个且全部被检出的情形。这一反直觉行为很可能因为图像与检测远离训练分布。
Note that this test is a test of generalization out-of-distribution by design, since there are very few example images with a lot of instances of a single class. It is difficult to disentangle, from the experiment, two types of out-of-domain generalization: the image itself vs the number of object per class. But since few to no COCO images contain only a lot of objects of the same class, this type of experiment represents our best effort to understand whether query objects overfit the label and position distribution of the dataset. Overall, the experiments suggests that the model does not overfit on these distributions since it yields near-perfect detections up to 50 objects.
注意:该测试按设计是分布外泛化测试,因为单类大量实例的示例图像极少。很难从实验中解耦两类域外泛化:图像本身 vs 每类物体数量。但由于极少或没有 COCO 图像只含大量同类物体,这类实验是我们理解 query 是否过拟合数据集标签与位置分布的最佳努力。总体而言,实验表明模型未过拟合这些分布,因为直到 50 个物体它仍给出近乎完美的检测。
0.A.6 PyTorch inference code
To demonstrate the simplicity of the approach, we include inference code with PyTorch and Torchvision libraries in Listing 13. The code runs with Python 3.6+, PyTorch 1.4 and Torchvision 0.5. Note that it does not support batching, hence it is suitable only for inference or training with DistributedDataParallel with one image per GPU. Also note that for clarity, this code uses learnt positional encodings in the encoder instead of fixed, and positional encodings are added to the input only instead of at each transformer layer. Making these changes requires going beyond PyTorch implementation of transformers, which hampers readability. The entire code to reproduce the experiments will be made available before the conference.
为展示方法的简洁性,我们在 Listing 13 中给出使用 PyTorch 与 Torchvision 库的推理代码。代码可在 Python 3.6+、PyTorch 1.4 与 Torchvision 0.5 上运行。注意它不支持批处理,因而只适于推理,或每 GPU 一张图的 DistributedDataParallel 训练。另请注意:为清晰起见,该代码在编码器中使用可学习位置编码而非固定编码,并且位置编码只加到输入上而非每个 Transformer 层。做这些改动需要超出 PyTorch 自带 Transformer 实现,有损可读性。复现实验的完整代码将在会前公开。
import torch
from torch import nn
from torchvision.models import resnet50
class DETR(nn.Module):
def init(self, num_classes, hidden_dim, nheads,
num_encoder_layers, num_decoder_layers):
super().init()
We take only convolutional layers from ResNet-50 model
self.backbone = nn.Sequential(*list(resnet50(pretrained=True).children())[:-2])
self.conv = nn.Conv2d(2048, hidden_dim, 1)
self.transformer = nn.Transformer(hidden_dim, nheads,
num_encoder_layers, num_decoder_layers)
self.linear_class = nn.Linear(hidden_dim, num_classes + 1)
self.linear_bbox = nn.Linear(hidden_dim, 4)
self.query_pos = nn.Parameter(torch.rand(100, hidden_dim))
self.row_embed = nn.Parameter(torch.rand(50, hidden_dim // 2))
self.col_embed = nn.Parameter(torch.rand(50, hidden_dim // 2))
def forward(self, inputs):
x = self.backbone(inputs)
h = self.conv(x)
H, W = h.shape[-2:]
pos = torch.cat([
self.col_embed[:W].unsqueeze(0).repeat(H, 1, 1),
self.row_embed[:H].unsqueeze(1).repeat(1, W, 1),
], dim=-1).flatten(0, 1).unsqueeze(1)
h = self.transformer(pos + h.flatten(2).permute(2, 0, 1),
self.query_pos.unsqueeze(1))
return self.linear_class(h), self.linear_bbox(h).sigmoid()
detr = DETR(num_classes=91, hidden_dim=256, nheads=8, num_encoder_layers=6, num_decoder_layers=6)
detr.eval()
inputs = torch.randn(1, 3, 800, 1200)
logits, bboxes = detr(inputs)
Figure 13: DETR PyTorch inference code. For clarity it uses learnt positional encodings in the encoder instead of fixed, and positional encodings are added to the input only instead of at each transformer layer. Making these changes requires going beyond PyTorch implementation of transformers, which hampers readability. The entire code to reproduce the experiments will be made available before the conference.
import torch
from torch import nn
from torchvision.models import resnet50
class DETR(nn.Module):
def init(self, num_classes, hidden_dim, nheads,
num_encoder_layers, num_decoder_layers):
super().init()
We take only convolutional layers from ResNet-50 model
self.backbone = nn.Sequential(*list(resnet50(pretrained=True).children())[:-2])
self.conv = nn.Conv2d(2048, hidden_dim, 1)
self.transformer = nn.Transformer(hidden_dim, nheads,
num_encoder_layers, num_decoder_layers)
self.linear_class = nn.Linear(hidden_dim, num_classes + 1)
self.linear_bbox = nn.Linear(hidden_dim, 4)
self.query_pos = nn.Parameter(torch.rand(100, hidden_dim))
self.row_embed = nn.Parameter(torch.rand(50, hidden_dim // 2))
self.col_embed = nn.Parameter(torch.rand(50, hidden_dim // 2))
def forward(self, inputs):
x = self.backbone(inputs)
h = self.conv(x)
H, W = h.shape[-2:]
pos = torch.cat([
self.col_embed[:W].unsqueeze(0).repeat(H, 1, 1),
self.row_embed[:H].unsqueeze(1).repeat(1, W, 1),
], dim=-1).flatten(0, 1).unsqueeze(1)
h = self.transformer(pos + h.flatten(2).permute(2, 0, 1),
self.query_pos.unsqueeze(1))
return self.linear_class(h), self.linear_bbox(h).sigmoid()
detr = DETR(num_classes=91, hidden_dim=256, nheads=8, num_encoder_layers=6, num_decoder_layers=6)
detr.eval()
inputs = torch.randn(1, 3, 800, 1200)
logits, bboxes = detr(inputs)
图 13:DETR 的 PyTorch 推理代码。为清晰起见,编码器使用可学习位置编码而非固定编码,且位置编码只加到输入上而非每个 Transformer 层。做这些改动需要超出 PyTorch 自带 Transformer 实现,有损可读性。复现实验的完整代码将在会前公开。