Dense Passage Retrieval for Open-Domain Question Answering
Dense Passage Retrieval for Open-Domain Question Answering
面向开放域问答的稠密段落检索
Vladimir Karpukhin Thanks: Equal contribution Barlas Oğuz † † footnotemark: Sewon Min Affiliation: University of Washington Patrick Lewis Ledell Wu Sergey Edunov Danqi Chen Affiliation: Princeton University {vladk, barlaso, plewis, ledell, edunov, scottyih}@fb.comsewon@cs.washington.edudanqic@cs.princeton.edu Wen-tau Yih Facebook AI
Abstract
摘要
Open-domain question answering relies on efficient passage retrieval to select candidate contexts, where traditional sparse vector space models, such as TF-IDF or BM25, are the de facto method. In this work, we show that retrieval can be practically implemented using dense representations alone, where embeddings are learned from a small number of questions and passages by a simple dual-encoder framework. When evaluated on a wide range of open-domain QA datasets, our dense retriever outperforms a strong Lucene-BM25 system greatly by 9%-19% absolute in terms of top-20 passage retrieval accuracy, and helps our end-to-end QA system establish new state-of-the-art on multiple open-domain QA benchmarks.[^1]
开放域问答依赖高效的段落检索来挑选候选上下文,传统的稀疏向量空间模型(如 TF-IDF 或 BM25)一直是事实上的标准方法。本文表明,检索可以只靠稠密表示来实际完成:用一个简单的双编码器框架,从数量不多的问题与段落中学习嵌入。在一系列开放域问答数据集上,我们的稠密检索器在 top-20 段落检索准确率上大幅超过较强的 Lucene-BM25 系统,绝对提升达 9%–19%,并帮助端到端问答系统在多个开放域问答基准上取得当时最好的结果。[^1]
1 Introduction
1 引言
Open-domain question answering (QA) Voorhees 1999 is a task that answers factoid questions using a large collection of documents. While early QA systems are often complicated and consist of multiple components (Ferrucci 2012; Moldovan et al. 2003, inter alia), the advances of reading comprehension models suggest a much simplified two-stage framework: (1) a context retriever first selects a small subset of passages where some of them contain the answer to the question, and then (2) a machine reader can thoroughly examine the retrieved contexts and identify the correct answer Chen et al. 2017. Although reducing open-domain QA to machine reading is a very reasonable strategy, a huge performance degradation is often observed in practice[^2], indicating the needs of improving retrieval.
开放域问答(QA)Voorhees 1999 的任务是:利用大规模文档集合来回答事实型问题。早期的问答系统往往很复杂,由多个组件构成(Ferrucci 2012;Moldovan et al. 2003,以及其他工作);阅读理解模型的进展则提示了一种大为简化的两阶段框架:(1) 上下文检索器先选出一小部分段落,其中有些包含问题的答案,然后 (2) 机器阅读器再仔细检查这些检索到的上下文并找出正确答案 Chen et al. 2017。把开放域问答归结为机器阅读固然合理,但实践中常常会看到性能大幅下降[^2],这说明检索这一环仍需改进。
Retrieval in open-domain QA is usually implemented using TF-IDF or BM25 Robertson and Zaragoza 2009, which matches keywords efficiently with an inverted index and can be seen as representing the question and context in high-dimensional, sparse vectors (with weighting). Conversely, the dense, latent semantic encoding is complementary to sparse representations by design. For example, synonyms or paraphrases that consist of completely different tokens may still be mapped to vectors close to each other. Consider the question “Who is the bad guy in lord of the rings?”, which can be answered from the context “Sala Baker is best known for portraying the villain Sauron in the Lord of the Rings trilogy.” A term-based system would have difficulty retrieving such a context, while a dense retrieval system would be able to better match “bad guy” with “villain” and fetch the correct context. Dense encodings are also learnable by adjusting the embedding functions, which provides additional flexibility to have a task-specific representation. With special in-memory data structures and indexing schemes, retrieval can be done efficiently using maximum inner product search (MIPS) algorithms (e.g., Shrivastava and Li 2014; Guo et al. 2016).
开放域问答中的检索通常用 TF-IDF 或 BM25 Robertson and Zaragoza 2009 实现:借助倒排索引高效匹配关键词,也可以看成把问题和上下文表示成高维稀疏向量(带权重)。与此相对,稠密的潜在语义编码在设计上与稀疏表示互补。例如,由完全不同记号组成的同义词或改述,仍可能被映射到彼此靠近的向量。考虑问题“Who is the bad guy in lord of the rings?”,它可以从上下文“Sala Baker is best known for portraying the villain Sauron in the Lord of the Rings trilogy.”中得到答案。基于词项的系统很难检索到这样的上下文,而稠密检索系统能更好地把“bad guy”与“villain”对应起来并取回正确上下文。稠密编码还可以通过调整嵌入函数来学习,从而为特定任务提供更灵活的表示。借助专用的内存数据结构和索引方案,检索可以用最大内积搜索(MIPS)算法高效完成(例如 Shrivastava and Li 2014;Guo et al. 2016)。
However, it is generally believed that learning a good dense vector representation needs a large number of labeled pairs of question and contexts. Dense retrieval methods have thus never be shown to outperform TF-IDF/BM25 for open-domain QA before ORQA Lee et al. 2019, which proposes a sophisticated inverse cloze task (ICT) objective, predicting the blocks that contain the masked sentence, for additional pretraining. The question encoder and the reader model are then fine-tuned using pairs of questions and answers jointly. Although ORQA successfully demonstrates that dense retrieval can outperform BM25, setting new state-of-the-art results on multiple open-domain QA datasets, it also suffers from two weaknesses. First, ICT pretraining is computationally intensive and it is not completely clear that regular sentences are good surrogates of questions in the objective function. Second, because the context encoder is not fine-tuned using pairs of questions and answers, the corresponding representations could be suboptimal.
不过,一般认为要学到好的稠密向量表示,需要大量带标注的问题–上下文对。因此在 ORQA Lee et al. 2019 之前,稠密检索方法从未在开放域问答上被证明能超过 TF-IDF/BM25。ORQA 提出了一种复杂的逆完型填空(inverse cloze task,ICT)目标,预测包含被遮盖句子的文本块,用于额外预训练;随后再用问题–答案对联合微调问题编码器和阅读器。ORQA 成功地表明稠密检索可以超过 BM25,并在多个开放域问答数据集上刷新了当时最好的结果,但它也有两点不足。第一,ICT 预训练计算代价很高,而且在目标函数里用普通句子充当问题的替代是否合适,并不完全清楚。第二,上下文编码器没有用问题–答案对再做微调,相应表示可能并非最优。
In this paper, we address the question: can we train a better dense embedding model using only pairs of questions and passages (or answers), without additional pretraining? By leveraging the now standard BERT pretrained model Devlin et al. 2019 and a dual-encoder architecture Bromley et al. 1994, we focus on developing the right training scheme using a relatively small number of question and passage pairs. Through a series of careful ablation studies, our final solution is surprisingly simple: the embedding is optimized for maximizing inner products of the question and relevant passage vectors, with an objective comparing all pairs of questions and passages in a batch. Our Dense Passage Retriever (DPR) is exceptionally strong. It not only outperforms BM25 by a large margin (65.2% vs. 42.9% in Top-5 accuracy), but also results in a substantial improvement on the end-to-end QA accuracy compared to ORQA (41.5% vs. 33.3%) in the open Natural Questions setting Lee et al. 2019; Kwiatkowski et al. 2019.
本文要回答的问题是:我们能否只利用问题与段落(或答案)对,在不做额外预训练的情况下,训练出更好的稠密嵌入模型?借助现已通行的 BERT 预训练模型 Devlin et al. 2019 以及双编码器结构 Bromley et al. 1994,我们把重点放在用相对少量的问题–段落对设计正确的训练方案。经过一系列细致的消融实验,最终方案出人意料地简单:嵌入的优化目标是最大化问题向量与相关段落向量的内积,并在一个批次内比较所有问题–段落对。我们的稠密段落检索器(Dense Passage Retriever,DPR)非常强:它不仅在 Top-5 准确率上大幅超过 BM25(65.2% 对 42.9%),而且在开放 Natural Questions 设定下 Lee et al. 2019;Kwiatkowski et al. 2019,把端到端问答准确率从 ORQA 的 33.3% 提升到 41.5%。
Our contributions are twofold. First, we demonstrate that with the proper training setup, simply fine-tuning the question and passage encoders on existing question-passage pairs is sufficient to greatly outperform BM25. Our empirical results also suggest that additional pretraining may not be needed. Second, we verify that, in the context of open-domain question answering, a higher retrieval precision indeed translates to a higher end-to-end QA accuracy. By applying a modern reader model to the top retrieved passages, we achieve comparable or better results on multiple QA datasets in the open-retrieval setting, compared to several, much complicated systems.
本文贡献有两点。第一,我们表明,只要训练设置得当,仅在已有的问题–段落对上微调问题编码器和段落编码器,就足以大幅超过 BM25。实验结果也提示,额外的预训练未必必要。第二,我们验证了:在开放域问答中,更高的检索精度确实会转化为更高的端到端问答准确率。把现代阅读器接到检索出的前列段落上,我们在开放检索设定下的多个问答数据集上取得了与若干更为复杂的系统相当或更好的结果。
2 Background
2 背景
The problem of open-domain QA studied in this paper can be described as follows. Given a factoid question, such as “Who first voiced Meg on Family Guy?” or “Where was the 8th Dalai Lama born?”, a system is required to answer it using a large corpus of diversified topics. More specifically, we assume the extractive QA setting, in which the answer is restricted to a span appearing in one or more passages in the corpus. Assume that our collection contains documents, . We first split each of the documents into text passages of equal lengths as the basic retrieval units[^3] and get total passages in our corpus , where each passage can be viewed as a sequence of tokens . Given a question , the task is to find a span from one of the passages that can answer the question. Notice that to cover a wide variety of domains, the corpus size can easily range from millions of documents (e.g., Wikipedia) to billions (e.g., the Web). As a result, any open-domain QA system needs to include an efficient retriever component that can select a small set of relevant texts, before applying the reader to extract the answer Chen et al. 2017.[^4] Formally speaking, a retriever is a function that takes as input a question and a corpus and returns a much smaller filter set of texts , where . For a fixed , a retriever can be evaluated in isolation on top-k retrieval accuracy, which is the fraction of questions for which contains a span that answers the question.
本文研究的开放域问答可以这样描述。给定一个事实型问题,例如“Who first voiced Meg on Family Guy?”或“Where was the 8th Dalai Lama born?”,系统需要利用主题多样的大规模语料来作答。更具体地说,我们采用抽取式问答设定:答案必须是语料中某个或某些段落里出现的一个片段。假设集合中有 篇文档 。我们先把每篇文档切成等长的文本段落作为基本检索单元[^3],得到语料 中共 个段落,每个段落 可看成记号序列 。给定问题 ,任务是从某个段落 中找出能够回答该问题的片段 。要注意,为了覆盖广泛领域,语料规模很容易从数百万篇文档(如 Wikipedia)到数十亿篇(如整个 Web)。因此,任何开放域问答系统都需要一个高效的检索组件,先选出一小部分相关文本,再让阅读器抽取答案 Chen et al. 2017。[^4] 形式上,检索器 是一个函数,输入问题 和语料 ,返回小得多的过滤集合 ,其中 。对固定的 ,可以单独用 top- 检索准确率评价检索器,即 中包含能回答该问题的片段的问题所占比例。
3 Dense Passage Retriever (DPR)
3 稠密段落检索器(DPR)
We focus our research in this work on improving the retrieval component in open-domain QA. Given a collection of text passages, the goal of our dense passage retriever (DPR) is to index all the passages in a low-dimensional and continuous space, such that it can retrieve efficiently the top passages relevant to the input question for the reader at run-time. Note that can be very large (e.g., 21 million passages in our experiments, described in Section 4.1) and is usually small, such as –.
本工作的研究重点是改进开放域问答中的检索组件。给定 个文本段落的集合,稠密段落检索器(DPR)的目标是把所有段落索引到一个低维连续空间中,从而在运行时能为阅读器高效检索出与输入问题最相关的前 个段落。注意 可以非常大(例如我们实验中有 2100 万个段落,见第 4.1 节),而 通常较小,如 –。
3.1 Overview
3.1 概览
Our dense passage retriever (DPR) uses a dense encoder which maps any text passage to a -dimensional real-valued vectors and builds an index for all the passages that we will use for retrieval. At run-time, DPR applies a different encoder that maps the input question to a -dimensional vector, and retrieves passages of which vectors are the closest to the question vector. We define the similarity between the question and the passage using the dot product of their vectors:
我们的稠密段落检索器(DPR)使用稠密编码器 ,把任意文本段落映射为 维实值向量,并为检索所用的全部 个段落建立索引。运行时,DPR 用另一个编码器 把输入问题映射为 维向量,再检索出向量与问题向量最接近的 个段落。我们用向量点积定义问题与段落的相似度:
Although more expressive model forms for measuring the similarity between a question and a passage do exist, such as networks consisting of multiple layers of cross attentions, the similarity function needs to be decomposable so that the representations of the collection of passages can be pre-computed. Most decomposable similarity functions are some transformations of Euclidean distance (L2). For instance, cosine is equivalent to inner product for unit vectors and the Mahalanobis distance is equivalent to L2 distance in a transformed space. Inner product search has been widely used and studied, as well as its connection to cosine similarity and L2 distance Mussmann and Ermon 2016; Ram and Gray 2012. As our ablation study finds other similarity functions perform comparably (Section 5.2; Appendix B), we thus choose the simpler inner product function and improve the dense passage retriever by learning better encoders.
尽管也存在表达能力更强的问题–段落相似度模型,例如由多层交叉注意力构成的网络,但相似度函数必须是可分解的,才能预先计算整段语料的表示。大多数可分解的相似度函数都是欧氏距离(L2)的某种变换。例如,对单位向量而言余弦等价于内积,马氏距离则等价于变换空间中的 L2 距离。内积搜索已被广泛使用和研究,它与余弦相似度和 L2 距离的关系也已有讨论 Mussmann and Ermon 2016;Ram and Gray 2012。消融实验发现其他相似度函数表现相当(第 5.2 节;附录 B),因此我们选择更简单的内积,并通过学习更好的编码器来改进稠密段落检索器。
Encoders
Although in principle the question and passage encoders can be implemented by any neural networks, in this work we use two independent BERT Devlin et al. 2019 networks (base, uncased) and take the representation at the [CLS] token as the output, so .
编码器
原则上问题和段落编码器可以用任何神经网络实现,本文使用两个独立的 BERT Devlin et al. 2019 网络(base,uncased),并把 [CLS] 记号处的表示当作输出,因此 。
Inference
During inference time, we apply the passage encoder to all the passages and index them using FAISS Johnson et al. 2017 offline. FAISS is an extremely efficient, open-source library for similarity search and clustering of dense vectors, which can easily be applied to billions of vectors. Given a question at run-time, we derive its embedding and retrieve the top passages with embeddings closest to .
推断
推断时,我们用段落编码器 处理所有段落,并离线用 FAISS Johnson et al. 2017 建立索引。FAISS 是一个极为高效的开源库,用于稠密向量的相似搜索与聚类,可以轻松应用到数十亿向量。运行时给定问题 ,我们计算其嵌入 ,并检索嵌入与 最接近的前 个段落。
3.2 Training
3.2 训练
Training the encoders so that the dot-product similarity (Eq. (1)) becomes a good ranking function for retrieval is essentially a metric learning problem Kulis 2013. The goal is to create a vector space such that relevant pairs of questions and passages will have smaller distance (i.e., higher similarity) than the irrelevant ones, by learning a better embedding function.
训练编码器,使点积相似度(公式 (1))成为良好的检索排序函数,本质上是一个度量学习问题 Kulis 2013。目标是通过学习更好的嵌入函数,构造一个向量空间,使相关的问题–段落对比不相关的对距离更小(也就是相似度更高)。
Let be the training data that consists of instances. Each instance contains one question and one relevant (positive) passage , along with irrelevant (negative) passages . We optimize the loss function as the negative log likelihood of the positive passage:
设 是由 个实例组成的训练数据。每个实例包含一个问题 、一个相关(正)段落 ,以及 个不相关(负)段落 。我们把损失函数优化为正段落的负对数似然:
Positive and negative passages
For retrieval problems, it is often the case that positive examples are available explicitly, while negative examples need to be selected from an extremely large pool. For instance, passages relevant to a question may be given in a QA dataset, or can be found using the answer. All other passages in the collection, while not specified explicitly, can be viewed as irrelevant by default. In practice, how to select negative examples is often overlooked but could be decisive for learning a high-quality encoder. We consider three different types of negatives: (1) Random: any random passage from the corpus; (2) BM25: top passages returned by BM25 which don’t contain the answer but match most question tokens; (3) Gold: positive passages paired with other questions which appear in the training set. We will discuss the impact of different types of negative passages and training schemes in Section 5.2. Our best model uses gold passages from the same mini-batch and one BM25 negative passage. In particular, re-using gold passages from the same batch as negatives can make the computation efficient while achieving great performance. We discuss this approach below.
正段落与负段落
对检索问题来说,正例往往可以直接获得,负例却需要从一个极大的池子里挑选。例如,与问题相关的段落可能已经在问答数据集里给出,也可以借助答案找到。集合中所有其他段落虽然没有被显式标出,默认都可以看成不相关。实践中,如何选择负例常常被忽视,但对学到高质量编码器可能起决定作用。我们考虑三类负例:(1) 随机:从语料中任意抽取的段落;(2) BM25:BM25 返回的前列段落,其中不含答案,但匹配了最多的问题记号;(3) 黄金:训练集中其他问题所配对的正段落。我们将在第 5.2 节讨论不同类型负段落和训练方案的影响。我们最好的模型使用同一小批次中的黄金段落,外加一个 BM25 负段落。尤其是,把同一批次里的黄金段落当作负例来复用,既能提高计算效率,又能取得很好的效果。下面讨论这一做法。
In-batch negatives
Assume that we have questions in a mini-batch and each one is associated with a relevant passage. Let and be the matrix of question and passage embeddings in a batch of size . is a matrix of similarity scores, where each row of which corresponds to a question, paired with passages. In this way, we reuse computation and effectively train on (, ) question/passage pairs in each batch. Any (, ) pair is a positive example when , and negative otherwise. This creates training instances in each batch, where there are negative passages for each question.
批内负例
假设一个小批次里有 个问题,每个问题都配有一个相关段落。令 和 为大小 的批次中问题和段落嵌入组成的 矩阵。 是 的相似度分数矩阵,每一行对应一个问题与 个段落的配对。这样我们复用了计算,并在每个批次里实际上对 个 问题/段落对做了训练。当 时 是正例,否则是负例。于是每个批次产生 个训练实例,每个问题对应 个负段落。
The trick of in-batch negatives has been used in the full batch setting Yih et al. 2011 and more recently for mini-batch Henderson et al. 2017; Gillick et al. 2019. It has been shown to be an effective strategy for learning a dual-encoder model that boosts the number of training examples.
批内负例这一技巧曾用于全批次设定 Yih et al. 2011,最近也被用于小批次 Henderson et al. 2017;Gillick et al. 2019。事实表明,它是学习双编码器模型、扩大训练例数量的有效策略。
4 Experimental Setup
4 实验设置
In this section, we describe the data we used for experiments and the basic setup.
本节介绍实验所用的数据以及基本设置。
4.1 Wikipedia Data Pre-processing
4.1 Wikipedia 数据预处理
Following Lee et al. 2019, we use the English Wikipedia dump from Dec. 20, 2018 as the source documents for answering questions. We first apply the pre-processing code released in DrQA Chen et al. 2017 to extract the clean, text-portion of articles from the Wikipedia dump. This step removes semi-structured data, such as tables, info-boxes, lists, as well as the disambiguation pages. We then split each article into multiple, disjoint text blocks of 100 words as passages, serving as our basic retrieval units, following Wang et al. 2019, which results in 21,015,324 passages in the end.[^5] Each passage is also prepended with the title of the Wikipedia article where the passage is from, along with an [SEP] token.
沿用 Lee et al. 2019,我们用 2018 年 12 月 20 日的英文 Wikipedia 转储作为回答问题的源文档。首先用 DrQA Chen et al. 2017 发布的预处理代码,从转储中抽出文章里干净的文本部分。这一步去掉半结构化数据,如表格、信息框、列表,以及消歧义页面。然后按 Wang et al. 2019,把每篇文章切成多个互不重叠、各约 100 词的文本块作为段落,作为基本检索单元,最终得到 21,015,324 个段落。[^5] 每个段落前还会加上该段落所属 Wikipedia 文章的标题,并以一个 [SEP] 记号分隔。
4.2 Question Answering Datasets
4.2 问答数据集
We use the same five QA datasets and training/dev/testing splitting method as in previous work Lee et al. 2019. Below we briefly describe each dataset and refer readers to their paper for the details of data preparation.
我们使用与先前工作 Lee et al. 2019 相同的五个问答数据集,以及相同的训练/开发/测试划分方法。下面简要介绍各数据集,数据准备细节请读者参阅他们的论文。
Natural Questions (NQ) Kwiatkowski et al. 2019 was designed for end-to-end question answering. The questions were mined from real Google search queries and the answers were spans in Wikipedia articles identified by annotators.
Natural Questions (NQ) Kwiatkowski et al. 2019 是为端到端问答设计的。问题来自真实的 Google 搜索查询,答案是标注者在 Wikipedia 文章中标出的片段。
TriviaQA Joshi et al. 2017 contains a set of trivia questions with answers that were originally scraped from the Web.
TriviaQA Joshi et al. 2017 包含一组最初从网上抓取的竞猜问题及其答案。
WebQuestions (WQ) Berant et al. 2013 consists of questions selected using Google Suggest API, where the answers are entities in Freebase.
WebQuestions (WQ) Berant et al. 2013 的问题用 Google Suggest API 选出,答案是 Freebase 中的实体。
CuratedTREC (TREC) Baudiš and Šedivỳ 2015 sources questions from TREC QA tracks as well as various Web sources and is intended for open-domain QA from unstructured corpora.
CuratedTREC (TREC) Baudiš and Šedivỳ 2015 的问题来自 TREC QA 赛道以及多种网络来源,面向从非结构化语料中做开放域问答。
SQuAD v1.1 Rajpurkar et al. 2016 is a popular benchmark dataset for reading comprehension. Annotators were presented with a Wikipedia paragraph, and asked to write questions that could be answered from the given text. Although SQuAD has been used previously for open-domain QA research, it is not ideal because many questions lack context in absence of the provided paragraph. We still include it in our experiments for providing a fair comparison to previous work and we will discuss more in Section 5.1.
SQuAD v1.1 Rajpurkar et al. 2016 是流行的阅读理解基准。标注者会看到一段 Wikipedia 段落,并被要求写出能从该文本中回答的问题。尽管 SQuAD 此前也被用于开放域问答研究,但它并不理想,因为一旦没有所给段落,许多问题会缺少上下文。为了与先前工作公平比较,我们仍把它纳入实验,并将在第 5.1 节进一步讨论。
Selection of positive passages
Because only pairs of questions and answers are provided in TREC, WebQuestions and TriviaQA[^6], we use the highest-ranked passage from BM25 that contains the answer as the positive passage. If none of the top 100 retrieved passages has the answer, the question will be discarded. For SQuAD and Natural Questions, since the original passages have been split and processed differently than our pool of candidate passages, we match and replace each gold passage with the corresponding passage in the candidate pool.[^7] We discard the questions when the matching is failed due to different Wikipedia versions or pre-processing. Table 1 shows the number of questions in training/dev/test sets for all the datasets and the actual questions used for training the retriever.
正段落的选取
TREC、WebQuestions 和 TriviaQA 只提供问题–答案对[^6],因此我们把包含答案且 BM25 排名最高的段落当作正段落。如果前 100 个检索段落中都没有答案,该问题就被丢弃。对 SQuAD 和 Natural Questions,原始段落的切分与处理方式和我们的候选段落池不同,于是我们把每个黄金段落匹配并替换成候选池中对应的段落。[^7] 若因 Wikipedia 版本或预处理不同而匹配失败,该问题也被丢弃。表 1 给出了各数据集训练/开发/测试集中的问题数,以及实际用来训练检索器的问题数。
| Dataset | Train | Dev | Test | |
|---|---|---|---|---|
| Natural Questions | 79,168 | 58,880 | 8,757 | 3,610 |
| TriviaQA | 78,785 | 60,413 | 8,837 | 11,313 |
| WebQuestions | 3,417 | 2,474 | 361 | 2,032 |
| CuratedTREC | 1,353 | 1,125 | 133 | 694 |
| SQuAD | 78,713 | 70,096 | 8,886 | 10,570 |
Table 1: Number of questions in each QA dataset. The two columns of Train denote the original training examples in the dataset and the actual questions used for training DPR after filtering. See text for more details.
| 数据集 | 训练 | 开发 | 测试 | |
|---|---|---|---|---|
| Natural Questions | 79,168 | 58,880 | 8,757 | 3,610 |
| TriviaQA | 78,785 | 60,413 | 8,837 | 11,313 |
| WebQuestions | 3,417 | 2,474 | 361 | 2,032 |
| CuratedTREC | 1,353 | 1,125 | 133 | 694 |
| SQuAD | 78,713 | 70,096 | 8,886 | 10,570 |
表 1:各问答数据集中的问题数量。训练下的两列分别表示数据集中原始训练例,以及过滤之后实际用来训练 DPR 的问题。细节见正文。
| Training | Retriever | Top-20 | Top-100 | ||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|
| NQ | TriviaQA | WQ | TREC | SQuAD | NQ | TriviaQA | WQ | TREC | SQuAD | ||
| None | BM25 | 59.1 | 66.9 | 55.0 | 70.9 | 68.8 | 73.7 | 76.7 | 71.1 | 84.1 | 80.0 |
| Single | DPR | 78.4 | 79.4 | 73.2 | 79.8 | 63.2 | 85.4 | 85.0 | 81.4 | 89.1 | 77.2 |
| BM25 + DPR | 76.6 | 79.8 | 71.0 | 85.2 | 71.5 | 83.8 | 84.5 | 80.5 | 92.7 | 81.3 | |
| Multi | DPR | 79.4 | 78.8 | 75.0 | 89.1 | 51.6 | 86.0 | 84.7 | 82.9 | 93.9 | 67.6 |
| BM25 + DPR | 78.0 | 79.9 | 74.7 | 88.5 | 66.2 | 83.9 | 84.4 | 82.3 | 94.1 | 78.6 |
Table 2: Top-20 & Top-100 retrieval accuracy on test sets, measured as the percentage of top 20/100 retrieved passages that contain the answer. Single and Multi denote that our Dense Passage Retriever (DPR) was trained using individial or combined training datasets (all the datasets excluding SQuAD). See text for more details.
| 训练 | 检索器 | Top-20 | Top-100 | ||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|
| NQ | TriviaQA | WQ | TREC | SQuAD | NQ | TriviaQA | WQ | TREC | SQuAD | ||
| 无 | BM25 | 59.1 | 66.9 | 55.0 | 70.9 | 68.8 | 73.7 | 76.7 | 71.1 | 84.1 | 80.0 |
| 单数据集 | DPR | 78.4 | 79.4 | 73.2 | 79.8 | 63.2 | 85.4 | 85.0 | 81.4 | 89.1 | 77.2 |
| BM25 + DPR | 76.6 | 79.8 | 71.0 | 85.2 | 71.5 | 83.8 | 84.5 | 80.5 | 92.7 | 81.3 | |
| 多数据集 | DPR | 79.4 | 78.8 | 75.0 | 89.1 | 51.6 | 86.0 | 84.7 | 82.9 | 93.9 | 67.6 |
| BM25 + DPR | 78.0 | 79.9 | 74.7 | 88.5 | 66.2 | 83.9 | 84.4 | 82.3 | 94.1 | 78.6 |
表 2:测试集上的 Top-20 与 Top-100 检索准确率,定义为前 20/100 个检索段落中包含答案的比例。单数据集与多数据集表示我们的稠密段落检索器(DPR)是用单个训练集还是合并训练集(除 SQuAD 外的全部数据集)训练的。细节见正文。
5 Experiments: Passage Retrieval
5 实验:段落检索
In this section, we evaluate the retrieval performance of our Dense Passage Retriever (DPR), along with analysis on how its output differs from traditional retrieval methods, the effects of different training schemes and the run-time efficiency.
本节评估稠密段落检索器(DPR)的检索表现,并分析其输出与传统检索方法有何不同、不同训练方案的影响,以及运行时效率。
The DPR model used in our main experiments is trained using the in-batch negative setting (Section 3.2) with a batch size of and one additional BM25 negative passage per question. We trained the question and passage encoders for up to epochs for large datasets (NQ, TriviaQA, SQuAD) and epochs for small datasets (TREC, WQ), with a learning rate of using Adam, linear scheduling with warm-up and dropout rate .
主实验中的 DPR 模型采用批内负例设定(第 3.2 节)训练,批次大小为 ,每个问题额外加一个 BM25 负段落。我们对问题和段落编码器训练最多 个周期(大规模数据集 NQ、TriviaQA、SQuAD)或 个周期(小规模数据集 TREC、WQ),用 Adam、学习率 ,线性调度并带预热,dropout 率为 。
While it is good to have the flexibility to adapt the retriever to each dataset, it would also be desirable to obtain a single retriever that works well across the board. To this end, we train a multi-dataset encoder by combining training data from all datasets excluding SQuAD.[^8] In addition to DPR, we also present the results of BM25, the traditional retrieval method[^9] and BM25+DPR, using a linear combination of their scores as the new ranking function. Specifically, we obtain two initial sets of top-2000 passages based on BM25 and DPR, respectively, and rerank the union of them using BM25(,) + as the ranking function. We used based on the retrieval accuracy in the development set.
能够为每个数据集单独适配检索器固然灵活,但若能得到一个在各处都好用的单一检索器则更理想。为此,我们把除 SQuAD 以外的所有数据集训练数据合并,训练一个多数据集编码器。[^8] 除 DPR 外,我们也报告传统检索方法 BM25[^9] 以及 BM25+DPR 的结果,后者用二者分数的线性组合作为新的排序函数。具体做法是:分别根据 BM25 和 DPR 得到两组前 2000 个段落,再对它们的并集用 重新排序。我们根据开发集上的检索准确率取 。
5.1 Main Results
5.1 主要结果
Table 2 compares different passage retrieval systems on five QA datasets, using the top- accuracy (). With the exception of SQuAD, DPR performs consistently better than BM25 on all datasets. The gap is especially large when is small (e.g., 78.4% vs. 59.1% for top-20 accuracy on Natural Questions). When training with multiple datasets, TREC, the smallest dataset of the five, benefits greatly from more training examples. In contrast, Natural Questions and WebQuestions improve modestly and TriviaQA degrades slightly. Results can be improved further in some cases by combining DPR with BM25 in both single- and multi-dataset settings.
表 2 在五个问答数据集上比较了不同段落检索系统,指标为 top- 准确率()。除 SQuAD 外,DPR 在所有数据集上都稳定好于 BM25。当 较小时差距尤其大(例如 Natural Questions 上 top-20 准确率为 78.4% 对 59.1%)。用多个数据集一起训练时,五个里最小的 TREC 从更多训练例中获益明显;相比之下,Natural Questions 和 WebQuestions 提升较温和,TriviaQA 略有下降。在单数据集和多数据集两种设定下,把 DPR 与 BM25 组合,有时还能进一步改进结果。
We conjecture that the lower performance on SQuAD is due to two reasons. First, the annotators wrote questions after seeing the passage. As a result, there is a high lexical overlap between passages and questions, which gives BM25 a clear advantage. Second, the data was collected from only 500+ Wikipedia articles and thus the distribution of training examples is extremely biased, as argued previously by Lee et al. 2019.
我们推测 SQuAD 上表现较差有两个原因。第一,标注者是看过段落后再写问题的,于是段落与问题之间词汇重叠很高,这明显有利于 BM25。第二,数据只来自 500 多篇 Wikipedia 文章,训练例的分布因此极为偏斜,Lee et al. 2019 此前也指出过这一点。
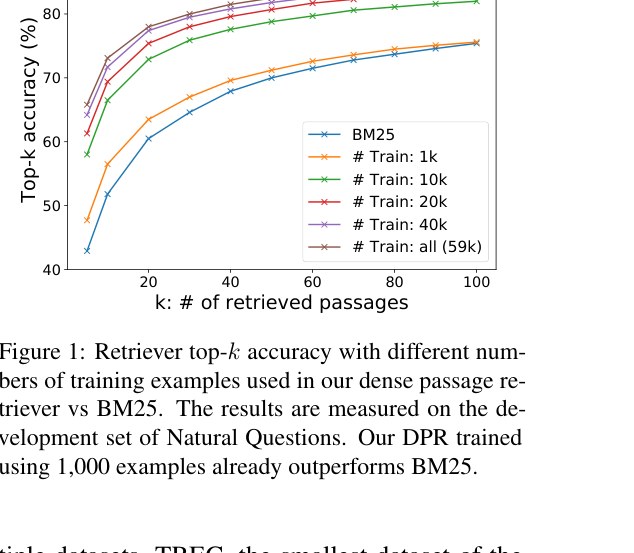
Figure 1: Retriever top- accuracy with different numbers of training examples used in our dense passage retriever vs BM25. The results are measured on the development set of Natural Questions. Our DPR trained using 1,000 examples already outperforms BM25.
图 1:在不同数量的训练例下,我们的稠密段落检索器与 BM25 的 top- 检索准确率。结果在 Natural Questions 开发集上测量。仅用 1,000 个例子训练的 DPR 已经超过 BM25。
5.2 Ablation Study on Model Training
5.2 关于模型训练的消融实验
To understand further how different model training options affect the results, we conduct several additional experiments and discuss our findings below.
为了进一步理解不同的模型训练选择如何影响结果,我们又做了若干实验,并在下面讨论发现。
Sample efficiency
We explore how many training examples are needed to achieve good passage retrieval performance. Figure 1 illustrates the top- retrieval accuracy with respect to different numbers of training examples, measured on the development set of Natural Questions. As is shown, a dense passage retriever trained using only 1,000 examples already outperforms BM25. This suggests that with a general pretrained language model, it is possible to train a high-quality dense retriever with a small number of question–passage pairs. Adding more training examples (from 1k to 59k) further improves the retrieval accuracy consistently.
样本效率
我们考察要达到良好的段落检索表现需要多少训练例。图 1 给出了不同训练例数量下的 top- 检索准确率,在 Natural Questions 开发集上测量。如图所示,仅用 1,000 个例子训练的稠密段落检索器已经超过 BM25。这说明,在通用预训练语言模型的基础上,用少量问题–段落对就有可能训练出高质量的稠密检索器。把训练例从 1k 增加到 59k,检索准确率还会持续提高。
In-batch negative training
We test different training schemes on the development set of Natural Questions and summarize the results in Table 3. The top block is the standard 1-of- training setting, where each question in the batch is paired with a positive passage and its own set of negative passages (Eq. (2)). We find that the choice of negatives — random, BM25 or gold passages (positive passages from other questions) — does not impact the top- accuracy much in this setting when .
批内负例训练
我们在 Natural Questions 开发集上测试不同训练方案,结果汇总于表 3。上半部分是标准的 1-of- 训练设定:批次中每个问题配一个正段落以及它自己的 个负段落(公式 (2))。我们发现,在这一设定下,当 时,负例的选择——随机、BM25 或黄金段落(其他问题的正段落)——对 top- 准确率影响不大。
The middle bock is the in-batch negative training (Section 3.2) setting. We find that using a similar configuration (7 gold negative passages), in-batch negative training improves the results substantially. The key difference between the two is whether the gold negative passages come from the same batch or from the whole training set. Effectively, in-batch negative training is an easy and memory-efficient way to reuse the negative examples already in the batch rather than creating new ones. It produces more pairs and thus increases the number of training examples, which might contribute to the good model performance. As a result, accuracy consistently improves as the batch size grows.
中间部分是批内负例训练(第 3.2 节)设定。我们发现,在相近配置(7 个黄金负段落)下,批内负例训练能明显改进结果。二者的关键差别在于:黄金负段落是来自同一批次,还是来自整个训练集。实际上,批内负例训练是一种简便且节省内存的方式,用来复用批次中已有的负例,而不是再造新的负例。它产生更多配对,从而增加了训练例数量,这可能有助于模型表现。因此,随着批次变大,准确率会持续提高。
Finally, we explore in-batch negative training with additional “hard” negative passages that have high BM25 scores given the question, but do not contain the answer string (the bottom block). These additional passages are used as negative passages for all questions in the same batch. We find that adding a single BM25 negative passage improves the result substantially while adding two does not help further.
最后,我们在批内负例训练之上再加入额外的“困难”负段落:这些段落在给定问题上的 BM25 分数很高,但不包含答案字符串(表的下半部分)。这些额外段落被当作同一批次中所有问题的负段落。我们发现,加入一个 BM25 负段落就能明显改进结果,再加第二个则没有进一步帮助。
| Type | #N | IB | Top-5 | Top-20 | Top-100 |
|---|---|---|---|---|---|
| Random | 7 | ✗ | 47.0 | 64.3 | 77.8 |
| BM25 | 7 | ✗ | 50.0 | 63.3 | 74.8 |
| Gold | 7 | ✗ | 42.6 | 63.1 | 78.3 |
| Gold | 7 | ✓ | 51.1 | 69.1 | 80.8 |
| Gold | 31 | ✓ | 52.1 | 70.8 | 82.1 |
| Gold | 127 | ✓ | 55.8 | 73.0 | 83.1 |
| G.+BM25*(1)* | 31+32 | ✓ | 65.0 | 77.3 | 84.4 |
| G.+BM25*(2)* | 31+64 | ✓ | 64.5 | 76.4 | 84.0 |
| G.+BM25*(1)* | 127+128 | ✓ | 65.8 | 78.0 | 84.9 |
Table 3: Comparison of different training schemes, measured as top- retrieval accuracy on Natural Questions (development set). #N: number of negative examples, IB: in-batch training. G.+BM25*(1)* and G.+BM25*(2)* denote in-batch training with 1 or 2 additional BM25 negatives, which serve as negative passages for all questions in the batch.
| 类型 | #N | IB | Top-5 | Top-20 | Top-100 |
|---|---|---|---|---|---|
| 随机 | 7 | ✗ | 47.0 | 64.3 | 77.8 |
| BM25 | 7 | ✗ | 50.0 | 63.3 | 74.8 |
| 黄金 | 7 | ✗ | 42.6 | 63.1 | 78.3 |
| 黄金 | 7 | ✓ | 51.1 | 69.1 | 80.8 |
| 黄金 | 31 | ✓ | 52.1 | 70.8 | 82.1 |
| 黄金 | 127 | ✓ | 55.8 | 73.0 | 83.1 |
| 黄金+BM25*(1)* | 31+32 | ✓ | 65.0 | 77.3 | 84.4 |
| 黄金+BM25*(2)* | 31+64 | ✓ | 64.5 | 76.4 | 84.0 |
| 黄金+BM25*(1)* | 127+128 | ✓ | 65.8 | 78.0 | 84.9 |
表 3:不同训练方案的比较,指标为 Natural Questions(开发集)上的 top- 检索准确率。#N:负例个数;IB:是否批内训练。黄金+BM25*(1)* 与 黄金+BM25*(2)* 表示在批内训练之外再加入 1 个或 2 个额外的 BM25 负例,它们作为该批次中所有问题的负段落。
Impact of gold passages
We use passages that match the gold contexts in the original datasets (when available) as positive examples (Section 4.2). Our experiments on Natural Questions show that switching to distantly-supervised passages (using the highest-ranked BM25 passage that contains the answer), has only a small impact: 1 point lower top- accuracy for retrieval. Appendix A contains more details.
黄金段落的影响
我们把与原始数据集中黄金上下文相匹配的段落(若有)当作正例(第 4.2 节)。在 Natural Questions 上的实验表明,改用远距离监督段落(即包含答案且 BM25 排名最高的段落)影响很小:检索的 top- 准确率只低大约 1 个百分点。更多细节见附录 A。
Similarity and loss
Besides dot product, cosine and Euclidean L2 distance are also commonly used as decomposable similarity functions. We test these alternatives and find that L2 performs comparable to dot product, and both of them are superior to cosine. Similarly, in addition to negative log-likelihood, a popular option for ranking is triplet loss, which compares a positive passage and a negative one directly with respect to a question Burges et al. 2005. Our experiments show that using triplet loss does not affect the results much. More details can be found in Appendix B.
相似度与损失
除点积外,余弦和欧氏 L2 距离也常被用作可分解的相似度函数。我们测试了这些替代方案,发现 L2 与点积表现相当,二者都优于余弦。类似地,除负对数似然外,排序里常用的还有三元组损失,它直接就一个问题比较一个正段落和一个负段落 Burges et al. 2005。实验表明,改用三元组损失对结果影响不大。更多细节见附录 B。
Cross-dataset generalization
One interesting question regarding DPR’s discriminative training is how much performance degradation it may suffer from a non-iid setting. In other words, can it still generalize well when directly applied to a different dataset without additional fine-tuning? To test the cross-dataset generalization, we train DPR on Natural Questions only and test it directly on the smaller WebQuestions and CuratedTREC datasets. We find that DPR generalizes well, with 3-5 points loss from the best performing fine-tuned model in top-20 retrieval accuracy (69.9/86.3 vs. 75.0/89.1 for WebQuestions and TREC, respectively), while still greatly outperforming the BM25 baseline (55.0/70.9).
跨数据集泛化
关于 DPR 的判别式训练,一个有意思的问题是:在非独立同分布设定下它会下降多少?也就是说,若不做额外微调、直接用到另一个数据集上,它还能不能泛化得很好?为测试跨数据集泛化,我们只在 Natural Questions 上训练 DPR,然后直接在较小的 WebQuestions 和 CuratedTREC 上测试。我们发现 DPR 泛化良好:相对于该数据集上微调得最好的模型,top-20 检索准确率只低 3–5 个百分点(WebQuestions / TREC 为 69.9/86.3,对应最好的 75.0/89.1),同时仍然大幅超过 BM25 基线(55.0/70.9)。
5.3 Qualitative Analysis
5.3 定性分析
Although DPR performs better than BM25 in general, passages retrieved by these two methods differ qualitatively. Term-matching methods like BM25 are sensitive to highly selective keywords and phrases, while DPR captures lexical variations or semantic relationships better. See Appendix C for examples and more discussion.
尽管 DPR 总体上好于 BM25,两种方法检索到的段落在性质上并不相同。BM25 这类词项匹配方法对区分度很高的关键词和短语更敏感,而 DPR 更能捕捉词汇变化或语义关系。例子与更多讨论见附录 C。
5.4 Run-time Efficiency
5.4 运行时效率
The main reason that we require a retrieval component for open-domain QA is to reduce the number of candidate passages that the reader needs to consider, which is crucial for answering user’s questions in real-time. We profiled the passage retrieval speed on a server with Intel Xeon CPU E5-2698 v4 @ 2.20GHz and 512GB memory. With the help of FAISS in-memory index for real-valued vectors[^10], DPR can be made incredibly efficient, processing 995.0 questions per second, returning top 100 passages per question. In contrast, BM25/Lucene (implemented in Java, using file index) processes 23.7 questions per second per CPU thread.
开放域问答之所以需要检索组件,主要是为了减少阅读器需要考虑的候选段落数量,这对实时回答用户问题至关重要。我们在一台配有 Intel Xeon CPU E5-2698 v4 @ 2.20GHz 和 512GB 内存的服务器上测量段落检索速度。借助用于实值向量的 FAISS 内存索引[^10],DPR 可以非常高效:每秒处理 995.0 个问题,每个问题返回前 100 个段落。相比之下,BM25/Lucene(用 Java 实现,采用文件索引)每个 CPU 线程每秒处理 23.7 个问题。
On the other hand, the time required for building an index for dense vectors is much longer. Computing dense embeddings on 21-million passages is resource intensive, but can be easily parallelized, taking roughly 8.8 hours on 8 GPUs. However, building the FAISS index on 21-million vectors on a single server takes 8.5 hours. In comparison, building an inverted index using Lucene is much cheaper and takes only about 30 minutes in total.
另一方面,为稠密向量建立索引所需的时间要长得多。在 2100 万个段落上计算稠密嵌入很耗资源,但不难并行,8 块 GPU 大约需要 8.8 小时。然而,在单台服务器上为 2100 万个向量建立 FAISS 索引需要 8.5 小时。相比之下,用 Lucene 建立倒排索引便宜得多,总共大约只需 30 分钟。
| Training | Model | NQ | TriviaQA | WQ | TREC | SQuAD |
|---|---|---|---|---|---|---|
| Single | BM25+BERT Lee et al. 2019 | 26.5 | 47.1 | 17.7 | 21.3 | 33.2 |
| Single | ORQA Lee et al. 2019 | 33.3 | 45.0 | 36.4 | 30.1 | 20.2 |
| Single | HardEM Min et al. 2019a | 28.1 | 50.9 | - | - | - |
| Single | GraphRetriever Min et al. 2019b | 34.5 | 56.0 | 36.4 | - | - |
| Single | PathRetriever Asai et al. 2020 | 32.6 | - | - | - | 56.5 |
| Single | REALM Guu et al. 2020 | 39.2 | - | 40.2 | 46.8 | - |
| Single | REALM Guu et al. 2020 | 40.4 | - | 40.7 | 42.9 | - |
| Single | BM25 | 32.6 | 52.4 | 29.9 | 24.9 | 38.1 |
| DPR | 41.5 | 56.8 | 34.6 | 25.9 | 29.8 | |
| BM25+DPR | 39.0 | 57.0 | 35.2 | 28.0 | 36.7 | |
| Multi | DPR | 41.5 | 56.8 | 42.4 | 49.4 | 24.1 |
| BM25+DPR | 38.8 | 57.9 | 41.1 | 50.6 | 35.8 |
Table 4: End-to-end QA (Exact Match) Accuracy. The first block of results are copied from their cited papers. REALM and REALM are the same model but pretrained on Wikipedia and CC-News, respectively. Single and Multi denote that our Dense Passage Retriever (DPR) is trained using individual or combined training datasets (all except SQuAD). For WQ and TREC in the Multi setting, we fine-tune the reader trained on NQ.
| 训练 | 模型 | NQ | TriviaQA | WQ | TREC | SQuAD |
|---|---|---|---|---|---|---|
| 单数据集 | BM25+BERT Lee et al. 2019 | 26.5 | 47.1 | 17.7 | 21.3 | 33.2 |
| 单数据集 | ORQA Lee et al. 2019 | 33.3 | 45.0 | 36.4 | 30.1 | 20.2 |
| 单数据集 | HardEM Min et al. 2019a | 28.1 | 50.9 | - | - | - |
| 单数据集 | GraphRetriever Min et al. 2019b | 34.5 | 56.0 | 36.4 | - | - |
| 单数据集 | PathRetriever Asai et al. 2020 | 32.6 | - | - | - | 56.5 |
| 单数据集 | REALM Guu et al. 2020 | 39.2 | - | 40.2 | 46.8 | - |
| 单数据集 | REALM Guu et al. 2020 | 40.4 | - | 40.7 | 42.9 | - |
| 单数据集 | BM25 | 32.6 | 52.4 | 29.9 | 24.9 | 38.1 |
| DPR | 41.5 | 56.8 | 34.6 | 25.9 | 29.8 | |
| BM25+DPR | 39.0 | 57.0 | 35.2 | 28.0 | 36.7 | |
| 多数据集 | DPR | 41.5 | 56.8 | 42.4 | 49.4 | 24.1 |
| BM25+DPR | 38.8 | 57.9 | 41.1 | 50.6 | 35.8 |
表 4:端到端问答(精确匹配)准确率。第一组结果摘自所引用的论文。REALM 与 REALM 是同一模型,分别在 Wikipedia 和 CC-News 上预训练。单数据集与多数据集表示我们的稠密段落检索器(DPR)用单个训练集还是合并训练集(除 SQuAD 外全部)训练。在多数据集设定下的 WQ 和 TREC,我们对在 NQ 上训练好的阅读器再做微调。
6 Experiments: Question Answering
6 实验:问答
In this section, we experiment with how different passage retrievers affect the final QA accuracy.
本节实验不同段落检索器会如何影响最终的问答准确率。
6.1 End-to-end QA System
6.1 端到端问答系统
We implement an end-to-end question answering system in which we can plug different retriever systems directly. Besides the retriever, our QA system consists of a neural reader that outputs the answer to the question. Given the top retrieved passages (up to in our experiments), the reader assigns a passage selection score to each passage. In addition, it extracts an answer span from each passage and assigns a span score. The best span from the passage with the highest passage selection score is chosen as the final answer. The passage selection model serves as a reranker through cross-attention between the question and the passage. Although cross-attention is not feasible for retrieving relevant passages in a large corpus due to its non-decomposable nature, it has more capacity than the dual-encoder model as in Eq. (1). Applying it to selecting the passage from a small number of retrieved candidates has been shown to work well Wang et al. 2019; Wang et al. 2018; Lin et al. 2018.
我们实现了一个端到端问答系统,不同检索器可以直接插入其中。除检索器外,该系统还包括一个神经阅读器,用来输出问题的答案。给定检索到的前 个段落(实验中最多 个),阅读器为每个段落打一个段落选择分数。同时,它从每个段落中抽出一个答案片段并给出片段分数。最终答案取自段落选择分数最高的那个段落中最好的片段。段落选择模型通过对问题和段落做交叉注意力来充当重排序器。交叉注意力由于其不可分解性,无法用来在大规模语料中检索相关段落,但它比公式 (1) 中的双编码器模型 容量更大。把它用在从少量检索候选中选择段落,已被证明效果很好 Wang et al. 2019;Wang et al. 2018;Lin et al. 2018。
Specifically, let () be a BERT (base, uncased in our experiments) representation for the -th passage, where is the maximum length of the passage and the hidden dimension. The probabilities of a token being the starting/ending positions of an answer span and a passage being selected are defined as:
具体地,令 ()为第 个段落的 BERT 表示(实验中为 base、uncased),其中 是段落的最大长度, 是隐层维度。一个记号作为答案片段起始/结束位置的概率,以及一个段落被选中的概率,定义为:
where and are learnable vectors. We compute a span score of the -th to -th words from the -th passage as , and a passage selection score of the -th passage as .
其中 ,且 是可学习向量。我们把第 个段落中第 到第 个词的片段分数算成 ,把第 个段落的选择分数算成 。
During training, we sample one positive and negative passages from the top 100 passages returned by the retrieval system (BM25 or DPR) for each question. is a hyper-parameter and we use in all the experiments. The training objective is to maximize the marginal log-likelihood of all the correct answer spans in the positive passage (the answer string may appear multiple times in one passage), combined with the log-likelihood of the positive passage being selected. We use the batch size of 16 for large (NQ, TriviaQA, SQuAD) and 4 for small (TREC, WQ) datasets, and tune on the development set. For experiments on small datasets under the Multi setting, in which using other datasets is allowed, we fine-tune the reader trained on Natural Questions to the target dataset. All experiments were done on eight 32GB GPUs.
训练时,对每个问题,我们从检索系统(BM25 或 DPR)返回的前 100 个段落中采样一个正段落和 个负段落。 是超参数,全部实验中取 。训练目标是最大化正段落中所有正确答案片段的边缘对数似然(答案字符串可能在同一段落中出现多次),再加上该正段落被选中的对数似然。大规模数据集(NQ、TriviaQA、SQuAD)的批次大小为 16,小规模数据集(TREC、WQ)为 4,并在开发集上调节 。在允许使用其他数据集的多数据集设定下,对小数据集的实验是把在 Natural Questions 上训练好的阅读器微调到目标数据集。全部实验在八块 32GB GPU 上完成。
6.2 Results
6.2 结果
Table 4 summarizes our final end-to-end QA results, measured by exact match with the reference answer after minor normalization as in Chen et al. 2017; Lee et al. 2019. From the table, we can see that higher retriever accuracy typically leads to better final QA results: in all cases except SQuAD, answers extracted from the passages retrieved by DPR are more likely to be correct, compared to those from BM25. For large datasets like NQ and TriviaQA, models trained using multiple datasets (Multi) perform comparably to those trained using the individual training set (Single). Conversely, on smaller datasets like WQ and TREC, the multi-dataset setting has a clear advantage. Overall, our DPR-based models outperform the previous state-of-the-art results on four out of the five datasets, with 1% to 12% absolute differences in exact match accuracy. It is interesting to contrast our results to those of ORQA Lee et al. 2019 and also the concurrently developed approach, REALM Guu et al. 2020. While both methods include additional pretraining tasks and employ an expensive end-to-end training regime, DPR manages to outperform them on both NQ and TriviaQA, simply by focusing on learning a strong passage retrieval model using pairs of questions and answers. The additional pretraining tasks are likely more useful only when the target training sets are small. Although the results of DPR on WQ and TREC in the single-dataset setting are less competitive, adding more question–answer pairs helps boost the performance, achieving the new state of the art.
表 4 汇总了最终的端到端问答结果,指标是与参考答案在轻微规范化之后的精确匹配,规范化方式与 Chen et al. 2017;Lee et al. 2019 相同。从表中可以看到,更高的检索准确率通常会带来更好的最终问答结果:除 SQuAD 外,从 DPR 检索出的段落中抽出的答案,比从 BM25 段落中抽出的更可能正确。对 NQ 和 TriviaQA 这类大规模数据集,用多个数据集训练的模型(多数据集)与只用各自训练集训练的模型(单数据集)表现相当。相反,在 WQ 和 TREC 这类较小的数据集上,多数据集设定有明显优势。总体而言,基于 DPR 的模型在五个数据集中的四个上超过了先前最好结果,精确匹配准确率的绝对差距在 1% 到 12% 之间。把我们的结果与 ORQA Lee et al. 2019 以及同时期发展的 REALM Guu et al. 2020 对照起来很有意思。后两种方法都包含额外的预训练任务,并采用代价很高的端到端训练机制;DPR 仅仅通过用问题–答案对学习一个强的段落检索模型,就在 NQ 和 TriviaQA 上都超过了它们。额外预训练任务很可能只在目标训练集较小时更有用。虽然单数据集设定下 DPR 在 WQ 和 TREC 上的结果竞争力较弱,但加入更多问题–答案对就能推高表现,并取得新的最好结果。
To compare our pipeline training approach with joint learning, we run an ablation on Natural Questions where the retriever and reader are jointly trained, following Lee et al. 2019. This approach obtains a score of 39.8 EM, which suggests that our strategy of training a strong retriever and reader in isolation can leverage effectively available supervision, while outperforming a comparable joint training approach with a simpler design (Appendix D).
为了把我们的流水线训练方法与联合学习相比较,我们在 Natural Questions 上做了一项消融:按 Lee et al. 2019 的做法联合训练检索器和阅读器。这一做法得到 39.8 的精确匹配分数,说明分别训练一个强检索器和一个阅读器的策略能够有效利用已有监督,并且以更简单的设计超过了可比较的联合训练方法(附录 D)。
One thing worth noticing is that our reader does consider more passages compared to ORQA, although it is not completely clear how much more time it takes for inference. While DPR processes up to 100 passages for each question, the reader is able to fit all of them into one batch on a single 32GB GPU, thus the latency remains almost identical to the single passage case (around 20ms). The exact impact on throughput is harder to measure: ORQA uses 2-3x longer passages compared to DPR (288 word pieces compared to our 100 tokens) and the computational complexity is super-linear in passage length. We also note that we found to be optimal for NQ, and leads to only marginal loss in exact match accuracy (40.8 vs. 41.5 EM on NQ), which should be roughly comparable to ORQA’s 5-passage setup.
值得注意的是,我们的阅读器考虑的段落比 ORQA 更多,不过推断会多花多少时间并不完全清楚。DPR 每个问题最多处理 100 个段落,阅读器能把它们全部放进一块 32GB GPU 上的同一个批次,因此延迟几乎与只处理单个段落时相同(大约 20 毫秒)。对吞吐量的精确影响更难测量:ORQA 使用的段落比 DPR 长 2–3 倍(288 个 word piece,对比我们的 100 个记号),而计算复杂度对段落长度是超线性的。我们还发现 NQ 上最优的是 ,而 只会带来很小的精确匹配损失(NQ 上 40.8 对 41.5),这应当与 ORQA 使用 5 个段落的设置大致可比。
7 Related Work
7 相关工作
Passage retrieval has been an important component for open-domain QA Voorhees 1999. It not only effectively reduces the search space for answer extraction, but also identifies the support context for users to verify the answer. Strong sparse vector space models like TF-IDF or BM25 have been used as the standard method applied broadly to various QA tasks (Chen et al. 2017; Yang et al. 2019a; Yang et al. 2019b; Nie et al. 2019; Min et al. 2019a; Wolfson et al. 2020, e.g.,). Augmenting text-based retrieval with external structured information, such as knowledge graph and Wikipedia hyperlinks, has also been explored recently Min et al. 2019b; Asai et al. 2020.
段落检索一直是开放域问答的重要组件 Voorhees 1999。它不仅有效缩小答案抽取的搜索空间,还为用户提供核验答案的支持上下文。TF-IDF 或 BM25 这类较强的稀疏向量空间模型,已被当作标准方法广泛用于各种问答任务(例如 Chen et al. 2017;Yang et al. 2019a;Yang et al. 2019b;Nie et al. 2019;Min et al. 2019a;Wolfson et al. 2020)。用外部结构化信息(如知识图谱和 Wikipedia 超链接)来增强基于文本的检索,近来也有人探索 Min et al. 2019b;Asai et al. 2020。
The use of dense vector representations for retrieval has a long history since Latent Semantic Analysis Deerwester et al. 1990. Using labeled pairs of queries and documents, discriminatively trained dense encoders have become popular recently Yih et al. 2011; Huang et al. 2013; Gillick et al. 2019, with applications to cross-lingual document retrieval, ad relevance prediction, Web search and entity retrieval. Such approaches complement the sparse vector methods as they can potentially give high similarity scores to semantically relevant text pairs, even without exact token matching. The dense representation alone, however, is typically inferior to the sparse one. While not the focus of this work, dense representations from pretrained models, along with cross-attention mechanisms, have also been shown effective in passage or dialogue re-ranking tasks Nogueira and Cho 2019; Humeau et al. 2020. Finally, a concurrent work Khattab and Zaharia 2020 demonstrates the feasibility of full dense retrieval in IR tasks. Instead of employing the dual-encoder framework, they introduced a late-interaction operator on top of the BERT encoders.
用稠密向量表示做检索,自潜在语义分析 Deerwester et al. 1990 以来已有很长历史。利用带标注的查询–文档对,判别式训练的稠密编码器近来再次流行 Yih et al. 2011;Huang et al. 2013;Gillick et al. 2019,并被用于跨语言文档检索、广告相关性预测、网页搜索和实体检索。这类方法与稀疏向量方法互补,因为它们即使没有精确的记号匹配,也可能给语义相关的文本对打出高相似度。不过,单独使用稠密表示通常仍弱于稀疏表示。虽非本文重点,预训练模型得到的稠密表示再加上交叉注意力,在段落或对话重排序任务上也已被证明有效 Nogueira and Cho 2019;Humeau et al. 2020。最后,一项同时期的工作 Khattab and Zaharia 2020 表明,在信息检索任务中做全程稠密检索是可行的。他们没有采用双编码器框架,而是在 BERT 编码器之上引入了一种延迟交互算子。
Dense retrieval for open-domain QA has been explored by Das et al. 2019, who propose to retrieve relevant passages iteratively using reformulated question vectors. As an alternative approach that skips passage retrieval, Seo et al. 2019 propose to encode candidate answer phrases as vectors and directly retrieve the answers to the input questions efficiently. Using additional pretraining with the objective that matches surrogates of questions and relevant passages, Lee et al. 2019 jointly train the question encoder and reader. Their approach outperforms the BM25 plus reader paradigm on multiple open-domain QA datasets in QA accuracy, and is further extended by REALM Guu et al. 2020, which includes tuning the passage encoder asynchronously by re-indexing the passages during training. The pretraining objective has also recently been improved by Xiong et al. 2020b. In contrast, our model provides a simple and yet effective solution that shows stronger empirical performance, without relying on additional pretraining or complex joint training schemes.
开放域问答中的稠密检索已被 Das et al. 2019 探索过,他们提出用改写后的问题向量迭代检索相关段落。作为一种跳过段落检索的替代做法,Seo et al. 2019 提议把候选答案短语编码成向量,并直接高效地检索输入问题的答案。Lee et al. 2019 用额外预训练、以匹配问题替代物与相关段落为目标,联合训练问题编码器和阅读器。他们的方法在多个开放域问答数据集的问答准确率上超过了 BM25 加阅读器的范式,并被 REALM Guu et al. 2020 进一步扩展:REALM 在训练过程中通过重新索引段落,异步地调节段落编码器。预训练目标最近也由 Xiong et al. 2020b 加以改进。与这些工作不同,我们的模型提供了一种简单却有效的方案,经验表现更强,并不依赖额外预训练或复杂的联合训练机制。
DPR has also been used as an important module in very recent work. For instance, extending the idea of leveraging hard negatives, Xiong et al. 2020a use the retrieval model trained in the previous iteration to discover new negatives and construct a different set of examples in each training iteration. Starting from our trained DPR model, they show that the retrieval performance can be further improved. Recent work Izacard and Grave 2020; Lewis et al. 2020b have also shown that DPR can be combined with generation models such as BART Lewis et al. 2020a and T5 Raffel et al. 2019, achieving good performance on open-domain QA and other knowledge-intensive tasks.
DPR 也已被最近的工作当作重要模块来用。例如,沿着利用困难负例的思路,Xiong et al. 2020a 用上一轮训练好的检索模型去发现新的负例,并在每一轮训练中构造不同的例子集合。从我们训练好的 DPR 模型出发,他们表明检索表现还能进一步提高。近期工作 Izacard and Grave 2020;Lewis et al. 2020b 也表明,DPR 可以与 BART Lewis et al. 2020a、T5 Raffel et al. 2019 这类生成模型结合,在开放域问答和其他知识密集型任务上取得良好表现。
8 Conclusion
8 结论
In this work, we demonstrated that dense retrieval can outperform and potentially replace the traditional sparse retrieval component in open-domain question answering. While a simple dual-encoder approach can be made to work surprisingly well, we showed that there are some critical ingredients to training a dense retriever successfully. Moreover, our empirical analysis and ablation studies indicate that more complex model frameworks or similarity functions do not necessarily provide additional values. As a result of improved retrieval performance, we obtained new state-of-the-art results on multiple open-domain question answering benchmarks.
本工作表明,稠密检索可以超过、并有可能取代开放域问答中传统的稀疏检索组件。虽然一个简单的双编码器方法就能出人意料地好用,我们也表明,要成功训练稠密检索器,有若干关键要素。此外,经验分析与消融实验显示,更复杂的模型框架或相似度函数并不一定带来额外收益。由于检索表现提高,我们在多个开放域问答基准上取得了新的最好结果。
Acknowledgments
致谢
We thank the anonymous reviewers for their helpful comments and suggestions.
感谢匿名审稿人提出的有益意见与建议。
References
参考文献
Asai et al. (2020) Akari Asai, Kazuma Hashimoto, Hannaneh Hajishirzi, Richard Socher, and Caiming Xiong. 2020. Learning to retrieve reasoning paths over Wikipedia graph for question answering. In International Conference on Learning Representations (ICLR) .
Baudiš and Šedivỳ (2015) Petr Baudiš and Jan Šedivỳ. 2015. Modeling of the question answering task in the yodaqa system. In International Conference of the Cross-Language Evaluation Forum for European Languages , pages 222–228. Springer.
Berant et al. (2013) Jonathan Berant, Andrew Chou, Roy Frostig, and Percy Liang. 2013. Semantic parsing on Freebase from question-answer pairs. In Empirical Methods in Natural Language Processing (EMNLP) .
Bromley et al. (1994) Jane Bromley, Isabelle Guyon, Yann LeCun, Eduard Säckinger, and Roopak Shah. 1994. Signature verification using a “Siamese” time delay neural network. In NIPS , pages 737–744.
Burges et al. (2005) Chris Burges, Tal Shaked, Erin Renshaw, Ari Lazier, Matt Deeds, Nicole Hamilton, and Greg Hullender. 2005. Learning to rank using gradient descent. In Proceedings of the 22nd international conference on Machine learning , pages 89–96.
Chen et al. (2017) Danqi Chen, Adam Fisch, Jason Weston, and Antoine Bordes. 2017. Reading Wikipedia to answer open-domain questions. In Association for Computational Linguistics (ACL) , pages 1870–1879.
Das et al. (2019) Rajarshi Das, Shehzaad Dhuliawala, Manzil Zaheer, and Andrew McCallum. 2019. Multi-step retriever-reader interaction for scalable open-domain question answering. In International Conference on Learning Representations (ICLR) .
Deerwester et al. (1990) Scott Deerwester, Susan T Dumais, George W Furnas, Thomas K Landauer, and Richard Harshman. 1990. Indexing by latent semantic analysis. Journal of the American society for information science , 41(6):391–407.
Devlin et al. (2019) Jacob Devlin, Ming-Wei Chang, Kenton Lee, and Kristina Toutanova. 2019. BERT: Pre-training of deep bidirectional transformers for language understanding. In North American Association for Computational Linguistics (NAACL) .
Ferrucci (2012) David A Ferrucci. 2012. Introduction to “This is Watson”. IBM Journal of Research and Development , 56(3.4):1–1.
Gillick et al. (2019) Daniel Gillick, Sayali Kulkarni, Larry Lansing, Alessandro Presta, Jason Baldridge, Eugene Ie, and Diego Garcia-Olano. 2019. Learning dense representations for entity retrieval. In Computational Natural Language Learning (CoNLL) .
Guo et al. (2016) Ruiqi Guo, Sanjiv Kumar, Krzysztof Choromanski, and David Simcha. 2016. Quantization based fast inner product search. In Artificial Intelligence and Statistics , pages 482–490.
Guu et al. (2020) Kelvin Guu, Kenton Lee, Zora Tung, Panupong Pasupat, and Ming-Wei Chang. 2020. REALM: Retrieval-augmented language model pre-training. ArXiv , abs/2002.08909.
Henderson et al. (2017) Matthew Henderson, Rami Al-Rfou, Brian Strope, Yun-hsuan Sung, László Lukács, Ruiqi Guo, Sanjiv Kumar, Balint Miklos, and Ray Kurzweil. 2017. Efficient natural language response suggestion for smart reply. ArXiv , abs/1705.00652.
Huang et al. (2013) Po-Sen Huang, Xiaodong He, Jianfeng Gao, Li Deng, Alex Acero, and Larry Heck. 2013. Learning deep structured semantic models for Web search using clickthrough data. In ACM International Conference on Information and Knowledge Management (CIKM) , pages 2333–2338.
Humeau et al. (2020) Samuel Humeau, Kurt Shuster, Marie-Anne Lachaux, and Jason Weston. 2020. Poly-encoders: Architectures and pre-training strategies for fast and accurate multi-sentence scoring. In International Conference on Learning Representations (ICLR) .
Izacard and Grave (2020) Gautier Izacard and Edouard Grave. 2020. Leveraging passage retrieval with generative models for open domain question answering. ArXiv , abs/2007.01282.
Johnson et al. (2017) Jeff Johnson, Matthijs Douze, and Hervé Jégou. 2017. Billion-scale similarity search with GPUs. ArXiv , abs/1702.08734.
Joshi et al. (2017) Mandar Joshi, Eunsol Choi, Daniel Weld, and Luke Zettlemoyer. 2017. TriviaQA: A large scale distantly supervised challenge dataset for reading comprehension. In Association for Computational Linguistics (ACL) , pages 1601–1611.
Khattab and Zaharia (2020) Omar Khattab and Matei Zaharia. 2020. ColBERT: Efficient and effective passage search via contextualized late interaction over BERT. In ACM SIGIR Conference on Research and Development in Information Retrieval (SIGIR) , pages 39–48.
Kulis (2013) Brian Kulis. 2013. Metric learning: A survey. Foundations and Trends in Machine Learning , 5(4):287–364.
Kwiatkowski et al. (2019) Tom Kwiatkowski, Jennimaria Palomaki, Olivia Redfield, Michael Collins, Ankur Parikh, Chris Alberti, Danielle Epstein, Illia Polosukhin, Matthew Kelcey, Jacob Devlin, Kenton Lee, Kristina N. Toutanova, Llion Jones, Ming-Wei Chang, Andrew Dai, Jakob Uszkoreit, Quoc Le, and Slav Petrov. 2019. Natural questions: a benchmark for question answering research. Transactions of the Association of Computational Linguistics (TACL) .
Lee et al. (2019) Kenton Lee, Ming-Wei Chang, and Kristina Toutanova. 2019. Latent retrieval for weakly supervised open domain question answering. In Association for Computational Linguistics (ACL) , pages 6086–6096.
Lewis et al. (2020a) Mike Lewis, Yinhan Liu, Naman Goyal, Marjan Ghazvininejad, Abdelrahman Mohamed, Omer Levy, Veselin Stoyanov, and Luke Zettlemoyer. 2020a. BART: Denoising sequence-to-sequence pre-training for natural language generation, translation, and comprehension. In Association for Computational Linguistics (ACL) , pages 7871–7880.
Lewis et al. (2020b) Patrick Lewis, Ethan Perez, Aleksandara Piktus, Fabio Petroni, Vladimir Karpukhin, Naman Goyal, Heinrich Küttler, Mike Lewis, Wen-tau Yih, Tim Rocktäschel, Sebastian Riedel, and Douwe Kiela. 2020b. Retrieval-augmented generation for knowledge-intensive NLP tasks. In Advances in Neural Information Processing Systems (NeurIPS) .
Lin et al. (2018) Yankai Lin, Haozhe Ji, Zhiyuan Liu, and Maosong Sun. 2018. Denoising distantly supervised open-domain question answering. In Association for Computational Linguistics (ACL) , pages 1736–1745.
Min et al. (2019a) Sewon Min, Danqi Chen, Hannaneh Hajishirzi, and Luke Zettlemoyer. 2019a. A discrete hard EM approach for weakly supervised question answering. In Empirical Methods in Natural Language Processing (EMNLP) .
Min et al. (2019b) Sewon Min, Danqi Chen, Luke Zettlemoyer, and Hannaneh Hajishirzi. 2019b. Knowledge guided text retrieval and reading for open domain question answering. ArXiv , abs/1911.03868.
Moldovan et al. (2003) Dan Moldovan, Marius Paşca, Sanda Harabagiu, and Mihai Surdeanu. 2003. Performance issues and error analysis in an open-domain question answering system. ACM Transactions on Information Systems (TOIS) , 21(2):133–154.
Mussmann and Ermon (2016) Stephen Mussmann and Stefano Ermon. 2016. Learning and inference via maximum inner product search. In International Conference on Machine Learning (ICML) , pages 2587–2596.
Nie et al. (2019) Yixin Nie, Songhe Wang, and Mohit Bansal. 2019. Revealing the importance of semantic retrieval for machine reading at scale. In Empirical Methods in Natural Language Processing (EMNLP) .
Nogueira and Cho (2019) Rodrigo Nogueira and Kyunghyun Cho. 2019. Passage re-ranking with BERT. ArXiv , abs/1901.04085.
Raffel et al. (2019) Colin Raffel, Noam Shazeer, Adam Roberts, Katherine Lee, Sharan Narang, Michael Matena, Yanqi Zhou, Wei Li, and Peter J Liu. 2019. Exploring the limits of transfer learning with a unified text-to-text transformer. ArXiv , abs/1910.10683.
Rajpurkar et al. (2016) Pranav Rajpurkar, Jian Zhang, Konstantin Lopyrev, and Percy Liang. 2016. SQuAD: 100,000+ questions for machine comprehension of text. In Empirical Methods in Natural Language Processing (EMNLP) , pages 2383–2392.
Ram and Gray (2012) Parikshit Ram and Alexander G Gray. 2012. Maximum inner-product search using cone trees. In Proceedings of the 18th ACM SIGKDD international conference on Knowledge discovery and data mining , pages 931–939.
Roberts et al. (2020) Adam Roberts, Colin Raffel, and Noam Shazeer. 2020. How much knowledge can you pack into the parameters of a language model? ArXiv , abs/2002.08910.
Robertson and Zaragoza (2009) Stephen Robertson and Hugo Zaragoza. 2009. The probabilistic relevance framework: BM25 and beyond. Foundations and Trends in Information Retrieval , 3(4):333–389.
Seo et al. (2019) Minjoon Seo, Jinhyuk Lee, Tom Kwiatkowski, Ankur Parikh, Ali Farhadi, and Hannaneh Hajishirzi. 2019. Real-time open-domain question answering with dense-sparse phrase index. In Association for Computational Linguistics (ACL) .
Shrivastava and Li (2014) Anshumali Shrivastava and Ping Li. 2014. Asymmetric LSH (ALSH) for sublinear time maximum inner product search (MIPS). In Advances in Neural Information Processing Systems (NIPS) , pages 2321–2329.
Voorhees (1999) Ellen M Voorhees. 1999. The TREC-8 question answering track report. In TREC , volume 99, pages 77–82.
Wang et al. (2018) Shuohang Wang, Mo Yu, Xiaoxiao Guo, Zhiguo Wang, Tim Klinger, Wei Zhang, Shiyu Chang, Gerry Tesauro, Bowen Zhou, and Jing Jiang. 2018. Rˆ3: Reinforced ranker-reader for open-domain question answering. In Conference on Artificial Intelligence (AAAI) .
Wang et al. (2019) Zhiguo Wang, Patrick Ng, Xiaofei Ma, Ramesh Nallapati, and Bing Xiang. 2019. Multi-passage BERT: A globally normalized bert model for open-domain question answering. In Empirical Methods in Natural Language Processing (EMNLP) .
Wolfson et al. (2020) Tomer Wolfson, Mor Geva, Ankit Gupta, Matt Gardner, Yoav Goldberg, Daniel Deutch, and Jonathan Berant. 2020. Break it down: A question understanding benchmark. Transactions of the Association of Computational Linguistics (TACL) .
Xiong et al. (2020a) Lee Xiong, Chenyan Xiong, Ye Li, Kwok-Fung Tang, Jialin Liu, Paul Bennett, Junaid Ahmed, and Arnold Overwijk. 2020a. Approximate nearest neighbor negative contrastive learning for dense text retrieval. ArXiv , abs/2007.00808.
Xiong et al. (2020b) Wenhan Xiong, Hankang Wang, and William Yang Wang. 2020b. Progressively pretrained dense corpus index for open-domain question answering. ArXiv , abs/2005.00038.
Yang et al. (2019a) Wei Yang, Yuqing Xie, Aileen Lin, Xingyu Li, Luchen Tan, Kun Xiong, Ming Li, and Jimmy Lin. 2019a. End-to-end open-domain question answering with bertserini. In North American Association for Computational Linguistics (NAACL) , pages 72–77.
Yang et al. (2019b) Wei Yang, Yuqing Xie, Luchen Tan, Kun Xiong, Ming Li, and Jimmy Lin. 2019b. Data augmentation for bert fine-tuning in open-domain question answering. ArXiv , abs/1904.06652.
Yih et al. (2011) Wen-tau Yih, Kristina Toutanova, John C Platt, and Christopher Meek. 2011. Learning discriminative projections for text similarity measures. In Computational Natural Language Learning (CoNLL) , pages 247–256.
Appendix A Distant Supervision
附录 A 远距离监督
When training our final DPR model using Natural Questions, we use the passages in our collection that best match the gold context as the positive passages. As some QA datasets contain only the question and answer pairs, it is thus interesting to see when using the passages that contain the answers as positives (i.e., the distant supervision setting), whether there is a significant performance degradation. Using the question and answer together as the query, we run Lucene-BM25 and pick the top passage that contains the answer as the positive passage. Table 5 shows the performance of DPR when trained using the original setting and the distant supervision setting.
在 Natural Questions 上训练最终的 DPR 模型时,我们把集合中与黄金上下文最匹配的段落当作正段落。由于有些问答数据集只包含问题–答案对,因此有必要考察:若改用包含答案的段落作为正例(也就是远距离监督设定),表现是否会明显下降。我们把问题与答案一起当作查询,运行 Lucene-BM25,并挑选包含答案的最靠前段落作为正段落。表 5 给出了 DPR 在原始设定与远距离监督设定下训练时的表现。
Appendix B Alternative Similarity Functions & Triplet Loss
附录 B 其他相似度函数与三元组损失
In addition to dot product (DP) and negative log-likelihood based on softmax (NLL), we also experiment with Euclidean distance (L2) and the triplet loss. We negate L2 similarity scores before applying softmax and change signs of question-to-positive and question-to-negative similarities when applying the triplet loss on dot product scores. The margin value of the triplet loss is set to 1. Table 6 summarizes the results. All these additional experiments are conducted using the same hyper-parameters tuned for the baseline (DP, NLL).
除点积(DP)和基于 softmax 的负对数似然(NLL)外,我们还实验了欧氏距离(L2)和三元组损失。在把 L2 相似度送入 softmax 之前先取反;在点积分数上使用三元组损失时,则改变问题到正例、问题到负例相似度的符号。三元组损失的间隔值设为 1。表 6 汇总了结果。这些额外实验都使用为基线(DP,NLL)调好的同一组超参数。
Note that the retrieval accuracy for our “baseline” settings reported in Table 5 (Gold) and Table 6 (DP, NLL) is slightly better than those reported in Table 3. This is due to a better hyper-parameter setting used in these analysis experiments, which is documented in our code release.
需要注意,表 5(黄金)和表 6(DP,NLL)中报告的“基线”设定检索准确率,略好于表 3 中的相应数字。这是因为这些分析实验使用了更好的超参数设置,相关设置记录在我们发布的代码中。
Appendix C Qualitative Analysis
附录 C 定性分析
Although DPR performs better than BM25 in general, the retrieved passages of these two retrievers actually differ qualitatively. Methods like BM25 are sensitive to highly selective keywords and phrases, but cannot capture lexical variations or semantic relationships well. In contrast, DPR excels at semantic representation, but might lack sufficient capacity to represent salient phrases which appear rarely. Table 7 illustrates this phenomenon with two examples. In the first example, the top scoring passage from BM25 is irrelevant, even though keywords such as England and Ireland appear multiple times. In comparison, DPR is able to return the correct answer, presumably by matching “body of water” with semantic neighbors such as sea and channel, even though no lexical overlap exists. The second example is one where BM25 does better. The salient phrase “Thoros of Myr” is critical, and DPR is unable to capture it.
尽管 DPR 总体上好于 BM25,两种检索器取回的段落在性质上其实并不相同。BM25 这类方法对区分度很高的关键词和短语很敏感,但不善于捕捉词汇变化或语义关系。相比之下,DPR 擅长语义表示,但对很少出现的显著短语,表征能力可能不够。表 7 用两个例子说明这一现象。第一个例子里,BM25 得分最高的段落并不相关,尽管 England 和 Ireland 这类关键词多次出现。DPR 则能返回正确答案,大概是因为把“body of water”与 sea、channel 这类语义近邻对应起来,尽管没有词汇重叠。第二个例子是 BM25 做得更好的情形。显著短语“Thoros of Myr”很关键,而 DPR 没能抓住它。
| Top-1 | Top-5 | Top-20 | Top-100 | |
|---|---|---|---|---|
| Gold | 44.9 | 66.8 | 78.1 | 85.0 |
| Dist. Sup. | 43.9 | 65.3 | 77.1 | 84.4 |
Table 5: Retrieval accuracy on the development set of Natural Questions, trained on passages that match the gold context (Gold) or the top BM25 passage that contains the answer (Dist. Sup.).
| Top-1 | Top-5 | Top-20 | Top-100 | |
|---|---|---|---|---|
| 黄金 | 44.9 | 66.8 | 78.1 | 85.0 |
| 远监督 | 43.9 | 65.3 | 77.1 | 84.4 |
表 5:Natural Questions 开发集上的检索准确率,分别用与黄金上下文匹配的段落(黄金)或包含答案的最靠前 BM25 段落(远监督)训练。
| Sim | Loss | Retrieval Accuracy | |||
|---|---|---|---|---|---|
| Top-1 | Top-5 | Top-20 | Top-100 | ||
| DP | NLL | 44.9 | 66.8 | 78.1 | 85.0 |
| Triplet | 41.6 | 65.0 | 77.2 | 84.5 | |
| L2 | NLL | 43.5 | 64.7 | 76.1 | 83.1 |
| Triplet | 42.2 | 66.0 | 78.1 | 84.9 |
Table 6: Retrieval Top- accuracy on the development set of Natural Questions using different similarity and loss functions.
| 相似度 | 损失 | 检索准确率 | |||
|---|---|---|---|---|---|
| Top-1 | Top-5 | Top-20 | Top-100 | ||
| DP | NLL | 44.9 | 66.8 | 78.1 | 85.0 |
| 三元组 | 41.6 | 65.0 | 77.2 | 84.5 | |
| L2 | NLL | 43.5 | 64.7 | 76.1 | 83.1 |
| 三元组 | 42.2 | 66.0 | 78.1 | 84.9 |
表 6:在 Natural Questions 开发集上,使用不同相似度和损失函数时的检索 Top- 准确率。
| Question | Passage received by BM25 | Passage retrieved by DPR |
|---|---|---|
| What is the body of water between England and Ireland? | Title:British Cycling | Title: Irish Sea |
| …England is not recognised as a region by the UCI, and there is no English cycling team outside the Commonwealth Games. For those occasions, British Cycling selects and supports the England team. Cycling is represented on the Isle of Man by the Isle of Man Cycling Association. Cycling in Northern Ireland is organised under Cycling Ulster, part of the all-Ireland governing body Cycling Ireland. Until 2006, a rival governing body existed, … | …Annual traffic between Great Britain and Ireland amounts to over 12 million passengers and of traded goods. The Irish Sea is connected to the North Atlantic at both its northern and southern ends. To the north, the connection is through the North Channel between Scotland and Northern Ireland and the Malin Sea. The southern end is linked to the Atlantic through the St George’s Channel between Ireland and Pembrokeshire, and the Celtic Sea. … | |
| Who plays Thoros of Myr in Game of Thrones? | Title: No One (Game of Thrones) | Title: Pål Sverre Hagen |
| …He may be ”no one,” but there’s still enough of a person left in him to respect, and admire who this girl is and what she’s become. Arya finally tells us something that we’ve kind of known all along, that she’s not no one, she’s Arya Stark of Winterfell.” ”No One” saw the reintroduction of Richard Dormer and Paul Kaye, who portrayed Beric Dondarrion and Thoros of Myr, respectively, in the third season, … | Pål Sverre Valheim Hagen (born 6 November 1980) is a Norwegian stage and screen actor. He appeared in the Norwegian film ”Max Manus” and played Thor Heyerdahl in the Oscar-nominated 2012 film ”Kon-Tiki”. Pål Hagen was born in Stavanger, Norway, the son of Roar Hagen, a Norwegian cartoonist who has long been associated with Norwayś largest daily, ”VG”. He lived in Jåtten, a neighborhood in the city of Stavanger in south-western Norway. … |
Table 7: Examples of passages returned from BM25 and DPR. Correct answers are written in blue and the content words in the question are written in bold.
| 问题 | BM25 返回的段落 | DPR 检索到的段落 |
|---|---|---|
| What is the body of water between England and Ireland? | Title:British Cycling | Title: Irish Sea |
| …England is not recognised as a region by the UCI, and there is no English cycling team outside the Commonwealth Games. For those occasions, British Cycling selects and supports the England team. Cycling is represented on the Isle of Man by the Isle of Man Cycling Association. Cycling in Northern Ireland is organised under Cycling Ulster, part of the all-Ireland governing body Cycling Ireland. Until 2006, a rival governing body existed, … | …Annual traffic between Great Britain and Ireland amounts to over 12 million passengers and of traded goods. The Irish Sea is connected to the North Atlantic at both its northern and southern ends. To the north, the connection is through the North Channel between Scotland and Northern Ireland and the Malin Sea. The southern end is linked to the Atlantic through the St George’s Channel between Ireland and Pembrokeshire, and the Celtic Sea. … | |
| Who plays Thoros of Myr in Game of Thrones? | Title: No One (Game of Thrones) | Title: Pål Sverre Hagen |
| …He may be ”no one,” but there’s still enough of a person left in him to respect, and admire who this girl is and what she’s become. Arya finally tells us something that we’ve kind of known all along, that she’s not no one, she’s Arya Stark of Winterfell.” ”No One” saw the reintroduction of Richard Dormer and Paul Kaye, who portrayed Beric Dondarrion and Thoros of Myr, respectively, in the third season, … | Pål Sverre Valheim Hagen (born 6 November 1980) is a Norwegian stage and screen actor. He appeared in the Norwegian film ”Max Manus” and played Thor Heyerdahl in the Oscar-nominated 2012 film ”Kon-Tiki”. Pål Hagen was born in Stavanger, Norway, the son of Roar Hagen, a Norwegian cartoonist who has long been associated with Norwayś largest daily, ”VG”. He lived in Jåtten, a neighborhood in the city of Stavanger in south-western Norway. … |
表 7:BM25 与 DPR 返回段落的例子。正确答案用蓝色标出,问题中的内容词用粗体标出。
Appendix D Joint Training of Retriever and Reader
附录 D 检索器与阅读器的联合训练
We fix the passage encoder in our joint-training scheme while allowing only the question encoder to receive backpropagation signal from the combined (retriever + reader) loss function. This allows us to leverage the HNSW-based FAISS index for efficient low-latency retrieving, without reindexing the passages during model updates. Our loss function largely follows ORQA’s approach, which uses log probabilities of positive passages selected from the retriever model, and correct spans and passages selected from the reader model. Since the passage encoder is fixed, we could use larger amount of retrieved passages when calculating the retriever loss. Specifically, we get top 100 passages for each question in a mini-batch and use the method similar to in-batch negative training: all retrieved passages’ vectors participate in the loss calculation for all questions in a batch. Our training batch size is set to 16, which effectively gives 1,600 passages per question to calculate retriever loss. The reader still uses 24 passages per question, which are selected from the top 5 positive and top 30 negative passages (from the set of top 100 passages retrieved from the same question). The question encoder’s initial state is taken from a DPR model previously trained on the NQ dataset. The reader’s initial state is a BERT-base model. In terms of the end-to-end QA results, our joint-training scheme does not provide better results compared to the usual retriever/reader training pipeline, resulting in the same 39.8 exact match score on NQ dev as in our regular reader model training.
在联合训练方案中,我们固定段落编码器,只让问题编码器从组合(检索器 + 阅读器)损失函数接收反向传播信号。这样就可以利用基于 HNSW 的 FAISS 索引做低延迟检索,而不必在模型更新时重新索引段落。损失函数大体沿用 ORQA 的做法:使用检索器模型选出的正段落的对数概率,以及阅读器模型选出的正确片段与段落的对数概率。由于段落编码器是固定的,计算检索器损失时可以使用更多检索到的段落。具体地,我们为小批次中的每个问题取前 100 个段落,并用类似于批内负例训练的方法:所有检索到的段落向量都参与该批次所有问题的损失计算。训练批次大小设为 16,这实际上为每个问题提供 1,600 个段落来计算检索器损失。阅读器仍对每个问题使用 24 个段落,它们选自同一问题检索出的前 100 个段落中最靠前的 5 个正段落和最靠前的 30 个负段落。问题编码器的初始状态来自先前在 NQ 数据集上训练好的 DPR 模型。阅读器的初始状态是 BERT-base 模型。就端到端问答结果而言,联合训练方案并不比通常的检索器/阅读器训练流水线更好,在 NQ 开发集上得到的精确匹配分数同为 39.8,与常规阅读器训练相同。