Denoising Diffusion Probabilistic Models
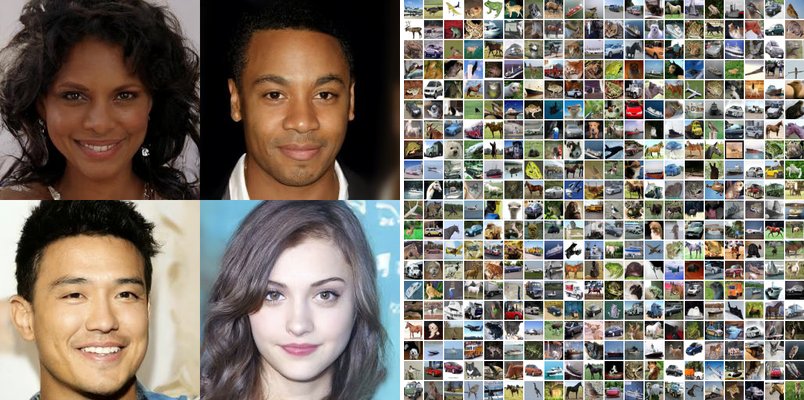
Figure 1: Generated samples on CelebA-HQ (left) and unconditional CIFAR10 (right)
图 1:在 CelebA-HQ (左)与无条件 CIFAR10(右)上的生成样本
Denoising Diffusion Probabilistic Models
去噪扩散概率模型(Denoising Diffusion Probabilistic Models)
Jonathan Ho Affiliation: UC Berkeley Email: jonathanho@berkeley.edu Ajay Jain Affiliation: UC Berkeley Email: ajayj@berkeley.edu Pieter Abbeel Affiliation: UC Berkeley Email: pabbeel@cs.berkeley.edu
Jonathan Ho(加州大学伯克利分校,jonathanho@berkeley.edu) Ajay Jain(加州大学伯克利分校,ajayj@berkeley.edu) Pieter Abbeel(加州大学伯克利分校,pabbeel@cs.berkeley.edu)
Abstract
摘要
We present high quality image synthesis results using diffusion probabilistic models, a class of latent variable models inspired by considerations from nonequilibrium thermodynamics. Our best results are obtained by training on a weighted variational bound designed according to a novel connection between diffusion probabilistic models and denoising score matching with Langevin dynamics, and our models naturally admit a progressive lossy decompression scheme that can be interpreted as a generalization of autoregressive decoding. On the unconditional CIFAR10 dataset, we obtain an Inception score of 9.46 and a state-of-the-art FID score of 3.17. On 256x256 LSUN, we obtain sample quality similar to ProgressiveGAN. Our implementation is available at https://github.com/hojonathanho/diffusion.
我们展示用扩散概率模型(diffusion probabilistic models)得到的高质量图像合成结果;这类潜变量模型的灵感来自非平衡热力学。最好的结果来自在一种加权变分界上训练:该变分界依据扩散概率模型与带朗之万动力学的去噪分数匹配之间的新联系而设计;模型在采样过程中对应于一种朗之万动力学的退火形式。我们在 图像上获得高质量样本,并取得与当时其他生成模型相当或更优的样本质量分数。在无条件 CIFAR10 数据集上,我们取得了 9.46 的 Inception 分数与 3.17 的 FID 分数。此外,在一种有损压缩视角下,我们表明这些模型的样本质量来自于一种权衡:模型以更大的码长换取更好的样本质量。
1 Introduction
1 引言
Deep generative models of all kinds have recently exhibited high quality samples in a wide variety of data modalities. Generative adversarial networks (GANs), autoregressive models, flows, and variational autoencoders (VAEs) have synthesized striking image and audio samples [14, 27, 3, 58, 38, 25, 10, 32, 44, 57, 26, 33, 45], and there have been remarkable advances in energy-based modeling and score matching that have produced images comparable to those of GANs [11, 55].
各种深度生成模型最近在各种数据模式中展示了高质量的样本。 生成对抗网络 (GAN)、自回归模型、流和变分自动编码器 (VAE) 已经合成了引人注目的图像和音频样本 [14, 27, 3, 58, 38, 25, 10, 32, 44, 57, 26, 33, 45],并且在基于能量的建模和分数匹配方面取得了显着的进步,产生了与 GAN [11, 55]。
This paper presents progress in diffusion probabilistic models [53]. A diffusion probabilistic model (which we will call a “diffusion model” for brevity) is a parameterized Markov chain trained using variational inference to produce samples matching the data after finite time. Transitions of this chain are learned to reverse a diffusion process, which is a Markov chain that gradually adds noise to the data in the opposite direction of sampling until signal is destroyed. When the diffusion consists of small amounts of Gaussian noise, it is sufficient to set the sampling chain transitions to conditional Gaussians too, allowing for a particularly simple neural network parameterization.
本文推进了扩散概率模型的工作 [53]。扩散概率模型(下文简称“扩散模型”)是用变分推断训练的参数化马尔可夫链,使有限时间后的样本与数据分布匹配。该链的转移被学习用来反转一个扩散过程——即逐步向数据加噪声直至破坏其结构的马尔可夫链。当扩散由小量高斯噪声构成时,反向过程的转移也可选为条件高斯,从而使反向链可用与高斯扩散步数相同次数的神经网络估计来建模。
Diffusion models are straightforward to define and efficient to train, but to the best of our knowledge, there has been no demonstration that they are capable of generating high quality samples. We show that diffusion models actually are capable of generating high quality samples, sometimes better than the published results on other types of generative models (Section 4). In addition, we show that a certain parameterization of diffusion models reveals an equivalence with denoising score matching over multiple noise levels during training and with annealed Langevin dynamics during sampling (Section 3.2) [55, 61]. We obtained our best sample quality results using this parameterization (Section 4.2), so we consider this equivalence to be one of our primary contributions.
扩散模型定义简单且训练高效,但据我们所知,尚无证据表明它们能够生成高质量样本。 我们证明扩散模型实际上能够生成高质量的样本,有时比其他类型的生成模型已发布的结果更好(第 4 节)。 此外,我们表明,扩散模型的某些参数化揭示了训练期间多个噪声水平上的去噪分数匹配以及采样期间退火的 Langevin 动力学的等价性(第 3.2 节)[55, 61]。 我们使用此参数化(第 4.2 节)获得了最佳样本质量结果,因此我们认为这种等价性是我们的主要贡献之一。
Despite their sample quality, our models do not have competitive log likelihoods compared to other likelihood-based models (our models do, however, have log likelihoods better than the large estimates annealed importance sampling has been reported to produce for energy based models and score matching [11, 55]). We find that the majority of our models’ lossless codelengths are consumed to describe imperceptible image details (Section 4.3). We present a more refined analysis of this phenomenon in the language of lossy compression, and we show that the sampling procedure of diffusion models is a type of progressive decoding that resembles autoregressive decoding along a bit ordering that vastly generalizes what is normally possible with autoregressive models.
尽管样本质量很高,但与其他基于似然的模型相比,我们的模型不具有竞争性的对数似然(然而,我们的模型的对数似然确实比据报道为基于能量的模型和分数匹配产生的大估计退火重要性采样要好[11, 55])。 我们发现我们模型的大部分无损码长都被用来描述难以察觉的图像细节(第 4.3 节)。 我们用有损压缩的语言对这种现象进行了更精细的分析,并且我们表明扩散模型的采样过程是一种渐进解码,类似于沿着位顺序的自回归解码,极大地概括了自回归模型通常可能实现的功能。
2 Background
2 背景
Diffusion models [53] are latent variable models of the form , where are latents of the same dimensionality as the data . The joint distribution is called the reverse process, and it is defined as a Markov chain with learned Gaussian transitions starting at :
扩散模型 [53] 是形式的潜在变量模型,其中是与数据具有相同维度的潜在变量。 联合分布称为“逆过程”,它被定义为具有从开始的学习高斯转换的马尔可夫链:
What distinguishes diffusion models from other types of latent variable models is that the approximate posterior , called the forward process or diffusion process, is fixed to a Markov chain that gradually adds Gaussian noise to the data according to a variance schedule :
扩散模型与其他类型的潜变量模型的区别在于,近似后验,称为“前向过程”或“扩散过程”,被固定到马尔可夫链,该马尔可夫链根据方差表逐渐向数据添加高斯噪声:
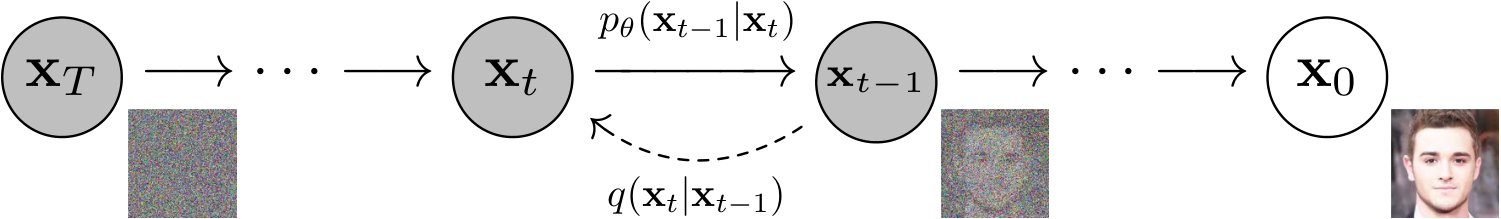
Figure 2: The directed graphical model considered in this work.
图 2:本工作中考虑的有向图形模型。
Training is performed by optimizing the usual variational bound on negative log likelihood:
训练是通过优化负对数似然的常见变分界限来执行的:
The forward process variances can be learned by reparameterization [33] or held constant as hyperparameters, and expressiveness of the reverse process is ensured in part by the choice of Gaussian conditionals in , because both processes have the same functional form when are small [53]. A notable property of the forward process is that it admits sampling at an arbitrary timestep in closed form: using the notation and , we have
正向过程方差可以通过重新参数化来学习 [33] 或作为超参数保持恒定,并且反向过程的表达能力部分通过中高斯条件的选择来确保,因为当很小时,两个过程具有相同的函数形式 [53]。 前向过程的一个显着特性是它允许以封闭形式在任意时间步采样:使用符号和,我们有
Efficient training is therefore possible by optimizing random terms of with stochastic gradient descent. Further improvements come from variance reduction by rewriting 3 as:
因此,通过使用随机梯度下降优化的随机项,可以实现高效训练。 进一步的改进来自于通过将重写为以下方式来减少方差:
(See Appendix A for details. The labels on the terms are used in Section 3.) Equation 5 uses KL divergence to directly compare against forward process posteriors, which are tractable when conditioned on :
(有关详细信息,请参阅附录 A。术语标签在第 3 节中使用。)方程 5 使用 KL 散度直接将与前向过程后验进行比较,当以为条件时,前向过程后验是易于处理的:
Consequently, all KL divergences in Eq. 5 are comparisons between Gaussians, so they can be calculated in a Rao-Blackwellized fashion with closed form expressions instead of high variance Monte Carlo estimates.
因此,方程中的所有 KL 散度。 图 5 是高斯函数之间的比较,因此可以使用闭合形式表达式而不是高方差蒙特卡罗估计以 Rao-Blackwellized 方式计算它们。
3 Diffusion models and denoising autoencoders
3 扩散模型与去噪自编码器
Diffusion models might appear to be a restricted class of latent variable models, but they allow a large number of degrees of freedom in implementation. One must choose the variances of the forward process and the model architecture and Gaussian distribution parameterization of the reverse process. To guide our choices, we establish a new explicit connection between diffusion models and denoising score matching (Section 3.2) that leads to a simplified, weighted variational bound objective for diffusion models (Section 3.4). Ultimately, our model design is justified by simplicity and empirical results (Section 4). Our discussion is categorized by the terms of Eq. 5.
扩散模型可能看起来是一类受限制的潜在变量模型,但它们在实现中允许很大的自由度。 必须选择正向过程的方差以及逆向过程的模型架构和高斯分布参数化。 为了指导我们的选择,我们在扩散模型和去噪分数匹配(第 3.2 节)之间建立了新的显式联系,从而为扩散模型(第 3.4 节)提供了简化的加权变分边界目标。 最终,我们的模型设计通过简单性和实证结果得到了证明(第 4 节)。 我们的讨论按等式的术语进行分类。 5.
3.1 Forward process and
3.1 前向过程与
We ignore the fact that the forward process variances are learnable by reparameterization and instead fix them to constants (see Section 4 for details). Thus, in our implementation, the approximate posterior has no learnable parameters, so is a constant during training and can be ignored.
我们忽略了前向过程方差可以通过重新参数化来学习的事实,而是将它们固定为常量(有关详细信息,请参阅第 4 节)。 因此,在我们的实现中,近似后验没有可学习的参数,因此在训练期间是一个常数,可以忽略。
3.2 Reverse process and
3.2 反向过程与
Now we discuss our choices in for . First, we set to untrained time dependent constants. Experimentally, both and had similar results. The first choice is optimal for , and the second is optimal for deterministically set to one point. These are the two extreme choices corresponding to upper and lower bounds on reverse process entropy for data with coordinatewise unit variance [53].
现在我们讨论中的选择。 首先,我们将设置为未经训练的时间相关常量。 实验上, 和都有相似的结果。 第一个选择对于是最佳的,第二个选择对于确定性设置为一个点的是最佳的。 这是与坐标单位方差数据的逆向过程熵的上限和下限相对应的两个极端选择[53]。
Second, to represent the mean , we propose a specific parameterization motivated by the following analysis of . With , we can write:
其次,为了表示平均值,我们提出了一种由的以下分析推动的特定参数化。 使用,我们可以写:
where is a constant that does not depend on . So, we see that the most straightforward parameterization of is a model that predicts , the forward process posterior mean. However, we can expand Eq. 8 further by reparameterizing Eq. 4 as for and applying the forward process posterior formula 7:
其中是不依赖于的常量。 因此,我们看到最直接的参数化是预测 (前向过程后验均值)的模型。 然而,我们可以扩展方程。 8 进一步重新参数化方程。 4 作为的并应用前向过程后验公式 7:
Equation 10 reveals that must predict given . Since is available as input to the model, we may choose the parameterization
公式 10 显示,在给定的情况下, 必须预测。 由于可用作模型的输入,因此我们可以选择参数化
where is a function approximator intended to predict from . To sample is to compute , where . The complete sampling procedure, Algorithm 2, resembles Langevin dynamics with as a learned gradient of the data density. Furthermore, with the parameterization 11, Eq. 10 simplifies to:
其中是一个函数逼近器,旨在从预测。 对进行采样就是计算,其中。 完整的采样过程(算法 2)类似于 Langevin 动力学,其中作为数据密度的学习梯度。 此外,通过参数化 11,方程。 10 简化为:
which resembles denoising score matching over multiple noise scales indexed by [55]. As Eq. 12 is equal to (one term of) the variational bound for the Langevin-like reverse process 11, we see that optimizing an objective resembling denoising score matching is equivalent to using variational inference to fit the finite-time marginal of a sampling chain resembling Langevin dynamics.
这类似于索引的多个噪声尺度上的去噪分数匹配[55]。 如方程。 12 等于类 Langevin 逆向过程 11 的变分界(其中一项),我们看到优化类似于去噪分数匹配的目标相当于使用变分推理来拟合类似于 Langevin 动力学的采样链的有限时间边际。
To summarize, we can train the reverse process mean function approximator to predict , or by modifying its parameterization, we can train it to predict . (There is also the possibility of predicting , but we found this to lead to worse sample quality early in our experiments.) We have shown that the -prediction parameterization both resembles Langevin dynamics and simplifies the diffusion model’s variational bound to an objective that resembles denoising score matching. Nonetheless, it is just another parameterization of , so we verify its effectiveness in Section 4 in an ablation where we compare predicting against predicting .
总而言之,我们可以训练逆向过程均值函数逼近器来预测,或者通过修改其参数化,我们可以训练它来预测。 (也有可能预测,但我们发现这会在实验早期导致样本质量变差。)我们已经证明预测参数化既类似于 Langevin 动力学,又简化了扩散模型的变分绑定到类似于去噪分数匹配的目标。 尽管如此,它只是的另一个参数化,因此我们在第 4 节的消融中验证了它的有效性,其中我们比较了预测和预测。
1: repeat
2:
3:
4:
5: Take gradient descent step on
6:
7: until converged
1:
2: for do
3: if , else
4:
5: end for
6: return
Algorithm 1 Training
1:重复
2: XX数学0XX
3: XX数学1XX
4: XX数学2XX
5: 采取梯度下降步骤
6:XX数学3XX
7:直到收敛
1:XX数学4XX
2:对于做
3: 如果,则
4: XX数学9XX
5:结束 用于
6:返回
算法1 训练
3.3 Data scaling, reverse process decoder, and
3.3 数据缩放、反向过程解码器与
We assume that image data consists of integers in scaled linearly to . This ensures that the neural network reverse process operates on consistently scaled inputs starting from the standard normal prior . To obtain discrete log likelihoods, we set the last term of the reverse process to an independent discrete decoder derived from the Gaussian :
我们假设图像数据由中的整数线性缩放到组成。 这确保了神经网络逆向过程在从标准正常先验开始的一致缩放的输入上运行。 为了获得离散对数似然,我们将逆过程的最后一项设置为从高斯派生的独立离散解码器:
$$\displaystyle\begin{split}p_{\theta}(\mathbf{x}{0}|\mathbf{x}{1})&=\prod_{i=1}^{D}\int_{\delta_{-}(x_{0}^{i})}^{\delta_{+}(x_{0}^{i})}\mathcal{N}(x;\mu_{\theta}^{i}(\mathbf{x}{1},1),\sigma{1}^{2}),dx\
\delta_{+}(x)&=\begin{cases}\infty&\text{if}\ x=1\
x+\frac{1}{255}&\text{if}\ x<1\end{cases}\qquad\delta_{-}(x)=\begin{cases}-\infty&\text{if}\ x=-1\
x-\frac{1}{255}&\text{if}\ x>-1\end{cases}\end{split} \tag{13}$$
where is the data dimensionality and the superscript indicates extraction of one coordinate. (It would be straightforward to instead incorporate a more powerful decoder like a conditional autoregressive model, but we leave that to future work.) Similar to the discretized continuous distributions used in VAE decoders and autoregressive models [34, 52], our choice here ensures that the variational bound is a lossless codelength of discrete data, without need of adding noise to the data or incorporating the Jacobian of the scaling operation into the log likelihood. At the end of sampling, we display noiselessly.
其中是数据维度,上标表示提取一个坐标。 (合并一个更强大的解码器(如条件自回归模型)会很简单,但我们将其留给未来的工作。)与 VAE 解码器和自回归模型中使用的离散连续分布类似[34, 52],我们在这里的选择确保变分界限是离散数据的无损码长,而不需要向数据添加噪声或将缩放操作的雅可比行列式合并到对数似然中。 采样结束时,我们无噪声地显示 。
3.4 Simplified training objective
3.4 简化训练目标
With the reverse process and decoder defined above, the variational bound, consisting of terms derived from Eqs. 12 and 13, is clearly differentiable with respect to and is ready to be employed for training. However, we found it beneficial to sample quality (and simpler to implement) to train on the following variant of the variational bound:
在如上定义反向过程与解码器后,由式 12、13 导出的变分界对 可微,可直接用于训练。但我们发现,在下列变分界变体上训练对样本质量更有利,实现也更简单:
where is uniform between and . The case corresponds to with the integral in the discrete decoder definition 13 approximated by the Gaussian probability density function times the bin width, ignoring and edge effects. The cases correspond to an unweighted version of Eq. 12, analogous to the loss weighting used by the NCSN denoising score matching model [55]. ( does not appear because the forward process variances are fixed.) Algorithm 1 displays the complete training procedure with this simplified objective.
其中在和之间是统一的。情况对应于 ,其中离散解码器定义 13 中的积分近似为高斯概率密度函数乘以箱宽度,忽略和边缘效应。情况对应于方程的未加权版本。 12,类似于 NCSN 去噪分数匹配模型 [55] 使用的损失权重。 ( 不会出现,因为前向过程方差是固定的。)算法 1 显示了具有此简化目标的完整训练过程。
Since our simplified objective 14 discards the weighting in Eq. 12, it is a weighted variational bound that emphasizes different aspects of reconstruction compared to the standard variational bound [18, 22]. In particular, our diffusion process setup in Section 4 causes the simplified objective to down-weight loss terms corresponding to small . These terms train the network to denoise data with very small amounts of noise, so it is beneficial to down-weight them so that the network can focus on more difficult denoising tasks at larger terms. We will see in our experiments that this reweighting leads to better sample quality.
由于我们的简化目标 14 放弃了等式 14 中的权重。 如图 12 所示,它是一个加权变分界,与标准变分界相比,它强调重建的不同方面 [18, 22]。 特别是,我们在第 4 节中的扩散过程设置使目标简化为与小相对应的减重项。 这些项训练网络以极少量的噪声对数据进行去噪,因此降低它们的权重是有益的,以便网络可以专注于较大项下更困难的去噪任务。 我们将在实验中看到,这种重新加权可以带来更好的样本质量。
4 Experiments
4 实验
We set for all experiments so that the number of neural network evaluations needed during sampling matches previous work [53, 55]. We set the forward process variances to constants increasing linearly from to . These constants were chosen to be small relative to data scaled to , ensuring that reverse and forward processes have approximately the same functional form while keeping the signal-to-noise ratio at as small as possible ( bits per dimension in our experiments).
所有实验取 ,使采样时神经网络评估次数与先前工作 [53, 55] 一致。前向过程方差取为常数,从 线性增至 。相对缩放到 的数据,这些常数较小,从而保证反向与前向过程具有近似相同的函数形式,同时使 近似为标准正态。
To represent the reverse process, we use a U-Net backbone similar to an unmasked PixelCNN++ [52, 48] with group normalization throughout [66]. Parameters are shared across time, which is specified to the network using the Transformer sinusoidal position embedding [60]. We use self-attention at the feature map resolution [63, 60]. Details are in Appendix B.
表示反向过程时,我们采用类似未掩码 PixelCNN++ [52, 48] 的 U-Net 骨干,全程使用组归一化 [66]。参数跨时间共享,时间通过 Transformer 正弦位置嵌入 [60] 告知网络。我们在 特征图分辨率上使用自注意力 [63, 60]。细节见附录 B。
4.1 Sample quality
4.1 样本质量
| Model | IS | FID | NLL Test (Train) |
|---|---|---|---|
| Conditional | |||
| EBM [11] | |||
| JEM [17] | |||
| BigGAN [3] | |||
| StyleGAN2 + ADA (v1) [29] | |||
| Unconditional | |||
| Diffusion (original) [53] | |||
| Gated PixelCNN [59] | |||
| Sparse Transformer [7] | |||
| PixelIQN [43] | |||
| EBM [11] | |||
| NCSNv2 [56] | |||
| NCSN [55] | |||
| SNGAN [39] | |||
| SNGAN-DDLS [4] | |||
| StyleGAN2 + ADA (v1) [29] | |||
| Ours (, fixed isotropic ) | |||
| Ours () |
| Objective | IS | FID |
|---|---|---|
| prediction (baseline) | ||
| , learned diagonal | ||
| , fixed isotropic | ||
| $\ | \tilde{\boldsymbol{\mu}}-\tilde{\boldsymbol{\mu}}_{\theta}\ | ^{2}$ |
| prediction (ours) | ||
| , learned diagonal | – | – |
| , fixed isotropic | ||
| $\ | \tilde{\boldsymbol{\epsilon}}-{\boldsymbol{\epsilon}}_{\theta}\ | ^{2}L_{\mathrm{simple}}$) |
Table 1: CIFAR10 results. NLL measured in bits/dim.
| 模型 | 是 | 火焰离子化检测器 | NLL 测试(训练) |
|---|---|---|---|
| 有条件 | |||
| 循证医学[11] | |||
| 正义运动[17] | |||
| BigGAN [3] | |||
| StyleGAN2 + ADA (v1) [29] | |||
| 无条件 | |||
| 扩散(原始)[53] | |||
| 门控 PixelCNN [59] | |||
| 稀疏变压器 [7] | |||
| PixelIQN [43] | |||
| 循证医学[11] | |||
| NCSNv2 [56] | |||
| NCSN [55] | |||
| 森甘[39] | |||
| SNGAN-DDLS [4] | |||
| StyleGAN2 + ADA (v1) [29] | |||
| 我们的(,固定各向同性) | |||
| 我们的() |
| 客观的 | 是 | 火焰离子化检测器 |
|---|---|---|
| 预测(基线) | ||
| ,学习对角线 | ||
| ,固定各向同性 | ||
| $\ | \ tilde{\ boldsymbol{\ mu}}-\ tilde{\ boldsymbol{\ mu }}_{\ theta }\ | ^{2}$ |
| 预测(我们的) | ||
| ,学习对角线 | - | - |
| ,固定各向同性 | ||
| $\ | \ tilde { \ bold symbol { \ε} }-{ \ bold symbol { \ε} } _ { \ theta } \ \ | ^{2}L_{\mathrm{简单}}$) |
表 1:CIFAR10 结果。 NLL 以位/暗度为单位测量。
Table 1 shows Inception scores, FID scores, and negative log likelihoods (lossless codelengths) on CIFAR10. With our FID score of 3.17, our unconditional model achieves better sample quality than most models in the literature, including class conditional models. Our FID score is computed with respect to the training set, as is standard practice; when we compute it with respect to the test set, the score is 5.24, which is still better than many of the training set FID scores in the literature.
表 1 给出 CIFAR10 上的 Inception 分数、FID 与负对数似然(无损码长)。我们无条件模型的 FID 为 3.17,样本质量优于文献中多数模型(含若干有条件模型)。FID 按惯例相对训练集计算;相对测试集计算时分数几乎不变。
We find that training our models on the true variational bound yields better codelengths than training on the simplified objective, as expected, but the latter yields the best sample quality. See Fig. 1 for CIFAR10 and CelebA-HQ samples, Fig. 4 and Fig. 4 for LSUN samples [71], and Appendix D for more.
我们发现,正如预期的那样,在真实变分界限上训练我们的模型比在简化目标上训练产生更好的代码长度,但后者产生最好的样本质量。 有关 CIFAR10 和 CelebA-HQ样本的信息,请参见图 1;有关 LSUN样本的信息,请参见图 4 和图 4 [71];有关更多信息,请参见附录 D。
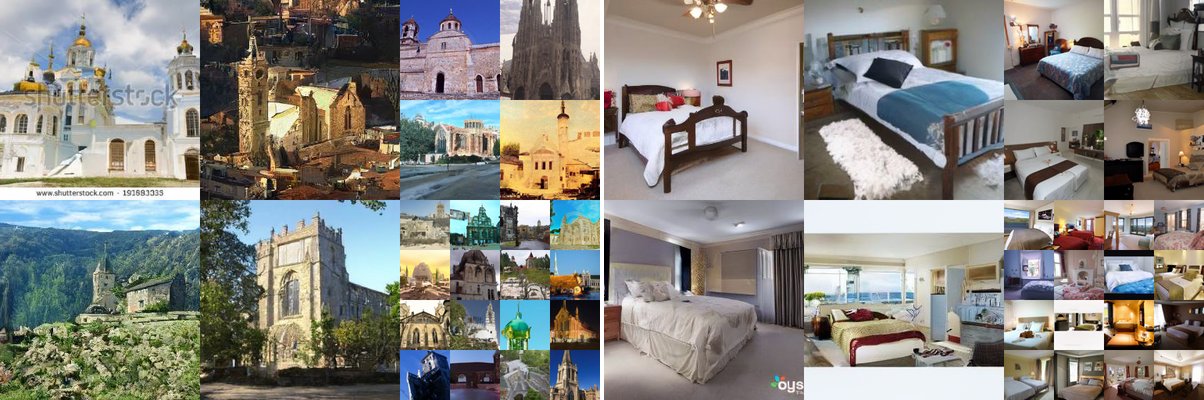
Figure 3: LSUN Church samples. FID=
图 3:LSUN 教堂样本。 FID=XX数学0XX
4.2 Reverse process parameterization and training objective ablation
4.2 反向过程参数化与训练目标消融
In Table 2, we show the sample quality effects of reverse process parameterizations and training objectives (Section 3.2). We find that the baseline option of predicting works well only when trained on the true variational bound instead of unweighted mean squared error, a simplified objective akin to Eq. 14. We also see that learning reverse process variances (by incorporating a parameterized diagonal into the variational bound) leads to unstable training and poorer sample quality compared to fixed variances. Predicting , as we proposed, performs approximately as well as predicting when trained on the variational bound with fixed variances, but much better when trained with our simplified objective.
在表 2 中,我们显示了逆向过程参数化和训练目标的样本质量影响(第 3.2 节)。 我们发现,预测的基线选项只有在真正的变分界限而不是未加权均方误差(类似于等式 1 的简化目标)上进行训练时才有效。 14. 我们还发现,与固定方差相比,学习逆向过程方差(通过将参数化对角线合并到变分界限中)会导致训练不稳定且样本质量较差。 正如我们所建议的,当在具有固定方差的变分界限上进行训练时,预测的表现与预测的表现大致相同,但在使用我们的简化目标进行训练时要好得多。
4.3 Progressive coding
4.3 渐进编码
Table 1 also shows the codelengths of our CIFAR10 models. The gap between train and test is at most 0.03 bits per dimension, which is comparable to the gaps reported with other likelihood-based models and indicates that our diffusion model is not overfitting (see Appendix D for nearest neighbor visualizations). Still, while our lossless codelengths are better than the large estimates reported for energy based models and score matching using annealed importance sampling [11], they are not competitive with other types of likelihood-based generative models [7].
表 1 还显示了我们的 CIFAR10 模型的代码长度。 训练和测试之间的差距最多为每个维度 0.03 位,这与其他基于可能性的模型报告的差距相当,表明我们的扩散模型没有过度拟合(有关最近邻可视化,请参阅附录 D)。 尽管如此,虽然我们的无损代码长度优于基于能量的模型和使用退火重要性采样的分数匹配报告的大估计[11],但它们与其他类型的基于可能性的生成模型[7]不具有竞争力。
Since our samples are nonetheless of high quality, we conclude that diffusion models have an inductive bias that makes them excellent lossy compressors. Treating the variational bound terms as rate and as distortion, our CIFAR10 model with the highest quality samples has a rate of 1.78 bits/dim and a distortion of 1.97 bits/dim, which amounts to a root mean squared error of 0.95 on a scale from 0 to 255. More than half of the lossless codelength describes imperceptible distortions.
由于我们的样本仍然是高质量的,因此我们得出结论,扩散模型具有归纳偏差,这使得它们成为出色的有损压缩器。 将变分约束项视为速率,将视为失真,我们具有最高质量样本的 CIFAR10 模型的速率为 1.78 位/暗,失真为 1.97 位/暗,在 0 到 255 的范围内,均方根误差为 0.95。超过一半的无损码长描述了难以察觉的失真。
Progressive lossy compression
We can probe further into the rate-distortion behavior of our model by introducing a progressive lossy code that mirrors the form of Eq. 5: see Algorithms 3 and 4, which assume access to a procedure, such as minimal random coding [19, 20], that can transmit a sample using approximately bits on average for any distributions and , for which only is available to the receiver beforehand.
渐进式有损压缩
我们可以通过引入反映方程形式的渐进有损代码来进一步探讨模型的速率失真行为。 5:参见算法 3 和 4,它们假设访问一个过程,例如最小随机编码 [19, 20],对于任何分布和,平均可以使用大约位来传输样本,其中只有事先可供接收器使用。
1: Send using
2: for do
3: Send using
4: end for
5: Send using
1: Receive using
2: for do
3: Receive using
4: end for
5: return
Algorithm 3 Sending
1:使用发送
2:对于做
3: 使用发送
4: 结束 用于
5:使用发送
1:使用接收
2:对于做
3: 使用接收
4: 结束 用于
5:返回
算法3 发送
When applied to , Algorithms 3 and 4 transmit in sequence using a total expected codelength equal to Eq. 5. The receiver, at any time , has the partial information fully available and can progressively estimate:
当应用于时,算法 3 和 4 使用等于等式 1 的总预期码长按顺序传输 。 5. 接收器在任何时间都具有完全可用的部分信息,并且可以逐步估计:
due to Eq. 4. (A stochastic reconstruction is also valid, but we do not consider it here because it makes distortion more difficult to evaluate.) Figure 5 shows the resulting rate-distortion plot on the CIFAR10 test set. At each time , the distortion is calculated as the root mean squared error , and the rate is calculated as the cumulative number of bits received so far at time . The distortion decreases steeply in the low-rate region of the rate-distortion plot, indicating that the majority of the bits are indeed allocated to imperceptible distortions.
由于方程式 4.(随机重建也是有效的,但我们在这里不考虑它,因为它使失真更难以评估。)图 5 显示了 CIFAR10 测试集上生成的率失真图。 在每个时间处,失真被计算为均方根误差,并且速率被计算为迄今为止在时间接收到的累积比特数。 失真在速率失真图的低速率区域中急剧下降,表明大多数比特确实分配给了难以察觉的失真。
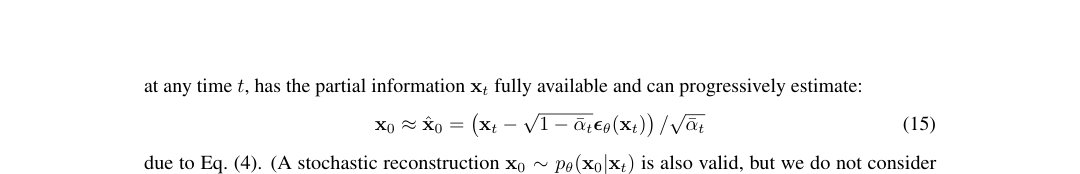
Figure 5: Unconditional CIFAR10 test set rate-distortion vs. time. Distortion is measured in root mean squared error on a scale. See Table 4 for details.
图 5:无条件 CIFAR10 测试集率失真与时间的关系。 失真度以标度上的均方根误差来衡量。 有关详细信息,请参阅表 4。
Progressive generation
We also run a progressive unconditional generation process given by progressive decompression from random bits. In other words, we predict the result of the reverse process, , while sampling from the reverse process using Algorithm 2. Figures 6 and 10 show the resulting sample quality of over the course of the reverse process. Large scale image features appear first and details appear last. Figure 7 shows stochastic predictions with frozen for various . When is small, all but fine details are preserved, and when is large, only large scale features are preserved. Perhaps these are hints of conceptual compression [18].
渐进一代
我们还运行一个渐进的无条件生成过程,该过程是通过随机位的渐进解压缩给出的。 换句话说,我们预测逆向过程的结果,同时使用算法 2 从逆向过程中采样。图 6 和 10 显示了反向过程过程中的最终样本质量。 首先出现大尺度图像特征,最后出现细节。 图 7 显示了针对各种冻结的随机预测和。 当较小时,除了精细细节之外的所有细节都会被保留,而当较大时,仅会保留大尺度特征。 也许这些都是概念压缩的暗示[18]。
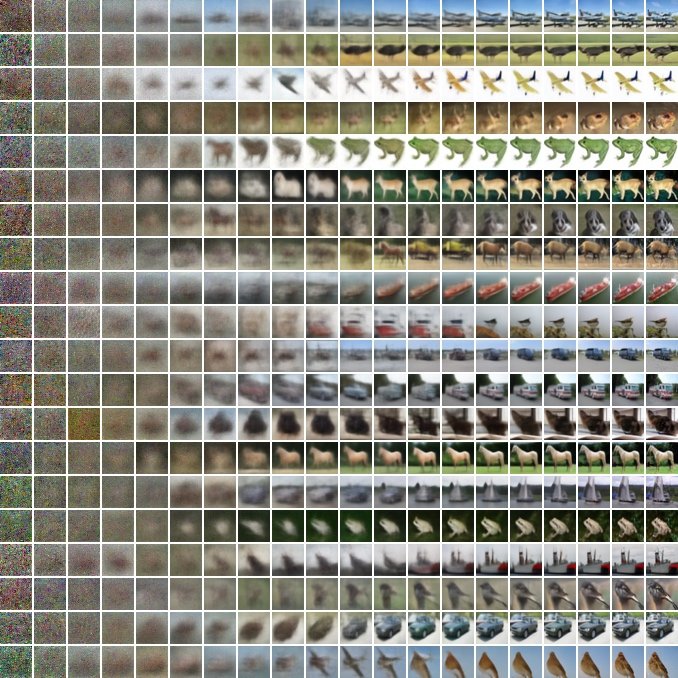
Figure 6: Unconditional CIFAR10 progressive generation ( over time, from left to right). Extended samples and sample quality metrics over time in the appendix (Figs. 14 and 10).
图 6:无条件 CIFAR10 渐进式生成( 随着时间的推移,从左到右)。 附录中随时间变化的扩展样本和样本质量指标(图 14 和 10)。
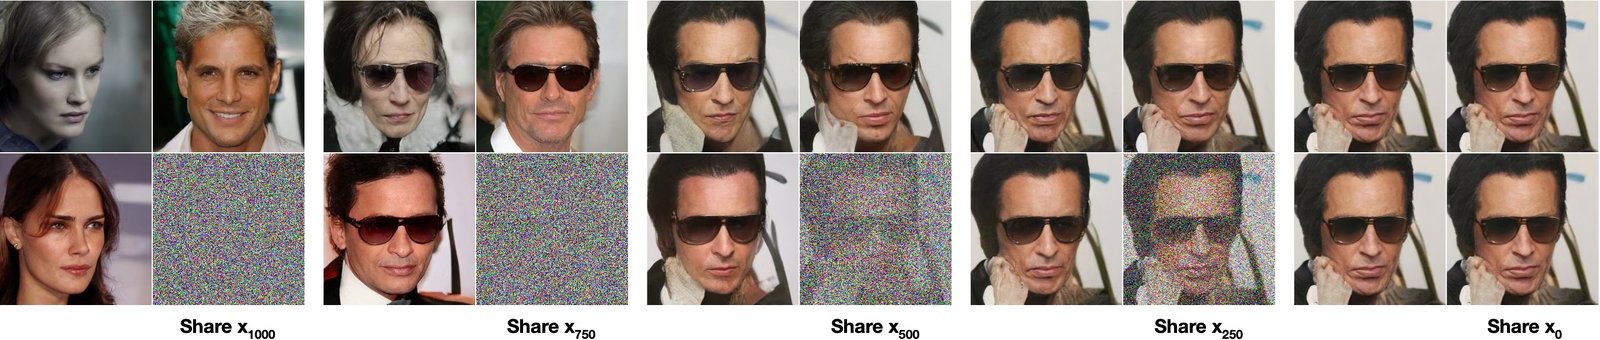
Figure 7: When conditioned on the same latent, CelebA-HQ samples share high-level attributes. Bottom-right quadrants are , and other quadrants are samples from .
图 7:当以相同潜在条件为条件时,CelebA-HQ样本共享高级属性。 右下象限是,其他象限是来自的样本。
Connection to autoregressive decoding
Note that the variational bound 5 can be rewritten as:
连接到自回归解码
请注意,变分界 5 可以重写为:
(See Appendix A for a derivation.) Now consider setting the diffusion process length to the dimensionality of the data, defining the forward process so that places all probability mass on with the first coordinates masked out (i.e. masks out the coordinate), setting to place all mass on a blank image, and, for the sake of argument, taking to be a fully expressive conditional distribution. With these choices, , and minimizing trains to copy coordinates unchanged and to predict the coordinate given . Thus, training with this particular diffusion is training an autoregressive model.
(推导请参见附录 A。)现在考虑将扩散过程长度设置为数据的维数,定义前向过程,以便将所有概率质量放置在上,并屏蔽第一个坐标(即屏蔽坐标),设置将所有质量放置在空白图像上,并且,为了 参数,将视为完全表达的条件分布。 通过这些选择,和最小化可以训练复制坐标不变,并在给定的情况下预测坐标。 因此,使用这种特定扩散训练就是训练自回归模型。
We can therefore interpret the Gaussian diffusion model 2 as a kind of autoregressive model with a generalized bit ordering that cannot be expressed by reordering data coordinates. Prior work has shown that such reorderings introduce inductive biases that have an impact on sample quality [38], so we speculate that the Gaussian diffusion serves a similar purpose, perhaps to greater effect since Gaussian noise might be more natural to add to images compared to masking noise. Moreover, the Gaussian diffusion length is not restricted to equal the data dimension; for instance, we use , which is less than the dimension of the or images in our experiments. Gaussian diffusions can be made shorter for fast sampling or longer for model expressiveness.
因此,我们可以将高斯扩散模型 2 解释为一种自回归模型,其具有无法通过重新排序数据坐标来表达的广义位排序。 之前的工作表明,这种重新排序会引入影响样本质量的归纳偏差[38],因此我们推测高斯扩散具有类似的目的,也许效果更大,因为与掩蔽噪声相比,高斯噪声可能更自然地添加到图像中。 而且,高斯扩散长度不限于等于数据维度; 例如,我们使用,它小于实验中或图像的尺寸。 高斯扩散可以缩短以实现快速采样,也可以延长以提高模型表达能力。
4.4 Interpolation
4.4 插值
We can interpolate source images in latent space using as a stochastic encoder, , then decoding the linearly interpolated latent into image space by the reverse process, . In effect, we use the reverse process to remove artifacts from linearly interpolating corrupted versions of the source images, as depicted in Fig. 8 (left). We fixed the noise for different values of so and remain the same. Fig. 8 (right) shows interpolations and reconstructions of original CelebA-HQ images (). The reverse process produces high-quality reconstructions, and plausible interpolations that smoothly vary attributes such as pose, skin tone, hairstyle, expression and background, but not eyewear. Larger results in coarser and more varied interpolations, with novel samples at (Appendix Fig. 9).
我们可以使用作为随机编码器在潜在空间中插值源图像,然后通过相反过程将线性插值的潜在解码到图像空间中。 实际上,我们使用相反的过程来消除源图像的线性插值损坏版本中的伪影,如图 8(左)所示。 我们修复了不同值的噪声,因此和保持不变。 图 8(右)显示了原始 CelebA-HQ图像 () 的插值和重建。 相反的过程会产生高质量的重建和合理的插值,这些插值可以平滑地改变姿势、肤色、发型、表情和背景等属性,但不能改变眼镜。 较大的会导致更粗糙和更多样的插值,并且具有新颖的样本(附录图 9)。
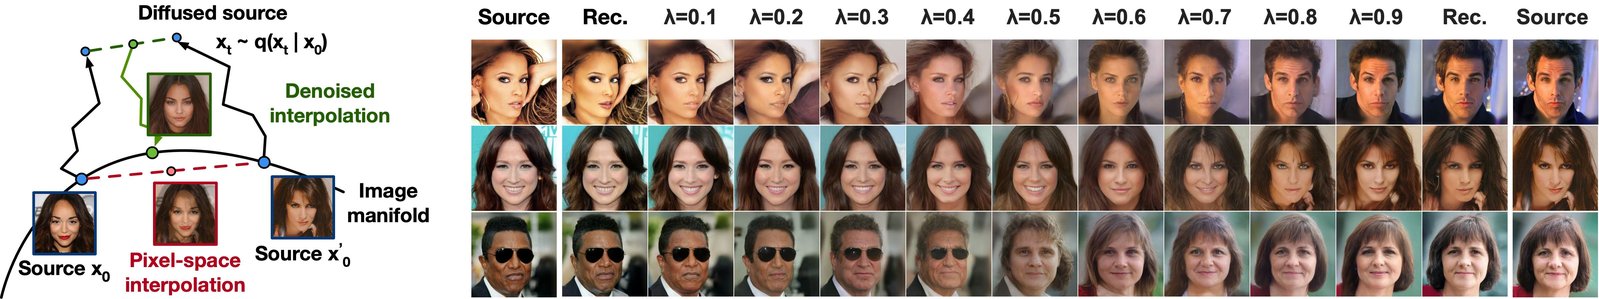
Figure 8: Interpolations of CelebA-HQ 256x256 images with 500 timesteps of diffusion.
图 8:具有 500 个扩散时间步长的 CelebA-HQ 256x256 图像的插值。
5 Related Work
5 相关工作
While diffusion models might resemble flows [9, 46, 10, 32, 5, 16, 23] and VAEs [33, 47, 37], diffusion models are designed so that has no parameters and the top-level latent has nearly zero mutual information with the data . Our -prediction reverse process parameterization establishes a connection between diffusion models and denoising score matching over multiple noise levels with annealed Langevin dynamics for sampling [55, 56]. Diffusion models, however, admit straightforward log likelihood evaluation, and the training procedure explicitly trains the Langevin dynamics sampler using variational inference (see Appendix C for details). The connection also has the reverse implication that a certain weighted form of denoising score matching is the same as variational inference to train a Langevin-like sampler. Other methods for learning transition operators of Markov chains include infusion training [2], variational walkback [15], generative stochastic networks [1], and others [50, 54, 36, 42, 35, 65].
虽然扩散模型可能类似于流 [9,46,10,32,5,16,23] 和 VAE [33,47,37],但扩散模型的设计使得没有参数,并且顶层潜在与数据的互信息几乎为零。 我们的预测逆向过程参数化在扩散模型和多个噪声级别的去噪分数匹配之间建立了联系,并使用退火的 Langevin 动力学进行采样 [55, 56]。 然而,扩散模型允许直接对数似然评估,并且训练过程使用变分推理明确训练 Langevin 动态采样器(有关详细信息,请参阅附录 C)。 这种联系还具有相反的含义,即去噪分数匹配的某种加权形式与训练类 Langevin 采样器的变分推理相同。 学习马尔可夫链转移算子的其他方法包括输注训练[2]、变分回走[15]、生成随机网络[1]和其他[50、54、36、42、35、65]。
By the known connection between score matching and energy-based modeling, our work could have implications for other recent work on energy-based models [67, 68, 69, 12, 70, 13, 11, 41, 17, 8]. Our rate-distortion curves are computed over time in one evaluation of the variational bound, reminiscent of how rate-distortion curves can be computed over distortion penalties in one run of annealed importance sampling [24]. Our progressive decoding argument can be seen in convolutional DRAW and related models [18, 40] and may also lead to more general designs for subscale orderings or sampling strategies for autoregressive models [38, 64].
通过分数匹配和基于能量的建模之间已知的联系,我们的工作可能会对基于能量的模型的其他近期工作产生影响[67,68,69,12,70,13,11,41,17,8]。 我们的速率失真曲线是在一次变分界限评估中随时间计算的,这让人想起如何在一次退火重要性采样中根据失真惩罚来计算速率失真曲线[24]。 我们的渐进式解码论点可以在卷积 DRAW 和相关模型中看到 [18, 40],并且还可能导致自回归模型的子尺度排序或采样策略的更通用设计 [38, 64]。
6 Conclusion
6 结论
We have presented high quality image samples using diffusion models, and we have found connections among diffusion models and variational inference for training Markov chains, denoising score matching and annealed Langevin dynamics (and energy-based models by extension), autoregressive models, and progressive lossy compression. Since diffusion models seem to have excellent inductive biases for image data, we look forward to investigating their utility in other data modalities and as components in other types of generative models and machine learning systems.
我们展示扩散模型能生成高质量样本,并发现带特定参数化的加权变分界对样本质量有利。扩散模型似然不及其他基于似然的模型,但样本质量往往更好;我们从渐进有损压缩角度解释了这一现象。
Broader Impact
更广泛的影响
Our work on diffusion models takes on a similar scope as existing work on other types of deep generative models, such as efforts to improve the sample quality of GANs, flows, autoregressive models, and so forth. Our paper represents progress in making diffusion models a generally useful tool in this family of techniques, so it may serve to amplify any impacts that generative models have had (and will have) on the broader world.
我们在扩散模型方面的工作与其他类型的深度生成模型的现有工作具有相似的范围,例如提高 GAN、流、自回归模型等样本质量的努力。 我们的论文代表了使扩散模型成为该技术系列中普遍有用的工具的进展,因此它可能有助于放大生成模型已经(并将)对更广泛的世界产生的影响。
Unfortunately, there are numerous well-known malicious uses of generative models. Sample generation techniques can be employed to produce fake images and videos of high profile figures for political purposes. While fake images were manually created long before software tools were available, generative models such as ours make the process easier. Fortunately, CNN-generated images currently have subtle flaws that allow detection [62], but improvements in generative models may make this more difficult. Generative models also reflect the biases in the datasets on which they are trained. As many large datasets are collected from the internet by automated systems, it can be difficult to remove these biases, especially when the images are unlabeled. If samples from generative models trained on these datasets proliferate throughout the internet, then these biases will only be reinforced further.
不幸的是,有许多众所周知的生成模型的恶意使用。 样本生成技术可用于出于政治目的制作知名人物的虚假图像和视频。 虽然假图像是在软件工具可用之前很久就手动创建的,但像我们这样的生成模型使这个过程变得更容易。 幸运的是,CNN 生成的图像目前存在允许检测的细微缺陷[62],但生成模型的改进可能会使检测变得更加困难。 生成模型还反映了训练它们的数据集中的偏差。 由于许多大型数据集是由自动化系统从互联网收集的,因此很难消除这些偏差,尤其是当图像未标记时。 如果在这些数据集上训练的生成模型的样本在整个互联网上激增,那么这些偏见只会进一步强化。
On the other hand, diffusion models may be useful for data compression, which, as data becomes higher resolution and as global internet traffic increases, might be crucial to ensure accessibility of the internet to wide audiences. Our work might contribute to representation learning on unlabeled raw data for a large range of downstream tasks, from image classification to reinforcement learning, and diffusion models might also become viable for creative uses in art, photography, and music.
另一方面,扩散模型可能对数据压缩有用,随着数据分辨率的提高和全球互联网流量的增加,这对于确保广大受众访问互联网可能至关重要。 我们的工作可能有助于对未标记的原始数据进行表征学习,以实现从图像分类到强化学习的大量下游任务,并且扩散模型也可能适用于艺术、摄影和音乐的创造性用途。
Acknowledgments and Disclosure of Funding
致谢与资金披露
This work was supported by ONR PECASE and the NSF Graduate Research Fellowship under grant number DGE-1752814. Google’s TensorFlow Research Cloud (TFRC) provided Cloud TPUs.
这项工作得到了 ONR PECASE 和 NSF 研究生研究奖学金的支持,拨款号为 DGE-1752814。 谷歌的 TensorFlow Research Cloud (TFRC) 提供了云 TPU。
References
参考文献
[1] Guillaume Alain, Yoshua Bengio, Li Yao, Jason Yosinski, Eric Thibodeau-Laufer, Saizheng Zhang, and Pascal Vincent. GSNs: generative stochastic networks. Information and Inference: A Journal of the IMA , 5(2):210–249, 2016.
[2] Florian Bordes, Sina Honari, and Pascal Vincent. Learning to generate samples from noise through infusion training. In International Conference on Learning Representations , 2017.
[3] Andrew Brock, Jeff Donahue, and Karen Simonyan. Large scale GAN training for high fidelity natural image synthesis. In International Conference on Learning Representations , 2019.
[4] Tong Che, Ruixiang Zhang, Jascha Sohl-Dickstein, Hugo Larochelle, Liam Paull, Yuan Cao, and Yoshua Bengio. Your GAN is secretly an energy-based model and you should use discriminator driven latent sampling. arXiv preprint arXiv:2003.06060 , 2020.
[5] Tian Qi Chen, Yulia Rubanova, Jesse Bettencourt, and David K Duvenaud. Neural ordinary differential equations. In Advances in Neural Information Processing Systems , pages 6571–6583, 2018a.
[6] Xi Chen, Nikhil Mishra, Mostafa Rohaninejad, and Pieter Abbeel. PixelSNAIL: An improved autoregressive generative model. In International Conference on Machine Learning , pages 863–871, 2018b.
[7] Rewon Child, Scott Gray, Alec Radford, and Ilya Sutskever. Generating long sequences with sparse transformers. arXiv preprint arXiv:1904.10509 , 2019.
[8] Yuntian Deng, Anton Bakhtin, Myle Ott, Arthur Szlam, and Marc’Aurelio Ranzato. Residual energy-based models for text generation. arXiv preprint arXiv:2004.11714 , 2020.
[9] Laurent Dinh, David Krueger, and Yoshua Bengio. NICE: Non-linear independent components estimation. arXiv preprint arXiv:1410.8516 , 2014.
[10] Laurent Dinh, Jascha Sohl-Dickstein, and Samy Bengio. Density estimation using Real NVP. arXiv preprint arXiv:1605.08803 , 2016.
[11] Yilun Du and Igor Mordatch. Implicit generation and modeling with energy based models. In Advances in Neural Information Processing Systems , pages 3603–3613, 2019.
[12] Ruiqi Gao, Yang Lu, Junpei Zhou, Song-Chun Zhu, and Ying Nian Wu. Learning generative ConvNets via multi-grid modeling and sampling. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition , pages 9155–9164, 2018.
[13] Ruiqi Gao, Erik Nijkamp, Diederik P Kingma, Zhen Xu, Andrew M Dai, and Ying Nian Wu. Flow contrastive estimation of energy-based models. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition , pages 7518–7528, 2020.
[14] Ian Goodfellow, Jean Pouget-Abadie, Mehdi Mirza, Bing Xu, David Warde-Farley, Sherjil Ozair, Aaron Courville, and Yoshua Bengio. Generative adversarial nets. In Advances in Neural Information Processing Systems , pages 2672–2680, 2014.
[15] Anirudh Goyal, Nan Rosemary Ke, Surya Ganguli, and Yoshua Bengio. Variational walkback: Learning a transition operator as a stochastic recurrent net. In Advances in Neural Information Processing Systems , pages 4392–4402, 2017.
[16] Will Grathwohl, Ricky T. Q. Chen, Jesse Bettencourt, and David Duvenaud. FFJORD: Free-form continuous dynamics for scalable reversible generative models. In International Conference on Learning Representations , 2019.
[17] Will Grathwohl, Kuan-Chieh Wang, Joern-Henrik Jacobsen, David Duvenaud, Mohammad Norouzi, and Kevin Swersky. Your classifier is secretly an energy based model and you should treat it like one. In International Conference on Learning Representations , 2020.
[18] Karol Gregor, Frederic Besse, Danilo Jimenez Rezende, Ivo Danihelka, and Daan Wierstra. Towards conceptual compression. In Advances In Neural Information Processing Systems , pages 3549–3557, 2016.
[19] Prahladh Harsha, Rahul Jain, David McAllester, and Jaikumar Radhakrishnan. The communication complexity of correlation. In Twenty-Second Annual IEEE Conference on Computational Complexity (CCC’07) , pages 10–23. IEEE, 2007.
[20] Marton Havasi, Robert Peharz, and José Miguel Hernández-Lobato. Minimal random code learning: Getting bits back from compressed model parameters. In International Conference on Learning Representations , 2019.
[21] Martin Heusel, Hubert Ramsauer, Thomas Unterthiner, Bernhard Nessler, and Sepp Hochreiter. GANs trained by a two time-scale update rule converge to a local Nash equilibrium. In Advances in Neural Information Processing Systems , pages 6626–6637, 2017.
[22] Irina Higgins, Loic Matthey, Arka Pal, Christopher Burgess, Xavier Glorot, Matthew Botvinick, Shakir Mohamed, and Alexander Lerchner. beta-VAE: Learning basic visual concepts with a constrained variational framework. In International Conference on Learning Representations , 2017.
[23] Jonathan Ho, Xi Chen, Aravind Srinivas, Yan Duan, and Pieter Abbeel. Flow++: Improving flow-based generative models with variational dequantization and architecture design. In International Conference on Machine Learning , 2019.
[24] Sicong Huang, Alireza Makhzani, Yanshuai Cao, and Roger Grosse. Evaluating lossy compression rates of deep generative models. In International Conference on Machine Learning , 2020.
[25] Nal Kalchbrenner, Aaron van den Oord, Karen Simonyan, Ivo Danihelka, Oriol Vinyals, Alex Graves, and Koray Kavukcuoglu. Video pixel networks. In International Conference on Machine Learning , pages 1771–1779, 2017.
[26] Nal Kalchbrenner, Erich Elsen, Karen Simonyan, Seb Noury, Norman Casagrande, Edward Lockhart, Florian Stimberg, Aaron van den Oord, Sander Dieleman, and Koray Kavukcuoglu. Efficient neural audio synthesis. In International Conference on Machine Learning , pages 2410–2419, 2018.
[27] Tero Karras, Timo Aila, Samuli Laine, and Jaakko Lehtinen. Progressive growing of GANs for improved quality, stability, and variation. In International Conference on Learning Representations , 2018.
[28] Tero Karras, Samuli Laine, and Timo Aila. A style-based generator architecture for generative adversarial networks. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition , pages 4401–4410, 2019.
[29] Tero Karras, Miika Aittala, Janne Hellsten, Samuli Laine, Jaakko Lehtinen, and Timo Aila. Training generative adversarial networks with limited data. arXiv preprint arXiv:2006.06676v1 , 2020a.
[30] Tero Karras, Samuli Laine, Miika Aittala, Janne Hellsten, Jaakko Lehtinen, and Timo Aila. Analyzing and improving the image quality of StyleGAN. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition , pages 8110–8119, 2020b.
[31] Diederik P Kingma and Jimmy Ba. Adam: A method for stochastic optimization. In International Conference on Learning Representations , 2015.
[32] Diederik P Kingma and Prafulla Dhariwal. Glow: Generative flow with invertible 1x1 convolutions. In Advances in Neural Information Processing Systems , pages 10215–10224, 2018.
[33] Diederik P Kingma and Max Welling. Auto-encoding variational Bayes. arXiv preprint arXiv:1312.6114 , 2013.
[34] Diederik P Kingma, Tim Salimans, Rafal Jozefowicz, Xi Chen, Ilya Sutskever, and Max Welling. Improved variational inference with inverse autoregressive flow. In Advances in Neural Information Processing Systems , pages 4743–4751, 2016.
[35] John Lawson, George Tucker, Bo Dai, and Rajesh Ranganath. Energy-inspired models: Learning with sampler-induced distributions. In Advances in Neural Information Processing Systems , pages 8501–8513, 2019.
[36] Daniel Levy, Matt D. Hoffman, and Jascha Sohl-Dickstein. Generalizing Hamiltonian Monte Carlo with neural networks. In International Conference on Learning Representations , 2018.
[37] Lars Maaløe, Marco Fraccaro, Valentin Liévin, and Ole Winther. BIVA: A very deep hierarchy of latent variables for generative modeling. In Advances in Neural Information Processing Systems , pages 6548–6558, 2019.
[38] Jacob Menick and Nal Kalchbrenner. Generating high fidelity images with subscale pixel networks and multidimensional upscaling. In International Conference on Learning Representations , 2019.
[39] Takeru Miyato, Toshiki Kataoka, Masanori Koyama, and Yuichi Yoshida. Spectral normalization for generative adversarial networks. In International Conference on Learning Representations , 2018.
[40] Alex Nichol. VQ-DRAW: A sequential discrete VAE. arXiv preprint arXiv:2003.01599 , 2020.
[41] Erik Nijkamp, Mitch Hill, Tian Han, Song-Chun Zhu, and Ying Nian Wu. On the anatomy of MCMC-based maximum likelihood learning of energy-based models. arXiv preprint arXiv:1903.12370 , 2019a.
[42] Erik Nijkamp, Mitch Hill, Song-Chun Zhu, and Ying Nian Wu. Learning non-convergent non-persistent short-run MCMC toward energy-based model. In Advances in Neural Information Processing Systems , pages 5233–5243, 2019b.
[43] Georg Ostrovski, Will Dabney, and Remi Munos. Autoregressive quantile networks for generative modeling. In International Conference on Machine Learning , pages 3936–3945, 2018.
[44] Ryan Prenger, Rafael Valle, and Bryan Catanzaro. WaveGlow: A flow-based generative network for speech synthesis. In ICASSP 2019-2019 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP) , pages 3617–3621. IEEE, 2019.
[45] Ali Razavi, Aaron van den Oord, and Oriol Vinyals. Generating diverse high-fidelity images with VQ-VAE-2. In Advances in Neural Information Processing Systems , pages 14837–14847, 2019.
[46] Danilo Rezende and Shakir Mohamed. Variational inference with normalizing flows. In International Conference on Machine Learning , pages 1530–1538, 2015.
[47] Danilo Jimenez Rezende, Shakir Mohamed, and Daan Wierstra. Stochastic backpropagation and approximate inference in deep generative models. In International Conference on Machine Learning , pages 1278–1286, 2014.
[48] Olaf Ronneberger, Philipp Fischer, and Thomas Brox. U-Net: Convolutional networks for biomedical image segmentation. In International Conference on Medical Image Computing and Computer-Assisted Intervention , pages 234–241. Springer, 2015.
[49] Tim Salimans and Durk P Kingma. Weight normalization: A simple reparameterization to accelerate training of deep neural networks. In Advances in Neural Information Processing Systems , pages 901–909, 2016.
[50] Tim Salimans, Diederik Kingma, and Max Welling. Markov Chain Monte Carlo and variational inference: Bridging the gap. In International Conference on Machine Learning , pages 1218–1226, 2015.
[51] Tim Salimans, Ian Goodfellow, Wojciech Zaremba, Vicki Cheung, Alec Radford, and Xi Chen. Improved techniques for training gans. In Advances in Neural Information Processing Systems , pages 2234–2242, 2016.
[52] Tim Salimans, Andrej Karpathy, Xi Chen, and Diederik P Kingma. PixelCNN++: Improving the PixelCNN with discretized logistic mixture likelihood and other modifications. In International Conference on Learning Representations , 2017.
[53] Jascha Sohl-Dickstein, Eric Weiss, Niru Maheswaranathan, and Surya Ganguli. Deep unsupervised learning using nonequilibrium thermodynamics. In International Conference on Machine Learning , pages 2256–2265, 2015.
[54] Jiaming Song, Shengjia Zhao, and Stefano Ermon. A-NICE-MC: Adversarial training for MCMC. In Advances in Neural Information Processing Systems , pages 5140–5150, 2017.
[55] Yang Song and Stefano Ermon. Generative modeling by estimating gradients of the data distribution. In Advances in Neural Information Processing Systems , pages 11895–11907, 2019.
[56] Yang Song and Stefano Ermon. Improved techniques for training score-based generative models. arXiv preprint arXiv:2006.09011 , 2020.
[57] Aaron van den Oord, Sander Dieleman, Heiga Zen, Karen Simonyan, Oriol Vinyals, Alex Graves, Nal Kalchbrenner, Andrew Senior, and Koray Kavukcuoglu. WaveNet: A generative model for raw audio. arXiv preprint arXiv:1609.03499 , 2016a.
[58] Aaron van den Oord, Nal Kalchbrenner, and Koray Kavukcuoglu. Pixel recurrent neural networks. International Conference on Machine Learning , 2016b.
[59] Aaron van den Oord, Nal Kalchbrenner, Oriol Vinyals, Lasse Espeholt, Alex Graves, and Koray Kavukcuoglu. Conditional image generation with PixelCNN decoders. In Advances in Neural Information Processing Systems , pages 4790–4798, 2016c.
[60] Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Łukasz Kaiser, and Illia Polosukhin. Attention is all you need. In Advances in Neural Information Processing Systems , pages 5998–6008, 2017.
[61] Pascal Vincent. A connection between score matching and denoising autoencoders. Neural Computation , 23(7):1661–1674, 2011.
[62] Sheng-Yu Wang, Oliver Wang, Richard Zhang, Andrew Owens, and Alexei A Efros. Cnn-generated images are surprisingly easy to spot…for now. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition , 2020.
[63] Xiaolong Wang, Ross Girshick, Abhinav Gupta, and Kaiming He. Non-local neural networks. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition , pages 7794–7803, 2018.
[64] Auke J Wiggers and Emiel Hoogeboom. Predictive sampling with forecasting autoregressive models. arXiv preprint arXiv:2002.09928 , 2020.
[65] Hao Wu, Jonas Köhler, and Frank Noé. Stochastic normalizing flows. arXiv preprint arXiv:2002.06707 , 2020.
[66] Yuxin Wu and Kaiming He. Group normalization. In Proceedings of the European Conference on Computer Vision (ECCV) , pages 3–19, 2018.
[67] Jianwen Xie, Yang Lu, Song-Chun Zhu, and Yingnian Wu. A theory of generative convnet. In International Conference on Machine Learning , pages 2635–2644, 2016.
[68] Jianwen Xie, Song-Chun Zhu, and Ying Nian Wu. Synthesizing dynamic patterns by spatial-temporal generative convnet. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition , pages 7093–7101, 2017.
[69] Jianwen Xie, Zilong Zheng, Ruiqi Gao, Wenguan Wang, Song-Chun Zhu, and Ying Nian Wu. Learning descriptor networks for 3d shape synthesis and analysis. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition , pages 8629–8638, 2018.
[70] Jianwen Xie, Song-Chun Zhu, and Ying Nian Wu. Learning energy-based spatial-temporal generative convnets for dynamic patterns. IEEE Transactions on Pattern Analysis and Machine Intelligence , 2019.
[71] Fisher Yu, Yinda Zhang, Shuran Song, Ari Seff, and Jianxiong Xiao. LSUN: Construction of a large-scale image dataset using deep learning with humans in the loop. arXiv preprint arXiv:1506.03365 , 2015.
[72] Sergey Zagoruyko and Nikos Komodakis. Wide residual networks. arXiv preprint arXiv:1605.07146 , 2016.
Extra information
额外信息
LSUN
FID scores for LSUN datasets are included in Table 3. Scores marked with ∗ are reported by StyleGAN2 as baselines, and other scores are reported by their respective authors.
LSUN
LSUN 数据集的 FID 分数包含在表 3 中。标有 * 的分数由 StyleGAN2 报告为基线,其他分数由各自的作者报告。
| Model | LSUN Bedroom | LSUN Church | LSUN Cat |
|---|---|---|---|
| ProgressiveGAN [27] | 8.34 | 6.42 | 37.52 |
| StyleGAN [28] | 2.65 | 4.21∗ | 8.53∗ |
| StyleGAN2 [30] | - | 3.86 | 6.93 |
| Ours () | 6.36 | 7.89 | 19.75 |
| Ours (, large) | 4.90 | - | - |
Table 3: FID scores for LSUN datasets
| 模型 | LSUN卧室 | 路圣教会 | LSUN猫 |
|---|---|---|---|
| 渐进式GAN [27] | 8.34 | 6.42 | 37.52 |
| 样式GAN [28] | ** 2.65 ** | 4.21* | 8.53* |
| tkwifhgf6u840yqmskqn | - | s3w33v32gtfybltpdy6u | cy6s8n1yqt4bifsbxvxm |
| 我们的() | 6.36 | 7.89 | 19.75 |
| 我们的(,大) | 4.90 | - | - |
表 3:LSUN数据集的 FID 分数
Progressive compression
Our lossy compression argument in Section 4.3 is only a proof of concept, because Algorithms 3 and 4 depend on a procedure such as minimal random coding [20], which is not tractable for high dimensional data. These algorithms serve as a compression interpretation of the variational bound 5 of [53], not yet as a practical compression system.
渐进式压缩
我们在 4.3 节中的有损压缩论点只是概念证明,因为算法 3 和 4 依赖于诸如最小随机编码 [20] 之类的过程,这对于高维数据来说是不易处理的。 这些算法用作[53]的变分界限5的压缩解释,但尚未作为实用的压缩系统。
| Reverse process time () | Rate (bits/dim) | Distortion (RMSE ) |
|---|---|---|
| 1000 | 1.77581 | 0.95136 |
| 900 | 0.11994 | 12.02277 |
| 800 | 0.05415 | 18.47482 |
| 700 | 0.02866 | 24.43656 |
| 600 | 0.01507 | 30.80948 |
| 500 | 0.00716 | 38.03236 |
| 400 | 0.00282 | 46.12765 |
| 300 | 0.00081 | 54.18826 |
| 200 | 0.00013 | 60.97170 |
| 100 | 0.00000 | 67.60125 |
Table 4: Unconditional CIFAR10 test set rate-distortion values (accompanies Fig. 5)
| 逆向处理时间 () | 速率(位/暗淡) | 失真(RMSE ) |
|---|---|---|
| 1000 | 1.77581 | 0.95136 |
| 900 | 0.11994 | 12.02277 |
| 800 | 0.05415 | 18.47482 |
| 700 | 0.02866 | 24.43656 |
| 600 | 0.01507 | 30.80948 |
| 500 | 0.00716 | 38.03236 |
| 400 | 0.00282 | 46.12765 |
| 300 | 0.00081 | 54.18826 |
| 200 | 0.00013 | 60.97170 |
| 100 | 0.00000 | 67.60125 |
表 4:无条件 CIFAR10 测试集率失真值(附图 5)
Appendix A Extended derivations
附录 A 扩展推导
Below is a derivation of Eq. 5, the reduced variance variational bound for diffusion models. This material is from [53]; we include it here only for completeness.
下面是方程的推导。 5,扩散模型的减少方差变分界。 该材料来自[53]; 我们将其放在这里只是为了完整性。
The following is an alternate version of . It is not tractable to estimate, but it is useful for our discussion in Section 4.3.
以下是的替代版本。 它不容易估计,但对我们在 4.3 节中的讨论很有用。
Appendix B Experimental details
附录 B 实验细节
Our neural network architecture follows the backbone of PixelCNN++ [52], which is a U-Net [48] based on a Wide ResNet [72]. We replaced weight normalization [49] with group normalization [66] to make the implementation simpler. Our models use four feature map resolutions ( to ), and our models use six. All models have two convolutional residual blocks per resolution level and self-attention blocks at the resolution between the convolutional blocks [6]. Diffusion time is specified by adding the Transformer sinusoidal position embedding [60] into each residual block. Our CIFAR10 model has 35.7 million parameters, and our LSUN and CelebA-HQ models have 114 million parameters. We also trained a larger variant of the LSUN Bedroom model with approximately 256 million parameters by increasing filter count.
我们的神经网络架构遵循 PixelCNN++ [52] 的主干,它是基于 Wide ResNet [72] 的 U-Net [48]。 我们用组标准化 [66] 替换了权重标准化 [49],以使实现更简单。 我们的模型使用四种特征图分辨率(到),我们的模型使用六种。 所有模型在每个分辨率级别都有两个卷积残差块,并且在卷积块之间具有分辨率的自注意力块 [6]。 扩散时间通过将 Transformer 正弦位置嵌入 [60] 添加到每个残差块中来指定。 我们的 CIFAR10 模型有 3570 万个参数,我们的 LSUN 和 CelebA-HQ 模型有 1.14 亿个参数。 我们还通过增加滤波器数量来训练 LSUN Bedroom 模型的更大变体,该模型具有约 2.56 亿个参数。
We used TPU v3-8 (similar to 8 V100 GPUs) for all experiments. Our CIFAR model trains at 21 steps per second at batch size 128 (10.6 hours to train to completion at 800k steps), and sampling a batch of 256 images takes 17 seconds. Our CelebA-HQ/LSUN (2562) models train at 2.2 steps per second at batch size 64, and sampling a batch of 128 images takes 300 seconds. We trained on CelebA-HQ for 0.5M steps, LSUN Bedroom for 2.4M steps, LSUN Cat for 1.8M steps, and LSUN Church for 1.2M steps. The larger LSUN Bedroom model was trained for 1.15M steps.
我们使用 TPU v3-8(类似于 8 个 V100 GPU)进行所有实验。 我们的 CIFAR 模型以每秒 21 步的速度进行训练,批量大小为 128(以 800k 步训练完成需要 10.6 小时),对一批 256 张图像进行采样需要 17 秒。 我们的 CelebA-HQ/LSUN (2562) 模型以每秒 2.2 步的速度进行训练,批量大小为 64,对一批 128 张图像进行采样需要 300 秒。 我们在 CelebA-HQ 上训练了 0.5M 步,在 LSUN Bedroom 上训练了 2.4M 步,在 LSUN Cat 上训练了 1.800 万步,在 LSUN Church 上训练了 1.200 万步。 较大的 LSUN Bedroom 模型接受了 115 万步的训练。
Apart from an initial choice of hyperparameters early on to make network size fit within memory constraints, we performed the majority of our hyperparameter search to optimize for CIFAR10 sample quality, then transferred the resulting settings over to the other datasets:
除了早期选择超参数以使网络大小适合内存限制之外,我们还执行了大部分超参数搜索来优化 CIFAR10 样本质量,然后将结果设置转移到其他数据集:
- • We chose the schedule from a set of constant, linear, and quadratic schedules, all constrained so that . We set without a sweep, and we chose a linear schedule from to .
- • We set the dropout rate on CIFAR10 to by sweeping over the values . Without dropout on CIFAR10, we obtained poorer samples reminiscent of the overfitting artifacts in an unregularized PixelCNN++ [52]. We set dropout rate on the other datasets to zero without sweeping.
- • We used random horizontal flips during training for CIFAR10; we tried training both with and without flips, and found flips to improve sample quality slightly. We also used random horizontal flips for all other datasets except LSUN Bedroom.
- • We tried Adam [31] and RMSProp early on in our experimentation process and chose the former. We left the hyperparameters to their standard values. We set the learning rate to without any sweeping, and we lowered it to for the images, which seemed unstable to train with the larger learning rate.
- • We set the batch size to 128 for CIFAR10 and 64 for larger images. We did not sweep over these values.
- • We used EMA on model parameters with a decay factor of 0.9999. We did not sweep over this value.
- • 我们从一组常数、线性和二次计划中选择了计划,所有这些都受到约束,以便。 我们设置而不进行扫描,并选择从到的线性时间表。
- • 我们通过扫描值 将CIFAR10 上的丢失率设置为。 在 CIFAR10 上没有 dropout 的情况下,我们获得了较差的样本,让人想起未正则化的 PixelCNN++ 中的过度拟合伪影 [52]。 我们将其他数据集的丢失率设置为零而不进行扫描。
- • 我们在 CIFAR10 的训练过程中使用了随机水平翻转; 我们尝试了有翻转和没有翻转的训练,发现翻转可以稍微提高样本质量。 我们还对除 LSUN Bedroom 之外的所有其他数据集使用随机水平翻转。
- • 我们在实验过程的早期尝试了 Adam [31] 和 RMSProp,并选择了前者。 我们将超参数保留为其标准值。 我们将学习率设置为 ,没有任何扫描,并且对于图像,我们将其降低到 ,这对于使用较大的学习率进行训练似乎不稳定。
- • 我们将CIFAR10 的批量大小设置为128,将较大图像的批量大小设置为64。 我们没有忽略这些价值观。
- • 我们对模型参数使用了EMA,衰减因子为0.9999。 我们没有扫过这个值。
Final experiments were trained once and evaluated throughout training for sample quality. Sample quality scores and log likelihood are reported on the minimum FID value over the course of training. On CIFAR10, we calculated Inception and FID scores on 50000 samples using the original code from the OpenAI [51] and TTUR [21] repositories, respectively. On LSUN, we calculated FID scores on 50000 samples using code from the StyleGAN2 [30] repository. CIFAR10 and CelebA-HQ were loaded as provided by TensorFlow Datasets (https://www.tensorflow.org/datasets), and LSUN was prepared using code from StyleGAN. Dataset splits (or lack thereof) are standard from the papers that introduced their usage in a generative modeling context. All details can be found in the source code release.
最终实验只训练一次,并在整个训练过程中评估样本质量。 样本质量得分和对数似然性根据训练过程中的最小 FID 值进行报告。 在 CIFAR10 上,我们分别使用 OpenAI [51] 和 TTUR [21] 存储库中的原始代码计算了 50000 个样本的 Inception 和 FID 分数。 在 LSUN 上,我们使用 StyleGAN2 [30] 存储库中的代码计算了 50000 个样本的 FID 分数。 CIFAR10 和 CelebA-HQ 按 TensorFlow 数据集 (https://www.tensorflow.org/datasets) 提供的方式加载,LSUN 是使用 StyleGAN 的代码准备的。 数据集分割(或缺乏数据集分割)是介绍数据集在生成建模环境中使用的论文中的标准。 所有详细信息都可以在源代码发布中找到。
Appendix C Discussion on related work
附录C 相关工作讨论
Our model architecture, forward process definition, and prior differ from NCSN [55, 56] in subtle but important ways that improve sample quality, and, notably, we directly train our sampler as a latent variable model rather than adding it after training post-hoc. In greater detail:
我们的模型架构、前向过程定义和先验与 NCSN [55, 56] 的不同之处在于微妙但重要的提高样本质量的方式,而且值得注意的是,我们直接将采样器训练为潜在变量模型,而不是在事后训练后添加它。 更详细地说:
- We use a U-Net with self-attention; NCSN uses a RefineNet with dilated convolutions. We condition all layers on by adding in the Transformer sinusoidal position embedding, rather than only in normalization layers (NCSNv1) or only at the output (v2).
- Diffusion models scale down the data with each forward process step (by a factor) so that variance does not grow when adding noise, thus providing consistently scaled inputs to the neural net reverse process. NCSN omits this scaling factor.
- Unlike NCSN, our forward process destroys signal (), ensuring a close match between the prior and aggregate posterior of . Also unlike NCSN, our are very small, which ensures that the forward process is reversible by a Markov chain with conditional Gaussians. Both of these factors prevent distribution shift when sampling.
- Our Langevin-like sampler has coefficients (learning rate, noise scale, etc.) derived rigorously from in the forward process. Thus, our training procedure directly trains our sampler to match the data distribution after steps: it trains the sampler as a latent variable model using variational inference. In contrast, NCSN’s sampler coefficients are set by hand post-hoc, and their training procedure is not guaranteed to directly optimize a quality metric of their sampler.
1.我们使用带有self-attention的U-Net; NCSN 使用带有扩张卷积的 RefineNet。 我们通过添加 Transformer 正弦位置嵌入来调节上的所有层,而不是仅在归一化层 (NCSNv1) 或仅在输出 (v2) 中。
2. 扩散模型在每个正向过程步骤中按比例缩小数据(通过因子),以便在添加噪声时方差不会增加,从而为神经网络反向过程提供一致缩放的输入。 NCSN 忽略了这个比例因子。
3. 与 NCSN 不同,我们的前向过程会破坏信号(),确保的先验和聚合后验之间的紧密匹配。 与 NCSN 不同的是,我们的非常小,这确保了前向过程可以通过具有条件高斯的马尔可夫链可逆。 这两个因素都可以防止采样时的分布变化。
4. 我们的类似 Langevin 的采样器具有在前向过程中从严格导出的系数(学习率、噪声尺度等)。 因此,我们的训练过程直接训练我们的采样器以匹配步骤后的数据分布:它使用变分推理将采样器训练为潜在变量模型。 相比之下,NCSN 的采样器系数是事后手动设置的,并且它们的训练过程不能保证直接优化采样器的质量指标。
Appendix D Samples
附录 D 示例
Additional samples
Figure 11, 13, 16, 17, 18, and 19 show uncurated samples from the diffusion models trained on CelebA-HQ, CIFAR10 and LSUN datasets.
附加示例
图 11、13、16、17、18 和 19 显示了在 CelebA-HQ、CIFAR10 和 LSUN 数据集上训练的扩散模型的未经整理的样本。
Latent structure and reverse process stochasticity
During sampling, both the prior and Langevin dynamics are stochastic. To understand the significance of the second source of noise, we sampled multiple images conditioned on the same intermediate latent for the CelebA dataset. Figure 7 shows multiple draws from the reverse process that share the latent for . To accomplish this, we run a single reverse chain from an initial draw from the prior. At the intermediate timesteps, the chain is split to sample multiple images. When the chain is split after the prior draw at , the samples differ significantly. However, when the chain is split after more steps, samples share high-level attributes like gender, hair color, eyewear, saturation, pose and facial expression. This indicates that intermediate latents like encode these attributes, despite their imperceptibility.
潜在结构和逆过程随机性
在采样过程中,先前的和 Langevin 动力学都是随机的。 为了了解第二个噪声源的重要性,我们对 CelebA数据集的相同中间潜伏条件下的多个图像进行了采样。 图 7 显示了来自反向过程的多次抽取,这些抽取共享的潜在。 为了实现这一点,我们从先前的初始绘制中运行单个反向链。 在中间时间步长,链被分割以采样多个图像。 当在的先前抽签之后链被分裂时,样本存在显着差异。 然而,当经过更多步骤分割链时,样本共享高级属性,如性别、头发颜色、眼镜、饱和度、姿势和面部表情。 这表明像这样的中间潜伏编码了这些属性,尽管它们难以察觉。
Coarse-to-fine interpolation
Figure 9 shows interpolations between a pair of source CelebA images as we vary the number of diffusion steps prior to latent space interpolation. Increasing the number of diffusion steps destroys more structure in the source images, which the model completes during the reverse process. This allows us to interpolate at both fine granularities and coarse granularities. In the limiting case of diffusion steps, the interpolation mixes source images in pixel space. On the other hand, after diffusion steps, source information is lost and interpolations are novel samples.
粗到精插值
图 9 显示了一对源 CelebA图像之间的插值,因为我们在潜在空间插值之前改变了扩散步骤的数量。 增加扩散步骤的数量会破坏源图像中的更多结构,这是模型在逆过程中完成的。 这使我们能够以细粒度和粗粒度进行插值。 在扩散步骤的限制情况下,插值在像素空间中混合源图像。 另一方面,在扩散步骤之后,源信息丢失并且插值是新样本。
Figure 9: Coarse-to-fine interpolations that vary the number of diffusion steps prior to latent mixing.
图 9:从粗到细的插值,改变潜在混合之前的扩散步骤数。
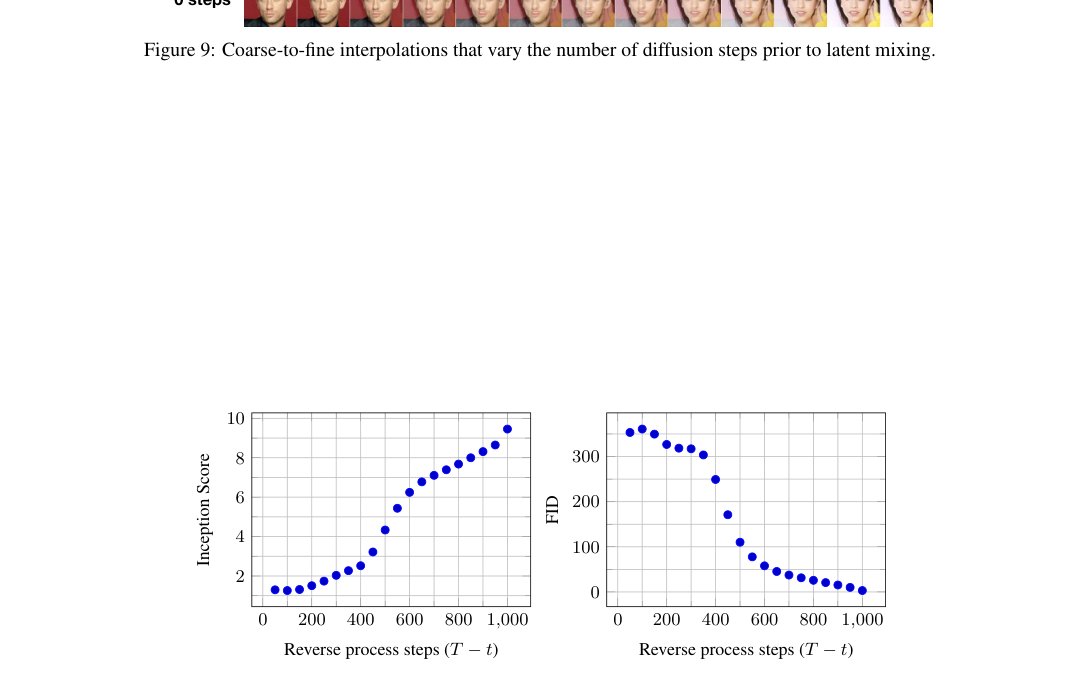
Figure 10: Unconditional CIFAR10 progressive sampling quality over time
图 10:随时间变化的无条件 CIFAR10 渐进采样质量
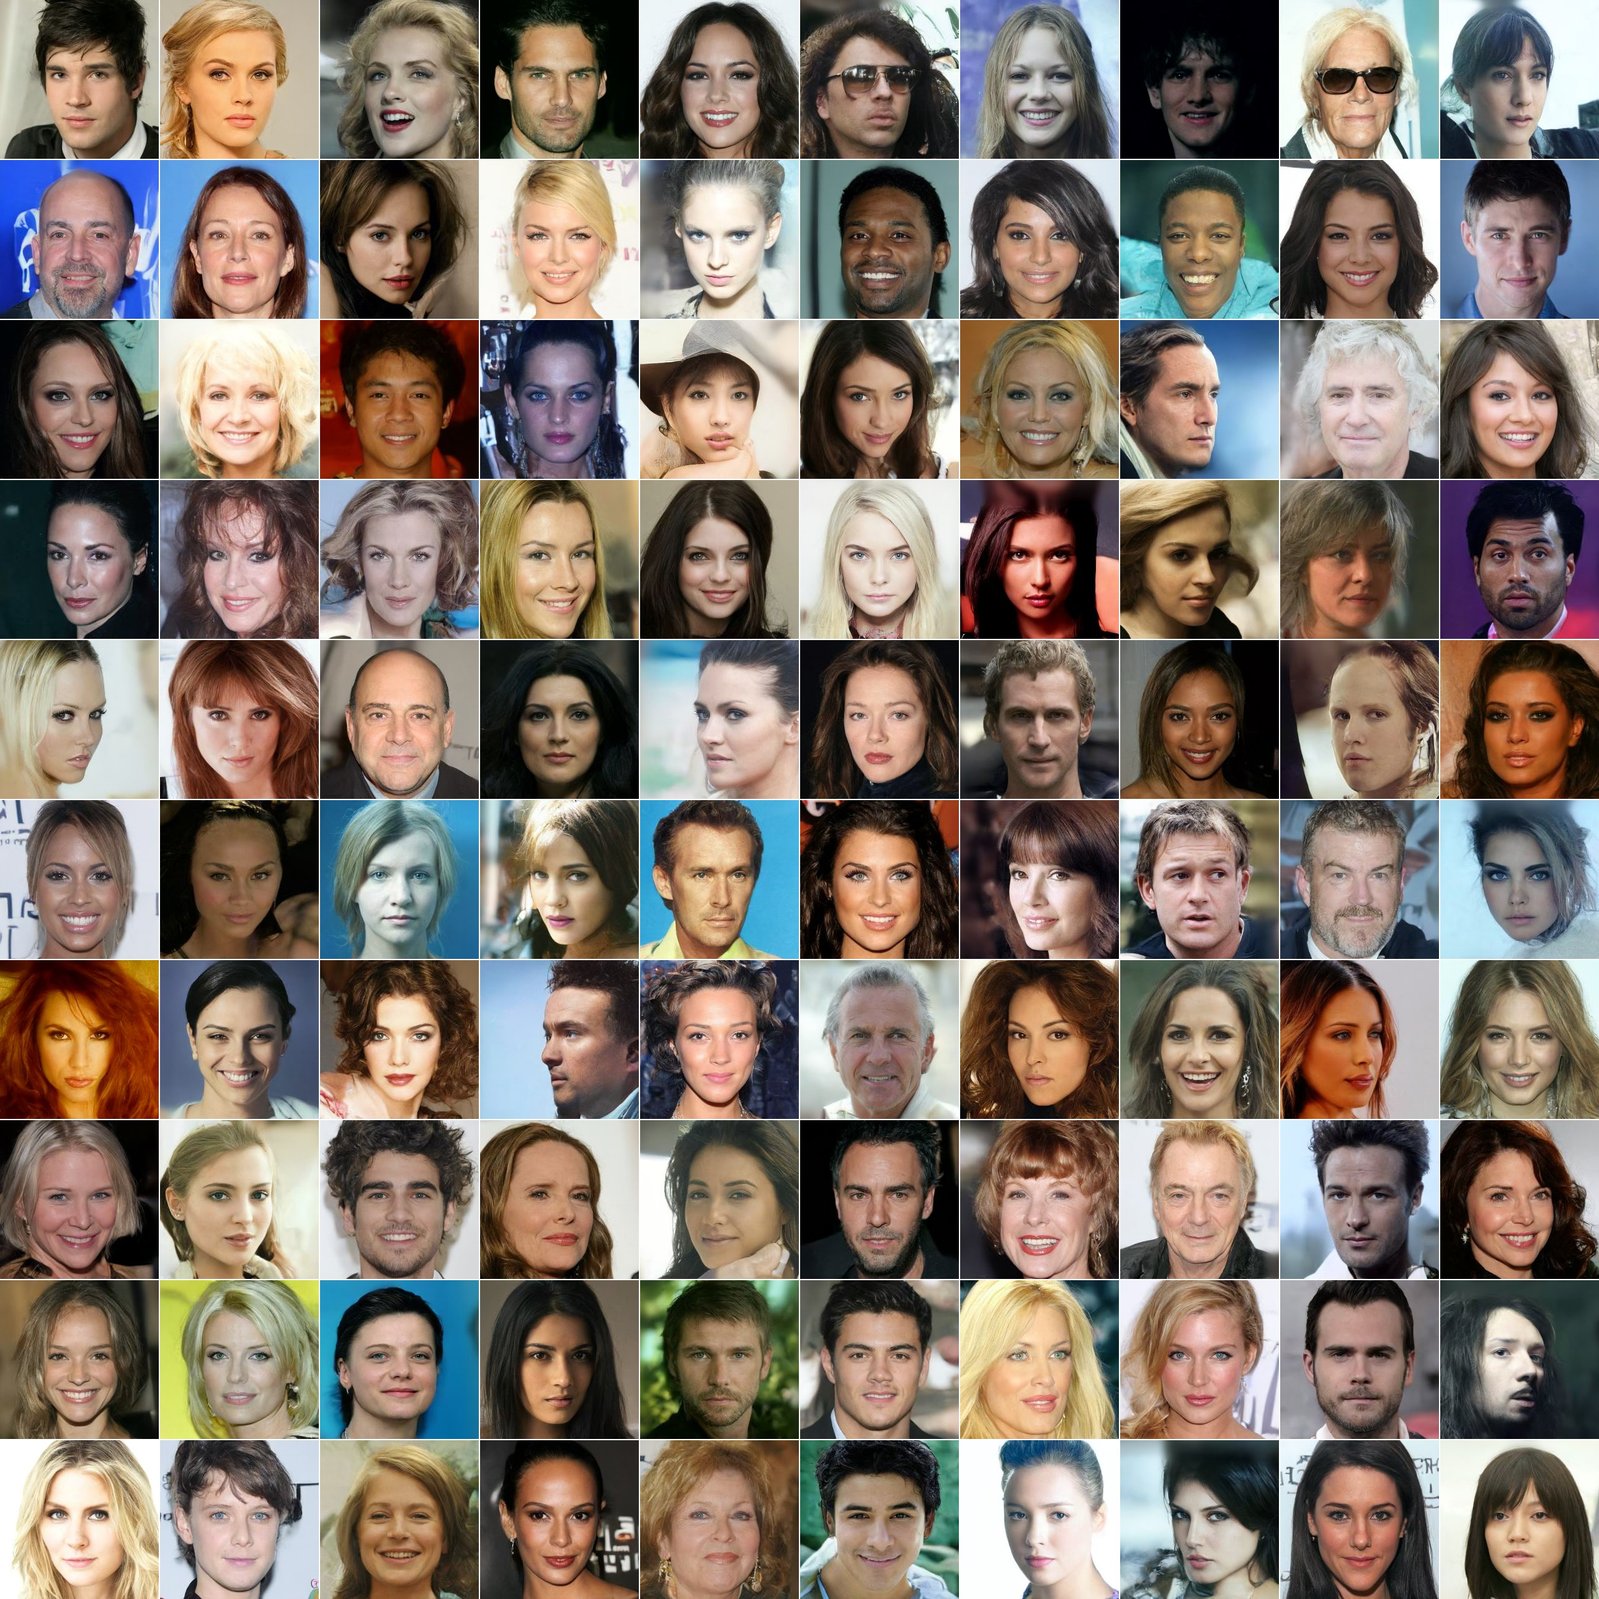
Figure 11: CelebA-HQ generated samples
图 11:CelebA-HQ生成的样本
(a) Pixel space nearest neighbors
(a) 像素空间最近邻
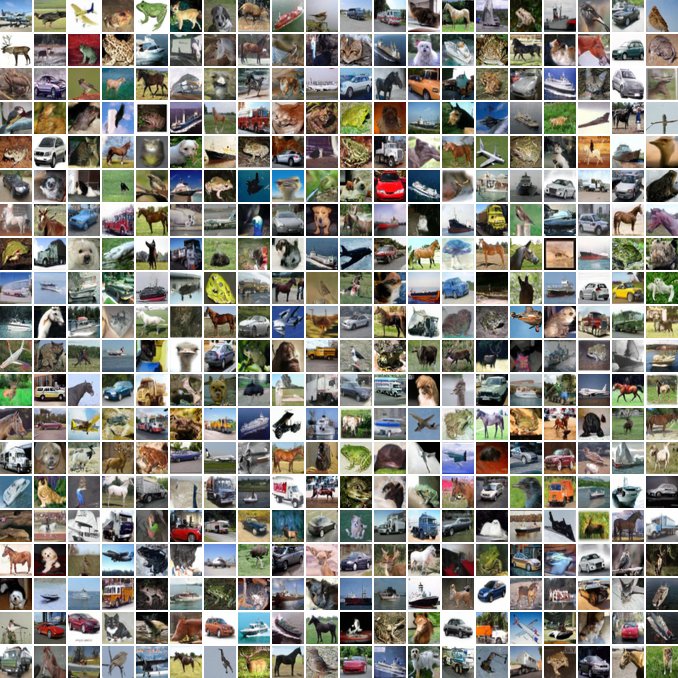
Figure 13: Unconditional CIFAR10 generated samples
图 13:无条件 CIFAR10 生成的样本
Figure 14: Unconditional CIFAR10 progressive generation
图 14:无条件 CIFAR10 渐进式生成
(a) Pixel space nearest neighbors
(a) 像素空间最近邻
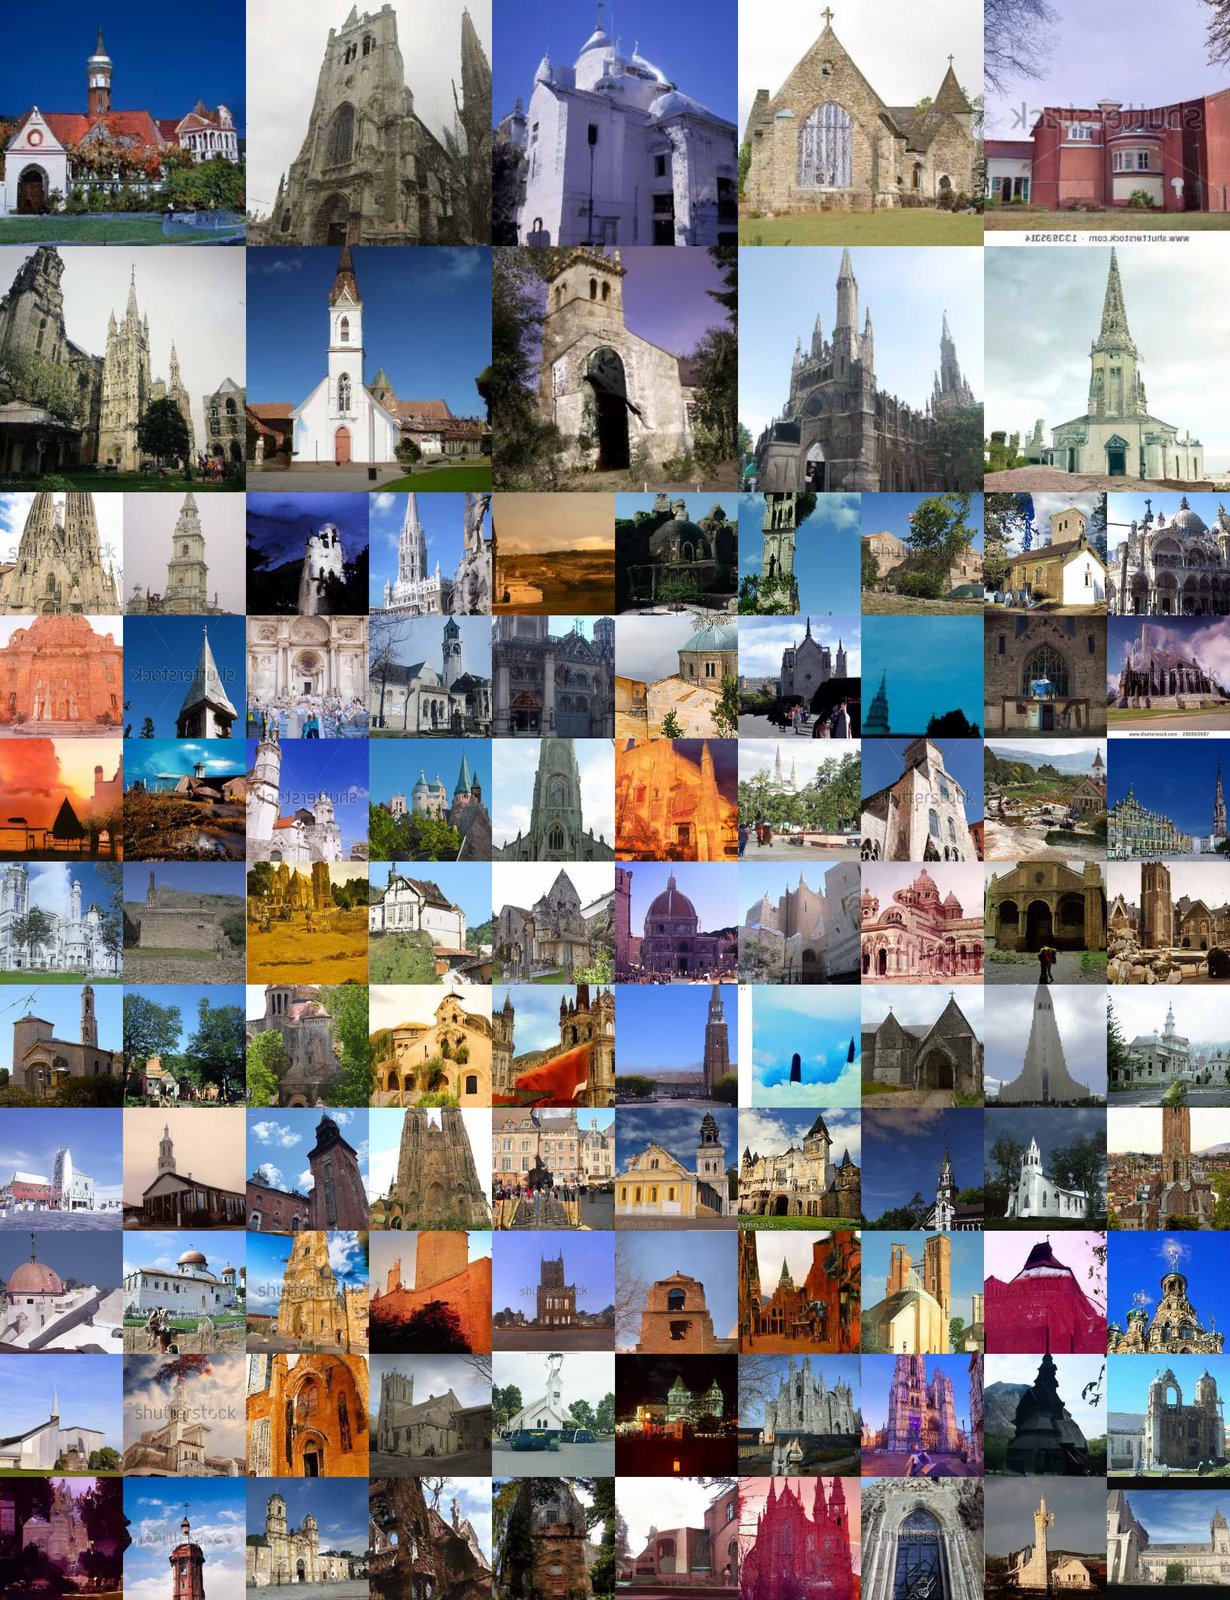
Figure 16: LSUN Church generated samples. FID=
图 16:LSUN Church 生成的样本。 FID=XX数学0XX
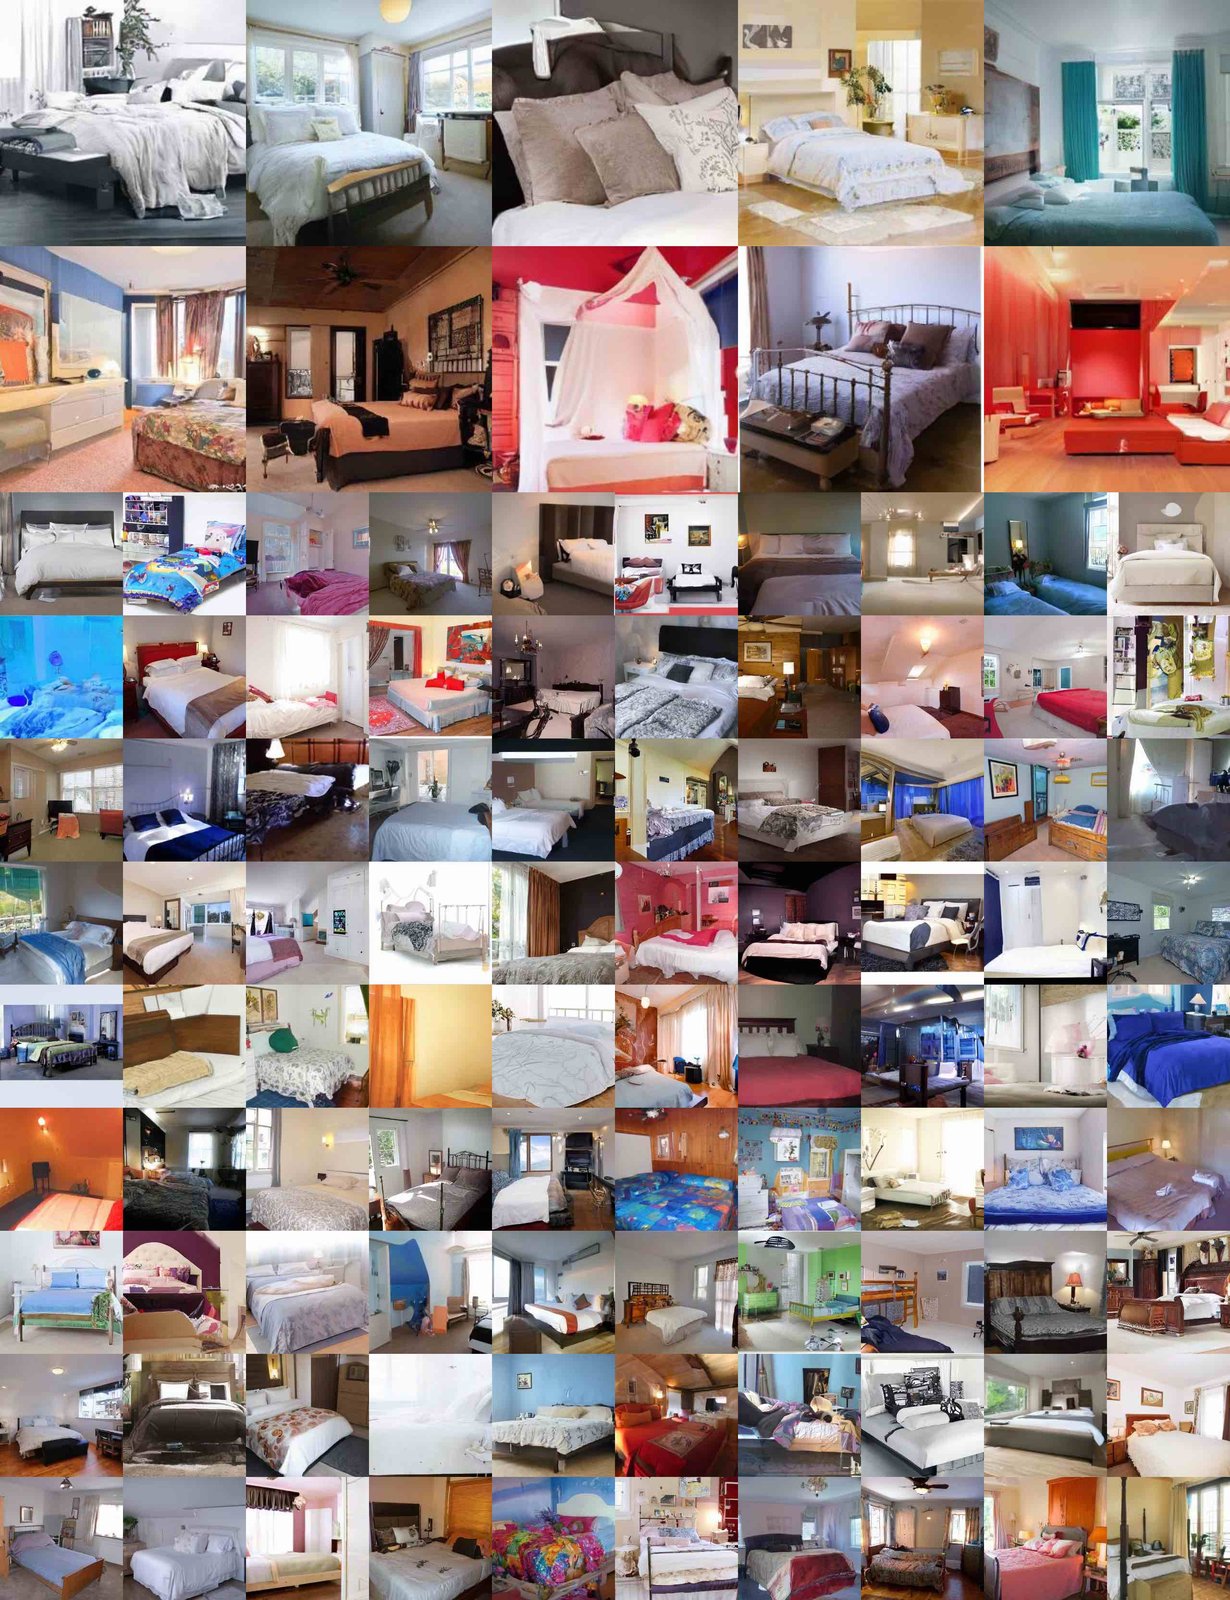
Figure 17: LSUN Bedroom generated samples, large model. FID=
图 17:LSUN Bedroom 生成的样本,大模型。 FID=XX数学0XX
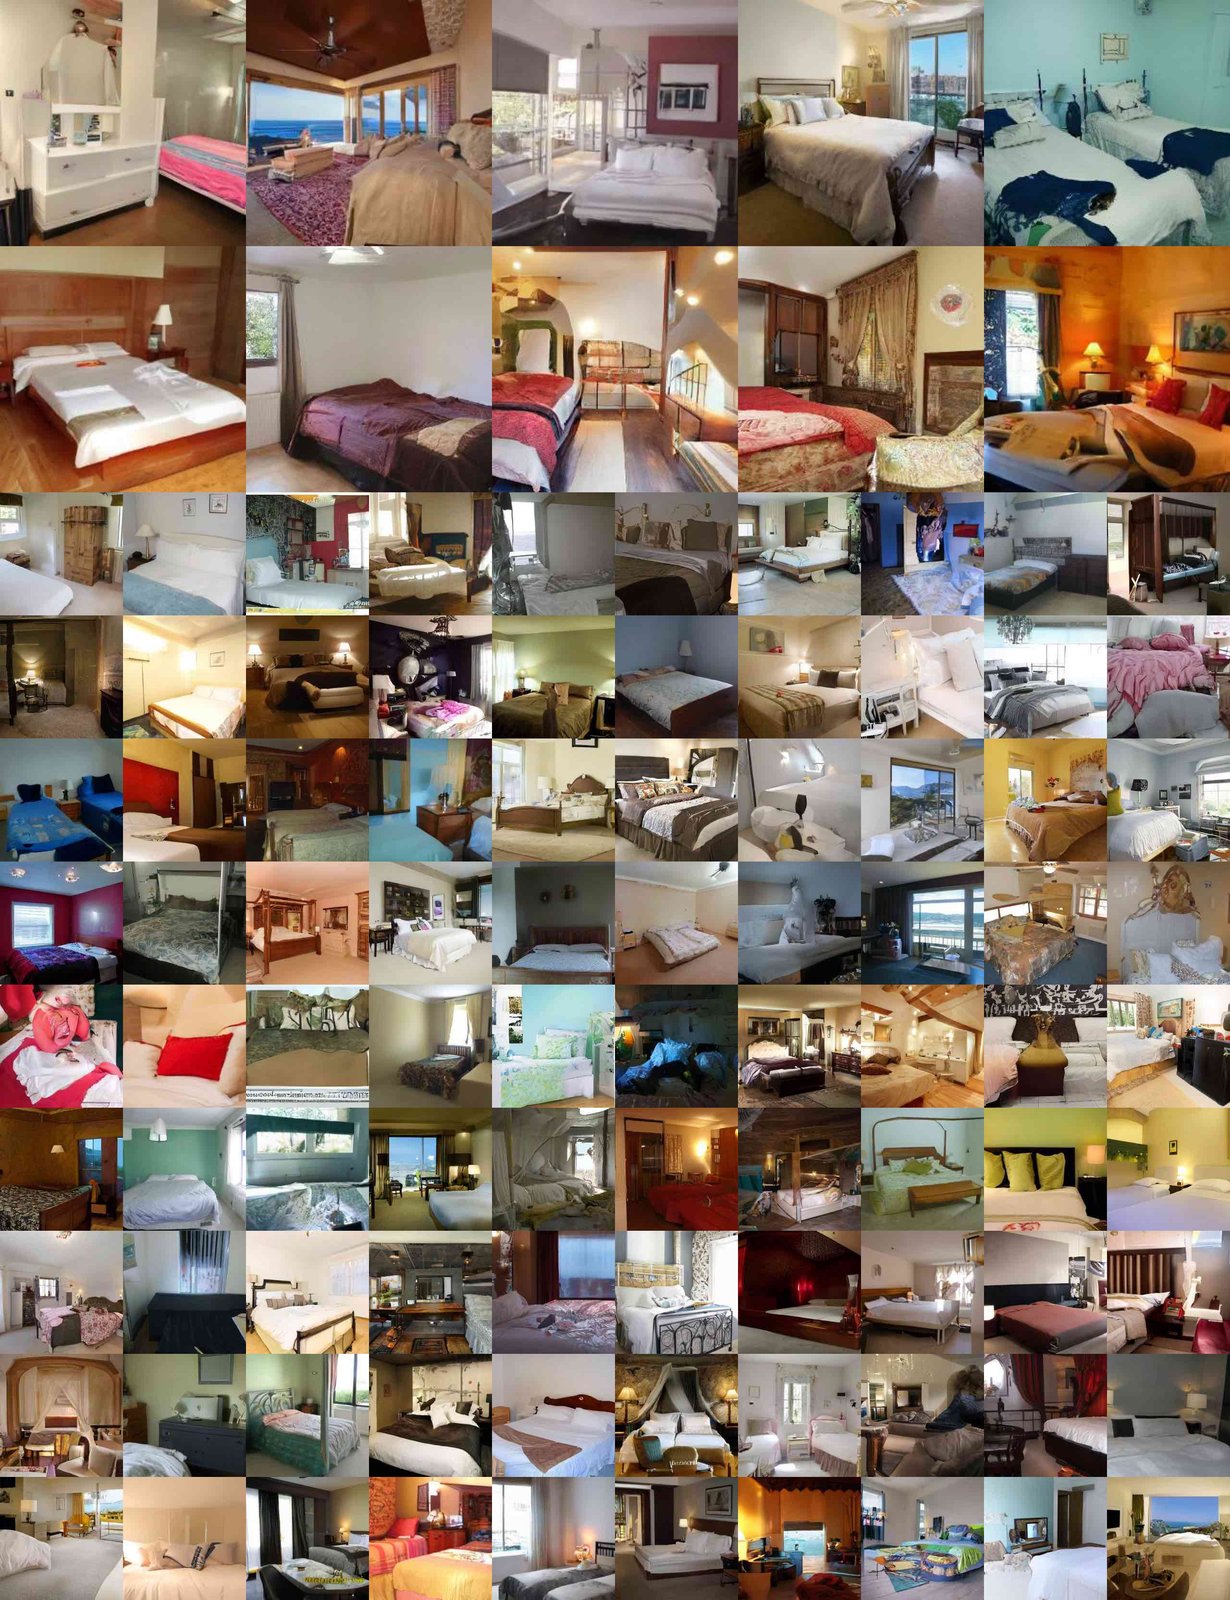
Figure 18: LSUN Bedroom generated samples, small model. FID=
图 18:LSUN Bedroom 生成的样本,小模型。 FID=XX数学0XX
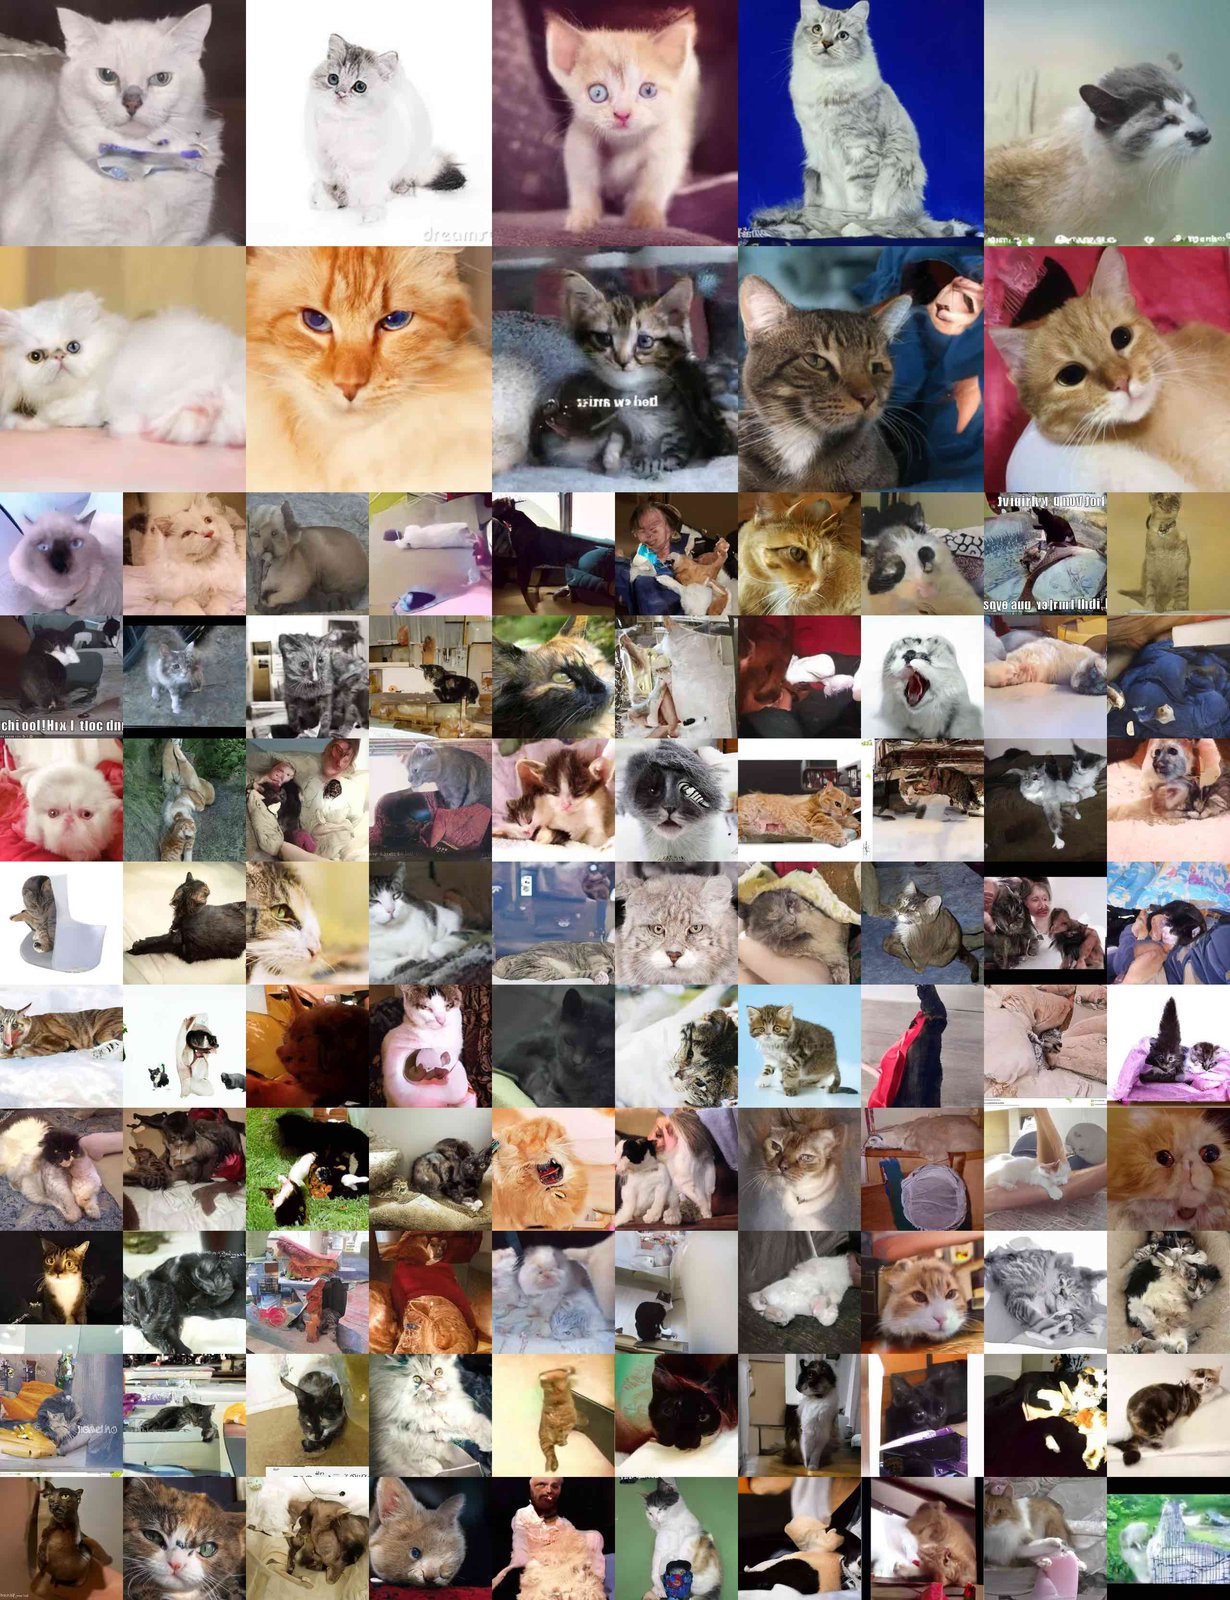
Figure 19: LSUN Cat generated samples. FID=
图 19:LSUN Cat 生成的示例。 FID=XX数学0XX