Deformable Convolutional Networks
Deformable Convolutional Networks
可变形卷积网络
Jifeng Dai Thanks: Equal contribution. †This work is done when Haozhi Qi, Yuwen Xiong, Yi Li and Guodong Zhang are interns at Microsoft Research Asia Haozhi Qi Affiliation: Yi Li Yuwen Xiong Affiliation: Yi Li Guodong ZhangHan HuYichen Wei Microsoft Research Asia {jifdai,v-haoq,v-yuxio,v-yii,v-guodzh,hanhu,yichenw}@microsoft.com Affiliation: Yi Li
Abstract
摘要
Convolutional neural networks (CNNs) are inherently limited to model geometric transformations due to the fixed geometric structures in their building modules. In this work, we introduce two new modules to enhance the transformation modeling capability of CNNs, namely, deformable convolution and deformable RoI pooling. Both are based on the idea of augmenting the spatial sampling locations in the modules with additional offsets and learning the offsets from the target tasks, without additional supervision. The new modules can readily replace their plain counterparts in existing CNNs and can be easily trained end-to-end by standard back-propagation, giving rise to deformable convolutional networks. Extensive experiments validate the performance of our approach. For the first time, we show that learning dense spatial transformation in deep CNNs is effective for sophisticated vision tasks such as object detection and semantic segmentation. The code is released at https://github.com/msracver/Deformable-ConvNets.
卷积神经网络(CNN)的构建模块具有固定的几何结构,因而在建模几何变换上先天受限。本文引入两个新模块来增强 CNN 的变换建模能力,分别称为可变形卷积(deformable convolution)和可变形感兴趣区域池化(deformable RoI pooling)。二者的共同想法是:给模块中的空间采样位置加上额外的偏移,并从目标任务中学习这些偏移,不需要额外监督。新模块可以方便地替换现有 CNN 中的普通对应模块,并用标准反向传播端到端训练,从而得到可变形卷积网络(deformable convolutional networks)。大量实验验证了这一方法的效果。我们首次表明,在深度 CNN 中学习稠密的空间变换,对目标检测和语义分割这类复杂视觉任务是有效的。代码发布于 https://github.com/msracver/Deformable-ConvNets。
1 Introduction
1 引言
A key challenge in visual recognition is how to accommodate geometric variations or model geometric transformations in object scale, pose, viewpoint, and part deformation. In general, there are two ways. The first is to build the training datasets with sufficient desired variations. This is usually realized by augmenting the existing data samples, e.g., by affine transformation. Robust representations can be learned from the data, but usually at the cost of expensive training and complex model parameters. The second is to use transformation-invariant features and algorithms. This category subsumes many well known techniques, such as SIFT (scale invariant feature transform) [42] and sliding window based object detection paradigm.
视觉识别的一个关键挑战,是如何容纳几何变化,或如何对物体在尺度、姿态、视角和部件形变上的几何变换建模。一般有两条路。第一条是构造带有足够所需变化的训练数据,通常靠增强已有样本实现,例如做仿射变换。可以从数据中学到稳健表示,但往往要以昂贵的训练和复杂的模型参数为代价。第二条是使用对变换不变的特征和算法。这一类包括许多著名技术,例如 SIFT(尺度不变特征变换)[42],以及基于滑动窗口的目标检测范式。
There are two drawbacks in above ways. First, the geometric transformations are assumed fixed and known. Such prior knowledge is used to augment the data, and design the features and algorithms. This assumption prevents generalization to new tasks possessing unknown geometric transformations, which are not properly modeled. Second, hand-crafted design of invariant features and algorithms could be difficult or infeasible for overly complex transformations, even when they are known.
上述两条路有两个缺点。第一,几何变换被假定为固定且已知。这种先验被用来增强数据,并设计特征和算法。这一假定妨碍了推广到带有未知几何变换、因而没有被恰当建模的新任务。第二,即便变换已知,手工设计不变特征和算法,对过于复杂的变换也可能困难或不可行。
Recently, convolutional neural networks (CNNs) [35] have achieved significant success for visual recognition tasks, such as image classification [31], semantic segmentation [41], and object detection [16]. Nevertheless, they still share the above two drawbacks. Their capability of modeling geometric transformations mostly comes from the extensive data augmentation, the large model capacity, and some simple hand-crafted modules (e.g., max-pooling [1] for small translation-invariance).
近年来,卷积神经网络(CNN)[35] 在图像分类 [31]、语义分割 [41] 和目标检测 [16] 等视觉识别任务上取得了显著成功。尽管如此,它们仍然具有上述两个缺点。它们建模几何变换的能力,主要来自充分的数据增强、较大的模型容量,以及一些简单的手工模块(例如用于小幅平移不变性的最大池化 [1])。
In short, CNNs are inherently limited to model large, unknown transformations. The limitation originates from the fixed geometric structures of CNN modules: a convolution unit samples the input feature map at fixed locations; a pooling layer reduces the spatial resolution at a fixed ratio; a RoI (region-of-interest) pooling layer separates a RoI into fixed spatial bins, etc. There lacks internal mechanisms to handle the geometric transformations. This causes noticeable problems. For one example, the receptive field sizes of all activation units in the same CNN layer are the same. This is undesirable for high level CNN layers that encode the semantics over spatial locations. Because different locations may correspond to objects with different scales or deformation, adaptive determination of scales or receptive field sizes is desirable for visual recognition with fine localization, e.g., semantic segmentation using fully convolutional networks [41]. For another example, while object detection has seen significant and rapid progress [16, 52, 15, 47, 46, 40, 7] recently, all approaches still rely on the primitive bounding box based feature extraction. This is clearly sub-optimal, especially for non-rigid objects.
简言之,CNN 在建模大幅度、未知的变换上先天受限。这一限制来自 CNN 模块固定的几何结构:卷积单元在固定位置上对输入特征图采样;池化层以固定比例降低空间分辨率;RoI(感兴趣区域)池化层把一个 RoI 分成固定的空间格子,等等。内部缺少处理几何变换的机制。这会带来明显问题。一个例子是,同一 CNN 层中所有激活单元的感受野大小都相同。对在空间位置上编码语义的高层 CNN 来说,这并不理想。因为不同位置可能对应不同尺度或形变的物体,自适应地决定尺度或感受野大小,对需要精细定位的视觉识别是可取的,例如用全卷积网络做语义分割 [41]。另一个例子是,尽管目标检测近来进展迅速 [16, 52, 15, 47, 46, 40, 7],各种方法仍依赖基于原始边界框的特征提取。这显然不是最优的,对非刚性物体尤其如此。
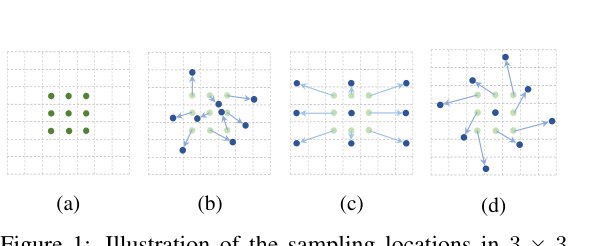
Figure 1: Illustration of the sampling locations in standard and deformable convolutions. (a) regular sampling grid (green points) of standard convolution. (b) deformed sampling locations (dark blue points) with augmented offsets (light blue arrows) in deformable convolution. (c)(d) are special cases of (b), showing that the deformable convolution generalizes various transformations for scale, (anisotropic) aspect ratio and rotation.
图 1: 标准卷积与可变形卷积中采样位置的示意。(a) 标准卷积的规则采样网格(绿色点)。(b) 可变形卷积中带有增强偏移(浅蓝色箭头)的变形采样位置(深蓝色点)。(c)(d) 是 (b) 的特殊情形,表明可变形卷积可以概括尺度、(各向异性)长宽比和旋转等多种变换。
In this work, we introduce two new modules that greatly enhance CNNs’ capability of modeling geometric transformations. The first is deformable convolution. It adds 2D offsets to the regular grid sampling locations in the standard convolution. It enables free form deformation of the sampling grid. It is illustrated in Figure 1. The offsets are learned from the preceding feature maps, via additional convolutional layers. Thus, the deformation is conditioned on the input features in a local, dense, and adaptive manner.
本文引入两个新模块,显著增强 CNN 建模几何变换的能力。第一个是可变形卷积。它在标准卷积的规则网格采样位置上加上二维偏移,使采样网格可以做自由形状的变形,如图 1 所示。偏移通过额外的卷积层从前一层特征图中学习。因此,变形以局部、稠密且自适应的方式条件于输入特征。
The second is deformable RoI pooling. It adds an offset to each bin position in the regular bin partition of the previous RoI pooling [15, 7]. Similarly, the offsets are learned from the preceding feature maps and the RoIs, enabling adaptive part localization for objects with different shapes.
第二个是可变形 RoI 池化。它在先前 RoI 池化 [15, 7] 的规则格子划分中,给每个格子位置加上一个偏移。类似地,偏移从前一层特征图和各个 RoI 中学习,从而能为不同形状的物体做自适应的部件定位。
Both modules are light weight. They add small amount of parameters and computation for the offset learning. They can readily replace their plain counterparts in deep CNNs and can be easily trained end-to-end with standard backpropagation. The resulting CNNs are called deformable convolutional networks, or deformable ConvNets.
两个模块都很轻量。它们只为学习偏移增加少量参数和计算。它们可以方便地替换深度 CNN 中的普通对应模块,并用标准反向传播端到端训练。得到的 CNN 称为可变形卷积网络,或 deformable ConvNets。
Our approach shares similar high level spirit with spatial transform networks [26] and deformable part models [11]. They all have internal transformation parameters and learn such parameters purely from data. A key difference in deformable ConvNets is that they deal with dense spatial transformations in a simple, efficient, deep and end-to-end manner. In Section 3.1, we discuss in details the relation of our work to previous works and analyze the superiority of deformable ConvNets.
我们的方法与空间变换网络 [26] 和可变形部件模型 [11] 在高层次想法上相近。它们都带有内部变换参数,并纯粹从数据中学习这些参数。可变形 ConvNets 的一个关键不同在于:它们以简单、高效、深层且端到端的方式处理稠密空间变换。第 3.1 节将详细讨论本文与先前工作的关系,并分析可变形 ConvNets 的优势。
2 Deformable Convolutional Networks
2 可变形卷积网络
The feature maps and convolution in CNNs are 3D. Both deformable convolution and RoI pooling modules operate on the 2D spatial domain. The operation remains the same across the channel dimension. Without loss of generality, the modules are described in 2D here for notation clarity. Extension to 3D is straightforward.
CNN 中的特征图和卷积是三维的。可变形卷积和 RoI 池化模块都作用在二维空间域上,并在通道维上保持相同操作。不失一般性,这里为记号清晰起见在二维中描述这些模块。推广到三维是直接的。
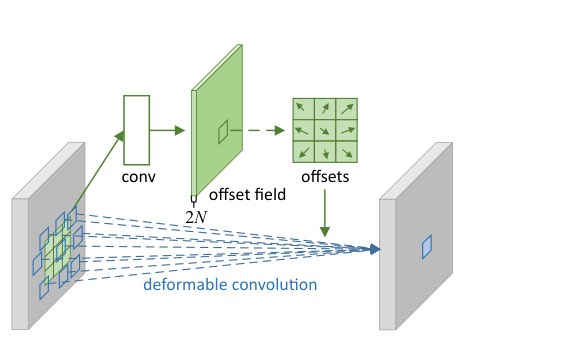
Figure 2: Illustration of deformable convolution.
图 2: 可变形卷积示意。
2.1 Deformable Convolution
2.1 可变形卷积
The 2D convolution consists of two steps: 1) sampling using a regular grid over the input feature map ; 2) summation of sampled values weighted by . The grid defines the receptive field size and dilation. For example,
二维卷积包含两步:1) 在输入特征图 上用规则网格 采样;2) 把采样值按 加权求和。网格 定义了感受野大小和膨胀。例如,
defines a kernel with dilation .
定义了一个膨胀为 的 核。
For each location on the output feature map , we have
对输出特征图 上的每个位置 ,我们有
where enumerates the locations in .
其中 枚举 中的各个位置。
In deformable convolution, the regular grid is augmented with offsets , where . Eq. (1) becomes
在可变形卷积中,规则网格 被加上偏移 ,其中 。公式 (1) 变为
Now, the sampling is on the irregular and offset locations . As the offset is typically fractional, Eq. (2) is implemented via bilinear interpolation as
此时采样发生在不规则的偏移位置 上。由于偏移 通常是分数,公式 (2) 通过双线性插值实现为
where denotes an arbitrary (fractional) location ( for Eq. (2)), enumerates all integral spatial locations in the feature map , and is the bilinear interpolation kernel. Note that is two dimensional. It is separated into two one dimensional kernels as
其中 表示任意(分数)位置(对公式 (2) 有 ), 枚举特征图 上所有整数空间位置, 是双线性插值核。注意 是二维的,它被分解成两个一维核:
where . Eq. (3) is fast to compute as is non-zero only for a few s.
其中 。公式 (3) 计算很快,因为 只对少数 非零。
As illustrated in Figure 2, the offsets are obtained by applying a convolutional layer over the same input feature map. The convolution kernel is of the same spatial resolution and dilation as those of the current convolutional layer (e.g., also with dilation 1 in Figure 2). The output offset fields have the same spatial resolution with the input feature map. The channel dimension corresponds to 2D offsets. During training, both the convolutional kernels for generating the output features and the offsets are learned simultaneously. To learn the offsets, the gradients are back-propagated through the bilinear operations in Eq. (3) and Eq. (4). It is detailed in appendix A.
如图 2 所示,偏移通过对同一输入特征图施加一个卷积层得到。该卷积核的空间分辨率和膨胀与当前卷积层相同(例如在图 2 中也是膨胀为 1 的 )。输出的偏移场与输入特征图具有相同的空间分辨率。通道维 对应 个二维偏移。训练时,生成输出特征的卷积核和偏移同时学习。为了学习偏移,梯度通过公式 (3) 和公式 (4) 中的双线性运算反向传播。细节见附录 A。
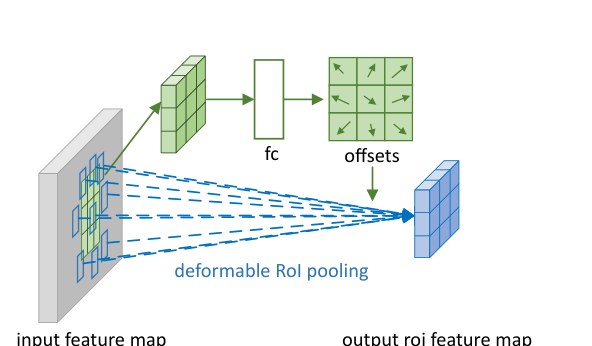
Figure 3: Illustration of deformable RoI pooling.
图 3: 可变形 RoI 池化示意。
2.2 Deformable RoI Pooling
2.2 可变形 RoI 池化
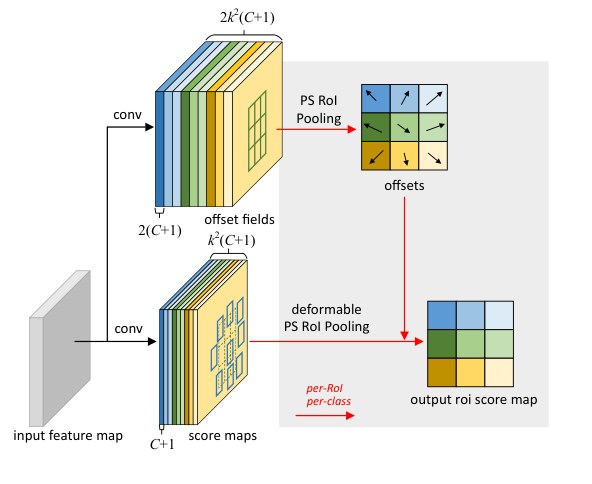
Figure 4: Illustration of deformable PS RoI pooling.
图 4: 可变形位置敏感 RoI 池化示意。
RoI pooling is used in all region proposal based object detection methods [16, 15, 47, 7]. It converts an input rectangular region of arbitrary size into fixed size features.
基于区域提议的目标检测方法都使用 RoI 池化 [16, 15, 47, 7]。它把任意大小的输入矩形区域转换成固定大小的特征。
RoI Pooling [15] Given the input feature map and a RoI of size and top-left corner , RoI pooling divides the RoI into ( is a free parameter) bins and outputs a feature map . For -th bin (), we have
RoI 池化 [15] 给定输入特征图 ,以及大小为 、左上角为 的 RoI,RoI 池化把该 RoI 分成 个格子( 是自由参数),并输出 的特征图 。对第 个格子(),我们有
where is the number of pixels in the bin. The -th bin spans and .
其中 是该格子中的像素数。第 个格子覆盖 以及 。
Similarly as in Eq. (2), in deformable RoI pooling, offsets are added to the spatial binning positions. Eq.(5) becomes
与公式 (2) 类似,可变形 RoI 池化把偏移 加到空间分格位置上。公式 (5) 变为
Typically, is fractional. Eq. (6) is implemented by bilinear interpolation via Eq. (3) and (4).
通常 是分数。公式 (6) 通过公式 (3) 和 (4) 的双线性插值实现。
Figure 3 illustrates how to obtain the offsets. Firstly, RoI pooling (Eq. (5)) generates the pooled feature maps. From the maps, a fc layer generates the normalized offsets , which are then transformed to the offsets in Eq. (6) by element-wise product with the RoI’s width and height, as . Here is a pre-defined scalar to modulate the magnitude of the offsets. It is empirically set to . The offset normalization is necessary to make the offset learning invariant to RoI size. The fc layer is learned by back-propagation, as detailed in appendix A.
图 3 说明了如何得到这些偏移。首先,RoI 池化(公式 (5))生成池化后的特征图。从这些图出发,一个全连接层生成归一化偏移 ,再通过与 RoI 宽高的逐元素乘积变换成公式 (6) 中的偏移,即 。这里 是预设标量,用来调节偏移幅度,经验上取 。偏移归一化是必要的,这样偏移学习才会对 RoI 大小不变。全连接层通过反向传播学习,细节见附录 A。
Position-Sensitive (PS) RoI Pooling [7] It is fully convolutional and different from RoI pooling. Through a conv layer, all the input feature maps are firstly converted to score maps for each object class (totally for object classes), as illustrated in the bottom branch in Figure 4. Without need to distinguish between classes, such score maps are denoted as where enumerates all bins. Pooling is performed on these score maps. The output value for -th bin is obtained by summation from one score map corresponding to that bin. In short, the difference from RoI pooling in Eq.(5) is that a general feature map is replaced by a specific positive-sensitive score map .
位置敏感(PS)RoI 池化 [7] 它是全卷积的,与 RoI 池化不同。通过一个卷积层,所有输入特征图首先被转换成每个物体类别的 张得分图( 个物体类别共 组),如图 4 下分支所示。不必区分类别时,这些得分图记为 ,其中 枚举各个格子。池化在这些得分图上进行。第 个格子的输出值,由对应该格子的一张得分图 求和得到。简言之,与公式 (5) 中 RoI 池化的差别在于:一般特征图 被换成了特定的位置敏感得分图 。
In deformable PS RoI pooling, the only change in Eq. (6) is that is also modified to . However, the offset learning is different. It follows the “fully convolutional” spirit in [7], as illustrated in Figure 4. In the top branch, a conv layer generates the full spatial resolution offset fields. For each RoI (also for each class), PS RoI pooling is applied on such fields to obtain normalized offsets , which are then transformed to the real offsets in the same way as in deformable RoI pooling described above.
在可变形 PS RoI 池化中,公式 (6) 唯一的改动是把 也改成 。不过偏移的学习方式不同。它遵循 [7] 中“全卷积”的思路,如图 4 所示。在上分支,一个卷积层生成全空间分辨率的偏移场。对每个 RoI(也对每个类别),在这些场上做 PS RoI 池化,得到归一化偏移 ,再按上面可变形 RoI 池化相同的方式变换成真实偏移 。
2.3 Deformable ConvNets
2.3 可变形 ConvNets
Both deformable convolution and RoI pooling modules have the same input and output as their plain versions. Hence, they can readily replace their plain counterparts in existing CNNs. In the training, these added conv and fc layers for offset learning are initialized with zero weights. Their learning rates are set to times ( by default, and for the fc layer in Faster R-CNN) of the learning rate for the existing layers. They are trained via back propagation through the bilinear interpolation operations in Eq. (3) and Eq. (4). The resulting CNNs are called deformable ConvNets.
可变形卷积和 RoI 池化模块的输入输出都与普通版本相同,因此可以方便地替换现有 CNN 中的对应模块。训练时,这些新增的、用于学习偏移的卷积层和全连接层用零权重初始化。它们的学习率设为现有层学习率的 倍(默认 ,Faster R-CNN 中的全连接层取 )。它们通过公式 (3) 和公式 (4) 中双线性插值运算的反向传播来训练。得到的 CNN 称为可变形 ConvNets。
To integrate deformable ConvNets with the state-of-the-art CNN architectures, we note that these architectures consist of two stages. First, a deep fully convolutional network generates feature maps over the whole input image. Second, a shallow task specific network generates results from the feature maps. We elaborate the two steps below.
为了把可变形 ConvNets 接到当时最好的 CNN 结构上,我们注意到这些结构由两个阶段组成。第一,一个深层全卷积网络在整张输入图像上生成特征图。第二,一个较浅的任务特定网络从特征图生成结果。下面分别说明这两步。
Deformable Convolution for Feature Extraction We adopt two state-of-the-art architectures for feature extraction: ResNet-101 [22] and a modifed version of Inception-ResNet [51]. Both are pre-trained on ImageNet [8] classification dataset.
用于特征提取的可变形卷积 我们采用两种当时最好的特征提取结构:ResNet-101 [22],以及对 Inception-ResNet [51] 的一个修改版本。二者都在 ImageNet [8] 分类数据集上预训练。
The original Inception-ResNet is designed for image recognition. It has a feature misalignment issue and problematic for dense prediction tasks. It is modified to fix the alignment problem [20]. The modified version is dubbed as “Aligned-Inception-ResNet” and is detailed in appendix B.
原始的 Inception-ResNet 是为图像识别设计的。它存在特征不对齐问题,对稠密预测任务不合适。我们按 [20] 修改以修复对齐问题。修改后的版本称为“Aligned-Inception-ResNet”,细节见附录 B。
Both models consist of several convolutional blocks, an average pooling and a 1000-way fc layer for ImageNet classification. The average pooling and the fc layers are removed. A randomly initialized convolution is added at last to reduce the channel dimension to . As in common practice [4, 7], the effective stride in the last convolutional block is reduced from pixels to pixels to increase the feature map resolution. Specifically, at the beginning of the last block, stride is changed from to (“conv5” for both ResNet-101 and Aligned-Inception-ResNet). To compensate, the dilation of all the convolution filters in this block (with kernel size ) is changed from to .
两个模型都由若干卷积块、一个平均池化和一个 1000 维全连接层(用于 ImageNet 分类)组成。平均池化和全连接层被去掉。最后加上一个随机初始化的 卷积,把通道维降到 。按常见做法 [4, 7],最后一个卷积块的有效步幅从 像素降到 像素,以提高特征图分辨率。具体地,在最后一块开头,步幅从 改成 (ResNet-101 和 Aligned-Inception-ResNet 都对应“conv5”)。作为补偿,该块中所有核大小大于 的卷积滤波器,膨胀从 改成 。
Optionally, deformable convolution is applied to the last few convolutional layers (with kernel size ). We experimented with different numbers of such layers and found as a good trade-off for different tasks, as reported in Table 1.
可选地,把可变形卷积用在最后几层卷积(核大小大于 )上。我们实验了不同层数,发现 层对不同任务都是较好的折中,见表 1。
Segmentation and Detection Networks A task specific network is built upon the output feature maps from the feature extraction network mentioned above.
分割与检测网络 在上述特征提取网络的输出特征图之上,再搭建任务特定网络。
In the below, denotes the number of object classes.
下文中, 表示物体类别数。
DeepLab [5] is a state-of-the-art method for semantic segmentation. It adds a convolutional layer over the feature maps to generates maps that represent the per-pixel classification scores. A following softmax layer then outputs the per-pixel probabilities.
DeepLab [5] 是当时语义分割的一流方法。它在特征图上加一个 卷积层,生成 张表示逐像素分类得分的图。随后的 softmax 层输出逐像素概率。
Category-Aware RPN is almost the same as the region proposal network in [47], except that the 2-class (object or not) convolutional classifier is replaced by a -class convolutional classifier. It can be considered as a simplified version of SSD [40].
类别感知 RPN 与 [47] 中的区域提议网络几乎相同,只是把二类(是不是物体)卷积分类器换成 类卷积分类器。它可以看成 SSD [40] 的简化版。
Faster R-CNN [47] is the state-of-the-art detector. In our implementation, the RPN branch is added on the top of the conv4 block, following [47]. In the previous practice [22, 24], the RoI pooling layer is inserted between the conv4 and the conv5 blocks in ResNet-101, leaving 10 layers for each RoI. This design achieves good accuracy but has high per-RoI computation. Instead, we adopt a simplified design as in [38]. The RoI pooling layer is added at last[^1]. On top of the pooled RoI features, two fc layers of dimension are added, followed by the bounding box regression and the classification branches. Although such simplification (from 10 layer conv5 block to 2 fc layers) would slightly decrease the accuracy, it still makes a strong enough baseline and is not a concern in this work.
Faster R-CNN [47] 是当时最好的检测器。我们的实现里,RPN 分支加在 conv4 块顶部,与 [47] 一致。先前做法 [22, 24] 把 RoI 池化层插在 ResNet-101 的 conv4 与 conv5 块之间,给每个 RoI 留下 10 层。这一设计准确率好,但每个 RoI 的计算量高。我们改用 [38] 中的简化设计:把 RoI 池化层加在最后。[^1] 在池化后的 RoI 特征之上,加上两个维度为 的全连接层,再接边界框回归和分类分支。虽然这种简化(从 10 层的 conv5 块变成 2 个全连接层)会略降准确率,它仍然是足够强的基线,在本工作中不必担心。
Optionally, the RoI pooling layer can be changed to deformable RoI pooling.
可选地,可以把 RoI 池化层改成可变形 RoI 池化。
R-FCN [7] is another state-of-the-art detector. It has negligible per-RoI computation cost. We follow the original implementation. Optionally, its RoI pooling layer can be changed to deformable position-sensitive RoI pooling.
R-FCN [7] 是另一种一流检测器,每个 RoI 的计算代价可以忽略。我们沿用原始实现。可选地,把它的 RoI 池化层改成可变形位置敏感 RoI 池化。
3 Understanding Deformable ConvNets
3 理解可变形 ConvNets
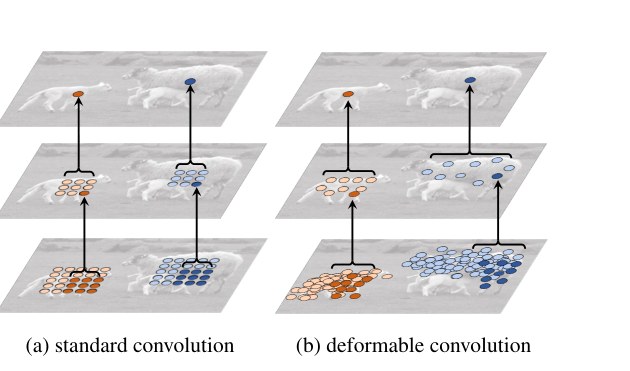
Figure 5: Illustration of the fixed receptive field in standard convolution (a) and the adaptive receptive field in deformable convolution (b), using two layers. Top: two activation units on the top feature map, on two objects of different scales and shapes. The activation is from a filter. Middle: the sampling locations of the filter on the preceding feature map. Another two activation units are highlighted. Bottom: the sampling locations of two levels of filters on the preceding feature map. Two sets of locations are highlighted, corresponding to the highlighted units above.
图 5:标准卷积中固定感受野 (a) 与可变形卷积中自适应感受野 (b) 的示意,使用两层。上:顶层特征图上两个激活单元,分别落在尺度和形状不同的两个物体上。激活来自 滤波器。中:该 滤波器在前一层特征图上的采样位置。另外两个激活单元被标出。下:两层 滤波器在前一层特征图上的采样位置。两套位置被标出,分别对应上面标出的单元。
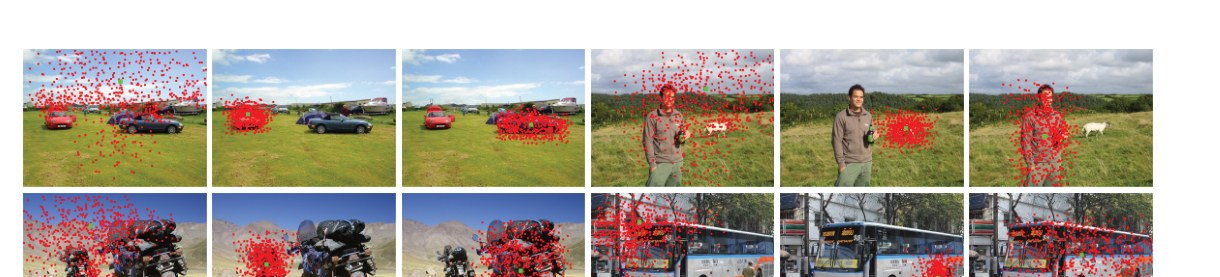
Figure 6: Each image triplet shows the sampling locations ( red points in each image) in three levels of deformable filters (see Figure 5 as a reference) for three activation units (green points) on the background (left), a small object (middle), and a large object (right), respectively.
图 6:每组三张图给出三层 可变形滤波器(参见图 5)中的采样位置(每张图 个红点),分别对应背景(左)、小物体(中)和大物体(右)上的三个激活单元(绿点)。
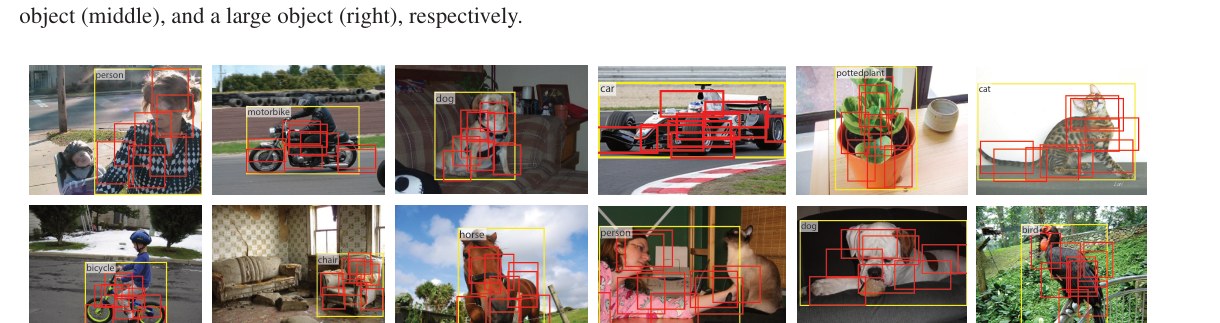
Figure 7: Illustration of offset parts in deformable (positive sensitive) RoI pooling in R-FCN [7] and bins (red) for an input RoI (yellow). Note how the parts are offset to cover the non-rigid objects.
图 7:R-FCN [7] 中可变形(位置敏感)RoI 池化的偏移部件示意,以及输入 RoI(黄)上的 格子(红)。注意这些部件如何偏移以覆盖非刚性物体。
This work is built on the idea of augmenting the spatial sampling locations in convolution and RoI pooling with additional offsets and learning the offsets from target tasks.
本工作的基础想法是:给卷积和 RoI 池化中的空间采样位置加上额外偏移,并从目标任务中学习这些偏移。
When the deformable convolution are stacked, the effect of composited deformation is profound. This is exemplified in Figure 5. The receptive field and the sampling locations in the standard convolution are fixed all over the top feature map (left). They are adaptively adjusted according to the objects’ scale and shape in deformable convolution (right). More examples are shown in Figure 6. Table 2 provides quantitative evidence of such adaptive deformation.
当可变形卷积被堆叠起来时,复合变形的效果相当显著。图 5 给出了例证。标准卷积的感受野和采样位置在整张顶层特征图上都是固定的(左);在可变形卷积中,它们会按物体的尺度和形状自适应调整(右)。更多例子见图 6。表 2 为这种自适应变形提供了定量证据。
The effect of deformable RoI pooling is similar, as illustrated in Figure 7. The regularity of the grid structure in standard RoI pooling no longer holds. Instead, parts deviate from the RoI bins and move onto the nearby object foreground regions. The localization capability is enhanced, especially for non-rigid objects.
可变形 RoI 池化的效果类似,如图 7 所示。标准 RoI 池化中规则的网格结构不再成立。部件会偏离 RoI 格子,移到附近的物体前景区域上。定位能力得到增强,对非刚性物体尤其明显。
3.1 In Context of Related Works
3.1 与相关工作的对照
Our work is related to previous works in different aspects. We discuss the relations and differences in details.
我们的工作在不同方面与先前工作相关。下面详细讨论这些关系与差别。
Spatial Transform Networks (STN) [26] It is the first work to learn spatial transformation from data in a deep learning framework. It warps the feature map via a global parametric transformation such as affine transformation. Such warping is expensive and learning the transformation parameters is known difficult. STN has shown successes in small scale image classification problems. The inverse STN method [37] replaces the expensive feature warping by efficient transformation parameter propagation.
空间变换网络(STN)[26] 这是在深度学习框架中从数据学习空间变换的第一项工作。它通过仿射变换这类全局参数化变换来扭曲特征图。这种扭曲代价高,学习变换参数也被认为困难。STN 在小规模图像分类问题上取得过成功。逆 STN 方法 [37] 用高效的变换参数传播,取代了昂贵的特征扭曲。
The offset learning in deformable convolution can be considered as an extremely light-weight spatial transformer in STN [26]. However, deformable convolution does not adopt a global parametric transformation and feature warping. Instead, it samples the feature map in a local and dense manner. To generate new feature maps, it has a weighted summation step, which is absent in STN.
可变形卷积中的偏移学习,可以看成 STN [26] 里一种极轻量的空间变换器。不过,可变形卷积并不采用全局参数化变换和特征扭曲,而是以局部、稠密的方式对特征图采样。为了生成新的特征图,它还有加权求和一步,这是 STN 所没有的。
Deformable convolution is easy to integrate into any CNN architectures. Its training is easy. It is shown effective for complex vision tasks that require dense (e.g., semantic segmentation) or semi-dense (e.g., object detection) predictions. These tasks are difficult (if not infeasible) for STN [26, 37].
可变形卷积容易接入任何 CNN 结构,训练也容易。它被证明对需要稠密(例如语义分割)或半稠密(例如目标检测)预测的复杂视觉任务有效。这些任务对 STN [26, 37] 来说很困难(即便不是不可行)。
Active Convolution [27] This work is contemporary. It also augments the sampling locations in the convolution with offsets and learns the offsets via back-propagation end-to-end. It is shown effective on image classification tasks.
主动卷积(Active Convolution)[27] 这项工作与我们同时期。它也给卷积中的采样位置加上偏移,并通过反向传播端到端学习偏移。它在图像分类任务上被证明有效。
Two crucial differences from deformable convolution make this work less general and adaptive. First, it shares the offsets all over the different spatial locations. Second, the offsets are static model parameters that are learnt per task or per training. In contrast, the offsets in deformable convolution are dynamic model outputs that vary per image location. They model the dense spatial transformations in the images and are effective for (semi-)dense prediction tasks such as object detection and semantic segmentation.
与可变形卷积的两个关键差别,使这项工作更不通用、也更不自适应。第一,它在不同空间位置上共享同一组偏移。第二,这些偏移是静态模型参数,按任务或按一次训练来学习。相比之下,可变形卷积中的偏移是动态的模型输出,随图像位置而变。它们对图像中的稠密空间变换建模,对目标检测和语义分割这类(半)稠密预测任务有效。
Effective Receptive Field [43] It finds that not all pixels in a receptive field contribute equally to an output response. The pixels near the center have much larger impact. The effective receptive field only occupies a small fraction of the theoretical receptive field and has a Gaussian distribution. Although the theoretical receptive field size increases linearly with the number of convolutional layers, a surprising result is that, the effective receptive field size increases linearly with the square root of the number, therefore, at a much slower rate than what we would expect.
有效感受野 [43] 这项工作发现,感受野中并非所有像素对输出响应的贡献都相同。靠近中心的像素影响大得多。有效感受野只占理论感受野的一小部分,并呈高斯分布。虽然理论感受野大小随卷积层数线性增加,一个出人意料的结果是:有效感受野大小随层数的平方根线性增加,因而比我们预期的要慢得多。
This finding indicates that even the top layer’s unit in deep CNNs may not have large enough receptive field. This partially explains why atrous convolution [23] is widely used in vision tasks (see below). It indicates the needs of adaptive receptive field learning.
这一发现表明,即便深度 CNN 顶层的单元,感受野也可能不够大。这在一定程度上解释了为什么空洞卷积 [23] 在视觉任务中被广泛使用(见下文)。它也说明需要自适应地学习感受野。
Deformable convolution is capable of learning receptive fields adaptively, as shown in Figure 5, 6 and Table 2.
可变形卷积能够自适应地学习感受野,如图 5、图 6 和表 2 所示。
Atrous convolution [23] It increases a normal filter’s stride to be larger than and keeps the original weights at sparsified sampling locations. This increases the receptive field size and retains the same complexity in parameters and computation. It has been widely used for semantic segmentation [41, 5, 54] (also called dilated convolution in [54]), object detection [7], and image classification [55].
空洞卷积 [23] 它把普通滤波器的采样步幅加大到大于 ,并在稀疏化的采样位置上保留原来的权重。这样在增大感受野的同时,参数量和计算量保持不变。它已被广泛用于语义分割 [41, 5, 54](在 [54] 中也称为膨胀卷积)、目标检测 [7] 和图像分类 [55]。
Deformable convolution is a generalization of atrous convolution, as easily seen in Figure 1 (c). Extensive comparison to atrous convolution is presented in Table 3.
可变形卷积是空洞卷积的推广,从图 1 (c) 很容易看出。与空洞卷积的详细比较见表 3。
| usage of deformable convolution ( layers) | DeepLab | class-aware RPN | Faster R-CNN | R-FCN | ||||
|---|---|---|---|---|---|---|---|---|
| mIoU@V (%) | mIoU@C (%) | mAP@0.5 (%) | mAP@0.7 (%) | mAP@0.5 (%) | mAP@0.7 (%) | mAP@0.5 (%) | mAP@0.7 (%) | |
| none (0, baseline) | 69.7 | 70.4 | 78.1 | 62.1 | 80.0 | 61.8 | ||
| res5c (1) | 73.9 | 73.5 | 78.6 | 63.8 | 80.6 | 63.0 | ||
| res5b,c (2) | 74.8 | 74.4 | 78.5 | 63.3 | 81.0 | 63.8 | ||
| res5a,b,c (3, default) | 78.6 | 63.3 | 81.4 | 64.7 | ||||
| res5 & res4b22,b21,b20 (6) | 74.8 | 75.1 |
Table 1: Results of using deformable convolution in the last , , , and convolutional layers (of filter) in ResNet-101 feature extraction network. For class-aware RPN, Faster R-CNN, and R-FCN, we report result on VOC 2007 test.
| 可变形卷积的用法(层数) | DeepLab | 类别感知 RPN | Faster R-CNN | R-FCN | ||||
|---|---|---|---|---|---|---|---|---|
| mIoU@V (%) | mIoU@C (%) | mAP@0.5 (%) | mAP@0.7 (%) | mAP@0.5 (%) | mAP@0.7 (%) | mAP@0.5 (%) | mAP@0.7 (%) | |
| 无(0,基线) | 69.7 | 70.4 | 78.1 | 62.1 | 80.0 | 61.8 | ||
| res5c(1) | 73.9 | 73.5 | 78.6 | 63.8 | 80.6 | 63.0 | ||
| res5b,c(2) | 74.8 | 74.4 | 78.5 | 63.3 | 81.0 | 63.8 | ||
| res5a,b,c(3,默认) | 78.6 | 63.3 | 81.4 | 64.7 | ||||
| res5 及 res4b22,b21,b20(6) | 74.8 | 75.1 |
表 1:在 ResNet-101 特征提取网络最后 、、 和 个卷积层( 滤波)中使用可变形卷积的结果。对类别感知 RPN、Faster R-CNN 和 R-FCN,我们报告 VOC 2007 测试集结果。
Deformable Part Models (DPM) [11] Deformable RoI pooling is similar to DPM because both methods learn the spatial deformation of object parts to maximize the classification score. Deformable RoI pooling is simpler since no spatial relations between the parts are considered.
可变形部件模型(DPM)[11] 可变形 RoI 池化与 DPM 相似,因为两种方法都学习物体部件的空间变形以最大化分类分数。可变形 RoI 池化更简单,因为它不考虑部件之间的空间关系。
DPM is a shallow model and has limited capability of modeling deformation. While its inference algorithm can be converted to CNNs [17] by treating the distance transform as a special pooling operation, its training is not end-to-end and involves heuristic choices such as selection of components and part sizes. In contrast, deformable ConvNets are deep and perform end-to-end training. When multiple deformable modules are stacked, the capability of modeling deformation becomes stronger.
DPM 是浅层模型,建模变形的能力有限。虽然其推断算法可以通过把距离变换看成一种特殊池化而转换成 CNN [17],但它的训练不是端到端的,并且涉及部件选择、部件大小等启发式选择。相比之下,可变形 ConvNets 是深层的,并且做端到端训练。当多个可变形模块堆叠时,建模变形的能力会更强。
DeepID-Net [44] It introduces a deformation constrained pooling layer which also considers part deformation for object detection. It therefore shares a similar spirit with deformable RoI pooling, but is much more complex. This work is highly engineered and based on RCNN [16]. It is unclear how to adapt it to the recent state-of-the-art object detection methods [47, 7] in an end-to-end manner.
DeepID-Net [44] 它引入了一种受变形约束的池化层,同样为了目标检测考虑部件变形。因此它与可变形 RoI 池化精神相近,但要复杂得多。这项工作工程性很强,建立在 RCNN [16] 之上。如何以端到端的方式把它接到后来最好的目标检测方法 [47, 7] 上,并不清楚。
Spatial manipulation in RoI pooling Spatial pyramid pooling [34] uses hand crafted pooling regions over scales. It is the predominant approach in computer vision and also used in deep learning based object detection [21, 15].
RoI 池化中的空间操作 空间金字塔池化 [34] 在不同尺度上使用手工设计的池化区域。它是计算机视觉中的主流做法,也被用于基于深度学习的目标检测 [21, 15]。
Learning the spatial layout of pooling regions has received little study. The work in [28] learns a sparse subset of pooling regions from a large over-complete set. The large set is hand engineered and the learning is not end-to-end.
学习池化区域的空间布局很少有人研究。[28] 从一个很大的过完备集合中学习稀疏的池化区域子集。这个大集合是手工设计的,学习也不是端到端的。
Deformable RoI pooling is the first to learn pooling regions end-to-end in CNNs. While the regions are of the same size currently, extension to multiple sizes as in spatial pyramid pooling [34] is straightforward.
可变形 RoI 池化是第一次在 CNN 中端到端学习池化区域。虽然目前这些区域大小相同,但像空间金字塔池化 [34] 那样扩展到多种大小是直接的。
Transformation invariant features and their learning There have been tremendous efforts on designing transformation invariant features. Notable examples include scale invariant feature transform (SIFT) [42] and ORB [49] (O for orientation). There is a large body of such works in the context of CNNs. The invariance and equivalence of CNN representations to image transformations are studied in [36]. Some works learn invariant CNN representations with respect to different types of transformations such as [50], scattering networks [3], convolutional jungles [32], and TI-pooling [33]. Some works are devoted for specific transformations such as symmetry [13, 9], scale [29], and rotation [53].
变换不变特征及其学习 设计变换不变特征的努力非常多。著名例子包括尺度不变特征变换(SIFT)[42] 和 ORB [49](O 代表方向)。在 CNN 的语境下也有大量这类工作。[36] 研究了 CNN 表示对图像变换的不变性与等价性。有些工作针对不同类型的变换学习不变的 CNN 表示,例如 [50]、散射网络 [3]、convolutional jungles [32] 以及 TI-pooling [33]。有些工作专门针对特定变换,如对称 [13, 9]、尺度 [29] 和旋转 [53]。
As analyzed in Section 1, in these works the transformations are known a priori. The knowledge (such as parameterization) is used to hand craft the structure of feature extraction algorithm, either fixed in such as SIFT, or with learnable parameters such as those based on CNNs. They cannot handle unknown transformations in the new tasks.
如第 1 节所分析,这些工作中的变换事先已知。这些知识(例如参数化方式)被用来手工设计特征提取算法的结构,或者像 SIFT 那样固定,或者像基于 CNN 的方法那样带有可学习参数。它们无法处理新任务中的未知变换。
In contrast, our deformable modules generalize various transformations (see Figure 1). The transformation invariance is learned from the target task.
相比之下,我们的可变形模块能够概括多种变换(见图 1)。变换不变性是从目标任务中学到的。
Dynamic Filter [2] Similar to deformable convolution, the dynamic filters are also conditioned on the input features and change over samples. Differently, only the filter weights are learned, not the sampling locations like ours. This work is applied for video and stereo prediction.
动态滤波器 [2] 与可变形卷积类似,动态滤波器也条件于输入特征,并随样本变化。不同的是,它只学习滤波器权重,而不像我们这样学习采样位置。这项工作被用于视频和立体预测。
Combination of low level filters Gaussian filters and its smooth derivatives [30] are widely used to extract low level image structures such as corners, edges, T-junctions, etc. Under certain conditions, such filters form a set of basis and their linear combination forms new filters within the same group of geometric transformations, such as multiple orientations in Steerable Filters [12] and multiple scales in [45]. We note that although the term deformable kernels is used in [45], its meaning is different from ours in this work.
低层滤波器的组合 高斯滤波器及其平滑导数 [30] 被广泛用于提取角点、边缘、T 形连接等低层图像结构。在一定条件下,这些滤波器构成一组基,它们的线性组合会形成同一类几何变换下的新滤波器,例如 Steerable Filters [12] 中的多个方向,以及 [45] 中的多个尺度。我们注意到,尽管 [45] 使用了 deformable kernels 这一术语,其含义与本文不同。
Most CNNs learn all their convolution filters from scratch. The recent work [25] shows that it could be unnecessary. It replaces the free form filters by weighted combination of low level filters (Gaussian derivatives up to 4-th order) and learns the weight coefficients. The regularization over the filter function space is shown to improve the generalization ability when training data are small.
大多数 CNN 从零开始学习全部卷积滤波器。近期工作 [25] 表明这未必必要。它用低层滤波器(直到 4 阶的高斯导数)的加权组合替换自由形式滤波器,并学习权重系数。在训练数据较小时,对滤波器函数空间的正则被证明能提高泛化能力。
Above works are related to ours in that, when multiple filters, especially with different scales, are combined, the resulting filter could have complex weights and resemble our deformable convolution filter. However, deformable convolution learns sampling locations instead of filter weights.
上述工作与我们相关之处在于:当多个滤波器、尤其是不同尺度的滤波器组合起来时,得到的滤波器可能具有复杂权重,并类似于我们的可变形卷积滤波器。不过,可变形卷积学习的是采样位置,而不是滤波器权重。
| layer | small | medium | large | background |
|---|---|---|---|---|
| mean std | ||||
| res5c | 5.3 3.3 | 5.8 3.5 | 8.4 4.5 | 6.2 3.0 |
| res5b | 2.5 1.3 | 3.1 1.5 | 5.1 2.5 | 3.2 1.2 |
| res5a | 2.2 1.2 | 2.9 1.3 | 4.2 1.6 | 3.1 1.1 |
Table 2: Statistics of effective dilation values of deformable convolutional filters on three layers and four categories. Similar as in COCO [39], we divide the objects into three categories equally according to the bounding box area. Small: area pixels; medium: area ; large: area pixels.
| 层 | 小 | 中 | 大 | 背景 |
|---|---|---|---|---|
| 均值 标准差 | ||||
| res5c | 5.3 3.3 | 5.8 3.5 | 8.4 4.5 | 6.2 3.0 |
| res5b | 2.5 1.3 | 3.1 1.5 | 5.1 2.5 | 3.2 1.2 |
| res5a | 2.2 1.2 | 2.9 1.3 | 4.2 1.6 | 3.1 1.1 |
表 2:三个层、四个类别上可变形卷积滤波器有效膨胀值的统计。与 COCO [39] 类似,我们按边界框面积把物体均分成三类。小:面积 像素;中: 面积 ;大:面积 像素。
| deformation modules | DeepLab mIoU@V / @C | DeepLab | mIoU@V / @C | class-aware RPN mAP@0.5 / @0.7 | class-aware RPN | mAP@0.5 / @0.7 | Faster R-CNN mAP@0.5 / @0.7 | Faster R-CNN | mAP@0.5 / @0.7 | R-FCN mAP@0.5 / @0.7 | R-FCN | mAP@0.5 / @0.7 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| DeepLab | ||||||||||||
| mIoU@V / @C | ||||||||||||
| class-aware RPN | ||||||||||||
| mAP@0.5 / @0.7 | ||||||||||||
| Faster R-CNN | ||||||||||||
| mAP@0.5 / @0.7 | ||||||||||||
| R-FCN | ||||||||||||
| mAP@0.5 / @0.7 | ||||||||||||
| atrous convolution (2,2,2) (default) | 69.7 / 70.4 | 68.0 / 44.9 | 78.1 / 62.1 | 80.0 / 61.8 | ||||||||
| atrous convolution (4,4,4) | 73.1 / 71.9 | 72.8 / 53.1 | 78.6 / 63.1 | 80.5 / 63.0 | ||||||||
| atrous convolution (6,6,6) | 73.6 / 72.7 | 73.6 / 55.2 | 78.5 / 62.3 | 80.2 / 63.5 | ||||||||
| atrous convolution (8,8,8) | 73.2 / 72.4 | 73.2 / 55.1 | 77.8 / 61.8 | 80.3 / 63.2 | ||||||||
| deformable convolution | / | / | 78.6 / 63.3 | 81.4 / 64.7 | ||||||||
| deformable RoI pooling | N.A | N.A | 78.3 / 66.6 | 81.2 / 65.0 | ||||||||
| deformable convolution & RoI pooling | N.A | N.A | / | / |
| DeepLab |
|---|
| mIoU@V / @C |
| class-aware RPN |
|---|
| mAP@0.5 / @0.7 |
| Faster R-CNN |
|---|
| mAP@0.5 / @0.7 |
| R-FCN |
|---|
| mAP@0.5 / @0.7 |
Table 3: Evaluation of our deformable modules and atrous convolution, using ResNet-101.
| 变形模块 | DeepLab mIoU@V / @C | 类别感知 RPN mAP@0.5 / @0.7 | Faster R-CNN mAP@0.5 / @0.7 | R-FCN mAP@0.5 / @0.7 |
|---|---|---|---|---|
| 空洞卷积 (2,2,2)(默认) | 69.7 / 70.4 | 68.0 / 44.9 | 78.1 / 62.1 | 80.0 / 61.8 |
| 空洞卷积 (4,4,4) | 73.1 / 71.9 | 72.8 / 53.1 | 78.6 / 63.1 | 80.5 / 63.0 |
| 空洞卷积 (6,6,6) | 73.6 / 72.7 | 73.6 / 55.2 | 78.5 / 62.3 | 80.2 / 63.5 |
| 空洞卷积 (8,8,8) | 73.2 / 72.4 | 73.2 / 55.1 | 77.8 / 61.8 | 80.3 / 63.2 |
| 可变形卷积 | / | / | 78.6 / 63.3 | 81.4 / 64.7 |
| 可变形 RoI 池化 | 不适用 | 不适用 | 78.3 / 66.6 | 81.2 / 65.0 |
| 可变形卷积及 RoI 池化 | 不适用 | 不适用 | / | / |
表 3:对我们的可变形模块与空洞卷积的评估,骨干为 ResNet-101。
| method | # params | net. forward (sec) | runtime (sec) |
|---|---|---|---|
| DeepLab@C | M | 0.610 | 0.650 |
| Ours | M | 0.656 | 0.696 |
| DeepLab@V | M | 0.084 | 0.094 |
| Ours | M | 0.088 | 0.098 |
| class-aware RPN | M | 0.142 | 0.323 |
| Ours | M | 0.152 | 0.334 |
| Faster R-CNN | M | 0.147 | 0.190 |
| Ours | M | 0.192 | 0.234 |
| R-FCN | M | 0.143 | 0.170 |
| Ours | M | 0.169 | 0.193 |
Table 4: Model complexity and runtime comparison of deformable ConvNets and the plain counterparts, using ResNet-101. The overall runtime in the last column includes image resizing, network forward, and post-processing (e.g., NMS for object detection). Runtime is counted on a workstation with Intel E5-2650 v2 CPU and Nvidia K40 GPU.
| 方法 | 参数量 | 网络前向(秒) | 运行时间(秒) |
|---|---|---|---|
| DeepLab@C | M | 0.610 | 0.650 |
| 本文 | M | 0.656 | 0.696 |
| DeepLab@V | M | 0.084 | 0.094 |
| 本文 | M | 0.088 | 0.098 |
| 类别感知 RPN | M | 0.142 | 0.323 |
| 本文 | M | 0.152 | 0.334 |
| Faster R-CNN | M | 0.147 | 0.190 |
| 本文 | M | 0.192 | 0.234 |
| R-FCN | M | 0.143 | 0.170 |
| 本文 | M | 0.169 | 0.193 |
表 4:可变形 ConvNets 与普通对应模型的复杂度与运行时间比较,骨干为 ResNet-101。最后一列的总体运行时间包括图像缩放、网络前向和后处理(例如目标检测中的 NMS)。运行时间在配备 Intel E5-2650 v2 CPU 和 Nvidia K40 GPU 的工作站上统计。
| method | backbone architecture | backbone | architecture | M | B | mAP@[0.5:0.95] | mAPr@0.5 | mAP@[0.5:0.95] (small) | mAP@[0.5:0.95] (mid) | mAP@[0.5:0.95] (large) |
|---|---|---|---|---|---|---|---|---|---|---|
| backbone | ||||||||||
| architecture | ||||||||||
| class-aware RPN | ResNet-101 | 23.2 | 42.6 | 6.9 | 27.1 | 35.1 | ||||
| Ours | ||||||||||
| Faster RCNN | ResNet-101 | 29.4 | 48.0 | 9.0 | 30.5 | 47.1 | ||||
| Ours | ||||||||||
| R-FCN | ResNet-101 | 30.8 | 52.6 | 11.8 | 33.9 | 44.8 | ||||
| Ours | ||||||||||
| Faster RCNN | Aligned-Inception-ResNet | 30.8 | 49.6 | 9.6 | 32.5 | 49.0 | ||||
| Ours | ||||||||||
| R-FCN | Aligned-Inception-ResNet | 32.9 | 54.5 | 12.5 | 36.3 | 48.3 | ||||
| Ours | ||||||||||
| R-FCN | ✓ | 34.5 | 55.0 | 16.8 | 37.3 | 48.3 | ||||
| Ours | Aligned-Inception-ResNet | ✓ | 37.1 | 57.3 | 18.8 | 39.7 | 52.3 | |||
| R-FCN | ✓ | ✓ | 35.5 | 55.6 | 17.8 | 38.4 | 49.3 | |||
| Ours | ✓ | ✓ |
| backbone |
|---|
| architecture |
Table 5: Object detection results of deformable ConvNets v.s. plain ConvNets on COCO test-dev set. M denotes multi-scale testing, and B denotes iterative bounding box average in the table.
| 方法 | 骨干结构 | M | B | mAP@[0.5:0.95] | mAP@0.5 | mAP@[0.5:0.95](小) | mAP@[0.5:0.95](中) | mAP@[0.5:0.95](大) |
|---|---|---|---|---|---|---|---|---|
| 类别感知 RPN | ResNet-101 | 23.2 | 42.6 | 6.9 | 27.1 | 35.1 | ||
| 本文 | ||||||||
| Faster RCNN | ResNet-101 | 29.4 | 48.0 | 9.0 | 30.5 | 47.1 | ||
| 本文 | ||||||||
| R-FCN | ResNet-101 | 30.8 | 52.6 | 11.8 | 33.9 | 44.8 | ||
| 本文 | ||||||||
| Faster RCNN | Aligned-Inception-ResNet | 30.8 | 49.6 | 9.6 | 32.5 | 49.0 | ||
| 本文 | ||||||||
| R-FCN | Aligned-Inception-ResNet | 32.9 | 54.5 | 12.5 | 36.3 | 48.3 | ||
| 本文 | ||||||||
| R-FCN | ✓ | 34.5 | 55.0 | 16.8 | 37.3 | 48.3 | ||
| 本文 | Aligned-Inception-ResNet | ✓ | 37.1 | 57.3 | 18.8 | 39.7 | 52.3 | |
| R-FCN | ✓ | ✓ | 35.5 | 55.6 | 17.8 | 38.4 | 49.3 | |
| 本文 | ✓ | ✓ |
表 5:可变形 ConvNets 与普通 ConvNets 在 COCO test-dev 上的目标检测结果。表中 M 表示多尺度测试,B 表示迭代边界框平均。
4 Experiments
4 实验
4.1 Experiment Setup and Implementation
4.1 实验设置与实现
Semantic Segmentation We use PASCAL VOC [10] and CityScapes [6]. For PASCAL VOC, there are semantic categories. Following the protocols in [19, 41, 4], we use VOC 2012 dataset and the additional mask annotations in [18]. The training set includes images. Evaluation is performed on images in the validation set. For CityScapes, following the protocols in [5], training and evaluation are performed on images in the train set and images in the validation set, respectively. There are semantic categories plus a background category.
语义分割 我们使用 PASCAL VOC [10] 和 CityScapes [6]。PASCAL VOC 有 个语义类别。按 [19, 41, 4] 的协议,我们使用 VOC 2012 数据集以及 [18] 中的额外掩码标注。训练集包括 张图像,评估在验证集的 张图像上进行。CityScapes 按 [5] 的协议,分别在训练集的 张图像和验证集的 张图像上训练和评估。共有 个语义类别外加一个背景类。
For evaluation, we use the mean intersection-over-union (mIoU) metric defined over image pixels, following the standard protocols [10, 6]. We use mIoU@V and mIoU@C for PASCAl VOC and Cityscapes, respectively.
评估使用定义在图像像素上的平均交并比(mIoU),遵循标准协议 [10, 6]。我们分别用 mIoU@V 和 mIoU@C 表示 PASCAL VOC 和 Cityscapes 上的结果。
In training and inference, the images are resized to have a shorter side of pixels for PASCAL VOC and pixels for Cityscapes. In SGD training, one image is randomly sampled in each mini-batch. A total of 30k and 45k iterations are performed for PASCAL VOC and Cityscapes, respectively, with 8 GPUs and one mini-batch on each. The learning rates are and in the first and the last iterations, respectively.
训练和推断时,图像被缩放到短边为 像素(PASCAL VOC)或 像素(Cityscapes)。SGD 训练中,每个小批次随机采样一张图像。PASCAL VOC 和 Cityscapes 分别进行 30k 和 45k 次迭代,使用 8 块 GPU,每块上一个小批次。学习率在前 次迭代为 ,在后 次迭代为 。
Object Detection We use PASCAL VOC and COCO [39] datasets. For PASCAL VOC, following the protocol in [15], training is performed on the union of VOC 2007 trainval and VOC 2012 trainval. Evaluation is on VOC 2007 test. For COCO, following the standard protocol [39], training and evaluation are performed on the 120k images in the trainval and the 20k images in the test-dev, respectively.
目标检测 我们使用 PASCAL VOC 和 COCO [39] 数据集。PASCAL VOC 按 [15] 的协议,在 VOC 2007 trainval 与 VOC 2012 trainval 的并集上训练,在 VOC 2007 test 上评估。COCO 按标准协议 [39],分别在 trainval 的 12 万张图像和 test-dev 的 2 万张图像上训练和评估。
For evaluation, we use the standard mean average precision (mAP) scores [10, 39]. For PASCAL VOC, we report mAP scores using IoU thresholds at 0.5 and 0.7. For COCO, we use the standard COCO metric of mAP@[0.5:0.95], as well as mAP@0.5.
评估使用标准的平均精度均值(mAP)分数 [10, 39]。对 PASCAL VOC,我们报告 IoU 阈值为 0.5 和 0.7 时的 mAP。对 COCO,我们使用标准的 COCO 指标 mAP@[0.5:0.95],以及 mAP@0.5。
In training and inference, the images are resized to have a shorter side of 600 pixels. In SGD training, one image is randomly sampled in each mini-batch. For class-aware RPN, 256 RoIs are sampled from the image. For Faster R-CNN and R-FCN, 256 and 128 RoIs are sampled for the region proposal and the object detection networks, respectively. bins are adopted in RoI pooling. To facilitate the ablation experiments on VOC, we follow [38] and utilize pre-trained and fixed RPN proposals for the training of Faster R-CNN and R-FCN, without feature sharing between the region proposal and the object detection networks. The RPN network is trained separately as in the first stage of the procedure in [47]. For COCO, joint training as in [48] is performed and feature sharing is enabled for training. A total of 30k and 240k iterations are performed for PASCAL VOC and COCO, respectively, on 8 GPUs. The learning rates are set as and in the first and the last iterations, respectively.
训练和推断时,图像被缩放到短边为 600 像素。SGD 训练中,每个小批次随机采样一张图像。对类别感知 RPN,从图像中采样 256 个 RoI。对 Faster R-CNN 和 R-FCN,区域提议网络和目标检测网络分别采样 256 和 128 个 RoI。RoI 池化采用 格子。为方便在 VOC 上做消融,我们按 [38] 使用预先训练并固定的 RPN 提议来训练 Faster R-CNN 和 R-FCN,区域提议网络与目标检测网络之间不共享特征。RPN 网络按 [47] 流程的第一阶段单独训练。对 COCO,按 [48] 做联合训练,并在训练时共享特征。PASCAL VOC 和 COCO 分别在 8 块 GPU 上进行 30k 和 240k 次迭代。学习率在前 次迭代设为 ,在后 次迭代设为 。
4.2 Ablation Study
4.2 消融实验
Extensive ablation studies are performed to validate the efficacy and efficiency of our approach.
我们做了大量消融实验,以验证本方法的有效性和效率。
Deformable Convolution Table 1 evaluates the effect of deformable convolution using ResNet-101 feature extraction network. Accuracy steadily improves when more deformable convolution layers are used, especially for DeepLab and class-aware RPN. The improvement saturates when using deformable layers for DeepLab, and for others. In the remaining experiments, we use in the feature extraction networks.
可变形卷积 表 1 评估了在 ResNet-101 特征提取网络中使用可变形卷积的效果。使用更多可变形卷积层时,准确率稳步提高,对 DeepLab 和类别感知 RPN 尤其明显。DeepLab 使用 个可变形层时提升趋于饱和,其他方法则是 个。在后续实验中,特征提取网络使用 个可变形层。
We empirically observed that the learned offsets in the deformable convolution layers are highly adaptive to the image content, as illustrated in Figure 5 and Figure 6. To better understand the mechanism of deformable convolution, we define a metric called effective dilation for a deformable convolution filter. It is the mean of the distances between all adjacent pairs of sampling locations in the filter. It is a rough measure of the receptive field size of the filter.
我们从经验上观察到,可变形卷积层学到的偏移对图像内容高度自适应,如图 5 和图 6 所示。为更好地理解可变形卷积的机制,我们为可变形卷积滤波器定义了一个称为有效膨胀的度量。它是滤波器中所有相邻采样位置对之间距离的均值,大致衡量该滤波器的感受野大小。
We apply the R-FCN network with deformable layers (as in Table 1) on VOC 2007 test images. We categorize the deformable convolution filters into four classes: small, medium, large, and background, according to the ground truth bounding box annotation and where the filter center is. Table 2 reports the statistics (mean and std) of the effective dilation values. It clearly shows that: 1) the receptive field sizes of deformable filters are correlated with object sizes, indicating that the deformation is effectively learned from image content; 2) the filter sizes on the background region are between those on medium and large objects, indicating that a relatively large receptive field is necessary for recognizing the background regions. These observations are consistent in different layers.
我们把带有 个可变形层的 R-FCN 网络(如表 1)用在 VOC 2007 测试图像上。根据真实边界框标注以及滤波器中心所在位置,我们把可变形卷积滤波器分成四类:小、中、大和背景。表 2 报告了有效膨胀值的统计(均值和标准差)。它清楚地表明:1)可变形滤波器的感受野大小与物体大小相关,说明变形是从图像内容中有效学到的;2)背景区域上的滤波器大小介于中等物体和大物体之间,说明识别背景区域需要相对较大的感受野。这些观察在不同层上是一致的。
The default ResNet-101 model uses atrous convolution with dilation for the last three convolutional layers (see Section 2.3). We further tried dilation values , , and and reported the results in Table 3. It shows that: 1) accuracy increases for all tasks when using larger dilation values, indicating that the default networks have too small receptive fields; 2) the optimal dilation values vary for different tasks, e.g., for DeepLab but for Faster R-CNN; 3) deformable convolution has the best accuracy. These observations verify that adaptive learning of filter deformation is effective and necessary.
默认的 ResNet-101 模型在最后三层 卷积上使用膨胀为 的空洞卷积(见第 2.3 节)。我们进一步尝试了膨胀值 、 和 ,结果见表 3。结果表明:1)使用更大的膨胀值时,所有任务的准确率都提高,说明默认网络的感受野过小;2)最优膨胀值因任务而异,例如 DeepLab 为 ,Faster R-CNN 为 ;3)可变形卷积的准确率最好。这些观察验证了自适应学习滤波器变形既有效,也有必要。
Deformable RoI Pooling It is applicable to Faster R-CNN and R-FCN. As shown in Table 3, using it alone already produces noticeable performance gains, especially at the strict mAP@0.7 metric. When both deformable convolution and RoI Pooling are used, significant accuracy improvements are obtained.
可变形 RoI 池化 它适用于 Faster R-CNN 和 R-FCN。如表 3 所示,单独使用它就已经带来明显的性能提升,在更严格的 mAP@0.7 指标上尤其如此。当可变形卷积和 RoI 池化一起使用时,准确率有显著提高。
Model Complexity and Runtime Table 4 reports the model complexity and runtime of the proposed deformable ConvNets and their plain versions. Deformable ConvNets only add small overhead over model parameters and computation. This indicates that the significant performance improvement is from the capability of modeling geometric transformations, other than increasing model parameters.
模型复杂度与运行时间 表 4 报告了所提出的可变形 ConvNets 与其普通版本的模型复杂度和运行时间。可变形 ConvNets 只在模型参数和计算上增加很小的开销。这说明显著的性能提升来自建模几何变换的能力,而不是增加模型参数。
4.3 Object Detection on COCO
4.3 在 COCO 上的目标检测
In Table 5, we perform extensive comparison between the deformable ConvNets and the plain ConvNets for object detection on COCO test-dev set. We first experiment using ResNet-101 model. The deformable versions of class-aware RPN, Faster R-CNN and R-FCN achieve mAP@[0.5:0.95] scores of 25.8%, 33.1%, and 34.5% respectively, which are 11%, 13%, and 12% relatively higher than their plain-ConvNets counterparts respectively. By replacing ResNet-101 by Aligned-Inception-ResNet in Faster R-CNN and R-FCN, their plain-ConvNet baselines both improve thanks to the more powerful feature representations. And the effective performance gains brought by deformable ConvNets also hold. By further testing on multiple image scales (the image shorter side is in [480, 576, 688, 864, 1200, 1400]) and performing iterative bounding box average [14], the mAP@[0.5:0.95] scores are increased to 37.5% for the deformable version of R-FCN. Note that the performance gain of deformable ConvNets is complementary to these bells and whistles.
在表 5 中,我们在 COCO test-dev 上对可变形 ConvNets 与普通 ConvNets 做了广泛比较。我们首先用 ResNet-101 模型实验。类别感知 RPN、Faster R-CNN 和 R-FCN 的可变形版本分别达到 25.8%、33.1% 和 34.5% 的 mAP@[0.5:0.95],相对各自的普通 ConvNet 对应模型分别高出 11%、13% 和 12%。在 Faster R-CNN 和 R-FCN 中把 ResNet-101 换成 Aligned-Inception-ResNet 后,普通 ConvNet 基线都因更强的特征表示而提高,可变形 ConvNets 带来的有效增益仍然成立。再在多个图像尺度上测试(图像短边取 [480, 576, 688, 864, 1200, 1400])并做迭代边界框平均 [14],可变形版本 R-FCN 的 mAP@[0.5:0.95] 提高到 37.5%。注意,可变形 ConvNets 的增益与这些附加技巧是互补的。
5 Conclusion
5 结论
This paper presents deformable ConvNets, which is a simple, efficient, deep, and end-to-end solution to model dense spatial transformations. For the first time, we show that it is feasible and effective to learn dense spatial transformation in CNNs for sophisticated vision tasks, such as object detection and semantic segmentation.
本文提出可变形 ConvNets,这是一种简单、高效、深层且端到端的方案,用来对稠密空间变换建模。我们首次表明,在 CNN 中为复杂视觉任务学习稠密空间变换是可行且有效的,例如目标检测和语义分割。
Acknowledgements
The Aligned-Inception-ResNet model was trained and investigated by Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun in unpublished work.
致谢
Aligned-Inception-ResNet 模型由 Kaiming He、Xiangyu Zhang、Shaoqing Ren 和 Jian Sun 在未发表的工作中训练并研究。
Appendix A Deformable Convolution/RoI Pooling Back-propagation
附录 A 可变形卷积 / RoI 池化的反向传播
In the deformable convolution Eq. (2), the gradient w.r.t. the offset is computed as
在可变形卷积公式 (2) 中,相对于偏移 的梯度计算为
$$\begin{split}\frac{\partial\mathbf{y}(\mathbf{p}{0})}{\partial\Delta\mathbf{p}{n}}&=\sum_{\mathbf{p}{n}\in\mathcal{R}}\mathbf{w}(\mathbf{p}{n})\cdot\frac{\partial\mathbf{x}(\mathbf{p}{0}+\mathbf{p}{n}+\Delta\mathbf{p}{n})}{\partial\Delta\mathbf{p}{n}}\
=\sum_{\mathbf{p}{n}\in\mathcal{R}}&\left[\mathbf{w}(\mathbf{p}{n})\cdot\sum_{\mathbf{q}}\frac{\partial G(\mathbf{q},\mathbf{p}{0}+\mathbf{p}{n}+\Delta\mathbf{p}{n})}{\partial\Delta\mathbf{p}{n}}\mathbf{x}(\mathbf{q})\right],\
\end{split} \tag{7}$$
where the term can be derived from Eq. (4). Note that the offset is 2D and we use to denote and for simplicity.
其中 可由公式 (4) 导出。注意偏移 是二维的,为简洁起见我们用 表示 和 。
Similarly, in the deformable RoI Pooling module, the gradient w.r.t. the offset can be computed by
类似地,在可变形 RoI 池化模块中,相对于偏移 的梯度可计算为
$$\begin{split}\frac{\partial\mathbf{y}(i,j)}{\partial\Delta\mathbf{p}{ij}}&=\frac{1}{n{ij}}\sum_{\mathbf{p}\in bin(i,j)}\frac{\partial\mathbf{x}(\mathbf{p}{0}+\mathbf{p}+\Delta\mathbf{p}{ij})}{\partial\Delta\mathbf{p}{ij}}\
=\frac{1}{n{ij}}&\sum_{\mathbf{p}\in bin(i,j)}\left[\sum_{\mathbf{q}}\frac{\partial G(\mathbf{q},\mathbf{p}{0}+\mathbf{p}+\Delta\mathbf{p}{ij})}{\partial\Delta\mathbf{p}_{ij}}\mathbf{x}(\mathbf{q})\right].\
\end{split} \tag{8}$$
And the gradient w.r.t. the normalized offsets can be easily obtained via computing derivatives in .
相对于归一化偏移 的梯度,可以通过对 求导直接得到。
Appendix B Details of Aligned-Inception-ResNet
附录 B Aligned-Inception-ResNet 的细节
| stage | spatial dim. | Aligned-Inception-ResNet | |
|---|---|---|---|
| conv1 | 112112 | 77, 64, stride 2 | |
| conv2 | 5656 | 33 max pool, stride 2 | |
| \left[\begin{array}[]{c}\text{256-d}\\[-1.00006pt] \text{IRB}\\ \end{array}\right]3 | \left[\begin{array}[]{c}\text{256-d}\\[-1.00006pt] \text{IRB}\\ \end{array}\right]3 | ||
| \left[\begin{array}[]{c}\text{256-d}\\[-1.00006pt] \text{IRB}\\ \end{array}\right]3 | |||
| conv3 | 2828 | \left[\begin{array}[]{c}\text{512-d}\\[-1.00006pt] \text{IRB}\\ \end{array}\right]4 | \left[\begin{array}[]{c}\text{512-d}\\[-1.00006pt] \text{IRB}\\ \end{array}\right]4 |
| \left[\begin{array}[]{c}\text{512-d}\\[-1.00006pt] \text{IRB}\\ \end{array}\right]4 | |||
| conv4 | 1414 | \left[\begin{array}[]{c}\text{1024-d}\\[-1.00006pt] \text{IRB}\\ \end{array}\right]23 | \left[\begin{array}[]{c}\text{1024-d}\\[-1.00006pt] \text{IRB}\\ \end{array}\right]23 |
| \left[\begin{array}[]{c}\text{1024-d}\\[-1.00006pt] \text{IRB}\\ \end{array}\right]23 | |||
| conv5 | 77 | \left[\begin{array}[]{c}\text{2048-d}\\[-1.00006pt] \text{IRB}\\ \end{array}\right]3 | \left[\begin{array}[]{c}\text{2048-d}\\[-1.00006pt] \text{IRB}\\ \end{array}\right]3 |
| \left[\begin{array}[]{c}\text{2048-d}\\[-1.00006pt] \text{IRB}\\ \end{array}\right]3 | |||
| classifier | 11 | global average pool, | |
| 1000-d fc, softmax |
| \left[\begin{array}[]{c}\text{256-d}\\[-1.00006pt] \text{IRB}\\ \end{array}\right]3 |
|---|
| \left[\begin{array}[]{c}\text{512-d}\\[-1.00006pt] \text{IRB}\\ \end{array}\right]4 |
|---|
| \left[\begin{array}[]{c}\text{1024-d}\\[-1.00006pt] \text{IRB}\\ \end{array}\right]23 |
|---|
| \left[\begin{array}[]{c}\text{2048-d}\\[-1.00006pt] \text{IRB}\\ \end{array}\right]3 |
|---|
Table 6: Network architecture of Aligned-Inception-ResNet. The Inception Residual Block (IRB) is detailed in Figure 8.
| 阶段 | 空间尺寸 | Aligned-Inception-ResNet | |
|---|---|---|---|
| conv1 | 112112 | 77,64,步幅 2 | |
| conv2 | 5656 | 33 最大池化,步幅 2 | |
| 256 维 IRB 3 | |||
| conv3 | 2828 | 512 维 IRB 4 | |
| conv4 | 1414 | 1024 维 IRB 23 | |
| conv5 | 77 | 2048 维 IRB 3 | |
| 分类器 | 11 | 全局平均池化,1000 维全连接,softmax |
表 6:Aligned-Inception-ResNet 的网络结构。Inception 残差块(IRB)详见图 8。
| Network | # params | top-1 err (%) | top-5 err (%) |
|---|---|---|---|
| ResNet-101 | M | 23.6 | 7.1 |
| Inception-ResNet-v2 | M | 19.6 | 4.7 |
| Aligned-Inception-ResNet | M | 22.1 | 6.0 |
Table 7: Comparison of Aligned-Inception-ResNet with ResNet-101 and Inception-ResNet-v2 on ImageNet-1K validation.
| 网络 | 参数量 | top-1 错误率 (%) | top-5 错误率 (%) |
|---|---|---|---|
| ResNet-101 | M | 23.6 | 7.1 |
| Inception-ResNet-v2 | M | 19.6 | 4.7 |
| Aligned-Inception-ResNet | M | 22.1 | 6.0 |
表 7:Aligned-Inception-ResNet 与 ResNet-101、Inception-ResNet-v2 在 ImageNet-1K 验证集上的比较。
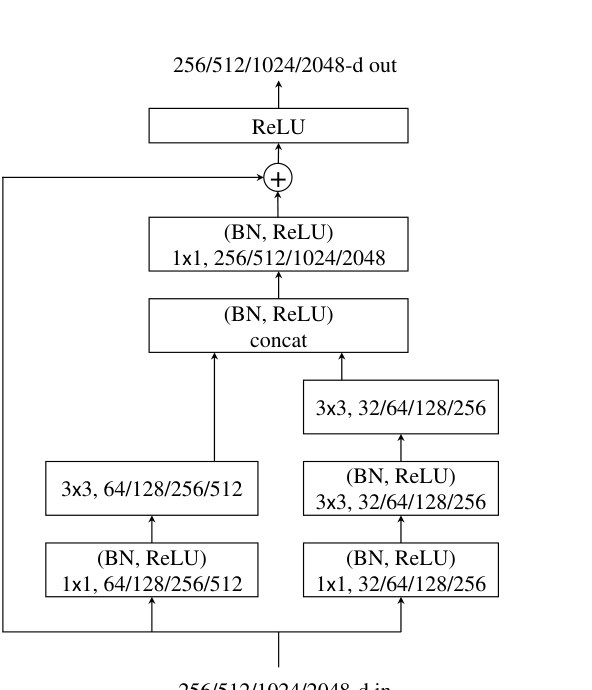
Figure 8: The Inception Residual Block (IRB) for different stages of Aligned-Inception-ResNet, where the dimensions of different stages are separated by slash (conv2/conv3/conv4/conv5).
图 8:Aligned-Inception-ResNet 不同阶段的 Inception 残差块(IRB),不同阶段的维度用斜杠分隔(conv2/conv3/conv4/conv5)。
In the original Inception-ResNet [51] architecture, multiple layers of valid convolution/pooling are utilized, which brings feature alignment issues for dense prediction tasks. For a cell on the feature maps close to the output, its projected spatial location on the image is not aligned with the location of its receptive field center. Meanwhile, the task specific networks are usually designed under the alignment assumption. For example, in the prevalent FCNs for semantic segmentation, the features from a cell are leveraged to predict the pixel’s label at the corresponding projected image location.
在原始 Inception-ResNet [51] 结构中,使用了多层 valid 卷积/池化,这会给稠密预测任务带来特征对齐问题。对靠近输出的特征图上的一个单元,它在图像上的投影空间位置与其感受野中心的位置并不对齐。与此同时,任务特定网络通常是在对齐假定下设计的。例如,在流行的语义分割全卷积网络中,一个单元的特征被用来预测相应投影图像位置上像素的标签。
To remedy this issue, the network architecture is modified [20], called “Aligned-Inception-ResNet” and shown in Table 6. When the feature dimension changes, a convolution layer with stride 2 is utilized. There are two main differences between Aligned-Inception-ResNet and the original Inception-ResNet [51]. Firstly, Aligned-Inception-ResNet does not have the feature alignment problem, by proper padding in convolutional and pooling layers. Secondly, Aligned-Inception-ResNet consists of repetitive modules, whose design is simpler than the original Inception-ResNet architectures.
为了补救这一问题,网络结构按 [20] 做了修改,称为“Aligned-Inception-ResNet”,见表 6。当特征维度变化时,使用步幅为 2 的 卷积层。Aligned-Inception-ResNet 与原始 Inception-ResNet [51] 有两个主要不同。第一,通过对卷积层和池化层做恰当填充,Aligned-Inception-ResNet 没有特征对齐问题。第二,Aligned-Inception-ResNet 由重复模块组成,设计比原始 Inception-ResNet 结构更简单。
The Aligned-Inception-ResNet model is pre-trained on ImageNet-1K classification [8]. The training procedure follows [22]. Table 7 reports the model complexity, top-1 and top-5 classification errors.
Aligned-Inception-ResNet 模型在 ImageNet-1K 分类 [8] 上预训练。训练流程遵循 [22]。表 7 报告了模型复杂度以及 top-1 和 top-5 分类错误率。
References
参考文献
[1] Y.-L. Boureau, J. Ponce, and Y. LeCun. A theoretical analysis of feature pooling in visual recognition. In ICML , 2010.
[2] B. D. Brabandere, X. Jia, T. Tuytelaars, and L. V. Gool. Dynamic filter networks. In NIPS , 2016.
[3] J. Bruna and S. Mallat. Invariant scattering convolution networks. TPAMI , 2013.
[4] L.-C. Chen, G. Papandreou, I. Kokkinos, K. Murphy, and A. L. Yuille. Semantic image segmentation with deep convolutional nets and fully connected crfs. In ICLR , 2015.
[5] L.-C. Chen, G. Papandreou, I. Kokkinos, K. Murphy, and A. L. Yuille. Deeplab: Semantic image segmentation with deep convolutional nets, atrous convolution, and fully connected crfs. arXiv preprint arXiv:1606.00915 , 2016.
[6] M. Cordts, M. Omran, S. Ramos, T. Rehfeld, M. Enzweiler, R. Benenson, U. Franke, S. Roth, and B. Schiele. The cityscapes dataset for semantic urban scene understanding. In CVPR , 2016.
[7] J. Dai, Y. Li, K. He, and J. Sun. R-fcn: Object detection via region-based fully convolutional networks. In NIPS , 2016.
[8] J. Deng, W. Dong, R. Socher, L.-J. Li, K. Li, and L. Fei-Fei. Imagenet: A large-scale hierarchical image database. In CVPR , 2009.
[9] S. Dieleman, J. D. Fauw, and K. Kavukcuoglu. Exploiting cyclic symmetry in convolutional neural networks. arXiv preprint arXiv:1602.02660 , 2016.
[10] M. Everingham, L. Van Gool, C. K. Williams, J. Winn, and A. Zisserman. The PASCAL Visual Object Classes (VOC) Challenge. IJCV , 2010.
[11] P. F. Felzenszwalb, R. B. Girshick, D. McAllester, and D. Ramanan. Object detection with discriminatively trained part-based models. TPAMI , 2010.
[12] W. T. Freeman and E. H. Adelson. The design and use of steerable filters. TPAMI , 1991.
[13] R. Gens and P. M. Domingos. Deep symmetry networks. In NIPS , 2014.
[14] S. Gidaris and N. Komodakis. Object detection via a multi-region & semantic segmentation-aware cnn model. In ICCV , 2015.
[15] R. Girshick. Fast R-CNN. In ICCV , 2015.
[16] R. Girshick, J. Donahue, T. Darrell, and J. Malik. Rich feature hierarchies for accurate object detection and semantic segmentation. In CVPR , 2014.
[17] R. Girshick, F. Iandola, T. Darrell, and J. Malik. Deformable part models are convolutional neural networks. arXiv preprint arXiv:1409.5403 , 2014.
[18] B. Hariharan, P. Arbeláez, L. Bourdev, S. Maji, and J. Malik. Semantic contours from inverse detectors. In ICCV , 2011.
[19] B. Hariharan, P. Arbeláez, R. Girshick, and J. Malik. Simultaneous detection and segmentation. In ECCV . 2014.
[20] K. He, X. Zhang, S. Ren, and J. Sun. Aligned-inception-resnet model, unpublished work.
[21] K. He, X. Zhang, S. Ren, and J. Sun. Spatial pyramid pooling in deep convolutional networks for visual recognition. In ECCV , 2014.
[22] K. He, X. Zhang, S. Ren, and J. Sun. Deep residual learning for image recognition. In CVPR , 2016.
[23] M. Holschneider, R. Kronland-Martinet, J. Morlet, and P. Tchamitchian. A real-time algorithm for signal analysis with the help of the wavelet transform. Wavelets: Time-Frequency Methods and Phase Space , page 289–297, 1989.
[24] J. Huang, V. Rathod, C. Sun, M. Zhu, A. Korattikara, A. Fathi, I. Fischer, Z. Wojna, Y. Song, S. Guadarrama, and K. Murphy. Speed/accuracy trade-offs for modern convolutional object detectors. arXiv preprint arXiv:1611.10012 , 2016.
[25] J.-H. Jacobsen, J. van Gemert, Z. Lou, and A. W.M.Smeulders. Structured receptive fields in cnns. In CVPR , 2016.
[26] M. Jaderberg, K. Simonyan, A. Zisserman, and K. Kavukcuoglu. Spatial transformer networks. In NIPS , 2015.
[27] Y. Jeon and J. Kim. Active convolution: Learning the shape of convolution for image classification. In CVPR , 2017.
[28] Y. Jia, C. Huang, and T. Darrell. Beyond spatial pyramids: Receptive field learning for pooled image features. In CVPR , 2012.
[29] A. Kanazawa, A. Sharma, and D. Jacobs. Locally scale-invariant convolutional neural networks. In NIPS , 2014.
[30] J. J. Koenderink and A. J. van Doom. Representation of local geometry in the visual system. Biological Cybernetics , 55(6):367–375, Mar. 1987.
[31] A. Krizhevsky, I. Sutskever, and G. E. Hinton. Imagenet classification with deep convolutional neural networks. In NIPS , 2012.
[32] D. Laptev and J. M.Buhmann. Transformation-invariant convolutional jungles. In CVPR , 2015.
[33] D. Laptev, N. Savinov, J. M. Buhmann, and M. Pollefeys. Ti-pooling: transformation-invariant pooling for feature learning in convolutional neural networks. arXiv preprint arXiv:1604.06318 , 2016.
[34] S. Lazebnik, C. Schmid, and J. Ponce. Beyond bags of features: Spatial pyramid matching for recognizing natural scene categories. In CVPR , 2006.
[35] Y. LeCun and Y. Bengio. Convolutional networks for images, speech, and time series. The handbook of brain theory and neural networks , 1995.
[36] K. Lenc and A. Vedaldi. Understanding image representations by measuring their equivariance and equivalence. In CVPR , 2015.
[37] C.-H. Lin and S. Lucey. Inverse compositional spatial transformer networks. arXiv preprint arXiv:1612.03897 , 2016.
[38] T.-Y. Lin, P. Dollár, R. Girshick, K. He, B. Hariharan, and S. Belongie. Feature pyramid networks for object detection. In CVPR , 2017.
[39] T.-Y. Lin, M. Maire, S. Belongie, J. Hays, P. Perona, D. Ramanan, P. Dollár, and C. L. Zitnick. Microsoft COCO: Common objects in context. In ECCV . 2014.
[40] W. Liu, D. Anguelov, D. Erhan, C. Szegedy, and S. Reed. Ssd: Single shot multibox detector. In ECCV , 2016.
[41] J. Long, E. Shelhamer, and T. Darrell. Fully convolutional networks for semantic segmentation. In CVPR , 2015.
[42] D. G. Lowe. Object recognition from local scale-invariant features. In ICCV , 1999.
[43] W. Luo, Y. Li, R. Urtasun, and R. Zemel. Understanding the effective receptive field in deep convolutional neural networks. arXiv preprint arXiv:1701.04128 , 2017.
[44] W. Ouyang, X. Wang, X. Zeng, S. Qiu, P. Luo, Y. Tian, H. Li, S. Yang, Z. Wang, C.-C. Loy, and X. Tang. Deepid-net: Deformable deep convolutional neural networks for object detection. In CVPR , 2015.
[45] P. Perona. Deformable kernels for early vision. TPAMI , 1995.
[46] J. Redmon, S. Divvala, R. Girshick, and A. Farhadi. You only look once: Unified, real-time object detection. In CVPR , 2016.
[47] S. Ren, K. He, R. Girshick, and J. Sun. Faster R-CNN: Towards real-time object detection with region proposal networks. In NIPS , 2015.
[48] S. Ren, K. He, R. Girshick, and J. Sun. Faster R-CNN: Towards real-time object detection with region proposal networks. TPAMI , 2016.
[49] E. Rublee, V. Rabaud, K. Konolige, and G. Bradski. Orb: an efficient alternative to sift or surf. In ICCV , 2011.
[50] K. Sohn and H. Lee. Learning invariant representations with local transformations. In ICML , 2012.
[51] C. Szegedy, S. Ioffe, V. Vanhoucke, and A. Alemi. Inception-v4, inception-resnet and the impact of residual connections on learning. arXiv preprint arXiv:1602.07261 , 2016.
[52] C. Szegedy, S. Reed, D. Erhan, and D. Anguelov. Scalable, high-quality object detection. arXiv:1412.1441v2 , 2014.
[53] D. E. Worrall, S. J. Garbin, D. Turmukhambetov, and G. J. Brostow. Harmonic networks: Deep translation and rotation equivariance. arXiv preprint arXiv:1612.04642 , 2016.
[54] F. Yu and V. Koltun. Multi-scale context aggregation by dilated convolutions. In ICLR , 2016.
[55] F. Yu, V. Koltun, and T. Funkhouser. Dilated residual networks. In CVPR , 2017.