Deep Speech 2: End-to-End Speech Recognition in English and Mandarin
Deep Speech 2: End-to-End Speech Recognition in English and Mandarin
Deep Speech 2:英语与普通话的端到端语音识别
Baidu Research – Silicon Valley AI Lab † † thanks: Authorship order is alphabetical. Affiliation: Dario Amodei, Rishita Anubhai, Eric Battenberg, Carl Case, Jared Casper, Bryan Catanzaro, Affiliation: Jingdong Chen, Mike Chrzanowski, Adam Coates, Greg Diamos, Erich Elsen, Jesse Engel, Affiliation: Linxi Fan, Christopher Fougner, Tony Han, Awni Hannun, Billy Jun, Patrick LeGresley, Affiliation: Libby Lin, Sharan Narang, Andrew Ng, Sherjil Ozair, Ryan Prenger, Jonathan Raiman, Affiliation: Sanjeev Satheesh, David Seetapun, Shubho Sengupta, Yi Wang, Zhiqian Wang, Chong Wang, Affiliation: Bo Xiao, Dani Yogatama, Jun Zhan, Zhenyao Zhu
Abstract
摘要
We show that an end-to-end deep learning approach can be used to recognize either English or Mandarin Chinese speech—two vastly different languages. Because it replaces entire pipelines of hand-engineered components with neural networks, end-to-end learning allows us to handle a diverse variety of speech including noisy environments, accents and different languages. Key to our approach is our application of HPC techniques, resulting in a 7x speedup over our previous system [26]. Because of this efficiency, experiments that previously took weeks now run in days. This enables us to iterate more quickly to identify superior architectures and algorithms. As a result, in several cases, our system is competitive with the transcription of human workers when benchmarked on standard datasets. Finally, using a technique called Batch Dispatch with GPUs in the data center, we show that our system can be inexpensively deployed in an online setting, delivering low latency when serving users at scale.
我们表明,端到端深度学习方法既能识别英语、也能识别普通话——两种差异极大的语言。端到端学习用神经网络替换整条手工组件流水线,因而能应对噪声环境、口音与不同语言等多样语音。方法的关键是应用高性能计算(HPC)技术,相对我们此前系统 [26] 加速约 7 倍。效率提升后,原先要几周的实验现在几天就能跑完,使我们能更快迭代、找出更好的架构与算法。结果是,在若干标准数据集上,系统可与人工转写员的水平竞争。最后,借助数据中心里的 Batch Dispatch 与 GPU,我们表明系统可廉价部署到在线场景,在规模化服务用户时仍保持低延迟。
1 Introduction
1 引言
Decades worth of hand-engineered domain knowledge has gone into current state-of-the-art automatic speech recognition (ASR) pipelines. A simple but powerful alternative solution is to train such ASR models end-to-end, using deep learning to replace most modules with a single model [26]. We present the second generation of our speech system that exemplifies the major advantages of end-to-end learning. The Deep Speech 2 ASR pipeline approaches or exceeds the accuracy of Amazon Mechanical Turk human workers on several benchmarks, works in multiple languages with little modification, and is deployable in a production setting. It thus represents a significant step towards a single ASR system that addresses the entire range of speech recognition contexts handled by humans. Since our system is built on end-to-end deep learning, we can employ a spectrum of deep learning techniques: capturing large training sets, training larger models with high performance computing, and methodically exploring the space of neural network architectures. We show that through these techniques we are able to reduce error rates of our previous end-to-end system [26] in English by up to 43%, and can also recognize Mandarin speech with high accuracy.
当今最优自动语音识别(ASR)流水线凝聚了数十年手工领域知识。一个简单却有力的替代方案,是用深度学习把多数模块换成单一模型,端到端训练 ASR [26]。我们给出第二代语音系统,用以体现端到端学习的主要优势。Deep Speech 2 的 ASR 流水线在若干基准上接近或超过 Amazon Mechanical Turk 人工标注员的精度,稍作修改即可用于多语言,且可部署到生产环境。它朝「单一 ASR 系统覆盖人类所能处理的全部语音识别情境」迈出了重要一步。由于系统建立在端到端深度学习之上,我们可以动用一整套深度学习手段:采集大规模训练集、用高性能计算训练更大模型、系统探索神经网络架构空间。借助这些技术,英语上相对先前端到端系统 [26] 错误率最多可降约 43%,普通话也能达到较高识别精度。
One of the challenges of speech recognition is the wide range of variability in speech and acoustics. As a result, modern ASR pipelines are made up of numerous components including complex feature extraction, acoustic models, language and pronunciation models, speaker adaptation, etc. Building and tuning these individual components makes developing a new speech recognizer very hard, especially for a new language. Indeed, many parts do not generalize well across environments or languages and it is often necessary to support multiple application-specific systems in order to provide acceptable accuracy. This state of affairs is different from human speech recognition: people have the innate ability to learn any language during childhood, using general skills to learn language. After learning to read and write, most humans can transcribe speech with robustness to variation in environment, speaker accent and noise, without additional training for the transcription task. To meet the expectations of speech recognition users, we believe that a single engine must learn to be similarly competent; able to handle most applications with only minor modifications and able to learn new languages from scratch without dramatic changes. Our end-to-end system puts this goal within reach, allowing us to approach or exceed the performance of human workers on several tests in two very different languages: Mandarin and English.
语音识别的难点之一是语音与声学变化极大。因此现代 ASR 流水线由复杂特征提取、声学模型、语言与发音模型、说话人自适应等众多组件组成。分别构建与调参使开发新识别器很难,尤其对新语言:许多部件跨环境或跨语言泛化不佳,常需维护多套应用专用系统才能达到可接受精度。这与人类语音识别不同:人在童年能以通用能力学会任意语言;学会读写后,多数人无需为转写任务额外训练,就能对说话环境、口音与噪声保持稳健。为满足用户预期,我们认为单一引擎必须学到类似能力:只需小改即可覆盖多数应用,并能从零学新语言而不必大改架构。我们的端到端系统使这一目标变得可达,在普通话与英语这两种迥异语言的若干测试上接近或超过人工标注员。
Since Deep Speech 2 (DS2) is an end-to-end deep learning system, we can achieve performance gains by focusing on three crucial components: the model architecture, large labeled training datasets, and computational scale. This approach has also yielded great advances in other application areas such as computer vision and natural language. This paper details our contribution to these three areas for speech recognition, including an extensive investigation of model architectures and the effect of data and model size on recognition performance. In particular, we describe numerous experiments with neural networks trained with the Connectionist Temporal Classification (CTC) loss function [22] to predict speech transcriptions from audio. We consider networks composed of many layers of recurrent connections, convolutional filters, and nonlinearities, as well as the impact of a specific instance of Batch Normalization [63] (BatchNorm) applied to RNNs. We not only find networks that produce much better predictions than those in previous work [26], but also find instances of recurrent models that can be deployed in a production setting with no significant loss in accuracy.
既然 Deep Speech 2(DS2)是端到端深度学习系统,性能提升可聚焦三件事:模型架构、大规模有标注训练集、计算规模。这一思路在计算机视觉与自然语言等领域也带来了巨大进步。本文详述我们在语音识别这三方面的贡献,包括对模型架构的广泛考察,以及数据量与模型规模对识别性能的影响。具体地,我们描述大量用联结时序分类(CTC)损失函数 [22] 训练、从音频预测转写文本的神经网络实验。网络由多层循环连接、卷积滤波器与非线性构成,并考察一种应用于 RNN 的批归一化(BatchNorm)[63] 实例。我们不仅找到比先前工作 [26] 预测好得多的网络,还找到可在生产环境部署且精度无明显损失的循环模型实例。
Beyond the search for better model architecture, deep learning systems benefit greatly from large quantities of training data. We detail our data capturing pipeline that has enabled us to create larger datasets than what is typically used to train speech recognition systems. Our English speech system is trained on 11,940 hours of speech, while the Mandarin system is trained on 9,400 hours. We use data synthesis to further augment the data during training.
除了搜寻更好架构,深度学习系统也极大受益于海量训练数据。我们详述数据采集流水线,得以构建比常规 ASR 训练集更大的数据集。英语系统用 11,940 小时语音训练,普通话系统用 9,400 小时。训练时还用数据合成进一步增强。
Training on large quantities of data usually requires the use of larger models. Indeed, our models have many more parameters than those used in our previous system. Training a single model at these scales requires tens of exaFLOPs[^1] that would require 3-6 weeks to execute on a single GPU. This makes model exploration a very time consuming exercise, so we have built a highly optimized training system that uses 8 or 16 GPUs to train one model. In contrast to previous large-scale training approaches that use parameter servers and asynchronous updates [18, 10], we use synchronous SGD, which is easier to debug while testing new ideas, and also converges faster for the same degree of data parallelism. To make the entire system efficient, we describe optimizations for a single GPU as well as improvements to scalability for multiple GPUs. We employ optimization techniques typically found in High Performance Computing to improve scalability. These optimizations include a fast implementation of the CTC loss function on the GPU, and a custom memory allocator. We also use carefully integrated compute nodes and a custom implementation of all-reduce to accelerate inter-GPU communication. Overall the system sustains approximately 50 teraFLOP/second when training on 16 GPUs. This amounts to 3 teraFLOP/second per GPU which is about 50% of peak theoretical performance. This scalability and efficiency cuts training times down to 3 to 5 days, allowing us to iterate more quickly on our models and datasets.
大数据通常需要更大模型。我们的模型参数量远超先前系统。在此规模上训练单个模型需要数十 exaFLOP[^1],单 GPU 约需 3–6 周。模型探索因此很耗时,于是我们构建了高度优化的训练系统,用 8 或 16 块 GPU 训练一个模型。相对使用参数服务器与异步更新的大规模训练 [18, 10],我们采用同步 SGD:调试新想法更方便,在相同数据并行度下也收敛更快。为使整系统高效,我们描述单 GPU 优化以及多 GPU 可扩展性改进,并采用高性能计算中常见的优化技术,包括 GPU 上快速 CTC 损失实现与定制内存分配器,以及精心集成的计算节点与定制 all-reduce 以加速 GPU 间通信。整体上,16 GPU 训练可持续约 50 teraFLOP/秒,即每 GPU 约 3 teraFLOP/秒,约为理论峰值的 50%。这种可扩展性与效率把训练时间压到 3–5 天,使我们能更快迭代模型与数据集。
We benchmark our system on several publicly available test sets and compare the results to our previous end-to-end system [26]. Our goal is to eventually reach human-level performance not only on specific benchmarks, where it is possible to improve through dataset-specific tuning, but on a range of benchmarks that reflects a diverse set of scenarios. To that end, we have also measured the performance of human workers on each benchmark for comparison. We find that our system outperforms humans in some commonly-studied benchmarks and has significantly closed the gap in much harder cases. In addition to public benchmarks, we show the performance of our Mandarin system on internal datasets that reflect real-world product scenarios.
我们在多个公开测试集上评测系统,并与先前端到端系统 [26] 比较。目标不仅是在可做数据集专用调优的特定基准上达到人类水平,还要在反映多样场景的一系列基准上做到这一点。为此,我们也在每个基准上测量了人工标注员表现以作对照。系统在一些常研究的基准上超过人类,并在更难情形中显著缩小差距。除公开基准外,我们还给出普通话系统在反映真实产品场景的内部数据集上的表现。
Deep learning systems can be challenging to deploy at scale. Large neural networks are computationally expensive to evaluate for each user utterance, and some network architectures are more easily deployed than others. Through model exploration, we find high-accuracy, deployable network architectures, which we detail here. We also employ a batching scheme suitable for GPU hardware called Batch Dispatch that leads to an efficient, real-time implementation of our Mandarin engine on production servers. Our implementation achieves a 98th percentile compute latency of 67 milliseconds, while the server is loaded with 10 simultaneous audio streams.
深度学习系统规模化部署并不容易。大网络对每条用户话语评估代价高,且有些架构更易部署。通过模型探索,我们找到高精度且可部署的网络架构,下文详述。我们还采用适合 GPU 硬件的批处理方案 Batch Dispatch,使普通话引擎在生产服务器上能高效实时运行。实现在服务器同时承载 10 路音频流时,计算延迟的第 98 百分位为 67 毫秒。
The remainder of the paper is as follows. We begin with a review of related work in deep learning, end-to-end speech recognition, and scalability in Section 2. Section 3 describes the architectural and algorithmic improvements to the model and Section 4 explains how to efficiently compute them. We discuss the training data and steps taken to further augment the training set in Section 5. An analysis of results for the DS2 system in English and Mandarin is presented in Section 6. We end with a description of the steps needed to deploy DS2 to real users in Section 7.
全文结构如下。第 2 节回顾深度学习、端到端语音识别与可扩展性相关工作。第 3 节描述模型的架构与算法改进,第 4 节说明如何高效计算。第 5 节讨论训练数据及进一步增强训练集的步骤。第 6 节分析 DS2 在英语与普通话上的结果。第 7 节说明把 DS2 部署给真实用户所需步骤。
2 Related Work
2 相关工作
This work is inspired by previous work in both deep learning and speech recognition. Feed-forward neural network acoustic models were explored more than 20 years ago [7, 50, 19]. Recurrent neural networks and networks with convolution were also used in speech recognition around the same time [51, 67]. More recently DNNs have become a fixture in the ASR pipeline with almost all state of the art speech work containing some form of deep neural network [42, 29, 17, 16, 43, 58]. Convolutional networks have also been found beneficial for acoustic models [1, 53]. Recurrent neural networks, typically LSTMs, are just beginning to be deployed in state-of-the art recognizers [24, 25, 55] and work well together with convolutional layers for the feature extraction [52]. Models with both bidirectional [24] and unidirectional recurrence have been explored as well.
本工作受深度学习与语音识别两方面先前研究启发。前馈神经网络声学模型二十多年前就有探索 [7, 50, 19]。同期也有人把循环网络与卷积网络用于语音识别 [51, 67]。近年来,深度前馈网络与循环网络的声学模型已进入工业 ASR 流水线 [31, 24, 56, 55]。卷积网络也被重新引入语音识别 [1, 53, 60],并与深度前馈网络结合 [54]。
End-to-end speech recognition is an active area of research, showing compelling results when used to re-score the outputs of a DNN-HMM [23] and standalone [26]. Two methods are currently used to map variable length audio sequences directly to variable length transcriptions. The RNN encoder-decoder paradigm uses an encoder RNN to map the input to a fixed length vector and a decoder network to expand the fixed length vector into a sequence of output predictions [11, 62]. Adding an attentional mechanism to the decoder greatly improves performance of the system, particularly with long inputs or outputs [2]. In speech, the RNN encoder-decoder with attention performs well both in predicting phonemes [12] or graphemes [3, 8].
端到端语音识别是活跃研究领域。早期工作把神经网络与隐马尔可夫模型(HMM)结合 [7]。近年来,人们用循环神经网络直接从声学帧映射到字符或音素序列 [26, 22, 23]。另一些工作用注意力机制做对齐,或把神经网络与加权有限状态转换器(WFST)解码结合 [5, 46]。我们的方法建立在 Deep Speech(DS1)[26] 之上,把整条声学与语言模型替换为单一深度 RNN。
The other commonly used technique for mapping variable length audio input to variable length output is the CTC loss function [22] coupled with an RNN to model temporal information. The CTC-RNN model performs well in end-to-end speech recognition with grapheme outputs [23, 27, 26, 40]. The CTC-RNN model has also been shown to work well in predicting phonemes [41, 54], though a lexicon is still needed in this case. Furthermore it has been necessary to pre-train the CTC-RNN network with a DNN cross-entropy network that is fed frame-wise alignments from a GMM-HMM system [54]. In contrast, we train the CTC-RNN networks from scratch without the need of frame-wise alignments for pre-training.
可扩展深度学习对大型语音数据集至关重要。大规模分布式训练常用参数服务器与异步 SGD [18, 10]。我们改用同步 SGD,配合高效的 GPU 实现与定制通信,在多 GPU 上达到高硬件利用率。相关工作还包括模型并行 [10]、数据并行的高效通信原语,以及针对语音序列模型的专用加速。
Exploiting scale in deep learning has been central to the success of the field thus far [36, 38]. Training on a single GPU resulted in substantial performance gains [49], which were subsequently scaled linearly to two [36] or more GPUs [15]. We take advantage of work in increasing individual GPU efficiency for low-level deep learning primitives [9]. We build on the past work in using model-parallelism [15], data-parallelism [18] or a combination of the two [64, 26] to create a fast and highly scalable system for training deep RNNs in speech recognition.
批归一化 [63] 已广泛用于加速前馈网络训练。将其扩展到循环网络有多种方案 [37];我们表明在大规模数据上对很深的简单 RNN,序列级 BatchNorm 既能加速训练,也能明显改善最终泛化误差。
Data has also been central to the success of end-to-end speech recognition, with over 7000 hours of labeled speech used in Deep Speech 1 (DS1) [26]. Data augmentation has been highly effective in improving the performance of deep learning in computer vision [39, 56, 14]. This has also been shown to improve speech systems [21, 26]. Techniques used for data augmentation in speech range from simple noise addition [26] to complex perturbations such as simulating changes to the vocal tract length and rate of speech of the speaker [31, 35].
课程学习 [6] 与按难度排序样本 [70] 在多种序列学习任务中有用。我们提出 SortaGrad:首个 epoch 按话语长度由短到长训练,以稳定 CTC 训练并改善优化。
Existing speech systems can also be used to bootstrap new data collection. In one approach, the authors use one speech engine to align and filter a thousand hours of read speech [46]. In another approach, a heavy-weight offline speech recognizer is used to generate transcriptions for tens of thousands of hours of speech [33]. This is then passed through a filter and used to re-train the recognizer, resulting in significant performance gains. We draw inspiration from these past approaches in bootstrapping larger datasets and data augmentation to increase the effective amount of labeled data for our system.
部署方面,在线低延迟 ASR 通常偏好单向模型。我们引入行卷积(row convolution),使单向网络在保留有限未来上下文的同时达到与双向模型相当的精度,从而便于流式部署。
3 Model Architecture
3 模型架构
A simple multi-layer model with a single recurrent layer cannot exploit thousands of hours of labelled speech. In order to learn from datasets this large, we increase the model capacity via depth. We explore architectures with up to 11 layers including many bidirectional recurrent layers and convolutional layers. These models have nearly 8 times the amount of computation per data example as the models in Deep Speech 1 making fast optimization and computation critical. In order to optimize these models successfully, we use Batch Normalization for RNNs and a novel optimization curriculum we call SortaGrad. We also exploit long strides between RNN inputs to reduce computation per example by a factor of 3. This is helpful for both training and evaluation, though requires some modifications in order to work well with CTC. Finally, though many of our research results make use of bidirectional recurrent layers, we find that excellent models exist using only unidirectional recurrent layers—a feature that makes such models much easier to deploy. Taken together these features allow us to tractably optimize deep RNNs and improve performance by more than 40% in both English and Mandarin error rates over the smaller baseline models.
本节描述 DS2 系统相对 DS1 的架构与算法改进。核心仍是用 CTC 训练的深度 RNN:输入语音频谱图,输出文本转写。我们系统探索卷积层数、循环层深度、BatchNorm、SortaGrad、简单 RNN 与 GRU、频率卷积、跨步、行卷积与语言模型集成。这些特性合在一起,使我们能有效优化很深的 RNN,并相对较小基线模型在英语与普通话错误率上均改善超过 40%。还存在仅用单向循环层的部署友好变体。
3.1 Preliminaries
3.1 预备知识
Figure 1 shows the architecture of the DS2 system which at its core is similar to the previous DS1 system [26]: a recurrent neural network (RNN) trained to ingest speech spectrograms and generate text transcriptions.
图 1 给出 DS2 系统架构,核心与先前 DS1 [26] 类似:用 RNN 吞入语音频谱图并生成文本转写。
Let a single utterance and label be sampled from a training set . Each utterance, , is a time-series of length where every time-slice is a vector of audio features, . We use a spectrogram of power normalized audio clips as the features to the system, so denotes the power of the ’th frequency bin in the audio frame at time . The goal of the RNN is to convert an input sequence into a final transcription . For notational convenience, we drop the superscripts and use to denote a chosen utterance and the corresponding label.
设单条话语 与标签 采自训练集 。每条话语 是长度 的时间序列,每个时间片是音频特征向量 。我们用功率归一化音频片段的频谱图作特征,故 表示时刻 音频帧中第 个频率箱的功率。RNN 的目标是把输入序列 转成最终转写 。为记号方便,省略上标,用 表示选定话语、 表示对应标签。
The outputs of the network are the graphemes of each language. At each output time-step , the RNN makes a prediction over characters, , where is either a character in the alphabet or the blank symbol. In English we have , where we have added the apostrophe as well as a space symbol to denote word boundaries. For the Mandarin system the network outputs simplified Chinese characters. We describe this in more detail in Section 3.9.
网络输出是各语言的字素。在每个输出时间步 ,RNN 对字符做预测 ,其中 是字母表中的字符或 blank 符号。英语中 ,我们加入 apostrophe 以及表示词边界的 space。普通话系统网络输出简体汉字,详见第 3.9 节。
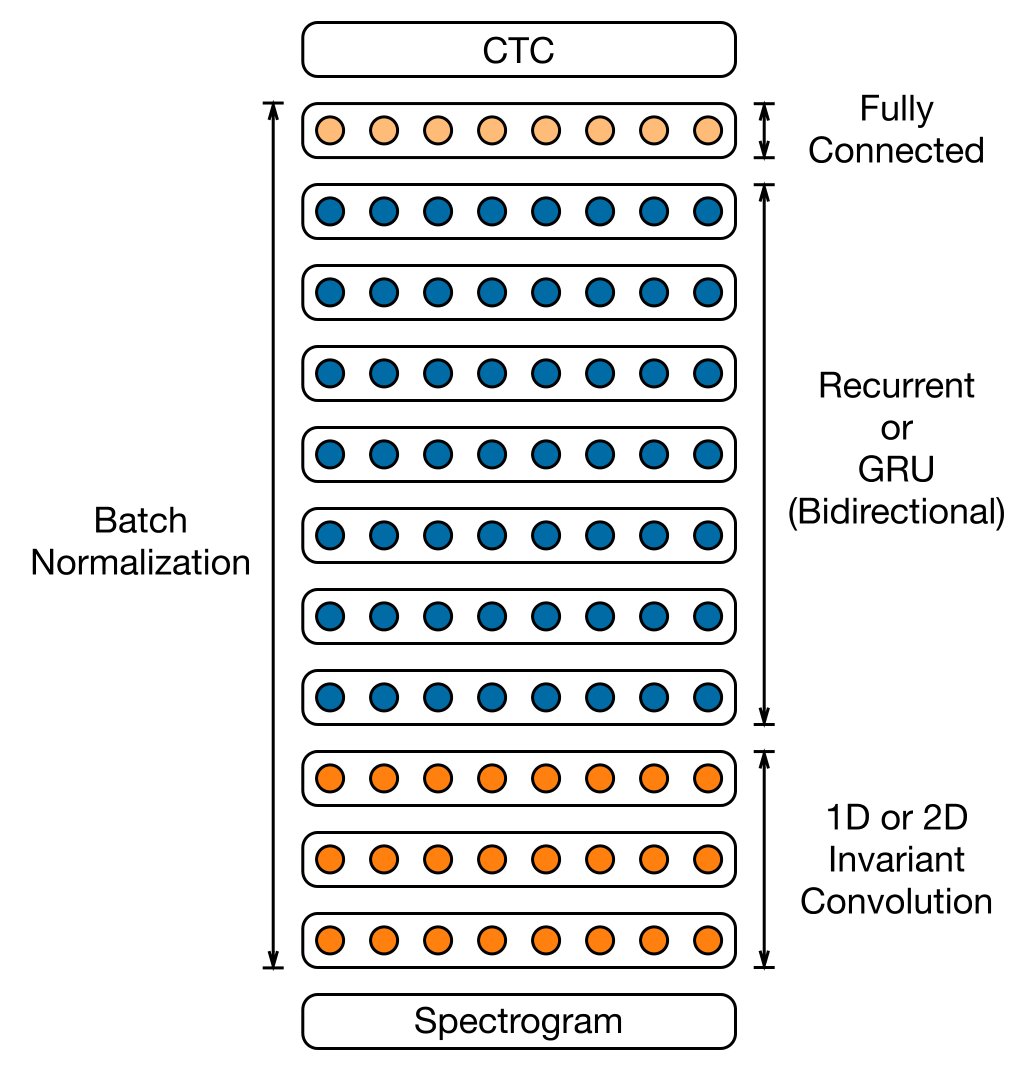
Figure 1: Architecture of the DS2 system used to train on both English and Mandarin speech. We explore variants of this architecture by varying the number of convolutional layers from 1 to 3 and the number of recurrent or GRU layers from 1 to 7.
图 1:用于英语与普通话语音训练的 DS2 系统架构。我们通过把卷积层数从 1 变到 3、循环或 GRU 层数从 1 变到 7 来探索该架构的变体。
The RNN model is composed of several layers of hidden units. The architectures we experiment with consist of one or more convolutional layers, followed by one or more recurrent layers, followed by one or more fully connected layers.
RNN 模型由若干隐层组成。所试验架构包含一层或多层卷积,后接一层或多层循环层,再接一层或多层全连接层。
The hidden representation at layer is given by with the convention that represents the input . The bottom of the network is one or more convolutions over the time dimension of the input. For a context window of size , the -th activation at time-step of the convolutional layer is given by
第 层隐表示为 ,约定 表示输入 。网络底部是对输入时间维的一层或多层卷积。对大小为 的上下文窗,卷积层在时间步 的第 个激活为
where denotes the element-wise product between the -th filter and the context window of the previous layers activations, and denotes a unary nonlinear function. We use the clipped rectified-linear (ReLU) function as our nonlinearity. In some layers, usually the first, we sub-sample by striding the convolution by frames. The goal is to shorten the number of time-steps for the recurrent layers above.
其中 表示第 个滤波器与前一层激活上下文窗的逐元素乘积, 为一元非线性。我们用截断 ReLU 作为非线性。某些层(通常是第一层)通过对卷积跨 帧做 stride 来子采样,目的是缩短上层循环层的时间步数。
Following the convolutional layers are one or more bidirectional recurrent layers [57]. The forward in time and backward in time recurrent layer activations are computed as
卷积层之后是一层或多层双向循环层 [57]。前向 与后向 循环层激活计算为
The two sets of activations are summed to form the output activations for the layer . The function can be the standard recurrent operation
两组激活相加得到该层输出激活 。函数 可以是标准循环运算
where is the input-hidden weight matrix, is the recurrent weight matrix and is a bias term. In this case the input-hidden weights are shared for both directions of the recurrence. The function can also represent more complex recurrence operations such as the Long Short-Term Memory (LSTM) units [30] and the gated recurrent units (GRU) [11].
其中 是输入–隐权重矩阵, 是循环权重矩阵, 是偏置。此时输入–隐权重在两个循环方向上共享。 也可表示更复杂的循环运算,如长短期记忆(LSTM)单元 [30] 与门控循环单元(GRU)[11]。
After the bidirectional recurrent layers we apply one or more fully connected layers with
双向循环层之后,我们施加一层或多层全连接层:
The output layer is a softmax computing a probability distribution over characters given by
输出层 是 softmax,计算字符上的概率分布:
The model is trained using the CTC loss function [22]. Given an input-output pair and the current parameters of the network , we compute the loss function and its derivative with respect to the parameters of the network . This derivative is then used to update the network parameters through the backpropagation through time algorithm.
模型用 CTC 损失函数 [22] 训练。给定输入–输出对 与当前网络参数 ,计算损失 及其对参数的导数 ,再用随时间反向传播算法更新网络参数。
In the following subsections we describe the architectural and algorithmic improvements made relative to DS1 [26]. Unless otherwise stated these improvements are language agnostic. We report results on an English speaker held out development set which is an internal dataset containing 2048 utterances of primarily read speech. All models are trained on datasets described in Section 5. We report Word Error Rate (WER) for the English system and Character Error Rate (CER) for the Mandarin system. In both cases we integrate a language model in a beam search decoding step as described in Section 3.8.
以下小节描述相对 DS1 [26] 的架构与算法改进。除非另有说明,这些改进与语言无关。我们在一个内部英语说话人留出开发集上报告结果,该集含 2048 条以朗读语音为主的话语。所有模型在第 5 节所述数据集上训练。英语报告词错误率(WER),普通话报告字错误率(CER)。两种情形都在束搜索解码步中接入语言模型,见第 3.8 节。
3.2 Batch Normalization for Deep RNNs
3.2 深度 RNN 的批归一化
To efficiently scale our model as we scale the training set, we increase the depth of the networks by adding more hidden layers, rather than making each layer larger. Previous work has examined doing so by increasing the number of consecutive bidirectional recurrent layers [24]. We explore Batch Normalization (BatchNorm) as a technique to accelerate training for such networks [63] since they often suffer from optimization issues.
为随训练集扩大而高效放大模型,我们通过增加隐层深度而非加宽单层。先前工作通过增加连续双向循环层数做过类似尝试 [24]。我们探索用批归一化(BatchNorm)加速此类网络训练 [63],因为它们常遇到优化困难。
Recent research has shown that BatchNorm improves the speed of convergence of recurrent nets, without showing any improvement in generalization performance [37]. In contrast, we demonstrate that when applied to very deep networks of simple RNNs on large data sets, batch normalization substantially improves final generalization error while greatly accelerating training.
近期研究表明 BatchNorm 能加快循环网收敛速度,但未显示泛化提升 [37]。相反,我们证明:在大规模数据上对很深的简单 RNN 施加批归一化,既能大幅加速训练,也能显著改善最终泛化误差。
In a typical feed-forward layer containing an affine transformation followed by a non-linearity , we insert a BatchNorm transformation by applying instead of , where
在典型的「仿射变换后接非线性 」前馈层中,我们插入 BatchNorm:用 替代 ,其中
The terms and are the empirical mean and variance over a minibatch. The bias of the layer is dropped since its effect is cancelled by mean removal. The learnable parameters and allow the layer to scale and shift each hidden unit as desired. The constant is small and positive, and is included only for numerical stability. In our convolutional layers the mean and variance are estimated over all the temporal output units for a given convolutional filter on a minibatch. The BatchNorm transformation reduces internal covariate shift by insulating a given layer from potentially uninteresting changes in the mean and variance of the layer’s input.
与 是小批量上的经验均值与方差。层偏置 被去掉,因其效果会被去均值抵消。可学习参数 与 允许层按需缩放与平移每个隐单元。常数 为小正数,仅为保证数值稳定。在卷积层中,均值与方差对给定卷积滤波器在小批量上的所有时间输出单元估计。BatchNorm 变换通过隔离某层输入均值与方差中可能无关紧要的变化,减少内部协变量偏移。
We consider two methods of extending BatchNorm to bidirectional RNNs [37]. A natural extension is to insert a BatchNorm transformation immediately before every non-linearity. Equation 3 then becomes
我们考虑把 BatchNorm 扩展到双向 RNN 的两种方法 [37]。自然扩展是在每个非线性前立即插入 BatchNorm。于是式 3 变为
In this case the mean and variance statistics are accumulated over a single time-step of the minibatch. The sequential dependence between time-steps prevents averaging over all time-steps. We find that this technique does not lead to improvements in optimization. We also tried accumulating an average over successive time-steps, so later time-steps are normalized over all present and previous time-steps. This also proved ineffective and greatly complicated backpropagation.
此时均值与方差统计量在小批量的单个时间步上累积。时间步之间的顺序依赖妨碍对所有时间步取平均。我们发现该技术并不改善优化。我们也尝试在相继时间步上累积平均,使较晚时间步对当前及先前所有时间步归一化;这同样无效,并大幅复杂化反向传播。
We find that sequence-wise normalization [37] overcomes these issues. The recurrent computation is given by
我们发现序列级归一化 [37] 能克服这些问题。循环计算为
| Architecture | Hidden Units | Train | Dev | ||||||
|---|---|---|---|---|---|---|---|---|---|
| Baseline | BatchNorm | Baseline | BatchNorm | ||||||
| 1 RNN, 5 total | 2400 | 10.55 | 11.99 | 13.55 | 14.40 | ||||
| 3 RNN, 5 total | 1880 | 9.55 | 8.29 | 11.61 | 10.56 | ||||
| 5 RNN, 7 total | 1510 | 8.59 | 7.61 | 10.77 | 9.78 | ||||
| 7 RNN, 9 total | 1280 | 8.76 | 7.68 | 10.83 | 9.52 |
Table 1: Comparison of WER on a training and development set for various depths of RNN, with and without BatchNorm. The number of parameters is kept constant as the depth increases, thus the number of hidden units per layer decreases. All networks have 38 million parameters. The architecture “M RNN, N total” implies 1 layer of 1D convolution at the input, M consecutive bidirectional RNN layers, and the rest as fully-connected layers with N total layers in the network.
| 架构 | 隐单元数 | 训练 | 开发 | ||||||
|---|---|---|---|---|---|---|---|---|---|
| 基线 | BatchNorm | 基线 | BatchNorm | ||||||
| 1 RNN,共 5 层 | 2400 | 10.55 | 11.99 | 13.55 | 14.40 | ||||
| 3 RNN,共 5 层 | 1880 | 9.55 | 8.29 | 11.61 | 10.56 | ||||
| 5 RNN,共 7 层 | 1510 | 8.59 | 7.61 | 10.77 | 9.78 | ||||
| 7 RNN,共 9 层 | 1280 | 8.76 | 7.68 | 10.83 | 9.52 |
表 1:不同 RNN 深度、有无 BatchNorm 时训练与开发集 WER 比较。深度增加时保持参数总量恒定,因而每层隐单元数减少。所有网络约 3800 万参数。「M RNN,共 N 层」表示输入处 1 层一维卷积、M 层连续双向 RNN,其余为全连接,网络总层数为 N。
For each hidden unit, we compute the mean and variance statistics over all items in the minibatch over the length of the sequence. Figure 2 shows that deep networks converge faster with sequence-wise normalization. Table 1 shows that the performance improvement from sequence-wise normalization increases with the depth of the network, with a 12% performance difference for the deepest network. When comparing depth, in order to control for model size we hold constant the total number of parameters and still see strong performance gains. We would expect to see even larger improvements from depth if we held constant the number of activations per layer and added layers. We also find that BatchNorm harms generalization error for the shallowest network just as it converges slower for shallower networks.
对每个隐单元,我们在小批量所有样本、整段序列长度上计算均值与方差。图 2 显示带序列级归一化时深层网络收敛更快。表 1 表明序列级归一化带来的性能提升随网络深度增加,最深网络约有 12% 相对差异。比较深度时,为控制模型规模我们固定总参数量,仍看到强劲增益。若固定每层激活数再加深,预期提升会更大。我们也发现 BatchNorm 会损害最浅网络的泛化误差,正如它在较浅网络上收敛更慢一样。
The BatchNorm approach works well in training, but is difficult to implement for a deployed ASR system, since it is often necessary to evaluate a single utterance in deployment rather than a batch. We find that normalizing each neuron to its mean and variance over just the sequence degrades performance. Instead, we store a running average of the mean and variance for the neuron collected during training, and use these for evaluation in deployment [63]. Using this technique, we can evaluate a single utterance at a time with better results than evaluating with a large batch.
BatchNorm 在训练时效果好,但部署 ASR 时难实现,因为部署常需评估单条话语而非一个批量。我们发现仅按该序列对每个神经元归一化到其均值与方差会损害性能。相反,我们存储训练期间收集的神经元均值与方差的运行平均,部署评估时使用这些统计量 [63]。借此可一次评估单条话语,效果优于用大批量评估。
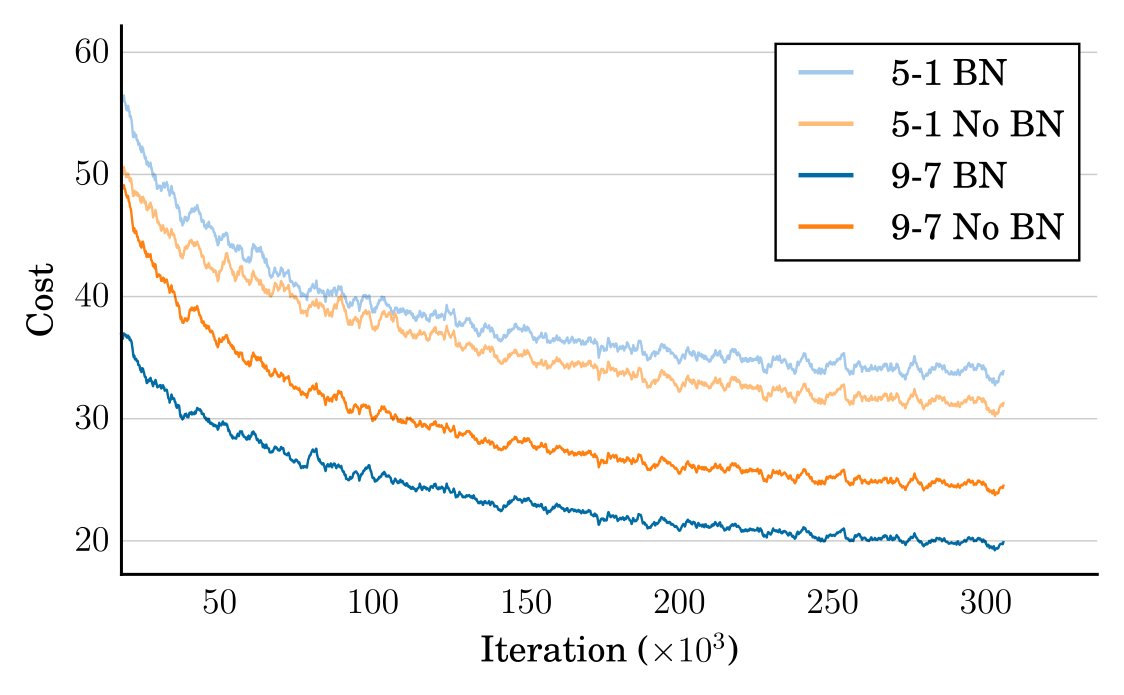
Figure 2: Training curves of two models trained with and without BatchNorm. We start the plot after the first epoch of training as the curve is more difficult to interpret due to the SortaGrad curriculum method mentioned in Section 3.3
图 2:两个模型有无 BatchNorm 的训练曲线。曲线从第一个 epoch 之后开始绘制,因第 3.3 节所述 SortaGrad 课程法使初期曲线更难解读。
3.3 SortaGrad
Training on examples of varying length pose some algorithmic challenges. One possible solution is truncating backpropagation through time [68], so that all examples have the same sequence length during training [52]. However, this can inhibit the ability to learn longer term dependencies. Other works have found that presenting examples in order of difficulty can accelerate online learning [6, 70]. A common theme in many sequence learning problems including machine translation and speech recognition is that longer examples tend to be more challenging [11].
在长度不一的样本上训练会带来一些算法挑战。一种可能方案是截断随时间反向传播 [68],使训练时所有样本序列长度相同 [52],但这会抑制学习更长程依赖的能力。另一些工作发现按难度顺序呈现样本可加速在线学习 [6, 70]。机器翻译与语音识别等许多序列学习问题中,较长样本往往更难 [11]。
The CTC cost function that we use implicitly depends on the length of the utterance,
我们使用的 CTC 代价函数隐含地依赖于话语长度,
where is the set of all possible alignments of the characters of the transcription to frames of input under the CTC operator. In equation 9, the inner term is a product over time-steps of the sequence, which shrinks with the length of the sequence since . This motivates a curriculum learning strategy we title SortaGrad. SortaGrad uses the length of the utterance as a heuristic for difficulty, since long utterances have higher cost than short utterances.
其中 是在 CTC 算子下,转写 的字符到输入 各帧的所有可能对齐集合。式 9 中,内层项是序列各时间步概率的乘积;由于 ,该乘积随序列变长而缩小。这促使我们提出名为 SortaGrad 的课程学习策略:用话语长度作为难度启发量,因为长话语代价高于短话语。
| Train | Dev | |||||||
|---|---|---|---|---|---|---|---|---|
| Baseline | BatchNorm | Baseline | BatchNorm | |||||
| Not Sorted | 10.71 | 8.04 | 11.96 | 9.78 | ||||
| Sorted | 8.76 | 7.68 | 10.83 | 9.52 |
Table 2: Comparison of WER on a training and development set with and without SortaGrad, and with and without batch normalization.
| 训练 | 开发 | |||||||
|---|---|---|---|---|---|---|---|---|
| 基线 | BatchNorm | 基线 | BatchNorm | |||||
| 未排序 | 10.71 | 8.04 | 11.96 | 9.78 | ||||
| 已排序 | 8.76 | 7.68 | 10.83 | 9.52 |
表 2:有无 SortaGrad、有无批归一化时训练与开发集 WER 比较。
In the first training epoch, we iterate through the training set in increasing order of the length of the longest utterance in the minibatch. After the first epoch, training reverts back to a random order over minibatches. Table 2 shows a comparison of training cost with and without SortaGrad on the 9 layer model with 7 recurrent layers. This effect is particularly pronounced for networks without BatchNorm, since they are numerically less stable. In some sense the two techniques substitute for one another, though we still find gains when applying SortaGrad and BatchNorm together. Even with BatchNorm we find that this curriculum improves numerical stability and sensitivity to small changes in training. Numerical instability can arise from different transcendental function implementations in the CPU and the GPU, especially when computing the CTC cost. This curriculum gives comparable results for both implementations.
第一个训练 epoch 中,我们按小批量内最长话语长度递增的顺序遍历训练集;之后恢复对小批量的随机顺序。表 2 比较了 9 层(含 7 层循环)模型有无 SortaGrad 的训练代价。对无 BatchNorm 的网络效果尤为明显,因其数值更不稳定。某种意义上两种技术可相互替代,但同时使用仍有增益。即便有 BatchNorm,该课程也能改善数值稳定性,并降低对训练中微小变化的敏感。数值不稳可来自 CPU 与 GPU 上不同的超越函数实现,尤其在计算 CTC 代价时。该课程使两种实现给出可比结果。
We suspect that these benefits occur primarily because long utterances tend to have larger gradients, yet we use a fixed learning rate independent of utterance length. Furthermore, longer utterances are more likely to cause the internal state of the RNNs to explode at an early stage in training.
我们怀疑收益主要因为长话语往往有更大梯度,而我们使用与话语长度无关的固定学习率;此外,较长话语更易在训练早期使 RNN 内部状态爆炸。
3.4 Comparison of simple RNNs and GRUs
3.4 简单 RNN 与 GRU 的比较
The models we have shown so far are simple RNNs that have bidirectional recurrent layers with the recurrence for both the forward in time and backward in time directions modeled by Equation 3. Current research in speech and language processing has shown that having a more complex recurrence can allow the network to remember state over more time-steps while making them more computationally expensive to train [52, 8, 62, 2]. Two commonly used recurrent architectures are the Long Short-Term Memory (LSTM) units [30] and the Gated Recurrent Units (GRU) [11], though many other variations exist. A recent comprehensive study of thousands of variations of LSTM and GRU architectures showed that a GRU is comparable to an LSTM with a properly initialized forget gate bias, and their best variants are competitive with each other [32]. We decided to examine GRUs because experiments on smaller data sets showed the GRU and LSTM reach similar accuracy for the same number of parameters, but the GRUs were faster to train and less likely to diverge.
此前展示的模型是简单 RNN:双向循环层的前向与后向均由式 3 建模。语音与语言处理近期研究表明,更复杂的循环可让网络在更多时间步上记住状态,但训练计算更贵 [52, 8, 62, 2]。常用的两种循环架构是长短期记忆(LSTM)单元 [30] 与门控循环单元(GRU)[11],另有许多变体。一项覆盖数千种 LSTM/GRU 变体的综合研究显示,在遗忘门偏置恰当初始化时 GRU 与 LSTM 可比,二者最佳变体彼此接近 [32]。我们选择考察 GRU,因为小数据集实验显示相同参数量下 GRU 与 LSTM 精度相近,但 GRU 训练更快、更不易发散。
The GRUs we use are computed by
所用 GRU 计算为
where is the sigmoid function, and represent the update and reset gates respectively, and we drop the layer superscripts for simplicity. We differ slightly from the standard GRU in that we multiply the hidden state by prior to scaling by the reset gate. This allows for all operations on to be computed in a single matrix multiplication. The output nonlinearity is typically the hyperbolic tangent function . However, we find similar performance for and clipped-ReLU nonlinearities and choose to use the clipped-ReLU for simplicity and uniformity with the rest of the network.
其中 为 sigmoid, 与 分别表示更新与重置门,为简洁省略层上标。与标准 GRU 略有不同:我们在用重置门缩放之前,先把隐状态 乘以 ,从而使对 的全部运算可在一次矩阵乘中完成。输出非线性 通常是双曲正切 ;我们发现 与截断 ReLU 表现相近,为简单并与网络其余部分统一,选用截断 ReLU。
| Architecture | Simple RNN | GRU |
|---|---|---|
| 5 layers, 1 Recurrent | 14.40 | 10.53 |
| 5 layers, 3 Recurrent | 10.56 | 8.00 |
| 7 layers, 5 Recurrent | 9.78 | 7.79 |
| 9 layers, 7 Recurrent | 9.52 | 8.19 |
Table 3: Comparison of development set WER for networks with either simple RNN or GRU, for various depths. All models have batch normalization, one layer of 1D-invariant convolution, and approximately 38 million parameters.
| 架构 | 简单 RNN | GRU |
|---|---|---|
| 5 层,1 循环 | 14.40 | 10.53 |
| 5 层,3 循环 | 10.56 | 8.00 |
| 7 层,5 循环 | 9.78 | 7.79 |
| 9 层,7 循环 | 9.52 | 8.19 |
表 3:不同深度下简单 RNN 与 GRU 在开发集上的 WER。所有模型含批归一化、一层一维不变卷积,约 3800 万参数。
Both GRU and simple RNN architectures benefit from batch normalization and show strong results with deep networks. However, Table 3 shows that for a fixed number of parameters, the GRU architectures achieve better WER for all network depths. This is clear evidence of the long term dependencies inherent in the speech recognition task present both within individual words and between words. As we discuss in Section 3.8, even simple RNNs are able to implicitly learn a language model due to the large amount of training data. Interestingly, the GRU networks with 5 or more recurrent layers do not significantly improve performance. We attribute this to the thinning from 1728 hidden units per layer for 1 recurrent layer to 768 hidden units per layer for 7 recurrent layers, to keep the total number of parameters constant.
GRU 与简单 RNN 均受益于批归一化,在深层网络上表现强劲。但表 3 显示,固定参数量时,各深度上 GRU 的 WER 更好。这清楚表明语音识别任务中存在词内与词间的长程依赖。如第 3.8 节所述,即便简单 RNN 也能因海量训练数据隐式学到语言模型。有意思的是,5 层及以上循环的 GRU 并未显著再提升;我们将其归因于为保持总参数恒定,隐单元从 1 循环层时的每层 1728 减到 7 循环层时的每层 768。
The GRU networks outperform the simple RNNs in Table 3. However, in later results (Section 6) we find that as we scale up the model size, for a fixed computational budget the simple RNN networks perform slightly better. Given this, most of the remaining experiments use the simple RNN layers rather than the GRUs.
表 3 中 GRU 优于简单 RNN。但后续结果(第 6 节)显示,放大模型规模后,在固定计算预算下简单 RNN 略优。因此其余多数实验采用简单 RNN 层而非 GRU。
3.5 Frequency Convolutions
3.5 频率卷积
Temporal convolution is commonly used in speech recognition to efficiently model temporal translation invariance for variable length utterances. This type of convolution was first proposed for neural networks in speech more than 25 years ago [67]. Many neural network speech models have a first layer that processes input frames with some context window [16, 66]. This can be viewed as a temporal convolution with a stride of one.
时间卷积在语音识别中常用,用以高效建模变长话语的时间平移不变性。这类卷积二十多年前就已用于语音神经网络 [67]。许多神经网络语音模型的第一层用某上下文窗处理输入帧 [16, 66],可视为 stride 为 1 的时间卷积。
Additionally, sub-sampling is essential to make recurrent neural networks computationally tractable with high sample-rate audio. The DS1 system accomplished this through the use of a spectrogram as input and temporal convolution in the first layer with a stride parameter to reduce the number of time-steps [26].
此外,子采样对使高采样率音频上的循环网络计算可行至关重要。DS1 通过频谱图输入,并在第一层时间卷积使用 stride 以减少时间步数来实现这一点 [26]。
Convolutions in frequency and time domains, when applied to the spectral input features prior to any other processing, can slightly improve ASR performance [1, 53, 60]. Convolution in frequency attempts to model spectral variance due to speaker variability more concisely than what is possible with large fully connected networks. Since spectral ordering of features is removed by fully-connected and recurrent layers, frequency convolutions work better as the first layers of the network.
在任何其他处理之前,对频谱输入特征施加频率与时间域卷积,可轻微提升 ASR 表现 [1, 53, 60]。频率卷积试图比大型全连接网络更简洁地建模说话人差异带来的频谱变化。由于全连接与循环层会抹掉特征的频谱顺序,频率卷积作为网络前几层效果更好。
We experiment with adding between one and three layers of convolution. These are both in the time-and-frequency domain (2D invariance) and in the time-only domain (1D invariance). In all cases we use a same convolution, preserving the number of input features in both frequency and time. In some cases, we specify a stride across either dimension which reduces the size of the output. We do not explicitly control for the number of parameters, since convolutional layers add a small fraction of parameters to our networks. All networks shown in Table 4 have about 35 million parameters.
我们试验加入一至三层卷积,既有时–频域(二维不变),也有仅时间域(一维不变)。所有情形使用 same 卷积,在频率与时间上保持输入特征数。有时在某一维指定 stride 以减小输出尺寸。我们不显式控制参数量,因卷积层只占网络参数的一小部分。表 4 中所有网络约 3500 万参数。
We report results on two datasets—a development set of 2048 utterances (“Regular Dev”) and a much noisier dataset of 2048 utterances (“Noisy Dev”) randomly sampled from the CHiME 2015 development datasets [4]. We find that multiple layers of 1D-invariant convolutions provides a very small benefit. The 2D-invariant convolutions improve results substantially on noisy data, while providing a small benefit on clean data. The change from one layer of 1D-invariant convolution to three layers of 2D-invariant convolution improves WER by 23.9% on the noisy development set.
我们在两个数据集上报告结果:2048 条话语的开发集(「常规 Dev」),以及从 CHiME 2015 开发集 [4] 随机抽样的同样 2048 条、噪声大得多的集(「噪声 Dev」)。多层一维不变卷积收益很小;二维不变卷积在噪声数据上大幅改善,在干净数据上略有收益。从一层一维不变卷积改为三层二维不变卷积,在噪声开发集上 WER 相对改善 23.9%。
| Architecture | Channels | Filter dimension | Stride | Regular Dev | Noisy Dev |
|---|---|---|---|---|---|
| 1-layer 1D | 1280 | 11 | 2 | 9.52 | 19.36 |
| 2-layer 1D | 640, 640 | 5, 5 | 1, 2 | 9.67 | 19.21 |
| 3-layer 1D | 512, 512, 512 | 5, 5, 5 | 1, 1, 2 | 9.20 | 20.22 |
| 1-layer 2D | 32 | 41x11 | 2x2 | 8.94 | 16.22 |
| 2-layer 2D | 32, 32 | 41x11, 21x11 | 2x2, 2x1 | 9.06 | 15.71 |
| 3-layer 2D | 32, 32, 96 | 41x11, 21x11, 21x11 | 2x2, 2x1, 2x1 | 8.61 | 14.74 |
Table 4: Comparison of WER for various arrangements of convolutional layers. In all cases, the convolutions are followed by 7 recurrent layers and 1 fully connected layer. For 2D-invariant convolutions the first dimension is frequency and the second dimension is time. All models have BatchNorm, SortaGrad, and 35 million parameters.
| 架构 | 通道 | 滤波器尺寸 | Stride | 常规 Dev | 噪声 Dev |
|---|---|---|---|---|---|
| 1 层 1D | 1280 | 11 | 2 | 9.52 | 19.36 |
| 2 层 1D | 640, 640 | 5, 5 | 1, 2 | 9.67 | 19.21 |
| 3 层 1D | 512, 512, 512 | 5, 5, 5 | 1, 1, 2 | 9.20 | 20.22 |
| 1 层 2D | 32 | 41x11 | 2x2 | 8.94 | 16.22 |
| 2 层 2D | 32, 32 | 41x11, 21x11 | 2x2, 2x1 | 9.06 | 15.71 |
| 3 层 2D | 32, 32, 96 | 41x11, 21x11, 21x11 | 2x2, 2x1, 2x1 | 8.61 | 14.74 |
表 4:不同卷积层安排的 WER 比较。所有情形卷积后接 7 层循环与 1 层全连接。二维不变卷积第一维为频率、第二维为时间。所有模型含 BatchNorm、SortaGrad,约 3500 万参数。
3.6 Striding
3.6 跨步(Striding)
In the convolutional layers, we apply a longer stride and wider context to speed up training as fewer time-steps are required to model a given utterance. Downsampling the input sound (through FFT and convolutional striding) reduces the number of time-steps and computation required in the following layers, but at the expense of reduced performance.
在卷积层中,我们使用更长 stride 与更宽上下文以加速训练,因为建模给定话语所需时间步更少。通过 FFT 与卷积 stride 对输入声音下采样,可减少后续层时间步与计算量,但以性能下降为代价。
In our Mandarin models, we employ striding in the straightforward way. However, in English, striding can reduce accuracy simply because the output of our network requires at least one time-step per output character, and the number of characters in English speech per time-step is high enough to cause problems when striding[^2]. To overcome this, we can enrich the English alphabet with symbols representing alternate labellings like whole words, syllables or non-overlapping n-grams. In practice, we use non-overlapping bi-graphemes or bigrams, since these are simple to construct, unlike syllables, and there are few of them compared to alternatives such as whole words. We transform unigram labels into bigram labels through a simple isomorphism.
普通话模型中我们按直接方式使用 stride。但在英语中,stride 可能仅因网络输出至少需要每个输出字符一个时间步而降低精度——英语语音每时间步字符数足够高,跨步会出问题[^2]。为克服这一点,可用表示整词、音节或不重叠 n-gram 等替代标注的符号丰富英语字母表。实践中我们用不重叠的双字素(bigram),因其构造简单(不像音节),且相对整词等替代数量更少。我们通过简单同构把 unigram 标签变成 bigram 标签。
Non-overlapping bigrams shorten the length of the output transcription and thus allow for a decrease in the length of the unrolled RNN. The sentence the cat sat with non-overlapping bigrams is segmented as . Notice that for words with odd number of characters, the last character becomes an unigram and is treated as an unigram as well. This isomorphism ensures that the same words are always composed of the same bigram and unigram tokens. The output set of bigrams consists of all bigrams that occur in the training set.
不重叠 bigram 缩短输出转写长度,从而允许缩短展开 RNN 的长度。句子 the cat sat 用不重叠 bigram 切分为 。注意奇数个字符的词末字符变为 unigram, 也当作 unigram。该同构保证相同词总由相同的 bigram 与 unigram 标记组成。输出 bigram 集合由训练集中出现的全部 bigram 构成。
In Table 5 we show results for both the bigram and unigram systems for various levels of striding, with or without a language model. We observe that bigrams allow for larger strides without any sacrifice in in the word error rate. This allows us to reduce the number of time-steps of the unrolled RNN benefiting both computation and memory usage.
表 5 给出不同跨步水平下 bigram 与 unigram 系统、有无语言模型的结果。我们观察到 bigram 允许更大跨步而不牺牲词错误率,从而减少展开 RNN 的时间步数,既利于计算也利于内存。
| Dev no LM | Dev LM | |||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Stride | Unigrams | Bigrams | Unigrams | Bigrams | ||||||||
| 2 | 14.93 | 14.56 | 9.52 | 9.66 | ||||||||
| 3 | 15.01 | 15.60 | 9.65 | 10.06 | ||||||||
| 4 | 18.86 | 14.84 | 11.92 | 9.93 |
Table 5: Comparison of WER with different amounts of striding for unigram and bigram outputs on a model with 1 layer of 1D-invariant convolution, 7 recurrent layers, and 1 fully connected layer. All models have BatchNorm, SortaGrad, and 35 million parameters. The models are compared on a development set with and without the use of a 5-gram language model.
| Dev 无 LM | Dev 有 LM | |||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Stride | Unigrams | Bigrams | Unigrams | Bigrams | ||||||||
| 2 | 14.93 | 14.56 | 9.52 | 9.66 | ||||||||
| 3 | 15.01 | 15.60 | 9.65 | 10.06 | ||||||||
| 4 | 18.86 | 14.84 | 11.92 | 9.93 |
表 5:不同跨步量下 unigram 与 bigram 输出的 WER。模型含 1 层一维不变卷积、7 层循环、1 层全连接;均有 BatchNorm、SortaGrad,约 3500 万参数。在有无 5-gram 语言模型的开发集上比较。
3.7 Row Convolution and Unidirectional Models
3.7 行卷积与单向模型
Bidirectional RNN models are challenging to deploy in an online, low-latency setting, because they are built to operate on an entire sample, and so it is not possible to perform the transcription process as the utterance streams from the user. We have found an unidirectional architecture that performs as well as our bidirectional models. This allows us to use unidirectional, forward-only RNN layers in our deployment system.
双向 RNN 模型难以部署到在线低延迟场景:它们设计为处理整段样本,因而无法在用户流式输入话语时同步转写。我们找到与双向模型表现相当的单向架构,从而可在部署系统中使用仅前向的单向 RNN 层。
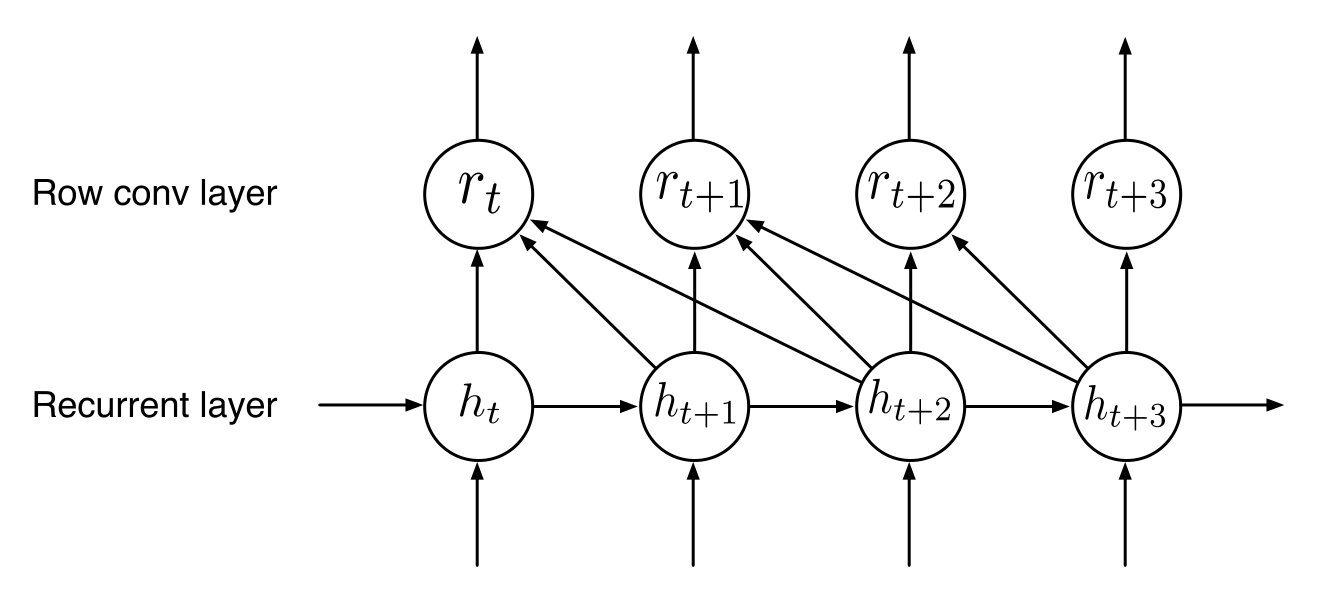
Figure 3: Row convolution architecture with future context size of 2
图 3:未来上下文大小为 2 的行卷积架构
To accomplish this, we employ a special layer that we call row convolution, shown in Figure 3. The intuition behind this layer is that we only need a small portion of future information to make an accurate prediction at the current time-step. Suppose at time-step , we use a future context of steps. We now have a feature matrix of size . We define a parameter matrix of the same size as . The activations for the new layer at time-step are
为此我们采用称为行卷积的特殊层,见图 3。直觉是:要在当前时间步做准确预测,只需一小段未来信息。设时间步 使用未来 步上下文,则有特征矩阵 ,尺寸 。定义与 同尺寸的参数矩阵 。新层在时间步 的激活 为
Since the convolution-like operation in Eq. 11 is row oriented for both and , we call this layer row convolution.
由于式 11 中的类卷积运算对 与 都是按行的,我们称该层为行卷积。
We place the row convolution layer above all recurrent layers. This has two advantages. First, this allows us to stream all computation below the row convolution layer on a finer granularity given little future context is needed. Second, this results in better CER compared to the best bidirectional model for Mandarin. We conjecture that the recurrent layers have learned good feature representations, so the row convolution layer simply gathers the appropriate information to feed to the classifier. Results for a unidirectional Mandarin speech system with row convolution and a comparison to a bidirectional model are given in Section 7 on deployment.
我们把行卷积层放在所有循环层之上。这有两点好处:其一,因所需未来上下文很少,行卷积以下的全部计算可以更细粒度流式进行;其二,相对最佳双向模型,普通话 CER 更好。我们猜想循环层已学到良好特征表示,行卷积层只需收集适当信息喂给分类器。带行卷积的单向普通话系统结果及其与双向模型的比较见第 7 节部署部分。
3.8 Language Model
3.8 语言模型
We train our RNN Models over millions of unique utterances, which enables the network to learn a powerful implicit language model. Our best models are quite adept at spelling, without any external language constraints. Further, in our development datasets we find many cases where our models can implicitly disambiguate homophones—for example, “he expects the Japanese agent to sell it for two hundred seventy five thousand dollars”. Nevertheless, the labeled training data is small compared to the size of unlabeled text corpora that are available. Thus we find that WER improves when we supplement our system with a language model trained from external text.
我们在数百万条独特话语上训练 RNN,使网络能学到强大的隐式语言模型。最佳模型在无外部语言约束时拼写已相当娴熟。开发集中还有许多能隐式消歧同音现象的例子——例如 “he expects the Japanese agent to sell it for two hundred seventy five thousand dollars”。不过,有标注训练数据相对可用的无标注文本语料仍偏小,因而在系统外再接从外部文本训练的语言模型时,WER 仍会改善。
We use an n-gram language model since they scale well to large amounts of unlabeled text [26]. For English, our language model is a Kneser-Ney smoothed 5-gram model with pruning that is trained using the KenLM toolkit [28] on cleaned text from the Common Crawl Repository[^3]. The vocabulary is the most frequently used 400,000 words from 250 million lines of text, which produces a language model with about 850 million n-grams. For Mandarin, the language model is a Kneser-Ney smoothed character level 5-gram model with pruning that is trained on an internal text corpus of 8 billion lines of text. This produces a language model with about 2 billion n-grams.
我们使用 n-gram 语言模型,因其能良好扩展到大规模无标注文本 [26]。英语语言模型是经剪枝的 Kneser-Ney 平滑 5-gram,用 KenLM 工具包 [28] 在 Common Crawl 仓库[^3] 清洗文本上训练。词表取 2.5 亿行文本中最高频的 40 万词,得到约 8.5 亿个 n-gram。普通话语言模型是经剪枝的 Kneser-Ney 平滑字符级 5-gram,在内部 80 亿行文本语料上训练,约含 20 亿个 n-gram。
During inference we search for the transcription that maximizes shown in Equation 12. This is a linear combination of probabilities from the CTC trained network and language model, along with a word insertion term [26].
推断时我们搜索使式 12 中 最大的转写 。这是 CTC 训练网络与语言模型的对数概率的线性组合,外加词插入项 [26]。
The weight controls the relative contributions of the language model and the CTC network. The weight encourages more words in the transcription. These parameters are tuned on a development set. We use a beam search to find the optimal transcription [27].
权重 控制语言模型与 CTC 网络的相对贡献;权重 鼓励转写中出现更多词。这些参数在开发集上调优。我们用束搜索寻找最优转写 [27]。
| Language | Architecture | Dev no LM | Dev LM | ||||
|---|---|---|---|---|---|---|---|
| English | 5-layer, 1 RNN | 27.79 | 14.39 | ||||
| English | 9-layer, 7 RNN | 14.93 | 9.52 | ||||
| Mandarin | 5-layer, 1 RNN | 9.80 | 7.13 | ||||
| Mandarin | 9-layer, 7 RNN | 7.55 | 5.81 |
Table 6: Comparison of WER for English and CER for Mandarin with and without a language model. These are simple RNN models with only one layer of 1D invariant convolution.
| 语言 | 架构 | Dev 无 LM | Dev 有 LM | ||||
|---|---|---|---|---|---|---|---|
| 英语 | 5 层,1 RNN | 27.79 | 14.39 | ||||
| 英语 | 9 层,7 RNN | 14.93 | 9.52 | ||||
| 普通话 | 5 层,1 RNN | 9.80 | 7.13 | ||||
| 普通话 | 9 层,7 RNN | 7.55 | 5.81 |
表 6:有无语言模型时英语 WER 与普通话 CER 比较。均为仅含一层一维不变卷积的简单 RNN 模型。
Table 6 shows that an external language model helps both English and Mandarin speech systems. The relative improvement given by the language model drops from 48% to 36% in English and 27% to 23% in Mandarin, as we go from a model with 5 layers and 1 recurrent layer to a model with 9 layers and 7 recurrent layers. We hypothesize that the network builds a stronger implicit language model with more recurrent layers.
表 6 显示外部语言模型对英语与普通话系统均有帮助。从 5 层(1 循环)到 9 层(7 循环),语言模型带来的相对提升在英语从 48% 降到 36%,普通话从 27% 降到 23%。我们假设循环层越多,网络构建的隐式语言模型越强。
The relative performance improvement from a language model is higher in English than in Mandarin. We attribute this to the fact that a Chinese character represents a larger block of information than an English character. For example, if we output directly to syllables or words in English, the model would make fewer spelling mistakes and the language model would likely help less.
语言模型带来的相对性能提升在英语高于普通话。我们将其归因于:一个汉字比一个英文字符承载更大信息块。例如,若英语直接输出到音节或词,模型拼写错误会更少,语言模型的帮助也可能更小。
3.9 Adaptation to Mandarin
3.9 适配普通话
The techniques that we have described so far can be used to build an end-to-end Mandarin speech recognition system that outputs Chinese characters directly. This precludes the need to construct a pronunciation model, which is often a fairly involved component for porting speech systems to other languages [59]. Direct output to characters also precludes the need to explicitly model language specific pronunciation features. For example we do not need to model Mandarin tones explicitly, as some speech systems must do [59, 45].
至此所述技术可用于构建直接输出汉字的端到端普通话语音识别系统,从而无需构造发音模型——后者往往是把语音系统移植到其他语言时相当繁琐的组件 [59]。直接输出到字符也无需显式建模语言特定发音特征。例如,我们不必像某些系统那样显式建模普通话声调 [59, 45]。
The only architectural changes we make to our networks are due to the characteristics of the Chinese character set. Firstly, the output layer of the network outputs about 6000 characters, which includes the Roman alphabet, since hybrid Chinese-English transcripts are common. We incur an out of vocabulary error at evaluation time if a character is not contained in this set. This is not a major concern, as our test set has only 0.74% out of vocab characters.
对网络唯一的架构改动来自汉字集特性。首先,输出层约输出 6000 个字符,其中含罗马字母,因中英混杂转写常见。评估时若字符不在该集合中会产生未登录词错误;这并非大问题,测试集仅有 0.74% 未登录字符。
We use a character level language model in Mandarin as words are not usually segmented in text. The word insertion term of Equation 12 becomes a character insertion term. In addition, we find that the performance of the beam search during decoding levels off at a smaller beam size. This allows us to use a beam size of 200 with a negligible degradation in CER. In Section 6.2, we show that our Mandarin speech models show roughly the same improvements to architectural changes as our English speech models.
因文本通常不分词,普通话使用字符级语言模型。式 12 的词插入项变为字符插入项。此外,解码时束搜索性能在较小束宽即趋于平稳,使我们可用束宽 200 且 CER 几乎不降。第 6.2 节表明,普通话模型对架构改动的改善幅度与英语模型大致相当。
4 System Optimizations
4 系统优化
Our networks have tens of millions of parameters, and the training algorithm takes tens of single-precision exaFLOPs to converge. Since our ability to evaluate hypotheses about our data and models depends on the ability to train models quickly, we built a highly optimized training system. This system has two main components—a deep learning library written in C++, along with a high-performance linear algebra library written in both CUDA and C++. Our optimized software, running on dense compute nodes with 8 Titan X GPUs per node, allows us to sustain 24 single-precision teraFLOP/second when training a single model on one node. This is of the theoretical peak computational throughput of each node. We also can scale to multiple nodes, as outlined in the next subsection.
我们的网络有数千万参数,训练算法收敛需数十单精度 exaFLOP。评估关于数据与模型的假设取决于能否快速训练,因此我们构建了高度优化的训练系统。系统有两大组件:用 C++ 编写的深度学习库,以及用 CUDA 与 C++ 编写的高性能线性代数库。优化软件运行在每节点 8 块 Titan X GPU 的高密度计算节点上,单节点训练单个模型可持续约 24 单精度 teraFLOP/秒,约为每节点理论峰值吞吐的 。如下小节所述,也可扩展到多节点。
4.1 Scalability and Data-Parallelism
4.1 可扩展性与数据并行
We use the standard technique of data-parallelism to train on multiple GPUs using synchronous SGD. Our most common configuration uses a minibatch of on GPUs. Our training pipeline binds one process to each GPU. These processes then exchange gradient matrices during the backpropagation by using all-reduce, which exchanges a matrix between multiple processes and sums the result so that at the end, each process has a copy of the sum of all matrices from all processes.
我们用标准数据并行技术,以同步 SGD 在多 GPU 上训练。最常见配置是 8 GPU 上小批量 。训练流水线把每个进程绑定到一块 GPU;反向传播时这些进程通过 all-reduce 交换梯度矩阵:在多进程间交换矩阵并求和,使每个进程最终都拥有所有矩阵之和的副本。
We find synchronous SGD useful because it is reproducible and deterministic. We have found that the appearance of non-determinism in our system often signals a serious bug, and so having reproducibility as a goal has greatly facilitates debugging. In contrast, asynchronous methods such as asynchronous SGD with parameter servers as found in Dean et al. [18] typically do not provide reproducibility and are therefore more difficult to debug. Synchronous SGD is simple to understand and implement. It scales well as we add multiple nodes to the training process.
我们发现同步 SGD 有用,因其可复现、确定。系统中出现非确定性往往意味着严重缺陷,以可复现为目标极大便利了调试。相比之下,Dean 等人 [18] 中带参数服务器的异步 SGD 等方法通常不可复现,因而更难调试。同步 SGD 易于理解与实现,随训练加入更多节点也能良好扩展。
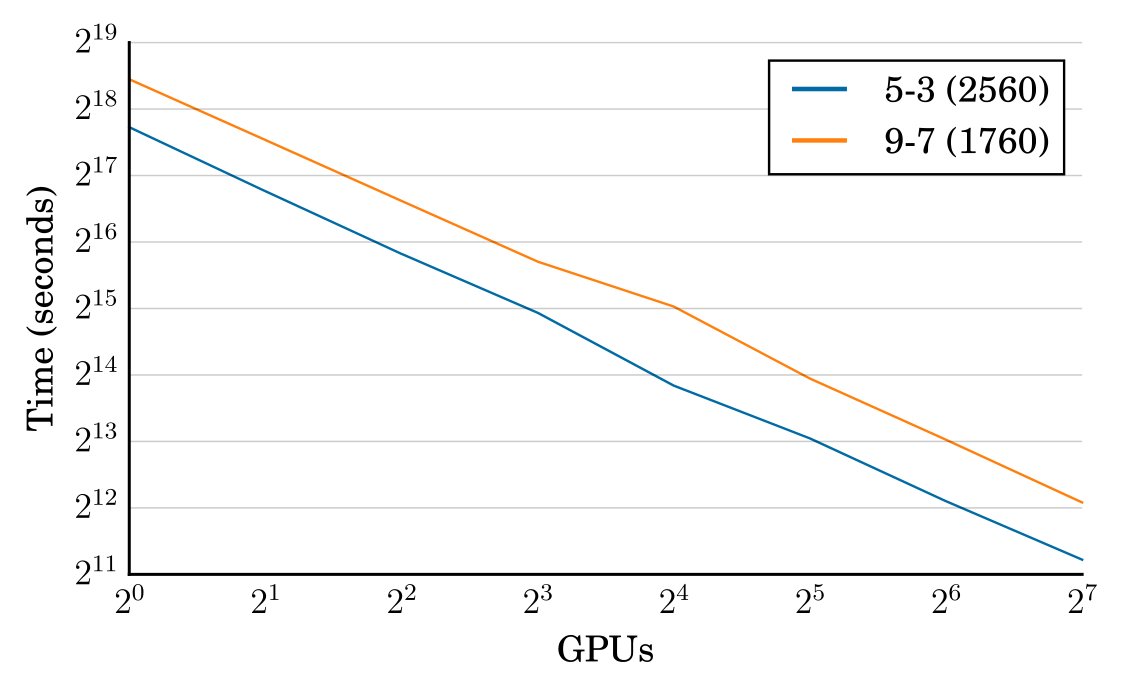
Figure 4: Scaling comparison of two networks—a 5 layer model with 3 recurrent layers containing 2560 hidden units in each layer and a 9 layer model with 7 recurrent layers containing 1760 hidden units in each layer. The times shown are to train 1 epoch. The 5 layer model trains faster because it uses larger matrices and is more computationally efficient.
图 4:两个网络的扩展性比较——5 层模型含 3 层循环、每层 2560 隐单元;9 层模型含 7 层循环、每层 1760 隐单元。所示时间为训练 1 个 epoch。5 层模型因矩阵更大、计算效率更高而训练更快。
Figure 4 shows that time taken to train one epoch halves as we double the number of GPUs that we train on, thus achieving near-linear weak scaling. We keep the minibatch per GPU constant at 64 during this experiment, effectively doubling the minibatch as we double the number of GPUs. Although we have the ability to scale to large minibatches, we typically use either 8 or 16 GPUs during training with a minibatch of 512 or 1024, in order to converge to the best result.
图 4 显示,训练所用 GPU 数加倍时,一个 epoch 的时间约减半,接近线性弱扩展。实验中每 GPU 小批量保持 64,等效于 GPU 加倍时小批量加倍。尽管能扩展到大批量,为收敛到最佳结果,训练时通常用 8 或 16 GPU,小批量 512 或 1024。
Since all-reduce is critical to the scalability of our training, we wrote our own implementation of the ring algorithm [48, 65] for higher performance and better stability. Our implementation avoids extraneous copies between CPU and GPU, and is fundamental to our scalability. We configure OpenMPI with the smcuda transport that can send and receive buffers residing in the memory of two different GPUs by using GPUDirect. When two GPUs are in the same PCI root complex, this avoids any unnecessary copies to CPU memory. This also takes advantage of tree-structured interconnects by running multiple segments of the ring concurrently between neighboring devices. We built our implementation using MPI send and receive, along with CUDA kernels for the element-wise operations.
由于 all-reduce 对训练可扩展性至关重要,我们自行实现了环算法 [48, 65] 以获得更高性能与更好稳定性。实现避免 CPU 与 GPU 间多余拷贝,是可扩展性的基础。我们配置 OpenMPI 使用 smcuda 传输,通过 GPUDirect 收发驻留在不同 GPU 内存中的缓冲区。当两块 GPU 在同一 PCI 根复合体时,可避免不必要的 CPU 内存拷贝。实现还利用树状互连,在相邻设备间并发运行环的多段。实现基于 MPI 发送/接收与用于逐元素运算的 CUDA 核。
Table 7 compares the performance of our all-reduce implementation with that provided by OpenMPI version 1.8.5. We report the time spent in all-reduce for a full training run that ran for one epoch on our English dataset using a 5 layer, 3 recurrent layer architecture with hidden units for all layers. In this table, we use a minibatch of 64 per GPU, expanding the algorithmic minibatch as we scale to more GPUs. We see that our implementation is considerably faster than OpenMPI’s when the communication is within a node (8 GPUs or less). As we increase the number of GPUs and increase the amount of inter-node communication, the gap shrinks, although our implementation is still 2-4X faster.
表 7 比较我们的 all-reduce 实现与 OpenMPI 1.8.5。我们报告在英语数据集上用 5 层(3 循环、每层 隐单元)架构训练完整一个 epoch 时花在 all-reduce 上的时间。表中每 GPU 小批量 64,随 GPU 增多扩大算法小批量。节点内通信(8 GPU 及以下)时我们的实现明显快于 OpenMPI;随 GPU 增多、节点间通信增加,差距缩小,但仍快约 2–4 倍。
| GPU | OpenMPI | Our | Performance | ||||||
|---|---|---|---|---|---|---|---|---|---|
| all-reduce | all-reduce | Gain | |||||||
| 4 | 55359.1 | 2587.4 | 21.4 | ||||||
| 8 | 48881.6 | 2470.9 | 19.8 | ||||||
| 16 | 21562.6 | 1393.7 | 15.5 | ||||||
| 32 | 8191.8 | 1339.6 | 6.1 | ||||||
| 64 | 1395.2 | 611.0 | 2.3 | ||||||
| 128 | 1602.1 | 422.6 | 3.8 |
Table 7: Comparison of two different all-reduce implementations. All times are in seconds. Performance gain is the ratio of OpenMPI all-reduce time to our all-reduce time.
| GPU | OpenMPI | 我们的 | 性能 | ||||||
|---|---|---|---|---|---|---|---|---|---|
| all-reduce | all-reduce | 增益 | |||||||
| 4 | 55359.1 | 2587.4 | 21.4 | ||||||
| 8 | 48881.6 | 2470.9 | 19.8 | ||||||
| 16 | 21562.6 | 1393.7 | 15.5 | ||||||
| 32 | 8191.8 | 1339.6 | 6.1 | ||||||
| 64 | 1395.2 | 611.0 | 2.3 | ||||||
| 128 | 1602.1 | 422.6 | 3.8 |
表 7:两种 all-reduce 实现比较。时间单位为秒。性能增益为 OpenMPI all-reduce 时间与我们的 all-reduce 时间之比。
All of our training runs use either 8 or 16 GPUs, and in this regime, our all-reduce implementation results in faster training for the full training run, compared to using OpenMPI directly. Optimizing all-reduce has thus resulted in important productivity benefits for our experiments, and has made our simple synchronous SGD approach scalable.
全部训练运行使用 8 或 16 GPU;在此区间,相对直接使用 OpenMPI,我们的 all-reduce 使完整训练运行快约 。优化 all-reduce 因而为实验带来重要生产力收益,并使简单的同步 SGD 方法可扩展。
4.2 GPU implementation of CTC loss function
4.2 CTC 损失函数的 GPU 实现
Calculating the CTC loss function is more complicated than performing forward and back propagation on our RNN architectures. Originally, we transferred activations from the GPUs to the CPU, where we calculated the loss function using an OpenMP parallelized implementation of CTC. However, this implementation limited our scalability rather significantly, for two reasons. Firstly, it became computationally more significant as we improved efficiency and scalability of the RNN itself. Secondly, transferring large activation matrices between CPU and GPU required us to spend interconnect bandwidth for CTC, rather than on transferring gradient matrices to allow us to scale using data parallelism to more processors.
计算 CTC 损失比在我们的 RNN 架构上做前向与反向传播更复杂。原先我们把激活从 GPU 传到 CPU,用 OpenMP 并行的 CTC 实现计算损失。该实现显著限制可扩展性,原因有二:其一,随着 RNN 本身效率与可扩展性提升,CTC 计算在整体中变得更突出;其二,在 CPU 与 GPU 间传输大激活矩阵会占用互连带宽做 CTC,而非传输梯度矩阵以通过数据并行扩展到更多处理器。
To overcome this, we wrote a GPU implementation of the CTC loss function. Our parallel implementation relies on a slight refactoring to simplify the dependences in the CTC calculation, as well as the use of optimized parallel sort implementations from ModernGPU [5]. We give more details of this parallelization in the Appendix.
为克服这一点,我们编写了 CTC 损失的 GPU 实现。并行实现依赖轻微重构以简化 CTC 计算中的依赖,并使用 ModernGPU [5] 的优化并行排序实现。并行化细节见附录。
| Language | Architecture | CPU CTC Time | GPU CTC Time | Speedup |
|---|---|---|---|---|
| English | 5-layer, 3 RNN | 5888.12 | 203.56 | 28.9 |
| Mandarin | 5-layer, 3 RNN | 1688.01 | 135.05 | 12.5 |
Table 8: Comparison of time spent in seconds in computing the CTC loss function and gradient in one epoch for two different implementations. Speedup is the ratio of CPU CTC time to GPU CTC time.
| 语言 | 架构 | CPU CTC 时间 | GPU CTC 时间 | 加速比 |
|---|---|---|---|---|
| 英语 | 5 层,3 RNN | 5888.12 | 203.56 | 28.9 |
| 普通话 | 5 层,3 RNN | 1688.01 | 135.05 | 12.5 |
表 8:两种实现对一个 epoch 中计算 CTC 损失与梯度所花秒数的比较。加速比为 CPU CTC 时间与 GPU CTC 时间之比。
Table 8 compares the performance of two CTC implementations. The GPU implementation saves us 95 minutes per epoch in English, and 25 minutes in Mandarin. This reduces overall training time by 10-20%, which is also an important productivity benefit for our experiments.
表 8 比较两种 CTC 实现的性能。GPU 实现每个 epoch 为英语节省约 95 分钟、普通话约 25 分钟,使总训练时间减少 10–20%,对实验生产力同样重要。
4.3 Memory allocation
4.3 内存分配
Our system makes frequent use of dynamic memory allocations to GPU and CPU memory, mainly to store activation data for variable length utterances, and for intermediate results. Individual allocations can be very large; over 1 GB for the longest utterances. For these very large allocations we found that CUDA’s memory allocator and even std::malloc introduced significant overhead into our application—over a 2x slowdown from using std::malloc in some cases. This is because both cudaMalloc and std::malloc forward very large allocations to the operating system or GPU driver to update the system page tables. This is a good optimization for systems running multiple applications, all sharing memory resources, but editing page tables is pure overhead for our system where nodes are dedicated entirely to running a single model. To get around this limitation, we wrote our own memory allocator for both CPU and GPU allocations. Our implementation follows the approach of the last level shared allocator in jemalloc: all allocations are carved out of contiguous memory blocks using the buddy algorithm [34]. To avoid fragmentation, we preallocate all of GPU memory at the start of training and subdivide individual allocations from this block. Similarly, we set the CPU memory block size that we forward to mmap to be substantially larger than std::malloc, at 12GB.
系统频繁向 GPU 与 CPU 内存做动态分配,主要用于存储变长话语的激活与中间结果。单次分配可能很大:最长话语超过 1 GB。对这些超大分配,我们发现 CUDA 内存分配器乃至 std::malloc 都会引入显著开销——某些情形下仅 std::malloc 就造成超过 2 倍减速。因为 cudaMalloc 与 std::malloc 都会把很大分配转发给操作系统或 GPU 驱动以更新系统页表;这对运行多个共享内存资源应用的系统是好优化,但在节点专用于跑单个模型的系统中,改页表纯属开销。为绕过限制,我们为 CPU 与 GPU 分配编写了自己的分配器,做法跟随 jemalloc 末级共享分配器:用 buddy 算法 [34] 从连续内存块切出所有分配。为避免碎片,训练开始时预分配全部 GPU 内存再从中细分;CPU 内存块通过 mmap 转发的尺寸也远大于 std::malloc,取 12GB。
Most of the memory required for training deep recurrent networks is used to store activations through each layer for use by back propagation, not to store the parameters of the network. For example, storing the weights for a 70M parameter network with 9 layers requires approximately 280 MB of memory, but storing the activations for a batch of 64, seven-second utterances requires 1.5 GB of memory. TitanX GPUs include 12GB of GDDR5 RAM, and sometimes very deep networks can exceed the GPU memory capacity when processing long utterances. This can happen unpredictably, especially when the distribution of utterance lengths includes outliers, and it is desirable to avoid a catastrophic failure when this occurs. When a requested memory allocation exceeds available GPU memory, we allocate page-locked GPU-memory-mapped CPU memory using cudaMallocHost instead. This memory can be accessed directly by the GPU by forwarding individual memory transactions over PCIe at reduced bandwidth, and it allows a model to continue to make progress even after encountering an outlier.
训练深度循环网络所需内存,大部分用于为反向传播存储各层激活,而非存储网络参数。例如,存储 9 层、7000 万参数网络的权重约需 280 MB,而存储批量 64、每条 7 秒话语的激活约需 1.5 GB。TitanX GPU 有 12GB GDDR5,处理很长话语时很深网络有时会超出 GPU 容量。这可能不可预期地发生,尤其当话语长度分布含离群点时;希望发生时避免灾难性失败。当请求分配超过可用 GPU 内存时,我们改用 cudaMallocHost 分配页锁定、GPU 内存映射的 CPU 内存。GPU 可通过 PCIe 以较低带宽直接访问该内存,使模型在遇到离群点后仍能继续推进。
The combination of fast memory allocation with a fallback mechanism that allows us to slightly overflow available GPU memory in exceptional cases makes the system significantly simpler, more robust, and more efficient.
快速内存分配与允许在例外情形轻微溢出可用 GPU 内存的回退机制相结合,使系统显著更简单、更稳健、更高效。
5 Training Data
5 训练数据
Large-scale deep learning systems require an abundance of labeled training data. We have collected an extensive training dataset for both English and Mandarin speech models, in addition to augmenting our training with publicly available datasets. In English we use 11,940 hours of labeled speech data containing 8 million utterances summarized in Table 9. For the Mandarin system we use 9,400 hours of labeled audio containing 11 million utterances. The Mandarin speech data consists of internal Baidu corpora, representing a mix of read speech and spontaneous speech, in both standard Mandarin and accented Mandarin.
大规模深度学习系统需要充足有标注训练数据。除用公开数据集增强外,我们为英语与普通话语音模型采集了广泛训练集。英语使用含 800 万条话语、共 11,940 小时的有标注语音,汇总见表 9。普通话系统使用含 1100 万条话语、共 9,400 小时的有标注音频,数据来自百度内部语料,混合朗读与自发语音,既有标准普通话也有带口音普通话。
| Dataset | Speech Type | Hours |
|---|---|---|
| WSJ | read | 80 |
| Switchboard | conversational | 300 |
| Fisher | conversational | 2000 |
| LibriSpeech | read | 960 |
| Baidu | read | 5000 |
| Baidu | mixed | 3600 |
| Total | 11940 |
Table 9: Summary of the datasets used to train DS2 in English. The Wall Street Journal (WSJ), Switchboard and Fisher [13] corpora are all published by the Linguistic Data Consortium. The LibriSpeech dataset [46] is available free on-line. The other datasets are internal Baidu corpora.
| 数据集 | 语音类型 | 小时 |
|---|---|---|
| WSJ | 朗读 | 80 |
| Switchboard | 对话 | 300 |
| Fisher | 对话 | 2000 |
| LibriSpeech | 朗读 | 960 |
| Baidu | 朗读 | 5000 |
| Baidu | 混合 | 3600 |
| 合计 | 11940 |
表 9:英语 DS2 训练所用数据集汇总。华尔街日报(WSJ)、Switchboard 与 Fisher [13] 语料均由语言数据联盟发布。LibriSpeech [46] 可免费在线获取。其余为百度内部语料。
5.1 Dataset Construction
5.1 数据集构建
Some of the internal English (3,600 hours) and Mandarin (1,400 hours) datasets were created from raw data captured as long audio clips with noisy transcriptions. The length of these clips ranged from several minutes to more than hour, making it impractical to unroll them in time in the RNN during training. To solve this problem, we developed an alignment, segmentation and filtering pipeline that can generate a training set with shorter utterances and few erroneous transcriptions.
部分内部英语(3,600 小时)与普通话(1,400 小时)数据集由原始长音频片段与带噪声转写生成。片段长度从数分钟到超过一小时,训练时在 RNN 中按时间展开不现实。为此我们开发了对齐、切分与过滤流水线,可生成话语更短、错误转写更少的训练集。
The first step in the pipeline is to use an existing bidirectional RNN model trained with CTC to align the transcription to the frames of audio. For a given audio-transcript pair, , we find the alignment that maximizes
流水线第一步是用已有、经 CTC 训练的双向 RNN 模型,把转写对齐到音频帧。对给定音频–转写对 ,我们寻找最大化下述量的对齐
This is essentially a Viterbi alignment found using a RNN model trained with CTC. Since Equation 9 integrates over the alignment, the CTC loss function is never explicitly asked to produce an accurate alignment. In principle, CTC could choose to emit all the characters of the transcription after some fixed delay and this can happen with unidirectional RNNs [54]. However, we found that CTC produces an accurate alignment when trained with a bidirectional RNN.
这本质上是用 CTC 训练的 RNN 做 Viterbi 对齐。由于式 9 对对齐积分,CTC 损失从未被显式要求产生精确对齐。原则上 CTC 可选择在某固定延迟后发出转写全部字符,单向 RNN 上可能发生 [54]。但我们发现用双向 RNN 训练时 CTC 能产生精确对齐。
Following the alignment is a segmentation step that splices the audio and the corresponding aligned transcription whenever it encounters a long series of consecutive blank labels occurs, since this usually denotes a stretch of silence. By tuning the number of consecutive blanks, we can tune the length of the utterances generated. For the English speech data, we also require a space token to be within the stretch of blanks in order to segment only on word boundaries. We tune the segmentation to generate utterances that are on average 7 seconds long.
对齐之后是切分步:每当遇到一长串连续 blank 标签(通常表示一段静音),就切开音频与对应已对齐转写。通过调节连续 blank 数量可调节生成话语长度。英语语音数据还要求 space 标记落在 blank 段内,以便只在词边界切分。我们把切分调到平均约 7 秒一条话语。
The final step in the pipeline removes erroneous examples that arise from a failed alignment. We crowd source the ground truth transcriptions for several thousand examples. The word level edit distance between the ground truth and the aligned transcription is used to produce a good or bad label. The threshold for the word level edit distance is chosen such that the resulting WER of the good portion of the development set is less than 5%. We then train a linear classifier to accurately predict bad examples given the input features generated from the speech recognizer. We find the following features useful: the raw CTC cost, the CTC cost normalized by the sequence length, the CTC cost normalized by the transcript length, the ratio of the sequence length to the transcript length, the number of words in the transcription and the number of characters in the transcription. For the English dataset, we find that the filtering pipeline reduces the WER from 17% to 5% while retaining more than 50% of the examples.
流水线最后一步去掉对齐失败产生的错误样本。我们众包数千例的真值转写,用真值与对齐转写之间的词级编辑距离打上 好 或 坏 标签。词级编辑距离阈值选得使开发集 好 部分的 WER 低于 5%。再用线性分类器,根据语音识别器生成的输入特征准确预测坏例。有用特征包括:原始 CTC 代价、按序列长度归一化的 CTC 代价、按转写长度归一化的 CTC 代价、序列长度与转写长度之比、转写词数与字符数。英语数据集上,过滤流水线把 WER 从 17% 降到 5%,同时保留超过 50% 的样本。
5.2 Data Augmentation
5.2 数据增强
We augment our training data by adding noise to increase the effective size of our training data and to improve our robustness to noisy speech [26]. Although the training data contains some intrinsic noise, we can increase the quantity and variety of noise through augmentation. Too much noise augmentation tends to make optimization difficult and can lead to worse results, and too little noise augmentation makes the system less robust to low signal-to-noise speech. We find that a good balance is to add noise to 40% of the utterances that are chosen at random. The noise source consists of several thousand hours of randomly selected audio clips combined to produce hundreds of hours of noise.
我们通过加噪声增强训练数据,以增大有效训练集规模并提高对噪声语音的稳健性 [26]。尽管训练数据已含内在噪声,增强仍可增加噪声数量与种类。噪声增强过多会使优化困难、结果变差;过少则系统对低信噪比语音不够稳健。我们发现较好平衡是对随机选取的 40% 话语加噪声。噪声源由数千小时随机选取的音频片段混合而成,产生数百小时噪声。
5.3 Scaling Data
5.3 数据规模缩放
Our English and Mandarin corpora are substantially larger than those commonly reported in speech recognition literature. In Table 10, we show the effect of increasing the amount of labeled training data on WER. This is done by randomly sampling the full dataset before training. For each dataset, the model was trained for up to 20 epochs though usually early-stopped based on the error on a held out development set. We note that the WER decreases with a power law for both the regular and noisy development sets. The WER decreases by 40% relative for each factor of 10 increase in training set size. We also observe a consistent gap in WER (60% relative) between the regular and noisy datasets, implying that more data benefits both cases equally.
我们的英语与普通话语料显著大于语音识别文献中常报告的规模。表 10 显示增加有标注训练数据量对 WER 的影响:训练前对全集随机抽样。每个子集最多训练 20 个 epoch,通常按留出开发集误差早停。我们注意到常规与噪声开发集上 WER 均呈幂律下降:训练集规模每增大 10 倍,WER 相对约降 40%。常规与噪声集之间还存在一致的 WER 差距(相对约 60%),说明更多数据对两种情形同等有益。
This implies that a speech system will continue to improve with more labeled training data. We hypothesize that equally as important as increasing raw number of hours is increasing the number of speech contexts that are captured in the dataset. A context can be any property that makes speech unique including different speakers, background noise, environment, and microphone hardware. While we do not have the labels needed to validate this claim, we suspect that measuring WER as a function of speakers in the dataset would lead to much larger relative gains than simple random sampling.
这意味着语音系统会随更多有标注训练数据继续改善。我们假设:与增加原始小时数同等重要的是增加数据集所捕获的语音情境数量。情境可以是使语音独特的任何属性,包括不同说话人、背景噪声、环境与麦克风硬件。虽无标签验证该说法,但我们怀疑把 WER 作为数据集中说话人数的函数来度量,会比简单随机抽样带来更大的相对收益。
| Fraction of Data | Hours | Regular Dev | Noisy Dev | ||||||
|---|---|---|---|---|---|---|---|---|---|
| 1% | 120 | 29.23 | 50.97 | ||||||
| 10% | 1200 | 13.80 | 22.99 | ||||||
| 20% | 2400 | 11.65 | 20.41 | ||||||
| 50% | 6000 | 9.51 | 15.90 | ||||||
| 100% | 12000 | 8.46 | 13.59 |
Table 10: Comparison of English WER for Regular and Noisy development sets on increasing training dataset size. The architecture is a 9-layer model with 2 layers of 2D-invariant convolution and 7 recurrent layers with 68M parameters.
| 数据比例 | 小时 | 常规 Dev | 噪声 Dev | ||||||
|---|---|---|---|---|---|---|---|---|---|
| 1% | 120 | 29.23 | 50.97 | ||||||
| 10% | 1200 | 13.80 | 22.99 | ||||||
| 20% | 2400 | 11.65 | 20.41 | ||||||
| 50% | 6000 | 9.51 | 15.90 | ||||||
| 100% | 12000 | 8.46 | 13.59 |
表 10:增大训练集规模时英语常规与噪声开发集 WER 比较。架构为 9 层模型,含 2 层二维不变卷积与 7 层循环,6800 万参数。
6 Results
6 结果
To better assess the real-world applicability of our speech system, we evaluate on a wide range of test sets. We use several publicly available benchmarks and several test sets collected internally. Together these test sets represent a wide range of challenging speech environments including low signal-to-noise ratios (noisy and far-field), accented, read, spontaneous and conversational speech.
为更好评估语音系统的现实适用性,我们在广泛测试集上评估。使用若干公开基准与若干内部采集测试集,共同覆盖低信噪比(噪声与远场)、口音、朗读、自发与对话语音等挑战环境。
All models are trained for 20 epochs on either the full English dataset, described in Table 9, or the full Mandarin dataset described in Section 5. We use stochastic gradient descent with Nesterov momentum [61] along with a minibatch of 512 utterances. If the norm of the gradient exceeds a threshold of 400, it is rescaled to 400 [47]. The model which performs the best on a held-out development set during training is chosen for evaluation. The learning rate is chosen from to yield fastest convergence and annealed by a constant factor of 1.2 after each epoch. We use a momentum of 0.99 for all models.
所有模型在表 9 所述完整英语数据集或第 5 节所述完整普通话数据集上训练 20 个 epoch。使用带 Nesterov 动量 [61] 的随机梯度下降,小批量 512 条话语。若梯度范数超过 400,则缩放到 400 [47]。训练期间在留出开发集上表现最佳的模型用于评估。学习率从 中选取以使收敛最快,每个 epoch 后按常数因子 1.2 退火。所有模型动量取 0.99。
The language models used are those described in Section 3.8. The decoding parameters from Equation 12 are tuned on a held-out development set. We use a beam size of 500 for the English decoder and a beam size of 200 for the Mandarin decoder.
所用语言模型见第 3.8 节。式 12 的解码参数在留出开发集上调优。英语解码器束宽 500,普通话束宽 200。
6.1 English
6.1 英语
The best DS2 model has 11 layers with 3 layers of 2D convolution, 7 bidirectional recurrent layers, a fully-connected output layer along with Batch Normalization. The first layer outputs to bigrams with a temporal stride of 3. By comparison the DS1 model has 5 layers with a single bidirectional recurrent layer and it outputs to unigrams with a temporal stride of 2 in the first layer. We report results on several test sets for both the DS2 and DS1 model. We do not tune or adapt either model to any of the speech conditions in the test sets. Language model decoding parameters are set once on a held-out development set.
最佳 DS2 模型共 11 层:3 层二维卷积、7 层双向循环、一层全连接输出,并含批归一化。第一层以时间 stride 3 输出到 bigram。相比之下,DS1 模型 5 层、仅一层双向循环,第一层以时间 stride 2 输出到 unigram。我们在若干测试集上报告 DS2 与 DS1 结果。不对任一模型针对测试集语音条件做调优或自适应;语言模型解码参数仅在留出开发集上设定一次。
To put the performance of our system in context, we benchmark most of our results against human workers, since speech recognition is an audio perception and language understanding problem that humans excel at. We obtain a measure of human level performance by paying workers from Amazon Mechanical Turk to hand-transcribe all of our test sets. Two workers transcribe the same audio clip, that is typically about 5 seconds long, and we use the better of the two transcriptions for the final WER calculation. They are free to listen to the audio clip as many times as they like. These workers are mostly based in the United States, and on average spend about 27 seconds per transcription. The hand-transcribed results are compared to the existing ground truth to produce a WER. While the existing ground truth transcriptions do have some label error, this is rarely more than 1%. This implies that disagreement between the ground truth transcripts and the human level transcripts is a good heuristic for human level performance.
为把系统表现放进语境,多数结果对照人工标注员:语音识别是人类擅长的听觉感知与语言理解问题。我们付费请 Amazon Mechanical Turk 工人手写转写全部测试集,以衡量人类水平。两条工人转写同一段通常约 5 秒的音频,最终 WER 取二者较好者;他们可任意多次回听。工人多在美国,平均每条转写约花 27 秒。手写结果与现有真值比较得到 WER。现有真值转写虽有标签误差,但很少超过 1%。因此真值与人类水平转写之间的分歧,是人类水平表现的良好启发量。
6.1.1 Model Size
Our English speech training set is substantially larger than the size of commonly used speech datasets. Furthermore, the data is augmented with noise synthesis. To get the best generalization error, we expect that the model size must increase to fully exploit the patterns in the data. In Section 3.2 we explored the effect of model depth while fixing the number of parameters. In contrast, here we show the effect of varying model size on the performance of the speech system. We only vary the size of each layer, while keeping the depth and other architectural parameters constant. We evaluate the models on the same Regular and Noisy development sets that we use in Section 3.5.
6.1.1 模型规模
英语语音训练集显著大于常用语音数据集,并经噪声合成增强。为获得最佳泛化误差,预期必须增大模型规模以充分挖掘数据中的模式。第 3.2 节在固定参数量下探索了模型深度;此处相反,展示改变模型规模对语音系统性能的影响。我们只改变每层大小,深度与其他架构参数保持不变。评估集与第 3.5 节相同的常规与噪声开发集。
| Model size | Model type | Regular Dev | Noisy Dev | ||||
|---|---|---|---|---|---|---|---|
| GRU | 10.59 | 21.38 | |||||
| GRU | 9.06 | 17.07 | |||||
| GRU | 8.54 | 15.98 | |||||
| RNN | 8.44 | 15.09 | |||||
| GRU | 7.78 | 14.17 | |||||
| RNN | 7.73 | 13.06 |
Table 11: Comparing the effect of model size on the WER of the English speech system on both the regular and noisy development sets. We vary the number of hidden units in all but the convolutional layers. The GRU model has 3 layers of bidirectional GRUs with 1 layer of 2D-invariant convolution. The RNN model has 7 layers of bidirectional simple recurrence with 3 layers of 2D-invariant convolution. Both models output bigrams with a temporal stride of 3. All models contain approximately 35 million parameters and are trained with BatchNorm and SortaGrad.
| 模型规模 | 模型类型 | 常规 Dev | 噪声 Dev | ||||
|---|---|---|---|---|---|---|---|
| GRU | 10.59 | 21.38 | |||||
| GRU | 9.06 | 17.07 | |||||
| GRU | 8.54 | 15.98 | |||||
| RNN | 8.44 | 15.09 | |||||
| GRU | 7.78 | 14.17 | |||||
| RNN | 7.73 | 13.06 |
表 11:模型规模对英语语音系统在常规与噪声开发集 WER 的影响。除卷积层外改变隐单元数。GRU 模型含 3 层双向 GRU 与 1 层二维不变卷积;RNN 模型含 7 层双向简单循环与 3 层二维不变卷积。二者均以时间 stride 3 输出 bigram。约 3500 万参数表述有误——表中规模从 1800 万到 1 亿不等;均用 BatchNorm 与 SortaGrad 训练。
The models in Table 11 differ from those in Table 3 in that we increase the the stride to 3 and output to bigrams. Because we increase the model size to as many as 100 million parameters, we find that an increase in stride is necessary for fast computation and memory constraints. However, in this regime we note that the performance advantage of the GRU networks appears to diminish over the simple RNN. In fact, for the 100 million parameter networks the simple RNN performs better than the GRU network and is faster to train despite the 2 extra layers of convolution.
表 11 中的模型与表 3 不同之处在于把 stride 增到 3 并输出到 bigram。因模型规模增至多达 1 亿参数,我们发现增大 stride 对快速计算与内存约束有必要。但在此区间,GRU 相对简单 RNN 的性能优势似乎减弱。事实上,对 1 亿参数网络,简单 RNN 优于 GRU,且尽管多两层卷积,训练仍更快。
Table 11 shows that the performance of the system improves consistently up to 100 million parameters. All further English DS2 results are reported with this same 100 million parameter RNN model since it achieves the lowest generalization errors.
表 11 显示系统性能持续改善直至 1 亿参数。此后全部英语 DS2 结果均用同一 1 亿参数 RNN 模型报告,因其泛化误差最低。
Table 12 shows that the 100 million parameter RNN model (DS2) gives a 43.4% relative improvement over the 5-layer model with 1 recurrent layer (DS1) on an internal Baidu dataset of 3,300 utterances that contains a wide variety of speech including challenging accents, low signal-to-noise ratios from far-field or background noise, spontaneous and conversational speech.
表 12 显示,在含 3300 条话语、覆盖口音、远场或背景噪声导致的低信噪比、自发与对话语音的内部百度测试集上,1 亿参数 RNN 模型(DS2)相对 5 层、1 循环层模型(DS1)相对改善 43.4%。
| Test set | DS1 | DS2 |
|---|---|---|
| Baidu Test | 24.01 | 13.59 |
Table 12: Comparison of DS1 and DS2 WER on an internal test set of 3,300 examples. The test set contains a wide variety of speech including accents, low signal-to-noise speech, spontaneous and conversational speech.
| 测试集 | DS1 | DS2 |
|---|---|---|
| Baidu Test | 24.01 | 13.59 |
表 12:DS1 与 DS2 在含 3300 例内部测试集上的 WER。测试集含口音、低信噪比、自发与对话等多样语音。
6.1.2 Read Speech
Read speech with high signal-to-noise ratio is arguably the easiest large vocabulary for a continuous speech recognition task. We benchmark our system on two test sets from the Wall Street Journal (WSJ) corpus of read news articles. These are available in the LDC catalog as LDC94S13B and LDC93S6B. We also take advantage of the recently developed LibriSpeech corpus constructed using audio books from the LibriVox project [46].
6.1.2 朗读语音
高信噪比朗读语音可以说是大词汇量连续语音识别中最容易的一类。我们在华尔街日报(WSJ)朗读新闻语料的两个测试集上评测,LDC 目录号为 LDC94S13B 与 LDC93S6B。也利用新近用 LibriVox 有声书构建的 LibriSpeech 语料 [46]。
Table 13 shows that the DS2 system outperforms humans in 3 out of the 4 test sets and is competitive on the fourth. Given this result, we suspect that there is little room for a generic speech system to further improve on clean read speech without further domain adaptation.
表 13 显示 DS2 在 4 个测试集中的 3 个上超过人类,在第 4 个上具有竞争力。据此我们怀疑:若不做进一步领域自适应,通用语音系统在干净朗读语音上几乎没有继续提升的空间。
| Read Speech | |||
|---|---|---|---|
| Test set | DS1 | DS2 | Human |
| WSJ eval’92 | 4.94 | 3.60 | 5.03 |
| WSJ eval’93 | 6.94 | 4.98 | 8.08 |
| LibriSpeech test-clean | 7.89 | 5.33 | 5.83 |
| LibriSpeech test-other | 21.74 | 13.25 | 12.69 |
Table 13: Comparison of WER for two speech systems and human level performance on read speech.
| 朗读语音 | |||
|---|---|---|---|
| 测试集 | DS1 | DS2 | 人类 |
| WSJ eval’92 | 4.94 | 3.60 | 5.03 |
| WSJ eval’93 | 6.94 | 4.98 | 8.08 |
| LibriSpeech test-clean | 7.89 | 5.33 | 5.83 |
| LibriSpeech test-other | 21.74 | 13.25 | 12.69 |
表 13:两套语音系统与人类水平在朗读语音上的 WER 比较。
6.1.3 Accented Speech
Our source for accented speech is the publicly available VoxForge (http://www.voxforge.org) dataset, which has clean speech read from speakers with many different accents. We group these accents into four categories. The American-Canadian and Indian groups are self-explanatory. The Commonwealth accent denotes speakers with British, Irish, South African, Australian and New Zealand accents. The European group contains speakers with accents from countries in Europe that do not have English as a first language. We construct a test set from the VoxForge data with 1024 examples from each accent group for a total of 4096 examples.
6.1.3 口音语音
口音语音来源是公开的 VoxForge(http://www.voxforge.org)数据集,含多种口音说话人的干净朗读语音。我们把口音分成四类:美加与印度组顾名思义;英联邦口音指英国、爱尔兰、南非、澳大利亚与新西兰口音说话人;欧洲组含母语非英语的欧洲国家口音说话人。从 VoxForge 构建测试集,每口音组 1024 例,共 4096 例。
Performance on these test sets is to some extent a measure of the breadth and quality of our training data. Table 14 shows that our performance improved on all the accents when we include more accented training data and use an architecture that can effectively train on that data. However human level performance is still notably better than that of DS2 for all but the Indian accent.
这些测试集上的表现在一定程度上衡量训练数据的广度与质量。表 14 显示,纳入更多带口音训练数据并用能有效训练这些数据的架构后,所有口音上表现均改善。但除印度口音外,人类水平仍明显好于 DS2。
| Accented Speech | |||
|---|---|---|---|
| Test set | DS1 | DS2 | Human |
| VoxForge American-Canadian | 15.01 | 7.55 | 4.85 |
| VoxForge Commonwealth | 28.46 | 13.56 | 8.15 |
| VoxForge European | 31.20 | 17.55 | 12.76 |
| VoxForge Indian | 45.35 | 22.44 | 22.15 |
Table 14: Comparing WER of the DS1 system to the DS2 system on accented speech.
| 口音语音 | |||
|---|---|---|---|
| 测试集 | DS1 | DS2 | 人类 |
| VoxForge 美加 | 15.01 | 7.55 | 4.85 |
| VoxForge 英联邦 | 28.46 | 13.56 | 8.15 |
| VoxForge 欧洲 | 31.20 | 17.55 | 12.76 |
| VoxForge 印度 | 45.35 | 22.44 | 22.15 |
表 14:DS1 与 DS2 在口音语音上的 WER 比较。
6.1.4 Noisy Speech
We test our performance on noisy speech using the publicly available test sets from the recently completed third CHiME challenge [4]. This dataset has 1320 utterances from the WSJ test set read in various noisy environments, including a bus, a cafe, a street and a pedestrian area. The CHiME set also includes 1320 utterances with simulated noise from the same environments as well as the control set containing the same utterances delivered by the same speakers in a noise-free environment. Differences between results on the control set and the noisy sets provide a measure of the network’s ability to handle a variety of real and synthetic noise conditions. The CHiME audio has 6 channels and using all of them can provide substantial performance improvements [69]. We use a single channel for all our results, since multi-channel audio is not pervasive on most devices. Table 15 shows that DS2 substantially improves upon DS1, however DS2 is worse than human level performance on noisy data. The relative gap between DS2 and human level performance is larger when the data comes from a real noisy environment instead of synthetically adding noise to clean speech.
6.1.4 噪声语音
我们用第三届 CHiME 挑战 [4] 刚完成时公开的测试集评估噪声语音表现。该集有 1320 条 WSJ 测试句,在公交、咖啡馆、街道与行人区等噪声环境中朗读;另有 1320 条在相同环境模拟噪声下的句子,以及同一说话人在无噪声环境中朗读相同句子的对照集。对照集与噪声集结果之差衡量网络处理多种真实与合成噪声条件的能力。CHiME 音频有 6 通道,全用可大幅提升表现 [69];我们所有结果只用单通道,因多数设备上多通道音频并不普遍。表 15 显示 DS2 相对 DS1 大幅改善,但噪声数据上仍逊于人类水平。当数据来自真实噪声环境而非向干净语音合成加噪时,DS2 与人类的相对差距更大。
| Noisy Speech | |||
|---|---|---|---|
| Test set | DS1 | DS2 | Human |
| CHiME eval clean | 6.30 | 3.34 | 3.46 |
| CHiME eval real | 67.94 | 21.79 | 11.84 |
| CHiME eval sim | 80.27 | 45.05 | 31.33 |
Table 15: Comparison of DS1 and DS2 system on noisy speech. “CHiME eval clean” is a noise-free baseline. The “CHiME eval real” dataset is collected in real noisy environments and the “CHiME eval sim” dataset has similar noise synthetically added to clean speech. Note that we use only one of the six channels to test each utterance.
| 噪声语音 | |||
|---|---|---|---|
| 测试集 | DS1 | DS2 | 人类 |
| CHiME eval clean | 6.30 | 3.34 | 3.46 |
| CHiME eval real | 67.94 | 21.79 | 11.84 |
| CHiME eval sim | 80.27 | 45.05 | 31.33 |
表 15:DS1 与 DS2 在噪声语音上的比较。「CHiME eval clean」为无噪声基线;「CHiME eval real」在真实噪声环境采集;「CHiME eval sim」向干净语音合成加入类似噪声。注意每条话语仅用六通道之一测试。
6.2 Mandarin
6.2 普通话
In Table 16 we compare several architectures trained on the Mandarin Chinese speech, on a development set of 2000 utterances as well as a test set of 1882 examples of noisy speech. This development set was also used to tune the decoding parameters We see that the deepest model with 2D-invariant convolution and BatchNorm outperforms the shallow RNN by 48% relative, thus continuing the trend that we saw with the English system—multiple layers of bidirectional recurrence improves performance substantially.
表 16 比较在普通话语音上训练的若干架构:开发集 2000 条,测试集 1882 条噪声语音。开发集也用于调解码参数。最深、含二维不变卷积与 BatchNorm 的模型相对浅层 RNN 相对优 48%,延续英语系统所见趋势——多层双向循环显著提升表现。
| Architecture | Dev | Test |
|---|---|---|
| 5-layer, 1 RNN | 7.13 | 15.41 |
| 5-layer, 3 RNN | 6.49 | 11.85 |
| 5-layer, 3 RNN + BatchNorm | 6.22 | 9.39 |
| 9-layer, 7 RNN + BatchNorm + 2D conv | 5.81 | 7.93 |
Table 16: Comparison of the improvements in DeepSpeech with architectural improvements. The development and test sets are Baidu internal corpora. All the models in the table have about 80 million parameters each
| 架构 | Dev | Test |
|---|---|---|
| 5 层,1 RNN | 7.13 | 15.41 |
| 5 层,3 RNN | 6.49 | 11.85 |
| 5 层,3 RNN + BatchNorm | 6.22 | 9.39 |
| 9 层,7 RNN + BatchNorm + 2D conv | 5.81 | 7.93 |
表 16:架构改进对 DeepSpeech 的提升比较。开发与测试集为百度内部语料。表中模型各约 8000 万参数。
We find that our best Mandarin Chinese speech system transcribes short voice-query like utterances better than a typical Mandarin Chinese speaker. To benchmark against humans we ran a test with 100 randomly selected utterances and had a group of 5 humans label all of them together. The group of humans had an error rate of 4.0% as compared to the speech systems performance of 3.7%. We also compared a single human transcriber to the speech system on 250 randomly selected utterances. In this case the speech system performs much better: 9.7% for the human compared to 5.7% for the speech model.
我们发现最佳普通话系统在转写短语音查询类话语时优于典型普通话说话人。为与人类对照,随机选 100 条话语,由 5 人一组共同标注,人类错误率 4.0%,语音系统 3.7%。另在随机 250 条上比较单一人类转写员与系统:人类 9.7%,语音模型 5.7%,系统明显更好。
7 Deployment
7 部署
Real-world applications usually require a speech system to transcribe in real time or with relatively low latency. The system used in Section 6.1 is not well-designed for this task, for several reasons. First, since the RNN has several bidirectional layers, transcribing the first part of an utterance requires the entire utterance to be presented to the RNN. Second, since we use a wide beam when decoding with a language model, beam search can be expensive, particularly in Mandarin where the number of possible next characters is very large (around 6000). Third, as described in Section 3, we normalize power across an entire utterance, which again requires the entire utterance to be available in advance.
现实应用通常要求语音系统实时或较低延迟转写。第 6.1 节所用系统并不适合该任务,原因有几:其一,RNN 有多层双向层,转写话语前半段需要整段话语都呈现给 RNN;其二,用语言模型解码时束宽较大,束搜索可能很贵,尤其普通话下一字符候选约 6000 个;其三,如第 3 节所述,我们在整段话语上做功率归一化,同样需要预先拿到整段话语。
We solve the power normalization problem by using some statistics from our training set to perform an adaptive normalization of speech inputs during online transcription. We can solve the other problems by modifying our network and decoding procedure to produce a model that performs almost as well while having much lower latency. We focus on our Mandarin system since some aspects of that system are more challenging to deploy (e.g. the large character set), but the same techniques could also be applied in English.
功率归一化问题通过用训练集部分统计量,在在线转写时对语音输入做自适应归一化来解决。其余问题可通过修改网络与解码流程,得到延迟低得多而表现几乎相当的模型。我们聚焦普通话系统,因其部分方面更难部署(如大字符集),但相同技术也可用于英语。
In this section, latency refers to the computational latency of our speech system as measured from the end of an utterance until the transcription is produced. This latency does not include data transmission over the internet, and does not measure latency from the beginning of an utterance until the first transcription is produced. We focus on latency from end of utterance to transcription because it is important to applications using speech recognition.
本节中,延迟指从话语结束到产生转写所测得的计算延迟,不含互联网数据传输,也不度量从话语开始到产生第一条转写的延迟。我们关注「话语结束到转写」的延迟,因其对使用语音识别的应用很重要。
7.1 Batch Dispatch
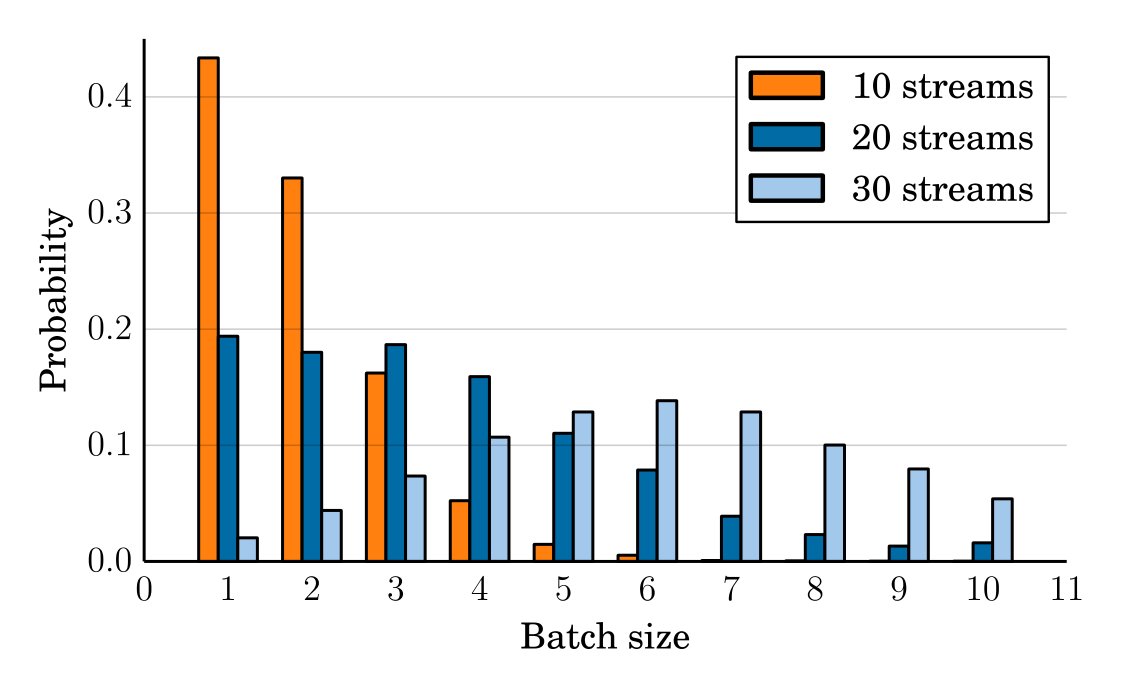
Figure 5: Probability that a request is processed in a batch of given size
图 5:请求在给定大小批量中被处理的概率
In order to deploy our relatively large deep neural networks at low latency, we have paid special attention to efficiency during deployment. Most internet applications process requests individually as they arrive in the data center. This makes for a straightforward implementation where each request can be managed by one thread. However, processing requests individually is inefficient computationally, for two main reasons. Firstly, when processing requests individually, the processor must load all the weights of the network for each request. This lowers the arithmetic intensity of the workload, and tends to make the computation memory bandwidth bound, as it is difficult to effectively use on-chip caches when requests are presented individually. Secondly, the amount of parallelism that can be exploited to classify one request is limited, making it difficult to exploit SIMD or multi-core parallelism. RNNs are especially challenging to deploy because evaluating RNNs sample by sample relies on sequential matrix vector multiplications, which are bandwidth bound and difficult to parallelize.
为在低延迟下部署相对较大的深度神经网络,我们特别关注部署效率。多数互联网应用在请求到达数据中心时逐个处理,实现简单:每请求可由一线程管理。但逐请求处理在计算上低效,主要有两点:其一,逐请求处理时处理器必须为每个请求加载全部网络权重,降低算术强度,易使计算受内存带宽限制——请求单独呈现时难以有效利用片上缓存;其二,分类单个请求可利用的并行度有限,难以发挥 SIMD 或多核并行。RNN 尤其难部署,因为逐样本评估依赖顺序的矩阵–向量乘,带宽受限且难并行。
To overcome these issues, we built a batching scheduler called Batch Dispatch that assembles streams of data from user requests into batches before performing forward propagation on these batches. In this case, there is a tradeoff between increased batch size, and consequently improved efficiency, and increased latency. The more we buffer user requests to assemble a large batch, the longer users must wait for their results. This places constraints on the amount of batching we can perform.
为克服这些问题,我们构建了名为 Batch Dispatch 的批调度器:先把用户请求的数据流组装成批量,再对这些批量做前向传播。此时存在批量增大(效率提高)与延迟增大之间的折中:缓冲用户请求以组装大批量越久,用户等待结果越久,从而限制可执行的批处理量。
We use an eager batching scheme that processes each batch as soon as the previous batch is completed, regardless of how much work is ready by that point. This scheduling algorithm has proved to be the best at reducing end-user latency, despite the fact that it is less efficient computationally, since it does not attempt to maximize batch size.
我们使用急切批处理方案:上一批量一完成就处理下一批,无论此刻已就绪多少工作。该调度算法被证明最能降低终端用户延迟,尽管计算上不如追求最大化批量的方案高效。
Figure 5 shows the probability that a request is processed in a batch of given size for our production system running on a single NVIDIA Quadro K1200 GPU, with 10-30 concurrent user requests. As expected, batching works best when the server is heavily loaded: as load increases, the distribution shifts to favor processing requests in larger batches. However, even with a light load of only 10 concurrent user requests, our system performs more than half the work in batches with at least 2 samples.
图 5 给出生产系统在单块 NVIDIA Quadro K1200 GPU、10–30 并发用户请求时,请求在给定大小批量中被处理的概率。如预期,服务器负载重时批处理效果最好:负载增加时分布偏向更大批量。但即便只有 10 路并发的轻负载,系统仍有一半以上工作在至少含 2 个样本的批量中完成。
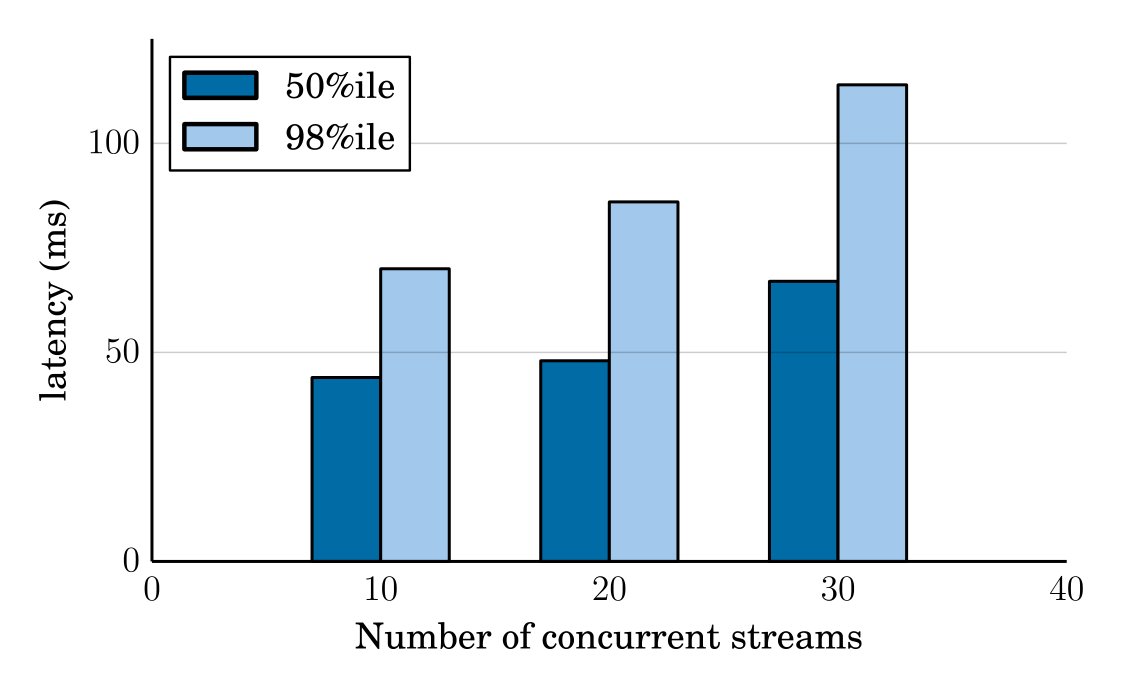
Figure 6: Median and 98 percentile latencies as a function of server load
图 6:中位与第 98 百分位延迟随服务器负载变化
We see in Figure 6, that our system achieves a median latency of 44 ms, and a 98 percentile latency of 70 ms when loaded with 10 concurrent streams. As the load increases on the server, the batching scheduler shifts work to more efficient batches, which keeps latency low. This shows that Batch Dispatch makes it possible to deploy these large models at high throughput and low latency.
图 6 显示,在 10 路并发流负载下,系统中位延迟 44 ms、第 98 百分位 70 ms。服务器负载增加时,批调度器把工作移向更高效的批量,从而保持低延迟。这说明 Batch Dispatch 使这些大模型能在高吞吐与低延迟下部署。
7.2 Deployment Optimized Matrix Multiply Kernels
7.2 面向部署优化的矩阵乘核
We have found that deploying our models using half-precision (16-bit) floating-point arithmetic does not measurably change recognition accuracy. Because deployment does not require any updates to the network weights, it is far less sensitive to numerical precision than training. Using half-precision arithmetic saves memory space and bandwidth, which is especially useful for deployment, since RNN evaluation is dominated by the cost of caching and streaming the weight matrices.
我们发现用半精度(16 位)浮点运算部署模型不会可测地改变识别精度。部署无需更新网络权重,对数值精度远不如训练敏感。半精度节省内存空间与带宽,对部署尤其有用,因为 RNN 评估主要由缓存与流式传输权重矩阵的代价主导。
As seen in Section 7.1, the batch size during deployment is much smaller than in training. We found that standard BLAS libraries are inefficient at this batch size. To overcome this, we wrote our own half-precision matrix-matrix multiply kernel. For 10 simultaneous streams over 90 percent of batches are for , a regime where the matrix multiply will be bandwidth bound. We store the matrix transposed to maximize bandwidth by using the widest possible vector loads while avoiding transposition after loading. Each warp computes four rows of output for all output columns. Note that for the matrix fits entirely in the L1 cache. This scheme achieves 90 percent of peak bandwidth for but starts to lose efficiency for larger as the matrix stops fitting into the L1 cache. Nonetheless, it continues to provide improved performance over existing libraries up to .
如第 7.1 节所见,部署时批量远小于训练。我们发现标准 BLAS 库在此批量下低效。为此我们编写了自己的半精度矩阵–矩阵乘核。对 10 路并发流,超过 90% 的批量满足 ,此时矩阵乘受带宽限制。我们存储转置的 矩阵,用尽可能宽的向量加载最大化带宽并避免加载后转置。每个 warp 为所有 个输出列计算四行输出。注意 时 矩阵完全放入 L1 缓存。该方案在 时达到峰值带宽的 90%,更大 时因 不再适合 L1 而效率下降,但仍优于现有库直至 。
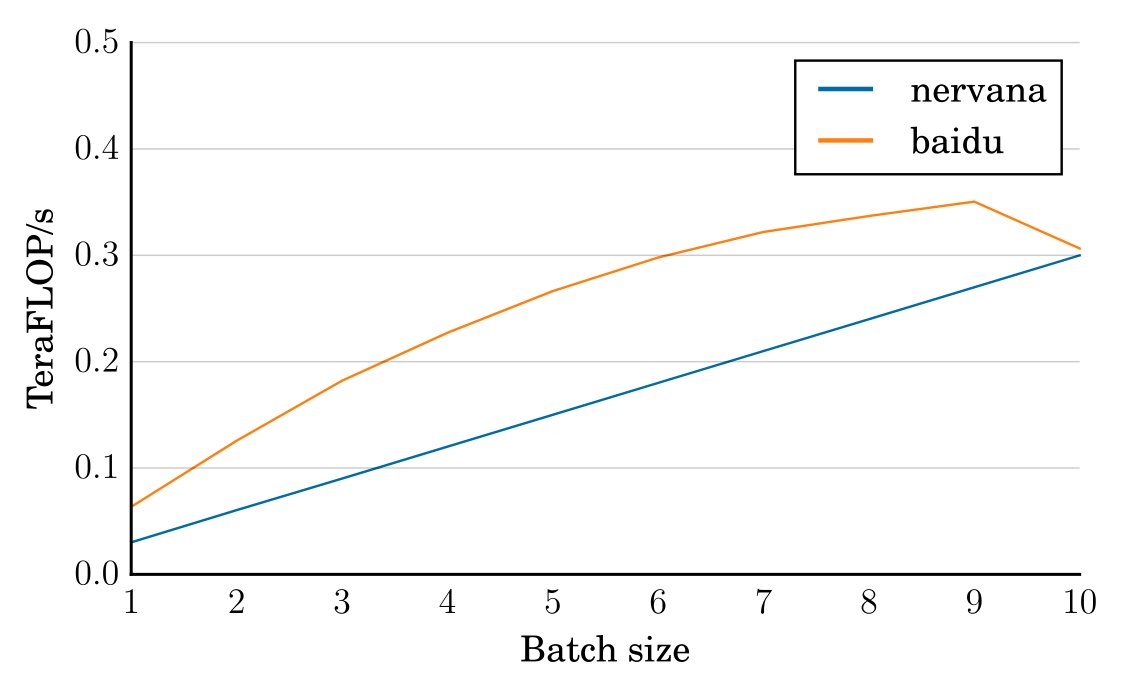
Figure 7: Comparison of kernels that compute where is a matrix with dimension , and is a matrix with dimension , where . All matrices are in half-precision format.
图 7:计算 的核比较,其中 尺寸 , 尺寸 ,。所有矩阵为半精度格式。
Figure 7 shows that our deployment kernel sustains a higher computational throughput than those from Nervana Systems [44] on the K1200 GPU, across the entire range of batch sizes that we use in deployment. Both our kernels and the Nervana kernels are significantly faster than NVIDIA CUBLAS version 7.0, more details are found here [20].
图 7 显示,在部署所用的全部批量范围内,我们的部署核在 K1200 GPU 上维持高于 Nervana Systems [44] 的计算吞吐。我们的核与 Nervana 核均显著快于 NVIDIA CUBLAS 7.0,更多细节见 [20]。
7.3 Beam Search
7.3 束搜索
Performing the beam search involves repeated lookups in the n-gram language model, most of which translate to uncached reads from memory. The direct implementation of beam search means that each time-step dispatches one lookup per character for each beam. In Mandarin, this results in over 1M lookups per 40ms stride of speech data, which is too slow for deployment. To deal with this problem, we use a heuristic to further prune the beam search. Rather than considering all characters as viable additions to the beam, we only consider the fewest number of characters whose cumulative probability is at least . In practice, we have found that works well. Additionally, we limit ourselves to no more than 40 characters. This speeds up the Mandarin language model lookup time by a factor of 150x, and has a negligible effect on the CER (0.1-0.3% relative).
执行束搜索涉及对 n-gram 语言模型的反复查找,多数转化为未缓存的内存读。束搜索的直接实现意味着每个时间步为每条束的每个字符派发一次查找。普通话上这导致每 40ms 语音跨步超过 100 万次查找,对部署过慢。为此我们用启发式进一步剪枝束搜索:不再把所有字符视为可加入束的候选,只考虑累积概率至少为 的最少数字符。实践中 效果好;另外最多限制 40 个字符。这使普通话语言模型查找加速约 150 倍,对 CER 影响可忽略(相对 0.1–0.3%)。
7.4 Results
7.4 结果
We can deploy our system at low latency and high throughput without sacrificing much accuracy. On a held-out set of 2000 utterances, our research system achieves 5.81 character error rate whereas the deployed system achieves 6.10 character error rate. This is only a 5% relative degradation for the deployed system. In order to accomplish this, we employ a neural network architecture with low deployment latency, reduce the precision of our network to 16-bit, built a batching scheduler to more efficiently evaluate RNNs, and find a simple heuristic to reduce beam search cost. The model has five forward-only recurrent layers with 2560 hidden units, one row convolution layer (Section 3.7) with , and one fully-connected layer with 2560 hidden units. These techniques allow us to deploy Deep Speech at low cost to interactive applications.
我们可在低延迟与高吞吐下部署系统,精度损失不大。在留出的 2000 条话语上,研究系统 CER 5.81,部署系统 6.10,相对仅降约 5%。为此我们采用低部署延迟的网络架构,把网络精度降到 16 位,构建批调度器以更高效评估 RNN,并找到降低束搜索代价的简单启发式。模型含五层仅前向循环(每层 2560 隐单元)、一层行卷积(第 3.7 节,)与一层 2560 隐单元全连接。这些技术使我们能以低成本把 Deep Speech 部署到交互式应用。
8 Conclusion
8 结论
End-to-end deep learning presents the exciting opportunity to improve speech recognition systems continually with increases in data and computation. Indeed, our results show that, compared to the previous incarnation, Deep Speech has significantly closed the gap in transcription performance with human workers by leveraging more data and larger models. Further, since the approach is highly generic, we’ve shown that it can quickly be applied to new languages. Creating high-performing recognizers for two very different languages, English and Mandarin, required essentially no expert knowledge of the languages. Finally, we have also shown that this approach can be efficiently deployed by batching user requests together on a GPU server, paving the way to deliver end-to-end Deep Learning technologies to users.
端到端深度学习提供了随数据与计算增长持续改进语音识别系统的令人兴奋的机会。的确,结果表明相对前一版本,Deep Speech 借助更多数据与更大模型显著缩小了与人工转写员的转写性能差距。此外,该方法高度通用,我们证明它能快速应用于新语言:为英语与普通话这两种迥异语言构建高性能识别器,几乎不需要语言专家知识。最后,我们还表明可通过在 GPU 服务器上批量处理用户请求来高效部署该方法,为把端到端深度学习技术交付给用户铺路。
To achieve these results, we have explored various network architectures, finding several effective techniques: enhancements to numerical optimization through SortaGrad and Batch Normalization, evaluation of RNNs with larger strides with bigram outputs for English, searching through both bidirectional and unidirectional models. This exploration was powered by a well optimized, High Performance Computing inspired training system that allows us to train new, full-scale models on our large datasets in just a few days.
为取得这些结果,我们探索了多种网络架构,找到若干有效技术:通过 SortaGrad 与批归一化增强数值优化、用 bigram 输出与更大跨步评估英语 RNN、同时搜索双向与单向模型。探索由一套高度优化、受高性能计算启发的训练系统驱动,使我们能在几天内于大规模数据集上训练全新全尺寸模型。
Overall, we believe our results confirm and exemplify the value of end-to-end Deep Learning methods for speech recognition in several settings. In those cases where our system is not already comparable to humans, the difference has fallen rapidly, largely because of application-agnostic Deep Learning techniques. We believe these techniques will continue to scale, and thus conclude that the vision of a single speech system that outperforms humans in most scenarios is imminently achievable.
总体而言,我们相信结果在多种设定下确认并例证了端到端深度学习方法对语音识别的价值。在系统尚不及人类的情形中,差距已迅速缩小,主要得益于与应用无关的深度学习技术。我们相信这些技术将继续扩展,因而得出结论:单一语音系统在多数场景上超过人类的愿景已近在咫尺。
Acknowledgments
致谢
We are grateful to Baidu’s speech technology group for help with data preparation and useful conversations. We would like to thank Scott Gray, Amir Khosrowshahi and all of Nervana Systems for their excellent matrix multiply routines and useful discussions. We would also like to thank Natalia Gimelshein of NVIDIA for useful discussions and thoughts on implementing our fast deployment matrix multiply.
感谢百度语音技术组在数据准备上的帮助与有益讨论。感谢 Scott Gray、Amir Khosrowshahi 以及 Nervana Systems 全体提供出色的矩阵乘例程与有益讨论。也感谢 NVIDIA 的 Natalia Gimelshein 就实现快速部署矩阵乘给出的讨论与想法。
References
参考文献
[1] O. Abdel-Hamid, A.-r. Mohamed, H. Jang, and G. Penn. Applying convolutional neural networks concepts to hybrid nn-hmm model for speech recognition. In ICASSP , 2012.
[2] D. Bahdanau, K. Cho, and Y. Bengio. Neural machine translation by jointly learning to align and translate. In ICLR , 2015.
[3] D. Bahdanau, J. Chorowski, D. Serdyuk, P. Brakel, and Y. Bengio. End-to-end attention-based large vocabulary speech recognition. abs/1508.04395, 2015. http://arxiv.org/abs/1508.04395.
[4] J. Barker, E. Marxer, Ricard Vincent, and S. Watanabe. The third ’CHiME’ speech separation and recognition challenge: Dataset, task and baselines. 2015. Submitted to IEEE 2015 Automatic Speech Recognition and Understanding Workshop (ASRU).
[5] S. Baxter. Modern GPU. https://nvlabs.github.io/moderngpu/ .
[6] Y. Bengio, J. Louradour, R. Collobert, and J. Weston. Curriculum learning. In International Conference on Machine Learning , 2009.
[7] H. Bourlard and N. Morgan. Connectionist Speech Recognition: A Hybrid Approach . Kluwer Academic Publishers, Norwell, MA, 1993.
[8] W. Chan, N. Jaitly, Q. Le, and O. Vinyals. Listen, attend, and spell. abs/1508.01211, 2015. http://arxiv.org/abs/1508.01211.
[9] S. Chetlur, C. Woolley, P. Vandermersch, J. Cohen, J. Tran, B. Catanzaro, and E. Shelhamer. cuDNN: Efficient primitives for deep learning.
[10] T. Chilimbi, Y. Suzue, J. Apacible, and K. Kalyanaraman. Project adam: Building an efficient and scalable deep learning training system. In USENIX Symposium on Operating Systems Design and Implementation , 2014.
[11] K. Cho, B. Van Merrienboer, C. Gulcehre, D. Bahdanau, F. Bougares, H. Schwenk, and Y. Bengio. Learning phrase representations using rnn encoder-decoder for statistical machine translation. In EMNLP , 2014.
[12] J. Chorowski, D. Bahdanau, K. Cho, and Y. Bengio. End-to-end continuous speech recognition using attention-based recurrent nn: First results. abs/1412.1602, 2015. http://arxiv.org/abs/1412.1602.
[13] C. Cieri, D. Miller, and K. Walker. The Fisher corpus: a resource for the next generations of speech-to-text. In LREC , volume 4, pages 69–71, 2004.
[14] A. Coates, B. Carpenter, C. Case, S. Satheesh, B. Suresh, T. Wang, D. J. Wu, and A. Y. Ng. Text detection and character recognition in scene images with unsupervised feature learning. In International Conference on Document Analysis and Recognition , 2011.
[15] A. Coates, B. Huval, T. Wang, D. J. Wu, A. Y. Ng, and B. Catanzaro. Deep learning with COTS HPC. In International Conference on Machine Learning , 2013.
[16] G. Dahl, D. Yu, and L. Deng. Large vocabulary continuous speech recognition with context-dependent DBN-HMMs. In Proc. ICASSP , 2011.
[17] G. Dahl, D. Yu, L. Deng, and A. Acero. Context-dependent pre-trained deep neural networks for large vocabulary speech recognition. IEEE Transactions on Audio, Speech, and Language Processing , 2011.
[18] J. Dean, G. S. Corrado, R. Monga, K. Chen, M. Devin, Q. Le, M. Mao, M. Ranzato, A. Senior, P. Tucker, K. Yang, and A. Ng. Large scale distributed deep networks. In Advances in Neural Information Processing Systems 25 , 2012.
[19] D. Ellis and N. Morgan. Size matters: An empirical study of neural network training for large vocabulary continuous speech recognition. In ICASSP , volume 2, pages 1013–1016. IEEE, 1999.
[20] E. Elsen. Optimizing RNN performance. http://svail.github.io/rnn_perf . Accessed: 2015-11-24.
[21] M. J. F. Gales, A. Ragni, H. Aldamarki, and C. Gautier. Support vector machines for noise robust ASR. In ASRU , pages 205–2010, 2009.
[22] A. Graves, S. Fernández, F. Gomez, and J. Schmidhuber. Connectionist temporal classification: Labelling unsegmented sequence data with recurrent neural networks. In ICML , pages 369–376. ACM, 2006.
[23] A. Graves and N. Jaitly. Towards end-to-end speech recognition with recurrent neural networks. In ICML , 2014.
[24] A. Graves, A.-r. Mohamed, and G. Hinton. Speech recognition with deep recurrent neural networks. In ICASSP , 2013.
[25] H. H. Sak, A. Senior, and F. Beaufays. Long short-term memory recurrent neural network architectures for large scale acoustic modeling. In Interspeech , 2014.
[26] A. Hannun, C. Case, J. Casper, B. Catanzaro, G. Diamos, E. Elsen, R. Prenger, S. Satheesh, S. Sengupta, A. Coates, and A. Y. Ng. Deep speech: Scaling up end-to-end speech recognition. 1412.5567, 2014. http://arxiv.org/abs/1412.5567.
[27] A. Y. Hannun, A. L. Maas, D. Jurafsky, and A. Y. Ng. First-pass large vocabulary continuous speech recognition using bi-directional recurrent DNNs. abs/1408.2873, 2014. http://arxiv.org/abs/1408.2873.
[28] K. Heafield, I. Pouzyrevsky, J. H. Clark, and P. Koehn. Scalable modified Kneser-Ney language model estimation. In Proceedings of the 51st Annual Meeting of the Association for Computational Linguistics , Sofia, Bulgaria, 8 2013.
[29] G. Hinton, L. Deng, D. Yu, G. Dahl, A. Mohamed, N. Jaitly, A. Senior, V. Vanhoucke, P. Nguyen, T. Sainath, and B. Kingsbury. Deep neural networks for acoustic modeling in speech recognition. IEEE Signal Processing Magazine , 29(November):82–97, 2012.
[30] S. Hochreiter and J. Schmidhuber. Long short-term memory. Neural Computation , 9(8):1735—1780, 1997.
[31] N. Jaitly and G. Hinton. Vocal tract length perturbation (VTLP) improves speech recognition. In ICML Workshop on Deep Learning for Audio, Speech, and Language Processing , 2013.
[32] R. Jozefowicz, W. Zaremba, and I. Sutskever. An empirical exploration of recurrent network architectures. In ICML , 2015.
[33] O. Kapralova, J. Alex, E. Weinstein, P. Moreno, and O. Siohan. A big data approach to acoustic model training corpus selection. In Interspeech , 2014.
[34] K. C. Knowlton. A fast storage allocator. Commun. ACM , 8(10):623–624, Oct. 1965.
[35] T. Ko, V. Peddinti, D. Povey, and S. Khudanpur. Audio augmentation for speech recognition. In Interspeech , 2015.
[36] A. Krizhevsky, I. Sutskever, and G. Hinton. Imagenet classification with deep convolutional neural networks. In Advances in Neural Information Processing Systems 25 , pages 1106–1114, 2012.
[37] C. Laurent, G. Pereyra, P. Brakel, Y. Zhang, and Y. Bengio. Batch normalized recurrent neural networks. abs/1510.01378, 2015. http://arxiv.org/abs/1510.01378.
[38] Q. Le, M. Ranzato, R. Monga, M. Devin, K. Chen, G. Corrado, J. Dean, and A. Ng. Building high-level features using large scale unsupervised learning. In International Conference on Machine Learning , 2012.
[39] Y. LeCun, F. J. Huang, and L. Bottou. Learning methods for generic object recognition with invariance to pose and lighting. In Computer Vision and Pattern Recognition , volume 2, pages 97–104, 2004.
[40] A. Maas, Z. Xie, D. Jurafsky, and A. Ng. Lexicon-free conversational speech recognition with neural networks. In NAACL , 2015.
[41] Y. Miao, M. Gowayyed, and F. Metz. EESEN: End-to-end speech recognition using deep rnn models and wfst-based decoding. In ASRU , 2015.
[42] A. Mohamed, G. Dahl, and G. Hinton. Acoustic modeling using deep belief networks. IEEE Transactions on Audio, Speech, and Language Processing , (99), 2011.
[43] A. S. N. Jaitly, P. Nguyen and V. Vanhoucke. Application of pretrained deep neural networks to large vocabulary speech recognition. In Interspeech , 2012.
[44] Nervana Systems. Nervana GPU. https://github.com/NervanaSystems/nervanagpu . Accessed: 2015-11-06.
[45] J. Niu, L. Xie, L. Jia, and N. Hu. Context-dependent deep neural networks for commercial mandarin speech recognition applications. In APSIPA , 2013.
[46] V. Panayotov, G. Chen, D. Povey, and S. Khudanpur. Librispeech: an asr corpus based on public domain audio books. In ICASSP , 2015.
[47] R. Pascanu, T. Mikolov, and Y. Bengio. On the difficulty of training recurrent neural networks. abs/1211.5063, 2012. http://arxiv.org/abs/1211.5063.
[48] P. Patarasuk and X. Yuan. Bandwidth optimal all-reduce algorithms for clusters of workstations. J. Parallel Distrib. Comput. , 69(2):117–124, Feb. 2009.
[49] R. Raina, A. Madhavan, and A. Ng. Large-scale deep unsupervised learning using graphics processors. In 26th International Conference on Machine Learning , 2009.
[50] S. Renals, N. Morgan, H. Bourlard, M. Cohen, and H. Franco. Connectionist probability estimators in HMM speech recognition. IEEE Transactions on Speech and Audio Processing , 2(1):161–174, 1994.
[51] T. Robinson, M. Hochberg, and S. Renals. The use of recurrent neural networks in continuous speech recognition. pages 253–258, 1996.
[52] T. Sainath, O. Vinyals, A. Senior, and H. Sak. Convolutional, long short-term memory, fully connected deep neural networks. In ICASSP , 2015.
[53] T. N. Sainath, A. rahman Mohamed, B. Kingsbury, and B. Ramabhadran. Deep convolutional neural networks for LVCSR. In ICASSP , 2013.
[54] H. Sak, A. Senior, K. Rao, and F. Beaufays. Fast and accurate recurrent neural network acoustic models for speech recognition. abs/1507.06947, 2015. http://arxiv.org/abs/1507.06947.
[55] H. Sak, O. Vinyals, G. Heigold, A. Senior, E. McDermott, R. Monga, and M. Mao. Sequence discriminative distributed training of long shortterm memory recurrent neural networks. In Interspeech , 2014.
[56] B. Sapp, A. Saxena, and A. Ng. A fast data collection and augmentation procedure for object recognition. In AAAI Twenty-Third Conference on Artificial Intelligence , 2008.
[57] M. Schuster and K. K. Paliwal. Bidirectional recurrent neural networks. IEEE Transactions on Signal Processing , 45(11):2673–2681, 1997.
[58] F. Seide, G. Li, and D. Yu. Conversational speech transcription using context-dependent deep neural networks. In Interspeech , pages 437–440, 2011.
[59] J. Shan, G. Wu, Z. Hu, X. Tang, M. Jansche, and P. Moreno. Search by voice in mandarin chinese. In Interspeech , 2010.
[60] H. Soltau, G. Saon, and T. Sainath. Joint training of convolutional and non-convolutional neural networks. In ICASSP , 2014.
[61] I. Sutskever, J. Martens, G. Dahl, and G. Hinton. On the importance of momentum and initialization in deep learning. In 30th International Conference on Machine Learning , 2013.
[62] I. Sutskever, O. Vinyals, and Q. V. Le. Sequence to sequence learning with neural networks. 2014. http://arxiv.org/abs/1409.3215.
[63] C. Szegedy and S. Ioffe. Batch normalization: Accelerating deep network training by reducing internal covariate shift. abs/1502.03167, 2015. http://arxiv.org/abs/1502.03167.
[64] C. Szegedy, W. Liu, Y. Jia, P. Sermanet, S. Reed, D. Anguelov, D. Erhan, V. Vanhoucke, and A. Rabinovich. Going deeper with convolutions. 2014.
[65] R. Thakur and R. Rabenseifner. Optimization of collective communication operations in mpich. International Journal of High Performance Computing Applications , 19:49–66, 2005.
[66] K. Vesely, A. Ghoshal, L. Burget, and D. Povey. Sequence-discriminative training of deep neural networks. In Interspeech , 2013.
[67] A. Waibel, T. Hanazawa, G. Hinton, K. Shikano, and K. Lang. Phoneme recognition using time-delay neural networks,” acoustics speech and signal processing. IEEE Transactions on Acoustics, Speech and Signal Processing , 37(3):328–339, 1989.
[68] R. Williams and J. Peng. An efficient gradient-based algorithm for online training of recurrent network trajectories. Neural computation , 2:490–501, 1990.
[69] T. Yoshioka, N. Ito, M. Delcroix, A. Ogawa, K. Kinoshita, M. F. C. Yu, W. J. Fabian, M. Espi, T. Higuchi, S. Araki, and T. Nakatani. The ntt chime-3 system: Advances in speech enhancement and recognition for mobile multi-microphone devices. In IEEE ASRU , 2015.
[70] W. Zaremba and I. Sutskever. Learning to execute. abs/1410.4615, 2014. http://arxiv.org/abs/1410.4615.
Appendix A Scalability improvements
附录 A 可扩展性改进
In this section, we discuss some of our scalability improvements in more detail.
本节更详细讨论我们的若干可扩展性改进。
A.1 Node and cluster architecture
A.1 节点与集群架构
The software stack runs on a compute dense node built from Intel CPUs and NVIDIA Titan X GPUs, with peak single-precision computational throughput of teraFLOP/second. Each node also has GB of CPU memory and an TB storage volume built from two 4 TB hard disks in RAID-0 configuration. We use the CPU memory to cache our input data so that we are not directly exposed to the low bandwidth and high latency of spinning disks. We replicate our English and Mandarin datasets on each node’s local hard disk. This allows us to use our network only for weight updates and avoids having to rely on centralized file servers.
软件栈运行在由 颗 Intel CPU 与 块 NVIDIA Titan X GPU 构成的计算密集型节点上,峰值单精度吞吐 teraFLOP/秒。每节点还有 GB CPU 内存,以及由两块 4 TB 硬盘 RAID-0 构成的 TB 存储卷。我们用 CPU 内存缓存输入数据,以免直接暴露于机械盘的低带宽与高延迟。英语与普通话数据集复制到各节点本地硬盘,从而使网络主要用于权重更新,无需依赖集中文件服务器。
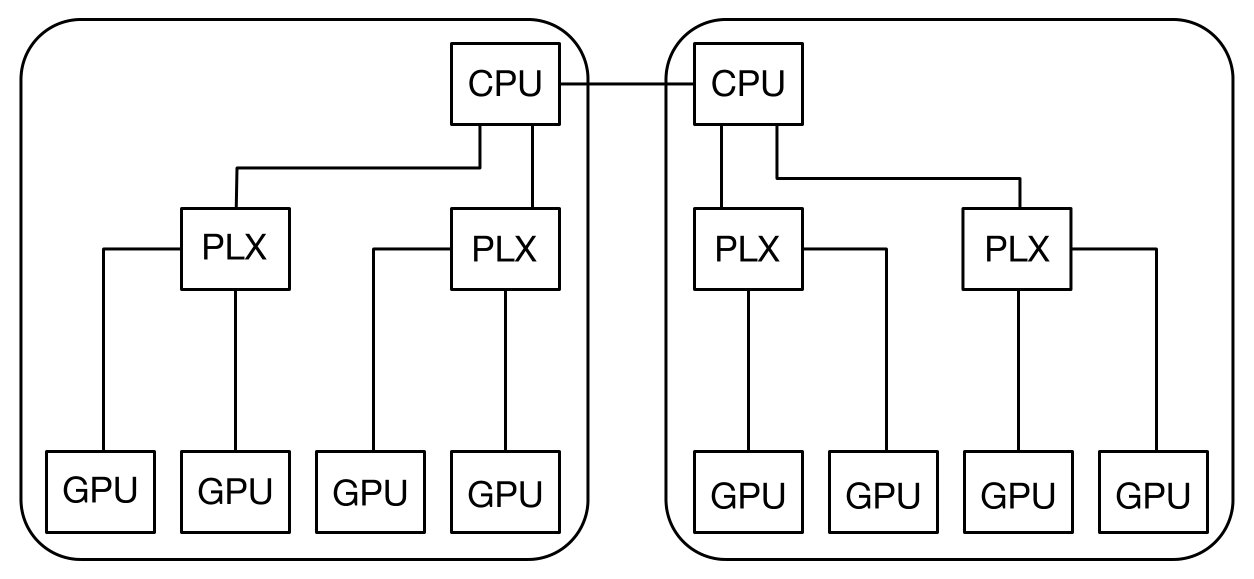
Figure 8: Schematic of our training node where PLX indicates a PCI switch and the dotted box includes all devices that are connected by the same PCI root complex.
图 8:训练节点示意,PLX 表示 PCI 交换机,虚线框包含由同一 PCI 根复合体连接的全部设备。
Figure 8 shows a schematic diagram of one our nodes, where all devices connected by the same PCI root complex are encapsulated in a dotted box. We have tried to maximize the number of GPUs within the root complex for faster communication between GPUs using GPUDirect. This allows us to use an efficient communication mechanism to transfer gradient matrices between GPUs.
图 8 给出节点示意图,同一 PCI 根复合体连接的设备包在虚线框内。我们尽量最大化根复合体内的 GPU 数,以便用 GPUDirect 在 GPU 间更快通信,从而用高效机制传输梯度矩阵。
All the nodes in our cluster are connected through Fourteen Data Rate (FDR) Infiniband which is primarily used for gradient transfer during back-propagation.
集群中所有节点通过 Fourteen Data Rate(FDR)InfiniBand 连接,主要用于反向传播期间的梯度传输。
A.2 GPU Implementation of CTC Loss Function
A.2 CTC 损失函数的 GPU 实现
The CTC loss function that we use to train our models has two passes: forward and backward, and the gradient computation involves element-wise addition of two matrices, and , generated during the forward and backward passes respectively. Finally, we sum the gradients using the character in the utterance label as the key, to generate one gradient per character. These gradients are then back-propagated through the network. The input to the CTC loss function are probabilities calculated by the softmax function which can be very small, so we compute in probability space for better numerical stability.
训练所用 CTC 损失有前向与后向两遍,梯度计算涉及对前向与后向分别生成的两个矩阵 与 做逐元素相加。最后以话语标签中的字符为键对梯度求和,使每个字符对应一个梯度,再经网络反向传播。CTC 损失的输入是 softmax 算出的概率,可能非常小,故在对数概率空间计算以改善数值稳定性。
The forward pass of the CTC algorithm calculates the matrix, which has rows and columns, where . The variable is the number of characters in the label and is the number of time-steps in the utterance. Our CPU-based implementation of the CTC algorithm assigns one thread to each utterance label in a minibatch, performing the CTC calculation for the utterances in parallel. Each thread calculates the relevant entries of the matrix sequentially. This is inefficient for two reasons.
CTC 算法前向遍计算 矩阵,有 行 列,其中 。 为标签字符数, 为话语时间步数。基于 CPU 的 CTC 实现为小批量中每条话语标签分配一线程,并行做 CTC 计算;每线程顺序计算矩阵相关项。这低效,原因有二。
Firstly, since the remainder of our network is computed on the GPU, the output of the softmax function has to be copied to the CPU for CTC calculation. The gradient matrices from the CTC function then has to be copied back to the GPU for backpropagation. For languages like Mandarin with large character sets, these matrices have hundreds of millions of entries, making this copy expensive. Furthermore, we need as much interconnect bandwidth as possible for synchronizing the gradient updates with data parallelism, so this copy incurs a substantial opportunity cost.
其一,因网络其余部分在 GPU 上计算,softmax 输出须拷到 CPU 做 CTC,CTC 梯度矩阵再拷回 GPU 做反向传播。对字符集大的普通话等语言,这些矩阵有数亿项,拷贝昂贵。此外,数据并行同步梯度更新需要尽可能多的互连带宽,该拷贝带来可观机会成本。
Secondly, although entries in each column of the matrix can be computed in parallel, the number of entries to calculate in each column depends both on the column and the number of repeated characters in the utterance label. Due to this complexity, the CPU implementation does not use SIMD parallelism optimally, making the computation inefficient.
其二,尽管 矩阵每列中的项可并行计算,但每列需计算的项数既依赖列号,也依赖话语标签中的重复字符数。因这种复杂性,CPU 实现未能最优利用 SIMD 并行,计算低效。
We wrote a GPU-based implementation of CTC in order to overcome these two problems. The key insight behind our implementation is that we can compute all elements in each column of the matrix, rather than just the valid entries. If we do so, Figure 9 shows that invalid elements either contain a finite garbage value (G), or (I), when we use a special summation function that adds probabilities in space that discards inputs that are . This summation is shown in Figure 9 where arrows incident on a circle are inputs and the result is stored in the circle. However, when we compute the final gradient by element-wise summing and , all finite garbage values will be added with a corresponding value from the other matrix, which results in , effectively ignoring the garbage value and computing the correct result. One important observation is that this element-wise sum of and is a simple sum and does not use our summation function.
为克服这两点,我们编写了基于 GPU 的 CTC 实现。关键洞察是:可计算 矩阵每列的全部元素,而非仅有效项。若如此做,图 9 显示无效元素要么含有限垃圾值(G),要么为 (I)——当我们使用在对数空间相加概率并丢弃 输入的特殊求和函数时。图 9 中箭头指向圆圈为输入,结果存在圆圈内。但当通过逐元素求和 与 计算最终梯度时,所有有限垃圾值都会与另一矩阵中对应的 相加,结果为 ,从而有效忽略垃圾值并得到正确结果。重要观察是:该 与 的逐元素和是简单求和,不使用我们的求和函数。
To compute the gradient, we take each column of the matrix generated from element-wise addition of and matrices, and do a key-value reduction using the character as key, using the ModernGPU library [5]. This means elements of the column corresponding to the same character will sum up their values. In the example shown in Figure 9, the blank character, , is the only repeated character and at some columns, say for of , both valid elements (gray) and correspond to it. Since our summation function in space effectively ignores the elements, only the valid elements are combined in the reduction.
为计算梯度,取 与 逐元素相加所得矩阵的每一列,以字符为键做键–值归约,使用 ModernGPU 库 [5]。这意味着列中对应同一字符的元素会把值加总。图 9 例子中,blank 字符 是唯一重复字符;在某些列(如 或 ),既有有效元素(灰色)也有对应它的 。由于对数空间求和函数有效忽略 ,归约时只合并有效元素。
Figure 9: Forward and backward pass for GPU implementation of CTC. Gray circles contain valid values, circle with I contain and circle with G contain garbage values that are finite. stand for the blank character that the CTC algorithm adds to the input utterance label. Column labels on top show different time-steps going from 1 to T.
图 9:CTC 的 GPU 实现前向与后向遍。灰色圆圈含有效值,标 I 的圆圈含 ,标 G 的圆圈含有限垃圾值。 表示 CTC 算法加入输入话语标签的 blank 字符。顶部列标签显示从 1 到 T 的不同时间步。
In our GPU implementation, we map each utterance in the minibatch to a CUDA thread block. Since there are no dependencies between the elements of a column, all of them can be computed in parallel by the threads in a threadblock. There are dependencies between columns, since the column corresponding to time-step cannot be computed before the column corresponding to time-step . The reverse happens when computing the matrix, when column corresponding to time-step cannot be computed before the column corresponding to time-step . Thus, in both cases, columns are processed sequentially by the thread block.
GPU 实现中,我们把小批量中每条话语映射到一个 CUDA 线程块。因列内元素无依赖,线程块内线程可全部并行计算。列之间有依赖:对应时间步 的列不能在对应 的列之前计算。计算 矩阵时相反:对应 的列不能在对应 的列之前计算。因此两种情形下,线程块都顺序处理各列。
Mapping the forward and backward passes to corresponding CUDA kernels is straightforward since there are no data dependencies between elements of a column. The kernel that does the backward pass also computes the gradient. However, since the gradients must be summed up based on the label values, with each character as key, we must deal with data dependencies due to repeated characters in an utterance label. For languages with small character sets like English, this happens with high probability. Even if there are no repeated characters, the CTC algorithm adds blank characters to the utterance label. We solve this problem by performing a key-value sort, where the keys are the characters in the utterance label, and the values are the indices of each character in the utterance. After sorting, all occurrences of a given character are arranged in contiguous segments. We only need to do the sort once for each utterance. The indices generated by the sort are then used to sequentially sum up the gradients for each character. This sum is done once per column and in parallel over all characters in the utterance. Amortizing the cost of key-value sort over columns is a key insight that makes the gradient calculation fast.
把前向与后向遍映射到对应 CUDA 核很直接,因列内元素无数据依赖。做后向遍的核也计算梯度。但由于梯度必须按标签值、以每个字符为键求和,必须处理话语标签中重复字符带来的数据依赖。对英语等小字符集语言,这以高概率发生;即便无重复字符,CTC 也会向话语标签加入 个 blank。我们通过键–值排序解决:键是话语标签中的字符,值是每个字符在话语中的下标。排序后,给定字符的所有出现排成连续段。每个话语只需排序一次。排序生成的下标再用于顺序累加每个字符的梯度;该求和对每列做一次,并在话语全部字符上并行。把键–值排序代价在 列上摊销,是使梯度计算变快的关键洞察。
Our GPU implementation uses fast shared memory and registers to achieve high performance when performing this task. Both forward and backward kernels store the matrix in shared memory. Since shared memory is a limited resource, it is not possible to store the entire matrix. However, as we go backward in time, we only need to keep one column of the matrix as we compute the gradient, adding element-wise the column of the matrix with the corresponding column of the matrix. Due to on-chip memory space constraints, we read the output of the softmax function directly from off-chip global memory.
GPU 实现使用快速共享内存与寄存器以在该任务上达到高性能。前向与后向核都把 矩阵存在共享内存中。因共享内存资源有限,无法存储整个 矩阵。但随时间后退,计算梯度时只需保留 的一列,与 对应列逐元素相加即可。因片上内存空间受限,我们直接从片外全局内存读取 softmax 输出。
Due to inaccuracies in floating-point arithmetic, especially in transcendental functions, our GPU and CPU implementation are not bit-wise identical. This is not an impediment in practice, since both implementations train models equally well when coupled with the technique of sorting utterances by length mentioned in Section 3.3.
由于浮点算术尤其是超越函数的不精确,GPU 与 CPU 实现并非按位相同。实践中这不是障碍:二者与第 3.3 节所述按长度排序话语的技术结合时,都能同样好地训练模型。