Deep Sets
Deep Sets
Carnegie Mellon University
Amazon Web Services
{manzilz,skottur,mravanba,bapoczos,rsalakhu,smola}@cs.cmu.edu
Abstract
摘要
We study the problem of designing models for machine learning tasks defined on sets. In contrast to traditional approach of operating on fixed dimensional vectors, we consider objective functions defined on sets that are invariant to permutations. Such problems are widespread, ranging from estimation of population statistics [1], to anomaly detection in piezometer data of embankment dams [2], to cosmology [3, 4]. Our main theorem characterizes the permutation invariant functions and provides a family of functions to which any permutation invariant objective function must belong. This family of functions has a special structure which enables us to design a deep network architecture that can operate on sets and which can be deployed on a variety of scenarios including both unsupervised and supervised learning tasks. We also derive the necessary and sufficient conditions for permutation equivariance in deep models. We demonstrate the applicability of our method on population statistic estimation, point cloud classification, set expansion, and outlier detection.
我们研究如何为定义在集合上的机器学习任务设计模型。与在固定维向量上操作的传统做法不同,我们考虑定义在集合上、对排列不变的目标函数。这类问题很常见,从总体统计量估计[1],到堤坝测压管数据的异常检测[2],再到宇宙学[3, 4]。我们的主定理刻画了排列不变函数,并给出任何排列不变目标函数都必须属于的一类函数。这类函数具有特殊结构,使我们能够设计可在集合上运算的深度网络,并用于无监督和监督两类学习任务。我们还推导了深度模型中排列等变的充要条件。我们在总体统计量估计、点云分类、集合扩展和异常检测上展示了该方法的适用性。
1 Introduction
1 引言
A typical machine learning algorithm, like regression or classification, is designed for fixed dimensional data instances. Their extensions to handle the case when the inputs or outputs are permutation invariant sets rather than fixed dimensional vectors is not trivial and researchers have only recently started to investigate them [5–8]. In this paper, we present a generic framework to deal with the setting where input and possibly output instances in a machine learning task are sets.
典型的机器学习算法,例如回归或分类,是为固定维的数据实例设计的。当输入或输出不再是固定维向量,而是对排列不变的集合时,如何加以推广并不平凡,研究者也是直到最近才开始讨论这类问题[5–8]。本文给出一个通用框架,用来处理机器学习任务中输入、以及可能的输出,是集合的情形。
Similar to fixed dimensional data instances, we can characterize two learning paradigms in case of sets. In supervised learning, we have an output label for a set that is invariant or equivariant to the permutation of set elements. Examples include tasks like estimation of population statistics [1], where applications range from giga-scale cosmology [3, 4] to nano-scale quantum chemistry [9].
与固定维数据类似,集合上也可以区分两类学习范式。在监督学习中,整个集合对应一个对元素排列不变或等变的输出标签。例如总体统计量估计[1],应用可以从十亿量级的宇宙学[3, 4]到纳米尺度的量子化学[9]。
Next, there can be the unsupervised setting, where the “set” structure needs to be learned, e.g. by leveraging the homophily/heterophily tendencies within sets. An example is the task of set expansion (a.k.a. audience expansion), where given a set of objects that are similar to each other (e.g. set of words {lion, tiger, leopard}), our goal is to find new objects from a large pool of candidates such that the selected new objects are similar to the query set (e.g. find words like jaguar or cheetah among all English words). This is a standard problem in similarity search and metric learning, and a typical application is to find new image tags given a small set of possible tags. Likewise, in the field of computational advertisement, given a set of high-value customers, the goal would be to find similar people. This is an important problem in many scientific applications, e.g. given a small set of interesting celestial objects, astrophysicists might want to find similar ones in large sky surveys.
接下来是无监督设定:需要把“集合”结构本身学出来,例如利用集合内部的同质性或异质性。一个例子是集合扩展(也称受众扩展):给定一组彼此相似的对象(例如词集合 {lion, tiger, leopard}),目标是从大量候选中找出与查询集合相似的新对象(例如在全部英语单词里找出 jaguar 或 cheetah)。这是相似性搜索和度量学习中的标准问题,典型应用是根据少量已有标签为图像补出新标签。在计算广告里,给定一组高价值顾客,目标则是找出相似的人。许多科学应用里也有同样的需求,例如天体物理学家拿到一小批有趣的天体后,希望在大规模巡天中找出相似对象。
Main contributions. In this paper, (i) we propose a fundamental architecture, DeepSets, to deal with sets as inputs and show that the properties of this architecture are both necessary and sufficient (Sec. 2). (ii) We extend this architecture to allow for conditioning on arbitrary objects, and (iii) based on this architecture we develop a deep network that can operate on sets with possibly different sizes (Sec. 3). We show that a simple parameter-sharing scheme enables a general treatment of sets within supervised and semi-supervised settings. (iv) Finally, we demonstrate the wide applicability of our framework through experiments on diverse problems (Sec. 4).
主要贡献。本文中,(i) 我们提出处理集合输入的基本结构 DeepSets,并说明该结构的性质既是必要的也是充分的(第 2 节)。(ii) 我们把该结构扩展为可以对任意对象做条件化;(iii) 基于这一结构,我们构造了可以处理大小可能不同的集合的深度网络(第 3 节)。我们表明,一种简单的参数共享方案,就能在监督和半监督设定下一般地处理集合。(iv) 最后,我们通过多样化问题上的实验,展示这一框架的广泛适用性(第 4 节)。
31st Conference on Neural Information Processing Systems (NIPS 2017), Long Beach, CA, USA.
2 Permutation Invariance and Equivariance
2 排列不变性与等变性
2.1 Problem Definition
2.1 问题定义
A function transforms its domain into its range . Usually, the input domain is a vector space and the output response range is either a discrete space, e.g. in case of classification, or a continuous space in case of regression. Now, if the input is a set , , i.e., the input domain is the power set , then we would like the response of the function to be “indifferent” to the ordering of the elements. In other words,
函数 把它的定义域 映到值域 。通常,输入域是向量空间 ,输出值域在分类时是离散空间,例如 ,在回归时是连续空间 。若输入是集合 ,,也就是说输入域是幂集 ,我们希望函数的响应对元素次序“无差别”。换句话说,
Property 1 A function acting on sets must be permutation invariant to the order of objects in the set, i.e. for any permutation : .
性质 1 作用在集合上的函数 必须对集合中对象的次序排列不变,即对任意排列 :。
In the supervised setting, given examples of of as well as their labels , the task would be to classify/regress (with variable number of predictors) while being permutation invariant w.r.t. predictors. Under unsupervised setting, the task would be to assign high scores to valid sets and low scores to improbable sets. These scores can then be used for set expansion tasks, such as image tagging or audience expansion in field of computational advertisement. In transductive setting, each instance has an associated labeled . Then, the objective would be instead to learn a permutation equivariant function that upon permutation of the input instances permutes the output labels, i.e. for any permutation :
在监督设定下,给定 个例子 及其标签 ,任务是在预测变量数目可变的情况下做分类或回归,同时对预测变量保持排列不变。在无监督设定下,任务是给合理的集合打高分,给不太可能出现的集合打低分。这些分数随后可用于集合扩展,例如图像标注,或计算广告中的受众扩展。在直推设定下,每个实例 都有对应的标签 。此时目标改为学习一个排列等变函数 ,输入实例一经排列,输出标签也跟着排列,即对任意排列 :
2.2 Structure
2.2 结构
We want to study the structure of functions on sets. Their study in total generality is extremely difficult, so we analyze case-by-case. We begin by analyzing the invariant case when is a countable set and , where the next theorem characterizes its structure.
我们希望研究集合上函数的结构。完全一般地讨论极为困难,因此我们分情形分析。先看不变情形:当 是可数集且 时,下面的定理刻画了它的结构。
Theorem 2 A function operating on a set having elements from a countable universe, is a valid set function, i.e., invariant to the permutation of instances in , iff it can be decomposed in the form , for suitable transformations and .
定理 2 函数 作用在元素来自可数全集的集合 上,是合法的集合函数,即对 中实例的排列不变,当且仅当它可以分解为 的形式,其中 和 是合适的变换。
The extension to case when is uncountable, like , we could only prove that holds for sets of fixed size. The proofs and difficulties in handling the uncountable case, are discussed in Appendix A. However, we still conjecture that exact equality holds in general.
推广到 不可数的情形,例如 ,我们只证明了 对固定大小的集合成立。证明以及处理不可数情形的困难,在附录 A 中讨论。不过我们仍然猜想,精确等式在一般情形下也成立。
Next, we analyze the equivariant case when and is restricted to be a neural network layer. The standard neural network layer is represented as where is the weight vector and is a nonlinearity such as sigmoid function. The following lemma states the necessary and sufficient conditions for permutation-equivariance in this type of function.
接下来分析等变情形:当 ,并把 限制为神经网络层。标准神经网络层写成 ,其中 是权重, 是 sigmoid 一类非线性。下面的引理给出这类函数排列等变的充要条件。
Lemma 3 The function defined above is permutation equivariant iff all the off-diagonal elements of are tied together and all the diagonal elements are equal as well. That is,
引理 3 上面定义的函数 排列等变,当且仅当 的所有非对角元绑在一起,并且所有对角元也相等。也就是说,
This result can be easily extended to higher dimensions, i.e., when can be matrices.
这一结果很容易推广到更高维,即 时,、 可以是矩阵。
2.3 Related Results
2.3 相关结果
The general form of Theorem 2 is closely related with important results in different domains. Here, we quickly review some of these connections.
定理 2 的一般形式与不同领域中的若干重要结果密切相关。这里我们简要回顾这些联系。
de Finetti theorem. A related concept is that of an exchangeable model in Bayesian statistics, It is backed by deFinetti’s theorem which states that any exchangeable model can be factored as
de Finetti 定理. 一个相关概念是贝叶斯统计中的可交换模型。它由 de Finetti 定理支撑,该定理指出任何可交换模型都可以分解为
where is some latent feature and , are the hyper-parameters of the prior. To see that this fits into our result, let us consider exponential families with conjugate priors, where we can analytically calculate the integral of (2). In this special case and . Now if we marginalize out , we get a form which looks exactly like the one in Theorem 2
其中 是某个潜在特征,、 是先验的超参数。为说明这与我们的结果相符,考虑带共轭先验的指数族,此时可以解析计算 (2) 中的积分。在这一特殊情形下,,且 。若把 边缘化掉,就会得到与定理 2 完全相同的形式
Representer theorem and kernel machines. Support distribution machines use as the prediction function [8, 10], where , are distributions and . In practice, the , distributions are never given to us explicitly, usually only i.i.d. sample sets are available from these distributions, and therefore we need to estimate kernel using these samples. A popular approach is to use , where is another kernel operating on the samples and . Now, these prediction functions can be seen fitting into the structure of our Theorem.
表示定理与核方法. 支持向量分布机使用 作为预测函数[8, 10],其中 、 是分布,。实践中,、 从来不会被显式给出,通常只能从这些分布中得到独立同分布的样本集合,因此需要用这些样本来估计核 。一种常见做法是使用 ,其中 是作用在样本 和 上的另一个核。这些预测函数可以看成落入我们定理所给出的结构。
Spectral methods. A consequence of the polynomial decomposition is that spectral methods [11] can be viewed as a special case of the mapping : in that case one can compute polynomials, usually only up to a relatively low degree (such as ), to perform inference about statistical properties of the distribution. The statistics are exchangeable in the data, hence they could be represented by the above map.
谱方法. 多项式分解的一个推论是,谱方法[11]可以看成映射 的特例:此时可以计算多项式,通常只到相对较低的次数(例如 ),来推断分布的统计性质。这些统计量对数据是可交换的,因此可以用上面的映射来表示。
3 Deep Sets
3.1 Architecture
3.1 结构
Invariant model. The structure of permutation invariant functions in Theorem 2 hints at a general strategy for inference over sets of objects, which we call DeepSets. Replacing and by universal approximators leaves matters unchanged, since, in particular, and can be used to approximate arbitrary polynomials. Then, it remains to learn these approximators, yielding in the following model:
不变模型. 定理 2 中排列不变函数的结构,提示了一种在对象集合上做推断的通用策略,我们称之为 DeepSets。用万能逼近器替换 和 并不改变结论,因为特别地, 和 可以用来逼近任意多项式。接下来只需学习这些逼近器,从而得到下面的模型:
- Each instance is transformed (possibly by several layers) into some representation .
- 每个实例 被变换(可以经过若干层)成某个表示 。
- The representations are added up and the output is processed using the network in the same manner as in any deep network (e.g. fully connected layers, nonlinearities, etc.).
- 把表示 加起来,再用 网络按普通深度网络的方式处理输出(例如全连接层、非线性等)。
- Optionally: If we have additional meta-information , then the above mentioned networks could be conditioned to obtain the conditioning mapping .
- 可选:若还有额外的元信息 ,可以把上述网络做成条件化的,得到条件映射 。
In other words, the key is to add up all representations and then apply nonlinear transformations.
换句话说,关键是把所有表示加起来,再施加非线性变换。
Equivariant model. Our goal is to design neural network layers that are equivariant to the permutations of elements in the input . Based on Lemma 3, a neural network layer is permutation equivariant if and only if all the off-diagonal elements of are tied together and all the diagonal elements are equal as well, i.e., for . This function is simply a non-linearity applied to a weighted combination of (i) its input and; (ii) the sum of input values . Since summation does not depend on the permutation, the layer is permutation-equivariant. We can further manipulate the operations and parameters in this layer to get other variations, e.g.:
等变模型. 我们的目标是设计对输入 中元素排列等变的神经网络层。根据引理 3,神经网络层 排列等变,当且仅当 的所有非对角元绑在一起,并且所有对角元也相等,即 ,其中 。这个函数不过是把非线性作用在以下两项的加权组合上:(i) 它的输入 ;(ii) 输入值的和 。由于求和与排列无关,该层是排列等变的。我们还可以进一步改写这一层中的运算和参数,得到其他变体,例如:
where the maxpooling operation over elements of the set (similar to sum) is commutative. In practice, this variation performs better in some applications. This may be due to the fact that for , the input to the non-linearity is max-normalized. Since composition of permutation equivariant functions is also permutation equivariant, we can build DeepSets by stacking such layers.
其中对集合元素做最大化池化(与求和类似)是可交换的。实践中,这一变体在某些应用上表现更好。这可能是因为当 时,非线性的输入是经过最大化归一的。由于排列等变函数的复合仍然排列等变,我们可以通过叠这样的层来构造 DeepSets。
3.2 Other Related Works
3.2 其他相关工作
Several recent works study equivariance and invariance in deep networks w.r.t. general group of transformations [12–14]. For example, [15] construct deep permutation invariant features by pairwise coupling of features at the previous layer, where is invariant to transposition of and . Pairwise interactions within sets have also been studied in [16, 17]. [18] approach unordered instances by finding “good” orderings.
若干近期工作研究深度网络相对于一般变换群的等变性与不变性[12–14]。例如,[15] 通过把上一层特征做两两耦合来构造深度排列不变特征,其中 对交换 与 不变。集合内部的成对交互也在 [16, 17] 中讨论过。[18] 则通过寻找“好的”排序来处理无序实例。
The idea of pooling a function across set-members is not new. In [19], pooling was used binary classification task for causality on a set of samples. [20] use pooling across a panoramic projection of 3D object for classification, while [21] perform pooling across multiple views. [22] observe the invariance of the payoff matrix in normal form games to the permutation of its rows and columns (i.e. player actions) and leverage pooling to predict the player action. The need of permutation equivariance also arise in deep learning over sensor networks and multi-agent setings, where a special case of Lemma 3 has been used as the architecture [23].
在集合成员上对某个函数做池化,这一想法并不新。[19] 在一组样本上的因果二分类任务中使用了池化。[20] 对三维物体的全景投影做池化以进行分类,[21] 则在多个视图上做池化。[22] 观察到正规形式博弈中支付矩阵对行和列(即参与人行动)的排列不变,并利用池化来预测参与人行动。在传感器网络和多智能体设定的深度学习中,同样需要排列等变性,那里把引理 3 的一个特例用作网络结构[23]。
In light of these related works, we would like to emphasize our novel contributions: (i) the universality result of Theorem 2 for permutation invariance that also relates DeepSets to other machine learning techniques, see Sec. 3; (ii) the permutation equivariant layer of (4), which, according to Lemma 3 identifies necessary and sufficient form of parameter-sharing in a standard neural layer and; (iii) novel application settings that we study next.
对照这些相关工作,我们想强调本文的新贡献:(i) 定理 2 关于排列不变性的普适性结果,它也把 DeepSets 与其他机器学习技术联系起来,见第 3 节;(ii) (4) 中的排列等变层,根据引理 3,它刻画了标准神经层中参数共享的必要且充分形式;(iii) 我们接下来研究的新应用设定。
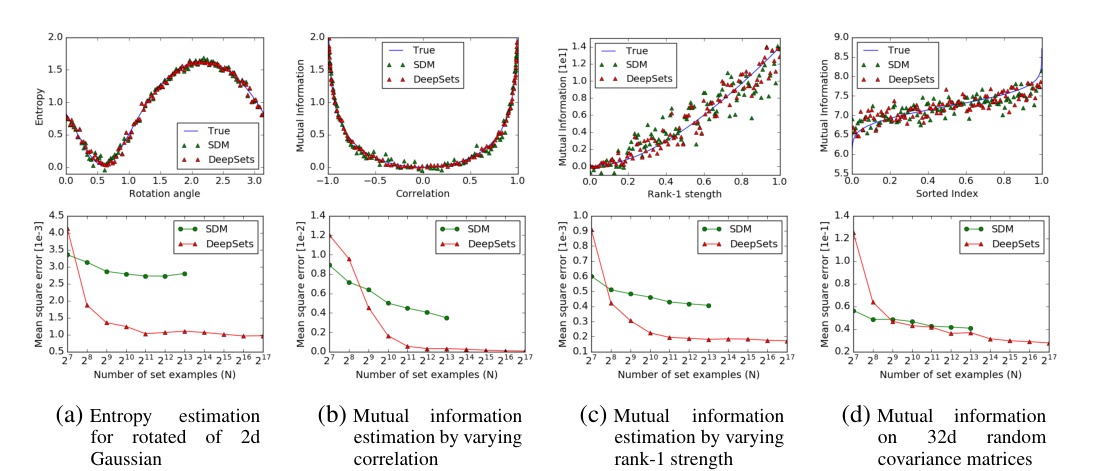
Figure 1: Population statistic estimation: Top set of figures, show prediction of DeepSets vs SDM for case. Bottom set of figures, depict the mean squared error behavior as number of sets is increased. SDM has lower error for small and DeepSets requires more data to reach similar accuracy. But for high dimensional problems DeepSets easily scales to large number of examples and produces much lower estimation error. Note that the matrix inversion in SDM makes it prohibitively expensive for .
图 1:总体统计量估计:上排图给出 时 DeepSets 与 SDM 的预测。下排图给出均方误差随集合数目增加的变化。 较小时 SDM 误差更低,DeepSets 需要更多数据才能达到相近精度。但在高维问题上,DeepSets 容易扩展到大量样本,并给出低得多的估计误差。注意 SDM 中要对 矩阵求逆,当 时代价高到难以承受。
4 Applications and Empirical Results
4 应用与实证结果
We present a diverse set of applications for DeepSets. For the supervised setting, we apply DeepSets to estimation of population statistics, sum of digits and classification of point-clouds, and regression with clustering side-information. The permutation-equivariant variation of DeepSets is applied to the task of outlier detection. Finally, we investigate the application of DeepSets to unsupervised set-expansion, in particular, concept-set retrieval and image tagging. In most cases we compare our approach with the state-of-the art and report competitive results.
我们为 DeepSets 展示一组多样化的应用。在监督设定下,把 DeepSets 用于总体统计量估计、数字求和、点云分类,以及带聚类辅助信息的回归。排列等变的 DeepSets 变体用于异常检测。最后,我们考察 DeepSets 在无监督集合扩展上的应用,尤其是概念集合检索和图像标注。多数情形下,我们与当时最好的方法比较,并报告有竞争力的结果。
4.1 Set Input Scalar Response
4.1 集合输入、标量响应
4.1.1 Supervised Learning: Learning to Estimate Population Statistics
4.1.1 监督学习:学习估计总体统计量
In the first experiment, we learn entropy and mutual information of Gaussian distributions, without providing any information about Gaussianity to DeepSets. The Gaussians are generated as follows:
在第一个实验中,我们学习高斯分布的熵和互信息,但不向 DeepSets 提供任何关于高斯性的信息。高斯分布按如下方式生成:
- Rotation: We randomly chose a covariance matrix , and then generated sample sets from of size for random values of . Our goal was to learn the entropy of the marginal distribution of first dimension. is the rotation matrix.
- 旋转: 我们随机选取一个 协方差矩阵 ,再对 个随机的 ,从 中生成大小为 的 个样本集合。目标是学习第一维边际分布的熵。 是旋转矩阵。
- Correlation: We randomly chose a covariance matrix for , and then generated sample sets from of size for random values of . Goal was to learn the mutual information of among the first and last dimension.
- 相关: 对 ,我们随机选取一个 协方差矩阵 ,再对 个随机的 ,从 中生成大小为 的 个样本集合。目标是学习前 维与后 维之间的互信息。
- Rank 1: We randomly chose and then generated a sample sets from of size for random values of . Goal was to learn the mutual information.
- 秩 1: 我们随机选取 ,再对 个随机的 ,从 中生成大小为 的样本集合。目标是学习互信息。
- Random: We chose random covariance matrices for , and using each, generated a sample set from of size . Goal was to learn the mutual information.
- 随机: 对 ,我们选取 个随机的 协方差矩阵 ,并用每一个从 中生成大小为 的样本集合。目标是学习互信息。
We train using loss with a DeepSets architecture having 3 fully connected layers with ReLU activation for both transformations and . We compare against Support Distribution Machines (SDM) using a RBF kernel [10], and analyze the results in Fig. 1.
我们用 损失训练,DeepSets 结构中 和 两个变换都采用 3 个带 ReLU 激活的全连接层。对照是使用 RBF 核的支持向量分布机(SDM)[10],结果在图 1 中分析。
4.1.2 Sum of Digits
4.1.2 数字求和
Next, we compare to what happens if our set data is treated as a sequence. We consider the task of finding sum of a given set of digits. We consider two variants of this experiment:
接下来,我们比较如果把集合数据当成序列会怎样。任务是求给定一组数字的和。这个实验考虑两种变体:
Text. We randomly sample a subset of maximum digits from this dataset to build 100k “sets” of training images, where the set-label is sum of digits in that set. We test against sums of digits, for starting from 5 all the way up to 100 over another 100k examples.
文本. 我们从该数据集中随机抽取最多 个数字,构造 10 万个训练“集合”,集合标签是该集合中数字之和。测试时,对 从 5 一直到 100,在另外 10 万个例子上求 个数字之和。
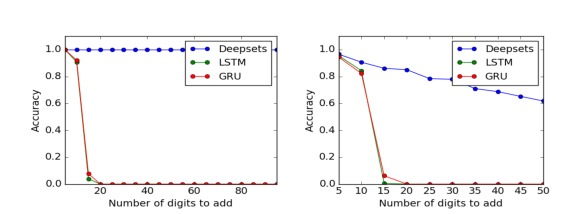
Figure 2: Accuracy of digit summation with text (left) and image (right) inputs. All approaches are trained on tasks of length 10 at most, tested on examples of length up to 100. We see that DeepSets generalizes better.
图 2:文本(左)和图像(右)输入上数字求和的准确率。所有方法都在长度至多为 10 的任务上训练,在长度直到 100 的例子上测试。可以看到 DeepSets 泛化更好。
Image. MNIST8m [24] contains 8 million instances of grey-scale stamps of digits in . We randomly sample a subset of maximum images from this dataset to build k “sets” of training and 100k sets of test images, where the set-label is the sum of digits in that set (i.e. individual labels per image is unavailable). We test against sums of images of MNIST digits, for starting from 5 all the way up to 50.
图像. MNIST8m [24] 包含 800 万张 的灰度数字图章,数字属于 。我们从该数据集中随机抽取最多 张图像,构造 万个训练“集合”和 10 万个测试集合,集合标签是该集合中数字之和(也就是说,单张图像的标签不可用)。测试时,对 从 5 一直到 50,求 张 MNIST 数字图像之和。
We compare against recurrent neural networks – LSTM and GRU. All models are defined to have similar number of layers and parameters. The output of all models is a scalar, predicting the sum of digits. Training is done on tasks of length 10 at most, while at test time we use examples of length up to 100. The accuracy, i.e. exact equality after rounding, is shown in Fig. 2. DeepSets generalize much better. Note for image case, the best classification error for single digit is around for MNIST8m, so in a collection of of images at least one image will be misclassified is , which is 40% for . This matches closely with observed value in Fig. 2(b).
对照是循环神经网络,即 LSTM 和 GRU。所有模型设定为层数和参数量相近。所有模型的输出都是一个标量,预测 个数字之和。训练只在长度至多为 10 的任务上进行,测试时使用长度直到 100 的例子。准确率,即四舍五入后完全相等,见图 2。DeepSets 的泛化好得多。注意在图像情形中,MNIST8m 上单张数字最好的分类误差大约是 ,因此在 张图像的集合里至少错一张的概率是 ,当 时为 40%。这与图 2(b) 中观察到的数值相当接近。
4.1.3 Point Cloud Classification
4.1.3 点云分类
A point-cloud is a set of low-dimensional vectors. This type of data is frequently encountered in various applications like robotics, vision, and cosmology. In these applications, existing methods often convert the point-cloud data to voxel or mesh representation as a preprocessing step, e.g. [26, 29, 30]. Since the output of many range sensors, such as LiDAR, is in the form of point-cloud, direct application of deep learning methods to point-cloud is highly desirable. Moreover, it is easy and cheaper to apply transformations, such as rotation and translation, when working with point-clouds than voxelized 3D objects.
点云是一组低维向量。这类数据在机器人、视觉和宇宙学等应用中经常出现。在这些应用里,已有方法常常先把点云转换成体素或网格表示,例如 [26, 29, 30]。由于许多测距传感器(例如 LiDAR)的输出本身就是点云,直接把深度学习方法用在点云上非常值得追求。而且,在点云上施加旋转和平移一类变换,也比在体素化的三维物体上更容易、更便宜。
Table 1: Classification accuracy and the representation-size used by different methods on the ModelNet40.
| Model | Instance Size | Representation | Accuracy |
|---|---|---|---|
| 3DShapeNets [25] | voxels (using convolutional deep belief net) | 77% | |
| VoxNet [26] | voxels (voxels from point-cloud + 3D CNN) | 83.10% | |
| MVCNN [21] | multi-view images (2D CNN + view-pooling) | 90.1% | |
| VRN Ensemble [27] | voxels (3D CNN, variational autoencoder) | 95.54% | |
| 3D GAN [28] | voxels (3D CNN, generative adversarial training) | 83.3% | |
| DeepSets | point-cloud | ||
| DeepSets | point-cloud |
表 1:不同方法在 ModelNet40 上的分类准确率及其所用表示的大小。
| 模型 | 实例大小 | 表示 | 准确率 |
|---|---|---|---|
| 3DShapeNets [25] | 体素(使用卷积深度信念网) | 77% | |
| VoxNet [26] | 体素(由点云得到的体素 + 三维 CNN) | 83.10% | |
| MVCNN [21] | 多视图图像(二维 CNN + 视图池化) | 90.1% | |
| VRN Ensemble [27] | 体素(三维 CNN,变分自编码器) | 95.54% | |
| 3D GAN [28] | 体素(三维 CNN,生成对抗训练) | 83.3% | |
| DeepSets | 点云 | ||
| DeepSets | 点云 |
As point-cloud data is just a set of points, we can use DeepSets to classify point-cloud representation of a subset of ShapeNet objects [31], called ModelNet40 [25]. This subset consists of 3D representation of 9,843 training and 2,468 test instances belonging to 40 classes of objects. We produce point-clouds with 100, 1000 and 5000 particles each (-coordinates) from the mesh representation of objects using the point-cloud-library’s sampling routine [32]. Each set is normalized by the initial layer of the deep network to have zero mean (along individual axes) and unit (global) variance. Tab. 1 compares our method using three permutation equivariant layers against the competition; see Appendix H for details.
点云数据不过是一组点,因此可以用 DeepSets 来分类 ShapeNet 物体子集[31]的点云表示,该子集称为 ModelNet40 [25]。它包含属于 40 类物体的 9,843 个训练实例和 2,468 个测试实例的三维表示。我们用点云库的采样程序[32],从物体的网格表示生成分别含 100、1000 和 5000 个粒子( 坐标)的点云。每个集合由深度网络的第一层归一化,使各轴均值为零、全局方差为 1。表 1 把我们使用三层排列等变层的方法与对照方法进行比较;细节见附录 H。
4.1.4 Improved Red-shift Estimation Using Clustering Information
4.1.4 利用聚类信息改进红移估计
An important regression problem in cosmology is to estimate the red-shift of galaxies, corresponding to their age as well as their distance from us [33] based on photometric observations. One way to estimate the red-shift from photometric observations is using a regression model [34] on the galaxy clusters. The prediction for each galaxy does not change by permuting the members of the galaxy cluster. Therefore, we can treat each galaxy cluster as a “set” and use DeepSets to estimate the individual galaxy red-shifts. See Appendix G for more details.
宇宙学中一个重要的回归问题,是根据测光观测估计星系的红移,红移对应它们的年龄以及与我们的距离[33]。从测光观测估计红移的一种做法,是在星系团上使用回归模型[34]。对每个星系的预测,不会因为把星系团成员重新排列而改变。因此可以把每个星系团看成一个“集合”,用 DeepSets 估计单个星系的红移。更多细节见附录 G。
For each galaxy, we have 17 photometric features from the redMaPPer galaxy cluster catalog [35] that contains photometric readings for 26,111 red galaxy clusters. Each galaxy-cluster in this catalog has between galaxies – i.e. , where is the cluster-size. The catalog also provides accurate spectroscopic red-shift estimates for a subset of these galaxies.
对每个星系,我们从 redMaPPer 星系团目录[35]中取 17 个测光特征,该目录包含 26,111 个红色星系团的测光读数。目录中每个星系团有大约 个星系,即 ,其中 是团的大小。该目录还为其中一部分星系提供了精确的光谱红移估计。
Table 2: Red-shift experiment. Lower scatter is better.
| Method | Scatter |
|---|---|
| MLP | 0.026 |
| redMaPPer | 0.025 |
| DeepSets | 0.023 |
表 2:红移实验。scatter 越低越好。
| 方法 | Scatter |
|---|---|
| MLP | 0.026 |
| redMaPPer | 0.025 |
| DeepSets | 0.023 |
We randomly split the data into 90% training and 10% test clusters, and minimize the squared loss of the prediction for available spectroscopic red-shifts. As it is customary in cosmology literature, we report the average scatter , where is the accurate spectroscopic measurement and is a photometric estimate in Tab. 2.
我们把数据随机划分成 90% 的训练星系团和 10% 的测试星系团,并对已有光谱红移的预测最小化平方损失。按宇宙学文献的惯例,我们在表 2 中报告平均 scatter ,其中 是精确的光谱测量, 是测光估计。
Table 3: Results on Text Concept Set Retrieval on LDA-1k, LDA-3k, and LDA-5k. Our DeepSets model outperforms other methods on LDA-3k and LDA-5k. However, all neural network based methods have inferior performance to w2v-Near baseline on LDA-1k, possibly due to small data size. Higher the better for recall@ and mean reciprocal rank (MRR). Lower the better for median rank (Med.)
| Method | LDA-1k (Vocab = 17k) | LDA-3k (Vocab = 38k) | LDA-5k (Vocab = 61k) | ||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Recall (%) | MRR | Med. | Recall (%) | MRR | Med. | Recall (%) | MRR | Med. | |||||||
| @10 | @100 | @1k | @10 | @100 | @1k | @10 | @100 | @1k | |||||||
| Random | 0.06 | 0.6 | 5.9 | 0.001 | 8520 | 0.02 | 0.2 | 2.6 | 0.000 | 28635 | 0.01 | 0.2 | 1.6 | 0.000 | 30600 |
| Bayes Set | 1.69 | 11.9 | 37.2 | 0.007 | 2848 | 2.01 | 14.5 | 36.5 | 0.008 | 3234 | 1.75 | 12.5 | 34.5 | 0.007 | 3590 |
| w2v Near | 6.00 | 28.1 | 54.7 | 0.021 | 641 | 4.80 | 21.2 | 43.2 | 0.016 | 2054 | 4.03 | 16.7 | 35.2 | 0.013 | 6900 |
| NN-max | 4.78 | 22.5 | 53.1 | 0.023 | 779 | 5.30 | 24.9 | 54.8 | 0.025 | 672 | 4.72 | 21.4 | 47.0 | 0.022 | 1320 |
| NN-sum-con | 4.58 | 19.8 | 48.5 | 0.021 | 1110 | 5.81 | 27.2 | 60.0 | 0.027 | 453 | 4.87 | 23.5 | 53.9 | 0.022 | 731 |
| NN-max-con | 3.36 | 16.9 | 46.6 | 0.018 | 1250 | 5.61 | 25.7 | 57.5 | 0.026 | 570 | 4.72 | 22.0 | 51.8 | 0.022 | 877 |
| DeepSets | 5.53 | 24.2 | 54.3 | 0.025 | 696 | 6.04 | 28.5 | 60.7 | 0.027 | 426 | 5.54 | 26.1 | 55.5 | 0.026 | 616 |
表 3:在 LDA-1k、LDA-3k 和 LDA-5k 上的文本概念集合检索结果。我们的 DeepSets 模型在 LDA-3k 和 LDA-5k 上超过其他方法。不过,所有基于神经网络的方法在 LDA-1k 上都不如 w2v-Near 基线,这可能是因为数据量较小。recall@ 和平均倒数排名(MRR)越高越好。中位排名(Med.)越低越好。
| 方法 | LDA-1k(词表 = 17k) | LDA-3k(词表 = 38k) | LDA-5k(词表 = 61k) | ||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Recall (%) | MRR | Med. | Recall (%) | MRR | Med. | Recall (%) | MRR | Med. | |||||||
| @10 | @100 | @1k | @10 | @100 | @1k | @10 | @100 | @1k | |||||||
| Random | 0.06 | 0.6 | 5.9 | 0.001 | 8520 | 0.02 | 0.2 | 2.6 | 0.000 | 28635 | 0.01 | 0.2 | 1.6 | 0.000 | 30600 |
| Bayes Set | 1.69 | 11.9 | 37.2 | 0.007 | 2848 | 2.01 | 14.5 | 36.5 | 0.008 | 3234 | 1.75 | 12.5 | 34.5 | 0.007 | 3590 |
| w2v Near | 6.00 | 28.1 | 54.7 | 0.021 | 641 | 4.80 | 21.2 | 43.2 | 0.016 | 2054 | 4.03 | 16.7 | 35.2 | 0.013 | 6900 |
| NN-max | 4.78 | 22.5 | 53.1 | 0.023 | 779 | 5.30 | 24.9 | 54.8 | 0.025 | 672 | 4.72 | 21.4 | 47.0 | 0.022 | 1320 |
| NN-sum-con | 4.58 | 19.8 | 48.5 | 0.021 | 1110 | 5.81 | 27.2 | 60.0 | 0.027 | 453 | 4.87 | 23.5 | 53.9 | 0.022 | 731 |
| NN-max-con | 3.36 | 16.9 | 46.6 | 0.018 | 1250 | 5.61 | 25.7 | 57.5 | 0.026 | 570 | 4.72 | 22.0 | 51.8 | 0.022 | 877 |
| DeepSets | 5.53 | 24.2 | 54.3 | 0.025 | 696 | 6.04 | 28.5 | 60.7 | 0.027 | 426 | 5.54 | 26.1 | 55.5 | 0.026 | 616 |
4.2 Set Expansion
4.2 集合扩展
In the set expansion task, we are given a set of objects that are similar to each other and our goal is to find new objects from a large pool of candidates such that the selected new objects are similar to the query set. To achieve this one needs to reason out the concept connecting the given set and then retrieve words based on their relevance to the inferred concept. It is an important task due to wide range of potential applications including personalized information retrieval, computational advertisement, tagging large amounts of unlabeled or weakly labeled datasets.
在集合扩展任务中,给定一组彼此相似的对象,目标是从大量候选中找出与查询集合相似的新对象。为此,需要推断把给定集合联系起来的概念,再按与该概念的相关程度检索词语。这一任务之所以重要,是因为它有广泛的潜在应用,包括个性化信息检索、计算广告,以及对大量未标注或弱标注数据做标注。
Going back to de Finetti’s theorem in Sec. 3.2, where we consider the marginal probability of a set of observations, the marginal probability allows for very simple metric for scoring additional elements to be added to . In other words, this allows one to perform set expansion via the following score
回到第 3.2 节的 de Finetti 定理,我们在那里考虑一组观测的边际概率。边际概率给出一种非常简单的度量,用来给要加入 的新元素打分。换句话说,可以用下面的分数来做集合扩展
Note that is the point-wise mutual information between and . Moreover, due to exchangeability, it follows that regardless of the order of elements we have
注意 是 与 之间的逐点互信息。而且,由于可交换性,无论元素次序如何,都有
When inferring sets, our goal is to find set completions for an initial set of query terms , such that the aggregate set is coherent. This is the key idea of the Bayesian Set algorithm [36] (details in Appendix D). Using DeepSets, we can solve this problem in more generality as we can drop the assumption of data belonging to certain exponential family.
在推断集合时,目标是为初始查询词集合 找到补全 ,使整个集合保持一致。这是 Bayesian Set 算法[36]的核心想法(细节见附录 D)。使用 DeepSets,我们可以更一般地解决这个问题,因为不必再假定数据属于某个指数族。
For learning the score , we take recourse to large-margin classification with structured loss functions [37] to obtain the relative loss objective . In other words, we want to ensure that whenever should be added and should not be added to .
为了学习分数 ,我们借助带结构化损失的大间隔分类[37],得到相对损失目标 。换句话说,每当应当把 加入 、而不应当加入 时,我们希望保证 。
Conditioning. Often machine learning problems do not exist in isolation. For example, task like tag completion from a given set of tags is usually related to an object , for example an image, that needs to be tagged. Such meta-data are usually abundant, e.g. author information in case of text, contextual data such as the user click history, or extra information collected with LiDAR point cloud.
条件化. 机器学习问题常常不是孤立存在的。例如,从一组已有标签做标签补全,通常与某个需要被标注的对象 相关,比如一张图像。这类元数据往往很丰富,例如文本中的作者信息、用户点击历史一类上下文数据,或与 LiDAR 点云一同采集的额外信息。
Conditioning graphical models with meta-data is often complicated. For instance, in the Beta-Binomial model we need to ensure that the counts are always nonnegative, regardless of . Fortunately, DeepSets does not suffer from such complications and the fusion of multiple sources of data can be done in a relatively straightforward manner. Any of the existing methods in deep learning, including feature concatenation by averaging, or by max-pooling, can be employed. Incorporating these metadata often leads to significantly improved performance as will be shown in experiments; Sec. 4.2.2.
用元数据对图模型做条件化往往很复杂。例如在 Beta-Binomial 模型中,必须保证计数无论 如何都始终非负。幸运的是,DeepSets 没有这类麻烦,多种数据源的融合可以用相对直接的方式完成。深度学习里已有的方法,包括通过平均或最大化池化做特征拼接,都可以使用。纳入这些元数据往往会显著提升性能,实验将表明这一点;见第 4.2.2 节。
4.2.1 Text Concept Set Retrieval
4.2.1 文本概念集合检索
In text concept set retrieval, the objective is to retrieve words belonging to a ‘concept’ or ‘cluster’, given few words from that particular concept. For example, given the set of words , we would need to retrieve other related words like , , etc, which belong to the same concept of big cats. This task of concept set retrieval can be seen as a set completion task conditioned on the latent semantic concept, and therefore our DeepSets form a desirable approach.
在文本概念集合检索中,目标是在给定某“概念”或“簇”中的几个词之后,检索属于该概念的其他词。例如,给定词集合 ,需要检索同属大型猫科这一概念的 、 等词。这一概念集合检索任务可以看成以潜在语义概念为条件的集合补全,因此我们的 DeepSets 是合适的方法。
Dataset. We construct a large dataset containing sets of related words by extracting topics from latent Dirichlet allocation [38, 39], taken out-of-the-box. To compare across scales, we consider three values of giving us three datasets LDA-1k, LDA-3k, and LDA-5k, with corresponding vocabulary sizes of 17k, 38k, and 61k.
数据集. 我们用开箱即用的潜在狄利克雷分配[38, 39]抽出主题,构造一个包含 个相关词集合的大型数据集。为了在不同尺度上比较,我们取三个 ,得到三个数据集 LDA-1k、LDA-3k 和 LDA-5k,对应词表大小分别为 17k、38k 和 61k。
github.com/dmlc/experimental-lda
Methods. We learn this using a margin loss with a DeepSets architecture having 3 fully connected layers with ReLU activation for both transformations and . Details of the architecture and training are in Appendix E. We compare to several baselines: (a) Random picks a word from the vocabulary uniformly at random. (b) Bayes Set [36]. (c) w2v-Near computes the nearest neighbors in the word2vec [40] space. Note that both Bayes Set and w2v NN are strong baselines. The former runs Bayesian inference using Beta-Binomial conjugate pair, while the latter uses the powerful 300 dimensional word2vec trained on the billion word GoogleNews corpus. (d) NN-max uses a similar architecture as our DeepSets but uses max pooling to compute the set feature, as opposed to sum pooling. (e) NN-max-con uses max pooling on set elements but concatenates this pooled representation with that of query for a final set feature. (f) NN-sum-con is similar to NN-max-con but uses sum pooling followed by concatenation with query representation.
方法. 我们用间隔损失来学习,DeepSets 结构中 和 两个变换都采用 3 个带 ReLU 激活的全连接层。结构和训练细节见附录 E。我们与若干基线比较:(a) Random 从词表中均匀随机取一个词。(b) Bayes Set [36]。(c) w2v-Near 在 word2vec [40] 空间中计算最近邻。注意 Bayes Set 和 w2v NN 都是很强的基线。前者用 Beta-Binomial 共轭对做贝叶斯推断,后者使用在十亿词 GoogleNews 语料上训练的 300 维 word2vec。(d) NN-max 使用与我们的 DeepSets 相似的结构,但用最大化池化而不是求和池化来计算集合特征。(e) NN-max-con 对集合成员做最大化池化,再把该池化表示与查询表示拼接,作为最终的集合特征。(f) NN-sum-con 与 NN-max-con 类似,但先做求和池化,再与查询表示拼接。
Evaluation. We consider the standard retrieval metrics – recall@, median rank and mean reciprocal rank, for evaluation. To elaborate, recall@ measures the number of true labels that were recovered in the top retrieved words. We use three values of . The other two metrics, as the names suggest, are the median and mean of reciprocals of the true label ranks, respectively. Each dataset is split into TRAIN (80%), VAL (10%) and TEST (10%). We learn models using TRAIN and evaluate on TEST, while VAL is used for hyperparameter selection and early stopping.
评价. 我们采用标准的检索指标做评价:recall@、中位排名和平均倒数排名。具体来说,recall@ 衡量在检索出的前 个词中恢复了多少真实标签。我们使用三个 。另外两个指标顾名思义,分别是真实标签排名的中位数,以及排名倒数的均值。每个数据集合被划分成 TRAIN(80%)、VAL(10%)和 TEST(10%)。模型在 TRAIN 上学习,在 TEST 上评价,VAL 用于超参数选择和早停。
Results and Observations. As seen in Tab. 3: (a) Our DeepSets model outperforms all other approaches on LDA-3k and LDA-5k by any metric, highlighting the significance of permutation invariance property. (b) On LDA-1k, our model does not perform well when compared to w2v-Near. We hypothesize that this is due to small size of the dataset insufficient to train a high capacity neural network, while w2v-Near has been trained on a billion word corpus. Nevertheless, our approach comes the closest to w2v-Near amongst other approaches, and is only 0.5% lower by Recall@10.
结果与观察. 如表 3 所示:(a) 我们的 DeepSets 模型在 LDA-3k 和 LDA-5k 上按所有指标都超过其他方法,突出了排列不变性质的重要性。(b) 在 LDA-1k 上,与 w2v-Near 相比我们的模型表现不好。我们猜想这是因为数据规模太小,不足以训练高容量的神经网络,而 w2v-Near 是在十亿词语料上训练的。尽管如此,在其他方法中我们的结果最接近 w2v-Near,按 Recall@10 只低 0.5%。
4.2.2 Image Tagging
4.2.2 图像标注
We next experiment with image tagging, where the task is to retrieve all relevant tags corresponding to an image. Images usually have only a subset of relevant tags, therefore predicting other tags can help enrich information that can further be leveraged in a downstream supervised task. In our setup, we learn to predict tags by conditioning DeepSets on the image, i.e., we train to predict a partial set of tags from the image and remaining tags. At test time, we predict tags from the image alone.
接下来我们做图像标注实验,任务是检索与一张图像相关的全部标签。图像通常只带有一部分相关标签,因此预测其他标签可以帮助丰富信息,并进一步用于下游监督任务。在我们的设定中,通过对图像做条件化来学习用 DeepSets 预测标签,也就是训练时根据图像和一部分标签来预测其余标签。测试时,只根据图像预测标签。
Table 4: Results of image tagging on ESPgame and IAPRTC-12.5 datasets. Performance of our DeepSets approach is roughly similar to the best competing approaches, except for precision. Higher the better for all metrics – precision (P), recall (R), f1 score (F1), and number of non-zero recall tags (N+).
| Method | ESP game | IAPRTC-12.5 | ||||||
|---|---|---|---|---|---|---|---|---|
| P | R | F1 | N+ | P | R | F1 | N+ | |
| Least Sq. | 35 | 19 | 25 | 215 | 40 | 19 | 26 | 198 |
| MBRM | 18 | 19 | 18 | 209 | 24 | 23 | 23 | 223 |
| JEC | 24 | 19 | 21 | 222 | 29 | 19 | 23 | 211 |
| FastTag | 46 | 22 | 30 | 247 | 47 | 26 | 34 | 280 |
| Least Sq.(D) | 44 | 32 | 37 | 232 | 46 | 30 | 36 | 218 |
| FastTag(D) | 44 | 32 | 37 | 229 | 46 | 33 | 38 | 254 |
| DeepSets | 39 | 34 | 36 | 246 | 42 | 31 | 36 | 247 |
表 4:在 ESPgame 和 IAPRTC-12.5 数据集上的图像标注结果。我们的 DeepSets 方法在除精确率外的各项指标上,与最好的对照方法大致相当。所有指标都是越高越好:精确率(P)、召回率(R)、F1 分数(F1),以及召回非零的标签数(N+)。
| 方法 | ESP game | IAPRTC-12.5 | ||||||
|---|---|---|---|---|---|---|---|---|
| P | R | F1 | N+ | P | R | F1 | N+ | |
| Least Sq. | 35 | 19 | 25 | 215 | 40 | 19 | 26 | 198 |
| MBRM | 18 | 19 | 18 | 209 | 24 | 23 | 23 | 223 |
| JEC | 24 | 19 | 21 | 222 | 29 | 19 | 23 | 211 |
| FastTag | 46 | 22 | 30 | 247 | 47 | 26 | 34 | 280 |
| Least Sq.(D) | 44 | 32 | 37 | 232 | 46 | 30 | 36 | 218 |
| FastTag(D) | 44 | 32 | 37 | 229 | 46 | 33 | 38 | 254 |
| DeepSets | 39 | 34 | 36 | 246 | 42 | 31 | 36 | 247 |
Datasets. We report results on the following three datasets – ESPGame, IAPRTC-12.5 and our in-house dataset, COCO-Tag. We refer the reader to Appendix F, for more details about datasets.
数据集. 我们在以下三个数据集上报告结果:ESPGame、IAPRTC-12.5,以及我们自己的数据集 COCO-Tag。更多数据集细节见附录 F。
Methods. The setup for DeepSets to tag images is similar to that described in Sec. 4.2.1. The only difference being the conditioning on the image features, which is concatenated with the set feature obtained from pooling individual element representations.
方法. 用 DeepSets 为图像打标签的设定,与第 4.2.1 节描述的类似。唯一的差别是对图像特征做条件化:把它与由单个元素表示池化得到的集合特征拼接在一起。
Baselines. We perform comparisons against several baselines, previously reported in [41]. Specifically, we have Least Sq., a ridge regression model, MBRM [42], JEC [43] and FastTag [41]. Note that these methods do not use deep features for images, which could lead to an unfair comparison. As there is no publicly available code for MBRM and JEC, we cannot report performances of these models with Resnet extracted features. However, we report results with deep features for FastTag and Least Sq., using code made available by the authors.
基线. 我们与 [41] 中先前报告的若干基线进行比较。具体包括:Least Sq.,一种岭回归模型;MBRM [42]、JEC [43] 和 FastTag [41]。注意这些方法没有使用图像的深度特征,这可能导致比较不公平。由于 MBRM 和 JEC 没有公开代码,我们无法报告这些模型在 ResNet 提取特征上的表现。不过,我们使用作者提供的代码,报告了 FastTag 和 Least Sq. 使用深度特征的结果。
code.google.com/archive/p/word2vec/
Evaluation. For ESPGame and IAPRTC-12.5, we follow the evaluation metrics as in [44]–precision (P), recall (R), F1 score (F1), and number of tags with non-zero recall (N+). These metrics are evaluate for each tag and the mean is reported (see [44] for further details). For COCO-Tag, however, we use recall@ for three values of , along with median rank and mean reciprocal rank (see evaluation in Sec. 4.2.1 for metric details).
评价. 对 ESPGame 和 IAPRTC-12.5,我们沿用 [44] 中的评价指标:精确率(P)、召回率(R)、F1 分数(F1),以及召回非零的标签数(N+)。这些指标对每个标签计算后再取平均(更多细节见 [44])。对 COCO-Tag,我们则使用三个 的 recall@,以及中位排名和平均倒数排名(指标细节见第 4.2.1 节的评价部分)。
Results and Observations. Tab. 4 shows results of image tagging on ESPgame and IAPRTC-12.5, and Tab. 5 on COCO-Tag. Here are the key observations from Tab. 4: (a) performance of our DeepSets model is comparable to the best approaches on all metrics but precision, (b) our recall beats the best approach by 2% in ESPgame. On further investigation, we found that the DeepSets model retrieves more relevant tags, which are not present in list of ground truth tags due to a limited 5 tag annotation. Thus, this takes a toll on precision while gaining on recall, yet yielding improvement on F1. On the larger and richer COCO-Tag, we see that the DeepSets approach outperforms other methods comprehensively, as expected. Qualitative examples are in Appendix F.
结果与观察. 表 4 给出 ESPgame 和 IAPRTC-12.5 上的图像标注结果,表 5 给出 COCO-Tag 上的结果。从表 4 可以得到如下关键观察:(a) 我们的 DeepSets 模型在除精确率外的所有指标上,与最好的方法相当;(b) 在 ESPgame 上,我们的召回比最好的方法高 2%。进一步检查后发现,DeepSets 模型检索到了更多相关标签,而这些标签由于只有 5 个标签的有限标注,并不出现在真实标签列表中。因此精确率会受损,召回则上升,F1 仍有改进。在更大、更丰富的 COCO-Tag 上,正如所料,DeepSets 方法全面超过其他方法。定性例子见附录 F。
Table 5: Results on COCO-Tag dataset. Clearly, DeepSets outperforms other baselines significantly. Higher the better for recall@ and mean reciprocal rank (MRR). Lower the better for median rank (Med).
| Method | Recall | MRR | Med. | ||
|---|---|---|---|---|---|
| @10 | @100 | @1k | |||
| w2v NN (blind) | 5.6 | 20.0 | 54.2 | 0.021 | 823 |
| DeepSets (blind) | 9.0 | 39.2 | 71.3 | 0.044 | 310 |
| DeepSets | 31.4 | 73.4 | 95.3 | 0.131 | 28 |
表 5:COCO-Tag 数据集上的结果。可以清楚看到,DeepSets 显著超过其他基线。recall@ 和平均倒数排名(MRR)越高越好。中位排名(Med)越低越好。
| 方法 | Recall | MRR | Med. | ||
|---|---|---|---|---|---|
| @10 | @100 | @1k | |||
| w2v NN (blind) | 5.6 | 20.0 | 54.2 | 0.021 | 823 |
| DeepSets (blind) | 9.0 | 39.2 | 71.3 | 0.044 | 310 |
| DeepSets | 31.4 | 73.4 | 95.3 | 0.131 | 28 |
4.3 Set Anomaly Detection
4.3 集合异常检测
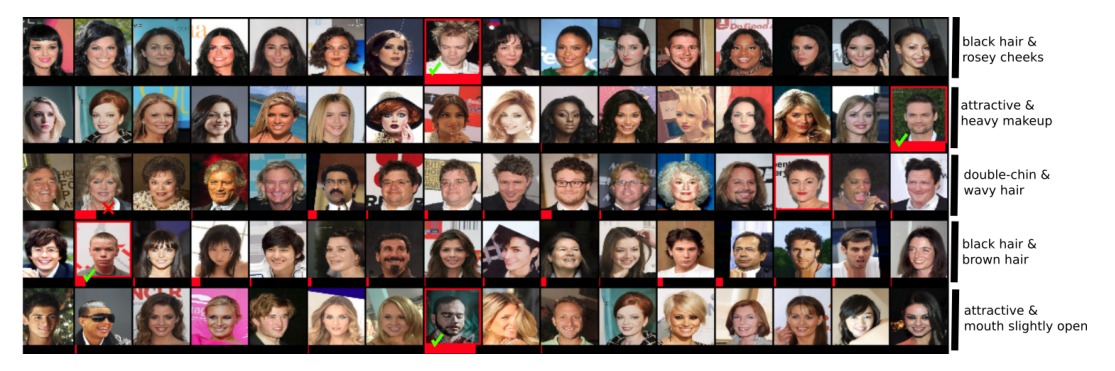
Figure 3: Each row shows a set, constructed from CelebA dataset, such that all set members except for an outlier, share at least two attributes (on the right). The outlier is identified with a red frame. The model is trained by observing examples of sets and their anomalous members, without access to the attributes. The probability assigned to each member by the outlier detection network is visualized using a red bar at the bottom of each image. The probabilities in each row sum to one.
图 3:每一行是一个从 CelebA 数据集构造的集合,除一个异常点外,所有成员至少共享两个属性(右侧标出)。异常点用红框标出。模型通过观察集合及其异常成员的例子来训练,并不能看到属性。异常检测网络给每个成员的概率,用每张图像底部的红色条显示。每一行的概率和为 1。
The objective here is to find the anomalous face in each set, simply by observing examples and without any access to the attribute values. CelebA dataset [45] contains 202,599 face images, each annotated with 40 boolean attributes. We build sets of stamps, using these attributes each containing images (on the training set) as follows: randomly select 2 attributes, draw 15 images having those attributes, and a single target image where both attributes are absent. Using a similar procedure we build sets on the test images. No individual person’s face appears in both train and test sets. Our deep neural network consists of 9 2D-convolution and max-pooling layers followed by 3 permutation-equivariant layers, and finally a softmax layer that assigns a probability value to each set member (Note that one could identify arbitrary number of outliers using a sigmoid activation at the output). Our trained model successfully finds the anomalous face in 75% of test sets. Visually inspecting these instances suggests that the task is non-trivial even for humans; see Fig. 3.
这里的目标是找出每个集合中的异常脸,只通过观察例子,而不能看到属性值。CelebA 数据集[45]包含 202,599 张人脸图像,每张标有 40 个布尔属性。我们利用这些属性构造 个 图章的集合,训练集合中每个含 张图像,做法如下:随机选 2 个属性,抽取 15 张具有这两个属性的图像,再加一张两个属性都不具备的目标图像。用类似程序在测试图像上构造集合。任何人的脸都不会同时出现在训练集和测试集中。我们的深度网络包含 9 个二维卷积和最大化池化层,再接 3 个排列等变层,最后是一个给每个集合成员赋值概率的 softmax 层(注意,若在输出端使用 sigmoid 激活,也可以识别任意数量的异常点)。训练好的模型在 75% 的测试集合中成功找到了异常脸。目视检查这些例子表明,即便对人来说,这一任务也并不轻松;见图 3。
As a baseline, we repeat the same experiment by using a set-pooling layer after convolution layers, and replacing the permutation-equivariant layers with fully connected layers of same size, where the final layer is a 16-way softmax. The resulting network shares the convolution filters for all instances within all sets, however the input to the softmax is not equivariant to the permutation of input images. Permutation equivariance seems to be crucial here as the baseline model achieves a training and test accuracy of ; the same as random selection. See Appendix I for more details.
作为基线,我们重复同一实验:在卷积层之后使用集合池化层,并把排列等变层换成同样大小的全连接层,最后一层是 16 路 softmax。得到的网络对所有集合中的所有实例共享卷积滤波器,但 softmax 的输入对输入图像的排列并不是等变的。排列等变性在这里似乎至关重要,因为基线模型的训练和测试准确率约为 ,与随机选择相同。更多细节见附录 I。
5 Summary
5 小结
In this paper, we develop DeepSets, a model based on powerful permutation invariance and equivariance properties, along with the theory to support its performance. We demonstrate the generalization ability of DeepSets across several domains by extensive experiments, and show both qualitative and quantitative results. In particular, we explicitly show that DeepSets outperforms other intuitive deep networks, which are not backed by theory (Sec. 4.2.1, Sec. 4.1.2). Last but not least, it is worth noting that the state-of-the-art we compare to is a specialized technique for each task, whereas our one model, i.e., DeepSets, is competitive across the board.
本文提出 DeepSets,这是一个建立在强排列不变性和等变性之上的模型,并有理论支撑其性能。我们通过广泛实验,展示 DeepSets 在多个领域的泛化能力,并给出定性和定量结果。特别地,我们明确表明 DeepSets 超过了其他缺乏理论支撑、仅凭直觉设计的深度网络(第 4.2.1 节、第 4.1.2 节)。最后值得指出的是,我们比较的当时最好方法,各自都是为单一任务设计的专门技术,而我们这一个模型,即 DeepSets,在各项任务上都具有竞争力。
References
参考文献
[1] B. Poczos, A. Rinaldo, A. Singh, and L. Wasserman. Distribution-free distribution regression. In International Conference on AI and Statistics (AISTATS), JMLR Workshop and Conference Proceedings, 2013. pages 1
[2] I. Jung, M. Berges, J. Garrett, and B. Poczos. Exploration and evaluation of ar, mpca and kl anomaly detection techniques to embankment dam piezometer data. Advanced Engineering Informatics, 2015. pages 1
[3] M. Ntampaka, H. Trac, D. Sutherland, S. Fromenteau, B. Poczos, and J. Schneider. Dynamical mass measurements of contaminated galaxy clusters using machine learning. The Astrophysical Journal, 2016. URL http://arxiv.org/abs/1509.05409. pages 1
[4] M. Ravanbakhsh, J. Oliva, S. Fromenteau, L. Price, S. Ho, J. Schneider, and B. Poczos. Estimating cosmological parameters from the dark matter distribution. In International Conference on Machine Learning (ICML), 2016. pages 1
[5] J. Oliva, B. Poczos, and J. Schneider. Distribution to distribution regression. In International Conference on Machine Learning (ICML), 2013. pages 1
[6] Z. Szabo, B. Sriperumbudur, B. Poczos, and A. Gretton. Learning theory for distribution regression. Journal of Machine Learning Research, 2016. pages
[7] K. Muandet, D. Balduzzi, and B. Schoelkopf. Domain generalization via invariant feature representation. In In Proceeding of the 30th International Conference on Machine Learning (ICML 2013), 2013. pages
[8] K. Muandet, K. Fukumizu, F. Dinuzzo, and B. Schoelkopf. Learning from distributions via support measure machines. In In Proceeding of the 26th Annual Conference on Neural Information Processing Systems (NIPS 2012), 2012. pages 1, 3
[9] Felix A. Faber, Alexander Lindmaa, O. Anatole von Lilienfeld, and Rickard Armiento. Machine learning energies of 2 million elpasolite (abC2D6) crystals. Phys. Rev. Lett., 117:135502, Sep 2016. doi: 10.1103/PhysRevLett.117.135502. pages 1
[10] B. Poczos, L. Xiong, D. Sutherland, and J. Schneider. Support distribution machines, 2012. URL http://arxiv.org/abs/1202.0302. pages 3, 4
[11] A. Anandkumar, R. Ge, D. Hsu, S. M. Kakade, and M. Telgarsky. Tensor decompositions for learning latent variable models. arXiv preprint arXiv:1210.7559, 2012. pages 3
[12] Robert Gens and Pedro M Domingos. Deep symmetry networks. In Advances in neural information processing systems, pages 2537–2545, 2014. pages 3
[13] Taco S Cohen and Max Welling. Group equivariant convolutional networks. arXiv preprint arXiv:1602.07576, 2016. pages
[14] Siamak Ravanbakhsh, Jeff Schneider, and Barnabas Poczos. Equivariance through parametersharing. arXiv preprint arXiv:1702.08389, 2017. pages 3
[15] Xu Chen, Xiuyuan Cheng, and Stéphane Mallat. Unsupervised deep haar scattering on graphs. In Advances in Neural Information Processing Systems, pages 1709–1717, 2014. pages 3
[16] Michael B Chang, Tomer Ullman, Antonio Torralba, and Joshua B Tenenbaum. A compositional object-based approach to learning physical dynamics. arXiv preprint arXiv:1612.00341, 2016. pages 3
[17] Nicholas Guttenberg, Nathaniel Virgo, Olaf Witkowski, Hidetoshi Aoki, and Ryota Kanai. Permutation-equivariant neural networks applied to dynamics prediction. arXiv preprint arXiv:1612.04530, 2016. pages 3
[18] Oriol Vinyals, Samy Bengio, and Manjunath Kudlur. Order matters: Sequence to sequence for sets. arXiv preprint arXiv:1511.06391, 2015. pages 3
[19] David Lopez-Paz, Robert Nishihara, Soumith Chintala, Bernhard Schölkopf, and Léon Bottou. Discovering causal signals in images. arXiv preprint arXiv:1605.08179, 2016. pages 3
[20] Baoguang Shi, Song Bai, Zhichao Zhou, and Xiang Bai. Deeppano: Deep panoramic representation for 3-d shape recognition. IEEE Signal Processing Letters, 22(12):2339–2343, 2015. pages 3, 26, 27
[21] Hang Su, Subhransu Maji, Evangelos Kalogerakis, and Erik Learned-Miller. Multi-view convolutional neural networks for 3d shape recognition. In Proceedings of the IEEE International Conference on Computer Vision, pages 945–953, 2015. pages 3, 5, 26, 27
[22] Jason S Hartford, James R Wright, and Kevin Leyton-Brown. Deep learning for predicting human strategic behavior. In Advances in Neural Information Processing Systems, pages 2424–2432, 2016. pages 3
[23] Sainbayar Sukhbaatar, Rob Fergus, et al. Learning multiagent communication with backpropagation. In Neural Information Processing Systems, pages 2244–2252, 2016. pages 3
[24] Gaëlle Loosli, Stéphane Canu, and Léon Bottou. Training invariant support vector machines using selective sampling. In Léon Bottou, Olivier Chapelle, Dennis DeCoste, and Jason Weston, editors, Large Scale Kernel Machines, pages 301–320. MIT Press, Cambridge, MA., 2007. pages 5
[25] Zhirong Wu, Shuran Song, Aditya Khosla, Fisher Yu, Linguang Zhang, Xiaoou Tang, and Jianxiong Xiao. 3d shapenets: A deep representation for volumetric shapes. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, pages 1912–1920, 2015. pages 5, 26
[26] Daniel Maturana and Sebastian Scherer. Voxnet: A 3d convolutional neural network for realtime object recognition. In Intelligent Robots and Systems (IROS), 2015 IEEE/RSJ International Conference on, pages 922–928. IEEE, 2015. pages 5, 26
[27] Andrew Brock, Theodore Lim, JM Ritchie, and Nick Weston. Generative and discriminative voxel modeling with convolutional neural networks. arXiv preprint arXiv:1608.04236, 2016. pages 5, 26
[28] Jiajun Wu, Chengkai Zhang, Tianfan Xue, William T Freeman, and Joshua B Tenenbaum. Learning a probabilistic latent space of object shapes via 3d generative-adversarial modeling. arXiv preprint arXiv:1610.07584, 2016. pages 5, 26
[29] Siamak Ravanbakhsh, Junier Oliva, Sebastien Fromenteau, Layne C Price, Shirley Ho, Jeff Schneider, and Barnabás Póczos. Estimating cosmological parameters from the dark matter distribution. In Proceedings of The 33rd International Conference on Machine Learning, 2016. pages 5
[30] Hong-Wei Lin, Chiew-Lan Tai, and Guo-Jin Wang. A mesh reconstruction algorithm driven by an intrinsic property of a point cloud. Computer-Aided Design, 36(1):1–9, 2004. pages 5
[31] Angel X Chang, Thomas Funkhouser, Leonidas Guibas, Pat Hanrahan, Qixing Huang, Zimo Li, Silvio Savarese, Manolis Savva, Shuran Song, Hao Su, et al. Shapenet: An information-rich 3d model repository. arXiv preprint arXiv:1512.03012, 2015. pages 5
[32] Radu Bogdan Rusu and Steve Cousins. 3D is here: Point Cloud Library (PCL). In IEEE International Conference on Robotics and Automation (ICRA), Shanghai, China, May 9-13 2011. pages 5
[33] James Binney and Michael Merrifield. Galactic astronomy. Princeton University Press, 1998. pages 5, 25
[34] AJ Connolly, I Csabai, AS Szalay, DC Koo, RG Kron, and JA Munn. Slicing through multicolor space: Galaxy redshifts from broadband photometry. arXiv preprint astro-ph/9508100, 1995. pages 5, 25
[35] Eduardo Rozo and Eli S Rykoff. redmapper ii: X-ray and sz performance benchmarks for the sdss catalog. The Astrophysical Journal, 783(2):80, 2014. pages 5, 25
[36] Zoubin Ghahramani and Katherine A Heller. Bayesian sets. In NIPS, volume 2, pages 22–23, 2005. pages 6, 7, 20, 21, 22
[37] B. Taskar, C. Guestrin, and D. Koller. Max-margin Markov networks. In S. Thrun, L. Saul, and B. Schölkopf, editors, Advances in Neural Information Processing Systems 16, pages 25–32, Cambridge, MA, 2004. MIT Press. pages 6
[38] Jonathan K. Pritchard, Matthew Stephens, and Peter Donnelly. Inference of population structure using multilocus genotype data. Genetics, 155(2):945–959, 2000. ISSN 0016-6731. URL http://www.genetics.org/content/155/2/945. pages 6, 22
[39] David M. Blei, Andrew Y. Ng, Michael I. Jordan, and John Lafferty. Latent dirichlet allocation. Journal of Machine Learning Research, 3:2003, 2003. pages 6, 22
[40] Tomas Mikolov, Ilya Sutskever, Kai Chen, Greg S Corrado, and Jeff Dean. Distributed representations of words and phrases and their compositionality. In Advances in neural information processing systems, pages 3111–3119, 2013. pages 7, 22
[41] Minmin Chen, Alice Zheng, and Kilian Weinberger. Fast image tagging. In Proceedings of The 30th International Conference on Machine Learning, pages 1274–1282, 2013. pages 7, 23
[42] S. L. Feng, R. Manmatha, and V. Lavrenko. Multiple bernoulli relevance models for image and video annotation. In Proceedings of the 2004 IEEE Computer Society Conference on Computer Vision and Pattern Recognition, CVPR’04, pages 1002–1009, Washington, DC, USA, 2004. IEEE Computer Society. pages 7, 23
[43] Ameesh Makadia, Vladimir Pavlovic, and Sanjiv Kumar. A new baseline for image annotation. In Proceedings of the 10th European Conference on Computer Vision: Part III, ECCV ’08, pages 316–329, Berlin, Heidelberg, 2008. Springer-Verlag. pages 7, 23
[44] Matthieu Guillaumin, Thomas Mensink, Jakob Verbeek, and Cordelia Schmid. Tagprop: Discriminative metric learning in nearest neighbor models for image auto-annotation. In Computer Vision, 2009 IEEE 12th International Conference on, pages 309–316. IEEE, 2009. pages 7, 23, 24
[45] Ziwei Liu, Ping Luo, Xiaogang Wang, and Xiaoou Tang. Deep learning face attributes in the wild. In Proceedings of International Conference on Computer Vision (ICCV), 2015. pages 8
[46] Branko ´Curgus and Vania Mascioni. Roots and polynomials as homeomorphic spaces. Expositiones Mathematicae, 24(1):81–95, 2006. pages 13, 15
[47] Boris A Khesin and Serge L Tabachnikov. Arnold: Swimming Against the Tide, volume 86. American Mathematical Society, 2014. pages 15
[48] Jerrold E Marsden and Michael J Hoffman. Elementary classical analysis. Macmillan, 1993. pages 15
[49] Nicolas Bourbaki. Eléments de mathématiques: théorie des ensembles, chapitres 1 à 4, volume 1. Masson, 1990. pages 15
[50] C. A. Micchelli. Interpolation of scattered data: distance matrices and conditionally positive definite functions. Constructive Approximation, 2:11–22, 1986. pages 18
[51] Luis Von Ahn and Laura Dabbish. Labeling images with a computer game. In Proceedings of the SIGCHI conference on Human factors in computing systems, pages 319–326. ACM, 2004. pages 23
[52] Michael Grubinger. Analysis and evaluation of visual information systems performance, 2007. URL http://eprints.vu.edu.au/1435. Thesis (Ph. D.)–Victoria University (Melbourne, Vic.), 2007. pages 23
[53] Tsung-Yi Lin, Michael Maire, Serge Belongie, James Hays, Pietro Perona, Deva Ramanan, Piotr Dollár, and C Lawrence Zitnick. Microsoft coco: Common objects in context. In European Conference on Computer Vision, pages 740–755. Springer, 2014. pages 23
[54] Diederik Kingma and Jimmy Ba. Adam: A method for stochastic optimization. arXiv preprint arXiv:1412.6980, 2014. pages 25, 26, 27
[55] Djork-Arné Clevert, Thomas Unterthiner, and Sepp Hochreiter. Fast and accurate deep network learning by exponential linear units (elus). arXiv preprint arXiv:1511.07289, 2015. pages 27