DDSP: Differentiable Digital Signal Processing
DDSP: Differentiable Digital Signal Processing
Google Research, Brain Team
Mountain View, CA 94043, USA
{jesseengel,hanoih,gcj,adarob}@google.com
Abstract
摘要
Most generative models of audio directly generate samples in one of two domains: time or frequency. While sufficient to express any signal, these representations are inefficient, as they do not utilize existing knowledge of how sound is generated and perceived. A third approach (vocoders/synthesizers) successfully incorporates strong domain knowledge of signal processing and perception, but has been less actively researched due to limited expressivity and difficulty integrating with modern auto-differentiation-based machine learning methods. In this paper, we introduce the Differentiable Digital Signal Processing (DDSP) library, which enables direct integration of classic signal processing elements with deep learning methods. Focusing on audio synthesis, we achieve high-fidelity generation without the need for large autoregressive models or adversarial losses, demonstrating that DDSP enables utilizing strong inductive biases without losing the expressive power of neural networks. Further, we show that combining interpretable modules permits manipulation of each separate model component, with applications such as independent control of pitch and loudness, realistic extrapolation to pitches not seen during training, blind dereverberation of room acoustics, transfer of extracted room acoustics to new environments, and transformation of timbre between disparate sources. In short, DDSP enables an interpretable and modular approach to generative modeling, without sacrificing the benefits of deep learning. The library is publicly available[^1] and we welcome further contributions from the community and domain experts.
现有的音频生成模型,大多直接在时域或频域里生成样本。这两种表示虽然足以表达任意信号,却并不高效,因为它们没有用上人们已经掌握的、关于声音如何产生和如何被感知的知识。第三种做法(声码器/合成器)能够把信号处理和听觉方面的领域知识用进去,但因为表达能力有限,又难以接到今天以自动求导为核心的机器学习方法上,相关研究并不活跃。本文介绍可微分数字信号处理(DDSP,Differentiable Digital Signal Processing)程序库,把经典信号处理元件直接接到深度学习方法里。我们以音频合成为重点,不必依靠大型自回归模型或对抗损失,也能实现高保真生成,表明 DDSP 可以在利用较强归纳偏置的同时,不牺牲神经网络的表达能力。我们还表明,把可解释的模块组合起来,就能分别操控模型的各个部件,例如独立控制音高和响度、把音高外推到训练时未见过的范围、对房间声学做盲去混响、把提取到的房间声学迁移到新环境,以及在差别很大的声源之间转换音色。简而言之,DDSP 为生成建模提供了一种可解释、可模块化的路径,同时又不必放弃深度学习的好处。程序库已经公开发布[^1],我们欢迎社区和领域专家继续贡献。
1 Online Resources: Code: https://github.com/magenta/ddsp Audio Examples: https://goo.gl/magenta/ddsp-examples Colab Demo: https://goo.gl/magenta/ddsp-demo
1 在线资源:代码:https://github.com/magenta/ddsp 音频示例:https://goo.gl/magenta/ddsp-examples Colab 演示:https://goo.gl/magenta/ddsp-demo
1 Introduction
1 引言
Neural networks are universal function approximators in the asymptotic limit (Hornik et al., 1989), but their practical success is largely due to the use of strong structural priors such as convolution (LeCun et al., 1989), recurrence (Sutskever et al., 2014; Williams & Zipser, 1990; Werbos, 1990), and self-attention (Vaswani et al., 2017). These architectural constraints promote generalization and data efficiency to the extent that they align with the data domain. From this perspective, end-to-end learning relies on structural priors to scale, but the practitioner’s toolbox is limited to functions that can be expressed differentiably. Here, we increase the size of that toolbox by introducing the Differentiable Digital Signal Processing (DDSP) library, which integrates interpretable signal processing elements into modern automatic differentiation software (TensorFlow). While this approach has broad applicability, we highlight its potential in this paper through exploring the example of audio synthesis.
在渐近极限下,神经网络是万能函数逼近器(Hornik et al., 1989),但它们在实践中的成功,很大程度上来自卷积(LeCun et al., 1989)、循环(Sutskever et al., 2014; Williams & Zipser, 1990; Werbos, 1990)和自注意力(Vaswani et al., 2017)这类结构性先验。只要这些结构约束与数据所在的领域相符,就能促进泛化、提高数据效率。由此看来,端到端学习要靠结构性先验才能做大,而实践者手里的工具箱,又只限于那些可以写成可微函数的操作。我们在这里扩大这个工具箱,提出可微分数字信号处理(DDSP)程序库,把可解释的信号处理元件接到当代自动求导软件(TensorFlow)中。这种方法有更广的适用面,本文则以音频合成为例,展示它的潜力。
Objects have a natural tendency to periodically vibrate. Small shape displacements are usually restored with elastic forces that conserve energy (similar to a canonical mass on a spring), leading to harmonic oscillation between kinetic and potential energy (Smith, 2010). Accordingly, human hearing has evolved to be highly sensitive to phase-coherent oscillation, decomposing audio into spectrotemporal responses through the resonant properties of the basilar membrane and tonotopic mappings into the auditory cortex (Moerel et al., 2012; Chi et al., 2005; Theunissen & Elie, 2014). However, neural synthesis models often do not exploit this periodic structure for generation and perception.
物体天然倾向于做周期性振动。形状上的微小位移,通常会被守恒的弹性力拉回去(类似于弹簧上的质量块),从而在动能和势能之间形成谐波振荡(Smith, 2010)。与此相应,人类听觉也对相位相干的振荡高度敏感:基底膜的谐振特性,以及听觉皮层中的音调拓扑映射,会把音频分解成时频谱响应(Moerel et al., 2012; Chi et al., 2005; Theunissen & Elie, 2014)。然而,神经合成模型在生成和感知上,往往并没有利用这种周期性结构。
1.1 Challenges of Neural Audio Synthesis
1.1 神经音频合成面临的困难
As shown in Figure 1, most neural synthesis models generate waveforms directly in the time domain, or from their corresponding Fourier coefficients in the frequency domain. While these representations are general and can represent any waveform, they are not free from bias. This is because they often apply a prior over generating audio with aligned wave packets rather than oscillations. For example, strided convolution models–such as SING (Defossez et al., 2018), MCNN (Arik et al., 2019), and WaveGAN (Donahue et al., 2019)–generate waveforms directly with overlapping frames. Since audio oscillates at many frequencies, all with different periods from the fixed frame hop size, the model must precisely align waveforms between different frames and learn filters to cover all possible phase variations. This challenge is visualized on the left of Figure 1.
如图 1 所示,大多数神经合成模型要么直接在时域里生成波形,要么从对应的傅里叶系数出发在频域里生成。这些表示虽然通用,能够表达任意波形,却并非没有偏置。原因在于,它们往往先验地按对齐的波包去生成音频,而不是按振荡去生成。例如,SING(Defossez et al., 2018)、MCNN(Arik et al., 2019)和 WaveGAN(Donahue et al., 2019)这类跨步卷积模型,是用互相重叠的帧直接生成波形的。音频会在许多频率上振荡,各频率的周期又都和固定的帧跳长不同,模型必须把不同帧之间的波形精确对齐,还要学习能够覆盖所有可能相位变化的滤波器。这一困难画在图 1 的左侧。
Fourier-based models–such as Tacotron (Wang et al., 2017) and GANSynth (Engel et al., 2019)–also suffer from the phase-alignment problem, as the Short-time Fourier Transform (STFT) is a representation over windowed wave packets. Additionally, they must contend with spectral leakage, where sinusoids at multiple neighboring frequencies and phases must be combined to represent a single sinusoid when Fourier basis frequencies do not perfectly match the audio. This effect can be seen in the middle diagram of Figure 1.
基于傅里叶的模型,例如 Tacotron(Wang et al., 2017)和 GANSynth(Engel et al., 2019),同样会碰到相位对齐问题,因为短时傅里叶变换(STFT)本身就是对加窗波包的表示。它们还要应对频谱泄漏:当傅里叶基的频率与音频不完全吻合时,必须把相邻多个频率和相位上的正弦波组合起来,才能表示一条正弦波。这一现象可以在图 1 中间的示意里看到。
Autoregressive waveform models–such as WaveNet (Oord et al., 2016), SampleRNN (Mehri et al., 2016), and WaveRNN (Kalchbrenner et al., 2018)–avoid these issues by generating the waveform a single sample at a time. They are not constrained by the bias over generating wave packets and can express arbitrary waveforms. However, they require larger and more data-hungry networks, as they do not take advantage of a bias over oscillation (size comparisons can be found in Table 3). Furthermore, the use of teacher-forcing during training leads to exposure bias during generation, where errors with feedback can compound. It also makes them incompatible with perceptual losses such as spectral features (Defossez et al., 2018), pretrained models (Dosovitskiy & Brox, 2016), and discriminators (Engel et al., 2019). This adds further inefficiency to these models, as a waveform’s shape does not perfectly correspond to perception. For example, the three waveforms on the right of Figure 1 sound identical (a relative phase offset of the harmonics) but would present different losses to an autoregressive model.
自回归波形模型,例如 WaveNet(Oord et al., 2016)、SampleRNN(Mehri et al., 2016)和 WaveRNN(Kalchbrenner et al., 2018),则是一次生成一个样本,从而避开上述问题。它们不受“按波包生成”这一偏置的约束,可以表达任意波形。可是,它们没有利用关于振荡的偏置,因而需要更大、更吃数据的网络(规模比较见表 3)。此外,训练时使用教师强制,在生成时会导致暴露偏差,误差经反馈后可能不断放大。它们也因此难以与频谱特征(Defossez et al., 2018)、预训练模型(Dosovitskiy & Brox, 2016)和判别器(Engel et al., 2019)这类感知损失一起使用。这进一步降低了效率,因为波形的形状与感知并不完全对应。例如,图 1 右侧的三条波形听起来完全一样(只是谐波的相对相位不同),但对自回归模型来说,损失却会不一样。
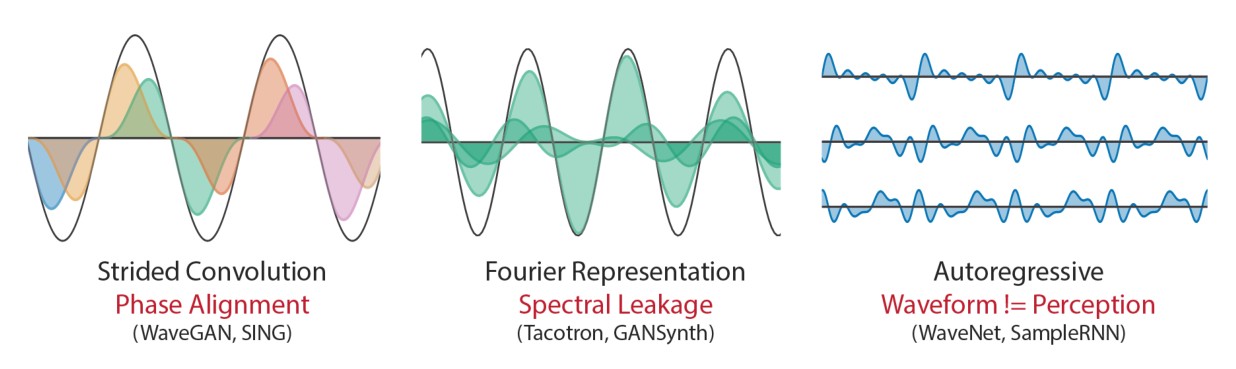
Figure 1: Challenges of neural audio synthesis. Full description provided in Section 1.1.
图 1:神经音频合成面临的困难。完整说明见第 1.1 节。
1.2 Oscillator Models
1.2 振荡器模型
Rather than predicting waveforms or Fourier coefficients, a third model class directly generates audio with oscillators. Known as vocoders or synthesizers, these models are physically and perceptually motivated and have a long history of research and applications (Beauchamp, 2007; Morise et al., 2016). These “analysis/synthesis” models use expert knowledge and hand-tuned heuristics to extract synthesis parameters (analysis) that are interpretable (loudness and frequencies) and can be used by the generative algorithm (synthesis).
第三类模型并不去预测波形或傅里叶系数,而是直接用振荡器生成音频。这类方法被称为声码器或合成器,有明确的物理和感知动机,也有很长的研究和应用历史(Beauchamp, 2007; Morise et al., 2016)。这些“分析/合成”模型依靠专家知识和手工调整的启发式规则,提取出可解释的合成参数(分析),例如响度和频率,再交给生成算法去用(合成)。
Neural networks have been used previously to some success in modeling pre-extracted synthesis parameters (Blaauw & Bonada, 2017; Chandna et al., 2019), but these models fall short of end-to-end learning. The analysis parameters must still be tuned by hand and gradients cannot flow through the synthesis procedure. As a result, small errors in parameters can lead to large errors in the audio that cannot propagate back to the network. Crucially, the realism of vocoders is limited by the expressivity of a given analysis/synthesis pair.
此前已有工作用神经网络去建模预先提取的合成参数,并取得了一定效果(Blaauw & Bonada, 2017; Chandna et al., 2019),但这些模型还谈不上端到端学习。分析参数仍需手工调整,梯度也无法穿过合成过程。于是,参数上的小误差可能在音频上变成大误差,却回传不到网络。更为关键的是,声码器能做到多逼真,最终受限于给定分析/合成对的表达能力。
1.3 Contributions
1.3 本文贡献
In this paper, we overcome the limitations outlined above by using the DDSP library to implement fully differentiable synthesizers and audio effects. DDSP models combine the strengths of the above approaches, benefiting from the inductive bias of using oscillators, while retaining the expressive power of neural networks and end-to-end training.
本文用 DDSP 程序库实现完全可微分的合成器和音频效果,以克服前面列出的限制。DDSP 模型把上述几类方法的长处合在一起:既受益于使用振荡器带来的归纳偏置,又保留了神经网络和端到端训练的表达能力。
We demonstrate that models employing DDSP components are capable of generating high-fidelity audio without autoregressive or adversarial losses. Further, we show the interpretability and modularity of these models enable:
我们表明,采用 DDSP 组件的模型,不必依靠自回归或对抗损失,也能生成高保真音频。我们还表明,这些模型的可解释性和模块化带来了以下能力:
- Independent control over pitch and loudness during synthesis.
- 合成时独立控制音高和响度。
- Realistic extrapolation to pitches not seen during training.
- 把音高合理地外推到训练时未见过的范围。
- Blind dereverberation of audio through seperate modelling of room acoustics.
- 通过对房间声学的单独建模,对音频做盲去混响。
- Transfer of extracted room acoustics to new environments.
- 把提取到的房间声学迁移到新环境。
- Timbre transfer between disparate sources, converting a singing voice into a violin.
- 在差别很大的声源之间转换音色,例如把歌声变成小提琴。
- Smaller network sizes than comparable neural synthesizers.
- 网络规模小于可比较的神经合成器。
Audio samples for all examples and figures are provided in the online supplement[^2]. We highly encourage readers to listen to the samples as part of reading the paper.
所有例子和插图的音频样本都放在在线补充材料中[^2]。我们非常建议读者在阅读论文时一并听这些样本。
Vocoders. Vocoders come in several varieties. Source-filter/subtractive models are inspired by the human vocal tract and dynamically filter a harmonically rich source signal (Flanagan, 2013), while sinusoidal/additive models generate sound as the combination of a set of time-varying sine waves (McAulay & Quatieri, 1986; Serra & Smith, 1990). Additive models are strictly more expressive than subtractive models but have more parameters as each sinusoid has its own time-varying loudness and frequency. This work builds a differentiable synthesizer off the Harmonic plus Noise model (Serra & Smith, 1990; Beauchamp, 2007): an additive synthesizer combines sinusoids in harmonic (integer) ratios of a fundamental frequency alongside a time-varying filtered noise signal.
声码器。 声码器有几类。源-滤波器/减性模型受到人类声道的启发,会对谐波丰富的源信号做动态滤波(Flanagan, 2013);正弦/加性模型则把一组时变正弦波叠加起来生成声音(McAulay & Quatieri, 1986; Serra & Smith, 1990)。加性模型在表达能力上严格强于减性模型,但参数也更多,因为每条正弦波都有自己的时变响度和频率。本文在 Harmonic plus Noise 模型(Serra & Smith, 1990; Beauchamp, 2007)上构建可微分合成器:加性合成器按基频的谐波(整数)比叠加正弦波,同时再叠加一路时变的滤波噪声。
Synthesizers. A separate thread of research has tried to estimate parameters for commercial synthesizers using gradient-free methods (Huang et al., 2014; Hoffman & Cook, 2006). Synthesizer outputs modeled with a variational autoencoder were recently used as a “world model” (Ha & Schmidhuber, 2018) to pass approximate gradients to a controller during learning (Esling et al., 2019). DDSP differs from black-box approaches to modeling existing synthesizers; it is a toolkit of differentiable DSP components for end-to-end learning.
合成器。 另有一条研究线索试图用无梯度方法去估计商业合成器的参数(Huang et al., 2014; Hoffman & Cook, 2006)。最近也有工作用变分自编码器去建模合成器输出,把它当作“世界模型”(Ha & Schmidhuber, 2018),以便在学习过程中把近似梯度传给控制器(Esling et al., 2019)。DDSP 不同于这类把现成合成器当黑箱来建模的做法;它是一套面向端到端学习的可微分 DSP 组件工具箱。
Neural Source Filter (NSF). Perhaps closest to this work, promising speech synthesis results were recently achieved using a differentiable waveshaping synthesizer (Wang et al., 2019). The NSF can be seen as a specific DDSP model, that uses convolutional waveshaping of a sinusoidal oscillator to create harmonic content, rather than additive synthesis explored in this work. Both works also generate audio in the time domain and impose multi-scale spectrograms losses in the frequency domain. A key contribution of this work is to highlight how these models are part of a common family of techniques and to release a modular library that makes them accessible by leveraging automatic differentiation to easily mix and match components at a high level.
神经源滤波器(NSF)。 与本文或许最接近的,是最近用可微分波形整形合成器在语音合成上取得的结果(Wang et al., 2019)。可以把 NSF 看成一种具体的 DDSP 模型:它通过对正弦振荡器做卷积波形整形来产生谐波内容,而不是本文探索的加性合成。两份工作都在时域生成音频,并在频域施加多尺度频谱损失。本文的一个关键贡献,是指出这些模型同属一个方法家族,并发布一个模块化程序库,借助自动求导,让人可以在较高层次上方便地组合、替换各个组件。
3 DDSP Components
3 DDSP 组件
Many DSP operations can be expressed as functions in modern automatic differentiation software. We express core components as feedforward functions, allowing efficient implementation on parallel hardware such as GPUs and TPUs, and generation of samples during training. These components include oscillators, envelopes, and filters (linear-time-varying finite-impulse-response, LTV-FIR). [^3]
许多 DSP 操作都可以写成当代自动求导软件中的函数。我们把核心组件表示成前馈函数,从而可以在 GPU 和 TPU 这类并行硬件上高效实现,并在训练过程中生成样本。这些组件包括振荡器、包络和滤波器(线性时变有限冲激响应,LTV-FIR)。[^3]
3 We have implemented further components such as wavetable synthesizers and non-sinusoidal oscillators, but focus here on components used in the experiments and leave the rest as future work.
3 我们还实现了波表合成器和非线性振荡器等更多组件,但本文只讨论实验中用到的部分,其余留作后续工作。
3.1 Spectral Modeling Synthesis
3.1 谱建模合成
Here, as an example DDSP model, we implement a differentiable version of Spectral Modeling Synthesis (SMS) Serra & Smith (1990). This model generates sound by combining an additive synthesizer (adding together many sinusoids) with a subtractive synthesizer (filtering white noise). We choose SMS because, despite being parametric, it is a highly expressive model of sound, and has found widespread adoption in tasks as diverse as spectral morphing, time stretching, pitch shifting, source separation, transcription, and even as a general purpose audio codec in MPEG-4 (Tellman et al., 1995; Klapuri et al., 2000; Purnhagen & Meine, 2000).
作为 DDSP 模型的一个例子,我们实现了谱建模合成(SMS)的可微分版本(Serra & Smith, 1990)。该模型把加性合成器(把许多正弦波加在一起)和减性合成器(对白噪声滤波)结合起来生成声音。我们选择 SMS,是因为它虽然是参数化的,对声音的表达能力却很强,并且已经广泛用于频谱变形、时间拉伸、音高变换、源分离、记谱,甚至作为 MPEG-4 中的通用音频编解码器(Tellman et al., 1995; Klapuri et al., 2000; Purnhagen & Meine, 2000)。
As we only consider monophonic sources in these experiments, we use the Harmonic plus Noise model, that further constrains sinusoids to be integer multiples of a fundamental frequency (Beauchamp, 2007). One of the reasons that SMS is more expressive than many other parametric models because it has so many more parameters. For example, in the 4 seconds of 16kHz audio in the datasets considered here, the synthesizer coefficients actually have 2.5 times more dimensions than the audio waveform itself ((1 amplitude + 100 harmonics + 65 noise band magnitudes) * 1000 timesteps = 165,000 dimensions, vs. 64,000 audio samples). This makes them amenable to control by a neural network, as it would be difficult to realistically specify all these parameters by hand.
本文实验只考虑单音声源,因此采用 Harmonic plus Noise 模型,进一步把正弦波约束为基频的整数倍(Beauchamp, 2007)。SMS 比许多其他参数化模型更有表达能力,原因之一正是它的参数多得多。例如,在本文所用数据集里 4 秒、16kHz 的音频上,合成器系数的维度大约是音频波形本身的 2.5 倍((1 个振幅 + 100 个谐波 + 65 个噪声带幅度)× 1000 个时间步 = 165,000 维,而音频样本只有 64,000 个)。这样的参数量很适合交给神经网络去控制,因为很难靠手工把它们全都指定得很逼真。
3.2 Harmonic Oscillator / Additive Synthesizer
3.2 谐振荡器 / 加性合成器
At the heart of the synthesis techniques explored in this paper is the sinusoidal oscillator. A bank of oscillators that outputs a signal over discrete time steps, , can be expressed as:
本文所探索的合成技术,核心是正弦振荡器。一组在离散时间步 上输出信号 的振荡器,可以写成:
where is the time-varying amplitude of the -th sinusoidal component and is its instantaneous phase. The phase is obtained by integrating the instantaneous frequency :
其中 是第 个正弦分量的时变振幅, 是它的瞬时相位。相位 由瞬时频率 积分得到:
where is the initial phase that can be randomized, fixed, or learned.
其中 是初相,可以随机化、固定,也可以学习。
For a harmonic oscillator, all the sinusoidal frequencies are harmonic (integer) multiples of a fundamental frequency, , i.e., , Thus the output of the harmonic oscillator is entirely parameterized by the time-varying fundamental frequency and harmonic amplitudes . To aid interpretablity we further factorize the harmonic amplitudes:
对谐振荡器而言,所有正弦频率都是基频 的谐波(整数)倍,即 。因此,谐振荡器的输出完全由时变基频 和谐波振幅 参数化。为了提高可解释性,我们进一步把谐波振幅分解为:
into a global amplitude that controls the loudness and a normalized distribution over harmonics that determines spectral variations, where and . We also constrain both amplitudes and harmonic distribution components to be positive through the use of a modified sigmoid nonlinearity as described in the appendix. Figure 6 provides a graphical example of the additive synthesizer. Audio is provided in our online supplement[^2].
其中全局振幅 控制响度,归一化的谐波分布 决定频谱变化,并满足 且 。我们还用附录中描述的改进 sigmoid 非线性,把振幅和谐波分布的各个分量都约束为非负。图 6 给出了加性合成器的图示。音频样本见在线补充材料[^2]。
3.3 Envelopes
3.3 包络
The oscillator formulation above requires time-varying amplitudes and frequencies at the audio sample rate, but our neural networks operate at a slower frame rate. For instantaneous frequency upsampling, we found bilinear interpolation to be adequate. However, the amplitudes and harmonic distributions of the additive synthesizer required smoothing to prevent artifacts. We are able to achieve this with a smoothed amplitude envelope by adding overlapping Hamming windows at the center of each frame and scaled by the amplitude. For these experiments we found a 4ms (64 timesteps) hop size and 8 ms frame size (50% overlap) to be responsive to changes while removing artifacts.
上面的振荡器公式要求振幅和频率按音频采样率随时间变化,而我们的神经网络工作在更慢的帧率上。对瞬时频率的上采样,我们发现双线性插值已经够用。但加性合成器的振幅和谐波分布需要平滑,否则会出现伪影。我们的做法是,在每一帧的中心放置互相重叠的汉明窗,再按该帧振幅缩放,从而得到平滑的振幅包络。在这些实验里,我们采用 4 毫秒(64 个时间步)的跳长和 8 毫秒的帧长(重叠 50%),既能跟上变化,又能去掉伪影。
3.4 Filter Design: Frequency Sampling Method
3.4 滤波器设计:频率采样法
Linear filter design is a cornerstone of many DSP techniques. Standard convolutional layers are equivalent to linear time invariant finite impulse response (LTI-FIR) filters. However, to ensure interpretability and prevent phase distortion, we employ the frequency sampling method to convert network outputs into impulse responses of linear-phase filters.
线性滤波器设计是许多 DSP 技术的基础。标准卷积层等价于线性时不变有限冲激响应(LTI-FIR)滤波器。但为了保证可解释性并避免相位失真,我们采用频率采样法,把网络输出转换成线性相位滤波器的冲激响应。
Here, we design a neural network to predict the frequency-domain transfer functions of a FIR filter for every output frame. In particular, the neural network outputs a vector (and accordingly ) for the -th frame of the output. We interpret as the frequency-domain transfer function of the corresponding FIR filter. We therefore implement a time-varying FIR filter.
具体而言,我们让神经网络为每一帧输出预测 FIR 滤波器的频域传递函数。对第 帧,网络输出向量 (相应地,)。我们把 解释为对应 FIR 滤波器的频域传递函数,从而实现时变 FIR 滤波。
To apply the time-varying FIR filter to the input, we divide the audio into non-overlapping frames to match the impulse responses . We then perform frame-wise convolution via multiplication of frames in the Fourier domain: where and is the output. We recover the frame-wise filtered audio, , and then overlap-add the resulting frames with the same hop size and rectangular window used to originally divide the input audio. The hop size is given by dividing the audio into equally spaced frames for each frame of conditioning. For 64000 samples and 250 frames, this corresponds to a hop size of 256.
要对输入施加这个时变 FIR 滤波器,我们把音频切成与冲激响应 相对应的、互不重叠的帧 。然后在傅里叶域里对帧做乘法,实现逐帧卷积:,其中 , 是输出。再由 得到逐帧滤波后的音频,并按当初切分输入时所用的同样跳长和矩形窗做重叠相加。跳长由把音频均匀分成与条件信息相同帧数来决定。对 64000 个样本和 250 帧,对应跳长为 256。
In practice, we do not use the neural network output directly as . Instead, we apply a window function on the network output to compute . The shape and size of the window can be decided independently to control the time-frequency resolution trade-off of the filter. In our experiments, we default to a Hann window of size 257. Without a window, the resolution implicitly defaults to a rectangular window which is not ideal for many cases. We take care to shift the IR to zero-phase (symmetric) form before applying the window and revert to causal form before applying the filter.
实践中,我们并不把网络输出直接当作 ,而是对网络输出施加窗函数 再计算 。窗的形状和长度可以单独选定,以控制滤波器的时频分辨率权衡。实验里我们默认使用长度为 257 的 Hann 窗。如果不加窗,分辨率会隐含地退化为矩形窗,在许多情况下并不理想。我们会先把冲激响应移到零相位(对称)形式再加窗,滤波前再改回因果形式。
3.5 Filtered Noise / Subtractive Synthesizer
3.5 滤波噪声 / 减性合成器
Natural sounds contain both harmonic and stochastic components. The Harmonic plus Noise model captures this by combining the output of an additive synthesizer with a stream of filtered noise (Serra & Smith, 1990; Beauchamp, 2007). We are able to realize a differentiable filtered noise synthesizer by simply applying the LTV-FIR filter from above to a stream of uniform noise where is the IDFT of uniform noise in domain [-1, 1].
自然声音既有谐波成分,也有随机成分。Harmonic plus Noise 模型把加性合成器的输出与一路滤波噪声结合起来,以刻画这一点(Serra & Smith, 1990; Beauchamp, 2007)。我们只需把上面的 LTV-FIR 滤波器加到一路均匀噪声上,就可以实现可微分的滤波噪声合成器:,其中 是取值在 上的均匀噪声的 IDFT。
3.6 Reverb: Long impulse responses
3.6 混响:长冲激响应
Room reverbation (reverb) is an essential characteristic of realistic audio, which is usually implicitly modeled by neural synthesis algorithms. In contrast, we gain interpretability by explicitly factorizing the room acoustics into a post-synthesis convolution step. A realistic room impulse response (IR) can be as long as several seconds, corresponding to extremely long convolutional kernel sizes (10-100k timesteps). Convolution via matrix multiplication scales as , which is intractable for such large kernel sizes. Instead, we implement reverb by explicitly performing convolution as multiplication in the frequency domain, which scales as and does not bottleneck training.
房间混响(reverb)是逼真音频的重要特征,神经合成算法通常把它隐含在模型里一起学。与此不同,我们把房间声学显式分解为合成之后的卷积步骤,从而获得可解释性。真实的房间冲激响应(IR)可以长达数秒,对应的卷积核尺寸极大(约 –k 个时间步)。若用矩阵乘法做卷积,复杂度是 ,对这样的核长是不可行的。我们改为在频域用乘法实现卷积,复杂度为 ,不会成为训练的瓶颈。
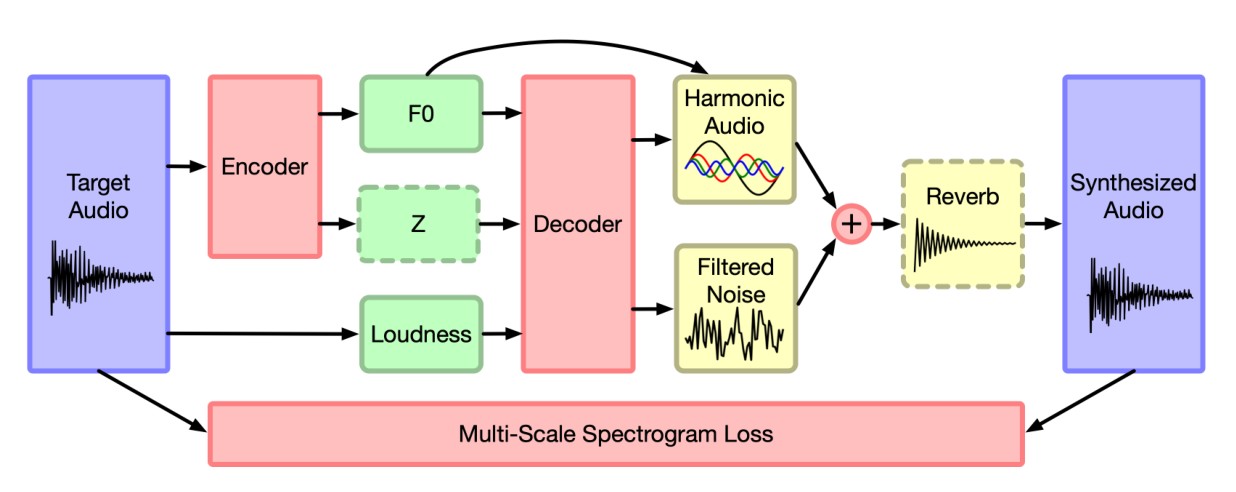
Figure 2: Autoencoder architecture. Red components are part of the neural network architecture, green components are the latent representation, and yellow components are deterministic synthesizers and effects. Components with dashed borders are not used in all of our experiments. Namely, is not used in the model trained on solo violin, and reverb is not used in the models trained on NSynth. See the appendix for more detailed diagrams of the neural network components.
图 2:自编码器结构。红色部分属于神经网络,绿色部分是潜表示,黄色部分是确定性的合成器和效果器。虚线边框的组件并非在所有实验中都使用。具体来说,在独奏小提琴上训练的模型不用 ,在 NSynth 上训练的模型不用混响。神经网络各组件更详细的图示见附录。
4 Experiments
4 实验
For empirical verification of this approach, we test two DDSP autoencoder variants–supervised and unsupervised–on two different musical datasets: NSynth (Engel et al., 2017) and a collection of solo violin performances. The supervised DDSP autoencoder is conditioned on fundamental frequency (F0) and loudness features extracted from audio, while the unsupervised DDSP autoencoder learns F0 jointly with the rest of the network.
为了用实验验证这一做法,我们在两个音乐数据集上测试了两种 DDSP 自编码器变体——有监督和无监督:NSynth(Engel et al., 2017)以及一组独奏小提琴演奏。有监督 DDSP 自编码器以从音频中提取的基频(F0)和响度特征为条件;无监督 DDSP 自编码器则与网络其余部分一起学习 F0。
4.1 DDSP Autoencoder
4.1 DDSP 自编码器
DDSP components do not put constraints on the choice of generative model (GAN, VAE, Flow, etc.), but we focus here on a deterministic autoencoder to investigate the strength of DDSP components independent of any particular approach to adversarial training, variational inference, or Jacobian design. Just as autoencoders utilizing convolutional layers outperform fully-connected autoencoders on images, we find DDSP components are able to dramatically improve autoencoder performance in the audio domain. Introducing stochastic latents (such as in GAN, VAE, and Flow models) will likely further improve performance, but we leave that to future work as it is orthogonal to the core question of DDSP component performance that we investigate in this paper.
DDSP 组件并不限制必须选用哪一种生成模型(GAN、VAE、Flow 等),但这里我们集中讨论确定性自编码器,以便在不依赖某一种对抗训练、变分推断或雅可比设计的前提下,考察 DDSP 组件本身的能力。正如在图像上采用卷积层的自编码器会优于全连接自编码器,我们发现 DDSP 组件也能大幅提高音频域自编码器的表现。引入随机潜变量(如 GAN、VAE 和 Flow 模型中那样)很可能还会进一步提高性能,但这一点与本文要考察的核心问题——DDSP 组件本身的表现——是正交的,我们留给后续工作。
In a standard autoencoder, an encoder network maps the input to a latent representation and a decoder network attempts to directly reconstruct the input . Our architecture (Figure 2) contrasts with this approach through the use of DDSP components and a decomposed latent representation.
在标准自编码器中,编码器网络 把输入 映到潜表示 ,解码器网络 再试图直接重建输入 。我们的结构(图 2)与此不同:它使用了 DDSP 组件,并把潜表示做了分解。
Encoders: Detailed descriptions of the encoders are given in Section B.1. For the supervised autoencoder, the loudness is extracted directly from the audio, a pretrained CREPE model with fixed weights (Kim et al., 2018) is used as an encoder to extact the fundamental frequency, and optional encoder extracts a time-varying latent encoding of the residual information. For the encoder, MFCC coefficients (30 per a frame) are first extracted from the audio, which correspond to the smoothed spectral envelope of harmonics (Beauchamp, 2007), and transformed by a single GRU layer into 16 latent variables per a frame.
编码器: 编码器的详细说明见第 B.1 节。对有监督自编码器,响度 直接从音频中提取;用权重固定的预训练 CREPE 模型(Kim et al., 2018)作为 编码器来提取基频;还可以选用一个可选编码器,提取残差信息的时变潜编码 。对 编码器,先从音频中提取 MFCC 系数(每帧 30 维),它们对应于谐波的平滑频谱包络(Beauchamp, 2007),再经单层 GRU 变换为每帧 16 个潜变量。
For the unsupervised autoencoder, the pretrained CREPE model is replaced with a Resnet architecture (He et al., 2016) that extracts from a mel-scaled log spectrogram of the audio, and is jointly trained with the rest of the network.
对无监督自编码器,预训练的 CREPE 模型被换成一个 ResNet 结构(He et al., 2016),它从音频的梅尔对数频谱图中提取 ,并与网络其余部分联合训练。
Decoder: A detailed description of the decoder network is given in Section B.2. The decoder network maps the tuple to control parameters for the additive and filtered noise synthesizers described in Section 3. The synthesizers generate audio based on these parameters, and a reconstruction loss between the synthesized and original audio is minimized. The network architecture is chosen to be fairly generic (fully connected, with a single recurrent layer) to demonstrate that it is the DDSP components, and not other modeling decisions, that enables the quality of the work.
解码器: 解码器网络的详细说明见第 B.2 节。解码器把元组 映射为第 3 节所述加性合成器和滤波噪声合成器的控制参数。合成器根据这些参数生成音频,再最小化合成音频与原始音频之间的重建损失。网络结构选得相当通用(全连接,外加单层循环网络),以表明带来音质的是 DDSP 组件,而不是其他建模选择。
Also unique to our approach, the latent is fed directly to the additive synthesizer as it has structural meaning for the synthesizer outside the context of any given dataset. As shown later in Section 5.2, this disentangled representation enables the model to both interpolate within and extrapolate outside the data distribution. Indeed, recent work support incorporation of strong inductive biases as a prerequisite for learning disentangled representations (Locatello et al., 2018).
我们的做法还有一点特别:潜变量 被直接送进加性合成器,因为它对合成器有不依赖于任何特定数据集的结构意义。如后文第 5.2 节所示,这种解耦表示使模型既能在数据分布内插值,也能外推到分布之外。事实上,近期工作也支持把较强的归纳偏置视为学习解耦表示的前提(Locatello et al., 2018)。
Model Size: Table 3, compares parameter counts for the DDSP models and comparable models including GANSynth (Engel et al., 2019), WaveRNN (Hantrakul et al., 2019), and a WaveNet Autoencoder (Engel et al., 2017). The DDSP models have the fewest parameters (up to 10 times less), despite no effort to minimize the model size in these experiments. Initial experiments with very small models (240k parameters, 300x smaller than a WaveNet Autoencoder) have less realistic outputs than the full models, but still have fairly high quality and are promising for low-latency applications, even on CPU or embedded devices. Audio samples are available in the online supplement[^2].
模型规模: 表 3 比较了 DDSP 模型与若干可比较模型的参数量,包括 GANSynth(Engel et al., 2019)、WaveRNN(Hantrakul et al., 2019)和 WaveNet 自编码器(Engel et al., 2017)。尽管这些实验并未刻意压缩模型规模,DDSP 模型的参数仍然最少(最多少约 10 倍)。用很小的模型(24 万参数,比 WaveNet 自编码器小 300 倍)做的初步实验,输出不如完整模型逼真,但音质仍然相当高,对低延迟应用、甚至在 CPU 或嵌入式设备上也很有潜力。音频样本见在线补充材料[^2]。
4.2 Datasets
4.2 数据集
NSynth: We focus on a smaller subset of the NSynth dataset (Engel et al., 2017) consistent with other work (Engel et al., 2019; Hantrakul et al., 2019). It totals 70,379 examples comprised mostly of strings, brass, woodwinds and mallets with pitch labels within MIDI pitch range 24-84. We employ a 80/20 train/test split shuffling across instrument families. For the NSynth experiments, we use the autoencoder as described above (with the encoder). We experiment with both the supervised and unsupervised variants.
NSynth: 我们采用与其他工作(Engel et al., 2019; Hantrakul et al., 2019)一致的 NSynth 数据集较小子集(Engel et al., 2017)。它共有 70,379 个样本,以弦乐、铜管、木管和锤击类乐器为主,音高标签落在 MIDI 音高 24–84 之间。我们按 80/20 划分训练/测试集,并在乐器族之间做了打乱。NSynth 实验使用上面描述的自编码器(带有 编码器),并分别试验有监督和无监督两种变体。
Solo Violin: The NSynth dataset does not capture aspects of a real musical performance. Using the MusOpen royalty free music library, we collected 13 minutes of expressive, solo violin performances[^4]. We purposefully selected pieces from a single performer (John Garner), that were monophonic and shared a consistent room environment to encourage the model to focus on performance. Like NSynth, audio is converted to mono 16kHz and divided into 4 second training examples (64000 samples total). Code to process the audio files into a dataset is available online.[^5]
独奏小提琴: NSynth 数据集并不能刻画真实音乐演奏的一些方面。我们借助 MusOpen 免版税音乐库,收集了 13 分钟富有表现力的独奏小提琴演奏[^4]。我们有意只选同一位演奏者(John Garner)的作品,这些片段都是单声的,并共享同一房间环境,以便促使模型把注意力放在演奏本身。与 NSynth 一样,音频被转换成单声道 16kHz,并切成 4 秒的训练样本(共 64,000 个采样点)。把音频文件处理成数据集的代码已在线上公布。[^5]
4 Five pieces by John Garner (II. Double, III. Corrente, IV. Double Presto, VI. Double, VIII. Double) from https://musopen.org/music/13574-violin-partita-no-1-bwv-1002/
4 John Garner 的五首作品(II. Double、III. Corrente、IV. Double Presto、VI. Double、VIII. Double),来自 https://musopen.org/music/13574-violin-partita-no-1-bwv-1002/
For the solo violin experiments, we use the supervised variant of the autoencoder (without the encoder), and add a reverb module to the signal processor chain to account for room reverberation. While the room impulse response could be produced as an output of the decoder, given that the solo violin dataset has a single acoustic environment, we use a single fixed variable (4 second reverb corresponding to 64000 dimensions) for the impulse response.
独奏小提琴实验采用有监督自编码器变体(不使用 编码器),并在信号处理链中加入混响模块,以考虑房间混响。房间冲激响应也可以作为解码器的输出,但鉴于该数据集只有一种声学环境,我们用一个固定变量来表示冲激响应(4 秒混响,对应 64,000 维)。
Table 1: Resynthesis accuracies. Comparison of DDSP models to SOTA WaveRNN model provided the same conditioning information. The supervised DDSP Autoencoder and WaveRNN models use the fundamental frequency from a pretrained CREPE model, while the unsupervised DDSP autoencoder learns to infer the frequency from the audio during training.
| Loudness () | F0 () | F0 Outliers | |
|---|---|---|---|
| Supervised | |||
| WaveRNN (Hantrakul et al., 2019) | 0.10 | 1.00 | 0.07 |
| DDSP Autoencoder | 0.07 | 0.02 | 0.003 |
| Unsupervised | |||
| DDSP Autoencoder | 0.09 | 0.80 | 0.04 |
表 1:重建精度。在给定相同条件信息的情况下,比较 DDSP 模型与当时最强的 WaveRNN 模型。有监督的 DDSP 自编码器和 WaveRNN 使用预训练 CREPE 模型给出的基频,无监督的 DDSP 自编码器则在训练中从音频里自行推断频率。
| 响度 () | 基频 () | 基频离群 | |
|---|---|---|---|
| 有监督 | |||
| WaveRNN (Hantrakul et al., 2019) | 0.10 | 1.00 | 0.07 |
| DDSP Autoencoder | 0.07 | 0.02 | 0.003 |
| 无监督 | |||
| DDSP Autoencoder | 0.09 | 0.80 | 0.04 |
4.2.1 Multi-scale spectral loss
4.2.1 多尺度频谱损失
The primary objective of the autoencoder is to minimize reconstruction loss. However, for audio waveforms, point-wise loss on the raw waveform is not ideal, as two perceptually identical audio samples may have distinct waveforms, and point-wise similar waveforms may sound very different.
自编码器的首要目标是最小化重建损失。但对音频波形而言,在原始波形上逐点计算损失并不理想:两段听感相同的音频,波形可能完全不同;波形上很接近的两段,听起来也可能差得很远。
Instead, we use a multi-scale spectral loss–similar to the multi-resolution spectral amplitude distance in Wang et al. (2019)–defined as follows. Given the original and synthesized audio, we compute their (magnitude) spectrogram and , respectively, with a given FFT size , and define the loss as the sum of the L1 difference between and as well as the L1 difference between and .
因此我们采用多尺度频谱损失——与 Wang et al.(2019)中的多分辨率频谱幅度距离类似——定义如下。给定原始音频和合成音频,我们用给定的 FFT 尺寸 分别计算它们的(幅度)频谱图 和 ,并把损失定义为 与 的 L1 差,再加上 与 的 L1 差。
where is a weighting term set to 1.0 in our experiments. The total reconstruction loss is then the sum of all the spectral losses, . In our experiments, we used FFT sizes (2048, 1024, 512, 256, 128, 64), and the neighboring frames in the Short-Time Fourier Transform (STFT) overlap by 75%. Therefore, the ’s cover differences between the original and synthesized audios at different spatial-temporal resolutions.
其中 是权重项,实验中取 1.0。总重建损失是所有频谱损失之和,。实验中使用的 FFT 尺寸为 (2048, 1024, 512, 256, 128, 64),短时傅里叶变换(STFT)中相邻帧重叠 75%。因此,各个 覆盖了原始音频与合成音频在不同时空分辨率上的差异。
5 Results
5 结果
5.1 High-fidelity Synthesis
5.1 高保真合成
As shown in Figure 5, the DDSP autoencoder learns to very accurately resynthesize the solo violin dataset. Again, we highly encourage readers to listen to the samples provided in the online supplement[^2]. A full decomposition of the components is provided Figure 5. High-quality neural audio synthesis has previously required very large autoregressive models (Oord et al., 2016; Kalchbrenner et al., 2018) or adversarial loss functions (Engel et al., 2019). While amenable to an adversarial loss, the DDSP autoencoder achieves these results with a straightforward L1 spectrogram loss, a small amount of data, and a relatively simple model. This demonstrates that the model is able to efficiently exploit the bias of the DSP components, while not losing the expressive power of neural networks.
如图 5 所示,DDSP 自编码器能够非常准确地重建独奏小提琴数据集。我们再次强烈建议读者去听在线补充材料中的样本[^2]。各分量的完整分解见图 5。此前,高质量的神经音频合成往往需要非常大的自回归模型(Oord et al., 2016; Kalchbrenner et al., 2018)或对抗损失函数(Engel et al., 2019)。虽然也可以接对抗损失,但 DDSP 自编码器仅用直接的频谱图 L1 损失、较少的数据和相对简单的模型,就达到了这些结果。这表明模型能够有效利用 DSP 组件带来的偏置,同时又没有失去神经网络的表达能力。
For the NSynth dataset, we quantitatively compare the quality of DDSP resynthesis with that of a state-of-the-art baseline using WaveRNN (Hantrakul et al., 2019). The models are comparable as they are trained on the same data, provided the same conditioning, and both targeted towards realtime synthesis applications. In Table 1, we compute loudness and fundamental frequency (F0) metrics described in Section C of the appendix. Despite the strong performance of the baseline, the supervised DDSP autoencoder still outperforms it, especially in F0 . This is not unexpected, as the additive synthesizer directly uses the conditioning frequency to synthesize audio.
在 NSynth 数据集上,我们把 DDSP 重建的质量与当时基于 WaveRNN 的最强基线(Hantrakul et al., 2019)做了定量比较。这些模型具有可比性:训练数据相同,给定的条件信息相同,并且都面向实时合成。在表 1 中,我们计算了附录 C 节所述的响度和基频(F0) 指标。尽管基线已经很强,有监督的 DDSP 自编码器仍然超过了它,尤其是在 F0 上。这一点并不令人意外,因为加性合成器直接使用条件频率来合成音频。
The unsupervised DDSP autoencoder must learn to infer its own F0 conditioning signal directly from the audio. As described in Section B.4, we improve optimization by also adding a perceptual loss in the form of a pretrained CREPE network (Kim et al., 2018). While not as accurate as the supervised DDSP version, the model does a fair job at learning to generate sounds with the correct frequencies without supervision, outperforming the supervised WaveRNN model.
无监督的 DDSP 自编码器必须直接从音频中自行推断 F0 条件信号。如第 B.4 节所述,我们还加入了以预训练 CREPE 网络(Kim et al., 2018)形式出现的感知损失,以改善优化。虽然精度不如有监督的 DDSP 版本,该模型在没有监督的情况下,仍能较好地生成频率正确的声音,并且超过了有监督的 WaveRNN 模型。
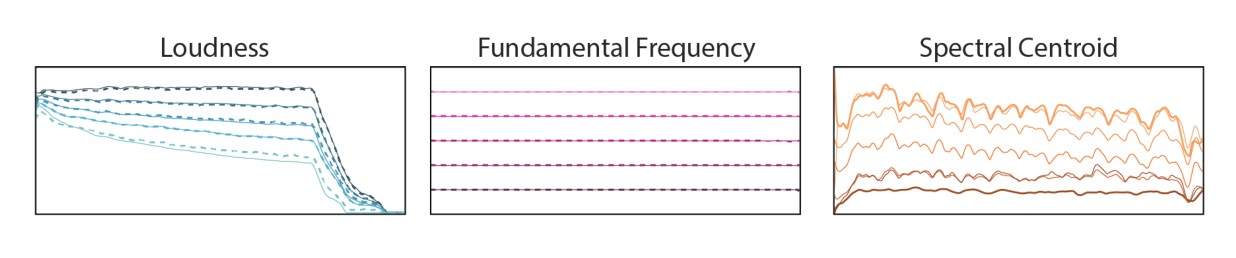
Figure 3: Separate interpolations over loudness, pitch, and timbre. The conditioning features (solid lines) are extracted from two notes and linearly mixed (dark to light coloring). The features of the resynthsized audio (dashed lines) closely follow the conditioning. On the right, the latent vectors, , are interpolated, and the spectral centroid of resulting audio (thin solid lines) smoothly varies between the original samples (dark solid lines).
图 3:分别对响度、音高和音色做插值。条件特征(实线)从两个音符中提取,再做线性混合(颜色由深到浅)。重建音频的特征(虚线)紧密跟随条件。右侧是对潜向量 做插值,得到音频的频谱质心(细实线)在原始样本(深实线)之间平滑变化。
5.2 Independent Control of Loudness and Pitch
5.2 响度与音高的独立控制
Interpolation: Interpretable structure allows for independent control over generative factors. Each component of the factorized latent variables independently alters samples along a matching perceptual axis. For example, Figure 3 shows an interpolation between two sound in the loudness conditioning . With other variables held constant, loudness of the synthesized audio closely matches the interpolated input. Similarly, the model reliably matches intermediate pitches between a high pitched and low pitched . In Table 4 of the appendix, we quantitatively demonstrate how across interpolations, conditioning independently controls the corresponding characteristics of the audio.
插值: 可解释的结构使得生成因子可以被独立控制。分解后的潜变量 的每个分量,都会沿着对应的感知轴独立地改变样本。例如,图 3 展示了在响度条件 上对两段声音做插值。在其他变量保持不变时,合成音频的响度会紧密跟上插值后的输入。类似地,模型也能可靠地匹配高音 与低音 之间的中间音高。在附录的表 4 中,我们定量表明:在各类插值中,条件信息都能独立控制音频的相应特性。
With loudness and pitch explicitly controlled by , the model should use the residual to encode timbre. Although architecture and training do not strictly enforce this encoding, we qualitatively demonstrate how varying leads to a smooth change in timbre. In Figure 3, we use the smooth shift in spectral centroid, or “center of mass” of a spectrum, to illustrate this behavior.
既然响度和音高已由 显式控制,模型就应当用残差 来编码音色。尽管结构和训练并不严格强制这种编码方式,我们从定性上表明,改变 会带来音色的平滑变化。在图 3 中,我们用频谱质心(频谱的“质心”)的平滑移动来说明这一行为。
Extrapolation: As described in Section 4.1, directly controls the additive synthesizer and has structural meaning outside the context of any given dataset. Beyond interpolating between datapoints, the model can extrapolate to new conditions not seen during training. The rightmost plot of Figure 7 demonstrates this by resynthesizing a clip of solo violin after shifting down an octave and outside the range of the training data. The audio remains coherent and resembles a related instrument such as a cello. is only modified for the synthesizer, as the decoder is still bounded by the nearby distribution of the training data and produces unrealistic harmonic content if conditioned far outside that distribution.
外推: 如第 4.1 节所述, 直接控制加性合成器,并且具有不依赖于任何特定数据集的结构意义。模型不仅能在数据点之间插值,还能外推到训练时未见过的新条件。图 7 最右侧的图把一段独奏小提琴的 下移一个八度,使其落到训练数据范围之外再做重建。音频仍然连贯,听起来接近大提琴一类的相关乐器。 只在合成器一侧被修改,因为解码器仍受训练数据邻近分布的约束:如果把条件推到离该分布很远的地方,它会产生不自然的谐波内容。
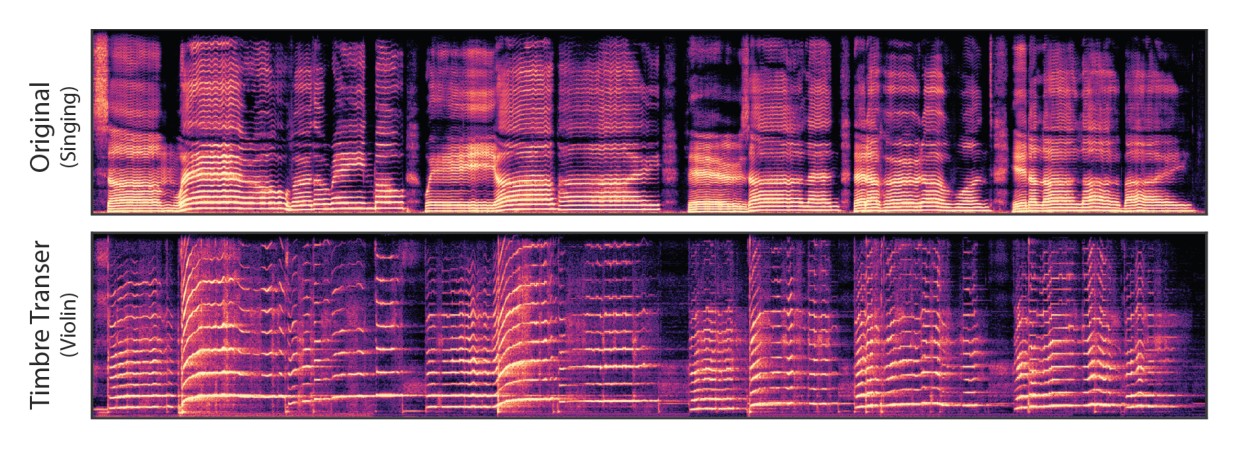
Figure 4: Timbre transfer from singing voice to violin. F0 and loudness features are extracted from the voice and resynthesized with a DDSP autoencoder trained on solo violin.
图 4:把歌声的音色转换成小提琴。从人声中提取 F0 和响度特征,再用在独奏小提琴上训练的 DDSP 自编码器重新合成。
5.3 Dereverberation and Acoustic Transfer
5.3 去混响与声学迁移
Removing reverb in a “blind” setting, where only reverberated audio is available, is a standing problem in acoustics (Naylor & Gaubitch, 2010). However, a benefit of our modular approach to generative modeling is that it becomes possible to completely separate the source audio from the effect of the room. For the solo violin dataset, the DDSP autoencoder is trained with an additional reverb module as shown in Figure 2 and described in Section 3.6. Figure 7 (left) demonstrates that bypassing the reverb module during resynthesis results in completely dereverberated audio, similar to recording in an anechoic chamber. The quality of the approach is limited by the underlying generative model, which is quite high for our autoencoder. Similarly, Figure 7 (center) demonstrates that we can also apply the learned reverb model to new audio, in this case singing, and effectively transfer the acoustic environment of the solo violin recordings.
在只有带混响音频、没有“干净”参考的“盲”条件下去除混响,是声学里一个长期存在的问题(Naylor & Gaubitch, 2010)。而模块化生成建模的一个好处是,可以把源音频与房间效果完全分开。对独奏小提琴数据集,DDSP 自编码器按图 2 和第 3.6 节所述,额外加入了混响模块。图 7(左)表明,重建时跳过混响模块,就能得到完全去混响的音频,效果类似于在消声室里录音。这种方法的质量受限于底层生成模型,而我们的自编码器质量已经相当高。类似地,图 7(中)表明,我们也可以把学到的混响模型加到新的音频上——这里是歌声——从而有效迁移独奏小提琴录音所处的声学环境。
5.4 Timbre Transfer
5.4 音色转换
Figure 4 demonstrates timbre transfer, converting the singing voice of an author into a violin. F0 and loudness features are extracted from the singing voice and the DDSP autoencoder trained on solo violin used for resynthesis. To better match the conditioning features, we first shift the fundamental frequency of the singing up by two octaves to fit a violin’s typical register. Next, we transfer the room acoustics of the violin recording (as described in Section 5.3) to the voice before extracting loudness, to better match the loudness contours of the violin recordings. The resulting audio captures many subtleties of the singing with the timbre and room acoustics of the violin dataset. Note the interesting “breathing” artifacts in the silence corresponding to unvoiced syllables from the singing.
图 4 展示了音色转换:把一位作者的歌声变成小提琴。我们从歌声中提取 F0 和响度特征,再用在独奏小提琴上训练的 DDSP 自编码器重新合成。为了让条件特征更匹配,我们先把歌声的基频提高两个八度,以贴近小提琴通常的音区。接着,在提取响度之前,先把小提琴录音的房间声学迁移到人声上(做法见第 5.3 节),以便更好地匹配小提琴录音的响度轮廓。得到的音频保留了歌声中的许多细微之处,同时具有小提琴数据集的音色和房间声学。注意静音段里有趣的“呼吸”伪影,它们对应于歌声中的清音音节。
6 Conclusion
6 结论
The DDSP library fuses classical DSP with deep learning, providing the ability to take advantage of strong inductive biases without losing the expressive power of neural networks and end-to-end learning. We encourage contributions from domain experts and look forward to expanding the scope of the DDSP library to a wide range of future applications.
DDSP 程序库把经典 DSP 与深度学习结合起来,使人既能利用较强的归纳偏置,又不失去神经网络和端到端学习的表达能力。我们欢迎领域专家的贡献,也期待把 DDSP 程序库的适用范围扩展到更多未来应用中。
References
参考文献
S. O. Arik, H. Jun, and G. Diamos. Fast spectrogram inversion using multi-head convolutional neural networks. IEEE Signal Processing Letters, 26(1):94–98, Jan 2019. doi: 10.1109/LSP.2018.2880284.
James W Beauchamp. Analysis, synthesis, and perception of musical sounds. Springer, 2007.
Merlijn Blaauw and Jordi Bonada. A neural parametric singing synthesizer modeling timbre and expression from natural songs. Applied Sciences, 7(12):1313, 2017.
Pritish Chandna, Merlijn Blaauw, Jordi Bonada, and Emilia Gomez. Wgansing: A multi-voice singing voice synthesizer based on the wasserstein-gan. arXiv preprint arXiv:1903.10729, 2019.
Taishih Chi, Powen Ru, and Shihab A Shamma. Multiresolution spectrotemporal analysis of complex sounds. The Journal of the Acoustical Society of America, 118(2):887–906, 2005.
Alexandre Defossez, Neil Zeghidour, Nicolas Usunier, Leon Bottou, and Francis Bach. Sing: Symbol-to-instrument neural generator. In S. Bengio, H. Wallach, H. Larochelle, K. Grauman, N. Cesa-Bianchi, and R. Garnett (eds.), Advances in Neural Information Processing Systems 31, pp. 9041–9051. Curran Associates, Inc., 2018. URL http://papers.nips.cc/paper/8118-sing-symbol-to-instrument-neural-generator.pdf.
Chris Donahue, Julian McAuley, and Miller Puckette. Adversarial audio synthesis. In International Conference on Learning Representations, 2019. URL https://openreview.net/forum?id=ByMVTsR5KQ.
Alexey Dosovitskiy and Thomas Brox. Generating images with perceptual similarity metrics based on deep networks. In Advances in neural information processing systems, pp. 658–666, 2016.
Jesse Engel, Cinjon Resnick, Adam Roberts, Sander Dieleman, Douglas Eck, Karen Simonyan, and Mohammad Norouzi. Neural audio synthesis of musical notes with WaveNet autoencoders. In ICML, 2017.
Jesse Engel, Kumar Krishna Agrawal, Shuo Chen, Ishaan Gulrajani, Chris Donahue, and Adam Roberts. GANSynth: Adversarial neural audio synthesis. In International Conference on Learning Representations, 2019. URL https://openreview.net/forum?id=H1xQVn09FX.
Philippe Esling, Naotake Masuda, Adrien Bardet, Romeo Despres, et al. Universal audio synthesizer control with normalizing flows. arXiv preprint arXiv:1907.00971, 2019.
James L Flanagan. Speech analysis synthesis and perception, volume 3. Springer Science & Business Media, 2013.
David Ha and Jürgen Schmidhuber. World models. arXiv preprint arXiv:1803.10122, 2018.
Lamtharn (Hanoi) Hantrakul, Jesse Engel, Adam Roberts, and Chenjie Gu. Fast and flexible neural audio synthesis. In ISMIR, 2019.
Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. Deep residual learning for image recognition. In Proceedings of the IEEE conference on computer vision and pattern recognition, pp. 770–778, 2016.
Matthew D Hoffman and Perry R Cook. Feature-based synthesis: Mapping acoustic and perceptual features onto synthesis parameters. In ICMC. Citeseer, 2006.
Kurt Hornik, Maxwell Stinchcombe, and Halbert White. Multilayer feedforward networks are universal approximators. Neural networks, 2(5):359–366, 1989.
Cheng-Zhi Anna Huang, David Duvenaud, Kenneth C Arnold, Brenton Partridge, Josiah W Oberholtzer, and Krzysztof Z Gajos. Active learning of intuitive control knobs for synthesizers using gaussian processes. In Proceedings of the 19th international conference on Intelligent User Interfaces, pp. 115–124. ACM, 2014.
Nal Kalchbrenner, Erich Elsen, Karen Simonyan, Seb Noury, Norman Casagrande, Edward Lockhart, Florian Stimberg, Aaron van den Oord, Sander Dieleman, and Koray Kavukcuoglu. Efficient neural audio synthesis. arXiv preprint arXiv:1802.08435, 2018.
Jong Wook Kim, Justin Salamon, Peter Li, and Juan Pablo Bello. Crepe: A convolutional representation for pitch estimation. In 2018 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), pp. 161–165. IEEE, 2018.
Anssi Klapuri, Tuomas Virtanen, and Jan-Markus Holm. Robust multipitch estimation for the analysis and manipulation of polyphonic musical signals. In Proc. COST-G6 Conference on Digital Audio Effects, pp. 233–236, 2000.
Y. LeCun, B. Boser, J. S. Denker, D. Henderson, R. E. Howard, W. Hubbard, and L. D. Jackel. Backpropagation applied to handwritten zip code recognition. Neural Computation, 1(4):541–551, 1989. doi: 10.1162/neco.1989.1.4.541. URL https://doi.org/10.1162/neco.1989.1.4.541.
Francesco Locatello, Stefan Bauer, Mario Lucic, Sylvain Gelly, Bernhard Schölkopf, and Olivier Bachem. Challenging common assumptions in the unsupervised learning of disentangled representations. arXiv preprint arXiv:1811.12359, 2018.
Robert McAulay and Thomas Quatieri. Speech analysis/synthesis based on a sinusoidal representation. IEEE Transactions on Acoustics, Speech, and Signal Processing, 34(4):744–754, 1986.
Soroush Mehri, Kundan Kumar, Ishaan Gulrajani, Rithesh Kumar, Shubham Jain, Jose Sotelo, Aaron Courville, and Yoshua Bengio. Samplernn: An unconditional end-to-end neural audio generation model. arXiv preprint arXiv:1612.07837, 2016.
Michelle Moerel, Federico De Martino, and Elia Formisano. Processing of natural sounds in human auditory cortex: tonotopy, spectral tuning, and relation to voice sensitivity. Journal of Neuroscience, 32(41):14205–14216, 2012.
Masanori Morise, Fumiya Yokomori, and Kenji Ozawa. World: a vocoder-based high-quality speech synthesis system for real-time applications. IEICE TRANSACTIONS on Information and Systems, 99(7):1877–1884, 2016.
Patrick A Naylor and Nikolay D Gaubitch. Speech dereverberation. Springer Science & Business Media, 2010.
Aaron van den Oord, Sander Dieleman, Heiga Zen, Karen Simonyan, Oriol Vinyals, Alex Graves, Nal Kalchbrenner, Andrew Senior, and Koray Kavukcuoglu. Wavenet: A generative model for raw audio. arXiv preprint arXiv:1609.03499, 2016.
Heiko Purnhagen and Nikolaus Meine. Hiln-the mpeg-4 parametric audio coding tools. In 2000 IEEE International Symposium on Circuits and Systems. Emerging Technologies for the 21st Century. Proceedings (IEEE Cat No. 00CH36353), volume 3, pp. 201–204. IEEE, 2000.
Xavier Serra and Julius Smith. Spectral modeling synthesis: A sound analysis/synthesis system based on a deterministic plus stochastic decomposition. Computer Music Journal, 14(4):12–24, 1990.
Julius Orion Smith. Physical audio signal processing: For virtual musical instruments and audio effects. W3K publishing, 2010.
Ilya Sutskever, Oriol Vinyals, and Quoc V Le. Sequence to sequence learning with neural networks. In Advances in neural information processing systems, pp. 3104–3112, 2014.
Edwin Tellman, Lippold Haken, and Bryan Holloway. Timbre morphing of sounds with unequal numbers of features. Journal of the Audio Engineering Society, 43(9):678–689, 1995.
Frédéric E Theunissen and Julie E Elie. Neural processing of natural sounds. Nature Reviews Neuroscience, 15(6):355, 2014.
Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Łukasz Kaiser, and Illia Polosukhin. Attention is all you need. In Advances in neural information processing systems, pp. 5998–6008, 2017.
Xin Wang, Shinji Takaki, and Junichi Yamagishi. Neural source-filter waveform models for statistical parametric speech synthesis. arXiv preprint arXiv:1904.12088, 2019.
Yuxuan Wang, RJ Skerry-Ryan, Daisy Stanton, Yonghui Wu, Ron J Weiss, Navdeep Jaitly, Zongheng Yang, Ying Xiao, Zhifeng Chen, Samy Bengio, et al. Tacotron: Towards end-to-end speech synthesis. In INTERSPEECH, 2017.
P. J. Werbos. Backpropagation through time: what it does and how to do it. Proceedings of the IEEE, 78(10):1550–1560, Oct 1990. doi: 10.1109/5.58337.
Ronald J Williams and David Zipser. Gradient-based learning algorithms for recurrent connectionist networks. College of Computer Science, Northeastern University Boston, MA, 1990.
A Appendix
A 附录
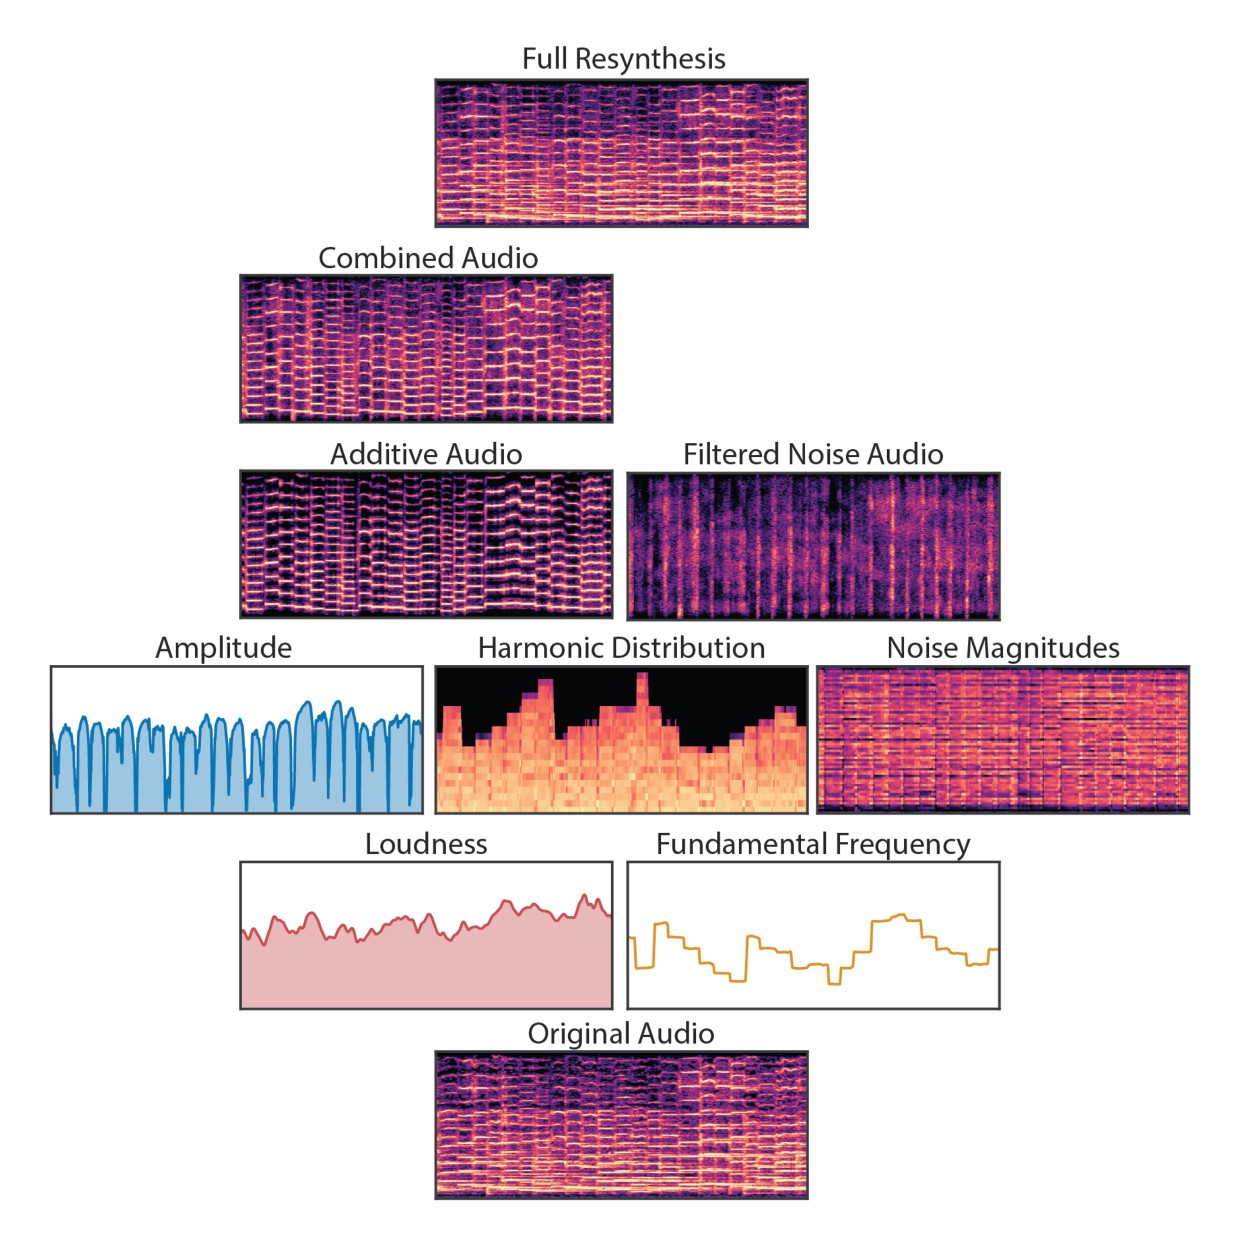
Figure 5: Decomposition of a clip of solo violin. Audio is visualized with log magnitude spectrograms. Loudness and fundamental frequency signals are extracted from the original audio. The loudness curve does not exhibit clear note segmentations because of the effects of the room acoustics. The DDSP autoencoder takes those conditioning signals and predicts amplitudes, harmonic distributions, and noise magnitudes. Note that the amplitudes are clearly segmented along note boundaries without supervision and that the harmonic and noise distributions are complex and dynamic despite the simple conditioning signals. Finally, the extracted impulse response is applied to the combined audio from the synthesizers to give the full resynthesis audio.
图 5:一段独奏小提琴的分解。音频用对数幅度频谱图来可视化。响度和基频信号从原始音频中提取。由于房间声学的影响,响度曲线并没有呈现出清晰的音符分段。DDSP 自编码器接收这些条件信号,预测振幅、谐波分布和噪声幅度。可以看到,振幅在没有监督的情况下仍沿音符边界清晰分段,而谐波分布和噪声分布尽管条件信号很简单,却复杂且随时间变化。最后,把提取到的冲激响应加到合成器合并后的音频上,得到完整的重建音频。
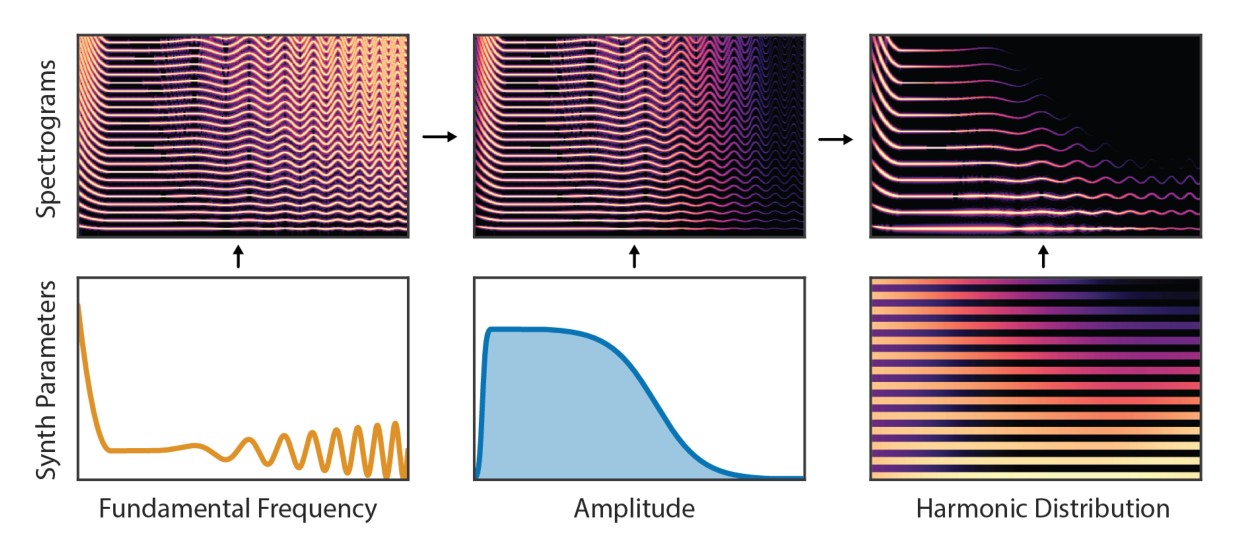
Figure 6: Diagram of the Additive Synthesizer component. The synthesizer generates audio as a sum of sinusoids at harmonic (integer) multiples of the fundamental frequency. The neural network is then tasked with emitting time-varying synthesizer parameters (fundamental frequency, amplitude, harmonic distribution). In this example linear-frequency log-magnitude spectrograms show how the harmonics initially follow the frequency contours of the fundamental. We then factorize the harmonic amplitudes into an overall amplitude envelope that controls the loudness, and a normalized distribution among the different harmonics that determines spectral variations.
图 6:加性合成器组件示意图。合成器把基频整数倍(谐波)上的正弦波相加,生成音频。神经网络的任务是发出时变的合成器参数(基频、振幅、谐波分布)。在这个例子里,线性频率的对数幅度频谱图显示,谐波起初跟随基频的频率轮廓。我们再把谐波振幅分解为控制响度的总振幅包络,以及决定频谱变化的、在不同谐波之间的归一化分布。
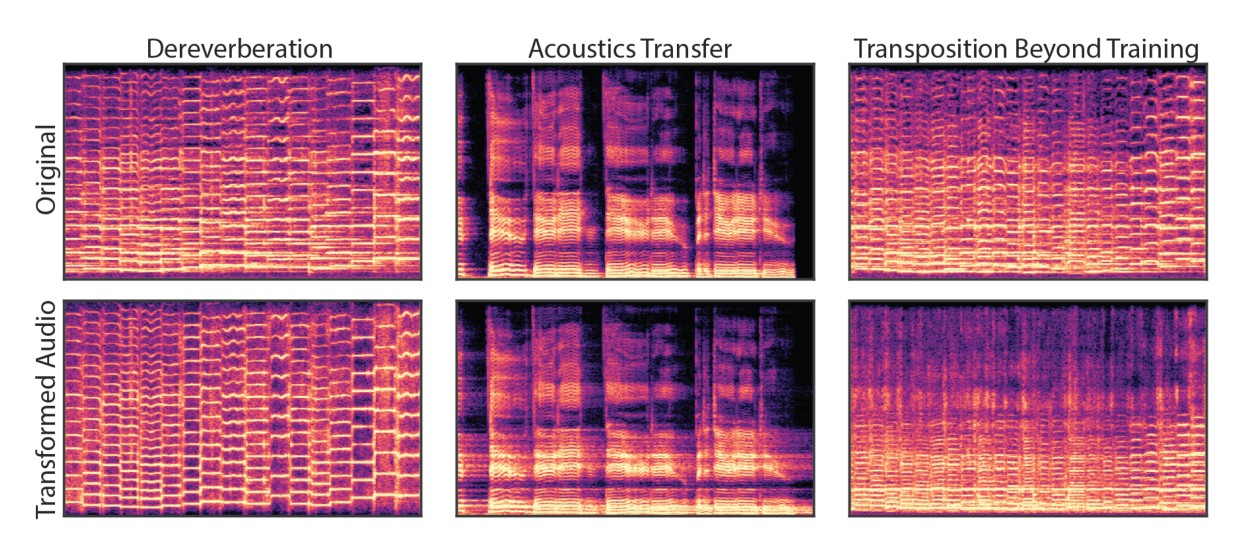
Figure 7: Interpretable generative models enables disentanglement and extrapolation. Spectrograms of audio examples include dereverberation of a clip of solo violin playing (left), transfer of the extracted room response to new audio (center), and transposition below the range of training data (right).
图 7:可解释的生成模型使解耦和外推成为可能。音频样本的频谱图包括:对一段独奏小提琴演奏去混响(左),把提取到的房间响应迁移到新音频上(中),以及移调到低于训练数据范围(右)。
Appendix B Model details
B 模型细节
B.1 Encoders
B.1 编码器
The model has three encoders: -encoder that outputs fundamental frequency , -encoder that outputs loudness , and a -encoder that outputs residual vector .
模型有三个编码器:-编码器输出基频 ,-编码器输出响度 ,以及 -编码器输出残差向量 。
-encoder: We use a pretrained CREPE pitch detector (Kim et al., 2018) as the -encoder to extract ground truth fundamental frequencies (F0) from the audio. We used the “large” variant of CREPE, which has SOTA accuracy for monophonic audio samples of musical instruments. For our supervised autoencoder experiments, we fixed the weights of the -encoder like (Hantrakul et al., 2019), and for our unsupervised autoencoder experiemnts we jointly learn the weights of a resnet model fed log mel spectrograms of the audio. Full details of the resnet architecture are show in Table 2.
-编码器:我们用预训练的 CREPE 音高检测器(Kim et al., 2018)作为 -编码器,从音频中提取作为基准的基频(F0)。我们使用 CREPE 的 “large” 变体,它在乐器单声音频上具有当时最好的精度。在有监督自编码器实验中,我们像 Hantrakul et al.(2019)那样固定 -编码器的权重;在无监督自编码器实验中,我们联合学习一个以音频对数梅尔频谱图为输入的 ResNet 的权重。ResNet 结构的完整细节见表 2。
-encoder: We use identical computational steps to extract loudness as (Hantrakul et al., 2019). Namely, an A-weighting of the power spectrum, which puts greater emphasis on higher frequencies, followed by log scaling. The vector is then centered according to the mean and standard deviation of the dataset.
-编码器:我们采用与 Hantrakul et al.(2019)相同的计算步骤来提取响度。具体是先对功率谱做 A 计权,以更强调高频,再取对数。随后按数据集的均值和标准差对向量做中心化。
-encoder: As shown in Figure 8, the encoder first calculates MFCC’s (Mel Frequency Cepstrum Coefficients) from the audio. MFCC is computed from the log-mel-spectrogram of the audio with a FFT size of 1024, 128 bins of frequency range between 20Hz to 8000Hz, overlap of 75%. We use only the first 30 MFCCs that correspond to a smoothed spectral envelope. The MFCCs are then passed through a normalization layer (which has learnable shift and scale parameters) and a 512-unit GRU. The GRU outputs (over time) fed to a 512-unit linear layer to obtain . The embedding reported in this model has 16 dimensions across 250 time-steps.
-编码器:如图 8 所示,编码器先从音频计算 MFCC(梅尔频率倒谱系数)。MFCC 由音频的对数梅尔频谱图得到,FFT 尺寸为 1024,在 20Hz 到 8000Hz 之间取 128 个频率箱,重叠 75%。我们只使用前 30 个 MFCC,它们对应于平滑的频谱包络。这些 MFCC 再经过一个归一化层(带可学习的平移和缩放参数)和一个 512 单元的 GRU。GRU 随时间的输出送入 512 单元的线性层,得到 。本文报告的 嵌入是 16 维、跨越 250 个时间步。
Table 2: Model architecture for the f(t) encoder using a Resnet on log mel spectrograms. Spectrograms have a frame size of 2048 and a hop size of 512, and are upsampled at the end to have the same time resoultion as other latents (4ms per a frame). All convolutions use “same” padding and a temporal stride of 1. Each residual block uses a bottleneck structure (He et al., 2016). The final output is a normalized probablity distribution over 128 frequency values (logarithmically scaled between 8.2Hz and 13.3kHz (https://www.inspiredacoustics.com/en/MIDI_note_numbers_and_center_frequencies)). The finally frequency value is the weighted sum of each frequency by its probability.
| Residual Block | Output Size | ||||
|---|---|---|---|---|---|
| layer norm + relu | - | - | - | - | - |
| conv | - | 1 | 1 | 1 | / 4 |
| layer norm + relu | - | - | - | - | - |
| conv | - | 3 | 3 | / 4 | |
| layer norm + relu | - | - | - | - | - |
| conv | - | 1 | 1 | 1 | |
| add residual | - | - | - | - | - |
| Resnet | Output Size | ||||
| LogMelSpectrogram | (125, 229, 1) | - | - | - | - |
| conv2d | (125, 115, 64) | 7 | 7 | 2 | 64 |
| max pool | (125, 58, 64) | 1 | 3 | 2 | - |
| residual block | (125, 58, 128) | 3 | 3 | 1 | 128 |
| residual block | (125, 57, 128) | 3 | 3 | 1 | 128 |
| residual block | (125, 29, 256) | 3 | 3 | 2 | 256 |
| residual block | (125, 29, 256) | 3 | 3 | 1 | 256 |
| residual block | (125, 29, 256) | 3 | 3 | 1 | 256 |
| residual block | (125, 15, 512) | 3 | 3 | 2 | 512 |
| residual block | (125, 15, 512) | 3 | 3 | 1 | 512 |
| residual block | (125, 15, 512) | 3 | 3 | 1 | 512 |
| residual block | (125, 15, 512) | 3 | 3 | 1 | 512 |
| residual block | (125, 8, 1024) | 3 | 3 | 2 | 1024 |
| residual block | (125, 8, 1024) | 3 | 3 | 1 | 1024 |
| residual block | (125, 8, 1024) | 3 | 3 | 1 | 1024 |
| dense | (125, 1, 128) | - | - | 128 | 1 |
| upsample time | (1000, 1, 128) | - | - | - | - |
| softplus and normalize | (1000, 1, 128) | - | - | - | - |
表 2: 编码器的模型结构,在对数梅尔频谱图上使用 ResNet。频谱图的帧长为 2048,跳长为 512,最后再上采样,使其与其他潜变量具有相同的时间分辨率(每帧 4 毫秒)。所有卷积使用 “same” 填充,时间维步长为 1。每个残差块采用瓶颈结构(He et al., 2016)。最终输出是在 128 个频率值上的归一化概率分布(在 8.2Hz 到 13.3kHz 之间按对数划分(https://www.inspiredacoustics.com/en/MIDI_note_numbers_and_center_frequencies))。最终的频率值是各频率按其概率加权求和。
| 残差块 | 输出尺寸 | ||||
|---|---|---|---|---|---|
| layer norm + relu | - | - | - | - | - |
| conv | - | 1 | 1 | 1 | / 4 |
| layer norm + relu | - | - | - | - | - |
| conv | - | 3 | 3 | / 4 | |
| layer norm + relu | - | - | - | - | - |
| conv | - | 1 | 1 | 1 | |
| add residual | - | - | - | - | - |
| Resnet | 输出尺寸 | ||||
| LogMelSpectrogram | (125, 229, 1) | - | - | - | - |
| conv2d | (125, 115, 64) | 7 | 7 | 2 | 64 |
| max pool | (125, 58, 64) | 1 | 3 | 2 | - |
| residual block | (125, 58, 128) | 3 | 3 | 1 | 128 |
| residual block | (125, 57, 128) | 3 | 3 | 1 | 128 |
| residual block | (125, 29, 256) | 3 | 3 | 2 | 256 |
| residual block | (125, 29, 256) | 3 | 3 | 1 | 256 |
| residual block | (125, 29, 256) | 3 | 3 | 1 | 256 |
| residual block | (125, 15, 512) | 3 | 3 | 2 | 512 |
| residual block | (125, 15, 512) | 3 | 3 | 1 | 512 |
| residual block | (125, 15, 512) | 3 | 3 | 1 | 512 |
| residual block | (125, 15, 512) | 3 | 3 | 1 | 512 |
| residual block | (125, 8, 1024) | 3 | 3 | 2 | 1024 |
| residual block | (125, 8, 1024) | 3 | 3 | 1 | 1024 |
| residual block | (125, 8, 1024) | 3 | 3 | 1 | 1024 |
| dense | (125, 1, 128) | - | - | 128 | 1 |
| upsample time | (1000, 1, 128) | - | - | - | - |
| softplus and normalize | (1000, 1, 128) | - | - | - | - |
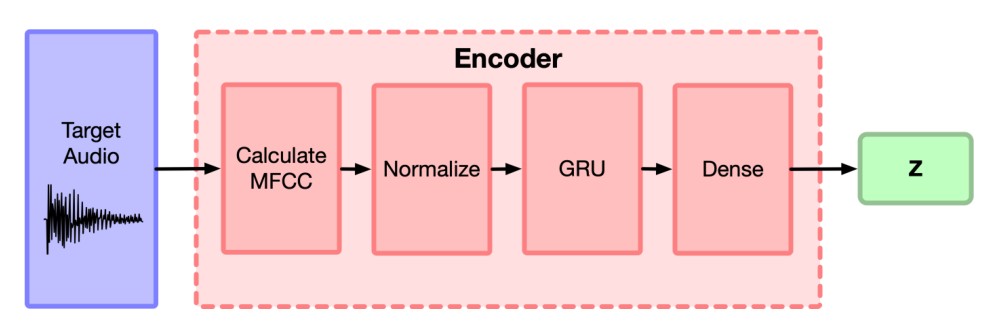
Figure 8: Diagram of the -encoder.
图 8:-编码器示意图。
B.2 Decoder
B.2 解码器
The decoder’s input is the latent tuple (250 timesteps). Its outputs are the parameters required by the synthesizers. For example, in the case of the harmonic synthesizer and filtered noise synthesizer setup, the decoder outputs (amplitudes of the harmonics) for the harmonic synthesizer (note that is fed directly from the latent), and (transfer function of the FIR filter) for the filtered noise synthesizer.
解码器的输入是潜变量元组 (250 个时间步),输出是合成器所需的参数。例如,在谐合成器与滤波噪声合成器的设置中,解码器为谐合成器输出 (各次谐波的振幅;注意 是从潜变量直接送入的),并为滤波噪声合成器输出 (FIR 滤波器的传递函数)。
As shown in Figure 9, we use a “shared-bottom” architecture, which computes a shared embedding from the latent tuple, and then have one head for each of the outputs.
如图 9 所示,我们采用“共享底部”结构:先从潜变量元组计算一个共享嵌入,再为 中的每一路输出设置一个头。
In particular, we apply separate MLPs to each of the input. The outputs of the MLPs are concatenated and passed to a 512-unit GRU. We concatenate the GRU outputs with the outputs of the and MLPs (in the channel dimenssion) and pass it through a final MLP and Linear layer to get the decoder outputs.
具体来说,我们对 中的每一路输入分别施加 MLP。各 MLP 的输出拼接后送入一个 512 单元的 GRU。再把 GRU 的输出与 和 两个 MLP 的输出在通道维上拼接,经过最后的 MLP 和线性层,得到解码器输出。
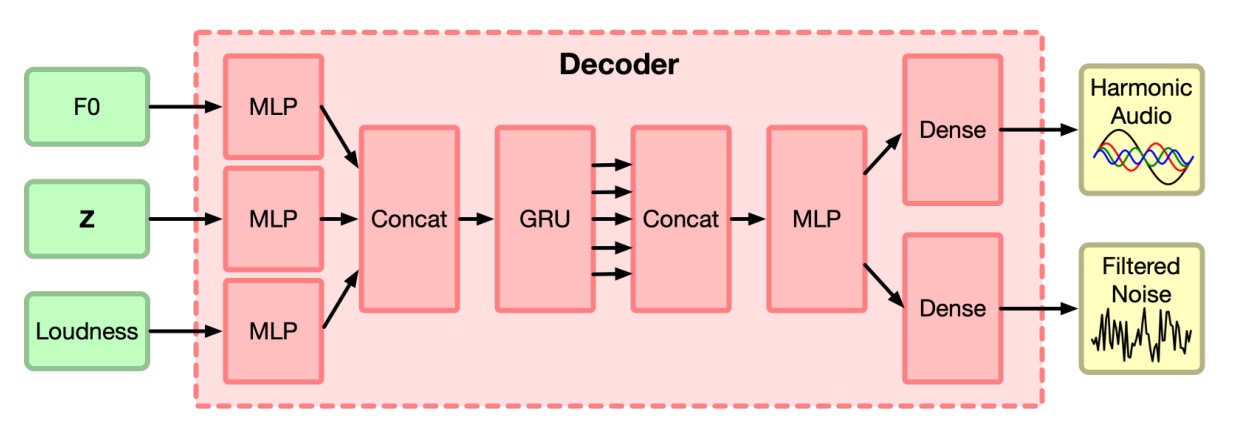
Figure 9: Diagram of the decoder for the harmonic synthesizer and the filtered noise synthesizer.
图 9:谐合成器和滤波噪声合成器的解码器示意图。
The MLP architecture, shown in Figure 10, is a standard MLP with a layer normalization (tf.contrib.layers.layer_norm ) before the RELU nonlinearity. In Figure 9, all the MLPs have 3 layers and each layer has 512 units.
MLP 结构如图 10 所示,是标准 MLP,在 RELU 非线性之前有一层归一化(tf.contrib.layers.layer_norm)。在图 9 中,所有 MLP 都是 3 层,每层 512 个单元。
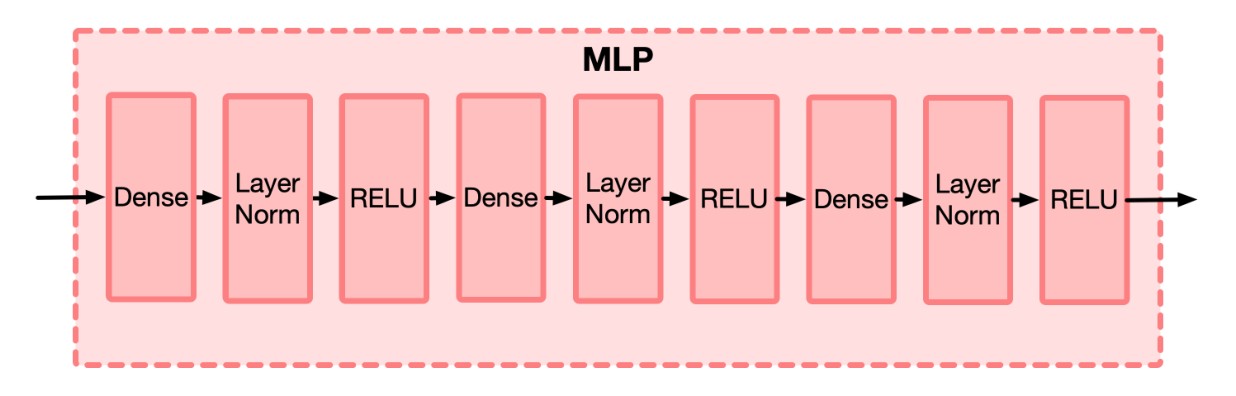
Figure 10: MLP in the decoder.
图 10:解码器中的 MLP。
B.3 Training
B.3 训练
Because all DDSP components are differentiable, the model is differentiable end-to-end. Therefore, we can apply any SGD optimizer to train the model. We used ADAM optimizer with learning rate 0.001 and exponential learning rate decay 0.98 every 10,000 steps.
因为所有 DDSP 组件都是可微分的,整个模型端到端可微。因此可以用任意 SGD 优化器来训练。我们使用 ADAM 优化器,学习率为 0.001,并每 10,000 步按 0.98 做指数学习率衰减。
B.4 Perceptual loss
B.4 感知损失
To help guide the DDSP autoencoder that must predict on the NSynth dataset, we also added an additional perceptual loss using pretrained models, such as the CREPE (Kim et al., 2018) pitch estimator and the encoder of the WaveNet autoencoder (Engel et al., 2017). Compared to the L1 loss on the spectrogram, the activations of different layers in these models correlate better with the perceptual quality of the audio. After a large-scale hyperparameter search, we obtained our best results by using the L1 distance between the activations of the small CREPE model’s fifth max pool layer with a weighting of relative to the spectral loss.
为了帮助必须在 NSynth 数据集上预测 的 DDSP 自编码器,我们还加入了额外的感知损失,使用预训练模型,例如 CREPE(Kim et al., 2018)音高估计器和 WaveNet 自编码器(Engel et al., 2017)的编码器。与频谱图上的 L1 损失相比,这些模型不同层的激活与音频的感知质量相关性更好。经过大规模超参数搜索后,我们得到的最好结果是:取小型 CREPE 模型第五个最大池化层激活之间的 L1 距离,相对频谱损失的权重为 。
B.5 Synthesizers
B.5 合成器
Harmonic synthesizer / Additive Synthesis: We use 101 harmonics in the harmonic synthesizer (i.e., ’s dimension is 101). Amplitude and harmonic distribution parameters are upsampled with overlapping Hamming window envelopes whose frame size is 128 and hop size is 64. Initial phases are all fixed to zero, as neither the spectrogram loss functions or human perception are sensitive to absolute offsets in harmonic phase. We also do not include synthesis elements to model DC components to signals as they are inaudible and not reflected in the spectrogram losses.
谐合成器/加性合成:谐合成器使用 101 个谐波(即 的维度为 101)。振幅和谐波分布参数用互相重叠的汉明窗包络上采样,帧长 128,跳长 64。初相全部固定为 0,因为频谱损失和人类听觉对谐波相位的绝对偏移都不敏感。我们也不加入用于建模信号直流分量的合成元件,因为它们听不见,也不会反映在频谱损失里。
We force the amplitudes, harmonic distributions, and filtered noise magnitudes to be non-negative by applying a sigmoid nonlinearity to network outputs. We find a slight improvement in traning stability by modifying the sigmoid to have a scaled output, larger slope by exponentiating, and threshold at a minimum value:
为了强制振幅、谐波分布和滤波噪声幅度非负,我们对网络输出施加 sigmoid 非线性。我们发现,把 sigmoid 改成带缩放的输出、通过取指数加大斜率,并设一个最小阈值,训练稳定性会略有改善:
Filtered noise synthesizer: We use 65 network output channels as magnitude inputs to the FIR filter of the filtered noise synthesizer.
滤波噪声合成器:我们使用 65 个网络输出通道,作为滤波噪声合成器中 FIR 滤波器的幅度输入。
B.6 Parameter Counts
B.6 参数量
Table 3: Parameter counts for different models. All models trained on NSynth dataset except for those marked (Solo Violin). Autoregressive models have the most parameters with GANs requiring less. The DDSP models examined in this paper (which have not been optimized at all for size) require 2 to 3 times less parameters than GANSynth. The unsupervised model has more parameters because of the CREPE (small) encoder, and the autoencoder has additional parameters for the encoder. Initial experiments with extremely small models (single GRU, 256 units), have slightly less realistic outputs, but still relatively high quality (as can be heard in the supplemental audio).
| Model | Parameters |
|---|---|
| WaveNet Autoencoder (Engel et al., 2017) | 75M |
| WaveRNN (Hantrakul et al., 2019) | 23M |
| GANSynth (Engel et al., 2019) | 15M |
| DDSP Autoencoder (Unsupervised) | 12M |
| DDSP Autoencoder (Supervised, NSynth) | 7M |
| DDSP Autoencoder (Supervised, Solo Violin) | 6M |
| DDSP Autoencoder Tiny (Supervised, Solo Violin) | 0.24M |
表 3:不同模型的参数量。除标明(Solo Violin)的以外,所有模型都在 NSynth 数据集上训练。自回归模型参数最多,GAN 所需参数较少。本文考察的 DDSP 模型(完全没有针对规模做优化)所需参数比 GANSynth 少 2 到 3 倍。无监督模型参数更多,是因为使用了 CREPE(small) 编码器;自编码器还为 编码器增加了参数。用极小模型(单层 GRU,256 个单元)做的初步实验,输出的逼真程度略低,但音质仍然相对较高(可在补充音频中听到)。
| 模型 | 参数量 |
|---|---|
| WaveNet Autoencoder (Engel et al., 2017) | 75M |
| WaveRNN (Hantrakul et al., 2019) | 23M |
| GANSynth (Engel et al., 2019) | 15M |
| DDSP Autoencoder (Unsupervised) | 12M |
| DDSP Autoencoder (Supervised, NSynth) | 7M |
| DDSP Autoencoder (Supervised, Solo Violin) | 6M |
| DDSP Autoencoder Tiny (Supervised, Solo Violin) | 0.24M |
Appendix C Evaluation details
C 评测细节
C.1 Metrics
C.1 指标
Loudness distance: The loudness vector is extracted from the synthesized audio and distance computed against the input’s conditioning loudness vector (ground truth). A better model will produce lower distances, indicating input and generated loudness vectors closely match. Note this distance is not back-propagated through the network as a training objective.
响度 距离:从合成音频中提取响度向量,再与输入的条件响度向量(基准)计算 距离。更好的模型会得到更低的 距离,表明输入响度与生成响度更接近。注意,这一距离不会作为训练目标回传到网络中。
F0 distance: The F0 distance is reported in MIDI space for easier interpretation; an average F0 of 1.0 corresponds to a semitone difference. We use the same confidence threshold of 0.85 in (Hantrakul et al., 2019) to select portions where there was detectable pitch content, and compute the metric only in these areas.
F0 距离:F0 的 距离在 MIDI 空间中报告,以便解释;平均 F0 为 1.0 对应一个半音的差异。我们采用 Hantrakul et al.(2019)中同样的 0.85 置信度阈值,只在检测到音高内容的区段上计算该指标。
F0 Outliers: Pitch tracking using CREPE, like any pitch tracker, is not completely reliable. Instabilities in pitch tracking, such as sudden octave jumps at low volumes, can result errors not due to model performance and need to be accounted for. F0 outliers accounts for pitch tracking imperfections in CREPE (Kim et al., 2018) vs. genuinely bad samples generated by the trained model. CREPE outputs both an F0 value as well as a F0 confidence. Samples with confidences below a threshold of 0.85 in (Hantrakul et al., 2019) are labeled as outliers and usually indicate the sample was mostly noise with no pitch or harmonic component. As the model outputs better quality audio, the number of outliers decrease, thus lower scores indicate better performance.
F0 离群: 用 CREPE 做音高跟踪,和任何音高跟踪器一样,并非完全可靠。音高跟踪的不稳定,例如低音量时突然跳八度,会造成并非来自模型表现的误差,需要单独处理。F0 离群用于区分 CREPE(Kim et al., 2018)自身的跟踪缺陷,与训练模型真正生成的劣质样本。CREPE 会同时输出 F0 值和 F0 置信度。按 Hantrakul et al.(2019)的做法,置信度低于 0.85 的样本被标为离群,通常表明该样本几乎全是噪声,没有音高或谐波成分。模型输出的音频质量越高,离群数量就越少,因此分数越低表示表现越好。
C.2 Interpolation Metrics
C.2 插值指标
Loudness and F0 are shown for different interpolation tasks in table 4. In reconstruction, the model is supplied with the standard . Loudness () and F0 () are computed against the ground truth inputs. In loudness interpolation, the model is supplied with , and Loudness () is calculated using as ground truth instead of (). For F0 interpolation, the model is supplied with and F0 () is calculated using as ground truth instead of . For Z interpolation, the model is supplied with . The low and constant Loudness () and F0 () metrics across these interpolations indicate the model is able independently vary these variables without affecting other components.
表 4 给出了不同插值任务上的响度 和 F0 。在重建任务中,模型得到标准输入 。响度()和 F0()相对基准输入计算。在响度插值中,模型得到 ,响度()以 而不是 作为基准。在 F0 插值中,模型得到 ,F0()以 而不是 作为基准。在 Z 插值中,模型得到 。这些插值上响度()和 F0()都较低且大致稳定,表明模型能够独立改变这些变量,而不明显影响其他成分。
Table 4: Loudness and F0 metrics for different interpolation tasks.
| Task | Loudness () | F0 () |
|---|---|---|
| Reconstruction | 0.042 | 0.060 |
| Loudness interp. | 0.061 | 0.060 |
| F0 interp. | 0.048 | 0.070 |
| Z interp. | 0.063 | 0.065 |
表 4:不同插值任务上的响度和 F0 指标。
| 任务 | 响度 () | 基频 () |
|---|---|---|
| 重建 | 0.042 | 0.060 |
| 响度 插值 | 0.061 | 0.060 |
| 基频 插值 | 0.048 | 0.070 |
| Z 插值 | 0.063 | 0.065 |
Appendix D Other notes
D 其他说明
D.1 Sinusoidal models
D.1 正弦模型
While unconstrained sinusoidal oscillator banks are strictly more expressive than harmonic oscillators, we restricted ourselves to harmonic synthesizers for the time being to focus the problem domain. However, this is not a fundamental limitation of the technique and perturbations such as inharmonicity can also be incorporated to handle phenomena such as stiff strings (Smith, 2010).
不受约束的正弦振荡器组在表达能力上严格强于谐振荡器,但为了先把问题域收窄,我们暂时只用谐合成器。这并不是该方法的根本限制:也可以加入非谐性一类的扰动,以处理硬弦等现象(Smith, 2010)。
D.2 Regularization
D.2 正则化
It is worth mentioning that the modular structure of the synthesizers also makes it possible to define additional losses in terms of different synthesizer outputs and parameters. For example, we may impose an SNR loss to penalize outputs with too much noise if we know the training data consists of mostly clean data. We have not experimented too much with such engineered losses, but we believe they can make training more efficient, even though such engineering methods deviates from the end-to-end training paradigm,
值得一提的是,合成器的模块化结构也使我们能够针对不同合成器输出和参数定义额外的损失。例如,如果知道训练数据大多比较干净,就可以施加一项信噪比损失,惩罚噪声过多的输出。我们还没有对这类专门设计的损失做太多实验,但我们认为它们可以提高训练效率,尽管这类工程方法偏离了端到端训练的范式,