Continuous control with deep reinforcement learning
Continuous control with deep reinforcement learning
深度强化学习中的连续控制(Continuous control with deep reinforcement learning)
Timothy P. Lillicrap Thanks: These authors contributed equally. Jonathan J. Hunt 1 1 footnotemark: 1 Alexander Pritzel Nicolas Heess Affiliation: Tom Erez, Yuval Tassa, David Silver & Daan Wierstra Affiliation: Google Deepmind Affiliation: London, UK Affiliation: {countzero, jjhunt, apritzel, heess, Affiliation: { etom, tassa, davidsilver, wierstra} @ google.com
Timothy P. Lillicrap* Jonathan J. Hunt* Alexander Pritzel Nicolas Heess Tom Erez Yuval Tassa David Silver Daan Wierstra
所属机构:Google DeepMind,伦敦,英国
*{countzero, jjhunt, apritzel, heess, etom, tassa, davidsilver, wierstra}@google.com
- 作者贡献相同
Abstract
摘要
We adapt the ideas underlying the success of Deep Q-Learning to the continuous action domain. We present an actor-critic, model-free algorithm based on the deterministic policy gradient that can operate over continuous action spaces. Using the same learning algorithm, network architecture and hyper-parameters, our algorithm robustly solves more than 20 simulated physics tasks, including classic problems such as cartpole swing-up, dexterous manipulation, legged locomotion and car driving. Our algorithm is able to find policies whose performance is competitive with those found by a planning algorithm with full access to the dynamics of the domain and its derivatives. We further demonstrate that for many of the tasks the algorithm can learn policies “end-to-end”: directly from raw pixel inputs.
我们把 Deep Q-Learning 成功背后的思想推广到连续动作域。本文提出一种基于确定性策略梯度的 actor-critic、无模型算法,可直接在连续动作空间上运行。使用同一学习算法、网络结构与超参数,本算法稳健地解决了 20 多个仿真物理任务,包括小车杆摆起、灵巧操作、腿式运动与驾车等经典问题。算法找到的策略,其表现可与拥有完整动力学及其导数的规划算法相竞争。我们还表明,在许多任务上算法能“端到端”学习策略:直接从原始像素输入出发。
1 Introduction
1 引言
One of the primary goals of the field of artificial intelligence is to solve complex tasks from unprocessed, high-dimensional, sensory input. Recently, significant progress has been made by combining advances in deep learning for sensory processing (Krizhevsky et al. 2012) with reinforcement learning, resulting in the “Deep Q Network” (DQN) algorithm (Mnih et al. 2015) that is capable of human level performance on many Atari video games using unprocessed pixels for input. To do so, deep neural network function approximators were used to estimate the action-value function.
人工智能领域的首要目标之一是从未经处理的高维,感官输入中解决复杂的任务. 最近,通过将 54 深度学习促进感官处理的进展(Krizhevsky等人,2012年)与强化学习相结合,取得了显著进展,形成了“深度Q网络”(DQN)算法(Mnih等人,2015年),该算法能够使用未处理像素进行输入,在许多阿塔里电子游戏上实现人的水平性化。 为此,使用了深神经网络功能近似器来估计动作值功能.
However, while DQN solves problems with high-dimensional observation spaces, it can only handle discrete and low-dimensional action spaces. Many tasks of interest, most notably physical control tasks, have continuous (real valued) and high dimensional action spaces. DQN cannot be straightforwardly applied to continuous domains since it relies on a finding the action that maximizes the action-value function, which in the continuous valued case requires an iterative optimization process at every step.
然而,虽然DQN解决了高维观测空间的问题,但它只能处理离散和低维的动作空间. 许多感兴趣的任务,最显著的是物理控制任务,有连续(真实价值)和高维的动作空间. 琌ぃ虏虫рDQN应用膥尿跋办 硂惠璶т翴 程笆 Governments - value场だ , function function function function
An obvious approach to adapting deep reinforcement learning methods such as DQN to continuous domains is to to simply discretize the action space. However, this has many limitations, most notably the curse of dimensionality: the number of actions increases exponentially with the number of degrees of freedom. For example, a 7 degree of freedom system (as in the human arm) with the coarsest discretization for each joint leads to an action space with dimensionality: . The situation is even worse for tasks that require fine control of actions as they require a correspondingly finer grained discretization, leading to an explosion of the number of discrete actions. Such large action spaces are difficult to explore efficiently, and thus successfully training DQN-like networks in this context is likely intractable. Additionally, naive discretization of action spaces needlessly throws away information about the structure of the action domain, which may be essential for solving many problems.
将DQN等深度强化学习方法适应连续域的明显方法是简单地将动作空间盘片化. 然而,这有许多限制,最显著的是维度的诅咒:行动的数量随着自由度的数量而成指数增长. 例如,一个7度的自由系统(如在人类手臂中),每关节最短的圆盘化导致一个具有维度的动作空间:. 对于需要精细控制行动的任务来说,情况更为糟糕,因为这些任务需要相应的精细粉碎,导致离散行动的数量激增。 此类大型行动空间难以有效探索,因此,在这方面成功培训类似DQN的网络可能难以解决。 此外,行动空间的天真化不必要地丢弃有关行动领域结构的信息,这对于解决许多问题可能至关重要。
In this work we present a model-free, off-policy actor-critic algorithm using deep function approximators that can learn policies in high-dimensional, continuous action spaces. Our work is based on the deterministic policy gradient (DPG) algorithm (Silver et al. 2014) (itself similar to NFQCA (Hafner & Riedmiller 2011), and similar ideas can be found in (Prokhorov et al. 1997)). However, as we show below, a naive application of this actor-critic method with neural function approximators is unstable for challenging problems.
在这部作品中,我们提出了一种没有模型,没有政策的actor-critic算法,它使用深层函数近似器,可以在高维的连续动作空间中学习政策. 我们的工作基于确定性政策梯度算法(Silver等人,2014年)(其本身类似于NFQCA(Hafner & Riedmiller,2011年),类似的想法可见于(Prokhorov等人,1997年))。 然而,如下文所示,这种带有神经功能近似器的actor-critic方法的天真应用对于挑战性的问题来说是不稳定的.
Here we combine the actor-critic approach with insights from the recent success of Deep Q Network (DQN) (Mnih et al. 2013; Mnih et al. 2015). Prior to DQN, it was generally believed that learning value functions using large, non-linear function approximators was difficult and unstable. DQN is able to learn value functions using such function approximators in a stable and robust way due to two innovations: 1. the network is trained off-policy with samples from a replay buffer to minimize correlations between samples; 2. the network is trained with a ‘target’ Q network to give consistent targets during temporal difference backups. In this work we make use of the same ideas, along with batch normalization (Ioffe & Szegedy 2015), a recent advance in deep learning.
在此,我们将演员-批评方法与对 " 深度Q网络 " 近期成功的见解结合起来(Mnih等人,2013年;Mnih等人,2015年)。 在DQN之前,一般认为使用大型非线性函数近似器的学习值函数是困难和不稳定的. 由于两个创新,DQN能够用这种函数近似器以稳定和有力的方式学习价值函数: 1. 网络接受从重播缓冲器中提取样本的培训,以尽量减少样本之间的关联性;2. 网络接受`目标 ' Q网络的培训,以便在时间差异备份时给出一致的目标。 在这项工作中,我们利用了同样的思想,以及批归一化(Ioffe & Szegedy 2015),这是深度学习的最新进展。
In order to evaluate our method we constructed a variety of challenging physical control problems that involve complex multi-joint movements, unstable and rich contact dynamics, and gait behavior. Among these are classic problems such as the cartpole swing-up problem, as well as many new domains. A long-standing challenge of robotic control is to learn an action policy directly from raw sensory input such as video. Accordingly, we place a fixed viewpoint camera in the simulator and attempted all tasks using both low-dimensional observations (e.g. joint angles) and directly from pixels.
为了评估我们的方法,我们构建了各种具有挑战性的物理控制问题,这些问题涉及复杂的多联动,不稳定和丰富的接触动力,以及步态行为. 其中包括一些典型的问题,如车杆摇摆问题,以及许多新的领域。 机器人控制的一个长期挑战是直接从视频等原始感官输入中学习动作政策. 因此,我们在模拟器中放置了固定的视角相机,并尝试使用低维观测(如联合视角)和直接从像素进行所有任务.
Our model-free approach which we call Deep DPG (DDPG) can learn competitive policies for all of our tasks using low-dimensional observations (e.g. cartesian coordinates or joint angles) using the same hyper-parameters and network structure. In many cases, we are also able to learn good policies directly from pixels, again keeping hyperparameters and network structure constant [^1].
我们的无模型方法,我们称之为Deep DPG(DDPG),可以使用相同的超参数和网络结构,利用低维观测(如笛卡尔坐标或联合角度)来学习我们所有任务的竞争性政策. 在许多情况下,我们还能够直接从像素中学习好的政策,再次保持超参数和网络结构不变[^1].
A key feature of the approach is its simplicity: it requires only a straightforward actor-critic architecture and learning algorithm with very few “moving parts”, making it easy to implement and scale to more difficult problems and larger networks. For the physical control problems we compare our results to a baseline computed by a planner (Tassa et al. 2012) that has full access to the underlying simulated dynamics and its derivatives (see supplementary information). Interestingly, DDPG can sometimes find policies that exceed the performance of the planner, in some cases even when learning from pixels (the planner always plans over the underlying low-dimensional state space).
这种方法的一个关键特点是简单:它只需要一个简单的演员-批评架构和学习算法,只有极少数的“移动部件”,这样它就容易执行和扩展到更困难的问题和更大的网络。 就物理控制问题而言,我们将我们的结果与一个完全能够访问基本模拟动态及其衍生物的规划者(Tassa等人,2012年)所计算的基线进行比较(见补充资料)。 有趣的是,DDPG有时可以找到超出规划者性能的政策,在某些情况下甚至从像素中学习(规划者总是在基础低维状态空间上进行规划).
2 Background
2 背景
We consider a standard reinforcement learning setup consisting of an agent interacting with an environment in discrete timesteps. At each timestep the agent receives an observation , takes an action and receives a scalar reward . In all the environments considered here the actions are real-valued . In general, the environment may be partially observed so that the entire history of the observation, action pairs may be required to describe the state. Here, we assumed the environment is fully-observed so .
我们考虑建立一个标准强化学习机制,由一种在离散时间步中与环境相互作用的剂组成。 在每一步时,代理人都会收到的观测结果,采取行动,并获得的分级奖励. 在本文所考虑的所有环境中,这些动作都是真实值的。 一般来说,环境可能会被部分观测到,这样就可以要求观测的整个历史,动作配对来描述状态. 在这里,我们假设环境是完全被观察的,因此是。
An agent’s behavior is defined by a policy, , which maps states to a probability distribution over the actions . The environment, , may also be stochastic. We model it as a Markov decision process with a state space , action space , an initial state distribution , transition dynamics , and reward function .
一个代理人的行为是由一个政策()定义的,该政策将动作的概率分布映射为. 环境,, 也可能具有斯图克性. 我们把它作为马可夫决定过程的模型,有状态空间,动作空间,初始状态分布,过渡动态,奖励函数.
The return from a state is defined as the sum of discounted future reward with a discounting factor . Note that the return depends on the actions chosen, and therefore on the policy , and may be stochastic. The goal in reinforcement learning is to learn a policy which maximizes the expected return from the start distribution . We denote the discounted state visitation distribution for a policy as .
从一个国家的回报被定义为贴现的未来奖励XXMAT将根据折现系数的总和. 请注意,返回取决于所选择的行动,因此取决于政策,而且可能具有扭曲性。 加强学习的目标是学习一项政策,从开始分发时,最大限度地实现预期回报。 我们表示,政策的州访量分配折扣为。
The action-value function is used in many reinforcement learning algorithms. It describes the expected return after taking an action in state and thereafter following policy :
动作值函数用于许多强化学习算法. 它描述了在州采取行动之后,以及其后在政策之后,预期的回报:
Many approaches in reinforcement learning make use of the recursive relationship known as the Bellman equation:
许多强化学习的方法都利用称为贝尔曼方程的递归关系:
If the target policy is deterministic we can describe it as a function and avoid the inner expectation:
如果目标政策是决定性的,我们可以将其描述为函数,避免内在期望:
The expectation depends only on the environment. This means that it is possible to learn off-policy, using transitions which are generated from a different stochastic behavior policy .
期望仅取决于环境。 这意味着有可能通过对这种由不同管教行为政策产生的转变来学习。
Q-learning (Watkins & Dayan 1992), a commonly used off-policy algorithm, uses the greedy policy . We consider function approximators parameterized by , which we optimize by minimizing the loss:
Q-learning (Watkins & Dayan 1992),一种常用的非政策算法,使用贪婪的政策. 我们认为由参数化的函数近似值, 通过最小化损失来优化:
where
地点
While is also dependent on , this is typically ignored.
虽然也依赖于,但这通常被忽略.
The use of large, non-linear function approximators for learning value or action-value functions has often been avoided in the past since theoretical performance guarantees are impossible, and practically learning tends to be unstable. Recently, (Mnih et al. 2013; Mnih et al. 2015) adapted the Q-learning algorithm in order to make effective use of large neural networks as function approximators. Their algorithm was able to learn to play Atari games from pixels. In order to scale Q-learning they introduced two major changes: the use of a replay buffer, and a separate target network for calculating . We employ these in the context of DDPG and explain their implementation in the next section.
使用大型的非线性函数近似器进行学习价值或动作-价值函数,由于理论性能保障是不可能的,实际上的学习往往不稳定,所以过去经常被避免. 最近,(Mnih等人,2013年;Mnih等人,2015年)调整了Q学习算法,以有效利用大型神经网络作为函数近似器. 他们的算法能够从像素中学习玩阿塔里游戏. 为了缩放Q学习,它们引入了两个主要变化:使用一个重播缓冲器,和一个单独的目标网络来计算. 我们在《德班宣言和行动纲领》中采用这些办法,并在下一节中解释其执行情况。
3 Algorithm
3 算法
It is not possible to straightforwardly apply Q-learning to continuous action spaces, because in continuous spaces finding the greedy policy requires an optimization of at every timestep; this optimization is too slow to be practical with large, unconstrained function approximators and nontrivial action spaces. Instead, here we used an actor-critic approach based on the DPG algorithm (Silver et al. 2014).
不可能直截了当地将Q学习应用于连续的行动空间,因为在连续的空间中,发现贪婪的政策需要每一步优化;这种优化太慢了,对大型的,不受约束的功能近似器和非三角行动空间来说是实用的. 相反,我们在此采用了基于DPG算法的演员-批评方法(Silver等人,2014年)。
The DPG algorithm maintains a parameterized actor function which specifies the current policy by deterministically mapping states to a specific action. The critic is learned using the Bellman equation as in Q-learning. The actor is updated by following the applying the chain rule to the expected return from the start distribution with respect to the actor parameters:
DPG算法维持一个参数化的演员函数,它通过定点映射状态到特定动作来指定当前政策. 评论家是使用贝尔曼方程在Q学习中学习的. 通过对起始发行关于演员参数的预期回报适用链式规则来更新演员:
$$\begin{split}\nabla_{\theta^{\mu}}J&\approx\E_{s_{t}\sim\rho^{\beta}}\left[\nabla_{\theta^{\mu}}Q(s,a|\theta^{Q})|{s=s{t},a=\mu(s_{t}|\theta^{\mu})}\right]\
&=\E_{s_{t}\sim\rho^{\beta}}\left[\nabla_{a}Q(s,a|\theta^{Q})|{s=s{t},a=\mu(s_{t})}\nabla_{\theta_{\mu}}\mu(s|\theta^{\mu})|{s=s{t}}\right]\end{split} \tag{6}$$
Silver et al. 2014 proved that this is the policy gradient, the gradient of the policy’s performance [^2].
Silver等人,2014年证明,这是 " 政策梯度 " ,即政策业绩的梯度[^2]。
As with Q learning, introducing non-linear function approximators means that convergence is no longer guaranteed. However, such approximators appear essential in order to learn and generalize on large state spaces. NFQCA (Hafner & Riedmiller 2011), which uses the same update rules as DPG but with neural network function approximators, uses batch learning for stability, which is intractable for large networks. A minibatch version of NFQCA which does not reset the policy at each update, as would be required to scale to large networks, is equivalent to the original DPG, which we compare to here. Our contribution here is to provide modifications to DPG, inspired by the success of DQN, which allow it to use neural network function approximators to learn in large state and action spaces online. We refer to our algorithm as Deep DPG (DDPG, Algorithm 1).
与Q学习一样,引入非线性函数近似值意味着趋同不再得到保证. 然而,这些近似者看来对于学习和普及大型国家空间至关重要。 NFQCA (Hafner & Riedmiller 2011),它使用与DPG相同的更新规则,但具有神经网络功能近似器,它使用批量学习实现稳定性,这对大型网络来说是难以解决的. 一个小批量版本的NFQCA,不按要求在每次更新时重设政策,以达到大型网络,相当于我们在这里比较的最初的DPG. 我们在这里的贡献是提供DPG的修改,灵感来自DQN的成功,它允许它使用神经网络功能近似器在大型状态和行动空间在线学习. 我们的算法称为深DPG(DDPG,算法1).
One challenge when using neural networks for reinforcement learning is that most optimization algorithms assume that the samples are independently and identically distributed. Obviously, when the samples are generated from exploring sequentially in an environment this assumption no longer holds. Additionally, to make efficient use of hardware optimizations, it is essential to learn in minibatches, rather than online.
在使用神经网络进行强化学习时遇到的一个挑战是,大多数优化算法都假设样本是独立和相同分布的. 显然,当样品是在环境内依次探索而生成时,这种假设不再存在。 此外,为了有效利用硬件优化,必须在小型电池而不是在线学习。
As in DQN, we used a replay buffer to address these issues. The replay buffer is a finite sized cache . Transitions were sampled from the environment according to the exploration policy and the tuple was stored in the replay buffer. When the replay buffer was full the oldest samples were discarded. At each timestep the actor and critic are updated by sampling a minibatch uniformly from the buffer. Because DDPG is an off-policy algorithm, the replay buffer can be large, allowing the algorithm to benefit from learning across a set of uncorrelated transitions.
与DQN一样,我们使用了重播缓冲器来解决这些问题. 重播缓冲器是一个有限大小的缓存. 根据勘探政策,从环境中对过渡进行了取样,Tuple 被储存在重播缓冲器中. 当回放缓冲器满载时,最古老的样本被丢弃. 每一步,演员和评论家都会通过取样从缓冲器中统一抽取一个小批量来更新. 由于DDPG是政策外的算法,重播缓冲可以很大,使得该算法能够从跨越一组不相关过渡的学习中受益.
Directly implementing Q learning (equation 4) with neural networks proved to be unstable in many environments. Since the network being updated is also used in calculating the target value (equation 5), the Q update is prone to divergence. Our solution is similar to the target network used in (Mnih et al. 2013) but modified for actor-critic and using “soft” target updates, rather than directly copying the weights. We create a copy of the actor and critic networks, and respectively, that are used for calculating the target values. The weights of these target networks are then updated by having them slowly track the learned networks: with . This means that the target values are constrained to change slowly, greatly improving the stability of learning. This simple change moves the relatively unstable problem of learning the action-value function closer to the case of supervised learning, a problem for which robust solutions exist. We found that having both a target and was required to have stable targets in order to consistently train the critic without divergence. This may slow learning, since the target network delays the propagation of value estimations. However, in practice we found this was greatly outweighed by the stability of learning.
以神经网络直接实施Q学习(方程式4)在许多环境中证明是不稳定的. 由于正在更新的也被用于计算目标值(方程式5),Q更新容易出现分歧. 我们的解决方案与(Mnih等人,2013年)中使用的目标网络相似,但因actor-critic而修改,并使用“软”目标更新,而不是直接复制权重. 我们创建了演员和评论家网络的副本,分别是和,用于计算目标值. 这些目标网络的权重随后通过缓慢跟踪学到的网络加以更新:与. 这意味着目标价值观被迫缓慢改变,大大改善了学习的稳定性. 这种简单的改变使学习动作-价值函数的相对不稳定的问题更接近监督学习的情况,这个问题存在强有力的解决办法。 我们发现,既要有目标,又要有目标,就必须有稳定的目标,以便始终如一地训练批评者。 这可能延缓学习,因为目标网络延迟了价值估计的传播。 然而,在实践中,我们发现学习的稳定性大大超过这一点。
When learning from low dimensional feature vector observations, the different components of the observation may have different physical units (for example, positions versus velocities) and the ranges may vary across environments. This can make it difficult for the network to learn effectively and may make it difficult to find hyper-parameters which generalise across environments with different scales of state values.
在从低维特征矢量观测中学习时,观测的不同组成部分可能具有不同的物理单位(例如位置与速度),范围可能因环境而异. 这可能使网络难以有效学习,并可能难以找到超参数,这些参数在具有不同尺度的状态值的环境中通用。
One approach to this problem is to manually scale the features so they are in similar ranges across environments and units. We address this issue by adapting a recent technique from deep learning called batch normalization (Ioffe & Szegedy 2015). This technique normalizes each dimension across the samples in a minibatch to have unit mean and variance. In addition, it maintains a running average of the mean and variance to use for normalization during testing (in our case, during exploration or evaluation). In deep networks, it is used to minimize covariance shift during training, by ensuring that each layer receives whitened input. In the low-dimensional case, we used batch normalization on the state input and all layers of the network and all layers of the network prior to the action input (details of the networks are given in the supplementary material). With batch normalization, we were able to learn effectively across many different tasks with differing types of units, without needing to manually ensure the units were within a set range.
解决这一问题的一个办法是手工扩大特征,使其在环境和单位之间具有类似的范围。 我们通过从深度学习中改编一种叫做“成功正常化”的最新技术来解决这一问题。 (Ioffe & Szegedy 2015) (英语). 这一技术使小批量样本中的每个维度都正常化,从而具有单位平均值和差异。 此外,在测试期间(就我们而言,在勘探或评估期间),它维持用于正常化的平均值和差异的运行平均数。 在深层网络中,它通过确保每层都接收白化输入,在训练期间用于尽量减少共变变换. 在低维情况下,我们在动作输入之前,在状态输入和网络的所有层和网络的所有层上使用批归一化(网络的细节见补充材料). 随着批归一化,我们能够有效地了解不同类型单位的许多不同任务,而不需要人工确保这些单位在规定范围内。
A major challenge of learning in continuous action spaces is exploration. An advantage of off-policies algorithms such as DDPG is that we can treat the problem of exploration independently from the learning algorithm. We constructed an exploration policy by adding noise sampled from a noise process to our actor policy
在连续动作空间学习的一个主要挑战是探索。 DDPG等非政策算法的一个优点是,我们可以从学习算法中独立处理探索问题. 我们制订了一项勘探政策,将从噪音过程采样的噪音添加到我们的演员政策中.
can be chosen to suit the environment. As detailed in the supplementary materials we used an Ornstein–-Uhlenbeck process (Uhlenbeck & Ornstein 1930) to generate temporally correlated exploration for exploration efficiency in physical control problems with inertia (similar use of autocorrelated noise was introduced in (Wawrzyński 2015)).
可以选择适合环境. 正如在补充材料中详述的那样,我们使用Ornstein--Uhlenbeck工艺(Uhlenbeck & Ornstein 1930)在惯性物理控制问题上产生时间上相关的勘探效率(在Wawrzyński 2015).
Randomly initialize critic network and actor with weights and .
Initialize target network and with weights ,
Initialize replay buffer
for episode = 1, M do
Initialize a random process for action exploration
Receive initial observation state
for t = 1, T do
Select action according to the current policy and exploration noise
Execute action and observe reward and observe new state
Store transition in
Sample a random minibatch of transitions from
Set
Update critic by minimizing the loss:
Update the actor policy using the sampled policy gradient:
Update the target networks:
end for
end for
Algorithm 1 DDPG algorithm
随机初始化评论家网络和演员,重量为和.
初始化目标网络和,重量为,
初始化重播缓冲
** 对于插曲=1,Mdo**
初始化一个随机过程用于行动探索
接收初始观测状态
** 对于** t = 1, T ** do **
根据当前政策和勘探噪音选择动作
执行行动和观察奖励和观察新状态
将存储在中
从随机抽取的过渡图
设定
尽量减少损失以更新批评者:
轩然大波的政策梯度
更新目标网络:
** 结束** ** 用于**
** 在处理时** **
** 算法 1 ** DDPG 算法
4 Results
4 结果
We constructed simulated physical environments of varying levels of difficulty to test our algorithm. This included classic reinforcement learning environments such as cartpole, as well as difficult, high dimensional tasks such as gripper, tasks involving contacts such as puck striking (canada) and locomotion tasks such as cheetah (Wawrzyński 2009). In all domains but cheetah the actions were torques applied to the actuated joints. These environments were simulated using MuJoCo (Todorov et al. 2012). Figure 1 shows renderings of some of the environments used in the task (the supplementary contains details of the environments and you can view some of the learned policies at https://goo.gl/J4PIAz).
我们构建了不同难度的模拟物理环境来测试我们的算法. 这包括经典的强化的文件学习环境,如Martpole,以及抓手等困难的、高维度的任务,涉及接触的任务,如puck 震动(canada)和运动任务,如cheetah(Wawrzyński,2009年)。 在所有领域,除了“猎豹”之外,这些行动都适用于引爆的关节。 这些环境是使用MujoCo模拟的(Todorov等人,2012年)。 图1显示了任务中使用的一些环境的渲染(补充内容包含环境细节,您可以在https://goo.gl/J4PIAz上查看一些学到的政策).
In all tasks, we ran experiments using both a low-dimensional state description (such as joint angles and positions) and high-dimensional renderings of the environment. As in DQN (Mnih et al. 2013; Mnih et al. 2015), in order to make the problems approximately fully observable in the high dimensional environment we used action repeats. For each timestep of the agent, we step the simulation 3 timesteps, repeating the agent’s action and rendering each time. Thus the observation reported to the agent contains 9 feature maps (the RGB of each of the 3 renderings) which allows the agent to infer velocities using the differences between frames. The frames were downsampled to 64x64 pixels and the 8-bit RGB values were converted to floating point scaled to . See supplementary information for details of our network structure and hyperparameters.
在所有任务中,我们同时使用低维状态描述(如联合角度和位置)和高维渲染环境进行实验. 与DQN一样(Mnih等人,2013年;Mnih等人,2015年),为了使问题在高维度环境中被大致完全观察到,我们使用了动作重复. 对于代理的每一个时间步,我们一步模拟三个时间步,重复代理的动作,每次渲染. 因此,向代理人报告的观察包含9个特征图(3个渲染图中的每个图的RGB),使代理人能够利用帧之间的差异推断速度. 帧被下取样到64x64像素,8位的RGB值被转换成浮点缩放到. 关于我们的网络结构和超参数,请参看补充资料。
We evaluated the policy periodically during training by testing it without exploration noise. Figure 2 shows the performance curve for a selection of environments. We also report results with components of our algorithm (i.e. the target network or batch normalization) removed. In order to perform well across all tasks, both of these additions are necessary. In particular, learning without a target network, as in the original work with DPG, is very poor in many environments.
在训练期间,我们定期评估政策,在没有勘探噪音的情况下进行测试。 图2显示选定环境的性能曲线。 我们还报告结果,取消了我们算法的组件(即目标网络或批归一化)。 为了很好地完成所有任务,需要增加这两项内容。 特别是没有目标网络的学习,如最初与DPG的工作一样,在许多环境中非常差.
Surprisingly, in some simpler tasks, learning policies from pixels is just as fast as learning using the low-dimensional state descriptor. This may be due to the action repeats making the problem simpler. It may also be that the convolutional layers provide an easily separable representation of state space, which is straightforward for the higher layers to learn on quickly.
令人惊讶的是,在一些更简单的任务中,从像素中学习政策的速度和使用低维状态描述符学习一样快. 这可能是因为重复的行动使问题变得更加简单. 也可能是,卷积层提供了一种易于分离的状态空间代表,对于较高层来说,这是可以快速学习的直截了当的.
Table 1 summarizes DDPG’s performance across all of the environments (results are averaged over 5 replicas). We normalized the scores using two baselines. The first baseline is the mean return from a naive policy which samples actions from a uniform distribution over the valid action space. The second baseline is iLQG (Todorov & Li 2005), a planning based solver with full access to the underlying physical model and its derivatives. We normalize scores so that the naive policy has a mean score of and iLQG has a mean score of . DDPG is able to learn good policies on many of the tasks, and in many cases some of the replicas learn policies which are superior to those found by iLQG, even when learning directly from pixels.
表1总结了DDPG在所有环境中的业绩(结果平均为5个复制品)。 我们用两个基线使分数正常化。 第一个基线是天真政策的平均回报,该政策对行动进行抽样,对有效行动空间进行统一分布。 第二个基线是iLQG(Todorov & Li 2005),这是一个基于规划的解析器,可全面访问基础物理模型及其衍生物. 这样,天真政策的平均得分就达到,iLQG的平均得分达到。 DDPG能够在许多任务上学习好的政策,在许多情况下,一些复制品学习的政策优于iLQG发现的政策,即使直接从像素学习.
It can be challenging to learn accurate value estimates. Q-learning, for example, is prone to over-estimating values (Hasselt 2010). We examined DDPG’s estimates empirically by comparing the values estimated by after training with the true returns seen on test episodes. Figure 3 shows that in simple tasks DDPG estimates returns accurately without systematic biases. For harder tasks the Q estimates are worse, but DDPG is still able learn good policies.
学习准确的价值估计可能具有挑战性。 例如,Q学习容易过高估计值(Hasselt,2010年)。 我们通过将在培训后估计的数值与测试中看到的真实回报进行比较,从实证角度审查了DDPG的估计数。 图3显示,在简单的任务中,DDPG估算返回准确而无系统性偏差. 对于更困难的任务,Q估计更糟糕,但DDPG仍然能够学习好的政策。
To demonstrate the generality of our approach we also include Torcs, a racing game where the actions are acceleration, braking and steering. Torcs has previously been used as a testbed in other policy learning approaches (Koutník et al. 2014b). We used an identical network architecture and learning algorithm hyper-parameters to the physics tasks but altered the noise process for exploration because of the very different time scales involved. On both low-dimensional and from pixels, some replicas were able to learn reasonable policies that are able to complete a circuit around the track though other replicas failed to learn a sensible policy.
为了展示我们的方法的概括性,我们还包括托克斯,一个赛车游戏,其中动作是加速,制动和引导. Torcs以前曾被用作其他政策学习方法的试金石(Koutník等人,2014年b)。 我们在物理任务中使用了相同的网络架构和学习算法超参数,但由于所涉及的时间尺度非常不同,我们改变了用于探索的噪音过程。 在低维和像素上,一些复制品能够学习到合理的政策,能够完成环绕赛道的电路,尽管其他复制品未能学习到明智的政策.
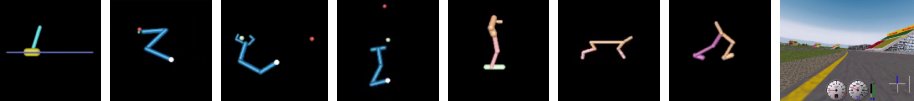
Figure 1: Example screenshots of a sample of environments we attempt to solve with DDPG. In order from the left: the cartpole swing-up task, a reaching task, a gasp and move task, a puck-hitting task, a monoped balancing task, two locomotion tasks and Torcs (driving simulator). We tackle all tasks using both low-dimensional feature vector and high-dimensional pixel inputs. Detailed descriptions of the environments are provided in the supplementary. Movies of some of the learned policies are available at https://goo.gl/J4PIAz.
图1:我们试图用DDPG解决的环境样本的示例截图。 được 从左侧排列: 推车摇摆式任务,一个伸展式任务,一个瓦斯和移动式任务,一个单打平衡式任务,两个龙卷风任务和Torcs(驾驶模拟器). 我们利用低维特性向量和高维像素输入来处理所有任务。 有关环境的详细说明见补编。 一些学习到的政策的电影见https://goo.gl/J4PIAz。
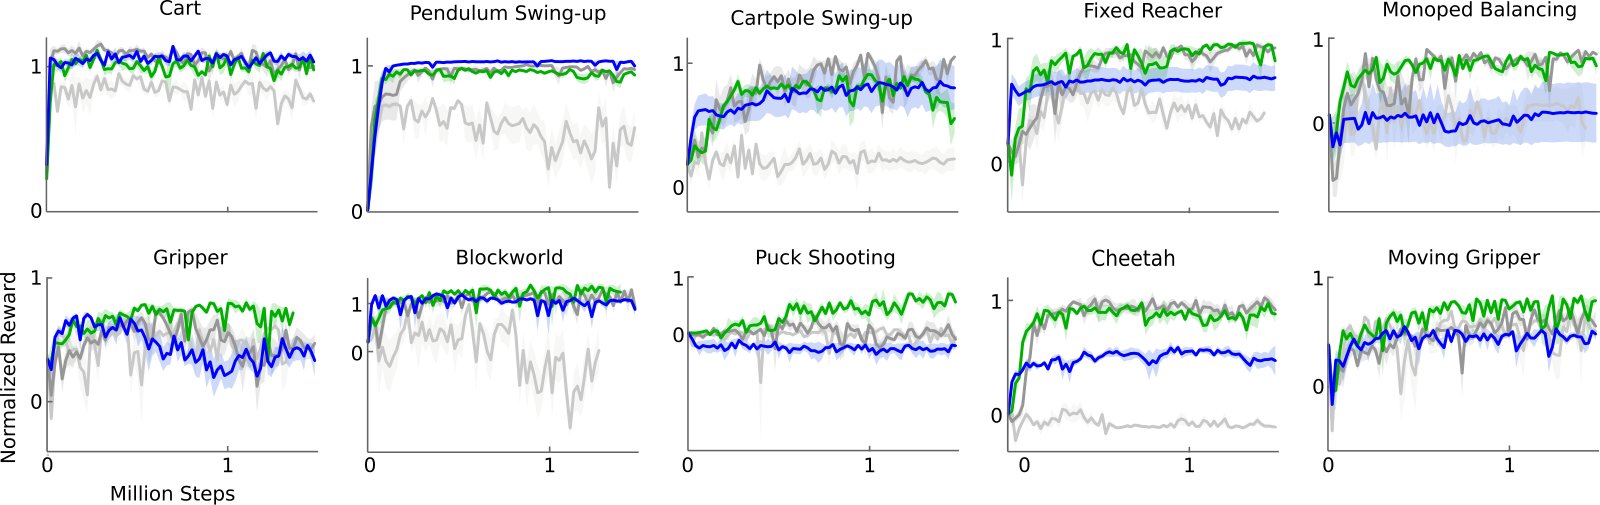
Figure 2: Performance curves for a selection of domains using variants of DPG: original DPG algorithm (minibatch NFQCA) with batch normalization (light grey), with target network (dark grey), with target networks and batch normalization (green), with target networks from pixel-only inputs (blue). Target networks are crucial.
图2:使用DPG的变体选择域的性能曲线:原DPG算法(minibatch NFQCA)具有批归一化(浅灰色),目标网络(暗灰色),目标网络和批归一化(绿色),目标网络来自像素-仅输入(蓝色). 目标网络至关重要。
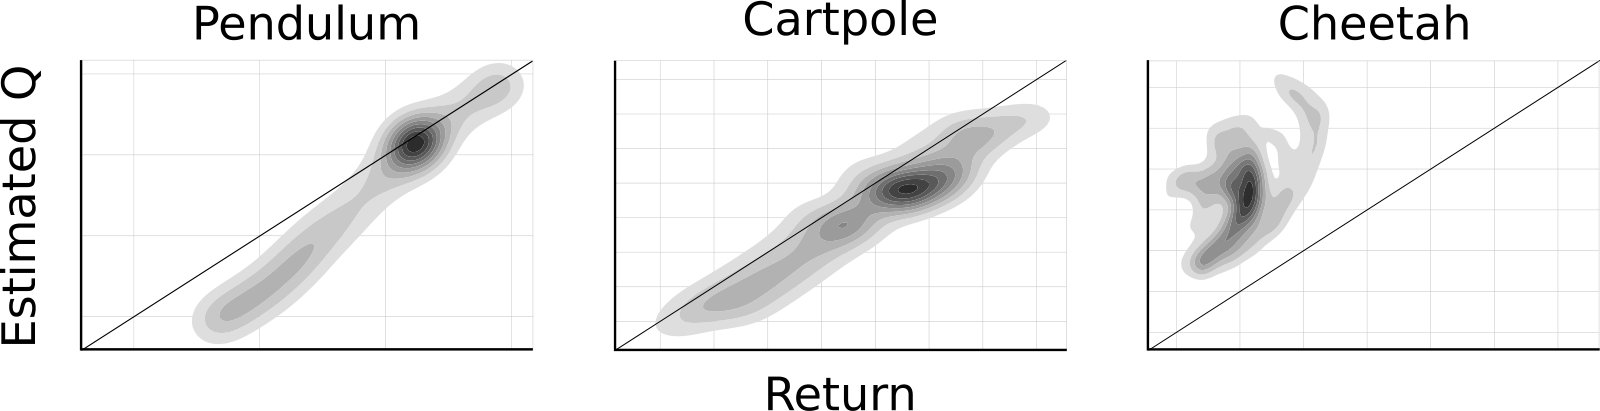
Figure 3: Density plot showing estimated Q values versus observed returns sampled from test episodes on 5 replicas. In simple domains such as pendulum and cartpole the Q values are quite accurate. In more complex tasks, the Q estimates are less accurate, but can still be used to learn competent policies. Dotted line indicates unity, units are arbitrary.
图3:显示估计Q值的密度图,与从5个复制品的测试中抽取的观察到的回报图。 在简单领域,如笔杆和手推杆,Q值相当准确。 在比较复杂的任务中,Q估计的准确性较低,但仍可用于学习称职的政策. 虚线表示统一,单位任意.
| environment | ||||||
|---|---|---|---|---|---|---|
| blockworld1 | 1.156 | 1.511 | 0.466 | 1.299 | -0.080 | 1.260 |
| blockworld3da | 0.340 | 0.705 | 0.889 | 2.225 | -0.139 | 0.658 |
| canada | 0.303 | 1.735 | 0.176 | 0.688 | 0.125 | 1.157 |
| canada2d | 0.400 | 0.978 | -0.285 | 0.119 | -0.045 | 0.701 |
| cart | 0.938 | 1.336 | 1.096 | 1.258 | 0.343 | 1.216 |
| cartpole | 0.844 | 1.115 | 0.482 | 1.138 | 0.244 | 0.755 |
| cartpoleBalance | 0.951 | 1.000 | 0.335 | 0.996 | -0.468 | 0.528 |
| cartpoleParallelDouble | 0.549 | 0.900 | 0.188 | 0.323 | 0.197 | 0.572 |
| cartpoleSerialDouble | 0.272 | 0.719 | 0.195 | 0.642 | 0.143 | 0.701 |
| cartpoleSerialTriple | 0.736 | 0.946 | 0.412 | 0.427 | 0.583 | 0.942 |
| cheetah | 0.903 | 1.206 | 0.457 | 0.792 | -0.008 | 0.425 |
| fixedReacher | 0.849 | 1.021 | 0.693 | 0.981 | 0.259 | 0.927 |
| fixedReacherDouble | 0.924 | 0.996 | 0.872 | 0.943 | 0.290 | 0.995 |
| fixedReacherSingle | 0.954 | 1.000 | 0.827 | 0.995 | 0.620 | 0.999 |
| gripper | 0.655 | 0.972 | 0.406 | 0.790 | 0.461 | 0.816 |
| gripperRandom | 0.618 | 0.937 | 0.082 | 0.791 | 0.557 | 0.808 |
| hardCheetah | 1.311 | 1.990 | 1.204 | 1.431 | -0.031 | 1.411 |
| hopper | 0.676 | 0.936 | 0.112 | 0.924 | 0.078 | 0.917 |
| hyq | 0.416 | 0.722 | 0.234 | 0.672 | 0.198 | 0.618 |
| movingGripper | 0.474 | 0.936 | 0.480 | 0.644 | 0.416 | 0.805 |
| pendulum | 0.946 | 1.021 | 0.663 | 1.055 | 0.099 | 0.951 |
| reacher | 0.720 | 0.987 | 0.194 | 0.878 | 0.231 | 0.953 |
| reacher3daFixedTarget | 0.585 | 0.943 | 0.453 | 0.922 | 0.204 | 0.631 |
| reacher3daRandomTarget | 0.467 | 0.739 | 0.374 | 0.735 | -0.046 | 0.158 |
| reacherSingle | 0.981 | 1.102 | 1.000 | 1.083 | 1.010 | 1.083 |
| walker2d | 0.705 | 1.573 | 0.944 | 1.476 | 0.393 | 1.397 |
| torcs | -393.385 | 1840.036 | -401.911 | 1876.284 | -911.034 | 1961.600 |
Table 1: Performance after training across all environments for at most 2.5 million steps. We report both the average and best observed (across 5 runs). All scores, except Torcs, are normalized so that a random agent receives 0 and a planning algorithm 1; for Torcs we present the raw reward score. We include results from the DDPG algorithn in the low-dimensional () version of the environment and high-dimensional (). For comparision we also include results from the original DPG algorithm with a replay buffer and batch normalization ().
| 环境 | 第二十届 | 第二十届 | 第二十届 | |||
|---|---|---|---|---|---|---|
| 块形世界1 | 1.156 | 1.511 | 0.466 | 1.299 | -0.080 | 1.260 |
| 块形世界3da | 0.340 | 0.705 | 0.889 | 2.225 | -0.139 | 0.658 |
| 加拿大语Name | 0.303 | 1.735 | 0.176 | 0.688 | 0.125 | 1.157 |
| 发件人 | 0.400 | 0.978 | -0.285 | 0.119 | -0.045 | 0.701 |
| cart | 0.938 | 1.336 | 1.096 | 1.258 | 0.343 | 1.216 |
| 车杆 | 0.844 | 1.115 | 0.482 | 1.138 | 0.244 | 0.755 |
| 车杆灯泡 | 0.951 | 1.000 | 0.335 | 0.996 | -0.468 | 0.528 |
| 手推杆Parallel双 | 0.549 | 0.900 | 0.188 | 0.323 | 0.197 | 0.572 |
| 手推杆串联 | 0.272 | 0.719 | 0.195 | 0.642 | 0.143 | 0.701 |
| 手推杆串联 | 0.736 | 0.946 | 0.412 | 0.427 | 0.583 | 0.942 |
| 猎豹 | 0.903 | 1.206 | 0.457 | 0.792 | -0.008 | 0.425 |
| 固定的 Reacher 软件 | 0.849 | 1.021 | 0.693 | 0.981 | 0.259 | 0.927 |
| 固定 Reacher 双 | 0.924 | 0.996 | 0.872 | 0.943 | 0.290 | 0.995 |
| 固定 Reacher 辛格 | 0.954 | 1.000 | 0.827 | 0.995 | 0.620 | 0.999 |
| 夹手 | 0.655 | 0.972 | 0.406 | 0.790 | 0.461 | 0.816 |
| 抓风车 | 0.618 | 0.937 | 0.082 | 0.791 | 0.557 | 0.808 |
| 硬谢塔 | 1.311 | 1.990 | 1.204 | 1.431 | -0.031 | 1.411 |
| hopper | 0.676 | 0.936 | 0.112 | 0.924 | 0.078 | 0.917 |
| 高级 | 0.416 | 0.722 | 0.234 | 0.672 | 0.198 | 0.618 |
| 移动驱动程序 | 0.474 | 0.936 | 0.480 | 0.644 | 0.416 | 0.805 |
| 笔调 | 0.946 | 1.021 | 0.663 | 1.055 | 0.099 | 0.951 |
| 到达者 | 0.720 | 0.987 | 0.194 | 0.878 | 0.231 | 0.953 |
| 的统计数据 60. 目标 | 0.585 | 0.943 | 0.453 | 0.922 | 0.204 | 0.631 |
| 目标 | 0.467 | 0.739 | 0.374 | 0.735 | -0.046 | 0.158 |
| 到达器 | 0.981 | 1.102 | 1.000 | 1.083 | 1.010 | 1.083 |
| 行脚2d | 0.705 | 1.573 | 0.944 | 1.476 | 0.393 | 1.397 |
| torcs | -393.385 | 1840.036 | -401.911 | 1876.284 | -911.034 | 1961.600 |
表1:在所有环境中培训后的业绩,最多250万步。 我们报告平均和最佳观察(共5次)。 除了Torcs之外,所有得分都正常化,这样随机代理获得0和规划算法1;对于Torcs,我们给出原始的奖励分数. 我们包含了低维()版环境和高维()中的DDPG algorithn的结果. 就比较而言,我们还包括原DPG算法的结果,带有重播缓冲和批归一化().
5 Related work
5 相关工作
The original DPG paper evaluated the algorithm with toy problems using tile-coding and linear function approximators. It demonstrated data efficiency advantages for off-policy DPG over both on- and off-policy stochastic actor critic. It also solved one more challenging task in which a multi-jointed octopus arm had to strike a target with any part of the limb. However, that paper did not demonstrate scaling the approach to large, high-dimensional observation spaces as we have here.
最初的DPG论文用瓦片编码和线性函数近似器来评价该算法的玩具问题. 这表明数据效率有利于政策外的DPG,优于政策外的有条理的演员评论家。 这还解决了另一项挑战性的任务,即多联结章鱼臂必须用肢体的任何部分打击目标。 然而,该文件并没有表明,我们在此所看到的大、高维观测空间的尺度。
It has often been assumed that standard policy search methods such as those explored in the present work are simply too fragile to scale to difficult problems (Levine et al. 2015). Standard policy search is thought to be difficult because it deals simultaneously with complex environmental dynamics and a complex policy. Indeed, most past work with actor-critic and policy optimization approaches have had difficulty scaling up to more challenging problems (Deisenroth et al. 2013). Typically, this is due to instability in learning wherein progress on a problem is either destroyed by subsequent learning updates, or else learning is too slow to be practical.
人们常常认为,标准的政策搜索方法,如目前工作中探讨的方法,太脆弱 你还好吗,无法应付困难的问题(Levine等人,2015年)。 标准政策搜索被认为是困难的,因为它同时涉及复杂的环境动态和复杂的政策。 事实上,过去与行为者批评和政策优化方法进行的大多数工作都难以解决更具挑战性的问题(Deisenroth等人,2013年)。 这通常是由于学习不稳定造成的,在学习中,问题的进展要么被随后的学习更新所破坏,要么学习太慢,不切实际。
Recent work with model-free policy search has demonstrated that it may not be as fragile as previously supposed. Wawrzyński 2009; Wawrzyński & Tanwani 2013 has trained stochastic policies in an actor-critic framework with a replay buffer. Concurrent with our work, Balduzzi & Ghifary 2015 extended the DPG algorithm with a “deviator” network which explicitly learns . However, they only train on two low-dimensional domains. Heess et al. 2015 introduced SVG(0) which also uses a Q-critic but learns a stochastic policy. DPG can be considered the deterministic limit of SVG(0). The techniques we described here for scaling DPG are also applicable to stochastic policies by using the reparametrization trick (Heess et al. 2015; Schulman et al. 2015a).
最近关于无模式政策搜索的研究表明,它可能不像以前想象的那样脆弱。 Wawrzyński 2009; Wawrzyński & Tanwani 2013 在演员-批评框架中培训了带有重播缓冲器的刻板政策. 与我们的工作同时,Balduzzi & Ghifary 2015扩展了DPG算法,使用一个明确学习的“演示器”网络。 然而,它们只在两个低维域上训练. Heess 等人2015年引入了SVG(0),它也使用Q批评,但学习了施展政策. DPG可以被认为是SVG(0)的定型极限. 我们在此所描述的用于缩放DPG的技术,也通过使用补正术来适用于有条理的政策(Heis等人,2015年;Schulman等人,2015年a)。
Another approach, trust region policy optimization (TRPO) (Schulman et al. 2015b), directly constructs stochastic neural network policies without decomposing problems into optimal control and supervised phases. This method produces near monotonic improvements in return by making carefully chosen updates to the policy parameters, constraining updates to prevent the new policy from diverging too far from the existing policy. This approach does not require learning an action-value function, and (perhaps as a result) appears to be significantly less data efficient.
另一种做法是信任区域政策优化(TRPO)(Schulman等人,2015年b),直接构建神经网络结构政策,不将问题分解为最佳控制和监督阶段。 这种方法对政策参数作了精心选择的更新,从而产生了近乎单一的改进,从而限制了更新,防止新政策与现行政策相差太远。 这种方法不需要学习一种行动价值功能,而且(也许因此)看来数据效率低得多。
To combat the challenges of the actor-critic approach, recent work with guided policy search (GPS) algorithms (e.g., (Levine et al. 2015)) decomposes the problem into three phases that are relatively easy to solve: first, it uses full-state observations to create locally-linear approximations of the dynamics around one or more nominal trajectories, and then uses optimal control to find the locally-linear optimal policy along these trajectories; finally, it uses supervised learning to train a complex, non-linear policy (e.g. a deep neural network) to reproduce the state-to-action mapping of the optimized trajectories.
为了应对演员-批评方法的挑战,最近与指导政策搜索(GPS)算法(如(Levine等人,2015年))合作,将问题分解为三个相对容易解决的阶段:第一,它使用全态观测来建立围绕一个或多个名义轨迹的动态的局部线性近似,然后使用最佳控制来沿着这些轨迹找到局部线性的最佳政策;最后,它利用监督学习来训练复杂的非线性政策(如深神经网络)来复制优化轨迹的状态到动作绘图.
This approach has several benefits, including data efficiency, and has been applied successfully to a variety of real-world robotic manipulation tasks using vision. In these tasks GPS uses a similar convolutional policy network to ours with 2 notable exceptions: 1. it uses a spatial softmax to reduce the dimensionality of visual features into a single coordinate for each feature map, and 2. the policy also receives direct low-dimensional state information about the configuration of the robot at the first fully connected layer in the network. Both likely increase the power and data efficiency of the algorithm and could easily be exploited within the DDPG framework.
这种方法有几个好处,包括数据效率,并成功应用于各种现实世界的利用视觉的机器人操纵任务. 在这些任务中,GPS使用一个与我们相似的进化政策网络,有两个显著的例外:1.它使用一个空间软max来降低视觉特征的维度,成为每个特征图的单一坐标,2.政策还收到网络中第一个完全连接层的机器人配置的直接低维状态信息. 两者都有可能提高算法的功率和数据效率,并且很容易在DDPG框架内加以利用。
PILCO (Deisenroth & Rasmussen 2011) uses Gaussian processes to learn a non-parametric, probabilistic model of the dynamics. Using this learned model, PILCO calculates analytic policy gradients and achieves impressive data efficiency in a number of control problems. However, due to the high computational demand, PILCO is “impractical for high-dimensional problems” (Wahlström et al. 2015). It seems that deep function approximators are the most promising approach for scaling reinforcement learning to large, high-dimensional domains.
PILCO(Deisenroth & Rasmussen 2011)使用高斯过程来学习动力学的非参数,概率模型. PILCO利用这个学习到的模式计算分析政策梯度,并在一些控制问题上实现令人印象深刻的数据效率. 然而,由于计算需求高,PILCO"对高维度问题不切实际"(Wahlström等人,2015年). 深度函数近似器似乎是将强化学习扩大到大型高维域的最有希望的方法.
Wahlström et al. 2015 used a deep dynamical model network along with model predictive control to solve the pendulum swing-up task from pixel input. They trained a differentiable forward model and encoded the goal state into the learned latent space. They use model-predictive control over the learned model to find a policy for reaching the target. However, this approach is only applicable to domains with goal states that can be demonstrated to the algorithm.
Wahlström et al. 2015年,用深动态模型网络与模型预测控制一起,从像素输入中解决了笔鼓摇摆任务. 他们训练了一种不同的前方模型 把目标状态编码到学习到的潜在空间中 他们利用对学到的模型的模型预测性控制来寻找达到目标的政策. 然而,这种方法只适用于能够对算法进行演示的目标状态域.
Recently, evolutionary approaches have been used to learn competitive policies for Torcs from pixels using compressed weight parametrizations (Koutník et al. 2014a) or unsupervised learning (Koutník et al. 2014b) to reduce the dimensionality of the evolved weights. It is unclear how well these approaches generalize to other problems.
最近,采用演化方法,通过压缩重量参数化(Koutník等人,2014年a)或无监督的学习(Koutník等人,2014年b),从像素中学习对托克的竞争性政策,以减少演化重量的维度. 不清楚这些办法在多大程度上概括到其他问题上。
6 Conclusion
6 结论
The work combines insights from recent advances in deep learning and reinforcement learning, resulting in an algorithm that robustly solves challenging problems across a variety of domains with continuous action spaces, even when using raw pixels for observations. As with most reinforcement learning algorithms, the use of non-linear function approximators nullifies any convergence guarantees; however, our experimental results demonstrate that stable learning without the need for any modifications between environments.
这部作品结合了最近深入斤斤计较和强化学派进步的洞察力,形成了一种算法,在具有连续动作空间的多个领域,即使在使用原始像素进行观测时,都能有力地解决具有挑战性的问题. 与大多数强化学习算法一样,使用非线性函数近似器使任何趋同保证无效;然而,我们的实验结果表明,稳定的学习不需要在环境之间进行任何修改.
Interestingly, all of our experiments used substantially fewer steps of experience than was used by DQN learning to find solutions in the Atari domain. Nearly all of the problems we looked at were solved within 2.5 million steps of experience (and usually far fewer), a factor of 20 fewer steps than DQN requires for good Atari solutions. This suggests that, given more simulation time, DDPG may solve even more difficult problems than those considered here.
有趣的是,我们所有的实验都使用了比DQN学习在阿塔里领域寻找解决方案时所使用的经验步骤要少得多. 我们所研究的几乎所有问题都是在250万个经验步骤(而且通常要少得多)内解决的,这个因素比DQN对良好的阿塔里解决方案需要的20个步骤少得多. 这表明,由于模拟时间更长,DDPG可能会比这里考虑的问题更难解决.
A few limitations to our approach remain. Most notably, as with most model-free reinforcement approaches, DDPG requires a large number of training episodes to find solutions. However, we believe that a robust model-free approach may be an important component of larger systems which may attack these limitations (Gläscher et al. 2010).
我们的做法仍然有一些局限性。 最值得注意的是,与大多数无模型强化方法一样,DDPG需要大量的培训来寻找解决方案.标明了这些限制(Gläscher等人,2010年)。
References
参考文献
Supplementary Information: Continuous control with deep reinforcement learning
** 补充资料:有深度强化学习的持续控制**
Balduzzi & Ghifary (2015) Balduzzi, David and Ghifary, Muhammad. Compatible value gradients for reinforcement learning of continuous deep policies. arXiv preprint arXiv:1509.03005 , 2015.
Deisenroth & Rasmussen (2011) Deisenroth, Marc and Rasmussen, Carl E. Pilco: A model-based and data-efficient approach to policy search. In Proceedings of the 28th International Conference on machine learning (ICML-11) , pp. 465–472, 2011.
Deisenroth et al. (2013) Deisenroth, Marc Peter, Neumann, Gerhard, Peters, Jan, et al. A survey on policy search for robotics. Foundations and Trends in Robotics , 2(1-2):1–142, 2013.
Gläscher et al. (2010) Gläscher, Jan, Daw, Nathaniel, Dayan, Peter, and O’Doherty, John P. States versus rewards: dissociable neural prediction error signals underlying model-based and model-free reinforcement learning. Neuron , 66(4):585–595, 2010.
Glorot et al. (2011) Glorot, Xavier, Bordes, Antoine, and Bengio, Yoshua. Deep sparse rectifier networks. In Proceedings of the 14th International Conference on Artificial Intelligence and Statistics. JMLR W&CP Volume , volume 15, pp. 315–323, 2011.
Hafner & Riedmiller (2011) Hafner, Roland and Riedmiller, Martin. Reinforcement learning in feedback control. Machine learning , 84(1-2):137–169, 2011.
Hasselt (2010) Hasselt, Hado V. Double q-learning. In Advances in Neural Information Processing Systems , pp. 2613–2621, 2010.
Heess et al. (2015) Heess, N., Hunt, J. J, Lillicrap, T. P, and Silver, D. Memory-based control with recurrent neural networks. NIPS Deep Reinforcement Learning Workshop (arXiv:1512.04455) , 2015.
Heess et al. (2015) Heess, Nicolas, Wayne, Gregory, Silver, David, Lillicrap, Tim, Erez, Tom, and Tassa, Yuval. Learning continuous control policies by stochastic value gradients. In Advances in Neural Information Processing Systems , pp. 2926–2934, 2015.
Ioffe & Szegedy (2015) Ioffe, Sergey and Szegedy, Christian. Batch normalization: Accelerating deep network training by reducing internal covariate shift. arXiv preprint arXiv:1502.03167 , 2015.
Kingma & Ba (2014) Kingma, Diederik and Ba, Jimmy. Adam: A method for stochastic optimization. arXiv preprint arXiv:1412.6980 , 2014.
Koutník et al. (2014a) Koutník, Jan, Schmidhuber, Jürgen, and Gomez, Faustino. Evolving deep unsupervised convolutional networks for vision-based reinforcement learning. In Proceedings of the 2014 conference on Genetic and evolutionary computation , pp. 541–548. ACM, 2014a.
Koutník et al. (2014b) Koutník, Jan, Schmidhuber, Jürgen, and Gomez, Faustino. Online evolution of deep convolutional network for vision-based reinforcement learning. In From Animals to Animats 13 , pp. 260–269. Springer, 2014b.
Krizhevsky et al. (2012) Krizhevsky, Alex, Sutskever, Ilya, and Hinton, Geoffrey E. Imagenet classification with deep convolutional neural networks. In Advances in neural information processing systems , pp. 1097–1105, 2012.
Levine et al. (2015) Levine, Sergey, Finn, Chelsea, Darrell, Trevor, and Abbeel, Pieter. End-to-end training of deep visuomotor policies. arXiv preprint arXiv:1504.00702 , 2015.
Mnih et al. (2013) Mnih, Volodymyr, Kavukcuoglu, Koray, Silver, David, Graves, Alex, Antonoglou, Ioannis, Wierstra, Daan, and Riedmiller, Martin. Playing atari with deep reinforcement learning. arXiv preprint arXiv:1312.5602 , 2013.
Mnih et al. (2015) Mnih, Volodymyr, Kavukcuoglu, Koray, Silver, David, Rusu, Andrei A, Veness, Joel, Bellemare, Marc G, Graves, Alex, Riedmiller, Martin, Fidjeland, Andreas K, Ostrovski, Georg, et al. Human-level control through deep reinforcement learning. Nature , 518(7540):529–533, 2015.
Prokhorov et al. (1997) Prokhorov, Danil V, Wunsch, Donald C, et al. Adaptive critic designs. Neural Networks, IEEE Transactions on , 8(5):997–1007, 1997.
Schulman et al. (2015a) Schulman, John, Heess, Nicolas, Weber, Theophane, and Abbeel, Pieter. Gradient estimation using stochastic computation graphs. In Advances in Neural Information Processing Systems , pp. 3510–3522, 2015a.
Schulman et al. (2015b) Schulman, John, Levine, Sergey, Moritz, Philipp, Jordan, Michael I, and Abbeel, Pieter. Trust region policy optimization. arXiv preprint arXiv:1502.05477 , 2015b.
Silver et al. (2014) Silver, David, Lever, Guy, Heess, Nicolas, Degris, Thomas, Wierstra, Daan, and Riedmiller, Martin. Deterministic policy gradient algorithms. In ICML , 2014.
Tassa et al. (2012) Tassa, Yuval, Erez, Tom, and Todorov, Emanuel. Synthesis and stabilization of complex behaviors through online trajectory optimization. In Intelligent Robots and Systems (IROS), 2012 IEEE/RSJ International Conference on , pp. 4906–4913. IEEE, 2012.
Todorov & Li (2005) Todorov, Emanuel and Li, Weiwei. A generalized iterative lqg method for locally-optimal feedback control of constrained nonlinear stochastic systems. In American Control Conference, 2005. Proceedings of the 2005 , pp. 300–306. IEEE, 2005.
Todorov et al. (2012) Todorov, Emanuel, Erez, Tom, and Tassa, Yuval. Mujoco: A physics engine for model-based control. In Intelligent Robots and Systems (IROS), 2012 IEEE/RSJ International Conference on , pp. 5026–5033. IEEE, 2012.
Uhlenbeck & Ornstein (1930) Uhlenbeck, George E and Ornstein, Leonard S. On the theory of the brownian motion. Physical review , 36(5):823, 1930.
Wahlström et al. (2015) Wahlström, Niklas, Schön, Thomas B, and Deisenroth, Marc Peter. From pixels to torques: Policy learning with deep dynamical models. arXiv preprint arXiv:1502.02251 , 2015.
Watkins & Dayan (1992) Watkins, Christopher JCH and Dayan, Peter. Q-learning. Machine learning , 8(3-4):279–292, 1992.
Wawrzyński (2009) Wawrzyński, Paweł. Real-time reinforcement learning by sequential actor–critics and experience replay. Neural Networks , 22(10):1484–1497, 2009.
Wawrzyński (2015) Wawrzyński, Paweł. Control policy with autocorrelated noise in reinforcement learning for robotics. International Journal of Machine Learning and Computing , 5:91–95, 2015.
Wawrzyński & Tanwani (2013) Wawrzyński, Paweł and Tanwani, Ajay Kumar. Autonomous reinforcement learning with experience replay. Neural Networks , 41:156–167, 2013.
7 Experiment Details
7 实验细节
We used Adam (Kingma & Ba 2014) for learning the neural network parameters with a learning rate of and for the actor and critic respectively. For we included weight decay of and used a discount factor of . For the soft target updates we used . The neural networks used the rectified non-linearity (Glorot et al. 2011) for all hidden layers. The final output layer of the actor was a layer, to bound the actions. The low-dimensional networks had 2 hidden layers with 400 and 300 units respectively ( 130,000 parameters). Actions were not included until the 2nd hidden layer of . When learning from pixels we used 3 convolutional layers (no pooling) with 32 filters at each layer. This was followed by two fully connected layers with 200 units ( 430,000 parameters). The final layer weights and biases of both the actor and critic were initialized from a uniform distribution and for the low dimensional and pixel cases respectively. This was to ensure the initial outputs for the policy and value estimates were near zero. The other layers were initialized from uniform distributions where is the fan-in of the layer. The actions were not included until the fully-connected layers. We trained with minibatch sizes of 64 for the low dimensional problems and 16 on pixels. We used a replay buffer size of .
我们用亚当(Kingma & Ba 2014)学习神经网络参数,演员和评论家的学习率分别为和. 对于,我们列入了重量衰减值,并使用了的折现系数. 对于软目标更新,我们使用了。 神经网络对所有隐藏层采用了纠正的非线性(Glorot等人,2011年)。 演员的最终输出层是层,以约束动作. 低维网络有两个隐藏层,分别有400个单元和300个单元( 130,000个参数). 直到的第二隐藏层才包含动作. 在学习像素时,我们使用了3个卷积层(没有集合),每个层有32个滤波器. 随后是两层全连接的200个单元( 43万参数). 演员和评论家的最后一层权重和偏差分别从对低维和像素案例的统一分配和中初始化. 这样做是为了确保政策和价值估计数的初始产出接近零。 其他各层由统一分布的初始化,其中是该层的扇形. 在完全连接的层层之前,动作不包括在内. 我们用64个小盒的尺寸来训练低维问题和16个像素。 我们使用了的重播缓冲尺寸。
For the exploration noise process we used temporally correlated noise in order to explore well in physical environments that have momentum. We used an Ornstein–-Uhlenbeck process (Uhlenbeck & Ornstein 1930) with and . The Ornstein-–Uhlenbeck process models the velocity of a Brownian particle with friction, which results in temporally correlated values centered around 0.
对于勘探噪音过程,我们使用了时间关联的噪音,以便在有动力的物理环境中进行良好的探索。 我们使用了Ornstein –-Uhlenbeck工艺(Uhlenbeck & Ornstein 1930),其中和. Ornstein–Uhlenbeck过程模拟了一个带有摩擦的布朗粒子的速度,这导致了时间相关值以0.
8 Planning algorithm
8 规划算法
Our planner is implemented as a model-predictive controller (Tassa et al. 2012): at every time step we run a single iteration of trajectory optimization (using iLQG, (Todorov & Li 2005)), starting from the true state of the system. Every single trajectory optimization is planned over a horizon between 250ms and 600ms, and this planning horizon recedes as the simulation of the world unfolds, as is the case in model-predictive control.
我们的计划者作为模型预测控制器执行(Tassa等人,2012年):在每一个步骤,我们都会运行一个单一的轨道优化迭代(使用iLQG,(Todorov & Li,2005年)),从系统的真实状态开始. 每一个单一的轨迹优化都是在250米至600米的视野内规划的,这种规划视野随着模拟世界的展开而退缩,模型预测控制中的情况就是这样.
The iLQG iteration begins with an initial rollout of the previous policy, which determines the nominal trajectory. We use repeated samples of simulated dynamics to approximate a linear expansion of the dynamics around every step of the trajectory, as well as a quadratic expansion of the cost function. We use this sequence of locally-linear-quadratic models to integrate the value function backwards in time along the nominal trajectory. This back-pass results in a putative modification to the action sequence that will decrease the total cost. We perform a derivative-free line-search over this direction in the space of action sequences by integrating the dynamics forward (the forward-pass), and choose the best trajectory. We store this action sequence in order to warm-start the next iLQG iteration, and execute the first action in the simulator. This results in a new state, which is used as the initial state in the next iteration of trajectory optimization.
iLQG迭代从最初推出之前的政策开始,它决定了名义轨迹. 我们使用模拟动力学的反复样本来大致显示轨道每个步骤周围的动力学的线性扩张,以及成本函数的四极扩张. 我们用这一系列的本地线性-夸德拉模型 沿着标称的轨迹 将价值函数反向整合起来。 这种回转导致对动作顺序的假定修改,从而降低总成本。为防止在动作序列空间对这个方向进行无衍生线搜索,将动力学前移(the *forward-pass *)整合,选择最佳轨迹. 我们存储此动作序列,以便温暖地启动下一个iLQG迭代,并在模拟器中执行第一个动作. 这导致了一个新的状态,在接下来的轨迹优化迭代中作为初始状态.
9 Environment details
9 环境细节
9.1 Torcs environment
9.1 TORCS 环境
For the Torcs environment we used a reward function which provides a positive reward at each step for the velocity of the car projected along the track direction and a penalty of for collisions. Episodes were terminated if progress was not made along the track after 500 frames.
算术和算术 如果在500帧后没有沿着赛道取得进展,则本集被终止.
9.2 MuJoCo environments
9.2 MuJoCo 环境
For physical control tasks we used reward functions which provide feedback at every step. In all tasks, the reward contained a small action cost. For all tasks that have a static goal state (e.g. pendulum swingup and reaching) we provide a smoothly varying reward based on distance to a goal state, and in some cases an additional positive reward when within a small radius of the target state. For grasping and manipulation tasks we used a reward with a term which encourages movement towards the payload and a second component which encourages moving the payload to the target. In locomotion tasks we reward forward action and penalize hard impacts to encourage smooth rather than hopping gaits (Schulman et al. 2015b). In addition, we used a negative reward and early termination for falls which were determined by simple threshholds on the height and torso angle (in the case of walker2d).
对于物理控制任务,我们使用奖励功能,在每一个步骤提供反馈。 在所有任务中,奖励都包含少量的行动成本. 对于玲珑有静态耿耿目标状态的所有任务(如笔杆摇摆和伸展),我们根据距离一个目标状态提供平稳变化的奖励,在某些情况下,在目标状态小半径范围内额外给予正面奖励. 为了掌握和操纵任务,我们使用了一种鼓励向有效载荷移动的奖励和鼓励将有效载荷向目标移动的第二个组成部分。 在运动任务中,我们奖励前进行动并惩罚硬性影响,以鼓励平滑而不是跳动(Schulman等人,2015年b)。 此外,我们对坠落使用了负面的奖励和提前终止,这些瀑布是由在高度和躯干角度(就行尸2d而言)上简单的血压决定的。
Table 2 states the dimensionality of the problems and below is a summary of all the physics environments.
طل الك الك الك الك الحيري العري العيري الحيري , الحيري , 3, 3, 5, 6, 6, 6, 6, 6, 6, 7, 7, 7, 7, 7, 7, 7, 7, 7, 7, 7, 7, 7, 7, 7, 7, 7, 7, 7, 7, 7, 7, 7, 7, 7, 7, 7, 7, 7, 7, 7, 7, 6, 7, 7, 7, 7, 7, 7, 7, 6, 7, 7, 7, 7, 7, o, , o, o, , o, o, o, o, o, , o, o
| task name | |||
|---|---|---|---|
| blockworld1 | 18 | 5 | 43 |
| blockworld3da | 31 | 9 | 102 |
| canada | 22 | 7 | 62 |
| canada2d | 14 | 3 | 29 |
| cart | 2 | 1 | 3 |
| cartpole | 4 | 1 | 14 |
| cartpoleBalance | 4 | 1 | 14 |
| cartpoleParallelDouble | 6 | 1 | 16 |
| cartpoleParallelTriple | 8 | 1 | 23 |
| cartpoleSerialDouble | 6 | 1 | 14 |
| cartpoleSerialTriple | 8 | 1 | 23 |
| cheetah | 18 | 6 | 17 |
| fixedReacher | 10 | 3 | 23 |
| fixedReacherDouble | 8 | 2 | 18 |
| fixedReacherSingle | 6 | 1 | 13 |
| gripper | 18 | 5 | 43 |
| gripperRandom | 18 | 5 | 43 |
| hardCheetah | 18 | 6 | 17 |
| hardCheetahNice | 18 | 6 | 17 |
| hopper | 14 | 4 | 14 |
| hyq | 37 | 12 | 37 |
| hyqKick | 37 | 12 | 37 |
| movingGripper | 22 | 7 | 49 |
| movingGripperRandom | 22 | 7 | 49 |
| pendulum | 2 | 1 | 3 |
| reacher | 10 | 3 | 23 |
| reacher3daFixedTarget | 20 | 7 | 61 |
| reacher3daRandomTarget | 20 | 7 | 61 |
| reacherDouble | 6 | 1 | 13 |
| reacherObstacle | 18 | 5 | 38 |
| reacherSingle | 6 | 1 | 13 |
| walker2d | 18 | 6 | 41 |
Table 2: Dimensionality of the MuJoCo tasks: the dimensionality of the underlying physics model , number of action dimensions and observation dimensions .
| ** 任务名称** | |||
|---|---|---|---|
| 块形世界1 | 18 | 5 | 43 |
| 块形世界3da | 31 | 9 | 102 |
| 加拿大语Name | 22 | 7 | 62 |
| 发件人 | 14 | 3 | 29 |
| cart | 2 | 1 | 3 |
| 车杆 | 4 | 1 | 14 |
| 车杆灯泡 | 4 | 1 | 14 |
| 手推杆Parallel双 | 6 | 1 | 16 |
| 推杆Parallel 三角形 | 8 | 1 | 23 |
| 手推杆串联 | 6 | 1 | 14 |
| 手推杆串联 | 8 | 1 | 23 |
| 猎豹 | 18 | 6 | 17 |
| 固定的 Reacher 软件 | 10 | 3 | 23 |
| 固定 Reacher 双 | 8 | 2 | 18 |
| 固定 Reacher 辛格 | 6 | 1 | 13 |
| 夹手 | 18 | 5 | 43 |
| 抓风车 | 18 | 5 | 43 |
| 硬谢塔 | 18 | 6 | 17 |
| 硬切片不错 | 18 | 6 | 17 |
| hopper | 14 | 4 | 14 |
| 高级 | 37 | 12 | 37 |
| 时髦 | 37 | 12 | 37 |
| 移动驱动程序 | 22 | 7 | 49 |
| 移动 GripperRandom | 22 | 7 | 49 |
| 笔调 | 2 | 1 | 3 |
| 到达者 | 10 | 3 | 23 |
| 别担心 | 20 | 7 | 61 |
| 目标 | 20 | 7 | 61 |
| 到达者双倍导则 | 6 | 1 | 13 |
| 目标 | 18 | 5 | 38 |
| 到达器 | 6 | 1 | 13 |
| 行脚2d | 18 | 6 | 41 |
表2:MuJoCo任务的维度:基础物理模型的维度,动作维度和观测维度.
| task name | Brief Description |
|---|---|
| blockworld1 | Agent is required to use an arm with gripper constrained to the 2D plane to grab a falling block and lift it against gravity to a fixed target position. |
| blockworld3da | Agent is required to use a human-like arm with 7-DOF and a simple gripper to grab a block and lift it against gravity to a fixed target position. |
| canada | Agent is required to use a 7-DOF arm with hockey-stick like appendage to hit a ball to a target. |
| canada2d | Agent is required to use an arm with hockey-stick like appendage to hit a ball initialzed to a random start location to a random target location. |
| cart | Agent must move a simple mass to rest at 0. The mass begins each trial in random positions and with random velocities. |
| cartpole | The classic cart-pole swing-up task. Agent must balance a pole attached to a cart by applying forces to the cart alone. The pole starts each episode hanging upside-down. |
| cartpoleBalance | The classic cart-pole balance task. Agent must balance a pole attached to a cart by applying forces to the cart alone. The pole starts in the upright positions at the beginning of each episode. |
| cartpoleParallelDouble | Variant on the classic cart-pole. Two poles, both attached to the cart, should be kept upright as much as possible. |
| cartpoleSerialDouble | Variant on the classic cart-pole. Two poles, one attached to the cart and the second attached to the end of the first, should be kept upright as much as possible. |
| cartpoleSerialTriple | Variant on the classic cart-pole. Three poles, one attached to the cart, the second attached to the end of the first, and the third attached to the end of the second, should be kept upright as much as possible. |
| cheetah | The agent should move forward as quickly as possible with a cheetah-like body that is constrained to the plane. This environment is based very closely on the one introduced by Wawrzyński 2009; Wawrzyński & Tanwani 2013. |
| fixedReacher | Agent is required to move a 3-DOF arm to a fixed target position. |
| fixedReacherDouble | Agent is required to move a 2-DOF arm to a fixed target position. |
| fixedReacherSingle | Agent is required to move a simple 1-DOF arm to a fixed target position. |
| gripper | Agent must use an arm with gripper appendage to grasp an object and manuver the object to a fixed target. |
| gripperRandom | The same task as gripper except that the arm object and target position are initialized in random locations. |
| hardCheetah | The agent should move forward as quickly as possible with a cheetah-like body that is constrained to the plane. This environment is based very closely on the one introduced by Wawrzyński 2009; Wawrzyński & Tanwani 2013, but has been made much more difficult by removing the stabalizing joint stiffness from the model. |
| hopper | Agent must balance a multiple degree of freedom monoped to keep it from falling. |
| hyq | Agent is required to keep a quadroped model based on the hyq robot from falling. |
| movingGripper | Agent must use an arm with gripper attached to a moveable platform to grasp an object and move it to a fixed target. |
| movingGripperRandom | The same as the movingGripper environment except that the object position, target position, and arm state are initialized randomly. |
| pendulum | The classic pendulum swing-up problem. The pendulum should be brought to the upright position and balanced. Torque limits prevent the agent from swinging the pendulum up directly. |
| reacher3daFixedTarget | Agent is required to move a 7-DOF human-like arm to a fixed target position. |
| reacher3daRandomTarget | Agent is required to move a 7-DOF human-like arm from random starting locations to random target positions. |
| reacher | Agent is required to move a 3-DOF arm from random starting locations to random target positions. |
| reacherSingle | Agent is required to move a simple 1-DOF arm from random starting locations to random target positions. |
| reacherObstacle | Agent is required to move a 5-DOF arm around an obstacle to a randomized target position. |
| walker2d | Agent should move forward as quickly as possible with a bipedal walker constrained to the plane without falling down or pitching the torso too far forward or backward. |
| ** 任务名称** | ** 简要说明** |
|---|---|
| 块形世界1 | 特工必须使用一个手持钳子的手臂,紧紧地压在2D平面上,抓住一个掉落的块,将其与重力抗衡到固定的目标位置. |
| 块形世界3da | 特工需要使用手持7-DOF和简单的抓手的类似人类的手臂来抓住一个街区,并将它反重力提升到固定的目标位置. |
| 加拿大语Name | 特工需要使用7-DOF手臂,手持曲棍球棒如附着物,才能将球击中目标. |
| 发件人 | 特工需要使用手持曲棍球棒如附着物的手臂来击打被草签到随机起始位置到随机目标位置的球. |
| cart | 特工必须移动一个简单的质量 休息在0。 质量以随机位置和随机速度开始每次试验. |
| 车杆 | 经典的车杆摇摆任务. 特工必须平衡一个附着在推车上的杆子,单靠对推车施加力量. 杆子开始每集倒挂. |
| 车杆灯泡 | 经典的车杆平衡任务. 特工必须平衡一个挂在推车上的杆子,烁出力量单靠推车. 每集开场时,杆头开始于直立位置. |
| 手推杆Parallel双 | 经典车杆上的变体 两根杆子,都附着在推车上,应该尽量保持直立. |
| 手推杆串联 | 经典车杆上的变体 两根杆子,一根附着在推车上,二根附着在第一根末端,应该尽量保持直立. |
| 手推杆串联 | 经典车杆上的变体 三根柱子,一根附着在推车上,二根附着在第一端,三根附着在第二端,应该尽量保持直立. |
| 猎豹 | 特工应该尽快用像猎豹一样的身躯向前移动,这个身躯被限制在飞机上. 这种环境非常接近于Wawrzyński 2009; Wawrzyński & Tanwani 2013介绍的环境. |
| 固定的 Reacher 软件 | 特工需要将3-DO制定出臂ý移动到固定的目标位置. |
| 固定 Reacher 双 | 特工需要将2-DOF臂移动到固定的目标位置. |
| 固定 Reacher 辛格 | 特工需要将简单的1-DOF臂移动到固定的目标位置. |
| 夹手 | 特工必须使用带有抓手附件的手臂来抓住一个物体,并将物体操纵到固定目标上. |
| 抓风车 | 除了臂物体和目标位置在随机位置上初始化之外,与抓取器相同的任务. |
| 硬谢塔 | 特工应该尽快用像猎豹一样的身躯向前移动,这个身躯被限制在飞机上. 这种环境非常紧密地基于Wawrzyński 2009; Wawrzyński & Tanwani 2013介绍的环境,但通过从模型中去除固化的关节僵硬度而变得更加困难. |
| hopper | 特工必须平衡 多重自由度 单一防止它下降。 |
| 。。。。。。。 。 。 | 特工需要保持一个基于hyq机器人的四投模型不坠落. |
| 移动驱动程序 | 特工必须使用手持抓手附着在可移动平台上来抓住一个物体并将其移动到固定目标上. |
| 正在移动 GripperRandom | 与移动的Gripper环境相同,只是对象位置,目标位置,和臂状态被随机初始化. |
| 笔调 | 典型的笔鼓摇摆问题. 笔杆应放在直立的位置上,保持平衡。 Torque限制使剂不能直接挥动笔杆. |
| 到达者3da Fixed目标 | 特工需要将7-DOF型人类手臂移动到固定的目标位置. |
| 目标 | 轩然大波需要将7-DOF型人型手臂从随机起始位置移动到随机目标位置. |
| 到达者 | 70. 特工需要将一个3-DOF臂从随机起始位置移动到随机目标位置。 |
| 到达器 | 31 31 31 23 24 31 26 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 55 |
| 目标 | 特工需要将5-DOF臂绕着障碍物移动到随机化的目标位置. |
| 行脚2d | 特工应该尽快前进,用双脚行尸被限制在飞机上,而不会掉下或把躯干投得太前或落后. |