Denoising Diffusion Implicit Models
Denoising Diffusion Implicit Models
Jiaming Song Chenlin Meng & Stefano Ermon Affiliation: Stanford University Email: {tsong,chenlin,ermon}@cs.stanford.edu
Abstract
摘要
Denoising diffusion probabilistic models (DDPMs) have achieved high quality image generation without adversarial training, yet they require simulating a Markov chain for many steps in order to produce a sample. To accelerate sampling, we present denoising diffusion implicit models (DDIMs), a more efficient class of iterative implicit probabilistic models with the same training procedure as DDPMs. In DDPMs, the generative process is defined as the reverse of a particular Markovian diffusion process. We generalize DDPMs via a class of non-Markovian diffusion processes that lead to the same training objective. These non-Markovian processes can correspond to generative processes that are deterministic, giving rise to implicit models that produce high quality samples much faster. We empirically demonstrate that DDIMs can produce high quality samples to faster in terms of wall-clock time compared to DDPMs, allow us to trade off computation for sample quality, perform semantically meaningful image interpolation directly in the latent space, and reconstruct observations with very low error.
去噪扩散概率模型(DDPM)无需对抗训练即可生成高质量图像,但采样需模拟很长的马尔可夫链。为加速采样,我们提出去噪扩散隐式模型(DDIM):一类更高效的迭代隐式概率模型,训练过程与 DDPM 相同。在 DDPM 中,生成过程定义为某特定马尔可夫扩散过程的逆。我们通过一类非马尔可夫扩散过程推广 DDPM,它们导向相同的训练目标。这些非马尔可夫过程可对应确定性的生成过程,从而得到能更快产出高质量样本的隐式模型。经验表明,相对 DDPM,DDIM 在墙钟时间上可快 到 产出高质量样本,允许在计算与样本质量之间权衡,可在潜空间直接做语义有意义的图像插值,并能以很低误差重建观测。
1 Introduction
1 引言
Deep generative models have demonstrated the ability to produce high quality samples in many domains (Karras et al. 2020; van den Oord et al. 2016a). In terms of image generation, generative adversarial networks (GANs, Goodfellow et al. 2014) currently exhibits higher sample quality than likelihood-based methods such as variational autoencoders (Kingma & Welling 2013), autoregressive models (van den Oord et al. 2016b) and normalizing flows (Rezende & Mohamed 2015; Dinh et al. 2016). However, GANs require very specific choices in optimization and architectures in order to stabilize training (Arjovsky et al. 2017; Gulrajani et al. 2017; Karras et al. 2018; Brock et al. 2018), and could fail to cover modes of the data distribution (Zhao et al. 2018).
深度生成模型已在许多领域展示高质量采样能力 (Karras et al. 2020; van den Oord et al. 2016a)。图像生成方面,生成对抗网络(GAN, Goodfellow et al. 2014)目前样本质量通常高于变分自编码器 (Kingma & Welling 2013)、自回归模型 (van den Oord et al. 2016b) 与归一化流 (Rezende & Mohamed 2015; Dinh et al. 2016) 等基于似然的方法。但 GAN 需要非常特定的优化与结构选择才能稳住训练 (Arjovsky et al. 2017; Gulrajani et al. 2017; Karras et al. 2018; Brock et al. 2018),也可能覆盖不到数据分布的全部模态 (Zhao et al. 2018)。
Recent works on iterative generative models (Bengio et al. 2014), such as denoising diffusion probabilistic models (DDPM, Ho et al. 2020) and noise conditional score networks (NCSN, Song & Ermon 2019) have demonstrated the ability to produce samples comparable to that of GANs, without having to perform adversarial training. To achieve this, many denoising autoencoding models are trained to denoise samples corrupted by various levels of Gaussian noise. Samples are then produced by a Markov chain which, starting from white noise, progressively denoises it into an image. This generative Markov Chain process is either based on Langevin dynamics (Song & Ermon 2019) or obtained by reversing a forward diffusion process that progressively turns an image into noise (Sohl-Dickstein et al. 2015).
关于迭代生成模型的近期工作 (Bengio et al. 2014),例如去噪扩散概率模型(DDPM, Ho et al. 2020)与噪声条件分数网络(NCSN, Song & Ermon 2019),已表明无需对抗训练也能产出可比 GAN 的样本。做法是训练许多去噪自编码模型,对被不同程度高斯噪声腐蚀的样本去噪;再从白噪声出发,用一条马尔可夫链逐步去噪成图像。该生成马尔可夫链过程要么基于 Langevin 动力学 (Song & Ermon 2019),要么通过对逐步把图像变成噪声的前向扩散过程取逆得到 (Sohl-Dickstein et al. 2015)。
A critical drawback of these models is that they require many iterations to produce a high quality sample. For DDPMs, this is because that the generative process (from noise to data) approximates the reverse of the forward diffusion process (from data to noise), which could have thousands of steps; iterating over all the steps is required to produce a single sample, which is much slower compared to GANs, which only needs one pass through a network. For example, it takes around 20 hours to sample 50k images of size from a DDPM, but less than a minute to do so from a GAN on a Nvidia 2080 Ti GPU. This becomes more problematic for larger images as sampling 50k images of size could take nearly hours on the same GPU.
这类模型的关键缺点是:要产出高质量样本需要很多次迭代。对 DDPM 而言,是因为生成过程(噪声到数据)近似前向扩散过程(数据到噪声)的逆,后者可能有数千步;要得到单个样本就必须遍历全部步骤,远慢于只需一次网络前向的 GAN。例如,在 Nvidia 2080 Ti 上,从 DDPM 采样 5 万张 图像约需 20 小时,而 GAN 不到一分钟。图像更大时更糟:同 GPU 上采 5 万张 可能接近 小时。
To close this efficiency gap between DDPMs and GANs, we present denoising diffusion implicit models (DDIMs). DDIMs are implicit probabilistic models (Mohamed & Lakshminarayanan 2016) and are closely related to DDPMs, in the sense that they are trained with the same objective function. In Section 3, we generalize the forward diffusion process used by DDPMs, which is Markovian, to non-Markovian ones, for which we are still able to design suitable reverse generative Markov chains. We show that the resulting variational training objectives have a shared surrogate objective, which is exactly the objective used to train DDPM. Therefore, we can freely choose from a large family of generative models using the same neural network simply by choosing a different, non-Markovian diffusion process (Section 4.1) and the corresponding reverse generative Markov Chain. In particular, we are able to use non-Markovian diffusion processes which lead to ”short” generative Markov chains (Section 4.2) that can be simulated in a small number of steps. This can massively increase sample efficiency only at a minor cost in sample quality.
为缩小 DDPM 与 GAN 之间的效率差距,我们提出去噪扩散隐式模型(DDIM)。DDIM 是隐式概率模型 (Mohamed & Lakshminarayanan 2016),与 DDPM 密切相关:训练目标函数相同。第 3 节把 DDPM 使用的马尔可夫前向扩散过程推广到非马尔可夫过程,并仍能设计合适的反向生成马尔可夫链。我们证明所得变分训练目标有一个共享替代目标,恰好是训练 DDPM 所用目标。因此,只需选择不同的非马尔可夫扩散过程(第 4.1 节)及相应反向生成马尔可夫链,即可用同一神经网络自由选用一大族生成模型。特别地,我们能使用导向「短」生成马尔可夫链的非马尔可夫扩散过程(第 4.2 节),用很少步数即可模拟。这可在样本质量仅小幅下降的代价下大幅提高采样效率。
In Section 5, we demonstrate several empirical benefits of DDIMs over DDPMs. First, DDIMs have superior sample generation quality compared to DDPMs, when we accelerate sampling by to using our proposed method. Second, DDIM samples have the following “consistency” property, which does not hold for DDPMs: if we start with the same initial latent variable and generate several samples with Markov chains of various lengths, these samples would have similar high-level features. Third, because of “consistency” in DDIMs, we can perform semantically meaningful image interpolation by manipulating the initial latent variable in DDIMs, unlike DDPMs which interpolates near the image space due to the stochastic generative process.
第 5 节展示 DDIM 相对 DDPM 的若干经验优势。第一,用所提方法把采样加速 到 时,DDIM 样本质量优于 DDPM。第二,DDIM 样本具有 DDPM 所不具备的「一致性」:从同一初始潜变量出发、用不同长度的马尔可夫链生成多个样本时,这些样本会有相似的高层特征。第三,因 DDIM 有「一致性」,可通过操纵初始潜变量做语义有意义的图像插值;而 DDPM 因生成过程随机,插值更靠近图像空间。
2 Background
2 背景
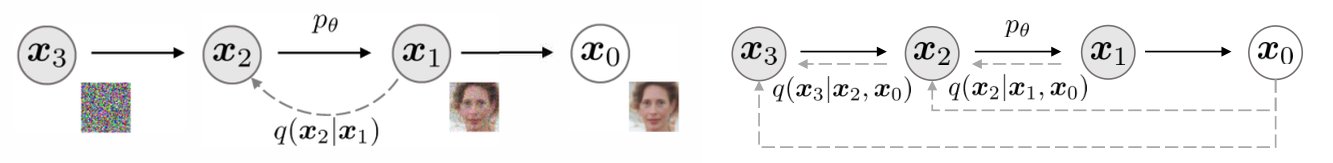
Figure 1: Graphical models for diffusion (left) and non-Markovian (right) inference models.
图 1:扩散(左)与非马尔可夫(右)推断模型的图模型。
Given samples from a data distribution , we are interested in learning a model distribution that approximates and is easy to sample from. Denoising diffusion probabilistic models (DDPMs, Sohl-Dickstein et al. 2015; Ho et al. 2020) are latent variable models of the form
给定数据分布 的样本,我们希望学习近似 且易于采样的模型分布 。去噪扩散概率模型(DDPM, Sohl-Dickstein et al. 2015; Ho et al. 2020)是如下形式的潜变量模型
where are latent variables in the same sample space as (denoted as ). The parameters are learned to fit the data distribution by maximizing a variational lower bound:
其中 是与 同一样本空间(记为 )中的潜变量。参数 通过最大化变分下界来拟合数据分布 :
where is some inference distribution over the latent variables. Unlike typical latent variable models (such as the variational autoencoder (Rezende et al. 2014)), DDPMs are learned with a fixed (rather than trainable) inference procedure , and latent variables are relatively high dimensional. For example, Ho et al. 2020 considered the following Markov chain with Gaussian transitions parameterized by a decreasing sequence :
其中 是潜变量上的某推断分布。与典型潜变量模型(如变分自编码器 (Rezende et al. 2014))不同,DDPM 用固定(而非可训练)的推断程序 学习,且潜变量维数相对较高。例如,Ho et al. 2020 考虑了由递减序列 参数化的如下高斯转移马尔可夫链:
where the covariance matrix is ensured to have positive terms on its diagonal. This is called the forward process due to the autoregressive nature of the sampling procedure (from to ). We call the latent variable model , which is a Markov chain that samples from to , the generative process, since it approximates the intractable reverse process . Intuitively, the forward process progressively adds noise to the observation , whereas the generative process progressively denoises a noisy observation (Figure 1, left).
其中协方差矩阵对角项保证为正。因其采样过程的自回归性质(从 到 ),这称为前向过程。我们把从 采到 的潜变量模型 称为生成过程,因为它近似难处理的反向过程 。直观上,前向过程逐步给观测 加噪,生成过程则逐步给带噪观测去噪(图 1,左)。
A special property of the forward process is that
前向过程的一个特殊性质是
so we can express as a linear combination of and a noise variable :
因此可将 写成 与噪声变量 的线性组合:
When we set sufficiently close to , converges to a standard Gaussian for all , so it is natural to set . If all the conditionals are modeled as Gaussians with trainable mean functions and fixed variances, the objective in Eq. (2) can be simplified to[^1]:
当把 设得充分接近 时,对一切 , 收敛到标准高斯,因而自然取 。若所有条件分布都建模为具有可训练均值函数与固定方差的高斯,则式 (2) 中的目标可简化为[^1]:
where is a set of functions, each (indexed by ) is a function with trainable parameters , and is a vector of positive coefficients in the objective that depends on . In Ho et al. 2020, the objective with is optimized instead to maximize generation performance of the trained model; this is also the same objective used in noise conditional score networks (Song & Ermon 2019) based on score matching (Hyvärinen 2005; Vincent 2011). From a trained model, is sampled by first sampling from the prior , and then sampling from the generative processes iteratively.
其中 是 个函数的集合,每个 (由 索引)带可训练参数 , 是目标中依赖 的正系数向量。Ho et al. 2020 优化 的目标以提升训练模型的生成表现;这也与基于分数匹配 (Hyvärinen 2005; Vincent 2011) 的噪声条件分数网络 (Song & Ermon 2019) 所用目标相同。从训练好的模型采样 时,先从先验 采 ,再迭代地从生成过程采 。
The length of the forward process is an important hyperparameter in DDPMs. From a variational perspective, a large allows the reverse process to be close to a Gaussian (Sohl-Dickstein et al. 2015), so that the generative process modeled with Gaussian conditional distributions becomes a good approximation; this motivates the choice of large values, such as in Ho et al. 2020. However, as all iterations have to be performed sequentially, instead of in parallel, to obtain a sample , sampling from DDPMs is much slower than sampling from other deep generative models, which makes them impractical for tasks where compute is limited and latency is critical.
前向过程长度 是 DDPM 的重要超参数。从变分视角看,大 使反向过程接近高斯 (Sohl-Dickstein et al. 2015),从而用高斯条件分布建模的生成过程成为好近似;这促使选择如 Ho et al. 2020 中 的大 。但要得到样本 ,全部 次迭代必须串行而非并行,因而从 DDPM 采样远慢于其他深度生成模型,在算力有限、延迟关键的任务上不实用。
3 Variational Inference for non-Markovian Forward Processes
3 非马尔可夫前向过程的变分推断
Because the generative model approximates the reverse of the inference process, we need to rethink the inference process in order to reduce the number of iterations required by the generative model. Our key observation is that the DDPM objective in the form of only depends on the marginals[^2] , but not directly on the joint . Since there are many inference distributions (joints) with the same marginals, we explore alternative inference processes that are non-Markovian, which leads to new generative processes (Figure 1, right). These non-Markovian inference process lead to the same surrogate objective function as DDPM, as we will show below. In Appendix A, we show that the non-Markovian perspective also applies beyond the Gaussian case.
因为生成模型近似推断过程的逆,要减少生成模型所需迭代次数,就需要重新思考推断过程。关键观察是:形如 的 DDPM 目标只依赖边缘[^2] ,而不直接依赖联合 。由于有许多具有相同边缘的推断分布(联合),我们探索非马尔可夫的替代推断过程,从而得到新的生成过程(图 1,右)。如下所示,这些非马尔可夫推断过程导向与 DDPM 相同的替代目标函数。附录 A 表明非马尔可夫视角也适用于高斯情形之外。
3.1 Non-Markovian forward processes
3.1 非马尔可夫前向过程
Let us consider a family of inference distributions, indexed by a real vector :
考虑由实向量 索引的一族推断分布 :
where and for all ,
其中 ,且对一切 ,
The mean function is chosen to order to ensure that for all (see Lemma 1 of Appendix B), so that it defines a joint inference distribution that matches the ‘‘marginals’’ as desired. The forward process[^3] can be derived from Bayes’ rule:
均值函数的选取是为了保证对一切 有 (见附录 B 引理 1),从而定义匹配所需「边缘」的联合推断分布。前向过程[^3]可由贝叶斯法则导出:
which is also Gaussian (although we do not use this fact for the remainder of this paper). Unlike the diffusion process in Eq. (3), the forward process here is no longer Markovian, since each could depend on both and . The magnitude of controls the how stochastic the forward process is; when , we reach an extreme case where as long as we observe and for some , then become known and fixed.
它也是高斯的(后文虽不用这一事实)。与式 (3) 中的扩散过程不同,这里的前向过程不再是马尔可夫的,因为每个 可能同时依赖 与 。 的大小控制前向过程有多随机;当 时,达到极端情形:只要观察到某 的 与 , 便已知且固定。
3.2 Generative process and unified variational inference objective
3.2 生成过程与统一变分推断目标
Next, we define a trainable generative process where each leverages knowledge of . Intuitively, given a noisy observation , we first make a prediction[^4] of the corresponding , and then use it to obtain a sample through the reverse conditional distribution , which we have defined.
接下来定义可训练生成过程 ,其中每个 利用 的知识。直观上,给定带噪观测 ,我们先对其对应的 做预测[^4],再通过已定义的反向条件分布 得到样本 。
For some and , can be obtained using Eq. (4). The model then attempts to predict from , without knowledge of . By rewriting Eq. (4), one can then predict the denoised observation, which is a prediction of given :
对某 与 ,可用式 (4) 得到 。模型 试图在不知 的情况下从 预测 。改写式 (4),即可预测去噪观测,亦即给定 对 的预测:
We can then define the generative process with a fixed prior and
于是可用固定先验 定义生成过程,并取
$$\displaystyle p_{\theta}^{(t)}({\bm{x}}{t-1}|{\bm{x}}{t})=\begin{cases}{\mathcal{N}}(f_{\theta}^{(1)}({\bm{x}}{1}),\sigma{1}^{2}{\bm{I}})&\text{if}\ t=1\
q_{\sigma}({\bm{x}}{t-1}|{\bm{x}}{t},f_{\theta}^{(t)}({\bm{x}}_{t}))&\text{otherwise,}\end{cases} \tag{10}$$
where is defined as in Eq. (7) with replaced by . We add some Gaussian noise (with covariance ) for the case of to ensure that the generative process is supported everywhere.
其中 按式 (7) 定义,只是把 换成 。对 的情形,我们加入协方差为 的高斯噪声,以保证生成过程在处处有支撑。
We optimize via the following variational inference objective (which is a functional over ):
我们通过如下变分推断目标(作为 上的泛函)优化 :
where we factorize according to Eq. (6) and according to Eq. (1).
其中我们按式 (6) 分解 ,按式 (1) 分解 。
From the definition of , it would appear that a different model has to be trained for every choice of , since it corresponds to a different variational objective (and a different generative process). However, is equivalent to for certain weights , as we show below.
从 的定义看,似乎对每个 都要训练不同模型,因为它对应不同变分目标(以及不同生成过程)。但如下所示,对某些权重 , 等价于 。
Theorem 1.
For all , there exists and , such that .
定理 1。
对一切 ,存在 与 ,使得 .
The variational objective is special in the sense that if parameters of the models are not shared across different , then the optimal solution for will not depend on the weights (as global optimum is achieved by separately maximizing each term in the sum). This property of has two implications. On the one hand, this justified the use of as a surrogate objective function for the variational lower bound in DDPMs; on the other hand, since is equivalent to some from Theorem 1, the optimal solution of is also the same as that of . Therefore, if parameters are not shared across in the model , then the objective used by Ho et al. 2020 can be used as a surrogate objective for the variational objective as well.
变分目标 的特殊之处在于:若模型 的参数 在不同 之间不共享,则 的最优解不依赖权重 (因为全局最优可通过分别最大化求和中的每一项达到)。 的这一性质有两重含义。一方面,它为在 DDPM 中用 作为变分下界的替代目标提供了理由;另一方面,由定理 1, 等价于某 ,因而 的最优解也与 相同。因此,若模型 中参数不跨 共享,则 Ho et al. 2020 使用的 目标也可作为变分目标 的替代目标。
4 Sampling from Generalized Generative Processes
4 从广义生成过程采样
With as the objective, we are not only learning a generative process for the Markovian inference process considered in Sohl-Dickstein et al. 2015 and Ho et al. 2020, but also generative processes for many non-Markovian forward processes parametrized by that we have described. Therefore, we can essentially use pretrained DDPM models as the solutions to the new objectives, and focus on finding a generative process that is better at producing samples subject to our needs by changing .
以 为目标时,我们不仅在为 Sohl-Dickstein et al. 2015 与 Ho et al. 2020 所考虑的马尔可夫推断过程学习生成过程,也为由 参数化的许多非马尔可夫前向过程学习生成过程。因此,本质上可以把预训练 DDPM 模型当作新目标的解,并通过改变 去寻找更符合需求的生成过程,而无需重训。
4.1 Denoising Diffusion Implicit Models
From in Eq. (10), one can generate a sample from a sample via:
由式 (10) 中的 ,可从样本 生成样本 :
where is standard Gaussian noise independent of , and we define . Different choices of values results in different generative processes, all while using the same model , so re-training the model is unnecessary. When for all , the forward process becomes Markovian, and the generative process becomes a DDPM.
其中 是与 独立的标准高斯噪声,并定义 。不同 取值给出不同生成过程,却共用同一模型 ,因而无需重训。当对一切 取 时,前向过程变为马尔可夫,生成过程变为 DDPM。
We note another special case when for all [^5]; the forward process becomes deterministic given and , except for ; in the generative process, the coefficient before the random noise becomes zero. The resulting model becomes an implicit probabilistic model (Mohamed & Lakshminarayanan 2016), where samples are generated from latent variables with a fixed procedure (from to ). We name this the denoising diffusion implicit model (DDIM, pronounced /d:Im/), because it is an implicit probabilistic model trained with the DDPM objective (despite the forward process no longer being a diffusion).
另一特殊情形是对一切 取 [^5]:给定 与 ,前向过程变为确定性的( 除外);生成过程中随机噪声 前的系数变为零。所得模型成为隐式概率模型 (Mohamed & Lakshminarayanan 2016),样本由潜变量经固定程序(从 到 )生成。我们称之为去噪扩散隐式模型(DDIM,读作 /d:Im/),因为它虽用 DDPM 目标训练,却是隐式概率模型(尽管前向过程已不再是扩散)。
4.2 Accelerated generation processes
4.2 加速生成过程
In the previous sections, the generative process is considered as the approximation to the reverse process; since of the forward process has steps, the generative process is also forced to sample steps. However, as the denoising objective does not depend on the specific forward procedure as long as is fixed, we may also consider forward processes with lengths smaller than , which accelerates the corresponding generative processes without having to train a different model.
前几节把生成过程视为反向过程的近似;由于前向过程有 步,生成过程也被强制采样 步。但只要 固定,去噪目标 就不依赖具体前向程序,因而也可考虑长度小于 的前向过程,从而在无需另训模型的情况下加速对应生成过程。
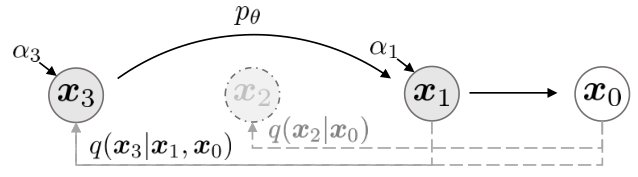
Figure 2: Graphical model for accelerated generation, where .
图 2:加速生成的图模型,其中 。
Let us consider the forward process as defined not on all the latent variables , but on a subset , where is an increasing sub-sequence of of length . In particular, we define the sequential forward process over such that matches the “marginals” (see Figure 2 for an illustration). The generative process now samples latent variables according to , which we term (sampling) trajectory. When the length of the sampling trajectory is much smaller than , we may achieve significant increases in computational efficiency due to the iterative nature of the sampling process.
考虑前向过程不是定义在全部潜变量 上,而是定义在子集 上,其中 是 的长度为 的递增子序列。特别地,我们在 上定义序列前向过程,使 匹配「边缘」(示意见图 2)。生成过程现在按 采样潜变量,我们称之为*(采样)轨迹*。当采样轨迹长度远小于 时,因采样过程的迭代本质,可显著提高计算效率。
Using a similar argument as in Section 3, we can justify using the model trained with the objective, so no changes are needed in training. We show that only slight changes to the updates in Eq. (12) are needed to obtain the new, faster generative processes, which applies to DDPM, DDIM, as well as all generative processes considered in Eq. (10). We include these details in Appendix C.1.
用与第 3 节类似的论证,可以说明使用以 目标训练的模型是合理的,因而训练无需改动。我们证明:对式 (12) 的更新只需轻微修改,即可得到新的、更快的生成过程,适用于 DDPM、DDIM 以及式 (10) 中考虑的全部生成过程。细节见附录 C.1。
In principle, this means that we can train a model with an arbitrary number of forward steps but only sample from some of them in the generative process. Therefore, the trained model could consider many more steps than what is considered in (Ho et al. 2020) or even a continuous time variable (Chen et al. 2020). We leave empirical investigations of this aspect as future work.
原则上,这意味着可用任意数量的前向步训练模型,但在生成过程中只从其中一部分采样。因此,训练模型可考虑远多于 (Ho et al. 2020) 的步数,甚至连续时间变量 (Chen et al. 2020)。经验研究留作未来工作。
4.3 Relevance to Neural ODEs
4.3 与 Neural ODE 的关系
Moreover, we can rewrite the DDIM iterate according to Eq. (12), and its similarity to Euler integration for solving ordinary differential equations (ODEs) becomes more apparent:
此外,可按式 (12) 改写 DDIM 迭代,其与求解常微分方程(ODE)的欧拉积分的相似性更加明显:
To derive the corresponding ODE, we can reparameterize with and with . In the continuous case, and are functions of , where is continous, increasing with . Equation (13) with can be treated as a Euler method over the following ODE:
为导出对应 ODE,可用 重参数化 ,用 重参数化 。连续情形下, 与 是 的函数,其中 连续、递增且 。带式 (13) 的更新可视为如下 ODE 上的欧拉法:
where the initial conditions is for a very large (which corresponds to the case of ). This suggests that with enough discretization steps, the we can also reverse the generation process (going from to ), which encodes to and simulates the reverse of the ODE in Eq. (14). This suggests that unlike DDPM, we can use DDIM to obtain encodings of the observations (as the form of ), which might be useful for other downstream applications that requires latent representations of a model.
初值为 ,且 很大(对应 )。这表明在足够多的离散化步下,我们也可反转生成过程(从 走到 ),把 编码到 ,并模拟式 (14) 中 ODE 的逆。这表明与 DDPM 不同,我们可用 DDIM 得到观测的编码(形式为 ),这可能对需要模型潜表示的其他下游应用有用。
In a concurrent work, (Song et al. 2020) proposed a “probability flow ODE” that aims to recover the marginal densities of a stochastic differential equation (SDE) based on scores, from which a similar sampling schedule can be obtained. Here, we state that the our ODE is equivalent to a special case of theirs (which corresponds to a continuous-time analog of DDPM).
同期工作 (Song et al. 2020) 提出「概率流 ODE」,旨在恢复基于分数的随机微分方程(SDE)的边缘密度,并可得到类似采样日程。此处我们指出:我们的 ODE 等价于他们的一个特例(对应 DDPM 的连续时间类比)。
Proposition 1.
The ODE in Eq. (14) with the optimal model has an equivalent probability flow ODE corresponding to the “Variance-Exploding” SDE in Song et al. 2020.
命题 1。
式 (14) 中带最优模型 的 ODE,有等价的概率流 ODE,对应于 Song et al. 2020 中的「方差爆炸」SDE。
We include the proof in Appendix B. While the ODEs are equivalent, the sampling procedures are not, since the Euler method for the probability flow ODE will make the following update:
证明见附录 B。尽管 ODE 等价,采样程序并不相同,因为概率流 ODE 的欧拉法将做如下更新:
which is equivalent to ours if and are close enough. In fewer sampling steps, however, these choices will make a difference; we take Euler steps with respect to (which depends less directly on the scaling of “time” ) whereas Song et al. 2020 take Euler steps with respect to .
若 与 足够接近,则与我们的更新等价。但在更少采样步时,这些选择会有差别:我们相对 走欧拉步(对「时间」 的缩放依赖更间接),而 Song et al. 2020 相对 走欧拉步。
5 Experiments
5 实验
In this section, we show that DDIMs outperform DDPMs in terms of image generation when fewer iterations are considered, giving speed ups of to over the original DDPM generation process. Moreover, unlike DDPMs, once the initial latent variables are fixed, DDIMs retain high-level image features regardless of the generation trajectory, so they are able to perform interpolation directly from the latent space. DDIMs can also be used to encode samples that reconstruct them from the latent code, which DDPMs cannot do due to the stochastic sampling process.
本节表明:在考虑更少迭代时,DDIM 在图像生成上优于 DDPM,相对原始 DDPM 生成过程可加速 到 。此外,与 DDPM 不同,一旦固定初始潜变量 ,无论生成轨迹如何,DDIM 都保留高层图像特征,因而能直接从潜空间插值。DDIM 还可用于编码样本并从潜码重建,而 DDPM 因采样随机无法做到。
For each dataset, we use the same trained model with and the objective being from Eq. (5) with ; as we argued in Section 3, no changes are needed with regards to the training procedure. The only changes that we make is how we produce samples from the model; we achieve this by controlling (which controls how fast the samples are obtained) and (which interpolates between the deterministic DDIM and the stochastic DDPM).
对每个数据集,我们使用同一以 、目标为式 (5) 中 的 训练的模型;如第 3 节所论,训练过程无需改动。唯一改动是如何从模型产出样本;我们通过控制 (控制采样有多快)与 (在确定性 DDIM 与随机 DDPM 之间插值)实现。
We consider different sub-sequences of and different variance hyperparameters indexed by elements of . To simplify comparisons, we consider with the form:
我们考虑 的不同子序列 ,以及由 元素索引的不同方差超参数 。为简化比较,考虑如下形式的 :
where is a hyperparameter that we can directly control. This includes an original DDPM generative process when and DDIM when . We also consider DDPM where the random noise has a larger standard deviation than , which we denote as : . This is used by the implementation in Ho et al. 2020 only to obtain the CIFAR10 samples, but not samples of the other datasets. We include more details in Appendix D.
其中 是可直接控制的超参数。这包含 时的原始 DDPM 生成过程与 时的 DDIM。我们也考虑随机噪声标准差大于 的 DDPM,记为 :。Ho et al. 2020 的实现仅在获取 CIFAR10 样本时使用它,其他数据集样本则不用。更多细节见附录 D。
5.1 Sample quality and efficiency
5.1 样本质量与效率
In Table 1, we report the quality of the generated samples with models trained on CIFAR10 and CelebA, as measured by Frechet Inception Distance (FID (Heusel et al. 2017)), where we vary the number of timesteps used to generate a sample () and the stochasticity of the process (). As expected, the sample quality becomes higher as we increase , presenting a trade-off between sample quality and computational costs. We observe that DDIM () achieves the best sample quality when is small, and DDPM ( and ) typically has worse sample quality compared to its less stochastic counterparts with the same , except for the case for and reported by Ho et al. 2020 where DDIM is marginally worse. However, the sample quality of becomes much worse for smaller , which suggests that it is ill-suited for shorter trajectories. DDIM, on the other hand, achieves high sample quality much more consistently.
表 1 报告在 CIFAR10 与 CelebA 上训练的模型生成样本质量,以 Frechet Inception Distance(FID (Heusel et al. 2017))度量;我们改变生成样本所用时间步数()与过程随机性()。一如预期,增大 时样本质量变高,呈现样本质量与计算成本的权衡。我们观察到:当 较小时,DDIM()取得最佳样本质量;在相同 下,DDPM( 与 )通常比更不随机的对应物更差,唯一例外是 Ho et al. 2020 报告的 且用 时 DDIM 略差。但 在更小 时质量急剧变差,说明它不适合更短轨迹。相较之下,DDIM 能更稳定地达到高质量。
In Figure 3, we show CIFAR10 and CelebA samples with the same number of sampling steps and varying . For the DDPM, the sample quality deteriorates rapidly when the sampling trajectory has 10 steps. For the case of , the generated images seem to have more noisy perturbations under short trajectories; this explains why the FID scores are much worse than other methods, as FID is very sensitive to such perturbations (as discussed in Jolicoeur-Martineau et al. 2020).
图 3 展示相同采样步数、不同 下的 CIFAR10 与 CelebA 样本。对 DDPM,采样轨迹只有 10 步时质量迅速恶化。对 ,短轨迹下生成图像似乎带有更多噪声扰动;这解释了为何 FID 远差于其他方法,因为 FID 对此类扰动非常敏感(见 Jolicoeur-Martineau et al. 2020 讨论)。
In Figure 4, we show that the amount of time needed to produce a sample scales linearly with the length of the sample trajectory. This suggests that DDIM is useful for producing samples more efficiently, as samples can be generated in much fewer steps. Notably, DDIM is able to produce samples with quality comparable to 1000 step models within to steps, which is a to speed up compared to the original DDPM. Even though DDPM could also achieve reasonable sample quality with steps, DDIM requires much fewer steps to achieve this; on CelebA, the FID score of the 100 step DDPM is similar to that of the 20 step DDIM.
图 4 表明产出一个样本所需时间随采样轨迹长度线性增长。这说明 DDIM 有助于更高效产出样本,因为可用少得多的步数生成。值得注意的是,DDIM 能在 到 步内产出与 1000 步模型可比的质量,相对原始 DDPM 加速 到 。尽管 DDPM 用 步也能达到合理质量,DDIM 达到该质量所需步数少得多;在 CelebA 上,100 步 DDPM 的 FID 与 20 步 DDIM 相近。
| CIFAR10 () | CelebA () | ||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|
| 10 | 20 | 50 | 100 | 1000 | 10 | 20 | 50 | 100 | 1000 | ||
| 13.36 | 6.84 | 4.67 | 4.16 | 4.04 | 17.33 | 13.73 | 9.17 | 6.53 | 3.51 | ||
| 0.2 | 14.04 | 7.11 | 4.77 | 4.25 | 4.09 | 17.66 | 14.11 | 9.51 | 6.79 | 3.64 | |
| 0.5 | 16.66 | 8.35 | 5.25 | 4.46 | 4.29 | 19.86 | 16.06 | 11.01 | 8.09 | 4.28 | |
| 1.0 | 41.07 | 18.36 | 8.01 | 5.78 | 4.73 | 33.12 | 26.03 | 18.48 | 13.93 | 5.98 | |
| 367.43 | 133.37 | 32.72 | 9.99 | 3.17 | 299.71 | 183.83 | 71.71 | 45.20 | 3.26 |
Table 1: CIFAR10 and CelebA image generation measured in FID. and are cases of DDPM (although Ho et al. 2020 only considered steps, and can be seen as simulating DDPMs trained with steps), and indicates DDIM.
| CIFAR10 () | CelebA () | ||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|
| 10 | 20 | 50 | 100 | 1000 | 10 | 20 | 50 | 100 | 1000 | ||
| 13.36 | 6.84 | 4.67 | 4.16 | 4.04 | 17.33 | 13.73 | 9.17 | 6.53 | 3.51 | ||
| 0.2 | 14.04 | 7.11 | 4.77 | 4.25 | 4.09 | 17.66 | 14.11 | 9.51 | 6.79 | 3.64 | |
| 0.5 | 16.66 | 8.35 | 5.25 | 4.46 | 4.29 | 19.86 | 16.06 | 11.01 | 8.09 | 4.28 | |
| 1.0 | 41.07 | 18.36 | 8.01 | 5.78 | 4.73 | 33.12 | 26.03 | 18.48 | 13.93 | 5.98 | |
| 367.43 | 133.37 | 32.72 | 9.99 | 3.17 | 299.71 | 183.83 | 71.71 | 45.20 | 3.26 |
表 1:CIFAR10 与 CelebA 图像生成的 FID。 与 为 DDPM 情形(尽管 Ho et al. 2020 只考虑了 步, 可视为模拟以 步训练的 DDPM), 表示 DDIM。
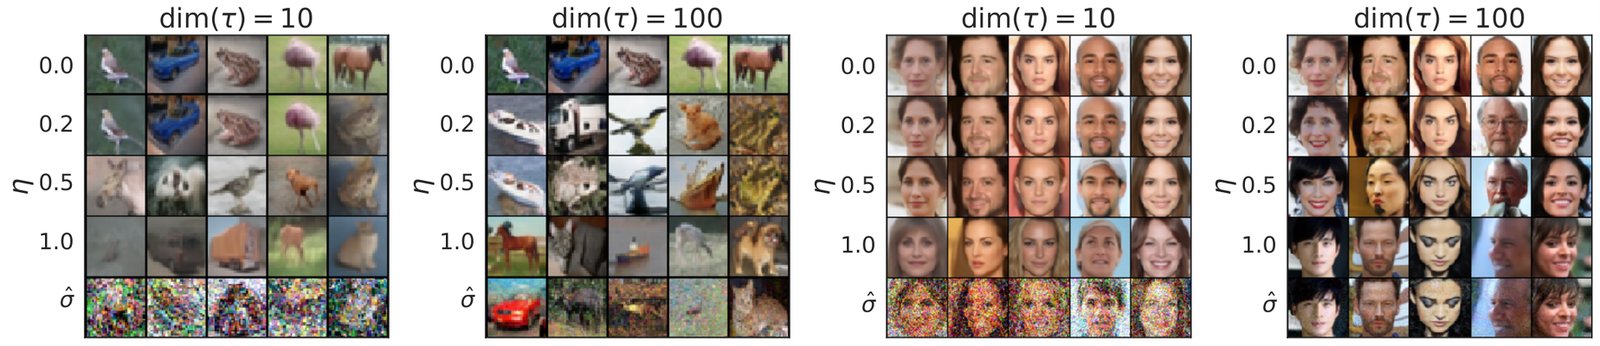
Figure 3: CIFAR10 and CelebA samples with and .
图 3: 与 时的 CIFAR10 与 CelebA 样本。
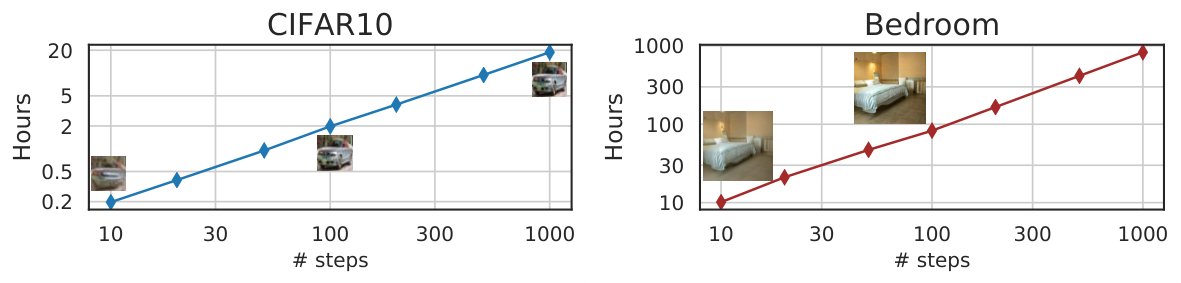
Figure 4: Hours to sample 50k images with one Nvidia 2080 Ti GPU and samples at different steps.
图 4:在一块 Nvidia 2080 Ti GPU 上采样 5 万张图像所需小时数,以及不同步数下的样本。
5.2 Sample consistency in DDIMs
5.2 DDIM 中的样本一致性
For DDIM, the generative process is deterministic, and would depend only on the initial state . In Figure 5, we observe the generated images under different generative trajectories (i.e. different ) while starting with the same initial . Interestingly, for the generated images with the same initial , most high-level features are similar, regardless of the generative trajectory. In many cases, samples generated with only 20 steps are already very similar to ones generated with 1000 steps in terms of high-level features, with only minor differences in details. Therefore, it would appear that alone would be an informative latent encoding of the image; and minor details that affects sample quality are encoded in the parameters, as longer sample trajectories gives better quality samples but do not significantly affect the high-level features. We show more samples in Appendix D.4.
对 DDIM,生成过程是确定性的, 只依赖初始状态 。图 5 中,我们观察从同一初始 出发、不同生成轨迹(即不同 )下的生成图像。有趣的是,对相同初始 的生成图像,无论生成轨迹如何,多数高层特征相似。许多情形下,仅 20 步生成的样本在高层特征上已与 1000 步非常接近,仅细节有小差别。因此, 本身似乎就是图像的信息性潜编码;而影响样本质量的次要细节编码在参数中,因为更长采样轨迹给出更好质量,却不显著改变高层特征。更多样本见附录 D.4。

Figure 5: Samples from DDIM with the same random and different number of steps.
图 5:同一随机 、不同步数下的 DDIM 样本。
5.3 Interpolation in deterministic generative processes
5.3 确定性生成过程中的插值

Figure 6: Interpolation of samples from DDIM with .
图 6: 时 DDIM 样本的插值。
Since the high level features of the DDIM sample is encoded by , we are interested to see whether it would exhibit the semantic interpolation effect similar to that observed in other implicit probabilistic models, such as GANs (Goodfellow et al. 2014). This is different from the interpolation procedure in Ho et al. 2020, since in DDPM the same would lead to highly diverse due to the stochastic generative process[^6]. In Figure 6, we show that simple interpolations in can lead to semantically meaningful interpolations between two samples. We include more details and samples in Appendix D.5. This allows DDIM to control the generated images on a high level directly through the latent variables, which DDPMs cannot.
由于 DDIM 样本的高层特征由 编码,我们关心它是否会表现出与 GAN (Goodfellow et al. 2014) 等其他隐式概率模型类似的语义插值效应。这不同于 Ho et al. 2020 中的插值程序:在 DDPM 中,因生成过程随机,同一 会导致高度多样的 [^6]。图 6 表明,在 上做简单插值即可得到两样本之间语义有意义的插值。更多细节与样本见附录 D.5。这使得 DDIM 能通过潜变量在高层直接控制生成图像,而 DDPM 做不到。
5.4 Reconstruction from Latent Space
5.4 从潜空间重建
As DDIM is the Euler integration for a particular ODE, it would be interesting to see whether it can encode from to (reverse of Eq. (14)) and reconstruct from the resulting (forward of Eq. (14))[^7]. We consider encoding and decoding on the CIFAR-10 test set with the CIFAR-10 model with steps for both encoding and decoding; we report the per-dimension mean squared error (scaled to ) in Table 2. Our results show that DDIMs have lower reconstruction error for larger values and have properties similar to Neural ODEs and normalizing flows. The same cannot be said for DDPMs due to their stochastic nature.
由于 DDIM 是某 ODE 的欧拉积分,值得看它能否从 编码到 (式 (14) 的逆)并从所得 重建 (式 (14) 的正演)[^7]。我们在 CIFAR-10 测试集上,用 CIFAR-10 模型以 步做编码与解码;表 2 报告缩放到 的逐维均方误差。结果表明:更大的 下 DDIM 重建误差更低,并具有类似 Neural ODE 与归一化流的性质。DDPM 因随机性不能如是说。
| 10 | 20 | 50 | 100 | 200 | 500 | 1000 | |
|---|---|---|---|---|---|---|---|
| Error | 0.014 | 0.0065 | 0.0023 | 0.0009 | 0.0004 | 0.0001 |
Table 2: Reconstruction error with DDIM on CIFAR-10 test set, rounded to .
| 10 | 20 | 50 | 100 | 200 | 500 | 1000 | |
|---|---|---|---|---|---|---|---|
| Error | 0.014 | 0.0065 | 0.0023 | 0.0009 | 0.0004 | 0.0001 |
表 2:CIFAR-10 测试集上 DDIM 的重建误差,四舍五入到 。
6 Related Work
6 相关工作
Our work is based on a large family of existing methods on learning generative models as transition operators of Markov chains (Sohl-Dickstein et al. 2015; Bengio et al. 2014; Salimans et al. 2014; Song et al. 2017; Goyal et al. 2017; Levy et al. 2017). Among them, denoising diffusion probabilistic models (DDPMs, Ho et al. 2020) and noise conditional score networks (NCSN, Song & Ermon 2019; Song & Ermon 2020) have recently achieved high sample quality comparable to GANs (Brock et al. 2018; Karras et al. 2018). DDPMs optimize a variational lower bound to the log-likelihood, whereas NCSNs optimize the score matching objective (Hyvärinen 2005) over a nonparametric Parzen density estimator of the data (Vincent 2011; Raphan & Simoncelli 2011).
本工作建立在把生成模型学成马尔可夫链转移算子的一大族已有方法之上 (Sohl-Dickstein et al. 2015; Bengio et al. 2014; Salimans et al. 2014; Song et al. 2017; Goyal et al. 2017; Levy et al. 2017)。其中,去噪扩散概率模型(DDPM, Ho et al. 2020)与噪声条件分数网络(NCSN, Song & Ermon 2019; Song & Ermon 2020)近来达到了可比 GAN (Brock et al. 2018; Karras et al. 2018) 的高样本质量。DDPM 优化对数似然的变分下界,而 NCSN 在数据的非参数 Parzen 密度估计上优化分数匹配目标 (Hyvärinen 2005) (Vincent 2011; Raphan & Simoncelli 2011)。
Despite their different motivations, DDPMs and NCSNs are closely related. Both use a denoising autoencoder objective for many noise levels, and both use a procedure similar to Langevin dynamics to produce samples (Neal et al. 2011). Since Langevin dynamics is a discretization of a gradient flow (Jordan et al. 1998), both DDPM and NCSN require many steps to achieve good sample quality. This aligns with the observation that DDPM and existing NCSN methods have trouble generating high-quality samples in a few iterations.
尽管动机不同,DDPM 与 NCSN 密切相关。两者都对许多噪声水平使用去噪自编码目标,两者都用类似 Langevin 动力学的程序产出样本 (Neal et al. 2011)。由于 Langevin 动力学是梯度流的离散化 (Jordan et al. 1998),DDPM 与 NCSN 都需要很多步才能达到好样本质量。这与 DDPM 及现有 NCSN 方法难以在很少迭代内生成高质量样本的观察一致。
DDIM, on the other hand, is an implicit generative model (Mohamed & Lakshminarayanan 2016) where samples are uniquely determined from the latent variables. Hence, DDIM has certain properties that resemble GANs (Goodfellow et al. 2014) and invertible flows (Dinh et al. 2016), such as the ability to produce semantically meaningful interpolations. We derive DDIM from a purely variational perspective, where the restrictions of Langevin dynamics are not relevant; this could partially explain why we are able to observe superior sample quality compared to DDPM under fewer iterations. The sampling procedure of DDIM is also reminiscent of neural networks with continuous depth (Chen et al. 2018; Grathwohl et al. 2018), since the samples it produces from the same latent variable have similar high-level visual features, regardless of the specific sample trajectory.
另一方面,DDIM 是隐式生成模型 (Mohamed & Lakshminarayanan 2016),样本由潜变量唯一决定。因此 DDIM 具有类似 GAN (Goodfellow et al. 2014) 与可逆流 (Dinh et al. 2016) 的某些性质,例如产出语义有意义插值的能力。我们从纯变分视角导出 DDIM,Langevin 动力学的限制在此并不相关;这可部分解释为何在更少迭代下我们能观察到优于 DDPM 的样本质量。DDIM 的采样程序也让人联想到连续深度神经网络 (Chen et al. 2018; Grathwohl et al. 2018):从同一潜变量出发,无论具体采样轨迹如何,产出的样本都有相似的高层视觉特征。
7 Discussion
7 讨论
We have presented DDIMs – an implicit generative model trained with denoising auto-encoding / score matching objectives – from a purely variational perspective. DDIM is able to generate high-quality samples much more efficiently than existing DDPMs and NCSNs, with the ability to perform meaningful interpolations from the latent space. The non-Markovian forward process presented here seems to suggest continuous forward processes other than Gaussian (which cannot be done in the original diffusion framework, since Gaussian is the only stable distribution with finite variance). We also demonstrated a discrete case with a multinomial forward process in Appendix A, and it would be interesting to investigate similar alternatives for other combinatorial structures.
我们从纯变分视角提出了 DDIM——用去噪自编码/分数匹配目标训练的隐式生成模型。相对现有 DDPM 与 NCSN,DDIM 能更高效地生成高质量样本,并能从潜空间做有意义插值。此处给出的非马尔可夫前向过程似乎暗示:除高斯外还可有连续前向过程(在原始扩散框架中做不到,因为有限方差的稳定分布只有高斯)。我们也在附录 A 展示了多项前向过程的离散情形;对其它组合结构研究类似替代会很有趣。
Moreover, since the sampling procedure of DDIMs is similar to that of an neural ODE, it would be interesting to see if methods that decrease the discretization error in ODEs, including multi-step methods such as Adams-Bashforth (Butcher & Goodwin 2008), could be helpful for further improving sample quality in fewer steps (Queiruga et al. 2020). It is also relevant to investigate whether DDIMs exhibit other properties of existing implicit models (Bau et al. 2019).
此外,由于 DDIM 采样程序类似 neural ODE,值得看减少 ODE 离散化误差的方法——包括 Adams-Bashforth (Butcher & Goodwin 2008) 等多步法——是否有助于在更少步内进一步提高样本质量 (Queiruga et al. 2020)。探究 DDIM 是否还表现出现有隐式模型的其他性质 (Bau et al. 2019) 也很相关。
Acknowledgements
The authors would like to thank Yang Song and Shengjia Zhao for helpful discussions over the ideas, Kuno Kim for reviewing an earlier draft of the paper, and Sharvil Nanavati and Sophie Liu for identifying typos. This research was supported by NSF (#1651565, #1522054, #1733686), ONR (N00014-19-1-2145), AFOSR (FA9550-19-1-0024), and Amazon AWS.
作者感谢 Yang Song 与 Shengjia Zhao 对想法的有益讨论,感谢 Kuno Kim 审阅论文初稿,感谢 Sharvil Nanavati 与 Sophie Liu 指出笔误。本研究得到 NSF (#1651565, #1522054, #1733686)、ONR (N00014-19-1-2145)、AFOSR (FA9550-19-1-0024) 与 Amazon AWS 资助。
References
Arjovsky et al. (2017) Martin Arjovsky, Soumith Chintala, and Léon Bottou. Wasserstein GAN. arXiv preprint arXiv:1701.07875 , January 2017.
Bau et al. (2019) David Bau, Jun-Yan Zhu, Jonas Wulff, William Peebles, Hendrik Strobelt, Bolei Zhou, and Antonio Torralba. Seeing what a gan cannot generate. In Proceedings of the IEEE International Conference on Computer Vision , pp. 4502–4511, 2019.
Bengio et al. (2014) Yoshua Bengio, Eric Laufer, Guillaume Alain, and Jason Yosinski. Deep generative stochastic networks trainable by backprop. In International Conference on Machine Learning , pp. 226–234, January 2014.
Bishop (2006) Christopher M Bishop. Pattern recognition and machine learning . springer, 2006.
Brock et al. (2018) Andrew Brock, Jeff Donahue, and Karen Simonyan. Large scale GAN training for high fidelity natural image synthesis. arXiv preprint arXiv:1809.11096 , September 2018.
Butcher & Goodwin (2008) John Charles Butcher and Nicolette Goodwin. Numerical methods for ordinary differential equations , volume 2. Wiley Online Library, 2008.
Chen et al. (2020) Nanxin Chen, Yu Zhang, Heiga Zen, Ron J Weiss, Mohammad Norouzi, and William Chan. WaveGrad: Estimating gradients for waveform generation. arXiv preprint arXiv:2009.00713 , September 2020.
Chen et al. (2018) Ricky T Q Chen, Yulia Rubanova, Jesse Bettencourt, and David Duvenaud. Neural ordinary differential equations. arXiv preprint arXiv:1806.07366 , June 2018.
Dinh et al. (2016) Laurent Dinh, Jascha Sohl-Dickstein, and Samy Bengio. Density estimation using real NVP. arXiv preprint arXiv:1605.08803 , May 2016.
Goodfellow et al. (2014) Ian Goodfellow, Jean Pouget-Abadie, Mehdi Mirza, Bing Xu, David Warde-Farley, Sherjil Ozair, Aaron Courville, and Yoshua Bengio. Generative adversarial nets. In Advances in neural information processing systems , pp. 2672–2680, 2014.
Goyal et al. (2017) Anirudh Goyal, Nan Rosemary Ke, Surya Ganguli, and Yoshua Bengio. Variational walkback: Learning a transition operator as a stochastic recurrent net. In Advances in Neural Information Processing Systems , pp. 4392–4402, 2017.
Grathwohl et al. (2018) Will Grathwohl, Ricky T Q Chen, Jesse Bettencourt, Ilya Sutskever, and David Duvenaud. FFJORD: Free-form continuous dynamics for scalable reversible generative models. arXiv preprint arXiv:1810.01367 , October 2018.
Gulrajani et al. (2017) Ishaan Gulrajani, Faruk Ahmed, Martin Arjovsky, Vincent Dumoulin, and Aaron C Courville. Improved training of wasserstein gans. In Advances in Neural Information Processing Systems , pp. 5769–5779, 2017.
Heusel et al. (2017) Martin Heusel, Hubert Ramsauer, Thomas Unterthiner, Bernhard Nessler, and Sepp Hochreiter. GANs trained by a two Time-Scale update rule converge to a local nash equilibrium. arXiv preprint arXiv:1706.08500 , June 2017.
Ho et al. (2020) Jonathan Ho, Ajay Jain, and Pieter Abbeel. Denoising diffusion probabilistic models. arXiv preprint arXiv:2006.11239 , June 2020.
Hyvärinen (2005) Aapo Hyvärinen. Estimation of Non-Normalized statistical models by score matching. Journal of Machine Learning Researc h , 6:695–709, 2005.
Jolicoeur-Martineau et al. (2020) Alexia Jolicoeur-Martineau, Rémi Piché-Taillefer, Rémi Tachet des Combes, and Ioannis Mitliagkas. Adversarial score matching and improved sampling for image generation. September 2020.
Jordan et al. (1998) Richard Jordan, David Kinderlehrer, and Felix Otto. The variational formulation of the fokker–planck equation. SIAM journal on mathematical analysis , 29(1):1–17, 1998.
Karras et al. (2018) Tero Karras, Samuli Laine, and Timo Aila. A Style-Based generator architecture for generative adversarial networks. arXiv preprint arXiv:1812.04948 , December 2018.
Karras et al. (2020) Tero Karras, Samuli Laine, Miika Aittala, Janne Hellsten, Jaakko Lehtinen, and Timo Aila. Analyzing and improving the image quality of stylegan. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition , pp. 8110–8119, 2020.
Kingma & Welling (2013) Diederik P Kingma and Max Welling. Auto-Encoding variational bayes. arXiv preprint arXiv:1312.6114v10 , December 2013.
Levy et al. (2017) Daniel Levy, Matthew D Hoffman, and Jascha Sohl-Dickstein. Generalizing hamiltonian monte carlo with neural networks. arXiv preprint arXiv:1711.09268 , 2017.
Mohamed & Lakshminarayanan (2016) Shakir Mohamed and Balaji Lakshminarayanan. Learning in implicit generative models. arXiv preprint arXiv:1610.03483 , October 2016.
Neal et al. (2011) Radford M Neal et al. Mcmc using hamiltonian dynamics. Handbook of markov chain monte carlo , 2(11):2, 2011.
Queiruga et al. (2020) Alejandro F Queiruga, N Benjamin Erichson, Dane Taylor, and Michael W Mahoney. Continuous-in-depth neural networks. arXiv preprint arXiv:2008.02389 , 2020.
Raphan & Simoncelli (2011) Martin Raphan and Eero P Simoncelli. Least squares estimation without priors or supervision. Neural computation , 23(2):374–420, February 2011. ISSN 0899-7667, 1530-888X.
Rezende & Mohamed (2015) Danilo Jimenez Rezende and Shakir Mohamed. Variational inference with normalizing flows. arXiv preprint arXiv:1505.05770 , May 2015.
Rezende et al. (2014) Danilo Jimenez Rezende, Shakir Mohamed, and Daan Wierstra. Stochastic backpropagation and approximate inference in deep generative models. arXiv preprint arXiv:1401.4082 , 2014.
Ronneberger et al. (2015) Olaf Ronneberger, Philipp Fischer, and Thomas Brox. U-net: Convolutional networks for biomedical image segmentation. In International Conference on Medical image computing and computer-assisted intervention , pp. 234–241. Springer, 2015.
Salimans et al. (2014) Tim Salimans, Diederik P Kingma, and Max Welling. Markov chain monte carlo and variational inference: Bridging the gap. arXiv preprint arXiv:1410.6460 , October 2014.
Shoemake (1985) Ken Shoemake. Animating rotation with quaternion curves. In Proceedings of the 12th annual conference on Computer graphics and interactive techniques , pp. 245–254, 1985.
Sohl-Dickstein et al. (2015) Jascha Sohl-Dickstein, Eric A Weiss, Niru Maheswaranathan, and Surya Ganguli. Deep unsupervised learning using nonequilibrium thermodynamics. arXiv preprint arXiv:1503.03585 , March 2015.
Song et al. (2017) Jiaming Song, Shengjia Zhao, and Stefano Ermon. A-nice-mc: Adversarial training for mcmc. arXiv preprint arXiv:1706.07561 , June 2017.
Song & Ermon (2019) Yang Song and Stefano Ermon. Generative modeling by estimating gradients of the data distribution. arXiv preprint arXiv:1907.05600 , July 2019.
Song & Ermon (2020) Yang Song and Stefano Ermon. Improved techniques for training Score-Based generative models. arXiv preprint arXiv:2006.09011 , June 2020.
Song et al. (2020) Yang Song, Jascha Sohl-Dickstein, Diederik P Kingma, Abhishek Kumar, Stefano Ermon, and Ben Poole. Score-based generative modeling through stochastic differential equations. arXiv preprint arXiv:2011.13456 , 2020.
van den Oord et al. (2016a) Aaron van den Oord, Sander Dieleman, Heiga Zen, Karen Simonyan, Oriol Vinyals, Alex Graves, Nal Kalchbrenner, Andrew Senior, and Koray Kavukcuoglu. WaveNet: A generative model for raw audio. arXiv preprint arXiv:1609.03499 , September 2016a.
van den Oord et al. (2016b) Aaron van den Oord, Nal Kalchbrenner, and Koray Kavukcuoglu. Pixel recurrent neural networks. arXiv preprint arXiv:1601.06759 , January 2016b.
Vincent (2011) Pascal Vincent. A connection between score matching and denoising autoencoders. Neural computation , 23(7):1661–1674, 2011.
Zagoruyko & Komodakis (2016) Sergey Zagoruyko and Nikos Komodakis. Wide residual networks. arXiv preprint arXiv:1605.07146 , May 2016.
Zhao et al. (2018) Shengjia Zhao, Hongyu Ren, Arianna Yuan, Jiaming Song, Noah Goodman, and Stefano Ermon. Bias and generalization in deep generative models: An empirical study. In Advances in Neural Information Processing Systems , pp. 10792–10801, 2018.
Appendix A Non-Markovian Forward Processes for a Discrete Case
附录 A 离散情形的非马尔可夫前向过程
In this section, we describe a non-Markovian forward processes for discrete data and corresponding variational objectives. Since the focus of this paper is to accelerate reverse models corresponding to the Gaussian diffusion, we leave empirical evaluations as future work.
本节描述离散数据的非马尔可夫前向过程及相应变分目标。由于本文重点是加速对应高斯扩散的反向模型,经验评估留作未来工作。
For a categorical observation that is a one-hot vector with possible values, we define the forward process as follows. First, we have as the following categorical distribution:
对取 个可能值的 one-hot 向量类别观测 ,如下定义前向过程。首先,把 取为如下类别分布:
where is a vector with all entries being , and decreasing from for to for . Then we define as the following mixture distribution:
其中 是各项均为 的向量, 从 的 递减到 的 。然后把 定义为如下混合分布:
$$\displaystyle q({\bm{x}}{t-1}|{\bm{x}}{t},{\bm{x}}{0})=\begin{cases}\mathrm{Cat}({\bm{x}}{t})&\text{with probability }\sigma_{t}\
\mathrm{Cat}({\bm{x}}{0})&\text{with probability }(\alpha{t-1}-\sigma_{t}\alpha_{t})\
\mathrm{Cat}({\bm{1}}{K})&\text{with probability }(1-\alpha{t-1})-(1-\alpha_{t})\sigma_{t}\end{cases}, \tag{18}$$
or equivalently:
或等价地:
which is consistent with how we have defined .
这与我们对 的定义一致。
Similarly, we can define our reverse process as:
类似地,可把反向过程 定义为:
where maps to a -dimensional vector. As , the sampling process will become less stochastic, in the sense that it will either choose or the predicted with high probability. The KL divergence
其中 把 映到 维向量。当 时,采样过程会变得更不随机:它将以高概率选择 或预测的 。KL 散度
is well-defined, and is simply the KL divergence between two categoricals. Therefore, the resulting variational objective function should be easy to optimize as well. Moreover, as KL divergence is convex, we have this upper bound (which is tight when the right hand side goes to zero):
有良好定义,且就是两个类别分布之间的 KL 散度。因此所得变分目标函数也应易于优化。此外,由于 KL 散度凸,我们有如下上界(当右侧趋于零时紧):
The right hand side is simply a multi-class classification loss (up to constants), so we can arrive at similar arguments regarding how changes in do not affect the objective (up to re-weighting).
右侧(差常数)就是多类分类损失,因而可得到类似论证: 的变化(直至重加权)不影响目标。
Appendix B Proofs
附录 B 证明
Lemma 1.
For defined in Eq. (6) and defined in Eq. (7), we have:
引理 1。
对式 (6) 定义的 与式 (7) 定义的 ,我们有:
Proof.
Assume for any , holds, if:
证明。
假设对任意 , 成立,若:
then we can prove the statement with an induction argument for from to , since the base case () already holds.
则可对 从 到 用归纳论证证明该命题,因为基情形()已成立。
First, we have that
首先,我们有
and
以及
From Bishop 2006 (2.115), we have that is Gaussian, denoted as where
由 Bishop 2006 (2.115), 是高斯,记为 ,其中
and
以及
Therefore, , which allows us to apply the induction argument. ∎
因此 ,从而可应用归纳论证。∎
See 1
见 1
Proof.
From the definition of :
证明。
由 的定义:
where we use to denote “equal up to a value that does not depend on (but may depend on )”. For :
其中用 表示「相等至一个不依赖 (但可依赖 )的值」。对 :
where is the dimension of . For :
其中 是 的维数。对 :
Therefore, when for all , we have
因此,当对一切 取 时,我们有
for all . From the definition of “”, we have that . ∎
对一切 成立。由「」的定义,。∎
See 1
见 1
Proof.
In the context of the proof, we consider as a continous, independent “time” variable and and as functions of . First, let us consider a reparametrization between DDIM and the VE-SDE[^8] by introducing the variables and :
证明。
在证明语境中,把 视为连续、独立的「时间」变量,把 与 视为 的函数。首先,通过引入变量 与 ,考虑 DDIM 与 VE-SDE[^8] 之间的重参数化:
for and an increasing continuous function where .
对 ,以及递增连续函数 且 。
We can then define and corresponding to DDIM case as:
于是可定义对应 DDIM 情形的 与 :
This also means that:
这也意味着:
which establishes an bijection between and . From Equation (4) we have (note that ):
从而在 与 之间建立双射。由式 (4)(注意 ):
which can be reparametrized into a form that is consistent with VE-SDE:
可重参数化为与 VE-SDE 一致的形式:
Now, we derive the ODE forms for both DDIM and VE-SDE and show that they are equivalent.
现在分别推导 DDIM 与 VE-SDE 的 ODE 形式,并证明它们等价。
ODE form for DDIM
We repeat Equation (13) here:
DDIM 的 ODE 形式
此处重复式 (13):
which is equivalent to:
它等价于:
Divide both sides by and as , we have:
两边除以 ,并令 ,得到:
which is exactly what we have in Equation (14).
这正是式 (14) 中的形式。
We note that for the optimal model, is a minimizer:
我们指出:对最优模型, 是如下最小化者:
where .
其中 。
ODE form for VE-SDE
Define as the data distribution perturbed with variance Gaussian noise. The probability flow for VE-SDE is defined as Song et al. 2020:
VE-SDE 的 ODE 形式
定义 为被方差 的高斯噪声扰动的数据分布。VE-SDE 的概率流按 Song et al. 2020 定义为:
where is the diffusion coefficient, and is the score of .
其中 是扩散系数, 是 的分数。
The -perturbed score function is also a minimizer (from denoising score matching (Vincent 2011)):
-扰动分数函数 也是最小化者(来自去噪分数匹配 (Vincent 2011)):
where .
其中 。
Since there is an equivalence between and , we have the following relationship:
由于 与 存在等价,我们有如下关系:
from Equation (46) and Equation (48). Plug Equation (49) and definition of in Equation (47), we have:
来自式 (46) 与式 (48)。把式 (49) 与 的定义代入式 (47),得到:
and we have the following by rearranging terms:
整理各项后有:
which is equivalent to Equation (45). In both cases the initial conditions are , so the resulting ODEs are identical. ∎
这与式 (45) 等价。两种情形初值都是 ,因而所得 ODE 相同。∎
Appendix C Additional Derivations
附录 C 补充推导
C.1 Accelerated sampling processes
C.1 加速采样过程
In the accelerated case, we can consider the inference process to be factored as:
在加速情形下,可把推断过程分解为:
where is a sub-sequence of of length with , and let be its complement. Intuitively, the graphical model of and form a chain, whereas the graphical model of and forms a star graph. We define:
其中 是 中长度为 且 的子序列,记 为其补集。直观上, 与 的图模型形成链,而 与 的图模型形成星图。我们定义:
where the coefficients are chosen such that:
其中系数的选取使得:
i.e., the “marginals” match.
亦即「边缘」匹配。
The corresponding “generative process” is defined as:
相应的「生成过程」定义为:
where only part of the models are actually being used to produce samples. The conditionals are:
其中实际用于产出样本的只是部分模型。条件分布为:
where we leverage as part of the inference process (similar to what we have done in Section 3). The resulting variational objective becomes (define for conciseness):
其中我们把 作为推断过程的一部分(类似第 3 节)。所得变分目标变为(为简洁定义 ):
where each KL divergence is between two Gaussians with variance independent of . A similar argument to the proof used in Theorem 1 can show that the variational objective can also be converted to an objective of the form .
其中每个 KL 散度是方差不依赖 的两个高斯之间的散度。与定理 1 证明类似的论证可表明:变分目标 也可转换成 形式的目标。
C.2 Derivation of denoising objectives for DDPMs
C.2 DDPM 去噪目标的推导
We note that in Ho et al. 2020, a diffusion hyperparameter [^9] is first introduced, and then relevant variables and are defined. In this paper, we have used the notation to represent the variable in Ho et al. 2020 for three reasons. First, it makes it more clear that we only need to choose one set of hyperparameters, reducing possible cross-references of the derived variables. Second, it allows us to introduce the generalization as well as the acceleration case easier, because the inference process is no longer motivated by a diffusion. Third, there exists an isomorphism between and , which is not the case for .
我们指出:Ho et al. 2020 先引入扩散超参数 [^9],再定义相关变量 与 。本文用记号 表示 Ho et al. 2020 中的 ,原因有三。第一,这样更清楚我们只需选择一组超参数,减少派生变量的交叉引用。第二,许多表达式更简洁。第三,它强调真正进入边缘 的是累积乘积。下文在需要与 Ho et al. 2020 的推导对齐时,会使用 与他们的 。
In this section, we use and to be more consistent with the derivation in Ho et al. 2020, where
本节使用 与 ,以便与 Ho et al. 2020 的推导更一致,其中
\displaystyle{\color[rgb]{0,0.5,0.5}\alpha_{t}}=\frac{\alpha_{t}}{\alpha_{t-1}} \\ \displaystyle{\color[rgb]{0,0.5,0.5}\beta_{t}}=1-\frac{\alpha_{t}}{\alpha_{t-1}} \tag{60}
can be uniquely determined from (i.e. ).
可由 (即 )唯一确定。
First, from the diffusion forward process:
首先,由扩散前向过程:
\displaystyle q({\bm{x}}_{t-1}|{\bm{x}}_{t},{\bm{x}}_{0})={\mathcal{N}}\Bigg(\underbrace{\frac{\sqrt{\alpha_{t-1}}{\color[rgb]{0,0.5,0.5}\beta_{t}}}{1-\alpha_{t}}{\bm{x}}_{0}+\frac{\sqrt{{\color[rgb]{0,0.5,0.5}\alpha_{t}}}(1-\alpha_{t-1})}{1-\alpha_{t}}{\bm{x}}_{t}}_{\color[rgb]{0,0.5,0.5}\tilde{\mu}({\bm{x}}_{t},{\bm{x}}_{0})},\frac{1-\alpha_{t-1}}{1-\alpha_{t}}{\color[rgb]{0,0.5,0.5}\beta_{t}}{\bm{I}}\Bigg)
Ho et al. 2020 considered a specific type of :
Ho et al. 2020 考虑了特定类型的 :
\displaystyle p_{\theta}^{(t)}({\bm{x}}_{t-1}|{\bm{x}}_{t})={\mathcal{N}}\left({\color[rgb]{0,0.5,0.5}\mu_{\theta}({\bm{x}}_{t},t)},\sigma_{t}{\bm{I}}\right) \tag{62}
which leads to the following variational objective:
从而得到如下变分目标:
\displaystyle{\color[rgb]{0,0.5,0.5}L} \\ \displaystyle:={\mathbb{E}}_{{\bm{x}}_{0:T}\sim q({\bm{x}}_{0:T})}\left[q({\bm{x}}_{T}|{\bm{x}}_{0})+\sum_{t=2}^{T}\log q({\bm{x}}_{t-1}|{\bm{x}}_{t},{\bm{x}}_{0})-\sum_{t=1}^{T}\log p_{\theta}^{(t)}({\bm{x}}_{t-1}|{\bm{x}}_{t})\right] \\ \displaystyle\equiv{\mathbb{E}}_{{\bm{x}}_{0:T}\sim q({\bm{x}}_{0:T})}\left[\sum_{t=2}^{T}\underbrace{D_{\mathrm{KL}}(q({\bm{x}}_{t-1}|{\bm{x}}_{t},{\bm{x}}_{0}))\|p_{\theta}^{(t)}({\bm{x}}_{t-1}|{\bm{x}}_{t}))}_{\color[rgb]{0,0.5,0.5}L_{t-1}}-\log p_{\theta}^{(1)}({\bm{x}}_{0}|{\bm{x}}_{1})\right] \tag{63}
One can write:
可以写出:
\displaystyle{\color[rgb]{0,0.5,0.5}L_{t-1}}={\mathbb{E}}_{q}\left[\frac{1}{2\sigma_{t}^{2}}{\lVert{{\color[rgb]{0,0.5,0.5}\mu_{\theta}({\bm{x}}_{t},t)}-{\color[rgb]{0,0.5,0.5}\tilde{\mu}({\bm{x}}_{t},{\bm{x}}_{0})}}\rVert}_{2}^{2}\right] \tag{64}
Ho et al. 2020 chose the parametrization
Ho et al. 2020 选择参数化
\displaystyle{\color[rgb]{0,0.5,0.5}\mu_{\theta}({\bm{x}}_{t},t)}=\frac{1}{\sqrt{{\color[rgb]{0,0.5,0.5}\alpha_{t}}}}\left({\bm{x}}_{t}-\frac{{\color[rgb]{0,0.5,0.5}\beta_{t}}}{\sqrt{1-\alpha_{t}}}{\color[rgb]{0,0.5,0.5}\epsilon_{\theta}({\bm{x}}_{t},t)}\right) \tag{65}
which can be simplified to:
可简化为:
\displaystyle{\color[rgb]{0,0.5,0.5}L_{t-1}}={\mathbb{E}}_{{\bm{x}}_{0},\epsilon}\left[\frac{{\color[rgb]{0,0.5,0.5}\beta_{t}}^{2}}{2\sigma_{t}^{2}(1-\alpha_{t}){\color[rgb]{0,0.5,0.5}\alpha_{t}}}{\lVert{\epsilon-{\color[rgb]{0,0.5,0.5}\epsilon_{\theta}(\sqrt{\alpha_{t}}{\bm{x}}_{0}+\sqrt{1-\alpha_{t}}\epsilon,t)}}\rVert}_{2}^{2}\right] \tag{66}
Appendix D Experimental Details
附录 D 实验细节
D.1 Datasets and architectures
D.1 数据集与架构
We consider 4 image datasets with various resolutions: CIFAR10 (, unconditional), CelebA (), LSUN Bedroom () and LSUN Church (). For all datasets, we set the hyperparameters according to the heuristic in (Ho et al. 2020) to make the results directly comparable. We use the same model for each dataset, and only compare the performance of different generative processes. For CIFAR10, Bedroom and Church, we obtain the pretrained checkpoints from the original DDPM implementation; for CelebA, we trained our own model using the denoising objective .
我们考虑四个不同分辨率的图像数据集:CIFAR10(,无条件)、CelebA()、LSUN Bedroom()与 LSUN Church()。对全部数据集,按 (Ho et al. 2020) 的启发式设定超参数 ,以便结果可直接比较。每个数据集使用同一模型,只比较不同生成过程的表现。对 CIFAR10、Bedroom 与 Church,我们取自原始 DDPM 实现的预训练检查点;对 CelebA,用去噪目标 自行训练模型。
Our architecture for follows that in Ho et al. 2020, which is a U-Net (Ronneberger et al. 2015) based on a Wide ResNet (Zagoruyko & Komodakis 2016). We use the pretrained models from Ho et al. 2020 for CIFAR10, Bedroom and Church, and train our own model for the CelebA model (since a pretrained model is not provided). Our CelebA model has five feature map resolutions from to , and we use the original CelebA dataset (not CelebA-HQ) using the pre-processing technique from the StyleGAN (Karras et al. 2018) repository.
我们对 的结构沿用 Ho et al. 2020:基于 Wide ResNet (Zagoruyko & Komodakis 2016) 的 U-Net (Ronneberger et al. 2015)。CIFAR10、Bedroom 与 Church 使用 Ho et al. 2020 的预训练模型;CelebA 模型因未提供预训练而自行训练。我们的 CelebA 模型有从 到 的五个特征图分辨率,并使用原始 CelebA 数据集(非 CelebA-HQ),预处理采用 StyleGAN (Karras et al. 2018) 仓库的技术。
| Bedroom () | Church () | |||||||
|---|---|---|---|---|---|---|---|---|
| 10 | 20 | 50 | 100 | 10 | 20 | 50 | 100 | |
| DDIM () | 16.95 | 8.89 | 6.75 | 6.62 | 19.45 | 12.47 | 10.84 | 10.58 |
| DDPM () | 42.78 | 22.77 | 10.81 | 6.81 | 51.56 | 23.37 | 11.16 | 8.27 |
Table 3: LSUN Bedroom and Church image generation results, measured in FID. For 1000 steps DDPM, the FIDs are 6.36 for Bedroom and 7.89 for Church.
| Bedroom () | Church () | |||||||
|---|---|---|---|---|---|---|---|---|
| 10 | 20 | 50 | 100 | 10 | 20 | 50 | 100 | |
| DDIM () | 16.95 | 8.89 | 6.75 | 6.62 | 19.45 | 12.47 | 10.84 | 10.58 |
| DDPM () | 42.78 | 22.77 | 10.81 | 6.81 | 51.56 | 23.37 | 11.16 | 8.27 |
表 3:LSUN Bedroom 与 Church 图像生成结果(FID)。1000 步 DDPM 的 FID 为 Bedroom 6.36、Church 7.89。
D.2 Reverse process sub-sequence selection
D.2 反向过程子序列选择
We consider two types of selection procedure for given the desired :
在给定所需 时,我们考虑两类 选择程序:
- • Linear: we select the timesteps such that for some ;
- • 线性:选取时间步使 ,其中 为某常数;
- • Quadratic: we select the timesteps such that for some .
- • 二次:选取时间步使 ,其中 为某常数。
The constant value is selected such that is close to . We used quadratic for CIFAR10 and linear for the remaining datasets. These choices achieve slightly better FID than their alternatives in the respective datasets.
常数 的选取使 接近 。CIFAR10 用二次,其余数据集用线性。这些选择在各自数据集上比替代方案取得略好的 FID。
D.3 Closed form equations for each sampling step
D.3 每步采样的闭式方程
From the general sampling equation in Eq. (12), we have the following update equation:
由式 (12) 的一般采样方程,有如下更新方程:
where
其中
For the case of (DDPM with a larger variance), the update equation becomes:
对 (方差更大的 DDPM)情形,更新方程变为:
which uses a different coefficient for compared with the update for , but uses the same coefficient for the non-stochastic parts. This update is more stochastic than the update for , which explains why it achieves worse performance when is small.
相对 的更新,它对 使用不同系数,但对非随机部分使用相同系数。该更新比 的更新更随机,这解释了为何在 较小时表现更差。
D.4 Samples and Consistency
D.4 样本与一致性
We show more samples in Figure 7 (CIFAR10), Figure 8 (CelebA), Figure 10 (Church) and consistency results of DDIM in Figure 9 (CelebA).
我们在图 7(CIFAR10)、图 8(CelebA)、图 10(Church)展示更多样本,并在图 9(CelebA)展示 DDIM 的一致性结果。

Figure 7: CIFAR10 samples from 1000 step DDPM, 1000 step DDIM and 100 step DDIM.
图 7:1000 步 DDPM、1000 步 DDIM 与 100 步 DDIM 的 CIFAR10 样本。

Figure 8: CelebA samples from 1000 step DDPM, 1000 step DDIM and 100 step DDIM.
图 8:1000 步 DDPM、1000 步 DDIM 与 100 步 DDIM 的 CelebA 样本。
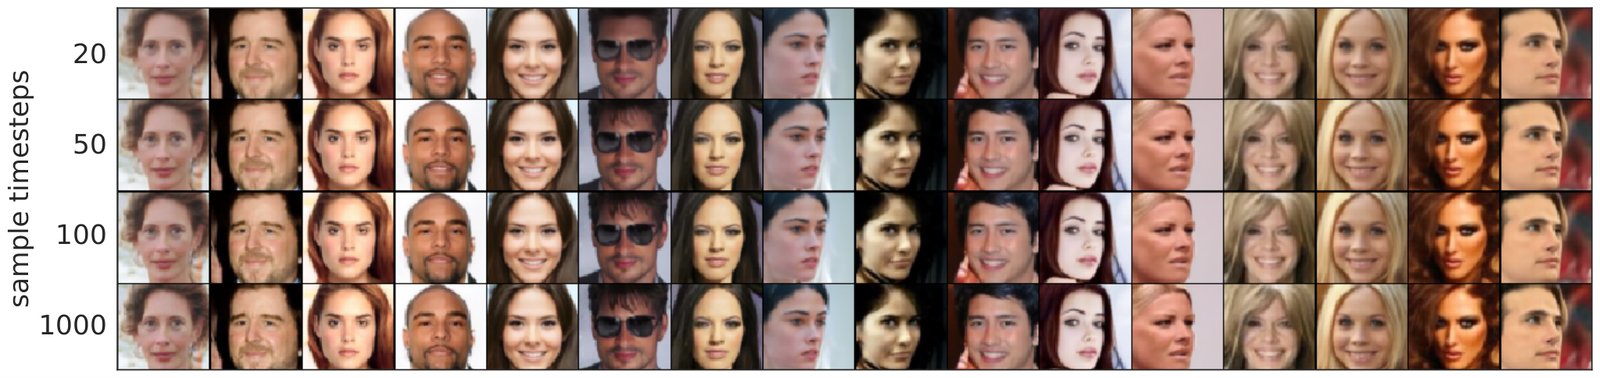
Figure 9: CelebA samples from DDIM with the same random and different number of steps.
图 9:同一随机 、不同步数下的 CelebA DDIM 样本。
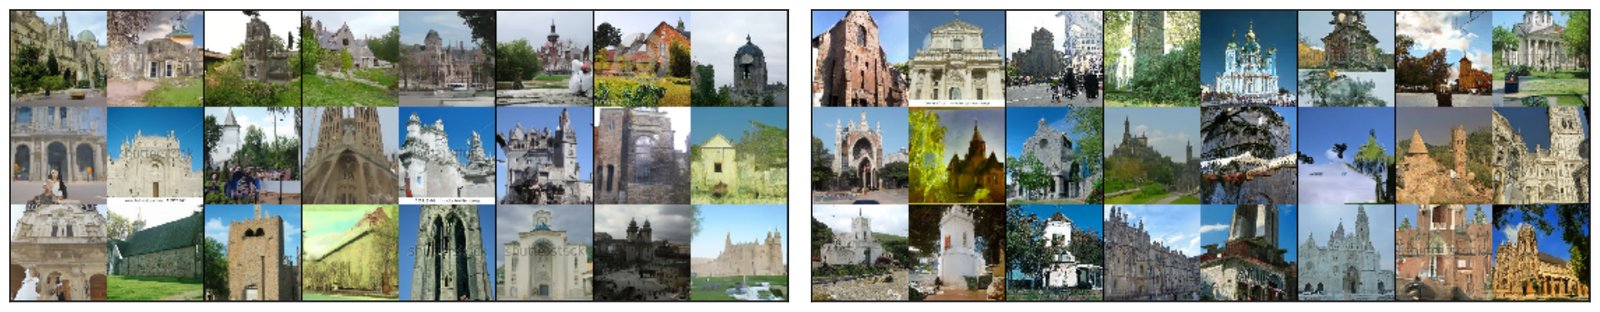
Figure 10: Church samples from 100 step DDPM and 100 step DDIM.
图 10:100 步 DDPM 与 100 步 DDIM 的 Church 样本。
D.5 Interpolation
D.5 插值
To generate interpolations on a line, we randomly sample two initial values from the standard Gaussian, interpolate them with spherical linear interpolation (Shoemake 1985), and then use the DDIM to obtain samples.
为生成直线上的插值,我们从标准高斯随机采两个初始 ,用球面线性插值(Shoemake 1985)插值它们,再用 DDIM 得到 样本。
where . These values are used to produce DDIM samples.
其中 。这些值用于产出 DDIM 样本。
To generate interpolations on a grid, we sample four latent variables and separate them in to two pairs; then we use slerp with the pairs under the same , and use slerp over the interpolated samples across the pairs (under an independently chosen interpolation coefficient). We show more grid interpolation results in Figure 11 (CelebA), Figure 12 (Bedroom), and Figure 13 (Church).
为生成网格上的插值,我们采样四个潜变量并分成两对;先在相同 下对两对分别做 slerp,再在两对的插值结果之间做 slerp(插值系数独立选取)。更多网格插值结果见图 11(CelebA)、图 12(Bedroom)与图 13(Church)。
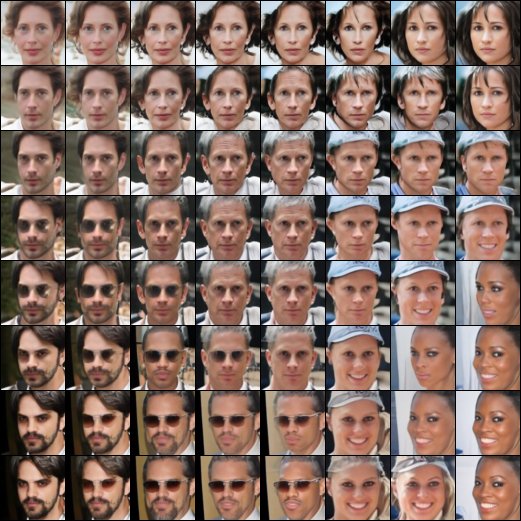
Figure 11: More interpolations from the CelebA DDIM with .
图 11: 时 CelebA DDIM 的更多插值。
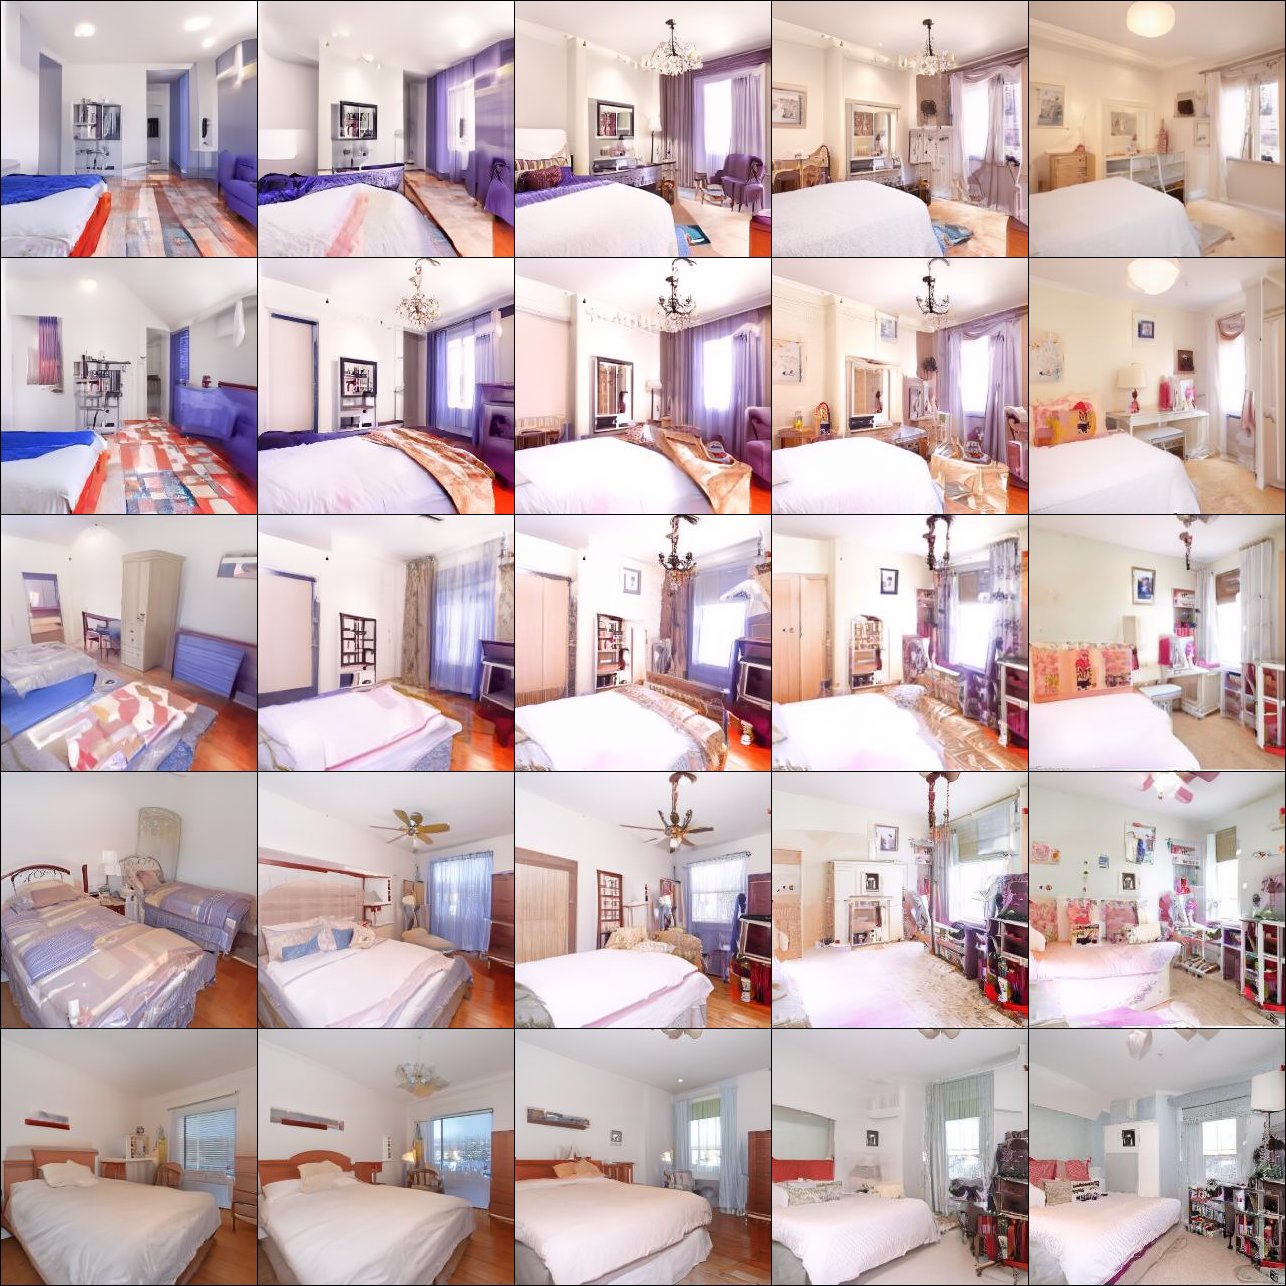
Figure 12: More interpolations from the Bedroom DDIM with .
图 12: 时 Bedroom DDIM 的更多插值。
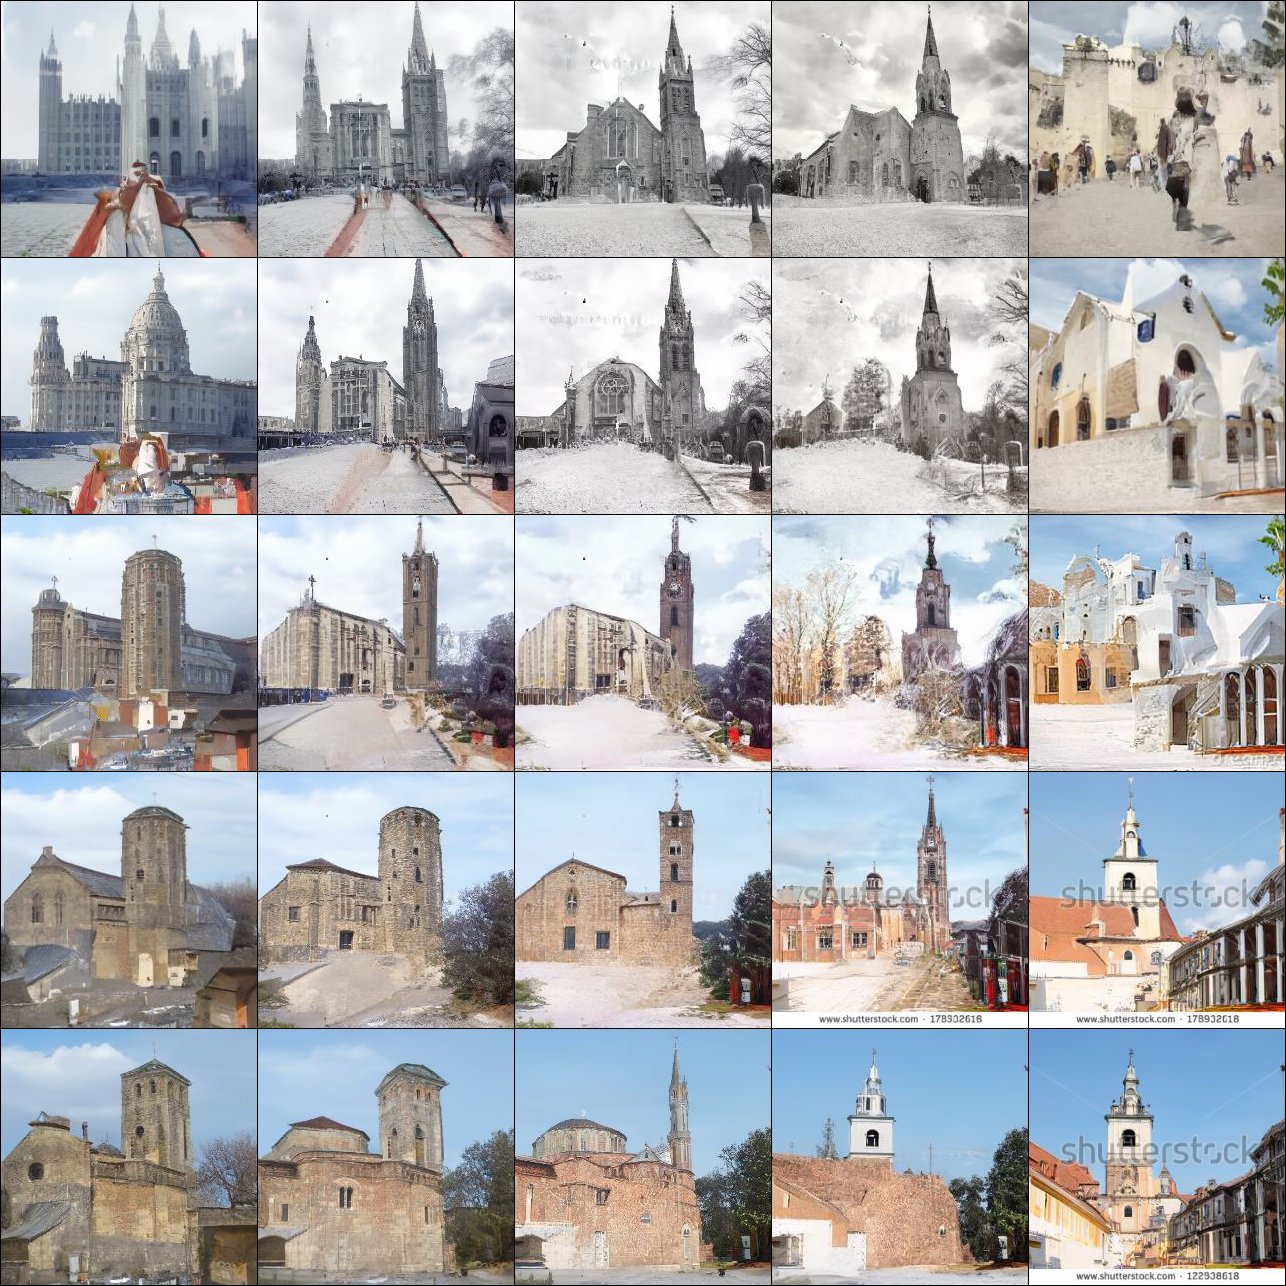
Figure 13: More interpolations from the Church DDIM with .
图 13: 时 Church DDIM 的更多插值。