Unsupervised Representation Learning with Deep Convolutional Generative Adversarial Networks
Unsupervised Representation Learning with Deep Convolutional Generative Adversarial Networks
用深度卷积生成对抗网络做无监督表示学习
Alec Radford & Luke Metz Affiliation: indico Research Affiliation: Boston, MA Email: {alec,luke}@indico.io Soumith Chintala Affiliation: Facebook AI Research Affiliation: New York, NY Email: soumith@fb.com
Abstract
摘要
In recent years, supervised learning with convolutional networks (CNNs) has seen huge adoption in computer vision applications. Comparatively, unsupervised learning with CNNs has received less attention. In this work we hope to help bridge the gap between the success of CNNs for supervised learning and unsupervised learning. We introduce a class of CNNs called deep convolutional generative adversarial networks (DCGANs), that have certain architectural constraints, and demonstrate that they are a strong candidate for unsupervised learning. Training on various image datasets, we show convincing evidence that our deep convolutional adversarial pair learns a hierarchy of representations from object parts to scenes in both the generator and discriminator. Additionally, we use the learned features for novel tasks - demonstrating their applicability as general image representations.
近年来,用卷积网络(CNN)做监督学习在计算机视觉里已被广泛采用;相对而言,CNN 的无监督学习关注较少。本文希望弥合二者差距。我们提出一类有特定结构约束的 CNN——深度卷积生成对抗网络(DCGAN),并说明它是无监督学习的有力候选。在多种图像数据集上训练后,我们给出有力证据:深度卷积对抗对在生成器与判别器中都学到了从物体部件到场景的层次表示。此外,我们把学到的特征用于新任务,展示其作为通用图像表示的可用性。
1 Introduction
1 引言
Learning reusable feature representations from large unlabeled datasets has been an area of active research. In the context of computer vision, one can leverage the practically unlimited amount of unlabeled images and videos to learn good intermediate representations, which can then be used on a variety of supervised learning tasks such as image classification. We propose that one way to build good image representations is by training Generative Adversarial Networks (GANs) (Goodfellow et al. 2014), and later reusing parts of the generator and discriminator networks as feature extractors for supervised tasks. GANs provide an attractive alternative to maximum likelihood techniques. One can additionally argue that their learning process and the lack of a heuristic cost function (such as pixel-wise independent mean-square error) are attractive to representation learning. GANs have been known to be unstable to train, often resulting in generators that produce nonsensical outputs. There has been very limited published research in trying to understand and visualize what GANs learn, and the intermediate representations of multi-layer GANs.
从大规模无标注数据学习可复用特征表示,一直是活跃研究方向。在计算机视觉里,可以利用近乎无限的无标注图像与视频学到好的中间表示,再用于分类等监督学习任务。我们提出:训练生成对抗网络(GAN)(Goodfellow et al. 2014),再把生成器与判别器的部分网络当作监督任务的特征抽取器,是构建良好图像表示的一条路径。GAN 相对最大似然方法有吸引力;也可认为其学习过程与不靠像素独立均方误差这类启发式代价,对表示学习有利。GAN 训练常不稳定,生成器容易产出无意义样本。关于 GAN 学到了什么、多层 GAN 中间表示如何可视化的公开发表研究仍然很少。
In this paper, we make the following contributions
本文贡献如下
- • We propose and evaluate a set of constraints on the architectural topology of Convolutional GANs that make them stable to train in most settings. We name this class of architectures Deep Convolutional GANs (DCGAN)
- • 提出并评估一组卷积 GAN 拓扑约束,使它们在多数设定下训练稳定。我们称这类结构为深度卷积 GAN(DCGAN)
- • We use the trained discriminators for image classification tasks, showing competitive performance with other unsupervised algorithms.
- • 用训好的判别器做图像分类,表现可与其他无监督算法竞争
- • We visualize the filters learnt by GANs and empirically show that specific filters have learned to draw specific objects.
- • 可视化 GAN 学到的滤波器,经验上表明特定滤波器学会绘制特定物体
- • We show that the generators have interesting vector arithmetic properties allowing for easy manipulation of many semantic qualities of generated samples.
- • 展示生成器的向量算术性质,便于操纵生成样本的多种语义属性
2 Related Work
2 相关工作
2.1 Representation Learning from unlabeled data
2.1 从无标注数据学表示
Unsupervised representation learning is a fairly well studied problem in general computer vision research, as well as in the context of images. A classic approach to unsupervised representation learning is to do clustering on the data (for example using K-means), and leverage the clusters for improved classification scores. In the context of images, one can do hierarchical clustering of image patches (Coates & Ng 2012) to learn powerful image representations. Another popular method is to train auto-encoders (convolutionally, stacked (Vincent et al. 2010), separating the what and where components of the code (Zhao et al. 2015), ladder structures (Rasmus et al. 2015)) that encode an image into a compact code, and decode the code to reconstruct the image as accurately as possible. These methods have also been shown to learn good feature representations from image pixels. Deep belief networks (Lee et al. 2009) have also been shown to work well in learning hierarchical representations.
无监督表示学习在计算机视觉与图像领域都已有较多研究。经典做法是对数据聚类(如 K-means),再用簇提升分类分数。对图像,可对图像块做层次聚类(Coates & Ng 2012)以学强表示。另一流行路线是训练自编码器(卷积的、堆叠的(Vincent et al. 2010)、分离 what/where 码(Zhao et al. 2015)、ladder 结构(Rasmus et al. 2015)):把图像编成紧凑码再解码重建。这些方法也能从像素学到好特征。深度信念网络(Lee et al. 2009)也被证明适于学层次表示。
2.2 Generating natural images
2.2 生成自然图像
Generative image models are well studied and fall into two categories: parametric and non-parametric.
生成图像模型研究充分,大致分参数与非参数两类。
The non-parametric models often do matching from a database of existing images, often matching patches of images, and have been used in texture synthesis (Efros et al. 1999), super-resolution (Freeman et al. 2002) and in-painting (Hays & Efros 2007).
非参数模型常从已有图像库做匹配(多为图像块匹配),用于纹理合成(Efros et al. 1999)、超分辨(Freeman et al. 2002)与补全(Hays & Efros 2007)。
Parametric models for generating images has been explored extensively (for example on MNIST digits or for texture synthesis (Portilla & Simoncelli 2000)). However, generating natural images of the real world have had not much success until recently. A variational sampling approach to generating images (Kingma & Welling 2013) has had some success, but the samples often suffer from being blurry. Another approach generates images using an iterative forward diffusion process (Sohl-Dickstein et al. 2015). Generative Adversarial Networks (Goodfellow et al. 2014) generated images suffering from being noisy and incomprehensible. A laplacian pyramid extension to this approach (Denton et al. 2015) showed higher quality images, but they still suffered from the objects looking wobbly because of noise introduced in chaining multiple models. A recurrent network approach (Gregor et al. 2015) and a deconvolution network approach (Dosovitskiy et al. 2014) have also recently had some success with generating natural images. However, they have not leveraged the generators for supervised tasks.
参数化生成也探索很多(如 MNIST 数字或纹理合成(Portilla & Simoncelli 2000)),但真实世界自然图像直到近年才有像样进展。变分采样(Kingma & Welling 2013)有一定成功,样本常偏糊。另一路线用迭代前向扩散过程生成(Sohl-Dickstein et al. 2015)。生成对抗网络(Goodfellow et al. 2014)生成的图像曾噪声大、难懂。拉普拉斯金字塔扩展(Denton et al. 2015)质量更高,但因多模型串联引入噪声,物体仍显晃动。循环网络(Gregor et al. 2015)与反卷积网络(Dosovitskiy et al. 2014)近来也有自然图像生成进展,但尚未把生成器用于监督任务。
2.3 Visualizing the internals of CNNs
2.3 可视化 CNN 内部
One constant criticism of using neural networks has been that they are black-box methods, with little understanding of what the networks do in the form of a simple human-consumable algorithm. In the context of CNNs, Zeiler et. al. (Zeiler & Fergus 2014) showed that by using deconvolutions and filtering the maximal activations, one can find the approximate purpose of each convolution filter in the network. Similarly, using a gradient descent on the inputs lets us inspect the ideal image that activates certain subsets of filters (Mordvintsev et al.).
神经网络常被批评为黑盒,缺少可被人理解的简单算法说明。对 CNN,Zeiler 等人(Zeiler & Fergus 2014)用反卷积与过滤最大激活,可近似看出各卷积滤波器用途。类似地,对输入做梯度下降可检查激活某些滤波器子集的理想图像(Mordvintsev et al.)。
3 Approach and Model Architecture
3 方法与模型结构
Historical attempts to scale up GANs using CNNs to model images have been unsuccessful. This motivated the authors of LAPGAN (Denton et al. 2015) to develop an alternative approach to iteratively upscale low resolution generated images which can be modeled more reliably. We also encountered difficulties attempting to scale GANs using CNN architectures commonly used in the supervised literature. However, after extensive model exploration we identified a family of architectures that resulted in stable training across a range of datasets and allowed for training higher resolution and deeper generative models.
历史上用 CNN 放大 GAN 去建模图像并不成功,这也促使 LAPGAN(Denton et al. 2015)改走迭代上采样低分辨率生成图、从而更可靠建模的路线。我们尝试把监督文献中常见的 CNN 结构直接放大到 GAN 时也遇困难。但经大量结构探索后,我们找到一类架构:在多种数据集上训练稳定,并允许更高分辨率、更深的生成模型。
Core to our approach is adopting and modifying three recently demonstrated changes to CNN architectures.
方法核心是采纳并改动近期三项 CNN 结构变化。
The first is the all convolutional net (Springenberg et al. 2014) which replaces deterministic spatial pooling functions (such as maxpooling) with strided convolutions, allowing the network to learn its own spatial downsampling. We use this approach in our generator, allowing it to learn its own spatial upsampling, and discriminator.
其一是全卷积网络(Springenberg et al. 2014):用步长卷积替换确定性空间池化(如最大池化),让网络自己学空间下采样。我们在生成器(学空间上采样)与判别器中都采用此思路。
Second is the trend towards eliminating fully connected layers on top of convolutional features. The strongest example of this is global average pooling which has been utilized in state of the art image classification models (Mordvintsev et al.). We found global average pooling increased model stability but hurt convergence speed. A middle ground of directly connecting the highest convolutional features to the input and output respectively of the generator and discriminator worked well. The first layer of the GAN, which takes a uniform noise distribution as input, could be called fully connected as it is just a matrix multiplication, but the result is reshaped into a 4-dimensional tensor and used as the start of the convolution stack. For the discriminator, the last convolution layer is flattened and then fed into a single sigmoid output. See Fig. 1 for a visualization of an example model architecture.
其二是去掉卷积特征之上的全连接层。最强例子是全局平均池化,已用于前沿图像分类(Mordvintsev et al.)。我们发现全局平均池化提高稳定性但伤收敛速度。折中做法是:把最高层卷积特征分别直接接到生成器与判别器的输入/输出,效果良好。GAN 第一层把均匀噪声分布 作为输入,可视为全连接(矩阵乘法),但结果会 reshape 成四维张量作为卷积栈起点。判别器则把最后一层卷积展平,送入单一 sigmoid 输出。示例结构见图 1。
Third is Batch Normalization (Ioffe & Szegedy 2015) which stabilizes learning by normalizing the input to each unit to have zero mean and unit variance. This helps deal with training problems that arise due to poor initialization and helps gradient flow in deeper models. This proved critical to get deep generators to begin learning, preventing the generator from collapsing all samples to a single point which is a common failure mode observed in GANs. Directly applying batchnorm to all layers however, resulted in sample oscillation and model instability. This was avoided by not applying batchnorm to the generator output layer and the discriminator input layer.
其三是批归一化(Ioffe & Szegedy 2015):把各单元输入归一到零均值单位方差以稳住学习,缓解差初始化带来的训练问题,并帮助更深模型中的梯度流动。这对让深层生成器开始学习至关重要,可防止生成器把所有样本塌成单点——GAN 常见失败模式。但若对所有层直接加 batchnorm,会出现样本振荡与不稳定;避免办法是:生成器输出层与判别器输入层不加 batchnorm。
The ReLU activation (Nair & Hinton 2010) is used in the generator with the exception of the output layer which uses the Tanh function. We observed that using a bounded activation allowed the model to learn more quickly to saturate and cover the color space of the training distribution. Within the discriminator we found the leaky rectified activation (Maas et al. 2013) (Xu et al. 2015) to work well, especially for higher resolution modeling. This is in contrast to the original GAN paper, which used the maxout activation (Goodfellow et al. 2013).
生成器使用 ReLU(Nair & Hinton 2010),输出层除外,改用 Tanh。我们观察到有界激活能让模型更快学会饱和并覆盖训练分布的色彩空间。判别器中 leaky ReLU(Maas et al. 2013;Xu et al. 2015)效果好,尤其在更高分辨率建模时。这与原始 GAN 使用的 maxout(Goodfellow et al. 2013)不同。
Architecture guidelines for stable Deep Convolutional GANs • Replace any pooling layers with strided convolutions (discriminator) and fractional-strided convolutions (generator). • Use batchnorm in both the generator and the discriminator. • Remove fully connected hidden layers for deeper architectures. • Use ReLU activation in generator for all layers except for the output, which uses Tanh. • Use LeakyReLU activation in the discriminator for all layers.
稳定深度卷积 GAN 的结构指南 • 用步长卷积(判别器)与分数步长卷积(生成器)替换任何池化层。• 生成器与判别器都使用 batchnorm。• 更深结构去掉全连接隐层。• 生成器除输出用 Tanh 外,其余层用 ReLU。• 判别器各层用 LeakyReLU。
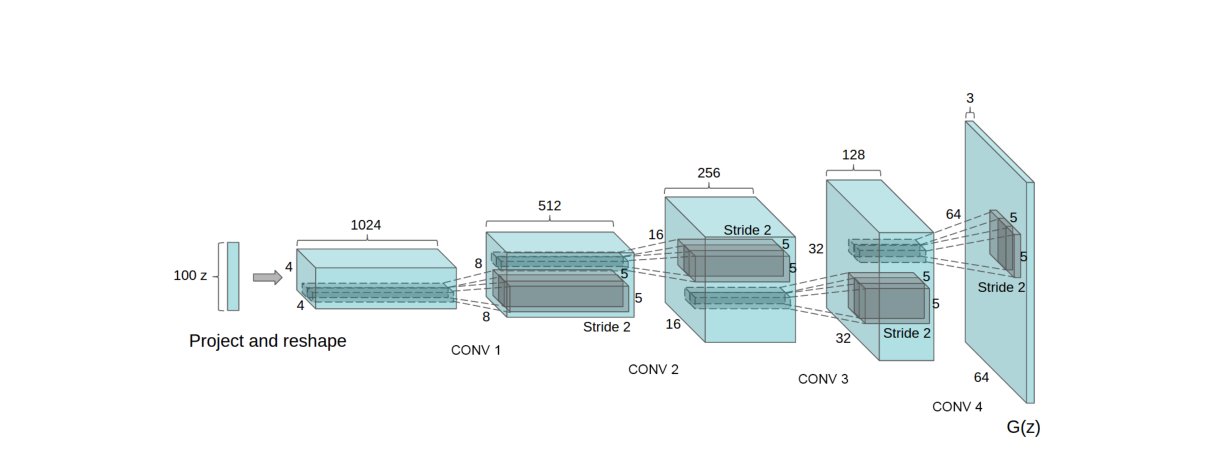
Figure 1: DCGAN generator used for LSUN scene modeling. A 100 dimensional uniform distribution is projected to a small spatial extent convolutional representation with many feature maps. A series of four fractionally-strided convolutions (in some recent papers, these are wrongly called deconvolutions) then convert this high level representation into a pixel image. Notably, no fully connected or pooling layers are used.
图 1:用于 LSUN 场景建模的 DCGAN 生成器。100 维均匀分布 被投影为空间范围小、特征图很多的卷积表示。随后四次分数步长卷积(近作有时误称反卷积)把该高层表示变成 像素图像。值得注意的是未使用全连接或池化层。
4 Details of adversarial training
4 对抗训练细节
We trained DCGANs on three datasets, Large-scale Scene Understanding (LSUN) (Yu et al. 2015), Imagenet-1k and a newly assembled Faces dataset. Details on the usage of each of these datasets are given below.
我们在三个数据集上训练 DCGAN:大规模场景理解(LSUN)(Yu et al. 2015)、Imagenet-1k,以及新整理的 Faces 数据集。各数据集用法见下。
No pre-processing was applied to training images besides scaling to the range of the tanh activation function [-1, 1]. All models were trained with mini-batch stochastic gradient descent (SGD) with a mini-batch size of 128. All weights were initialized from a zero-centered Normal distribution with standard deviation 0.02. In the LeakyReLU, the slope of the leak was set to 0.2 in all models. While previous GAN work has used momentum to accelerate training, we used the Adam optimizer (Kingma & Ba 2014) with tuned hyperparameters. We found the suggested learning rate of 0.001, to be too high, using 0.0002 instead. Additionally, we found leaving the momentum term at the suggested value of 0.9 resulted in training oscillation and instability while reducing it to 0.5 helped stabilize training.
训练图像除缩放到 tanh 激活范围 外不做预处理。全部模型用 mini-batch SGD,batch size 128。权重从零均值、标准差 0.02 的正态初始化。LeakyReLU 的泄漏斜率一律 0.2。先前 GAN 常用动量加速;我们改用调过超参的 Adam(Kingma & Ba 2014)。建议学习率 0.001 偏高,改用 0.0002。动量项 若保持建议值 0.9 会导致振荡与不稳,降到 0.5 有助于稳住训练。
4.1 LSUN
As visual quality of samples from generative image models has improved, concerns of over-fitting and memorization of training samples have risen. To demonstrate how our model scales with more data and higher resolution generation, we train a model on the LSUN bedrooms dataset containing a little over 3 million training examples. Recent analysis has shown that there is a direct link between how fast models learn and their generalization performance (Hardt et al. 2015). We show samples from one epoch of training (Fig.2), mimicking online learning, in addition to samples after convergence (Fig.3), as an opportunity to demonstrate that our model is not producing high quality samples via simply overfitting/memorizing training examples. No data augmentation was applied to the images.
随着生成图像视觉质量提升,过拟合与记忆训练样本的担忧也在增加。为展示模型如何随更多数据与更高分辨率扩展,我们在含逾 300 万训练例的 LSUN bedrooms 上训练。近期分析表明学习速度与泛化直接相关(Hardt et al. 2015)。我们给出训练一个 epoch 后的样本(图 2)以模拟在线学习,以及收敛后的样本(图 3),用以说明高质量样本并非简单过拟合/记忆训练例。图像未做数据增强。
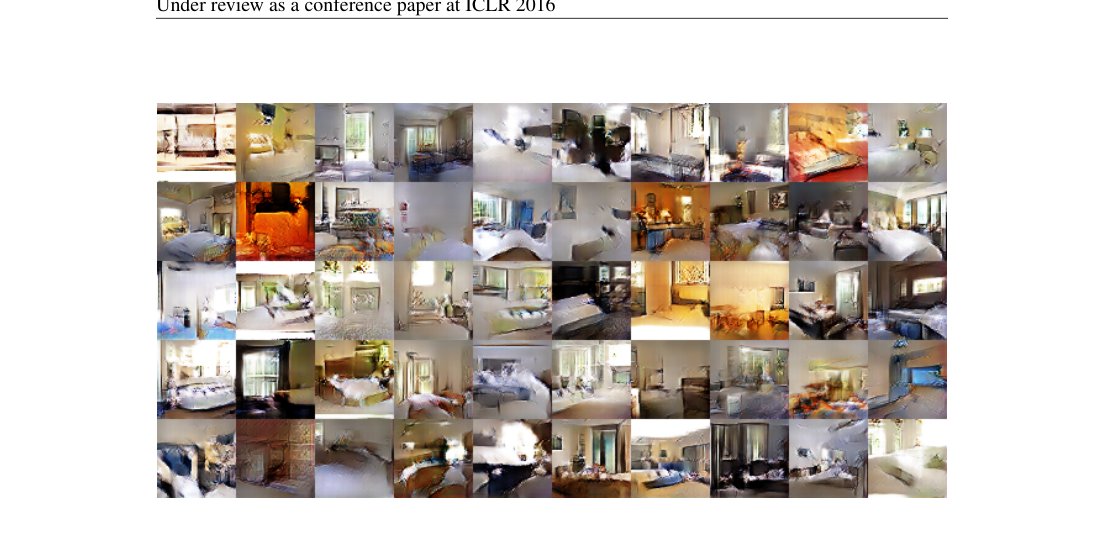
Figure 2: Generated bedrooms after one training pass through the dataset. Theoretically, the model could learn to memorize training examples, but this is experimentally unlikely as we train with a small learning rate and minibatch SGD. We are aware of no prior empirical evidence demonstrating memorization with SGD and a small learning rate.
图 2:遍历数据集一轮后生成的卧室。理论上模型可记忆训练例,但以小学习率与 mini-batch SGD 训练,实验上不太可能。我们不知道先前有经验证据表明小学习率 SGD 会出现记忆。
4.1.1 Deduplication
To further decrease the likelihood of the generator memorizing input examples (Fig.2) we perform a simple image de-duplication process. We fit a 3072-128-3072 de-noising dropout regularized RELU autoencoder on 32x32 downsampled center-crops of training examples. The resulting code layer activations are then binarized via thresholding the ReLU activation which has been shown to be an effective information preserving technique (Srivastava et al. 2014) and provides a convenient form of semantic-hashing, allowing for linear time de-duplication . Visual inspection of hash collisions showed high precision with an estimated false positive rate of less than 1 in 100. Additionally, the technique detected and removed approximately 275,000 near duplicates, suggesting a high recall.
4.1.1 去重
为进一步降低生成器记忆输入例(图 2)的可能,我们做简单图像去重:在训练例的 32×32 下采样中心裁剪上拟合 3072-128-3072、带去噪 dropout 正则的 ReLU 自编码器。码层激活经 ReLU 阈值二值化——这被证明是有效保信息技巧(Srivastava et al. 2014),并提供便利的语义哈希,可线性时间去重。哈希碰撞的目检精度高,估计假阳性低于 1/100。该方法还检出并移除约 275,000 近重复,召回看来也高。
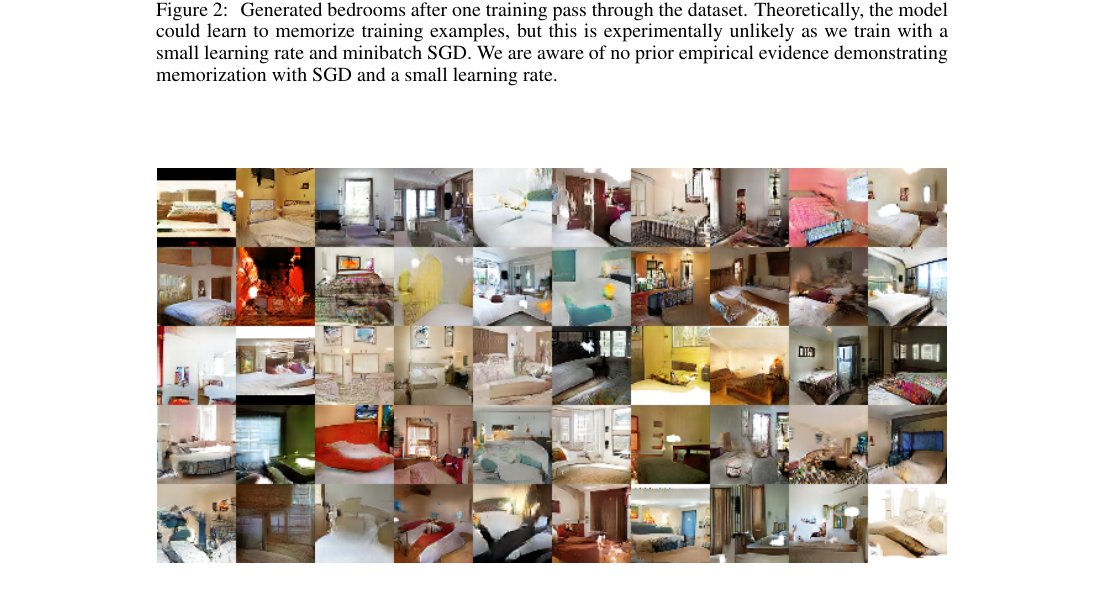
Figure 3: Generated bedrooms after five epochs of training. There appears to be evidence of visual under-fitting via repeated noise textures across multiple samples such as the base boards of some of the beds.
图 3:训练五个 epoch 后生成的卧室。可见视觉欠拟合迹象:多样本重复出现噪声纹理,例如某些床的踢脚线。
4.2 Faces
4.2 人脸
We scraped images containing human faces from random web image queries of peoples names. The people names were acquired from dbpedia, with a criterion that they were born in the modern era. This dataset has 3M images from 10K people. We run an OpenCV face detector on these images, keeping the detections that are sufficiently high resolution, which gives us approximately 350,000 face boxes. We use these face boxes for training. No data augmentation was applied to the images.
我们用现代人名的随机网页图像查询抓取含人脸图片;人名来自 dbpedia,条件为生于现当代。该集约 300 万张、来自约 1 万人。用 OpenCV 人脸检测器,保留足够高分辨率的检测框,得到约 350,000 个人脸框用于训练。未做数据增强。
4.3 Imagenet-1k
We use Imagenet-1k (Deng et al. 2009) as a source of natural images for unsupervised training. We train on min-resized center crops. No data augmentation was applied to the images.
我们用 Imagenet-1k(Deng et al. 2009)作为无监督训练的自然图像源。在 最小边缩放后的中心裁剪上训练。未做数据增强。
5 Empirical Validation of DCGANs capabilities
5 DCGAN 能力的经验验证
5.1 Classifying CIFAR-10 using GANs as a feature extractor
5.1 用 GAN 作特征抽取器分类 CIFAR-10
One common technique for evaluating the quality of unsupervised representation learning algorithms is to apply them as a feature extractor on supervised datasets and evaluate the performance of linear models fitted on top of these features.
评估无监督表示学习质量的常用做法,是把它们当作监督数据集上的特征抽取器,再评估其上线性模型的表现。
On the CIFAR-10 dataset, a very strong baseline performance has been demonstrated from a well tuned single layer feature extraction pipeline utilizing K-means as a feature learning algorithm. When using a very large amount of feature maps (4800) this technique achieves 80.6% accuracy. An unsupervised multi-layered extension of the base algorithm reaches 82.0% accuracy (Coates & Ng 2011). To evaluate the quality of the representations learned by DCGANs for supervised tasks, we train on Imagenet-1k and then use the discriminator’s convolutional features from all layers, maxpooling each layers representation to produce a spatial grid. These features are then flattened and concatenated to form a 28672 dimensional vector and a regularized linear L2-SVM classifier is trained on top of them. This achieves 82.8% accuracy, out performing all K-means based approaches. Notably, the discriminator has many less feature maps (512 in the highest layer) compared to K-means based techniques, but does result in a larger total feature vector size due to the many layers of spatial locations. The performance of DCGANs is still less than that of Exemplar CNNs (Dosovitskiy et al. 2015), a technique which trains normal discriminative CNNs in an unsupervised fashion to differentiate between specifically chosen, aggressively augmented, exemplar samples from the source dataset. Further improvements could be made by finetuning the discriminator’s representations, but we leave this for future work. Additionally, since our DCGAN was never trained on CIFAR-10 this experiment also demonstrates the domain robustness of the learned features.
在 CIFAR-10 上,调得好的单层特征抽取管线、以 K-means 作特征学习,已给出很强基线:特征图很多(4800)时准确率 80.6%。该算法的无监督多层扩展达到 82.0%(Coates & Ng 2011)。为评估 DCGAN 学到的表示对监督任务的质量,我们在 Imagenet-1k 上训练,再取判别器各层卷积特征,每层最大池化到 空间网格,展平拼接成 28672 维向量,其上训练正则线性 L2-SVM。准确率 82.8%,超过所有基于 K-means 的方法。值得注意的是判别器特征图更少(最高层 512),但因多层 空间位置,总特征维更大。DCGAN 仍低于 Exemplar CNN(Dosovitskiy et al. 2015)——后者以无监督方式训练普通判别 CNN,去区分经强增强、特意挑选的 exemplar。微调判别器表示或可再提升,留待未来。此外,DCGAN 从未在 CIFAR-10 上训练,本实验也说明所学特征的跨域稳健性。
| Model | Accuracy | Accuracy (400 per class) | max # of features units |
|---|---|---|---|
| 1 Layer K-means | 80.6% | 63.7% (0.7%) | 4800 |
| 3 Layer K-means Learned RF | 82.0% | 70.7% (0.7%) | 3200 |
| View Invariant K-means | 81.9% | 72.6% (0.7%) | 6400 |
| Exemplar CNN | 84.3% | 77.4% (0.2%) | 1024 |
| DCGAN (ours) + L2-SVM | 82.8% | 73.8% (0.4%) | 512 |
Table 1: CIFAR-10 classification results using our pre-trained model. Our DCGAN is not pre-trained on CIFAR-10, but on Imagenet-1k, and the features are used to classify CIFAR-10 images.
| 模型 | 准确率 | 准确率(每类 400) | 最大特征单元数 |
|---|---|---|---|
| 1 Layer K-means | 80.6% | 63.7% (0.7%) | 4800 |
| 3 Layer K-means Learned RF | 82.0% | 70.7% (0.7%) | 3200 |
| View Invariant K-means | 81.9% | 72.6% (0.7%) | 6400 |
| Exemplar CNN | 84.3% | 77.4% (0.2%) | 1024 |
| DCGAN(本文)+ L2-SVM | 82.8% | 73.8% (0.4%) | 512 |
表 1:用预训练模型在 CIFAR-10 上的分类结果。我们的 DCGAN 在 Imagenet-1k 而非 CIFAR-10 上预训练,特征用于分类 CIFAR-10 图像。
5.2 Classifying SVHN digits using GANs as a feature extractor
5.2 用 GAN 作特征抽取器分类 SVHN 数字
On the StreetView House Numbers dataset (SVHN)(Netzer et al. 2011), we use the features of the discriminator of a DCGAN for supervised purposes when labeled data is scarce. Following similar dataset preparation rules as in the CIFAR-10 experiments, we split off a validation set of 10,000 examples from the non-extra set and use it for all hyperparameter and model selection. 1000 uniformly class distributed training examples are randomly selected and used to train a regularized linear L2-SVM classifier on top of the same feature extraction pipeline used for CIFAR-10. This achieves state of the art (for classification using 1000 labels) at 22.48% test error, improving upon another modifcation of CNNs designed to leverage unlabled data (Zhao et al. 2015). Additionally, we validate that the CNN architecture used in DCGAN is not the key contributing factor of the model’s performance by training a purely supervised CNN with the same architecture on the same data and optimizing this model via random search over 64 hyperparameter trials (Bergstra & Bengio 2012). It achieves a signficantly higher 28.87% validation error.
在 StreetView House Numbers(SVHN)(Netzer et al. 2011)上,标注稀缺时用 DCGAN 判别器特征做监督。数据准备类似 CIFAR-10:从非 extra 集划出 10,000 验证集,用于全部超参与模型选择。随机选取按类均匀的 1000 个训练例,在与 CIFAR-10 相同的特征抽取管线上训练正则线性 L2-SVM。测试错误率 22.48%,刷新(用 1000 标签分类的)当时最优,超过另一为利用无标注数据而改动 CNN 的方法(Zhao et al. 2015)。另外,为验证 DCGAN 所用 CNN 结构本身不是关键贡献因素,我们用相同结构在相同数据上训练纯监督 CNN,并经 64 次超参随机搜索优化(Bergstra & Bengio 2012),验证错误率显著更高,为 28.87%。
| Model | error rate |
|---|---|
| KNN | 77.93% |
| TSVM | 66.55% |
| M1+KNN | 65.63% |
| M1+TSVM | 54.33% |
| M1+M2 | 36.02% |
| SWWAE without dropout | 27.83% |
| SWWAE with dropout | 23.56% |
| DCGAN (ours) + L2-SVM | 22.48% |
| Supervised CNN with the same architecture | 28.87% (validation) |
Table 2: SVHN classification with 1000 labels
| 模型 | 错误率 |
|---|---|
| KNN | 77.93% |
| TSVM | 66.55% |
| M1+KNN | 65.63% |
| M1+TSVM | 54.33% |
| M1+M2 | 36.02% |
| SWWAE without dropout | 27.83% |
| SWWAE with dropout | 23.56% |
| DCGAN(本文)+ L2-SVM | 22.48% |
| 同结构监督 CNN | 28.87%(验证) |
表 2:1000 标签下的 SVHN 分类
6 Investigating and visualizing the internals of the networks
6 探究与可视化网络内部
We investigate the trained generators and discriminators in a variety of ways. We do not do any kind of nearest neighbor search on the training set. Nearest neighbors in pixel or feature space are trivially fooled (Theis et al. 2015) by small image transforms. We also do not use log-likelihood metrics to quantitatively assess the model, as it is a poor (Theis et al. 2015) metric.
我们从多种角度考察训好的生成器与判别器。不做训练集上的最近邻搜索:像素或特征空间最近邻很容易被小变换愚弄(Theis et al. 2015)。也不用对数似然定量评估模型,因其是差指标(Theis et al. 2015)。
6.1 Walking in the latent space
6.1 在潜空间中行走
The first experiment we did was to understand the landscape of the latent space. Walking on the manifold that is learnt can usually tell us about signs of memorization (if there are sharp transitions) and about the way in which the space is hierarchically collapsed. If walking in this latent space results in semantic changes to the image generations (such as objects being added and removed), we can reason that the model has learned relevant and interesting representations. The results are shown in Fig.4.
第一个实验是理解潜空间地貌。在学到的流形上行走,通常能提示是否记忆(若有尖锐跃迁),以及空间如何被层次折叠。若潜空间行走带来生成图像的语义变化(如物体增减),可推断模型学到了相关且有趣的表示。结果见图 4。
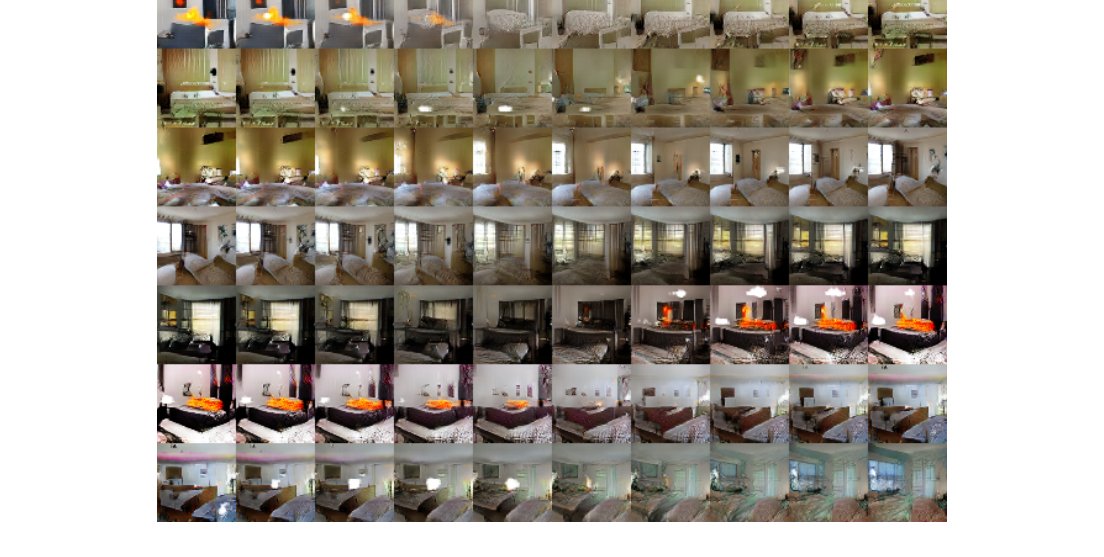
Figure 4: Top rows: Interpolation between a series of 9 random points in show that the space learned has smooth transitions, with every image in the space plausibly looking like a bedroom. In the 6th row, you see a room without a window slowly transforming into a room with a giant window. In the 10th row, you see what appears to be a TV slowly being transformed into a window.
图 4:上排:在 中 9 个随机点之间插值,显示所学空间过渡平滑,空间中每张图都像合理的卧室。第 6 行可见无窗房间慢慢变成带大窗的房间。第 10 行可见像电视的东西慢慢变成窗户。
6.2 Visualizing the Discriminator Features
6.2 可视化判别器特征
Previous work has demonstrated that supervised training of CNNs on large image datasets results in very powerful learned features (Zeiler & Fergus 2014). Additionally, supervised CNNs trained on scene classification learn object detectors (Oquab et al. 2014). We demonstrate that an unsupervised DCGAN trained on a large image dataset can also learn a hierarchy of features that are interesting. Using guided backpropagation as proposed by (Springenberg et al. 2014), we show in Fig.5 that the features learnt by the discriminator activate on typical parts of a bedroom, like beds and windows. For comparison, in the same figure, we give a baseline for randomly initialized features that are not activated on anything that is semantically relevant or interesting.
先前工作表明,在大型图像集上监督训练的 CNN 会学到很强特征(Zeiler & Fergus 2014);场景分类上训的监督 CNN 还会学到物体检测器(Oquab et al. 2014)。我们说明:在大型图像集上无监督训练的 DCGAN 也能学到有趣的层次特征。用 Springenberg et al. 2014 提出的 guided backpropagation,图 5 显示判别器特征会激活在床、窗等典型卧室部件上。同图给出随机初始化特征基线:几乎不对任何语义相关结构激活。
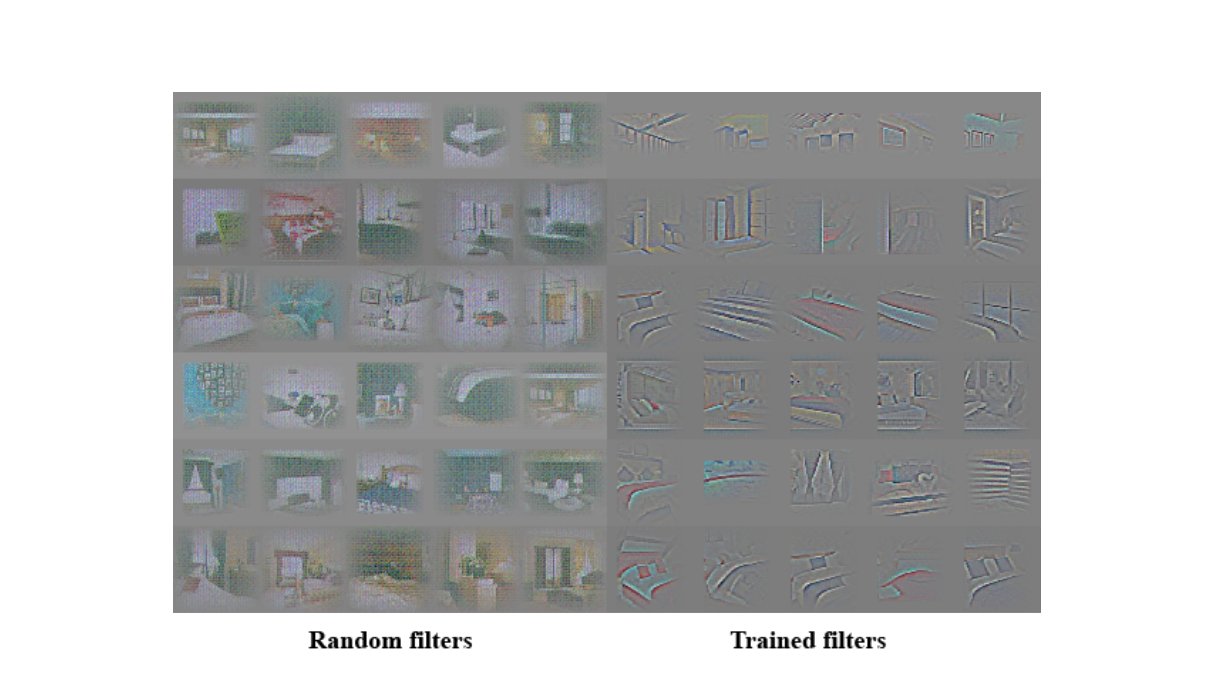
Figure 5: On the right, guided backpropagation visualizations of maximal axis-aligned responses for the first 6 learned convolutional features from the last convolution layer in the discriminator. Notice a significant minority of features respond to beds - the central object in the LSUN bedrooms dataset. On the left is a random filter baseline. Comparing to the previous responses there is little to no discrimination and random structure.
图 5:右侧为判别器最后一层卷积前 6 个学到特征的最大轴对齐响应的 guided backpropagation 可视化。相当一部分特征对床响应——这是 LSUN bedrooms 的中心物体。左侧为随机滤波器基线;相较之下几乎无判别、结构随机。
6.3 Manipulating the Generator Representation
6.3 操纵生成器表示
6.3.1 Forgetting to draw certain objects
In addition to the representations learnt by a discriminator, there is the question of what representations the generator learns. The quality of samples suggest that the generator learns specific object representations for major scene components such as beds, windows, lamps, doors, and miscellaneous furniture. In order to explore the form that these representations take, we conducted an experiment to attempt to remove windows from the generator completely.
6.3.1 忘记绘制某些物体
除判别器学到的表示外,还有生成器学到什么的问题。样本质量暗示生成器为床、窗、灯、门与杂项家具等主要场景部件学到了具体物体表示。为探究这些表示的形态,我们尝试让生成器完全不再画窗户。
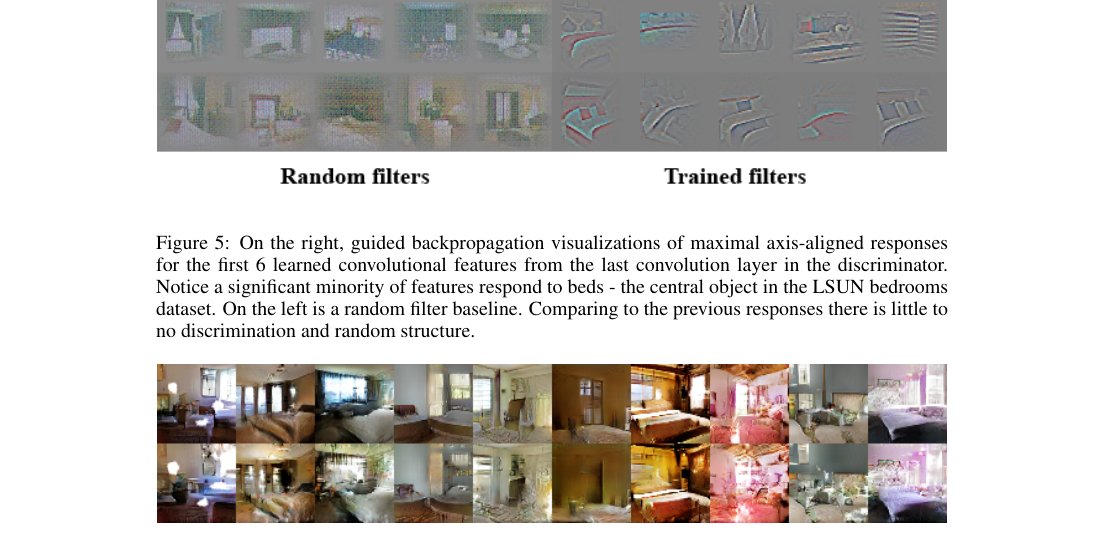
Figure 6: Top row: un-modified samples from model. Bottom row: the same samples generated with dropping out ”window” filters. Some windows are removed, others are transformed into objects with similar visual appearance such as doors and mirrors. Although visual quality decreased, overall scene composition stayed similar, suggesting the generator has done a good job disentangling scene representation from object representation. Extended experiments could be done to remove other objects from the image and modify the objects the generator draws.
图 6:上排:模型未修改样本。下排:去掉「窗户」滤波器后生成的同样样本。部分窗户被移除,另一些变成门、镜子等外观相近物体。视觉质量下降,但整体场景构图仍相似,说明生成器较好地把场景表示与物体表示解开。可扩展实验去移除其他物体或改写生成器绘制的物体。
On 150 samples, 52 window bounding boxes were drawn manually. On the second highest convolution layer features, logistic regression was fit to predict whether a feature activation was on a window (or not), by using the criterion that activations inside the drawn bounding boxes are positives and random samples from the same images are negatives. Using this simple model, all feature maps with weights greater than zero ( 200 in total) were dropped from all spatial locations. Then, random new samples were generated with and without the feature map removal.
在 150 个样本上手动画了 52 个窗户框。在次高卷积层特征上拟合逻辑回归,预测特征激活是否落在窗上:框内激活为正、同图随机采样为负。用该简单模型,把权重大于零的全部特征图(约 200 个)在所有空间位置丢弃。再分别在去掉/不去掉特征图时生成随机新样本。
The generated images with and without the window dropout are shown in Fig.6, and interestingly, the network mostly forgets to draw windows in the bedrooms, replacing them with other objects.
有无窗户 dropout 的生成图见图 6;有趣的是,网络大多忘记在卧室里画窗,改换成其他物体。
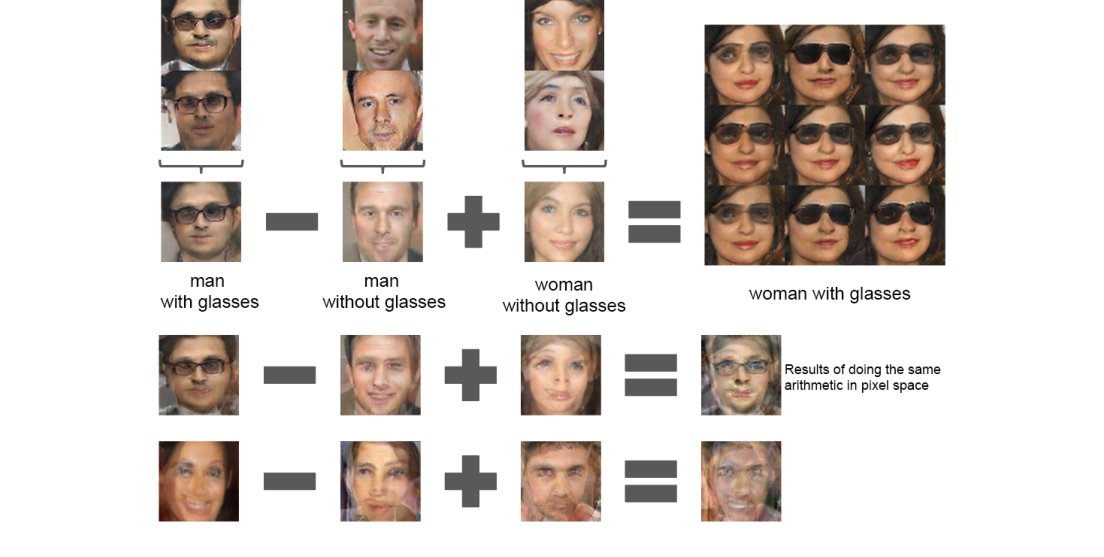
Figure 7: Vector arithmetic for visual concepts. For each column, the vectors of samples are averaged. Arithmetic was then performed on the mean vectors creating a new vector . The center sample on the right hand side is produce by feeding as input to the generator. To demonstrate the interpolation capabilities of the generator, uniform noise sampled with scale +-0.25 was added to to produce the 8 other samples. Applying arithmetic in the input space (bottom two examples) results in noisy overlap due to misalignment.
图 7:视觉概念上的向量算术。每列对样本的 向量取平均,再对均值向量做算术得到新向量 。右侧中间样本由把 送入生成器得到。为展示插值能力,向 加入尺度 ±0.25 的均匀噪声,得到其余 8 个样本。在输入空间做算术(底部两例)会因未对齐而产生嘈杂重叠。
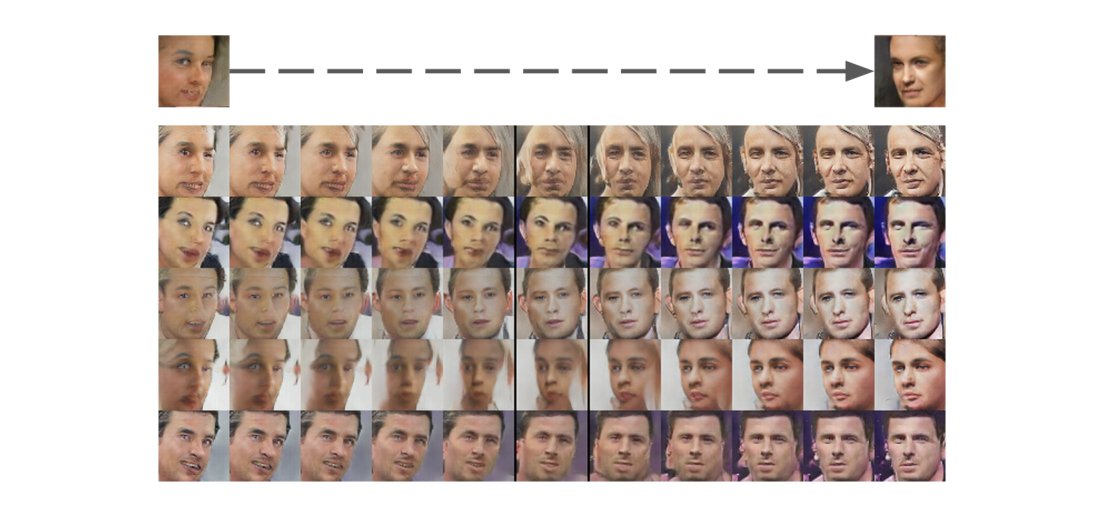
Figure 8: A ”turn” vector was created from four averaged samples of faces looking left vs looking right. By adding interpolations along this axis to random samples we were able to reliably transform their pose.
图 8:由「朝左看」与「朝右看」人脸各四个样本平均,构造「转向」向量。把沿该轴的插值加到随机样本上,可可靠地改变姿态。
6.3.2 Vector arithmetic on face samples
In the context of evaluating learned representations of words (Mikolov et al. 2013) demonstrated that simple arithmetic operations revealed rich linear structure in representation space. One canonical example demonstrated that the vector(”King”) - vector(”Man”) + vector(”Woman”) resulted in a vector whose nearest neighbor was the vector for Queen. We investigated whether similar structure emerges in the representation of our generators. We performed similar arithmetic on the vectors of sets of exemplar samples for visual concepts. Experiments working on only single samples per concept were unstable, but averaging the vector for three examplars showed consistent and stable generations that semantically obeyed the arithmetic. In addition to the object manipulation shown in (Fig. 7), we demonstrate that face pose is also modeled linearly in space (Fig. 8).
6.3.2 在人脸样本上做向量算术
在词表示评估语境下,Mikolov et al. 2013 表明简单算术能揭示表示空间丰富的线性结构。经典例子是 vector("King") − vector("Man") + vector("Woman") 的近邻是 Queen。我们考察生成器的 表示是否出现类似结构:对视觉概念的示例样本集的 向量做类似算术。每个概念只用单样本时不稳定;对三个示例的 取平均后,生成稳定且语义服从算术。除图 7 的物体操纵外,图 8 表明人脸姿态也在 中被线性建模。
These demonstrations suggest interesting applications can be developed using representations learned by our models. It has been previously demonstrated that conditional generative models can learn to convincingly model object attributes like scale, rotation, and position (Dosovitskiy et al. 2014). This is to our knowledge the first demonstration of this occurring in purely unsupervised models. Further exploring and developing the above mentioned vector arithmetic could dramatically reduce the amount of data needed for conditional generative modeling of complex image distributions.
这些演示提示:可用模型学到的 表示开发有趣应用。先前已有条件生成模型令人信服地建模尺度、旋转与位置等物体属性(Dosovitskiy et al. 2014)。据我们所知,这是首次在纯无监督模型中展示这一点。进一步探索上述向量算术,或可大幅减少复杂图像分布条件生成建模所需数据量。
7 Conclusion and Future Work
7 结论与未来工作
We propose a more stable set of architectures for training generative adversarial networks and we give evidence that adversarial networks learn good representations of images for supervised learning and generative modeling. There are still some forms of model instability remaining - we noticed as models are trained longer they sometimes collapse a subset of filters to a single oscillating mode. Further work is needed to tackle this from of instability. We think that extending this framework to other domains such as video (for frame prediction) and audio (pre-trained features for speech synthesis) should be very interesting. Further investigations into the properties of the learnt latent space would be interesting as well.
我们提出更稳定的 GAN 训练结构集合,并给出证据:对抗网络能为监督学习与生成建模学到良好图像表示。仍有某些不稳定形式——训练更久时,有时会有一部分滤波器塌成单一振荡模态,需后续工作处理。把该框架扩展到视频(帧预测)与音频(语音合成的预训练特征)等领域应很有意思;对所学潜空间性质的进一步探究同样值得。
Acknowledgments
We are fortunate and thankful for all the advice and guidance we have received during this work, especially that of Ian Goodfellow, Tobias Springenberg, Arthur Szlam and Durk Kingma. Additionally we’d like to thank all of the folks at indico for providing support, resources, and conversations, especially the two other members of the indico research team, Dan Kuster and Nathan Lintz. Finally, we’d like to thank Nvidia for donating a Titan-X GPU used in this work.
致谢
我们幸运地得到许多建议与指导,尤其感谢 Ian Goodfellow、Tobias Springenberg、Arthur Szlam 与 Durk Kingma。也感谢 indico 提供支持、资源与讨论,尤其研究组另两位成员 Dan Kuster 与 Nathan Lintz。最后感谢 Nvidia 捐赠本工作所用的 Titan-X GPU。
References
参考文献
Bergstra & Bengio (2012) Bergstra, James and Bengio, Yoshua. Random search for hyper-parameter optimization. JMLR , 2012.
Coates & Ng (2011) Coates, Adam and Ng, Andrew. Selecting receptive fields in deep networks. NIPS , 2011.
Coates & Ng (2012) Coates, Adam and Ng, Andrew Y. Learning feature representations with k-means. In Neural Networks: Tricks of the Trade , pp. 561–580. Springer, 2012.
Deng et al. (2009) Deng, Jia, Dong, Wei, Socher, Richard, Li, Li-Jia, Li, Kai, and Fei-Fei, Li. Imagenet: A large-scale hierarchical image database. In Computer Vision and Pattern Recognition, 2009. CVPR 2009. IEEE Conference on , pp. 248–255. IEEE, 2009.
Denton et al. (2015) Denton, Emily, Chintala, Soumith, Szlam, Arthur, and Fergus, Rob. Deep generative image models using a laplacian pyramid of adversarial networks. arXiv preprint arXiv:1506.05751 , 2015.
Dosovitskiy et al. (2014) Dosovitskiy, Alexey, Springenberg, Jost Tobias, and Brox, Thomas. Learning to generate chairs with convolutional neural networks. arXiv preprint arXiv:1411.5928 , 2014.
Dosovitskiy et al. (2015) Dosovitskiy, Alexey, Fischer, Philipp, Springenberg, Jost Tobias, Riedmiller, Martin, and Brox, Thomas. Discriminative unsupervised feature learning with exemplar convolutional neural networks. In Pattern Analysis and Machine Intelligence, IEEE Transactions on , volume 99. IEEE, 2015.
Efros et al. (1999) Efros, Alexei, Leung, Thomas K, et al. Texture synthesis by non-parametric sampling. In Computer Vision, 1999. The Proceedings of the Seventh IEEE International Conference on , volume 2, pp. 1033–1038. IEEE, 1999.
Freeman et al. (2002) Freeman, William T, Jones, Thouis R, and Pasztor, Egon C. Example-based super-resolution. Computer Graphics and Applications, IEEE , 22(2):56–65, 2002.
Goodfellow et al. (2013) Goodfellow, Ian J, Warde-Farley, David, Mirza, Mehdi, Courville, Aaron, and Bengio, Yoshua. Maxout networks. arXiv preprint arXiv:1302.4389 , 2013.
Goodfellow et al. (2014) Goodfellow, Ian J., Pouget-Abadie, Jean, Mirza, Mehdi, Xu, Bing, Warde-Farley, David, Ozair, Sherjil, Courville, Aaron C., and Bengio, Yoshua. Generative adversarial nets. NIPS , 2014.
Gregor et al. (2015) Gregor, Karol, Danihelka, Ivo, Graves, Alex, and Wierstra, Daan. Draw: A recurrent neural network for image generation. arXiv preprint arXiv:1502.04623 , 2015.
Hardt et al. (2015) Hardt, Moritz, Recht, Benjamin, and Singer, Yoram. Train faster, generalize better: Stability of stochastic gradient descent. arXiv preprint arXiv:1509.01240 , 2015.
Hauberg et al. (2015) Hauberg, Søren, Freifeld, Oren, Larsen, Anders Boesen Lindbo, Fisher III, John W., and Hansen, Lars Kair. Dreaming more data: Class-dependent distributions over diffeomorphisms for learned data augmentation. arXiv preprint arXiv:1510.02795 , 2015.
Hays & Efros (2007) Hays, James and Efros, Alexei A. Scene completion using millions of photographs. ACM Transactions on Graphics (TOG) , 26(3):4, 2007.
Ioffe & Szegedy (2015) Ioffe, Sergey and Szegedy, Christian. Batch normalization: Accelerating deep network training by reducing internal covariate shift. arXiv preprint arXiv:1502.03167 , 2015.
Kingma & Ba (2014) Kingma, Diederik P and Ba, Jimmy Lei. Adam: A method for stochastic optimization. arXiv preprint arXiv:1412.6980 , 2014.
Kingma & Welling (2013) Kingma, Diederik P and Welling, Max. Auto-encoding variational bayes. arXiv preprint arXiv:1312.6114 , 2013.
Lee et al. (2009) Lee, Honglak, Grosse, Roger, Ranganath, Rajesh, and Ng, Andrew Y. Convolutional deep belief networks for scalable unsupervised learning of hierarchical representations. In Proceedings of the 26th Annual International Conference on Machine Learning , pp. 609–616. ACM, 2009.
Loosli et al. (2007) Loosli, Gaëlle, Canu, Stéphane, and Bottou, Léon. Training invariant support vector machines using selective sampling. In Bottou, Léon, Chapelle, Olivier, DeCoste, Dennis, and Weston, Jason (eds.), Large Scale Kernel Machines , pp. 301–320. MIT Press, Cambridge, MA., 2007. URL http://leon.bottou.org/papers/loosli-canu-bottou-2006 .
Maas et al. (2013) Maas, Andrew L, Hannun, Awni Y, and Ng, Andrew Y. Rectifier nonlinearities improve neural network acoustic models. In Proc. ICML , volume 30, 2013.
Mikolov et al. (2013) Mikolov, Tomas, Sutskever, Ilya, Chen, Kai, Corrado, Greg S, and Dean, Jeff. Distributed representations of words and phrases and their compositionality. In Advances in neural information processing systems , pp. 3111–3119, 2013.
(23) Mordvintsev, Alexander, Olah, Christopher, and Tyka, Mike. Inceptionism : Going deeper into neural networks. http://googleresearch.blogspot.com/2015/06/inceptionism-going-deeper-into-neural.html . Accessed: 2015-06-17.
Nair & Hinton (2010) Nair, Vinod and Hinton, Geoffrey E. Rectified linear units improve restricted boltzmann machines. In Proceedings of the 27th International Conference on Machine Learning (ICML-10) , pp. 807–814, 2010.
Netzer et al. (2011) Netzer, Yuval, Wang, Tao, Coates, Adam, Bissacco, Alessandro, Wu, Bo, and Ng, Andrew Y. Reading digits in natural images with unsupervised feature learning. In NIPS workshop on deep learning and unsupervised feature learning , volume 2011, pp. 5. Granada, Spain, 2011.
Oquab et al. (2014) Oquab, M., Bottou, L., Laptev, I., and Sivic, J. Learning and transferring mid-level image representations using convolutional neural networks. In CVPR , 2014.
Portilla & Simoncelli (2000) Portilla, Javier and Simoncelli, Eero P. A parametric texture model based on joint statistics of complex wavelet coefficients. International Journal of Computer Vision , 40(1):49–70, 2000.
Rasmus et al. (2015) Rasmus, Antti, Valpola, Harri, Honkala, Mikko, Berglund, Mathias, and Raiko, Tapani. Semi-supervised learning with ladder network. arXiv preprint arXiv:1507.02672 , 2015.
Sohl-Dickstein et al. (2015) Sohl-Dickstein, Jascha, Weiss, Eric A, Maheswaranathan, Niru, and Ganguli, Surya. Deep unsupervised learning using nonequilibrium thermodynamics. arXiv preprint arXiv:1503.03585 , 2015.
Springenberg et al. (2014) Springenberg, Jost Tobias, Dosovitskiy, Alexey, Brox, Thomas, and Riedmiller, Martin. Striving for simplicity: The all convolutional net. arXiv preprint arXiv:1412.6806 , 2014.
Srivastava et al. (2014) Srivastava, Rupesh Kumar, Masci, Jonathan, Gomez, Faustino, and Schmidhuber, Jürgen. Understanding locally competitive networks. arXiv preprint arXiv:1410.1165 , 2014.
Theis et al. (2015) Theis, L., van den Oord, A., and Bethge, M. A note on the evaluation of generative models. arXiv:1511.01844, Nov 2015. URL http://arxiv.org/abs/1511.01844 .
Vincent et al. (2010) Vincent, Pascal, Larochelle, Hugo, Lajoie, Isabelle, Bengio, Yoshua, and Manzagol, Pierre-Antoine. Stacked denoising autoencoders: Learning useful representations in a deep network with a local denoising criterion. The Journal of Machine Learning Research , 11:3371–3408, 2010.
Xu et al. (2015) Xu, Bing, Wang, Naiyan, Chen, Tianqi, and Li, Mu. Empirical evaluation of rectified activations in convolutional network. arXiv preprint arXiv:1505.00853 , 2015.
Yu et al. (2015) Yu, Fisher, Zhang, Yinda, Song, Shuran, Seff, Ari, and Xiao, Jianxiong. Construction of a large-scale image dataset using deep learning with humans in the loop. arXiv preprint arXiv:1506.03365 , 2015.
Zeiler & Fergus (2014) Zeiler, Matthew D and Fergus, Rob. Visualizing and understanding convolutional networks. In Computer Vision–ECCV 2014 , pp. 818–833. Springer, 2014.
Zhao et al. (2015) Zhao, Junbo, Mathieu, Michael, Goroshin, Ross, and Lecun, Yann. Stacked what-where auto-encoders. arXiv preprint arXiv:1506.02351 , 2015.
8 Supplementary Material
8 补充材料
8.1 Evaluating DCGANs capability to capture data distributions
8.1 评估 DCGAN 刻画数据分布的能力
We propose to apply standard classification metrics to a conditional version of our model, evaluating the conditional distributions learned. We trained a DCGAN on MNIST (splitting off a 10K validation set) as well as a permutation invariant GAN baseline and evaluated the models using a nearest neighbor classifier comparing real data to a set of generated conditional samples. We found that removing the scale and bias parameters from batchnorm produced better results for both models. We speculate that the noise introduced by batchnorm helps the generative models to better explore and generate from the underlying data distribution. The results are shown in Table 3 which compares our models with other techniques. The DCGAN model achieves the same test error as a nearest neighbor classifier fitted on the training dataset - suggesting the DCGAN model has done a superb job at modeling the conditional distributions of this dataset. At one million samples per class, the DCGAN model outperforms InfiMNIST (Loosli et al. 2007), a hand developed data augmentation pipeline which uses translations and elastic deformations of training examples. The DCGAN is competitive with a probabilistic generative data augmentation technique utilizing learned per class transformations (Hauberg et al. 2015) while being more general as it directly models the data instead of transformations of the data.
我们建议把标准分类指标用到条件版模型上,评估所学条件分布。在 MNIST(划出 10K 验证集)上训练 DCGAN,以及置换不变的 GAN 基线;用最近邻分类器比较真实数据与一组条件生成样本来评估。发现去掉 batchnorm 的尺度与偏置参数对两模型都更好。我们推测 batchnorm 引入的噪声有助于生成模型更好地探索并生成底层数据分布。结果见表 3。DCGAN 测试错误率与在训练集上拟合的最近邻分类器相同——说明它对条件分布建模出色。每类一百万样本时,DCGAN 超过 InfiMNIST(Loosli et al. 2007)这一用手写平移与弹性形变做增强的管线。相对利用每类学到的变换做概率生成增强的方法(Hauberg et al. 2015),DCGAN 具竞争力,且更一般:它直接建模数据而非数据的变换。
| Model | Test Error @50K samples | Test Error @10M samples |
|---|---|---|
| AlignMNIST | - | 1.4% |
| InfiMNIST | - | 2.6% |
| Real Data | 3.1% | - |
| GAN | 6.28% | 5.65% |
| DCGAN (ours) | 2.98% | 1.48% |
Table 3: Nearest neighbor classification results.
| 模型 | 测试错误 @50K 样本 | 测试错误 @10M 样本 |
|---|---|---|
| AlignMNIST | - | 1.4% |
| InfiMNIST | - | 2.6% |
| Real Data | 3.1% | - |
| GAN | 6.28% | 5.65% |
| DCGAN(本文) | 2.98% | 1.48% |
表 3:最近邻分类结果。
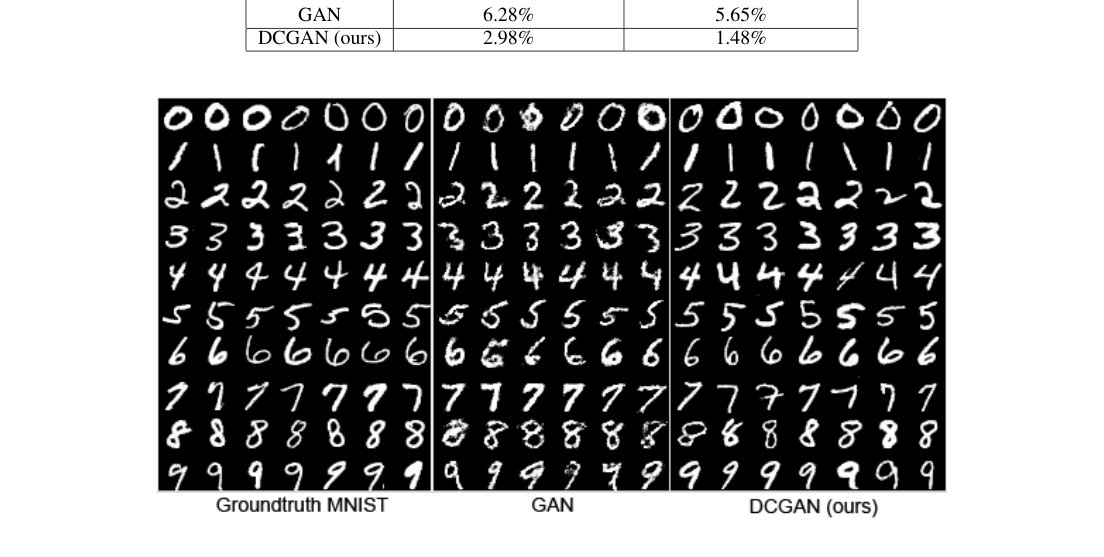
Figure 9: Side-by-side illustration of (from left-to-right) the MNIST dataset, generations from a baseline GAN, and generations from our DCGAN .
图 9:并排示意(从左到右)MNIST 数据集、基线 GAN 生成、以及我们的 DCGAN 生成。
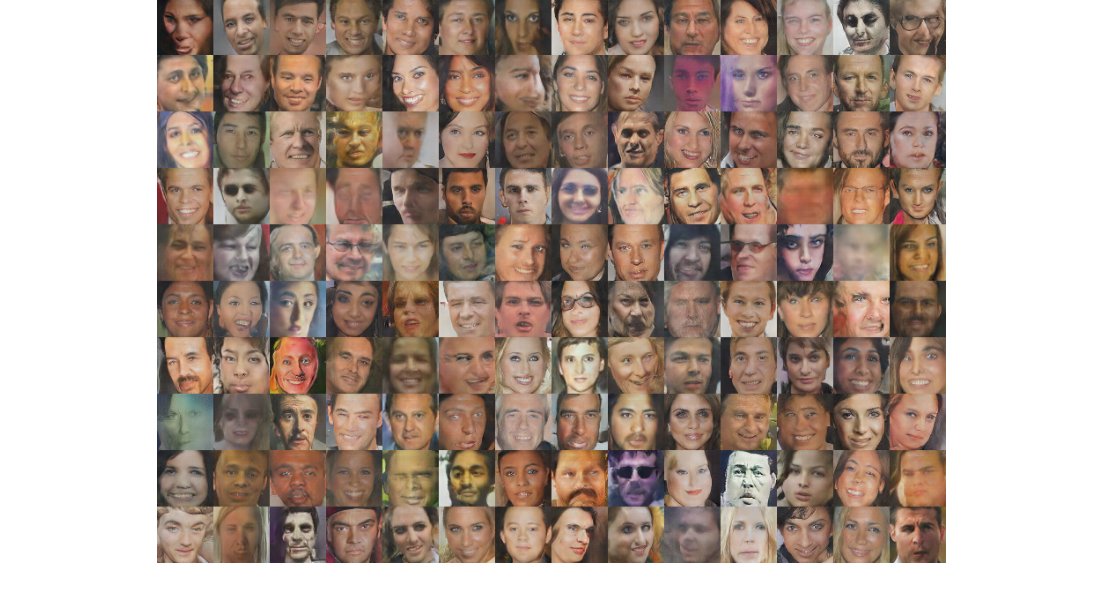
Figure 10: More face generations from our Face DCGAN.
图 10:人脸 DCGAN 的更多生成样例。
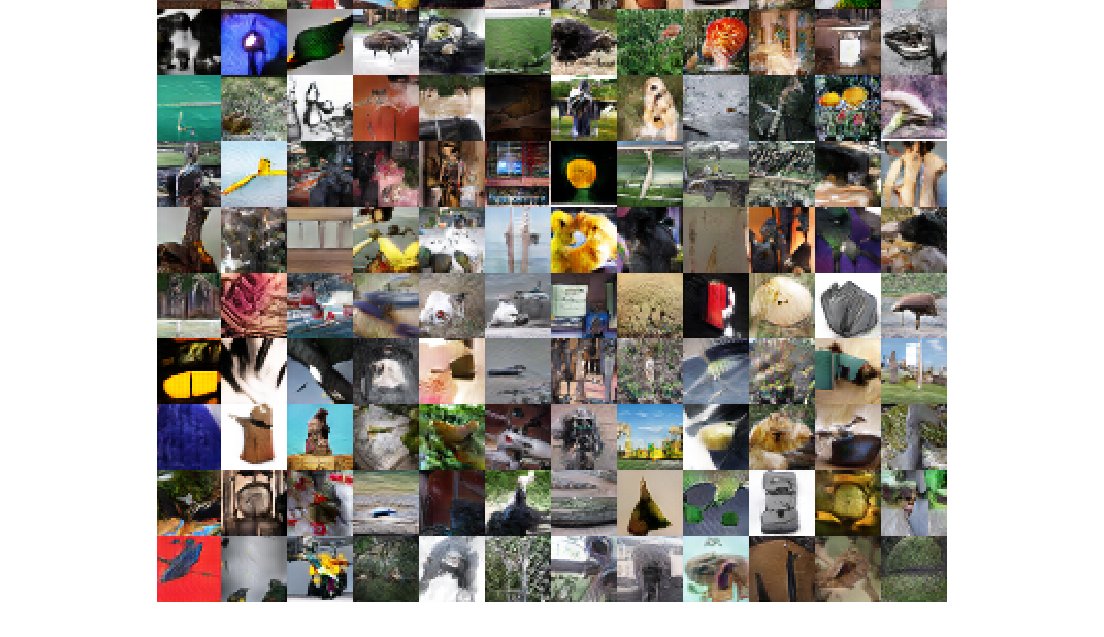
Figure 11: Generations of a DCGAN that was trained on the Imagenet-1k dataset.
图 11:在 Imagenet-1k 上训练的 DCGAN 生成样例。