Zero-Shot Text-to-Image Generation
Zero-Shot Text-to-Image Generation
零样本文生图
Aditya Ramesh Affiliation: OpenAI, San Francisco, California, United States Correspondence to: _@adityaramesh.com Mikhail Pavlov Affiliation: OpenAI, San Francisco, California, United States Gabriel Goh Affiliation: OpenAI, San Francisco, California, United States Scott Gray Affiliation: OpenAI, San Francisco, California, United States Chelsea Voss Affiliation: OpenAI, San Francisco, California, United States Alec Radford Affiliation: OpenAI, San Francisco, California, United States Mark Chen Affiliation: OpenAI, San Francisco, California, United States Ilya Sutskever Affiliation: OpenAI, San Francisco, California, United States
Abstract
摘要
Text-to-image generation has traditionally focused on finding better modeling assumptions for training on a fixed dataset. These assumptions might involve complex architectures, auxiliary losses, or side information such as object part labels or segmentation masks supplied during training. We describe a simple approach for this task based on a transformer that autoregressively models the text and image tokens as a single stream of data. With sufficient data and scale, our approach is competitive with previous domain-specific models when evaluated in a zero-shot fashion.
文生图传统上关注:在固定数据集上训练时,如何找到更好的建模假设。这些假设可能涉及复杂架构、辅助损失,或训练时提供的物体部件标签、分割掩码等旁路信息。我们描述一种简单做法:用 transformer 把文本与图像 token 当作单一数据流做自回归建模。只要数据与规模足够,该方法在零样本评测下可与先前面向特定领域的模型相竞争。
1 Introduction
1 引言
Keywords:
Modern machine learning approaches to text to image synthesis started with the work of Mansimov et al. 2015, who showed that the DRAW Gregor et al. 2015 generative model, when extended to condition on image captions, could also generate novel visual scenes. Reed et al. 2016b later demonstrated that using a generative adversarial network (Goodfellow et al. 2014), rather than a recurrent variational auto-encoder, improved image fidelity. Reed et al. 2016b showed that this system could not only generate objects with recognizable properties, but also could zero-shot generalize to held-out categories.
关键词:
现代机器学习意义上的文生图,始于 Mansimov et al. 2015:他们表明,把 DRAW(Gregor et al. 2015)生成模型扩展到以图像描述为条件后,也能生成新的视觉场景。Reed et al. 2016b 随后表明,用生成对抗网络(Goodfellow et al. 2014)代替循环变分自编码器,可提升图像保真度。Reed et al. 2016b 还表明,该系统不仅能生成可识别属性的物体,还能对留出类别做零样本泛化。
Over the next few years, progress continued using a combination of methods. These include improving the generative model architecture with modifications like multi-scale generators (Zhang et al. 2017; Zhang et al. 2018), integrating attention and auxiliary losses (Xu et al. 2018), and leveraging additional sources of conditioning information beyond just text (Reed et al. 2016a; Li et al. 2019; Koh et al. 2021).
此后数年,进展来自多种方法的组合:用多尺度生成器等改动改进生成模型架构(Zhang et al. 2017;Zhang et al. 2018),引入注意力与辅助损失(Xu et al. 2018),以及在文本之外利用更多条件信息(Reed et al. 2016a;Li et al. 2019;Koh et al. 2021)。
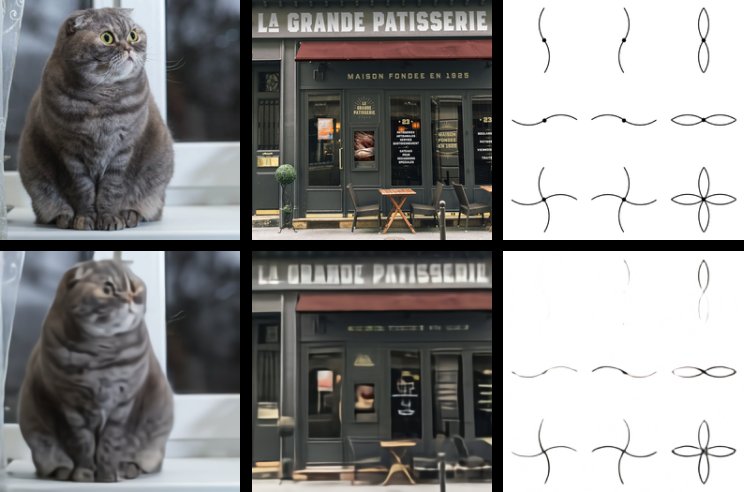
Figure 1: Comparison of original images (top) and reconstructions from the discrete VAE (bottom). The encoder downsamples the spatial resolution by a factor of 8. While details (e.g., the texture of the cat’s fur, the writing on the storefront, and the thin lines in the illustration) are sometimes lost or distorted, the main features of the image are still typically recognizable. We use a large vocabulary size of 8192 to mitigate the loss of information.
图 1:原图(上)与离散 VAE 重建(下)的对比。编码器把空间分辨率下采样 8 倍。细节(如猫毛纹理、店招文字、插图细线)有时会丢失或变形,但图像主要特征通常仍可辨认。我们采用 8192 的大词表以减轻信息损失。
Separately, Nguyen et al. 2017 propose an energy-based framework for conditional image generation that obtained a large improvement in sample quality relative to contemporary methods. Their approach can incorporate pretrained discriminative models, and they show that it is capable of performing text-to-image generation when applied to a captioning model pretrained on MS-COCO. More recently, Cho et al. 2020 also propose a method that involves optimizing the input to a pretrained cross-modal masked language model. While significant increases in visual fidelity have occurred as a result of the work since Mansimov et al. 2015, samples can still suffer from severe artifacts such as object distortion, illogical object placement, or unnatural blending of foreground and background elements.
另一方面,Nguyen et al. 2017 提出条件图像生成的能量框架,相对当时方法在样本质量上有大幅提升。其做法可接入预训练判别模型,并表明应用到在 MS-COCO 上预训练的描述模型时,可做文生图。更近的 Cho et al. 2020 也提出优化预训练跨模态掩码语言模型输入的方法。自 Mansimov et al. 2015 以来视觉保真度虽显著提升,样本仍常出现严重伪影:物体扭曲、摆放不合逻辑,或前景与背景不自然融合。
Recent advances fueled by large-scale generative models suggest a possible route for further improvements. Specifically, when compute, model size, and data are scaled carefully, autoregressive transformers (Vaswani et al. 2017) have achieved impressive results in several domains such as text (Radford et al. 2019), images (Chen et al. 2020), and audio (Dhariwal et al. 2020).
大规模生成模型的进展提示了另一条改进路径。具体而言,当算力、模型规模与数据被谨慎放大时,自回归 transformer(Vaswani et al. 2017)已在文本(Radford et al. 2019)、图像(Chen et al. 2020)与音频(Dhariwal et al. 2020)等多个领域取得亮眼结果。
(a) a tapir made of accordion. a tapir with the texture of an accordion.
By comparison, text-to-image generation has typically been evaluated on relatively small datasets such as MS-COCO and CUB-200 (Welinder et al. 2010). Could dataset size and model size be the limiting factor of current approaches? In this work, we demonstrate that training a 12-billion parameter autoregressive transformer on 250 million image-text pairs collected from the internet results in a flexible, high fidelity generative model of images controllable through natural language.
相比之下,文生图通常在相对小的数据集上评测,如 MS-COCO 与 CUB-200(Welinder et al. 2010)。会不会是数据集规模与模型规模限制了现有方法?本文表明:在从互联网收集的 2.5 亿图文对上训练 120 亿参数的自回归 transformer,可得到灵活、高保真、可用自然语言控制的图像生成模型。
The resulting system achieves high quality image generation on the popular MS-COCO dataset zero-shot, without using any of the training labels. It is preferred over prior work trained on the dataset by human evaluators 90% of the time. We also find that it is able to perform complex tasks such as image-to-image translation at a rudimentary level. This previously required custom approaches (Isola et al. 2017), rather emerging as a capability of a single, large generative model.
所得系统在流行的 MS-COCO 数据集上做零样本高质量图像生成,且不使用任何该集训练标签。人工评测中,它有 90% 的时间被偏好于在该数据集上训练的先前工作。我们还发现它能以初步水平完成图到图翻译等复杂任务——这类任务以往需要定制方法(Isola et al. 2017),如今作为单一大规模生成模型的能力自然涌现。
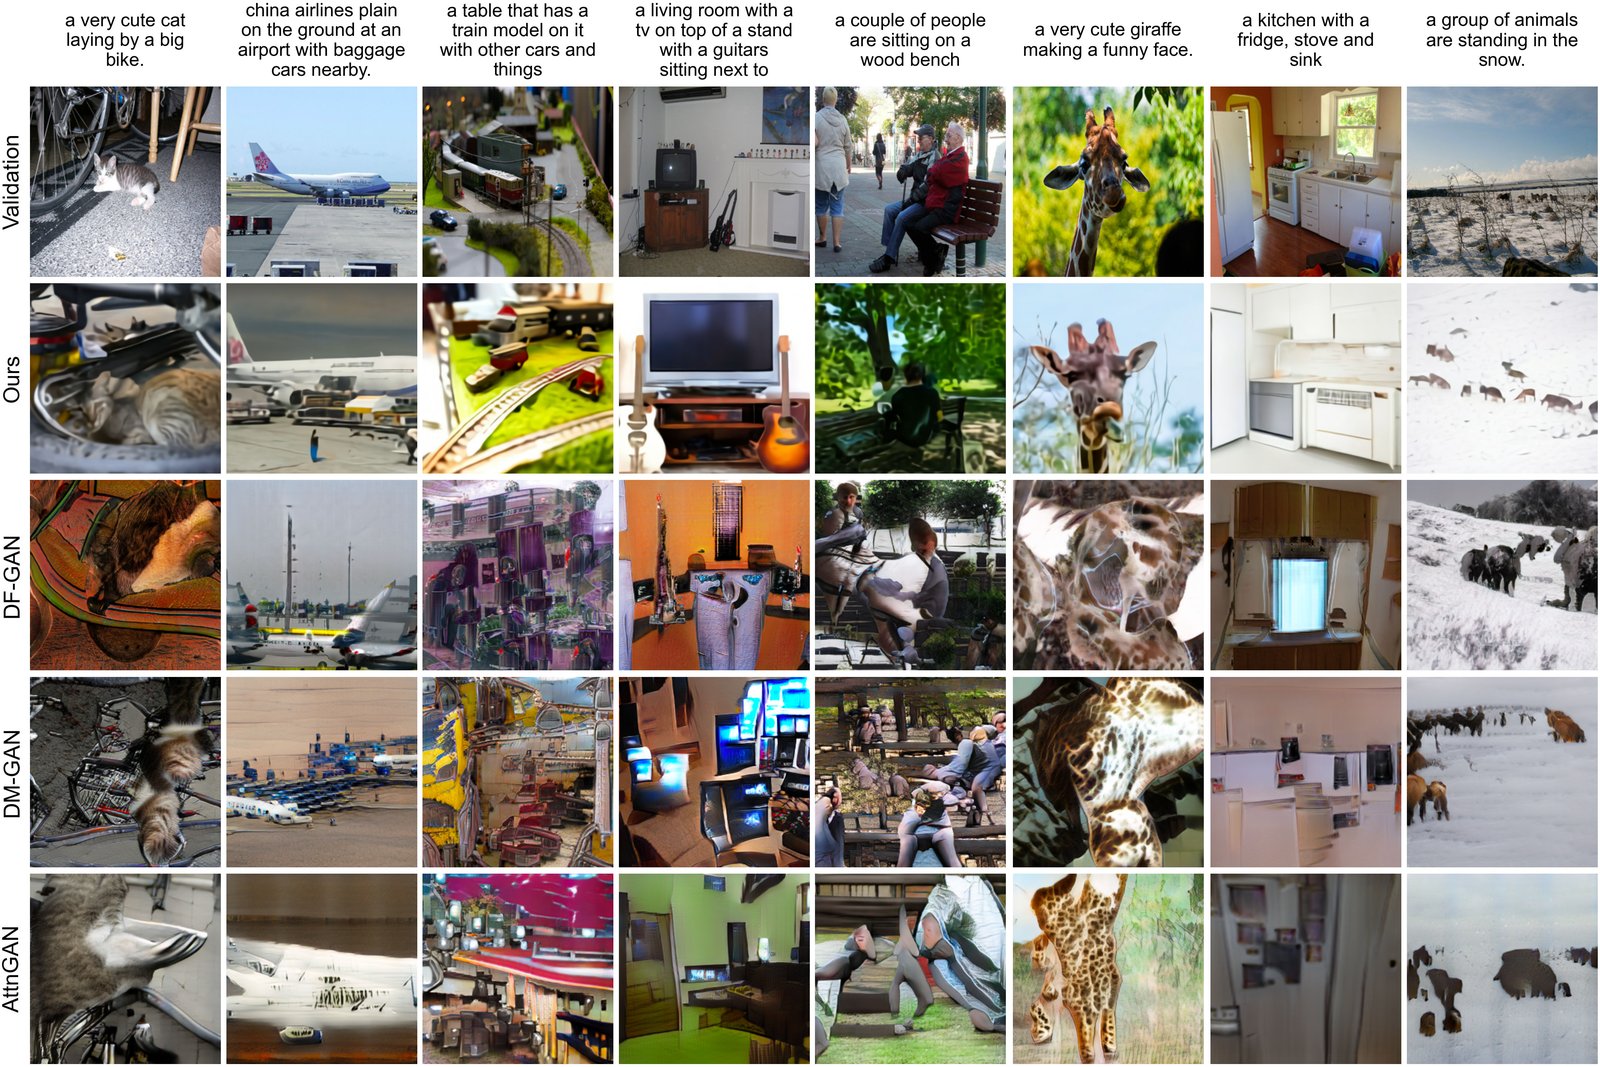
Figure 3: Comparison of samples from our model to those from prior approaches on captions from MS-COCO. Each of our model samples is the best of 512 as ranked by the contrastive model. We do not use any manual cherrypicking with the selection of either the captions or the samples from any of the models.
图 3:在 MS-COCO 描述上,将我们模型的样本与先前方法对比。我们模型的每个样本均为对比模型在 512 个候选中排名最优者。对描述的选取以及任一模型的样本,均不做人工精挑。
2 Method
2 方法
Our goal is to train a transformer (Vaswani et al. 2017) to autoregressively model the text and image tokens as a single stream of data. However, using pixels directly as image tokens would require an inordinate amount of memory for high-resolution images. Likelihood objectives tend to prioritize modeling short-range dependencies between pixels (Salimans et al. 2017), so much of the modeling capacity would be spent capturing high-frequency details instead of the low-frequency structure that makes objects visually recognizable to us.
目标是训练一个 transformer(Vaswani et al. 2017),把文本与图像 token 当作单一数据流做自回归建模。但若直接把像素当图像 token,高分辨率图像会消耗过量内存。似然目标往往优先建模像素间的短程依赖(Salimans et al. 2017),大量建模容量会花在捕获高频细节上,而不是让物体在视觉上可辨认的低频结构。
We address these issues by using a two-stage training procedure, similar to (Oord et al. 2017; Razavi et al. 2019):
我们用两阶段训练应对这些问题,做法类似(Oord et al. 2017;Razavi et al. 2019):
- • Stage 1. We train a discrete variational autoencoder (dVAE)[^1] to compress each RGB image into a grid of image tokens, each element of which can assume possible values. This reduces the context size of the transformer by a factor of without a large degradation in visual quality (see Figure 1).
- • 阶段 1。 训练离散变分自编码器(dVAE)[^1],把每张 RGB 图像压缩为 的图像 token 网格,每个元素可取 个可能值。这使 transformer 上下文长度缩小 倍,而视觉质量不致大幅下降(见图 1)。
- • Stage 2. We concatenate up to 256 BPE-encoded text tokens with the image tokens, and train an autoregressive transformer to model the joint distribution over the text and image tokens.
- • 阶段 2。 将最多 256 个 BPE 编码的文本 token 与 个图像 token 拼接,训练自回归 transformer,对文本与图像 token 的联合分布建模。
The overall procedure can be viewed as maximizing the evidence lower bound (ELB) (Kingma & Welling 2013; Rezende et al. 2014) on the joint likelihood of the model distribution over images , captions , and the tokens for the encoded RGB image. We model this distribution using the factorization , which yields the lower bound
整体流程可视为最大化模型分布在图像 、描述 以及编码后 RGB 图像的 token 上的联合似然证据下界(ELB)(Kingma & Welling 2013;Rezende et al. 2014)。我们用因式分解 建模该分布,由此得到下界
$$\ln p_{\theta,\psi}(x,y)\geqslant!!!!!!!!\mathop{\mathbb{E}}{\begin{subarray}{c}\vskip 0.28453pt\
z\sim q{\phi}(z,|,x)\end{subarray}}!!!!!!!!\big(\ln p_{\theta}(x,|,y,z);-\
\beta,D_{\mathrm{KL}}(q_{\phi}(y,z,|,x),p_{\psi}(y,z))\big), \tag{1}$$
where:
其中:
- • denotes the distribution over the image tokens generated by the dVAE encoder given the RGB image [^2];
- • 表示给定 RGB 图像 时,由 dVAE 编码器产生的 图像 token 分布[^2];
- • denotes the distribution over the RGB images generated by the dVAE decoder given the image tokens; and
- • 表示给定图像 token 时,由 dVAE 解码器产生的 RGB 图像分布;以及
- • denotes the joint distribution over the text and image tokens modeled by the transformer.
- • 表示由 transformer 建模的文本与图像 token 联合分布。
Note that the bound only holds for , while in practice we find it helpful to use larger values (Higgins et al. 2016). The following subsections describe both stages in further detail.[^3]
注意该下界仅在 时严格成立,实践中我们发现用更大的值更有帮助(Higgins et al. 2016)。以下两小节分别详述两个阶段。[^3]
2.1 Stage One: Learning the Visual Codebook
2.1 第一阶段:学习视觉码本
In the first stage of training, we maximize the ELB with respect to and , which corresponds to training a dVAE on the images alone. We set the initial prior to the uniform categorical distribution over the 8192$$ codebook vectors, and to be categorical distributions parameterized by the logits at the same spatial position in the grid output by the encoder.
训练第一阶段对 与 最大化 ELB,等价于仅在图像上训练 dVAE。我们将初始先验 设为对 8192$$ 个码本向量的均匀类别分布,并将 设为类别分布,其参数为编码器输出的 网格上同一空间位置的 个 logit。
The ELB now becomes difficult to optimize: as is a discrete distribution, and we cannot use the reparameterization gradient to maximize it. Oord et al. 2017; Razavi et al. 2019 address this using an online cluster assignment procedure coupled with the straight-through estimator (Bengio et al. 2013). We instead use the gumbel-softmax relaxation (Jang et al. 2016; Maddison et al. 2016), replacing the expectation over with one over , where the relaxation becomes tight as the temperature . The likelihood for is evaluated using the log-laplace distribution (see Appendix A.3 for a derivation).
此时 ELB 变得难优化:因为 是离散分布,无法用重参数化梯度最大化。Oord et al. 2017;Razavi et al. 2019 用在线聚类指派配合直通估计器(Bengio et al. 2013)处理。我们改为使用 gumbel-softmax 松弛(Jang et al. 2016;Maddison et al. 2016),把对 的期望换成对 的期望,当温度 时松弛变紧。 的似然用 log-laplace 分布评估(推导见附录 A.3)。
The relaxed ELB is maximized using Adam (Kingma & Ba 2014) with exponentially weighted iterate averaging. Appendix A.2 gives a complete description of the hyperparameters, but we found the following to be especially important for stable training:
松弛后的 ELB 用 Adam(Kingma & Ba 2014)并配合指数加权迭代平均来最大化。附录 A.2 给出完整超参;我们发现以下几点对稳定训练尤为重要:
- • Specific annealing schedules for the relaxation temperature and step size. We found that annealing to was sufficient to close the gap between the relaxed validation ELB and the true validation ELB with intsead of .
- • 对松弛温度与步长使用特定退火日程。我们发现把 退火到 ,足以弥合松弛验证 ELB 与用 而非 的真实验证 ELB 之间的差距。
- • The use of convolutions at the end of the encoder and the beginning of the decoder. We found that reducing the receptive field size for the convolutions around the relaxation led to it generalizing better to the true ELB.
- • 在编码器末尾与解码器开头使用 卷积。我们发现缩小松弛附近卷积的感受野,有助于更好地泛化到真实 ELB。
- • Multiplication of the outgoing activations from the encoder and decoder resblocks by a small constant, to ensure stable training at initialization.
- • 将编码器与解码器残差块的出射激活乘以一个小常数,以保证初始化时训练稳定。
We also found that increasing the KL weight to promotes better codebook usage and ultimately leads to a smaller reconstruction error at the end of training.[^4]
我们还发现,把 KL 权重提高到 能促进更好的码本利用率,并最终在训练结束时得到更小的重建误差。[^4]
2.2 Stage Two: Learning the Prior
2.2 第二阶段:学习先验
In the second stage, we fix and , and learn the prior distribution over the text and image tokens by maximizing the ELB with respect to . Here, is represented by a 12-billion parameter sparse transformer (Child et al. 2019).
第二阶段固定 与 ,通过对 最大化 ELB 来学习文本与图像 token 上的先验分布。此处 由一个 120 亿参数的稀疏 transformer(Child et al. 2019)表示。
Given a text-image pair, we BPE-encode (Sennrich et al. 2015) the lowercased caption using at most 256 tokens[^5] with vocabulary size , and encode the image using tokens with vocabulary size . The image tokens are obtained using argmax sampling from the dVAE encoder logits, without adding any gumbel noise.[^6] Finally, the text and image tokens are concatenated and modeled autoregressively as a single stream of data.
给定一对图文,我们对小写描述做 BPE 编码(Sennrich et al. 2015),最多 256 个 token[^5],词表大小 ;图像则编码为 个 token,词表大小 。图像 token 由 dVAE 编码器 logit 经 argmax 采样得到,不加 gumbel 噪声。[^6] 最后将文本与图像 token 拼接,作为单一数据流做自回归建模。
The transformer is a decoder-only model in which each image token can attend to all text tokens in any one of its 64 self-attention layers. The full architecture is described in Appendix B.1. There are three different kinds of self-attention masks used in the model. The part of the attention masks corresponding to the text-to-text attention is the standard causal mask, and the part for the image-to-image attention uses either a row, column, or convolutional attention mask.[^7]
该 transformer 为仅解码器结构:任一图像 token 可在其 64 层自注意力中的任一层关注全部文本 token。完整架构见附录 B.1。模型使用三种自注意力掩码:对应文本–文本注意力的部分是标准因果掩码;图像–图像注意力部分则使用行、列或卷积注意力掩码。[^7]
We limit the length of a text caption to 256 tokens, though it is not totally clear what to do for the “padding” positions in between the last text token and the start-of-image token. One option is to set the logits for these tokens to in the self-attention operations. Instead, we opt to learn a special padding token separately for each of the 256 text positions. This token is used only when no text token is available. In preliminary experiments on Conceptual Captions (Sharma et al. 2018), we found that this resulted in higher validation loss, but better performance on out-of-distribution captions.
我们将文本描述长度限制为 256 个 token,但最后一个文本 token 与图像起始 token 之间的「填充」位置如何处理并不完全清楚。一种做法是在自注意力中把这些位置的 logit 设为 。我们改为对 256 个文本位置各自学习一个特殊填充 token,仅在没有文本 token 可用时使用。在 Conceptual Captions(Sharma et al. 2018)上的初步实验中,我们发现这会提高验证损失,但对分布外描述的表现更好。
We normalize the cross-entropy losses for the text and image tokens by the total number of each kind in a batch of data. Since we are primarily interested in image modeling, we multiply the cross-entropy loss for the text by and the cross-entropy loss for the image by . The objective is optimized using Adam with exponentially weighted iterate averaging; Appendix B.2 describes the training procedure in more detail. We reserved about images for validation, and found no signs of overfitting at convergence.
我们对文本与图像 token 的交叉熵损失分别按批次中各自的总数归一化。由于主要关心图像建模,将文本交叉熵乘以 、图像交叉熵乘以 。目标用 Adam 与指数加权迭代平均优化;附录 B.2 更详细描述训练过程。我们留出约 张图像做验证,收敛时未见过拟合迹象。
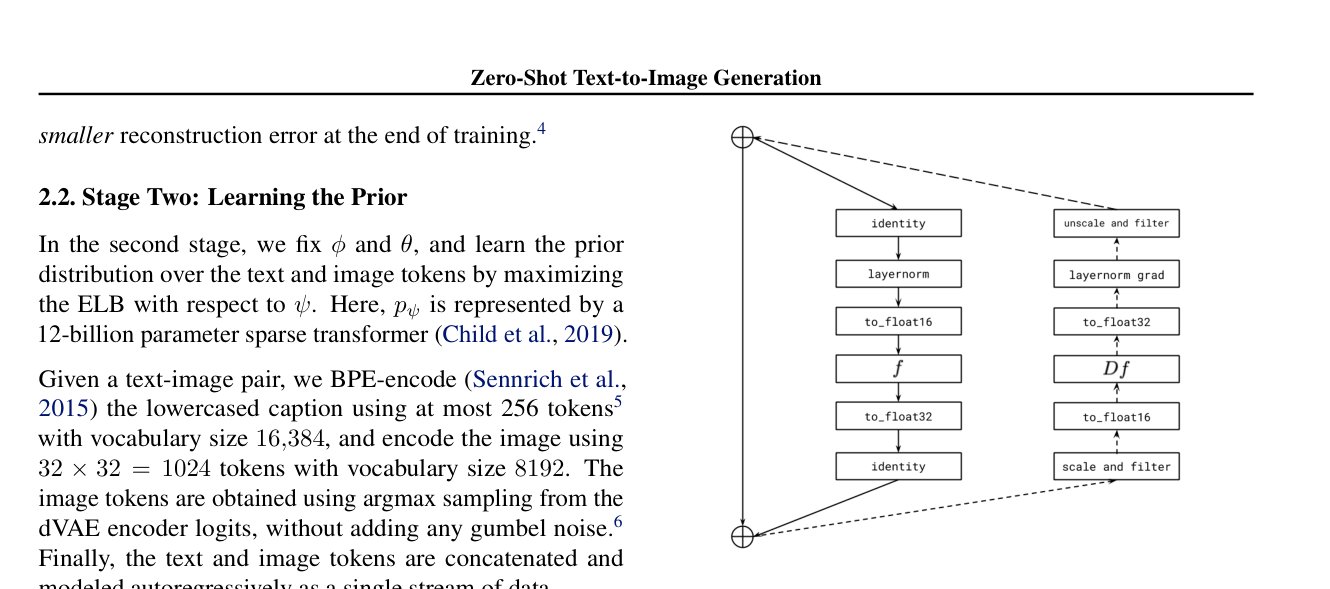
Figure 4: Illustration of per-resblock gradient scaling for a transformer resblock. The solid line indicates the sequence of operations for forward propagation, and the dashed line the sequence of operations for backpropagation. We scale the incoming gradient for each resblock by its gradient scale, and unscale the outgoing gradient before it is added to the sum of the gradients from the successive resblocks. The activations and gradients along the identity path are stored in 32-bit precision. The “filter” operation sets all Inf and NaN values in the activation gradient to zero. Without this, a nonfinite event in the current resblock would cause the gradient scales for all preceding resblocks to unnecessarily drop, thereby resulting in underflow.
图 4:transformer 残差块的逐残差块梯度缩放示意。实线为前向传播运算序列,虚线为反向传播运算序列。我们对每个残差块的入射梯度按其梯度缩放系数缩放,并在出射梯度加到后续残差块梯度之和以前取消缩放。恒等路径上的激活与梯度以 32 位精度存储。「过滤」操作把激活梯度中的全部 Inf 与 NaN 置零。否则,当前残差块的一次非有限事件会不必要地拉低所有先前残差块的梯度缩放,从而导致下溢。
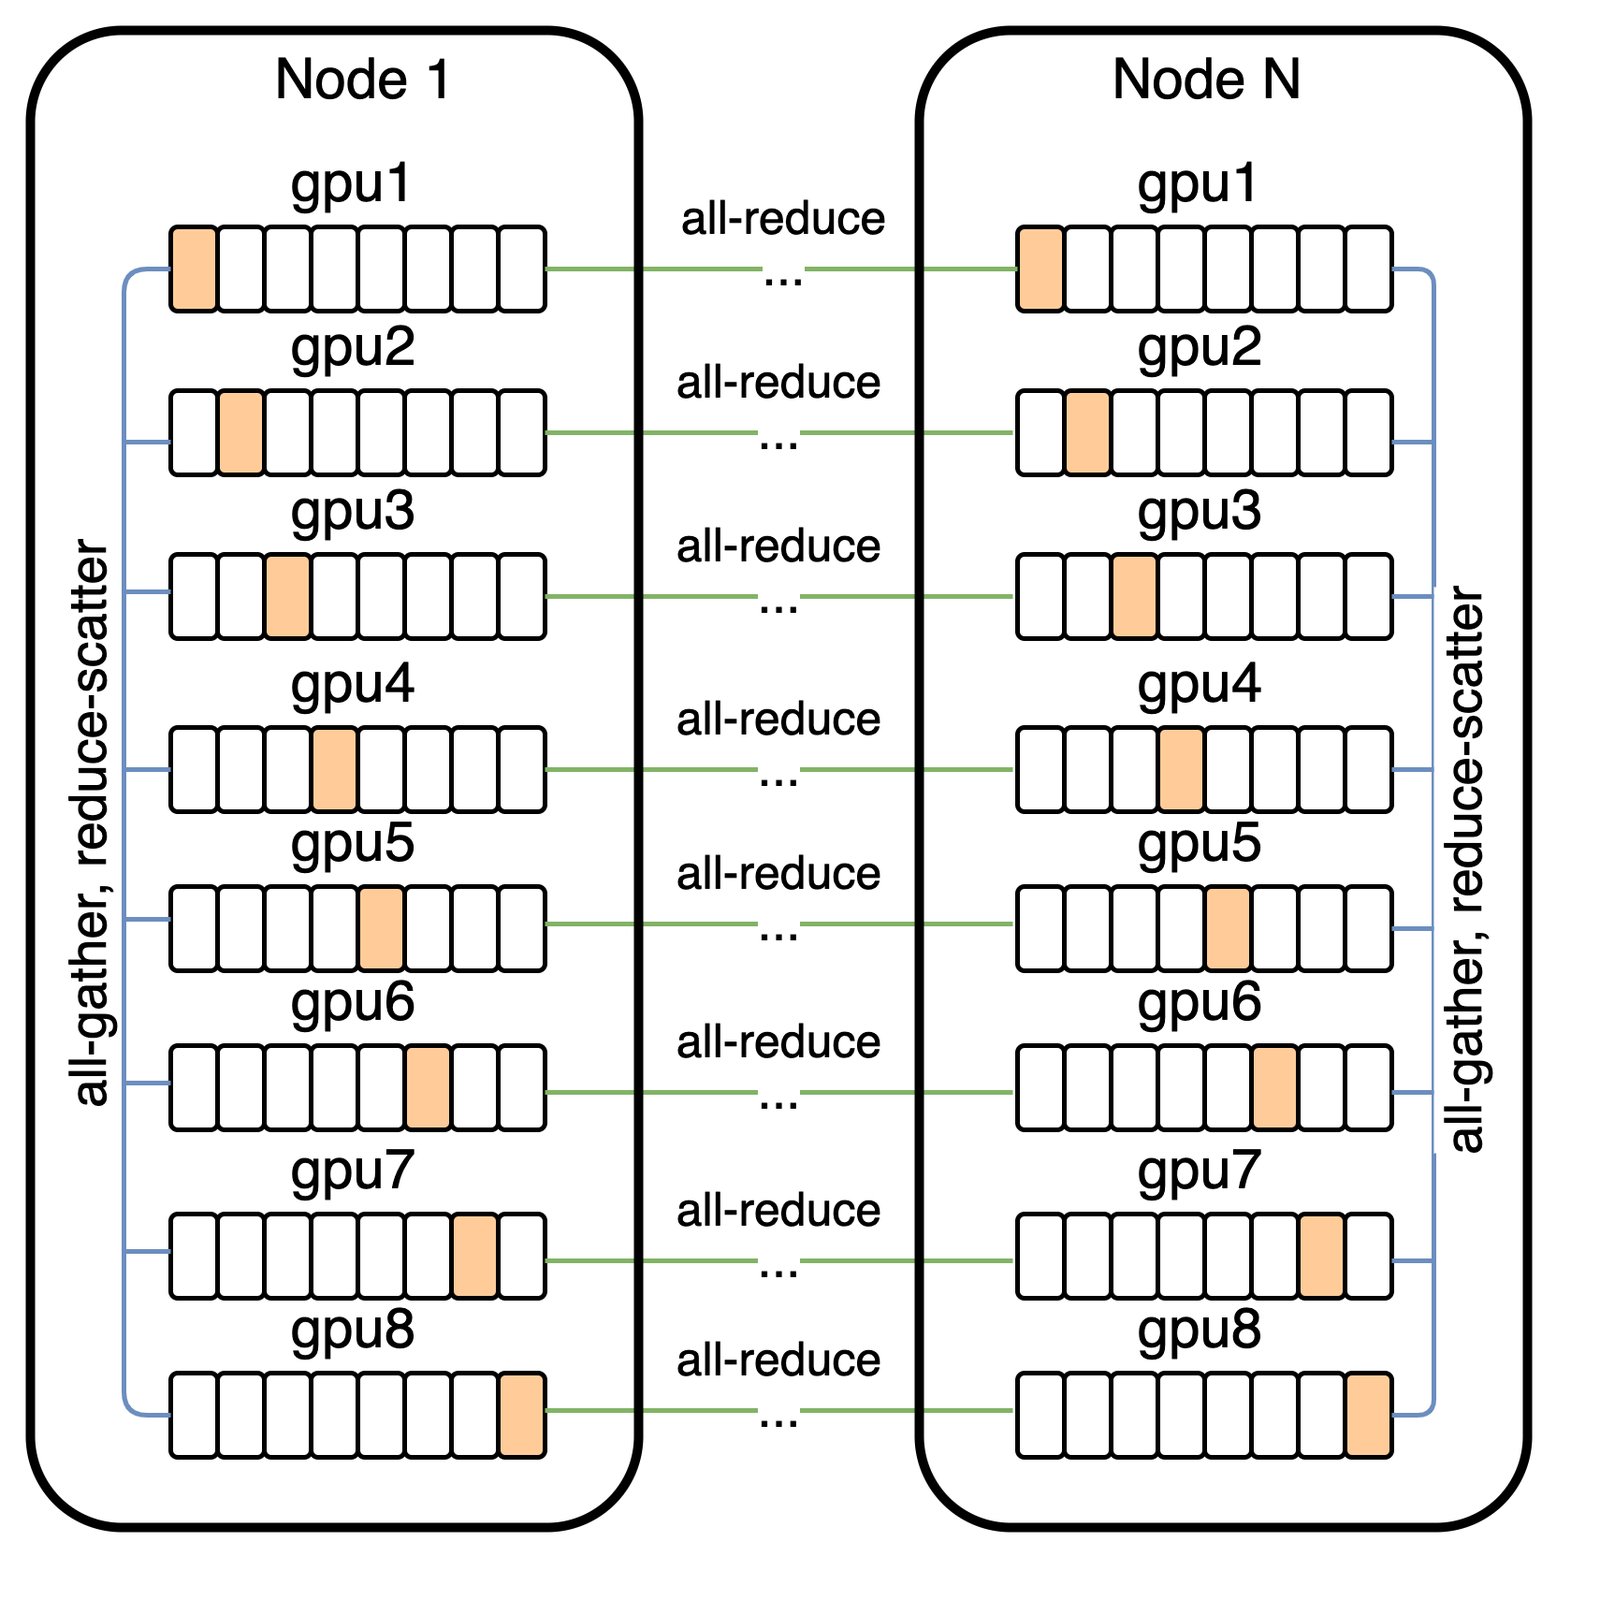
Figure 5: Communication patterns used for distributed training. Each parameter array in the model is sharded among the eight GPUs on each machine. During forward propagation, we prefetch the parameter shards for the next resblock (using all-gather) while computing the activations for the current resblock. To conserve memory, the parameter shards from the other GPUs are immediately discarded. Similarly, during backpropagation, we prefetch the parameter shards for the previous resblock while computing the activations and gradients for the current resblock. After all GPUs have computed the gradient with respect to an all-gathered parameter, the reduce-scatter operation leaves each GPU with only one slice – i.e., the gradient for its parameter shard, averaged over the eight GPUs.
图 5:分布式训练所用的通信模式。模型中每个参数数组在每台机器的八块 GPU 之间分片。前向传播时,我们在计算当前残差块激活的同时,用 all-gather 预取下一残差块的参数分片。为节省内存,来自其他 GPU 的参数分片随即丢弃。类似地,反向传播时,我们在计算当前残差块的激活与梯度的同时,预取上一残差块的参数分片。当所有 GPU 都算完对某次 all-gather 参数的梯度后,reduce-scatter 使每块 GPU 只留下一片——即对其参数分片、在八块 GPU 上平均后的梯度。
2.3 Data Collection
2.3 数据收集
Our preliminary experiments for models up to billion parameters were carried out on Conceptual Captions, a dataset of 3.3 million text-image pairs that was developed as an extension to MS-COCO (Lin et al. 2014).
对不超过 亿参数的模型,初步实验在 Conceptual Captions 上进行:该数据集含 330 万图文对,是作为 MS-COCO(Lin et al. 2014)扩展而开发的。
To scale up to -billion parameters, we created a dataset of a similar scale to JFT-300M (Sun et al. 2017) by collecting 250 million text-images pairs from the internet. This dataset does not include MS-COCO, but does include Conceptual Captions and a filtered subset of YFCC100M (Thomee et al. 2016). As MS-COCO was created from the latter, our training data includes a fraction of the MS-COCO validation images (but none of the captions). We control for this in the quantitative results presented in Section 3 and find that it has no appreciable bearing on the results. We provide further details about the data collection process in Appendix C.
为扩展到 亿参数,我们从互联网收集了 2.5 亿图文对,规模接近 JFT-300M(Sun et al. 2017)。该数据集不含 MS-COCO,但包含 Conceptual Captions 以及对 YFCC100M(Thomee et al. 2016)的过滤子集。由于 MS-COCO 由后者构建,我们的训练数据包含一小部分 MS-COCO 验证图像(但不含其描述)。第 3 节定量结果中我们对此做了控制,发现对结果没有可察觉影响。数据收集过程的更多细节见附录 C。
2.4 Mixed-Precision Training
2.4 混合精度训练
To save GPU memory and increase throughput, most parameters, Adam moments, and activations are stored in 16-bit precision. We also use activation checkpointing and recompute the activations within the resblocks during the backward pass. Getting the model to train in 16-bit precision past one billion parameters, without diverging, was the most challenging part of this project.
为节省 GPU 内存并提高吞吐,多数参数、Adam 矩与激活以 16 位精度存储。我们还使用激活检查点,并在反向传播时重算残差块内的激活。让模型在超过十亿参数后仍能以 16 位精度训练且不发散,是本项目最具挑战的部分。
We believe the root cause of this instability to be underflow in the 16-bit gradients. Appendix D presents a set of guidelines we developed to avoid underflow when training large-scale generative models. Here, we describe one of these guidelines: per-resblock gradient scaling.
我们认为这种不稳定性的根因是 16 位梯度下溢。附录 D 给出我们为避免大规模生成模型训练下溢而总结的一组准则。这里描述其中一条:逐残差块梯度缩放。
Similar to prior work (Liu et al. 2020), we found that the norms of the activation gradients from the resblocks decrease monotonically as we move from the earlier resblocks to the later ones.[^8] As the model is made deeper and wider, the true exponents of the activation gradients for later resblocks can fall below the minimum exponent of the 16-bit format. Consequently, they get rounded to zero, a phenomenon called underflow. We found that eliminating underflow allowed for stable training to convergence.
与先前工作类似(Liu et al. 2020),我们发现残差块激活梯度的范数从较早残差块到较晚残差块单调递减。[^8] 当模型更深更宽时,较晚残差块激活梯度的真实指数会落到 16 位格式的最小指数之下,从而被舍入为零,即下溢。我们发现消除下溢后,即可稳定训练至收敛。
Standard loss scaling (Micikevicius et al. 2017) is able to avoid underflow when the range spanned by the smallest and largest activation gradients (in absolute value) fits within the exponent range of the 16-bit format. On NVIDIA V100 GPUs, this exponent range is specified by five bits. While this is sufficient for training vanilla language models of the same size, we found the range to be too small for the text-to-image model.
标准损失缩放(Micikevicius et al. 2017)在最小与最大激活梯度(绝对值)所跨范围落在 16 位格式指数范围内时,可以避免下溢。在 NVIDIA V100 GPU 上,该指数范围由五位指定。这对训练同规模的普通语言模型足够,但对文生图模型则过小。
Our fix, which is shown in Figure 4, involves using a separate “gradient scale” for each resblock in the model. This can be seen as a practical alternative to a more general framework for mixed-precision training called Flexpoint (Köster et al. 2017), with the advantage that specialized GPU kernels are not required. We found that Sun et al. 2020 had independently developed similar procedure for training convolutional networks in 4-bit precision.
我们的修复如图 4 所示:对模型中每个残差块使用独立的「梯度缩放」。这可视为更一般的混合精度训练框架 Flexpoint(Köster et al. 2017)的实用替代,优点是不需要专用 GPU 核。我们发现 Sun et al. 2020 曾独立提出类似流程,用于以 4 位精度训练卷积网络。
2.5 Distributed Optimization
2.5 分布式优化
| Effective Parameter Count | Compression Rank | Compression Rate |
|---|---|---|
| () | 512 | |
| () | 640 | |
| () | 896 |
Table 1: We show the relationship between model size and the minimum compression rank for the gradients (up to a multiple of 128) necessary to avoid a gap in the training loss during the first of training. These results suggest that in our setting, we can achieve a compression rate of about , independent of model size.
| Effective Parameter Count | Compression Rank | Compression Rate |
|---|---|---|
| () | 512 | |
| () | 640 | |
| () | 896 |
表 1:模型规模与为避免训练前 阶段出现训练损失缺口所需的最小梯度压缩秩(取 128 的倍数)之间的关系。结果表明,在我们的设定下可达到约 的压缩率,且与模型规模基本无关。
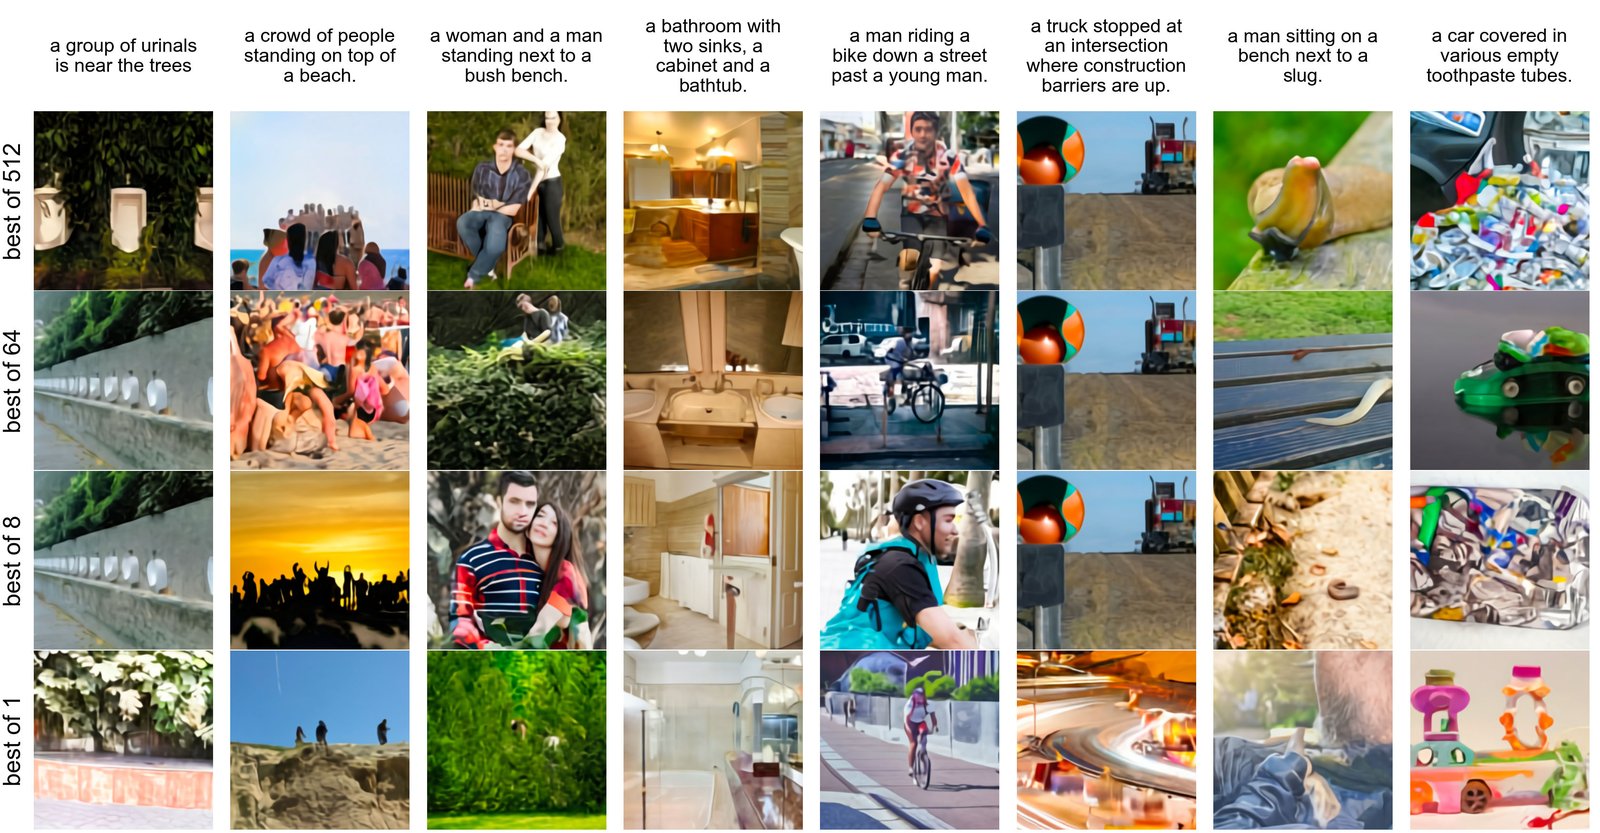
Figure 6: Effect of increasing the number of images for the contrastive reranking procedure on MS-COCO captions.
图 6:在 MS-COCO 描述上,增大对比重排序所用图像数量的影响。
Our 12-billion parameter model consumes about 24 GB of memory when stored in 16-bit precision, which exceeds the memory of a 16 GB NVIDIA V100 GPU. We address this using parameter sharding (Rajbhandari et al. 2019). As shown in Figure 5, parameter sharding allows us to almost completely hide the latency of the intra-machine communication by overlapping it with compute-intensive operations.
我们的 120 亿参数模型以 16 位精度存储约占用 24 GB 内存,超过 16 GB 的 NVIDIA V100 GPU。我们用参数分片(Rajbhandari et al. 2019)解决。如图 5 所示,参数分片使我们几乎能把机内通信延迟完全隐藏在计算密集操作之后。
On the cluster used to train the model, the bandwidth between machines is much lower than the bandwidth among GPUs on the same machine. This makes the cost of the operation used to average the gradient among the machines (all-reduce) the main bottleneck during training. We were able to drastically reduce this cost by compressing the gradients using PowerSGD (Vogels et al. 2019).
在训练所用集群上,机器之间的带宽远低于同一机器上 GPU 之间的带宽。因此,用于在机器间平均梯度的 all-reduce 成为训练的主要瓶颈。我们用 PowerSGD(Vogels et al. 2019)压缩梯度,大幅降低了该成本。
In our implementation, each GPU in a machine computes the low-rank factors for its parameter shard gradients independently of its neighboring GPUs.[^9] Once the low-rank factors are computed, each machine sets its error buffer to the residual between the uncompressed gradient averaged over its eight GPUs (obtained from reduce-scatter), and the decompressed gradient obtained from the low-rank factors.
实现中,一台机器上的每块 GPU 独立计算其参数分片梯度的低秩因子,不依赖邻接 GPU。[^9] 低秩因子算完后,每台机器把误差缓冲设为:在其八块 GPU 上平均后的未压缩梯度(由 reduce-scatter 得到)与由低秩因子解压得到的梯度之间的残差。
PowerSGD replaces the large communication operation for an uncompressed parameter gradient with two, much smaller communication operations for its low-rank factors. For a given compression rank and transformer activation size , the compression rate is given by (see Appendix E.1). Table 1 shows that we can achieve a compression rate of about , independent of model size.
PowerSGD 把针对未压缩参数梯度的一次大通信,换成针对其低秩因子的两次小得多的通信。对给定压缩秩 与 transformer 激活维度 ,压缩率为 (见附录 E.1)。表 1 表明我们可达到约 的压缩率,且与模型规模无关。
In Appendix E.2, we describe various details that were necessary to get PowerSGD to perform well at scale. These include:
附录 E.2 描述了使 PowerSGD 在大规模下表现良好所必需的若干细节,包括:
- • Saving memory by accumulating the gradient into the error buffers during backpropagation, rather than allocating separate buffers.
- • 在反向传播时把梯度累加进误差缓冲,而不是另开缓冲,以节省内存。
- • Minimizing instances in which we zero out the error buffers (e.g., due to nonfinite values encountered during mixed-precision backpropagation, or when resuming training from a checkpoint).
- • 尽量减少将误差缓冲清零的情形(例如混合精度反向传播遇到非有限值,或从检查点恢复训练时)。
- • Improving numerical stability by using Householder orthogonalization instead of Gram-Schmidt, together with the addition of a small multiple of the identity matrix to the input.
- • 用 Householder 正交化代替 Gram-Schmidt,并在输入上加单位矩阵的一个小倍数,以提高数值稳定性。
- • Avoiding underflow by using a custom 16-bit floating point format for the error buffers, their low-rank factors, and the all-reduce communication operations involving them.
- • 对误差缓冲、其低秩因子以及涉及它们的 all-reduce 通信,使用定制的 16 位浮点格式,以避免下溢。
We also found the warm-start procedure for the matrix described in Vogels et al. 2019 to be unnecessary: we were able to get equivalent results by fixing to a random gaussian matrix at the start of training, and never updating it.[^10]
我们还发现 Vogels et al. 2019 所述对 矩阵的热启动并非必要:在训练开始时把 固定为随机高斯矩阵且永不更新,也能得到等价结果。[^10]
2.6 Sample Generation
2.6 样本生成
Similar to Razavi et al. 2019, we rerank the samples drawn from the transformer using a pretrained contrastive model (Radford et al. 2021). Given a caption and a candidate image, the contrastive model assigns a score based on how well the image matches the caption. Figure 6 shows the effect of increasing the number of samples from which we select the top images. This process can be seen as a kind of language-guided search (Andreas et al. 2017), and is also similar to the auxiliary text-image matching loss proposed by Xu et al. 2018. Unless otherwise stated, all samples used for both qualitative and quantitative results are obtained without temperature reduction (i.e., using ) (except for Figure 2) and use reranking with .
与 Razavi et al. 2019 类似,我们用预训练对比模型(Radford et al. 2021)对 transformer 抽出的样本重排序。给定描述与候选图像,对比模型按图像与描述的匹配程度打分。图 6 展示了增大从中选出 top- 图像的样本数 的效果。该过程可视为一种语言引导搜索(Andreas et al. 2017),也类似 Xu et al. 2018 提出的辅助图文匹配损失。除非另有说明,定性与定量结果所用样本均不降温度(即 )(图 2 除外),并以 做重排序。
3 Experiments
3 实验
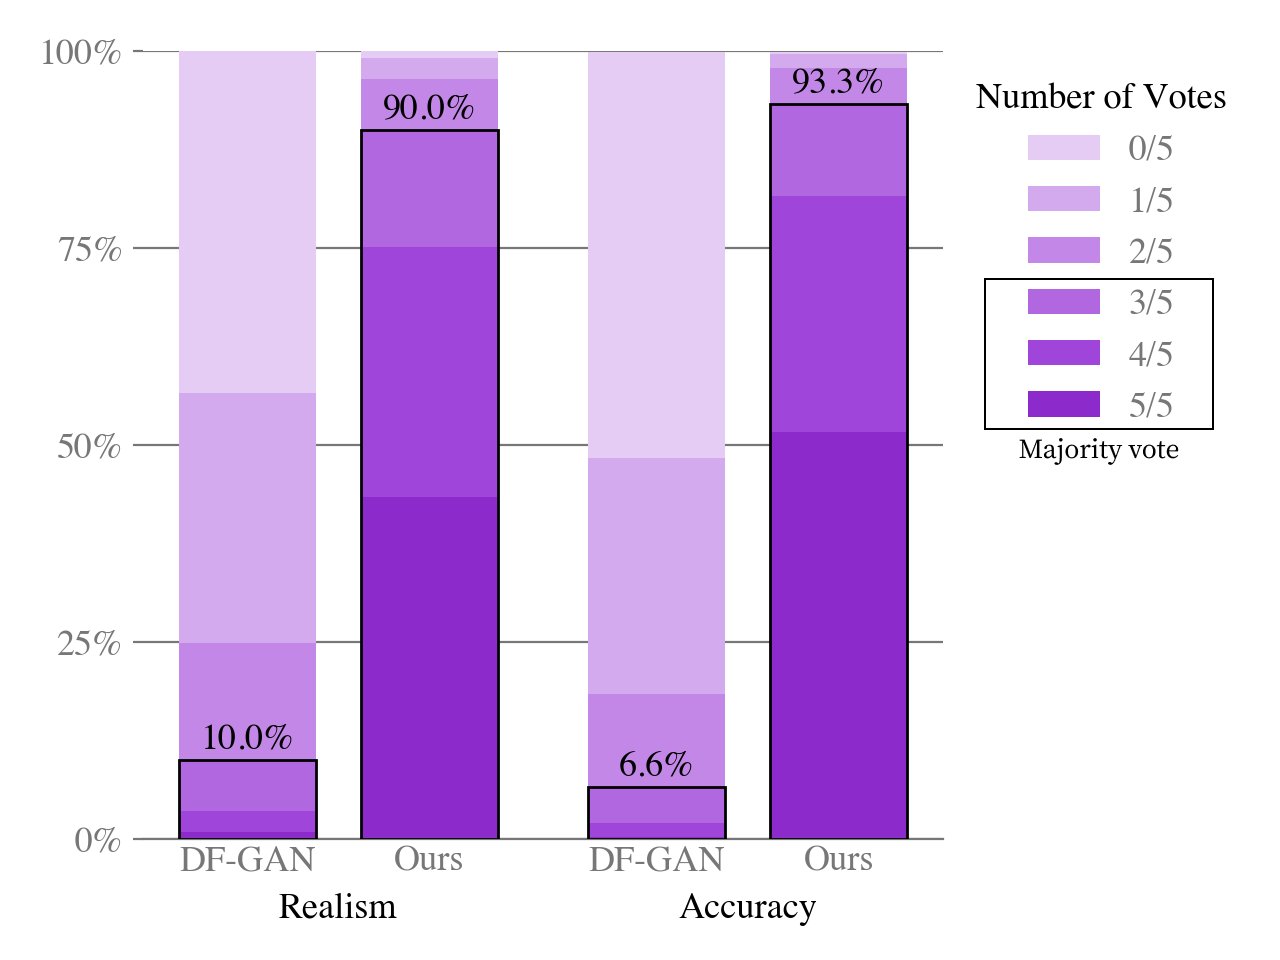
Figure 7: Human evaluation of our model (evaluated zero-shot without temperature reduction) vs prior work (DF-GAN) on captions from MS-COCO. In a best-of-five vote, our model’s sample was chosen as the most realistic 90.0% of the time, and was chosen as the image best matching a shared caption 93.3% of the time.
图 7:我们的模型(零样本、不降温度)相对先前工作(DF-GAN)在 MS-COCO 描述上的人工评测。五选一投票中,我们的样本有 90.0% 的时间被选为最真实,有 93.3% 的时间被选为与共享描述最匹配的图像。
3.1 Quantitative Results
3.1 定量结果
We evaluate our model zero-shot by comparing it to three prior approaches: AttnGAN (Xu et al. 2018), DM-GAN (Zhu et al. 2019), and DF-GAN (Tao et al. 2020), the last of which reports the best Inception Score (Salimans et al. 2016) and Fréchet Inception Distance (Heusel et al. 2017) on MS-COCO. Figure 3 qualitatively compares samples from our model to those from prior work.
我们以零样本方式评测模型,并与三种先前方法对比:AttnGAN(Xu et al. 2018)、DM-GAN(Zhu et al. 2019)与 DF-GAN(Tao et al. 2020);后者在 MS-COCO 上报告了当时最好的 Inception Score(Salimans et al. 2016)与 Fréchet Inception Distance(Heusel et al. 2017)。图 3 定性对比了我们模型与先前工作的样本。
We also conduct a human evaluation similar to the one used in Koh et al. 2021 to compare our approach to DF-GAN, the results of which are shown in Figure 7. Given a caption, the sample from our model receives the majority vote for better matching the caption 93% of the time. It also receives the majority vote for being more realistic 90% of the time.
我们还做了类似 Koh et al. 2021 的人工评测,与 DF-GAN 对比,结果见图 7。给定描述时,我们的样本有 93% 的时间获得「更匹配描述」的多数票,有 90% 的时间获得「更真实」的多数票。
Figure 9(a) shows that our model also obtains an FID score on MS-COCO within 2 points of the best prior approach, despite having never been trained on the captions. Our training data incorporates a filtered subset of YFCC100M, and we found that it includes about of the images in the MS-COCO validation set from a de-duplication procedure described in the next section. To isolate this effect, we compute the FID statistics for the validation set both with these images (solid lines) and without them (dashed lines), finding no significant change in the results.
图 9(a) 表明,我们的模型在 MS-COCO 上的 FID 也落在最优先前方法 2 分以内,尽管从未在这些描述上训练。训练数据纳入了 YFCC100M 的过滤子集;按下一节所述去重流程,我们发现其中约含 MS-COCO 验证集 的图像。为隔离该影响,我们分别在包含这些图像(实线)与剔除它们(虚线)时计算验证集 FID 统计,结果无显著变化。
Training the transformer on the tokens from the dVAE encoder allows us to allocate its modeling capacity to the low-frequency information that makes images visually recognizable to us. However, it also disadvantages the model, since the heavy compression renders it unable to produce high-frequency details. To test the effect of this on the quantitative evaluations, we compute the FID and IS in Figure 9(a) after applying a Gaussian filter with varying radius to both the validation images and samples from the models. Our approach achieves the best FID by a margin of about 6 points with a slight blur of radius 1. The gap between our approach and others tends to widen as the blur radius is increased. We also obtain the highest IS when the blur radius is greater than or equal to two.
在 dVAE 编码器的 token 上训练 transformer,使我们能把建模容量分配给让图像在视觉上可辨认的低频信息。但这也使模型吃亏:重度压缩令其无法产生高频细节。为检验这对定量评测的影响,我们在图 9(a) 中对验证图像与各模型样本施加不同半径的高斯滤波后再算 FID 与 IS。在半径为 1 的轻微模糊下,我们的方法以约 6 分优势取得最好 FID。模糊半径增大时,与其他方法的差距往往拉大。当模糊半径大于等于二时,我们也取得最高 IS。
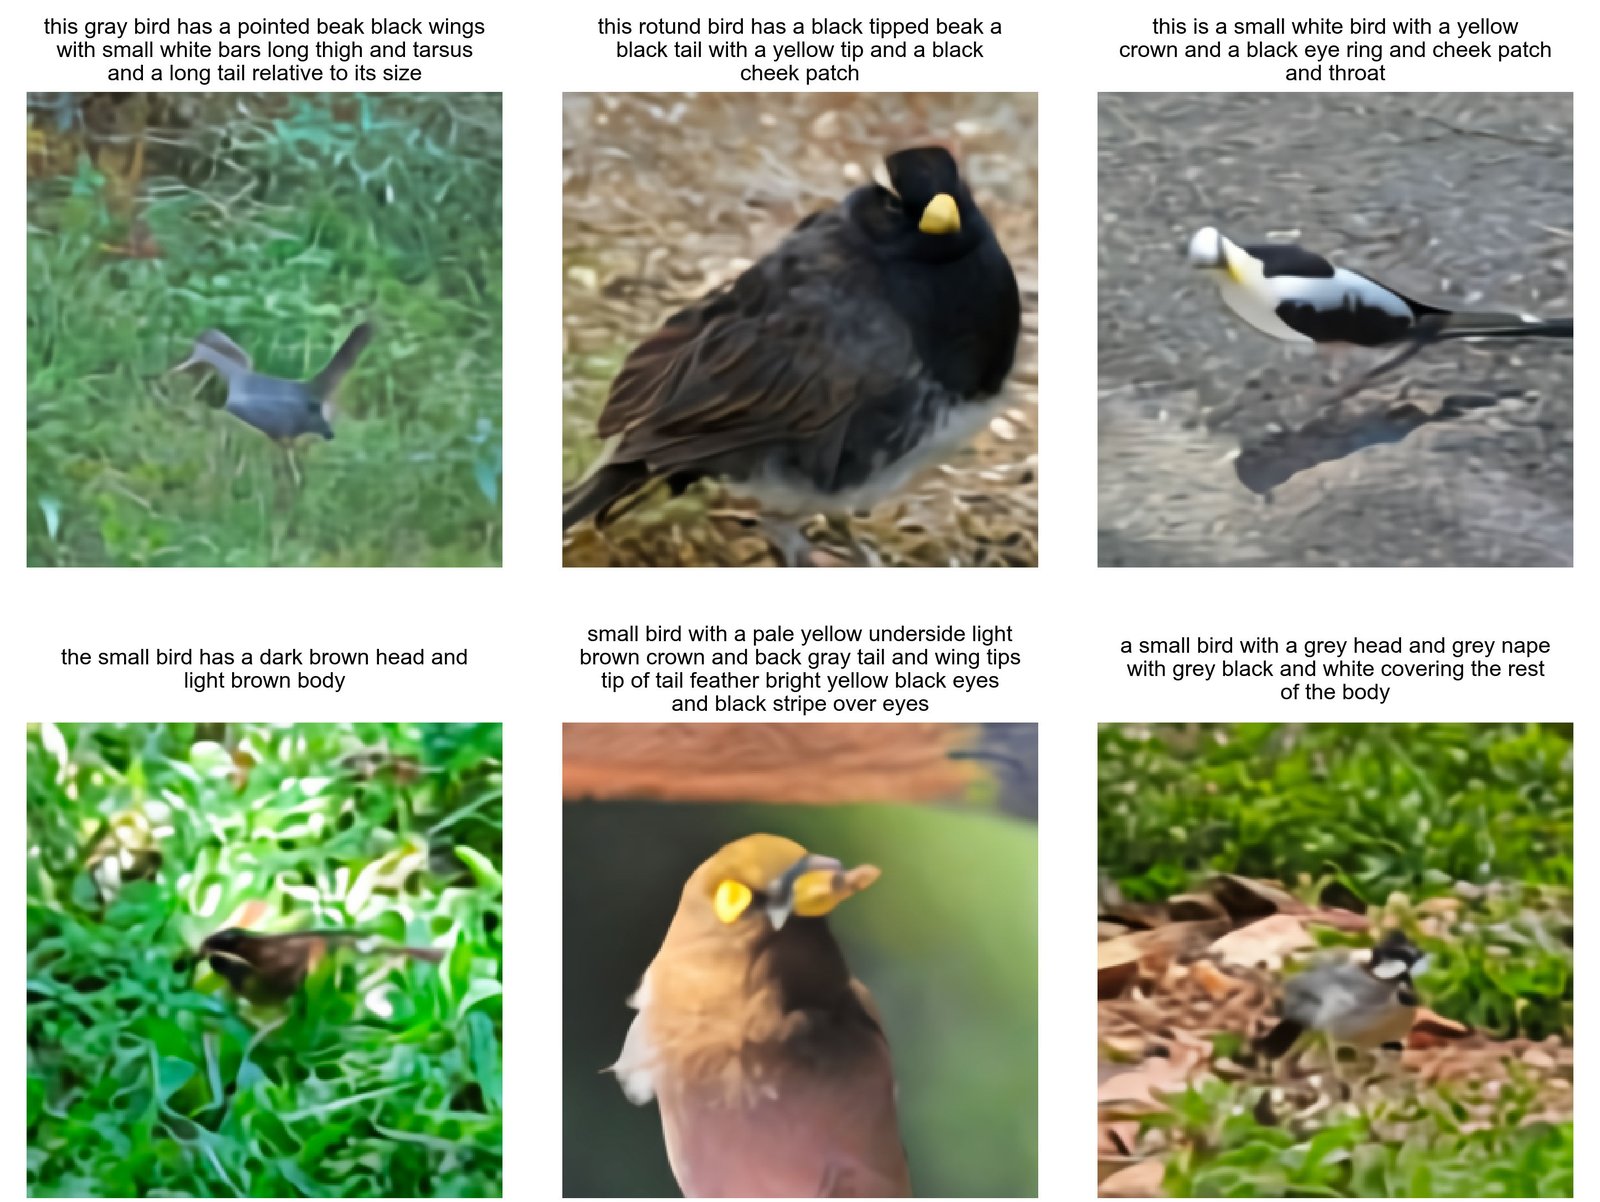
Figure 8: Zero-shot samples from our model on the CUB dataset.
图 8:我们的模型在 CUB 数据集上的零样本样本。
(a) FID and IS on MS-COCO as a function of blur radius.
Our model fares significantly worse on the CUB dataset, for which there is a nearly 40-point gap in FID between our model and the leading prior approach (Figure 9(b)). We found an overlap rate for this dataset, and again observed no significant difference in the results after removing these images. We speculate that our zero-shot approach is less likely to compare favorably on specialized distributions such as CUB. We believe that fine-tuning is a promising direction for improvement, and leave this investigation to future work. Samples from our model for captions in this dataset are shown in Figure 8.
在 CUB 数据集上我们的模型明显更差:相对领先的先前方法有近 40 分的 FID 差距(图 9(b))。我们发现该集重叠率约 ,剔除这些图像后结果同样无显著差异。我们推测,零样本做法在 CUB 这类专用分布上更不容易占优。我们认为微调是有希望的改进方向,留待未来工作。该数据集描述上的样本见图 8。
Finally, Figure 9(c) shows clear improvements in FID and IS for MS-COCO as the sample size used for reranking with the contrastive model is increased. This trend continues up to a sample size of 32, after which we observe diminishing returns.
最后,图 9(c) 表明:增大对比模型重排序所用的样本量时,MS-COCO 上的 FID 与 IS 有明显改善。该趋势持续到样本量为 32,之后收益递减。
3.2 Data Overlap Analysis
3.2 数据重叠分析
We used the deduplication procedure described in Radford et al. 2021 to determine which images to remove. For each validation image, we find the closest image in the training data using a contrastive model specifically trained for this task. We then sort the images in descending order by closeness to their nearest matches in the training data. After inspecting the results by hand, we determine the images to remove by manually selecting a conservative threshold designed to minimize the false negative rate.
我们使用 Radford et al. 2021 所述去重流程决定剔除哪些图像。对每张验证图像,用专为该任务训练的对比模型在训练数据中找最近邻。再按与训练数据最近匹配的接近程度降序排列。人工检查结果后,我们手动选取偏保守的阈值以尽量降低假阴性率,从而确定要剔除的图像。
3.3 Qualitative Findings
3.3 定性发现
We found that our model has the ability to generalize in ways that we did not originally anticipate. When given the caption “a tapir made of accordion…” (Figure 2a), the model appears to draw a tapir with an accordion for a body, or an accordion whose keyboard or bass are in the shape of a tapir’s trunk or legs. This suggests that it has developed a rudimentary ability to compose unusual concepts at high levels of abstraction.
我们发现模型具备一些最初未预料到的泛化能力。给定描述「a tapir made of accordion…」(图 2a)时,模型似乎会画出以手风琴为身体的貘,或键盘/低音部分呈貘鼻/腿形状的手风琴。这表明它已形成在较高抽象层次上组合罕见概念的初步能力。
Our model also appears to be capable of combinatorial generalization, such as when rendering text (Figure 2b) or when probed on sentences like “an illustration of a baby hedgehog in a christmas sweater walking a dog” (Figure 2c). Prompts like the latter require the model to perform variable binding (Smolensky 1990; Greff et al. 2020) – it is the hedgehog that is in the christmas sweater, not the dog. We note, however, that the model performs inconsistently on the task, sometimes drawing both animals with christmas sweaters, or drawing a hedgehog walking a smaller hedgehog.
模型似乎也具备组合泛化能力,例如渲染文字(图 2b),或在「an illustration of a baby hedgehog in a christmas sweater walking a dog」这类句子上探测时(图 2c)。后一类提示要求模型做变量绑定(Smolensky 1990;Greff et al. 2020)——穿圣诞毛衣的是刺猬,不是狗。不过我们也指出:模型在该任务上表现不稳定,有时会给两只动物都画上圣诞毛衣,或画成一只刺猬遛着更小的刺猬。
To a limited degree of reliability, we also find our model to be capable of zero-shot image-to-image translation controllable by natural language (Figure 2d). When the model is given the caption “the exact same cat on the top as a sketch at the bottom” and the top part of the image token grid for a photo of a cat, it is able to draw a sketch of a similar looking cat on the bottom.
在有限可靠程度下,我们还发现模型能做由自然语言控制的零样本图到图翻译(图 2d)。当给定描述「the exact same cat on the top as a sketch at the bottom」,并把一张猫照片图像 token 网格顶部 部分提供给模型时,它能在底部画出外形相近的猫素描。
This works with several other kinds of transformations, including image operations (e.g., changing the color of the image, converting it to grayscale, or flipping it upside-down) and style transfer (e.g., drawing the cat on a greeting card, a postage stamp, or a cell phone case). Some transformations, such as those that involve only changing the color of the animal, suggest that the model is capable of performing a rudimentary kind of object segmentation. We provide additional examples of zero-shot image-to-image translation in Section G.
这对其它多种变换也成立,包括图像操作(如改色、转灰度、上下翻转)与风格迁移(如画成贺卡、邮票或手机壳上的猫)。有些只改动物颜色的变换暗示模型具备初步的物体分割能力。更多零样本图到图翻译例子见第 G 节。
4 Conclusion
4 结论
We investigate a simple approach for text-to-image generation based on an autoregressive transformer, when it is executed at scale. We find that scale can lead to improved generalization, both in terms of zero-shot performance relative to previous domain-specific approaches, and in terms of the range of capabilities that emerge from a single generative model. Our findings suggest that improving generalization as a function of scale may be a useful driver for progress on this task.
我们研究一种基于自回归 transformer、并在大规模下执行的简单文生图方法。我们发现规模可带来更好的泛化:既相对先前领域专用方法提升零样本表现,也扩展了单一生成模型涌现出的能力范围。结果表明,把「随规模改善泛化」当作驱动力,可能有助于推进该任务。
Acknowledgements
致谢
We would like to thank Matthew Knight for reviewing the code release for this work, and Rewon Child, John Schulman, Heewoo Jun, and Prafulla Dhariwal for helpful early feedback on the paper. We would also like to thank Jong Wook Kim for writing the PyTorch package for the contrastive model described in Radford et al. 2019 that we used to rerank the samples from our model.
感谢 Matthew Knight 审阅本工作的代码发布,感谢 Rewon Child、John Schulman、Heewoo Jun 与 Prafulla Dhariwal 对论文的早期有益反馈。也感谢 Jong Wook Kim 为 Radford et al. 2019 所述对比模型编写了我们用于对模型样本重排序的 PyTorch 软件包。
References
参考文献
Abadi et al. (2016) Abadi, M., Barham, P., Chen, J., Chen, Z., Davis, A., Dean, J., Devin, M., Ghemawat, S., Irving, G., Isard, M., et al. Tensorflow: A system for large-scale machine learning. In 12th { { USENIX } } symposium on operating systems design and implementation ( { { OSDI } } 16) , pp. 265–283, 2016.
Andreas et al. (2017) Andreas, J., Klein, D., and Levine, S. Learning with latent language. arXiv preprint arXiv:1711.00482 , 2017.
Bengio et al. (2013) Bengio, Y., Léonard, N., and Courville, A. Estimating or propagating gradients through stochastic neurons for conditional computation. arXiv preprint arXiv:1308.3432 , 2013.
Bowman et al. (2015) Bowman, S. R., Vilnis, L., Vinyals, O., Dai, A. M., Jozefowicz, R., and Bengio, S. Generating sentences from a continuous space. arXiv preprint arXiv:1511.06349 , 2015.
Chen et al. (2020) Chen, M., Radford, A., Child, R., Wu, J., Jun, H., Luan, D., and Sutskever, I. Generative pretraining from pixels. In International Conference on Machine Learning , pp. 1691–1703. PMLR, 2020.
Child et al. (2019) Child, R., Gray, S., Radford, A., and Sutskever, I. Generating long sequences with sparse transformers. arXiv preprint arXiv:1904.10509 , 2019.
Cho et al. (2020) Cho, J., Lu, J., Schwenk, D., Hajishirzi, H., and Kembhavi, A. X-lxmert: Paint, caption and answer questions with multi-modal transformers. arXiv preprint arXiv:2009.11278 , 2020.
Deng et al. (2009) Deng, J., Dong, W., Socher, R., Li, L.-J., Li, K., and Fei-Fei, L. Imagenet: A large-scale hierarchical image database. In 2009 IEEE conference on computer vision and pattern recognition , pp. 248–255. Ieee, 2009.
Dhariwal et al. (2020) Dhariwal, P., Jun, H., Payne, C., Kim, J. W., Radford, A., and Sutskever, I. Jukebox: A generative model for music. arXiv preprint arXiv:2005.00341 , 2020.
Goodfellow et al. (2014) Goodfellow, I. J., Pouget-Abadie, J., Mirza, M., Xu, B., Warde-Farley, D., Ozair, S., Courville, A., and Bengio, Y. Generative adversarial networks. arXiv preprint arXiv:1406.2661 , 2014.
Greff et al. (2020) Greff, K., van Steenkiste, S., and Schmidhuber, J. On the binding problem in artificial neural networks. arXiv preprint arXiv:2012.05208 , 2020.
Gregor et al. (2015) Gregor, K., Danihelka, I., Graves, A., Rezende, D., and Wierstra, D. Draw: A recurrent neural network for image generation. In International Conference on Machine Learning , pp. 1462–1471. PMLR, 2015.
He et al. (2016) He, K., Zhang, X., Ren, S., and Sun, J. Identity mappings in deep residual networks. In European conference on computer vision , pp. 630–645. Springer, 2016.
Heusel et al. (2017) Heusel, M., Ramsauer, H., Unterthiner, T., Nessler, B., and Hochreiter, S. Gans trained by a two time-scale update rule converge to a local nash equilibrium. arXiv preprint arXiv:1706.08500 , 2017.
Higgins et al. (2016) Higgins, I., Matthey, L., Pal, A., Burgess, C., Glorot, X., Botvinick, M., Mohamed, S., and Lerchner, A. beta-vae: Learning basic visual concepts with a constrained variational framework. 2016.
Isola et al. (2017) Isola, P., Zhu, J.-Y., Zhou, T., and Efros, A. A. Image-to-image translation with conditional adversarial networks. In Proceedings of the IEEE conference on computer vision and pattern recognition , pp. 1125–1134, 2017.
Jang et al. (2016) Jang, E., Gu, S., and Poole, B. Categorical reparameterization with gumbel-softmax. arXiv preprint arXiv:1611.01144 , 2016.
Kingma & Ba (2014) Kingma, D. P. and Ba, J. Adam: A method for stochastic optimization. arXiv preprint arXiv:1412.6980 , 2014.
Kingma & Welling (2013) Kingma, D. P. and Welling, M. Auto-encoding variational bayes. arXiv preprint arXiv:1312.6114 , 2013.
Koh et al. (2021) Koh, J. Y., Baldridge, J., Lee, H., and Yang, Y. Text-to-image generation grounded by fine-grained user attention. In Proceedings of the IEEE/CVF Winter Conference on Applications of Computer Vision , pp. 237–246, 2021.
Köster et al. (2017) Köster, U., Webb, T. J., Wang, X., Nassar, M., Bansal, A. K., Constable, W. H., Elibol, O. H., Gray, S., Hall, S., Hornof, L., et al. Flexpoint: An adaptive numerical format for efficient training of deep neural networks. arXiv preprint arXiv:1711.02213 , 2017.
LeCun et al. (1998) LeCun, Y., Bottou, L., Bengio, Y., and Haffner, P. Gradient-based learning applied to document recognition. Proceedings of the IEEE , 86(11):2278–2324, 1998.
Li et al. (2019) Li, W., Zhang, P., Zhang, L., Huang, Q., He, X., Lyu, S., and Gao, J. Object-driven text-to-image synthesis via adversarial training. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition , pp. 12174–12182, 2019.
Lin et al. (2014) Lin, T.-Y., Maire, M., Belongie, S., Hays, J., Perona, P., Ramanan, D., Dollár, P., and Zitnick, C. L. Microsoft coco: Common objects in context. In European conference on computer vision , pp. 740–755. Springer, 2014.
Liu et al. (2020) Liu, L., Liu, X., Gao, J., Chen, W., and Han, J. Understanding the difficulty of training transformers. arXiv preprint arXiv:2004.08249 , 2020.
Loshchilov & Hutter (2017) Loshchilov, I. and Hutter, F. Decoupled weight decay regularization. arXiv preprint arXiv:1711.05101 , 2017.
Maddison et al. (2016) Maddison, C. J., Mnih, A., and Teh, Y. W. The concrete distribution: A continuous relaxation of discrete random variables. arXiv preprint arXiv:1611.00712 , 2016.
Mansimov et al. (2015) Mansimov, E., Parisotto, E., Ba, J. L., and Salakhutdinov, R. Generating images from captions with attention. arXiv preprint arXiv:1511.02793 , 2015.
Micikevicius et al. (2017) Micikevicius, P., Narang, S., Alben, J., Diamos, G., Elsen, E., Garcia, D., Ginsburg, B., Houston, M., Kuchaiev, O., Venkatesh, G., et al. Mixed precision training. arXiv preprint arXiv:1710.03740 , 2017.
Nguyen et al. (2017) Nguyen, A., Clune, J., Bengio, Y., Dosovitskiy, A., and Yosinski, J. Plug & play generative networks: Conditional iterative generation of images in latent space. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition , pp. 4467–4477, 2017.
Oord et al. (2017) Oord, A. v. d., Vinyals, O., and Kavukcuoglu, K. Neural discrete representation learning. arXiv preprint arXiv:1711.00937 , 2017.
Provilkov et al. (2019) Provilkov, I., Emelianenko, D., and Voita, E. Bpe-dropout: Simple and effective subword regularization. arXiv preprint arXiv:1910.13267 , 2019.
Radford et al. (2019) Radford, A., Wu, J., Child, R., Luan, D., Amodei, D., and Sutskever, I. Language models are unsupervised multitask learners. 2019.
Radford et al. (2021) Radford, A., Kim, J. W., Hallacy, C., Ramesh, A., Goh, G., Agarwal, S., Sastry, G., Askell, A., Mishkin, P., Clark, J., Krueger, G., and Sutskever, I. Learning transferable visual models from natural language supervision. 2021.
Rajbhandari et al. (2019) Rajbhandari, S., Rasley, J., Ruwase, O., and He, Y. Zero: Memory optimization towards training a trillion parameter models. arXiv preprint arXiv:1910.02054 , 2019.
Razavi et al. (2019) Razavi, A., Oord, A. v. d., and Vinyals, O. Generating diverse high-fidelity images with vq-vae-2. arXiv preprint arXiv:1906.00446 , 2019.
Reed et al. (2016a) Reed, S., Akata, Z., Mohan, S., Tenka, S., Schiele, B., and Lee, H. Learning what and where to draw. arXiv preprint arXiv:1610.02454 , 2016a.
Reed et al. (2016b) Reed, S., Akata, Z., Yan, X., Logeswaran, L., Schiele, B., and Lee, H. Generative adversarial text to image synthesis. In International Conference on Machine Learning , pp. 1060–1069. PMLR, 2016b.
Rezende et al. (2014) Rezende, D. J., Mohamed, S., and Wierstra, D. Stochastic backpropagation and approximate inference in deep generative models. In International conference on machine learning , pp. 1278–1286. PMLR, 2014.
Salimans et al. (2016) Salimans, T., Goodfellow, I., Zaremba, W., Cheung, V., Radford, A., and Chen, X. Improved techniques for training gans. arXiv preprint arXiv:1606.03498 , 2016.
Salimans et al. (2017) Salimans, T., Karpathy, A., Chen, X., and Kingma, D. P. Pixelcnn++: Improving the pixelcnn with discretized logistic mixture likelihood and other modifications. arXiv preprint arXiv:1701.05517 , 2017.
Sennrich et al. (2015) Sennrich, R., Haddow, B., and Birch, A. Neural machine translation of rare words with subword units. arXiv preprint arXiv:1508.07909 , 2015.
Sharma et al. (2018) Sharma, P., Ding, N., Goodman, S., and Soricut, R. Conceptual captions: A cleaned, hypernymed, image alt-text dataset for automatic image captioning. In Proceedings of the 56th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) , pp. 2556–2565, 2018.
Smolensky (1990) Smolensky, P. Tensor product variable binding and the representation of symbolic structures in connectionist systems. Artificial intelligence , 46(1-2):159–216, 1990.
Sun et al. (2017) Sun, C., Shrivastava, A., Singh, S., and Gupta, A. Revisiting unreasonable effectiveness of data in deep learning era. In Proceedings of the IEEE international conference on computer vision , pp. 843–852, 2017.
Sun et al. (2020) Sun, X., Wang, N., Chen, C.-Y., Ni, J., Agrawal, A., Cui, X., Venkataramani, S., El Maghraoui, K., Srinivasan, V. V., and Gopalakrishnan, K. Ultra-low precision 4-bit training of deep neural networks. Advances in Neural Information Processing Systems , 33, 2020.
Tao et al. (2020) Tao, M., Tang, H., Wu, S., Sebe, N., Wu, F., and Jing, X.-Y. Df-gan: Deep fusion generative adversarial networks for text-to-image synthesis. arXiv preprint arXiv:2008.05865 , 2020.
Thomee et al. (2016) Thomee, B., Shamma, D. A., Friedland, G., Elizalde, B., Ni, K., Poland, D., Borth, D., and Li, L.-J. Yfcc100m: The new data in multimedia research. Communications of the ACM , 59(2):64–73, 2016.
Vaswani et al. (2017) Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., and Polosukhin, I. Attention is all you need. arXiv preprint arXiv:1706.03762 , 2017.
Vogels et al. (2019) Vogels, T., Karimireddy, S. P., and Jaggi, M. Powersgd: Practical low-rank gradient compression for distributed optimization. arXiv preprint arXiv:1905.13727 , 2019.
Welinder et al. (2010) Welinder, P., Branson, S., Mita, T., Wah, C., Schroff, F., Belongie, S., and Perona, P. Caltech-ucsd birds 200. 2010.
Xu et al. (2018) Xu, T., Zhang, P., Huang, Q., Zhang, H., Gan, Z., Huang, X., and He, X. Attngan: Fine-grained text to image generation with attentional generative adversarial networks. In Proceedings of the IEEE conference on computer vision and pattern recognition , pp. 1316–1324, 2018.
Zhang et al. (2017) Zhang, H., Xu, T., Li, H., Zhang, S., Wang, X., Huang, X., and Metaxas, D. N. Stackgan: Text to photo-realistic image synthesis with stacked generative adversarial networks. In Proceedings of the IEEE international conference on computer vision , pp. 5907–5915, 2017.
Zhang et al. (2018) Zhang, H., Xu, T., Li, H., Zhang, S., Wang, X., Huang, X., and Metaxas, D. N. Stackgan++: Realistic image synthesis with stacked generative adversarial networks. IEEE transactions on pattern analysis and machine intelligence , 41(8):1947–1962, 2018.
Zhu et al. (2019) Zhu, M., Pan, P., Chen, W., and Yang, Y. Dm-gan: Dynamic memory generative adversarial networks for text-to-image synthesis. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition , pp. 5802–5810, 2019.
Appendix A Details for Discrete VAE
附录 A 离散 VAE 细节
A.1 Architecture
A.1 架构
The dVAE encoder and decoder are convolutional (LeCun et al. 1998) ResNets (He et al. 2016) with bottleneck-style resblocks. The models primarily use convolutions, with convolutions along skip connections in which the number of feature maps changes between the input and output of a resblock. The first convolution of the encoder is , and the last convolution of the encoder (which produces the output used as the logits for the categorical distributions for the image tokens) is . Both the first and last convolutions of the decoder are . The encoder uses max-pooling (which we found to yield better ELB than average-pooling) to downsample the feature maps, and the decoder uses nearest-neighbor upsampling. The precise details for the architectures are given in the files dvae/encoder.py and dvae/decoder.py of the code release.
dVAE 的编码器与解码器是带瓶颈式残差块的卷积(LeCun et al. 1998)ResNet(He et al. 2016)。模型主要使用 卷积;当残差块输入与输出特征图数量变化时,跳跃连接上使用 卷积。编码器首个卷积为 ,末个卷积(产生用作图像 token 类别分布 logit 的 输出)为 。解码器首尾卷积均为 。编码器用最大池化(我们发现其 ELB 优于平均池化)下采样特征图,解码器用最近邻上采样。架构精确细节见代码发布中的 dvae/encoder.py 与 dvae/decoder.py。
A.2 Training
A.2 训练
def preprocess_image(img, target_res):
h, w = tf.shape(img)[0], tf.shape(img)[1]
s_min = tf.minimum(h, w)
img = tf.image.random_crop(img, 2 * [s_min] + [3])
t_min = tf.minimum(s_min, round(9 / 8 * target_res))
t_max = tf.minimum(s_min, round(12 / 8 * target_res))
t = tf.random.uniform([], t_min, t_max + 1, dtype=tf.int32)
img = tf.image.resize_images(img, [t, t], method=tf.image.ResizeMethod.AREA,
align_corners=True)
img = tf.cast(tf.rint(tf.clip_by_value(img, 0, 255)), tf.uint8)
img = tf.image.random_crop(img, 2 * [target_res] + [channel_count])
return tf.image.random_flip_left_right(img)
Listing 1: TensorFlow (Abadi et al. 2016) image preprocessing code for training dVAE. We use target_res = 256 and channel_count = 3.
def preprocess_image(img, target_res):
h, w = tf.shape(img)[0], tf.shape(img)[1]
s_min = tf.minimum(h, w)
img = tf.image.random_crop(img, 2 * [s_min] + [3])
t_min = tf.minimum(s_min, round(9 / 8 * target_res))
t_max = tf.minimum(s_min, round(12 / 8 * target_res))
t = tf.random.uniform([], t_min, t_max + 1, dtype=tf.int32)
img = tf.image.resize_images(img, [t, t], method=tf.image.ResizeMethod.AREA,
align_corners=True)
img = tf.cast(tf.rint(tf.clip_by_value(img, 0, 255)), tf.uint8)
img = tf.image.random_crop(img, 2 * [target_res] + [channel_count])
return tf.image.random_flip_left_right(img)
代码清单 1:训练 dVAE 所用的 TensorFlow(Abadi et al. 2016)图像预处理代码。我们取 target_res = 256、channel_count = 3。
The dVAE is trained on the same dataset as the transformer, using the data augmentation code given in Listing 1. Several quantities are decayed during training, all of which use a cosine schedule:
dVAE 在与 transformer 相同的数据集上训练,数据增强代码见代码清单 1。训练中若干量按余弦日程衰减:
- The KL weight is increased from to over the first updates. Bowman et al. 2015 use a similar schedule based on the sigmoid function.
- KL 权重 在前 次更新中从 增至 。Bowman et al. 2015 使用基于 sigmoid 的类似日程。
- The relaxation temperature is annealed from to over the first updates. Using a linear annealing schedule for this typically led to divergence.
- 松弛温度 在前 次更新中从 退火到 。对该量使用线性退火通常会导致发散。
- The step size is annealed from to over updates.
- 步长在 次更新中从 退火到 。
The decay schedules for the relaxation temperature and the step size are especially important for stability and successful optimization.
松弛温度与步长的衰减日程对稳定性与成功优化尤为重要。
We update the parameters using AdamW (Loshchilov & Hutter 2017) with , , , and weight decay multiplier . We use exponentially weighted iterate averaging for the parameters with decay coefficient . The reconstruction term in the ELB is a joint distribution over the values for the image pixels, and the KL term is a joint distribution over the positions in the spatial grid output by the encoder. We divide the overall loss by , so that the weight of the KL term becomes , where is the KL weight. The model is trained in mixed-precision using standard (i.e., global) loss scaling on 16 GB NVIDIA V100 GPUs, with a per-GPU batch size of , resulting in a total batch size of 512. It is trained for a total of updates.
参数用 AdamW(Loshchilov & Hutter 2017)更新:,,,权重衰减乘数 。对参数做指数加权迭代平均,衰减系数 。ELB 中重建项是图像像素 个取值上的联合分布,KL 项是编码器输出空间网格 个位置上的联合分布。我们将总损失除以 ,从而使 KL 项权重变为 ,其中 为 KL 权重。模型以混合精度、标准(即全局)损失缩放,在 块 16 GB NVIDIA V100 上训练,每 GPU 批次大小为 ,总批次大小为 512。共训练 次更新。
A.3 The Logit-Laplace Distribution
A.3 Logit-Laplace 分布
The and reconstruction objectives are commonly used when training VAEs. These objectives correspond to using Laplace and Gaussian distributions for in Equation 1, respectively. There is a strange mismatch in this modeling choice: pixel values lie within a bounded interval, but both of these distributions are supported by the entire real line. Hence, some amount of likelihood will be placed outside the admissible range of pixel values.
训练 VAE 时常用 与 重建目标。它们分别对应在公式 1 中对 使用 Laplace 与 Gaussian 分布。这一建模选择有奇怪的错配:像素值落在有界区间,而这两种分布的支撑都是整条实线。因此,会有一部分似然落在像素值允许范围之外。
We present a variant of the Laplace distribution that is also supported by a bounded interval. This resolves the discrepancy between the range of the pixel values being modeled and the support of the distribution used to model them. We consider the pdf of the random variable obtained by applying the sigmoid function to a Laplace-distributed random variable. This pdf is defined on and is given by
我们提出一种同样以有界区间为支撑的 Laplace 分布变体,以消除被建模像素值范围与建模所用分布支撑之间的不一致。考虑对 Laplace 分布随机变量施加 sigmoid 后所得随机变量的 pdf。该 pdf 定义在 上,形式为
we call it the logit-Laplace distribution. We use the logarithm of the RHS of Equation 2 as the reconstruction term for the training objective of the dVAE.
我们称之为 logit-Laplace 分布。将公式 2 右侧取对数,作为 dVAE 训练目标的重建项。
The decoder of the dVAE produces six feature maps representing the sufficient statistics of the logit-Laplace distribution for the RGB channels of the image being reconstructed. The first three feature maps represent the parameter for the RGB channels, and the last three represent . Before feeding an image into the dVAE encoder, we transform its values using , which is given by
dVAE 解码器输出六张特征图,表示被重建图像 RGB 通道的 logit-Laplace 分布充分统计量。前三张表示 RGB 通道的 参数,后三张表示 。图像送入 dVAE 编码器前,先用 变换其取值,定义为
This restricts the range of the pixel values to be modeled by the dVAE decoder to , which avoids numerical problems arising from the in Equation 2. We use . To reconstruct an image for manual inspection or computing metrics, we ignore and compute , where is given by the first three feature maps output by the dVAE decoder.[^11]
这将 dVAE 解码器要建模的像素值范围限制在 ,以避免公式 2 中 带来的数值问题。我们取 。为人工检查或计算指标而重建图像时,忽略 ,计算 ,其中 由 dVAE 解码器输出的前三张特征图给出。[^11]
Appendix B Details for Transformer
附录 B Transformer 细节
B.1 Architecture
B.1 架构
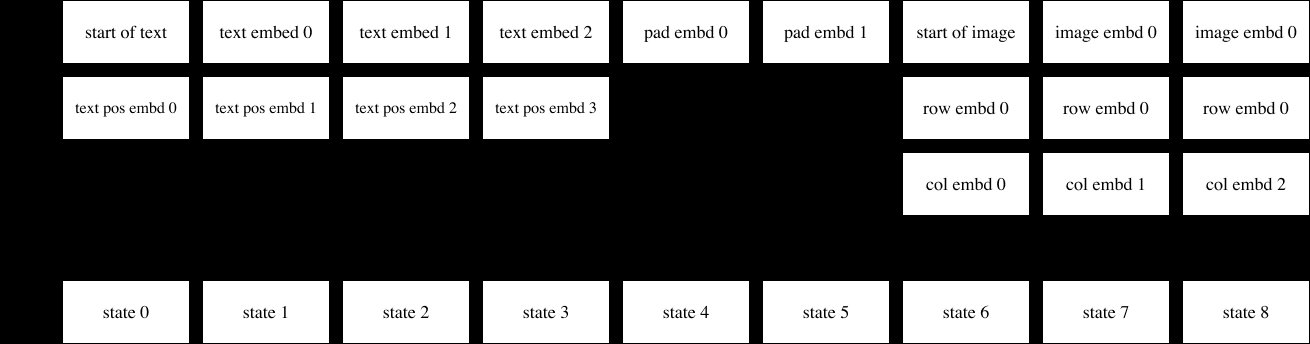
Figure 10: Illustration of the embedding scheme for a hypothetical version of our transformer with a maximum text length of 6 tokens. Each box denotes a vector of size . In this illustration, the caption has a length of 4 tokens, so 2 padding tokens are used (as described in Section 2.2). Each image vocabulary embedding is summed with a row and column embedding.
图 10:我们 transformer 的一种假想版本(最大文本长度 6 个 token)的嵌入方案示意。每个方框表示大小为 的向量。图中描述长度为 4 个 token,因此使用 2 个填充 token(如第 2.2 节所述)。每个图像词表嵌入与一个行嵌入和一个列嵌入相加。
(a) Row attention mask.
(a) 行注意力掩码。
Our model is a decoder-only sparse transformer of the same kind described in Child et al. 2019, with broadcasted row and column embeddings for the part of the context for the image tokens. A complete description of the embedding scheme used in our model is shown in Figure 10. We use 64 attention layers, each of which uses 62 attention heads with a per-head state size of 64.
我们的模型是 Child et al. 2019 所述同类的仅解码器稀疏 transformer,并对图像 token 上下文部分使用广播的行、列嵌入。模型所用嵌入方案的完整说明见图 10。我们使用 64 个注意力层,每层 62 个注意力头,每头状态大小为 64。
The model uses three kinds of sparse attention masks, which we show in Figure 11. The convolutional attention mask (Figure 11(d)) is only used in the last self-attention layer. Otherwise, given the index of a self-attention layer (with ), we use the column attention mask (Figure 11(c)) if , and row attention otherwise. E.g., the first four self-attention layers use “row, column, row, row”, respectively. With the exception of the convolutional attention mask, which we found to provide a small boost in performance over the row and dense causal attention masks when used in the final self-attention layer, this is the same configuration used in Child et al. 2019.
模型使用三种稀疏注意力掩码,见图 11。卷积注意力掩码(图 11(d))仅用于最后一层自注意力。其余情况下,给定自注意力层下标 (),若 则用列注意力掩码(图 11(c)),否则用行注意力。例如,前四层自注意力分别使用「行、列、行、行」。除卷积注意力掩码外——我们发现它在最后一层自注意力中相对行掩码与稠密因果掩码能带来小幅提升——这与 Child et al. 2019 所用配置相同。
B.2 Training
B.2 训练
def preprocess_image(img, target_res):
h, w = tf.shape(img)[0], tf.shape(img)[1]
s_min = tf.minimum(h, w)
off_h = tf.random.uniform([], 3 * (h - s_min) // 8,
tf.maximum(3 * (h - s_min) // 8 + 1, 5 * (h - s_min) // 8),
dtype=tf.int32)
off_w = tf.random.uniform([], 3 * (w - s_min) // 8,
tf.maximum(3 * (w - s_min) // 8 + 1, 5 * (w - s_min) // 8),
dtype=tf.int32)
# Random full square crop.
img = tf.image.crop_to_bounding_box(img, off_h, off_w, s_min, s_min)
t_max = tf.minimum(s_min, round(9 / 8 * target_res))
t = tf.random.uniform([], target_res, t_max + 1, dtype=tf.int32)
img = tf.image.resize_images(img, [t, t], method=tf.image.ResizeMethod.AREA,
align_corners=True)
img = tf.cast(tf.rint(tf.clip_by_value(img, 0, 255)), tf.uint8)
# We don’t use hflip aug since the image may contain text.
return tf.image.random_crop(img, 2 * [target_res] + [channel_count])
Listing 2: TensorFlow (Abadi et al. 2016) image preprocessing code for training the transformer. We use target_res = 256 and channel_count = 3.
def preprocess_image(img, target_res):
h, w = tf.shape(img)[0], tf.shape(img)[1]
s_min = tf.minimum(h, w)
off_h = tf.random.uniform([], 3 * (h - s_min) // 8,
tf.maximum(3 * (h - s_min) // 8 + 1, 5 * (h - s_min) // 8),
dtype=tf.int32)
off_w = tf.random.uniform([], 3 * (w - s_min) // 8,
tf.maximum(3 * (w - s_min) // 8 + 1, 5 * (w - s_min) // 8),
dtype=tf.int32)
# Random full square crop.
img = tf.image.crop_to_bounding_box(img, off_h, off_w, s_min, s_min)
t_max = tf.minimum(s_min, round(9 / 8 * target_res))
t = tf.random.uniform([], target_res, t_max + 1, dtype=tf.int32)
img = tf.image.resize_images(img, [t, t], method=tf.image.ResizeMethod.AREA,
align_corners=True)
img = tf.cast(tf.rint(tf.clip_by_value(img, 0, 255)), tf.uint8)
# We don’t use hflip aug since the image may contain text.
return tf.image.random_crop(img, 2 * [target_res] + [channel_count])
代码清单 2:训练 transformer 所用的 TensorFlow(Abadi et al. 2016)图像预处理代码。我们取 target_res = 256、channel_count = 3。
When training the transformer, we apply data augmentation to the images before encoding them using the dVAE encoder. We use slightly different augmentations from the ones used to train the dVAE; the code used for this is given in Listing 2. We also apply 10% BPE dropout when BPE-encoding the captions for training. The model is trained using per-resblock scaling (see Section 2.4) and gradient compression (see Section 2.5) with total compression rank 896 (so that each GPU uses a compression rank of 112 for its parameter shards). As shown in Table 1, this results in a compression rate of about 86%, which we analyze in Section E.1.
训练 transformer 时,我们在用 dVAE 编码器编码之前对图像做数据增强。所用增强与训练 dVAE 时略有不同;代码见代码清单 2。对训练用描述做 BPE 编码时还施加 10% BPE dropout。模型使用逐残差块缩放(见第 2.4 节)与梯度压缩(见第 2.5 节),总压缩秩 896(因此每块 GPU 对其参数分片使用压缩秩 112)。如表 1 所示,压缩率约 ,我们在第 E.1 节分析。
We update the parameters using AdamW with , , , and weight decay multiplier . We clip the decompressed gradients by norm using a threshold of 4, prior to applying the Adam update. Gradient clipping is only triggered during the warm-up phase at the start of training. To conserve memory, most Adam moments (see Section D for details) are stored in 16-bit formats, with a 1-6-9 format for the running mean (i.e., 1 bit for the sign, 6 bits for the exponent, and 9 bits for the significand), and a 0-6-10 format for the running variance. We clip the estimate for running variance by value to 5 before it is used to update the parameters or moments. Finally, we apply exponentially weighted iterate averaging by asynchronously copying the model parameters from the GPU to the CPU once every 25 updates, using a decay coefficient of 0.99.
参数用 AdamW 更新:,,,权重衰减乘数 。在应用 Adam 更新前,按范数以阈值 4 裁剪解压后的梯度。梯度裁剪仅在训练开始的预热阶段被触发。为节省内存,多数 Adam 矩(细节见第 D 节)以 16 位格式存储:运行均值用 1-6-9 格式(1 位符号、6 位指数、9 位尾数),运行方差用 0-6-10 格式。在用于更新参数或矩之前,将运行方差估计按值裁剪到 5。最后,每 25 次更新异步把模型参数从 GPU 拷到 CPU,做指数加权迭代平均,衰减系数 0.99。
We trained the model using 1024, 16 GB NVIDIA V100 GPUs and a total batch size of , for a total of updates. At the start of training, we use a linear schedule to ramp up the step size to over updates, and halved the step size each time the training loss appeared to plateau. We did this a total of five times, ending training with a final step size that was 32 times smaller than the initial one. We reserved about images for validation, and did not observe overfitting at any point during training.
我们用 1024 块 16 GB NVIDIA V100 GPU、总批次大小 训练模型,共 次更新。训练开始时用线性日程在 次更新内把步长升至 ;每当训练损失看似进入平台期,就把步长减半。共减半五次,最终步长为初始值的 1/32。我们留出约 张图像做验证,训练全程未见过拟合。
Appendix C Details for Data Collection
附录 C 数据收集细节
In order to train the 12-billion parameter transformer, we created a dataset of a similar scale to JFT-300M by collecting 250 million text-image pairs from the internet. As described in Section 2.3, this dataset incorporates Conceptual Captions, the text-image pairs from Wikipedia, and a filtered subset of YFCC100M. We use a subset of the text, image, and joint text and image filters described in Sharma et al. 2018 to construct this dataset. These filters include discarding instances whose captions are too short, are classified as non-English by the Python package cld3, or that consist primarily of boilerplate phrases such as “photographed on ¡date¿”, where ¡date¿ matches various formats for dates that we found in the data. We also discard instances whose images have aspect ratios not in . If we were to use to very tall or wide images, then the square crops used during training would likely exclude objects mentioned in the caption.
为训练 120 亿参数 transformer,我们从互联网收集了 2.5 亿图文对,规模接近 JFT-300M。如第 2.3 节所述,该数据集纳入 Conceptual Captions、Wikipedia 图文对,以及对 YFCC100M 的过滤子集。我们使用 Sharma et al. 2018 所述文本、图像与联合图文过滤器的一个子集来构建该数据集。这些过滤器包括:丢弃描述过短、被 Python 包 cld3 判为非英语,或以「photographed on ¡date¿」这类模板短语为主的样本(¡date¿ 匹配我们在数据中发现的多种日期格式)。我们也丢弃宽高比不在 内的图像。若使用过瘦或过宽的图像,训练时的方形裁剪很可能排除描述中提到的物体。
Appendix D Guidelines for Mixed-Precision Training
附录 D 混合精度训练准则
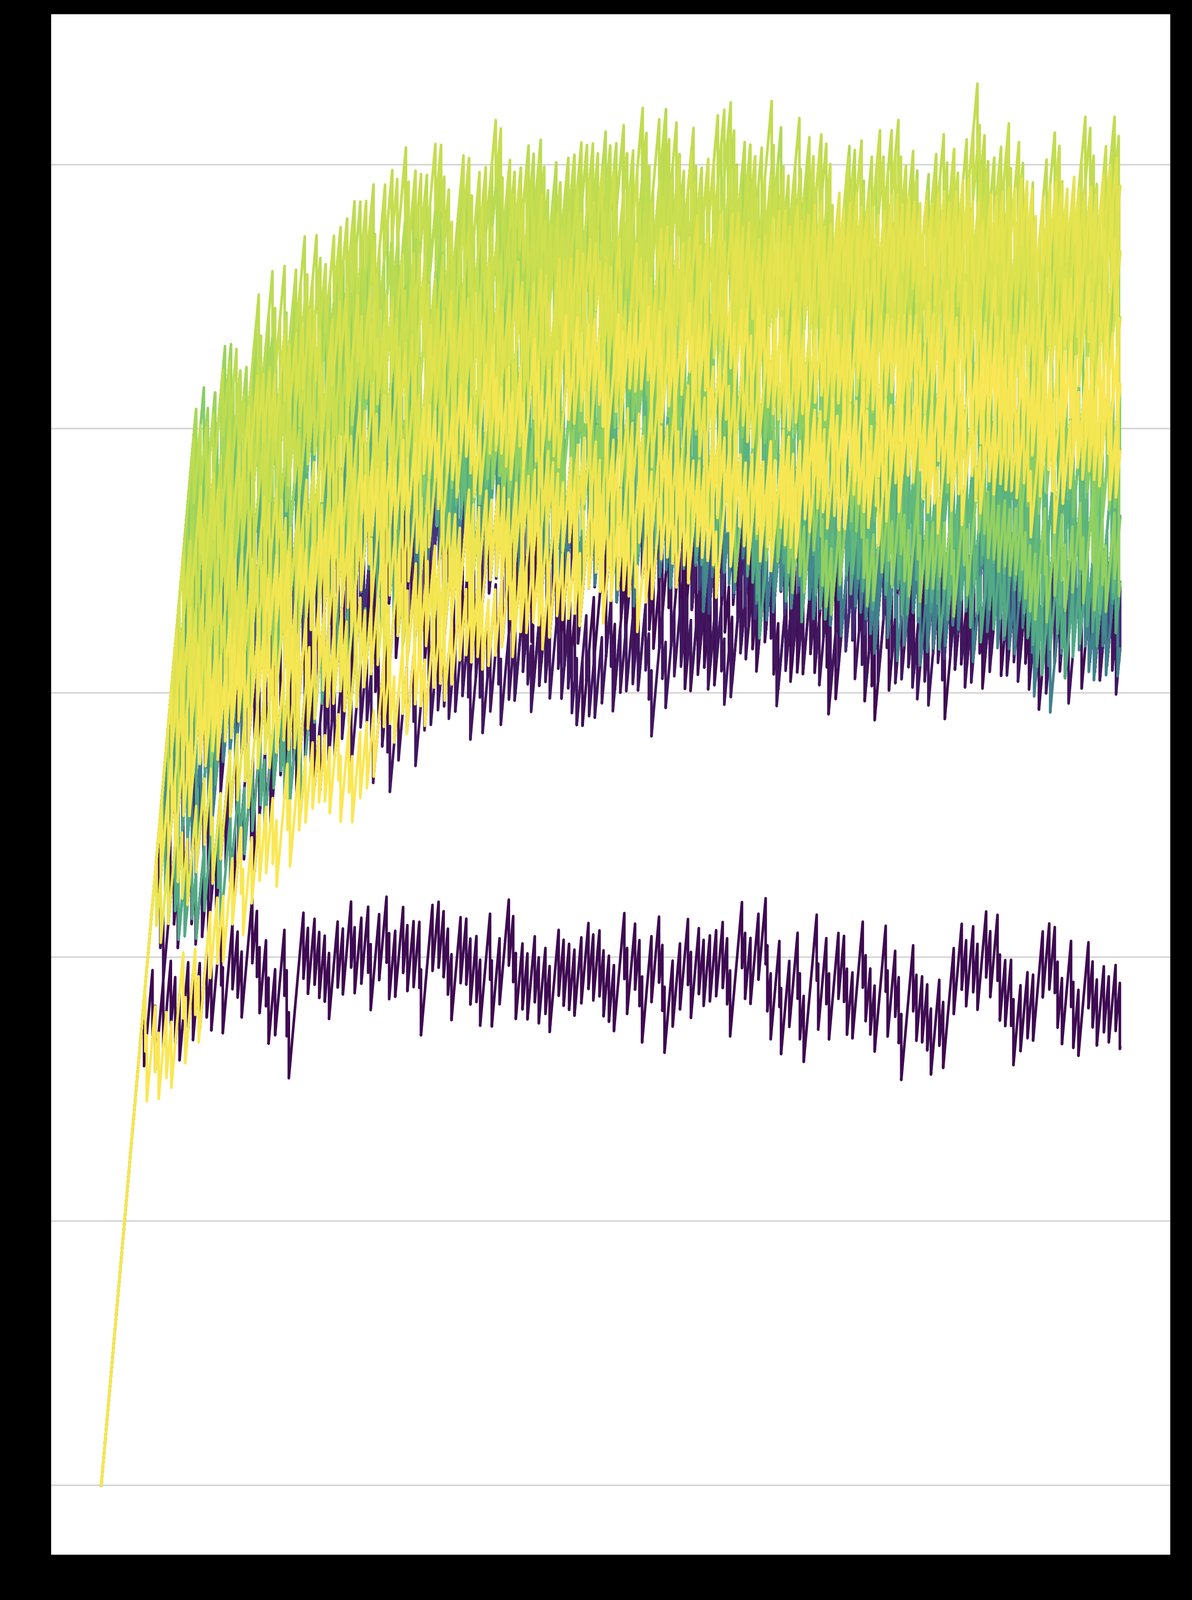
Figure 12: Plot of per-resblock gradient scales for a 2.8-billion parameter text-to-image transformer trained without gradient compression. The -axis is parameter updates, and the -axis is the base-2 logarithm of the gradient scale. Darkest violet corresponds to the first resblock, and brightest yellow corresponds to the last (of which there are 128 total). The gradient scale for the second MLP resblock hovers at around , while the others stay within a 4-bit range. The extent of this range increases as the model is made larger.
图 12:在未使用梯度压缩的情况下,一个 28 亿参数文生图 transformer 的逐残差块梯度缩放曲线。横轴为参数更新次数,纵轴为梯度缩放的以 2 为底的对数。最深紫对应第一个残差块,最亮黄对应最后一个(共 128 个)。第二个 MLP 残差块的梯度缩放约在 附近徘徊,其余则落在 4 位范围内。该范围随模型变大而扩大。
The most challenging part of this project was getting the model to train in 16-bit precision past one billion parameters. We were able to do this after detecting for underflow in various parts of training, and revising the code to eliminate it. We developed a set of guidelines as a result of this process that we present here.[^12]
本项目最具挑战的部分,是让模型在超过十亿参数后仍能以 16 位精度训练。我们通过检测训练各环节的下溢并修改代码消除它,才得以做到。由此总结的一组准则如下。[^12]
- Use per-resblock gradient scaling (Figure 4) instead of standard loss scaling. Our model uses 128 gradient scales, one for each of its resblocks. All of the gradient scales are initialized to , where is the number of data-parallel replicas (i.e., the number of GPUs). In our setup, each grad scale is multiplied by at every parameter update when there are no nonfinite values for any parameter gradient in that resblock. Otherwise, we divide the grad scale by and skip the update. We also disallow consecutive divisions of the same grad scale within a window of updates. All grad scales are clamped to the range after being updated. Figure 12 shows the gradient scales in the early phase of training for a 2.8-billion parameter model.
- 使用逐残差块梯度缩放(图 4),而不是标准损失缩放。 我们的模型有 128 个梯度缩放,每个残差块一个。全部梯度缩放初始化为 ,其中 为数据并行副本数(即 GPU 数)。在我们的设定下,若某残差块任一参数梯度均无非有限值,则每次参数更新将该 grad scale 乘以 ;否则除以 并跳过更新。我们也禁止同一 grad scale 在 次更新窗口内连续被除。更新后所有 grad scale 钳制在 。图 12 展示了 28 亿参数模型训练早期的梯度缩放。
- Only use 16-bit precision where it is really necessary for performance. In particular, store all gains, biases, embeddings, and unembeddings in 32-bit precision, with 32-bit gradients (including for remote communication) and 32-bit Adam moments. We disable gradient compression for these parameters (though PowerSGD would not make sense for 1D parameters like gains and biases). The logits for the text and image tokens are computed and stored in 32-bit precision. We found that storing the embeddings in 16-bit precision sometimes caused divergence early in optimization, and using 16-bit logits resulted in a small shift in the training curve, so we switched to use 32-bit precision out of an abundance of caution.
- 仅在性能真正需要处使用 16 位精度。 具体而言,所有增益、偏置、嵌入与反嵌入以 32 位精度存储,配 32 位梯度(含远程通信)与 32 位 Adam 矩。对这些参数关闭梯度压缩(对增益、偏置这类 1D 参数,PowerSGD 本身也不合适)。文本与图像 token 的 logit 以 32 位计算并存储。我们发现把嵌入存成 16 位有时会在优化早期导致发散,而用 16 位 logit 会使训练曲线小幅偏移,因此出于谨慎改用 32 位。
- Avoid underflow when dividing the gradient. For data-parallel training, we need to divide the gradients by the total number of data-parallel workers . One way to do this is to divide the loss by the per-machine batch size, and then divide the parameter gradients by before summing them over the machines (using all-reduce). To save time and space, the gradients are usually computed and stored in 16-bit precision. When is large, this division could result in underflow before the gradients are summed. On the other hand, if we attempt to sum the gradients first and then divide them later, we could encounter overflow in the all-reduce. Our solution for this problem attempts to minimize the loss of information in the division prior to the all-reduce, without danger of overflow. To do this, we divide the loss by the overall batch size (which includes as a factor) rather than the per-machine batch size, and multiply the gradient scales by to compensate, as described in (1). Then, prior to the all-reduce operation, we divide the gradients by a constant that was tuned by hand to avoid both underflow and overflow. This was done by inspecting histograms of the exponents (i.e., base-2 logarithms) of the absolute values of the scalar components of the per-parameter gradients. Since the gradient scaling keeps the gradients close to right end of the exponent range of the 16-bit format, we found that the same constant worked well for all parameters in the model with 16-bit gradients. When using PowerSGD, we chose different constants for the and matrices.
- 在除以梯度时避免下溢。 对数据并行训练,需要把梯度除以数据并行工作者总数 。一种做法是先把损失除以每机批次大小,再在机器间求和(all-reduce)之前把参数梯度除以 。为省时省空间,梯度通常以 16 位计算并存储。当 很大时,该除法可能在求和前造成下溢。反之,若先求和再除,all-reduce 中可能溢出。我们的解决办法尽量减少 all-reduce 前除法中的信息损失,同时避免溢出危险:把损失除以总体批次大小(其中已含因子 ),并如 (1) 所述把梯度缩放乘以 作为补偿。然后在 all-reduce 之前,用手工调好的常数去除梯度,以同时避免下溢与溢出。做法是检查各参数梯度标量分量绝对值指数(即以 2 为底的对数)的直方图。由于梯度缩放把梯度推近 16 位格式指数范围的右端,我们发现同一常数对模型中所有带 16 位梯度的参数都适用。使用 PowerSGD 时,我们对 与 矩阵选用不同常数。
Appendix E Details for Distributed Optimization
附录 E 分布式优化细节
We use PowerSGD (Vogels et al. 2019) to compress the gradients with respect to all parameters except the embeddings, unembeddings, gains, and biases. In Section E.1, we derive an expression for the reduction in the amount of data communicated as a function of the compression rank and model size. In Section E.2, we present a detailed overview of our adaptation of PowerSGD, and the modifications we had to make in order to fix performance regressions, some of which only manifest at billion-parameter scale.
我们对除嵌入、反嵌入、增益与偏置以外的全部参数梯度使用 PowerSGD(Vogels et al. 2019)压缩。第 E.1 节推导通信量随压缩秩与模型规模的减少表达式。第 E.2 节详细概述我们对 PowerSGD 的改编,以及为修复性能回退——其中一些仅在十亿参数规模显现——所做的修改。
E.1 Bandwidth Analysis
E.1 带宽分析
| Parameter Names | Parameter Shard Gradient Shape (No Compression) | shape | shape |
|---|---|---|---|
| qkv and post-attention matrices | |||
| First MLP matrix | |||
| Second MLP matrix | |||
| Total size |
Table 2: We analyze the amount of data sent from each GPU on a given machine to GPUs on other machines, in the case where we shard the parameters among the GPUs on each machine. Here, denotes the rank used for compression, and the transformer hidden size. The compression ratio is given by the sum of the last two columns of the last row, divided by the first column of the last row. This comes out to , which for is .
| Parameter Names | Parameter Shard Gradient Shape (No Compression) | shape | shape |
|---|---|---|---|
| qkv and post-attention matrices | |||
| First MLP matrix | |||
| Second MLP matrix | |||
| Total size |
表 2:分析在每台机器的 块 GPU 间对参数分片时,该机每块 GPU 向其他机器 GPU 发送的数据量。此处 为压缩秩, 为 transformer 隐层大小。压缩比由末行后两列之和除以末行第一列得到,即 ;当 时为 。
Gradient compression uses the factorization , where and both have rank . Instead of using a single all-reduce to transmit , we use two, smaller all-reduces to transmit both and in succession. Hence, the compression ratio is the sum of the sizes of the and matrices divided by the sum of the sizes of the matrices. We shard along axis 1 for all parameters except for the second MLP matrix. The derivation of the compression ratio in our setup is given in Table 2. We note that the choice of shard axis changes the compression ratio for the MLP matrices. Finally, this analysis excludes the embeddings, unembeddings, gains, and biases, for which we do not use compression. The total fraction of the bandwidth used by these parameters becomes smaller as the model size is increased.
梯度压缩使用因式分解 ,其中 与 的秩均为 。我们不用单次 all-reduce 传输 ,而是先后用两次更小的 all-reduce 传输 与 。因此压缩比是 、 矩阵大小之和除以 矩阵大小之和。除第二个 MLP 矩阵外,我们都沿轴 1 分片。我们设定下压缩比的推导见表 2。注意分片轴选择会改变 MLP 矩阵的压缩比。最后,该分析排除了不做压缩的嵌入、反嵌入、增益与偏置。随着模型变大,这些参数占用的带宽份额会变小。
E.2 Implementation Details
E.2 实现细节
We describe the steps in our implementation of PowerSGD in detail, since these details were crucial in getting it to work efficiently and reliably at billion-parameter scale.
我们详细描述 PowerSGD 实现中的各步骤,因为这些细节对在十亿参数规模下高效可靠运行至关重要。
- Our training setup uses a combination of parameter sharding and gradient compression, as described in Section 2.5. During backpropagation, while recomputing the activations and computing the gradients for the current resblock, we prefetch the parameters for the preceding resblock using all-gather. Once each GPU has computed the gradient with respect to a full parameter matrix, we compute the average of the slice of the gradient corresponding to the GPU’s parameter shard, and discard the full gradient immediately to conserve memory. This average is taken over all of the GPUs on a machine using reduce-scatter.
- 我们的训练设定结合参数分片与梯度压缩,如第 2.5 节所述。反向传播时,在重算激活并计算当前残差块梯度的同时,用 all-gather 预取前一残差块的参数。一旦每块 GPU 算完对完整参数矩阵的梯度,我们就计算对应该 GPU 参数分片的梯度切片平均值,并立即丢弃完整梯度以省内存。该平均在机器上全部 GPU 间用 reduce-scatter 完成。
- If there are no nonfinite values in the result of the reduce-scatter (which could be caused by overflow in backpropagation or the reduce-scatter), we divide the result by the resblock’s gradient scale, and add it to the error buffer (i.e., the buffer used for error correction). Otherwise, we do nothing and proceed with backpropagation; a single nonfinite value in the gradient means that the entire update will be skipped, which happens about 5% of the time. The error buffer uses the same 1-6-9 format used for the Adam mean, which we describe in Section B.2; the larger exponent range ensures that this division does not result in underflow. Adding the gradients directly to the error buffers avoids redundantly allocating another set of buffers of size equal to the parameter shard gradients.
- 若 reduce-scatter 结果中无非有限值(可能由反向传播或 reduce-scatter 溢出引起),则将其除以该残差块的梯度缩放,并加到误差缓冲(即用于误差校正的缓冲)。否则什么也不做,继续反向传播;梯度中出现单个非有限值意味着整次更新会被跳过,这种情况大约占 。误差缓冲使用第 B.2 节所述与 Adam 均值相同的 1-6-9 格式;更大的指数范围保证这次除法不会下溢。把梯度直接加到误差缓冲,可避免再分配一套与参数分片梯度等大的缓冲。
- Once the reduce-scatter operations for the resblock have finished, we schedule the operations to compute the matrices from the errors buffers and the matrices, whose values are fixed at the start of training (see Section 2.5). Both the and matrices are stored in 1-6-9 format and have their values scaled by predetermined constants, as discussed in Section D.
- 残差块的 reduce-scatter 完成后,我们调度从误差缓冲与 矩阵计算 矩阵的操作; 的值在训练开始时固定(见第 2.5 节)。 与 均以 1-6-9 格式存储,并按预定常数缩放,如第 D 节所述。
- Once each GPU has computed the matrices for the parameter shards in a resblock, they are averaged with the matrices from the GPUs with the same ordinal on all other machines, using a single, grouped all-reduce operation. This all-reduce is carried out in the 1-6-9 format, using a custom kernel. The grouping results in better bandwidth utilization, since it avoids scheduling many all-reduce calls for smaller, individual parameters, each of which carries some overhead. We clamp any infinities in the results of the all-reduce to the maximum value of the 1-6-9 format (which is slightly less than 16), retaining the sign. With our choice of scaling factors for the and matrices, this clamping happens very rarely.
- 每块 GPU 算完某残差块内参数分片的 矩阵后,用一次分组 all-reduce,与所有其他机器上同序号 GPU 的 矩阵取平均。该 all-reduce 以 1-6-9 格式、用定制核执行。分组可提高带宽利用率,因为避免了对许多较小单个参数分别调度 all-reduce 及其开销。我们将 all-reduce 结果中的无穷大钳制到 1-6-9 格式的最大值(略小于 16),并保留符号。以我们对 、 矩阵的缩放选择,这种钳制极少发生。
- Once the all-reduce operation for the matrices for a resblock have finished, we orthogonalize the columns of the resulting matrices. We use a custom Householder orthogonalization kernel rather than Gram-Schmidt, as we found the latter to be numerically unstable. We also add to in order to ensure that the result is not near rank-deficient, where . Here, is a rectangular matrix of the same size as the matrix to which it is added; it contains the identity matrix and has zeros elsewhere. The orthogonalizalied matrices are stored in 1-6-9 format, but without scaling.
- 某残差块的 矩阵 all-reduce 完成后,对其结果矩阵的列做正交化。我们使用定制 Householder 正交化核而非 Gram-Schmidt,因为后者数值不稳定。我们还向 加上 以确保结果不接近亏秩,其中 。此处 是与所加 同尺寸的矩形矩阵:含 单位阵,其余为零。正交化后的 以 1-6-9 格式存储,但不再缩放。
- Once the matrices for a resblock have been orthogonalized, we schedule the operations to compute the new matrices from the error buffers and the matrices.
- 某残差块的 矩阵正交化完成后,我们调度从误差缓冲与 矩阵计算新 矩阵的操作。
- Once the new matrices for a resblock have been computed, we schedule another grouped all-reduce, similar to what we did for the matrices. As in step (4), we clamp all infinities in the results of the all-reduce to the maximum value of the 1-6-9 format, retaining the sign. The error buffers for the resblock have now been decomposed into low-rank factors and .
- 某残差块的新 矩阵算完后,我们再调度一次分组 all-reduce,类似对 所做。与步骤 (4) 一样,将 all-reduce 结果中的无穷大钳制到 1-6-9 最大值并保留符号。至此,该残差块的误差缓冲已被分解为低秩因子 与 。
- The gradients for all parameters that are not compressed are grouped together into a single, 32-bit precision all-reduce. Section D explains why we use 32-bit precision for these parameters and their gradients.
- 所有不做压缩的参数梯度被分到一次 32 位精度的 all-reduce 中。第 D 节说明了为何对这些参数及其梯度使用 32 位。
- Once all GPUs on a machine have finished steps (7) and (8) for every resblock in the model, the values of the and matrices for the same parameter shard on all machines will be identical. We then compute the global gradient norm, which is the sum of two quantities: (a) the sum of the squared Frobenius norms of the matrices over all of the parameter shards on a machine, and (b) the sum of the squared norms of the gradients for the parameter shards that do not use compression, taken over all such parameter shards on a machine. We need to compute this value for gradient clipping (see Section B.2).
- 当一台机器上所有 GPU 对模型每个残差块都完成步骤 (7) 与 (8) 后,各机器上同一参数分片的 、 值将相同。我们随后计算全局梯度范数,它是两项之和:(a) 一台机器上所有参数分片的 矩阵 Frobenius 范数平方之和;(b) 该机上所有不做压缩的参数分片梯度范数平方之和。梯度裁剪需要该值(见第 B.2 节)。
- While computing the global norm, we also synchronize the information from step (2) about which parameter shard gradients contained nonfinite values after the reduce-scatter. After doing this, we have two pieces of information for each parameter shard: (a) whether its error buffer from step (2) contains nonfinite values on the current GPU, and (b) whether or contains nonfinite values. We cannot rely on the values of the and matrices to determine (b), since we clamp infinities as described in step (4). If we find that the gradient with respect to any parameter shard on the machine contains nonfinite values, then we set the global norm to infinity.
- 计算全局范数的同时,我们同步步骤 (2) 关于哪些参数分片梯度在 reduce-scatter 后含非有限值的信息。之后对每个参数分片有两条信息:(a) 当前 GPU 上步骤 (2) 的误差缓冲是否含非有限值;(b) 或 是否含非有限值。我们不能依赖 、 的值来判定 (b),因为步骤 (4) 已钳制无穷大。若发现该机任一参数分片的梯度含非有限值,则把全局范数设为无穷大。
- Once all of the all-reduces have finished and the global norm has been computed, we can apply the parameter updates. Like backpropagation, the parameter updates proceed resblock-by-resblock. The first step is to compute the decompressed gradients by forming the product for all parameters in a given resblock. To avoid overflow, these products are computed in 32-bit precision. We can then apply the Adam update to the parameters using the decompressed gradients and the global norm computed in step (9). If the global norm is not finite, then the update to the parameters and Adam moments is skipped. We note that the decompressed gradient must be divided by the scale of the matrix (the matrix is stored without scaling after orthogonalization).
- 全部 all-reduce 完成且全局范数算完后,即可应用参数更新。与反向传播一样,参数更新按残差块进行。第一步是对给定残差块内全部参数形成乘积 ,得到解压梯度。为避免溢出,这些乘积以 32 位精度计算。然后可用解压梯度与步骤 (9) 的全局范数对参数做 Adam 更新。若全局范数非有限,则跳过对参数与 Adam 矩的更新。注意解压梯度须除以 矩阵的缩放(正交化后 不再缩放存储)。
- The second step is the update to the error buffers. First, we use the results from step (10) to check if the and matrices for a given parameter shard contain only finite values. If this is the case, then we divide the decompressed gradient by the total number of machines, and subtract it from the current value for the error buffer. This sets the error buffer to the difference between the “local” gradient averaged over the GPUs on the machine using reduce-scatter, and the “remote” decompressed gradient (i.e., the “error”). If either or contains nonfinite values, then we check if the error buffer computed in step (2) contains only finite values. If it does, then we preserve its value and do nothing. If it does not, then we set it to zero. The purpose of this tedious logic is to set an error buffer to zero only when we must do so, because it has been contaminated with nonfinite values. We found that error buffers getting set to zero too frequently by gradient scaling events leads to performance regressions.
- 第二步是更新误差缓冲。首先用步骤 (10) 的结果检查给定参数分片的 、 是否仅含有限值。若是,则把解压梯度除以机器总数,再从当前误差缓冲中减去。这将误差缓冲设为:经 reduce-scatter 在机器 GPU 上平均的「本地」梯度,与「远程」解压梯度之差(即「误差」)。若 或 含非有限值,则检查步骤 (2) 算出的误差缓冲是否仅含有限值;若是则保留其值不做改动;若否,则置零。这套繁琐逻辑的目的是:仅在必须时(误差缓冲已被非有限值污染)才把误差缓冲置零。我们发现,因梯度缩放事件过于频繁地把误差缓冲置零会导致性能回退。
- The parameter shards whose gradients are not compressed are updated separately.
- 梯度不做压缩的参数分片另行更新。
We also note the following important optimizations:
我们还指出以下重要优化:
- There are several opportunities for overlap between compute and communication in the above steps. For example, while we are running step (2) for resblock , we can proceed to steps (3)–(8) for all resblocks . Exploiting opportunities for overlap is necessary to achieve good performance.
- 上述步骤中有多处计算与通信可重叠。例如,对残差块 执行步骤 (2) 时,可同时对所有 的残差块推进步骤 (3)–(8)。利用重叠机会对获得良好性能是必要的。
- We throttle specific operations that are liable to exhaust all available memory. For example, we only prefetch the parameters from the preceding resblock when the reduce-scatter operations have finished for the current one. Otherwise, we risk running out of memory by holding on to the full parameters. We also throttle the Adam updates, so that we do not decompress all of the gradients at once.
- 我们对容易耗尽可用内存的特定操作做节流。例如,仅当当前残差块的 reduce-scatter 完成后才预取前一残差块参数;否则可能因一直持有完整参数而内存不足。我们也节流 Adam 更新,以免一次性解压全部梯度。
- There are two places in the implementation where the transposition matters: (a) the choice of shard axis for the MLP matrices and (b) whether we compute the low-rank factorization for a gradient or its transpose. The former influences the bandwidth analysis, which we present in Section E.1. The latter influences the cost of the orthogonalization. Suppose that the gradient is and its low-rank factors and are and , respectively, with . To make orthogonalization cheaper, we transpose appropriately so that . At first glance, it may seem like a limitation that the NCCL all-gather and reduce-scatter primitives shard along axis 0 only. We may need to transpose some matrices before and after communication operations because of (a) and (b), which would require additional time and potentially special care to avoid out-of-memory errors. In fact, we never actually needed to do this. This is because we stored some of the parameters in their transposed formats and exploited the transpose_a and transpose_b parameters of the matrix multiplication kernels used in forward propagation, backpropagation, and steps (1)–(13) above. This allowed us to avoid explicit transposition while retaining the freedom to choose how to handle (a) and (b).
- 实现中有两处转置很重要:(a) MLP 矩阵的分片轴选择;(b) 对梯度还是其转置做低秩分解。前者影响第 E.1 节的带宽分析;后者影响正交化成本。设梯度 为 ,低秩因子 、 分别为 与 ,且 。为降低正交化成本,我们适当转置 使 。乍看之下,NCCL 的 all-gather 与 reduce-scatter 原语只沿轴 0 分片似乎是限制。由于 (a)(b),我们可能需要在通信前后转置某些矩阵,既耗时又可能需特别小心以免内存不足。实际上我们从未真正需要显式转置:因为部分参数以转置格式存储,并利用前向、反向以及上述步骤 (1)–(13) 中矩阵乘核的 transpose_a、transpose_b 参数。这样既避免显式转置,又保留处理 (a)(b) 的自由度。
- In step (12) above, we note that setting the error buffers to zero too often can cause performance regressions. We wanted to avoid doing this when resuming training from a checkpoint, which happens more frequently for larger jobs as it is likely that a machine will periodically fail. Naively, this would require uploading the error buffers from all of the machines along with the model checkpoints. Since we use a total of 128 machines for training, this would lead to 128 times greater storage usage, which is extremely wasteful. Fortunately, this is unnecessary, as error correction depends only on the sum of the error buffers. This property follows from linearity and the sequence of operations used by PowerSGD. Hence, it suffices to store the sums of the errors buffers taken across all GPUs with the same ordinal. When resuming from a checkpoint, we can divide the error buffers by the total number of machines and broadcast them.
- 步骤 (12) 中我们指出,过于频繁地将误差缓冲置零会导致性能回退。我们希望从检查点恢复训练时也避免这样做;对更大作业这更常见,因为机器会周期性故障。朴素做法是把所有机器的误差缓冲与模型检查点一并上传。我们用 128 台机器训练,存储用量会放大 128 倍,极为浪费。幸运的是这并不必要:误差校正只依赖于误差缓冲之和。该性质由线性性与 PowerSGD 所用运算序列得出。因此只需存储按同序号 GPU 跨机求和后的误差缓冲。从检查点恢复时,把误差缓冲除以机器总数再广播即可。
Appendix F Details for Human Evaluation Experiments
附录 F 人工评测实验细节
Figure 13: Example task interface shown to workers.
图 13:展示给工人的任务界面示例。
We start with a list of captions and generate one sample image per model per caption. Captions and sample images are then used to create image comparison tasks per experiment, which we submitted to Amazon’s Mechanical Turk. Each task was answered by five distinct workers. Workers were asked to compare two images and answer two questions about them: (1) which image is most realistic, and (2) which image best matches the shared caption. The experimental setup provided to workers is shown in Figure 13. One worker’s answers were disqualified due to a high rate of disagreement with other workers combined with a fast answer velocity (with many submission times under 4 seconds); all other worker answers were kept.
我们从 条描述出发,对每个模型每条描述生成一张样本图像。再用描述与样本图像为每次实验创建 个图像对比任务,提交到 Amazon Mechanical Turk。每个任务由五名不同工人作答。工人需比较两张图像并回答两个问题:(1) 哪张更真实;(2) 哪张与共享描述更匹配。提供给工人的实验界面见图 13。一名工人因与其他工人分歧率高且作答速度过快(许多提交时间不足 4 秒)被取消资格;其余工人答案全部保留。
Appendix G Zero-Shot Image-to-Image Translation
附录 G 零样本图到图翻译
(a) “the exact same cat on the top as a sketch on the bottom”
Figure 14 shows further examples of zero-shot image-to-image translation, which we discussed in Section 3.3. We did not anticipate that this capability would emerge, and made no modifications to the training procedure to encourage it.
图 14 给出更多零样本图到图翻译例子,我们在第 3.3 节讨论过。我们并未预料到该能力会出现,也未修改训练流程去鼓励它。