Conceptual Captions: A Cleaned, Hypernymed, Image Alt-text Dataset For Automatic Image Captioning
Conceptual Captions: A Cleaned, Hypernymed, Image Alt-text Dataset For Automatic Image Captioning
Google AI
Venice, CA 90291
{piyushsharma,dingnan,seabass,rsoricut}@google.com
Proceedings of the 56th Annual Meeting of the Association for Computational Linguistics (Long Papers), pages 2556–2565
Melbourne, Australia, July 15 - 20, 2018. ©2018 Association for Computational Linguistics
Abstract
摘要
We present a new dataset of image caption annotations, Conceptual Captions, which contains an order of magnitude more images than the MS-COCO dataset (Lin et al., 2014) and represents a wider variety of both images and image caption styles. We achieve this by extracting and filtering image caption annotations from billions of webpages. We also present quantitative evaluations of a number of image captioning models and show that a model architecture based on Inception-ResNet-v2 (Szegedy et al., 2016) for image-feature extraction and Transformer (Vaswani et al., 2017) for sequence modeling achieves the best performance when trained on the Conceptual Captions dataset.
我们介绍一套新的图像描述标注数据集 Conceptual Captions。它的图像数量比 MS-COCO 数据集(Lin et al., 2014)高一个数量级,并且在图像和描述风格上都更加多样。我们通过从数十亿个网页中抽取并过滤图像描述标注来做成这一点。我们还对若干图像描述模型做了定量评价,并表明:用 Inception-ResNet-v2(Szegedy et al., 2016)抽取图像特征、用 Transformer(Vaswani et al., 2017)做序列建模的结构,在 Conceptual Captions 上训练时取得了最好的成绩。
1 Introduction
1 引言
Automatic image description is the task of producing a natural-language utterance (usually a sentence) which correctly reflects the visual content of an image. This task has seen an explosion in proposed solutions based on deep learning architectures (Bengio, 2009), starting with the winners of the 2015 COCO challenge (Vinyals et al., 2015a; Fang et al., 2015), and continuing with a variety of improvements (see e.g. Bernardi et al. (2016) for a review). Practical applications of automatic image description systems include leveraging descriptions for image indexing or retrieval, and helping those with visual impairments by transforming visual signals into information that can be communicated via text-to-speech technology. The scientific challenge is seen as aligning, exploiting, and pushing further the latest improvements at the intersection of Computer Vision and Natural Language Processing.
自动图像描述这项任务,是要生成一句自然语言(通常是一个句子),正确反映一幅图像的视觉内容。自 2015 年 COCO 挑战赛的优胜系统开始(Vinyals et al., 2015a; Fang et al., 2015),基于深度学习结构(Bengio, 2009)的方案大量涌现,随后又出现了各种各样的改进(综述可见 Bernardi et al., 2016)。自动图像描述系统的实际应用包括:用描述来做图像索引或检索,以及把视觉信号转成可用语音合成传达的信息,以帮助有视力障碍的人。在科学上,这项挑战被看作是在计算机视觉与自然语言处理的交汇处,把最新进展对齐、利用并继续向前推进。
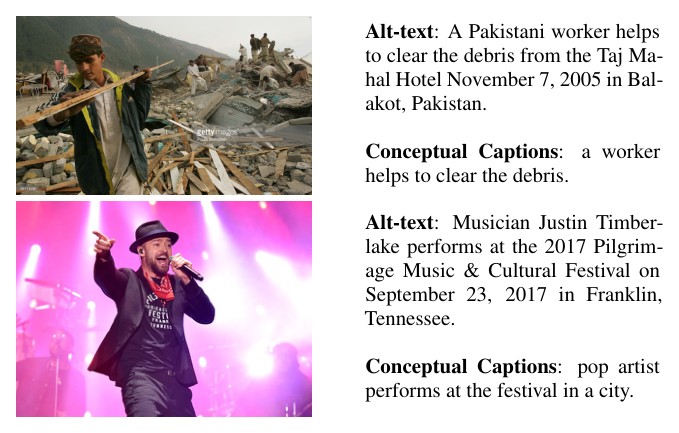
Figure 1: Examples of images and image descriptions from the Conceptual Captions dataset; we start from existing alt-text descriptions, and automatically process them into Conceptual Captions with a balance of cleanliness, informativeness, fluency, and learnability.
图 1:Conceptual Captions 数据集中的图像与图像描述例子;我们从已有的 alt-text 描述出发,自动把它们加工成在干净程度、信息量、流畅性和可学习性之间取得平衡的 Conceptual Captions。
There are two main categories of advances responsible for increased interest in this task. The first is the availability of large amounts of annotated data. Relevant datasets include the ImageNet dataset (Deng et al., 2009), with over 14 million images and 1 million bounding-box annotations, and the MS-COCO dataset (Lin et al., 2014), with 120,000 images and 5-way image-caption annotations. The second is the availability of powerful modeling mechanisms such as modern Convolutional Neural Networks (e.g. Krizhevsky et al. (2012)), which are capable of converting image pixels into high-level features with no manual feature-engineering.
对这项任务兴趣上升,主要有两类进展。第一是大量标注数据的出现。相关数据集包括 ImageNet(Deng et al., 2009),其中有超过 1,400 万张图像和 100 万条边界框标注,以及 MS-COCO(Lin et al., 2014),其中有 120,000 张图像和每图 5 条描述标注。第二是强大建模机制的出现,例如现代卷积神经网络(如 Krizhevsky et al., 2012),它们能够在不做人工特征工程的情况下,把图像像素转成高层特征。
In this paper, we make contributions to both the data and modeling categories. First, we present a new dataset of caption annotations, Conceptual Captions (Fig. 1), which has an order of magnitude more images than the COCO dataset. Conceptual Captions consists of about 3.3M image, description pairs. In contrast with the curated style of the COCO images, Conceptual Captions images and their raw descriptions are harvested from the web, and therefore represent a wider variety of styles. The raw descriptions are harvested from the Alt-text HTML attribute associated with web images. We developed an automatic pipeline (Fig. 2) that extracts, filters, and transforms candidate image/caption pairs, with the goal of achieving a balance of cleanliness, informativeness, fluency, and learnability of the resulting captions.
在本文中,我们在数据和模型两类问题上都有贡献。首先,我们给出一套新的描述标注数据集,即 Conceptual Captions(图 1),其图像数量比 COCO 数据集高一个数量级。Conceptual Captions 大约包含 330 万个 图像, 描述 对。与 COCO 图像那种经过策划的风格不同,Conceptual Captions 的图像及其原始描述都是从网上采集的,因而风格更为多样。原始描述来自网页图像所附的 Alt-text HTML 属性。我们开发了一套自动管线(图 2),对候选的图像/描述对进行抽取、过滤和变换,目标是使最终描述在干净程度、信息量、流畅性和可学习性之间取得平衡。
As a contribution to the modeling category, we evaluate several image-captioning models. Based on the findings of Huang et al. (2016), we use Inception-ResNet-v2 (Szegedy et al., 2016) for image-feature extraction, which confers optimization benefits via residual connections and computationally efficient Inception units. For caption generation, we use both RNN-based (Hochreiter and Schmidhuber, 1997) and Transformer-based (Vaswani et al., 2017) models. Our results indicate that Transformer-based models achieve higher output accuracy; combined with the reports of Vaswani et al. (2017) regarding the reduced number of parameters and FLOPs required for training & serving (compared with RNNs), models such as T2T (Section 4) push forward the performance on image-captioning and deserve further attention.
作为对模型一侧的贡献,我们评价了若干图像描述模型。根据 Huang et al. (2016) 的发现,我们用 Inception-ResNet-v2(Szegedy et al., 2016)抽取图像特征,它借助残差连接和计算上更高效的 Inception 单元,给优化带来好处。在描述生成上,我们同时使用基于 RNN(Hochreiter and Schmidhuber, 1997)和基于 Transformer(Vaswani et al., 2017)的模型。结果表明,基于 Transformer 的模型输出精度更高;再结合 Vaswani et al. (2017) 关于训练与服务所需参数量和 FLOPs 少于 RNN 的报告,像 T2T(第 4 节)这样的模型把图像描述的性能又向前推了一步,值得继续关注。
2 Related Work
2 相关工作
Automatic image captioning has a long history (Hodosh et al., 2013; Donahue et al., 2014; Karpathy and Fei-Fei, 2015; Kiros et al., 2015). It has accelerated with the success of Deep Neural Networks (Bengio, 2009) and the availability of annotated data as offered by datasets such as Flickr30K (Young et al., 2014) and MS-COCO (Lin et al., 2014).
自动图像描述已有相当长的历史(Hodosh et al., 2013; Donahue et al., 2014; Karpathy and Fei-Fei, 2015; Kiros et al., 2015)。随着深度神经网络(Bengio, 2009)的成功,以及 Flickr30K(Young et al., 2014)和 MS-COCO(Lin et al., 2014)这类标注数据的出现,这一方向明显加快。
The COCO dataset is not large (order of images), given the training needs of DNNs. In spite of that, it has been very popular, in part because it offers annotations for images with non-iconic views, or non-canonical perspectives of objects, and therefore reflects the composition of everyday scenes (the same is true about Flickr30K (Young et al., 2014)). COCO annotations–category labeling, instance spotting, and instance segmentation–are done for all objects in an image, including those in the background, in a cluttered environment, or partially occluded. Its images are also annotated with captions, i.e. sentences produced by human annotators to reflect the visual content of the images in terms of objects and their actions or relations.
就深度网络的训练需求而言,COCO 数据集并不算大(约 张图像)。尽管如此,它仍然非常流行,部分原因是它为非标志性视角、或物体的非典型视角提供了标注,因而更能反映日常场景的构成(Flickr30K 也是如此,Young et al., 2014)。COCO 的标注——类别标注、实例点选和实例分割——覆盖图像中的全部物体,包括位于背景中、处于杂乱环境里、或被部分遮挡的物体。它的图像还带有描述,也就是由人工标注员写出的句子,用来从物体及其动作或关系的角度反映图像的视觉内容。
A large number of DNN models for image caption generation have been trained and evaluated using COCO captions (Vinyals et al., 2015a; Fang et al., 2015; Xu et al., 2015; Ranzato et al., 2015; Yang et al., 2016; Liu et al., 2017; Ding and Soricut, 2017). These models are inspired by sequence-to-sequence models (Sutskever et al., 2014; Bahdanau et al., 2015) but use CNN-based encodings instead of RNNs (Hochreiter and Schmidhuber, 1997; Chung et al., 2014). Recently, the Transformer architecture (Vaswani et al., 2017) has been shown to be a viable alternative to RNNs (and CNNs) for sequence modeling. In this work, we evaluate the impact of the Conceptual Captions dataset on the image captioning task using models that combine CNN, RNN, and Transformer layers.
大量用于图像描述生成的深度网络模型,都是用 COCO 描述来训练和评价的(Vinyals et al., 2015a; Fang et al., 2015; Xu et al., 2015; Ranzato et al., 2015; Yang et al., 2016; Liu et al., 2017; Ding and Soricut, 2017)。这些模型受到序列到序列模型的启发(Sutskever et al., 2014; Bahdanau et al., 2015),但用基于 CNN 的编码来代替 RNN(Hochreiter and Schmidhuber, 1997; Chung et al., 2014)。近来,Transformer 结构(Vaswani et al., 2017)已被证明可以作为 RNN(以及 CNN)在序列建模上的可行替代。在本工作中,我们用结合了 CNN、RNN 和 Transformer 层的模型,来评价 Conceptual Captions 数据集对图像描述任务的影响。
Also related to this work is the Pinterest image and sentence-description dataset (Mao et al., 2016). It is a large dataset (order of examples), but its text descriptions do not strictly reflect the visual content of the associated image, and therefore cannot be used directly for training image-captioning models.
与本工作相关的还有 Pinterest 的图像与句子描述数据集(Mao et al., 2016)。它的规模很大(约 条例子),但其文本描述并不严格反映所配图像的视觉内容,因而不能直接用来训练图像描述模型。
3 Conceptual Captions Dataset Creation
3 Conceptual Captions 数据集的创建
The Conceptual Captions dataset is programmatically created using a Flume (Chambers et al., 2010) pipeline. This pipeline processes billions of Internet webpages in parallel. From these webpages, it extracts, filters, and processes candidate image, caption pairs. The filtering and processing steps are described in detail in the following sections.
Conceptual Captions 数据集是用一条 Flume(Chambers et al., 2010)管线以程序化方式创建的。这条管线并行处理数十亿个互联网网页。它从这些网页中抽取、过滤并处理候选的 图像, 描述 对。过滤与处理步骤将在下面各节详细说明。
Image-based Filtering
基于图像的过滤
The first filtering stage, image-based filtering, discards images based on encoding format, size, aspect ratio, and offensive content. It only keeps JPEG images where both dimensions are greater than 400 pixels, and the ratio of larger to smaller dimension is no more than 2. It excludes images that trigger pornography or profanity detectors. These filters discard more than 65% of the candidates.
第一阶段是基于图像的过滤,按编码格式、尺寸、长宽比和不良内容丢弃图像。它只保留两个边都大于 400 像素、且较长边与较短边之比不超过 2 的 JPEG 图像,并排除触发色情或脏话检测器的图像。这些过滤器丢掉了超过 65% 的候选。
Text-based Filtering
基于文本的过滤
The second filtering stage, text-based filtering, harvests Alt-text from HTML webpages. Alt-text generally accompanies images, and intends to describe the nature or the content of the image. Because these Alt-text values are not in any way restricted or enforced to be good image descriptions, many of them have to be discarded, e.g., search engine optimization (SEO) terms, or Twitter hash-tag terms.
第二阶段是基于文本的过滤,从 HTML 网页中采集 Alt-text。Alt-text 通常伴随图像出现,本意是说明图像的性质或内容。可这些 Alt-text 并没有被以任何方式限制或强制必须是好的图像描述,因此其中许多必须丢掉,例如搜索引擎优化(SEO)用语,或 Twitter 话题标签。
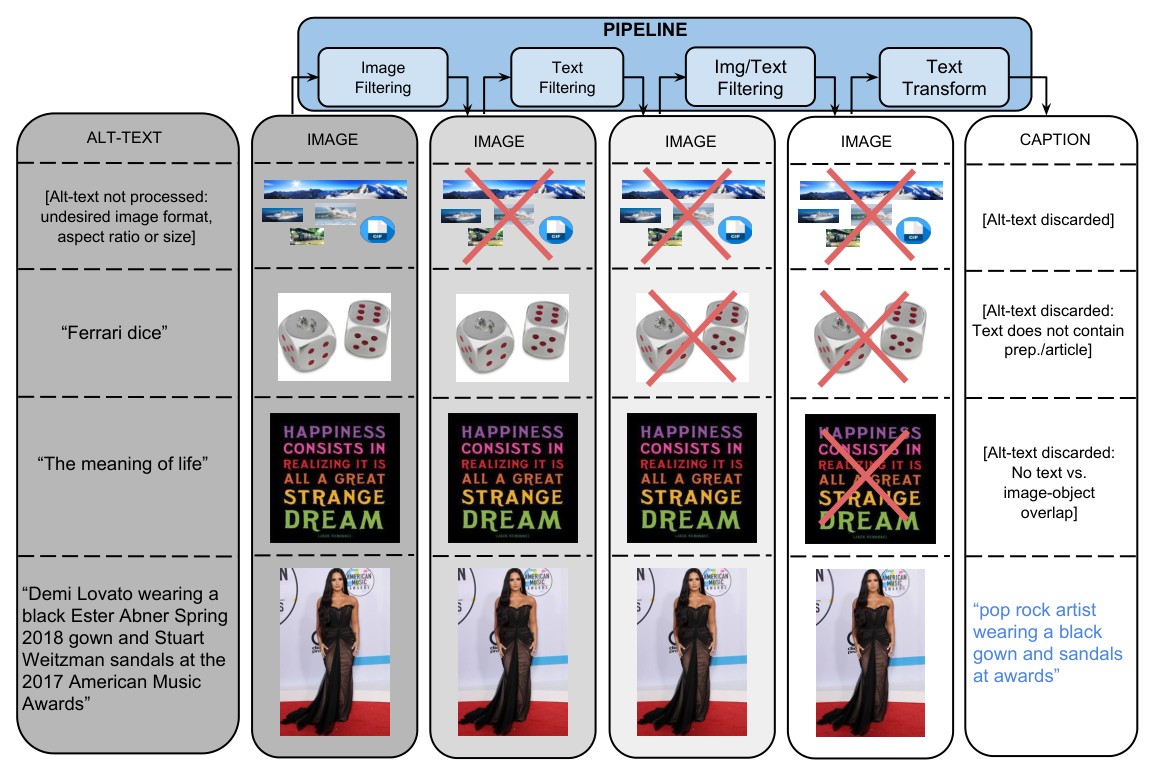
Figure 2: Conceptual Captions pipeline steps with examples and final output.
图 2:Conceptual Captions 管线各步骤,配有例子和最终输出。
We analyze candidate Alt-text using the Google Cloud Natural Language APIs, specifically part-of-speech (POS), sentiment/polarity, and pornography/profanity annotations. On top of these annotations, we have the following heuristics:
我们用 Google Cloud Natural Language API 分析候选 Alt-text,具体使用词性(POS)、情感/极性,以及色情/脏话标注。在这些标注之上,我们还有如下启发式规则:
• a well-formed caption should have a high unique word ratio covering various POS tags; candidates with no determiner, no noun, or no preposition are discarded; candidates with a high noun ratio are also discarded;
• 形态良好的描述应有较高的独特词比例,并覆盖多种词性;没有限定词、没有名词、或没有介词的候选被丢弃;名词比例过高的候选也被丢弃;
• candidates with a high rate of token repetition are discarded;
• 记号重复率过高的候选被丢弃;
• capitalization is a good indicator of well-composed sentences; candidates where the first word is not capitalized, or with too high capitalized-word ratio are discarded;
• 大小写是句子是否写得像样的一个好指标;首词未大写,或大写词比例过高的候选被丢弃;
• highly unlikely tokens are a good indicator of not desirable text; we use a vocabulary of 1B token types, appearing at least 5 times in the English Wikipedia, and discard candidates that contain tokens that are not found in this vocabulary.
• 极不可能出现的记号,往往说明文本并不理想;我们使用一个包含 10 亿类记号的词表 ,这些记号在英语维基百科中至少出现 5 次,并丢弃含有该词表中找不到的记号的候选。
• candidates that score too high or too low on the polarity annotations, or trigger the pornography/profanity detectors, are discarded;
• 极性标注分数过高或过低,或触发色情/脏话检测器的候选被丢弃;
• predefined boiler-plate prefix/suffix sequences matching the text are cropped, e.g. “click to enlarge picture”, “stock photo”; we also drop text which begins/ends in certain patterns, e.g. “embedded image permalink”, “profile photo”.
• 与文本匹配的预定义套话前缀/后缀会被裁掉,例如 “click to enlarge picture”、“stock photo”;我们也丢掉以特定模式开头或结尾的文本,例如 “embedded image permalink”、“profile photo”。
These filters only allow around 3% of the incoming candidates to pass to the later stages.
这些过滤器只让大约 3% 的进入候选进入后续阶段。
Image&Text-based Filtering
基于图像与文本的过滤
In addition to the separate filtering based on image and text content, we filter out candidates for which none of the text tokens can be mapped to the content of the image. To this end, we use classifiers available via the Google Cloud Vision APIs to assign class labels to images, using an image classifier with a large number of labels (order of magnitude of ). Notably, these labels are also 100% covered by the token types.
除了分别基于图像内容和文本内容的过滤之外,我们还丢掉那些文本记号完全无法映射到图像内容的候选。为此,我们使用 Google Cloud Vision API 中的分类器为图像分配类别标签,所用图像分类器的标签数量很大(约 量级)。值得注意的是,这些标签也被 的记号类型 100% 覆盖。
Images are generally assigned between 5 to 20 labels, though the exact number depends on the image. We match these labels against the candidate text, taking into account morphology-based stemming as provided by the text annotation. Candidate image, caption pairs with no overlap are discarded. This filter discards around 60% of the incoming candidates.
图像通常会被分到 5 到 20 个标签,具体数目取决于图像本身。我们把这些标签与候选文本匹配,并计入文本标注所提供的、基于形态学的词干处理。没有重叠的候选 图像, 描述 对被丢弃。这一过滤器丢掉了大约 60% 的进入候选。
Text Transformation with Hypernymization
带上位词化的文本变换
In the current version of the dataset, we considered over 5 billion images from about 1 billion English webpages. The filtering criteria above are designed to be high-precision (which comes with potentially low recall). From the original input candidates, only 0.2% image, caption pairs pass the filtering criteria described above.
在当前版本的数据集中,我们考虑了来自约 10 亿个英文网页的超过 50 亿张图像。上面的过滤标准被设计成高精度的(因而召回可能较低)。在最初的输入候选中,只有 0.2% 的 图像, 描述 对通过了上述过滤标准。
While the remaining candidate captions tend to be appropriate Alt-text image descriptions (see Alt-text in Fig. 1), a majority of these candidate captions contain proper names (people, venues, locations, etc.), which would be extremely difficult to learn as part of the image captioning task. To give an idea of what would happen in such cases, we train an RNN-based captioning model (see Section 4) on non-hypernymized Alt-text data and present an output example in Fig. 3. If automatic determination of person identity, location, etc. is needed, it should be attempted as a separate task and would need to leverage image meta-information about the image (e.g. location).
剩下的候选描述往往已经是合适的 Alt-text 图像说明(见图 1 中的 Alt-text),但其中大多数仍含有专名(人物、场所、地点等),这些作为图像描述任务的一部分会极难学会。为了说明在这种情况下会发生什么,我们用未经上位词化的 Alt-text 数据训练了一个基于 RNN 的描述模型(见第 4 节),并在图 3 中给出一个输出例子。如果需要自动判定人物身份、地点等,那应作为单独任务来做,并且需要利用关于图像的元信息(例如位置)。
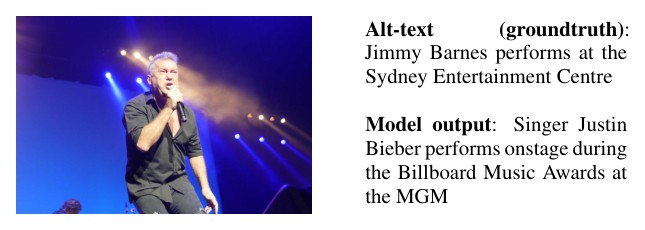
Figure 3: Example of model output trained on clean, non-hypernymized Alt-text data.
图 3:在干净、但未做上位词化的 Alt-text 数据上训练的模型输出例子。
Using the Google Cloud Natural Language APIs, we obtain named-entity and syntactic-dependency annotations. We then use the Google Knowledge Graph (KG) Search API to match the named-entities to KG entries and exploit the associated hypernym terms. For instance, both “Harrison Ford” and “Calista Flockhart” identify as named-entities, so we match them to their corresponding KG entries. These KG entries have “actor” as their hypernym, so we replace the original surface tokens with that hypernym.
我们使用 Google Cloud Natural Language API 得到命名实体和句法依存标注,再用 Google Knowledge Graph(KG)Search API 把命名实体匹配到知识图谱条目,并利用其关联的上位词。例如,“Harrison Ford” 和 “Calista Flockhart” 都被识别为命名实体,于是我们把它们匹配到相应的知识图谱条目。这些条目的上位词是 “actor”,因此我们用该上位词替换原来的表层记号。
The following steps are applied to achieve text transformations:
为实现文本变换,我们采取下列步骤:
• noun modifiers of certain types (proper nouns, numbers, units) are removed;
• 去掉某些类型的名词修饰语(专有名词、数字、单位);
• dates, durations, and preposition-based locations (e.g., “in Los Angeles”) are removed;
• 去掉日期、时长,以及介词性地点(例如 “in Los Angeles”);
• named-entities are identified, matched against the KG entries, and substitute with their hypernym;
• 识别命名实体,将其与知识图谱条目匹配,并用其上位词替换;
• resulting coordination noun-phrases with the same head (e.g., “actor and actor”) are resolved into a single-head, pluralized form (e.g., “actors”);
• 由此产生的、中心词相同的并列名词短语(例如 “actor and actor”)被归并成单一中心、复数形式(例如 “actors”);
Around 20% of samples are discarded during this transformation because it can leave sentences too short or inconsistent.
在这一变换过程中,大约 20% 的样本被丢弃,因为它可能使句子过短或不连贯。
Finally, we perform another round of text analysis and entity resolution to identify concepts with low-count. We cluster all resolved entities (e.g., “actor”, “dog”, “neighborhood”, etc.) and keep only the candidates for which all detected types have a count of over 100 (around 55% of the candidates). These remaining image, caption pairs contain around 16,000 entity types, guaranteed to be well represented in terms of number of examples. Table 1 contains several examples of before/after-transformation pairs.
最后,我们再做一轮文本分析和实体解析,以找出计数偏低的概念。我们把所有已解析的实体聚类(例如 “actor”、“dog”、“neighborhood” 等),只保留所检测到的全部类型计数都超过 100 的候选(约占候选的 55%)。这些留下来的 图像, 描述 对大约包含 16,000 种实体类型,并保证在例子数量上有充分表示。表 1 给出了若干变换前后的对照例子。
Table 1: Examples of Conceptual Captions as derived from their original Alt-text versions.
| Original Alt-text | Harrison Ford and Calista Flockhart attend the premiere of ‘Hollywood Homicide’ at the 29th American Film Festival September 5, 2003 in Deauville, France. |
| Conceptual Captions | actors attend the premiere at festival. |
| what-happened | “Harrison Ford and Calista Flockhart” mapped to “actors”; name, location, and date dropped. |
| Original Alt-text | Side view of a British Airways Airbus A319 aircraft on approach to land with landing gear down - Stock Image |
| Conceptual Captions | side view of an aircraft on approach to land with landing gear down |
| what-happened | phrase “British Airways Airbus A319 aircraft” mapped to “aircraft”; boilerplate removed. |
| Original Alt-text | Two sculptures by artist Duncan McKellar adorn trees outside the derelict Norwich Union offices in Bristol, UK - Stock Image |
| Conceptual Captions | sculptures by person adorn trees outside the derelict offices |
| what-happened | object count (e.g. “Two”) dropped; proper noun-phrase hypernymized to “person”; proper-noun modifiers dropped; location dropped; boilerplate removed. |
表 1:由原始 Alt-text 得到 Conceptual Captions 的例子。
| 原始 Alt-text | Harrison Ford and Calista Flockhart attend the premiere of ‘Hollywood Homicide’ at the 29th American Film Festival September 5, 2003 in Deauville, France. |
| Conceptual Captions | actors attend the premiere at festival. |
| 发生了什么 | “Harrison Ford and Calista Flockhart” 被映射为 “actors”;姓名、地点和日期被去掉。 |
| 原始 Alt-text | Side view of a British Airways Airbus A319 aircraft on approach to land with landing gear down - Stock Image |
| Conceptual Captions | side view of an aircraft on approach to land with landing gear down |
| 发生了什么 | 短语 “British Airways Airbus A319 aircraft” 被映射为 “aircraft”;套话被去掉。 |
| 原始 Alt-text | Two sculptures by artist Duncan McKellar adorn trees outside the derelict Norwich Union offices in Bristol, UK - Stock Image |
| Conceptual Captions | sculptures by person adorn trees outside the derelict offices |
| 发生了什么 | 物体计数(例如 “Two”)被去掉;专有名词短语被上位词化为 “person”;专有名词修饰语被去掉;地点被去掉;套话被去掉。 |
Conceptual Captions Quality
Conceptual Captions 的质量
To evaluate the precision of our pipeline, we consider a random sample of 4K examples extracted from the test split of the Conceptual Captions dataset. We perform a human evaluation on this sample, using the same methodology described in Section 5.4.
为了评价管线的精度,我们从 Conceptual Captions 数据集的测试划分中随机抽出 4,000 条例子,并用第 5.4 节所述的同一套方法对这个样本做人工评价。
Table 2: Human evaluation results on a sample from Conceptual Captions.
| | GOOD (out of 3) | | |
| | 1+ | 2+ | 3 |
| Conceptual Captions | 96.9% | 90.3% | 78.5% |
表 2:在 Conceptual Captions 一个样本上的人工评价结果。
| | GOOD(满分 3) | | |
| | 1+ | 2+ | 3 |
| Conceptual Captions | 96.9% | 90.3% | 78.5% |
The results are presented in Table 2 and show that, out of 3 annotations, over 90% of the captions receive a majority (2+) of GOOD judgments. This indicates that the Conceptual Captions pipeline, though involving extensive algorithmic processing, produces high-quality image captions.
结果见表 2:在 3 次标注中,超过 90% 的描述获得了多数(2+)的 GOOD 判断。这表明,尽管 Conceptual Captions 管线包含大量算法处理,它仍然能产生高质量的图像描述。
Table 3: Statistics over Train/Validation/Test splits for Conceptual Captions.
| | Examples | Unique Tokens | Tokens/Caption | | |
| | | | Mean | StdDev | Median |
| Train | 3,318,333 | 51,201 | 10.3 | 4.5 | 9.0 |
| Valid. | 28,355 | 13,063 | 10.3 | 4.6 | 9.0 |
| Test | 22,530 | 11,731 | 10.1 | 4.5 | 9.0 |
表 3:Conceptual Captions 训练/验证/测试划分上的统计。
| | 例子数 | 独特记号数 | 每条描述的记号数 | | |
| | | | 均值 | 标准差 | 中位数 |
| 训练 | 3,318,333 | 51,201 | 10.3 | 4.5 | 9.0 |
| 验证 | 28,355 | 13,063 | 10.3 | 4.6 | 9.0 |
| 测试 | 22,530 | 11,731 | 10.1 | 4.5 | 9.0 |
We present in Table 3 statistics over the Train/Validation/Test splits for the Conceptual Captions dataset. The training set consists of slightly over 3.3M examples, while there are slightly over 28K examples in the validation set and 22.5K examples in the test set. The size of the training set vocabulary (unique tokens) is 51,201. Note that the test set has been cleaned using human judgements (2+ GOOD), while both the training and validation splits contain all the data, as produced by our automatic pipeline. The mean/stddev/median statistics for tokens-per-caption over the data splits are consistent with each other, at around 10.3/4.5/9.0, respectively.
表 3 给出了 Conceptual Captions 数据集在训练/验证/测试划分上的统计。训练集略多于 330 万条例子,验证集约 2.8 万条,测试集约 2.25 万条。训练集词表(独特记号)大小为 51,201。需要说明的是,测试集已用人工判断做过清理(2+ GOOD),而训练集和验证集则包含自动管线产出的全部数据。各划分上每条描述的记号数均值/标准差/中位数彼此一致,分别大约为 10.3/4.5/9.0。
4 Image Captioning Models
4 图像描述模型
In order to assess the impact of the Conceptual Captions dataset, we consider several image captioning models previously proposed in the literature. These models can be understood using the illustration in Fig. 4, as they mainly differ in the way in which they instantiate some of these components.
为了评估 Conceptual Captions 数据集的影响,我们考察了文献中先前提出的若干图像描述模型。这些模型可以用图 4 来理解,因为它们的主要差别,在于如何实例化其中的某些组件。
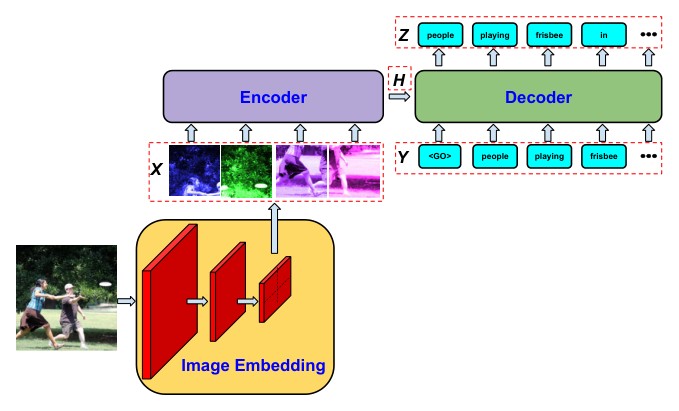
Figure 4: The main model components.
图 4:模型的主要组件。
There are three main components to this architecture:
这一结构有三个主要组件:
• A deep CNN that takes a (preprocessed) image and outputs a vector of image embeddings .
• 一个深度 CNN,它接收一幅(经过预处理的)图像,并输出图像嵌入向量 。
• An Encoder module that takes the image embeddings and encodes them into a tensor .
• 一个编码器模块,它接收图像嵌入并把它们编码成张量 。
• A Decoder model that generates outputs at each step , conditioned on as well as the decoder inputs .
• 一个解码器模型,它在每一步 生成输出 ,条件是 以及解码器输入 。
We explore two main instantiations of this architecture. One uses RNNs with LSTM cells (Hochreiter and Schmidhuber, 1997) to implement the and functions, corresponding to the Show-And-Tell (Vinyals et al., 2015b) model. The other uses Transformer self-attention networks (Vaswani et al., 2017) to implement and . All models in this paper use Inception-ResNet-v2 as the CNN component (Szegedy et al., 2016).
我们对这一结构探索了两种主要的实例化方式。一种用带 LSTM 单元的 RNN(Hochreiter and Schmidhuber, 1997)来实现 和 ,对应于 Show-And-Tell(Vinyals et al., 2015b)模型。另一种用 Transformer 自注意力网络(Vaswani et al., 2017)来实现 和 。本文中的所有模型都以 Inception-ResNet-v2 作为 CNN 组件(Szegedy et al., 2016)。
4.1 RNN-based Models
4.1 基于 RNN 的模型
Our instantiation of the RNN-based model is close to the Show-And-Tell (Vinyals et al., 2015b) model.
我们基于 RNN 的模型实例,接近于 Show-And-Tell(Vinyals et al., 2015b)模型。
In the original Show-And-Tell model, a single image embedding of the entire image is fed to the first cell of an RNN, which is also used for text generation. In our model, a single image embedding is fed to an with only one cell, and then a different is used for text generation. We tried both single image (1x1) embeddings and 8x8 partitions of the image, where each partition has its own embedding. In the 8x8 case, image embeddings are fed in a sequence to the . In both cases, we apply plain RNNs without cross attention, same as the Show-And-Tell model. RNNs with cross attention were used in the Show-Attend-Tell model (Xu et al., 2015), but we find its performance to be inferior to the Show-And-Tell model.
在原来的 Show-And-Tell 模型中,整幅图像的单个图像嵌入被送入一个 RNN 的第一个单元,而这个 RNN 同时也用于文本生成。在我们的模型中,单个图像嵌入被送入一个只有一个单元的 ,然后再用另一个 来生成文本。我们既试过整图的单个(1x1)嵌入,也试过把图像分成 块、每块各自有嵌入的做法。在 的情形下,图像嵌入按序列送入 。两种情形下,我们都使用不加交叉注意力的普通 RNN,与 Show-And-Tell 模型相同。带交叉注意力的 RNN 曾用于 Show-Attend-Tell 模型(Xu et al., 2015),但我们发现其性能不如 Show-And-Tell 模型。
4.2 Transformer Model
4.2 Transformer 模型
In the Transformer-based models, both the encoder and the decoder contain a stack of layers. We denote the -th layer in the encoder by , and , . Each of these layers contains two sub-layers: a multi-head self-attention layer , and a position-wise feedforward network :
在基于 Transformer 的模型中,编码器和解码器都包含 层的堆叠。我们把编码器中的第 层记为 ,并且 ,。每一层包含两个子层:一个多头自注意力层 ,以及一个按位置的前馈网络 :
where , , and are the encoder weight matrices for query, key, and value transformation in the self-attention sub-layer; and denotes the encoder weight matrix of the feedforward sub-layer. Similar to the RNN-based model, we consider using a single image embedding (1x1) and a vector of 8x8 image embeddings.
其中 、 和 是编码器自注意力子层中用于查询、键和值变换的权重矩阵; 表示编码器前馈子层的权重矩阵。与基于 RNN 的模型类似,我们也考虑使用单个图像嵌入(1x1)以及 图像嵌入组成的向量。
In the decoder, we denote the -th layer by and . There are two main differences between the decoder and encoder layers. First, the self-attention sub-layer in the decoder is masked to the right, in order to prevent attending to “future” positions (i.e. does not attend to ). Second, in between the self-attention layer and the feedforward layer, the decoder adds a third cross-attention layer that connects to the top-layer encoder representation .
在解码器中,我们把第 层记为 ,并且 。解码器层与编码器层有两个主要差别。第一,解码器中的自注意力子层向右屏蔽,以防止注意到“未来”位置(也就是 不会注意到 )。第二,在自注意力层和前馈层之间,解码器还增加了第三个交叉注意力层,把 连接到编码器顶层表示 。
where , , and are the weight matrices for query, key, and value transformation in the decoder self-attention sub-layer; , , are the corresponding decoder weight matrices in the cross-attention sub-layer; and is the decoder weight matrix of the feedforward sub-layer.
其中 、 和 是解码器自注意力子层中用于查询、键和值变换的权重矩阵;、、 是交叉注意力子层中相应的解码器权重矩阵; 是解码器前馈子层的权重矩阵。
The Transformer-based models utilize position information at the embedding layer. In the 8x8 case, the 64 embedding vectors are serialized to a 1D sequence with positions from . The position information is modeled by applying sine and cosine functions at each position and with different frequencies for each embedding dimension, as in (Vaswani et al., 2017), and subsequently added to the embedding representations.
基于 Transformer 的模型在嵌入层使用位置信息。在 的情形下,64 个嵌入向量被串成一个一维序列,位置为 。位置信息的建模方式是:在每个位置上,对每个嵌入维使用不同频率的正弦和余弦函数,与(Vaswani et al., 2017)中相同,然后再加到嵌入表示上。
5 Experimental Results
5 实验结果
In this section, we evaluate the impact of using the Conceptual Captions dataset (referred to as ’Conceptual’ in what follows) for training image captioning models. To this end, we train the models described in Section 4 under two experimental conditions: using the training & development sets provided by the COCO dataset (Lin et al., 2014), versus training & development sets using the Conceptual dataset. We quantitatively evaluate the resulting models using three different test sets: the blind COCO-C40 test set (in-domain for COCO-trained models, out-of-domain for Conceptual-trained models); the Conceptual test set (out-of-domain for COCO-trained models, in-domain for Conceptual-trained models); and the Flickr (Young et al., 2014) 1K test set (out-of-domain for both COCO-trained models and Conceptual-trained models).
在这一节中,我们评价用 Conceptual Captions 数据集(下文称为 ’Conceptual’)训练图像描述模型的影响。为此,我们在两种实验条件下训练第 4 节所述的模型:一种使用 COCO 数据集(Lin et al., 2014)提供的训练与开发集,另一种使用 Conceptual 数据集的训练与开发集。我们用三个不同的测试集对得到的模型做定量评价:未公开的 COCO-C40 测试集(对用 COCO 训练的模型是域内,对用 Conceptual 训练的模型是域外);Conceptual 测试集(对用 COCO 训练的模型是域外,对用 Conceptual 训练的模型是域内);以及 Flickr(Young et al., 2014)1K 测试集(对用 COCO 训练和用 Conceptual 训练的模型都是域外)。
5.1 Dataset Details
5.1 数据集细节
COCO Image Captions The COCO image captioning dataset is normally divided into 82K images for training, and 40K images for validation. Each of these images comes with at least 5 groundtruth captions. Following standard practice, we combine the training set with most of the validation dataset for training our model, and only hold out a subset of 4K images for validation.
COCO 图像描述 COCO 图像描述数据集通常划分为 8.2 万张训练图像和 4 万张验证图像。每张图像至少带有 5 条参考描述。按照惯例,我们把训练集与验证集中的大部分合并起来训练模型,只留出 4,000 张图像的子集做验证。
Conceptual Captions The Conceptual Captions dataset contains around 3.3M images for training, 28K for validation and 22.5K for the test set. For more detailed statistics, see Table 3.
Conceptual Captions Conceptual Captions 数据集大约有 330 万张训练图像、2.8 万张验证图像和 2.25 万张测试图像。更详细的统计见表 3。
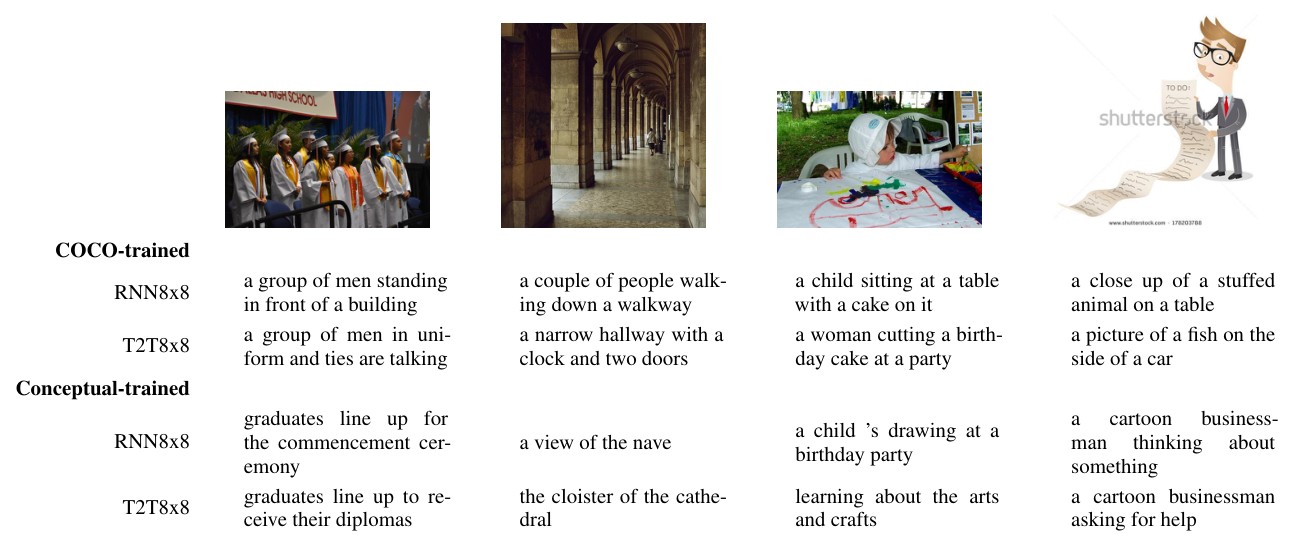
Figure 5: Side by side comparison of model outputs under two training conditions. Conceptual-based models (lower half) tend to hallucinate less, are more expressive, and handle well a larger variety of images. The two images in the middle are from Flickr; the other two are from Conceptual Captions.
图 5:两种训练条件下模型输出的并排对照。基于 Conceptual 的模型(下半部分)往往更少胡编,表达更丰富,也能更好地处理更多种类的图像。中间两张图来自 Flickr,另外两张来自 Conceptual Captions。
5.2 Experimental Setup
5.2 实验设置
Image Preprocessing Each input image is first preprocessed by random distortion and cropping (using a random ratio from 50%∼100%). This prevents models from overfitting individual pixels of the training images.
图像预处理 每张输入图像先经过随机畸变和裁剪(随机比例为 50%∼100%)预处理。这可以防止模型对训练图像的单个像素过拟合。
Encoder-Decoder For RNN-based models, we use a 1-layer, 512-dim LSTM as the RNN cell. For the Transformer-based models, we use the default setup from (Vaswani et al., 2017), with encoder and decoder layers, a hidden-layer size of 512, and 8 attention heads.
编码器-解码器 对基于 RNN 的模型,我们使用 1 层、512 维的 LSTM 作为 RNN 单元。对基于 Transformer 的模型,我们采用(Vaswani et al., 2017)中的默认设置: 层编码器和解码器,隐层大小为 512,并有 8 个注意力头。
Text Handling Training captions are truncated to maximum 15 tokens. We use a token type min-count of 4, which results in around 9,000 token types for the COCO dataset, and around 25,000 token types for the Conceptual Captions dataset. All other tokens are replaced with special token UNK. The word embedding matrix has size 512 and is tied to the output projection matrix.
文本处理 训练描述被截断到最多 15 个记号。我们采用记号类型最小计数为 4,由此 COCO 数据集大约得到 9,000 类记号,Conceptual Captions 数据集大约得到 25,000 类记号。其余记号都替换成特殊记号 UNK。词嵌入矩阵大小为 512,并与输出投影矩阵绑定。
Optimization All models are trained using MLE loss and optimized using Adagrad (Duchi et al., 2011) with learning rate 0.01. Mini-batch size is 25. All model parameters are trained for a total number of 5M steps, with batch updates asynchronously distributed across 40 workers. The final model is selected based on the best CIDEr score on the development set for the given training condition.
优化 所有模型都用最大似然损失训练,并用 Adagrad(Duchi et al., 2011)优化,学习率为 0.01。小批量大小为 25。全部模型参数一共训练 500 万步,批量更新在 40 个工作进程上异步分布。最终模型按给定训练条件下开发集上最好的 CIDEr 分数来选取。
Inference During inference, the decoder prediction of the previous position is fed to the input of the next position. We use a beam search of beam size 4 to compute the most likely output sequence.
推理 在推理时,解码器前一位置的预测被送入下一位置的输入。我们使用束宽为 4 的束搜索,来计算最可能的输出序列。
5.3 Qualitative Results
5.3 定性结果
Before we present the numerical results for our experiments, we discuss briefly the patterns that we have observed.
在给出实验的数值结果之前,我们先简要讨论我们所观察到的模式。
One difference between COCO-trained models and Conceptual-trained models is their ability to use the appropriate natural language terms for the entities in an image. For the left-most image in Fig. 5, COCO-trained models use “group of men” to refer to the people in the image; Conceptual-based models use the more appropriate and informative term “graduates”. The second image, from the Flickr test set, makes this even more clear. The Conceptual-trained T2T model is perfectly rendering the image content as “the cloister of the cathedral”. None of the other models come close to producing such an accurate description.
用 COCO 训练的模型和用 Conceptual 训练的模型,一个差别在于它们能否为图像中的实体使用恰当的自然语言说法。对图 5 最左边的图像,用 COCO 训练的模型用 “group of men” 来指称图中的人;基于 Conceptual 的模型则使用更恰当、也更有信息量的词 “graduates”。第二张来自 Flickr 测试集的图把这一点表现得更清楚。用 Conceptual 训练的 T2T 模型把图像内容准确地写成 “the cloister of the cathedral”。其他模型都远不能给出这样准确的描述。
A second difference is that COCO-trained models often seem to hallucinate objects. For instance, they hallucinate “front of building” for the first image, “clock and two doors” for the second, and “birthday cake” for the third image. In contrast, Conceptual-trained models do not seem to have this problem. We hypothesize that the hallucination issue for COCO-based models comes from the high correlations present in the COCO data (e.g., if there is a kid at a table, there is also cake). This high degree of correlation in the data does not allow the captioning model to correctly disentangle and learn representations at the right level of granularity.
第二个差别是,用 COCO 训练的模型常常会胡编出物体。例如,它们为第一张图胡编出 “front of building”,为第二张图胡编出 “clock and two doors”,为第三张图胡编出 “birthday cake”。相比之下,用 Conceptual 训练的模型似乎没有这个问题。我们猜想,COCO 模型的胡编问题来自 COCO 数据中很强的共现(例如,如果桌上有孩子,往往也就有蛋糕)。数据里这种高度相关,使描述模型难以正确拆开并在合适的粒度上学习表示。
A third difference is the resilience to a large spectrum of image types. COCO only contains natural images, and therefore a cartoon image like the fourth one results in massive hallucination effects for COCO-trained models (“stuffed animal”, “fish”, “side of car”). In contrast, Conceptual-trained models handle such images with ease.
第三个差别是对多种图像类型的适应力。COCO 只包含自然图像,因此像第四张那样的漫画,会让用 COCO 训练的模型出现严重的胡编(“stuffed animal”、“fish”、“side of car”)。相比之下,用 Conceptual 训练的模型能够轻松处理这类图像。
5.4 Quantitative Results
5.4 定量结果
In this section, we present quantitative results on the quality of the outputs produced by several image captioning models. We present both automatic evaluation results and human evaluation results.
在这一节中,我们给出若干图像描述模型输出质量的定量结果,同时包括自动评价和人工评价。
5.4.1 Human Evaluation Results
5.4.1 人工评价结果
For human evaluations, we use a pool of professional raters (tens of raters), with a double-blind evaluation condition. Raters are asked to assign a GOOD or BAD label to a given image, caption input, using just common-sense judgment. This approximates the reaction of a typical user, who normally would not accept predefined notions of GOOD vs. BAD. We ask 3 separate raters to rate each input pair and report the percentage of pairs that receive or more () GOOD annotations.
人工评价使用一组专业评分员(数十人),并采用双盲评价条件。评分员只需凭常识判断,给给定的 图像, 描述 输入打上 GOOD 或 BAD 标签。这近似于普通用户的反应,他们通常不会接受预先规定的 GOOD 与 BAD 定义。我们请 3 名不同的评分员为每一对输入评分,并报告获得 个或更多()GOOD 标注的配对比例。
Table 4: Human eval results on Flickr 1K Test.
| Model | Training | 1+ | 2+ | 3+ |
|---|---|---|---|---|
| RNN | COCO | 0.390 | 0.276 | 0.173 |
| T2T | COCO | 0.478 | 0.362 | 0.275 |
| RNN | Conceptual | 0.571 | 0.418 | 0.277 |
| T2T | Conceptual | 0.659 | 0.506 | 0.355 |
表 4:Flickr 1K 测试集上的人工评价结果。
| 模型 | 训练数据 | 1+ | 2+ | 3+ |
|---|---|---|---|---|
| RNN | COCO | 0.390 | 0.276 | 0.173 |
| T2T | COCO | 0.478 | 0.362 | 0.275 |
| RNN | Conceptual | 0.571 | 0.418 | 0.277 |
| T2T | Conceptual | 0.659 | 0.506 | 0.355 |
In Table 4, we report the results on the Flickr 1K test set. This evaluation is out-of-domain for both training conditions, so all models are on relatively equal footing. The results indicate that the Conceptual-based models are superior. In 50.6% (for the T2T model) of cases, a majority of annotators (2+) assigned a GOOD label. The results also indicate that the Transformer-based models are superior to the RNN-based models by a good margin, by over 8-points (for 2+) under both COCO and Conceptual training conditions.
表 4 给出了 Flickr 1K 测试集上的结果。这一评价对两种训练条件都是域外的,因此各模型大体处于同一起跑线。结果表明,基于 Conceptual 的模型更好。在 50.6% 的情形中(对 T2T 模型),多数标注员(2+)给出了 GOOD 标签。结果还表明,基于 Transformer 的模型明显优于基于 RNN 的模型,在 COCO 和 Conceptual 两种训练条件下,(按 2+ 计)都高出 8 个点以上。
Table 5: Auto metrics on the COCO C40 Test.
| Model | Training | CIDEr | ROUGE-L | METEOR |
|---|---|---|---|---|
| RNN | COCO | 1.021 | 0.694 | 0.348 |
| RNN | COCO | 1.044 | 0.698 | 0.354 |
| T2T | COCO | 1.032 | 0.700 | 0.358 |
| T2T | COCO | 1.032 | 0.700 | 0.356 |
| RNN | Conceptual | 0.403 | 0.445 | 0.191 |
| RNN | Conceptual | 0.410 | 0.437 | 0.189 |
| T2T | Conceptual | 0.348 | 0.403 | 0.171 |
| T2T | Conceptual | 0.345 | 0.400 | 0.170 |
表 5:COCO C40 测试集上的自动指标。
| 模型 | 训练数据 | CIDEr | ROUGE-L | METEOR |
|---|---|---|---|---|
| RNN | COCO | 1.021 | 0.694 | 0.348 |
| RNN | COCO | 1.044 | 0.698 | 0.354 |
| T2T | COCO | 1.032 | 0.700 | 0.358 |
| T2T | COCO | 1.032 | 0.700 | 0.356 |
| RNN | Conceptual | 0.403 | 0.445 | 0.191 |
| RNN | Conceptual | 0.410 | 0.437 | 0.189 |
| T2T | Conceptual | 0.348 | 0.403 | 0.171 |
| T2T | Conceptual | 0.345 | 0.400 | 0.170 |
Table 6: Auto metrics on the 22.5K Conceptual Captions Test set.
| Model | Training | CIDEr | ROUGE-L | SPICE |
|---|---|---|---|---|
| RNN | COCO | 0.183 | 0.149 | 0.062 |
| RNN | COCO | 0.191 | 0.152 | 0.065 |
| T2T | COCO | 0.184 | 0.148 | 0.062 |
| T2T | COCO | 0.190 | 0.151 | 0.064 |
| RNN | Conceptual | 1.351 | 0.326 | 0.235 |
| RNN | Conceptual | 1.401 | 0.330 | 0.240 |
| T2T | Conceptual | 1.588 | 0.331 | 0.254 |
| T2T | Conceptual | 1.676 | 0.336 | 0.257 |
表 6:2.25 万条 Conceptual Captions 测试集上的自动指标。
| 模型 | 训练数据 | CIDEr | ROUGE-L | SPICE |
|---|---|---|---|---|
| RNN | COCO | 0.183 | 0.149 | 0.062 |
| RNN | COCO | 0.191 | 0.152 | 0.065 |
| T2T | COCO | 0.184 | 0.148 | 0.062 |
| T2T | COCO | 0.190 | 0.151 | 0.064 |
| RNN | Conceptual | 1.351 | 0.326 | 0.235 |
| RNN | Conceptual | 1.401 | 0.330 | 0.240 |
| T2T | Conceptual | 1.588 | 0.331 | 0.254 |
| T2T | Conceptual | 1.676 | 0.336 | 0.257 |
Table 7: Auto metrics on the Flickr 1K Test.
| Model | Training | CIDEr | ROUGE-L | SPICE |
|---|---|---|---|---|
| RNN | COCO | 0.340 | 0.414 | 0.101 |
| RNN | COCO | 0.356 | 0.413 | 0.103 |
| T2T | COCO | 0.341 | 0.404 | 0.101 |
| T2T | COCO | 0.359 | 0.416 | 0.103 |
| RNN | Conceptual | 0.269 | 0.310 | 0.076 |
| RNN | Conceptual | 0.275 | 0.309 | 0.076 |
| T2T | Conceptual | 0.226 | 0.280 | 0.068 |
| T2T | Conceptual | 0.227 | 0.277 | 0.066 |
表 7:Flickr 1K 测试集上的自动指标。
| 模型 | 训练数据 | CIDEr | ROUGE-L | SPICE |
|---|---|---|---|---|
| RNN | COCO | 0.340 | 0.414 | 0.101 |
| RNN | COCO | 0.356 | 0.413 | 0.103 |
| T2T | COCO | 0.341 | 0.404 | 0.101 |
| T2T | COCO | 0.359 | 0.416 | 0.103 |
| RNN | Conceptual | 0.269 | 0.310 | 0.076 |
| RNN | Conceptual | 0.275 | 0.309 | 0.076 |
| T2T | Conceptual | 0.226 | 0.280 | 0.068 |
| T2T | Conceptual | 0.227 | 0.277 | 0.066 |
5.4.2 Automatic Evaluation Results
5.4.2 自动评价结果
In this section, we report automatic evaluation results, using established image captioning metrics.
在这一节中,我们用已有的图像描述指标报告自动评价结果。
For the COCO C40 test set (Fig. 5), we report the numerical values returned by the COCO online evaluation server, using the CIDEr (Vedantam et al., 2015), ROUGE-L (Lin and Och, 2004), and METEOR (Banerjee and Lavie, 2005) metrics. For Conceptual Captions (Fig. 6) and Flickr (Fig. 7) test sets, we report numerical values for the CIDEr, ROUGE-L, and SPICE (Anderson et al., 2016). For all metrics, higher number means closer distance between the candidates and the groundtruth captions.
对 COCO C40 测试集(图 5),我们报告 COCO 在线评价服务器 返回的数值,所用指标为 CIDEr(Vedantam et al., 2015)、ROUGE-L(Lin and Och, 2004)和 METEOR(Banerjee and Lavie, 2005)。对 Conceptual Captions(图 6)和 Flickr(图 7)测试集,我们报告 CIDEr、ROUGE-L 和 SPICE(Anderson et al., 2016) 的数值。对所有指标,数值越高,表示候选与参考描述之间越接近。
The automatic metrics are good at detecting in- vs out-of-domain situations. For COCO-models tested on COCO, the results in Fig. 5 show CIDEr scores in the 1.02-1.04 range, for both RNN- and Transformer-based models; the scores drop in the 0.35-0.41 range (CIDEr) for the Conceptual-based models tested against COCO groundtruth. For Conceptual-models tested on the Conceptual Captions test set, the results in Fig. 6 show scores as high as 1.468 CIDEr for the T2T model, which corroborates the human-eval results for the Transformer-based models being superior to the RNN-based models; the scores for the COCO-based models tested against Conceptual Captions groundtruth are all below 0.2 CIDEr.
自动指标很善于分辨域内与域外情形。对在 COCO 上测试的 COCO 模型,图 5 中的结果显示,基于 RNN 和基于 Transformer 的模型 CIDEr 都在 1.02–1.04 之间;用 Conceptual 训练的模型对照 COCO 参考描述时,分数落到 0.35–0.41(CIDEr)。对在 Conceptual Captions 测试集上测试的 Conceptual 模型,图 6 中的结果显示,T2T 模型的 CIDEr 高达 1.468,这与人工评价中 Transformer 模型优于 RNN 模型的结果相一致;用 COCO 训练的模型对照 Conceptual Captions 参考描述时,分数都低于 0.2 CIDEr。
The automatic metrics fail to corroborate the human evaluation results. According to the automatic metrics, the COCO-trained models are superior to the Conceptual-trained models (CIDEr scores in the mid-0.3 for the COCO-trained condition, versus mid-0.2 for the Conceptual-trained condition), and the RNN-based models are superior to Transformer-based models. Notably, these are the same metrics which score humans lower than the methods that won the COCO 2015 challenge (Vinyals et al., 2015a; Fang et al., 2015), despite the fact that humans are still much better at this task. The failure of these metrics to align with the human evaluation results casts again grave doubts on their ability to drive progress in this field. A significant weakness of these metrics is that hallucination effects are under-penalized (a small precision penalty for tokens with no correspondent in the reference), compared to human judgments that tend to dive dramatically in the presence of hallucinations.
自动指标没能印证人工评价的结果。按自动指标,用 COCO 训练的模型优于用 Conceptual 训练的模型(COCO 训练条件下 CIDEr 在 0.3 左右,Conceptual 训练条件下在 0.2 左右),而且基于 RNN 的模型优于基于 Transformer 的模型。值得注意的是,正是这些指标曾把人类的分数打得低于 2015 年 COCO 挑战赛的优胜方法(Vinyals et al., 2015a; Fang et al., 2015),尽管人类在这项任务上仍然好得多。这些指标再次没能与人工评价对齐,使人更加怀疑它们能否推动这一领域的进展。这些指标的一个明显弱点是,对胡编物体的惩罚过轻(只是对参考中没有对应的记号给一点精确率惩罚),而人在看到胡编时,判断往往会大幅下降。
6 Conclusions
6 结论
We present a new image captioning dataset, Conceptual Captions, which has several key characteristics: it has around 3.3M examples, an order of magnitude larger than the COCO image-captioning dataset; it consists of a wide variety of images, including natural images, product images, professional photos, cartoons, drawings, etc.; and, its captions are based on descriptions taken from original Alt-text attributes, automatically transformed to achieve a balance between cleanliness, informativeness, and learnability.
我们介绍一套新的图像描述数据集 Conceptual Captions,它有几个关键特点:大约有 330 万条例子,比 COCO 图像描述数据集高一个数量级;图像种类广泛,包括自然图像、产品图、专业照片、漫画、绘画等;其描述来自原始 Alt-text 属性,并经过自动变换,以在干净程度、信息量和可学习性之间取得平衡。
We evaluate both the quality of the resulting image/caption pairs, as well as the performance of several image-captioning models when trained on the Conceptual Captions data. The results indicate that such models achieve better performance, and avoid some of the pitfalls seen with COCO-trained models, such as object hallucination. We hope that the availability of the Conceptual Captions dataset will foster considerable progress on the automatic image-captioning task.
我们既评价了由此得到的图像/描述对的质量,也评价了若干图像描述模型在 Conceptual Captions 数据上训练后的表现。结果表明,这些模型能够取得更好的成绩,并避开用 COCO 训练的模型常见的一些陷阱,例如胡编物体。我们希望 Conceptual Captions 数据集的发布,能够推动自动图像描述任务取得可观进展。
References
参考文献
Peter Anderson, Basura Fernando, Mark Johnson, and Stephen Gould. 2016. SPICE: semantic propositional image caption evaluation. In ECCV.
D. Bahdanau, K. Cho, and Y. Bengio. 2015. Neural machine translation by jointly learning to align and translate. In Proceedings of ICLR.
Satanjeev Banerjee and Alon Lavie. 2005. METEOR: An automatic metric for MT evaluation with improved correlation with human judgments. In Proceedings of the ACL Workshop on intrinsic and extrinsic evaluation measures for machine translation and/or summarization.
Yoshua Bengio. 2009. Learning deep architectures for ai. Found. Trends Mach. Learn. 2(1):1–127.
Raffaella Bernardi, Ruket Cakici, Desmond Elliott, Aykut Erdem, Erkut Erdem, Nazli Ikizler-Cinbis, Frank Keller, Adrian Muscat, and Barbara Plank. 2016. Automatic description generation from images: A survey of models, datasets, and evaluation measures. JAIR 55.
Craig Chambers, Ashish Raniwala, Frances Perry, Stephen Adams, Robert Henry, Robert Bradshaw, and Nathan. 2010. Flumejava: Easy, efficient data-parallel pipelines. In ACM SIGPLAN Conference on Programming Language Design and Implementation (PLDI). 2 Penn Plaza, Suite 701 New York, NY 10121-0701, pages 363–375. http://dl.acm.org/citation.cfm?id=1806638.
Junyoung Chung, Caglar Gulcehre, KyungHyun Cho, and Yoshua Bengio. 2014. Empirical evaluation of gated recurrent neural networks on sequence modeling. arXiv preprint arXiv:1412.3555.
J. Deng, W. Dong, R. Socher, L.-J. Li, K. Li, and L. Fei-Fei. 2009. ImageNet: A large-scale hierarchical image database. In CVPR.
Nan Ding and Radu Soricut. 2017. Cold-start reinforcement learning with softmax policy gradients. In NIPS.
Jeff Donahue, Lisa Anne Hendricks, Sergio Guadarrama, Marcus Rohrbach, Subhashini Venugopalan, Kate Saenko, and Trevor Darrell. 2014. Long-term recurrent convolutional networks for visual recognition and description. In Proc. of IEEE Conference on Computer Vision and Pattern Recognition (CVPR).
John Duchi, Elad Hazan, and Yoram Singer. 2011. Adaptive subgradient methods for online learning and stochastic optimization. Journal of Machine Learning Research 12(Jul):2121–2159.
Hao Fang, Saurabh Gupta, Forrest Iandola, Rupesh Srivastava, Li Deng, Piotr Dollár, Jianfeng Gao, Xiaodong He, Margaret Mitchell, John Platt, et al. 2015. From captions to visual concepts and back. In Proc. of IEEE Conference on Computer Vision and Pattern Recognition (CVPR).
Sepp Hochreiter and Jürgen Schmidhuber. 1997. Long short-term memory. Neural computation 9(8):1735–1780.
Micah Hodosh, Peter Young, and Julia Hockenmaier. 2013. Framing image description as a ranking task: Data, models and evaluation metrics. JAIR.
Jonathan Huang, Vivek Rathod, Chen Sun, Menglong Zhu, Anoop Korattikara, Alireza Fathi, Ian Fischer, Zbigniew Wojna, Yang Song, Sergio Guadarrama, and Kevin Murphy. 2016. Speed/accuracy trade-offs for modern convolutional object detectors. CoRR abs/1611.10012.
Andrej Karpathy and Li Fei-Fei. 2015. Deep visual-semantic alignments for generating image descriptions. In Proc. of IEEE Conference on Computer Vision and Pattern Recognition (CVPR).
Ryan Kiros, Ruslan Salakhutdinov, and Richard S Zemel. 2015. Unifying visual-semantic embeddings with multimodal neural language models. Transactions of the Association for Computational Linguistics.
A. Krizhevsky, I. Sutskever, and G. Hinton. 2012. Imagenet classification with deep convolutional neural networks. In NIPS.
Chin-Yew Lin and Franz Josef Och. 2004. Automatic evaluation of machine translation quality using longest common subsequence and skip-bigram statistics. In Proceedings of ACL.
Tsung-Yi Lin, Michael Maire, Serge J. Belongie, Lubomir D. Bourdev, Ross B. Girshick, James Hays, Pietro Perona, Deva Ramanan, Piotr Dollár, and C. Lawrence Zitnick. 2014. Microsoft COCO: common objects in context. CoRR abs/1405.0312.
Siqi Liu, Zhenhai Zhu, Ning Ye, Sergio Guadarrama, and Kevin Murphy. 2017. Optimization of image description metrics using policy gradient methods. In International Conference on Computer Vision (ICCV).
Junhua Mao, Jiajing Xu, Yushi Jing, and Alan Yuille. 2016. Training and evaluating multimodal word embeddings with large-scale web annotated images. In NIPS.
Marc’Aurelio Ranzato, Sumit Chopra, Michael Auli, and Wojciech Zaremba. 2015. Sequence level training with recurrent neural networks. CoRR abs/1511.06732.
Ilya Sutskever, Oriol Vinyals, and Quoc V Le. 2014. Sequence to sequence learning with neural networks. In Advances in neural information processing systems. pages 3104–3112.
Christian Szegedy, Sergey Ioffe, and Vincent Vanhoucke. 2016. Inception-v4, inception-resnet and the impact of residual connections on learning. CoRR abs/1602.07261.
Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Lukasz Kaiser, and Illia Polosukhin. 2017. Attention is all you need. In Advances in Neural Information Processing Systems.
Ramakrishna Vedantam, C. Lawrence Zitnick, and Devi Parikh. 2015. Cider: Consensus-based image description evaluation. In The IEEE Conference on Computer Vision and Pattern Recognition (CVPR).
Oriol Vinyals, Alexander Toshev, Samy Bengio, and Dumitru Erhan. 2015a. Show and tell: A neural image caption generator. In Proceedings of the IEEE conference on computer vision and pattern recognition. pages 3156–3164.
Oriol Vinyals, Alexander Toshev, Samy Bengio, and Dumitru Erhan. 2015b. Show and tell: A neural image caption generator. In Proc. of IEEE Conference on Computer Vision and Pattern Recognition (CVPR).
Kelvin Xu, Jimmy Ba, Ryan Kiros, Aaron Courville, Ruslan Salakhutdinov, Richard Zemel, and Yoshua Bengio. 2015. Show, attend and tell: Neural image caption generation with visual attention. In Proc. of the 32nd International Conference on Machine Learning (ICML).
Z. Yang, Y. Yuan, Y. Wu, R. Salakhutdinov, and W. W. Cohen. 2016. Review networks for caption generation. In NIPS.
Peter Young, Alice Lai, Micah Hodosh, and Julia Hockenmaier. 2014. From image descriptions to visual denotations: New similarity metrics for semantic inference over event descriptions. TACL 2:67–78.