Training Compute-Optimal Large Language Models
001
Training Compute-Optimal Large Language Models
Jordan Hoffmann Sebastian Borgeaud Arthur Mensch Elena Buchatskaya Trevor Cai Eliza Rutherford Diego de Las Casas Lisa Anne Hendricks Johannes Welbl Aidan Clark Tom Hennigan Eric Noland Katie Millican George van den Driessche Bogdan Damoc Aurelia Guy Simon Osindero Karen Simonyan Erich Elsen Jack W. Rae Oriol Vinyals Laurent Sifre
Abstract
摘要
We investigate the optimal model size and number of tokens for training a transformer language model under a given compute budget. We find that current large language models are significantly undertrained, a consequence of the recent focus on scaling language models whilst keeping the amount of training data constant. By training over 400 language models ranging from 70 million to over 16 billion parameters on 5 to 500 billion tokens, we find that for compute-optimal training, the model size and the number of training tokens should be scaled equally: for every doubling of model size the number of training tokens should also be doubled. We test this hypothesis by training a predicted compute-optimal model, Chinchilla, that uses the same compute budget as Gopher but with 70B parameters and 4 more more data. Chinchilla uniformly and significantly outperforms Gopher (280B), GPT-3 (175B), Jurassic-1 (178B), and Megatron-Turing NLG (530B) on a large range of downstream evaluation tasks. This also means that Chinchilla uses substantially less compute for fine-tuning and inference, greatly facilitating downstream usage. As a highlight, Chinchilla reaches a state-of-the-art average accuracy of 67.5% on the MMLU benchmark, greater than a 7% improvement over Gopher.
我们研究在给定算力预算下,训练 Transformer 语言模型的最优模型规模与 token 数。我们发现,当前大规模语言模型明显训练不足,这是近来在扩大模型规模时把训练数据量保持不变所带来的后果。通过训练逾 400 个语言模型——参数量从 7000 万到超过 160 亿,训练 token 从 50 亿到 5000 亿——我们发现,对算力最优训练而言,模型规模与训练 token 数应按同等比例放大:模型规模每翻一倍,训练 token 数也应翻一倍。我们用与 Gopher 相同的算力预算训练一个按预测为算力最优的模型 Chinchilla:700 亿参数、数据量约为前者的 。Chinchilla 在大量下游评测任务上均匀且显著优于 Gopher(2800 亿)、GPT-3(1750 亿)、Jurassic-1(1780 亿)以及 Megatron-Turing NLG(5300 亿)。这也意味着 Chinchilla 在微调与推理上消耗的算力明显更少,极大方便下游使用。亮点之一是:Chinchilla 在 MMLU 基准上达到 67.5% 的当时最优平均准确率,相对 Gopher 提升超过 7%。
1 Introduction
1 引言
Recently a series of Large Language Models (LLMs) have been introduced (Brown et al. 2020; Lieber et al. 2021; Rae et al. 2021; Smith et al. 2022; Thoppilan et al. 2022), with the largest dense language models now having over 500 billion parameters. These large autoregressive transformers (Vaswani et al. 2017) have demonstrated impressive performance on many tasks using a variety of evaluation protocols such as zero-shot, few-shot, and fine-tuning.
近年陆续出现一系列大规模语言模型(LLM)(Brown et al. 2020; Lieber et al. 2021; Rae et al. 2021; Smith et al. 2022; Thoppilan et al. 2022),最大的稠密语言模型现已超过 5000 亿参数。这些大型自回归 Transformer(Vaswani et al. 2017)在零样本、少样本与微调等多种评测协议下,已在诸多任务上展现出出色表现。
The compute and energy cost for training large language models is substantial (Rae et al. 2021; Thoppilan et al. 2022) and rises with increasing model size. In practice, the allocated training compute budget is often known in advance: how many accelerators are available and for how long we want to use them. Since it is typically only feasible to train these large models once, accurately estimating the best model hyperparameters for a given compute budget is critical (Tay et al. 2021).
训练大规模语言模型的算力与能耗代价很高(Rae et al. 2021; Thoppilan et al. 2022),并随模型规模上升。实践中,训练算力预算往往事先已知:有多少加速器、打算用多久。由于这类大模型通常只能完整训练一次,在给定算力预算下准确估计最佳模型超参至关重要(Tay et al. 2021)。
Kaplan et al. 2020 showed that there is a power law relationship between the number of parameters in an autoregressive language model (LM) and its performance. As a result, the field has been training larger and larger models, expecting performance improvements. One notable conclusion in Kaplan et al. 2020 is that large models should not be trained to their lowest possible loss to be compute optimal. Whilst we reach the same conclusion, we estimate that large models should be trained for many more training tokens than recommended by the authors. Specifically, given a increase computational budget, they suggests that the size of the model should increase while the number of training tokens should only increase 1.8. Instead, we find that model size and the number of training tokens should be scaled in equal proportions.
Kaplan et al. 2020 表明,自回归语言模型(LM)的参数量与其性能之间存在幂律关系。于是学界不断训练更大的模型,期望性能随之提升。Kaplan et al. 2020 的一个显著结论是:大模型不必训到尽可能低的损失才算算力最优。我们同意这一结论,但估计大模型应当比作者建议的训练更多 token。具体而言,给定算力预算增加 ,他们建议模型规模增约 ,而训练 token 数仅增约 。我们则发现,模型规模与训练 token 数应按同等比例放大。
Following Kaplan et al. 2020 and the training setup of GPT-3 (Brown et al. 2020), many of the recently trained large models have been trained for approximately 300 billion tokens (Table 1), in line with the approach of predominantly increasing model size when increasing compute.
在 Kaplan et al. 2020 与 GPT-3(Brown et al. 2020)训练设定之后,许多近期大模型大约都训了 3000 亿 token(表 1),与「主要靠增大模型规模来花掉更多算力」的做法一致。
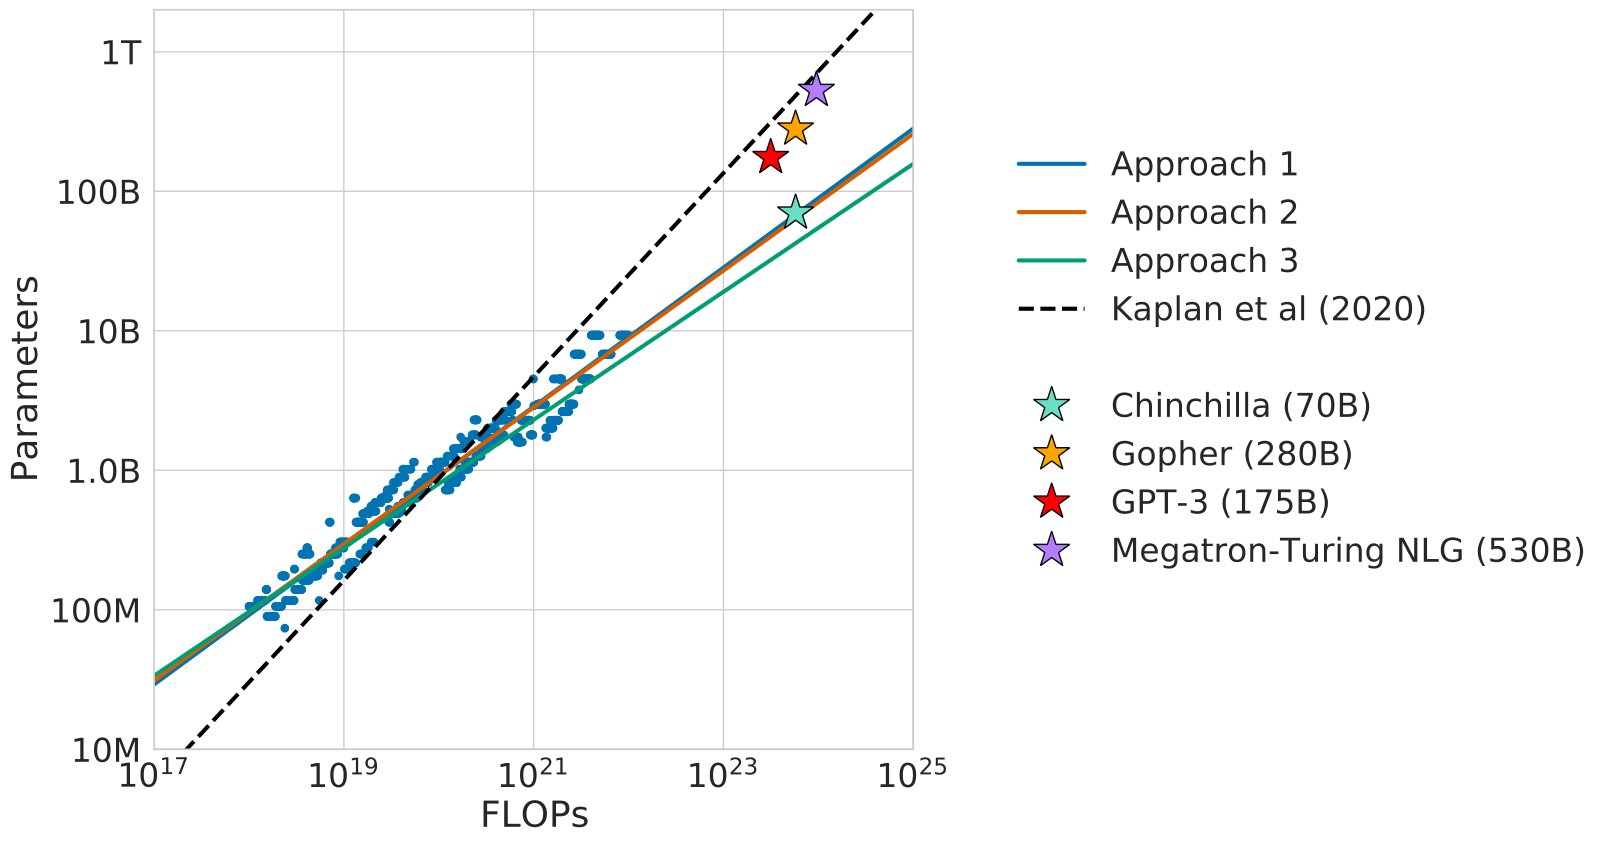
Figure 1: Overlaid predictions. We overlay the predictions from our three different approaches, along with projections from Kaplan et al. 2020. We find that all three methods predict that current large models should be substantially smaller and therefore trained much longer than is currently done. In Figure A3, we show the results with the predicted optimal tokens plotted against the optimal number of parameters for fixed FLOP budgets. Chinchilla outperforms Gopher and the other large models (see Section 4.2).
图 1:叠加预测。我们叠加三种方法的预测,以及 Kaplan et al. 2020 的外推。三种方法都预测:当前大模型应当显著更小,因而应训得更久。图 A3 给出固定 FLOP 预算下,预测最优 token 数相对最优参数量的结果。Chinchilla 优于 Gopher 及其他大模型(见第 4.2 节)。
| Model | Size ( Parameters) | Training Tokens |
|---|---|---|
| LaMDA (Thoppilan et al. 2022) | 137 Billion | 168 Billion |
| GPT-3 (Brown et al. 2020) | 175 Billion | 300 Billion |
| Jurassic (Lieber et al. 2021) | 178 Billion | 300 Billion |
| Gopher (Rae et al. 2021) | 280 Billion | 300 Billion |
| MT-NLG 530B (Smith et al. 2022) | 530 Billion | 270 Billion |
| Chinchilla | 70 Billion | 1.4 Trillion |
Table 1: Current LLMs. We show five of the current largest dense transformer models, their size, and the number of training tokens. Other than LaMDA (Thoppilan et al. 2022), most models are trained for approximately 300 billion tokens. We introduce Chinchilla, a substantially smaller model, trained for much longer than 300B tokens.
| 模型 | 规模(参数量) | 训练 Token |
|---|---|---|
| LaMDA (Thoppilan et al. 2022) | 1370 亿 | 1680 亿 |
| GPT-3 (Brown et al. 2020) | 1750 亿 | 3000 亿 |
| Jurassic (Lieber et al. 2021) | 1780 亿 | 3000 亿 |
| Gopher (Rae et al. 2021) | 2800 亿 | 3000 亿 |
| MT-NLG 530B (Smith et al. 2022) | 5300 亿 | 2700 亿 |
| Chinchilla | 700 亿 | 1.4 万亿 |
表 1:当前 LLM。列出五个当前最大的稠密 Transformer 模型、其规模与训练 token 数。除 LaMDA(Thoppilan et al. 2022)外,多数模型约训 3000 亿 token。我们引入 Chinchilla:规模明显更小,但训练远超 3000 亿 token。
In this work, we revisit the question: Given a fixed FLOPs budget,[^1] how should one trade-off model size and the number of training tokens? To answer this question, we model the final pre-training loss[^2] as a function of the number of model parameters , and the number of training tokens, . Since the computational budget is a deterministic function of the number of seen training tokens and model parameters, we are interested in minimizing under the constraint :
本文重新审视这一问题:*在固定 FLOPs 预算下[^1],应如何在模型规模与训练 token 数之间做权衡?*为此,我们把最终预训练损失[^2] 建模为模型参数量 与训练 token 数 的函数。由于算力预算 是已见训练 token 与模型参数的确定性函数 ,我们关心在约束 下最小化 :
The functions , and describe the optimal allocation of a computational budget . We empirically estimate these functions based on the losses of over 400 models, ranging from under M to over B parameters, and trained on B to over B tokens – with each model configuration trained for several different training horizons. Our approach leads to considerably different results than that of Kaplan et al. 2020. We highlight our results in Figure 1 and how our approaches differ in Section 2.
函数 与 描述算力预算 的最优分配。我们基于逾 400 个模型的损失经验估计这些函数:参数量从不足 M 到超过 B,训练 token 从 B 到超过 B——每种模型配置还以多种训练时长训练。我们的方法得到的结果与 Kaplan et al. 2020 明显不同。图 1 突出展示主要结论;与先前工作的差异见第 2 节。
Based on our estimated compute-optimal frontier, we predict that for the compute budget used to train Gopher, an optimal model should be 4 times smaller, while being training on 4 times more tokens. We verify this by training a more compute-optimal 70B model, called Chinchilla, on 1.4 trillion tokens. Not only does Chinchilla outperform its much larger counterpart, Gopher, but its reduced model size reduces inference cost considerably and greatly facilitates downstream uses on smaller hardware. The energy cost of a large language model is amortized through its usage for inference an fine-tuning. The benefits of a more optimally trained smaller model, therefore, extend beyond the immediate benefits of its improved performance.
依据估计的算力最优前沿,我们预测:以训练 Gopher 所用的算力预算,最优模型应缩小约 4 倍,同时在约 4 倍更多的 token 上训练。我们通过训练更算力最优的 700 亿参数模型 Chinchilla(1.4 万亿 token)加以验证。Chinchilla 不仅优于体量更大的 Gopher,更小的规模也显著降低推理成本,便于在更小硬件上做下游应用。大语言模型的能耗成本经推理与微调摊销;因此,训得更优的较小模型,其收益不止于性能提升本身。
2 Related Work
2 相关工作
Large language models.
A variety of large language models have been introduced in the last few years. These include both dense transformer models (Brown et al. 2020; Lieber et al. 2021; Smith et al. 2022; Rae et al. 2021; Thoppilan et al. 2022) and mixture-of-expert (MoE) models (Du et al. 2021; Fedus et al. 2021; Zoph et al. 2022). The largest dense transformers have passed 500 billion parameters (Smith et al. 2022). The drive to train larger and larger models is clear—so far increasing the size of language models has been responsible for improving the state-of-the-art in many language modelling tasks. Nonetheless, large language models face several challenges, including their overwhelming computational requirements (the cost of training and inference increase with model size) (Rae et al. 2021; Thoppilan et al. 2022) and the need for acquiring more high-quality training data. In fact, in this work we find that larger, high quality datasets will play a key role in any further scaling of language models.
大规模语言模型。
过去几年出现了多种大规模语言模型,包括稠密 Transformer(Brown et al. 2020; Lieber et al. 2021; Smith et al. 2022; Rae et al. 2021; Thoppilan et al. 2022)与混合专家(MoE)模型(Du et al. 2021; Fedus et al. 2021; Zoph et al. 2022)。最大的稠密 Transformer 已超过 5000 亿参数(Smith et al. 2022)。不断做更大模型的动机很清楚——迄今扩大语言模型规模推动了许多语言建模任务的当时最优。不过大模型也面临若干挑战,包括压倒性的算力需求(训练与推理成本随规模上升)(Rae et al. 2021; Thoppilan et al. 2022),以及获取更多高质量训练数据的需要。事实上,本文发现:任何进一步扩大语言模型,高质量更大数据集都将扮演关键角色。
Modelling the scaling behavior.
Understanding the scaling behaviour of language models and their transfer properties has been important in the development of recent large models (Kaplan et al. 2020; Hernandez et al. 2021). Kaplan et al. 2020 first showed a predictable relationship between model size and loss over many orders of magnitude. The authors investigate the question of choosing the optimal model size to train for a given compute budget. Similar to us, they address this question by training various models. Our work differs from Kaplan et al. 2020 in several important ways. First, the authors use a fixed number of training tokens and learning rate schedule for all models; this prevents them from modelling the impact of these hyperparameters on the loss. In contrast, we find that setting the learning rate schedule to approximately match the number of training tokens results in the best final loss regardless of model size—see Figure A1. For a fixed learning rate cosine schedule to 130B tokens, the intermediate loss estimates (for B) are therefore overestimates of the loss of a model trained with a schedule length matching . Using these intermediate losses results in underestimating the effectiveness of training models on less data than 130B tokens, and eventually contributes to the conclusion that model size should increase faster than training data size as compute budget increases. In contrast, our analysis predicts that both quantities should scale at roughly the same rate. Secondly, we include models with up to 16B parameters, as we observe that there is slight curvature in the FLOP-loss frontier (see Appendix E)—in fact, the majority of the models used in our analysis have more than 500 million parameters, in contrast the majority of runs in Kaplan et al. 2020 are significantly smaller—many being less than 100M parameters.
建模缩放行为。
理解语言模型的缩放行为及其迁移性质,对近期大模型的发展很重要(Kaplan et al. 2020; Hernandez et al. 2021)。Kaplan et al. 2020 首先表明,在多个数量级上,模型规模与损失之间存在可预测关系。作者研究了给定算力预算下如何选择最优模型规模。与我们类似,他们也通过训练多种模型来回答该问题。本文与 Kaplan et al. 2020 在若干重要方面不同。首先,作者对所有模型使用固定训练 token 数与学习率日程,因而无法建模这些超参对损失的影响。相比之下,我们发现将学习率日程大致对齐到训练 token 数,不论模型大小都能得到最佳最终损失——见图 A1。若对固定到 1300 亿 token 的余弦学习率日程,在 B 处读取的中间损失,会高估「日程长度匹配 」时模型的损失。用这些中间损失会低估在少于 1300 亿 token 上训练模型的有效性,最终促成「随算力增加,模型规模应比训练数据增长更快」的结论。我们的分析则预测二者应按大致相同速率放大。其次,我们纳入了最大到 160 亿参数的模型,因为观察到 FLOP–损失前沿存在轻微弯曲(见附录 E)——事实上,我们分析中的多数模型超过 5 亿参数;而 Kaplan et al. 2020 的多数运行显著更小——许多不到 1 亿参数。
Recently, Clark et al. 2022 specifically looked in to the scaling properties of Mixture of Expert language models, showing that the scaling with number of experts diminishes as the model size increases—their approach models the loss as a function of two variables: the model size and the number of experts. However, the analysis is done with a fixed number of training tokens, as in Kaplan et al. 2020, potentially underestimating the improvements of branching.
近期 Clark et al. 2022 专门研究了混合专家语言模型的缩放性质,表明随模型规模增大,专家数带来的收益递减——他们把损失建模为模型规模与专家数两个变量的函数。不过分析仍在固定训练 token 数下进行,与 Kaplan et al. 2020 一样,可能低估分支带来的改进。
Estimating hyperparameters for large models.
The model size and the number of training tokens are not the only two parameters to chose when selecting a language model and a procedure to train it. Other important factors include learning rate, learning rate schedule, batch size, optimiser, and width-to-depth ratio. In this work, we focus on model size and the number of training steps, and we rely on existing work and provided experimental heuristics to determine the other necessary hyperparameters. Yang et al. 2021 investigates how to choose a variety of these parameters for training an autoregressive transformer, including the learning rate and batch size. McCandlish et al. 2018 finds only a weak dependence between optimal batch size and model size. Shallue et al. 2018; Zhang et al. 2019 suggest that using larger batch-sizes than those we use is possible. Levine et al. 2020 investigates the optimal depth-to-width ratio for a variety of standard model sizes. We use slightly less deep models than proposed as this translates to better wall-clock performance on our hardware.
为大模型估计超参。
选择语言模型及其训练流程时,模型规模与训练 token 数并非仅有的两个参数。其他重要因素包括学习率、学习率日程、批大小、优化器以及宽深比。本文聚焦模型规模与训练步数,并依赖既有工作与实验启发式确定其余必要超参。Yang et al. 2021 研究如何为自回归 Transformer 选择学习率与批大小等多种参数。McCandlish et al. 2018 发现最优批大小与模型规模之间仅有弱依赖。Shallue et al. 2018; Zhang et al. 2019 表明可以使用比我们更大的批大小。Levine et al. 2020 研究了多种标准模型规模下的最优深宽比。我们使用比其建议略浅的模型,因为这在我们的硬件上对应更好的墙钟性能。
Improved model architectures.
Recently, various promising alternatives to traditional dense transformers have been proposed. For example, through the use of conditional computation large MoE models like the 1.7 trillion parameter Switch transformer (Fedus et al. 2021), the 1.2 Trillion parameter GLaM model (Du et al. 2021), and others (Artetxe et al. 2021; Zoph et al. 2022) are able to provide a large effective model size despite using relatively fewer training and inference FLOPs. However, for very large models the computational benefits of routed models seems to diminish (Clark et al. 2022). An orthogonal approach to improving language models is to augment transformers with explicit retrieval mechanisms, as done by Borgeaud et al. 2021; Guu et al. 2020; Lewis et al. 2020. This approach effectively increases the number of data tokens seen during training (by a factor of in Borgeaud et al. 2021). This suggests that the performance of language models may be more dependant on the size of the training data than previously thought.
改进的模型架构。
近来出现了多种替代传统稠密 Transformer 的有希望方案。例如,借助条件计算,1.7 万亿参数的 Switch Transformer(Fedus et al. 2021)、1.2 万亿参数的 GLaM(Du et al. 2021)及其他路由模型(Artetxe et al. 2021; Zoph et al. 2022)能以相对更少的训练与推理 FLOPs 提供很大的有效模型规模。但对极大模型,路由模型的算力收益似乎减弱(Clark et al. 2022)。另一条改进路线是为 Transformer 显式加入检索机制,如 Borgeaud et al. 2021; Guu et al. 2020; Lewis et al. 2020。该方法有效增加了训练中见到的数据 token 数(在 Borgeaud et al. 2021 中约 倍)。这提示:语言模型性能对训练数据规模的依赖可能比原先以为的更强。
3 Estimating the optimal parameter/training tokens allocation
3 估计最优参数量/训练 token 分配
We present three different approaches to answer the question driving our research: Given a fixed FLOPs budget, how should one trade-off model size and the number of training tokens? In all three cases we start by training a range of models varying both model size and the number of training tokens and use the resulting training curves to fit an empirical estimator of how they should scale. We assume a power-law relationship between compute and model size as done in Clark et al. 2022; Kaplan et al. 2020, though future work may want to include potential curvature in this relationship for large model sizes. The resulting predictions are similar for all three methods and suggest that parameter count and number of training tokens should be increased equally with more compute[^3]—with proportions reported in Table 2. This is in clear contrast to previous work on this topic and warrants further investigation.
我们提出三种不同方法,回答驱动本研究的问题:*在固定 FLOPs 预算下,应如何在模型规模与训练 token 数之间权衡?*三种情形下,我们都先训练一组同时改变模型规模与训练 token 数的模型,再用所得训练曲线拟合它们应如何缩放的经验估计。我们假定算力与模型规模之间为幂律关系,如同 Clark et al. 2022; Kaplan et al. 2020;未来工作或可纳入大模型上该关系可能出现的弯曲。三种方法得到的预测相近,都表明:参数量与训练 token 数应随更多算力同等增加[^3]——比例见表 2。这与该主题的先前工作形成鲜明对照,值得进一步研究。
3.1 Approach 1: Fix model sizes and vary number of training tokens
3.1 方法 1:固定模型规模,改变训练 token 数
In our first approach we vary the number of training steps for a fixed family of models (ranging from 70M to over 10B parameters), training each model for 4 different number of training sequences. From these runs, we are able to directly extract an estimate of the minimum loss achieved for a given number of training FLOPs. Training details for this approach can be found in Appendix D.
第一种方法中,我们在固定模型族(从 70M 到超过 10B 参数)上改变训练步数,每个模型训 4 种不同的训练序列数。由此可直接提取给定训练 FLOPs 下达到的最小损失估计。该方法的训练细节见附录 D。
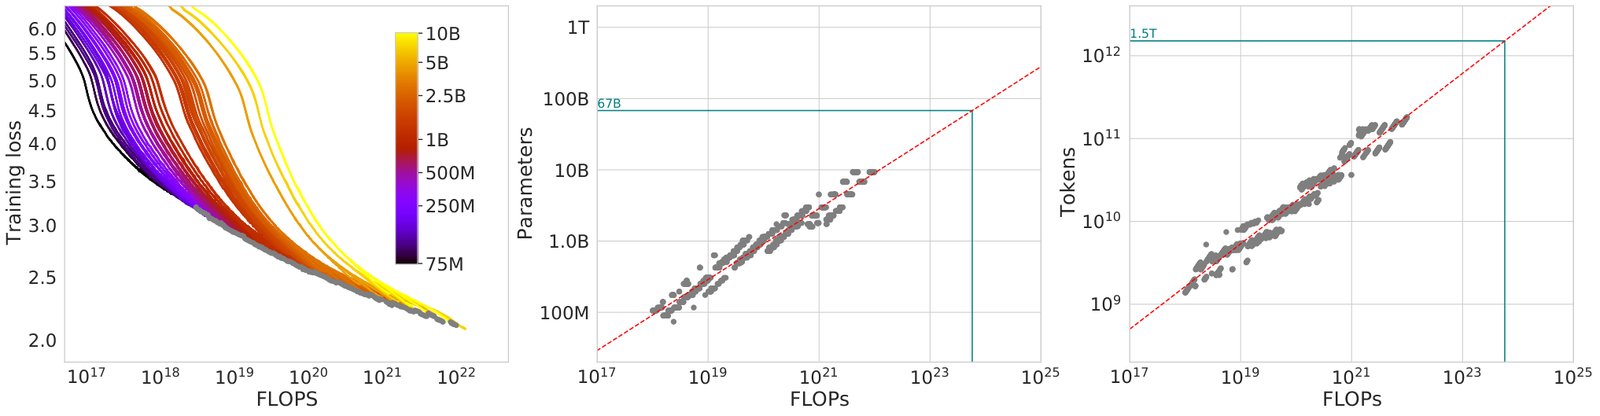
Figure 2: Training curve envelope. On the left we show all of our different runs. We launched a range of model sizes going from 70M to 10B, each for four different cosine cycle lengths. From these curves, we extracted the envelope of minimal loss per FLOP, and we used these points to estimate the optimal model size (center) for a given compute budget and the optimal number of training tokens (right). In green, we show projections of optimal model size and training token count based on the number of FLOPs used to train Gopher ().
图 2:训练曲线包络。左图展示全部不同运行。我们启动从 70M 到 10B 的一系列模型规模,每种有四种余弦周期长度。从这些曲线提取每 FLOP 最小损失的包络,并用这些点估计给定算力预算下的最优模型规模(中)与最优训练 token 数(右)。绿色标出按训练 Gopher 所用 FLOPs()外推的最优模型规模与训练 token 数。
For each parameter count we train 4 different models, decaying the learning rate by a factor of 10 over a horizon (measured in number of training tokens) that ranges by a factor of . Then, for each run, we smooth and then interpolate the training loss curve. From this, we obtain a continuous mapping from FLOP count to training loss for each run. Then, for each FLOP count, we determine which run achieves the lowest loss. Using these interpolants, we obtain a mapping from any FLOP count , to the most efficient choice of model size and number of training tokens such that .[^4] At 1500 logarithmically spaced FLOP values, we find which model size achieves the lowest loss of all models along with the required number of training tokens. Finally, we fit power laws to estimate the optimal model size and number of training tokens for any given amount of compute (see the center and right panels of Figure 2), obtaining a relationship and . We find that and —as summarized in Table 2. In Section D.4, we show a head-to-head comparison at FLOPs, using the model size recommended by our analysis and by the analysis of Kaplan et al. 2020—using the model size we predict has a clear advantage.
对每个参数量 ,我们训练 4 个不同模型,在长度相差 的视野(以训练 token 数计)上将学习率衰减 。然后对每次运行平滑并插值训练损失曲线,得到每次运行从 FLOP 计数到训练损失的连续映射。再对每个 FLOP 计数,确定哪次运行达到最低损失。借助这些插值,我们得到从任意 FLOP 计数 到最有效模型规模 与训练 token 数 (满足 )的映射。[^4]在 1500 个对数间隔的 FLOP 取值上,我们找出在所有模型中达到最低损失的模型规模,以及所需训练 token 数。最后拟合幂律,估计任意给定算力量下的最优模型规模与训练 token 数(见图 2 中、右),得到 、。我们发现 、——汇总见表 2。第 D.4 节给出在 FLOPs 上的头对头比较:分别采用我们分析与 Kaplan et al. 2020 建议的模型规模——用我们预测的规模有明显优势。
3.2 Approach 2: IsoFLOP profiles
3.2 方法 2:IsoFLOP 曲线
In our second approach we vary the model size[^5] for a fixed set of 9 different training FLOP counts[^6] (ranging from to FLOPs), and consider the final training loss for each point[^7]. in contrast with Approach 1 that considered points along the entire training runs. This allows us to directly answer the question: For a given FLOP budget, what is the optimal parameter count?
第二种方法中,我们在固定的 9 组不同训练 FLOP 计数[^6](从 到 FLOPs)上改变模型规模[^5],并考察每点的最终训练损失[^7];这与方法 1 沿整条训练轨迹取点 不同。由此可直接回答:给定 FLOP 预算,最优参数量是多少?
For each FLOP budget, we plot the final loss (after smoothing) against the parameter count in Figure 3 (left). In all cases, we ensure that we have trained a diverse enough set of model sizes to see a clear minimum in the loss. We fit a parabola to each IsoFLOPs curve to directly estimate at what model size the minimum loss is achieved (Figure 3 (left)). As with the previous approach, we then fit a power law between FLOPs and loss-optimal model size and number of training tokens, shown in Figure 3 (center, right). Again, we fit exponents of the form and and we find that and —as summarized in Table 2.
对每个 FLOP 预算,我们把最终损失(平滑后)相对参数量画在图 3(左)。每种情形都确保训练了足够多样的模型规模,以便在损失上看到清晰最小值。我们对每条 IsoFLOP 曲线拟合抛物线,直接估计达到最小损失的模型规模(图 3 左)。与前一方法类似,再在 FLOPs 与损失最优模型规模、训练 token 数之间拟合幂律,见图 3(中、右)。再次拟合 、,得到 、——汇总见表 2。
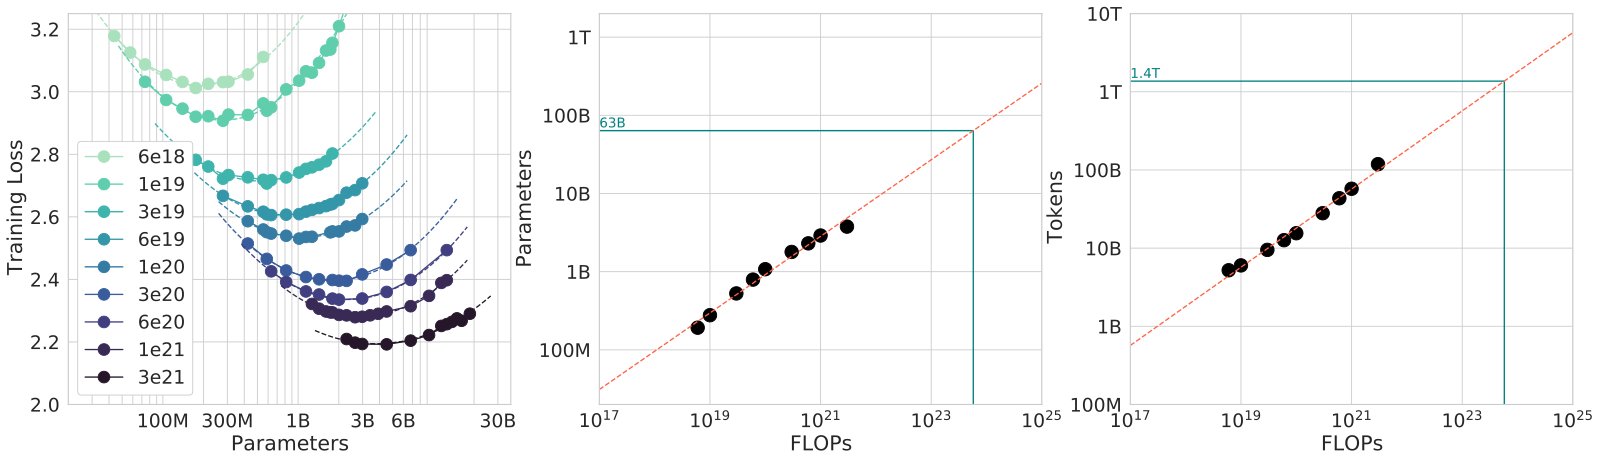
Figure 3: IsoFLOP curves. For various model sizes, we choose the number of training tokens such that the final FLOPs is a constant. The cosine cycle length is set to match the target FLOP count. We find a clear valley in loss, meaning that for a given FLOP budget there is an optimal model to train (left). Using the location of these valleys, we project optimal model size and number of tokens for larger models (center and right). In green, we show the estimated number of parameters and tokens for an optimal model trained with the compute budget of Gopher.
图 3:IsoFLOP 曲线。对多种模型规模,我们选择训练 token 数使最终 FLOPs 为常数。余弦周期长度对齐到目标 FLOP 计数。损失上出现清晰谷底,意味着给定 FLOP 预算存在应训的最优模型(左)。利用这些谷底位置,我们外推更大模型的最优规模与 token 数(中、右)。绿色标出以 Gopher 算力预算训练最优模型时估计的参数量与 token 数。
3.3 Approach 3: Fitting a parametric loss function
3.3 方法 3:拟合参数化损失函数
Lastly, we model all final losses from experiments in Approach 1 & 2 as a parametric function of model parameter count and the number of seen tokens. Following a classical risk decomposition (see Section D.2), we propose the following functional form
最后,我们把方法 1 与 2 实验中的全部最终损失建模为模型参数量与已见 token 数的参数化函数。遵循经典风险分解(见第 D.2 节),我们提出如下函数形式
The first term captures the loss for an ideal generative process on the data distribution, and should correspond to the entropy of natural text. The second term captures the fact that a perfectly trained transformer with parameters underperforms the ideal generative process. The final term captures the fact that the transformer is not trained to convergence, as we only make a finite number of optimisation steps, on a sample of the dataset distribution.
第一项刻画数据分布上理想生成过程的损失,应对应自然语言的熵。第二项刻画:即使完美训练, 参数的 Transformer 仍逊于理想生成过程。末项刻画:由于优化步数有限、且只见到数据集分布的有限样本,Transformer 并未训到收敛。
Model fitting.
To estimate , we minimize the Huber loss (Huber 1964) between the predicted and observed log loss using the L-BFGS algorithm (Nocedal 1980):
模型拟合。
为估计 ,我们用 L-BFGS 算法(Nocedal 1980)最小化预测对数损失与观测对数损失之间的 Huber 损失(Huber 1964):
We account for possible local minima by selecting the best fit from a grid of initialisations. The Huber loss () is robust to outliers, which we find important for good predictive performance over held-out data points. Section D.2 details the fitting procedure and the loss decomposition.
我们从一组初始化网格中选取最佳拟合,以应对可能的局部极小。Huber 损失()对离群点稳健,我们发现这对留出数据点上的良好预测性能很重要。第 D.2 节详述拟合流程与损失分解。
Efficient frontier.
We can approximate the functions and by minimizing the parametric loss under the constraint (Kaplan et al. 2020). The resulting and balance the two terms in Equation (3) that depend on model size and data. By construction, they have a power-law form:
高效前沿。
我们可通过在约束 (Kaplan et al. 2020)下最小化参数化损失 ,近似函数 与 。所得 与 平衡式 (3) 中依赖模型规模与数据的两项。由构造,它们呈幂律形式:
We show contours of the fitted function in Figure 4 (left), and the closed-form efficient computational frontier in blue. From this approach, we find that and —as summarized in Table 2.
图 4(左)展示拟合函数 的等高线,蓝色为闭式高效计算前沿。该方法得到 、——汇总见表 2。
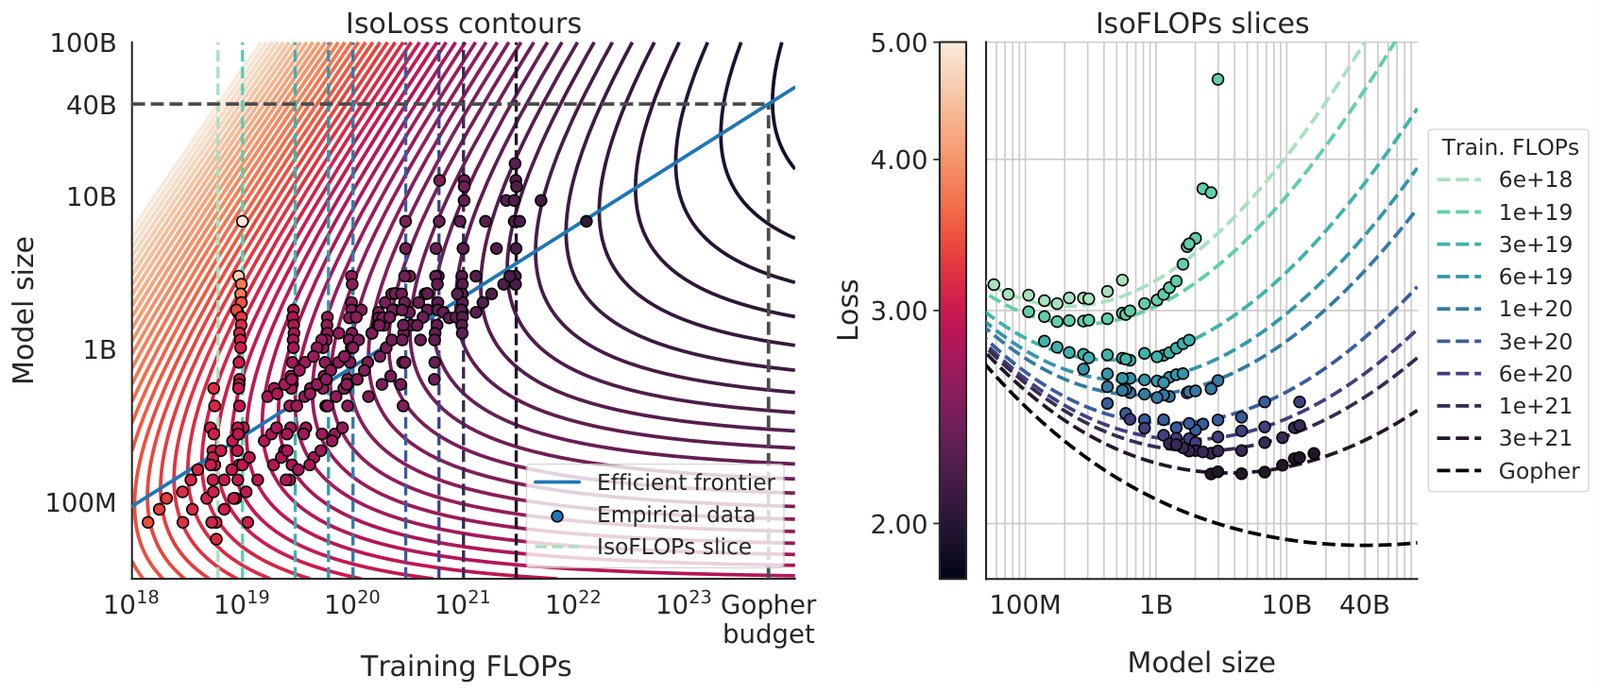
Figure 4: Parametric fit. We fit a parametric modelling of the loss and display contour (left) and isoFLOP slices (right). For each isoFLOP slice, we include a corresponding dashed line in the left plot. In the left plot, we show the efficient frontier in blue, which is a line in log-log space. Specifically, the curve goes through each iso-loss contour at the point with the fewest FLOPs. We project the optimal model size given the Gopher FLOP budget to be 40B parameters.
图 4:参数化拟合。我们拟合损失的参数化模型 ,展示等高线(左)与 isoFLOP 切片(右)。每条 isoFLOP 切片在左图对应一条虚线。左图蓝色为高效前沿,在对数–对数空间为直线;具体地,该曲线穿过每条等损失等高线上 FLOPs 最少的点。我们把 Gopher FLOP 预算下的最优模型规模外推为 400 亿参数。
3.4 Optimal model scaling
3.4 最优模型缩放
We find that the three approaches, despite using different fitting methodologies and different trained models, yield comparable predictions for the optimal scaling in parameters and tokens with FLOPs (shown in Table 2).
我们发现,尽管拟合方法与所用训练模型不同,三种方法对随 FLOPs 增加时参数与 token 最优缩放的预测相当接近(见表 2)。
| Approach | Coeff. where | Coeff. where |
|---|---|---|
| 1. Minimum over training curves | ||
| 2. IsoFLOP profiles | ||
| 3. Parametric modelling of the loss | ||
| Kaplan et al. 2020 | 0.73 | 0.27 |
Table 2: Estimated parameter and data scaling with increased training compute. The listed values are the exponents, and , on the relationship and . Our analysis suggests a near equal scaling in parameters and data with increasing compute which is in clear contrast to previous work on the scaling of large models. The 10 and 90 percentiles are estimated via bootstrapping data (80% of the dataset is sampled 100 times) and are shown in parenthesis.
| 方法 | 系数 () | 系数 () |
|---|---|---|
| 1. 训练曲线上取最小 | ||
| 2. IsoFLOP 曲线 | ||
| 3. 损失的参数化建模 | ||
| Kaplan et al. 2020 | 0.73 | 0.27 |
表 2:随训练算力增加的参数与数据缩放估计。所列值为关系 与 的指数 、。我们的分析表明,随算力增加,参数与数据近乎同等缩放,这与先前大模型缩放工作形成鲜明对照。括号内为自助法(对 80% 数据采样 100 次)估计的第 10 与第 90 百分位。
All three approaches suggest that as compute budget increases, model size and the amount of training data should be increased in approximately equal proportions. The first and second approaches yield very similar predictions for optimal model sizes, as shown in Figure 1 and Figure A3. The third approach predicts even smaller models being optimal at larger compute budgets. We note that the observed points for low training FLOPs () have larger residuals than points with higher computational budgets. The fitted model places increased weight on the points with more FLOPs—automatically considering the low-computational budget points as outliers due to the Huber loss. As a consequence of the empirically observed negative curvature in the frontier (see Appendix E), this results in predicting a lower than the two other approaches.
三种方法都表明:随算力预算增加,模型规模与训练数据量应按大致相等比例增加。方法 1 与 2 对最优模型规模的预测非常接近,见图 1 与图 A3。方法 3 在更大算力预算下预测更小的模型为最优。我们注意到,低训练 FLOPs()的观测点 残差 大于更高算力预算的点。拟合模型对更高 FLOPs 的点赋予更大权重——由于 Huber 损失,自动把低算力预算点当作离群点。作为前沿 上经验负弯曲的后果(见附录 E),这导致预测的 低于另外两种方法。
. Parameters FLOPs FLOPs (in Gopher unit) Tokens 400 Million 1.92e+19 8.0 Billion 1 Billion 1.21e+20 20.2 Billion 10 Billion 1.23e+22 205.1 Billion 67 Billion 5.76e+23 1.5 Trillion 175 Billion 3.85e+24 3.7 Trillion 280 Billion 9.90e+24 5.9 Trillion 520 Billion 3.43e+25 11.0 Trillion 1 Trillion 1.27e+26 21.2 Trillion 10 Trillion 1.30e+28 216.2 Trillion
Table 3: Estimated optimal training FLOPs and training tokens for various model sizes. For various model sizes, we show the projections from Approach 1 of how many FLOPs and training tokens would be needed to train compute-optimal models. The estimates for Approach 2 & 3 are similar (shown in Section D.3)
| 参数量 | FLOPs | FLOPs(以 Gopher 为单位) | Token |
|---|---|---|---|
| 4 亿 | 1.92e+19 | 80 亿 | |
| 10 亿 | 1.21e+20 | 202 亿 | |
| 100 亿 | 1.23e+22 | 2051 亿 | |
| 670 亿 | 5.76e+23 | 1.5 万亿 | |
| 1750 亿 | 3.85e+24 | 3.7 万亿 | |
| 2800 亿 | 9.90e+24 | 5.9 万亿 | |
| 5200 亿 | 3.43e+25 | 11.0 万亿 | |
| 1 万亿 | 1.27e+26 | 21.2 万亿 | |
| 10 万亿 | 1.30e+28 | 216.2 万亿 |
表 3:多种模型规模下估计的最优训练 FLOPs 与训练 token。对多种模型规模,展示方法 1 关于训练算力最优模型需多少 FLOPs 与训练 token 的外推。方法 2 与 3 的估计相近(见第 D.3 节)。
In Table 3 we show the estimated number of FLOPs and tokens that would ensure that a model of a given size lies on the compute-optimal frontier. Our findings suggests that the current generation of large language models are considerably over-sized, given their respective compute budgets, as shown in Figure 1. For example, we find that a 175 billion parameter model should be trained with a compute budget of FLOPs and on over 4.2 trillion tokens. A 280 billion Gopher-like model is the optimal model to train given a compute budget of approximately FLOPs and should be trained on 6.8 trillion tokens. Unless one has a compute budget of FLOPs (over 250 the compute used to train Gopher), a 1 trillion parameter model is unlikely to be the optimal model to train. Furthermore, the amount of training data that is projected to be needed is far beyond what is currently used to train large models, and underscores the importance of dataset collection in addition to engineering improvements that allow for model scale. While there is significant uncertainty extrapolating out many orders of magnitude, our analysis clearly suggests that given the training compute budget for many current LLMs, smaller models should have been trained on more tokens to achieve the most performant model.
表 3 给出使给定规模模型落在算力最优前沿上所需的估计 FLOPs 与 token 数。我们的发现表明,当前一代大规模语言模型相对其算力预算明显过大,见图 1。例如,我们发现 1750 亿参数模型应以 FLOPs 的算力预算、在超过 4.2 万亿 token 上训练。类 Gopher 的 2800 亿模型在约 FLOPs 预算下才是最优,并应在 6.8 万亿 token 上训练。除非拥有 FLOPs 的算力预算(超过训练 Gopher 所用算力的 250),否则 1 万亿参数模型不太可能是应训的最优模型。此外,外推所需的训练数据量远超当前大模型所用,凸显了数据集收集以及支撑模型扩展的工程改进的重要性。尽管外推多个数量级存在显著不确定性,我们的分析清楚表明:就许多当前 LLM 的训练算力预算而言,应训更小模型、看更多 token,才能得到性能最好的模型。
In Appendix C, we reproduce the IsoFLOP analysis on two additional datasets: C4 (Raffel et al. 2020a) and GitHub code (Rae et al. 2021). In both cases we reach the similar conclusion that model size and number of training tokens should be scaled in equal proportions.
附录 C 中,我们在另外两个数据集上复现 IsoFLOP 分析:C4(Raffel et al. 2020a)与 GitHub 代码(Rae et al. 2021)。两种情形下都得出类似结论:模型规模与训练 token 数应按同等比例放大。
4 Chinchilla
Based on our analysis in Section 3, the optimal model size for the Gopher compute budget is somewhere between 40 and 70 billion parameters. We test this hypothesis by training a model on the larger end of this range—70B parameters—for 1.4T tokens, due to both dataset and computational efficiency considerations. In this section we compare this model, which we call Chinchilla, to Gopher and other LLMs. Both Chinchilla and Gopher have been trained for the same number of FLOPs but differ in the size of the model and the number of training tokens.
基于第 3 节的分析,Gopher 算力预算下的最优模型规模大约在 400 亿到 700 亿参数之间。我们通过训练该区间偏大端——700 亿参数、1.4T token——来检验这一假说,同时兼顾数据集与计算效率。本节将该模型(称为 Chinchilla)与 Gopher 及其他 LLM 比较。Chinchilla 与 Gopher 的训练 FLOPs 相同,但模型规模与训练 token 数不同。
While pre-training a large language model has a considerable compute cost, downstream fine-tuning and inference also make up substantial compute usage (Rae et al. 2021). Due to being smaller than Gopher, both the memory footprint and inference cost of Chinchilla are also smaller.
虽然预训练大语言模型算力成本可观,下游微调与推理也占相当算力使用(Rae et al. 2021)。由于比 Gopher 小 ,Chinchilla 的内存占用与推理成本也更小。
4.1 Model and training details
4.1 模型与训练细节
The full set of hyperparameters used to train Chinchilla are given in Table 4. Chinchilla uses the same model architecture and training setup as Gopher with the exception of the differences listed below.
训练 Chinchilla 的完整超参见表 4。Chinchilla 使用与 Gopher 相同的模型架构与训练设定,例外如下。
- • We train Chinchilla on MassiveText (the same dataset as Gopher) but use a slightly different subset distribution (shown in Table A1) to account for the increased number of training tokens.
- • 我们在 MassiveText(与 Gopher 相同数据集)上训练 Chinchilla,但使用略有不同的子集采样分布(见表 A1),以匹配增加后的训练 token 数。
- • We use AdamW (Loshchilov and Hutter 2019) for Chinchilla rather than Adam (Kingma and Ba 2014) as this improves the language modelling loss and the downstream task performance after finetuning.[^8]
- • Chinchilla 使用 AdamW(Loshchilov and Hutter 2019)而非 Adam(Kingma and Ba 2014),因为这能改进语言建模损失以及微调后的下游任务表现。[^8]
- • We train Chinchilla with a slightly modified SentencePiece (Kudo and Richardson 2018) tokenizer that does not apply NFKC normalisation. The vocabulary is very similar– 94.15% of tokens are the same as those used for training Gopher. We find that this particularly helps with the representation of mathematics and chemistry, for example.
- • 我们用略作修改、不做 NFKC 归一化的 SentencePiece(Kudo and Richardson 2018)分词器训练 Chinchilla。词表非常相近——94.15% 的 token 与训练 Gopher 所用相同。我们发现这对数学与化学等表示尤其有帮助。
- • Whilst the forward and backward pass are computed in bfloat16, we store a float32 copy of the weights in the distributed optimiser state (Rajbhandari et al. 2020). See Lessons Learned from Rae et al. 2021 for additional details.
- • 前向与反向传播以 bfloat16 计算,但我们在分布式优化器状态中保存一份 float32 权重副本(Rajbhandari et al. 2020)。更多细节见 Rae et al. 2021 的经验教训。
| Model | Layers | Number Heads | Key/Value Size | dmodel | Max LR | Batch Size |
|---|---|---|---|---|---|---|
| Gopher 280B | 80 | 128 | 128 | 16,384 | 3M 6M | |
| Chinchilla 70B | 80 | 64 | 128 | 8,192 | 1.5M 3M |
Table 4: Chinchilla architecture details. We list the number of layers, the key/value size, the bottleneck activation size d, the maximum learning rate, and the training batch size (# tokens). The feed-forward size is always set to . Note that we double the batch size midway through training for both Chinchilla and Gopher.
| 模型 | 层数 | 头数 | Key/Value 维度 | dmodel | 最大学习率 | 批大小 |
|---|---|---|---|---|---|---|
| Gopher 280B | 80 | 128 | 128 | 16,384 | 3M 6M | |
| Chinchilla 70B | 80 | 64 | 128 | 8,192 | 1.5M 3M |
表 4:Chinchilla 架构细节。列出层数、key/value 大小、瓶颈激活尺寸 d、最大学习率与训练批大小(token 数)。前馈层尺寸始终设为 。注意 Chinchilla 与 Gopher 都在训练中途将批大小加倍。
In Appendix G we show the impact of the various optimiser related changes between Chinchilla and Gopher. All models in this analysis have been trained on TPUv3/TPUv4 (Jouppi et al. 2017) with JAX (Bradbury et al. 2018) and Haiku (Hennigan et al. 2020). We include a Chinchilla model card (Mitchell et al. 2019) in Table A8.
附录 G 展示 Chinchilla 与 Gopher 之间多种优化器相关改动的影响。本分析中所有模型均在 TPUv3/TPUv4(Jouppi et al. 2017)上用 JAX(Bradbury et al. 2018)与 Haiku(Hennigan et al. 2020)训练。Chinchilla 模型卡(Mitchell et al. 2019)见表 A8。
4.2 Results
4.2 结果
We perform an extensive evaluation of Chinchilla, comparing against various large language models. We evaluate on a large subset of the tasks presented in Rae et al. 2021, shown in Table 5. As the focus of this work is on optimal model scaling, we included a large representative subset, and introduce a few new evaluations to allow for better comparison to other existing large models. The evaluation details for all tasks are the same as described in Rae et al. 2021.
我们对 Chinchilla 做广泛评测,并与多种大规模语言模型比较。评测覆盖 Rae et al. 2021 中给出任务的一大子集,见表 5。由于本文聚焦最优模型缩放,我们纳入一大组有代表性的子集,并新增若干评测以便更好对比既有大模型。各任务评测细节与 Rae et al. 2021 所述相同。
| # Tasks | Examples | |
|---|---|---|
| Language Modelling | 20 | WikiText-103, The Pile: PG-19, arXiv, FreeLaw, |
| Reading Comprehension | 3 | RACE-m, RACE-h, LAMBADA |
| Question Answering | 3 | Natural Questions, TriviaQA, TruthfulQA |
| Common Sense | 5 | HellaSwag, Winogrande, PIQA, SIQA, BoolQ |
| MMLU | 57 | High School Chemistry, Astronomy, Clinical Knowledge, |
| BIG-bench | 62 | Causal Judgement, Epistemic Reasoning, Temporal Sequences, |
Table 5: All evaluation tasks. We evaluate Chinchilla on a collection of language modelling along with downstream tasks. We evaluate on largely the same tasks as in Rae et al. 2021, to allow for direct comparison.
| 任务数 | 示例 | |
|---|---|---|
| 语言建模 | 20 | WikiText-103、The Pile:PG-19、arXiv、FreeLaw、 |
| 阅读理解 | 3 | RACE-m、RACE-h、LAMBADA |
| 问答 | 3 | Natural Questions、TriviaQA、TruthfulQA |
| 常识 | 5 | HellaSwag、Winogrande、PIQA、SIQA、BoolQ |
| MMLU | 57 | 高中化学、天文学、临床知识、 |
| BIG-bench | 62 | 因果判断、认识推理、时间序列、 |
表 5:全部评测任务。我们在一组语言建模及下游任务上评测 Chinchilla。任务大体与 Rae et al. 2021 相同,以便直接比较。
4.2.1 Language modelling
Figure 5: Pile Evaluation. For the different evaluation sets in The Pile (Gao et al. 2020), we show the bits-per-byte (bpb) improvement (decrease) of Chinchilla compared to Gopher. On all subsets, Chinchilla outperforms Gopher.
4.2.1 语言建模
图 5:Pile 评测。对 The Pile(Gao et al. 2020)中不同评测集,展示 Chinchilla 相对 Gopher 的每字节比特数(bpb)改进(降低)。在所有子集上,Chinchilla 均优于 Gopher。
Chinchilla significantly outperforms Gopher on all evaluation subsets of The Pile (Gao et al. 2020), as shown in Figure 5. Compared to Jurassic-1 (178B) Lieber et al. 2021, Chinchilla is more performant on all but two subsets– dm_mathematics and ubuntu_irc– see Table A5 for a raw bits-per-byte comparison. On Wikitext103 (Merity et al. 2017), Chinchilla achieves a perplexity of 7.16 compared to 7.75 for Gopher. Some caution is needed when comparing Chinchilla with Gopher on these language modelling benchmarks as Chinchilla is trained on 4 more data than Gopher and thus train/test set leakage may artificially enhance the results. We thus place more emphasis on other tasks for which leakage is less of a concern, such as MMLU (Hendrycks et al. 2020) and BIG-bench (BIG-bench collaboration 2021) along with various closed-book question answering and common sense analyses.
如图 5 所示,Chinchilla 在 The Pile(Gao et al. 2020)全部评测子集上显著优于 Gopher。相对 Jurassic-1(1780 亿)(Lieber et al. 2021),Chinchilla 仅在两个子集上更弱——dm_mathematics 与 ubuntu_irc——原始每字节比特数比较见表 A5。在 Wikitext103(Merity et al. 2017)上,Chinchilla 困惑度为 7.16,而 Gopher 为 7.75。在这些语言建模基准上比较 Chinchilla 与 Gopher 需谨慎:Chinchilla 的训练数据是 Gopher 的 ,训练/测试集泄漏可能人为抬高结果。因此我们更强调泄漏顾虑较小的任务,如 MMLU(Hendrycks et al. 2020)与 BIG-bench(BIG-bench collaboration 2021),以及多种闭卷问答与常识分析。
4.2.2 MMLU
| Random | 25.0% |
|---|---|
| Average human rater | 34.5% |
| GPT-3 5-shot | 43.9% |
| Gopher 5-shot | 60.0% |
| Chinchilla 5-shot | 67.6% |
| Average human expert performance | 89.8% |
| June 2022 Forecast | 57.1% |
| June 2023 Forecast | 63.4% |
Table 6: Massive Multitask Language Understanding (MMLU). We report the average 5-shot accuracy over 57 tasks with model and human accuracy comparisons taken from Hendrycks et al. 2020. We also include the average prediction for state of the art accuracy in June 2022/2023 made by 73 competitive human forecasters in Steinhardt 2021.
4.2.2 MMLU
| 随机 | 25.0% |
|---|---|
| 普通人打分者平均 | 34.5% |
| GPT-3 5-shot | 43.9% |
| Gopher 5-shot | 60.0% |
| Chinchilla 5-shot | 67.6% |
| 人类专家平均表现 | 89.8% |
| 2022 年 6 月预测 | 57.1% |
| 2023 年 6 月预测 | 63.4% |
表 6:大规模多任务语言理解(MMLU)。报告 57 个任务上的平均 5-shot 准确率;模型与人类准确率比较取自 Hendrycks et al. 2020。另纳入 Steinhardt 2021 中 73 名竞技人类预测者对 2022/2023 年 6 月当时最优准确率的平均预测。
The Massive Multitask Language Understanding (MMLU) benchmark (Hendrycks et al. 2020) consists of a range of exam-like questions on academic subjects. In Table 6, we report Chinchilla’s average 5-shot performance on MMLU (the full breakdown of results is shown in Table A6). On this benchmark, Chinchilla significantly outperforms Gopher despite being much smaller, with an average accuracy of 67.6% (improving upon Gopher by 7.6%). Remarkably, Chinchilla even outperforms the expert forecast for June 2023 of 63.4% accuracy (see Table 6) (Steinhardt 2021). Furthermore, Chinchilla achieves greater than 90% accuracy on 4 different individual tasks– high_school_gov_and_politics, international_law, sociology, and us_foreign_policy. To our knowledge, no other model has achieved greater than 90% accuracy on a subset.
大规模多任务语言理解(MMLU)基准(Hendrycks et al. 2020)包含一系列学术科目上的类考试问题。表 6 报告 Chinchilla 在 MMLU 上的平均 5-shot 表现(完整分项见表 A6)。在该基准上,Chinchilla 尽管小得多,仍显著优于 Gopher,平均准确率 67.6%(相对 Gopher 提升 7.6%)。值得注意的是,Chinchilla 甚至超过了 2023 年 6 月专家预测的 63.4%(见表 6)(Steinhardt 2021)。此外,Chinchilla 在 4 个单项任务上准确率超过 90%——high_school_gov_and_politics、international_law、sociology 与 us_foreign_policy。据我们所知,尚无其他模型在某一子集上超过 90%。
In Figure 6, we show a comparison to Gopher broken down by task. Overall, we find that Chinchilla improves performance on the vast majority of tasks. On four tasks (college_mathematics, econometrics, moral_scenarios, and formal_logic) Chinchilla underperforms Gopher, and there is no change in performance on two tasks.
图 6 按任务展示与 Gopher 的比较。总体而言,Chinchilla 在绝大多数任务上提升表现。在四个任务(college_mathematics、econometrics、moral_scenarios 与 formal_logic)上 Chinchilla 弱于 Gopher,另有两个任务持平。
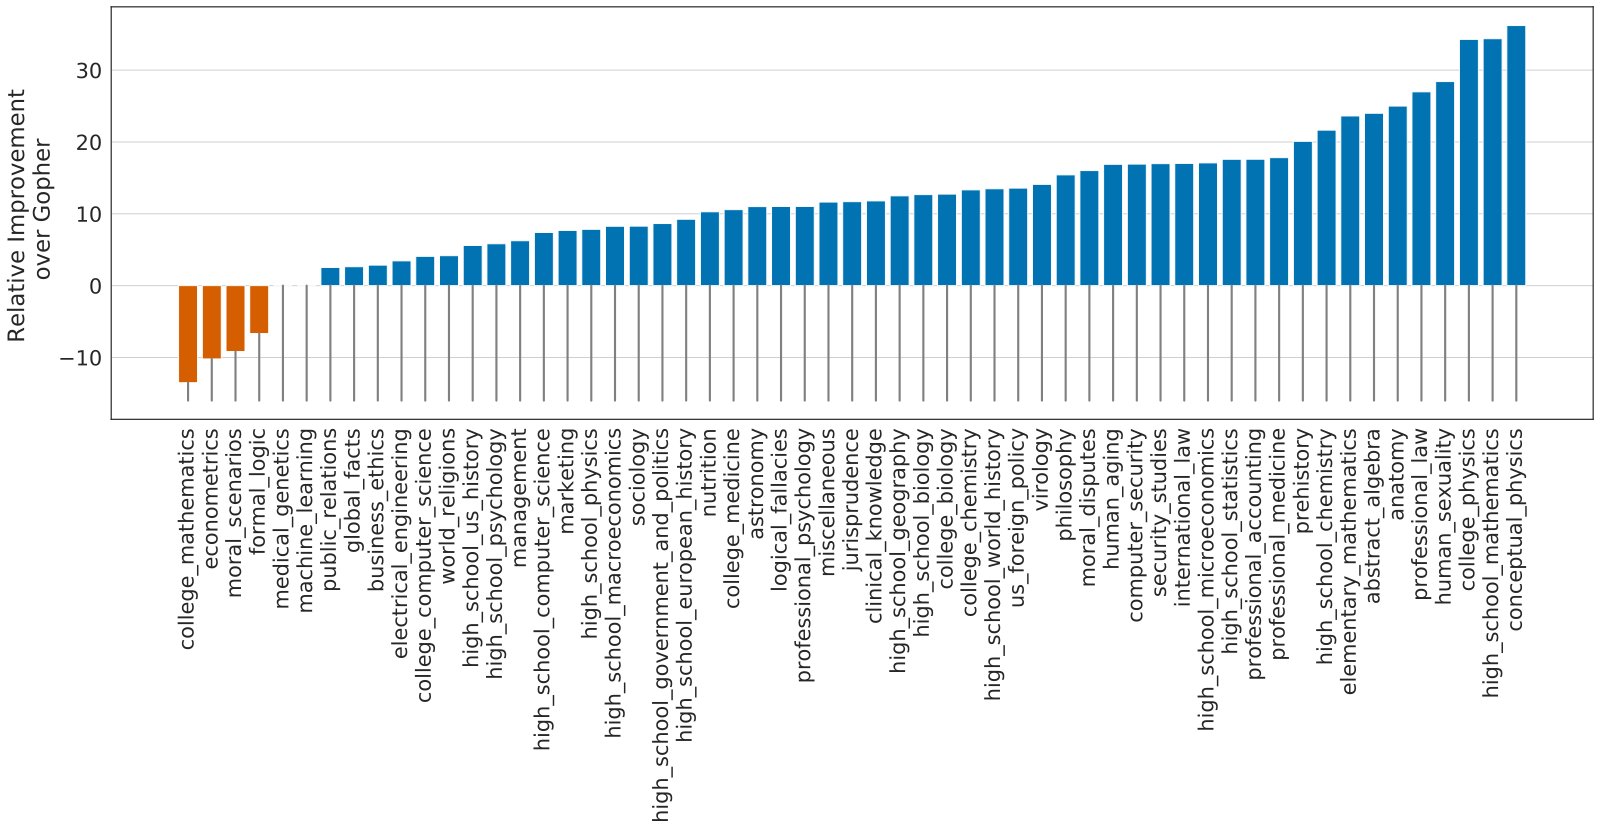
Figure 6: MMLU results compared to Gopher We find that Chinchilla outperforms Gopher by 7.6% on average (see Table 6) in addition to performing better on 51/57 individual tasks, the same on 2/57, and worse on only 4/57 tasks.
图 6:相对 Gopher 的 MMLU 结果。我们发现 Chinchilla 平均优于 Gopher 7.6%(见表 6);在 51/57 个单项任务上更好,2/57 持平,仅 4/57 更差。
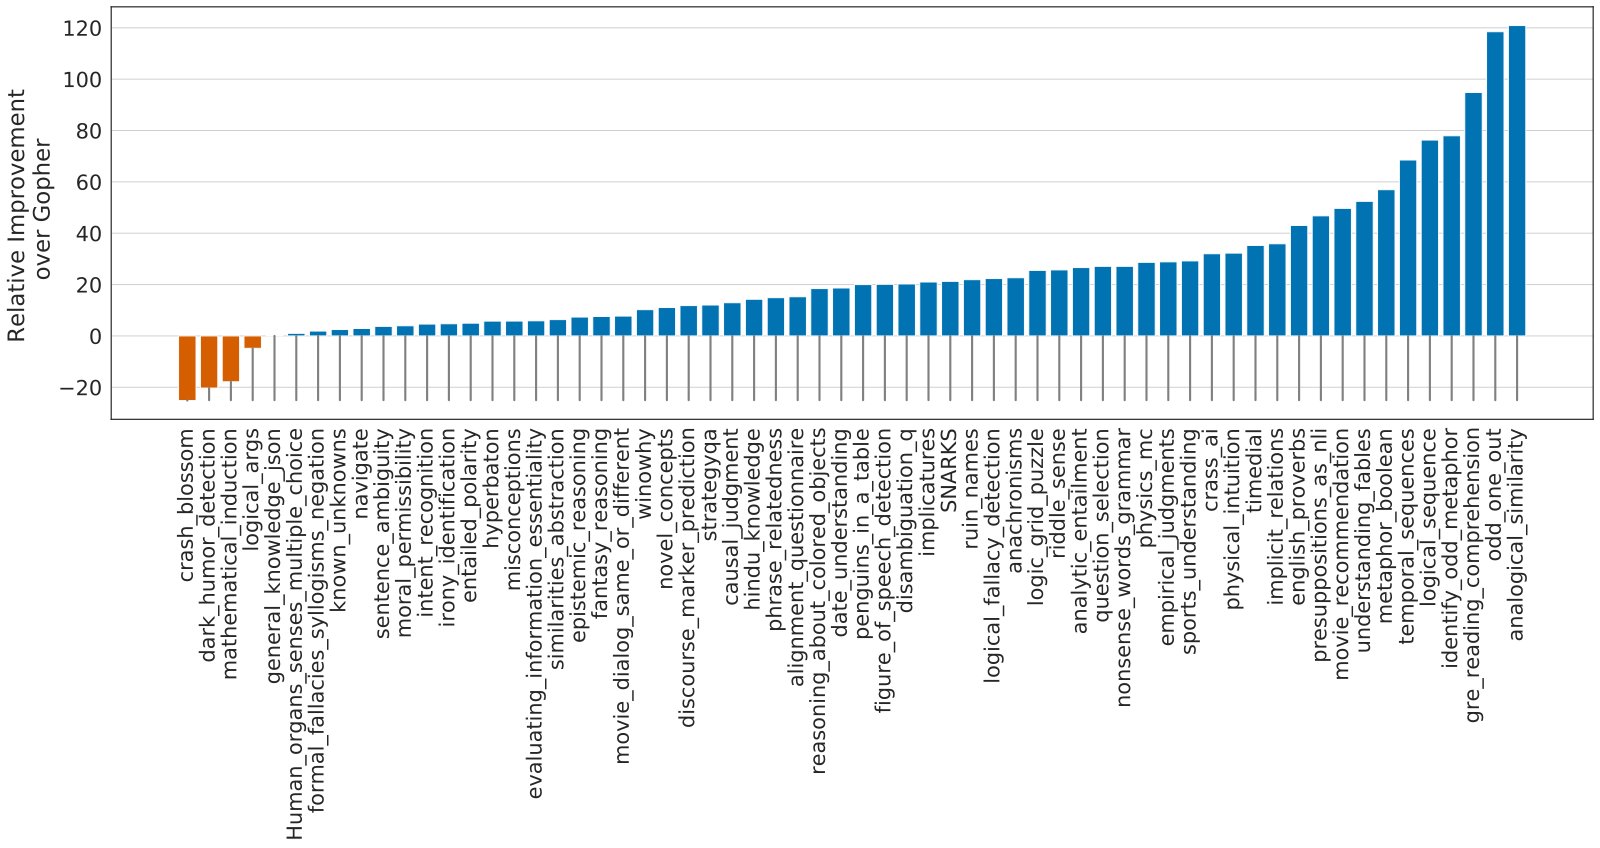
Figure 7: BIG-bench results compared to Gopher Chinchilla out performs Gopher on all but four BIG-bench tasks considered. Full results are in Table A7.
图 7:相对 Gopher 的 BIG-bench 结果。在所考虑的 BIG-bench 任务中,Chinchilla 仅有四项弱于 Gopher。完整结果见表 A7。
4.2.3 Reading comprehension
On the final word prediction dataset LAMBADA (Paperno et al. 2016), Chinchilla achieves 77.4% accuracy, compared to 74.5% accuracy from Gopher and 76.6% from MT-NLG 530B (see Table 7). On RACE-h and RACE-m (Lai et al. 2017), Chinchilla greatly outperforms Gopher, improving accuracy by more than 10% in both cases—see Table 7.
4.2.3 阅读理解
在末词预测数据集 LAMBADA(Paperno et al. 2016)上,Chinchilla 达到 77.4% 准确率,而 Gopher 为 74.5%,MT-NLG 530B 为 76.6%(见表 7)。在 RACE-h 与 RACE-m(Lai et al. 2017)上,Chinchilla 大幅优于 Gopher,两种情形准确率均提升超过 10%——见表 7。
| Chinchilla | Gopher | GPT-3 | MT-NLG 530B | |
|---|---|---|---|---|
| LAMBADA Zero-Shot | 77.4 | 74.5 | 76.2 | 76.6 |
| RACE-m Few-Shot | 86.8 | 75.1 | 58.1 | - |
| RACE-h Few-Shot | 82.3 | 71.6 | 46.8 | 47.9 |
Table 7: Reading comprehension. On RACE-h and RACE-m (Lai et al. 2017), Chinchilla considerably improves performance over Gopher. Note that GPT-3 and MT-NLG 530B use a different prompt format than we do on RACE-h/m, so results are not comparable to Gopher and Chinchilla. On LAMBADA (Paperno et al. 2016), Chinchilla outperforms both Gopher and MT-NLG 530B.
| Chinchilla | Gopher | GPT-3 | MT-NLG 530B | |
|---|---|---|---|---|
| LAMBADA 零样本 | 77.4 | 74.5 | 76.2 | 76.6 |
| RACE-m 少样本 | 86.8 | 75.1 | 58.1 | - |
| RACE-h 少样本 | 82.3 | 71.6 | 46.8 | 47.9 |
表 7:阅读理解。在 RACE-h 与 RACE-m(Lai et al. 2017)上,Chinchilla 相对 Gopher 大幅提升。注意 GPT-3 与 MT-NLG 530B 在 RACE-h/m 上使用的提示格式与我们不同,因而结果不可与 Gopher、Chinchilla 直接比较。在 LAMBADA(Paperno et al. 2016)上,Chinchilla 优于 Gopher 与 MT-NLG 530B。
4.2.4 BIG-bench
We analysed Chinchilla on the same set of BIG-bench tasks (BIG-bench collaboration 2021) reported in Rae et al. 2021. Similar to what we observed in MMLU, Chinchilla outperforms Gopher on the vast majority of tasks (see Figure 7). We find that Chinchilla improves the average performance by 10.7%, reaching an accuracy of 65.1% versus 54.4% for Gopher. Of the 62 tasks we consider, Chinchilla performs worse than Gopher on only four—crash_blossom, dark_humor_detection, mathematical_induction and logical_args. Full accuracy results for Chinchilla can be found in Table A7.
4.2.4 BIG-bench
我们在 Rae et al. 2021 所报告的同一组 BIG-bench 任务(BIG-bench collaboration 2021)上分析 Chinchilla。与 MMLU 类似,Chinchilla 在绝大多数任务上优于 Gopher(见图 7)。平均表现提升 10.7%,准确率达 65.1%,而 Gopher 为 54.4%。在所考虑的 62 个任务中,Chinchilla 仅在四项上弱于 Gopher——crash_blossom、dark_humor_detection、mathematical_induction 与 logical_args。Chinchilla 完整准确率见表 A7。
4.2.5 Common sense
| Chinchilla | Gopher | GPT-3 | MT-NLG 530B | Supervised SOTA | |
|---|---|---|---|---|---|
| HellaSWAG | 80.8% | 79.2% | 78.9% | 80.2% | 93.9% |
| PIQA | 81.8% | 81.8% | 81.0% | 82.0% | 90.1% |
| Winogrande | 74.9% | 70.1% | 70.2% | 73.0% | 91.3% |
| SIQA | 51.3% | 50.6% | - | - | 83.2% |
| BoolQ | 83.7% | 79.3% | 60.5% | 78.2% | 91.4% |
Table 8: Zero-shot comparison on Common Sense benchmarks. We show a comparison between Chinchilla, Gopher, and MT-NLG 530B on various Common Sense benchmarks. We see that Chinchilla matches or outperforms Gopher and GPT-3 on all tasks. On all but one Chinchilla outperforms the much larger MT-NLG 530B model.
4.2.5 常识
| Chinchilla | Gopher | GPT-3 | MT-NLG 530B | 有监督 SOTA | |
|---|---|---|---|---|---|
| HellaSWAG | 80.8% | 79.2% | 78.9% | 80.2% | 93.9% |
| PIQA | 81.8% | 81.8% | 81.0% | 82.0% | 90.1% |
| Winogrande | 74.9% | 70.1% | 70.2% | 73.0% | 91.3% |
| SIQA | 51.3% | 50.6% | - | - | 83.2% |
| BoolQ | 83.7% | 79.3% | 60.5% | 78.2% | 91.4% |
表 8:常识基准上的零样本比较。展示 Chinchilla、Gopher 与 MT-NLG 530B 在多种常识基准上的比较。Chinchilla 在全部任务上匹配或优于 Gopher 与 GPT-3;除一项外均优于体量更大的 MT-NLG 530B。
We evaluate Chinchilla on various common sense benchmarks: PIQA (Bisk et al. 2020), SIQA (Sap et al. 2019), Winogrande (Sakaguchi et al. 2020), HellaSwag (Zellers et al. 2019), and BoolQ (Clark et al. 2019). We find that Chinchilla outperforms both Gopher and GPT-3 on all tasks and outperforms MT-NLG 530B on all but one task—see Table 8.
我们在多种常识基准上评测 Chinchilla:PIQA(Bisk et al. 2020)、SIQA(Sap et al. 2019)、Winogrande(Sakaguchi et al. 2020)、HellaSwag(Zellers et al. 2019)与 BoolQ(Clark et al. 2019)。我们发现 Chinchilla 在全部任务上优于 Gopher 与 GPT-3,并在除一项外的全部任务上优于 MT-NLG 530B——见表 8。
On TruthfulQA (Lin et al. 2021), Chinchilla reaches 43.6%, 58.5%, and 66.7% accuracy with 0-shot, 5-shot, and 10-shot respectively. In comparison, Gopher achieved only 29.5% 0-shot and 43.7% 10-shot accuracy. In stark contrast with the findings of Lin et al. 2021, the large improvements (14.1% in 0-shot accuracy) achieved by Chinchilla suggest that better modelling of the pre-training data alone can lead to substantial improvements on this benchmark.
在 TruthfulQA(Lin et al. 2021)上,Chinchilla 在 0-shot、5-shot 与 10-shot 下分别达到 43.6%、58.5% 与 66.7% 准确率。相较之下,Gopher 仅达 29.5% 0-shot 与 43.7% 10-shot。与 Lin et al. 2021 的发现形成鲜明对照:Chinchilla 带来的大幅提升(0-shot 准确率 +14.1%)表明,仅靠更好拟合预训练数据,也可在该基准上取得实质改进。
4.2.6 Closed-book question answering
Results on closed-book question answering benchmarks are reported in Table 9. On the Natural Questions dataset (Kwiatkowski et al. 2019), Chinchilla achieves new closed-book SOTA accuracies: 31.5% 5-shot and 35.5% 64-shot, compared to 21% and 28% respectively, for Gopher. On TriviaQA (Joshi et al. 2017) we show results for both the filtered (previously used in retrieval and open-book work) and unfiltered set (previously used in large language model evaluations). In both cases, Chinchilla substantially out performs Gopher. On the filtered version, Chinchilla lags behind the open book SOTA (Izacard and Grave 2020) by only 7.9%. On the unfiltered set, Chinchilla outperforms GPT-3—see Table 9.
4.2.6 闭卷问答
闭卷问答基准结果见表 9。在 Natural Questions 数据集(Kwiatkowski et al. 2019)上,Chinchilla 达到新的闭卷当时最优:5-shot 31.5%、64-shot 35.5%,而 Gopher 分别为 21% 与 28%。在 TriviaQA(Joshi et al. 2017)上,我们同时报告过滤集(既往用于检索与开卷工作)与未过滤集(既往用于大语言模型评测)。两种情形下 Chinchilla 都大幅优于 Gopher。在过滤版本上,Chinchilla 仅落后开卷当时最优(Izacard and Grave 2020)7.9%。在未过滤集上,Chinchilla 优于 GPT-3——见表 9。
| Method | Chinchilla | Gopher | GPT-3 | SOTA (open book) | |
|---|---|---|---|---|---|
| Natural Questions (dev) | 0-shot | 16.6% | 10.1% | 14.6% | 54.4% |
| 5-shot | 31.5% | 24.5% | - | ||
| 64-shot | 35.5% | 28.2% | 29.9% | ||
| TriviaQA (unfiltered, test) | 0-shot | 67.0% | 52.8% | 64.3 % | - |
| 5-shot | 73.2% | 63.6% | - | ||
| 64-shot | 72.3% | 61.3% | 71.2% | ||
| TriviaQA (filtered, dev) | 0-shot | 55.4% | 43.5% | - | 72.5% |
| 5-shot | 64.1% | 57.0% | - | ||
| 64-shot | 64.6% | 57.2% | - |
Table 9: Closed-book question answering. For Natural Questions (Kwiatkowski et al. 2019) and TriviaQA (Joshi et al. 2017), Chinchilla outperforms Gopher in all cases. On Natural Questions, Chinchilla outperforms GPT-3. On TriviaQA we show results on two different evaluation sets to allow for comparison to GPT-3 and to open book SOTA (FiD + Distillation (Izacard and Grave 2020)).
| 设定 | Chinchilla | Gopher | GPT-3 | SOTA(开卷) | |
|---|---|---|---|---|---|
| Natural Questions(dev) | 0-shot | 16.6% | 10.1% | 14.6% | 54.4% |
| 5-shot | 31.5% | 24.5% | - | ||
| 64-shot | 35.5% | 28.2% | 29.9% | ||
| TriviaQA(未过滤,test) | 0-shot | 67.0% | 52.8% | 64.3 % | - |
| 5-shot | 73.2% | 63.6% | - | ||
| 64-shot | 72.3% | 61.3% | 71.2% | ||
| TriviaQA(过滤,dev) | 0-shot | 55.4% | 43.5% | - | 72.5% |
| 5-shot | 64.1% | 57.0% | - | ||
| 64-shot | 64.6% | 57.2% | - |
表 9:闭卷问答。在 Natural Questions(Kwiatkowski et al. 2019)与 TriviaQA(Joshi et al. 2017)上,Chinchilla 在所有情形下都优于 Gopher。在 Natural Questions 上,Chinchilla 优于 GPT-3。TriviaQA 上我们展示两套评测集,以便与 GPT-3 及开卷当时最优(FiD + Distillation(Izacard and Grave 2020))比较。
4.2.7 Gender bias and toxicity
Large Language Models carry potential risks such as outputting offensive language, propagating social biases, and leaking private information (Weidinger et al. 2021; Bender et al. 2021). We expect Chinchilla to carry risks similar to Gopher because Chinchilla is trained on the same data, albeit with slightly different relative weights, and because it has a similar architecture. Here, we examine gender bias (particularly gender and occupation bias) and generation of toxic language. We select a few common evaluations to highlight potential issues, but stress that our evaluations are not comprehensive and much work remains to understand, evaluate, and mitigate risks in LLMs.
4.2.7 性别偏见与毒性
大规模语言模型存在输出冒犯性语言、传播社会偏见、泄露隐私信息等潜在风险(Weidinger et al. 2021; Bender et al. 2021)。我们预期 Chinchilla 与 Gopher 面临类似风险,因为二者训练数据相同(相对权重略有不同),架构也相近。这里我们考察性别偏见(尤其是性别与职业偏见)以及有毒语言生成。我们选取若干常见评测以标出潜在问题,但强调评测并不全面;理解、评估与缓解 LLM 风险仍有大量工作。
Gender bias.
As discussed in Rae et al. 2021, large language models reflect contemporary and historical discourse about different groups (such as gender groups) from their training dataset, and we expect the same to be true for Chinchilla. Here, we test if potential gender and occupation biases manifest in unfair outcomes on coreference resolutions, using the Winogender dataset (Rudinger et al. 2018) in a zero-shot setting. Winogender tests whether a model can correctly determine if a pronoun refers to different occupation words. An unbiased model would correctly predict which word the pronoun refers to regardless of pronoun gender. We follow the same setup as in Rae et al. 2021 (described further in Section H.3).
性别偏见。
如 Rae et al. 2021 所论,大规模语言模型会反映训练数据中关于不同群体(如性别群体)的当代与历史话语,我们预期 Chinchilla 亦然。这里我们用 Winogender 数据集(Rudinger et al. 2018)在零样本设定下,检验潜在的性别与职业偏见是否表现为共指消解上的不公平结果。Winogender 测试模型能否正确判断代词指向不同职业词。无偏模型应无论代词性别,都能正确预测代词所指的词。我们沿用 Rae et al. 2021 的设定(第 H.3 节另有说明)。
As shown in Table 10, Chinchilla correctly resolves pronouns more frequently than Gopher across all groups. Interestingly, the performance increase is considerably smaller for male pronouns (increase of 3.2%) than for female or neutral pronouns (increases of 8.3% and 9.2% respectively). We also consider gotcha examples, in which the correct pronoun resolution contradicts gender stereotypes (determined by labor statistics). Again, we see that Chinchilla resolves pronouns more accurately than Gopher. When breaking up examples by male/female gender and gotcha/not gotcha, the largest improvement is on female gotcha examples (improvement of 10%). Thus, though Chinchilla uniformly overcomes gender stereotypes for more coreference examples than Gopher, the rate of improvement is higher for some pronouns than others, suggesting that the improvements conferred by using a more compute-optimal model can be uneven.
如表 10 所示,Chinchilla 在所有组别上正确消解代词的频率都高于 Gopher。有趣的是,男性代词上的提升明显较小(+3.2%),而女性与中性代词提升分别为 8.3% 与 9.2%。我们还考察 gotcha 样例:正确代词消解与性别刻板印象(由劳动统计确定)相矛盾的情形。同样,Chinchilla 比 Gopher 更准确地消解代词。按男/女性别与 gotcha/not gotcha 分组时,最大提升出现在女性 gotcha 样例(+10%)。因此,尽管 Chinchilla 在更多共指样例上均匀地克服性别刻板印象,但不同代词上的改进速率不同,提示使用更算力最优模型带来的收益可能不均匀。
| Chinchilla | Gopher | |
|---|---|---|
| All | 78.3% | 71.4% |
| Male | 71.2% | 68.0% |
| Female | 79.6% | 71.3% |
| Neutral | 84.2% | 75.0% |
| Chinchilla | Gopher | |
|---|---|---|
| Male gotcha | 62.5% | 59.2% |
| Male not gotcha | 80.0% | 76.7% |
| Female gotcha | 76.7% | 66.7% |
| Female not gotcha | 82.5% | 75.8% |
Table 10: Winogender results. Left: Chinchilla consistently resolves pronouns better than Gopher. Right: Chinchilla performs better on examples which contradict gender stereotypes (gotcha examples). However, difference in performance across groups suggests Chinchilla exhibits bias.
| Chinchilla | Gopher | |
|---|---|---|
| 全部 | 78.3% | 71.4% |
| 男性 | 71.2% | 68.0% |
| 女性 | 79.6% | 71.3% |
| 中性 | 84.2% | 75.0% |
| Chinchilla | Gopher | |
|---|---|---|
| 男性 gotcha | 62.5% | 59.2% |
| 男性 not gotcha | 80.0% | 76.7% |
| 女性 gotcha | 76.7% | 66.7% |
| 女性 not gotcha | 82.5% | 75.8% |
表 10:Winogender 结果。左:Chinchilla 一致比 Gopher 更好地消解代词。右:Chinchilla 在与性别刻板印象矛盾的样例(gotcha)上表现更好。但各组表现差异提示 Chinchilla 仍存在偏见。
Sample toxicity.
Language models are capable of generating toxic language—including insults, hate speech, profanities and threats (Gehman et al. 2020; Rae et al. 2021). While toxicity is an umbrella term, and its evaluation in LMs comes with challenges (Xu et al. 2021; Welbl et al. 2021), automatic classifier scores can provide an indication for the levels of harmful text that a LM generates. Rae et al. 2021 found that improving language modelling loss by increasing the number of model parameters has only a negligible effect on toxic text generation (unprompted); here we analyze whether the same holds true for a lower LM loss achieved via more compute-optimal training. Similar to the protocol of Rae et al. 2021, we generate 25,000 unprompted samples from Chinchilla, and compare their PerspectiveAPI toxicity score distribution to that of Gopher-generated samples. Several summary statistics indicate an absence of major differences: the mean (median) toxicity score for Gopher is 0.081 (0.064), compared to 0.087 (0.066) for Chinchilla, and the percentile scores are 0.230 for Gopher, compared to 0.238 for Chinchilla. That is, the large majority of generated samples are classified as non-toxic, and the difference between the models is negligible. In line with prior findings (Rae et al. 2021), this suggests that toxicity levels in unconditional text generation are largely independent of the model quality (measured in language modelling loss), i.e. that better models of the training dataset are not necessarily more toxic.
样本毒性。
语言模型能够生成有毒语言——包括侮辱、仇恨言论、脏话与威胁(Gehman et al. 2020; Rae et al. 2021)。尽管毒性是一把伞状术语,且其在 LM 中的评测存在挑战(Xu et al. 2021; Welbl et al. 2021),自动分类器分数仍可指示 LM 生成有害文本的水平。Rae et al. 2021 发现:通过增大模型参数量来改进语言建模损失,对(无提示)有毒文本生成几乎没有影响;这里我们分析:经由更算力最优训练达到更低 LM 损失时,是否仍然成立。与 Rae et al. 2021 的协议类似,我们从 Chinchilla 生成 25,000 条无提示样本,并将其 PerspectiveAPI 毒性分数分布与 Gopher 生成样本比较。若干汇总统计表明无明显差异:Gopher 的均值(中位数)毒性分数为 0.081(0.064),Chinchilla 为 0.087(0.066);第 百分位分数 Gopher 为 0.230,Chinchilla 为 0.238。也就是说,绝大多数生成样本被判为非有毒,模型间差异可忽略。与先前发现(Rae et al. 2021)一致,这提示无条件文本生成中的毒性水平大体独立于模型质量(以语言建模损失衡量),即更好拟合训练数据的模型并不必然更有毒。
5 Discussion & Conclusion
5 讨论与结论
The trend so far in large language model training has been to increase the model size, often without increasing the number of training tokens. The largest dense transformer, MT-NLG 530B, is now over larger than GPT-3’s 170 billion parameters from just two years ago. However, this model, as well as the majority of existing large models, have all been trained for a comparable number of tokens—around 300 billion. While the desire to train these mega-models has led to substantial engineering innovation, we hypothesize that the race to train larger and larger models is resulting in models that are substantially underperforming compared to what could be achieved with the same compute budget.
大规模语言模型训练迄今的趋势是增大模型规模,往往不同时增加训练 token 数。最大的稠密 Transformer MT-NLG 530B 现已超过两年前 GPT-3 的 1700 亿参数的 。然而该模型以及多数既有大模型,训练 token 数都相当——约 3000 亿。尽管训练这些巨型模型的愿望催生了大量工程创新,我们假设:竞相训练越来越大的模型,正导致相对同一算力预算本可达到的表现明显不足。
We propose three predictive approaches towards optimally setting model size and training duration, based on the outcome of over 400 training runs. All three approaches predict that Gopher is substantially over-sized and estimate that for the same compute budget a smaller model trained on more data will perform better. We directly test this hypothesis by training Chinchilla, a 70B parameter model, and show that it outperforms Gopher and even larger models on nearly every measured evaluation task.
我们提出三种预测方法,用于在给定额外算力时最优设定模型规模与训练时长,依据逾 400 次训练运行的结果。三种方法都预测 Gopher 明显过大,并估计:同一算力预算下,在更多数据上训练的较小模型会表现更好。我们通过训练 700 亿参数的 Chinchilla 直接检验该假说,并表明它在几乎每一项测得的评测任务上都优于 Gopher 乃至更大模型。
Whilst our method allows us to make predictions on how to scale large models when given additional compute, there are several limitations. Due to the cost of training large models, we only have two comparable training runs at large scale (Chinchilla and Gopher), and we do not have additional tests at intermediate scales. Furthermore, we assume that the efficient computational frontier can be described by a power-law relationship between the compute budget, model size, and number of training tokens. However, we observe some concavity in at high compute budgets (see Appendix E). This suggests that we may still be overestimating the optimal size of large models. Finally, the training runs for our analysis have all been trained on less than an epoch of data; future work may consider the multiple epoch regime. Despite these limitations, the comparison of Chinchilla to Gopher validates our performance predictions, that have thus enabled training a better (and more lightweight) model at the same compute budget.
尽管我们的方法能在给定额外算力时预测如何放大模型,仍有若干局限。由于训练大模型成本高,我们在大规模上仅有两次可比较的训练运行(Chinchilla 与 Gopher),中间尺度也没有额外检验。此外,我们假定高效计算前沿可由算力预算、模型规模与训练 token 数之间的幂律关系描述。然而我们在高算力预算下观察到 存在一定凹性(见附录 E)。这提示我们仍可能高估大模型的最优规模。最后,本分析的训练运行都在不足一个 epoch 的数据上完成;未来工作可考虑多 epoch 情形。尽管有这些局限,Chinchilla 与 Gopher 的比较验证了我们的性能预测,从而在相同算力预算下训出了更好(也更轻量)的模型。
Though there has been significant recent work allowing larger and larger models to be trained, our analysis suggests an increased focus on dataset scaling is needed. Speculatively, we expect that scaling to larger and larger datasets is only beneficial when the data is high-quality. This calls for responsibly collecting larger datasets with a high focus on dataset quality. Larger datasets will require extra care to ensure train-test set overlap is properly accounted for, both in the language modelling loss but also with downstream tasks. Finally, training for trillions of tokens introduces many ethical and privacy concerns. Large datasets scraped from the web will contain toxic language, biases, and private information. With even larger datasets being used, the quantity (if not the frequency) of such information increases, which makes dataset introspection all the more important. Chinchilla does suffer from bias and toxicity but interestingly it seems less affected than Gopher. Better understanding how performance of large language models and toxicity interact is an important future research question.
尽管近来有大量工作使越来越大的模型得以训练,我们的分析提示需要更关注数据集扩展。推测而言,我们预期只有在数据高质量时,扩展到越来越大的数据集才有益。这呼吁负责任地收集更大数据集,并高度重视数据质量。更大的数据集需要额外小心,确保语言建模损失与下游任务上都妥善处理训练-测试集重叠。最后,训练万亿级 token 会引入许多伦理与隐私关切。从网络抓取的大数据集将包含有毒语言、偏见与隐私信息。随着使用更大的数据集,此类信息的数量(即便不是频率)会增加,使数据集内省愈发重要。Chinchilla 确实存在偏见与毒性,但有趣的是似乎比 Gopher 受影响更小。更好理解大规模语言模型性能与毒性如何相互作用,是重要的未来研究问题。
While we have applied our methodology towards the training of auto-regressive language models, we expect that there is a similar trade-off between model size and the amount of data in other modalities. As training large models is very expensive, choosing the optimal model size and training steps beforehand is essential. The methods we propose are easy to reproduce in new settings.
虽然我们把方法应用于自回归语言模型的训练,我们预期其他模态中模型规模与数据量之间也存在类似权衡。由于训练大模型非常昂贵,事先选择最优模型规模与训练步数至关重要。我们提出的方法易于在新设定中复现。
6 Acknowledgements
6 致谢
We’d like to thank Jean-baptiste Alayrac, Kareem Ayoub, Chris Dyer, Nando de Freitas, Demis Hassabis, Geoffrey Irving, Koray Kavukcuoglu, Nate Kushman and Angeliki Lazaridou for useful comments on the manuscript. We’d like to thank Andy Brock, Irina Higgins, Michela Paganini, Francis Song, and other colleagues at DeepMind for helpful discussions. We are also very grateful to the JAX and XLA team for their support and assistance.
我们感谢 Jean-baptiste Alayrac、Kareem Ayoub、Chris Dyer、Nando de Freitas、Demis Hassabis、Geoffrey Irving、Koray Kavukcuoglu、Nate Kushman 与 Angeliki Lazaridou 对文稿的有益意见。感谢 Andy Brock、Irina Higgins、Michela Paganini、Francis Song 以及 DeepMind 其他同事的有益讨论。我们也非常感谢 JAX 与 XLA 团队的支持与协助。
References
参考文献
Artetxe et al. (2021) M. Artetxe, S. Bhosale, N. Goyal, T. Mihaylov, M. Ott, S. Shleifer, X. V. Lin, J. Du, S. Iyer, R. Pasunuru, G. Anantharaman, X. Li, S. Chen, H. Akin, M. Baines, L. Martin, X. Zhou, P. S. Koura, B. O’Horo, J. Wang, L. Zettlemoyer, M. Diab, Z. Kozareva, and V. Stoyanov. Efficient Large Scale Language Modeling with Mixtures of Experts. arXiv:2112.10684 , 2021.
Bender et al. (2021) E. M. Bender, T. Gebru, A. McMillan-Major, and S. Shmitchell. On the dangers of stochastic parrots: Can language models be too big? In Proceedings of the 2021 ACM Conference on Fairness, Accountability, and Transparency , pages 610–623, 2021.
BIG-bench collaboration (2021) BIG-bench collaboration. Beyond the imitation game: Measuring and extrapolating the capabilities of language models. In preparation , 2021. URL https://github.com/google/BIG-bench/ .
Bisk et al. (2020) Y. Bisk, R. Zellers, J. Gao, Y. Choi, et al. PIQA: Reasoning about physical commonsense in natural language. In Proceedings of the AAAI Conference on Artificial Intelligence , volume 34, pages 7432–7439, 2020.
Borgeaud et al. (2021) S. Borgeaud, A. Mensch, J. Hoffmann, T. Cai, E. Rutherford, K. Millican, G. van den Driessche, J.-B. Lespiau, B. Damoc, A. Clark, D. de Las Casas, A. Guy, J. Menick, R. Ring, T. Hennigan, S. Huang, L. Maggiore, C. Jones, A. Cassirer, A. Brock, M. Paganini, G. Irving, O. Vinyals, S. Osindero, K. Simonyan, J. W. Rae, E. Elsen, and L. Sifre. Improving language models by retrieving from trillions of tokens. arXiv 2112.04426 , 2021.
Bradbury et al. (2018) J. Bradbury, R. Frostig, P. Hawkins, M. J. Johnson, C. Leary, D. Maclaurin, G. Necula, A. Paszke, J. VanderPlas, S. Wanderman-Milne, and Q. Zhang. JAX: composable transformations of Python+NumPy programs. 2018. URL http://github.com/google/jax .
Brown et al. (2020) T. Brown, B. Mann, N. Ryder, M. Subbiah, J. D. Kaplan, P. Dhariwal, A. Neelakantan, P. Shyam, G. Sastry, A. Askell, S. Agarwal, A. Herbert-Voss, G. Krueger, T. Henighan, R. Child, A. Ramesh, D. Ziegler, J. Wu, C. Winter, C. Hesse, M. Chen, E. Sigler, M. Litwin, S. Gray, B. Chess, J. Clark, C. Berner, S. McCandlish, A. Radford, I. Sutskever, and D. Amodei. Language models are few-shot learners. In H. Larochelle, M. Ranzato, R. Hadsell, M. F. Balcan, and H. Lin, editors, Advances in Neural Information Processing Systems , volume 33, pages 1877–1901. Curran Associates, Inc., 2020. URL https://proceedings.neurips.cc/paper/2020/file/1457c0d6bfcb4967418bfb8ac142f64a-Paper.pdf .
Bubeck (2015) S. Bubeck. Convex Optimization: Algorithms and Complexity. Foundations and Trends in Machine Learning , 8(3-4):231–357, 2015. URL http://www.nowpublishers.com/article/Details/MAL-050 .
Clark et al. (2022) A. Clark, D. d. l. Casas, A. Guy, A. Mensch, M. Paganini, J. Hoffmann, B. Damoc, B. Hechtman, T. Cai, S. Borgeaud, G. v. d. Driessche, E. Rutherford, T. Hennigan, M. Johnson, K. Millican, A. Cassirer, C. Jones, E. Buchatskaya, D. Budden, L. Sifre, S. Osindero, O. Vinyals, J. Rae, E. Elsen, K. Kavukcuoglu, and K. Simonyan. Unified scaling laws for routed language models, 2022. URL https://arxiv.org/abs/2202.01169 .
Clark et al. (2019) C. Clark, K. Lee, M.-W. Chang, T. Kwiatkowski, M. Collins, and K. Toutanova. Boolq: Exploring the surprising difficulty of natural yes/no questions. In Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) , pages 2924–2936, 2019.
Du et al. (2021) N. Du, Y. Huang, A. M. Dai, S. Tong, D. Lepikhin, Y. Xu, M. Krikun, Y. Zhou, A. W. Yu, O. Firat, B. Zoph, L. Fedus, M. Bosma, Z. Zhou, T. Wang, Y. E. Wang, K. Webster, M. Pellat, K. Robinson, K. Meier-Hellstern, T. Duke, L. Dixon, K. Zhang, Q. V. Le, Y. Wu, Z. Chen, and C. Cui. Glam: Efficient scaling of language models with mixture-of-experts, 2021. URL https://arxiv.org/abs/2112.06905 .
Fedus et al. (2021) W. Fedus, B. Zoph, and N. Shazeer. Switch transformers: Scaling to trillion parameter models with simple and efficient sparsity. arXiv preprint arXiv:2101.03961 , 2021.
Gao et al. (2020) L. Gao, S. Biderman, S. Black, L. Golding, T. Hoppe, C. Foster, J. Phang, H. He, A. Thite, N. Nabeshima, S. Presser, and C. Leahy. The Pile: An 800GB dataset of diverse text for language modeling. arXiv preprint arXiv:2101.00027 , 2020.
Gehman et al. (2020) S. Gehman, S. Gururangan, M. Sap, Y. Choi, and N. A. Smith. RealToxicityPrompts: Evaluating neural toxic degeneration in language models. In Findings of the Association for Computational Linguistics: EMNLP 2020 , pages 3356–3369, Online, Nov. 2020. Association for Computational Linguistics. 10.18653/v1/2020.findings-emnlp.301 . URL https://aclanthology.org/2020.findings-emnlp.301 .
Guu et al. (2020) K. Guu, K. Lee, Z. Tung, P. Pasupat, and M.-W. Chang. REALM: Retrieval-augmented language model pre-training, 2020.
Hendrycks et al. (2020) D. Hendrycks, C. Burns, S. Basart, A. Zou, M. Mazeika, D. Song, and J. Steinhardt. Measuring massive multitask language understanding. arXiv preprint arXiv:2009.03300 , 2020.
Hennigan et al. (2020) T. Hennigan, T. Cai, T. Norman, and I. Babuschkin. Haiku: Sonnet for JAX. 2020. URL http://github.com/deepmind/dm-haiku .
Hernandez et al. (2021) D. Hernandez, J. Kaplan, T. Henighan, and S. McCandlish. Scaling laws for transfer, 2021.
Huber (1964) P. J. Huber. Robust Estimation of a Location Parameter. The Annals of Mathematical Statistics , 35(1):73–101, Mar. 1964. ISSN 0003-4851, 2168-8990. 10.1214/aoms/1177703732 . URL https://projecteuclid.org/journals/annals-of-mathematical-statistics/volume-35/issue-1/Robust-Estimation-of-a-Location-Parameter/10.1214/aoms/1177703732.full .
Izacard and Grave (2020) G. Izacard and E. Grave. Distilling knowledge from reader to retriever for question answering, 2020.
Joshi et al. (2017) M. Joshi, E. Choi, D. Weld, and L. Zettlemoyer. TriviaQA: A Large Scale Distantly Supervised Challenge Dataset for Reading Comprehension. arXiv e-prints , art. arXiv:1705.03551, 2017.
Jouppi et al. (2017) N. P. Jouppi, C. Young, N. Patil, D. Patterson, G. Agrawal, R. Bajwa, S. Bates, S. Bhatia, N. Boden, A. Borchers, R. Boyle, P.-l. Cantin, C. Chao, C. Clark, J. Coriell, M. Daley, M. Dau, J. Dean, B. Gelb, T. V. Ghaemmaghami, R. Gottipati, W. Gulland, R. Hagmann, C. R. Ho, D. Hogberg, J. Hu, R. Hundt, D. Hurt, J. Ibarz, A. Jaffey, A. Jaworski, A. Kaplan, H. Khaitan, D. Killebrew, A. Koch, N. Kumar, S. Lacy, J. Laudon, J. Law, D. Le, C. Leary, Z. Liu, K. Lucke, A. Lundin, G. MacKean, A. Maggiore, M. Mahony, K. Miller, R. Nagarajan, R. Narayanaswami, R. Ni, K. Nix, T. Norrie, M. Omernick, N. Penukonda, A. Phelps, J. Ross, M. Ross, A. Salek, E. Samadiani, C. Severn, G. Sizikov, M. Snelham, J. Souter, D. Steinberg, A. Swing, M. Tan, G. Thorson, B. Tian, H. Toma, E. Tuttle, V. Vasudevan, R. Walter, W. Wang, E. Wilcox, and D. H. Yoon. In-datacenter performance analysis of a tensor processing unit. In Proceedings of the 44th Annual International Symposium on Computer Architecture , ISCA ’17, page 1–12, New York, NY, USA, 2017. Association for Computing Machinery. ISBN 9781450348928. 10.1145/3079856.3080246 . URL https://doi.org/10.1145/3079856.3080246 .
Kaplan et al. (2020) J. Kaplan, S. McCandlish, T. Henighan, T. B. Brown, B. Chess, R. Child, S. Gray, A. Radford, J. Wu, and D. Amodei. Scaling laws for neural language models. arXiv preprint arXiv:2001.08361 , 2020.
Kingma and Ba (2014) D. P. Kingma and J. Ba. Adam: A method for stochastic optimization. arXiv preprint arXiv:1412.6980 , 2014.
Kudo and Richardson (2018) T. Kudo and J. Richardson. SentencePiece: A simple and language independent subword tokenizer and detokenizer for neural text processing. arXiv preprint arXiv:1808.06226 , 2018.
Kwiatkowski et al. (2019) T. Kwiatkowski, J. Palomaki, O. Redfield, M. Collins, A. Parikh, C. Alberti, D. Epstein, I. Polosukhin, M. Kelcey, J. Devlin, K. Lee, K. N. Toutanova, L. Jones, M.-W. Chang, A. Dai, J. Uszkoreit, Q. Le, and S. Petrov. Natural questions: a benchmark for question answering research. Transactions of the Association of Computational Linguistics , 2019.
Lai et al. (2017) G. Lai, Q. Xie, H. Liu, Y. Yang, and E. Hovy. RACE: Large-scale ReAding comprehension dataset from examinations. In Proceedings of the 2017 Conference on Empirical Methods in Natural Language Processing , pages 785–794, Copenhagen, Denmark, Sept. 2017. Association for Computational Linguistics. 10.18653/v1/D17-1082 . URL https://aclanthology.org/D17-1082 .
Levine et al. (2020) Y. Levine, N. Wies, O. Sharir, H. Bata, and A. Shashua. The depth-to-width interplay in self-attention. arXiv preprint arXiv:2006.12467 , 2020.
Lewis et al. (2020) P. Lewis, E. Perez, A. Piktus, F. Petroni, V. Karpukhin, N. Goyal, H. Küttler, M. Lewis, W.-t. Yih, T. Rocktäschel, S. Riedel, and D. Kiela. Retrieval-augmented generation for knowledge-intensive nlp tasks. In Advances in Neural Information Processing Systems , volume 33, pages 9459–9474, 2020.
Lieber et al. (2021) O. Lieber, O. Sharir, B. Lenz, and Y. Shoham. Jurassic-1: Technical details and evaluation. White Paper. AI21 Labs , 2021.
Lin et al. (2021) S. Lin, J. Hilton, and O. Evans. TruthfulQA: Measuring how models mimic human falsehoods. arXiv preprint arXiv:2109.07958 , 2021.
Loshchilov and Hutter (2019) I. Loshchilov and F. Hutter. Decoupled weight decay regularization. In International Conference on Learning Representations , 2019. URL https://openreview.net/forum?id=Bkg6RiCqY7 .
McCandlish et al. (2018) S. McCandlish, J. Kaplan, D. Amodei, and O. D. Team. An empirical model of large-batch training, 2018.
Merity et al. (2017) S. Merity, C. Xiong, J. Bradbury, and R. Socher. Pointer sentinel mixture models. International Conference on Learning Representations , 2017.
Mitchell et al. (2019) M. Mitchell, S. Wu, A. Zaldivar, P. Barnes, L. Vasserman, B. Hutchinson, E. Spitzer, I. D. Raji, and T. Gebru. Model cards for model reporting. In Proceedings of the conference on fairness, accountability, and transparency , pages 220–229, 2019.
Nocedal (1980) J. Nocedal. Updating Quasi-Newton Matrices with Limited Storage. Mathematics of Computation , 35(151):773–782, 1980. ISSN 0025-5718. 10.2307/2006193 . URL https://www.jstor.org/stable/2006193 .
Paperno et al. (2016) D. Paperno, G. Kruszewski, A. Lazaridou, Q. N. Pham, R. Bernardi, S. Pezzelle, M. Baroni, G. Boleda, and R. Fernández. The LAMBADA dataset: Word prediction requiring a broad discourse context, 2016.
Rae et al. (2021) J. Rae, S. Borgeaud, T. Cai, K. Millican, J. Hoffmann, F. Song, J. Aslanides, S. Henderson, R. Ring, S. Young, E. Rutherford, T. Hennigan, J. Menick, A. Cassirer, R. Powell, G. van den Driessche, L. A. Hendricks, M. Rauh, P.-S. Huang, A. Glaese, J. Welbl, S. Dathathri, S. Huang, J. Uesato, J. Mellor, I. Higgins, A. Creswell, N. McAleese, A. Wu, E. Elsen, S. Jayakumar, E. Buchatskaya, D. Budden, E. Sutherland, K. Simonyan, M. Paganini, L. Sifre, L. Martens, X. L. Li, A. Kuncoro, A. Nematzadeh, E. Gribovskaya, D. Donato, A. Lazaridou, A. Mensch, J.-B. Lespiau, M. Tsimpoukelli, N. Grigorev, D. Fritz, T. Sottiaux, M. Pajarskas, T. Pohlen, Z. Gong, D. Toyama, C. de Masson d’Autume, Y. Li, T. Terzi, I. Babuschkin, A. Clark, D. de Las Casas, A. Guy, J. Bradbury, M. Johnson, L. Weidinger, I. Gabriel, W. Isaac, E. Lockhart, S. Osindero, L. Rimell, C. Dyer, O. Vinyals, K. Ayoub, J. Stanway, L. Bennett, D. Hassabis, K. Kavukcuoglu, and G. Irving. Scaling language models: Methods, analysis & insights from training Gopher. arXiv 2112.11446 , 2021.
Rae et al. (2020) J. W. Rae, A. Potapenko, S. M. Jayakumar, T. P. Lillicrap, K. Choromanski, V. Likhosherstov, D. Dohan, X. Song, A. Gane, T. Sarlos, et al. Compressive transformers for long-range sequence modelling. Advances in Neural Information Processing Systems , 33:6154–6158, 2020.
Raffel et al. (2020a) C. Raffel, N. Shazeer, A. Roberts, K. Lee, S. Narang, M. Matena, Y. Zhou, W. Li, and P. J. Liu. Exploring the limits of transfer learning with a unified text-to-text transformer. Journal of Machine Learning Research , 21(140):1–67, 2020a. URL http://jmlr.org/papers/v21/20-074.html .
Raffel et al. (2020b) C. Raffel, N. Shazeer, A. Roberts, K. Lee, S. Narang, M. Matena, Y. Zhou, W. Li, and P. J. Liu. Exploring the limits of transfer learning with a unified text-to-text transformer. Journal of Machine Learning Research , 21(140):1–67, 2020b.
Rajbhandari et al. (2020) S. Rajbhandari, J. Rasley, O. Ruwase, and Y. He. Zero: Memory optimizations toward training trillion parameter models. In SC20: International Conference for High Performance Computing, Networking, Storage and Analysis , pages 1–16. IEEE, 2020.
Robbins and Monro (1951) H. Robbins and S. Monro. A Stochastic Approximation Method. The Annals of Mathematical Statistics , 22(3):400–407, Sept. 1951.
Rudinger et al. (2018) R. Rudinger, J. Naradowsky, B. Leonard, and B. Van Durme. Gender bias in coreference resolution. In Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies , New Orleans, Louisiana, June 2018. Association for Computational Linguistics.
Sakaguchi et al. (2020) K. Sakaguchi, R. Le Bras, C. Bhagavatula, and Y. Choi. Winogrande: An adversarial winograd schema challenge at scale. In Proceedings of the AAAI Conference on Artificial Intelligence , volume 34, pages 8732–8740, 2020.
Sap et al. (2019) M. Sap, H. Rashkin, D. Chen, R. LeBras, and Y. Choi. SocialIQA: Commonsense reasoning about social interactions. Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing , 2019.
Shallue et al. (2018) C. J. Shallue, J. Lee, J. Antognini, J. Sohl-Dickstein, R. Frostig, and G. E. Dahl. Measuring the effects of data parallelism on neural network training. arXiv preprint arXiv:1811.03600 , 2018.
Siegel and Xu (2020) J. W. Siegel and J. Xu. Approximation rates for neural networks with general activation functions. Neural Networks , 128:313–321, Aug. 2020. URL https://www.sciencedirect.com/science/article/pii/S0893608020301891 .
Smith et al. (2022) S. Smith, M. Patwary, B. Norick, P. LeGresley, S. Rajbhandari, J. Casper, Z. Liu, S. Prabhumoye, G. Zerveas, V. Korthikanti, E. Zhang, R. Child, R. Y. Aminabadi, J. Bernauer, X. Song, M. Shoeybi, Y. He, M. Houston, S. Tiwary, and B. Catanzaro. Using Deepspeed and Megatron to Train Megatron-turing NLG 530b, A Large-Scale Generative Language Model. arXiv preprint arXiv:2201.11990 , 2022.
Steinhardt (2021) J. Steinhardt. Updates and lessons from AI forecasting, 2021. URL https://bounded-regret.ghost.io/ai-forecasting/ .
Tay et al. (2021) Y. Tay, M. Dehghani, J. Rao, W. Fedus, S. Abnar, H. W. Chung, S. Narang, D. Yogatama, A. Vaswani, and D. Metzler. Scale efficiently: Insights from pre-training and fine-tuning transformers, 2021.
Thoppilan et al. (2022) R. Thoppilan, D. D. Freitas, J. Hall, N. Shazeer, A. Kulshreshtha, H.-T. Cheng, A. Jin, T. Bos, L. Baker, Y. Du, Y. Li, H. Lee, H. S. Zheng, A. Ghafouri, M. Menegali, Y. Huang, M. Krikun, D. Lepikhin, J. Qin, D. Chen, Y. Xu, Z. Chen, A. Roberts, M. Bosma, Y. Zhou, C.-C. Chang, I. Krivokon, W. Rusch, M. Pickett, K. Meier-Hellstern, M. R. Morris, T. Doshi, R. D. Santos, T. Duke, J. Soraker, B. Zevenbergen, V. Prabhakaran, M. Diaz, B. Hutchinson, K. Olson, A. Molina, E. Hoffman-John, J. Lee, L. Aroyo, R. Rajakumar, A. Butryna, M. Lamm, V. Kuzmina, J. Fenton, A. Cohen, R. Bernstein, R. Kurzweil, B. Aguera-Arcas, C. Cui, M. Croak, E. Chi, and Q. Le. LaMDA: Language models for dialog applications, 2022.
Vaswani et al. (2017) A. Vaswani, N. Shazeer, N. Parmar, J. Uszkoreit, L. Jones, A. N. Gomez, Ł. Kaiser, and I. Polosukhin. Attention is all you need. In Advances in neural information processing systems , pages 5998–6008, 2017.
Weidinger et al. (2021) L. Weidinger, J. Mellor, M. Rauh, C. Griffin, J. Uesato, P.-S. Huang, M. Cheng, M. Glaese, B. Balle, A. Kasirzadeh, Z. Kenton, S. Brown, W. Hawkins, T. Stepleton, C. Biles, A. Birhane, J. Haas, L. Rimell, L. A. Hendricks, W. Isaac, S. Legassick, G. Irving, and I. Gabriel. Ethical and social risks of harm from language models. arXiv submission , 2021.
Welbl et al. (2021) J. Welbl, A. Glaese, J. Uesato, S. Dathathri, J. Mellor, L. A. Hendricks, K. Anderson, P. Kohli, B. Coppin, and P.-S. Huang. Challenges in detoxifying language models. In Findings of the Association for Computational Linguistics: EMNLP 2021 , pages 2447–2469, Punta Cana, Dominican Republic, Nov. 2021. Association for Computational Linguistics. URL https://aclanthology.org/2021.findings-emnlp.210 .
Xu et al. (2021) A. Xu, E. Pathak, E. Wallace, S. Gururangan, M. Sap, and D. Klein. Detoxifying language models risks marginalizing minority voices. In Proceedings of the 2021 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies , pages 2390–2397, Online, June 2021. Association for Computational Linguistics. 10.18653/v1/2021.naacl-main.190 . URL https://aclanthology.org/2021.naacl-main.190 .
Yang et al. (2021) G. Yang, E. J. Hu, I. Babuschkin, S. Sidor, X. Liu, D. Farhi, N. Ryder, J. Pachocki, W. Chen, and J. Gao. Tuning large neural networks via zero-shot hyperparameter transfer. In A. Beygelzimer, Y. Dauphin, P. Liang, and J. W. Vaughan, editors, Advances in Neural Information Processing Systems , 2021. URL https://openreview.net/forum?id=Bx6qKuBM2AD .
Zellers et al. (2019) R. Zellers, A. Holtzman, Y. Bisk, A. Farhadi, and Y. Choi. HellaSwag: Can a machine really finish your sentence? In Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics , 2019.
Zhang et al. (2019) G. Zhang, L. Li, Z. Nado, J. Martens, S. Sachdeva, G. Dahl, C. Shallue, and R. B. Grosse. Which algorithmic choices matter at which batch sizes? insights from a noisy quadratic model. In H. Wallach, H. Larochelle, A. Beygelzimer, F. d'Alché-Buc, E. Fox, and R. Garnett, editors, Advances in Neural Information Processing Systems , volume 32. Curran Associates, Inc., 2019. URL https://proceedings.neurips.cc/paper/2019/file/e0eacd983971634327ae1819ea8b6214-Paper.pdf .
Zoph et al. (2022) B. Zoph, I. Bello, S. Kumar, N. Du, Y. Huang, J. Dean, N. Shazeer, and W. Fedus. Designing effective sparse expert models, 2022.
Appendix
附录
Appendix A Training dataset
附录 A 训练数据集
In Table A1 we show the training dataset makeup used for Chinchilla and all scaling runs. Note that both the MassiveWeb and Wikipedia subsets are both used for more than one epoch.
表 A1 展示用于 Chinchilla 与全部缩放运行的训练数据构成。注意 MassiveWeb 与 Wikipedia 子集都被使用超过一个 epoch。
| Disk Size | Documents | Sampling proportion | Epochs in 1.4T tokens | |
|---|---|---|---|---|
| MassiveWeb | 1.9 TB | 604M | 45% (48%) | 1.24 |
| Books | 2.1 TB | 4M | 30% (27%) | 0.75 |
| C4 | 0.75 TB | 361M | 10% (10%) | 0.77 |
| News | 2.7 TB | 1.1B | 10% (10%) | 0.21 |
| GitHub | 3.1 TB | 142M | 4% (3%) | 0.13 |
| Wikipedia | 0.001 TB | 6M | 1% (2%) | 3.40 |
Table A1: MassiveText data makeup. For each subset of MassiveText, we list its total disk size, the number of documents and the sampling proportion used during training—we use a slightly different distribution than in Rae et al. 2021 (shown in parenthesis). In the rightmost column show the number of epochs that are used in 1.4 trillion tokens.
| 磁盘大小 | 文档数 | 采样比例 | 1.4T token 中的 epoch 数 | |
|---|---|---|---|---|
| MassiveWeb | 1.9 TB | 604M | 45% (48%) | 1.24 |
| Books | 2.1 TB | 4M | 30% (27%) | 0.75 |
| C4 | 0.75 TB | 361M | 10% (10%) | 0.77 |
| News | 2.7 TB | 1.1B | 10% (10%) | 0.21 |
| GitHub | 3.1 TB | 142M | 4% (3%) | 0.13 |
| Wikipedia | 0.001 TB | 6M | 1% (2%) | 3.40 |
表 A1:MassiveText 数据构成。对 MassiveText 的每个子集,列出总磁盘大小、文档数与训练时采样比例——我们使用与 Rae et al. 2021 略有不同的分布(括号内)。最右列给出在 1.4 万亿 token 中使用的 epoch 数。
Appendix B Optimal cosine cycle length
附录 B 最优余弦周期长度
One key assumption is made on the cosine cycle length and the corresponding learning rate drop (we use a 10 learning rate decay in line with Rae et al. 2021).[^9] We find that setting the cosine cycle length too much longer than the target number of training steps results in sub-optimally trained models, as shown in Figure A1. As a result, we assume that an optimally trained model will have the cosine cycle length correctly calibrated to the maximum number of steps, given the FLOP budget; we follow this rule in our main analysis.
一个关键假设涉及余弦周期长度与相应的学习率下降(我们按 Rae et al. 2021 使用 学习率衰减)。[^9]我们发现,若余弦周期长度远长于目标训练步数,会导致模型训练次优,见图 A1。因此我们假定:算力最优训练的模型会把余弦周期长度正确校准到给定 FLOP 预算下的最大步数;主分析遵循这一规则。
Figure A1: Grid over cosine cycle length. We show 6 curves with the cosine cycle length set to 1, 1.1, 1.25, 1.5, 2, and 5 longer than the target number of training steps. When the cosine cycle length is too long, and the learning rate does not drop appropriately, then performance is impaired. We find that overestimating the number of training steps beyond 25% leads to clear drops in performance. We show results where we have set the number of training steps to two different values (top and bottom).
图 A1:余弦周期长度网格。展示 6 条曲线,余弦周期长度分别设为目标训练步数的 1、1.1、1.25、1.5、2 与 5。当余弦周期过长、学习率未适当下降时,性能受损。我们发现对训练步数的高估超过 25% 会导致明显掉点。上下两行对应将训练步数设为两个不同取值的结果。
Appendix C Consistency of scaling results across datasets
附录 C 缩放结果跨数据集的一致性
Figure A2: C4 and GitHub IsoFLOP curves. Using the C4 dataset (Raffel et al. 2020b) and a GitHub dataset (Rae et al. 2021), we generate 4 IsoFLOP profiles and show the parameter and token count scaling, as in Figure 3. Scaling coefficients are shown in Table A2.
图 A2:C4 与 GitHub 的 IsoFLOP 曲线。使用 C4 数据集(Raffel et al. 2020b)与 GitHub 数据集(Rae et al. 2021),我们生成 4 条 IsoFLOP 曲线,并展示参数量与 token 数缩放,如图 3。缩放系数见表 A2。
We show scaling results from an IsoFLOP (Approach 2) analysis after training on two different datasets: C4 (Raffel et al. 2020b) and GitHub code (we show results with data from Rae et al. 2021), results are shown in Table A2. For both set of experiments using subsets of MassiveText, we use the same tokenizer as the MassiveText experiments.
我们展示在两个不同数据集上训练后的 IsoFLOP(方法 2)缩放结果:C4(Raffel et al. 2020b)与 GitHub 代码(数据来自 Rae et al. 2021),结果见表 A2。两组使用 MassiveText 子集的实验都采用与 MassiveText 实验相同的分词器。
We find that the scaling behaviour on these datasets is very similar to what we found on MassiveText, as shown in Figure A2 and Table A2. This suggests that our results are independent of the dataset as long as one does not train for more than one epoch.
我们发现这些数据集上的缩放行为与 MassiveText 上非常相似,见图 A2 与表 A2。这提示:只要训练不超过一个 epoch,我们的结果与数据集无关。
| Approach | Coef. where | Coef. where |
|---|---|---|
| C4 | 0.50 | 0.50 |
| GitHub | 0.53 | 0.47 |
| Kaplan et al. 2020 | 0.73 | 0.27 |
Table A2: Estimated parameter and data scaling with increased training compute on two alternate datasets. The listed values are the exponents, and , on the relationship and . Using IsoFLOP profiles, we estimate the scaling on two different datasets.
| 方法 | 系数 () | 系数 () |
|---|---|---|
| C4 | 0.50 | 0.50 |
| GitHub | 0.53 | 0.47 |
| Kaplan et al. 2020 | 0.73 | 0.27 |
表 A2:在另外两个数据集上,随训练算力增加的参数与数据缩放估计。所列值为关系 与 的指数。我们用 IsoFLOP 曲线在两个不同数据集上估计缩放。
Appendix D Details on the scaling analyses
附录 D 缩放分析细节
D.1 Approach 1: Fixing model sizes and varying training sequences
D.1 方法 1:固定模型规模并改变训练序列数
We use a maximum learning rate of for the smallest models and for the largest models. In all cases, the learning rate drops by a factor of during training, using a cosine schedule. We make the assumption that the cosine cycle length should be approximately matched to the number of training steps. We find that when the cosine cycle overshoots the number of training steps by more than 25%, performance is noticeably degraded—see Figure A1.[^10] We use Gaussian smoothing with a window length of 10 steps to smooth the training curve.
最小模型最大学习率为 ,最大模型为 。所有情形下,训练中学习率按余弦日程下降 。我们假定余弦周期长度应大致匹配训练步数。若余弦周期超出训练步数超过 25%,性能明显下降——见图 A1。[^10]我们用窗口长度为 10 步的高斯平滑来平滑训练曲线。
D.2 Approach 3: Parametric fitting of the loss
D.2 方法 3:损失的参数化拟合
In this section, we first show how Equation (2) can be derived. We repeat the equation below for clarity,
本节先说明如何推导式 (2)。为清晰起见重写如下,
based on a decomposition of the expected risk between a function approximation term and an optimisation suboptimality term. We then give details on the optimisation procedure for fitting the parameters.
其基于期望风险在函数逼近项与优化次优项之间的分解。随后给出拟合参数的优化流程细节。
Loss decomposition.
Formally, we consider the task of predicting the next token based on the previous tokens in a sequence , with varying from to —the maximum sequence length. We consider a distribution of tokens in and their past in . A predictor computes the probability of each token given the past sequence. The Bayes classifier, , minimizes the cross-entropy of with the observed tokens , with expectation taken on the whole data distribution. We let be the expected risk
损失分解。
形式上,我们考虑基于序列中先前 token ( 从 到最大序列长度 )预测下一 token 的任务。考虑 中 token 及其过去 的分布 。预测器 计算给定过去序列时各 token 的概率。贝叶斯分类器 最小化 与观测 token 的交叉熵,期望取在整个数据分布上。令 为期望风险
The set of all transformers of size , that we denote , forms a subset of all functions that map sequences to distributions of tokens . Fitting a transformer of size on the expected risk amounts to minimizing such risk on a restricted functional space
规模为 的全部 Transformer 构成集合 ,它是把序列映射到 token 分布 的全部函数的一个子集。在期望风险 上拟合规模 的 Transformer,等价于在受限函数空间上最小化该风险
When we observe a dataset of size , we do not have access to , but instead to the empirical expectation over the empirical distribution . What happens when we are given datapoints that we can only see once, and when we constrain the size of the hypothesis space to be -dimensional ? We are making steps toward minimizing the empirical risk within a finite-dimensional functional space :
当我们观测到大小为 的数据集 时,我们无法访问 ,而只能访问经验分布 上的经验期望 。当我们只有可看一遍的 个数据点、并把假设空间限制为 维时会发生什么?我们是在有限维函数空间 内朝最小化经验风险迈进:
We are never able to obtain as we typically perform a single epoch over the dataset of size . Instead, be obtain , which is the result of applying a certain number of gradient steps based on the datapoints—the number of steps to perform depends on the gradient batch size, for which we use well-tested heuristics.
我们通常无法得到 ,因为对大小为 的数据集通常只做单个 epoch。相反,我们得到 :基于这 个数据点执行一定次数梯度步的结果——步数取决于梯度批大小,我们对此使用经验证的启发式。
Using the Bayes-classifier , the expected-risk minimizer and the “single-epoch empirical-risk minimizer” , we can finally decompose the loss into
利用贝叶斯分类器 、期望风险最小化子 与「单 epoch 经验风险最小化子」,我们最终可将损失 分解为
The loss comprises three terms: the Bayes risk, i.e. the minimal loss achievable for next-token prediction on the full distribution , a.k.a the “entropy of natural text.”; a functional approximation term that depends on the size of the hypothesis space; finally, a stochastic approximation term that captures the suboptimality of minimizing instead of , and of making a single epoch on the provided dataset.
损失包含三项:贝叶斯风险,即在完整分布 上次 token 预测可达到的最小损失,亦即「自然语言的熵」;依赖假设空间大小的函数逼近项;以及随机逼近项,刻画最小化 而非 、且对给定数据集只做单个 epoch 所带来的次优性。
Expected forms of the loss terms.
In the decomposition (9), the second term depends entirely on the number of parameters that defines the size of the functional approximation space. On the set of two-layer neural networks, it is expected to be proportional to (Siegel and Xu 2020). Finally, given that it corresponds to early stopping in stochastic first order methods, the third term should scale as the convergence rate of these methods, which is lower-bounded by (Robbins and Monro 1951) (and may attain the bound). This convergence rate is expected to be dimension free (see e.g. Bubeck 2015, for a review) and depends only on the loss smoothness; hence we assume that the second term only depends on in (2). Empirically, we find after fitting (2) that
损失项的期望形式。
在分解 (9) 中,第二项完全依赖定义函数逼近空间大小的参数量 。在两层神经网络集合上,预期它与 成正比(Siegel and Xu 2020)。最后,由于它对应随机一阶方法中的早停,第三项应按这些方法的收敛速率缩放,其下界为 (Robbins and Monro 1951)(并可能达到该界)。该收敛速率预期与维度无关(综述见 Bubeck 2015),仅依赖损失光滑性;因此我们假定式 (2) 中第二项只依赖 。经验上,拟合 (2) 后我们发现
with , , . We note that the parameter/data coefficients are both lower than ; this is expected for the data-efficiency coefficient (but far from the known lower-bound). Future models and training approaches should endeavor to increase these coefficients.
其中 ,,。我们注意到参数/数据系数都低于 ;对数据效率系数这在预期之中(但远离已知下界)。未来的模型与训练方法应致力于提高这些系数。
Fitting the decomposition to data.
We effectively minimize the following problem
将分解拟合到数据。
我们实际最小化如下问题
where is the log-sum-exp operator. We then set .
其中 为 log-sum-exp 算子。随后令 。
We use the LBFGS algorithm to find local minima of the objective above, started on a grid of initialisation given by: , , , , and . We find that the optimal initialisation is not on the boundary of our initialisation sweep.
我们用 LBFGS 算法寻找上述目标的局部极小,并在如下初始化网格上启动:,,,,。我们发现最优初始化不在初始化扫描的边界上。
We use for the Huber loss. We find that using larger values of pushes the model to overfit the small compute regime and poorly predict held-out data from larger runs. We find that using a smaller than does not impact the resulting predictions.
Huber 损失取 。我们发现更大的 会促使模型过拟合小算力区间,对更大运行的留出数据预测很差。小于 的 不影响所得预测。
D.3 Predicted compute optimal frontier for all three methods
D.3 三种方法预测的算力最优前沿
For Approaches 2 and 3, we show the estimated model size and number of training tokens for a variety of compute budgets in Table A3. We plot the predicted number of tokens and parameters for a variety of FLOP budgets for the three methods in Figure A3.
对方法 2 与 3,表 A3 给出多种算力预算下估计的模型规模与训练 token 数。图 A3 绘制三种方法在多种 FLOP 预算下预测的 token 数与参数量。
| Approach 2 | Approach 3 | |||
|---|---|---|---|---|
| Parameters | FLOPs | Tokens | FLOPs | Tokens |
| 400 Million | 1.84e+19 | 7.7 Billion | 2.21e+19 | 9.2 Billion |
| 1 Billion | 1.20e+20 | 20.0 Billion | 1.62e+20 | 27.1 Billion |
| 10 Billion | 1.32e+22 | 219.5 Billion | 2.46e+22 | 410.1 Billion |
| 67 Billion | 6.88e+23 | 1.7 Trillion | 1.71e+24 | 4.1 Trillion |
| 175 Billion | 4.54e+24 | 4.3 Trillion | 1.26e+24 | 12.0 Trillion |
| 280 Billion | 1.18e+25 | 7.1 Trillion | 3.52e+25 | 20.1 Trillion |
| 520 Billion | 4.19e+25 | 13.4 Trillion | 1.36e+26 | 43.5 Trillion |
| 1 Trillion | 1.59e+26 | 26.5 Trillion | 5.65e+26 | 94.1 Trillion |
| 10 Trillion | 1.75e+28 | 292.0 Trillion | 8.55e+28 | 1425.5 Trillion |
Table A3: Estimated optimal training FLOPs and training tokens for various model sizes. Analogous to Table 3, we show the model size/token count projections from Approaches 2 and 3 for various compute budgets.
| 方法 2 | 方法 3 | |||
|---|---|---|---|---|
| 参数量 | FLOPs | Token | FLOPs | Token |
| 4 亿 | 1.84e+19 | 77 亿 | 2.21e+19 | 92 亿 |
| 10 亿 | 1.20e+20 | 200 亿 | 1.62e+20 | 271 亿 |
| 100 亿 | 1.32e+22 | 2195 亿 | 2.46e+22 | 4101 亿 |
| 670 亿 | 6.88e+23 | 1.7 万亿 | 1.71e+24 | 4.1 万亿 |
| 1750 亿 | 4.54e+24 | 4.3 万亿 | 1.26e+24 | 12.0 万亿 |
| 2800 亿 | 1.18e+25 | 7.1 万亿 | 3.52e+25 | 20.1 万亿 |
| 5200 亿 | 4.19e+25 | 13.4 万亿 | 1.36e+26 | 43.5 万亿 |
| 1 万亿 | 1.59e+26 | 26.5 万亿 | 5.65e+26 | 94.1 万亿 |
| 10 万亿 | 1.75e+28 | 292.0 万亿 | 8.55e+28 | 1425.5 万亿 |
表 A3:多种模型规模下估计的最优训练 FLOPs 与训练 token。与表 3 类似,展示方法 2 与 3 在多种算力预算下的模型规模/token 数外推。
Figure A3: Optimal number of tokens and parameters for a training FLOP budget. For a fixed FLOP budget, we show the optimal number of tokens and parameters as predicted by Approaches 1, 2, and 3. For an alternate representation, see Figure 1.
图 A3:给定训练 FLOP 预算下的最优 token 数与参数量。对固定 FLOP 预算,展示方法 1、2、3 预测的最优 token 数与参数量。另一表示见图 1。
D.4 Small-scale comparison to Kaplan et al. (2020)
D.4 与 Kaplan et al.(2020)的小规模比较
For FLOPs, we perform a head-to-head comparison of a model predicted by Approach 1 and that predicted by Kaplan et al. 2020. For both models, we use a batch size of 0.5M tokens and a maximum learning rate of that decays by . From Kaplan et al. 2020, we find that the optimal model size should be 4.68 billion parameters. From our approach 1, we estimate a 2.86 billion parameter model should be optimal. We train a 4.74 billion parameter and a 2.80 billion parameter transformer to test this hypothesis, using the same depth-to-width ratio to avoid as many confounding factors as possible. We find that our predicted model outperforms the model predicted by Kaplan et al. 2020 as shown in Figure A4.
对 FLOPs,我们将方法 1 预测的模型与 Kaplan et al. 2020 预测的模型做头对头比较。两个模型批大小均为 0.5M token,最大学习率 并衰减 。按 Kaplan et al. 2020,最优模型规模应为 46.8 亿参数;按我们的方法 1,估计 28.6 亿参数模型最优。我们训练 47.4 亿与 28.0 亿参数的 Transformer 检验该假说,并使用相同深宽比以尽量减少混杂因素。如图 A4 所示,我们预测的模型优于 Kaplan et al. 2020 预测的模型。
Figure A4: Comparison to Kaplan et al. 2020 at FLOPs. We train 2.80 and 4.74 billion parameter transformers predicted as optimal for FLOPs by Approach 1 and by Kaplan et al. 2020. We find that our prediction results in a more performant model at the end of training.
图 A4:在 FLOPs 上与 Kaplan et al. 2020 比较。我们训练方法 1 与 Kaplan et al. 2020 分别预测为 FLOPs 最优的 28.0 亿与 47.4 亿参数 Transformer。我们发现我们的预测在训练结束时得到更强的模型。
Appendix E Curvature of the FLOP-loss frontier
附录 E FLOP–损失前沿的弯曲
We observe that as models increase there is a curvature in the FLOP-minimal loss frontier. This means that projections from very small models lead to different predictions than those from larger models. In Figure A5 we show linear fits using the first, middle, and final third of frontier-points. In this work, we do not take this in to account and we leave this as interesting future work as it suggests that even smaller models may be optimal for large FLOP budgets.
我们观察到,随模型增大,FLOP–最小损失前沿出现弯曲。这意味着从很小模型做外推,会与从更大模型得到的预测不同。图 A5 展示用前沿点的前、中、后三分之一分别做线性拟合。本文未计入该效应,留作有趣的未来工作——它提示:对大 FLOP 预算,甚至更小的模型也可能是最优的。
Figure A5: Training curve envelopes. We fit to the first third (orange), the middle third (green), and the last third (blue) of all points along the loss frontier. We plot only a subset of the points.
图 A5:训练曲线包络。我们分别拟合损失前沿上全部点的前三分之一(橙)、中三分之一(绿)与后三分之一(蓝)。图中只画出点的一个子集。
Appendix F FLOPs computation
附录 F FLOPs 计算
We include all training FLOPs, including those contributed to by the embedding matrices, in our analysis. Note that we also count embeddings matrices in the total parameter count. For large models the FLOP and parameter contribution of embedding matrices is small. We use a factor of 2 to describe the multiply accumulate cost. For the forward pass, we consider contributions from:
我们的分析计入全部训练 FLOPs,包括嵌入矩阵的贡献。注意总参数量也计入嵌入矩阵。对大模型,嵌入矩阵的 FLOP 与参数贡献很小。我们用因子 2 描述乘加代价。对前向传播,我们考虑如下贡献:
- • Embeddings –
- • 嵌入 –
- • Attention (Single Layer) – Key, query and value projections: – Key @ Query logits: – Softmax: – Softmax @ query reductions: – Final Linear:
- • 注意力(单层)– Key、query 与 value 投影: – Key @ Query logits: – Softmax: – Softmax @ query 归约: – 最终线性层:
- • Dense Block (Single Layer) –
- • 稠密块(单层)–
- • Final Logits –
- • 最终 Logits –
- • Total forward pass FLOPs: + logits
- • 前向总 FLOPs: + logits
As in Kaplan et al. 2020 we assume that the backward pass has twice the FLOPs of the forward pass. We show a comparison between our calculation and that using the common approximation (Kaplan et al. 2020) where is FLOPs, is the number of training tokens, and is the number of parameters in Table A4. We find the differences in FLOP calculation to be very small and they do not impact our analysis.
与 Kaplan et al. 2020 一样,我们假定反向传播的 FLOPs 为前向的两倍。表 A4 比较我们的计算与常用近似 (Kaplan et al. 2020),其中 为 FLOPs, 为训练 token 数, 为参数量。我们发现 FLOP 计算差异很小,不影响分析。
| Parameters | num_layers | d_model | ffw_size | num_heads | k/q size | FLOP Ratio (Ours/) |
|---|---|---|---|---|---|---|
| 73M | 10 | 640 | 2560 | 10 | 64 | 1.03 |
| 305M | 20 | 1024 | 4096 | 16 | 64 | 1.10 |
| 552M | 24 | 1280 | 5120 | 10 | 128 | 1.08 |
| 1.1B | 26 | 1792 | 7168 | 14 | 128 | 1.04 |
| 1.6B | 28 | 2048 | 8192 | 16 | 128 | 1.03 |
| 6.8B | 40 | 3584 | 14336 | 28 | 128 | 0.99 |
Table A4: FLOP comparison. For a variety of different model sizes, we show the ratio of the FLOPs that we compute per sequence to that using the approximation.
| 参数量 | num_layers | d_model | ffw_size | num_heads | k/q size | FLOP 比(本文/) |
|---|---|---|---|---|---|---|
| 73M | 10 | 640 | 2560 | 10 | 64 | 1.03 |
| 305M | 20 | 1024 | 4096 | 16 | 64 | 1.10 |
| 552M | 24 | 1280 | 5120 | 10 | 128 | 1.08 |
| 1.1B | 26 | 1792 | 7168 | 14 | 128 | 1.04 |
| 1.6B | 28 | 2048 | 8192 | 16 | 128 | 1.03 |
| 6.8B | 40 | 3584 | 14336 | 28 | 128 | 0.99 |
表 A4:FLOP 比较。对多种模型规模,展示我们每条序列计算的 FLOPs 与 近似之比。
Compared to the results presented in Rae et al. 2021, we use a slightly more accurate calculation giving a slightly different value ( compared to ).
相对 Rae et al. 2021 给出的结果,我们使用略更精确的计算,得到略有不同的数值( 对比 )。
Appendix G Other differences between Chinchilla and Gopher
附录 G Chinchilla 与 Gopher 的其他差异
Beyond differences in model size and number of training tokens, there are some additional minor differences between Chinchilla and Gopher. Specifically, Gopher was trained with Adam (Kingma and Ba 2014) whereas Chinchilla was trained with AdamW (Loshchilov and Hutter 2019). Furthermore, as discussed in Lessons Learned in Rae et al. 2021, Chinchilla stored a higher-precision copy of the weights in the sharded optimiser state.
除模型规模与训练 token 数差异外,Chinchilla 与 Gopher 还有若干次要差异。具体地,Gopher 用 Adam(Kingma and Ba 2014)训练,而 Chinchilla 用 AdamW(Loshchilov and Hutter 2019)。此外,如 Rae et al. 2021 经验教训所论,Chinchilla 在分片优化器状态中保存更高精度的权重副本。
We show comparisons of models trained with Adam and AdamW in Figure A6 and Figure A7. We find that, independent of the learning rate schedule, AdamW trained models outperform models trained with Adam.
图 A6 与图 A7 比较用 Adam 与 AdamW 训练的模型。我们发现:独立于学习率日程,AdamW 训练的模型优于 Adam。
Figure A6: Comparison of other differences. Using an 680 million parameter model, we show a comparison between the setup used to train Gopher and Chinchilla— the change in optimiser and using a higher precision copy of the weights in the optimiser state. The setup used for Chinchilla (orange) clearly outperforms the setup used to train Gopher (green).
图 A6:其他差异的比较。用 6.8 亿参数模型,比较训练 Gopher 与 Chinchilla 所用设定——优化器更换,以及在优化器状态中使用更高精度权重副本。Chinchilla 所用设定(橙)明显优于训练 Gopher 的设定(绿)。
Figure A7: Adam vs AdamW. For a 417M (blue) and 1.4B model (green), we find that training with AdamW improves performance over training with Adam.
图 A7:Adam 对比 AdamW。对 417M(蓝)与 1.4B(绿)模型,我们发现用 AdamW 训练优于 Adam。
In Figure A6 we show a comparison of an 680 million parameter model trained with and without the higher precision copy of the weights and with Adam/AdamW for comparison.
图 A6 比较 6.8 亿参数模型在有/无更高精度权重副本、以及 Adam/AdamW 下的训练结果。
Appendix H Results
附录 H 结果
H.1 The Pile
In Table A5 we show the bits-per-byte (bpb) on The Pile (Gao et al. 2020) of Chinchilla, Gopher, and Jurassic-1. Chinchilla outperforms Gopher on all subsets. Jurassic-1 outperforms Chinchilla on 2 subsets— dm_mathematics and ubuntu_irc.
表 A5 给出 Chinchilla、Gopher 与 Jurassic-1 在 The Pile(Gao et al. 2020)上的每字节比特数(bpb)。Chinchilla 在所有子集上优于 Gopher。Jurassic-1 在两个子集上优于 Chinchilla——dm_mathematics 与 ubuntu_irc。
| Subset | Chinchilla (70B) | Gopher (280B) | Jurassic-1 (170B) |
|---|---|---|---|
| pile_cc | 0.667 | 0.691 | 0.669 |
| pubmed_abstracts | 0.559 | 0.578 | 0.587 |
| stackexchange | 0.614 | 0.641 | 0.655 |
| github | 0.337 | 0.377 | 0.358 |
| openwebtext2 | 0.647 | 0.677 | - |
| arxiv | 0.627 | 0.662 | 0.680 |
| uspto_backgrounds | 0.526 | 0.546 | 0.537 |
| freelaw | 0.476 | 0.513 | 0.514 |
| pubmed_central | 0.504 | 0.525 | 0.579 |
| dm_mathematics | 1.111 | 1.142 | 1.037 |
| hackernews | 0.859 | 0.890 | 0.869 |
| nih_exporter | 0.572 | 0.590 | 0.590 |
| opensubtitles | 0.871 | 0.900 | 0.879 |
| europarl | 0.833 | 0.938 | - |
| books3 | 0.675 | 0.712 | 0.835 |
| philpapers | 0.656 | 0.695 | 0.742 |
| gutenberg_pg_19 | 0.548 | 0.656 | 0.890 |
| bookcorpus2 | 0.714 | 0.741 | - |
| ubuntu_irc | 1.026 | 1.090 | 0.857 |
Table A5: Bits-per-Byte on The Pile. We show the bpb on The Pile for Chinchilla compared to Gopher and Jurassic-1.
| 子集 | Chinchilla (70B) | Gopher (280B) | Jurassic-1 (170B) |
|---|---|---|---|
| pile_cc | 0.667 | 0.691 | 0.669 |
| pubmed_abstracts | 0.559 | 0.578 | 0.587 |
| stackexchange | 0.614 | 0.641 | 0.655 |
| github | 0.337 | 0.377 | 0.358 |
| openwebtext2 | 0.647 | 0.677 | - |
| arxiv | 0.627 | 0.662 | 0.680 |
| uspto_backgrounds | 0.526 | 0.546 | 0.537 |
| freelaw | 0.476 | 0.513 | 0.514 |
| pubmed_central | 0.504 | 0.525 | 0.579 |
| dm_mathematics | 1.111 | 1.142 | 1.037 |
| hackernews | 0.859 | 0.890 | 0.869 |
| nih_exporter | 0.572 | 0.590 | 0.590 |
| opensubtitles | 0.871 | 0.900 | 0.879 |
| europarl | 0.833 | 0.938 | - |
| books3 | 0.675 | 0.712 | 0.835 |
| philpapers | 0.656 | 0.695 | 0.742 |
| gutenberg_pg_19 | 0.548 | 0.656 | 0.890 |
| bookcorpus2 | 0.714 | 0.741 | - |
| ubuntu_irc | 1.026 | 1.090 | 0.857 |
表 A5:The Pile 上的每字节比特数。展示 Chinchilla 相对 Gopher 与 Jurassic-1 在 The Pile 上的 bpb。
H.2 MMLU
In Table A6 we show the performance of Chinchilla and Gopher on each subset of MMLU.
表 A6 给出 Chinchilla 与 Gopher 在 MMLU 各子集上的表现。
| Task | Chinchilla | Gopher | Task | Chinchilla | Gopher |
|---|---|---|---|---|---|
| abstract_algebra | 31.0 | 25.0 | anatomy | 70.4 | 56.3 |
| astronomy | 73.0 | 65.8 | business_ethics | 72.0 | 70.0 |
| clinical_knowledge | 75.1 | 67.2 | college_biology | 79.9 | 70.8 |
| college_chemistry | 51.0 | 45.0 | college_computer_science | 51.0 | 49.0 |
| college_mathematics | 32.0 | 37.0 | college_medicine | 66.5 | 60.1 |
| college_physics | 46.1 | 34.3 | computer_security | 76.0 | 65.0 |
| conceptual_physics | 67.2 | 49.4 | econometrics | 38.6 | 43.0 |
| electrical_engineering | 62.1 | 60.0 | elementary_mathematics | 41.5 | 33.6 |
| formal_logic | 33.3 | 35.7 | global_facts | 39.0 | 38.0 |
| high_school_biology | 80.3 | 71.3 | high_school_chemistry | 58.1 | 47.8 |
| high_school_computer_science | 58.0 | 54.0 | high_school_european_history | 78.8 | 72.1 |
| high_school_geography | 86.4 | 76.8 | high_school_gov_and_politics | 91.2 | 83.9 |
| high_school_macroeconomics | 70.5 | 65.1 | high_school_mathematics | 31.9 | 23.7 |
| high_school_microeconomics | 77.7 | 66.4 | high_school_physics | 36.4 | 33.8 |
| high_school_psychology | 86.6 | 81.8 | high_school_statistics | 58.8 | 50.0 |
| high_school_us_history | 83.3 | 78.9 | high_school_world_history | 85.2 | 75.1 |
| human_aging | 77.6 | 66.4 | human_sexuality | 86.3 | 67.2 |
| international_law | 90.9 | 77.7 | jurisprudence | 79.6 | 71.3 |
| logical_fallacies | 80.4 | 72.4 | machine_learning | 41.1 | 41.1 |
| management | 82.5 | 77.7 | marketing | 89.7 | 83.3 |
| medical_genetics | 69.0 | 69.0 | miscellaneous | 84.5 | 75.7 |
| moral_disputes | 77.5 | 66.8 | moral_scenarios | 36.5 | 40.2 |
| nutrition | 77.1 | 69.9 | philosophy | 79.4 | 68.8 |
| prehistory | 81.2 | 67.6 | professional_accounting | 52.1 | 44.3 |
| professional_law | 56.5 | 44.5 | professional_medicine | 75.4 | 64.0 |
| professional_psychology | 75.7 | 68.1 | public_relations | 73.6 | 71.8 |
| security_studies | 75.9 | 64.9 | sociology | 91.0 | 84.1 |
| us_foreign_policy | 92.0 | 81.0 | virology | 53.6 | 47.0 |
| world_religions | 87.7 | 84.2 |
Table A6: Chinchilla MMLU results. For each subset of MMLU (Hendrycks et al. 2020), we show Chinchilla’s accuracy compared to Gopher.
| 任务 | Chinchilla | Gopher | 任务 | Chinchilla | Gopher |
|---|---|---|---|---|---|
| abstract_algebra | 31.0 | 25.0 | anatomy | 70.4 | 56.3 |
| astronomy | 73.0 | 65.8 | business_ethics | 72.0 | 70.0 |
| clinical_knowledge | 75.1 | 67.2 | college_biology | 79.9 | 70.8 |
| college_chemistry | 51.0 | 45.0 | college_computer_science | 51.0 | 49.0 |
| college_mathematics | 32.0 | 37.0 | college_medicine | 66.5 | 60.1 |
| college_physics | 46.1 | 34.3 | computer_security | 76.0 | 65.0 |
| conceptual_physics | 67.2 | 49.4 | econometrics | 38.6 | 43.0 |
| electrical_engineering | 62.1 | 60.0 | elementary_mathematics | 41.5 | 33.6 |
| formal_logic | 33.3 | 35.7 | global_facts | 39.0 | 38.0 |
| high_school_biology | 80.3 | 71.3 | high_school_chemistry | 58.1 | 47.8 |
| high_school_computer_science | 58.0 | 54.0 | high_school_european_history | 78.8 | 72.1 |
| high_school_geography | 86.4 | 76.8 | high_school_gov_and_politics | 91.2 | 83.9 |
| high_school_macroeconomics | 70.5 | 65.1 | high_school_mathematics | 31.9 | 23.7 |
| high_school_microeconomics | 77.7 | 66.4 | high_school_physics | 36.4 | 33.8 |
| high_school_psychology | 86.6 | 81.8 | high_school_statistics | 58.8 | 50.0 |
| high_school_us_history | 83.3 | 78.9 | high_school_world_history | 85.2 | 75.1 |
| human_aging | 77.6 | 66.4 | human_sexuality | 86.3 | 67.2 |
| international_law | 90.9 | 77.7 | jurisprudence | 79.6 | 71.3 |
| logical_fallacies | 80.4 | 72.4 | machine_learning | 41.1 | 41.1 |
| management | 82.5 | 77.7 | marketing | 89.7 | 83.3 |
| medical_genetics | 69.0 | 69.0 | miscellaneous | 84.5 | 75.7 |
| moral_disputes | 77.5 | 66.8 | moral_scenarios | 36.5 | 40.2 |
| nutrition | 77.1 | 69.9 | philosophy | 79.4 | 68.8 |
| prehistory | 81.2 | 67.6 | professional_accounting | 52.1 | 44.3 |
| professional_law | 56.5 | 44.5 | professional_medicine | 75.4 | 64.0 |
| professional_psychology | 75.7 | 68.1 | public_relations | 73.6 | 71.8 |
| security_studies | 75.9 | 64.9 | sociology | 91.0 | 84.1 |
| us_foreign_policy | 92.0 | 81.0 | virology | 53.6 | 47.0 |
| world_religions | 87.7 | 84.2 |
表 A6:Chinchilla 的 MMLU 结果。对 MMLU(Hendrycks et al. 2020)的每个子集,展示 Chinchilla 相对 Gopher 的准确率。
H.3 Winogender Setup
H.3 Winogender 设定
We follow the same setup as in Rae et al. 2021. To test coreference resolution in Chinchilla, we input a sentence which includes a pronoun reference (e.g., “The librarian helped the child pick out a book because {pronoun} liked to encourage reading.”), then measure the probability of the model completing the sentence “‘{Pronoun}’ refers to the” with different sentence roles (“librarian” and “child” in this example). Each example is annotated with the correct pronoun resolution (the pronoun corresponds to the librarian in this example). Each sentence is tested with a female, male, and gender-neutral pronoun. An unbiased model would correctly predict which word the pronoun refers to regardless of pronoun gender.
我们沿用 Rae et al. 2021 的设定。为测试 Chinchilla 的共指消解,输入包含代词指代的句子(例如 “The librarian helped the child pick out a book because {pronoun} liked to encourage reading.”),再测量模型以不同句子角色(本例中为 “librarian” 与 “child”)完成 “‘{Pronoun}’ refers to the” 的概率。每个样例标注正确的代词消解(本例中代词对应 librarian)。每个句子分别用女性、男性与性别中性代词测试。无偏模型应无论代词性别,都能正确预测代词所指的词。
H.4 BIG-bench
In Table A7 we show Chinchilla and Gopher performance on each subset of BIG-bench that we consider.
表 A7 给出我们所考虑的 BIG-bench 各子集上 Chinchilla 与 Gopher 的表现。
| Task | Chinchilla | Gopher | Task | Chinchilla | Gopher |
|---|---|---|---|---|---|
| hyperbaton | 54.2 | 51.7 | movie_dialog_same_or_diff | 54.5 | 50.7 |
| causal_judgment | 57.4 | 50.8 | winowhy | 62.5 | 56.7 |
| formal_fallacies_syllogisms_neg | 52.1 | 50.7 | movie_recommendation | 75.6 | 50.5 |
| crash_blossom | 47.6 | 63.6 | moral_permissibility | 57.3 | 55.1 |
| discourse_marker_prediction | 13.1 | 11.7 | strategyqa | 68.3 | 61.0 |
| general_knowledge_json | 94.3 | 93.9 | nonsense_words_grammar | 78.0 | 61.4 |
| sports_understanding | 71.0 | 54.9 | metaphor_boolean | 93.1 | 59.3 |
| implicit_relations | 49.4 | 36.4 | navigate | 52.6 | 51.1 |
| penguins_in_a_table | 48.7 | 40.6 | presuppositions_as_nli | 49.9 | 34.0 |
| intent_recognition | 92.8 | 88.7 | temporal_sequences | 32.0 | 19.0 |
| reasoning_about_colored_objects | 59.7 | 49.2 | question_selection | 52.6 | 41.4 |
| logic_grid_puzzle | 44.0 | 35.1 | logical_fallacy_detection | 72.1 | 58.9 |
| timedial | 68.8 | 50.9 | physical_intuition | 79.0 | 59.7 |
| epistemic_reasoning | 60.6 | 56.4 | physics_mc | 65.5 | 50.9 |
| ruin_names | 47.1 | 38.6 | identify_odd_metaphor | 68.8 | 38.6 |
| hindu_knowledge | 91.4 | 80.0 | understanding_fables | 60.3 | 39.6 |
| misconceptions | 65.3 | 61.7 | logical_sequence | 64.1 | 36.4 |
| implicatures | 75.0 | 62.0 | mathematical_induction | 47.3 | 57.6 |
| disambiguation_q | 54.7 | 45.5 | fantasy_reasoning | 69.0 | 64.1 |
| known_unknowns | 65.2 | 63.6 | SNARKS | 58.6 | 48.3 |
| dark_humor_detection | 66.2 | 83.1 | crass_ai | 75.0 | 56.8 |
| analogical_similarity | 38.1 | 17.2 | entailed_polarity | 94.0 | 89.5 |
| sentence_ambiguity | 71.7 | 69.1 | irony_identification | 73.0 | 69.7 |
| riddle_sense | 85.7 | 68.2 | evaluating_info_essentiality | 17.6 | 16.7 |
| date_understanding | 52.3 | 44.1 | phrase_relatedness | 94.0 | 81.8 |
| analytic_entailment | 67.1 | 53.0 | novel_concepts | 65.6 | 59.1 |
| odd_one_out | 70.9 | 32.5 | empirical_judgments | 67.7 | 52.5 |
| logical_args | 56.2 | 59.1 | figure_of_speech_detection | 63.3 | 52.7 |
| alignment_questionnaire | 91.3 | 79.2 | english_proverbs | 82.4 | 57.6 |
| similarities_abstraction | 87.0 | 81.8 | Human_organs_senses_mcc | 85.7 | 84.8 |
| anachronisms | 69.1 | 56.4 | gre_reading_comprehension | 53.1 | 27.3 |
Table A7: Chinchilla BIG-bench results. For each subset of BIG-bench (BIG-bench collaboration 2021), we show Chinchilla and Gopher’s accuracy.
| 任务 | Chinchilla | Gopher | 任务 | Chinchilla | Gopher |
|---|---|---|---|---|---|
| hyperbaton | 54.2 | 51.7 | movie_dialog_same_or_diff | 54.5 | 50.7 |
| causal_judgment | 57.4 | 50.8 | winowhy | 62.5 | 56.7 |
| formal_fallacies_syllogisms_neg | 52.1 | 50.7 | movie_recommendation | 75.6 | 50.5 |
| crash_blossom | 47.6 | 63.6 | moral_permissibility | 57.3 | 55.1 |
| discourse_marker_prediction | 13.1 | 11.7 | strategyqa | 68.3 | 61.0 |
| general_knowledge_json | 94.3 | 93.9 | nonsense_words_grammar | 78.0 | 61.4 |
| sports_understanding | 71.0 | 54.9 | metaphor_boolean | 93.1 | 59.3 |
| implicit_relations | 49.4 | 36.4 | navigate | 52.6 | 51.1 |
| penguins_in_a_table | 48.7 | 40.6 | presuppositions_as_nli | 49.9 | 34.0 |
| intent_recognition | 92.8 | 88.7 | temporal_sequences | 32.0 | 19.0 |
| reasoning_about_colored_objects | 59.7 | 49.2 | question_selection | 52.6 | 41.4 |
| logic_grid_puzzle | 44.0 | 35.1 | logical_fallacy_detection | 72.1 | 58.9 |
| timedial | 68.8 | 50.9 | physical_intuition | 79.0 | 59.7 |
| epistemic_reasoning | 60.6 | 56.4 | physics_mc | 65.5 | 50.9 |
| ruin_names | 47.1 | 38.6 | identify_odd_metaphor | 68.8 | 38.6 |
| hindu_knowledge | 91.4 | 80.0 | understanding_fables | 60.3 | 39.6 |
| misconceptions | 65.3 | 61.7 | logical_sequence | 64.1 | 36.4 |
| implicatures | 75.0 | 62.0 | mathematical_induction | 47.3 | 57.6 |
| disambiguation_q | 54.7 | 45.5 | fantasy_reasoning | 69.0 | 64.1 |
| known_unknowns | 65.2 | 63.6 | SNARKS | 58.6 | 48.3 |
| dark_humor_detection | 66.2 | 83.1 | crass_ai | 75.0 | 56.8 |
| analogical_similarity | 38.1 | 17.2 | entailed_polarity | 94.0 | 89.5 |
| sentence_ambiguity | 71.7 | 69.1 | irony_identification | 73.0 | 69.7 |
| riddle_sense | 85.7 | 68.2 | evaluating_info_essentiality | 17.6 | 16.7 |
| date_understanding | 52.3 | 44.1 | phrase_relatedness | 94.0 | 81.8 |
| analytic_entailment | 67.1 | 53.0 | novel_concepts | 65.6 | 59.1 |
| odd_one_out | 70.9 | 32.5 | empirical_judgments | 67.7 | 52.5 |
| logical_args | 56.2 | 59.1 | figure_of_speech_detection | 63.3 | 52.7 |
| alignment_questionnaire | 91.3 | 79.2 | english_proverbs | 82.4 | 57.6 |
| similarities_abstraction | 87.0 | 81.8 | Human_organs_senses_mcc | 85.7 | 84.8 |
| anachronisms | 69.1 | 56.4 | gre_reading_comprehension | 53.1 | 27.3 |
表 A7:Chinchilla 的 BIG-bench 结果。对所考虑的 BIG-bench(BIG-bench collaboration 2021)每个子集,展示 Chinchilla 与 Gopher 的准确率。
Appendix I Model Card
附录 I 模型卡
We present the Chinchilla model card in Table A8, following the framework presented by Mitchell et al. 2019.
我们按 Mitchell et al. 2019 提出的框架,在表 A8 给出 Chinchilla 模型卡。
| Model Details | |
|---|---|
| Organization Developing the Model | DeepMind |
| Model Date | March 2022 |
| Model Type | Autoregressive Transformer Language Model (Section 4.1 for details) |
| Feedback on the Model | {jordanhoffmann, sborgeaud, amensch,sifre}@deepmind.com |
| Intended Uses | |
| Primary Intended Uses | The primary use is research on language models, including: research on the scaling behaviour of language models along with those listed in Rae et al. 2021. |
| Primary Intended Users | DeepMind researchers. We will not make this model available publicly. |
| Out-of-Scope Uses | Uses of the language model for language generation in harmful or deceitful settings. More generally, the model should not be used for downstream applications without further safety and fairness mitigations. |
| Factors | |
| Card Prompts – Relevant Factor | Relevant factors include which language is used. Our model is trained on English data. Furthermore, in the analysis of models trained on the same corpus in Rae et al. 2021, we found it has unequal performance when modelling some dialects (e.g., African American English). Our model is designed for research. The model should not be used for downstream applications without further analysis on factors in the proposed downstream application. |
| Card Prompts – Evaluation Factors | See the results in Rae et al. 2021 which analyzes models trained on the same text corpus. |
| Metrics | |
| Model Performance Measures | • Perplexity and bits per byte on language modelling datasets • Accuracy on completion tasks, reading comprehension, MMLU, BIG-bench and fact checking. • Exact match accuracy for question answering. • Generation toxicity from Real Toxicity Prompts (RTP) alongside toxicity classification accuracy. • Gender and occupation bias. Test include comparing the probability of generating different gender terms and the Winogender coreference resolution task. We principally focus on Chinchilla’s performance compared to Gopher on text likelihood prediction. |
| Decision thresholds | N/A |
| Approaches to Uncertainty and Variability | Due to the costs of training large language models, we did not train Chinchilla multiple times. However, the breadth of our evaluation on a range of different task types gives a reasonable estimate of the overall performance of the model. Furthermore, the existence of another large model trained on the same dataset (Gopher) provides a clear point of comparison. |
| Evaluation Data | |
| Datasets | • Language modelling on LAMBADA, Wikitext103 (Merity et al. 2017), C4 (Raffel et al. 2020a), PG-19 (Rae et al. 2020) and the Pile (Gao et al. 2020). • Language understanding, real world knowledge, mathematical and logical reasoning on the Massive Multitask Language Understanding (MMLU) benchmark (Hendrycks et al. 2020) and on the “Beyond the Imitation Game Benchmark” (BIG-bench) (BIG-bench collaboration 2021). • Question answering (closed book) on Natural Questions (Kwiatkowski et al. 2019) and TriviaQA (Joshi et al. 2017). • Reading comprehension on RACE (Lai et al. 2017) • Common sense understanding on HellaSwag (Zellers et al. 2019), PIQA (Bisk et al. 2020), Winogrande (Sakaguchi et al. 2020), SIQA (Sap et al. 2019), BoolQ (Clark et al. 2019), and TruthfulQA (Lin et al. 2021). |
| Motivation | We chose evaluations from Rae et al. 2021 to allow us to most directly compare to Gopher. |
| Preprocessing | Input text is tokenized using a SentencePiece tokenizer with a vocabulary of size 32,000. Unlike the tokenizer used for Gopher, the tokenizer used for Chinchilla does not perform NFKC normalization. |
| Training Data | |
| The same dataset is used as in Rae et al. 2021. Differences in sampling are shown in Table A1. | |
| Quantitative Analyses | |
| Unitary Results | Section 4.2gives a detailed description of our analysis. Main take-aways include: • Our model is capable of outputting toxic language as measured by the PerspectiveAPI. This is particularly true when the model is prompted with toxic prompts. • Gender: Our model emulates stereotypes found in our dataset, with occupations such as “dietician” and “receptionist” being more associated with women and “carpenter” and “sheriff” being more associated with men. • Race/religion/country sentiment: Prompting our model to discuss some groups leads to sentences with lower or higher sentiment, likely reflecting text in our dataset. |
| Intersectional Results | We did not investigate intersectional biases. |
| Ethical Considerations | |
| Data | The data is the same as described in Rae et al. 2021. |
| Human Life | The model is not intended to inform decisions about matters central to human life or flourishing. |
| Mitigations | We considered filtering the dataset to remove toxic content but decided against it due to the observation that this can introduce new biases as studied by Welbl et al. 2021. More work is needed on mitigation approaches to toxic content and other types of risks associated with language models, such as those discussed in Weidinger et al. 2021. |
| Risks and Harms | The data is collected from the internet, and thus undoubtedly there is toxic/biased content in our training dataset. Furthermore, it is likely that personal information is also in the dataset that has been used to train our models. We defer to the more detailed discussion in Weidinger et al. 2021. |
| Use Cases | Especially fraught use cases include the generation of factually incorrect information with the intent of distributing it or using the model to generate racist, sexist or otherwise toxic text with harmful intent. Many more use cases that could cause harm exist. Such applications to malicious use are discussed in detail in Weidinger et al. 2021. |
Table A8: Chinchilla model card. We follow the framework presented in Mitchell et al. 2019.
| 模型细节 | |
|---|---|
| 开发模型的组织 | DeepMind |
| 模型日期 | 2022 年 3 月 |
| 模型类型 | 自回归 Transformer 语言模型(细节见第 4.1 节) |
| 模型反馈 | {jordanhoffmann, sborgeaud, amensch,sifre}@deepmind.com |
| 预期用途 | |
| 主要预期用途 | 主要用于语言模型研究,包括:研究语言模型的缩放行为,以及 Rae et al. 2021 所列用途。 |
| 主要预期用户 | DeepMind 研究者。我们不会公开提供该模型。 |
| 超出范围的用途 | 在有害或欺骗性设定中用该语言模型做语言生成。更一般地,未经进一步安全与公平缓解,模型不应被用于下游应用。 |
| 因素 | |
| 卡片提示 – 相关因素 | 相关因素包括所用语言。我们的模型在英语数据上训练。此外,在 Rae et al. 2021 对同一语料训练的模型分析中,我们发现它对某些方言(如非裔美国人英语)的建模表现不均。本模型面向研究。未经对拟议下游应用中因素的进一步分析,不应用于下游应用。 |
| 卡片提示 – 评测因素 | 见 Rae et al. 2021 中对同一文本语料训练模型的分析结果。 |
| 指标 | |
| 模型性能度量 | • 语言建模数据集上的困惑度与每字节比特数 • 补全任务、阅读理解、MMLU、BIG-bench 与事实核查上的准确率 • 问答的精确匹配准确率 • 来自 Real Toxicity Prompts(RTP)的生成毒性,以及毒性分类准确率 • 性别与职业偏见。测试包括比较生成不同性别词的概率,以及 Winogender 共指消解任务。我们主要关注 Chinchilla 相对 Gopher 在文本似然预测上的表现。 |
| 决策阈值 | 不适用 |
| 不确定性与变异性的处理 | 由于训练大规模语言模型成本高,我们未多次训练 Chinchilla。不过,在多种任务类型上的广泛评测给出了模型整体表现的合理估计。此外,在同一数据集上训练的另一大模型(Gopher)提供了清晰的比较点。 |
| 评测数据 | |
| 数据集 | • 在 LAMBADA、Wikitext103(Merity et al. 2017)、C4(Raffel et al. 2020a)、PG-19(Rae et al. 2020)与 the Pile(Gao et al. 2020)上的语言建模。 • 在大规模多任务语言理解(MMLU)基准(Hendrycks et al. 2020)与 “Beyond the Imitation Game Benchmark”(BIG-bench)(BIG-bench collaboration 2021)上的语言理解、现实世界知识、数学与逻辑推理。 • 在 Natural Questions(Kwiatkowski et al. 2019)与 TriviaQA(Joshi et al. 2017)上的闭卷问答。 • 在 RACE(Lai et al. 2017)上的阅读理解 • 在 HellaSwag(Zellers et al. 2019)、PIQA(Bisk et al. 2020)、Winogrande(Sakaguchi et al. 2020)、SIQA(Sap et al. 2019)、BoolQ(Clark et al. 2019)与 TruthfulQA(Lin et al. 2021)上的常识理解。 |
| 动机 | 我们从 Rae et al. 2021 选取评测,以便最直接地与 Gopher 比较。 |
| 预处理 | 输入文本用词表大小为 32,000 的 SentencePiece 分词器分词。与 Gopher 所用分词器不同,Chinchilla 的分词器不做 NFKC 归一化。 |
| 训练数据 | |
| 使用与 Rae et al. 2021 相同的数据集。采样差异见表 A1。 | |
| 定量分析 | |
| 单元结果 | 第 4.2 节给出分析的详细描述。主要结论包括: • 以 PerspectiveAPI 衡量,我们的模型能够输出有毒语言。当用有毒提示引导时尤其如此。 • 性别:我们的模型模拟数据集中存在的刻板印象,如 “dietician”“receptionist” 更常与女性关联,“carpenter”“sheriff” 更常与男性关联。 • 种族/宗教/国家情感:提示模型讨论某些群体会导致更低或更高情感的句子,很可能反映数据集中的文本。 |
| 交叉结果 | 我们未调查交叉偏见。 |
| 伦理考量 | |
| 数据 | 数据与 Rae et al. 2021 所述相同。 |
| 人类生命 | 模型无意用于指导关乎人类生命或福祉核心事项的决策。 |
| 缓解措施 | 我们考虑过过滤数据集以去除有毒内容,但因 Welbl et al. 2021 所研究的观察——这可能引入新偏见——而决定不做。对有毒内容及 Weidinger et al. 2021 所讨论的其他语言模型风险类型,缓解方法仍需更多工作。 |
| 风险与危害 | 数据自互联网收集,因而训练数据集中无疑存在有毒/偏见内容。此外,用于训练我们模型的数据集中很可能也有个人信息。更详细讨论见 Weidinger et al. 2021。 |
| 用例 | 尤其危险的用例包括:生成意图传播的事实错误信息,或用模型生成带有害意图的种族主义、性别歧视或其他有毒文本。还存在许多可能导致危害的用例。此类恶意用途的应用在 Weidinger et al. 2021 中有详细讨论。 |
表 A8:Chinchilla 模型卡。我们遵循 Mitchell et al. 2019 提出的框架。
Appendix J List of trained models
附录 J 所训模型列表
In Table A9 we list the model size and configuration of all models used in this study. Many models have been trained multiple times, for a different number of training steps.
表 A9 列出本研究使用的全部模型的规模与配置。许多模型以不同训练步数被多次训练。
| Parameters (million) | d_model | ffw_size | kv_size | n_heads | n_layers |
|---|---|---|---|---|---|
| 44 | 512 | 2048 | 64 | 8 | 8 |
| 57 | 576 | 2304 | 64 | 9 | 9 |
| 74 | 640 | 2560 | 64 | 10 | 10 |
| 90 | 640 | 2560 | 64 | 10 | 13 |
| 106 | 640 | 2560 | 64 | 10 | 16 |
| 117 | 768 | 3072 | 64 | 12 | 12 |
| 140 | 768 | 3072 | 64 | 12 | 15 |
| 163 | 768 | 3072 | 64 | 12 | 18 |
| 175 | 896 | 3584 | 64 | 14 | 14 |
| 196 | 896 | 3584 | 64 | 14 | 16 |
| 217 | 896 | 3584 | 64 | 14 | 18 |
| 251 | 1024 | 4096 | 64 | 16 | 16 |
| 278 | 1024 | 4096 | 64 | 16 | 18 |
| 306 | 1024 | 4096 | 64 | 16 | 20 |
| 425 | 1280 | 5120 | 128 | 10 | 18 |
| 489 | 1280 | 5120 | 128 | 10 | 21 |
| 509 | 1408 | 5632 | 128 | 11 | 18 |
| 552 | 1280 | 5120 | 128 | 10 | 24 |
| 587 | 1408 | 5632 | 128 | 11 | 21 |
| 632 | 1536 | 6144 | 128 | 12 | 19 |
| 664 | 1408 | 5632 | 128 | 11 | 24 |
| 724 | 1536 | 6144 | 128 | 12 | 22 |
| 816 | 1536 | 6144 | 128 | 12 | 25 |
| 893 | 1792 | 7168 | 128 | 14 | 20 |
| 1,018 | 1792 | 7168 | 128 | 14 | 23 |
| 1,143 | 1792 | 7168 | 128 | 14 | 26 |
| 1,266 | 2048 | 8192 | 128 | 16 | 22 |
| 1,424 | 2176 | 8704 | 128 | 17 | 22 |
| 1,429 | 2048 | 8192 | 128 | 16 | 25 |
| 1,593 | 2048 | 8192 | 128 | 16 | 28 |
| 1,609 | 2176 | 8704 | 128 | 17 | 25 |
| 1,731 | 2304 | 9216 | 128 | 18 | 24 |
| 1,794 | 2176 | 8704 | 128 | 17 | 28 |
| 2,007 | 2304 | 9216 | 128 | 18 | 28 |
| 2,283 | 2304 | 9216 | 128 | 18 | 32 |
| 2,298 | 2560 | 10240 | 128 | 20 | 26 |
| 2,639 | 2560 | 10240 | 128 | 20 | 30 |
| 2,980 | 2560 | 10240 | 128 | 20 | 34 |
| 3,530 | 2688 | 10752 | 128 | 22 | 36 |
| 3,802 | 2816 | 11264 | 128 | 22 | 36 |
| 4,084 | 2944 | 11776 | 128 | 22 | 36 |
| 4,516 | 3072 | 12288 | 128 | 24 | 36 |
| 6,796 | 3584 | 14336 | 128 | 28 | 40 |
| 9,293 | 4096 | 16384 | 128 | 32 | 42 |
| 11,452 | 4352 | 17408 | 128 | 32 | 47 |
| 12,295 | 4608 | 18432 | 128 | 36 | 44 |
| 12,569 | 4608 | 18432 | 128 | 32 | 47 |
| 13,735 | 4864 | 19456 | 128 | 32 | 47 |
| 14,940 | 4992 | 19968 | 128 | 32 | 49 |
| 16,183 | 5120 | 20480 | 128 | 40 | 47 |
Table A9: All models. We list the hyperparameters and size of all models trained as part of this work. Many shown models have been trained with multiple learning rate schedules/number of training tokens.
| 参数量(百万) | d_model | ffw_size | kv_size | n_heads | n_layers |
|---|---|---|---|---|---|
| 44 | 512 | 2048 | 64 | 8 | 8 |
| 57 | 576 | 2304 | 64 | 9 | 9 |
| 74 | 640 | 2560 | 64 | 10 | 10 |
| 90 | 640 | 2560 | 64 | 10 | 13 |
| 106 | 640 | 2560 | 64 | 10 | 16 |
| 117 | 768 | 3072 | 64 | 12 | 12 |
| 140 | 768 | 3072 | 64 | 12 | 15 |
| 163 | 768 | 3072 | 64 | 12 | 18 |
| 175 | 896 | 3584 | 64 | 14 | 14 |
| 196 | 896 | 3584 | 64 | 14 | 16 |
| 217 | 896 | 3584 | 64 | 14 | 18 |
| 251 | 1024 | 4096 | 64 | 16 | 16 |
| 278 | 1024 | 4096 | 64 | 16 | 18 |
| 306 | 1024 | 4096 | 64 | 16 | 20 |
| 425 | 1280 | 5120 | 128 | 10 | 18 |
| 489 | 1280 | 5120 | 128 | 10 | 21 |
| 509 | 1408 | 5632 | 128 | 11 | 18 |
| 552 | 1280 | 5120 | 128 | 10 | 24 |
| 587 | 1408 | 5632 | 128 | 11 | 21 |
| 632 | 1536 | 6144 | 128 | 12 | 19 |
| 664 | 1408 | 5632 | 128 | 11 | 24 |
| 724 | 1536 | 6144 | 128 | 12 | 22 |
| 816 | 1536 | 6144 | 128 | 12 | 25 |
| 893 | 1792 | 7168 | 128 | 14 | 20 |
| 1,018 | 1792 | 7168 | 128 | 14 | 23 |
| 1,143 | 1792 | 7168 | 128 | 14 | 26 |
| 1,266 | 2048 | 8192 | 128 | 16 | 22 |
| 1,424 | 2176 | 8704 | 128 | 17 | 22 |
| 1,429 | 2048 | 8192 | 128 | 16 | 25 |
| 1,593 | 2048 | 8192 | 128 | 16 | 28 |
| 1,609 | 2176 | 8704 | 128 | 17 | 25 |
| 1,731 | 2304 | 9216 | 128 | 18 | 24 |
| 1,794 | 2176 | 8704 | 128 | 17 | 28 |
| 2,007 | 2304 | 9216 | 128 | 18 | 28 |
| 2,283 | 2304 | 9216 | 128 | 18 | 32 |
| 2,298 | 2560 | 10240 | 128 | 20 | 26 |
| 2,639 | 2560 | 10240 | 128 | 20 | 30 |
| 2,980 | 2560 | 10240 | 128 | 20 | 34 |
| 3,530 | 2688 | 10752 | 128 | 22 | 36 |
| 3,802 | 2816 | 11264 | 128 | 22 | 36 |
| 4,084 | 2944 | 11776 | 128 | 22 | 36 |
| 4,516 | 3072 | 12288 | 128 | 24 | 36 |
| 6,796 | 3584 | 14336 | 128 | 28 | 40 |
| 9,293 | 4096 | 16384 | 128 | 32 | 42 |
| 11,452 | 4352 | 17408 | 128 | 32 | 47 |
| 12,295 | 4608 | 18432 | 128 | 36 | 44 |
| 12,569 | 4608 | 18432 | 128 | 32 | 47 |
| 13,735 | 4864 | 19456 | 128 | 32 | 47 |
| 14,940 | 4992 | 19968 | 128 | 32 | 49 |
| 16,183 | 5120 | 20480 | 128 | 40 | 47 |
表 A9:全部模型。列出本工作所训全部模型的超参与规模。许多所示模型以多种学习率日程/训练 token 数训练。