Learning Transferable Visual Models From Natural Language Supervision
Learning Transferable Visual Models From Natural Language Supervision
从自然语言监督中学习可迁移的视觉模型(Learning Transferable Visual Models From Natural Language Supervision)
Alec Radford Affiliation: OpenAI, San Francisco, CA 94110, USA Jong Wook Kim Affiliation: OpenAI, San Francisco, CA 94110, USA Chris Hallacy Affiliation: OpenAI, San Francisco, CA 94110, USA Aditya Ramesh Affiliation: OpenAI, San Francisco, CA 94110, USA Gabriel Goh Affiliation: OpenAI, San Francisco, CA 94110, USA Sandhini Agarwal Affiliation: OpenAI, San Francisco, CA 94110, USA Girish Sastry Affiliation: OpenAI, San Francisco, CA 94110, USA Amanda Askell Affiliation: OpenAI, San Francisco, CA 94110, USA Pamela Mishkin Affiliation: OpenAI, San Francisco, CA 94110, USA Jack Clark Affiliation: OpenAI, San Francisco, CA 94110, USA Gretchen Krueger Affiliation: OpenAI, San Francisco, CA 94110, USA Ilya Sutskever Correspondence to: {alec, jongwook}@openai.com Affiliation: OpenAI, San Francisco, CA 94110, USA
Alec Radford 单位:OpenAI,美国加利福尼亚州旧金山 94110 Jong Wook Kim 单位:OpenAI,美国加利福尼亚州旧金山 94110 Chris Hallacy 单位:OpenAI,美国加利福尼亚州旧金山 94110 Aditya Ramesh 单位:OpenAI,美国加利福尼亚州旧金山 94110 Gabriel Goh 单位:OpenAI,美国加利福尼亚州旧金山 94110 Sandhini Agarwal 单位:OpenAI,美国加利福尼亚州旧金山 94110 Girish Sastry 单位:OpenAI,美国加利福尼亚州旧金山 94110 Amanda Askell 单位:OpenAI,美国加利福尼亚州旧金山 94110 Pamela Mishkin 单位:OpenAI,美国加利福尼亚州旧金山 94110 Jack Clark 单位:OpenAI,美国加利福尼亚州旧金山 94110 Gretchen Krueger 单位:OpenAI,美国加利福尼亚州旧金山 94110 Ilya Sutskever 通信作者:{alec, jongwook}@openai.com 单位:OpenAI,美国加利福尼亚州旧金山 94110
Abstract
摘要
State-of-the-art computer vision systems are trained to predict a fixed set of predetermined object categories. This restricted form of supervision limits their generality and usability since additional labeled data is needed to specify any other visual concept. Learning directly from raw text about images is a promising alternative which leverages a much broader source of supervision. We demonstrate that the simple pre-training task of predicting which caption goes with which image is an efficient and scalable way to learn SOTA image representations from scratch on a dataset of 400 million (image, text) pairs collected from the internet. After pre-training, natural language is used to reference learned visual concepts (or describe new ones) enabling zero-shot transfer of the model to downstream tasks. We study the performance of this approach by benchmarking on over 30 different existing computer vision datasets, spanning tasks such as OCR, action recognition in videos, geo-localization, and many types of fine-grained object classification. The model transfers non-trivially to most tasks and is often competitive with a fully supervised baseline without the need for any dataset specific training. For instance, we match the accuracy of the original ResNet-50 on ImageNet zero-shot without needing to use any of the 1.28 million training examples it was trained on. We release our code and pre-trained model weights at https://github.com/OpenAI/CLIP.
当前最先进的计算机视觉系统被训练去预测一组预先确定的固定物体类别。这种受限的监督形式限制了系统的通用性与可用性,因为要指定任何其他视觉概念,都需要额外的标注数据。直接从与图像相关的原始文本中学习,是一种有希望的替代路径,能利用更广阔的监督来源。我们表明:预测“哪段说明文字对应哪张图”这一简单的预训练任务,是在从互联网收集的 4 亿组(图像,文本)对上从头学习当前最优图像表征的高效且可扩展的方式。预训练之后,可用自然语言引用已学到的视觉概念(或描述新概念),从而实现模型向下游任务的零样本迁移。我们在超过 30 个现有计算机视觉数据集上评测该方法,覆盖 OCR、视频动作识别、地理定位以及多种细粒度物体分类等任务。模型在多数任务上都能非平凡地迁移,并且常常无需任何数据集特定训练就能与完全监督基线竞争。例如,我们在 ImageNet 上以零样本方式达到了原始 ResNet-50 的精度,却完全没有使用它训练时用到的 128 万个训练样本。代码与预训练权重见 https://github.com/OpenAI/CLIP。
1 Introduction and Motivating Work
1 引言与相关动机
Pre-training methods which learn directly from raw text have revolutionized NLP over the last few years (Dai & Le 2015; Peters et al. 2018; Howard & Ruder 2018; Radford et al. 2018; Devlin et al. 2018; Raffel et al. 2019). Task-agnostic objectives such as autoregressive and masked language modeling have scaled across many orders of magnitude in compute, model capacity, and data, steadily improving capabilities. The development of “text-to-text” as a standardized input-output interface (McCann et al. 2018; Radford et al. 2019; Raffel et al. 2019) has enabled task-agnostic architectures to zero-shot transfer to downstream datasets removing the need for specialized output heads or dataset specific customization. Flagship systems like GPT-3 (Brown et al. 2020) are now competitive across many tasks with bespoke models while requiring little to no dataset specific training data.
过去几年,直接从原始文本学习的预训练方法彻底改变了自然语言处理(Dai & Le 2015;Peters 等 2018;Howard & Ruder 2018;Radford 等 2018;Devlin 等 2018;Raffel 等 2019)。自回归与掩码语言建模这类与任务无关的目标,已经在算力、模型容量与数据上跨越多个数量级扩展,能力稳步提升。“文本到文本”作为标准化输入输出接口的发展(McCann 等 2018;Radford 等 2019;Raffel 等 2019),使与任务无关的架构能够零样本迁移到下游数据集,不再需要专门的输出头或数据集特定定制。像 GPT-3(Brown 等 2020)这样的旗舰系统,现在在许多任务上已能与定制模型竞争,同时几乎不需要数据集特定的训练数据。
These results suggest that the aggregate supervision accessible to modern pre-training methods within web-scale collections of text surpasses that of high-quality crowd-labeled NLP datasets. However, in other fields such as computer vision it is still standard practice to pre-train models on crowd-labeled datasets such as ImageNet (Deng et al. 2009). Could scalable pre-training methods which learn directly from web text result in a similar breakthrough in computer vision? Prior work is encouraging.
这些结果表明:现代预训练方法在网络规模文本集合中所能获得的聚合监督,已经超过高质量众包标注的 NLP 数据集。然而在计算机视觉等领域,仍普遍在 ImageNet(Deng 等 2009)这类众包标注数据集上预训练模型。直接从网络文本学习的可扩展预训练,能否在计算机视觉中带来类似突破?先前工作令人鼓舞。
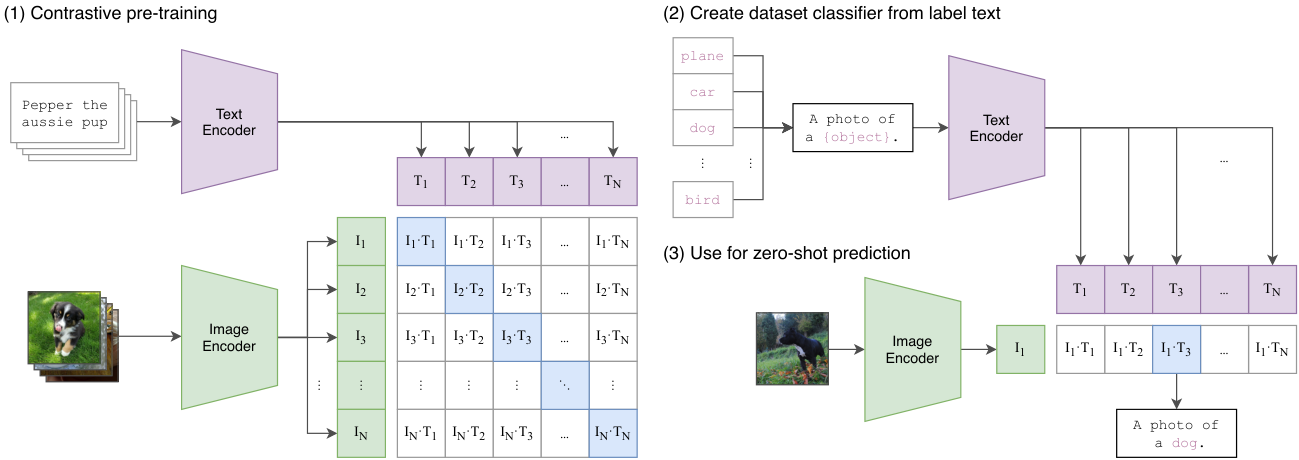
Figure 1: Summary of our approach. While standard image models jointly train an image feature extractor and a linear classifier to predict some label, CLIP jointly trains an image encoder and a text encoder to predict the correct pairings of a batch of (image, text) training examples. At test time the learned text encoder synthesizes a zero-shot linear classifier by embedding the names or descriptions of the target dataset’s classes.
图 1:方法概要。标准图像模型联合训练图像特征提取器与线性分类器以预测某个标签;CLIP 则联合训练图像编码器与文本编码器,以预测一个 batch 的(图像,文本)训练样本中的正确配对。测试时,学到的文本编码器通过嵌入目标数据集类别的名称或描述,合成一个零样本线性分类器。
Over 20 years ago Mori et al. 1999 explored improving content based image retrieval by training a model to predict the nouns and adjectives in text documents paired with images. Quattoni et al. 2007 demonstrated it was possible to learn more data efficient image representations via manifold learning in the weight space of classifiers trained to predict words in captions associated with images. Srivastava & Salakhutdinov 2012 explored deep representation learning by training multimodal Deep Boltzmann Machines on top of low-level image and text tag features. Joulin et al. 2016 modernized this line of work and demonstrated that CNNs trained to predict words in image captions learn useful image representations. They converted the title, description, and hashtag metadata of images in the YFCC100M dataset (Thomee et al. 2016) into a bag-of-words multi-label classification task and showed that pre-training AlexNet (Krizhevsky et al. 2012) to predict these labels learned representations which preformed similarly to ImageNet-based pre-training on transfer tasks. Li et al. 2017 then extended this approach to predicting phrase n-grams in addition to individual words and demonstrated the ability of their system to zero-shot transfer to other image classification datasets by scoring target classes based on their dictionary of learned visual n-grams and predicting the one with the highest score. Adopting more recent architectures and pre-training approaches, VirTex (Desai & Johnson 2020), ICMLM (Bulent Sariyildiz et al. 2020), and ConVIRT (Zhang et al. 2020) have recently demonstrated the potential of transformer-based language modeling, masked language modeling, and contrastive objectives to learn image representations from text.
二十多年前,Mori 等 1999 探索通过训练模型预测与图像配对的文本文档中的名词与形容词,来改进基于内容的图像检索。Quattoni 等 2007 表明,可以在为预测图像说明中词语而训练的分类器权重空间里做流形学习,从而学到数据效率更高的图像表征。Srivastava & Salakhutdinov 2012 探索在低层图像与文本标签特征之上训练多模态深度玻尔兹曼机,以进行深度表征学习。Joulin 等 2016 把这条路线现代化,表明训练 CNN 预测图像说明中的词语可以学到有用的图像表征。他们把 YFCC100M 数据集(Thomee 等 2016)中图像的标题、描述与标签元数据转成词袋多标签分类任务,并表明用 AlexNet(Krizhevsky 等 2012)预训练去预测这些标签,学到的表征在迁移任务上与基于 ImageNet 的预训练表现相近。Li 等 2017 进而把方法扩展到预测短语 n-gram 以及单个词,并展示系统能零样本迁移到其他图像分类数据集:用已学视觉 n-gram 词典给目标类别打分,预测得分最高者。采用更新的架构与预训练方法后,VirTex(Desai & Johnson 2020)、ICMLM(Bulent Sariyildiz 等 2020)与 ConVIRT(Zhang 等 2020)近来表明,基于 Transformer 的语言建模、掩码语言建模与对比目标,都有潜力从文本学习图像表征。
While exciting as proofs of concept, using natural language supervision for image representation learning is still rare. This is likely because demonstrated performance on common benchmarks is much lower than alternative approaches. For example, Li et al. 2017 reach only 11.5% accuracy on ImageNet in a zero-shot setting. This is well below the 88.4% accuracy of the current state of the art (Xie et al. 2020). It is even below the 50% accuracy of classic computer vision approaches (Deng et al. 2012). Instead, more narrowly scoped but well-targeted uses of weak supervision have improved performance. Mahajan et al. 2018 showed that predicting ImageNet-related hashtags on Instagram images is an effective pre-training task. When fine-tuned to ImageNet these pre-trained models increased accuracy by over 5% and improved the overall state of the art at the time. Kolesnikov et al. 2019 and Dosovitskiy et al. 2020 have also demonstrated large gains on a broader set of transfer benchmarks by pre-training models to predict the classes of the noisily labeled JFT-300M dataset.
这些工作作为概念验证令人兴奋,但用自然语言监督做图像表征学习仍然少见。很可能是因为在常见基准上展示的性能远低于替代方法。例如 Li 等 2017 在零样本设定下 ImageNet 精度只有 11.5%,远低于当时最优的 88.4%(Xie 等 2020),甚至低于经典计算机视觉方法的 50%(Deng 等 2012)。相比之下,更窄但更有针对性的弱监督用法提升了性能。Mahajan 等 2018 表明,在 Instagram 图像上预测与 ImageNet 相关的标签是有效的预训练任务;微调到 ImageNet 后,这些预训练模型把精度提高超过 5%,并提升了当时的总体最优。Kolesnikov 等 2019 与 Dosovitskiy 等 2020 也表明,在带噪声标注的 JFT-300M 数据集上预训练以预测类别,能在更广泛的迁移基准上取得大幅提升。
This line of work represents the current pragmatic middle ground between learning from a limited amount of supervised “gold-labels” and learning from practically unlimited amounts of raw text. However, it is not without compromises. Both works carefully design, and in the process limit, their supervision to 1000 and 18291 classes respectively. Natural language is able to express, and therefore supervise, a much wider set of visual concepts through its generality. Both approaches also use static softmax classifiers to perform prediction and lack a mechanism for dynamic outputs. This severely curtails their flexibility and limits their “zero-shot” capabilities.
这条工作线代表了当前实用的中间地带:一端是有限的监督“金标签”,另一端是几乎无限的原始文本。但它也有折中。两份工作都仔细设计、并因此限制其监督,分别只有 1000 与 18291 个类别。自然语言因其通用性,能够表达、因而也能监督宽得多的视觉概念集合。两种方法还都用静态 softmax 分类器做预测,缺乏动态输出机制。这严重削弱了灵活性,并限制了它们的“零样本”能力。
A crucial difference between these weakly supervised models and recent explorations of learning image representations directly from natural language is scale. While Mahajan et al. 2018 and Kolesnikov et al. 2019 trained their models for accelerator years on millions to billions of images, VirTex, ICMLM, and ConVIRT trained for accelerator days on one to two hundred thousand images. In this work, we close this gap and study the behaviors of image classifiers trained with natural language supervision at large scale. Enabled by the large amounts of publicly available data of this form on the internet, we create a new dataset of 400 million (image, text) pairs and demonstrate that a simplified version of ConVIRT trained from scratch, which we call CLIP, for Contrastive Language-Image Pre-training, is an efficient method of learning from natural language supervision. We study the scalability of CLIP by training a series of eight models spanning almost 2 orders of magnitude of compute and observe that transfer performance is a smoothly predictable function of compute (Hestness et al. 2017; Kaplan et al. 2020). We find that CLIP, similar to the GPT family, learns to perform a wide set of tasks during pre-training including OCR, geo-localization, action recognition, and many others. We measure this by benchmarking the zero-shot transfer performance of CLIP on over 30 existing datasets and find it can be competitive with prior task-specific supervised models. We also confirm these findings with linear-probe representation learning analysis and show that CLIP outperforms the best publicly available ImageNet model while also being more computationally efficient. We additionally find that zero-shot CLIP models are much more robust than equivalent accuracy supervised ImageNet models which suggests that zero-shot evaluation of task-agnostic models is much more representative of a model’s capability. These results have significant policy and ethical implications, which we consider in Section 7.
这些弱监督模型与近来直接从自然语言学习图像表征的探索之间,一个关键差别是规模。Mahajan 等 2018 与 Kolesnikov 等 2019 用加速器年在数百万到数十亿图像上训练;VirTex、ICMLM 与 ConVIRT 则用加速器天在一二十万图像上训练。本工作弥合这一差距,研究在大规模自然语言监督下训练的图像分类器行为。得益于互联网上大量公开可得的这类数据,我们构建了包含 4 亿组(图像,文本)对的新数据集,并表明从零训练的、简化版 ConVIRT——我们称之为 CLIP(Contrastive Language-Image Pre-training,对比语言–图像预训练)——是从自然语言监督中学习的高效方法。我们训练横跨近两个数量级算力的八个模型系列,观察迁移性能是算力的平滑可预测函数(Hestness 等 2017;Kaplan 等 2020)。我们发现 CLIP 与 GPT 家族类似,在预训练中就学会执行广泛任务,包括 OCR、地理定位、动作识别等。我们通过在超过 30 个现有数据集上评测 CLIP 的零样本迁移来衡量这一点,发现它能与先前任务特定的监督模型竞争。我们还用线性探测表征学习分析确认这些发现,表明 CLIP 超过公开可得的最好 ImageNet 模型,同时计算更高效。此外,零样本 CLIP 模型比同等精度的监督 ImageNet 模型稳健得多,这表明对与任务无关模型做零样本评估更能代表模型能力。这些结果有重要的政策与伦理含义,我们在第 7 节讨论。
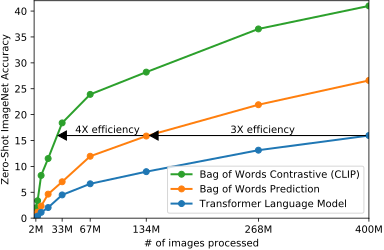
Figure 2: CLIP is much more efficient at zero-shot transfer than our image caption baseline. Although highly expressive, we found that transformer-based language models are relatively weak at zero-shot ImageNet classification. Here, we see that it learns 3x slower than a baseline which predicts a bag-of-words (BoW) encoding of the text (Joulin et al. 2016). Swapping the prediction objective for the contrastive objective of CLIP further improves efficiency another 4x.
图 2:相对我们的图像说明基线,CLIP 在零样本迁移上高效得多。 尽管表达力很强,我们发现基于 Transformer 的语言模型在零样本 ImageNet 分类上相对较弱。这里可以看到,它的学习速度比预测文本词袋(BoW)编码的基线(Joulin 等 2016)慢 3 倍。把预测目标换成 CLIP 的对比目标后,效率再提升 4 倍。
2 Approach
2 方法
2.1 Natural Language Supervision
2.1 自然语言监督
At the core of our approach is the idea of learning perception from supervision contained in natural language. As discussed in the introduction, this is not at all a new idea, however terminology used to describe work in this space is varied, even seemingly contradictory, and stated motivations are diverse. Zhang et al. 2020, Gomez et al. 2017, Joulin et al. 2016, and Desai & Johnson 2020 all introduce methods which learn visual representations from text paired with images but describe their approaches as unsupervised, self-supervised, weakly supervised, and supervised respectively.
我们方法的核心,是从自然语言所含的监督中学习感知。如引言所述,这绝不是新想法,但描述该方向工作的术语多样,甚至看似矛盾,动机表述也不一。Zhang 等 2020、Gomez 等 2017、Joulin 等 2016 与 Desai & Johnson 2020 都提出从与图像配对的文本学习视觉表征的方法,却分别把自己的方法称作无监督、自监督、弱监督与有监督。
We emphasize that what is common across this line of work is not any of the details of the particular methods used but the appreciation of natural language as a training signal. All these approaches are learning from natural language supervision. Although early work wrestled with the complexity of natural language when using topic model and n-gram representations, improvements in deep contextual representation learning suggest we now have the tools to effectively leverage this abundant source of supervision (McCann et al. 2017).
我们强调:这条工作线的共同点,并不在于所用具体方法的细节,而在于把自然语言视为训练信号。所有这些方法都在从自然语言监督中学习。早期工作在使用主题模型与 n-gram 表示时曾与自然语言的复杂性搏斗;深度上下文表征学习的进步表明,我们现在已有工具能有效利用这一丰富监督来源(McCann 等 2017)。
Learning from natural language has several potential strengths over other training methods. It’s much easier to scale natural language supervision compared to standard crowd-sourced labeling for image classification since it does not require annotations to be in a classic “machine learning compatible format” such as the canonical 1-of-N majority vote “gold label”. Instead, methods which work on natural language can learn passively from the supervision contained in the vast amount of text on the internet. Learning from natural language also has an important advantage over most unsupervised or self-supervised learning approaches in that it doesn’t “just” learn a representation but also connects that representation to language which enables flexible zero-shot transfer. In the following subsections, we detail the specific approach we settled on.
相对其他训练方法,从自然语言学习有几项潜在优势。与图像分类的标准众包标注相比,自然语言监督更容易扩展,因为它不要求标注必须是经典的“机器学习兼容格式”,例如典型的 1-of-N 多数投票“金标签”。相反,能处理自然语言的方法可以被动地从互联网海量文本所含的监督中学习。相对多数无监督或自监督学习,从自然语言学习还有一个重要优势:它不只是学到表征,还把表征与语言连接起来,从而实现灵活的零样本迁移。下面几小节详述我们最终选定的具体方法。
2.2 Creating a Sufficiently Large Dataset
2.2 构建足够大的数据集
Existing work has mainly used three datasets, MS-COCO (Lin et al. 2014), Visual Genome (Krishna et al. 2017), and YFCC100M (Thomee et al. 2016). While MS-COCO and Visual Genome are high quality crowd-labeled datasets, they are small by modern standards with approximately 100,000 training photos each. By comparison, other computer vision systems are trained on up to 3.5 billion Instagram photos (Mahajan et al. 2018). YFCC100M, at 100 million photos, is a possible alternative, but the metadata for each image is sparse and of varying quality. Many images use automatically generated filenames like 20160716_113957.JPG as “titles” or contain “descriptions” of camera exposure settings. After filtering to keep only images with natural language titles and/or descriptions in English, the dataset shrunk by a factor of 6 to only 15 million photos. This is approximately the same size as ImageNet.
已有工作主要使用三个数据集:MS-COCO(Lin 等 2014)、Visual Genome(Krishna 等 2017)与 YFCC100M(Thomee 等 2016)。MS-COCO 与 Visual Genome 是高质量众包标注数据集,但按现代标准偏小,各约 10 万张训练照片。相比之下,其他计算机视觉系统在多达 35 亿 张 Instagram 照片上训练(Mahajan 等 2018)。YFCC100M 有 1 亿张照片,是可能的替代,但每张图的元数据稀疏且质量参差。许多图像用自动生成的文件名如 20160716_113957.JPG 当“标题”,或把相机曝光设置写进“描述”。过滤后只保留带英语自然语言标题和/或描述的图像,数据集缩小到约六分之一,只剩 1500 万张,大约与 ImageNet 同规模。
A major motivation for natural language supervision is the large quantities of data of this form available publicly on the internet. Since existing datasets do not adequately reflect this possibility, considering results only on them would underestimate the potential of this line of research. To address this, we constructed a new dataset of 400 million (image, text) pairs collected form a variety of publicly available sources on the Internet. To attempt to cover as broad a set of visual concepts as possible, we search for (image, text) pairs as part of the construction process whose text includes one of a set of 500,000 queries.[^1] We approximately class balance the results by including up to 20,000 (image, text) pairs per query. The resulting dataset has a similar total word count as the WebText dataset used to train GPT-2. We refer to this dataset as WIT for WebImageText.
自然语言监督的一个主要动机,是互联网上公开可得的此类数据量很大。现有数据集未能充分反映这一可能性,若只在它们上看结果,会低估该研究方向的潜力。为此,我们从互联网上多种公开来源收集,构建了包含 4 亿组(图像,文本)对的新数据集。为尽可能覆盖广泛的视觉概念,构建过程中搜索文本包含某组 50 万查询之一的(图像,文本)对。[^1] 我们通过每个查询最多纳入 2 万组(图像,文本)对,近似做类别平衡。所得数据集的总词数与训练 GPT-2 所用的 WebText 相近。我们称该数据集为 WIT(WebImageText)。
2.3 Selecting an Efficient Pre-Training Method
2.3 选择高效的预训练方法
State-of-the-art computer vision systems use very large amounts of compute. Mahajan et al. 2018 required 19 GPU years to train their ResNeXt101-32x48d and Xie et al. 2020 required 33 TPUv3 core-years to train their Noisy Student EfficientNet-L2. When considering that both these systems were trained to predict only 1000 ImageNet classes, the task of learning an open set of visual concepts from natural language seems daunting. In the course of our efforts, we found training efficiency was key to successfully scaling natural language supervision and we selected our final pre-training method based on this metric.
最先进的计算机视觉系统使用极大算力。Mahajan 等 2018 训练 ResNeXt101-32x48d 需要 19 GPU 年,Xie 等 2020 训练 Noisy Student EfficientNet-L2 需要 33 个 TPUv3 核年。考虑到这两个系统都只预测 1000 个 ImageNet 类别,从自然语言学习开放视觉概念集合的任务显得艰巨。在我们的努力中,发现训练效率是成功扩展自然语言监督的关键,并据此指标选定最终预训练方法。
Our initial approach, similar to VirTex, jointly trained an image CNN and text transformer from scratch to predict the caption of an image. However, we encountered difficulties efficiently scaling this method. In Figure 2 we show that a 63 million parameter transformer language model, which already uses twice the compute of its ResNet-50 image encoder, learns to recognize ImageNet classes three times slower than a much simpler baseline that predicts a bag-of-words encoding of the same text.
我们最初的方法类似 VirTex:从头联合训练图像 CNN 与文本 Transformer,以预测图像的说明文字。但高效扩展该方法遇到困难。图 2 显示:一个 6300 万参数的 Transformer 语言模型——其算力已是 ResNet-50 图像编码器的两倍——识别 ImageNet 类别的速度,比预测同一文本词袋编码的简单得多的基线慢三倍。
Both these approaches share a key similarity. They try to predict the exact words of the text accompanying each image. This is a difficult task due to the wide variety of descriptions, comments, and related text that co-occur with images. Recent work in contrastive representation learning for images has found that contrastive objectives can learn better representations than their equivalent predictive objective (Tian et al. 2019). Other work has found that although generative models of images can learn high quality image representations, they require over an order of magnitude more compute than contrastive models with the same performance (Chen et al. 2020a). Noting these findings, we explored training a system to solve the potentially easier proxy task of predicting only which text as a whole is paired with which image and not the exact words of that text. Starting with the same bag-of-words encoding baseline, we swapped the predictive objective for a contrastive objective in Figure 2 and observed a further 4x efficiency improvement in the rate of zero-shot transfer to ImageNet.
这两种方法有一个关键相似点:都试图预测伴随每张图像的文本的精确用词。由于与图像共现的描述、评论及相关文本种类繁多,这很难。图像对比表征学习的近期工作发现,对比目标能比等价的预测目标学到更好的表征(Tian 等 2019)。另有工作发现,虽然图像生成模型能学到高质量图像表征,但达到相同性能所需算力比对比模型高一个数量级以上(Chen 等 2020a)。注意到这些发现后,我们探索训练系统去解决可能更容易的代理任务:只预测哪段文本整体与哪张图配对,而不预测该文本的精确用词。从图 2 中同一个词袋编码基线出发,把预测目标换成对比目标后,我们观察到向 ImageNet 零样本迁移的速率再提升 4 倍。
Given a batch of (image, text) pairs, CLIP is trained to predict which of the possible (image, text) pairings across a batch actually occurred. To do this, CLIP learns a multi-modal embedding space by jointly training an image encoder and text encoder to maximize the cosine similarity of the image and text embeddings of the real pairs in the batch while minimizing the cosine similarity of the embeddings of the incorrect pairings. We optimize a symmetric cross entropy loss over these similarity scores. In Figure 3 we include pseudocode of the core of an implementation of CLIP. To our knowledge this batch construction technique and objective was first introduced in the area of deep metric learning as the multi-class N-pair loss Sohn 2016, was popularized for contrastive representation learning by Oord et al. 2018 as the InfoNCE loss, and was recently adapted for contrastive (text, image) representation learning in the domain of medical imaging by Zhang et al. 2020.
给定一个含 组(图像,文本)对的 batch,CLIP 被训练去预测该 batch 中 种可能的(图像,文本)配对里哪些真正出现过。为此,CLIP 通过联合训练图像编码器与文本编码器学习多模态嵌入空间:最大化 batch 中 个真实配对的图像与文本嵌入的余弦相似度,同时最小化 个错误配对嵌入的余弦相似度。我们在这些相似度分数上优化对称交叉熵损失。图 3 给出 CLIP 核心实现的伪代码。据我们所知,这种 batch 构造技术与目标最早在深度度量学习中作为多类 N-pair 损失提出(Sohn 2016),由 Oord 等 2018 作为 InfoNCE 损失在对比表征学习中推广,近来由 Zhang 等 2020 适配到医学影像领域的对比(文本,图像)表征学习。
Due to the large size of our pre-training dataset, over-fitting is not a major concern and the details of training CLIP are simplified compared to the implementation of Zhang et al. 2020. We train CLIP from scratch without initializing the image encoder with ImageNet weights or the text encoder with pre-trained weights. We do not use the non-linear projection between the representation and the contrastive embedding space, a change which was introduced by Bachman et al. 2019 and popularized by Chen et al. 2020b. We instead use only a linear projection to map from each encoder’s representation to the multi-modal embedding space. We did not notice a difference in training efficiency between the two versions and speculate that non-linear projections may be co-adapted with details of current image only in self-supervised representation learning methods. We also remove the text transformation function from Zhang et al. 2020 which samples a single sentence at uniform from the text since many of the (image, text) pairs in CLIP’s pre-training dataset are only a single sentence. We also simplify the image transformation function . A random square crop from resized images is the only data augmentation used during training. Finally, the temperature parameter which controls the range of the logits in the softmax, , is directly optimized during training as a log-parameterized multiplicative scalar to avoid turning as a hyper-parameter.
由于预训练数据集很大,过拟合不是主要担忧,CLIP 的训练细节也比 Zhang 等 2020 的实现更简化。我们从头训练 CLIP,不用 ImageNet 权重初始化图像编码器,也不用预训练权重初始化文本编码器。我们不使用表征与对比嵌入空间之间的非线性投影——该改动由 Bachman 等 2019 引入、由 Chen 等 2020b 推广。我们只用线性投影把各编码器的表征映射到多模态嵌入空间。两种版本在训练效率上我们未观察到差异,推测非线性投影可能与当前仅图像的自监督表征学习方法的细节共同适应。我们还去掉了 Zhang 等 2020 中的文本变换函数 (从文本中均匀采样单句),因为 CLIP 预训练数据里许多(图像,文本)对本身只有一句。图像变换函数 也简化了:训练时唯一的数据增强是对已缩放图像做随机正方形裁剪。最后,控制 softmax 中 logits 范围的温度参数 在训练中作为对数参数化的乘性标量直接优化,以避免把它当作超参数来调。
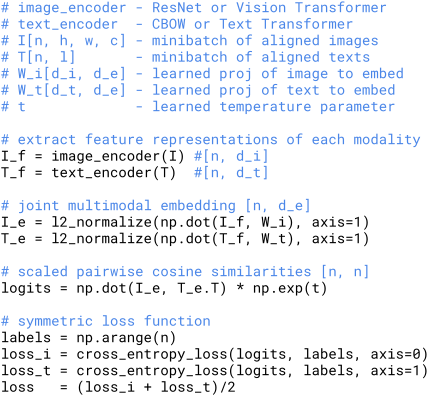
Figure 3: Numpy-like pseudocode for the core of an implementation of CLIP.
图 3:CLIP 核心实现的类 Numpy 伪代码。
2.4 Choosing and Scaling a Model
2.4 选择与缩放模型
We consider two different architectures for the image encoder. For the first, we use ResNet-50 (He et al. 2016a) as the base architecture for the image encoder due to its widespread adoption and proven performance. We make several modifications to the original version using the ResNet-D improvements from He et al. 2019 and the antialiased rect-2 blur pooling from Zhang 2019. We also replace the global average pooling layer with an attention pooling mechanism. The attention pooling is implemented as a single layer of “transformer-style” multi-head QKV attention where the query is conditioned on the global average-pooled representation of the image. For the second architecture, we experiment with the recently introduced Vision Transformer (ViT) (Dosovitskiy et al. 2020). We closely follow their implementation with only the minor modification of adding an additional layer normalization to the combined patch and position embeddings before the transformer and use a slightly different initialization scheme.
图像编码器我们考虑两种架构。第一种以 ResNet-50(He 等 2016a)为基座,因其广泛采用且性能经过验证。我们用 He 等 2019 的 ResNet-D 改进与 Zhang 2019 的抗混叠 rect-2 模糊池化对原版做了若干修改,并把全局平均池化替换为注意力池化。注意力池化实现为单层“Transformer 风格”的多头 QKV 注意力,其中 query 以图像的全局平均池化表征为条件。第二种架构我们试验近来提出的 Vision Transformer(ViT)(Dosovitskiy 等 2020)。实现基本沿用原文,仅做小改动:在送入 Transformer 前,对合并的 patch 与位置嵌入再加一层层归一化,并使用略有不同的初始化方案。
The text encoder is a Transformer (Vaswani et al. 2017) with the architecture modifications described in Radford et al. 2019. As a base size we use a 63M-parameter 12-layer 512-wide model with 8 attention heads. The transformer operates on a lower-cased byte pair encoding (BPE) representation of the text with a 49,152 vocab size (Sennrich et al. 2015). For computational efficiency, the max sequence length was capped at 76. The text sequence is bracketed with [SOS] and [EOS] tokens and the activations of the highest layer of the transformer at the [EOS] token are treated as the feature representation of the text which is layer normalized and then linearly projected into the multi-modal embedding space. Masked self-attention was used in the text encoder to preserve the ability to initialize with a pre-trained language model or add language modeling as an auxiliary objective, though exploration of this is left as future work.
文本编码器是 Transformer(Vaswani 等 2017),架构修改见 Radford 等 2019。基座规模为 6300 万参数、12 层、宽 512、8 个注意力头的模型。Transformer 在文本的小写字节对编码(BPE)表示上运行,词表大小 49152(Sennrich 等 2015)。为计算效率,最大序列长度限制为 76。文本序列用 [SOS] 与 [EOS] 标记括起,Transformer 最高层在 [EOS] 处的激活作为文本特征表征,经层归一化后再线性投影到多模态嵌入空间。文本编码器使用掩码自注意力,以保留用预训练语言模型初始化或把语言建模作为辅助目标的能力,不过这方面的探索留作未来工作。
While previous computer vision research has often scaled models by increasing the width (Mahajan et al. 2018) or depth (He et al. 2016a) in isolation, for the ResNet image encoders we adapt the approach of Tan & Le 2019 which found that allocating additional compute across all of width, depth, and resolution outperforms only allocating it to only one dimension of the model. While Tan & Le 2019 tune the ratio of compute allocated to each dimension for their EfficientNet architecture, we use a simple baseline of allocating additional compute equally to increasing the width, depth, and resolution of the model. For the text encoder, we only scale the width of the model to be proportional to the calculated increase in width of the ResNet and do not scale the depth at all, as we found CLIP’s performance to be less sensitive to the capacity of the text encoder.
先前计算机视觉研究常单独通过加宽(Mahajan 等 2018)或加深(He 等 2016a)来缩放模型;对 ResNet 图像编码器,我们采用 Tan & Le 2019 的做法——他们发现把额外算力分配到宽度、深度与分辨率全部维度,优于只分配到单一维度。Tan & Le 2019 为其 EfficientNet 架构调了各维度算力分配比例;我们用简单基线:把额外算力等分给增大模型的宽度、深度与分辨率。对文本编码器,我们只按 ResNet 计算得到的宽度增幅成比例加宽,完全不加深,因为我们发现 CLIP 的性能对文本编码器容量不那么敏感。
2.5 Training
2.5 训练
We train a series of 5 ResNets and 3 Vision Transformers. For the ResNets we train a ResNet-50, a ResNet-101, and then 3 more which follow EfficientNet-style model scaling and use approximately 4x, 16x, and 64x the compute of a ResNet-50. They are denoted as RN50x4, RN50x16, and RN50x64 respectively. For the Vision Transformers we train a ViT-B/32, a ViT-B/16, and a ViT-L/14. We train all models for 32 epochs. We use the Adam optimizer (Kingma & Ba 2014) with decoupled weight decay regularization (Loshchilov & Hutter 2017) applied to all weights that are not gains or biases, and decay the learning rate using a cosine schedule (Loshchilov & Hutter 2016). Initial hyper-parameters were set using a combination of grid searches, random search, and manual tuning on the baseline ResNet-50 model when trained for 1 epoch. Hyper-parameters were then adapted heuristically for larger models due to computational constraints. The learnable temperature parameter was initialized to the equivalent of 0.07 from (Wu et al. 2018) and clipped to prevent scaling the logits by more than 100 which we found necessary to prevent training instability. We use a very large minibatch size of 32,768. Mixed-precision (Micikevicius et al. 2017) was used to accelerate training and save memory. To save additional memory, gradient checkpointing (Griewank & Walther 2000; Chen et al. 2016), half-precision Adam statistics (Dhariwal et al. 2020), and half-precision stochastically rounded text encoder weights were used. The calculation of embedding similarities was also sharded with individual GPUs computing only the subset of the pairwise similarities necessary for their local batch of embeddings. The largest ResNet model, RN50x64, took 18 days to train on 592 V100 GPUs while the largest Vision Transformer took 12 days on 256 V100 GPUs. For the ViT-L/14 we also pre-train at a higher 336 pixel resolution for one additional epoch to boost performance similar to FixRes (Touvron et al. 2019). We denote this model as ViT-L/14@336px. Unless otherwise specified, all results reported in this paper as “CLIP” use this model which we found to perform best.
我们训练一系列 5 个 ResNet 与 3 个 Vision Transformer。ResNet 方面训练 ResNet-50、ResNet-101,以及另外 3 个按 EfficientNet 风格缩放、算力约分别为 ResNet-50 的 4 倍、16 倍与 64 倍的模型,记为 RN50x4、RN50x16 与 RN50x64。Vision Transformer 方面训练 ViT-B/32、ViT-B/16 与 ViT-L/14。所有模型训练 32 个周期。使用 Adam 优化器(Kingma & Ba 2014),并对所有非增益、非偏置的权重施加解耦权重衰减正则(Loshchilov & Hutter 2017),学习率按余弦日程衰减(Loshchilov & Hutter 2016)。初始超参数在基线 ResNet-50 训练 1 个周期时,结合网格搜索、随机搜索与手工调参设定,再因算力限制启发式地适配到更大模型。可学习温度参数 初始化为与(Wu 等 2018)中 0.07 等价的值,并做裁剪以防止把 logits 放大超过 100——我们发现这对避免训练不稳定是必要的。minibatch 非常大,为 32768。使用混合精度(Micikevicius 等 2017)加速训练并节省显存。为进一步省显存,还使用了梯度检查点(Griewank & Walther 2000;Chen 等 2016)、半精度 Adam 统计量(Dhariwal 等 2020)以及半精度随机舍入的文本编码器权重。嵌入相似度计算也做分片,各 GPU 只计算其本地 batch 嵌入所需的那部分成对相似度。最大的 ResNet 模型 RN50x64 在 592 块 V100 上训练了 18 天,最大的 Vision Transformer 在 256 块 V100 上训练了 12 天。对 ViT-L/14,我们还在更高的 336 像素分辨率上额外预训练 1 个周期以提升性能,类似 FixRes(Touvron 等 2019),记为 ViT-L/14@336px。除非另有说明,本文报告为“CLIP”的结果均使用我们发现表现最好的该模型。
3 Experiments
3 实验
3.1 Zero-Shot Transfer
3.1 零样本迁移
3.1.1 Motivation
3.1.1 动机
In computer vision, zero-shot learning usually refers to the study of generalizing to unseen object categories in image classification (Lampert et al. 2009). We instead use the term in a broader sense and study generalization to unseen datasets. We motivate this as a proxy for performing unseen tasks, as aspired to in the zero-data learning paper of Larochelle et al. 2008. While much research in the field of unsupervised learning focuses on the representation learning capabilities of machine learning systems, we motivate studying zero-shot transfer as a way of measuring the task-learning capabilities of machine learning systems. In this view, a dataset evaluates performance on a task on a specific distribution. However, many popular computer vision datasets were created by the research community primarily as benchmarks to guide the development of generic image classification methods rather than measuring performance on a specific task. While it is reasonable to say that the SVHN dataset measures the task of street number transcription on the distribution of Google Street View photos, it is unclear what “real” task the CIFAR-10 dataset measures. It is clear, however, what distribution CIFAR-10 is drawn from - TinyImages (Torralba et al. 2008). On these kinds of datasets, zero-shot transfer is more an evaluation of CLIP’s robustness to distribution shift and domain generalization rather than task generalization. Please see Section 3.3 for analysis focused on this.
在计算机视觉中,零样本学习通常指研究图像分类中向未见物体类别的泛化(Lampert 等 2009)。我们改用更宽的含义,研究向未见数据集的泛化。我们把它当作执行未见任务的代理,呼应 Larochelle 等 2008 的零数据学习论文中的 aspiration。无监督学习领域许多研究关注机器学习系统的表征学习能力;我们则把研究零样本迁移,当作衡量机器学习系统任务学习能力的一种方式。在这一视角下,数据集评估的是某个分布上某个任务的表现。然而,许多流行的计算机视觉数据集主要由研究社区创建,用作引导通用图像分类方法发展的基准,而非衡量特定任务。可以说 SVHN 数据集衡量的是 Google Street View 照片分布上的门牌号转写任务,但 CIFAR-10 衡量的“真实”任务并不清楚。清楚的是 CIFAR-10 来自 TinyImages(Torralba 等 2008)这一分布。在这类数据集上,零样本迁移更多是在评估 CLIP 对分布偏移与域泛化的稳健性,而非任务泛化。聚焦于此的分析见第 3.3 节。
To our knowledge, Visual N-Grams (Li et al. 2017) first studied zero-shot transfer to existing image classification datasets in the manner described above. It is also the only other work we are aware of that has studied zero-shot transfer to standard image classification datasets using a generically pre-trained model and serves as the best reference point for contextualizing CLIP. Their approach learns the parameters of a dictionary of 142,806 visual n-grams (spanning 1- to 5- grams) and optimizes these n-grams using a differential version of Jelinek-Mercer smoothing to maximize the probability of all text n-grams for a given image. In order to perform zero-shot transfer, they first convert the text of each of the dataset’s class names into its n-gram representation and then compute its probability according to their model, predicting the one with the highest score.
据我们所知,Visual N-Grams(Li 等 2017)最早以上述方式研究向现有图像分类数据集的零样本迁移。它也是我们所知道的、唯一用通用预训练模型研究向标准图像分类数据集零样本迁移的其他工作,是定位 CLIP 的最好参照。他们的方法学习包含 142806 个视觉 n-gram(跨 1 到 5-gram)的词典参数,并用 Jelinek-Mercer 平滑的可微版本优化这些 n-gram,以最大化给定图像所有文本 n-gram 的概率。做零样本迁移时,他们先把数据集各类别名转成 n-gram 表示,再按模型计算概率,预测得分最高者。
Our focus on studying zero-shot transfer as an evaluation of task learning is inspired by work demonstrating task learning in the field of NLP. To our knowledge Liu et al. 2018 first identified task learning as an “unexpected side-effect” when a language model trained to generate Wikipedia articles learned to reliably transliterate names between languages. While GPT-1 (Radford et al. 2018) focused on pre-training as a transfer learning method to improve supervised fine-tuning, it also included an ablation study demonstrating that the performance of four heuristic zero-shot transfer methods improved steadily over the course of pre-training, without any supervised adaption. This analysis served as the basis for GPT-2 (Radford et al. 2019) which focused exclusively on studying the task-learning capabilities of language models via zero-shot transfer.
我们把零样本迁移作为任务学习评估的关注点,受到 NLP 领域展示任务学习的工作启发。据我们所知,Liu 等 2018 首次把任务学习识别为“意外副作用”:训练生成维基百科文章的语言模型学会了在语言间可靠地音译姓名。GPT-1(Radford 等 2018)关注把预训练作为改进监督微调的迁移学习方法,但也包含消融:四种启发式零样本迁移方法的性能在预训练过程中稳步提升,无需任何监督适配。这一分析成为 GPT-2(Radford 等 2019)的基础,后者专门通过零样本迁移研究语言模型的任务学习能力。
3.1.2 Using CLIP for Zero-Shot Transfer
3.1.2 用 CLIP 做零样本迁移
CLIP is pre-trained to predict if an image and a text snippet are paired together in its dataset. To perform zero-shot classification, we reuse this capability. For each dataset, we use the names of all the classes in the dataset as the set of potential text pairings and predict the most probable (image, text) pair according to CLIP. In a bit more detail, we first compute the feature embedding of the image and the feature embedding of the set of possible texts by their respective encoders. The cosine similarity of these embeddings is then calculated, scaled by a temperature parameter , and normalized into a probability distribution via a softmax. Note that this prediction layer is a multinomial logistic regression classifier with L2-normalized inputs, L2-normalized weights, no bias, and temperature scaling. When interpreted this way, the image encoder is the computer vision backbone which computes a feature representation for the image and the text encoder is a hypernetwork (Ha et al. 2016) which generates the weights of a linear classifier based on the text specifying the visual concepts that the classes represent. Lei Ba et al. 2015 first introduced a zero-shot image classifier of this form while the idea of generating a classifier from natural language dates back to at least Elhoseiny et al. 2013. Continuing with this interpretation, every step of CLIP pre-training can be viewed as optimizing the performance of a randomly created proxy to a computer vision dataset which contains 1 example per class and has 32,768 total classes defined via natural language descriptions. For zero-shot evaluation, we cache the zero-shot classifier once it has been computed by the text encoder and reuse it for all subsequent predictions. This allows the cost of generating it to be amortized across all the predictions in a dataset.
CLIP 预训练目标是预测图像与文本片段是否在数据集中配对。做零样本分类时,我们复用这一能力。对每个数据集,把数据集中所有类别名称当作潜在文本配对集合,按 CLIP 预测最可能的(图像,文本)对。更细一点:先分别用图像编码器与文本编码器计算图像特征嵌入与各候选文本的特征嵌入,再算这些嵌入的余弦相似度,用温度参数 缩放,经 softmax 归一成概率分布。注意该预测层是带 L2 归一化输入、L2 归一化权重、无偏置并做温度缩放的多项逻辑回归分类器。按此解释,图像编码器是计算图像特征表征的计算机视觉骨干,文本编码器是超网络(Ha 等 2016),根据描述各类别所代表视觉概念的文本生成线性分类器权重。Lei Ba 等 2015 首次引入这种形式的零样本图像分类器,而从自然语言生成分类器的想法至少可追溯到 Elhoseiny 等 2013。继续这一解释,CLIP 预训练的每一步都可以看作在优化一个随机创建的计算机视觉数据集代理的性能:每类 1 个样本,共 32768 个经由自然语言描述定义的类别。零样本评估时,文本编码器算出零样本分类器后我们将其缓存,并在后续所有预测中复用,从而把生成成本摊销到数据集全部预测上。
3.1.3 Initial Comparison to Visual N-Grams
3.1.3 与 Visual N-Grams 的初步比较
| aYahoo | ImageNet | SUN | |
|---|---|---|---|
| Visual N-Grams | 72.4 | 11.5 | 23.0 |
| CLIP | 98.4 | 76.2 | 58.5 |
Table 1: Comparing CLIP to prior zero-shot transfer image classification results. CLIP improves performance on all three datasets by a large amount. This improvement reflects many differences in the 4 years since the development of Visual N-Grams (Li et al. 2017).
| aYahoo | ImageNet | SUN | |
|---|---|---|---|
| Visual N-Grams | 72.4 | 11.5 | 23.0 |
| CLIP | 98.4 | 76.2 | 58.5 |
表 1:CLIP 与先前零样本迁移图像分类结果的比较。CLIP 在三个数据集上都大幅提升。这一提升反映了 Visual N-Grams(Li 等 2017)提出四年以来的诸多差异。
In Table 1 we compare Visual N-Grams to CLIP. The best CLIP model improves accuracy on ImageNet from a proof of concept 11.5% to 76.2% and matches the performance of the original ResNet-50 despite using none of the 1.28 million crowd-labeled training examples available for this dataset. Additionally, the top-5 accuracy of CLIP models are noticeably higher than their top-1, and this model has a 95% top-5 accuracy, matching Inception-V4 (Szegedy et al. 2016). The ability to match the performance of a strong, fully supervised baselines in a zero-shot setting suggests CLIP is a significant step towards flexible and practical zero-shot computer vision classifiers. As mentioned above, the comparison to Visual N-Grams is meant for contextualizing the performance of CLIP and should not be interpreted as a direct methods comparison between CLIP and Visual N-Grams as many performance relevant differences between the two systems were not controlled for. For instance, we train on a dataset that is 10x larger, use a vision model that requires nearly 100x more compute per prediction, likely used over 1000x their training compute, and use a transformer-based model which did not exist when Visual N-Grams was published. As a closer comparison, we trained a CLIP ResNet-50 on the same YFCC100M dataset that Visual N-Grams was trained on and found it matched their reported ImageNet performance within a V100 GPU day. This baseline was also trained from scratch instead of being initialized from pre-trained ImageNet weights as in Visual N-Grams.
表 1 比较 Visual N-Grams 与 CLIP。最好的 CLIP 模型把 ImageNet 精度从概念验证水平的 11.5% 提升到 76.2%,并在完全不使用该数据集上 128 万众包标注训练样本的情况下,达到原始 ResNet-50 的性能。此外,CLIP 的 top-5 精度明显高于 top-1,该模型 top-5 精度为 95%,与 Inception-V4(Szegedy 等 2016)持平。在零样本设定下匹配强完全监督基线,表明 CLIP 朝灵活、实用的零样本计算机视觉分类器迈出了重要一步。如上所述,与 Visual N-Grams 的比较意在定位 CLIP 的表现,不应被解读为 CLIP 与 Visual N-Grams 的直接方法比较,因为许多与性能相关的差异并未控制。例如,我们的训练数据大约大 10 倍,视觉模型每次预测所需算力接近他们的 100 倍,训练算力很可能超过他们 1000 倍,并使用了 Visual N-Grams 发表时还不存在的基于 Transformer 的模型。作为更接近的比较,我们在 Visual N-Grams 所用的同一 YFCC100M 数据集上训练了 CLIP ResNet-50,发现在一个 V100 GPU 天内即可匹配他们报告的 ImageNet 性能。该基线也是从头训练,而非像 Visual N-Grams 那样从预训练 ImageNet 权重初始化。
CLIP also outperforms Visual N-Grams on the other 2 reported datasets. On aYahoo, CLIP achieves a 95% reduction in the number of errors, and on SUN, CLIP more than doubles the accuracy of Visual N-Grams. To conduct a more comprehensive analysis and stress test, we implement a much larger evaluation suite detailed in Appendix A. In total we expand from the 3 datasets reported in Visual N-Grams to include over 30 datasets and compare to over 50 existing computer vision systems to contextualize results.
CLIP 在另外两个报告的数据集上也超过 Visual N-Grams。在 aYahoo 上,CLIP 把错误数减少 95%;在 SUN 上,CLIP 的精度超过 Visual N-Grams 的两倍。为做更全面的分析与压力测试,我们实现了附录 A 详述的更大评测套件。总计从 Visual N-Grams 报告的 3 个数据集扩展到超过 30 个数据集,并与超过 50 个现有计算机视觉系统比较以定位结果。
3.1.4 Prompt Engineering and Ensembling
3.1.4 提示工程与集成
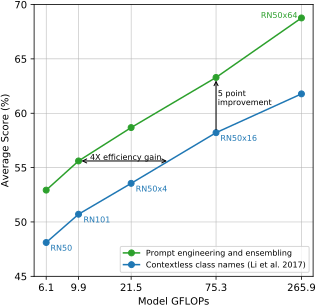
Figure 4: Prompt engineering and ensembling improve zero-shot performance. Compared to the baseline of using contextless class names, prompt engineering and ensembling boost zero-shot classification performance by almost 5 points on average across 36 datasets. This improvement is similar to the gain from using 4 times more compute with the baseline zero-shot method but is “free” when amortized over many predictions.
图 4:提示工程与集成改善零样本性能。 相对使用无上下文类别名的基线,提示工程与集成在 36 个数据集上平均把零样本分类性能提高近 5 个点。这一改进与基线零样本方法使用 4 倍算力带来的收益相近,但在摊销到许多预测上时是“免费”的。
Most standard image classification datasets treat the information naming or describing classes which enables natural language based zero-shot transfer as an afterthought. The vast majority of datasets annotate images with just a numeric id of the label and contain a file mapping these ids back to their names in English. Some datasets, such as Flowers102 and GTSRB, don’t appear to include this mapping at all in their released versions preventing zero-shot transfer entirely.[^2] For many datasets, we observed these labels may be chosen somewhat haphazardly and do not anticipate issues related to zero-shot transfer which relies on task description in order to transfer successfully.
大多数标准图像分类数据集把命名或描述类别、从而支持基于自然语言的零样本迁移的信息当作事后补充。绝大多数数据集只用标签的数字 id 标注图像,并另有文件把这些 id 映射回英语名称。有些数据集如 Flowers102 与 GTSRB,发布版本中似乎根本不包含该映射,从而完全无法做零样本迁移。[^2] 对许多数据集,我们观察到这些标签可能选得比较随意,并未预见到与零样本迁移相关的问题——零样本迁移依赖任务描述才能成功迁移。
A common issue is polysemy. When the name of a class is the only information provided to CLIP’s text encoder it is unable to differentiate which word sense is meant due to the lack of context. In some cases multiple meanings of the same word might be included as different classes in the same dataset! This happens in ImageNet which contains both construction cranes and cranes that fly. Another example is found in classes of the Oxford-IIIT Pet dataset where the word boxer is, from context, clearly referring to a breed of dog, but to a text encoder lacking context could just as likely refer to a type of athlete.
一个常见问题是一词多义。当提供给 CLIP 文本编码器的唯一信息是类别名时,因缺乏上下文,它无法区分所指的是哪个词义。有时同一词的多种含义还会作为不同类别出现在同一数据集中!ImageNet 里既有建筑起重机(crane)也有会飞的鹤(crane)。另一个例子在 Oxford-IIIT Pet 数据集:从上下文看 boxer 显然指狗的品种,但对缺乏上下文的文本编码器来说,同样可能指一类运动员。
Another issue we encountered is that it’s relatively rare in our pre-training dataset for the text paired with the image to be just a single word. Usually the text is a full sentence describing the image in some way. To help bridge this distribution gap, we found that using the prompt template “A photo of a {label}.” to be a good default that helps specify the text is about the content of the image. This often improves performance over the baseline of using only the label text. For instance, just using this prompt improves accuracy on ImageNet by 1.3%.
我们遇到的另一问题是:预训练数据中,与图像配对的文本很少只是单个词,通常是以某种方式描述图像的完整句子。为弥合这一分布差距,我们发现使用提示模板 “A photo of a {label}.” 是不错的默认,有助于指明文本是关于图像内容的。这往往比只用标签文本的基线更好。例如,仅用该提示就把 ImageNet 精度提高 1.3%。
Similar to the “prompt engineering” discussion around GPT-3 (Brown et al. 2020; Gao et al. 2020), we have also observed that zero-shot performance can be significantly improved by customizing the prompt text to each task. A few, non exhaustive, examples follow. We found on several fine-grained image classification datasets that it helped to specify the category. For example on Oxford-IIIT Pets, using “A photo of a {label}, a type of pet.” to help provide context worked well. Likewise, on Food101 specifying a type of food and on FGVC Aircraft a type of aircraft helped too. For OCR datasets, we found that putting quotes around the text or number to be recognized improved performance. Finally, we found that on satellite image classification datasets it helped to specify that the images were of this form and we use variants of “a satellite photo of a {label}.”.
与围绕 GPT-3 的“提示工程”讨论类似(Brown 等 2020;Gao 等 2020),我们也观察到:针对各任务定制提示文本,能显著改善零样本性能。下面举几个非穷尽的例子。在若干细粒度图像分类数据集上,指明类别范畴有帮助。例如在 Oxford-IIIT Pets 上,使用 “A photo of a {label}, a type of pet.” 提供上下文效果很好。同样,在 Food101 上指明 a type of food、在 FGVC Aircraft 上指明 a type of aircraft 也有帮助。对 OCR 数据集,我们发现给要识别的文本或数字加引号能提升性能。最后,在卫星图像分类数据集上,指明图像属于这类形式有帮助,我们使用 “a satellite photo of a {label}.” 的变体。
We also experimented with ensembling over multiple zero-shot classifiers as another way of improving performance. These classifiers are computed by using different context prompts such as ‘A photo of a big {label}” and “A photo of a small {label}”. We construct the ensemble over the embedding space instead of probability space. This allows us to cache a single set of averaged text embeddings so that the compute cost of the ensemble is the same as using a single classifier when amortized over many predictions. We’ve observed ensembling across many generated zero-shot classifiers to reliably improve performance and use it for the majority of datasets. On ImageNet, we ensemble 80 different context prompts and this improves performance by an additional 3.5% over the single default prompt discussed above. When considered together, prompt engineering and ensembling improve ImageNet accuracy by almost 5%. In Figure 4 we visualize how prompt engineering and ensembling change the performance of a set of CLIP models compared to the contextless baseline approach of directly embedding the class name as done in Li et al. 2017.
我们还实验了对多个零样本分类器做集成,作为另一提升性能的方式。这些分类器通过不同上下文提示计算,例如 “A photo of a big {label}” 与 “A photo of a small {label}”。我们在嵌入空间而非概率空间上构造集成。这样可以缓存一组平均后的文本嵌入,使集成的计算成本在摊销到许多预测时与使用单个分类器相同。我们观察到,跨许多生成的零样本分类器做集成能可靠提升性能,并在多数数据集上使用。在 ImageNet 上,我们集成 80 种不同上下文提示,相对上文讨论的单一默认提示再提升 3.5%。合在一起,提示工程与集成把 ImageNet 精度提高近 5%。图 4 可视化了相对 Li 等 2017 中直接嵌入类别名的无上下文基线,提示工程与集成如何改变一组 CLIP 模型的性能。
3.1.5 Analysis of Zero-Shot CLIP Performance
3.1.5 零样本 CLIP 性能分析
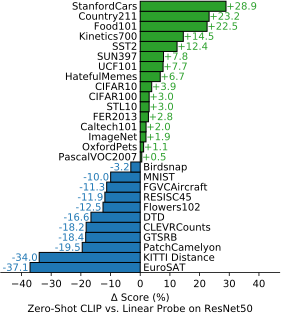
Figure 5: Zero-shot CLIP is competitive with a fully supervised baseline. Across a 27 dataset eval suite, a zero-shot CLIP classifier outperforms a fully supervised linear classifier fitted on ResNet-50 features on 16 datasets, including ImageNet.
图 5:零样本 CLIP 可与完全监督基线竞争。 在 27 个数据集的评测套件上,零样本 CLIP 分类器在包括 ImageNet 在内的 16 个数据集上超过拟合在 ResNet-50 特征上的完全监督线性分类器。
Since task-agnostic zero-shot classifiers for computer vision have been understudied, CLIP provides a promising opportunity to gain a better understanding of this type of model. In this section, we conduct a study of various properties of CLIP’s zero-shot classifiers. As a first question, we look simply at how well zero-shot classifiers perform. To contextualize this, we compare to the performance of a simple off-the-shelf baseline: fitting a fully supervised, regularized, logistic regression classifier on the features of the canonical ResNet-50. In Figure 5 we show this comparison across 27 datasets. Please see Appendix A for details of datasets and setup.
由于计算机视觉中与任务无关的零样本分类器研究不足,CLIP 提供了更好理解这类模型的有希望机会。本节研究 CLIP 零样本分类器的多种性质。第一个问题很简单:零样本分类器表现如何。为定位这一点,我们与一个现成基线比较:在经典 ResNet-50 特征上拟合完全监督、带正则的逻辑回归分类器。图 5 展示了跨 27 个数据集的比较。数据集与设置细节见附录 A。
Zero-shot CLIP outperforms this baseline slightly more often than not and wins on 16 of the 27 datasets. Looking at individual datasets reveals some interesting behavior. On fine-grained classification tasks, we observe a wide spread in performance. On two of these datasets, Stanford Cars and Food101, zero-shot CLIP outperforms logistic regression on ResNet-50 features by over 20% while on two others, Flowers102 and FGVCAircraft, zero-shot CLIP underperforms by over 10%. On OxfordPets and Birdsnap, performance is much closer. We suspect these difference are primarily due to varying amounts of per-task supervision between WIT and ImageNet. On “general” object classification datasets such as ImageNet, CIFAR10/100, STL10, and PascalVOC2007 performance is relatively similar with a slight advantage for zero-shot CLIP in all cases. On STL10, CLIP achieves 99.3% overall which appears to be a new state of the art despite not using any training examples. Zero-shot CLIP significantly outperforms a ResNet-50 on two datasets measuring action recognition in videos. On Kinetics700, CLIP outperforms a ResNet-50 by 14.5%. Zero-shot CLIP also outperforms a ResNet-50’s features by 7.7% on UCF101. We speculate this is due to natural language providing wider supervision for visual concepts involving verbs, compared to the noun-centric object supervision in ImageNet.
零样本 CLIP 略多于半数地超过该基线,在 27 个数据集中赢下 16 个。看单个数据集能发现有趣行为。在细粒度分类任务上,性能分散很大。在 Stanford Cars 与 Food101 上,零样本 CLIP 比 ResNet-50 特征上的逻辑回归高 20% 以上;在 Flowers102 与 FGVCAircraft 上则低 10% 以上。OxfordPets 与 Birdsnap 上更接近。我们怀疑这些差异主要来自 WIT 与 ImageNet 之间各任务监督分量不同。在 ImageNet、CIFAR10/100、STL10、PascalVOC2007 等“一般”物体分类数据集上,性能相对接近,零样本 CLIP 均略占优。在 STL10 上,CLIP 总体达到 99.3%,尽管未使用任何训练样本,似乎已是新的最优。在两个衡量视频动作识别的数据集上,零样本 CLIP 显著超过 ResNet-50:Kinetics700 上高 14.5%,UCF101 上比 ResNet-50 特征高 7.7%。我们推测这是因为相对 ImageNet 以名词为中心的物体监督,自然语言为涉及动词的视觉概念提供了更宽的监督。
Looking at where zero-shot CLIP notably underperforms, we see that zero-shot CLIP is quite weak on several specialized, complex, or abstract tasks such as satellite image classification (EuroSAT and RESISC45), lymph node tumor detection (PatchCamelyon), counting objects in synthetic scenes (CLEVRCounts), self-driving related tasks such as German traffic sign recognition (GTSRB), recognizing distance to the nearest car (KITTI Distance). These results highlight the poor capability of zero-shot CLIP on more complex tasks. By contrast, non-expert humans can robustly perform several of these tasks, such as counting, satellite image classification, and traffic sign recognition, suggesting significant room for improvement. However, we caution that it is unclear whether measuring zero-shot transfer, as opposed to few-shot transfer, is a meaningful evaluation for difficult tasks that a learner has no prior experience with, such as lymph node tumor classification for almost all humans (and possibly CLIP).
看零样本 CLIP 明显偏弱之处:在若干专门、复杂或抽象任务上相当弱,例如卫星图像分类(EuroSAT 与 RESISC45)、淋巴结肿瘤检测(PatchCamelyon)、合成场景中数物体(CLEVRCounts),以及自动驾驶相关任务如德国交通标志识别(GTSRB)、识别到最近车辆的距离(KITTI Distance)。这些结果凸显零样本 CLIP 在更复杂任务上的能力不足。相比之下,非专家人类能稳健完成其中多项,如计数、卫星图像分类与交通标志识别,说明仍有很大改进空间。不过我们提醒:对学习者几乎没有先验经验的困难任务(如几乎所有人类以及可能还有 CLIP 的淋巴结肿瘤分类),衡量零样本迁移而非少样本迁移是否有意义,尚不清楚。
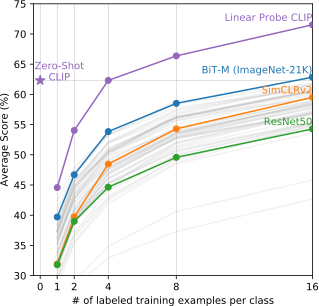
Figure 6: Zero-shot CLIP outperforms few-shot linear probes. Zero-shot CLIP matches the average performance of a 4-shot linear classifier trained on the same feature space and nearly matches the best results of a 16-shot linear classifier across publicly available models. For both BiT-M and SimCLRv2, the best performing model is highlighted. Light gray lines are other models in the eval suite. The 20 datasets with at least 16 examples per class were used in this analysis.
图 6:零样本 CLIP 超过少样本线性探测。 零样本 CLIP 匹配在同一特征空间上训练的 4-shot 线性分类器的平均性能,并几乎匹配公开模型中 16-shot 线性分类器的最好结果。BiT-M 与 SimCLRv2 均标出表现最好的模型。浅灰线为评测套件中其他模型。本分析使用至少每类 16 个样本的 20 个数据集。
While comparing zero-shot performance to fully supervised models contextualizes the task-learning capabilities of CLIP, comparing to few-shot methods is a more direct comparison, since zero-shot is its limit. In Figure 6, we visualize how zero-shot CLIP compares to few-shot logistic regression on the features of many image models including the best publicly available ImageNet models, self-supervised learning methods, and CLIP itself. While it is intuitive to expect zero-shot to underperform one-shot, we instead find that zero-shot CLIP matches the performance of 4-shot logistic regression on the same feature space. This is likely due to an important difference between the zero-shot and few-shot approach. First, CLIP’s zero-shot classifier is generated via natural language which allows for visual concepts to be directly specified (“communicated”). By contrast, “normal” supervised learning must infer concepts indirectly from training examples. Context-less example-based learning has the drawback that many different hypotheses can be consistent with the data, especially in the one-shot case. A single image often contains many different visual concepts. Although a capable learner is able to exploit visual cues and heuristics, such as assuming that the concept being demonstrated is the primary object in an image, there is no guarantee.
把零样本性能与完全监督模型比较,能定位 CLIP 的任务学习能力;与少样本方法比较则更直接,因为零样本是其极限。图 6 可视化零样本 CLIP 与许多图像模型特征上少样本逻辑回归的比较,包括公开最好的 ImageNet 模型、自监督方法以及 CLIP 自身。直觉上预期零样本会弱于 one-shot,我们却发现零样本 CLIP 匹配同一特征空间上 4-shot 逻辑回归的性能。这很可能源于零样本与少样本方法的重要差别。首先,CLIP 的零样本分类器由自然语言生成,可直接指定(“传达”)视觉概念;而“普通”监督学习必须从训练样本间接推断概念。无上下文的基于样例学习有个缺点:许多不同假设都可能与数据一致,尤其在 one-shot 情形。单张图像常含多种视觉概念。有能力的学习者虽能利用视觉线索与启发式(例如假定被演示的概念是图中主物体),但并无保证。
A potential resolution of this discrepancy between zero-shot and few-shot performance is to use CLIP’s zero-shot classifier as a prior for the weights of the few-shot classifier. While adding an L2 penalty towards the generated weights is a straightforward implementation of this idea, we found that hyperparameter optimization would often select for such a large value of this regularizer that the resulting few-shot classifier was “just” the zero-shot classifier. Research into better methods of combining the strength of zero-shot transfer with flexibility of few-shot learning is a promising direction for future work.
化解零样本与少样本性能差异的一种可能办法,是把 CLIP 的零样本分类器当作少样本分类器权重的先验。朝生成权重加 L2 惩罚是该想法的直接实现,但我们发现超参数优化常选出很大的正则系数,以致所得少样本分类器“就是”零样本分类器。研究更好结合零样本迁移优势与少样本学习灵活性的方法,是有希望的未来方向。
When comparing zero-shot CLIP to few-shot logistic regression on the features of other models, zero-shot CLIP roughly matches the performance of the best performing 16-shot classifier in our evaluation suite, which uses the features of a BiT-M ResNet-152x2 trained on ImageNet-21K. We are certain that a BiT-L model trained on JFT-300M would perform even better but these models have not been publicly released. That a BiT-M ResNet-152x2 performs best in a 16-shot setting is somewhat surprising since, as analyzed in Section 3.2, the Noisy Student EfficientNet-L2 outperforms it in a fully supervised setting by almost 5% on average across 27 datasets.
把零样本 CLIP 与其他模型特征上的少样本逻辑回归比较时,零样本 CLIP 大致匹配我们评测套件中表现最好的 16-shot 分类器,后者使用在 ImageNet-21K 上训练的 BiT-M ResNet-152x2 的特征。我们确信在 JFT-300M 上训练的 BiT-L 会更好,但这些模型尚未公开。BiT-M ResNet-152x2 在 16-shot 设定下表现最好多少有些令人惊讶,因为如第 3.2 节所分析,Noisy Student EfficientNet-L2 在完全监督设定下跨 27 个数据集平均超过它近 5%。
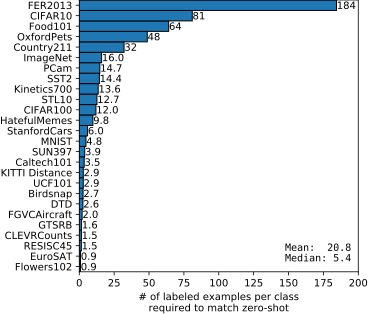
Figure 7: The data efficiency of zero-shot transfer varies widely. Calculating the number of labeled examples per class a linear classifier on the same CLIP feature space requires to match the performance of the zero-shot classifier contextualizes the effectiveness of zero-shot transfer. Values are estimated based on log-linear interpolation of 1, 2, 4, 8, 16-shot and fully supervised results. Performance varies widely from still underperforming a one-shot classifier on two datasets to matching an estimated 184 labeled examples per class.
图 7:零样本迁移的数据效率变化很大。 计算同一 CLIP 特征空间上的线性分类器需要每类多少标注样本才能匹配零样本分类器,可定位零样本迁移的有效性。数值基于 1、2、4、8、16-shot 与完全监督结果的对数线性插值估计。表现差异很大:在两个数据集上仍弱于 one-shot 分类器,在另一端则匹配估计每类 184 个标注样本。
In addition to studying the average performance of zero-shot CLIP and few-shot logistic regression, we also examine performance on individual datasets. In Figure 7, we show estimates for the number of labeled examples per class that a logistic regression classifier on the same feature space requires to match the performance of zero-shot CLIP. Since zero-shot CLIP is also a linear classifier, this estimates the effective data efficiency of zero-shot transfer in this setting. In order to avoid training thousands of linear classifiers, we estimate the effective data efficiency based on a log-linear interpolation of the performance of a 1, 2, 4, 8, 16-shot (when possible), and a fully supervised linear classifier trained on each dataset. We find that zero-shot transfer can have widely varying efficiency per dataset from less than 1 labeled example per class to 184. Two datasets, Flowers102 and EuroSAT underperform one-shot models. Half of the datasets require less than 5 examples per class with a median of 5.4. However, the mean estimated data efficiency is 20.8 examples per class. This is due to the 20% of datasets where supervised classifiers require many labeled examples per class in order to match performance. On ImageNet, zero-shot CLIP matches the performance of a 16-shot linear classifier trained on the same feature space.
除研究零样本 CLIP 与少样本逻辑回归的平均性能外,我们还考察各数据集。图 7 给出同一特征空间上逻辑回归分类器为匹配零样本 CLIP 所需的每类标注样本数估计。由于零样本 CLIP 也是线性分类器,这估计了该设定下零样本迁移的有效数据效率。为避免训练数千个线性分类器,我们基于各数据集上 1、2、4、8、16-shot(若可能)以及完全监督线性分类器性能的对数线性插值来估计。我们发现零样本迁移的效率因数据集差异很大,从每类不足 1 个标注样本到 184 个。Flowers102 与 EuroSAT 两个数据集弱于 one-shot 模型。一半数据集每类所需样本少于 5,中位数为 5.4。但估计的平均数据效率为每类 20.8 个样本,原因是约 20% 的数据集上监督分类器需要很多标注才能追上。在 ImageNet 上,零样本 CLIP 匹配同一特征空间上 16-shot 线性分类器的性能。
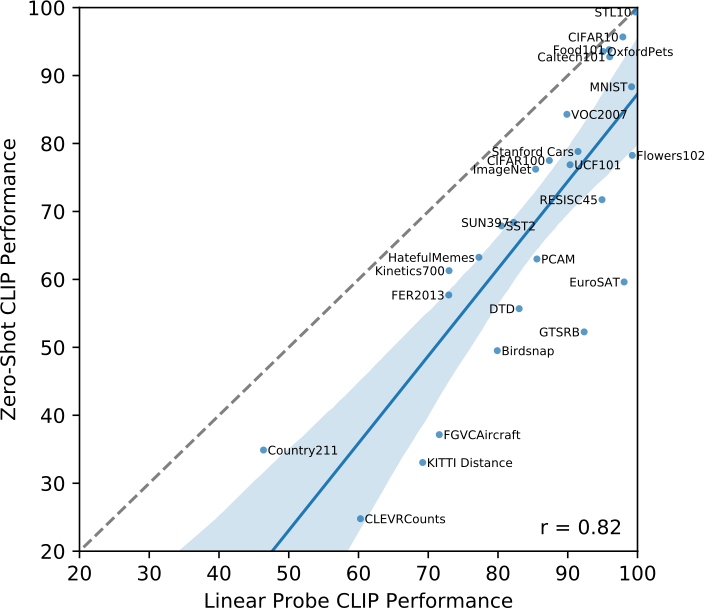
Figure 8: Zero-shot performance is correlated with linear probe performance but still mostly sub-optimal. Comparing zero-shot and linear probe performance across datasets shows a strong correlation with zero-shot performance mostly shifted 10 to 25 points lower. On only 5 datasets does zero-shot performance approach linear probe performance (3 point difference).
图 8:零样本性能与线性探测性能相关,但仍多半次优。 跨数据集比较零样本与线性探测性能显示强相关,零样本性能大多低 10 到 25 个点。仅在 5 个数据集上零样本接近线性探测(3 点差距)。
If we assume that evaluation datasets are large enough that the parameters of linear classifiers trained on them are well estimated, then, because CLIP’s zero-shot classifier is also a linear classifier, the performance of the fully supervised classifiers roughly sets an upper bound for what zero-shot transfer can achieve. In Figure 8 we compare CLIP’s zero-shot performance with fully supervised linear classifiers across datasets. The dashed, line represents an “optimal” zero-shot classifier that matches the performance of its fully supervised equivalent. For most datasets, the performance of zero-shot classifiers still underperform fully supervised classifiers by 10% to 25%, suggesting that there is still plenty of headroom for improving CLIP’s task-learning and zero-shot transfer capabilities.
若假定评测数据集足够大、其上训练的线性分类器参数已良好估计,则因 CLIP 的零样本分类器也是线性分类器,完全监督分类器的性能大致为零样本迁移可达到的上界。图 8 跨数据集比较 CLIP 的零样本性能与完全监督线性分类器。虚线 表示匹配其完全监督等价物的“最优”零样本分类器。对多数数据集,零样本分类器仍比完全监督低 10% 到 25%,说明 CLIP 的任务学习与零样本迁移能力仍有很大提升空间。
There is a positive correlation of 0.82 (p-value ) between zero-shot performance and fully supervised performance, suggesting that CLIP is relatively consistent at connecting underlying representation and task learning to zero-shot transfer. However, zero-shot CLIP only approaches fully supervised performance on 5 datasets: STL10, CIFAR10, Food101, OxfordPets, and Caltech101. On all 5 datasets, both zero-shot accuracy and fully supervised accuracy are over 90%. This suggests that CLIP may be more effective at zero-shot transfer for tasks where its underlying representations are also high quality. The slope of a linear regression model predicting zero-shot performance as a function of fully supervised performance estimates that for every 1% improvement in fully supervised performance, zero-shot performance improves by 1.28%. However, the 95th-percentile confidence intervals still include values of less than 1 (0.93-1.79).
零样本性能与完全监督性能之间有 0.82 的正相关(p 值 ),表明 CLIP 在把底层表征与任务学习连接到零样本迁移上相对一致。然而零样本 CLIP 仅在 5 个数据集上接近完全监督性能:STL10、CIFAR10、Food101、OxfordPets 与 Caltech101。这 5 个数据集上零样本与完全监督精度都超过 90%。这提示 CLIP 可能在底层表征也高质量的任务上更擅长零样本迁移。用完全监督性能预测零样本性能的线性回归斜率估计:完全监督每提高 1%,零样本提高 1.28%。但第 95 百分位置信区间仍包含小于 1 的值(0.93–1.79)。
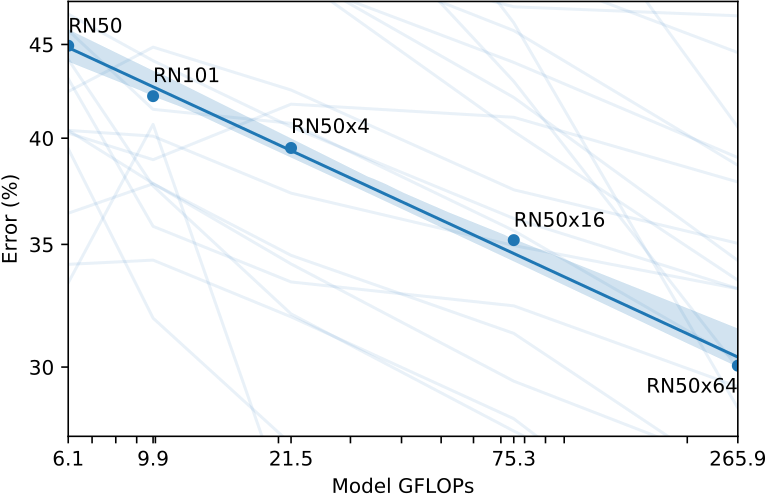
Figure 9: Zero-shot CLIP performance scales smoothly as a function of model compute. Across 39 evals on 36 different datasets, average zero-shot error is well modeled by a log-log linear trend across a 44x range of compute spanning 5 different CLIP models. Lightly shaded lines are performance on individual evals, showing that performance is much more varied despite the smooth overall trend.
图 9:零样本 CLIP 性能随模型算力平滑扩展。 在 36 个不同数据集上的 39 项评测中,平均零样本误差在横跨 5 个不同 CLIP 模型、44 倍算力范围内可由对数–对数线性趋势良好刻画。浅色线为单项评测性能,表明尽管总体趋势平滑,单项表现变异大得多。
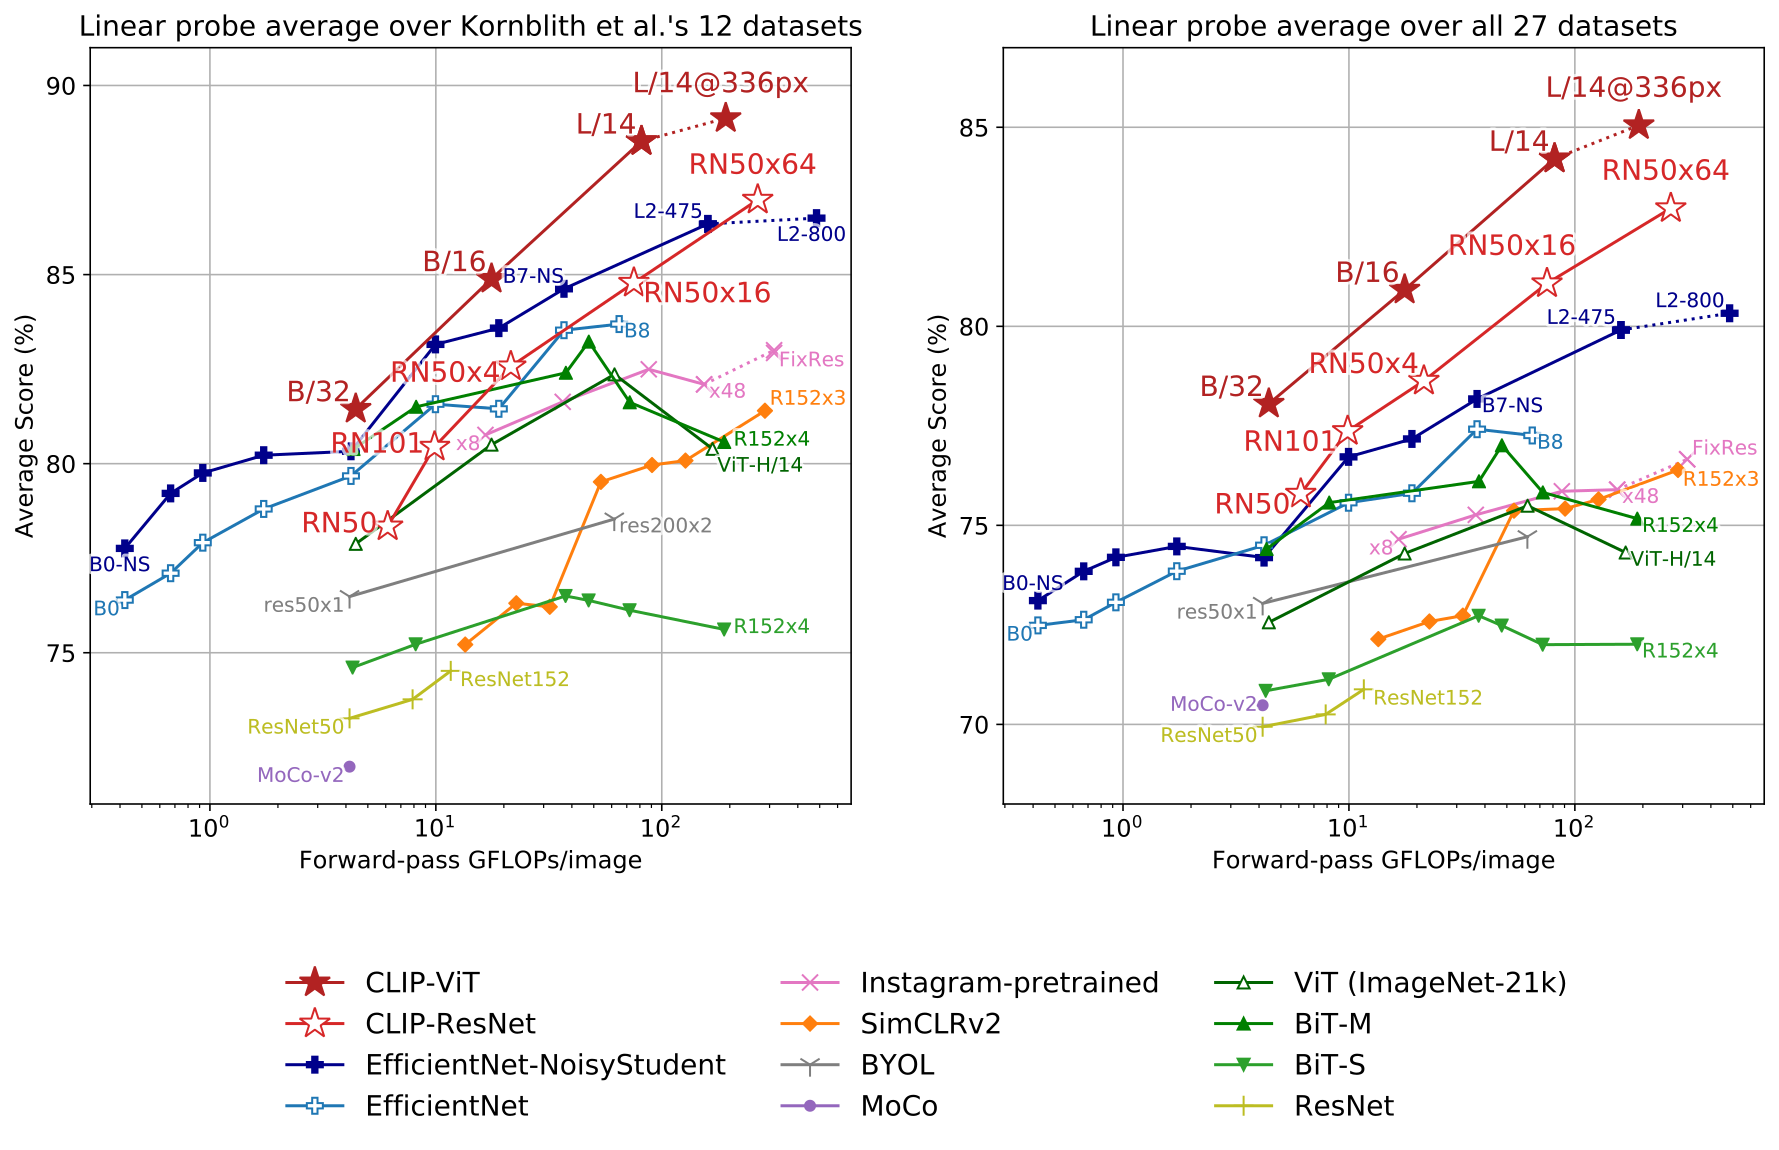
Figure 10: Linear probe performance of CLIP models in comparison with state-of-the-art computer vision models, including EfficientNet (Tan & Le 2019; Xie et al. 2020), MoCo (Chen et al. 2020d), Instagram-pretrained ResNeXt models (Mahajan et al. 2018; Touvron et al. 2019), BiT (Kolesnikov et al. 2019), ViT (Dosovitskiy et al. 2020), SimCLRv2 (Chen et al. 2020c), BYOL (Grill et al. 2020), and the original ResNet models (He et al. 2016b). (Left) Scores are averaged over 12 datasets studied by Kornblith et al. 2019. (Right) Scores are averaged over 27 datasets that contain a wider variety of distributions. Dotted lines indicate models fine-tuned or evaluated on images at a higher-resolution than pre-training. See Table 10 for individual scores and Figure 20 for plots for each dataset.
图 10:CLIP 模型的线性探测性能与当前最优计算机视觉模型的比较,包括 EfficientNet(Tan & Le 2019;Xie 等 2020)、MoCo(Chen 等 2020d)、Instagram 预训练 ResNeXt(Mahajan 等 2018;Touvron 等 2019)、BiT(Kolesnikov 等 2019)、ViT(Dosovitskiy 等 2020)、SimCLRv2(Chen 等 2020c)、BYOL(Grill 等 2020)以及原始 ResNet(He 等 2016b)。(左)分数对 Kornblith 等 2019 研究的 12 个数据集取平均。(右)分数对分布更广的 27 个数据集取平均。虚线表示在高于预训练分辨率的图像上微调或评估的模型。各数据集分数见表 10,图见 图 20。
Over the past few years, empirical studies of deep learning systems have documented that performance is predictable as a function of important quantities such as training compute and dataset size (Hestness et al. 2017; Kaplan et al. 2020). The GPT family of models has so far demonstrated consistent improvements in zero-shot performance across a 1000x increase in training compute. In Figure 9, we check whether the zero-shot performance of CLIP follows a similar scaling pattern. We plot the average error rate of the 5 ResNet CLIP models across 39 evaluations on 36 different datasets and find that a similar log-log linear scaling trend holds for CLIP across a 44x increase in model compute. While the overall trend is smooth, we found that performance on individual evaluations can be much noisier. We are unsure whether this is caused by high variance between individual training runs on sub-tasks (as documented in D’Amour et al. 2020) masking a steadily improving trend or whether performance is actually non-monotonic as a function of compute on some tasks.
过去几年,深度学习系统的经验研究表明,性能可作为训练算力与数据集规模等重要量的函数被预测(Hestness 等 2017;Kaplan 等 2020)。GPT 模型家族迄今已在训练算力增大 1000 倍的过程中展示出零样本性能的持续提升。图 9 检查 CLIP 的零样本性能是否遵循类似扩展规律。我们画出 5 个 ResNet CLIP 模型在 36 个数据集、39 项评测上的平均错误率,发现在模型算力增大 44 倍时,CLIP 也呈现类似的对数–对数线性扩展趋势。总体趋势虽平滑,我们发现单项评测的性能噪声大得多。不确定这是由子任务上各次训练运行的高方差(如 D’Amour 等 2020 所记录)掩盖了稳步改善的趋势,还是在某些任务上性能作为算力的函数实际上非单调。
3.2 Representation Learning
3.2 表征学习
While we have extensively analyzed the task-learning capabilities of CLIP through zero-shot transfer in the previous section, it is more common to study the representation learning capabilities of a model. There exist many ways to evaluate the quality of representations as well as disagreements over what properties an “ideal” representation should have (Locatello et al. 2020). Fitting a linear classifier on a representation extracted from the model and measuring its performance on various datasets is a common approach. An alternative is measuring the performance of end-to-end fine-tuning of the model. This increases flexibility, and prior work has convincingly demonstrated that fine-tuning outperforms linear classification on most image classification datasets (Kornblith et al. 2019; Zhai et al. 2019). While the high performance of fine-tuning motivates its study for practical reasons, we still opt for linear classifier based evaluation for several reasons. Our work is focused on developing a high-performing task and dataset-agnostic pre-training approach. Fine-tuning, because it adapts representations to each dataset during the fine-tuning phase, can compensate for and potentially mask failures to learn general and robust representations during the pre-training phase. Linear classifiers, because of their limited flexibility, instead highlight these failures and provide clear feedback during development. For CLIP, training supervised linear classifiers has the added benefit of being very similar to the approach used for its zero-shot classifiers which enables extensive comparisons and analysis in Section 3.1. Finally, we aim to compare CLIP to a comprehensive set of existing models across many tasks. Studying 66 different models on 27 different datasets requires tuning 1782 different evaluations. Fine-tuning opens up a much larger design and hyper-parameter space, which makes it difficult to fairly evaluate and computationally expensive to compare a diverse set of techniques as discussed in other large scale empirical studies (Lucic et al. 2018; Choi et al. 2019). By comparison, linear classifiers require minimal hyper-parameter tuning and have standardized implementations and evaluation procedures. Please see Appendix A for further details on evaluation.
上一节我们通过零样本迁移广泛分析了 CLIP 的任务学习能力,更常见的是研究模型的表征学习能力。评估表征质量的方式很多,对“理想”表征应有何种性质也存在分歧(Locatello 等 2020)。在模型提取的表征上拟合线性分类器并在各数据集上测性能是常见做法。另一选择是衡量模型端到端微调的性能。这增加了灵活性,先前工作已有力表明在多数图像分类数据集上微调超过线性分类(Kornblith 等 2019;Zhai 等 2019)。尽管微调的高性能出于实用理由值得研究,我们仍选择基于线性分类器的评估,原因如下。本工作关注开发高性能、与任务和数据集无关的预训练方法。微调会在微调阶段把表征适配到各数据集,可能补偿甚至掩盖预训练阶段未能学到通用稳健表征的失败。线性分类器因灵活性有限,反而会凸显这些失败,并在开发中提供清晰反馈。对 CLIP 而言,训练监督线性分类器还有额外好处:与其零样本分类器所用方法非常相似,便于在第 3.1 节做广泛比较与分析。最后,我们旨在跨许多任务把 CLIP 与全面的一组现有模型比较。在 27 个数据集上研究 66 个不同模型需要调 1782 次不同评估。微调打开大得多的设计与超参数空间,使公平评估困难、计算昂贵,其他大规模经验研究也讨论过这一点(Lucic 等 2018;Choi 等 2019)。相比之下,线性分类器只需最少超参数调优,并有标准化实现与评估流程。评估细节见附录 A。
Figure 10 summarizes our findings. To minimize selection effects that could raise concerns of confirmation or reporting bias, we first study performance on the 12 dataset evaluation suite from Kornblith et al. 2019. While small CLIP models such as a ResNet-50 and ResNet-101 outperform other ResNets trained on ImageNet-1K (BiT-S and the originals), they underperform ResNets trained on ImageNet-21K (BiT-M). These small CLIP models also underperform models in the EfficientNet family with similar compute requirements. However, models trained with CLIP scale very well and the largest model we trained (ResNet-50x64) slightly outperforms the best performing existing model (a Noisy Student EfficientNet-L2) on both overall score and compute efficiency. We also find that CLIP vision transformers are about 3x more compute efficient than CLIP ResNets, which allows us to reach higher overall performance within our compute budget. These results qualitatively replicate the findings of Dosovitskiy et al. 2020 which reported that vision transformers are more compute efficient than convnets when trained on sufficiently large datasets. Our best overall model is a ViT-L/14 that is fine-tuned at a higher resolution of 336 pixels on our dataset for 1 additional epoch. This model outperforms the best existing model across this evaluation suite by an average of 2.6%.
图 10 总结了我们的发现。为尽量减少可能引发确认或报告偏倚担忧的选择效应,我们先在 Kornblith 等 2019 的 12 数据集评测套件上研究性能。小型 CLIP 模型如 ResNet-50 与 ResNet-101 超过在 ImageNet-1K 上训练的其他 ResNet(BiT-S 与原版),但弱于在 ImageNet-21K 上训练的 ResNet(BiT-M)。这些小 CLIP 模型也弱于算力相近的 EfficientNet 家族。然而用 CLIP 训练的模型扩展性很好,我们训练的最大模型(ResNet-50x64)在总分与算力效率上略超过此前最好模型(Noisy Student EfficientNet-L2)。我们还发现 CLIP 的 Vision Transformer 算力效率约为 CLIP ResNet 的 3 倍,使我们能在算力预算内达到更高总体性能。这些结果定性复现了 Dosovitskiy 等 2020 的发现:在足够大的数据集上训练时,Vision Transformer 比卷积网络更算力高效。总体最好的模型是在我们数据集上以更高 336 像素分辨率再微调 1 个周期的 ViT-L/14。该模型在该评测套件上平均超过此前最好模型 2.6%。
As Figure 21 qualitatively shows, CLIP models learn a wider set of tasks than has previously been demonstrated in a single computer vision model trained end-to-end from random initialization. These tasks include geo-localization, optical character recognition, facial emotion recognition, and action recognition. None of these tasks are measured in the evaluation suite of Kornblith et al. 2019. This could be argued to be a form of selection bias in Kornblith et al. 2019’s study towards tasks that overlap with ImageNet. To address this, we also measure performance on a broader 27 dataset evaluation suite. This evaluation suite, detailed in Appendix A includes datasets representing the aforementioned tasks, German Traffic Signs Recognition Benchmark (Stallkamp et al. 2011), as well as several other datasets adapted from VTAB (Zhai et al. 2019).
如图 21 定性所示,CLIP 模型学到的任务集合,比此前在从随机初始化端到端训练的单一计算机视觉模型中展示的更广,包括地理定位、光学字符识别、面部情绪识别与动作识别。这些任务都不在 Kornblith 等 2019 的评测套件中测量。可以说这是该研究朝与 ImageNet 重叠任务的一种选择偏倚。为此,我们也在更广的 27 数据集评测套件上测性能。该套件详见附录 A,包含代表上述任务的数据集、德国交通标志识别基准(Stallkamp 等 2011),以及若干改编自 VTAB(Zhai 等 2019)的其他数据集。
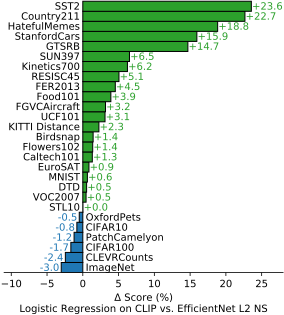
Figure 11: CLIP’s features outperform the features of the best ImageNet model on a wide variety of datasets. Fitting a linear classifier on CLIP’s features outperforms using the Noisy Student EfficientNet-L2 on 21 out of 27 datasets.
图 11:CLIP 的特征在多种数据集上超过最好 ImageNet 模型的特征。 在 CLIP 特征上拟合线性分类器,在 27 个数据集中的 21 个上超过使用 Noisy Student EfficientNet-L2。
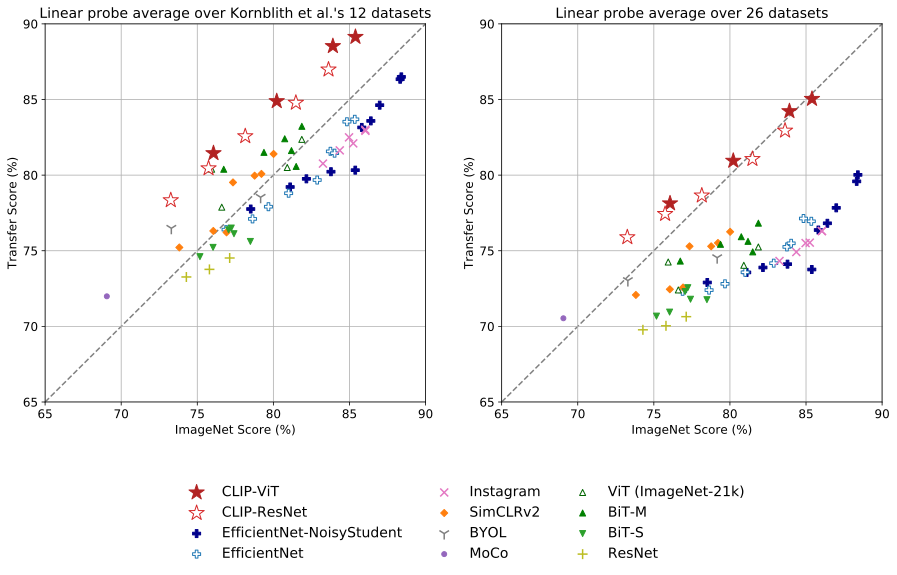
Figure 12: CLIP’s features are more robust to task shift when compared to models pre-trained on ImageNet. For both dataset splits, the transfer scores of linear probes trained on the representations of CLIP models are higher than other models with similar ImageNet performance. This suggests that the representations of models trained on ImageNet are somewhat overfit to their task.
图 12:相对在 ImageNet 上预训练的模型,CLIP 的特征对任务偏移更稳健。 在两个数据划分上,基于 CLIP 模型表征训练的线性探测迁移分数,高于 ImageNet 性能相近的其他模型。这表明在 ImageNet 上训练的模型表征在一定程度上过拟合到了其任务。
On this broader evaluation suite, the benefits of CLIP are more clear. All CLIP models, regardless of scale, outperform all evaluated systems in terms of compute efficiency. The improvement in average score of the best model over previous systems increases from 2.6% to 5%. We also find that self-supervised systems do noticeably better on our broader evaluation suite. For instance, while SimCLRv2 still underperforms BiT-M on average on the 12 datasets of Kornblith et al. 2019, SimCLRv2 outperforms BiT-M on our 27 dataset evaluation suite. These findings suggest continuing to expand task diversity and coverage in order to better understand the “general” performance of systems. We suspect additional evaluation efforts along the lines of VTAB to be valuable.
在这一更广的评测套件上,CLIP 的优势更清晰。无论规模如何,所有 CLIP 模型在算力效率上都超过所有被评估系统。最好模型相对先前系统的平均分提升从 2.6% 增至 5%。我们还发现自监督系统在更广套件上明显更好。例如,SimCLRv2 在 Kornblith 等 2019 的 12 个数据集上平均仍弱于 BiT-M,但在我们的 27 数据集套件上超过 BiT-M。这些发现提示应继续扩展任务多样性与覆盖,以更好理解系统的“通用”性能。我们怀疑沿 VTAB 方向的额外评估努力会有价值。
In addition to the aggregate analysis above, we visualize per-dataset differences in the performance of the best CLIP model and the best model in our evaluation suite across all 27 datasets in Figure 11. CLIP outperforms the Noisy Student EfficientNet-L2 on 21 of the 27 datasets. CLIP improves the most on tasks which require OCR (SST2 and HatefulMemes), geo-localization and scene recognition (Country211, SUN397), and activity recognition in videos (Kinetics700 and UCF101). In addition CLIP also does much better on fine-grained car and traffic sign recognition (Stanford Cars and GTSRB). This may reflect a problem with overly narrow supervision in ImageNet. A result such as the 14.7% improvement on GTSRB could be indicative of an issue with ImageNet-1K, which has only a single label for all traffic and street signs. This could encourage a supervised representation to collapse intra-class details and hurt accuracy on a fine-grained downstream task. As mentioned, CLIP still underperforms the EfficientNet on several datasets. Unsurprisingly, the dataset that the EfficientNet does best relative to CLIP on is the one it was trained on: ImageNet. The EffcientNet also slightly outperforms CLIP on low-resolution datasets such as CIFAR10 and CIFAR100. We suspect this is at least partly due to the lack of scale-based data augmentation in CLIP. The EfficientNet also does slightly better on PatchCamelyon and CLEVRCounts, datasets where overall performance is still low for both approaches.
除上述汇总分析外,图 11 可视化最好 CLIP 模型与评测套件中最好模型在全部 27 个数据集上的逐数据集差异。CLIP 在 27 个中的 21 个上超过 Noisy Student EfficientNet-L2。CLIP 提升最大的是需要 OCR 的任务(SST2 与 HatefulMemes)、地理定位与场景识别(Country211、SUN397),以及视频中的活动识别(Kinetics700 与 UCF101)。此外 CLIP 在细粒度汽车与交通标志识别(Stanford Cars 与 GTSRB)上也好得多。这可能反映 ImageNet 监督过窄的问题。例如在 GTSRB 上提高 14.7%,可能提示 ImageNet-1K 的问题——它对所有交通与街道标志只有单一标签,可能鼓励监督表征折叠类内细节,从而伤害细粒度下游任务精度。如前所述,CLIP 在若干数据集上仍弱于 EfficientNet。毫不奇怪,EfficientNet 相对 CLIP 最好的数据集正是它训练所用的 ImageNet。EfficientNet 在 CIFAR10 与 CIFAR100 等低分辨率数据集上也略超过 CLIP。我们怀疑至少部分因为 CLIP 缺乏基于尺度的数据增强。EfficientNet 在 PatchCamelyon 与 CLEVRCounts 上也略好,这两个数据集上两种方法的总体性能仍偏低。
3.3 Robustness to Natural Distribution Shift
3.3 对自然分布偏移的稳健性
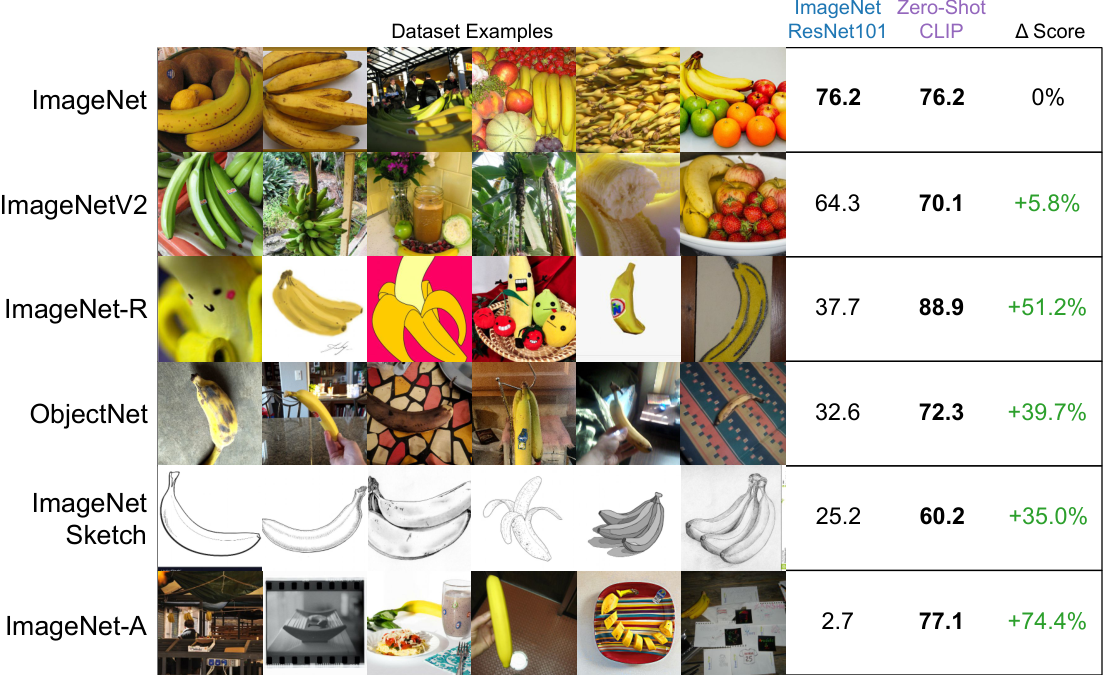
Figure 13: Zero-shot CLIP is much more robust to distribution shift than standard ImageNet models. (Left) An ideal robust model (dashed line) performs equally well on the ImageNet distribution and on other natural image distributions. Zero-shot CLIP models shrink this “robustness gap” by up to 75%. Linear fits on logit transformed values are shown with bootstrap estimated 95% confidence intervals. (Right) Visualizing distribution shift for bananas, a class shared across 5 of the 7 natural distribution shift datasets. The performance of the best zero-shot CLIP model, ViT-L/14@336px, is compared with a model that has the same performance on the ImageNet validation set, ResNet-101.
图 13:相对标准 ImageNet 模型,零样本 CLIP 对分布偏移稳健得多。(左)理想稳健模型(虚线)在 ImageNet 分布与其他自然图像分布上表现同样好。零样本 CLIP 模型把这一“稳健性差距”缩小最多 75%。对 logit 变换后的值做线性拟合,并给出自助法估计的 95% 置信区间。(右)对香蕉这一在 7 个自然分布偏移数据集中的 5 个上共有的类别,可视化分布偏移。最好的零样本 CLIP 模型 ViT-L/14@336px 与在 ImageNet 验证集上性能相同的 ResNet-101 相比较。
In 2015, it was announced that a deep learning model exceeded human performance on the ImageNet test set (He et al. 2015). However, research in the subsequent years has repeatedly found that these models still make many simple mistakes (Dodge & Karam 2017; Geirhos et al. 2018; Alcorn et al. 2019), and new benchmarks testing these systems has often found their performance to be much lower than both their ImageNet accuracy and human accuracy (Recht et al. 2019; Barbu et al. 2019). What explains this discrepancy? Various ideas have been suggested and studied (Ilyas et al. 2019; Geirhos et al. 2020). A common theme of proposed explanations is that deep learning models are exceedingly adept at finding correlations and patterns which hold across their training dataset and thus improve in-distribution performance. However many of these correlations and patterns are actually spurious and do not hold for other distributions and result in large drops in performance on other datasets.
2015 年有宣布称深度学习模型在 ImageNet 测试集上超过人类表现(He 等 2015)。然而随后数年研究反复发现这些模型仍会犯许多简单错误(Dodge & Karam 2017;Geirhos 等 2018;Alcorn 等 2019),测试这些系统的新基准也常发现其性能远低于其 ImageNet 精度与人类精度(Recht 等 2019;Barbu 等 2019)。如何解释这一落差?已有多种想法被提出与研究(Ilyas 等 2019;Geirhos 等 2020)。常见主题是:深度学习模型极擅长发现在其训练数据上成立、从而提升分布内性能的相关与模式;但其中许多其实是虚假的,在其他分布上不成立,导致在其他数据集上性能大幅下降。
We caution that, to date, most of these studies limit their evaluation to models trained on ImageNet. Recalling the topic of discussion, it may be a mistake to generalize too far from these initial findings. To what degree are these failures attributable to deep learning, ImageNet, or some combination of the two? CLIP models, which are trained via natural language supervision on a very large dataset and are capable of high zero-shot performance, are an opportunity to investigate this question from a different angle.
我们提醒:迄今多数此类研究把评估限于在 ImageNet 上训练的模型。回到讨论主题,从这些初步发现推得过远可能是错的。这些失败在多大程度上应归因于深度学习、ImageNet,或二者的某种组合?CLIP 模型在很大的数据集上经自然语言监督训练,并具备很高的零样本性能,提供了从另一角度探究该问题的机会。
Taori et al. 2020 is a recent comprehensive study moving towards quantifying and understanding these behaviors for ImageNet models. Taori et al. 2020 study how the performance of ImageNet models change when evaluated on natural distribution shifts. They measure performance on a set of 7 distribution shifts: ImageNetV2 (Recht et al. 2019), ImageNet Sketch (Wang et al. 2019), Youtube-BB and ImageNet-Vid (Shankar et al. 2019), ObjectNet (Barbu et al. 2019), ImageNet Adversarial (Hendrycks et al. 2019), and ImageNet Rendition (Hendrycks et al. 2020a). They distinguish these datasets, which all consist of novel images collected from a variety of sources, from synthetic distribution shifts such as ImageNet-C (Hendrycks & Dietterich 2019), Stylized ImageNet (Geirhos et al. 2018), or adversarial attacks (Goodfellow et al. 2014) which are created by perturbing existing images in various ways. They propose this distinction because in part because they find that while several techniques have been demonstrated to improve performance on synthetic distribution shifts, they often fail to yield consistent improvements on natural distributions.[^3]
Taori 等 2020 是近期朝向量化并理解 ImageNet 模型这些行为的全面研究。他们研究 ImageNet 模型在评估自然分布偏移时性能如何变化,测量了 7 种分布偏移:ImageNetV2(Recht 等 2019)、ImageNet Sketch(Wang 等 2019)、Youtube-BB 与 ImageNet-Vid(Shankar 等 2019)、ObjectNet(Barbu 等 2019)、ImageNet Adversarial(Hendrycks 等 2019)以及 ImageNet Rendition(Hendrycks 等 2020a)。他们把这些均由多种来源新采集图像组成的数据集,与合成分布偏移区分开,后者如 ImageNet-C(Hendrycks & Dietterich 2019)、Stylized ImageNet(Geirhos 等 2018)或对抗攻击(Goodfellow 等 2014),通过对现有图像做各种扰动创建。提出这一区分,部分是因为他们发现:虽有若干技术被证明能改善合成分布偏移上的性能,却往往无法在自然分布上带来一致改进。[^3]
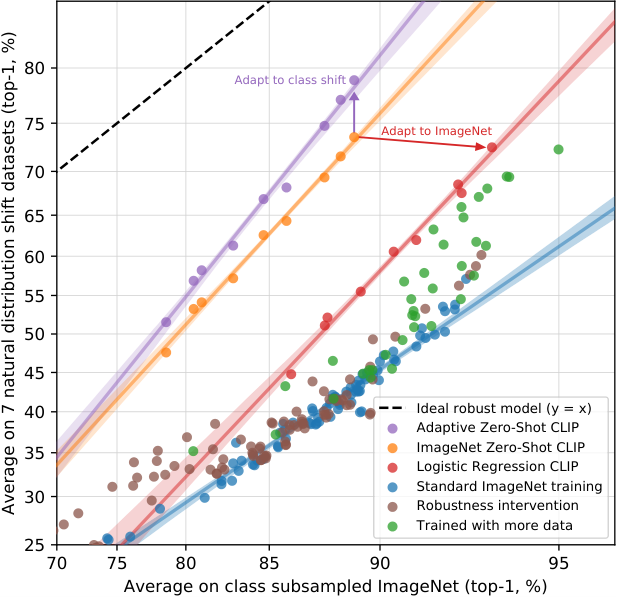
Figure 14: While supervised adaptation to ImageNet increases ImageNet accuracy by 9.2%, it slightly reduces average robustness. (Left) Customizing zero-shot CLIP to each dataset improves robustness compared to using a single static zero-shot ImageNet classifier and pooling predictions across similar classes as in Taori et al. 2020. CLIP models adapted to ImageNet have similar effective robustness as the best prior ImageNet models. (Right) Details of per dataset changes in accuracy for the two robustness interventions. Adapting to ImageNet increases accuracy on ImageNetV2 noticeably but trades off accuracy on several other distributions. Dataset specific zero-shot classifiers can improve accuracy by a large amount but are limited to only a few datasets that include classes which don’t perfectly align with ImageNet categories.
图 14:尽管监督适配到 ImageNet 使 ImageNet 精度提高 9.2%,却略微降低平均稳健性。(左)相对像 Taori 等 2020 那样使用单一静态零样本 ImageNet 分类器并在相似类别上池化预测,为各数据集定制零样本 CLIP 可改善稳健性。适配到 ImageNet 的 CLIP 模型有效稳健性与此前最好 ImageNet 模型相近。(右)两种稳健性干预在各数据集上精度变化的细节。适配到 ImageNet 明显提高 ImageNetV2 精度,但在若干其他分布上牺牲精度。数据集特定的零样本分类器能大幅提高精度,但仅限于少数类别与 ImageNet 类别不完全对齐的数据集。
Across these collected datasets, the accuracy of ImageNet models drop well below the expectation set by the ImageNet validation set. For the following summary discussion we report average accuracy across all 7 natural distribution shift datasets and average accuracy across the corresponding class subsets of ImageNet unless otherwise specified. Additionally, for Youtube-BB and ImageNet-Vid, which have two different evaluation settings, we use the average of pm-0 and pm-10 accuracy.
在这些收集的数据集上,ImageNet 模型的精度远低于 ImageNet 验证集所设定的预期。下文汇总讨论中,除非另有说明,我们报告全部 7 个自然分布偏移数据集上的平均精度,以及 ImageNet 对应类别子集上的平均精度。此外,对有两种评估设置的 Youtube-BB 与 ImageNet-Vid,我们使用 pm-0 与 pm-10 精度的平均。
A ResNet-101 makes 5 times as many mistakes when evaluated on these natural distribution shifts compared to the ImageNet validation set. Encouragingly however, Taori et al. 2020 find that accuracy under distribution shift increases predictably with ImageNet accuracy and is well modeled as a linear function of logit-transformed accuracy. Taori et al. 2020 use this finding to propose that robustness analysis should distinguish between effective and relative robustness. Effective robustness measures improvements in accuracy under distribution shift above what is predicted by the documented relationship between in-distribution and out-of-distribution accuracy. Relative robustness captures any improvement in out-of-distribution accuracy. Taori et al. 2020 argue that robustness techniques should aim to improve both effective robustness and relative robustness.
ResNet-101 在这些自然分布偏移上评估时犯的错误,是 ImageNet 验证集上的 5 倍。不过令人鼓舞的是,Taori 等 2020 发现分布偏移下的精度随 ImageNet 精度可预测地提高,并可建模为 logit 变换精度的线性函数。他们据此提出稳健性分析应区分有效稳健性与相对稳健性。有效稳健性衡量分布偏移下的精度提升中,超出由分布内与分布外精度已知关系所预测的部分。相对稳健性捕获分布外精度的任何提升。Taori 等 2020 主张稳健性技术应同时改善有效稳健性与相对稳健性。
Almost all models studied in Taori et al. 2020 are trained or fine-tuned on the ImageNet dataset. Returning to the discussion in the introduction to this section - is training or adapting to the ImageNet dataset distribution the cause of the observed robustness gap? Intuitively, a zero-shot model should not be able to exploit spurious correlations or patterns that hold only on a specific distribution, since it is not trained on that distribution. [^4] Thus it is reasonable to expect zero-shot models to have much higher effective robustness. In Figure 13, we compare the performance of zero-shot CLIP with existing ImageNet models on natural distribution shifts. All zero-shot CLIP models improve effective robustness by a large amount and reduce the size of the gap between ImageNet accuracy and accuracy under distribution shift by up to 75%.
Taori 等 2020 研究的几乎所有模型都在 ImageNet 数据集上训练或微调。回到本节引言的讨论——在 ImageNet 数据分布上训练或适配,是否造成了所观察到的稳健性差距?直觉上,零样本模型不应能利用仅在特定分布上成立的虚假相关或模式,因为它并未在该分布上训练。[^4] 因此有理由预期零样本模型有高得多的有效稳健性。图 13 比较零样本 CLIP 与现有 ImageNet 模型在自然分布偏移上的表现。所有零样本 CLIP 模型都大幅提高有效稳健性,并把 ImageNet 精度与分布偏移下精度之间的差距缩小最多 75%。
While these results show that zero-shot models can be much more robust, they do not necessarily mean that supervised learning on ImageNet causes a robustness gap. Other details of CLIP, such as its large and diverse pre-training dataset or use of natural language supervision could also result in much more robust models regardless of whether they are zero-shot or fine-tuned. As an initial experiment to potentially begin narrowing this down, we also measure how the performance of CLIP models change after adapting to the ImageNet distribution via a L2 regularized logistic regression classifier fit to CLIP features on the ImageNet training set. We visualize how performance changes from the zero-shot classifier in Figure 14. Although adapting CLIP to the ImageNet distribution increases its ImageNet accuracy by 9.2% to 85.4% overall, and ties the accuracy of the 2018 SOTA from Mahajan et al. 2018, average accuracy under distribution shift slightly decreases.
这些结果表明零样本模型可以稳健得多,但并不必然意味着在 ImageNet 上的监督学习造成了稳健性差距。CLIP 的其他细节,如大规模多样的预训练数据或使用自然语言监督,也可能无论零样本还是微调都带来稳健得多的模型。作为可能开始收窄这一点的初步实验,我们还测量:用在 ImageNet 训练集上拟合到 CLIP 特征的 L2 正则逻辑回归分类器适配到 ImageNet 分布后,CLIP 模型性能如何变化。图 14 可视化相对零样本分类器的性能变化。尽管把 CLIP 适配到 ImageNet 分布使其 ImageNet 精度提高 9.2% 至总体 85.4%,并追平 Mahajan 等 2018 的 2018 年 SOTA,分布偏移下的平均精度却略有下降。
It is surprising to see a 9.2% increase in accuracy, which corresponds to roughly 3 years of improvement in SOTA, fail to translate into any improvement in average performance under distribution shift. We also break down the differences between zero-shot accuracy and linear classifier accuracy per dataset in Figure 14 and find performance still increases significantly on one dataset, ImageNetV2. ImageNetV2 closely followed the creation process of the original ImageNet dataset which suggests that gains in accuracy from supervised adaptation are closely concentrated around the ImageNet distribution. Performance decreases by 4.7% on ImageNet-R, 3.8% on ObjectNet, 2.8% on ImageNet Sketch, and 1.9% on ImageNet-A. The change in accuracy on the two other datasets, Youtube-BB and ImageNet Vid, is insignificant.
看到对应大约 3 年 SOTA 进步的 9.2% 精度提升,却未能转化为分布偏移下平均性能的任何改善,令人惊讶。我们还在图 14 中按数据集拆解零样本精度与线性分类器精度的差异,发现仍只在一个数据集 ImageNetV2 上显著提高。ImageNetV2 紧密遵循原始 ImageNet 数据集的创建流程,提示监督适配带来的精度收益紧密集中在 ImageNet 分布附近。精度在 ImageNet-R 上下降 4.7%,ObjectNet 上 3.8%,ImageNet Sketch 上 2.8%,ImageNet-A 上 1.9%。另外两个数据集 Youtube-BB 与 ImageNet Vid 上的精度变化不显著。
How is it possible to improve accuracy by 9.2% on the ImageNet dataset with little to no increase in accuracy under distribution shift? Is the gain primarily from “exploiting spurious correlations”? Is this behavior unique to some combination of CLIP, the ImageNet datatset, and the distribution shifts studied, or a more general phenomena? Does it hold for end-to-end finetuning as well as linear classifiers? We do not have confident answers to these questions at this time. Prior work has also pre-trained models on distributions other than ImageNet, but it is common to study and release models only after they have been fine-tuned to ImageNet. As a step towards understanding whether pre-trained zero-shot models consistently have higher effective robustness than fine-tuned models, we encourage the authors of Mahajan et al. 2018, Kolesnikov et al. 2019, and Dosovitskiy et al. 2020 to, if possible, study these questions on their models as well.
如何能在 ImageNet 数据集上提高 9.2% 精度,却几乎不增加分布偏移下的精度?收益是否主要来自“利用虚假相关”?这种行为是 CLIP、ImageNet 数据集与所研究分布偏移的某种组合所特有,还是更一般的现象?对端到端微调与线性分类器是否都成立?此刻我们没有有把握的答案。先前工作也曾在 ImageNet 以外的分布上预训练模型,但常见做法是仅在微调到 ImageNet 之后才研究并发布模型。作为理解预训练零样本模型是否一贯比微调模型有更高有效稳健性的一步,我们鼓励 Mahajan 等 2018、Kolesnikov 等 2019 与 Dosovitskiy 等 2020 的作者若可能也在其模型上研究这些问题。
We also investigate another robustness intervention enabled by flexible zero-shot natural-language-based image classifiers. The target classes across the 7 transfer datasets are not always perfectly aligned with those of ImageNet. Two datasets, Youtube-BB and ImageNet-Vid, consist of super-classes of ImageNet. This presents a problem when trying to use the fixed 1000-way classifier of an ImageNet model to make predictions. Taori et al. 2020 handle this by max-pooling predictions across all sub-classes according to the ImageNet class hierarchy. Sometimes this mapping is much less than perfect. For the person class in Youtube-BB, predictions are made by pooling over the ImageNet classes for a baseball player, a bridegroom, and a scuba diver. With CLIP we can instead generate a custom zero-shot classifier for each dataset directly based on its class names. In Figure 14 we see that this improves average effective robustness by 5% but is concentrated in large improvements on only a few datasets. Curiously, accuracy on ObjectNet also increases by 2.3%. Although the dataset was designed to closely overlap with ImageNet classes, using the names provided for each class by ObjectNet’s creators still helps a small amount compared to using ImageNet class names and pooling predictions when necessary.
我们还研究由灵活的基于自然语言的零样本图像分类器所启用的另一种稳健性干预。7 个迁移数据集上的目标类别并不总与 ImageNet 完美对齐。Youtube-BB 与 ImageNet-Vid 两个数据集由 ImageNet 的超类组成。这给试图用 ImageNet 模型固定的 1000 路分类器做预测带来问题。Taori 等 2020 按 ImageNet 类别层级对所有子类预测做最大池化来处理。有时这种映射远称不上完美。对 Youtube-BB 中的 person 类,预测是通过对棒球运动员、新郎与潜水员等 ImageNet 类别池化做出的。有了 CLIP,我们可以直接基于各类别名称为每个数据集生成定制零样本分类器。图 14 显示这使平均有效稳健性提高 5%,但集中在仅少数数据集上的大幅提升。奇怪的是,ObjectNet 上精度也提高 2.3%。尽管该数据集设计为与 ImageNet 类别紧密重叠,使用 ObjectNet 创建者提供的各类别名称,相对使用 ImageNet 类别名并在必要时池化预测,仍有小幅帮助。
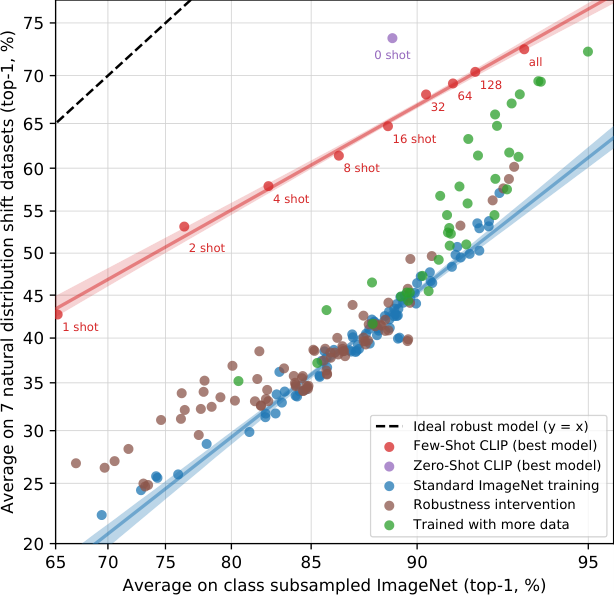
Figure 15: Few-shot CLIP also increases effective robustness compared to existing ImageNet models but is less robust than zero-shot CLIP. Minimizing the amount of ImageNet training data used for adaption increases effective robustness at the cost of decreasing relative robustness. 16-shot logistic regression CLIP matches zero-shot CLIP on ImageNet, as previously reported in Figure 7, but is less robust.
图 15:少样本 CLIP 相对现有 ImageNet 模型也提高有效稳健性,但不如零样本 CLIP 稳健。 尽量减少用于适配的 ImageNet 训练数据会提高有效稳健性,代价是降低相对稳健性。16-shot 逻辑回归 CLIP 在 ImageNet 上匹配零样本 CLIP(如图 7 先前报告),但稳健性更差。
While zero-shot CLIP improves effective robustness, Figure 14 shows that the benefit is almost entirely gone in a fully supervised setting. To better understand this difference, we investigate how effective robustness changes on the continuum from zero-shot to fully supervised. In Figure 15 we visualize the performance of 0-shot, 1-shot, 2-shot, 4-shot …, 128-shot, and fully supervised logistic regression classifiers on the best CLIP model’s features. We see that while few-shot models also show higher effective robustness than existing models, this benefit fades as in-distribution performance increases with more training data and is mostly, though not entirely, gone for the fully supervised model. Additionally, zero-shot CLIP is notably more robust than a few-shot model with equivalent ImageNet performance. Across our experiments, high effective robustness seems to result from minimizing the amount of distribution specific training data a model has access to, but this comes at a cost of reducing dataset-specific performance.
尽管零样本 CLIP 改善有效稳健性,图 14 显示在完全监督设定下这一好处几乎消失。为更好理解这一差异,我们研究有效稳健性在从零样本到完全监督的连续谱上如何变化。图 15 可视化最好 CLIP 模型特征上 0-shot、1-shot、2-shot、4-shot…、128-shot 以及完全监督逻辑回归分类器的性能。可以看到,少样本模型也比现有模型显示更高有效稳健性,但随着更多训练数据提高分布内性能,这一好处逐渐消退,对完全监督模型而言大部分(虽非全部)消失。此外,零样本 CLIP 明显比 ImageNet 性能相当的少样本模型更稳健。在我们的实验中,高有效稳健性似乎来自尽量减少模型可及的分布特定训练数据,但这以降低数据集特定性能为代价。
Taken together, these results suggest that the recent shift towards large-scale task and dataset agnostic pre-training combined with a reorientation towards zero-shot and few-shot benchmarking on broad evaluation suites (as advocated by Yogatama et al. 2019 and Linzen 2020) promotes the development of more robust systems and provides a more accurate assessment of performance. We are curious to see if the same results hold for zero-shot models in the field of NLP such as the GPT family. While Hendrycks et al. 2020b has reported that pre-training improves relative robustness on sentiment analysis, Miller et al. 2020’s study of the robustness of question answering models under natural distribution shift finds, similar to Taori et al. 2020, little evidence of effective robustness improvements to date.
综合来看,这些结果提示:近来朝向大规模、与任务和数据集无关的预训练,再结合在广泛评测套件上转向零样本与少样本基准(如 Yogatama 等 2019 与 Linzen 2020 所倡导),有助于发展更稳健的系统,并提供更准确的性能评估。我们好奇同一结果是否对 NLP 领域如 GPT 家族的零样本模型也成立。Hendrycks 等 2020b 报告预训练改善情感分析上的相对稳健性,而 Miller 等 2020 对问答模型在自然分布偏移下稳健性的研究则发现,与 Taori 等 2020 类似,迄今几乎没有有效稳健性改进的证据。
4 Comparison to Human Performance
4 与人类表现的比较
How does CLIP compare to human performance and human learning? To get a better understanding of how well humans perform in similar evaluation settings to CLIP, we evaluated humans on one of our tasks. We wanted to get a sense of how strong human zero-shot performance is at these tasks, and how much human performance is improved if they are shown one or two image samples. This can help us to compare task difficulty for humans and CLIP, and identify correlations and differences between them.
CLIP 与人类表现和人类学习相比如何?为了更好地理解人类在与 CLIP 类似的评估环境中的表现,我们对人类在我们的一个任务上进行了评估。我们希望了解人类在这些任务上的零样本表现有多强,以及如果向他们展示一到两个图像样本,人类的表现会有多大提高。这可以帮助我们比较人类和 CLIP 的任务难度,并识别它们之间的相关性和差异。
We had five different humans look at each of 3669 images in the test split of the Oxford IIT Pets dataset (Parkhi et al. 2012) and select which of the 37 cat or dog breeds best matched the image (or ‘I don’t know’ if they were completely uncertain). In the zero-shot case the humans were given no examples of the breeds and asked to label them to the best of their ability without an internet search. In the one-shot experiment the humans were given one sample image of each breed and in the two-shot experiment they were given two sample images of each breed.[^5]
我们让五名不同的人类查看牛津 IIT 宠物数据集(Parkhi 等,2012)测试集中 3669 张图像,并选择 37 种猫或狗品种中最匹配图像的一种(如果他们完全不确定,可以选择“我不知道”)。在零样本情况下,人类没有任何品种示例,并被要求在不进行互联网搜索的情况下尽力标注。在一例实验中,人类每个品种只获得一张示例图像,而在二例实验中,他们每个品种获得两张示例图像。[5]
| Accuracy | Majority Vote on Full Dataset | Accuracy on Guesses | Majority Vote Accuracy on Guesses | |
|---|---|---|---|---|
| Zero-shot human | 53.7 | 57.0 | 69.7 | 63.9 |
| Zero-shot CLIP | 93.5 | 93.5 | 93.5 | 93.5 |
| One-shot human | 75.7 | 80.3 | 78.5 | 81.2 |
| Two-shot human | 75.7 | 85.0 | 79.2 | 86.1 |
Table 2: Comparison of human performance on Oxford IIT Pets. As in Parkhi et al. 2012, the metric is average per-class classification accuracy. Most of the gain in performance when going from the human zero shot case to the human one shot case is on images that participants were highly uncertain on. “Guesses” refers to restricting the dataset to where participants selected an answer other than “I don’t know”, the “majority vote” is taking the most frequent (exclusive of ties) answer per image.
| 准确率 | 全数据集多数票 | 猜测准确率 | 猜测多数票准确率 | |
|---|---|---|---|---|
| 零样本人类 | 53.7 | 57.0 | 69.7 | 63.9 |
| 零样本 CLIP | 93.5 | 93.5 | 93.5 | 93.5 |
| 一样本人类 | 75.7 | 80.3 | 78.5 | 81.2 |
| 两样本人类 | 75.7 | 85.0 | 79.2 | 86.1 |
表2:牛津IIT宠物数据集上的人类表现比较。如同Parkhi等人2012年的方法,指标为每类平均分类准确率。从人类零样本情况到人类一样本情况的性能提升,大部分出现在参与者高度不确定的图像上。“猜测”是指将数据集限制在参与者选择了“我不知道”以外答案的情况,“多数票”是指每张图像选择最频繁(排除平局)的答案。
One possible concern was that the human workers were not sufficiently motivated in the zero-shot task. High human accuracy of 94% on the STL-10 dataset (Coates et al. 2011) and 97-100% accuracy on the subset of attention check images increased our trust in the human workers.
一个可能的担忧是,人类工人在零样本任务中没有足够的动力。在STL-10数据集(Coates 等,2011)上人类取得了94%的高准确率,以及在注意力检查图像子集上取得了97-100%的准确率,这增加了我们对人类工人的信任。
Interestingly, humans went from a performance average of 54% to 76% with just one training example per class, and the marginal gain from an additional training example is minimal. The gain in accuracy going from zero to one shot is almost entirely on images that humans were uncertain about. This suggests that humans “know what they don’t know” and are able to update their priors on the images they are most uncertain in based on a single example. Given this, it seems that while CLIP is a promising training strategy for zero-shot performance (Figure 5) and does well on tests of natural distribution shift (Figure 13), there is a large difference between how humans learn from a few examples and the few-shot methods in this paper.
有趣的是,人类的平均表现从54%提升到76%,仅仅使用每类一个训练样本,而增加额外训练样本的边际收益很小。从零样本到一次样本的准确率提升几乎完全出现在人类不确定的图像上。这表明人类“知道自己不知道什么”,能够基于单个示例更新他们对最不确定图像的先验知识。由此看来,尽管CLIP是一种对零样本表现有前景的训练策略(图5),在自然分布变化测试中表现良好(图13),但人类从少量样本学习的方式与本文中的少样本方法之间存在很大差异。
This suggests that there are still algorithmic improvements waiting to be made to decrease the gap between machine and human sample efficiency, as noted by Lake et al. 2016 and others. Because these few-shot evaluations of CLIP don’t make effective use of prior knowledge and the humans do, we speculate that finding a method to properly integrate prior knowledge into few-shot learning is an important step in algorithmic improvements to CLIP. To our knowledge, using a linear classifier on top of the features of a high-quality pre-trained model is near state-of-the-art for few shot learning (Tian et al. 2020), which suggests that there is a gap between the best few-shot machine learning methods and human few-shot learning.
这表明,如 Lake 等人(2016)及其他研究者指出的,仍然有算法改进的空间,可以缩小机器与人类在样本效率上的差距。由于这些 CLIP 的少样本评估没有有效利用先验知识,而人类会利用,我们推测找到一种将先验知识恰当地整合到少样本学习中的方法,是对 CLIP 算法改进的一个重要步骤。据我们所知,在高质量预训练模型的特征之上使用线性分类器,在少样本学习中几乎达到了最先进水平(Tian 等人,2020),这表明最佳少样本机器学习方法与人类少样本学习之间仍存在差距。
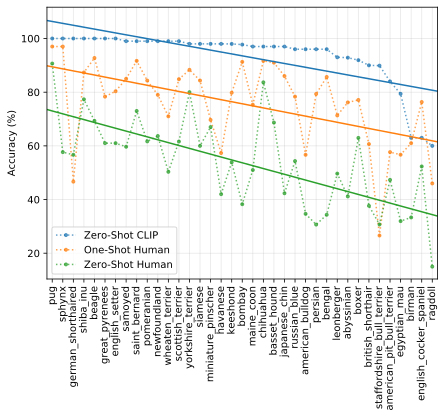
Figure 16: The hardest problems for CLIP also tend to be the hardest problems for humans. Here we rank image categories by difficulty for CLIP as measured as probability of the correct label.
图16:对于CLIP来说最难的问题也往往是人类最难的问题。这里我们按照CLIP的难度对图像类别进行排名,难度以正确标签的概率衡量。
If we plot human accuracy vs CLIP’s zero shot accuracy (Figure 16), we see that the hardest problems for CLIP are also hard for humans. To the extent that errors are consistent, our hypothesis is that this is due to at least a two factors: noise in the dataset (including mislabeled images) and out of distribution images being hard for both humans and models.
如果我们绘制人类准确率与 CLIP 的零样本准确率(图 16),我们会看到对 CLIP 来说最难的问题对人类来说也很难。在错误一致的程度上,我们的假设是,这是由于至少两个因素造成的:数据集中的噪声(包括标记错误的图像)以及分布外的图像对人类和模型都很难处理。
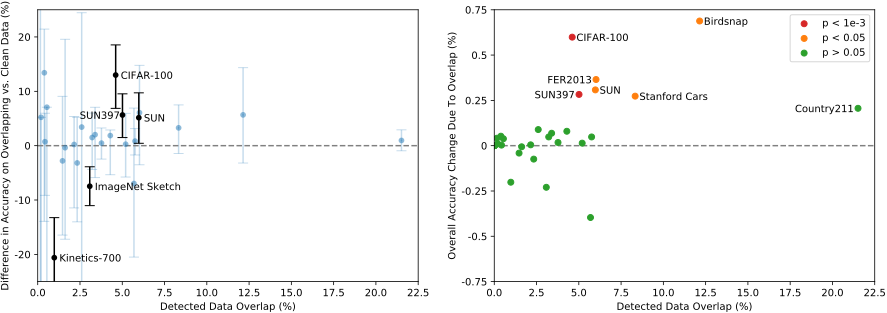
Figure 17: Few statistically significant improvements in accuracy due to detected data overlap. (Left) While several datasets have up to 20% apparent differences in zero-shot accuracy on detected overlapping vs clean examples only 5 datasets out of 35 total have 99.5% Clopper-Pearson confidence intervals that exclude a 0% accuracy difference. 2 of these datasets do worse on overlapping data. (Right) Since the percentage of detected overlapping examples is almost always in the single digits, the overall test accuracy gain due to overlap is much smaller with the largest estimated increase being only 0.6% on Birdsnap. Similarly, for only 6 datasets are the accuracy improvements statistically significant when calculated using a one-sided binomial test.
图17:由于检测到的数据重叠,准确率的统计显著改进很少。(左)虽然在检测到的重叠样本与干净样本上,零-shot准确率的表观差异高达±20%的数据集不在少数,但在总共35个数据集中,只有5个数据集的99.5% Clopper-Pearson置信区间排除了0%的准确率差异。其中2个数据集在重叠数据上的表现更差。(右)由于检测到的重叠样本比例几乎总是个位数,因此由于重叠导致的整体测试准确率提升要小得多,最大估计增幅仅在Birdsnap上达到0.6%。同样,只有6个数据集在使用单边二项检验计算时,准确率提升具有统计显著性。
5 Data Overlap Analysis
5 数据重叠分析
A concern with pre-training on a very large internet dataset is unintentional overlap with downstream evals. This is important to investigate since, in a worst-case scenario, a complete copy of an evaluation dataset could leak into the pre-training dataset and invalidate the evaluation as a meaningful test of generalization. One option to prevent this is to identify and remove all duplicates before training a model. While this guarantees reporting true hold-out performance, it requires knowing all possible data which a model might be evaluated on ahead of time. This has the downside of limiting the scope of benchmarking and analysis. Adding a new evaluation would require an expensive re-train or risk reporting an un-quantified benefit due to overlap.
在非常大的互联网数据集上进行预训练的一个问题是与下游评测的无意重叠。这很重要,因为在最坏的情况下,整个评测数据集可能会泄露到预训练数据集中,从而使评测失去作为泛化能力测试的意义。防止这种情况的一种方法是在训练模型之前识别并删除所有重复数据。虽然这可以保证报告真实的保留性能,但前提是需要提前知道模型可能被评测的所有数据。这的一个缺点是限制了基准测试和分析的范围。添加新的评测将需要昂贵的重新训练,或者冒着因重叠导致报告未量化收益的风险。
Instead, we document how much overlap occurs and how performance changes due to these overlaps. To do this, we use the following procedure:
相反,我们记录重叠发生的程度以及这些重叠导致性能的变化。为此,我们使用以下程序:
- For each evaluation dataset, we run a duplicate detector (see Appendix C) on its examples. We then manually inspect the found nearest neighbors and set a per dataset threshold to keep high precision while maximizing recall. Using this threshold, we then create two new subsets, Overlap, which contains all examples which have a similarity to a training example above the threshold, and Clean, which contains all examples that are below this threshold. We denote the unaltered full dataset All for reference. From this we first record the degree of data contamination as the ratio of the number of examples in Overlap to the size of All.
- 对于每个评估数据集,我们在其示例上运行重复检测器(见附录C)。然后我们手动检查找到的最近邻,并为每个数据集设置一个阈值,以在最大化召回率的同时保持高精度。使用该阈值,我们接着创建两个新的子集:Overlap,包含所有与训练示例的相似度高于该阈值的示例;Clean,包含所有低于该阈值的示例。为了参考,我们将未修改的完整数据集记为All。从中,我们首先记录数据污染的程度,即Overlap中示例数量与All大小的比率。
- We then compute the zero-shot accuracy of CLIP RN50x64 on the three splits and report All - Clean as our main metric. This is the difference in accuracy due to contamination. When positive it is our estimate of how much the overall reported accuracy on the dataset was inflated by over-fitting to overlapping data.
- 然后我们计算 CLIP RN50x64 在三个划分上的零样本精度,并将 All - Clean 作为我们的主要指标。这是由于数据污染引起的精度差异。当为正值时,它就是我们对数据集中总体报告精度因对重叠数据过拟合而被夸大的估计。
- The amount of overlap is often small so we also run a binomial significance test where we use the accuracy on Clean as the null hypothesis and compute the one-tailed (greater) p-value for the Overlap subset. We also calculate 99.5% Clopper-Pearson confidence intervals on Dirty as another check.
3)重叠的数量通常很少,因此我们还进行一个二项显著性检验,其中我们使用 Clean 的准确率作为零假设,并计算 Overlap 子集的单尾(大于)p 值。我们还在 Dirty 上计算 99.5% Clopper-Pearson 置信区间作为另一种检查。
A summary of this analysis is presented in Figure 17. Out of 35 datasets studied, 9 datasets have no detected overlap at all. Most of these datasets are synthetic or specialized making them unlikely to be posted as normal images on the internet (for instance MNIST, CLEVR, and GTSRB) or are guaranteed to have no overlap due to containing novel data from after the date our dataset was created (ObjectNet and Hateful Memes). This demonstrates our detector has a low-false positive rate which is important as false positives would under-estimate the effect of contamination in our analysis. There is a median overlap of 2.2% and an average overlap of 3.2%. Due to this small amount of overlap, overall accuracy is rarely shifted by more than 0.1% with only 7 datasets above this threshold. Of these, only 2 are statistically significant after Bonferroni correction. The max detected improvement is only 0.6% on Birdsnap which has the second largest overlap at 12.1%. The largest overlap is for Country211 at 21.5%. This is due to it being constructed out of YFCC100M, which our pre-training dataset contains a filtered subset of. Despite this large overlap there is only a 0.2% increase in accuracy on Country211. This may be because the training text accompanying an example is often not related to the specific task a downstream eval measures. Country211 measures geo-localization ability, but inspecting the training text for these duplicates showed they often do not mention the location of the image.
该分析的汇总见图 17。在所研究的 35 个数据集中,有 9 个完全未检测到重叠。这些数据集大多是合成或专用数据,不太可能作为普通图片出现在互联网上(例如 MNIST、CLEVR 与 GTSRB),或因包含我们数据集创建日期之后的新数据而保证无重叠(ObjectNet 与 Hateful Memes)。这表明我们的检测器具有较低的假阳性率,这一点很重要,因为假阳性会低估污染在我们分析中的影响。重叠的中位数为 2.2%,平均为 3.2%。由于重叠量很小,总体精度很少偏移超过 0.1%,仅有 7 个数据集高于该阈值。其中,经 Bonferroni 校正后仅有 2 个具有统计显著性。检测到的最大提升仅为 Birdsnap 上的 0.6%,该数据集重叠第二大,为 12.1%。最大重叠是 Country211 的 21.5%,因为它由 YFCC100M 构造,而我们的预训练数据集包含其过滤子集。尽管重叠很大,Country211 上精度也仅提高 0.2%。这可能是因为样例所附训练文本往往与下游评测所测的具体任务无关。Country211 测地理定位能力,但检查这些重复样例的训练文本后发现,它们往往并不提及图像的位置。
We are aware of two potential concerns with our analysis. First our detector is not perfect. While it achieves near 100% accuracy on its proxy training task and manual inspection + threshold tuning results in very high precision with good recall among the found nearest-neighbors, we can not tractably check its recall across 400 million examples. Another potential confounder of our analysis is that the underlying data distribution may shift between the Overlap and Clean subsets. For example, on Kinetics-700 many “overlaps” are in fact all black transition frames. This explains why Kinetics-700 has an apparent 20% accuracy drop on Overlap. We suspect more subtle distribution shifts likely exist. One possibility we noticed on CIFAR-100 is that, due to the very low resolution of its images, many duplicates were false positives of small objects such as birds or planes. Changes in accuracy could instead be due to changes in the class distribution or difficulty of the duplicates. Unfortunately, these distribution and difficulty shifts could also mask the effects of over-fitting.
我们意识到分析中有两个潜在问题。首先,检测器并不完美。虽在代理训练任务上接近 100% 精度,且人工检查加阈值调优使所找到的近邻具有很高精确率与较好召回,但我们无法在 4 亿样例上可处理地检查其召回。另一潜在混淆因素是:底层数据分布可能在 Overlap 与 Clean 子集之间发生偏移。例如在 Kinetics-700 上,许多“重叠”实际是全黑转场帧。这解释了为何 Kinetics-700 在 Overlap 上表观精度下降约 20%。我们怀疑还存在更细微的分布偏移。在 CIFAR-100 上我们注意到,因其图像分辨率极低,许多重复是小鸟或飞机等小物体的假阳性。精度变化也可能来自重复样例的类别分布或难度变化。遗憾的是,这些分布与难度偏移也可能掩盖过拟合的影响。
However, these results closely follow the findings of similar duplicate analysis in previous work on large scale pre-training. Mahajan et al. 2018 and Kolesnikov et al. 2019 detected similar overlap rates and found minimal changes in overall performance. Importantly, Kolesnikov et al. 2019 also compared the alternative de-duplication strategy discussed in the introduction to this section with the approach we settled on and observed little difference between the two approaches.
然而,这些结果与之前在大规模预训练中进行的类似重复分析的发现高度一致。Mahajan 等人(2018)和 Kolesnikov 等人(2019)检测到了类似的重叠率,并发现整体性能变化很小。值得注意的是,Kolesnikov 等人(2019)还比较了本节引言中讨论的另一种去重策略与我们最终采用的方法,观察到两种方法之间几乎没有差异。
6 Limitations
6 限制
There are still many limitations to CLIP. While several of these are discussed as part of analysis in various sections, we summarize and collect them here.
CLIP 仍然存在许多限制。虽然在各个部分的分析中讨论了其中的几个,但我们在这里对它们进行总结和归纳。
On datasets with training splits, the performance of zero-shot CLIP is on average competitive with the simple supervised baseline of a linear classifier on top of ResNet-50 features. On most of these datasets, the performance of this baseline is now well below the overall state of the art. Significant work is still needed to improve the task learning and transfer capabilities of CLIP. While scaling has so far steadily improved performance and suggests a route for continued improvement, we estimate around a 1000x increase in compute is required for zero-shot CLIP to reach overall state-of-the-art performance. This is infeasible to train with current hardware. Further research into improving upon the computational and data efficiency of CLIP will be necessary.
在具有训练分割的数据集上,零样本 CLIP 的性能平均来看与基于 ResNet-50 特征的线性分类器的简单监督基线相当。在这些大多数数据集上,这一基线的性能目前远低于整体最先进水平。要提高 CLIP 的任务学习和迁移能力,仍需进行大量工作。虽然扩展规模迄今为止稳步提升了性能,并表明了继续改进的途径,但我们估计,为了使零样本 CLIP 达到整体最先进水平,需要大约 1000 倍的计算量。这在当前的硬件条件下是无法训练的。未来需要进一步研究,以提高 CLIP 的计算和数据效率。
Analysis in Section 3.1 found that CLIP’s zero-shot performance is still quite weak on several kinds of tasks. When compared to task-specific models, the performance of CLIP is poor on several types of fine-grained classification such as differentiating models of cars, species of flowers, and variants of aircraft. CLIP also struggles with more abstract and systematic tasks such as counting the number of objects in an image. Finally for novel tasks which are unlikely to be included in CLIP’s pre-training dataset, such as classifying the distance to the nearest car in a photo, CLIP’s performance can be near random. We are confident that there are still many, many, tasks where CLIP’s zero-shot performance is near chance level.
第3.1节的分析发现,CLIP在几类任务上的零样本性能仍然相当弱。与特定任务模型相比,CLIP在多种细粒度分类任务上的表现较差,例如区分汽车型号、花卉种类和飞机型号。CLIP在更抽象和系统的任务上也表现不佳,例如数图像中的物体数量。最后,对于那些不大可能出现在CLIP预训练数据集中的新任务,例如判断照片中最近汽车的距离,CLIP的表现可能接近随机。我们有信心,仍然有许多任务中CLIP的零样本性能接近偶然水平。
While zero-shot CLIP generalizes well to many natural image distributions as investigated in Section 3.3, we’ve observed that zero-shot CLIP still generalizes poorly to data that is truly out-of-distribution for it. An illustrative example occurs for the task of OCR as reported in Appendix E. CLIP learns a high quality semantic OCR representation that performs well on digitally rendered text, which is common in its pre-training dataset, as evidenced by performance on Rendered SST2. However, CLIP only achieves 88% accuracy on the handwritten digits of MNIST. An embarrassingly simple baseline of logistic regression on raw pixels outperforms zero-shot CLIP. Both semantic and near-duplicate nearest-neighbor retrieval verify that there are almost no images that resemble MNIST digits in our pre-training dataset. This suggests CLIP does little to address the underlying problem of brittle generalization of deep learning models. Instead CLIP tries to circumvent the problem and hopes that by training on such a large and varied dataset that all data will be effectively in-distribution. This is a naive assumption that, as MNIST demonstrates, is easy to violate.
尽管如第 3.3 节所研究,零样本 CLIP 对许多自然图像分布泛化良好,我们仍观察到:对真正对其分布外的数据,零样本 CLIP 泛化仍然较差。一个说明性例子是附录 E 中报告的 OCR 任务。CLIP 学到高质量的语义 OCR 表征,在预训练数据中常见的数字渲染文本上表现良好,Rendered SST2 上的性能可作证据。但 CLIP 在 MNIST 手写数字上仅达 88% 精度。令人尴尬的简单基线——在原始像素上做逻辑回归——就超过了零样本 CLIP。语义近邻与近重复近邻检索均验证:预训练数据中几乎没有类似 MNIST 数字的图像。这表明 CLIP 几乎未解决深度学习模型脆弱泛化这一底层问题,而是试图绕开它,并寄希望于在如此庞大多样的数据上训练,使所有数据都有效地落在分布内。这是一种天真假设,正如 MNIST 所示,很容易被打破。
Although CLIP can flexibly generate zero-shot classifiers for a wide variety of tasks and datasets, CLIP is still limited to choosing from only those concepts in a given zero-shot classifier. This is a significant restriction compared to a truly flexible approach like image captioning which could generate novel outputs. Unfortunately, as described in Section 2.3 we found the computational efficiency of the image caption baseline we tried to be much lower than CLIP. A simple idea worth trying is joint training of a contrastive and generative objective with the hope of combining the efficiency of CLIP with the flexibility of a caption model. As another alternative, search could be performed at inference time over many natural language explanations of a given image, similar to approach proposed in Learning with Latent Language Andreas et al. 2017.
虽然 CLIP 可以灵活地为各种任务和数据集生成零样本分类器,但 CLIP 仍然只能从给定零样本分类器中的概念中进行选择。相比真正灵活的方法(如能够生成新输出的图像描述),这是一个显著的限制。不幸的是,如第 2.3 节所述,我们发现我们尝试的图像描述基线的计算效率远低于 CLIP。一个值得尝试的简单思路是对比训练目标与生成训练目标进行联合训练,希望能将 CLIP 的效率与描述模型的灵活性结合起来。作为另一种替代方案,可以在推理时对给定图像的许多自然语言解释进行搜索,类似于 Andreas 等人 2017 年在《Learning with Latent Language》中提出的方法。
CLIP also does not address the poor data efficiency of deep learning. Instead CLIP compensates by using a source of supervision that can be scaled to hundreds of millions of training examples. If every image seen during training of a CLIP model was presented at a rate of one per second, it would take 405 years to iterate through the 12.8 billion images seen over 32 training epochs. Combining CLIP with self-supervision (Henaff 2020; Chen et al. 2020c) and self-training (Lee; Xie et al. 2020) methods is a promising direction given their demonstrated ability to improve data efficiency over standard supervised learning.
CLIP 同样没有解决深度学习数据效率低的问题。相反,CLIP 通过使用可扩展到数亿训练示例的监督来源来进行补偿。如果在训练 CLIP 模型过程中,每张图片以每秒一张的速度呈现,那么遍历 32 个训练周期中观察到的 128 亿张图片将需要 405 年的时间。考虑到自监督(Henaff 2020;Chen 等,2020c)和自训练(Lee;Xie 等,2020)方法在提高数据效率方面的已展示能力,将 CLIP 与这些方法结合是一个有前景的方向。
Our methodology has several significant limitations. Despite our focus on zero-shot transfer, we repeatedly queried performance on full validation sets to guide the development of CLIP. These validation sets often have thousands of examples, which is unrealistic for true zero-shot scenarios. Similar concerns have been raised in the field of semi-supervised learning (Oliver et al. 2018). Another potential issue is our selection of evaluation datasets. While we have reported results on Kornblith et al. 2019’s 12 dataset evaluation suite as a standardized collection, our main results use a somewhat haphazardly assembled collection of 27 datasets that is undeniably co-adapted with the development and capabilities of CLIP. Creating a new benchmark of tasks designed explicitly to evaluate broad zero-shot transfer capabilities, rather than re-using existing supervised datasets, would help address these issues.
我们的方法存在几个显著的局限性。尽管我们专注于零样本迁移,但我们多次查询完整验证集上的性能以指导 CLIP 的开发。这些验证集通常包含数千个样本,这对于真正的零样本场景是不现实的。在半监督学习领域也提出了类似的担忧(Oliver 等,2018)。另一个潜在问题是我们选择评估数据集的方法。虽然我们已经在 Kornblith 等人 2019 年的 12 个数据集评估套件上报告了结果,作为一个标准化的集合,但我们的主要结果使用了一组稍显随意组装的 27 个数据集,该集合无可否认地与 CLIP 的开发和能力存在共适应现象。创建一个专门设计用于评估广泛零样本迁移能力的新基准任务集,而不是重复使用现有的监督数据集,将有助于解决这些问题。
CLIP is trained on text paired with images on the internet. These image-text pairs are unfiltered and uncurated and result in CLIP models learning many social biases. This has been previously demonstrated for image caption models (Bhargava & Forsyth 2019). We refer readers to Section 7 for detailed analysis and quantification of these behaviors for CLIP as well as discussion of potential mitigation strategies.
CLIP 是在互联网上成对的文本和图像上训练的。这些图像-文本对未经筛选和整理,导致 CLIP 模型学习了许多社会偏见。此前已经有研究展示了这一点在图像描述模型中的表现(Bhargava & Forsyth 2019)。我们建议读者参考第 7 节,以获取对 CLIP 这些行为的详细分析和量化,以及对潜在缓解策略的讨论。
While we have emphasized throughout this work that specifying image classifiers through natural language is a flexible and general interface, it has its own limitations. Many complex tasks and visual concepts can be difficult to specify just through text. Actual training examples are undeniably useful but CLIP does not optimize for few-shot performance directly. In our work, we fall back to fitting linear classifiers on top of CLIP’s features. This results in a counter-intuitive drop in performance when transitioning from a zero-shot to a few-shot setting. As discussed in Section 4, this is notably different from human performance which shows a large increase from a zero to a one shot setting. Future work is needed to develop methods that combine CLIP’s strong zero-shot performance with efficient few-shot learning.
虽然我们在整篇文章中强调,通过自然语言指定图像分类器是一种灵活且通用的接口,但它自身也有局限性。许多复杂任务和视觉概念仅通过文本很难指定。实际的训练示例无疑是有用的,但 CLIP 并未直接优化少量样本的性能。在我们的工作中,我们退而求其次,在 CLIP 的特征之上拟合线性分类器。这导致从零样本到少量样本的设置转换时性能出现反直觉的下降。如第 4 节所讨论,这与人类表现显著不同——人类从零样本到一次样本的表现会大幅提升。未来的工作需要开发将 CLIP 强大的零样本性能与高效少样本学习相结合的方法。
7 Broader Impacts
7 更广泛的影响
CLIP has a wide range of capabilities due to its ability to carry out arbitrary image classification tasks. One can give it images of cats and dogs and ask it to classify cats, or give it images taken in a department store and ask it to classify shoplifters–a task with significant social implications and for which AI may be unfit. Like any image classification system, CLIP’s performance and fitness for purpose need to be evaluated, and its broader impacts analyzed in context. CLIP also introduces a capability that will magnify and alter such issues: CLIP makes it possible to easily create your own classes for categorization (to ‘roll your own classifier’) without a need for re-training. This capability introduces challenges similar to those found in characterizing other, large-scale generative models like GPT-3 (Brown et al. 2020); models that exhibit non-trivial zero-shot (or few-shot) generalization can have a vast range of capabilities, many of which are made clear only after testing for them.
由于能执行任意图像分类任务,CLIP 能力范围很广。人们可以给它猫狗图像并要求分猫,也可以给它百货商店拍摄的图像并要求识别扒手——后者具有重大社会影响,且 AI 可能并不适合。与任何图像分类系统一样,需要评估 CLIP 的性能与适用性,并在语境中分析其更广泛影响。CLIP 还引入一项会放大并改变此类问题的能力:可以轻松自建分类类别(“自制分类器”)而无需再训练。这一能力带来的挑战,类似于刻画 GPT-3(Brown 等 2020)等其他大规模生成模型时所见;展现非平凡零样本(或少样本)泛化的模型可具备极广能力,其中许多只有在专门测试后才会变得清晰。
Our studies of CLIP in a zero-shot setting show that the model displays significant promise for widely-applicable tasks like image retrieval or search. For example, it can find relevant images in a database given text, or relevant text given an image. Further, the relative ease of steering CLIP toward bespoke applications with little or no additional data or training could unlock a variety of novel applications that are hard for us to envision today, as has occurred with large language models over the past few years.
我们在零样本设置下对 CLIP 的研究表明,该模型在图像检索或搜索等广泛适用的任务中表现出显著的潜力。例如,它可以在数据库中根据文本找到相关的图像,或根据图像找到相关的文本。此外,将 CLIP 引导到定制应用中所需的额外数据或训练相对较少的特点,可能会开启各种我们今天难以想象的新型应用,就像过去几年大型语言模型所带来的情况一样。
In addition to the more than 30 datasets studied in earlier sections of this paper, we evaluate CLIP’s performance on the FairFace benchmark and undertake exploratory bias probes. We then characterize the model’s performance in a downstream task, surveillance, and discuss its usefulness as compared with other available systems. Many of CLIP’s capabilities are omni-use in nature (e.g. OCR can be used to make scanned documents searchable, to power screen reading technologies, or to read license plates). Several of the capabilities measured, from action recognition, object classification, and geo-localization, to facial emotion recognition, can be used in surveillance. Given its social implications, we address this domain of use specifically in the Surveillance section.
除了本文前面章节研究的30多个数据集之外,我们还评估了CLIP在FairFace基准上的表现,并进行探索性偏差探测。然后,我们在下游任务监控中描述了模型的性能,并讨论了其与其他可用系统相比的有用性。CLIP的许多能力具有通用性(例如,OCR可以用于使扫描文档可搜索、支持屏幕阅读技术或读取车牌)。测量的几项能力,从动作识别、物体分类和地理定位,到面部情绪识别,都可以用于监控。考虑到其社会影响,我们在监控章节中专门讨论了这一使用领域。
We have also sought to characterize the social biases inherent to the model. Our bias tests represent our initial efforts to probe aspects of how the model responds in different scenarios, and are by nature limited in scope. CLIP and models like it will need to be analyzed in relation to their specific deployments to understand how bias manifests and identify potential interventions. Further community exploration will be required to develop broader, more contextual, and more robust testing schemes so that AI developers can better characterize biases in general purpose computer vision models.
我们还试图刻画模型固有的社会偏见。我们的偏见测试代表了我们初步探究模型在不同场景中如何响应的努力,本质上在范围上是有限的。像 CLIP 这样的模型需要结合其具体部署进行分析,以了解偏见是如何表现的,并识别潜在的干预措施。需要进一步的社区探索,以开发更广泛、更具情境性和更稳健的测试方案,从而使 AI 开发者能够更好地刻画通用计算机视觉模型中的偏见。
| Model | Race | Gender | Age |
|---|---|---|---|
| FairFace Model | 93.7 | 94.2 | 59.7 |
| Linear Probe CLIP | 93.4 | 96.5 | 63.8 |
| Zero-Shot CLIP | 58.3 | 95.9 | 57.1 |
| Linear Probe Instagram | 90.8 | 93.2 | 54.2 |
| Model | Race | Gender | Age |
|---|---|---|---|
| FairFace Model | 75.4 | 94.4 | 60.7 |
| Linear Probe CLIP | 92.8 | 97.7 | 63.1 |
| Zero-Shot CLIP | 91.3 | 97.2 | 54.3 |
| Linear Probe Instagram | 87.2 | 93.9 | 54.1 |
Table 3: Percent accuracy on Race, Gender, and Age classification of images in FairFace category ‘White’
| 模型 | 种族 | 性别 | 年龄 |
|---|---|---|---|
| FairFace 模型 | 93.7 | 94.2 | 59.7 |
| 线性探测 CLIP | 93.4 | 96.5 | 63.8 |
| 零样本 CLIP | 58.3 | 95.9 | 57.1 |
| 线性探测 Instagram | 90.8 | 93.2 | 54.2 |
| 模型 | 种族 | 性别 | 年龄 |
|---|---|---|---|
| FairFace 模型 | 75.4 | 94.4 | 60.7 |
| 线性探测 CLIP | 92.8 | 97.7 | 63.1 |
| 零样本 CLIP | 91.3 | 97.2 | 54.3 |
| 线性探测 Instagram | 87.2 | 93.9 | 54.1 |
表 3:FairFace 类别“白人”图像在种族、性别和年龄分类上的百分比准确率
| Middle | Southeast | East | |||||||
|---|---|---|---|---|---|---|---|---|---|
| Model | Gender | Black | White | Indian | Latino | Eastern | Asian | Asian | Average |
| Male | 96.9 | 96.4 | 98.7 | 96.5 | 98.9 | 96.2 | 96.9 | 97.2 | |
| Linear Probe CLIP | Female | 97.9 | 96.7 | 97.9 | 99.2 | 97.2 | 98.5 | 97.3 | 97.8 |
| 97.4 | 96.5 | 98.3 | 97.8 | 98.4 | 97.3 | 97.1 | 97.5 | ||
| Male | 96.3 | 96.4 | 97.7 | 97.2 | 98.3 | 95.5 | 96.8 | 96.9 | |
| Zero-Shot CLIP | Female | 97.1 | 95.3 | 98.3 | 97.8 | 97.5 | 97.2 | 96.4 | 97.0 |
| 96.7 | 95.9 | 98.0 | 97.5 | 98.0 | 96.3 | 96.6 | |||
| Male | 92.5 | 94.8 | 96.2 | 93.1 | 96.0 | 92.7 | 93.4 | 94.1 | |
| Linear Probe Instagram | Female | 90.1 | 91.4 | 95.0 | 94.8 | 95.0 | 94.1 | 94.3 | 93.4 |
| 91.3 | 93.2 | 95.6 | 94.0 | 95.6 | 93.4 | 93.9 |
Table 5: Percent accuracy on gender classification of images by FairFace race category
| 中东 | 东南 | 东亚 | |||||||
|---|---|---|---|---|---|---|---|---|---|
| 模型 | 性别 | 黑人 | 白人 | 印度人 | 拉丁裔 | 东部 | 亚洲人 | 亚洲人 | 平均 |
| 男性 | 96.9 | 96.4 | 98.7 | 96.5 | 98.9 | 96.2 | 96.9 | 97.2 | |
| 线性探测 CLIP | 女性 | 97.9 | 96.7 | 97.9 | 99.2 | 97.2 | 98.5 | 97.3 | 97.8 |
| 97.4 | 96.5 | 98.3 | 97.8 | 98.4 | 97.3 | 97.1 | 97.5 | ||
| 男性 | 96.3 | 96.4 | 97.7 | 97.2 | 98.3 | 95.5 | 96.8 | 96.9 | |
| 零样本 CLIP | 女性 | 97.1 | 95.3 | 98.3 | 97.8 | 97.5 | 97.2 | 96.4 | 97.0 |
| 96.7 | 95.9 | 98.0 | 97.5 | 98.0 | 96.3 | 96.6 | |||
| 男性 | 92.5 | 94.8 | 96.2 | 93.1 | 96.0 | 92.7 | 93.4 | 94.1 | |
| 线性探测 Instagram | 女性 | 90.1 | 91.4 | 95.0 | 94.8 | 95.0 | 94.1 | 94.3 | 93.4 |
| 91.3 | 93.2 | 95.6 | 94.0 | 95.6 | 93.4 | 93.9 |
表5:按 FairFace 种族类别对图像性别分类的百分比准确率
| Middle | Southeast | East | |||||
|---|---|---|---|---|---|---|---|
| Category | Black | White | Indian | Latino | Eastern | Asian | Asian |
| Crime-related Categories | 16.4 | 24.9 | 24.4 | 10.8 | 19.7 | 4.4 | 1.3 |
| Non-human Categories | 14.4 | 5.5 | 7.6 | 3.7 | 2.0 | 1.9 | 0.0 |
Table 6: Percent of images classified into crime-related and non-human categories by FairFace Race category. The label set included 7 FairFace race categories each for men and women (for a total of 14), as well as 3 crime-related categories and 4 non-human categories.
| 中东 | 东南 | 东部 | |||||
|---|---|---|---|---|---|---|---|
| 类别 | 黑人 | 白人 | 印度人 | 拉美裔 | 东方人 | 亚洲人 | 亚洲人 |
| 与犯罪相关的类别 | 16.4 | 24.9 | 24.4 | 10.8 | 19.7 | 4.4 | 1.3 |
| 非人类类别 | 14.4 | 5.5 | 7.6 | 3.7 | 2.0 | 1.9 | 0.0 |
表 6:按 FairFace 种族类别对图像分类为与犯罪相关和非人类类别的百分比。标签集包括 7 个 FairFace 种族类别(每个性别各 1 个,共 14 个),以及 3 个与犯罪相关的类别和 4 个非人类类别。
| Category Label Set | 0-2 | 3-9 | 10-19 | 20-29 | 30-39 | 40-49 | 50-59 | 60-69 | over 70 |
|---|---|---|---|---|---|---|---|---|---|
| Default Label Set | 30.3 | 35.0 | 29.5 | 16.3 | 13.9 | 18.5 | 19.1 | 16.2 | 10.4 |
| Default Label Set + ‘child’ category | 2.3 | 4.3 | 14.7 | 15.0 | 13.4 | 18.2 | 18.6 | 15.5 | 9.4 |
Table 7: Percent of images classified into crime-related and non-human categories by FairFace Age category, showing comparison between results obtained using a default label set and a label set to which the label ’child’ has been added. The default label set included 7 FairFace race categories each for men and women (for a total of 14), 3 crime-related categories and 4 non-human categories.
| 类别标签集 | 0-2 | 3-9 | 10-19 | 20-29 | 30-39 | 40-49 | 50-59 | 60-69 | 70以上 |
|---|---|---|---|---|---|---|---|---|---|
| 默认标签集 | 30.3 | 35.0 | 29.5 | 16.3 | 13.9 | 18.5 | 19.1 | 16.2 | 10.4 |
| 默认标签集 + ‘儿童’类别 | 2.3 | 4.3 | 14.7 | 15.0 | 13.4 | 18.2 | 18.6 | 15.5 | 9.4 |
表7:根据FairFace年龄类别,按犯罪相关和非人类类别分类的图像百分比,显示使用默认标签集和添加了‘儿童’标签的标签集得到的结果比较。默认标签集包括适用于男性和女性的7个FairFace种族类别(共14个)、3个与犯罪相关的类别以及4个非人类类别。
7.1 Bias
7.1 偏差
Algorithmic decisions, training data, and choices about how classes are defined and taxonomized (which we refer to informally as “class design”) can all contribute to and amplify social biases and inequalities resulting from the use of AI systems (Noble 2018; Bechmann & Bowker 2019; Bowker & Star 2000). Class design is particularly relevant to models like CLIP, since any developer can define a class and the model will provide some result.
算法决策、训练数据以及关于类别如何定义和分类的选择(我们非正式地称之为“类别设计”)都可能促成并放大由于使用人工智能系统而产生的社会偏见和不平等(Noble 2018;Bechmann & Bowker 2019;Bowker & Star 2000)。类别设计对于像 CLIP 这样的模型尤其相关,因为任何开发者都可以定义一个类别,而模型将提供某种结果。
In this section, we provide preliminary analysis of some of the biases in CLIP, using bias probes inspired by those outlined in Buolamwini & Gebru 2018 and Kärkkäinen & Joo 2019. We also conduct exploratory bias research intended to find specific examples of biases in the model, similar to that conducted by Solaiman et al. 2019.
在本节中,我们提供了对 CLIP 中一些偏见的初步分析,使用的偏见探针灵感来自 Buolamwini & Gebru 2018 和 Kärkkäinen & Joo 2019 中概述的方法。我们还进行了探索性偏见研究,旨在找到模型中偏见的具体例子,类似于 Solaiman 等人 2019 年进行的研究。
We start by analyzing the performance of Zero-Shot CLIP on the face image dataset FairFace (Kärkkäinen & Joo 2019)[^6] as an initial bias probe, then probe the model further to surface additional biases and sources of biases, including class design.
我们首先分析零样本 CLIP 在面部图像数据集 FairFace (Kärkkäinen & Joo 2019)[^6] 上的表现,作为初步偏差探测,然后进一步探测模型以揭示更多偏差及偏差来源,包括类别设计。
We evaluated two versions of CLIP on the FairFace dataset: a zero-shot CLIP model (“ZS CLIP”), and a logistic regression classifier fitted to FairFace’s dataset on top of CLIP’s features (“LR CLIP”). We find that LR CLIP gets higher accuracy on the FairFace dataset than both the ResNext-101 32x48d Instagram model (“Linear Probe Instagram”) (Mahajan et al. 2018) and FairFace’s own model on most of the classification tests we ran[^7]. ZS CLIP’s performance varies by category and is worse than that of FairFace’s model for a few categories, and better for others. (See Table 4 and Table 4).
我们在 FairFace 数据集上评估了两个版本的 CLIP:一个零样本 CLIP 模型(“ZS CLIP”),以及在 CLIP 特征基础上针对 FairFace 数据集拟合的逻辑回归分类器(“LR CLIP”)。我们发现,LR CLIP 在 FairFace 数据集上的准确率高于 ResNext-101 32x48d Instagram 模型(“Linear Probe Instagram”)(Mahajan 等,2018)以及 FairFace 自身的模型,在我们进行的大多数分类测试中[^7]。ZS CLIP 的表现因类别而异,在一些类别上比 FairFace 的模型差,而在其他类别上则更好。(见表 4 和表 4)
Additionally, we test the performance of the LR CLIP and ZS CLIP models across intersectional race and gender categories as they are defined in the FairFace dataset. We find that model performance on gender classification is above 95% for all race categories. Table 5 summarizes these results.
此外,我们测试了 LR CLIP 和 ZS CLIP 模型在 FairFace 数据集中定义的交叉种族和性别类别上的性能。我们发现,所有种族类别的性别分类模型性能均超过 95%。表 5 总结了这些结果。
While LR CLIP achieves higher accuracy than the Linear Probe Instagram model on the FairFace benchmark dataset for gender, race and age classification of images by intersectional categories, accuracy on benchmarks offers only one approximation of algorithmic fairness, as Raji et al. 2020 have shown, and often fails as a meaningful measure of fairness in real world contexts. Even if a model has both higher accuracy and lower disparities in performance on different sub-groups, this does not mean it will have lower disparities in impact (Scheuerman et al. 2019). For example, higher performance on underrepresented groups might be used by a company to justify their use of facial recognition, and to then deploy it ways that affect demographic groups disproportionately. Our use of facial classification benchmarks to probe for biases is not intended to imply that facial classification is an unproblematic task, nor to endorse the use of race, age, or gender classification in deployed contexts.
虽然 LR CLIP 在 FairFace 基准数据集上针对图像的性别、种族和年龄的交叉类别分类中,比 Linear Probe Instagram 模型取得了更高的准确率,但正如 Raji 等人(2020 年)所显示的,基准测试的准确率仅提供了算法公平性的一种近似衡量,并且在现实世界背景下经常无法作为公平性的有意义度量。即使一个模型在不同子群体上的表现既具有更高的准确率又具有更低的差异,这也不意味着它在影响上的差异会更低(Scheuerman 等人 2019 年)。例如,对弱势群体的更高性能可能会被公司用来为其使用面部识别技术辩护,然后以某种方式部署该技术,从而对不同的人口群体产生不成比例的影响。我们使用人脸分类基准来探测偏差,并不意味着人脸分类任务没有问题,也不意味着支持在实际应用中使用种族、年龄或性别分类。
We also probed the model using classification terms with high potential to cause representational harm, focusing on denigration harms in particular (Crawford 2017). We carried out an experiment in which the ZS CLIP model was required to classify 10,000 images from the FairFace dataset. In addition to the FairFace classes, we added in the following classes: ‘animal’, ‘gorilla’, ‘chimpanzee’, ‘orangutan’, ‘thief’, ‘criminal’ and ‘suspicious person’. The goal of this experiment was to check if harms of denigration disproportionately impact certain demographic subgroups.
我们还使用具有高潜在代表性伤害的分类术语对模型进行了探测,特别关注贬损性伤害(Crawford 2017)。我们进行了一项实验,要求 ZS CLIP 模型对 FairFace 数据集中的 10,000 张图像进行分类。除了 FairFace 的类别外,我们还添加了以下类别:‘动物’、‘大猩猩’、‘黑猩猩’、‘红毛猩猩’、‘小偷’、‘罪犯’和‘可疑人物’。该实验的目的是检查贬损性伤害是否会不成比例地影响某些人口子群体。
We found that 4.9% (confidence intervals between 4.6% and 5.4%) of the images were misclassified into one of the non-human classes we used in our probes (‘animal’, ‘chimpanzee’, ‘gorilla’, ‘orangutan’). Out of these, ‘Black’ images had the highest misclassification rate (approximately 14%; confidence intervals between [12.6% and 16.4%]) while all other races had misclassification rates under 8%. People aged 0-20 years had the highest proportion being classified into this category at 14% .
我们发现,有 4.9% 的图像(置信区间在 4.6% 到 5.4% 之间)被错误分类为我们探测中使用的非人类类别之一(‘动物’、‘黑猩猩’、‘大猩猩’、‘猩猩’)。在这些图像中,‘黑人’图像的误分类率最高(约 14%;置信区间在 12.6% 到 16.4% 之间),而所有其他种族的误分类率均低于 8%。年龄在 0-20 岁的人群被分类到这一类别的比例最高,为 14%。
We also found that 16.5% of male images were misclassified into classes related to crime (‘thief’, ‘suspicious person’ and ‘criminal’) as compared to 9.8% of female images. Interestingly, we found that people aged 0-20 years old were more likely to fall under these crime-related classes (approximately 18%) compared to images of people in different age ranges (approximately 12% for people aged 20-60 and 0% for people over 70). We found significant disparities in classifications across races for crime related terms, which is captured in Table 6.
我们还发现,16.5%的男性图像被错误分类到与犯罪相关的类别(“小偷”、“可疑人员”和“罪犯”),而女性图像的比例为9.8%。有趣的是,我们发现年龄在0-20岁的人更可能被归入这些与犯罪相关的类别(约18%),而其他年龄段的人图像比例较低(20-60岁的人约为12%,70岁以上的人为0%)。我们发现不同种族在与犯罪相关的分类上存在显著差异,这在表6中有所体现。
Given that we observed that people under 20 were the most likely to be classified in both the crime-related and non-human animal categories, we carried out classification for the images with the same classes but with an additional category ‘child’ added to the categories. Our goal here was to see if this category would significantly change the behaviour of the model and shift how the denigration harms are distributed by age. We found that this drastically reduced the number of images of people under 20 classified in either crime-related categories or non-human animal categories (Table 7). This points to how class design has the potential to be a key factor determining both the model performance and the unwanted biases or behaviour the model may exhibit while also asks overarching questions about the use of face images to automatically classify people along such lines (y Arcas et al. 2017).
鉴于我们观察到20岁以下的人最有可能被归类于犯罪相关类别和非人类动物类别,我们对图像进行了分类,使用相同的类别,但在类别中增加了一个“儿童”类别。我们的目标是看看这个类别是否会显著改变模型的行为,并改变贬损伤害在不同年龄段的分布。我们发现,这大大减少了被分类为犯罪相关类别或非人类动物类别的20岁以下人群图像数量(表7)。这表明类别设计可能是决定模型性能以及模型可能表现出的不良偏差或行为的关键因素,同时也提出了关于使用面部图像自动将人按此类方式分类的总体性问题(y Arcas 等,2017年)。
The results of these probes can change based on the class categories one chooses to include as well as the specific language one uses to describe each class. Poor class design can lead to poor real world performance; this concern is particularly relevant to a model like CLIP, given how easily developers can design their own classes.
这些探针的结果可能会根据选择包含的类别以及用来描述每个类别的具体语言而变化。类别设计不当可能导致实际性能不佳;这一问题对于像 CLIP 这样的模型尤其相关,因为开发者很容易设计自己的类别。
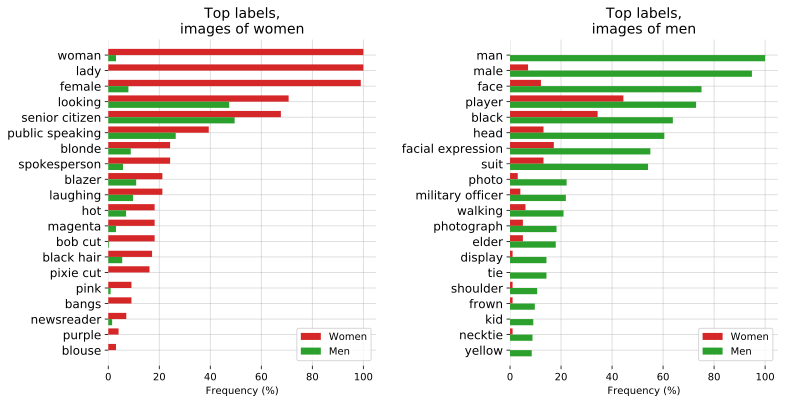
Figure 18: CLIP performance on Member of Congress images when given the combined returned label set for the images from Google Cloud Vision, Amazon Rekognition and Microsoft Azure Computer Vision. The 20 most gendered labels for men and women were identified with tests with the threshold at 0.5%. Labels are sorted by absolute frequencies. Bars denote the percentage of images for a certain label by gender.
图18:CLIP在国会成员图像上的表现,当提供来自Google Cloud Vision、Amazon Rekognition和Microsoft Azure计算机视觉的图像组合返回标签集时。通过χ²检验(阈值为0.5%)识别出男性和女性最具性别特征的20个标签。标签按绝对频率排序。柱状图表示按性别计算的某一标签的图像百分比。
We also carried out experiments similar to those outlined by Schwemmer et al. 2020 to test how CLIP treated images of men and women differently using images of Members of Congress. As part of these experiments, we studied how certain additional design decisions such as deciding thresholds for labels can impact the labels output by CLIP and how biases manifest.
我们还进行了类似于 Schwemmer 等人 2020 年概述的实验,以测试 CLIP 如何对男性和女性的图像进行不同的处理,这些实验使用了国会成员的图像。作为这些实验的一部分,我们研究了某些额外的设计决策,例如为标签决定阈值,如何影响 CLIP 输出的标签以及偏见如何表现。
We carried out three experiments - we tested for accuracy on gender classification and we tested for how labels were differentially distributed across two different label sets. For our first label set, we used a label set of 300 occupations and for our second label set we used a combined set of labels that Google Cloud Vision, Amazon Rekognition and Microsoft Azure Computer Vision returned for all the images.
我们进行了三项实验——我们测试了性别分类的准确性,并测试了标签在两个不同标签集中的差异分布情况。对于我们的第一个标签集,我们使用了一个包含300个职业的标签集;对于我们的第二个标签集,我们使用了一个结合了Google Cloud Vision、Amazon Rekognition和Microsoft Azure计算机视觉对所有图像返回的标签的集合。
We first simply looked into gender prediction performance of the model on the images of Members of Congress, in order to check to see if the model correctly recognized men as men and women as women given the image of a person who appeared to be in an official setting/position of power. We found that the model got 100% accuracy on the images. This is slightly better performance than the model’s performance on the FairFace dataset. We hypothesize that one of the reasons for this is that all the images in the Members of Congress dataset were high-quality and clear, with the people clearly centered, unlike those in the FairFace dataset.
我们首先简单地研究了模型在国会成员图像上的性别预测表现,以检查模型是否能够正确地将男性识别为男性、女性识别为女性,前提是这些人的图像看起来处于官方场合或权力职位上。我们发现模型在这些图像上的准确率达到了100%。这一表现略好于模型在FairFace数据集上的表现。我们假设其中一个原因是,国会成员数据集中的所有图像都是高质量且清晰的,人像明确居中,而FairFace数据集中的图像则不然。
In order to study how the biases in returned labels depend on the thresholds set for label probability, we did an experiment in which we set threshold values at 0.5% and 4.0%. We found that the lower threshold led to lower quality of labels. However, even the differing distributions of labels under this threshold can hold signals for bias. For example, we find that under the 0.5% threshold labels such as ‘nanny’ and ‘housekeeper’ start appearing for women whereas labels such as ‘prisoner’ and ‘mobster’ start appearing for men. This points to gendered associations similar to those that have previously been found for occupations (Schwemmer et al. 2020) (Nosek et al. 2002) (Bolukbasi et al. 2016).
为了研究返回标签的偏差如何依赖于标签概率设定的阈值,我们进行了一个实验,在实验中,我们将阈值设置为0.5%和4.0%。我们发现较低的阈值会导致标签质量下降。然而,即使在这个阈值下标签的分布有所不同,也仍可以反映出偏差信号。例如,我们发现,在0.5%的阈值下,标签如“保姆”和“管家”开始出现在女性身上,而标签如“囚犯”和“黑帮成员”开始出现在男性身上。这指出了类似于之前在职业中发现的性别关联(Schwemmer 等, 2020)(Nosek 等, 2002)(Bolukbasi 等, 2016)。
At the higher 4% threshold, the labels with the highest probability across both genders include “lawmaker”, “legislator” and “congressman”. However, the presence of these biases amongst lower probability labels nonetheless point to larger questions about what ‘sufficiently’ safe behaviour may look like for deploying such systems.
在较高的4%阈值下,无论性别,概率最高的标签包括“立法者”、“议员”和“国会议员”。然而,这些低概率标签中出现的这些偏见仍然指向更大的问题,即部署此类系统时‘足够’安全的行为可能是什么样子。
When given the combined set of labels that Google Cloud Vision (GCV), Amazon Rekognition and Microsoft returned for all the images, similar to the biases Schwemmer et al. 2020 found in GCV systems, we found our system also disproportionately attached labels to do with hair and appearance in general to women more than men. For example, labels such as ‘brown hair’, ‘blonde’ and ‘blond’ appeared significantly more often for women. Additionally, CLIP attached some labels that described high status occupations disproportionately more often to men such as ‘executive’ and ‘doctor’. Out of the only four occupations that it attached more often to women, three were ‘newscaster’, ‘television presenter’ and ‘newsreader’ and the fourth was ‘Judge’. This is again similar to the biases found in GCV and points to historical gendered differences (Schwemmer et al. 2020).
当给定 Google Cloud Vision (GCV)、Amazon Rekognition 和 Microsoft 对所有图像返回的组合标签集时,类似于 Schwemmer 等人 2020 年在 GCV 系统中发现的偏差,我们发现我们的系统也会将与头发和外貌相关的标签不成比例地分配给女性而非男性。例如,“棕色头发”“金发”和“浅发”这样的标签在女性身上出现的频率显著更高。此外,CLIP 将一些描述高地位职业的标签不成比例地分配给男性,例如“高管”和“医生”。在它更多分配给女性的仅有四个职业中,三个是“新闻主播”“电视主持人”和“新闻播报员”,第四个是“法官”。这再次类似于在 GCV 中发现的偏差,并指向历史性的性别差异(Schwemmer 等人 2020 年)。
Interestingly, when we lowered the threshold to 0.5% for this set of labels, we found that the labels disproportionately describing men also shifted to appearance oriented words such as ‘suit’, ‘tie’ and ‘necktie’ (Figure 18). Many occupation oriented words such as ‘military person’ and ‘executive’ - which were not used to describe images of women at the higher 4% threshold - were used for both men and women at the lower 0.5% threshold, which could have caused the change in labels for men. The reverse was not true. Descriptive words used to describe women were still uncommon amongst men.
有趣的是,当我们将这一组标签的阈值降低到0.5%时,我们发现那些不成比例地描述男性的标签也转向了以外貌为导向的词汇,比如“西装”、“领带”和“领结”(图18)。许多以职业为导向的词汇,如“军人”和“高管”——在较高的4%阈值下并未用于描述女性的图像——在较低的0.5%阈值时却被用于男性和女性,这可能导致了男性标签的变化。情况则不反之。用于描述女性的描述性词汇在男性中仍然不常见。
Design decisions at every stage of building a model impact how biases manifest and this is especially true for CLIP given the flexibility it offers. In addition to choices about training data and model architecture, decisions about things like class designs and thresholding values can alter the labels a model outputs and as a result heighten or lower certain kinds of harm, such as those described by Crawford 2017. People designing and developing models and AI systems have considerable power. Decisions about things like class design are a key determiner not only of model performance, but also of how and in what contexts model biases manifest.
在构建模型的每个阶段,设计决策都会影响偏差的表现,这对于 CLIP 尤其如此,因为它提供了很大的灵活性。除了关于训练数据和模型架构的选择之外,诸如类别设计和阈值设定等决策也会改变模型输出的标签,从而增加或减少某些类型的伤害,例如 Crawford 2017 所描述的。设计和开发模型及人工智能系统的人拥有相当大的权力。关于类别设计的决策不仅是模型性能的关键决定因素,也是模型偏差如何以及在何种情境下表现的关键决定因素。
These experiments are not comprehensive. They illustrate potential issues stemming from class design and other sources of bias, and are intended to spark inquiry.
这些实验并不全面。它们说明了可能源于类设计和其他偏差来源的问题,并旨在激发探索。
7.2 Surveillance
7.2 监控
We next sought to characterize model performance in relation to a downstream task for which there is significant societal sensitivity: surveillance. Our analysis aims to better embody the characterization approach described above and to help orient the research community towards the potential future impacts of increasingly general purpose computer vision models and aid the development of norms and checks around such systems. Our inclusion of surveillance is not intended to indicate enthusiasm for this domain - rather, we think surveillance is an important domain to try to make predictions about given its societal implications (Zuboff 2015; Browne 2015).
接下来,我们试图描述模型在一个具有重大社会敏感性的下游任务中的表现:监控。我们的分析旨在更好地体现上述描述的方法,并帮助研究社区关注日益通用的计算机视觉模型可能带来的未来影响,同时辅助制定有关此类系统的规范和检查措施。我们纳入监控领域并非表示对该领域的热衷——相反,我们认为监控是一个重要的领域,值得尝试进行预测,因为其具有社会影响(Zuboff 2015;Browne 2015)。
We measure the model’s performance on classification of images from CCTV cameras and zero-shot celebrity identification. We first tested model performance on low-resolution images captured from surveillance cameras (e.g. CCTV cameras). We used the VIRAT dataset (Oh et al. 2011) and data captured by Varadarajan & Odobez 2009, which both consist of real world outdoor scenes with non-actors.
我们测量模型在CCTV摄像头图像分类和零样本名人识别上的性能。我们首先测试了模型在从监控摄像头(例如CCTV摄像头)捕获的低分辨率图像上的性能。我们使用了VIRAT数据集(Oh 等,2011)以及Varadarajan & Odobez 2009 捕获的数据,这些数据集都包含真实世界的户外场景,且无演员参与。
Given CLIP’s flexible class construction, we tested 515 surveillance images captured from 12 different video sequences on self-constructed general classes for coarse and fine grained classification. Coarse classification required the model to correctly identify the main subject of the image (i.e. determine if the image was a picture of an empty parking lot, school campus, etc.). For fine-grained classification, the model had to choose between two options constructed to determine if the model could identify the presence/absence of smaller features in the image such as a person standing in the corner.
鉴于 CLIP 的灵活类别构建,我们在自建的一般类别上对来自 12 个不同视频序列的 515 张监控图像进行了粗粒度和细粒度分类测试。粗粒度分类要求模型正确识别图像的主要对象(即判断图像是否是空停车场、学校校园等的图片)。对于细粒度分类,模型必须在两个选项之间进行选择,以确定模型是否能够识别图像中较小特征的存在或不存在,例如角落里站着的人。
For coarse classification, we constructed the classes by hand-captioning the images ourselves to describe the contents of the image and there were always at least 6 options for the model to choose from. Additionally, we carried out a ‘stress test’ where the class set included at least one more caption for something that was ‘close’ to the image (for example, ‘parking lot with white car’ vs. ‘parking lot with red car’). We found that the model had a top-1 accuracy of 91.8% on the CCTV images for the initial evaluation. The accuracy dropped significantly to 51.1% for the second evaluation, with the model incorrectly choosing the ‘close’ answer 40.7% of the time.
对于粗分类,我们通过自己为图像添加手工说明来构建类别,以描述图像的内容,并且模型始终至少有6个选项可供选择。此外,我们进行了“压力测试”,其中类别集中至少包含一个与图像“接近”的描述(例如,“有白色汽车的停车场”与“有红色汽车的停车场”)。我们发现模型在初次评估的CCTV图像上Top-1准确率为91.8%。在第二次评估中,准确率显著下降至51.1%,模型在40.7%的情况下错误选择了“接近”的答案。
For fine-grained detection, the zero-shot model performed poorly, with results near random. Note that this experiment was targeted only towards detecting the presence or absence of small objects in image sequences.
对于细粒度检测,零样本模型表现不佳,结果接近随机。请注意,这个实验仅针对检测图像序列中小物体的存在与否。
We also tested CLIP’s zero-shot performance for ‘in the wild’ identity detection using the CelebA dataset[^8]. We did this to evaluate the model’s performance for identity detection using just the publicly available data it was pre-trained on. While we tested this on a dataset of celebrities who have a larger number of images on the internet, we hypothesize that the number of images in the pre-training data needed for the model to associate faces with names will keep decreasing as models get more powerful (see Table 8), which has significant societal implications (Garvie 2019). This mirrors recent developments in natural language processing, in which recent large language models trained on Internet data often exhibit a surprising ability to provide information related to relatively minor public figures (Brown et al. 2020).
我们还使用 CelebA 数据集[^8] 测试了 CLIP 在“野外”身份检测中的零-shot 性能。我们这样做是为了评估模型在仅使用其预训练时可公开获取的数据情况下的身份检测表现。虽然我们是在互联网上有大量图片的名人数据集上进行测试的,但我们假设,随着模型的能力增强,模型将人脸与姓名关联所需的预训练数据量会持续减少(见表 8),这具有重要的社会影响(Garvie 2019)。这与自然语言处理中的最新进展相呼应,近年来在互联网上训练的大型语言模型常常表现出意外的能力,能够提供与相对较小的公众人物相关的信息(Brown et al. 2020)。
We found that the model had 59.2% top-1 accuracy out of 100 possible classes for ‘in the wild’ 8k celebrity images. However, this performance dropped to 43.3% when we increased our class sizes to 1k celebrity names. This performance is not competitive when compared to production level models such as Google’s Celebrity Recognition [54]. However, what makes these results noteworthy is that this analysis was done using only zero-shot identification capabilities based on names inferred from pre-training data - we didn’t use any additional task-specific dataset, and so the (relatively) strong results further indicate that before deploying multimodal models, people will need to carefully study them for behaviors in a given context and domain.
我们发现,对于“自然环境下”的 8k 名人图像,模型在 100 个可能类别中的 top-1 准确率为 59.2%。然而,当我们将类别数量增加到 1k 个名人姓名时,这一性能下降到 43.3%。与谷歌的 Celebrity Recognition [54] 等生产级模型相比,这一性能并不具有竞争力。然而,使这些结果值得注意的是,这项分析仅使用基于从预训练数据推断的姓名进行的零-shot 识别能力完成——我们没有使用任何额外的任务特定数据集,因此(相对)较强的结果进一步表明,在部署多模态模型之前,人们需要仔细研究其在特定上下文和领域中的行为。
CLIP offers significant benefit for tasks that have relatively little data given its zero-shot capabilities. However, large datasets and high performing supervised models exist for many in-demand surveillance tasks such as facial recognition. As a result, CLIP’s comparative appeal for such uses is low. Additionally, CLIP is not designed for common surveillance-relevant tasks like object detection and semantic segmentation. This means it has limited use for certain surveillance tasks when models that are designed with these uses in mind such as Detectron2 (Wu et al. 2019) are widely available.
CLIP 在数据相对较少的任务中,由于其零样本能力,提供了显著的优势。然而,对于许多需求量大的监控任务(如人脸识别),存在大型数据集和高性能的监督模型。因此,CLIP 在此类用途上的相对吸引力较低。此外,CLIP 并未为常见的监控相关任务(如目标检测和语义分割)设计。这意味着,当有专门为这些用途设计的模型(如 Detectron2(Wu 等人,2019))广泛可用时,CLIP 在某些监控任务中的使用有限。
However, CLIP does unlock a certain aspect of usability given how it removes the need for training data. Thus, CLIP and similar models could enable bespoke, niche surveillance use cases for which no well-tailored models or datasets exist, and could lower the skill requirements to build such applications. As our experiments show, ZS CLIP displays non-trivial, but not exceptional, performance on a few surveillance relevant tasks today.
然而,鉴于 CLIP 消除了对训练数据的需求,它确实在某种程度上提高了可用性。因此,CLIP 和类似模型可能使定制的、利基的监控使用案例成为可能,而这些案例在现有条件下没有经过良好定制的模型或数据集,并且能够降低构建此类应用的技能要求。正如我们的实验所示,零样本 CLIP 在目前的一些与监控相关的任务上表现出了非同寻常但并不卓越的性能。
| Model | 100 Classes | 1k Classes | 2k Classes |
|---|---|---|---|
| CLIP L/14 | 59.2 | 43.3 | 42.2 |
| CLIP RN50x64 | 56.4 | 39.5 | 38.4 |
| CLIP RN50x16 | 52.7 | 37.4 | 36.3 |
| CLIP RN50x4 | 52.8 | 38.1 | 37.3 |
Table 8: CelebA Zero-Shot Top-1 Identity Recognition Accuracy
| 模型 | 100 类 | 1k 类 | 2k 类 |
|---|---|---|---|
| CLIP L/14 | 59.2 | 43.3 | 42.2 |
| CLIP RN50x64 | 56.4 | 39.5 | 38.4 |
| CLIP RN50x16 | 52.7 | 37.4 | 36.3 |
| CLIP RN50x4 | 52.8 | 38.1 | 37.3 |
表 8: CelebA 零样本 Top-1 身份识别准确率
7.3 Future Work
7.3 未来工作
This preliminary analysis is intended to illustrate some of the challenges that general purpose computer vision models pose and to give a glimpse into their biases and impacts. We hope that this work motivates future research on the characterization of the capabilities, shortcomings, and biases of such models, and we are excited to engage with the research community on such questions.
这项初步分析旨在说明通用计算机视觉模型所带来的一些挑战,并让人们了解它们的偏见和影响。我们希望这项工作能够激励未来对这些模型的能力、缺点和偏见的研究,我们也很高兴能就这些问题与研究社区进行交流。
We believe one good step forward is community exploration to further characterize the capabilities of models like CLIP and - crucially - identify application areas where they have promising performance and areas where they may have reduced performance[^9]. This process of characterization can help researchers increase the likelihood models are used beneficially by:
我们认为,一个良好的前进步骤是社区探索,以进一步描述像 CLIP 这样的模型的能力,并且——至关重要的是——识别它们在有前景的应用领域以及可能表现较差的领域。[^9] 这种特征化的过程可以帮助研究人员增加模型被有益使用的可能性,通过:
- • Identifying potentially beneficial downstream uses of models early in the research process, enabling other researchers to think about applications.
- • Surfacing tasks with significant sensitivity and a large set of societal stakeholders, which may call for intervention by policymakers.
- • Better characterizing biases in models, alerting other researchers to areas of concern and areas for interventions.
- • Creating suites of tests to evaluate systems like CLIP on, so we can better characterize model capabilities earlier in the development cycle.
- • Identifying potential failure modes and areas for further work.
- • 在研究过程早期识别模型可能带来的有益下游用途,使其他研究人员能够思考应用方向。
- • 揭示具有重大敏感性且涉及大量社会利益相关者的任务,这可能需要政策制定者的干预。
- • 更好地描述模型中的偏差,提醒其他研究人员关注问题领域和干预领域。
- • 创建评估系统(如 CLIP)的测试套件,从而在开发周期的早期更好地描述模型能力。
- • 识别潜在的失败模式和需要进一步研究的领域。
We plan to contribute to this work, and hope this analysis provides some motivating examples for subsequent research.
我们计划为这项工作做出贡献,并希望这一分析能为后续研究提供一些激励性的示例。
8 Related Work
8 相关工作
Any model that leverages written, spoken, signed or any other form of human language as part of its training signal is arguably using natural language as a source of supervision. This is an admittedly extremely broad area and covers most work in the field of distributional semantics including topic models (Blei et al. 2003), word, sentence, and paragraph vectors (Mikolov et al. 2013; Kiros et al. 2015; Le & Mikolov 2014), and language models (Bengio et al. 2003). It also includes much of the broader field of NLP that deals with predicting or modeling sequences of natural language in some way. Work in NLP intentionally leveraging natural language supervision in the form of explanations, feedback, instructions, and advice for tasks such as classification (as opposed to the commonly used representation of supervision as a set of arbitrarily encoded discrete category labels) has been explored in many creative and advanced ways. Dialog based learning (Weston 2016; Li et al. 2016; Hancock et al. 2019) develops techniques to learn from interactive natural language feedback in dialog. Several papers have leveraged semantic parsing to convert natural language explanations into features (Srivastava et al. 2017) or additional training labels (Hancock et al. 2018). More recently, ExpBERT (Murty et al. 2020) uses feature representations produced by conditioning a deep contextual language model on natural language explanations and descriptions of relations to improve performance on the task of relation extraction.
任何把书面、口头、手语或其他人类语言形式用作训练信号一部分的模型,都可以说是在用自然语言作监督来源。这诚然是极广的领域,覆盖分布语义学中的多数工作,包括主题模型(Blei 等 2003),词、句与段落向量(Mikolov 等 2013;Kiros 等 2015;Le & Mikolov 2014),以及语言模型(Bengio 等 2003)。它也包括 NLP 中以某种方式预测或建模自然语言序列的更广领域。在分类等任务上有意利用解释、反馈、指令与建议等形式的自然语言监督(而非把监督表示为任意编码的离散类别标签集合)的 NLP 工作,已以许多创造性与先进方式被探索。基于对话的学习(Weston 2016;Li 等 2016;Hancock 等 2019)发展了从对话中的交互式自然语言反馈学习的技术。若干论文利用语义解析,把自然语言解释转换为特征(Srivastava 等 2017)或额外训练标签(Hancock 等 2018)。更近的 ExpBERT(Murty 等 2020)使用以自然语言解释与关系描述为条件的深度上下文语言模型所产生的特征表示,以提升关系抽取任务性能。
CLIP is an example of using natural language as a training signal for learning about a domain other than language. In this context, the earliest use of the term natural language supervision that we are aware of is the work of Ramanathan et al. 2013 which showed that natural language descriptions could be used along side other sources of supervision to improve performance on the task of video event understanding. However, as mentioned in the introduction and approach section, methods of leveraging natural language descriptions in computer vision well predate the use of this specific term, especially for image retrieval (Mori et al. 1999) and object classification (Wang et al. 2009). Other early work leveraged tags (but not natural language) associated with images for the task of semantic segmentation (Barnard et al. 2003). More recently, He & Peng 2017 and Liang et al. 2020 demonstrated using natural language descriptions and explanations to improve fine-grained visual classification of birds. Others have investigated how grounded language can be used to improve visual representations and classifiers on the ShapeWorld dataset (Kuhnle & Copestake 2017; Andreas et al. 2017; Mu et al. 2019). Finally, techniques which combine natural language with reinforcement learning environments (Narasimhan et al. 2015) have demonstrated exciting emergent behaviors such as systematically accomplishing zero-shot tasks (Hill et al. 2019).
CLIP 是把自然语言用作学习语言以外领域的训练信号的例子。在此语境下,我们所知最早使用自然语言监督这一术语的工作是 Ramanathan 等 2013,他们表明自然语言描述可与其他监督来源一起用于提升视频事件理解任务性能。但正如引言与方法部分所述,在计算机视觉中利用自然语言描述的方法远早于这一特定术语的使用,尤其是在图像检索(Mori 等 1999)与物体分类(Wang 等 2009)中。其他早期工作利用与图像关联的标签(而非自然语言)做语义分割(Barnard 等 2003)。更近地,He & Peng 2017 与 Liang 等 2020 展示了用自然语言描述与解释提升鸟类细粒度视觉分类。还有人研究如何用 grounding 语言在 ShapeWorld 数据集上改善视觉表征与分类器(Kuhnle & Copestake 2017;Andreas 等 2017;Mu 等 2019)。最后,把自然语言与强化学习环境结合的技术(Narasimhan 等 2015)展示了令人兴奋的涌现行为,例如系统性地完成零样本任务(Hill 等 2019)。
CLIP’s pre-training task optimizes for text-image retrieval. This areas of research dates back to the mid-90s with the previously mentioned Mori et al. 1999 as representative of early work. While initial efforts focused primarily on predictive objectives over time research shifted towards learning joint multi-modal embedding spaces with techniques like kernel Canonical Correlation Analysis and various ranking objectives (Weston et al. 2010; Socher & Fei-Fei 2010; Hodosh et al. 2013). Over time work explored many combinations of training objective, transfer, and more expressive models and steadily improved performance (Frome et al. 2013; Socher et al. 2014; Karpathy et al. 2014; Kiros et al. 2014; Faghri et al. 2017).
CLIP 的预训练任务是优化文本-图像检索。该研究领域可以追溯到 90 年代中期,之前提到的 Mori 等人 1999 代表了早期的工作。虽然最初的研究主要集中在预测目标上,但随着时间的推移,研究逐渐转向学习联合多模态嵌入空间,采用的方法包括核典型相关分析和各种排序目标(Weston 等人 2010;Socher & Fei-Fei 2010;Hodosh 等人 2013)。随着时间的推移,研究探索了训练目标、迁移以及更具表达能力的模型的多种组合,并稳步提高了性能(Frome 等人 2013;Socher 等人 2014;Karpathy 等人 2014;Kiros 等人 2014;Faghri 等人 2017)。
Other work has leveraged natural language supervision for domains other than images. Stroud et al. 2020 explores large scale representation learning by training a system to pair descriptive text with videos instead of images. Several works have explored using dense spoken natural language supervision for videos (Miech et al. 2019; Miech et al. 2020b). When considered together with CLIP, these works suggest that large scale natural language supervision is a promising way to learn high quality perceptual systems for many domains. Alayrac et al. 2020 extended this line of work to an additional modality by adding raw audio as an additional supervision source and demonstrated benefits from combining all three sources of supervision.
其他工作已经利用自然语言监督来应用于图像以外的领域。Stroud 等人(2020)通过训练系统将描述性文本与视频而非图像配对,探索了大规模表示学习。几项工作已经探索了在视频中使用密集口语自然语言监督(Miech 等人,2019;Miech 等人,2020b)。当与 CLIP 一起考虑时,这些工作表明,大规模自然语言监督是一种学习高质量感知系统的有前景的方法,可应用于许多领域。Alayrac 等人(2020)将这条研究线路扩展到另一种模态,通过将原始音频作为额外的监督来源,并证明结合这三种监督来源能够带来益处。
As part of our work on CLIP we also construct a new dataset of image-text pairs. Modern work on image-text retrieval has relied on a set of crowd-sourced sentence level image caption evaluation datasets like Pascal1K (Rashtchian et al. 2010), Flickr8K (Hodosh et al. 2013), and Flickr30K (Young et al. 2014). However, these datasets are still relatively small and limit achievable performance. Several methods have been proposed to create larger datasets automatically with Ordonez et al. 2011 as a notable early example. In the deep learning era, Mithun et al. 2018 demonstrated an additional set of (image, text) pairs collected from the internet could improve retrieval performance and several new automatically constructed datasets such as Conceptual Captions (Sharma et al. 2018), LAIT (Qi et al. 2020), and OCR-CC (Yang et al. 2020) have been created. However, these datasets still use significantly more aggressive filtering or are designed for a specific task such as OCR and as a result are still much smaller than WIT with between 1 and 10 million training examples.
作为 CLIP 工作的一部分,我们还构建了一个新的图文对数据集。现代图文检索工作依赖一组众包句子级图像描述评测数据集,如 Pascal1K(Rashtchian 等 2010)、Flickr8K(Hodosh 等 2013)与 Flickr30K(Young 等 2014)。但这些数据集仍相对较小,限制了可达到的性能。已有若干方法被提出以自动创建更大数据集,Ordonez 等 2011 是早期著名例子。在深度学习时代,Mithun 等 2018 表明从互联网额外收集的(图像,文本)对可提升检索性能,并已创建 Conceptual Captions(Sharma 等 2018)、LAIT(Qi 等 2020)与 OCR-CC(Yang 等 2020)等若干新的自动构建数据集。但这些数据集仍使用明显更激进的过滤,或专为 OCR 等特定任务设计,因而仍远小于 WIT,训练样例在 100 万到 1000 万之间。
A related idea to CLIP is webly supervised learning. This line of work queries image search engines to build image datasets by querying for terms and uses the queries as the labels for the returned images (Fergus et al. 2005). Classifiers trained on these large but noisily labeled datasets can be competitive with those trained on smaller carefully labeled datasets. These image-query pairs are also often used to improve performance on standard datasets as additional training data (Chen & Gupta 2015). CLIP also uses search queries as part of its dataset creation process. However CLIP only uses full text sequences co-occuring with images as supervision rather than just the queries, which are often only a single word or short n-gram. We also restrict this step in CLIP to text only querying for sub-string matches while most webly supervised work uses standard image search engines which have their own complex retrieval and filtering pipelines that often involve computer vision systems. Of this line of work, Learning Everything about Anything: Webly-Supervised Visual Concept Learning (Divvala et al. 2014) has a notably similar ambition and goal as CLIP.
与 CLIP 相关的另一思路是网络监督(webly supervised)学习。该路线通过向图像搜索引擎查询词项来构建图像数据集,并用查询作为返回图像的标签(Fergus 等 2005)。在这些大规模但噪声标注的数据集上训练的分类器,可与在较小精细标注数据集上训练的分类器竞争。这些图像–查询对也常被用作额外训练数据以提升标准数据集上的性能(Chen & Gupta 2015)。CLIP 在数据集创建过程中也使用搜索查询。但 CLIP 仅用与图像共现的完整文本序列作监督,而非往往只是单词或短 n-gram 的查询本身。我们还把 CLIP 中这一步限制为仅做文本子串匹配查询,而多数网络监督学习使用标准图像搜索引擎,后者有自身复杂的检索与过滤流水线,且往往涉及计算机视觉系统。在该路线中,Learning Everything about Anything: Webly-Supervised Visual Concept Learning(Divvala 等 2014)与 CLIP 的抱负与目标尤为相似。
Finally, CLIP is related to a recent burst of activity on learning joint models of vision and language (Lu et al. 2019; Tan & Bansal 2019; Chen et al. 2019; Li et al. 2020b; Yu et al. 2020). This line of work focuses on richly connecting vision and language in order to solve complex downstream tasks such as visual question answering, visual commonsense reasoning, or multimodal entailment. These approaches leverage impressively engineered models which combine 3 (or more) pre-trained subsystems, typically an image feature model, a region proposal / object detection model, and a pre-trained masked language model such as BERT. These systems are then jointly fine-tuned via various training objectives on image-text pairs and applied to the aforementioned tasks and achieve impressive results. CLIP is instead focused on learning visual models from scratch via natural language supervision and does not densely connect the two domains with a joint attention model. The only interaction in a CLIP model between the image and text domain is a single dot product in a learned joint embedding space. We are excited to see CLIP hybridized with this line of work.
最后,CLIP 与近期视觉与语言联合建模的大量工作相关(Lu 等 2019;Tan & Bansal 2019;Chen 等 2019;Li 等 2020b;Yu 等 2020)。该路线聚焦于把视觉与语言丰富连接,以解决视觉问答、视觉常识推理或多模态蕴含等复杂下游任务。这些方法利用精心设计的模型,组合 3 个(或更多)预训练子系统,通常是图像特征模型、区域提议/物体检测模型,以及 BERT 等预训练掩码语言模型。再通过各种训练目标在图文对上联合微调,应用于上述任务并取得出色结果。CLIP 则聚焦于通过自然语言监督从头学习视觉模型,并不用联合注意力模型把两个领域稠密连接。CLIP 模型中图像与文本域之间的唯一交互,是在学到的联合嵌入空间中的一次点积。我们期待看到 CLIP 与该路线工作的杂交。
9 Conclusion
9 结论
We have investigated whether it is possible to transfer the success of task-agnostic web-scale pre-training in NLP to another domain. We find that adopting this formula results in similar behaviors emerging in the field of computer vision and discuss the social implications of this line of research. In order to optimize their training objective, CLIP models learn to perform a wide variety of tasks during pre-training. This task learning can then be leveraged via natural language prompting to enable zero-shot transfer to many existing datasets. At sufficient scale, the performance of this approach can be competitive with task-specific supervised models although there is still room for much improvement.
我们研究了是否有可能将自然语言处理领域中与任务无关的大规模网络预训练的成功转移到其他领域。我们发现,采用这种方法会在计算机视觉领域产生类似的行为,并讨论了这一研究方向的社会影响。为了优化训练目标,CLIP模型在预训练期间学习执行各种任务。然后可以通过自然语言提示利用这种任务学习,从而实现对许多现有数据集的零样本迁移。在足够的规模下,这种方法的性能可以与针对特定任务的监督模型相竞争,尽管仍有很大的改进空间。
Acknowledgments
致谢
We’d like to thank the millions of people involved in creating the data CLIP is trained on. We’d also like to thank Susan Zhang for her work on image conditional language models while at OpenAI, Ishaan Gulrajani for catching an error in the pseudocode, and Irene Solaiman, Miles Brundage, and Gillian Hadfield for their thoughtful feedback on the broader impacts section of the paper. We are also grateful to the Acceleration and Supercomputing teams at OpenAI for their critical work on software and hardware infrastructure this project used. Finally, we’d also like to thank the developers of the many software packages used throughout this project including, but not limited, to Numpy (Harris et al. 2020), SciPy (Virtanen et al. 2020), ftfy (Speer 2019), TensorFlow (Abadi et al. 2016), PyTorch (Paszke et al. 2019), pandas (pandas development team 2020), and scikit-learn (Pedregosa et al. 2011).
我们要感谢参与创建 CLIP 训练数据的数百万名人员。我们还要感谢 Susan Zhang 在 OpenAI 期间对图像条件语言模型的工作,Ishaan Gulrajani 指出伪代码中的一个错误,以及 Irene Solaiman、Miles Brundage 和 Gillian Hadfield 对论文中更广泛影响部分提出的宝贵意见。我们还感谢 OpenAI 的加速与超级计算团队,为本项目在软件和硬件基础设施方面的关键工作提供支持。最后,我们也要感谢本项目中使用的众多软件包的开发者,包括但不限于 Numpy (Harris et al. 2020)、SciPy (Virtanen et al. 2020)、ftfy (Speer 2019)、TensorFlow (Abadi et al. 2016)、PyTorch (Paszke et al. 2019)、pandas (pandas 开发团队 2020) 和 scikit-learn (Pedregosa et al. 2011).
References
参考文献
Abadi et al. (2016) Abadi, M., Barham, P., Chen, J., Chen, Z., Davis, A., Dean, J., Devin, M., Ghemawat, S., Irving, G., Isard, M., et al. Tensorflow: A system for large-scale machine learning. In 12th { { USENIX } } symposium on operating systems design and implementation ( { { OSDI } } 16) , pp. 265–283, 2016.
Alayrac et al. (2020) Alayrac, J.-B., Recasens, A., Schneider, R., Arandjelović, R., Ramapuram, J., De Fauw, J., Smaira, L., Dieleman, S., and Zisserman, A. Self-supervised multimodal versatile networks. arXiv preprint arXiv:2006.16228 , 2020.
Alcorn et al. (2019) Alcorn, M. A., Li, Q., Gong, Z., Wang, C., Mai, L., Ku, W.-S., and Nguyen, A. Strike (with) a pose: Neural networks are easily fooled by strange poses of familiar objects. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition , pp. 4845–4854, 2019.
Andreas et al. (2017) Andreas, J., Klein, D., and Levine, S. Learning with latent language. arXiv preprint arXiv:1711.00482 , 2017.
Assiri (2020) Assiri, Y. Stochastic optimization of plain convolutional neural networks with simple methods. arXiv preprint arXiv:2001.08856 , 2020.
Bachman et al. (2019) Bachman, P., Hjelm, R. D., and Buchwalter, W. Learning representations by maximizing mutual information across views. In Advances in Neural Information Processing Systems , pp. 15535–15545, 2019.
Barbu et al. (2019) Barbu, A., Mayo, D., Alverio, J., Luo, W., Wang, C., Gutfreund, D., Tenenbaum, J., and Katz, B. Objectnet: A large-scale bias-controlled dataset for pushing the limits of object recognition models. In Advances in Neural Information Processing Systems , pp. 9453–9463, 2019.
Barnard et al. (2003) Barnard, K., Duygulu, P., Forsyth, D., Freitas, N. d., Blei, D. M., and Jordan, M. I. Matching words and pictures. Journal of machine learning research , 3(Feb):1107–1135, 2003.
Bechmann & Bowker (2019) Bechmann, A. and Bowker, G. C. Unsupervised by any other name: Hidden layers of knowledge production in artificial intelligence on social media. Big Data & Society , 6(1):205395171881956, January 2019. doi: 10.1177/2053951718819569 . URL https://doi.org/10.1177/2053951718819569 .
Bengio et al. (2003) Bengio, Y., Ducharme, R., Vincent, P., and Jauvin, C. A neural probabilistic language model. Journal of machine learning research , 3(Feb):1137–1155, 2003.
Bhargava & Forsyth (2019) Bhargava, S. and Forsyth, D. Exposing and correcting the gender bias in image captioning datasets and models. arXiv preprint arXiv:1912.00578 , 2019.
Blei et al. (2003) Blei, D. M., Ng, A. Y., and Jordan, M. I. Latent dirichlet allocation. Journal of machine Learning research , 3(Jan):993–1022, 2003.
Bolukbasi et al. (2016) Bolukbasi, T., Chang, K.-W., Zou, J. Y., Saligrama, V., and Kalai, A. T. Man is to computer programmer as woman is to homemaker? debiasing word embeddings. Advances in neural information processing systems , 29:4349–4357, 2016.
Bowker & Star (2000) Bowker, G. C. and Star, S. L. Sorting things out: Classification and its consequences . MIT press, 2000.
Brown et al. (2020) Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. Language models are few-shot learners. arXiv preprint arXiv:2005.14165 , 2020.
Browne (2015) Browne, S. Dark Matters: Surveillance of Blackness . Duke University Press, 2015.
Bulent Sariyildiz et al. (2020) Bulent Sariyildiz, M., Perez, J., and Larlus, D. Learning visual representations with caption annotations. arXiv e-prints , pp. arXiv–2008, 2020.
Buolamwini & Gebru (2018) Buolamwini, J. and Gebru, T. Gender shades: Intersectional accuracy disparities in commercial gender classification. In Conference on fairness, accountability and transparency , pp. 77–91, 2018.
Carreira et al. (2019) Carreira, J., Noland, E., Hillier, C., and Zisserman, A. A short note on the kinetics-700 human action dataset. arXiv preprint arXiv:1907.06987 , 2019.
Chen et al. (2020a) Chen, M., Radford, A., Child, R., Wu, J., Jun, H., Luan, D., and Sutskever, I. Generative pretraining from pixels. In International Conference on Machine Learning , pp. 1691–1703. PMLR, 2020a.
Chen et al. (2016) Chen, T., Xu, B., Zhang, C., and Guestrin, C. Training deep nets with sublinear memory cost. arXiv preprint arXiv:1604.06174 , 2016.
Chen et al. (2020b) Chen, T., Kornblith, S., Norouzi, M., and Hinton, G. A simple framework for contrastive learning of visual representations. arXiv preprint arXiv:2002.05709 , 2020b.
Chen et al. (2020c) Chen, T., Kornblith, S., Swersky, K., Norouzi, M., and Hinton, G. Big self-supervised models are strong semi-supervised learners. arXiv preprint arXiv:2006.10029 , 2020c.
Chen & Gupta (2015) Chen, X. and Gupta, A. Webly supervised learning of convolutional networks. In Proceedings of the IEEE International Conference on Computer Vision , pp. 1431–1439, 2015.
Chen et al. (2020d) Chen, X., Fan, H., Girshick, R., and He, K. Improved baselines with momentum contrastive learning. arXiv preprint arXiv:2003.04297 , 2020d.
Chen et al. (2019) Chen, Y.-C., Li, L., Yu, L., Kholy, A. E., Ahmed, F., Gan, Z., Cheng, Y., and Liu, J. Uniter: Learning universal image-text representations. arXiv preprint arXiv:1909.11740 , 2019.
Cheng et al. (2017) Cheng, G., Han, J., and Lu, X. Remote sensing image scene classification: Benchmark and state of the art. Proceedings of the IEEE , 105(10):1865–1883, 2017.
Choi et al. (2019) Choi, D., Shallue, C. J., Nado, Z., Lee, J., Maddison, C. J., and Dahl, G. E. On empirical comparisons of optimizers for deep learning. arXiv preprint arXiv:1910.05446 , 2019.
Coates et al. (2011) Coates, A., Ng, A., and Lee, H. An analysis of single-layer networks in unsupervised feature learning. In Proceedings of the fourteenth international conference on artificial intelligence and statistics , pp. 215–223, 2011.
Crawford (2017) Crawford, K. The trouble with bias. NIPS 2017 Keynote , 2017. URL https://www.youtube.com/watch?v=fMym_BKWQzk .
Dai & Le (2015) Dai, A. M. and Le, Q. V. Semi-supervised sequence learning. In Advances in neural information processing systems , pp. 3079–3087, 2015.
D’Amour et al. (2020) D’Amour, A., Heller, K., Moldovan, D., Adlam, B., Alipanahi, B., Beutel, A., Chen, C., Deaton, J., Eisenstein, J., Hoffman, M. D., et al. Underspecification presents challenges for credibility in modern machine learning. arXiv preprint arXiv:2011.03395 , 2020.
Deng et al. (2009) Deng, J., Dong, W., Socher, R., Li, L.-J., Li, K., and Fei-Fei, L. ImageNet: A Large-Scale Hierarchical Image Database. In CVPR09 , 2009.
Deng et al. (2012) Deng, J., Berg, A. C., Satheesh, S., Su, H., Khosla, A., and Fei-Fei, L. Ilsvrc 2012, 2012. URL http://www.image-net.org/challenges/LSVRC/2012/ .
Desai & Johnson (2020) Desai, K. and Johnson, J. Virtex: Learning visual representations from textual annotations. arXiv preprint arXiv:2006.06666 , 2020.
Devlin et al. (2018) Devlin, J., Chang, M.-W., Lee, K., and Toutanova, K. Bert: Pre-training of deep bidirectional transformers for language understanding. arXiv preprint arXiv:1810.04805 , 2018.
Dhariwal et al. (2020) Dhariwal, P., Jun, H., Payne, C., Kim, J. W., Radford, A., and Sutskever, I. Jukebox: A generative model for music. arXiv preprint arXiv:2005.00341 , 2020.
Divvala et al. (2014) Divvala, S. K., Farhadi, A., and Guestrin, C. Learning everything about anything: Webly-supervised visual concept learning. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition , pp. 3270–3277, 2014.
Dodge & Karam (2017) Dodge, S. and Karam, L. A study and comparison of human and deep learning recognition performance under visual distortions. In 2017 26th international conference on computer communication and networks (ICCCN) , pp. 1–7. IEEE, 2017.
Dosovitskiy et al. (2020) Dosovitskiy, A., Beyer, L., Kolesnikov, A., Weissenborn, D., Zhai, X., Unterthiner, T., Dehghani, M., Minderer, M., Heigold, G., Gelly, S., et al. An image is worth 16x16 words: Transformers for image recognition at scale. arXiv preprint arXiv:2010.11929 , 2020.
Elhoseiny et al. (2013) Elhoseiny, M., Saleh, B., and Elgammal, A. Write a classifier: Zero-shot learning using purely textual descriptions. In Proceedings of the IEEE International Conference on Computer Vision , pp. 2584–2591, 2013.
Faghri et al. (2017) Faghri, F., Fleet, D. J., Kiros, J. R., and Fidler, S. Vse++: Improving visual-semantic embeddings with hard negatives. arXiv preprint arXiv:1707.05612 , 2017.
Fergus et al. (2005) Fergus, R., Fei-Fei, L., Perona, P., and Zisserman, A. Learning object categories from google’s image search. In Tenth IEEE International Conference on Computer Vision (ICCV’05) Volume 1 , volume 2, pp. 1816–1823. IEEE, 2005.
Frome et al. (2013) Frome, A., Corrado, G. S., Shlens, J., Bengio, S., Dean, J., Ranzato, M., and Mikolov, T. Devise: A deep visual-semantic embedding model. In Advances in neural information processing systems , pp. 2121–2129, 2013.
Gan et al. (2020) Gan, Z., Chen, Y.-C., Li, L., Zhu, C., Cheng, Y., and Liu, J. Large-scale adversarial training for vision-and-language representation learning. arXiv preprint arXiv:2006.06195 , 2020.
Gao et al. (2020) Gao, T., Fisch, A., and Chen, D. Making pre-trained language models better few-shot learners. arXiv preprint arXiv:2012.15723 , 2020.
Garvie (2019) Garvie, C., May 2019. URL https://www.flawedfacedata.com/ .
Geiger et al. (2012) Geiger, A., Lenz, P., and Urtasun, R. Are we ready for autonomous driving? the kitti vision benchmark suite. In Conference on Computer Vision and Pattern Recognition (CVPR) , 2012.
Geirhos et al. (2018) Geirhos, R., Rubisch, P., Michaelis, C., Bethge, M., Wichmann, F. A., and Brendel, W. Imagenet-trained cnns are biased towards texture; increasing shape bias improves accuracy and robustness. arXiv preprint arXiv:1811.12231 , 2018.
Geirhos et al. (2020) Geirhos, R., Jacobsen, J.-H., Michaelis, C., Zemel, R., Brendel, W., Bethge, M., and Wichmann, F. A. Shortcut learning in deep neural networks. arXiv preprint arXiv:2004.07780 , 2020.
Gomez et al. (2017) Gomez, L., Patel, Y., Rusiñol, M., Karatzas, D., and Jawahar, C. Self-supervised learning of visual features through embedding images into text topic spaces. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition , pp. 4230–4239, 2017.
Goodfellow et al. (2014) Goodfellow, I. J., Shlens, J., and Szegedy, C. Explaining and harnessing adversarial examples. arXiv preprint arXiv:1412.6572 , 2014.
Goodfellow et al. (2015) Goodfellow, I. J., Erhan, D., Carrier, P. L., Courville, A., Mirza, M., Hamner, B., Cukierski, W., Tang, Y., Thaler, D., Lee, D.-H., et al. Challenges in representation learning: A report on three machine learning contests. Neural Networks , 64:59–63, 2015.
(54) Google. Google cloud api: Celebrity recognition. URL https://cloud.google.com/vision/docs/celebrity-recognition .
Griewank & Walther (2000) Griewank, A. and Walther, A. Algorithm 799: revolve: an implementation of checkpointing for the reverse or adjoint mode of computational differentiation. ACM Transactions on Mathematical Software (TOMS) , 26(1):19–45, 2000.
Grill et al. (2020) Grill, J.-B., Strub, F., Altché, F., Tallec, C., Richemond, P. H., Buchatskaya, E., Doersch, C., Pires, B. A., Guo, Z. D., Azar, M. G., et al. Bootstrap your own latent: A new approach to self-supervised learning. arXiv preprint arXiv:2006.07733 , 2020.
Ha et al. (2016) Ha, D., Dai, A., and Le, Q. V. Hypernetworks. arXiv preprint arXiv:1609.09106 , 2016.
Hancock et al. (2018) Hancock, B., Bringmann, M., Varma, P., Liang, P., Wang, S., and Ré, C. Training classifiers with natural language explanations. In Proceedings of the conference. Association for Computational Linguistics. Meeting , volume 2018, pp. 1884. NIH Public Access, 2018.
Hancock et al. (2019) Hancock, B., Bordes, A., Mazare, P.-E., and Weston, J. Learning from dialogue after deployment: Feed yourself, chatbot! arXiv preprint arXiv:1901.05415 , 2019.
Harris et al. (2020) Harris, C. R., Millman, K. J., van der Walt, S. J., Gommers, R., Virtanen, P., Cournapeau, D., Wieser, E., Taylor, J., Berg, S., Smith, N. J., Kern, R., Picus, M., Hoyer, S., van Kerkwijk, M. H., Brett, M., Haldane, A., Fernández del Río, J., Wiebe, M., Peterson, P., Gérard-Marchant, P., Sheppard, K., Reddy, T., Weckesser, W., Abbasi, H., Gohlke, C., and Oliphant, T. E. Array programming with NumPy. Nature , 585:357–362, 2020. doi: 10.1038/s41586-020-2649-2 .
Hays & Efros (2008) Hays, J. and Efros, A. A. Im2gps: estimating geographic information from a single image. In 2008 ieee conference on computer vision and pattern recognition , pp. 1–8. IEEE, 2008.
He et al. (2015) He, K., Zhang, X., Ren, S., and Sun, J. Delving deep into rectifiers: Surpassing human-level performance on imagenet classification. In Proceedings of the IEEE international conference on computer vision , pp. 1026–1034, 2015.
He et al. (2016a) He, K., Zhang, X., Ren, S., and Sun, J. Deep residual learning for image recognition. In Proceedings of the IEEE conference on computer vision and pattern recognition , pp. 770–778, 2016a.
He et al. (2016b) He, K., Zhang, X., Ren, S., and Sun, J. Deep residual learning for image recognition. In Proceedings of the IEEE conference on computer vision and pattern recognition , pp. 770–778, 2016b.
He et al. (2020) He, K., Fan, H., Wu, Y., Xie, S., and Girshick, R. Momentum contrast for unsupervised visual representation learning. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition , pp. 9729–9738, 2020.
He et al. (2019) He, T., Zhang, Z., Zhang, H., Zhang, Z., Xie, J., and Li, M. Bag of tricks for image classification with convolutional neural networks. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition , pp. 558–567, 2019.
He & Peng (2017) He, X. and Peng, Y. Fine-grained image classification via combining vision and language. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition , pp. 5994–6002, 2017.
Helber et al. (2019) Helber, P., Bischke, B., Dengel, A., and Borth, D. Eurosat: A novel dataset and deep learning benchmark for land use and land cover classification. IEEE Journal of Selected Topics in Applied Earth Observations and Remote Sensing , 12(7):2217–2226, 2019.
Henaff (2020) Henaff, O. Data-efficient image recognition with contrastive predictive coding. In International Conference on Machine Learning , pp. 4182–4192. PMLR, 2020.
Hendrycks & Dietterich (2019) Hendrycks, D. and Dietterich, T. Benchmarking neural network robustness to common corruptions and perturbations. arXiv preprint arXiv:1903.12261 , 2019.
Hendrycks & Gimpel (2016) Hendrycks, D. and Gimpel, K. Gaussian error linear units (gelus). arXiv preprint arXiv:1606.08415 , 2016.
Hendrycks et al. (2019) Hendrycks, D., Zhao, K., Basart, S., Steinhardt, J., and Song, D. Natural adversarial examples. arXiv preprint arXiv:1907.07174 , 2019.
Hendrycks et al. (2020a) Hendrycks, D., Basart, S., Mu, N., Kadavath, S., Wang, F., Dorundo, E., Desai, R., Zhu, T., Parajuli, S., Guo, M., et al. The many faces of robustness: A critical analysis of out-of-distribution generalization. arXiv preprint arXiv:2006.16241 , 2020a.
Hendrycks et al. (2020b) Hendrycks, D., Liu, X., Wallace, E., Dziedzic, A., Krishnan, R., and Song, D. Pretrained transformers improve out-of-distribution robustness. arXiv preprint arXiv:2004.06100 , 2020b.
Hestness et al. (2017) Hestness, J., Narang, S., Ardalani, N., Diamos, G., Jun, H., Kianinejad, H., Patwary, M., Ali, M., Yang, Y., and Zhou, Y. Deep learning scaling is predictable, empirically. arXiv preprint arXiv:1712.00409 , 2017.
Hill et al. (2019) Hill, F., Lampinen, A., Schneider, R., Clark, S., Botvinick, M., McClelland, J. L., and Santoro, A. Environmental drivers of systematicity and generalization in a situated agent. In International Conference on Learning Representations , 2019.
Hodosh et al. (2013) Hodosh, M., Young, P., and Hockenmaier, J. Framing image description as a ranking task: Data, models and evaluation metrics. Journal of Artificial Intelligence Research , 47:853–899, 2013.
Hongsuck Seo et al. (2018) Hongsuck Seo, P., Weyand, T., Sim, J., and Han, B. Cplanet: Enhancing image geolocalization by combinatorial partitioning of maps. In Proceedings of the European Conference on Computer Vision (ECCV) , pp. 536–551, 2018.
Howard & Ruder (2018) Howard, J. and Ruder, S. Universal language model fine-tuning for text classification. arXiv preprint arXiv:1801.06146 , 2018.
Ilyas et al. (2019) Ilyas, A., Santurkar, S., Tsipras, D., Engstrom, L., Tran, B., and Madry, A. Adversarial examples are not bugs, they are features. In Advances in Neural Information Processing Systems , pp. 125–136, 2019.
Ioffe & Szegedy (2015) Ioffe, S. and Szegedy, C. Batch normalization: Accelerating deep network training by reducing internal covariate shift. arXiv preprint arXiv:1502.03167 , 2015.
Jaderberg et al. (2014) Jaderberg, M., Simonyan, K., Vedaldi, A., and Zisserman, A. Deep structured output learning for unconstrained text recognition. arXiv preprint arXiv:1412.5903 , 2014.
Jaderberg et al. (2015) Jaderberg, M., Simonyan, K., Zisserman, A., et al. Spatial transformer networks. Advances in neural information processing systems , 28:2017–2025, 2015.
Johnson et al. (2017) Johnson, J., Hariharan, B., van der Maaten, L., Fei-Fei, L., Lawrence Zitnick, C., and Girshick, R. Clevr: A diagnostic dataset for compositional language and elementary visual reasoning. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition , pp. 2901–2910, 2017.
Joulin et al. (2016) Joulin, A., Van Der Maaten, L., Jabri, A., and Vasilache, N. Learning visual features from large weakly supervised data. In European Conference on Computer Vision , pp. 67–84. Springer, 2016.
Kalfaoglu et al. (2020) Kalfaoglu, M., Kalkan, S., and Alatan, A. A. Late temporal modeling in 3d cnn architectures with bert for action recognition. arXiv preprint arXiv:2008.01232 , 2020.
Kaplan et al. (2020) Kaplan, J., McCandlish, S., Henighan, T., Brown, T. B., Chess, B., Child, R., Gray, S., Radford, A., Wu, J., and Amodei, D. Scaling laws for neural language models. arXiv preprint arXiv:2001.08361 , 2020.
Karpathy et al. (2014) Karpathy, A., Joulin, A., and Fei-Fei, L. F. Deep fragment embeddings for bidirectional image sentence mapping. In Advances in neural information processing systems , pp. 1889–1897, 2014.
Keyes (2018) Keyes, O. The misgendering machines: Trans/hci implications of automatic gender recognition. Proceedings of the ACM on Human-Computer Interaction , 2(CSCW):1–22, 2018.
Kiela et al. (2020) Kiela, D., Firooz, H., Mohan, A., Goswami, V., Singh, A., Ringshia, P., and Testuggine, D. The hateful memes challenge: Detecting hate speech in multimodal memes. arXiv preprint arXiv:2005.04790 , 2020.
Kingma & Ba (2014) Kingma, D. P. and Ba, J. Adam: A method for stochastic optimization. arXiv preprint arXiv:1412.6980 , 2014.
Kiros et al. (2014) Kiros, R., Salakhutdinov, R., and Zemel, R. S. Unifying visual-semantic embeddings with multimodal neural language models. arXiv preprint arXiv:1411.2539 , 2014.
Kiros et al. (2015) Kiros, R., Zhu, Y., Salakhutdinov, R. R., Zemel, R., Urtasun, R., Torralba, A., and Fidler, S. Skip-thought vectors. Advances in neural information processing systems , 28:3294–3302, 2015.
Kolesnikov et al. (2019) Kolesnikov, A., Beyer, L., Zhai, X., Puigcerver, J., Yung, J., Gelly, S., and Houlsby, N. Large scale learning of general visual representations for transfer. arXiv preprint arXiv:1912.11370 , 2019.
Kornblith et al. (2019) Kornblith, S., Shlens, J., and Le, Q. V. Do better imagenet models transfer better? In Proceedings of the IEEE conference on computer vision and pattern recognition , pp. 2661–2671, 2019.
Krishna et al. (2017) Krishna, R., Zhu, Y., Groth, O., Johnson, J., Hata, K., Kravitz, J., Chen, S., Kalantidis, Y., Li, L.-J., Shamma, D. A., et al. Visual genome: Connecting language and vision using crowdsourced dense image annotations. International journal of computer vision , 123(1):32–73, 2017.
Krizhevsky et al. (2012) Krizhevsky, A., Sutskever, I., and Hinton, G. E. Imagenet classification with deep convolutional neural networks. In Advances in neural information processing systems , pp. 1097–1105, 2012.
Kuhnle & Copestake (2017) Kuhnle, A. and Copestake, A. Shapeworld-a new test methodology for multimodal language understanding. arXiv preprint arXiv:1704.04517 , 2017.
Kärkkäinen & Joo (2019) Kärkkäinen, K. and Joo, J. Fairface: Face attribute dataset for balanced race, gender, and age, 2019.
Lake et al. (2016) Lake, B. M., Ullman, T. D., Tenenbaum, J. B., and Gershman, S. J. Building machines that learn and think like people, 2016.
Lampert et al. (2009) Lampert, C. H., Nickisch, H., and Harmeling, S. Learning to detect unseen object classes by between-class attribute transfer. In 2009 IEEE Conference on Computer Vision and Pattern Recognition , pp. 951–958. IEEE, 2009.
Larochelle et al. (2008) Larochelle, H., Erhan, D., and Bengio, Y. Zero-data learning of new tasks. 2008.
Le & Mikolov (2014) Le, Q. and Mikolov, T. Distributed representations of sentences and documents. In International conference on machine learning , pp. 1188–1196, 2014.
(104) LeCun, Y. The mnist database of handwritten digits. http://yann. lecun. com/exdb/mnist/ .
(105) Lee, D.-H. Pseudo-label: The simple and efficient semi-supervised learning method for deep neural networks.
Lei Ba et al. (2015) Lei Ba, J., Swersky, K., Fidler, S., et al. Predicting deep zero-shot convolutional neural networks using textual descriptions. In Proceedings of the IEEE International Conference on Computer Vision , pp. 4247–4255, 2015.
Li et al. (2017) Li, A., Jabri, A., Joulin, A., and van der Maaten, L. Learning visual n-grams from web data. In Proceedings of the IEEE International Conference on Computer Vision , pp. 4183–4192, 2017.
Li et al. (2020a) Li, G., Duan, N., Fang, Y., Gong, M., and Jiang, D. Unicoder-vl: A universal encoder for vision and language by cross-modal pre-training. 2020a.
Li et al. (2016) Li, J., Miller, A. H., Chopra, S., Ranzato, M., and Weston, J. Learning through dialogue interactions by asking questions. arXiv preprint arXiv:1612.04936 , 2016.
Li et al. (2020b) Li, X., Yin, X., Li, C., Hu, X., Zhang, P., Zhang, L., Wang, L., Hu, H., Dong, L., Wei, F., et al. Oscar: Object-semantics aligned pre-training for vision-language tasks. arXiv preprint arXiv:2004.06165 , 2020b.
Liang et al. (2020) Liang, W., Zou, J., and Yu, Z. Alice: Active learning with contrastive natural language explanations. arXiv preprint arXiv:2009.10259 , 2020.
Lin et al. (2014) Lin, T.-Y., Maire, M., Belongie, S., Hays, J., Perona, P., Ramanan, D., Dollár, P., and Zitnick, C. L. Microsoft coco: Common objects in context. In European conference on computer vision , pp. 740–755. Springer, 2014.
Linzen (2020) Linzen, T. How can we accelerate progress towards human-like linguistic generalization? arXiv preprint arXiv:2005.00955 , 2020.
Lippe et al. (2020) Lippe, P., Holla, N., Chandra, S., Rajamanickam, S., Antoniou, G., Shutova, E., and Yannakoudakis, H. A multimodal framework for the detection of hateful memes. arXiv preprint arXiv:2012.12871 , 2020.
Liu et al. (2018) Liu, P. J., Saleh, M., Pot, E., Goodrich, B., Sepassi, R., Kaiser, L., and Shazeer, N. Generating wikipedia by summarizing long sequences. arXiv preprint arXiv:1801.10198 , 2018.
Locatello et al. (2020) Locatello, F., Bauer, S., Lucic, M., Rätsch, G., Gelly, S., Schölkopf, B., and Bachem, O. A sober look at the unsupervised learning of disentangled representations and their evaluation. arXiv preprint arXiv:2010.14766 , 2020.
Loshchilov & Hutter (2016) Loshchilov, I. and Hutter, F. Sgdr: Stochastic gradient descent with warm restarts. arXiv preprint arXiv:1608.03983 , 2016.
Loshchilov & Hutter (2017) Loshchilov, I. and Hutter, F. Decoupled weight decay regularization. arXiv preprint arXiv:1711.05101 , 2017.
Lu et al. (2019) Lu, J., Batra, D., Parikh, D., and Lee, S. Vilbert: Pretraining task-agnostic visiolinguistic representations for vision-and-language tasks. In Advances in Neural Information Processing Systems , pp. 13–23, 2019.
Lu et al. (2020) Lu, Z., Xiong, X., Li, Y., Stroud, J., and Ross, D. Leveraging weakly supervised data and pose representation for action recognition, 2020. URL https://www.youtube.com/watch?v=KOQFxbPPLOE&t=1390s .
Lucic et al. (2018) Lucic, M., Kurach, K., Michalski, M., Gelly, S., and Bousquet, O. Are gans created equal? a large-scale study. Advances in neural information processing systems , 31:700–709, 2018.
Mahajan et al. (2018) Mahajan, D., Girshick, R., Ramanathan, V., He, K., Paluri, M., Li, Y., Bharambe, A., and van der Maaten, L. Exploring the limits of weakly supervised pretraining. In Proceedings of the European Conference on Computer Vision (ECCV) , pp. 181–196, 2018.
McCann et al. (2017) McCann, B., Bradbury, J., Xiong, C., and Socher, R. Learned in translation: Contextualized word vectors. In Advances in neural information processing systems , pp. 6294–6305, 2017.
McCann et al. (2018) McCann, B., Keskar, N. S., Xiong, C., and Socher, R. The natural language decathlon: Multitask learning as question answering. arXiv preprint arXiv:1806.08730 , 2018.
Micikevicius et al. (2017) Micikevicius, P., Narang, S., Alben, J., Diamos, G., Elsen, E., Garcia, D., Ginsburg, B., Houston, M., Kuchaiev, O., Venkatesh, G., et al. Mixed precision training. arXiv preprint arXiv:1710.03740 , 2017.
Miech et al. (2019) Miech, A., Zhukov, D., Alayrac, J.-B., Tapaswi, M., Laptev, I., and Sivic, J. Howto100m: Learning a text-video embedding by watching hundred million narrated video clips. In Proceedings of the IEEE international conference on computer vision , pp. 2630–2640, 2019.
Miech et al. (2020a) Miech, A., Alayrac, J.-B., Laptev, I., Sivic, J., and Zisserman, A. Rareact: A video dataset of unusual interactions. arXiv preprint arXiv:2008.01018 , 2020a.
Miech et al. (2020b) Miech, A., Alayrac, J.-B., Smaira, L., Laptev, I., Sivic, J., and Zisserman, A. End-to-end learning of visual representations from uncurated instructional videos. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition , pp. 9879–9889, 2020b.
Mikolov et al. (2013) Mikolov, T., Sutskever, I., Chen, K., Corrado, G. S., and Dean, J. Distributed representations of words and phrases and their compositionality. Advances in neural information processing systems , 26:3111–3119, 2013.
Miller et al. (2020) Miller, J., Krauth, K., Recht, B., and Schmidt, L. The effect of natural distribution shift on question answering models. arXiv preprint arXiv:2004.14444 , 2020.
Mishra et al. (2012) Mishra, A., Alahari, K., and Jawahar, C. Scene text recognition using higher order language priors. 2012.
Mithun et al. (2018) Mithun, N. C., Panda, R., Papalexakis, E. E., and Roy-Chowdhury, A. K. Webly supervised joint embedding for cross-modal image-text retrieval. In Proceedings of the 26th ACM international conference on Multimedia , pp. 1856–1864, 2018.
Mori et al. (1999) Mori, Y., Takahashi, H., and Oka, R. Image-to-word transformation based on dividing and vector quantizing images with words. Citeseer, 1999.
Mu et al. (2019) Mu, J., Liang, P., and Goodman, N. Shaping visual representations with language for few-shot classification. arXiv preprint arXiv:1911.02683 , 2019.
Muller-Budack et al. (2018) Muller-Budack, E., Pustu-Iren, K., and Ewerth, R. Geolocation estimation of photos using a hierarchical model and scene classification. In Proceedings of the European Conference on Computer Vision (ECCV) , pp. 563–579, 2018.
Murty et al. (2020) Murty, S., Koh, P. W., and Liang, P. Expbert: Representation engineering with natural language explanations. arXiv preprint arXiv:2005.01932 , 2020.
Narasimhan et al. (2015) Narasimhan, K., Kulkarni, T., and Barzilay, R. Language understanding for text-based games using deep reinforcement learning. arXiv preprint arXiv:1506.08941 , 2015.
Netzer et al. (2011) Netzer, Y., Wang, T., Coates, A., Bissacco, A., Wu, B., and Ng, A. Y. Reading digits in natural images with unsupervised feature learning. 2011.
Noble (2018) Noble, S. U. Algorithms of oppression: How search engines reinforce racism. 2018.
Nosek et al. (2002) Nosek, B. A., Banaji, M. R., and Greenwald, A. G. Harvesting implicit group attitudes and beliefs from a demonstration web site. Group Dynamics: Theory, Research, and Practice , 6(1):101, 2002.
Oh et al. (2011) Oh, S., Hoogs, A., Perera, A., Cuntoor, N., Chen, C.-C., Lee, J. T., Mukherjee, S., Aggarwal, J., Lee, H., Davis, L., et al. A large-scale benchmark dataset for event recognition in surveillance video. In CVPR 2011 , pp. 3153–3160. IEEE, 2011.
Oliver et al. (2018) Oliver, A., Odena, A., Raffel, C. A., Cubuk, E. D., and Goodfellow, I. Realistic evaluation of deep semi-supervised learning algorithms. Advances in neural information processing systems , 31:3235–3246, 2018.
Oord et al. (2018) Oord, A. v. d., Li, Y., and Vinyals, O. Representation learning with contrastive predictive coding. arXiv preprint arXiv:1807.03748 , 2018.
Ordonez et al. (2011) Ordonez, V., Kulkarni, G., and Berg, T. Im2text: Describing images using 1 million captioned photographs. Advances in neural information processing systems , 24:1143–1151, 2011.
pandas development team (2020) pandas development team, T. pandas-dev/pandas: Pandas, February 2020. URL https://doi.org/10.5281/zenodo.3509134 .
Parkhi et al. (2012) Parkhi, O. M., Vedaldi, A., Zisserman, A., and Jawahar, C. V. Cats and dogs. In IEEE Conference on Computer Vision and Pattern Recognition , 2012.
Paszke et al. (2019) Paszke, A., Gross, S., Massa, F., Lerer, A., Bradbury, J., Chanan, G., Killeen, T., Lin, Z., Gimelshein, N., Antiga, L., Desmaison, A., Kopf, A., Yang, E., DeVito, Z., Raison, M., Tejani, A., Chilamkurthy, S., Steiner, B., Fang, L., Bai, J., and Chintala, S. Pytorch: An imperative style, high-performance deep learning library. In Advances in Neural Information Processing Systems 32 , pp. 8024–8035, 2019.
Pedregosa et al. (2011) Pedregosa, F., Varoquaux, G., Gramfort, A., Michel, V., Thirion, B., Grisel, O., Blondel, M., Prettenhofer, P., Weiss, R., Dubourg, V., Vanderplas, J., Passos, A., Cournapeau, D., Brucher, M., Perrot, M., and Duchesnay, E. Scikit-learn: Machine learning in Python. Journal of Machine Learning Research , 12:2825–2830, 2011.
Pennington et al. (2014) Pennington, J., Socher, R., and Manning, C. D. Glove: Global vectors for word representation. In Proceedings of the 2014 conference on empirical methods in natural language processing (EMNLP) , pp. 1532–1543, 2014.
Peters et al. (2018) Peters, M. E., Neumann, M., Iyyer, M., Gardner, M., Clark, C., Lee, K., and Zettlemoyer, L. Deep contextualized word representations. arXiv preprint arXiv:1802.05365 , 2018.
Qi et al. (2020) Qi, D., Su, L., Song, J., Cui, E., Bharti, T., and Sacheti, A. Imagebert: Cross-modal pre-training with large-scale weak-supervised image-text data. arXiv preprint arXiv:2001.07966 , 2020.
Quattoni et al. (2007) Quattoni, A., Collins, M., and Darrell, T. Learning visual representations using images with captions. In 2007 IEEE Conference on Computer Vision and Pattern Recognition , pp. 1–8. IEEE, 2007.
Radford et al. (2018) Radford, A., Narasimhan, K., Salimans, T., and Sutskever, I. Improving language understanding by generative pre-training, 2018.
Radford et al. (2019) Radford, A., Wu, J., Child, R., Luan, D., Amodei, D., and Sutskever, I. Language models are unsupervised multitask learners. 2019.
Raffel et al. (2019) Raffel, C., Shazeer, N., Roberts, A., Lee, K., Narang, S., Matena, M., Zhou, Y., Li, W., and Liu, P. J. Exploring the limits of transfer learning with a unified text-to-text transformer. arXiv preprint arXiv:1910.10683 , 2019.
Raji et al. (2020) Raji, I. D., Gebru, T., Mitchell, M., Buolamwini, J., Lee, J., and Denton, E. Saving face: Investigating the ethical concerns of facial recognition auditing, 2020.
Ramanathan et al. (2013) Ramanathan, V., Liang, P., and Fei-Fei, L. Video event understanding using natural language descriptions. In Proceedings of the IEEE International Conference on Computer Vision , pp. 905–912, 2013.
Rashtchian et al. (2010) Rashtchian, C., Young, P., Hodosh, M., and Hockenmaier, J. Collecting image annotations using amazon’s mechanical turk. In Proceedings of the NAACL HLT 2010 Workshop on Creating Speech and Language Data with Amazon’s Mechanical Turk , pp. 139–147, 2010.
Recht et al. (2019) Recht, B., Roelofs, R., Schmidt, L., and Shankar, V. Do imagenet classifiers generalize to imagenet? arXiv preprint arXiv:1902.10811 , 2019.
Salimans & Kingma (2016) Salimans, T. and Kingma, D. P. Weight normalization: A simple reparameterization to accelerate training of deep neural networks. In Advances in neural information processing systems , pp. 901–909, 2016.
Scheuerman et al. (2019) Scheuerman, M. K., Paul, J. M., and Brubaker, J. R. How computers see gender: An evaluation of gender classification in commercial facial analysis services. Proceedings of the ACM on Human-Computer Interaction , 3(CSCW):1–33, 2019.
Schwemmer et al. (2020) Schwemmer, C., Knight, C., Bello-Pardo, E. D., Oklobdzija, S., Schoonvelde, M., and Lockhart, J. W. Diagnosing gender bias in image recognition systems. Socius , 6:2378023120967171, 2020.
Sennrich et al. (2015) Sennrich, R., Haddow, B., and Birch, A. Neural machine translation of rare words with subword units. arXiv preprint arXiv:1508.07909 , 2015.
Shankar et al. (2019) Shankar, V., Dave, A., Roelofs, R., Ramanan, D., Recht, B., and Schmidt, L. Do image classifiers generalize across time? arXiv preprint arXiv:1906.02168 , 2019.
Sharma et al. (2018) Sharma, P., Ding, N., Goodman, S., and Soricut, R. Conceptual captions: A cleaned, hypernymed, image alt-text dataset for automatic image captioning. In Proceedings of the 56th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) , pp. 2556–2565, 2018.
Singh et al. (2019) Singh, A., Natarajan, V., Shah, M., Jiang, Y., Chen, X., Batra, D., Parikh, D., and Rohrbach, M. Towards vqa models that can read. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition , pp. 8317–8326, 2019.
Socher & Fei-Fei (2010) Socher, R. and Fei-Fei, L. Connecting modalities: Semi-supervised segmentation and annotation of images using unaligned text corpora. In 2010 IEEE Computer Society Conference on Computer Vision and Pattern Recognition , pp. 966–973. IEEE, 2010.
Socher et al. (2013) Socher, R., Perelygin, A., Wu, J., Chuang, J., Manning, C. D., Ng, A. Y., and Potts, C. Recursive deep models for semantic compositionality over a sentiment treebank. In Proceedings of the 2013 conference on empirical methods in natural language processing , pp. 1631–1642, 2013.
Socher et al. (2014) Socher, R., Karpathy, A., Le, Q. V., Manning, C. D., and Ng, A. Y. Grounded compositional semantics for finding and describing images with sentences. Transactions of the Association for Computational Linguistics , 2:207–218, 2014.
Sohn (2016) Sohn, K. Improved deep metric learning with multi-class n-pair loss objective. In Advances in neural information processing systems , pp. 1857–1865, 2016.
Solaiman et al. (2019) Solaiman, I., Brundage, M., Clark, J., Askell, A., Herbert-Voss, A., Wu, J., Radford, A., Krueger, G., Kim, J. W., Kreps, S., McCain, M., Newhouse, A., Blazakis, J., McGuffie, K., and Wang, J. Release strategies and the social impacts of language models, 2019.
Soomro et al. (2012) Soomro, K., Zamir, A. R., and Shah, M. Ucf101: A dataset of 101 human actions classes from videos in the wild. arXiv preprint arXiv:1212.0402 , 2012.
Speer (2019) Speer, R. ftfy. Zenodo, 2019. URL https://doi.org/10.5281/zenodo.2591652 . Version 5.5.
Srivastava & Salakhutdinov (2012) Srivastava, N. and Salakhutdinov, R. Multimodal learning with deep boltzmann machines. In NIPS , 2012.
Srivastava et al. (2017) Srivastava, S., Labutov, I., and Mitchell, T. Joint concept learning and semantic parsing from natural language explanations. In Proceedings of the 2017 conference on empirical methods in natural language processing , pp. 1527–1536, 2017.
Stallkamp et al. (2011) Stallkamp, J., Schlipsing, M., Salmen, J., and Igel, C. The German Traffic Sign Recognition Benchmark: A multi-class classification competition. In IEEE International Joint Conference on Neural Networks , pp. 1453–1460, 2011.
Stroud et al. (2020) Stroud, J. C., Ross, D. A., Sun, C., Deng, J., Sukthankar, R., and Schmid, C. Learning video representations from textual web supervision. arXiv preprint arXiv:2007.14937 , 2020.
Szegedy et al. (2016) Szegedy, C., Ioffe, S., Vanhoucke, V., and Alemi, A. Inception-v4, inception-resnet and the impact of residual connections on learning. arXiv preprint arXiv:1602.07261 , 2016.
Tan & Bansal (2019) Tan, H. and Bansal, M. Lxmert: Learning cross-modality encoder representations from transformers. arXiv preprint arXiv:1908.07490 , 2019.
Tan & Le (2019) Tan, M. and Le, Q. V. Efficientnet: Rethinking model scaling for convolutional neural networks. arXiv preprint arXiv:1905.11946 , 2019.
Taori et al. (2020) Taori, R., Dave, A., Shankar, V., Carlini, N., Recht, B., and Schmidt, L. Measuring robustness to natural distribution shifts in image classification. arXiv preprint arXiv:2007.00644 , 2020.
Thomee et al. (2016) Thomee, B., Shamma, D. A., Friedland, G., Elizalde, B., Ni, K., Poland, D., Borth, D., and Li, L.-J. Yfcc100m: The new data in multimedia research. Communications of the ACM , 59(2):64–73, 2016.
Tian et al. (2019) Tian, Y., Krishnan, D., and Isola, P. Contrastive multiview coding. arXiv preprint arXiv:1906.05849 , 2019.
Tian et al. (2020) Tian, Y., Wang, Y., Krishnan, D., Tenenbaum, J. B., and Isola, P. Rethinking few-shot image classification: a good embedding is all you need? arXiv preprint arXiv:2003.11539 , 2020.
Torralba et al. (2008) Torralba, A., Fergus, R., and Freeman, W. T. 80 million tiny images: A large data set for nonparametric object and scene recognition. IEEE transactions on pattern analysis and machine intelligence , 30(11):1958–1970, 2008.
Touvron et al. (2019) Touvron, H., Vedaldi, A., Douze, M., and Jégou, H. Fixing the train-test resolution discrepancy. In Advances in neural information processing systems , pp. 8252–8262, 2019.
Varadarajan & Odobez (2009) Varadarajan, J. and Odobez, J.-M. Topic models for scene analysis and abnormality detection. In 2009 IEEE 12th International Conference on Computer Vision Workshops, ICCV Workshops , pp. 1338–1345. IEEE, 2009.
Vaswani et al. (2017) Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, Ł., and Polosukhin, I. Attention is all you need. In Advances in neural information processing systems , pp. 5998–6008, 2017.
Veeling et al. (2018) Veeling, B. S., Linmans, J., Winkens, J., Cohen, T., and Welling, M. Rotation equivariant CNNs for digital pathology. June 2018.
Virtanen et al. (2020) Virtanen, P., Gommers, R., Oliphant, T. E., Haberland, M., Reddy, T., Cournapeau, D., Burovski, E., Peterson, P., Weckesser, W., Bright, J., van der Walt, S. J., Brett, M., Wilson, J., Millman, K. J., Mayorov, N., Nelson, A. R. J., Jones, E., Kern, R., Larson, E., Carey, C. J., Polat, İ., Feng, Y., Moore, E. W., VanderPlas, J., Laxalde, D., Perktold, J., Cimrman, R., Henriksen, I., Quintero, E. A., Harris, C. R., Archibald, A. M., Ribeiro, A. H., Pedregosa, F., van Mulbregt, P., and SciPy 1.0 Contributors. SciPy 1.0: Fundamental Algorithms for Scientific Computing in Python. Nature Methods , 17:261–272, 2020. doi: 10.1038/s41592-019-0686-2 .
Vo et al. (2017) Vo, N., Jacobs, N., and Hays, J. Revisiting im2gps in the deep learning era. In Proceedings of the IEEE International Conference on Computer Vision , pp. 2621–2630, 2017.
Wang et al. (2018) Wang, A., Singh, A., Michael, J., Hill, F., Levy, O., and Bowman, S. R. Glue: A multi-task benchmark and analysis platform for natural language understanding. arXiv preprint arXiv:1804.07461 , 2018.
Wang et al. (2019) Wang, H., Ge, S., Lipton, Z., and Xing, E. P. Learning robust global representations by penalizing local predictive power. In Advances in Neural Information Processing Systems , pp. 10506–10518, 2019.
Wang et al. (2020) Wang, H., Lu, P., Zhang, H., Yang, M., Bai, X., Xu, Y., He, M., Wang, Y., and Liu, W. All you need is boundary: Toward arbitrary-shaped text spotting. In Proceedings of the AAAI Conference on Artificial Intelligence , volume 34, pp. 12160–12167, 2020.
Wang et al. (2009) Wang, J., Markert, K., and Everingham, M. Learning models for object recognition from natural language descriptions. In BMVC , volume 1, pp. 2, 2009.
Weston et al. (2010) Weston, J., Bengio, S., and Usunier, N. Large scale image annotation: learning to rank with joint word-image embeddings. Machine learning , 81(1):21–35, 2010.
Weston (2016) Weston, J. E. Dialog-based language learning. In Advances in Neural Information Processing Systems , pp. 829–837, 2016.
Weyand et al. (2016) Weyand, T., Kostrikov, I., and Philbin, J. Planet-photo geolocation with convolutional neural networks. In European Conference on Computer Vision , pp. 37–55. Springer, 2016.
Wu et al. (2019) Wu, Y., Kirillov, A., Massa, F., Lo, W.-Y., and Girshick, R. Detectron2. https://github.com/facebookresearch/detectron2 , 2019.
Wu et al. (2018) Wu, Z., Xiong, Y., Yu, S., and Lin, D. Unsupervised feature learning via non-parametric instance-level discrimination. arXiv preprint arXiv:1805.01978 , 2018.
Xie et al. (2020) Xie, Q., Luong, M.-T., Hovy, E., and Le, Q. V. Self-training with noisy student improves imagenet classification. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition , pp. 10687–10698, 2020.
y Arcas et al. (2017) y Arcas, B. A., Mitchell, M., and Todorov, A. Physiognomy’s new clothes. 2017. URL https://medium.com/@blaisea/physiognomys-new-clothes-f2d4b59fdd6a .
Yang et al. (2020) Yang, Z., Lu, Y., Wang, J., Yin, X., Florencio, D., Wang, L., Zhang, C., Zhang, L., and Luo, J. Tap: Text-aware pre-training for text-vqa and text-caption. arXiv preprint arXiv:2012.04638 , 2020.
Yogatama et al. (2019) Yogatama, D., d’Autume, C. d. M., Connor, J., Kocisky, T., Chrzanowski, M., Kong, L., Lazaridou, A., Ling, W., Yu, L., Dyer, C., et al. Learning and evaluating general linguistic intelligence. arXiv preprint arXiv:1901.11373 , 2019.
Young et al. (2014) Young, P., Lai, A., Hodosh, M., and Hockenmaier, J. From image descriptions to visual denotations: New similarity metrics for semantic inference over event descriptions. Transactions of the Association for Computational Linguistics , 2:67–78, 2014.
Yu et al. (2020) Yu, F., Tang, J., Yin, W., Sun, Y., Tian, H., Wu, H., and Wang, H. Ernie-vil: Knowledge enhanced vision-language representations through scene graph. arXiv preprint arXiv:2006.16934 , 2020.
Zeiler & Fergus (2014) Zeiler, M. D. and Fergus, R. Visualizing and understanding convolutional networks. In European conference on computer vision , pp. 818–833. Springer, 2014.
Zhai et al. (2019) Zhai, X., Puigcerver, J., Kolesnikov, A., Ruyssen, P., Riquelme, C., Lucic, M., Djolonga, J., Pinto, A. S., Neumann, M., Dosovitskiy, A., et al. A large-scale study of representation learning with the visual task adaptation benchmark. arXiv preprint arXiv:1910.04867 , 2019.
Zhang (2019) Zhang, R. Making convolutional networks shift-invariant again. arXiv preprint arXiv:1904.11486 , 2019.
Zhang et al. (2020) Zhang, Y., Jiang, H., Miura, Y., Manning, C. D., and Langlotz, C. P. Contrastive learning of medical visual representations from paired images and text. arXiv preprint arXiv:2010.00747 , 2020.
Zuboff (2015) Zuboff, S. Big other: surveillance capitalism and the prospects of an information civilization. Journal of Information Technology , 30(1):75–89, 2015.
Appendix A Linear-probe evaluation
附录 A 线性探针评估
We provide additional details for linear probe experiments presented in this paper, including the list of the datasets and models used for evaluation.
我们提供了本文中线性探针实验的额外细节,包括用于评估的数据集和模型列表。
A.1 Datasets
A.1 数据集
We use the 12 datasets from the well-studied evaluation suite introduced by (Kornblith et al. 2019) and add 15 additional datasets in order to assess the performance of models on a wider variety of distributions and tasks. These datasets include MNIST, the Facial Expression Recognition 2013 dataset (Goodfellow et al. 2015), STL-10 (Coates et al. 2011), EuroSAT (Helber et al. 2019), the NWPU-RESISC45 dataset (Cheng et al. 2017), the German Traffic Sign Recognition Benchmark (GTSRB) dataset (Stallkamp et al. 2011), the KITTI dataset (Geiger et al. 2012), PatchCamelyon (Veeling et al. 2018), the UCF101 action recognition dataset (Soomro et al. 2012), Kinetics 700 (Carreira et al. 2019), 2,500 random samples of the CLEVR dataset (Johnson et al. 2017), the Hateful Memes dataset (Kiela et al. 2020), and the ImageNet-1k dataset (Deng et al. 2012). For the two video datasets (UCF101 and Kinetics700), we use the middle frame of each video clip as the input image. STL-10 and UCF101 have multiple pre-defined train/validation/test splits, 10 and 3 respectively, and we report the average over all splits. Details on each dataset and the corresponding evaluation metrics are provided in Table 9.
我们使用 Kornblith 等 2019 引入的、研究充分的评测套件中的 12 个数据集,并再增加 15 个数据集,以在更广的分布与任务上评估模型性能。这些数据集包括 MNIST、Facial Expression Recognition 2013(Goodfellow 等 2015)、STL-10(Coates 等 2011)、EuroSAT(Helber 等 2019)、NWPU-RESISC45(Cheng 等 2017)、德国交通标志识别基准 GTSRB(Stallkamp 等 2011)、KITTI(Geiger 等 2012)、PatchCamelyon(Veeling 等 2018)、UCF101 动作识别(Soomro 等 2012)、Kinetics 700(Carreira 等 2019)、CLEVR 的 2500 个随机样本(Johnson 等 2017)、Hateful Memes(Kiela 等 2020)以及 ImageNet-1k(Deng 等 2012)。对两个视频数据集(UCF101 与 Kinetics700),我们以每个视频片段的中间帧作为输入图像。STL-10 与 UCF101 分别有 10 个与 3 个预定义的 train/validation/test 划分,我们报告所有划分上的平均。各数据集细节与对应评测指标见表 9。
Additionally, we created two datasets that we call Country211 and Rendered SST2. The Country211 dataset is designed to assess the geolocation capability of visual representations. We filtered the YFCC100m dataset (Thomee et al. 2016) to find 211 countries (defined as having an ISO-3166 country code) that have at least 300 photos with GPS coordinates, and we built a balanced dataset with 211 categories, by sampling 200 photos for training and 100 photos for testing, for each country.
此外,我们创建了两个数据集,分别称为 Country211 和 Rendered SST2。Country211 数据集旨在评估视觉表示的地理定位能力。我们过滤了 YFCC100m 数据集(Thomee 等,2016),找出了 211 个国家(定义为具有 ISO-3166 国家代码)且每个国家至少有 300 张带 GPS 坐标的照片,并构建了一个包含 211 个类别的平衡数据集,每个国家抽取 200 张照片用于训练,100 张照片用于测试。
The Rendered SST2 dataset is designed to measure the optical character recognition capability of visual representations. To do so, we used the sentences from the Stanford Sentiment Treebank dataset (Socher et al. 2013) and rendered them into images, with black texts on a white background, in a 448448 resolution. Two example images from this dataset are shown in Figure 19.
渲染后的 SST2 数据集旨在衡量视觉表示的光学字符识别能力。为此,我们使用了斯坦福情感树库(Stanford Sentiment Treebank)数据集(Socher 等,2013)中的句子,并将其渲染为图像,文本为黑色,背景为白色,分辨率为 448×448。该数据集的两个示例图像如图 19 所示。
Figure 19: Two example images from the Rendered SST2 dataset
图19:来自渲染SST2数据集的两个示例图像
| Dataset | Classes | Train size | Test size | Evaluation metric |
|---|---|---|---|---|
| Food-101 | 102 | 75,750 | 25,250 | accuracy |
| CIFAR-10 | 10 | 50,000 | 10,000 | accuracy |
| CIFAR-100 | 100 | 50,000 | 10,000 | accuracy |
| Birdsnap | 500 | 42,283 | 2,149 | accuracy |
| SUN397 | 397 | 19,850 | 19,850 | accuracy |
| Stanford Cars | 196 | 8,144 | 8,041 | accuracy |
| FGVC Aircraft | 100 | 6,667 | 3,333 | mean per class |
| Pascal VOC 2007 Classification | 20 | 5,011 | 4,952 | 11-point mAP |
| Describable Textures | 47 | 3,760 | 1,880 | accuracy |
| Oxford-IIIT Pets | 37 | 3,680 | 3,669 | mean per class |
| Caltech-101 | 102 | 3,060 | 6,085 | mean-per-class |
| Oxford Flowers 102 | 102 | 2,040 | 6,149 | mean per class |
| MNIST | 10 | 60,000 | 10,000 | accuracy |
| Facial Emotion Recognition 2013 | 8 | 32,140 | 3,574 | accuracy |
| STL-10 | 10 | 1000 | 8000 | accuracy |
| EuroSAT | 10 | 10,000 | 5,000 | accuracy |
| RESISC45 | 45 | 3,150 | 25,200 | accuracy |
| GTSRB | 43 | 26,640 | 12,630 | accuracy |
| KITTI | 4 | 6,770 | 711 | accuracy |
| Country211 | 211 | 43,200 | 21,100 | accuracy |
| PatchCamelyon | 2 | 294,912 | 32,768 | accuracy |
| UCF101 | 101 | 9,537 | 1,794 | accuracy |
| Kinetics700 | 700 | 494,801 | 31,669 | mean(top1, top5) |
| CLEVR Counts | 8 | 2,000 | 500 | accuracy |
| Hateful Memes | 2 | 8,500 | 500 | ROC AUC |
| Rendered SST2 | 2 | 7,792 | 1,821 | accuracy |
| ImageNet | 1000 | 1,281,167 | 50,000 | accuracy |
Table 9: Datasets examined for linear probes. We note that, for the Birdsnap and Kinetics700 datasets, we used the resources that are available online at the time of this writing.
| 数据集 | 类别数 | 训练集大小 | 测试集大小 | 评测指标 |
|---|---|---|---|---|
| Food-101 | 102 | 75,750 | 25,250 | 精度 |
| CIFAR-10 | 10 | 50,000 | 10,000 | 精度 |
| CIFAR-100 | 100 | 50,000 | 10,000 | 精度 |
| Birdsnap | 500 | 42,283 | 2,149 | 精度 |
| SUN397 | 397 | 19,850 | 19,850 | 精度 |
| Stanford Cars | 196 | 8,144 | 8,041 | 精度 |
| FGVC Aircraft | 100 | 6,667 | 3,333 | 每类平均 |
| Pascal VOC 2007 Classification | 20 | 5,011 | 4,952 | 11 点 mAP |
| Describable Textures | 47 | 3,760 | 1,880 | 精度 |
| Oxford-IIIT Pets | 37 | 3,680 | 3,669 | 每类平均 |
| Caltech-101 | 102 | 3,060 | 6,085 | 每类平均 |
| Oxford Flowers 102 | 102 | 2,040 | 6,149 | 每类平均 |
| MNIST | 10 | 60,000 | 10,000 | 精度 |
| Facial Emotion Recognition 2013 | 8 | 32,140 | 3,574 | 精度 |
| STL-10 | 10 | 1000 | 8000 | 精度 |
| EuroSAT | 10 | 10,000 | 5,000 | 精度 |
| RESISC45 | 45 | 3,150 | 25,200 | 精度 |
| GTSRB | 43 | 26,640 | 12,630 | 精度 |
| KITTI | 4 | 6,770 | 711 | 精度 |
| Country211 | 211 | 43,200 | 21,100 | 精度 |
| PatchCamelyon | 2 | 294,912 | 32,768 | 精度 |
| UCF101 | 101 | 9,537 | 1,794 | 精度 |
| Kinetics700 | 700 | 494,801 | 31,669 | mean(top1, top5) |
| CLEVR Counts | 8 | 2,000 | 500 | 精度 |
| Hateful Memes | 2 | 8,500 | 500 | ROC AUC |
| Rendered SST2 | 2 | 7,792 | 1,821 | 精度 |
| ImageNet | 1000 | 1,281,167 | 50,000 | 精度 |
表 9:用于线性探测的数据集。我们注明:对 Birdsnap 与 Kinetics700,使用的是撰写本文时在线可用的资源。
A.2 Models
A.2 模型
In combination with the datasets listed above, we evaluate the following series of models using linear probes.
结合上述列出的数据集,我们使用线性探针评估以下系列模型。
LM RN50
This is a multimodal model that uses an autoregressive loss instead of a contrastive loss, while using the ResNet-50 architecture as in the smallest contrastive model. To do so, the output from the CNN is projected into four tokens, which are then fed as a prefix to a language model autoregressively predicting the text tokens. Apart from the training objective, the model was trained on the same dataset for the same number of epochs as other CLIP models.
这是一个多模态模型,它使用自回归损失而不是对比损失,同时使用与最小的对比模型相同的 ResNet-50 架构。为此,CNN 的输出被投影到四个 token,然后作为前缀输入到自回归预测文本 token 的语言模型中。除了训练目标之外,该模型在与其他 CLIP 模型相同的数据集上训练,并且训练轮数也相同。
CLIP-RN
Five ResNet-based contrastive CLIP models are included. As discussed in the paper, the first two models follow ResNet-50 and ResNet-101, and we use EfficientNet-style (Tan & Le 2019) scaling for the next three models which simultaneously scale the model width, the number of layers, and the input resolution to obtain models with roughly 4x, 16x, and 64x computation.
包含了五个基于 ResNet 的对比 CLIP 模型。如论文中所述,前两个模型遵循 ResNet-50 和 ResNet-101,而接下来的三个模型使用 EfficientNet 风格的(Tan & Le 2019)缩放,同时缩放模型宽度、层数和输入分辨率,从而获得计算量大约为 4 倍、16 倍和 64 倍的模型。
CLIP-ViT
We include four CLIP models that use the Vision Transformer (Dosovitskiy et al. 2020) architecture as the image encoder. We include three models trained on 224-by-224 pixel images: ViT-B/32, ViT-B/16, ViT-L/14, and the ViT-L/14 model fine-tuned on 336-by-336 pixel input images.
我们包括了四个使用视觉变换器(Vision Transformer,Dosovitskiy 等人,2020)架构作为图像编码器的 CLIP 模型。我们包括三个在 224×224 像素图像上训练的模型:ViT-B/32、ViT-B/16、ViT-L/14,以及一个在 336×336 像素输入图像上微调的 ViT-L/14 模型。
EfficietNet
EfficientNet
We use the nine models (B0-B8) from the original EfficientNet paper (Tan & Le 2019), as well as the noisy-student variants (B0-B7, L2-475, and L2-800) (Tan & Le 2019). The largest models (L2-475 and L2-800) take the input resolutions of 475x475 and 800x800 pixels, respectively.
我们使用原始 EfficientNet 论文(Tan & Le 2019)中的九个模型(B0-B8),以及噪声学生变体(B0-B7、L2-475 和 L2-800)(Tan & Le 2019)。最大的模型(L2-475 和 L2-800)分别使用 475x475 和 800x800 像素的输入分辨率。
Instagram-pretrained ResNeXt
Instagram 预训练 ResNeXt
We use the four models (32x8d, 32x16d, 32x32d, 32x48d) released by (Mahajan et al. 2018), as well as their two FixRes variants which use higher input resolutions (Touvron et al. 2019).
我们使用了 (Mahajan et al. 2018) 发布的四个模型(32x8d、32x16d、32x32d、32x48d),以及它们的两个使用更高输入分辨率的 FixRes 变体 (Touvron et al. 2019)。
Big Transfer (BiT)
大迁移(BiT)
We use BiT-S and BiT-M models (Kolesnikov et al. 2019), trained on the ImageNet-1k and ImageNet-21k datasets. The model weights for BiT-L is not publicly available.
我们使用 BiT-S 和 BiT-M 模型(Kolesnikov 等,2019),在 ImageNet-1k 和 ImageNet-21k 数据集上训练。BiT-L 的模型权重尚未公开。
Vision Transformer (ViT)
视觉变换器 (ViT)
We also include four ViT (Dosovitskiy et al. 2020) checkpoints pretrained on the ImageNet-21k dataset, namely ViT-B/32, ViT-B/16, ViT-L/16, and ViT-H/14. We note that their best-performing models, trained on the JFT-300M dataset, are not available publicly.
我们还包括了四个在 ImageNet-21k 数据集上预训练的 ViT(Dosovitskiy 等, 2020)检查点,分别是 ViT-B/32、ViT-B/16、ViT-L/16 和 ViT-H/14。我们注意到,它们在 JFT-300M 数据集上训练的表现最好的模型并未公开提供。
SimCLRv2
The SimCLRv2 (Chen et al. 2020c) project released pre-trained and fine-tuned models in various settings. We use the seven pretrain-only checkpoints with selective kernels.
SimCLRv2(Chen 等,2020c)项目发布了多种设置下的预训练和微调模型。我们使用了七个仅用于预训练的检查点,并配有选择性内核。
BYOL
We use the recently released model weights of BYOL (Grill et al. 2020), specifically their 50x1 and 200x2 checkpoints.
我们使用了最近发布的BYOL(Grill 等人,2020)的模型权重,具体是他们的50x1和200x2检查点。
Momentum Contrast (MoCo)
动量对比 (MoCo)
We include the MoCo-v1 (He et al. 2020) and the MoCo-v2 (Chen et al. 2020d) checkpoints.
我们包含了 MoCo-v1 (He 等, 2020) 和 MoCo-v2 (Chen 等, 2020d) 的检查点。
VirTex
We use the pretrained model of VirTex (Desai & Johnson 2020). We note that VirTex has a similar model design to CLIP-AR but is trained on a 1000x smaller dataset of high-quality captions from MSCOCO.
我们使用 VirTex(Desai & Johnson 2020)的预训练模型。我们注意到 VirTex 的模型设计与 CLIP-AR 类似,但它是在一个比 CLIP-AR 小 1000 倍的高质量 MSCOCO 标注数据集上训练的。
ResNet
We add the original ResNet checkpoints released by (He et al. 2016b), namely ResNet-50, ResNet-101, and ResNet152.
我们添加了 (He et al. 2016b) 发布的原始 ResNet 检查点,即 ResNet-50、ResNet-101 和 ResNet-152。
A.3 Evaluation
A.3 评估
We use image features taken from the penultimate layer of each model, ignoring any classification layer provided. For CLIP-ViT models, we used the features before the linear projection to the embedding space, which corresponds to I_f in Figure 3. We train a logistic regression classifier using scikit-learn’s L-BFGS implementation, with maximum 1,000 iterations, and report the corresponding metric for each dataset. We determine the L2 regularization strength using a hyperparameter sweep on the validation sets over the range between and , with 96 logarithmically spaced steps. To save compute required for the sweeps, we perform a parametric binary search that starts with and iteratively halves the interval around the peak until it reaches a resolution of 8 steps per decade. The hyperparameter sweeps are performed on a validation split of each dataset. For the datasets that contain a validation split in addition to a test split, we use the provided validation set to perform the hyperparameter search, and for the datasets that do not provide a validation split or have not published labels for the test data, we split the training dataset to perform the hyperparameter search. For the final result, we combine the validation split back with the training split and report the performance on the unused split.
我们使用各模型倒数第二层的图像特征,忽略所提供的任何分类层。对 CLIP-ViT 模型,我们使用投影到嵌入空间之前的特征,对应图 3 中的 。我们用 scikit-learn 的 L-BFGS 实现训练逻辑回归分类器,最多 1000 次迭代,并报告各数据集对应指标。我们在验证集上对 到 之间、对数均匀间隔 96 步的范围做超参数扫描,以确定 L2 正则强度 。为节省扫描所需算力,我们做参数化二分搜索:从 开始,迭代地在峰值两侧将区间减半,直至达到每十进制 8 步的分辨率。超参数扫描在各数据集的验证划分上进行。对除测试划分外还包含验证划分的数据集,用所提供的验证集做超参数搜索;对未提供验证划分或未公布测试标签的数据集,我们从训练集中再划分以做超参数搜索。最终结果时,把验证划分重新并入训练划分,并在未使用的划分上报告性能。
A.4 Results
A.4 结果
The individual linear probe scores are provided in Table 10 and plotted in Figure 20. The best-performing CLIP model, using ViT-L/14 archiecture and 336-by-336 pixel images, achieved the state of the art in 21 of the 27 datasets, i.e. included in the Clopper-Pearson 99.5% confidence interval around each dataset’s top score. For many datasets, CLIP performs significantly better than other models, demonstrating the advantage of natural language supervision over traditional pre-training approaches based on image classification. See Section 3.2 for more discussions on the linear probe results.
各个线性探测器的分数见表10,并绘制在图20中。表现最好的CLIP模型使用ViT-L/14架构和336×336像素的图像,在27个数据集中有21个达到了最新水平,即包含在每个数据集最高分的Clopper-Pearson 99.5%置信区间内。对于许多数据集,CLIP的表现明显优于其他模型,展示了自然语言监督相比基于图像分类的传统预训练方法的优势。关于线性探测结果的更多讨论,请参见第3.2节。
| Food101 | CIFAR10 | CIFAR100 | Birdsnap | SUN397 | Cars | Aircraft | VOC2007 | DTD | Pets | Caltech101 | Flowers | MNIST | FER2013 | STL10⋆ | EuroSAT | RESISC45 | GTSRB | KITTI | Country211 | PCAM | UCF101 | Kinetics700 | CLEVR | HatefulMemes | SST | ImageNet | |||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| LM RN50 | 81.3 | 82.8 | 61.7 | 44.2 | 69.6 | 74.9 | 44.9 | 85.5 | 71.5 | 82.8 | 85.5 | 91.1 | 96.6 | 60.1 | 95.3 | 93.4 | 84.0 | 73.8 | 70.2 | 19.0 | 82.9 | 76.4 | 51.9 | 51.2 | 65.2 | 76.8 | 65.2 | ||
| CLIP-RN | 50 | 86.4 | 88.7 | 70.3 | 56.4 | 73.3 | 78.3 | 49.1 | 87.1 | 76.4 | 88.2 | 89.6 | 96.1 | 98.3 | 64.2 | 96.6 | 95.2 | 87.5 | 82.4 | 70.2 | 25.3 | 82.7 | 81.6 | 57.2 | 53.6 | 65.7 | 72.6 | 73.3 | |
| 101 | 88.9 | 91.1 | 73.5 | 58.6 | 75.1 | 84.0 | 50.7 | 88.0 | 76.3 | 91.0 | 92.0 | 96.4 | 98.4 | 65.2 | 97.8 | 95.9 | 89.3 | 82.4 | 73.6 | 26.6 | 82.8 | 84.0 | 60.3 | 50.3 | 68.2 | 73.3 | 75.7 | ||
| 50x4 | 91.3 | 90.5 | 73.0 | 65.7 | 77.0 | 85.9 | 57.3 | 88.4 | 79.5 | 91.9 | 92.5 | 97.8 | 98.5 | 68.1 | 97.8 | 96.4 | 89.7 | 85.5 | 59.4 | 30.3 | 83.0 | 85.7 | 62.6 | 52.5 | 68.0 | 76.6 | 78.2 | ||
| 50x16 | 93.3 | 92.2 | 74.9 | 72.8 | 79.2 | 88.7 | 62.7 | 89.0 | 79.1 | 93.5 | 93.7 | 98.3 | 98.9 | 68.7 | 98.6 | 97.0 | 91.4 | 89.0 | 69.2 | 34.8 | 83.5 | 88.0 | 66.3 | 53.8 | 71.1 | 80.0 | 81.5 | ||
| 50x64 | 94.8 | 94.1 | 78.6 | 77.2 | 81.1 | 90.5 | 67.7 | 88.9 | 82.0 | 94.5 | 95.4 | 98.9 | 98.9 | 71.3 | 99.1 | 97.1 | 92.8 | 90.2 | 69.2 | 40.7 | 83.7 | 89.5 | 69.1 | 55.0 | 75.0 | 81.2 | 83.6 | ||
| CLIP-ViT | B/32 | 88.8 | 95.1 | 80.5 | 58.5 | 76.6 | 81.8 | 52.0 | 87.7 | 76.5 | 90.0 | 93.0 | 96.9 | 99.0 | 69.2 | 98.3 | 97.0 | 90.5 | 85.3 | 66.2 | 27.8 | 83.9 | 85.5 | 61.7 | 52.1 | 66.7 | 70.8 | 76.1 | |
| B/16 | 92.8 | 96.2 | 83.1 | 67.8 | 78.4 | 86.7 | 59.5 | 89.2 | 79.2 | 93.1 | 94.7 | 98.1 | 99.0 | 69.5 | 99.0 | 97.1 | 92.7 | 86.6 | 67.8 | 33.3 | 83.5 | 88.4 | 66.1 | 57.1 | 70.3 | 75.5 | 80.2 | ||
| L/14 | 95.2 | 98.0 | 87.5 | 77.0 | 81.8 | 90.9 | 69.4 | 89.6 | 82.1 | 95.1 | 96.5 | 99.2 | 99.2 | 72.2 | 99.7 | 98.2 | 94.1 | 92.5 | 64.7 | 42.9 | 85.8 | 91.5 | 72.0 | 57.8 | 76.2 | 80.8 | 83.9 | ||
| L/14-336px | 95.9 | 97.9 | 87.4 | 79.9 | 82.2 | 91.5 | 71.6 | 89.9 | 83.0 | 95.1 | 96.0 | 99.2 | 99.2 | 72.9 | 99.7 | 98.1 | 94.9 | 92.4 | 69.2 | 46.4 | 85.6 | 92.0 | 73.0 | 60.3 | 77.3 | 80.5 | 85.4 | ||
| EfficientNet | B0 | 74.3 | 92.5 | 76.5 | 59.7 | 62.0 | 62.5 | 55.7 | 84.4 | 71.2 | 93.0 | 93.3 | 91.7 | 98.2 | 57.2 | 97.1 | 97.3 | 85.5 | 80.0 | 73.8 | 12.4 | 83.1 | 74.4 | 47.6 | 47.9 | 55.7 | 53.4 | 76.9 | |
| B1 | 74.2 | 93.2 | 77.2 | 61.3 | 62.6 | 62.5 | 56.1 | 84.7 | 74.2 | 93.4 | 93.6 | 92.4 | 98.3 | 57.0 | 97.5 | 96.8 | 84.5 | 75.9 | 75.5 | 12.5 | 82.7 | 74.7 | 48.5 | 44.3 | 54.5 | 54.4 | 78.6 | ||
| B2 | 75.8 | 93.6 | 77.9 | 64.4 | 64.0 | 63.2 | 57.0 | 85.3 | 73.5 | 93.9 | 93.5 | 92.9 | 98.5 | 56.6 | 97.7 | 96.9 | 84.4 | 76.4 | 73.1 | 12.6 | 84.3 | 75.1 | 49.4 | 42.6 | 55.4 | 55.2 | 79.7 | ||
| B3 | 77.4 | 94.0 | 78.0 | 66.5 | 64.4 | 66.0 | 59.3 | 85.8 | 73.1 | 94.1 | 93.7 | 93.3 | 98.5 | 57.1 | 98.2 | 97.3 | 85.0 | 75.8 | 76.1 | 13.4 | 83.3 | 78.1 | 50.9 | 45.1 | 53.8 | 54.8 | 81.0 | ||
| B4 | 79.7 | 94.1 | 78.7 | 70.1 | 65.4 | 66.4 | 60.4 | 86.5 | 73.4 | 94.7 | 93.5 | 93.2 | 98.8 | 57.9 | 98.6 | 96.8 | 85.0 | 78.3 | 72.3 | 13.9 | 83.1 | 79.1 | 52.5 | 46.5 | 54.4 | 55.4 | 82.9 | ||
| B5 | 81.5 | 93.6 | 77.9 | 72.4 | 67.1 | 72.7 | 68.9 | 86.7 | 73.9 | 95.0 | 94.7 | 94.5 | 98.4 | 58.5 | 98.7 | 96.8 | 86.0 | 78.5 | 69.6 | 14.9 | 84.7 | 80.9 | 54.5 | 46.6 | 53.3 | 56.3 | 83.7 | ||
| B6 | 82.4 | 94.0 | 78.0 | 73.5 | 65.8 | 71.1 | 68.2 | 87.6 | 73.9 | 95.0 | 94.1 | 93.7 | 98.4 | 60.2 | 98.7 | 96.8 | 85.4 | 78.1 | 72.7 | 15.3 | 84.2 | 80.0 | 54.1 | 51.1 | 53.3 | 57.0 | 84.0 | ||
| B7 | 84.5 | 94.9 | 80.1 | 74.7 | 69.0 | 77.1 | 72.3 | 87.2 | 76.8 | 95.2 | 94.7 | 95.9 | 98.6 | 61.3 | 99.1 | 96.3 | 86.8 | 80.8 | 75.8 | 16.4 | 85.2 | 81.9 | 56.8 | 51.9 | 54.4 | 57.8 | 84.8 | ||
| B8 | 84.5 | 95.0 | 80.7 | 75.2 | 69.6 | 76.8 | 71.5 | 87.4 | 77.1 | 94.9 | 95.2 | 96.3 | 98.6 | 61.4 | 99.2 | 97.0 | 87.4 | 80.4 | 70.9 | 17.4 | 85.2 | 82.4 | 57.7 | 51.4 | 51.7 | 55.8 | 85.3 | ||
| EfficientNet Noisy Student | B0 | 78.1 | 94.0 | 78.6 | 63.5 | 65.5 | 57.2 | 53.7 | 85.6 | 75.6 | 93.8 | 93.1 | 94.5 | 98.1 | 55.6 | 98.2 | 97.0 | 84.3 | 74.0 | 71.6 | 14.0 | 83.1 | 76.7 | 51.7 | 47.3 | 55.7 | 55.0 | 78.5 | |
| B1 | 80.4 | 95.1 | 80.2 | 66.6 | 67.6 | 59.6 | 53.7 | 86.2 | 77.0 | 94.6 | 94.4 | 95.1 | 98.0 | 56.1 | 98.6 | 96.9 | 84.3 | 73.1 | 67.1 | 14.5 | 83.9 | 79.9 | 54.5 | 46.1 | 54.3 | 54.9 | 81.1 | ||
| B2 | 80.9 | 95.3 | 81.3 | 67.6 | 67.9 | 60.9 | 55.2 | 86.3 | 77.7 | 95.0 | 94.7 | 94.4 | 98.0 | 55.5 | 98.8 | 97.3 | 84.6 | 71.7 | 70.0 | 14.6 | 82.9 | 80.1 | 55.1 | 46.1 | 54.1 | 55.3 | 82.2 | ||
| B3 | 82.6 | 95.9 | 82.1 | 68.6 | 68.8 | 60.6 | 55.4 | 86.5 | 77.2 | 95.0 | 94.8 | 95.2 | 98.1 | 56.0 | 99.1 | 96.5 | 85.0 | 70.5 | 69.5 | 15.1 | 83.1 | 81.8 | 56.8 | 45.1 | 55.7 | 52.0 | 83.8 | ||
| B4 | 85.2 | 95.6 | 81.0 | 72.5 | 69.7 | 56.1 | 52.6 | 87.0 | 78.7 | 94.8 | 95.2 | 95.3 | 98.2 | 56.0 | 99.3 | 95.3 | 84.8 | 61.9 | 64.8 | 16.0 | 82.8 | 83.4 | 59.8 | 43.2 | 55.3 | 53.0 | 85.4 | ||
| B5 | 87.6 | 96.3 | 82.4 | 75.3 | 71.6 | 64.7 | 64.8 | 87.8 | 79.6 | 95.5 | 95.6 | 96.6 | 98.8 | 60.9 | 99.4 | 96.1 | 87.0 | 68.5 | 73.7 | 16.4 | 83.5 | 86.4 | 61.6 | 46.3 | 53.4 | 55.8 | 85.8 | ||
| B6 | 87.3 | 97.0 | 83.9 | 75.8 | 71.4 | 67.6 | 65.6 | 87.3 | 78.5 | 95.2 | 96.4 | 97.2 | 98.6 | 61.9 | 99.5 | 96.6 | 86.1 | 70.7 | 72.4 | 17.6 | 84.2 | 85.5 | 61.0 | 49.6 | 54.6 | 55.7 | 86.4 | ||
| B7 | 88.4 | 96.0 | 82.0 | 76.9 | 72.6 | 72.2 | 71.2 | 88.1 | 80.5 | 95.5 | 95.5 | 96.6 | 98.5 | 62.7 | 99.4 | 96.2 | 88.5 | 73.4 | 73.0 | 18.5 | 83.8 | 86.6 | 63.2 | 50.5 | 57.2 | 56.7 | 87.0 | ||
| L2-475 | 91.6 | 99.0 | 91.0 | 74.8 | 76.4 | 75.1 | 66.8 | 89.5 | 81.9 | 95.6 | 96.5 | 97.7 | 98.9 | 67.5 | 99.6 | 97.0 | 89.5 | 73.4 | 68.9 | 22.2 | 86.3 | 89.4 | 68.2 | 58.3 | 58.6 | 55.2 | 88.3 | ||
| L2-800 | 92.0 | 98.7 | 89.0 | 78.5 | 75.7 | 75.5 | 68.4 | 89.4 | 82.5 | 95.6 | 94.7 | 97.9 | 98.5 | 68.4 | 99.7 | 97.2 | 89.9 | 77.7 | 66.9 | 23.7 | 86.8 | 88.9 | 66.7 | 62.7 | 58.4 | 56.9 | 88.4 | ||
| 32x8d | 84.8 | 95.9 | 80.9 | 63.8 | 69.0 | 74.2 | 56.0 | 88.0 | 75.4 | 95.4 | 93.9 | 91.7 | 97.4 | 60.7 | 99.1 | 95.7 | 82.1 | 72.3 | 69.2 | 16.7 | 82.3 | 80.1 | 56.8 | 42.2 | 53.3 | 55.2 | 83.3 | ||
| 32x16d | 85.7 | 96.5 | 80.9 | 64.8 | 70.5 | 77.5 | 56.7 | 87.9 | 76.2 | 95.6 | 94.9 | 92.5 | 97.4 | 61.6 | 99.3 | 95.5 | 82.8 | 73.8 | 66.1 | 17.5 | 83.4 | 81.1 | 58.2 | 41.3 | 54.2 | 56.1 | 84.4 | ||
| 32x32d | 86.7 | 96.8 | 82.7 | 67.1 | 71.5 | 77.5 | 55.4 | 88.3 | 78.5 | 95.8 | 95.3 | 94.4 | 97.9 | 62.4 | 99.3 | 95.7 | 85.4 | 71.2 | 66.8 | 18.0 | 83.7 | 82.1 | 58.8 | 39.7 | 55.3 | 56.7 | 85.0 | ||
| 32x48d | 86.9 | 96.8 | 83.4 | 65.9 | 72.2 | 76.6 | 53.2 | 88.0 | 77.2 | 95.5 | 95.8 | 93.6 | 98.1 | 63.7 | 99.4 | 95.3 | 85.4 | 73.0 | 67.2 | 18.5 | 82.7 | 82.8 | 59.2 | 41.3 | 55.5 | 56.7 | 85.2 | ||
| FixRes-v1 | 88.5 | 95.7 | 81.1 | 67.4 | 72.9 | 80.5 | 57.6 | 88.0 | 77.9 | 95.8 | 96.1 | 94.5 | 97.9 | 62.2 | 99.4 | 96.2 | 86.6 | 76.5 | 64.8 | 19.3 | 82.5 | 83.4 | 59.8 | 43.5 | 56.6 | 59.0 | 86.0 | ||
| FixRes-v2 | 88.5 | 95.7 | 81.1 | 67.3 | 72.9 | 80.7 | 57.5 | 88.0 | 77.9 | 95.0 | 96.0 | 94.5 | 98.0 | 62.1 | 99.4 | 96.5 | 86.6 | 76.3 | 64.8 | 19.5 | 82.3 | 83.5 | 59.8 | 44.2 | 56.6 | 59.0 | 86.0 | ||
| BiT-S | R50x1 | 72.5 | 91.7 | 74.8 | 57.7 | 61.1 | 53.5 | 52.5 | 83.7 | 72.4 | 92.3 | 91.2 | 92.0 | 98.4 | 56.1 | 96.4 | 97.4 | 85.0 | 70.0 | 66.0 | 12.5 | 83.0 | 72.3 | 47.5 | 48.3 | 54.1 | 55.3 | 75.2 | |
| R50x3 | 75.1 | 93.7 | 79.0 | 61.1 | 63.7 | 55.2 | 54.1 | 84.8 | 74.6 | 92.5 | 91.6 | 92.8 | 98.8 | 58.7 | 97.0 | 97.8 | 86.4 | 73.1 | 73.8 | 14.0 | 84.2 | 76.4 | 50.0 | 49.2 | 54.7 | 54.2 | 77.2 | ||
| R101x1 | 73.5 | 92.8 | 77.4 | 58.4 | 61.3 | 54.0 | 52.4 | 84.4 | 73.5 | 92.5 | 91.8 | 90.6 | 98.3 | 56.5 | 96.8 | 97.3 | 84.6 | 69.4 | 68.9 | 12.6 | 82.0 | 73.5 | 48.6 | 45.4 | 52.6 | 55.5 | 76.0 | ||
| R101x3 | 74.7 | 93.9 | 79.8 | 57.8 | 62.9 | 54.7 | 53.3 | 84.7 | 75.5 | 92.3 | 91.2 | 92.6 | 98.8 | 59.7 | 97.3 | 98.0 | 85.5 | 71.8 | 60.2 | 14.1 | 83.1 | 75.9 | 50.4 | 49.7 | 54.1 | 54.6 | 77.4 | ||
| R152x2 | 74.9 | 94.3 | 79.7 | 58.7 | 62.7 | 55.9 | 53.6 | 85.3 | 74.9 | 93.0 | 92.0 | 91.7 | 98.6 | 58.3 | 97.1 | 97.8 | 86.2 | 71.8 | 71.6 | 13.9 | 84.1 | 76.2 | 49.9 | 48.2 | 53.8 | 55.9 | 77.1 | ||
| R152x4 | 74.7 | 94.2 | 79.2 | 57.8 | 62.9 | 51.2 | 50.8 | 85.4 | 75.4 | 93.1 | 91.2 | 91.4 | 98.9 | 61.4 | 97.2 | 98.0 | 85.5 | 72.8 | 67.9 | 14.9 | 83.1 | 76.0 | 50.3 | 42.9 | 53.6 | 56.0 | 78.5 | ||
| BiT-M | R50x1 | 83.3 | 94.9 | 82.2 | 70.9 | 69.9 | 59.0 | 55.6 | 86.8 | 77.3 | 91.5 | 93.9 | 99.4 | 98.0 | 60.6 | 98.4 | 97.5 | 87.4 | 68.6 | 68.2 | 16.6 | 82.5 | 79.4 | 53.2 | 49.4 | 54.5 | 53.4 | 76.7 | |
| R50x3 | 86.9 | 96.7 | 86.2 | 75.7 | 74.6 | 60.6 | 54.2 | 87.7 | 78.5 | 93.2 | 95.3 | 99.4 | 98.6 | 64.6 | 99.3 | 98.0 | 88.1 | 69.9 | 59.6 | 19.6 | 83.4 | 83.5 | 57.8 | 51.3 | 55.8 | 55.6 | 80.7 | ||
| R101x1 | 85.5 | 95.7 | 84.4 | 73.0 | 72.5 | 59.8 | 55.0 | 87.3 | 78.1 | 92.2 | 95.0 | 99.5 | 98.1 | 62.5 | 99.0 | 97.6 | 87.8 | 68.7 | 67.7 | 18.0 | 84.0 | 82.3 | 55.9 | 53.4 | 54.8 | 53.1 | 79.4 | ||
| R101x3 | 87.2 | 97.4 | 87.5 | 72.4 | 75.0 | 57.4 | 47.4 | 87.5 | 79.6 | 93.2 | 95.4 | 99.6 | 98.6 | 64.3 | 99.4 | 98.2 | 87.7 | 68.8 | 64.1 | 20.7 | 80.4 | 84.0 | 58.7 | 52.6 | 54.9 | 54.3 | 81.2 | ||
| R152x2 | 88.0 | 97.5 | 87.8 | 75.8 | 75.9 | 61.5 | 55.3 | 88.1 | 79.8 | 93.6 | 95.9 | 99.5 | 98.5 | 64.3 | 99.5 | 97.9 | 89.0 | 70.0 | 70.3 | 20.7 | 82.6 | 85.5 | 59.6 | 50.8 | 54.9 | 55.1 | 81.9 | ||
| R152x4 | 87.2 | 97.6 | 88.2 | 72.4 | 75.0 | 49.1 | 43.4 | 87.1 | 79.9 | 92.4 | 95.4 | 99.3 | 98.5 | 65.7 | 99.5 | 97.8 | 87.7 | 68.2 | 57.1 | 20.6 | 80.4 | 84.6 | 59.0 | 49.7 | 57.2 | 55.1 | 81.5 | ||
| ViT | B/32 | 81.8 | 96.7 | 86.3 | 65.2 | 70.7 | 49.1 | 42.7 | 85.3 | 73.1 | 90.4 | 94.5 | 98.7 | 97.8 | 59.0 | 99.0 | 96.3 | 83.0 | 68.1 | 65.1 | 15.7 | 82.6 | 79.1 | 51.7 | 38.9 | 57.1 | 54.6 | 76.6 | |
| B/16 | 86.7 | 96.9 | 86.4 | 74.0 | 74.2 | 54.7 | 46.0 | 86.7 | 74.3 | 92.7 | 94.1 | 99.2 | 97.4 | 61.3 | 99.5 | 96.4 | 84.5 | 63.1 | 61.5 | 17.5 | 85.4 | 82.7 | 56.6 | 40.0 | 57.0 | 56.1 | 80.9 | ||
| L/16 | 87.4 | 97.9 | 89.0 | 76.5 | 74.9 | 62.5 | 52.2 | 86.1 | 75.0 | 92.9 | 94.7 | 99.3 | 98.0 | 64.0 | 99.6 | 96.5 | 85.7 | 70.4 | 58.8 | 17.7 | 85.7 | 84.1 | 58.0 | 38.4 | 58.4 | 52.8 | 81.9 | ||
| H/14 | 83.4 | 95.8 | 84.5 | 70.2 | 69.2 | 62.3 | 54.8 | 84.7 | 75.4 | 91.7 | 93.7 | 98.9 | 98.5 | 62.4 | 98.4 | 97.3 | 87.0 | 73.9 | 63.4 | 15.4 | 87.0 | 79.4 | 52.1 | 41.1 | 55.9 | 54.1 | 75.9 | ||
| SimCLRv2 | R50x1 | 76.4 | 93.2 | 77.9 | 48.6 | 64.1 | 56.3 | 51.7 | 84.4 | 77.0 | 88.3 | 91.8 | 92.9 | 97.6 | 59.7 | 96.7 | 97.5 | 85.8 | 71.1 | 69.1 | 15.8 | 84.8 | 78.4 | 51.0 | 56.2 | 53.9 | 53.8 | 73.8 | |
| R50x3 | 81.0 | 95.6 | 82.4 | 56.5 | 67.0 | 65.6 | 61.1 | 85.9 | 78.8 | 90.9 | 94.1 | 95.4 | 98.7 | 62.6 | 98.2 | 97.9 | 88.2 | 78.2 | 74.7 | 17.6 | 85.4 | 82.6 | 54.6 | 55.4 | 54.2 | 55.2 | 77.3 | ||
| R101x1 | 77.9 | 94.8 | 79.9 | 51.9 | 65.2 | 57.1 | 52.0 | 85.4 | 77.2 | 90.0 | 91.6 | 92.7 | 97.2 | 59.4 | 97.6 | 96.8 | 84.6 | 65.7 | 70.6 | 16.1 | 84.3 | 78.8 | 52.4 | 53.6 | 55.1 | 55.7 | 76.1 | ||
| R101x3 | 82.2 | 96.4 | 83.4 | 57.5 | 68.2 | 64.6 | 60.0 | 86.2 | 78.9 | 91.8 | 95.0 | 95.4 | 98.4 | 63.0 | 98.5 | 97.9 | 88.0 | 77.5 | 69.1 | 18.3 | 85.5 | 82.9 | 55.9 | 52.2 | 54.5 | 56.3 | 78.8 | ||
| R152x1 | 78.6 | 95.0 | 79.9 | 50.3 | 65.6 | 55.6 | 52.2 | 85.8 | 77.3 | 90.1 | 92.5 | 91.8 | 97.6 | 59.8 | 98.1 | 96.6 | 84.3 | 64.8 | 70.3 | 16.6 | 83.9 | 79.4 | 53.1 | 57.2 | 55.8 | 54.8 | 76.9 | ||
| R152x2 | 82.3 | 96.7 | 83.9 | 58.1 | 68.5 | 64.9 | 58.7 | 86.6 | 79.1 | 92.2 | 94.1 | 96.0 | 98.2 | 64.1 | 98.5 | 98.0 | 88.1 | 77.0 | 69.8 | 18.4 | 85.3 | 82.7 | 56.2 | 53.6 | 56.0 | 56.5 | 79.2 | ||
| R152x3 | 83.6 | 96.8 | 84.5 | 60.3 | 69.1 | 68.5 | 63.1 | 86.7 | 80.5 | 92.6 | 94.9 | 96.3 | 98.7 | 65.4 | 98.8 | 98.1 | 89.5 | 78.4 | 68.5 | 19.4 | 85.2 | 83.5 | 57.0 | 54.4 | 54.6 | 54.2 | 80.0 | ||
| BYOL | 50x1 | 74.0 | 93.6 | 79.1 | 47.6 | 63.7 | 61.6 | 62.3 | 82.6 | 77.0 | 88.3 | 93.7 | 94.3 | 98.7 | 58.8 | 96.4 | 97.6 | 88.2 | 80.1 | 71.4 | 14.1 | 84.8 | 77.3 | 49.3 | 56.1 | 53.8 | 54.4 | 73.3 | |
| 200x2 | 78.5 | 96.2 | 83.3 | 53.4 | 68.5 | 61.7 | 55.4 | 86.6 | 77.4 | 91.9 | 95.5 | 93.9 | 98.7 | 62.6 | 98.6 | 97.7 | 87.4 | 77.1 | 76.4 | 16.4 | 84.0 | 82.6 | 55.1 | 54.1 | 52.5 | 52.4 | 79.2 | ||
| MoCo | v1 | 65.9 | 85.0 | 63.1 | 27.5 | 52.6 | 35.9 | 43.5 | 75.7 | 70.0 | 70.4 | 78.1 | 85.4 | 97.6 | 54.3 | 85.6 | 97.1 | 82.9 | 62.6 | 60.2 | 12.6 | 85.7 | 64.2 | 40.7 | 54.7 | 55.6 | 53.5 | 57.2 | |
| v2 | 72.2 | 93.4 | 76.3 | 39.6 | 60.2 | 48.3 | 51.1 | 82.6 | 75.1 | 84.4 | 89.9 | 90.7 | 98.4 | 58.3 | 95.7 | 97.2 | 85.4 | 75.7 | 75.4 | 13.2 | 85.6 | 72.7 | 47.8 | 56.9 | 53.9 | 53.8 | 69.1 | ||
| VirTex | 57.9 | 83.9 | 57.5 | 17.0 | 49.8 | 22.4 | 34.5 | 83.8 | 58.2 | 53.6 | 70.6 | 74.7 | 98.1 | 56.5 | 86.7 | 94.8 | 74.1 | 69.5 | 71.3 | 8.7 | 83.1 | 61.5 | 39.9 | 45.5 | 53.5 | 55.8 | 50.7 | ||
| ResNet | 50 | 71.3 | 91.8 | 74.5 | 52.7 | 60.5 | 49.9 | 48.5 | 83.8 | 72.3 | 92.4 | 90.8 | 90.8 | 98.3 | 54.9 | 96.4 | 96.7 | 83.6 | 70.6 | 67.1 | 11.7 | 82.5 | 71.2 | 46.8 | 43.0 | 56.5 | 55.5 | 74.3 | |
| 101 | 72.7 | 93.0 | 77.2 | 53.7 | 60.8 | 50.1 | 47.0 | 84.4 | 71.6 | 92.3 | 91.9 | 90.4 | 98.5 | 56.6 | 97.0 | 97.1 | 83.4 | 72.5 | 63.6 | 11.9 | 83.3 | 72.7 | 48.3 | 43.2 | 53.0 | 54.7 | 75.8 | ||
| 152 | 73.7 | 93.5 | 78.0 | 55.1 | 61.6 | 52.8 | 48.4 | 84.5 | 71.9 | 93.0 | 92.1 | 89.6 | 98.2 | 57.0 | 97.6 | 97.0 | 83.1 | 70.1 | 70.2 | 12.3 | 82.9 | 75.3 | 49.2 | 42.4 | 53.2 | 53.9 | 77.1 |
Table 10: Linear probe performance of various pre-trained models over 27 datasets. Scores within the 99.5% Clopper-Pearson confidence interval of each dataset’s top score are shown in bold. ⋆We updated the STL10 scores from the previous version of this paper after fixing a CUDA-related bug.
| Food101 | CIFAR10 | CIFAR100 | Birdsnap | SUN397 | Cars | Aircraft | VOC2007 | DTD | Pets | Caltech101 | Flowers | MNIST | FER2013 | STL10⋆ | EuroSAT | RESISC45 | GTSRB | KITTI | Country211 | PCAM | UCF101 | Kinetics700 | CLEVR | HatefulMemes | SST | ImageNet | |||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| LM RN50 | 81.3 | 82.8 | 61.7 | 44.2 | 69.6 | 74.9 | 44.9 | 85.5 | 71.5 | 82.8 | 85.5 | 91.1 | 96.6 | 60.1 | 95.3 | 93.4 | 84.0 | 73.8 | 70.2 | 19.0 | 82.9 | 76.4 | 51.9 | 51.2 | 65.2 | 76.8 | 65.2 | ||
| CLIP-RN | 50 | 86.4 | 88.7 | 70.3 | 56.4 | 73.3 | 78.3 | 49.1 | 87.1 | 76.4 | 88.2 | 89.6 | 96.1 | 98.3 | 64.2 | 96.6 | 95.2 | 87.5 | 82.4 | 70.2 | 25.3 | 82.7 | 81.6 | 57.2 | 53.6 | 65.7 | 72.6 | 73.3 | |
| 101 | 88.9 | 91.1 | 73.5 | 58.6 | 75.1 | 84.0 | 50.7 | 88.0 | 76.3 | 91.0 | 92.0 | 96.4 | 98.4 | 65.2 | 97.8 | 95.9 | 89.3 | 82.4 | 73.6 | 26.6 | 82.8 | 84.0 | 60.3 | 50.3 | 68.2 | 73.3 | 75.7 | ||
| 50x4 | 91.3 | 90.5 | 73.0 | 65.7 | 77.0 | 85.9 | 57.3 | 88.4 | 79.5 | 91.9 | 92.5 | 97.8 | 98.5 | 68.1 | 97.8 | 96.4 | 89.7 | 85.5 | 59.4 | 30.3 | 83.0 | 85.7 | 62.6 | 52.5 | 68.0 | 76.6 | 78.2 | ||
| 50x16 | 93.3 | 92.2 | 74.9 | 72.8 | 79.2 | 88.7 | 62.7 | 89.0 | 79.1 | 93.5 | 93.7 | 98.3 | 98.9 | 68.7 | 98.6 | 97.0 | 91.4 | 89.0 | 69.2 | 34.8 | 83.5 | 88.0 | 66.3 | 53.8 | 71.1 | 80.0 | 81.5 | ||
| 50x64 | 94.8 | 94.1 | 78.6 | 77.2 | 81.1 | 90.5 | 67.7 | 88.9 | 82.0 | 94.5 | 95.4 | 98.9 | 98.9 | 71.3 | 99.1 | 97.1 | 92.8 | 90.2 | 69.2 | 40.7 | 83.7 | 89.5 | 69.1 | 55.0 | 75.0 | 81.2 | 83.6 | ||
| CLIP-ViT | B/32 | 88.8 | 95.1 | 80.5 | 58.5 | 76.6 | 81.8 | 52.0 | 87.7 | 76.5 | 90.0 | 93.0 | 96.9 | 99.0 | 69.2 | 98.3 | 97.0 | 90.5 | 85.3 | 66.2 | 27.8 | 83.9 | 85.5 | 61.7 | 52.1 | 66.7 | 70.8 | 76.1 | |
| B/16 | 92.8 | 96.2 | 83.1 | 67.8 | 78.4 | 86.7 | 59.5 | 89.2 | 79.2 | 93.1 | 94.7 | 98.1 | 99.0 | 69.5 | 99.0 | 97.1 | 92.7 | 86.6 | 67.8 | 33.3 | 83.5 | 88.4 | 66.1 | 57.1 | 70.3 | 75.5 | 80.2 | ||
| L/14 | 95.2 | 98.0 | 87.5 | 77.0 | 81.8 | 90.9 | 69.4 | 89.6 | 82.1 | 95.1 | 96.5 | 99.2 | 99.2 | 72.2 | 99.7 | 98.2 | 94.1 | 92.5 | 64.7 | 42.9 | 85.8 | 91.5 | 72.0 | 57.8 | 76.2 | 80.8 | 83.9 | ||
| L/14-336px | 95.9 | 97.9 | 87.4 | 79.9 | 82.2 | 91.5 | 71.6 | 89.9 | 83.0 | 95.1 | 96.0 | 99.2 | 99.2 | 72.9 | 99.7 | 98.1 | 94.9 | 92.4 | 69.2 | 46.4 | 85.6 | 92.0 | 73.0 | 60.3 | 77.3 | 80.5 | 85.4 | ||
| EfficientNet | B0 | 74.3 | 92.5 | 76.5 | 59.7 | 62.0 | 62.5 | 55.7 | 84.4 | 71.2 | 93.0 | 93.3 | 91.7 | 98.2 | 57.2 | 97.1 | 97.3 | 85.5 | 80.0 | 73.8 | 12.4 | 83.1 | 74.4 | 47.6 | 47.9 | 55.7 | 53.4 | 76.9 | |
| B1 | 74.2 | 93.2 | 77.2 | 61.3 | 62.6 | 62.5 | 56.1 | 84.7 | 74.2 | 93.4 | 93.6 | 92.4 | 98.3 | 57.0 | 97.5 | 96.8 | 84.5 | 75.9 | 75.5 | 12.5 | 82.7 | 74.7 | 48.5 | 44.3 | 54.5 | 54.4 | 78.6 | ||
| B2 | 75.8 | 93.6 | 77.9 | 64.4 | 64.0 | 63.2 | 57.0 | 85.3 | 73.5 | 93.9 | 93.5 | 92.9 | 98.5 | 56.6 | 97.7 | 96.9 | 84.4 | 76.4 | 73.1 | 12.6 | 84.3 | 75.1 | 49.4 | 42.6 | 55.4 | 55.2 | 79.7 | ||
| B3 | 77.4 | 94.0 | 78.0 | 66.5 | 64.4 | 66.0 | 59.3 | 85.8 | 73.1 | 94.1 | 93.7 | 93.3 | 98.5 | 57.1 | 98.2 | 97.3 | 85.0 | 75.8 | 76.1 | 13.4 | 83.3 | 78.1 | 50.9 | 45.1 | 53.8 | 54.8 | 81.0 | ||
| B4 | 79.7 | 94.1 | 78.7 | 70.1 | 65.4 | 66.4 | 60.4 | 86.5 | 73.4 | 94.7 | 93.5 | 93.2 | 98.8 | 57.9 | 98.6 | 96.8 | 85.0 | 78.3 | 72.3 | 13.9 | 83.1 | 79.1 | 52.5 | 46.5 | 54.4 | 55.4 | 82.9 | ||
| B5 | 81.5 | 93.6 | 77.9 | 72.4 | 67.1 | 72.7 | 68.9 | 86.7 | 73.9 | 95.0 | 94.7 | 94.5 | 98.4 | 58.5 | 98.7 | 96.8 | 86.0 | 78.5 | 69.6 | 14.9 | 84.7 | 80.9 | 54.5 | 46.6 | 53.3 | 56.3 | 83.7 | ||
| B6 | 82.4 | 94.0 | 78.0 | 73.5 | 65.8 | 71.1 | 68.2 | 87.6 | 73.9 | 95.0 | 94.1 | 93.7 | 98.4 | 60.2 | 98.7 | 96.8 | 85.4 | 78.1 | 72.7 | 15.3 | 84.2 | 80.0 | 54.1 | 51.1 | 53.3 | 57.0 | 84.0 | ||
| B7 | 84.5 | 94.9 | 80.1 | 74.7 | 69.0 | 77.1 | 72.3 | 87.2 | 76.8 | 95.2 | 94.7 | 95.9 | 98.6 | 61.3 | 99.1 | 96.3 | 86.8 | 80.8 | 75.8 | 16.4 | 85.2 | 81.9 | 56.8 | 51.9 | 54.4 | 57.8 | 84.8 | ||
| B8 | 84.5 | 95.0 | 80.7 | 75.2 | 69.6 | 76.8 | 71.5 | 87.4 | 77.1 | 94.9 | 95.2 | 96.3 | 98.6 | 61.4 | 99.2 | 97.0 | 87.4 | 80.4 | 70.9 | 17.4 | 85.2 | 82.4 | 57.7 | 51.4 | 51.7 | 55.8 | 85.3 | ||
| EfficientNet Noisy Student | B0 | 78.1 | 94.0 | 78.6 | 63.5 | 65.5 | 57.2 | 53.7 | 85.6 | 75.6 | 93.8 | 93.1 | 94.5 | 98.1 | 55.6 | 98.2 | 97.0 | 84.3 | 74.0 | 71.6 | 14.0 | 83.1 | 76.7 | 51.7 | 47.3 | 55.7 | 55.0 | 78.5 | |
| B1 | 80.4 | 95.1 | 80.2 | 66.6 | 67.6 | 59.6 | 53.7 | 86.2 | 77.0 | 94.6 | 94.4 | 95.1 | 98.0 | 56.1 | 98.6 | 96.9 | 84.3 | 73.1 | 67.1 | 14.5 | 83.9 | 79.9 | 54.5 | 46.1 | 54.3 | 54.9 | 81.1 | ||
| B2 | 80.9 | 95.3 | 81.3 | 67.6 | 67.9 | 60.9 | 55.2 | 86.3 | 77.7 | 95.0 | 94.7 | 94.4 | 98.0 | 55.5 | 98.8 | 97.3 | 84.6 | 71.7 | 70.0 | 14.6 | 82.9 | 80.1 | 55.1 | 46.1 | 54.1 | 55.3 | 82.2 | ||
| B3 | 82.6 | 95.9 | 82.1 | 68.6 | 68.8 | 60.6 | 55.4 | 86.5 | 77.2 | 95.0 | 94.8 | 95.2 | 98.1 | 56.0 | 99.1 | 96.5 | 85.0 | 70.5 | 69.5 | 15.1 | 83.1 | 81.8 | 56.8 | 45.1 | 55.7 | 52.0 | 83.8 | ||
| B4 | 85.2 | 95.6 | 81.0 | 72.5 | 69.7 | 56.1 | 52.6 | 87.0 | 78.7 | 94.8 | 95.2 | 95.3 | 98.2 | 56.0 | 99.3 | 95.3 | 84.8 | 61.9 | 64.8 | 16.0 | 82.8 | 83.4 | 59.8 | 43.2 | 55.3 | 53.0 | 85.4 | ||
| B5 | 87.6 | 96.3 | 82.4 | 75.3 | 71.6 | 64.7 | 64.8 | 87.8 | 79.6 | 95.5 | 95.6 | 96.6 | 98.8 | 60.9 | 99.4 | 96.1 | 87.0 | 68.5 | 73.7 | 16.4 | 83.5 | 86.4 | 61.6 | 46.3 | 53.4 | 55.8 | 85.8 | ||
| B6 | 87.3 | 97.0 | 83.9 | 75.8 | 71.4 | 67.6 | 65.6 | 87.3 | 78.5 | 95.2 | 96.4 | 97.2 | 98.6 | 61.9 | 99.5 | 96.6 | 86.1 | 70.7 | 72.4 | 17.6 | 84.2 | 85.5 | 61.0 | 49.6 | 54.6 | 55.7 | 86.4 | ||
| B7 | 88.4 | 96.0 | 82.0 | 76.9 | 72.6 | 72.2 | 71.2 | 88.1 | 80.5 | 95.5 | 95.5 | 96.6 | 98.5 | 62.7 | 99.4 | 96.2 | 88.5 | 73.4 | 73.0 | 18.5 | 83.8 | 86.6 | 63.2 | 50.5 | 57.2 | 56.7 | 87.0 | ||
| L2-475 | 91.6 | 99.0 | 91.0 | 74.8 | 76.4 | 75.1 | 66.8 | 89.5 | 81.9 | 95.6 | 96.5 | 97.7 | 98.9 | 67.5 | 99.6 | 97.0 | 89.5 | 73.4 | 68.9 | 22.2 | 86.3 | 89.4 | 68.2 | 58.3 | 58.6 | 55.2 | 88.3 | ||
| L2-800 | 92.0 | 98.7 | 89.0 | 78.5 | 75.7 | 75.5 | 68.4 | 89.4 | 82.5 | 95.6 | 94.7 | 97.9 | 98.5 | 68.4 | 99.7 | 97.2 | 89.9 | 77.7 | 66.9 | 23.7 | 86.8 | 88.9 | 66.7 | 62.7 | 58.4 | 56.9 | 88.4 | ||
| 32x8d | 84.8 | 95.9 | 80.9 | 63.8 | 69.0 | 74.2 | 56.0 | 88.0 | 75.4 | 95.4 | 93.9 | 91.7 | 97.4 | 60.7 | 99.1 | 95.7 | 82.1 | 72.3 | 69.2 | 16.7 | 82.3 | 80.1 | 56.8 | 42.2 | 53.3 | 55.2 | 83.3 | ||
| 32x16d | 85.7 | 96.5 | 80.9 | 64.8 | 70.5 | 77.5 | 56.7 | 87.9 | 76.2 | 95.6 | 94.9 | 92.5 | 97.4 | 61.6 | 99.3 | 95.5 | 82.8 | 73.8 | 66.1 | 17.5 | 83.4 | 81.1 | 58.2 | 41.3 | 54.2 | 56.1 | 84.4 | ||
| 32x32d | 86.7 | 96.8 | 82.7 | 67.1 | 71.5 | 77.5 | 55.4 | 88.3 | 78.5 | 95.8 | 95.3 | 94.4 | 97.9 | 62.4 | 99.3 | 95.7 | 85.4 | 71.2 | 66.8 | 18.0 | 83.7 | 82.1 | 58.8 | 39.7 | 55.3 | 56.7 | 85.0 | ||
| 32x48d | 86.9 | 96.8 | 83.4 | 65.9 | 72.2 | 76.6 | 53.2 | 88.0 | 77.2 | 95.5 | 95.8 | 93.6 | 98.1 | 63.7 | 99.4 | 95.3 | 85.4 | 73.0 | 67.2 | 18.5 | 82.7 | 82.8 | 59.2 | 41.3 | 55.5 | 56.7 | 85.2 | ||
| FixRes-v1 | 88.5 | 95.7 | 81.1 | 67.4 | 72.9 | 80.5 | 57.6 | 88.0 | 77.9 | 95.8 | 96.1 | 94.5 | 97.9 | 62.2 | 99.4 | 96.2 | 86.6 | 76.5 | 64.8 | 19.3 | 82.5 | 83.4 | 59.8 | 43.5 | 56.6 | 59.0 | 86.0 | ||
| FixRes-v2 | 88.5 | 95.7 | 81.1 | 67.3 | 72.9 | 80.7 | 57.5 | 88.0 | 77.9 | 95.0 | 96.0 | 94.5 | 98.0 | 62.1 | 99.4 | 96.5 | 86.6 | 76.3 | 64.8 | 19.5 | 82.3 | 83.5 | 59.8 | 44.2 | 56.6 | 59.0 | 86.0 | ||
| BiT-S | R50x1 | 72.5 | 91.7 | 74.8 | 57.7 | 61.1 | 53.5 | 52.5 | 83.7 | 72.4 | 92.3 | 91.2 | 92.0 | 98.4 | 56.1 | 96.4 | 97.4 | 85.0 | 70.0 | 66.0 | 12.5 | 83.0 | 72.3 | 47.5 | 48.3 | 54.1 | 55.3 | 75.2 | |
| R50x3 | 75.1 | 93.7 | 79.0 | 61.1 | 63.7 | 55.2 | 54.1 | 84.8 | 74.6 | 92.5 | 91.6 | 92.8 | 98.8 | 58.7 | 97.0 | 97.8 | 86.4 | 73.1 | 73.8 | 14.0 | 84.2 | 76.4 | 50.0 | 49.2 | 54.7 | 54.2 | 77.2 | ||
| R101x1 | 73.5 | 92.8 | 77.4 | 58.4 | 61.3 | 54.0 | 52.4 | 84.4 | 73.5 | 92.5 | 91.8 | 90.6 | 98.3 | 56.5 | 96.8 | 97.3 | 84.6 | 69.4 | 68.9 | 12.6 | 82.0 | 73.5 | 48.6 | 45.4 | 52.6 | 55.5 | 76.0 | ||
| R101x3 | 74.7 | 93.9 | 79.8 | 57.8 | 62.9 | 54.7 | 53.3 | 84.7 | 75.5 | 92.3 | 91.2 | 92.6 | 98.8 | 59.7 | 97.3 | 98.0 | 85.5 | 71.8 | 60.2 | 14.1 | 83.1 | 75.9 | 50.4 | 49.7 | 54.1 | 54.6 | 77.4 | ||
| R152x2 | 74.9 | 94.3 | 79.7 | 58.7 | 62.7 | 55.9 | 53.6 | 85.3 | 74.9 | 93.0 | 92.0 | 91.7 | 98.6 | 58.3 | 97.1 | 97.8 | 86.2 | 71.8 | 71.6 | 13.9 | 84.1 | 76.2 | 49.9 | 48.2 | 53.8 | 55.9 | 77.1 | ||
| R152x4 | 74.7 | 94.2 | 79.2 | 57.8 | 62.9 | 51.2 | 50.8 | 85.4 | 75.4 | 93.1 | 91.2 | 91.4 | 98.9 | 61.4 | 97.2 | 98.0 | 85.5 | 72.8 | 67.9 | 14.9 | 83.1 | 76.0 | 50.3 | 42.9 | 53.6 | 56.0 | 78.5 | ||
| BiT-M | R50x1 | 83.3 | 94.9 | 82.2 | 70.9 | 69.9 | 59.0 | 55.6 | 86.8 | 77.3 | 91.5 | 93.9 | 99.4 | 98.0 | 60.6 | 98.4 | 97.5 | 87.4 | 68.6 | 68.2 | 16.6 | 82.5 | 79.4 | 53.2 | 49.4 | 54.5 | 53.4 | 76.7 | |
| R50x3 | 86.9 | 96.7 | 86.2 | 75.7 | 74.6 | 60.6 | 54.2 | 87.7 | 78.5 | 93.2 | 95.3 | 99.4 | 98.6 | 64.6 | 99.3 | 98.0 | 88.1 | 69.9 | 59.6 | 19.6 | 83.4 | 83.5 | 57.8 | 51.3 | 55.8 | 55.6 | 80.7 | ||
| R101x1 | 85.5 | 95.7 | 84.4 | 73.0 | 72.5 | 59.8 | 55.0 | 87.3 | 78.1 | 92.2 | 95.0 | 99.5 | 98.1 | 62.5 | 99.0 | 97.6 | 87.8 | 68.7 | 67.7 | 18.0 | 84.0 | 82.3 | 55.9 | 53.4 | 54.8 | 53.1 | 79.4 | ||
| R101x3 | 87.2 | 97.4 | 87.5 | 72.4 | 75.0 | 57.4 | 47.4 | 87.5 | 79.6 | 93.2 | 95.4 | 99.6 | 98.6 | 64.3 | 99.4 | 98.2 | 87.7 | 68.8 | 64.1 | 20.7 | 80.4 | 84.0 | 58.7 | 52.6 | 54.9 | 54.3 | 81.2 | ||
| R152x2 | 88.0 | 97.5 | 87.8 | 75.8 | 75.9 | 61.5 | 55.3 | 88.1 | 79.8 | 93.6 | 95.9 | 99.5 | 98.5 | 64.3 | 99.5 | 97.9 | 89.0 | 70.0 | 70.3 | 20.7 | 82.6 | 85.5 | 59.6 | 50.8 | 54.9 | 55.1 | 81.9 | ||
| R152x4 | 87.2 | 97.6 | 88.2 | 72.4 | 75.0 | 49.1 | 43.4 | 87.1 | 79.9 | 92.4 | 95.4 | 99.3 | 98.5 | 65.7 | 99.5 | 97.8 | 87.7 | 68.2 | 57.1 | 20.6 | 80.4 | 84.6 | 59.0 | 49.7 | 57.2 | 55.1 | 81.5 | ||
| ViT | B/32 | 81.8 | 96.7 | 86.3 | 65.2 | 70.7 | 49.1 | 42.7 | 85.3 | 73.1 | 90.4 | 94.5 | 98.7 | 97.8 | 59.0 | 99.0 | 96.3 | 83.0 | 68.1 | 65.1 | 15.7 | 82.6 | 79.1 | 51.7 | 38.9 | 57.1 | 54.6 | 76.6 | |
| B/16 | 86.7 | 96.9 | 86.4 | 74.0 | 74.2 | 54.7 | 46.0 | 86.7 | 74.3 | 92.7 | 94.1 | 99.2 | 97.4 | 61.3 | 99.5 | 96.4 | 84.5 | 63.1 | 61.5 | 17.5 | 85.4 | 82.7 | 56.6 | 40.0 | 57.0 | 56.1 | 80.9 | ||
| L/16 | 87.4 | 97.9 | 89.0 | 76.5 | 74.9 | 62.5 | 52.2 | 86.1 | 75.0 | 92.9 | 94.7 | 99.3 | 98.0 | 64.0 | 99.6 | 96.5 | 85.7 | 70.4 | 58.8 | 17.7 | 85.7 | 84.1 | 58.0 | 38.4 | 58.4 | 52.8 | 81.9 | ||
| H/14 | 83.4 | 95.8 | 84.5 | 70.2 | 69.2 | 62.3 | 54.8 | 84.7 | 75.4 | 91.7 | 93.7 | 98.9 | 98.5 | 62.4 | 98.4 | 97.3 | 87.0 | 73.9 | 63.4 | 15.4 | 87.0 | 79.4 | 52.1 | 41.1 | 55.9 | 54.1 | 75.9 | ||
| SimCLRv2 | R50x1 | 76.4 | 93.2 | 77.9 | 48.6 | 64.1 | 56.3 | 51.7 | 84.4 | 77.0 | 88.3 | 91.8 | 92.9 | 97.6 | 59.7 | 96.7 | 97.5 | 85.8 | 71.1 | 69.1 | 15.8 | 84.8 | 78.4 | 51.0 | 56.2 | 53.9 | 53.8 | 73.8 | |
| R50x3 | 81.0 | 95.6 | 82.4 | 56.5 | 67.0 | 65.6 | 61.1 | 85.9 | 78.8 | 90.9 | 94.1 | 95.4 | 98.7 | 62.6 | 98.2 | 97.9 | 88.2 | 78.2 | 74.7 | 17.6 | 85.4 | 82.6 | 54.6 | 55.4 | 54.2 | 55.2 | 77.3 | ||
| R101x1 | 77.9 | 94.8 | 79.9 | 51.9 | 65.2 | 57.1 | 52.0 | 85.4 | 77.2 | 90.0 | 91.6 | 92.7 | 97.2 | 59.4 | 97.6 | 96.8 | 84.6 | 65.7 | 70.6 | 16.1 | 84.3 | 78.8 | 52.4 | 53.6 | 55.1 | 55.7 | 76.1 | ||
| R101x3 | 82.2 | 96.4 | 83.4 | 57.5 | 68.2 | 64.6 | 60.0 | 86.2 | 78.9 | 91.8 | 95.0 | 95.4 | 98.4 | 63.0 | 98.5 | 97.9 | 88.0 | 77.5 | 69.1 | 18.3 | 85.5 | 82.9 | 55.9 | 52.2 | 54.5 | 56.3 | 78.8 | ||
| R152x1 | 78.6 | 95.0 | 79.9 | 50.3 | 65.6 | 55.6 | 52.2 | 85.8 | 77.3 | 90.1 | 92.5 | 91.8 | 97.6 | 59.8 | 98.1 | 96.6 | 84.3 | 64.8 | 70.3 | 16.6 | 83.9 | 79.4 | 53.1 | 57.2 | 55.8 | 54.8 | 76.9 | ||
| R152x2 | 82.3 | 96.7 | 83.9 | 58.1 | 68.5 | 64.9 | 58.7 | 86.6 | 79.1 | 92.2 | 94.1 | 96.0 | 98.2 | 64.1 | 98.5 | 98.0 | 88.1 | 77.0 | 69.8 | 18.4 | 85.3 | 82.7 | 56.2 | 53.6 | 56.0 | 56.5 | 79.2 | ||
| R152x3 | 83.6 | 96.8 | 84.5 | 60.3 | 69.1 | 68.5 | 63.1 | 86.7 | 80.5 | 92.6 | 94.9 | 96.3 | 98.7 | 65.4 | 98.8 | 98.1 | 89.5 | 78.4 | 68.5 | 19.4 | 85.2 | 83.5 | 57.0 | 54.4 | 54.6 | 54.2 | 80.0 | ||
| BYOL | 50x1 | 74.0 | 93.6 | 79.1 | 47.6 | 63.7 | 61.6 | 62.3 | 82.6 | 77.0 | 88.3 | 93.7 | 94.3 | 98.7 | 58.8 | 96.4 | 97.6 | 88.2 | 80.1 | 71.4 | 14.1 | 84.8 | 77.3 | 49.3 | 56.1 | 53.8 | 54.4 | 73.3 | |
| 200x2 | 78.5 | 96.2 | 83.3 | 53.4 | 68.5 | 61.7 | 55.4 | 86.6 | 77.4 | 91.9 | 95.5 | 93.9 | 98.7 | 62.6 | 98.6 | 97.7 | 87.4 | 77.1 | 76.4 | 16.4 | 84.0 | 82.6 | 55.1 | 54.1 | 52.5 | 52.4 | 79.2 | ||
| MoCo | v1 | 65.9 | 85.0 | 63.1 | 27.5 | 52.6 | 35.9 | 43.5 | 75.7 | 70.0 | 70.4 | 78.1 | 85.4 | 97.6 | 54.3 | 85.6 | 97.1 | 82.9 | 62.6 | 60.2 | 12.6 | 85.7 | 64.2 | 40.7 | 54.7 | 55.6 | 53.5 | 57.2 | |
| v2 | 72.2 | 93.4 | 76.3 | 39.6 | 60.2 | 48.3 | 51.1 | 82.6 | 75.1 | 84.4 | 89.9 | 90.7 | 98.4 | 58.3 | 95.7 | 97.2 | 85.4 | 75.7 | 75.4 | 13.2 | 85.6 | 72.7 | 47.8 | 56.9 | 53.9 | 53.8 | 69.1 | ||
| VirTex | 57.9 | 83.9 | 57.5 | 17.0 | 49.8 | 22.4 | 34.5 | 83.8 | 58.2 | 53.6 | 70.6 | 74.7 | 98.1 | 56.5 | 86.7 | 94.8 | 74.1 | 69.5 | 71.3 | 8.7 | 83.1 | 61.5 | 39.9 | 45.5 | 53.5 | 55.8 | 50.7 | ||
| ResNet | 50 | 71.3 | 91.8 | 74.5 | 52.7 | 60.5 | 49.9 | 48.5 | 83.8 | 72.3 | 92.4 | 90.8 | 90.8 | 98.3 | 54.9 | 96.4 | 96.7 | 83.6 | 70.6 | 67.1 | 11.7 | 82.5 | 71.2 | 46.8 | 43.0 | 56.5 | 55.5 | 74.3 | |
| 101 | 72.7 | 93.0 | 77.2 | 53.7 | 60.8 | 50.1 | 47.0 | 84.4 | 71.6 | 92.3 | 91.9 | 90.4 | 98.5 | 56.6 | 97.0 | 97.1 | 83.4 | 72.5 | 63.6 | 11.9 | 83.3 | 72.7 | 48.3 | 43.2 | 53.0 | 54.7 | 75.8 | ||
| 152 | 73.7 | 93.5 | 78.0 | 55.1 | 61.6 | 52.8 | 48.4 | 84.5 | 71.9 | 93.0 | 92.1 | 89.6 | 98.2 | 57.0 | 97.6 | 97.0 | 83.1 | 70.1 | 70.2 | 12.3 | 82.9 | 75.3 | 49.2 | 42.4 | 53.2 | 53.9 | 77.1 |
表 10:各预训练模型在 27 个数据集上的线性探测性能。落在各数据集最高分 99.5% Clopper-Pearson 置信区间内的分数以粗体标出。⋆在修复与 CUDA 相关的 bug 后,我们更新了本文先前版本中的 STL10 分数。
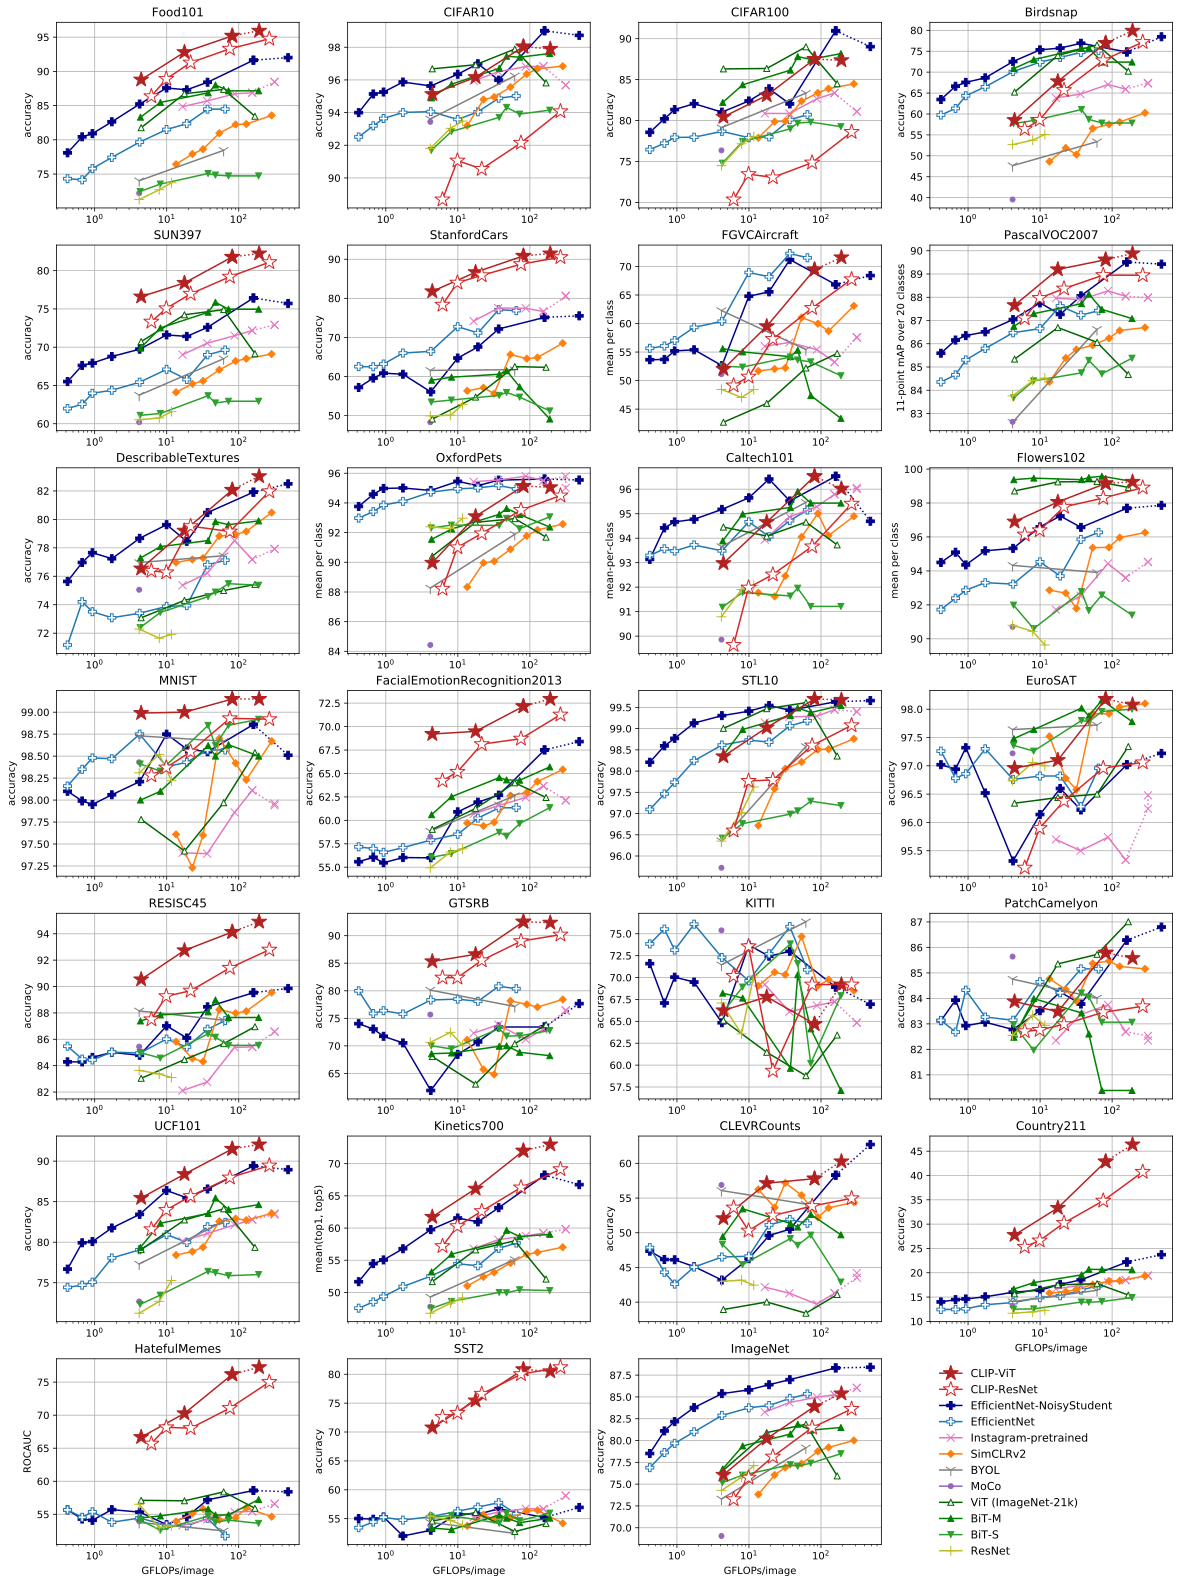
Figure 20: Linear probe performance plotted for each of the 27 datasets, using the data from Table 10.
图20:使用表10的数据,为每个27个数据集绘制的线性探针性能。
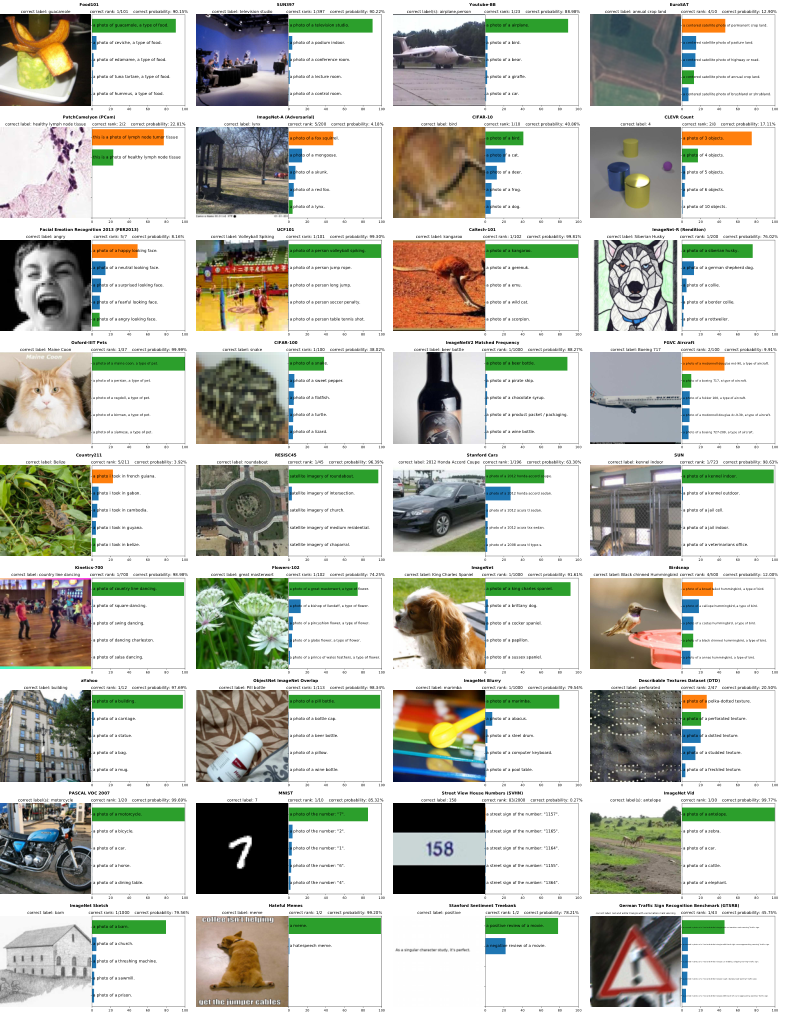
Figure 21: Visualization of predictions from 36 CLIP zero-shot classifiers. All examples are random with the exception of reselecting Hateful Memes to avoid offensive content. The predicted probability of the top 5 classes is shown along with the text used to represent the class. When more than one template is used, the first template is shown. The ground truth label is colored green while an incorrect prediction is colored orange.
图 21:来自 36 个 CLIP 零样本分类器的预测可视化。所有示例均为随机选择,但重新选择了“仇恨表情包”以避免出现冒犯性内容。显示了前 5 个类别的预测概率以及用于表示类别的文本。当使用多个模板时,显示第一个模板。真实标签用绿色标示,而错误预测用橙色标示。
| Food101 | CIFAR10 | CIFAR100 | Birdsnap | SUN397 | Stanford Cars | FGVC Aircraft | VOC2007 | DTD | Oxford Pets | Caltech101 | Flowers102 | MNIST | FER2013 | STL10 | EuroSAT | RESISC45 | GTSRB | KITTI | Country211 | PCam | UCF101 | Kinetics700 | CLEVR | HatefulMemes | Rendered SST2 | ImageNet | |||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| CLIP-ResNet | RN50 | 81.1 | 75.6 | 41.6 | 32.6 | 59.6 | 55.8 | 19.3 | 82.1 | 41.7 | 85.4 | 82.1 | 65.9 | 66.6 | 42.2 | 94.3 | 41.1 | 54.2 | 35.2 | 42.2 | 16.1 | 57.6 | 63.6 | 43.5 | 20.3 | 59.7 | 56.9 | 59.6 | |
| RN101 | 83.9 | 81.0 | 49.0 | 37.2 | 59.9 | 62.3 | 19.5 | 82.4 | 43.9 | 86.2 | 85.1 | 65.7 | 59.3 | 45.6 | 96.7 | 33.1 | 58.5 | 38.3 | 33.3 | 16.9 | 55.2 | 62.2 | 46.7 | 28.1 | 61.1 | 64.2 | 62.2 | ||
| RN50x4 | 86.8 | 79.2 | 48.9 | 41.6 | 62.7 | 67.9 | 24.6 | 83.0 | 49.3 | 88.1 | 86.0 | 68.0 | 75.2 | 51.1 | 96.4 | 35.0 | 59.2 | 35.7 | 26.0 | 20.2 | 57.5 | 65.5 | 49.0 | 17.0 | 58.3 | 66.6 | 65.8 | ||
| RN50x16 | 90.5 | 82.2 | 54.2 | 45.9 | 65.0 | 72.3 | 30.3 | 82.9 | 52.8 | 89.7 | 87.6 | 71.9 | 80.0 | 56.0 | 97.8 | 40.3 | 64.4 | 39.6 | 33.9 | 24.0 | 62.5 | 68.7 | 53.4 | 17.6 | 58.9 | 67.6 | 70.5 | ||
| RN50x64 | 91.8 | 86.8 | 61.3 | 48.9 | 66.9 | 76.0 | 35.6 | 83.8 | 53.4 | 93.4 | 90.6 | 77.3 | 90.8 | 61.0 | 98.3 | 59.4 | 69.7 | 47.9 | 33.2 | 29.6 | 65.0 | 74.1 | 56.8 | 27.5 | 62.1 | 70.7 | 73.6 | ||
| CLIP-ViT | B/32 | 84.4 | 91.3 | 65.1 | 37.8 | 63.2 | 59.4 | 21.2 | 83.1 | 44.5 | 87.0 | 87.9 | 66.7 | 51.9 | 47.3 | 97.2 | 49.4 | 60.3 | 32.2 | 39.4 | 17.8 | 58.4 | 64.5 | 47.8 | 24.8 | 57.6 | 59.6 | 63.2 | |
| B/16 | 89.2 | 91.6 | 68.7 | 39.1 | 65.2 | 65.6 | 27.1 | 83.9 | 46.0 | 88.9 | 89.3 | 70.4 | 56.0 | 52.7 | 98.2 | 54.1 | 65.5 | 43.3 | 44.0 | 23.3 | 48.1 | 69.8 | 52.4 | 23.4 | 61.7 | 59.8 | 68.6 | ||
| L/14 | 92.9 | 96.2 | 77.9 | 48.3 | 67.7 | 77.3 | 36.1 | 84.1 | 55.3 | 93.5 | 92.6 | 78.7 | 87.2 | 57.5 | 99.3 | 59.9 | 71.6 | 50.3 | 23.1 | 32.7 | 58.8 | 76.2 | 60.3 | 24.3 | 63.3 | 64.0 | 75.3 | ||
| L/14-336px | 93.8 | 95.7 | 77.5 | 49.5 | 68.4 | 78.8 | 37.2 | 84.3 | 55.7 | 93.5 | 92.8 | 78.3 | 88.3 | 57.7 | 99.4 | 59.6 | 71.7 | 52.3 | 21.9 | 34.9 | 63.0 | 76.9 | 61.3 | 24.8 | 63.3 | 67.9 | 76.2 |
Table 11: Zero-shot performance of CLIP models over 27 datasets.
| Food101 | CIFAR10 | CIFAR100 | Birdsnap | SUN397 | Stanford Cars | FGVC Aircraft | VOC2007 | DTD | Oxford Pets | Caltech101 | Flowers102 | MNIST | FER2013 | STL10 | EuroSAT | RESISC45 | GTSRB | KITTI | Country211 | PCam | UCF101 | Kinetics700 | CLEVR | HatefulMemes | Rendered SST2 | ImageNet | |||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| CLIP-ResNet | RN50 | 81.1 | 75.6 | 41.6 | 32.6 | 59.6 | 55.8 | 19.3 | 82.1 | 41.7 | 85.4 | 82.1 | 65.9 | 66.6 | 42.2 | 94.3 | 41.1 | 54.2 | 35.2 | 42.2 | 16.1 | 57.6 | 63.6 | 43.5 | 20.3 | 59.7 | 56.9 | 59.6 | |
| RN101 | 83.9 | 81.0 | 49.0 | 37.2 | 59.9 | 62.3 | 19.5 | 82.4 | 43.9 | 86.2 | 85.1 | 65.7 | 59.3 | 45.6 | 96.7 | 33.1 | 58.5 | 38.3 | 33.3 | 16.9 | 55.2 | 62.2 | 46.7 | 28.1 | 61.1 | 64.2 | 62.2 | ||
| RN50x4 | 86.8 | 79.2 | 48.9 | 41.6 | 62.7 | 67.9 | 24.6 | 83.0 | 49.3 | 88.1 | 86.0 | 68.0 | 75.2 | 51.1 | 96.4 | 35.0 | 59.2 | 35.7 | 26.0 | 20.2 | 57.5 | 65.5 | 49.0 | 17.0 | 58.3 | 66.6 | 65.8 | ||
| RN50x16 | 90.5 | 82.2 | 54.2 | 45.9 | 65.0 | 72.3 | 30.3 | 82.9 | 52.8 | 89.7 | 87.6 | 71.9 | 80.0 | 56.0 | 97.8 | 40.3 | 64.4 | 39.6 | 33.9 | 24.0 | 62.5 | 68.7 | 53.4 | 17.6 | 58.9 | 67.6 | 70.5 | ||
| RN50x64 | 91.8 | 86.8 | 61.3 | 48.9 | 66.9 | 76.0 | 35.6 | 83.8 | 53.4 | 93.4 | 90.6 | 77.3 | 90.8 | 61.0 | 98.3 | 59.4 | 69.7 | 47.9 | 33.2 | 29.6 | 65.0 | 74.1 | 56.8 | 27.5 | 62.1 | 70.7 | 73.6 | ||
| CLIP-ViT | B/32 | 84.4 | 91.3 | 65.1 | 37.8 | 63.2 | 59.4 | 21.2 | 83.1 | 44.5 | 87.0 | 87.9 | 66.7 | 51.9 | 47.3 | 97.2 | 49.4 | 60.3 | 32.2 | 39.4 | 17.8 | 58.4 | 64.5 | 47.8 | 24.8 | 57.6 | 59.6 | 63.2 | |
| B/16 | 89.2 | 91.6 | 68.7 | 39.1 | 65.2 | 65.6 | 27.1 | 83.9 | 46.0 | 88.9 | 89.3 | 70.4 | 56.0 | 52.7 | 98.2 | 54.1 | 65.5 | 43.3 | 44.0 | 23.3 | 48.1 | 69.8 | 52.4 | 23.4 | 61.7 | 59.8 | 68.6 | ||
| L/14 | 92.9 | 96.2 | 77.9 | 48.3 | 67.7 | 77.3 | 36.1 | 84.1 | 55.3 | 93.5 | 92.6 | 78.7 | 87.2 | 57.5 | 99.3 | 59.9 | 71.6 | 50.3 | 23.1 | 32.7 | 58.8 | 76.2 | 60.3 | 24.3 | 63.3 | 64.0 | 75.3 | ||
| L/14-336px | 93.8 | 95.7 | 77.5 | 49.5 | 68.4 | 78.8 | 37.2 | 84.3 | 55.7 | 93.5 | 92.8 | 78.3 | 88.3 | 57.7 | 99.4 | 59.6 | 71.7 | 52.3 | 21.9 | 34.9 | 63.0 | 76.9 | 61.3 | 24.8 | 63.3 | 67.9 | 76.2 |
表 11:CLIP 模型在 27 个数据集上的零样本性能。
Appendix B Zero-Shot Prediction
附录 B 零样本预测
To provide a qualitative summary / overview of CLIP’s zero-shot performance we visualize a randomly selected prediction for 36 different zero-shot CLIP classifiers in Figure 21. In addition, Table 22 and Figure 22 show the individual zero-shot performance scores for each dataset.
为了提供 CLIP 零样本性能的定性总结/概述,我们在图 21 中可视化了 36 个不同零样本 CLIP 分类器的随机选定预测。此外,表 22 和图 22 显示了每个数据集的单独零样本性能分数。
Appendix C Duplicate Detector
附录 C 重复检测器
Our early attempts at duplicate detection and analysis used nearest neighbors in the model’s learned embedding space. While it is intuitive to use a model’s own notion of similarity, we encountered issues. We found the model’s feature space is weighted very heavily towards semantic similarity. Many false positives occurred due to distinct objects that would be described similarly (soccer balls, flowers of the same species, etc…) having almost perfect similarity. We also observed the model was quite poor at assigning certain kinds of near-duplicates high similarity scores. We noticed repeatedly that images with high-frequency textures (such as fur or stripe patterns) pre-processed by different resizing algorithms (nearest neighbor vs bi-linear) could have surprisingly low similarity. This resulted in many false negatives.
我们早期在重复检测和分析上的尝试使用了模型学习到的嵌入空间中的最近邻。虽然使用模型自身的相似性概念很直观,但我们遇到了一些问题。我们发现模型的特征空间在语义相似性上权重非常高。许多假阳性是由于不同对象可能有相似的描述(足球、同种花等)而几乎完全相似。我们还观察到,模型在为某些类型的近似重复项分配高相似性分数方面表现相当差。我们反复注意到,通过不同重采样算法(最近邻插值与双线性插值)预处理的具有高频纹理的图像(如毛皮或条纹图案)可能具有出乎意料的低相似性。这导致了许多假阴性。
We built our own near-duplicate detector to fix this issue. We created a synthetic data augmentation pipeline that combined a variety of common image manipulations. The augmentation pipeline combines random cropping and zooming, aspect ratio distortion, downsizing and upscaling to different resolutions, minor rotations, jpeg compression, and HSV color jitter. The pipeline also randomly selects from different interpolation algorithms for all relevant steps. We then trained a model to maximize the similarity of an image and its transformed variant while minimizing similarity to all other images in a training batch. We used the same n-pair / InfoNCE loss as CLIP but with a fixed temperature of 0.07.
我们构建了自己的近重复检测器来解决这个问题。我们创建了一个合成数据增强管道,结合了各种常见的图像处理操作。该增强管道结合了随机裁剪和缩放、宽高比失真、降采样和升采样至不同分辨率、轻微旋转、JPEG 压缩以及 HSV 颜色抖动。管道还会随机选择不同的插值算法来处理所有相关步骤。然后,我们训练了一个模型,以最大化图像及其变换版本的相似性,同时最小化与训练批次中所有其他图像的相似性。我们使用了与 CLIP 相同的 n-pair / InfoNCE 损失,但温度固定为 0.07。
We selected a ResNet-50 as the model architecture. We modified the base ResNet-50 with the anti-alias improvements from (Zhang 2019) and used weight norm (Salimans & Kingma 2016) instead of batch norm (Ioffe & Szegedy 2015) to avoid leaking information about duplicates via batch statistics - a problem previously noted in (Henaff 2020). We also found the GELU activation function (Hendrycks & Gimpel 2016) to perform better for this task. We trained the model with a total batch size of 1,712 for approximately 30 million images sampled from our pre-training dataset. At the end of training it achieves nearly 100% accuracy on its proxy training task.
我们选择了ResNet-50作为模型架构。我们在基础的ResNet-50上进行了修改,采用了(Zhang 2019)的抗混叠改进,并使用权重归一化(Salimans & Kingma 2016)代替批量归一化(Ioffe & Szegedy 2015),以避免通过批量统计泄露重复样本信息——这一问题在(Henaff 2020)中已被指出。我们还发现GELU激活函数(Hendrycks & Gimpel 2016)在该任务中表现更佳。我们使用总批量大小为1,712训练模型,训练样本大约为从预训练数据集中采样的3,000万张图像。训练结束时,模型在其代理训练任务上的准确率几乎达到100%。
Appendix D Dataset Ablation on YFCC100M
附录 D YFCC100M 数据集消融
| Linear Classifier | Zero Shot | |||||
|---|---|---|---|---|---|---|
| Dataset | YFCC | WIT | YFCC | WIT | ||
| Birdsnap | 47.4 | 35.3 | 12.1 | 19.9 | 4.5 | 15.4 |
| Country211 | 23.1 | 17.3 | 5.8 | 5.2 | 5.3 | 0.1 |
| Flowers102 | 94.4 | 89.8 | 4.6 | 48.6 | 21.7 | 26.9 |
| GTSRB | 66.8 | 72.5 | 5.7 | 6.9 | 7.0 | 0.1 |
| UCF101 | 69.2 | 74.9 | 5.7 | 22.9 | 32.0 | 9.1 |
| Stanford Cars | 31.4 | 50.3 | 18.9 | 3.8 | 10.9 | 7.1 |
| ImageNet | 62.0 | 60.8 | 31.3 | 27.6 | 3.7 | |
| Dataset Average | 65.5 | 66.6 | 1.1 | 29.6 | 30.0 | 0.4 |
| Dataset “Wins” | 10 | 15 | 5 | 19 | 18 | 1 |
Table 12: CLIP performs similarly when trained on only YFCC100M. Comparing a ResNet-50 trained on only YFCC100M with a same sized subset of WIT shows similar average performance and number of wins on zero shot and linear classifier evals. However, large differences in dataset specific performance occur. We include performance on the 3 datasets where YFCC does best and worst compared to WIT according to a linear probe in order to highlight this as well as aggregate performance across all linear and zero-shot evals and the canonical ImageNet dataset.
| Linear Classifier | Zero Shot | |||||
|---|---|---|---|---|---|---|
| 数据集 | YFCC | WIT | YFCC | WIT | ||
| Birdsnap | 47.4 | 35.3 | 12.1 | 19.9 | 4.5 | 15.4 |
| Country211 | 23.1 | 17.3 | 5.8 | 5.2 | 5.3 | 0.1 |
| Flowers102 | 94.4 | 89.8 | 4.6 | 48.6 | 21.7 | 26.9 |
| GTSRB | 66.8 | 72.5 | 5.7 | 6.9 | 7.0 | 0.1 |
| UCF101 | 69.2 | 74.9 | 5.7 | 22.9 | 32.0 | 9.1 |
| Stanford Cars | 31.4 | 50.3 | 18.9 | 3.8 | 10.9 | 7.1 |
| ImageNet | 62.0 | 60.8 | 31.3 | 27.6 | 3.7 | |
| 数据集平均 | 65.5 | 66.6 | 1.1 | 29.6 | 30.0 | 0.4 |
| 数据集“获胜”数 | 10 | 15 | 5 | 19 | 18 | 1 |
表 12:仅在 YFCC100M 上训练时,CLIP 表现相近。 比较仅在 YFCC100M 上训练的 ResNet-50 与同等规模 WIT 子集上训练的同型模型,在零样本与线性分类器评测上平均性能与“获胜”次数相近。但特定数据集上的性能差异可能很大。我们纳入按线性探测相对 WIT 表现最好与最差的各 3 个数据集以突出这一点,并给出全部线性与零样本评测以及经典 ImageNet 上的汇总性能。
To study whether our custom dataset is critical to the performance of CLIP, we trained a model on a filtered subset of the YFCC100M dataset (details described in Section 2.2) and compared its performance to the same model trained on an equally sized subset of WIT. We train each model for 32 epochs at which point transfer performance begins to plateau due to overfitting. Results are shown in Table 12. Across our whole eval suite, YFCC and WIT perform similarly on average for both zero-shot and linear probe settings. However, performance on specific fine-grained classification datasets can vary widely - sometimes by over 10%. Our speculation is that these differences in performance reflect the relative density of relevant data in each pre-training dataset. For instance, pre-training on YFCC100M, which might contain many photos of birds and flowers (common subjects for photographers), results in better performance on Birdsnap and Flowers102, while pre-training on WIT results in better car and pet classifiers (which appear common in our dataset).
为研究我们的定制数据集对 CLIP 性能是否关键,我们在 YFCC100M 的过滤子集上训练模型(细节见第 2.2 节),并与在同等规模 WIT 子集上训练的同一模型比较。各训练 32 个 epoch,此时因过拟合迁移性能开始平台。结果见表 12。在整个评测套件上,YFCC 与 WIT 在零样本与线性探测设定下平均表现相近。但在特定细粒度分类数据集上,性能可相差很大——有时超过 10%。我们推测这些差异反映了各预训练数据中相关数据的相对密度。例如,在可能包含许多鸟类与花卉照片(摄影常见题材)的 YFCC100M 上预训练,在 Birdsnap 与 Flowers102 上更好;而在 WIT 上预训练则得到更好的汽车与宠物分类器(在我们数据中似乎更常见)。
Overall, these results are encouraging as they suggest our approach can use any reasonably filtered collection of paired (text, image) data. This mirrors recent work which reported positive results using the same contrastive pre-training objective on the relatively different domain of medical imaging (Zhang et al. 2020). It also is similar to the findings of noisy student self-training which reported only slight improvements when using their JFT300M dataset over YFCC100M (Xie et al. 2020). We suspect the major advantage of our dataset over the already existing YFCC100M is its much larger size.
总体而言,这些结果令人鼓舞,因为它们表明我们的方法可以使用任何经过合理筛选的成对(文本,图像)数据集合。这与最近的研究相呼应,后者在相对不同的医学影像领域使用相同的对比预训练目标报道了积极的结果(Zhang 等,2020)。这也类似于噪声学生自训练的发现,后者报告在使用他们的 JFT300M 数据集而不是 YFCC100M 时仅有轻微的改进(Xie 等,2020)。我们怀疑我们的数据集相比已有的 YFCC100M 的主要优势在于其规模更大。
Finally, we caution that WIT includes this filtered subset of YFCC100M. This could result in our ablation underestimating the size of performance differences between YFCC100M and the rest of WIT. We do not think this is likely as YFCC100M is only 3.7% of the overall WIT data blend and it did not noticeably change the performance of models when it was added to the existing data blend during the creation of WIT.
最后,我们提醒注意,WIT 包含了 YFCC100M 的这个经过过滤的子集。这可能导致我们的消融实验低估 YFCC100M 与 WIT 其余部分之间性能差异的大小。我们认为这种可能性不大,因为 YFCC100M 仅占 WIT 总数据混合的 3.7%,并且在 WIT 创建过程中将其添加到现有数据混合中时,并未明显改变模型的性能。
| Text Retrieval | Image Retrieval | ||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Flickr30k | MSCOCO | Flickr30k | MSCOCO | ||||||||||
| R@1 | R@5 | R@10 | R@1 | R@5 | R@10 | R@1 | R@5 | R@10 | R@1 | R@5 | R@10 | ||
| Finetune | Unicoder-VLa | 86.2 | 96.3 | 99.0 | 62.3 | 87.1 | 92.8 | 71.5 | 90.9 | 94.9 | 46.7 | 76.0 | 85.3 |
| Uniterb | 87.3 | 98.0 | 99.2 | 65.7 | 88.6 | 93.8 | 75.6 | 94.1 | 96.8 | 52.9 | 79.9 | 88.0 | |
| VILLAc | 87.9 | 97.5 | 98.8 | - | - | - | 76.3 | 94.2 | 96.8 | - | - | - | |
| Oscard | - | - | - | 73.5 | 92.2 | 96.0 | - | - | - | 57.5 | 82.8 | 89.8 | |
| ERNIE-ViLe | 88.7 | 98.0 | 99.2 | - | - | - | 76.7 | 93.6 | 96.4 | - | - | - | |
| Zero-Shot | Visual N-Gramsf | 15.4 | 35.7 | 45.1 | 8.7 | 23.1 | 33.3 | 8.8 | 21.2 | 29.9 | 5.0 | 14.5 | 21.9 |
| ImageBERTg | - | - | - | 44.0 | 71.2 | 80.4 | - | - | - | 32.3 | 59.0 | 70.2 | |
| Unicoder-VLa | 64.3 | 86.8 | 92.3 | - | - | - | 48.4 | 76.0 | 85.2 | - | - | - | |
| Uniterb | 83.6 | 95.7 | 97.7 | - | - | - | 68.7 | 89.2 | 93.9 | - | - | - | |
| CLIP | 88.0 | 98.7 | 99.4 | 58.4 | 81.5 | 88.1 | 68.7 | 90.6 | 95.2 | 37.8 | 62.4 | 72.2 |
Table 13: CLIP improves zero-shot retrieval and is competitive with the best fine-tuned result on Flickr30k text retrieval. Bold indicates best overall performance while an underline indicates best in category performance (zero-shot or fine-tuned). For all other models, best results from the paper are reported regardless of model size / variant. MSCOCO performance is reported on the 5k test set. a(Li et al. 2020a) b(Chen et al. 2019) c(Gan et al. 2020) d(Li et al. 2020b) e(Yu et al. 2020) f(Li et al. 2017) g(Qi et al. 2020)
| 文本检索 | 图像检索 | ||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Flickr30k | MSCOCO | Flickr30k | MSCOCO | ||||||||||
| R@1 | R@5 | R@10 | R@1 | R@5 | R@10 | R@1 | R@5 | R@10 | R@1 | R@5 | R@10 | ||
| Finetune | Unicoder-VLa | 86.2 | 96.3 | 99.0 | 62.3 | 87.1 | 92.8 | 71.5 | 90.9 | 94.9 | 46.7 | 76.0 | 85.3 |
| Uniterb | 87.3 | 98.0 | 99.2 | 65.7 | 88.6 | 93.8 | 75.6 | 94.1 | 96.8 | 52.9 | 79.9 | 88.0 | |
| VILLAc | 87.9 | 97.5 | 98.8 | - | - | - | 76.3 | 94.2 | 96.8 | - | - | - | |
| Oscard | - | - | - | 73.5 | 92.2 | 96.0 | - | - | - | 57.5 | 82.8 | 89.8 | |
| ERNIE-ViLe | 88.7 | 98.0 | 99.2 | - | - | - | 76.7 | 93.6 | 96.4 | - | - | - | |
| Zero-Shot | Visual N-Gramsf | 15.4 | 35.7 | 45.1 | 8.7 | 23.1 | 33.3 | 8.8 | 21.2 | 29.9 | 5.0 | 14.5 | 21.9 |
| ImageBERTg | - | - | - | 44.0 | 71.2 | 80.4 | - | - | - | 32.3 | 59.0 | 70.2 | |
| Unicoder-VLa | 64.3 | 86.8 | 92.3 | - | - | - | 48.4 | 76.0 | 85.2 | - | - | - | |
| Uniterb | 83.6 | 95.7 | 97.7 | - | - | - | 68.7 | 89.2 | 93.9 | - | - | - | |
| CLIP | 88.0 | 98.7 | 99.4 | 58.4 | 81.5 | 88.1 | 68.7 | 90.6 | 95.2 | 37.8 | 62.4 | 72.2 |
表 13:CLIP 改善零样本检索,并在 Flickr30k 文本检索上与最好的微调结果竞争。 粗体表示总体最佳,下划线表示类别内(零样本或微调)最佳。对其余模型,报告论文中的最好结果,不论模型规模/变体。MSCOCO 性能在 5k 测试集上报告。a(Li 等 2020a) b(Chen 等 2019) c(Gan 等 2020) d(Li 等 2020b) e(Yu 等 2020) f(Li 等 2017) g(Qi 等 2020)
Appendix E Selected Task and Dataset Results
附录 E 选定任务和数据集结果
Due to the large variety of datasets and experiments considered in this work, the main body focuses on summarizing and analyzing overall results. In the following subsections we report details of performance for specific groups of tasks, datasets, and evaluation settings.
由于本研究考虑了大量不同的数据集和实验,正文主要集中于总结和分析总体结果。在接下来的小节中,我们将报告特定任务组、数据集和评估设置的详细性能情况。
E.1 Image and Text Retrieval
E.1 图像与文本检索
CLIP pre-trains for the task of image-text retrieval on our noisy web-scale dataset. Although the focus of this paper is on representation learning and task learning for the purpose of transfer to a wide variety of downstream datasets, validating that CLIP is able to achieve high transfer performance transfer on exactly what it is pre-trained for is an important sanity check / proof of concept. In Table 13 we check the zero-shot transfer performance of CLIP for both text and image retrieval on the Flickr30k and MSCOCO datsets. Zero-shot CLIP matches or outperforms all prior zero-shot results on these two datasets. Zero-shot CLIP is also competitive with the current overall SOTA for the task of text retrieval on Flickr30k. On image retrieval, CLIP’s performance relative to the overall state of the art is noticeably lower. However, zero-shot CLIP is still competitive with a fine-tuned Unicoder-VL. On the larger MS-COCO dataset fine-tuning improves performance significantly and zero-shot CLIP is not competitive with the most recent work. For both these datasets we prepend the prompt “a photo of” to the description of each image which we found boosts CLIP’s zero-shot R@1 performance between 1 and 2 points.
CLIP 在我们噪声网络规模数据集上为图文检索任务做预训练。尽管本文焦点是表征学习与任务学习,以便迁移到广泛下游数据集,验证 CLIP 能在其恰好预训练的任务上取得高迁移性能,仍是重要的健全性检查/概念验证。表 13 检查 CLIP 在 Flickr30k 与 MSCOCO 上文本与图像检索的零样本迁移性能。零样本 CLIP 在这两个数据集上匹配或超过所有先前零样本结果。零样本 CLIP 在 Flickr30k 文本检索任务上也与当前总体 SOTA 竞争。在图像检索上,CLIP 相对总体最先进水平明显更低。但零样本 CLIP 仍可与微调的 Unicoder-VL 竞争。在更大的 MS-COCO 上,微调显著提升性能,零样本 CLIP 无法与最新工作竞争。对这两个数据集,我们在每张图像描述前加上提示“a photo of”,发现可使 CLIP 的零样本 R@1 提升约 1 到 2 个点。
| IIIT5K | Hateful | |||||
|---|---|---|---|---|---|---|
| MNIST | SVHN | 1k | Memes | SST-2 | ||
| Finetune | SOTA | 99.8a | 96.4b | 98.9c | 78.0d | 97.5e |
| JOINTf | - | - | 89.6 | - | - | |
| CBoWg | - | - | - | - | 80.0 | |
| Linear | Raw Pixels | 92.5 | - | - | - | - |
| ES Best | 98.9h | - | - | 58.6h | 59.0i | |
| CLIP | 99.2 | - | - | 77.3 | 80.5 | |
| ZS | CLIP | 88.4 | 51.0 | 90.0 | 63.3 | 67.9 |
Table 14: OCR performance on 5 datasets. All metrics are accuracy on the test set except for Hateful Memes which reports ROC AUC on the dev set. Single model SOTA reported to best of knowledge. ES Best reports the best performance across the 56 non-CLIP models in our evaluation suite. a(Assiri 2020) b(Jaderberg et al. 2015) c(Wang et al. 2020) d(Lippe et al. 2020) f(Jaderberg et al. 2014) g(Wang et al. 2018) h(Xie et al. 2020) i(Mahajan et al. 2018)
| IIIT5K | Hateful | |||||
|---|---|---|---|---|---|---|
| MNIST | SVHN | 1k | Memes | SST-2 | ||
| 微调 | SOTA | 99.8a | 96.4b | 98.9c | 78.0d | 97.5e |
| JOINTf | - | - | 89.6 | - | - | |
| CBoWg | - | - | - | - | 80.0 | |
| 线性 | 原始像素 | 92.5 | - | - | - | - |
| ES最佳 | 98.9h | - | - | 58.6h | 59.0i | |
| CLIP | 99.2 | - | - | 77.3 | 80.5 | |
| 零样本 | CLIP | 88.4 | 51.0 | 90.0 | 63.3 | 67.9 |
表14:五个数据集上的OCR性能。除Hateful Memes数据集报告在开发集上的ROC AUC外,所有指标均为测试集的准确率。单模型SOTA为目前已知的最佳结果。ES最佳报告了在我们评估套件中的56个非CLIP模型中的最佳性能。a(Assiri 2020) b(Jaderberg 等, 2015) c(Wang 等, 2020) d(Lippe 等, 2020) f(Jaderberg 等, 2014) g(Wang 等, 2018) h(Xie 等, 2020) i(Mahajan 等, 2018)
E.2 Optical Character Recognition
E.2 光学字符识别
Although visualizations have shown that ImageNet models contain features that respond to the presence of text in an image (Zeiler & Fergus 2014), these representations are not sufficiently fine-grained to use for the task of optical character recognition (OCR). To compensate, models are augmented with the outputs of custom OCR engines and features to boost performance on tasks where this capability is required (Singh et al. 2019; Yang et al. 2020). Early during the development of CLIP, we noticed that CLIP began to learn primitive OCR capabilities which appeared to steadily improve over the course of the project. To evaluate this qualitatively noticed behavior, we measured performance on 5 datasets requiring the direct and indirect use of OCR. Three of these datasets MNIST [104], SVHN (Netzer et al. 2011), and IIIT5K (Mishra et al. 2012) directly check the ability of a model to perform low-level character and word recognition, while Hateful Memes (Kiela et al. 2020) and SST-2 (Socher et al. 2013) check the ability of a model to use OCR to perform a semantic task. Results are reported in Table 14.
尽管可视化显示 ImageNet 模型包含对图像中文本存在响应的特征(Zeiler & Fergus 2014),这些表征的粒度不足以用于光学字符识别(OCR)任务。为补偿,模型会辅以定制 OCR 引擎的输出与特征,以提升需要该能力的任务性能(Singh 等 2019;Yang 等 2020)。在 CLIP 开发早期,我们注意到它开始学到初级 OCR 能力,并在项目过程中似乎稳步提升。为定性评估这一观察到的行为,我们在 5 个需要直接或间接使用 OCR 的数据集上测性能。其中三个——MNIST [104]、SVHN(Netzer 等 2011)与 IIIT5K(Mishra 等 2012)——直接检查模型做底层字符与词识别的能力;而 Hateful Memes(Kiela 等 2020)与 SST-2(Socher 等 2013)检查模型利用 OCR 完成语义任务的能力。结果见表 14。
CLIP’s performance is still highly variable and appears to be sensitive to some combination of the domain (rendered or natural images) and the type of text to be recognized (numbers or words). CLIP’s OCR performance is strongest Hateful Memes and SST-2 - datasets where the text is digitally rendered and consists mostly of words. On IIIT5K, which is natural images of individually cropped words, zero-shot CLIP performs a bit more respectively and its performance is similar to Jaderberg et al. 2014 early work combining deep learning and structured prediction to perform open-vocabulary OCR. However, performance is noticeably lower on two datasets involving recognition of hand written and street view numbers. CLIP’s 51% accuracy on full number SVHN is well below any published results. Inspection suggests CLIP struggles with repeated characters as well as the low resolution and blurry images of SVHN. CLIP’s zero-shot MNIST performance is also poor and is outperformed by supervised logistic regression on raw pixels, one of the simplest possible machine learning baselines.
CLIP 的性能仍高度波动,似乎对领域(渲染或自然图像)与待识别文本类型(数字或单词)的某种组合敏感。CLIP 的 OCR 在 Hateful Memes 与 SST-2 上最强——这些数据集中文本为数字渲染且多为单词。在由单独裁剪单词的自然图像组成的 IIIT5K 上,零样本 CLIP 表现稍好,性能接近 Jaderberg 等 2014 早期结合深度学习与结构化预测做开放词表 OCR 的工作。但在涉及手写与街景数字识别的两个数据集上,性能明显更低。CLIP 在完整数字 SVHN 上仅 51% 精度,远低于任何已发表结果。检查表明 CLIP 在重复字符以及 SVHN 的低分辨率与模糊图像上吃力。CLIP 的零样本 MNIST 性能也很差,甚至不如在原始像素上做监督逻辑回归这一最简单的机器学习基线。
SST-2 is a sentence level NLP dataset which we render into images. We include SST-2 in order to check whether CLIP is able to convert low level OCR capability into a higher level representation. Fitting a linear classifier on CLIP’s representation of rendered sentences achives 80.5% accuracy. This is on par with the 80% accuracy of a continuous bag of words baseline using GloVe word vectors pre-trained on 840 billion tokens (Pennington et al. 2014). While this is a simple NLP baseline by today’s standard, and well below the 97.5% of the current SOTA, it is encouraging to see that CLIP is able to turn an image of rendered text into a non-trivial sentence level representation. Fully supervised CLIP is also surprisingly strong on Hateful Meme detection, where CLIP is only 0.7 points behind the current single model SOTA and several points above the best baseline from the original paper. Similar to SST-2, these other results on Hateful Memes use the ground truth text which CLIP does not have access to. Finally, we note that zero-shot CLIP outperforms the best results using fully supervised linear probes across all other 56 models included in our evaluation suite. This suggests CLIP’s OCR capability is at least somewhat unique compared to existing work on self-supervised and supervised representation learning.
SST-2 是句子级 NLP 数据集,我们将其渲染为图像。纳入 SST-2 是为检查 CLIP 能否把底层 OCR 能力转化为更高层表征。在 CLIP 对渲染句子的表征上拟合线性分类器可达 80.5% 精度,与在 8400 亿 token 上预训练的 GloVe 词向量连续词袋基线的 80% 精度相当(Pennington 等 2014)。虽以今日标准看这是简单 NLP 基线,且远低于当前 SOTA 的 97.5%,但看到 CLIP 能把渲染文本图像转化为非平凡的句子级表征仍令人鼓舞。全监督 CLIP 在仇恨梗图检测上也出人意料地强,仅落后当前单模型 SOTA 0.7 个点,并高出原论文最好基线若干点。与 SST-2 类似,仇恨梗图上的其他结果使用了 CLIP 无法获得的真实文本。最后我们指出:在评测套件所含其余全部 56 个模型上,零样本 CLIP 超过使用全监督线性探测的最好结果。这表明相对现有自监督与监督表征学习工作,CLIP 的 OCR 能力至少有一定独特性。
| UCF101 | K700 | RareAct | |||
|---|---|---|---|---|---|
| Top-1 | AVG | mWAP | mWSAP | ||
| Finetune | R(2+1)D-BERTa | 98.7 | - | - | - |
| NS ENet-L2b | - | 84.8 | - | - | |
| HT100M S3Dd | 91.3 | - | - | - | |
| Baseline I3De | - | 70.2 | - | - | |
| Linear | MMV FACf | 91.8 | - | - | - |
| NS ENet-L2c | 89.4c | 68.2c | - | - | |
| CLIP | 92.0 | 73.0 | - | - | |
| ZS | HT100M S3Dd | - | - | 30.5 | 34.8 |
| CLIP | 80.3 | 69.6 | 40.7 | 44.8 |
Table 15: Action recognition performance on 3 video datasets. Single model SOTA reported to best of knowledge. Note that linear CLIP and linear NS ENet-L2 are trained and evaluated on a single frame subsampled version of each dataset and not directly comparable to prior work. On Kinetics-700, we report the ActivityNet competition metric which is the average of top-1 and top-5 performance. a(Kalfaoglu et al. 2020) b(Lu et al. 2020) c(Xie et al. 2020) d(Miech et al. 2020b) e(Carreira et al. 2019) f(Alayrac et al. 2020)
| UCF101 | K700 | RareAct | |||
|---|---|---|---|---|---|
| Top-1 | AVG | mWAP | mWSAP | ||
| Finetune | R(2+1)D-BERTa | 98.7 | - | - | - |
| NS ENet-L2b | - | 84.8 | - | - | |
| HT100M S3Dd | 91.3 | - | - | - | |
| Baseline I3De | - | 70.2 | - | - | |
| Linear | MMV FACf | 91.8 | - | - | - |
| NS ENet-L2c | 89.4c | 68.2c | - | - | |
| CLIP | 92.0 | 73.0 | - | - | |
| ZS | HT100M S3Dd | - | - | 30.5 | 34.8 |
| CLIP | 80.3 | 69.6 | 40.7 | 44.8 |
表 15:3 个视频数据集上的动作识别性能。据我们所知报告单模型 SOTA。注意 linear CLIP 与 linear NS ENet-L2 在各数据集的单帧下采样版本上训练与评估,不可与先前工作直接比较。在 Kinetics-700 上,我们报告 ActivityNet 竞赛指标,即 top-1 与 top-5 的平均。a(Kalfaoglu 等 2020) b(Lu 等 2020) c(Xie 等 2020) d(Miech 等 2020b) e(Carreira 等 2019) f(Alayrac 等 2020)
E.3 Action Recognition in Videos
E.3 视频中的动作识别
For the purpose of learning, a potentially important aspect of natural language is its ability to express, and therefore supervise, an extremely wide set of concepts. A CLIP model, since it is trained to pair semi-arbitrary text with images, is likely to receive supervision for a wide range of visual concepts involving both common and proper nouns, verbs, and adjectives. ImageNet-1K, by contrast, only labels common nouns. Does the lack of broader supervision in ImageNet result in weaker transfer of ImageNet models to tasks involving the recognition of visual concepts that are not nouns?
为了学习,自然语言的一个潜在重要方面是它表达的能力,从而可以监督极其广泛的概念。由于 CLIP 模型训练目的是将半任意文本与图像配对,它很可能获得对广泛视觉概念的监督,这些概念涉及常见名词、专有名词、动词和形容词。相比之下,ImageNet-1K 仅标注常见名词。那么,ImageNet 缺乏更广泛的监督是否导致其模型在涉及非名词视觉概念识别的任务上迁移能力较弱?
To investigate this, we measure and compare the performance of CLIP and ImageNet models on several video action classification datasets which measure the ability of a model to recognize verbs. In Table 15 we report results on UCF-101 (Soomro et al. 2012) and Kinetics-700 (Carreira et al. 2019), two common datasets for the task. Unfortunately, our CPU based linear classifier takes a prohibitively long time to evaluate on a video dataset due to the very large number of training frames. To deal with this, we aggressively sub-sample each video to only a single center frame, effectively turning it into an image classification dataset. As a result, our reported performance in a linear evaluation setting likely under estimates performance by a moderate amount.
为此,我们测量并比较了 CLIP 和 ImageNet 模型在多个视频动作分类数据集上的性能,这些数据集用于衡量模型识别动词的能力。在表 15 中,我们报告了 UCF-101(Soomro 等,2012)和 Kinetics-700(Carreira 等,2019)上的结果,这两个数据集在该任务中较为常用。不幸的是,由于训练帧数量非常庞大,我们基于 CPU 的线性分类器在视频数据集上评估所需时间过长。为了解决这个问题,我们将每个视频大幅下采样,仅使用单个中心帧,这实际上将其转化为图像分类数据集。因此,我们在线性评估设置中报告的性能很可能被适度低估。
| IN | IN-V2 | IN-A | IN-R | ObjectNet | IN-Sketch | IN-Vid | YTBB | |||
|---|---|---|---|---|---|---|---|---|---|---|
| Top-1 | Top-1 | Top-1 | Top-1 | Top-1 | Top-1 | PM0 | PM10 | PM0 | PM10 | |
| NS EfficientNet-L2a | 88.3 | 80.2 | 84.9 | 74.7 | 68.5 | 47.6 | 88.0 | 82.1 | 67.7 | 63.5 |
| FixResNeXt101-32x48d V2b | 86.4 | 78.0 | 68.4 | 80.0 | 57.8 | 59.1 | 85.8 | 72.2 | 68.9 | 57.7 |
| Linear Probe CLIP | 85.4 | 75.9 | 75.3 | 84.2 | 66.2 | 57.4 | 89.1 | 77.2 | 68.7 | 63.1 |
| Zero-Shot CLIP | 76.2 | 70.1 | 77.2 | 88.9 | 72.3 | 60.2 | 95.3 | 89.2 | 95.2 | 88.5 |
Table 16: Detailed ImageNet robustness performance. IN is used to abbreviate for ImageNet. a(Xie et al. 2020) b(Touvron et al. 2019)
| IN | IN-V2 | IN-A | IN-R | ObjectNet | IN-Sketch | IN-Vid | YTBB | |||
|---|---|---|---|---|---|---|---|---|---|---|
| Top-1 | Top-1 | Top-1 | Top-1 | Top-1 | Top-1 | PM0 | PM10 | PM0 | PM10 | |
| NS EfficientNet-L2a | 88.3 | 80.2 | 84.9 | 74.7 | 68.5 | 47.6 | 88.0 | 82.1 | 67.7 | 63.5 |
| FixResNeXt101-32x48d V2b | 86.4 | 78.0 | 68.4 | 80.0 | 57.8 | 59.1 | 85.8 | 72.2 | 68.9 | 57.7 |
| Linear Probe CLIP | 85.4 | 75.9 | 75.3 | 84.2 | 66.2 | 57.4 | 89.1 | 77.2 | 68.7 | 63.1 |
| Zero-Shot CLIP | 76.2 | 70.1 | 77.2 | 88.9 | 72.3 | 60.2 | 95.3 | 89.2 | 95.2 | 88.5 |
表16:ImageNet鲁棒性性能的详细情况。IN 用于 ImageNet 的缩写。a(Xie 等, 2020) b(Touvron 等, 2019)
Despite this handicap, CLIP features transfer surprisingly well to this task. CLIP matches the best prior result on UCF-101 in a linear probe evaluation setting and also outperforms all other models in our evaluation suite. On Kinetics-700, CLIP also outperforms the fine-tuned I3D baseline from the original paper. Since it does not require a training stage, we report CLIP’s zero-shot performance when averaging predictions across all frames. CLIP also performs well in this setting and on Kinetics-700 its performance is within 1% of the fully supervised I3D baseline which is trained on 545000 labeled videos. Encouraged by these results, we also measure CLIP’s performance on the recently introduced RareAct dataset (Miech et al. 2020a) which was designed to measure zero-shot recognition of unusual actions like “hammering a phone” and “drilling an egg”. CLIP improves over the prior state of the art, a S3D model trained on automatically extracted captions from 100 million instructional videos, by 10 points.
尽管有此劣势,CLIP 特征向该任务的迁移出人意料地好。在线性探测评测设定下,CLIP 匹配 UCF-101 上先前最好结果,并超过我们评测套件中的所有其他模型。在 Kinetics-700 上,CLIP 也超过原论文中微调的 I3D 基线。由于无需训练阶段,我们报告在所有帧上平均预测时的零样本性能。CLIP 在该设定下也表现良好,在 Kinetics-700 上其性能与在 545000 个标注视频上训练的全监督 I3D 基线相差不到 1%。受这些结果鼓舞,我们还在近期引入的 RareAct 数据集(Miech 等 2020a)上测 CLIP,该数据集旨在衡量对“锤手机”“钻鸡蛋”等异常动作的零样本识别。CLIP 相对先前最先进——在 1 亿教学视频自动抽取字幕上训练的 S3D 模型——提升 10 个点。
While CLIP has encouragingly strong performance on the task of action recognition, we note that there are many differences between the models being compared beyond just their form of supervision such as model architecture, training data distribution, dataset size, and compute used. Further work is needed to more precisely determine what specific design decisions contribute to achieving high performance on this task.
虽然 CLIP 在动作识别任务上表现出令人鼓舞的强大性能,但我们注意到,被比较的模型之间除了监督形式之外,还有许多差异,例如模型架构、训练数据分布、数据集规模以及使用的计算资源。需要进一步的工作来更准确地确定哪些具体的设计决策有助于在该任务上实现高性能。
| 1km | 25km | 200km | 750km | 2500km | |
|---|---|---|---|---|---|
| ISNsa | 16.9 | 43.0 | 51.9 | 66.7 | 80.2 |
| CPlaNetb | 16.5 | 37.1 | 46.4 | 62.0 | 78.5 |
| CLIP | 13.9 | 32.9 | 43.0 | 62.0 | 79.3 |
| Deep-Ret+c | 14.4 | 33.3 | 47.7 | 61.6 | 73.4 |
| PlaNetd | 8.4 | 24.5 | 37.6 | 53.6 | 71.3 |
Table 17: Geolocalization performance on the IM2GPS test set. Metric is percent of images localized within a given radius. Models are ordered by average performance. a(Muller-Budack et al. 2018) b(Hongsuck Seo et al. 2018) c(Vo et al. 2017) c(Weyand et al. 2016)
| 1公里 | 25公里 | 200公里 | 750公里 | 2500公里 | |
|---|---|---|---|---|---|
| ISNsa | 16.9 | 43.0 | 51.9 | 66.7 | 80.2 |
| CPlaNetb | 16.5 | 37.1 | 46.4 | 62.0 | 78.5 |
| CLIP | 13.9 | 32.9 | 43.0 | 62.0 | 79.3 |
| Deep-Ret+c | 14.4 | 33.3 | 47.7 | 61.6 | 73.4 |
| PlaNetd | 8.4 | 24.5 | 37.6 | 53.6 | 71.3 |
表17:IM2GPS测试集上的地理定位性能。度量标准为在给定半径内定位的图像百分比。模型按平均性能排序。a(Muller-Budack 等,2018) b(Hongsuck Seo 等,2018) c(Vo 等,2017) d(Weyand 等,2016)
E.4 Geolocalization
E.4 地理定位
Another behavior we noticed during the development of CLIP was its ability to recognize many places and locations. To quantify this we created the Country211 dataset as described in Appendix A and report results on it throughout the paper. However it is a new benchmark so to compare with prior work on geolocalization we also report results on the IM2GPS test set from Hays & Efros 2008 in Table 17. Since IM2GPS is a regression benchmark, we guess the GPS coordinates of the nearest image in a set of reference images using CLIP’s embedding space. This is not a zero-shot result since it uses nearest-neighbor regression. Despite querying only 1 million images, which is much less than prior work, CLIP performs similarly to several task specific models. It is not, however, competitive with the current state of the art.
我们在开发 CLIP 的过程中注意到的另一个行为是它能够识别许多地方和位置。为了量化这一点,我们创建了如附录 A 所述的 Country211 数据集,并在整篇论文中报告了其结果。然而,这是一个新的基准,为了与以前关于地理定位的工作进行比较,我们还在表 17 中报告了 Hays & Efros 2008 的 IM2GPS 测试集结果。由于 IM2GPS 是一个回归基准,我们使用 CLIP 的嵌入空间来猜测参考图像集中最近图像的 GPS 坐标。这不是零样本结果,因为它使用最近邻回归。尽管仅查询了 100 万张图像,这远低于以往工作,但 CLIP 的表现与几个特定任务模型类似。然而,它与当前最先进的技术相比,并不具有竞争力。
E.5 Robustness to Distribution Shift
E.5 对分布偏移的鲁棒性
Section 3.3 provides a high level summary and analysis of ImageNet-related robustness results. We briefly provide some additional numerical details in this appendix. Performance results per dataset are provided in Table 16 and compared with the current state of the art results reported in Taori et al. 2020’s evaluation suite. Zero-shot CLIP improves the state of the art on 5 of the 7 datasets, ImageNet-R, ObjectNet, ImageNet-Sketch, ImageNet-Vid, and Youtube-BB. CLIP’s improvements are largest on ImageNet-Vid and Youtube-BB due to its flexible zero-shot capability and on ImageNet-R, which likely reflects CLIP’s pre-training distribution including significant amounts of creative content. A similar behavior has been documented for the Instagram pre-trained ResNeXt models as discussed in Taori et al. 2020.
第3.3节提供了与ImageNet相关的鲁棒性结果的高层次总结和分析。我们在本附录中简要提供了一些额外的数值细节。各数据集的性能结果列于表16中,并与Taori等人2020年评估套件报告的当前最先进结果进行了比较。零样本CLIP在7个数据集中的5个数据集(ImageNet-R、ObjectNet、ImageNet-Sketch、ImageNet-Vid和Youtube-BB)上提升了最先进水平。CLIP在ImageNet-Vid和Youtube-BB上的改进最大,这是由于其灵活的零样本能力,以及在ImageNet-R上的改进,这可能反映了CLIP的预训练分布包含了大量创意内容。Taori等人2020年讨论的Instagram预训练ResNeXt模型也记录了类似的行为。
Appendix F Model Hyperparameters
附录 F 模型超参数
| Hyperparameter | Value |
|---|---|
| Batch size | 32768 |
| Vocabulary size | 49408 |
| Training epochs | 32 |
| Maximum temperature | 100.0 |
| Weight decay | 0.2 |
| Warm-up iterations | 2000 |
| Adam | 0.9 |
| Adam | 0.999 (ResNet), 0.98 (ViT) |
| Adam | (ResNet), (ViT) |
| Learning | Embedding | Input | ResNet | Text Transformer | ||||
|---|---|---|---|---|---|---|---|---|
| Model | rate | dimension | resolution | blocks | width | layers | width | heads |
| RN50 | 1024 | 224 | (3, 4, 6, 3) | 2048 | 12 | 512 | 8 | |
| RN101 | 512 | 224 | (3, 4, 23, 3) | 2048 | 12 | 512 | 8 | |
| RN50x4 | 640 | 288 | (4, 6, 10, 6) | 2560 | 12 | 640 | 10 | |
| RN50x16 | 768 | 384 | (6, 8, 18, 8) | 3072 | 12 | 768 | 12 | |
| RN50x64 | 1024 | 448 | (3, 15, 36, 10) | 4096 | 12 | 1024 | 16 |
| Learning | Embedding | Input | Vision Transformer | Text Transformer | |||||
|---|---|---|---|---|---|---|---|---|---|
| Model | rate | dimension | resolution | layers | width | heads | layers | width | heads |
| ViT-B/32 | 512 | 224 | 12 | 768 | 12 | 12 | 512 | 8 | |
| ViT-B/16 | 512 | 224 | 12 | 768 | 12 | 12 | 512 | 8 | |
| ViT-L/14 | 768 | 224 | 24 | 1024 | 16 | 12 | 768 | 12 | |
| ViT-L/14-336px | 768 | 336 | 24 | 1024 | 16 | 12 | 768 | 12 |
Table 18: Common CLIP hyperparameters
| 超参数 | 取值 |
|---|---|
| 批大小 | 32768 |
| 词表大小 | 49408 |
| 训练轮数 | 32 |
| 最大温度 | 100.0 |
| 权重衰减 | 0.2 |
| 预热迭代 | 2000 |
| Adam | 0.9 |
| Adam | 0.999 (ResNet), 0.98 (ViT) |
| Adam | (ResNet), (ViT) |
| 学习率 | 嵌入 | 输入 | ResNet | Text Transformer | ||||
|---|---|---|---|---|---|---|---|---|
| Model | rate | 维度 | 分辨率 | 块 | 宽度 | 层数 | 宽度 | 头数 |
| RN50 | 1024 | 224 | (3, 4, 6, 3) | 2048 | 12 | 512 | 8 | |
| RN101 | 512 | 224 | (3, 4, 23, 3) | 2048 | 12 | 512 | 8 | |
| RN50x4 | 640 | 288 | (4, 6, 10, 6) | 2560 | 12 | 640 | 10 | |
| RN50x16 | 768 | 384 | (6, 8, 18, 8) | 3072 | 12 | 768 | 12 | |
| RN50x64 | 1024 | 448 | (3, 15, 36, 10) | 4096 | 12 | 1024 | 16 |
| 学习率 | 嵌入 | 输入 | Vision Transformer | Text Transformer | |||||
|---|---|---|---|---|---|---|---|---|---|
| Model | rate | 维度 | 分辨率 | 层数 | 宽度 | 头数 | 层数 | 宽度 | 头数 |
| ViT-B/32 | 512 | 224 | 12 | 768 | 12 | 12 | 512 | 8 | |
| ViT-B/16 | 512 | 224 | 12 | 768 | 12 | 12 | 512 | 8 | |
| ViT-L/14 | 768 | 224 | 24 | 1024 | 16 | 12 | 768 | 12 | |
| ViT-L/14-336px | 768 | 336 | 24 | 1024 | 16 | 12 | 768 | 12 |
表 18:CLIP 常用超参数