A Distributional Perspective on Reinforcement Learning
A Distributional Perspective on Reinforcement Learning
强化学习的分布视角
Marc G. Bellemare Affiliation: DeepMind, London, UK Correspondence to: bellemare@google.com Will Dabney Affiliation: DeepMind, London, UK Rémi Munos Affiliation: DeepMind, London, UK
Abstract
摘要
In this paper we argue for the fundamental importance of the value distribution: the distribution of the random return received by a reinforcement learning agent. This is in contrast to the common approach to reinforcement learning which models the expectation of this return, or value. Although there is an established body of literature studying the value distribution, thus far it has always been used for a specific purpose such as implementing risk-aware behaviour. We begin with theoretical results in both the policy evaluation and control settings, exposing a significant distributional instability in the latter. We then use the distributional perspective to design a new algorithm which applies Bellman’s equation to the learning of approximate value distributions. We evaluate our algorithm using the suite of games from the Arcade Learning Environment. We obtain both state-of-the-art results and anecdotal evidence demonstrating the importance of the value distribution in approximate reinforcement learning. Finally, we combine theoretical and empirical evidence to highlight the ways in which the value distribution impacts learning in the approximate setting.
本文主张价值分布具有根本重要性:它是强化学习智能体所收到的随机回报的分布。这与强化学习中的常见做法形成对照——后者建模的是这一回报的期望,也就是价值。尽管已有相当多文献研究价值分布,但迄今为止它总是被用于某个具体目的,例如实现风险敏感行为。我们从策略评估和控制两种设定下的理论结果入手,并揭示控制设定中一种显著的分布不稳定性。随后,我们利用分布视角设计了一种新算法,把贝尔曼方程用于学习近似的价值分布。我们在 Arcade Learning Environment 的游戏套件上评估该算法,既得到了当时最好的成绩,也得到了一些轶事性的证据,说明价值分布在近似强化学习中的重要性。最后,我们把理论与经验证据结合起来,说明价值分布如何影响近似设定下的学习。
1 Introduction
1 引言
One of the major tenets of reinforcement learning states that, when not otherwise constrained in its behaviour, an agent should aim to maximize its expected utility , or value (Sutton & Barto, 1998). Bellman’s equation succintly describes this value in terms of the expected reward and expected outcome of the random transition :
强化学习的一条主要信条是:当智能体的行为不受其他约束时,它应当致力于最大化其期望效用 ,也就是价值(Sutton & Barto, 1998)。贝尔曼方程把这一价值简明地写成期望奖励,以及随机转移 的期望结果:
In this paper, we aim to go beyond the notion of value and argue in favour of a distributional perspective on reinforcement learning. Specifically, the main object of our study is the random return whose expectation is the value . This random return is also described by a recursive equation, but one of a distributional nature:
在本文中,我们希望超越价值这一概念,并为强化学习的一种分布视角作辩护。具体来说,我们研究的主要对象是随机回报 ,其期望就是价值 。这一随机回报同样由一个递归方程描述,不过是分布意义上的递归:
The distributional Bellman equation states that the distribution of is characterized by the interaction of three random variables: the reward , the next state-action , and its random return . By analogy with the well-known case, we call this quantity the value distribution.
分布贝尔曼方程表明, 的分布由三个随机变量的相互作用所刻画:奖励 、下一状态-动作 ,以及它的随机回报 。类比熟知的情形,我们把这一量叫做价值分布。
Although the distributional perspective is almost as old as Bellman’s equation itself (Jaquette, 1973; Sobel, 1982; White, 1988), in reinforcement learning it has thus far been subordinated to specific purposes: to model parametric uncertainty (Dearden et al., 1998), to design risk-sensitive algorithms (Morimura et al., 2010b; Morimura et al., 2010a), or for theoretical analysis (Azar et al., 2012; Lattimore & Hutter, 2012). By contrast, we believe the value distribution has a central role to play in reinforcement learning.
尽管分布视角几乎与贝尔曼方程本身一样古老(Jaquette, 1973; Sobel, 1982; White, 1988),但在强化学习中,它迄今为止一直从属于某些特定目的:建模参数不确定性(Dearden et al., 1998),设计风险敏感算法(Morimura et al., 2010b; Morimura et al., 2010a),或用于理论分析(Azar et al., 2012; Lattimore & Hutter, 2012)。相比之下,我们相信价值分布在强化学习中应占据中心位置。
Contraction of the policy evaluation Bellman operator. Basing ourselves on results by Rösler (1992) we show that, for a fixed policy, the Bellman operator over value distributions is a contraction in a maximal form of the Wasserstein (also called Kantorovich or Mallows) metric. Our particular choice of metric matters: the same operator is not a contraction in total variation, Kullback-Leibler divergence, or Kolmogorov distance.
策略评估贝尔曼算子的压缩性。 基于 Rösler(1992)的结果,我们证明:对固定策略,价值分布上的贝尔曼算子在一种极大形式的 Wasserstein 度量(也称 Kantorovich 或 Mallows 度量)下是压缩映射。我们对度量的这一特定选择是要紧的:同一个算子在全变差、Kullback-Leibler 散度或 Kolmogorov 距离下并不是压缩映射。
Instability in the control setting. We will demonstrate an instability in the distributional version of Bellman’s optimality equation, in contrast to the policy evaluation case. Specifically, although the optimality operator is a contraction in expected value (matching the usual optimality result), it is not a contraction in any metric over distributions. These results provide evidence in favour of learning algorithms that model the effects of nonstationary policies.
控制设定中的不稳定性。 我们将说明,与策略评估情形不同,贝尔曼最优性方程的分布版本存在一种不稳定性。具体来说,尽管最优性算子在期望价值上是压缩映射(与通常的最优性结果一致),它在任何分布度量下都不是压缩映射。这些结果为那些会建模非平稳策略效应的学习算法提供了依据。
Better approximations. From an algorithmic standpoint, there are many benefits to learning an approximate distribution rather than its approximate expectation. The distributional Bellman operator preserves multimodality in value distributions, which we believe leads to more stable learning. Approximating the full distribution also mitigates the effects of learning from a nonstationary policy. As a whole, we argue that this approach makes approximate reinforcement learning significantly better behaved.
更好的近似。 从算法角度看,学习一个近似分布,而不是学习其近似期望,有许多好处。分布贝尔曼算子会保留价值分布中的多峰性,我们认为这会带来更稳定的学习。对完整分布做近似,也能减轻从非平稳策略中学习所带来的影响。总的来说,我们主张这一方法会让近似强化学习表现得显著更好。
We will illustrate the practical benefits of the distributional perspective in the context of the Arcade Learning Environment (Bellemare et al., 2013). By modelling the value distribution within a DQN agent (Mnih et al., 2015), we obtain considerably increased performance across the gamut of benchmark Atari 2600 games, and in fact achieve state-of-the-art performance on a number of games. Our results echo those of Veness et al. (2015), who obtained extremely fast learning by predicting Monte Carlo returns.
我们将在 Arcade Learning Environment(Bellemare et al., 2013)的语境中说明分布视角的实际好处。通过在 DQN 智能体(Mnih et al., 2015)内部对价值分布建模,我们在一系列基准 Atari 2600 游戏上获得了相当可观的性能提升,并且事实上在不少游戏上达到了当时最好的成绩。我们的结果与 Veness et al.(2015)相呼应,他们通过预测蒙特卡洛回报获得了极快的学习。
From a supervised learning perspective, learning the full value distribution might seem obvious: why restrict ourselves to the mean? The main distinction, of course, is that in our setting there are no given targets. Instead, we use Bellman’s equation to make the learning process tractable; we must, as Sutton & Barto (1998) put it, “learn a guess from a guess”. It is our belief that this guesswork ultimately carries more benefits than costs.
从监督学习的角度看,学习完整的价值分布似乎是理所当然的:为什么要把自己限制在均值上?当然,主要区别在于,我们的设定里并没有给定的目标。相反,我们用贝尔曼方程让学习过程变得可行;用 Sutton & Barto(1998)的话说,我们必须“从一个猜测中学习另一个猜测”。我们相信,这种猜测最终带来的好处多于代价。
2 Setting
2 设定
We consider an agent interacting with an environment in the standard fashion: at each step, the agent selects an action based on its current state, to which the environment responds with a reward and the next state. We model this interaction as a time-homogeneous Markov Decision Process . As usual, and are respectively the state and action spaces, is the transition kernel , is the discount factor, and is the reward function, which in this work we explicitly treat as a random variable. A stationary policy maps each state to a probability distribution over the action space .
我们按标准方式考虑智能体与环境的交互:在每一步,智能体根据当前状态选择一个动作,环境则以一个奖励和下一状态作为回应。我们把这一交互建模为时间齐次的马尔可夫决策过程 。照例, 和 分别是状态空间和动作空间, 是转移核 , 是折扣因子, 是奖励函数,在本文中我们明确把它当作一个随机变量。平稳策略 把每个状态 映射为动作空间 上的一个概率分布。
2.1 Bellman’s Equations
2.1 贝尔曼方程
The return is the sum of discounted rewards along the agent’s trajectory of interactions with the environment. The value function of a policy describes the expected return from taking action from state , then acting according to :
回报 是智能体与环境交互轨迹上折扣奖励的总和。策略 的价值函数 描述的是:从状态 采取动作 ,然后按 行动所得到的期望回报:
Fundamental to reinforcement learning is the use of Bellman’s equation (Bellman, 1957) to describe the value function:
强化学习的一个基本做法,是用贝尔曼方程(Bellman, 1957)来描述价值函数:
In reinforcement learning we are typically interested in acting so as to maximize the return. The most common approach for doing so involves the optimality equation
在强化学习中,我们通常关心如何行动以最大化回报。最常见的做法涉及最优性方程
Q^{*}(x,a)=\expect R(x,a)+\gamma\expect\nolimits_{P}\max_{a^{\prime}\in\mathcal{A}}Q^{*}(x^{\prime},a^{\prime}).
This equation has a unique fixed point , the optimal value function, corresponding to the set of optimal policies ( is optimal if ).
这一方程有唯一不动点 ,即最优价值函数,它对应于最优策略集合 (若 ,则 是最优的)。
We view value functions as vectors in , and the expected reward function as one such vector. In this context, the Bellman operator and optimality operator are
我们把价值函数看作 中的向量,并把期望奖励函数也看作这样的一个向量。在这一语境下,贝尔曼算子 和最优性算子 是
\displaystyle\mathcal{T}^{\pi}Q(x,a) \\ \displaystyle:=\expect R(x,a)+\gamma\expect_{P,\pi}Q(x^{\prime},a^{\prime}) \\ \displaystyle\mathcal{T}Q(x,a) \\ \displaystyle:=\expect R(x,a)+\gamma\expect\nolimits_{P}\max_{a^{\prime}\in\mathcal{A}}Q(x^{\prime},a^{\prime}). \tag{2}
These operators are useful as they describe the expected behaviour of popular learning algorithms such as SARSA and Q-Learning. In particular they are both contraction mappings, and their repeated application to some initial converges exponentially to or , respectively (Bertsekas & Tsitsiklis, 1996).
这些算子是有用的,因为它们描述了 SARSA 和 Q 学习等流行学习算法的期望行为。特别地,它们都是压缩映射,反复作用于某个初始的 ,会指数地收敛到 或 (Bertsekas & Tsitsiklis, 1996)。
3 The Distributional Bellman Operators
3 分布贝尔曼算子
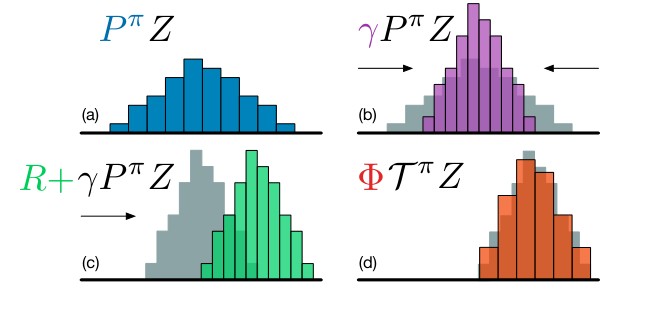
Figure 1: A distributional Bellman operator with a deterministic reward function: (a) Next state distribution under policy , (b) Discounting shrinks the distribution towards 0, (c) The reward shifts it, and (d) Projection step (Section 4).
图 1:带确定性奖励函数的分布贝尔曼算子:(a)策略 下的下一状态分布,(b)折扣把分布向 0 收缩,(c)奖励使它平移,以及(d)投影步骤(第 4 节)。
In this paper we take away the expectations inside Bellman’s equations and consider instead the full distribution of the random variable . From here on, we will view as a mapping from state-action pairs to distributions over returns, and call it the value distribution.
在本文中,我们去掉贝尔曼方程内部的期望,转而考虑随机变量 的完整分布。从此以后,我们将把 看作从状态-动作对到回报分布的映射,并称之为价值分布。
Our first aim is to gain an understanding of the theoretical behaviour of the distributional analogues of the Bellman operators, in particular in the less well-understood control setting. The reader strictly interested in the algorithmic contribution may choose to skip this section.
我们的第一个目标,是理解分布形式的贝尔曼算子在理论上的行为,尤其是在理解还较少的控制设定中。只关心算法贡献的读者可以选择跳过本节。
3.1 Distributional Equations
3.1 分布式方程
It will sometimes be convenient to make use of the probability space . The reader unfamiliar with measure theory may think of as the space of all possible outcomes of an experiment (Billingsley, 1995). We will write to denote the norm of a vector for ; the same applies to vectors in . The norm of a random vector (or ) is then , and for we have (we will omit the dependency on whenever unambiguous). We will denote the c.d.f. of a random variable by , and its inverse c.d.f. by .
有时使用概率空间 会比较方便。不熟悉测度论的读者可以把 理解为一次试验所有可能结果的空间(Billingsley, 1995)。我们将用 表示向量 的 范数,其中 ;这对 中的向量同样适用。随机向量 (或 )的 范数则为 ;当 时,有 (只要不会引起歧义,我们将省略对 的依赖)。我们将把随机变量 的累积分布函数记为 ,并把它的逆累积分布函数记为 。
A distributional equation indicates that the random variable is distributed according to the same law as . Without loss of generality, the reader can understand the two sides of a distributional equation as relating the distributions of two independent random variables. Distributional equations have been used in reinforcement learning by Engel et al. (2005); Morimura et al. (2010a) among others, and in operations research by White (1988).
分布式方程 表示随机变量 与 服从同一规律。在不失一般性的前提下,读者可以把分布式方程的两边理解为两个独立随机变量的分布之间的关系。分布式方程已被 Engel et al.(2005)、Morimura et al.(2010a)等用于强化学习,也被 White(1988)用于运筹学。
3.2 The Wasserstein Metric
3.2 Wasserstein 度量
The main tool for our analysis is the Wasserstein metric between cumulative distribution functions (see e.g. Bickel & Freedman, 1981, where it is called the Mallows metric). For , two c.d.fs over the reals, it is defined as
我们分析的主要工具是累积分布函数之间的 Wasserstein 度量 (例如见 Bickel & Freedman, 1981,他们称之为 Mallows 度量)。对实数上的两个累积分布函数 、,它定义为
where the infimum is taken over all pairs of random variables with respective cumulative distributions and . The infimum is attained by the inverse c.d.f. transform of a random variable uniformly distributed on :
其中下确界取遍所有分别具有累积分布 和 的随机变量对 。该下确界由均匀分布在 上的随机变量 的逆累积分布变换达到:
For this is more explicitly written as
当 时,这可以更显式地写成
Given two random variables , with c.d.fs , , we will write . We will find it convenient to conflate the random variables under consideration with their versions under the , writing
给定两个分别具有累积分布 、 的随机变量 、,我们将写 。为方便起见,我们会把所考虑的随机变量与它们在 下的版本混为一谈,写成
whenever unambiguous; we believe the greater legibility justifies the technical inaccuracy. Finally, we extend this metric to vectors of random variables, such as value distributions, using the corresponding norm.
只要不会引起歧义;我们相信更高的可读性足以弥补这一技术上的不严谨。最后,我们用相应的 范数,把这一度量推广到随机变量的向量上,例如价值分布。
Consider a scalar and a random variable independent of . The metric has the following properties:
考虑标量 以及与 独立的随机变量 。度量 具有下列性质:
We will need the following additional property, which makes no independence assumptions on its variables. Its proof, and that of later results, is given in the appendix.
我们还需要下面这条额外的性质,它对其中的变量不做独立性假设。它的证明以及后面结果的证明,都放在附录中。
Lemma 1(Partition lemma).
Let be a set of random variables describing a partition of , i.e. and for any there is exactly one with . Let be two random variables. Then
引理 1(划分引理)。
设 是描述 的一个划分的一组随机变量,也就是 ,并且对任意 恰好有一个 满足 。设 是两个随机变量。则
Let denote the space of value distributions with bounded moments. For two value distributions we will make use of a maximal form of the Wasserstein metric:
设 表示矩有界的价值分布空间。对两个价值分布 ,我们将使用一种极大形式的 Wasserstein 度量:
We will use to establish the convergence of the distributional Bellman operators.
我们将用 来建立分布贝尔曼算子的收敛性。
Lemma 2.
is a metric over value distributions.
引理 2。
是价值分布上的一个度量。
3.3 Policy Evaluation
3.3 策略评估
In the policy evaluation setting (Sutton & Barto, 1998) we are interested in the value function associated with a given policy . The analogue here is the value distribution . In this section we characterize and study the behaviour of the policy evaluation operator . We emphasize that describes the intrinsic randomness of the agent’s interactions with its environment, rather than some measure of uncertainty about the environment itself.
在策略评估设定中(Sutton & Barto, 1998),我们关心与给定策略 相关联的价值函数 。这里的对应物是价值分布 。本节我们刻画 ,并研究策略评估算子 的行为。我们强调, 描述的是智能体与环境交互的内在随机性,而不是关于环境本身的某种不确定性度量。
We view the reward function as a random vector , and define the transition operator
我们把奖励函数看作一个随机向量 ,并定义转移算子
where we use capital letters to emphasize the random nature of the next state-action pair . We define the distributional Bellman operator as
这里我们用大写字母来强调下一状态-动作对 的随机性。我们把分布贝尔曼算子 定义为
While bears a surface resemblance to the usual Bellman operator (2), it is fundamentally different. In particular, three sources of randomness define the compound distribution :
虽然 表面上类似于通常的贝尔曼算子 (2),但两者有根本不同。特别地,有三个随机性来源共同定义了复合分布 :
a) The randomness in the reward ,
a) 奖励 中的随机性,
b) The randomness in the transition , and
b) 转移 中的随机性,以及
c) The next-state value distribution .
c) 下一状态的价值分布 。
In particular, we make the usual assumption that these three quantities are independent. In this section we will show that (5) is a contraction mapping whose unique fixed point is the random return .
特别地,我们作通常的假定:这三个量是相互独立的。在本节中我们将证明,(5) 是一个压缩映射,其唯一不动点就是随机回报 。
3.3.1 Contraction in
Consider the process , starting with some . We may expect the limiting expectation of to converge exponentially quickly, as usual, to . As we now show, the process converges in a stronger sense: is a contraction in , which implies that all moments also converge exponentially quickly.
3.3.1 在 下的压缩性
考虑过程 ,从某个 开始。我们可以预期, 的极限期望会像往常一样指数快速地收敛到 。正如下面将表明的,这一过程在更强的意义下收敛: 在 下是压缩映射,这意味着所有矩也都指数快速地收敛。
Lemma 3.
is a -contraction in .
引理 3。
在 下是一个 -压缩映射。
Using Lemma 3, we conclude using Banach’s fixed point theorem that has a unique fixed point. By inspection, this fixed point must be as defined in (1). As we assume all moments are bounded, this is sufficient to conclude that the sequence converges to in for .
利用引理 3,我们借助 Banach 不动点定理得出 有唯一不动点。通过直接检查,这一不动点必须是 (1) 中定义的 。由于我们假定所有矩都有界,这足以得出:对 ,序列 在 下收敛到 。
To conclude, we remark that not all distributional metrics are equal; for example, Chung & Sobel (1987) have shown that is not a contraction in total variation distance. Similar results can be derived for the Kullback-Leibler divergence and the Kolmogorov distance.
作为结束,我们指出并非所有分布度量都是等价的;例如,Chung & Sobel(1987)已经表明 在全变差距离下不是压缩映射。对 Kullback-Leibler 散度和 Kolmogorov 距离也可以得出类似结果。
3.3.2 Contraction in Centered Moments
Observe that (and more generally, ) relates to a coupling , in the sense that
3.3.2 中心矩上的压缩性
注意到 (更一般地,)与一个耦合 有关,意义是
As a result, we cannot directly use to bound the variance difference . However, is in fact a contraction in variance (Sobel, 1982, see also appendix). In general, is not a contraction in the centered moment, , but the centered moments of the iterates still converge exponentially quickly to those of ; the proof extends the result of Rösler (1992).
因此,我们不能直接用 来界定方差差 。然而, 实际上在方差上是压缩映射(Sobel, 1982,亦见附录)。一般而言, 在 的 阶中心矩上不是压缩映射,但迭代 的中心矩仍然会指数快速地收敛到 的中心矩;证明是对 Rösler(1992)结果的推广。
3.4 Control
3.4 控制
Thus far we have considered a fixed policy , and studied the behaviour of its associated operator . We now set out to understand the distributional operators of the control setting – where we seek a policy that maximizes value – and the corresponding notion of an optimal value distribution. As with the optimal value function, this notion is intimately tied to that of an optimal policy. However, while all optimal policies attain the same value , in our case a difficulty arises: in general there are many optimal value distributions.
到目前为止,我们考虑的是固定策略 ,并研究与之相关的算子 的行为。现在我们着手理解控制设定下的分布算子——此时我们寻求一个最大化价值的策略 ——以及相应的最优价值分布概念。与最优价值函数一样,这一概念与最优策略紧密相连。然而,虽然所有最优策略都达到同一个价值 ,在我们这里却会出现一个困难:一般而言,最优价值分布有许多个。
In this section we show that the distributional analogue of the Bellman optimality operator converges, in a weak sense, to the set of optimal value distributions. However, this operator is not a contraction in any metric between distributions, and is in general much more temperamental than the policy evaluation operators. We believe the convergence issues we outline here are a symptom of the inherent instability of greedy updates, as highlighted by e.g. Tsitsiklis (2002) and most recently Harutyunyan et al. (2016).
在本节中我们表明,贝尔曼最优性算子的分布对应物会在一种弱的意义上收敛到最优价值分布的集合。不过,这一算子在任何分布之间的度量下都不是压缩映射,并且一般比策略评估算子更不稳定。我们相信,这里勾勒出的收敛问题,是贪心更新固有不稳定性的一种症状,例如 Tsitsiklis(2002)以及最近 Harutyunyan et al.(2016)所强调的那样。
Let be the set of optimal policies. We begin by characterizing what we mean by an optimal value distribution.
设 为最优策略的集合。我们首先刻画我们所说的最优价值分布是什么意思。
Definition 1(Optimal value distribution).
An optimal value distribution is the v.d. of an optimal policy. The set of optimal value distributions is $\mathcal{Z}^{}:={Z^{\pi^{}}:\pi^{}\in\Pi^{}}$.
定义 1(最优价值分布)。
最优价值分布是某一最优策略的价值分布。最优价值分布的集合是 $\mathcal{Z}^{}:={Z^{\pi^{}}:\pi^{}\in\Pi^{}}$。
We emphasize that not all value distributions with expectation are optimal: they must match the full distribution of the return under some optimal policy.
我们强调,并非所有期望为 的价值分布都是最优的:它们必须与某个最优策略下回报的完整分布相一致。
Definition 2.
A greedy policy for maximizes the expectation of . The set of greedy policies for is
定义 2。
对 ,贪心策略 最大化 的期望。 的贪心策略集合是
Recall that the expected Bellman optimality operator is
回忆期望形式的贝尔曼最优性算子 是
\mathcal{T}Q(x,a)=\expect R(x,a)+\gamma\expect\nolimits_{P}\max_{a^{\prime}\in\mathcal{A}}Q(x^{\prime},a^{\prime}). \tag{6}
The maximization at corresponds to some greedy policy. Although this policy is implicit in (6), we cannot ignore it in the distributional setting. We will call a distributional Bellman optimality operator any operator which implements a greedy selection rule, i.e.
在 处的最大化对应于某个贪心策略。尽管这一策略在 (6) 中是隐含的,在分布设定下我们却不能忽略它。凡是实现某种贪心选择规则的算子 ,我们都称之为分布贝尔曼最优性算子,也就是
As in the policy evaluation setting, we are interested in the behaviour of the iterates , . Our first result is to assert that behaves as expected.
与策略评估设定一样,我们关心迭代 、 的行为。我们的第一个结果是断言 的表现符合预期。
Lemma 4.
Let . Then
引理 4。
设 。则
and in particular $\expect Z_{k}\to Q^{}$ exponentially quickly.*
并且特别地, 会指数快速地收敛到 $Q^{}$。*
By inspecting Lemma 4, we might expect that converges quickly in to some fixed point in . Unfortunately, convergence is neither quick nor assured to reach a fixed point. In fact, the best we can hope for is pointwise convergence, not even to the set but to the larger set of nonstationary optimal value distributions.
若只看引理 4,我们或许会期望 在 下快速收敛到 中的某个不动点。遗憾的是,收敛既不迅速,也不能保证到达一个不动点。事实上,我们最多只能指望逐点收敛,而且甚至不是收敛到集合 ,而是收敛到更大的非平稳最优价值分布集合。
Definition 3.
A nonstationary optimal value distribution is the value distribution corresponding to a sequence of optimal policies. The set of n.o.v.d. is .
定义 3。
非平稳最优价值分布 是对应于一列最优策略的价值分布。非平稳最优价值分布的集合是 。
Theorem 1(Convergence in the control setting).
Let be measurable and suppose that is finite. Then
定理 1(控制设定中的收敛性)。
设 是可测的,并假定 是有限的。则
If is finite, then converges to uniformly. Furthermore, if there is a total ordering on $\Pi^{}Z^{}\in\mathcal{Z}^{}$,*
若 是有限的,则 一致收敛到 。此外,若 $\Pi^{}\precZ^{}\in\mathcal{Z}^{}$,*
Then has a unique fixed point $Z^{}\in\mathcal{Z}^{}$.
则 有唯一不动点 $Z^{}\in\mathcal{Z}^{}$。
Comparing Theorem 1 to Lemma 4 reveals a significant difference between the distributional framework and the usual setting of expected return. While the mean of converges exponentially quickly to , its distribution need not be as well-behaved! To emphasize this difference, we now provide a number of negative results concerning .
把定理 1 与引理 4 相比较,可以看出分布框架与通常的期望回报设定之间有显著差别。 的均值会指数快速地收敛到 ,但它的分布却不必同样表现良好!为了强调这一差别,我们现在给出关于 的若干否定性结果。
Proposition 1.
The operator is not a contraction.
命题 1。
算子 不是压缩映射。
Consider the following example (Figure 2, left). There are two states, and ; a unique transition from to ; from , action yields no reward, while the optimal action yields or with equal probability. Both actions are terminal. There is a unique optimal policy and therefore a unique fixed point . Now consider as given in Figure 2 (right), and its distance to :
考虑下面的例子(图 2,左)。有两个状态 和 ;从 到 有唯一的转移;在 处,动作 不产生奖励,而最优动作 以相等的概率产生 或 。两个动作都是终止的。存在唯一的最优策略,因而有唯一的不动点 。现在考虑图 2(右)中给出的 ,以及它到 的距离:
$$\bar{d}{1}(Z,Z^{*})=d{1}(Z(x_{2},a_{2}),Z^{*}(x_{2},a_{2}))=2\epsilon,\
$$
where we made use of the fact that everywhere except at . When we apply to , however, the greedy action is selected and . But
这里我们用到了除 外, 处处成立这一事实。然而,当我们对 应用 时,贪心动作 被选中,并且 。但
for a sufficiently small . This shows that the undiscounted update is not a nonexpansion: . With , the same proof shows it is not a contraction. Using a more technically involved argument, we can extend this result to any metric which separates and .
对足够小的 成立。这表明无折扣更新不是非扩张的:。当 时,同样的证明表明它不是压缩映射。用一个技术上更复杂的论证,我们可以把这一结果推广到任何能分开 和 的度量。
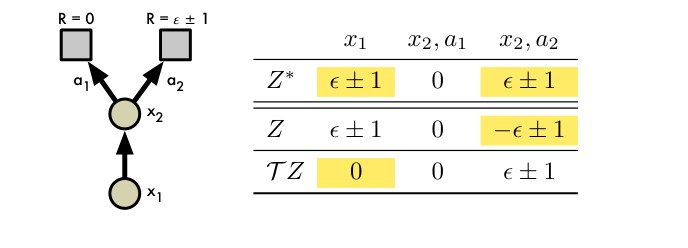
Figure 2: Undiscounted two-state MDP for which the optimality operator is not a contraction, with example. The entries that contribute to and are highlighted.
图 2:最优性算子 并非压缩映射的无折扣两状态 MDP,并给出例子。对 和 有贡献的表项被标出。
Proposition 2.
Not all optimality operators have a fixed point $Z^{}=\mathcal{T}Z^{}$.
命题 2。
并非所有最优性算子都有不动点 $Z^{}=\mathcal{T}Z^{}$。
To see this, consider the same example, now with , and a greedy operator which breaks ties by picking if , and otherwise. Then the sequence alternates between and .
为说明这一点,考虑同一个例子,现在取 ,以及一个贪心算子 :它在 时打破平局选择 ,否则选择 。于是序列 会在 与 之间交替。
Proposition 3.
That has a fixed point $Z^{}=\mathcal{T}Z^{}{Z_{k}}\mathcal{Z}^{}$.*
命题 3。
有不动点 $Z^{}=\mathcal{T}Z^{}{Z_{k}}\mathcal{Z}^{}$。*
Theorem 1 paints a rather bleak picture of the control setting. It remains to be seen whether the dynamical eccentricies highlighted here actually arise in practice. One open question is whether theoretically more stable behaviour can be derived using stochastic policies, for example from conservative policy iteration (Kakade & Langford, 2002).
定理 1 给控制设定描绘了一幅相当黯淡的图景。这里突出的这些动态异常是否真的会在实践中出现,仍有待观察。一个未决的问题是:能否通过使用随机策略,例如来自保守策略迭代(Kakade & Langford, 2002),在理论上得到更稳定的行为。
4 Approximate Distributional Learning
4 近似分布学习
In this section we propose an algorithm based on the distributional Bellman optimality operator. In particular, this will require choosing an approximating distribution. Although the Gaussian case has previously been considered (Morimura et al., 2010a; Tamar et al., 2016), to the best of our knowledge we are the first to use a rich class of parametric distributions.
在本节中,我们提出一种基于分布贝尔曼最优性算子的算法。特别地,这需要选择一种近似分布。尽管高斯情形先前已被考虑过(Morimura et al., 2010a; Tamar et al., 2016),但据我们所知,我们是最先使用一类表达力更丰富的参数分布的。
4.1 Parametric Distribution
4.1 参数化分布
We will model the value distribution using a discrete distribution parametrized by and , and whose support is the set of atoms , . In a sense, these atoms are the “canonical returns” of our distribution. The atom probabilities are given by a parametric model
我们将用一个离散分布来建模价值分布,其参数为 以及 ,支撑是原子集合 ,其中 。在某种意义上,这些原子就是我们分布的“典型回报”。原子上的概率由参数模型 给出
The discrete distribution has the advantages of being highly expressive and computationally friendly (Van den Oord et al., 2016, see e.g.).
离散分布的优点是表达力强,并且在计算上友好(例如见 Van den Oord et al., 2016)。
4.2 Projected Bellman Update
4.2 投影贝尔曼更新
Using a discrete distribution poses a problem: the Bellman update and our parametrization almost always have disjoint supports. From the analysis of Section 3 it would seem natural to minimize the Wasserstein metric (viewed as a loss) between and , which is also conveniently robust to discrepancies in support. However, a second issue prevents this: in practice we are typically restricted to learning from sample transitions, which is not possible under the Wasserstein loss (see Prop. 5 and toy results in the appendix).
使用离散分布会带来一个问题:贝尔曼更新 与我们的参数化 几乎总是具有不相交的支撑。从第 3 节的分析看,在 与 之间最小化 Wasserstein 度量(把它看作一种损失)似乎是自然的,而且它对支撑上的不一致也相当稳健。然而第二个问题阻碍了这一点:在实践中我们通常只能从样本转移中学习,而这在 Wasserstein 损失下是不可行的(见命题 5 以及附录中的玩具结果)。
Instead, we project the sample Bellman update onto the support of (Figure 1, Algorithm 1), effectively reducing the Bellman update to multiclass classification. Let be the greedy policy w.r.t. . Given a sample transition , we compute the Bellman update for each atom , then distribute its probability to the immediate neighbours of . The component of the projected update is
取而代之,我们把样本贝尔曼更新 投影到 的支撑上(图 1,算法 1),从而有效地把贝尔曼更新化成多类分类。设 是关于 的贪心策略。给定一个样本转移 ,我们对每个原子 计算贝尔曼更新 ,再把它的概率 分配给 的紧邻原子。投影更新 的第 个分量是
where bounds its argument in the range .[^1] As is usual, we view the next-state distribution as parametrized by a fixed parameter . The sample loss is the cross-entropy term of the KL divergence
其中 把它的自变量限制在区间 内。[^1] 照例,我们把下一状态分布看作由固定参数 参数化。样本损失 是 KL 散度中的交叉熵项
which is readily minimized e.g. using gradient descent. We call this choice of distribution and loss the categorical algorithm. When , a simple one-parameter alternative is we call this the Bernoulli algorithm. We note that, while these algorithms appear unrelated to the Wasserstein metric, recent work (Bellemare et al., 2017) hints at a deeper connection.
它可以方便地用例如梯度下降来最小化。我们把这一分布与损失的选择叫做分类算法。当 时,一个简单的单参数替代是 我们称之为伯努利算法。我们指出,尽管这些算法看起来与 Wasserstein 度量无关,最近的工作(Bellemare et al., 2017)暗示它们之间有更深层的联系。
0: A transition ,
for do
Compute the projection of onto the support
#
,
Distribute probability of
end for
# Cross-entropy loss
Algorithm 1 Categorical Algorithm
0: 一次转移 ,
for do
计算 到支撑 上的投影
#
,
分配 的概率
end for
# 交叉熵损失
算法 1 分类算法
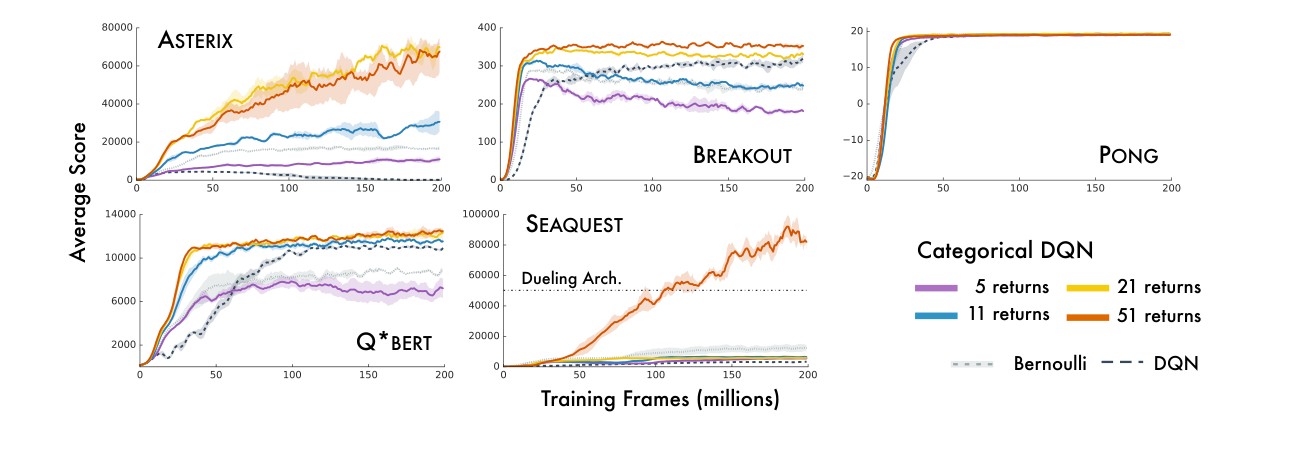
Figure 3: Categorical DQN: Varying number of atoms in the discrete distribution. Scores are moving averages over 5 million frames.
图 3:分类 DQN:改变离散分布中的原子个数。分数是 500 万帧上的滑动平均。
5 Evaluation on Atari 2600 Games
5 在 Atari 2600 游戏上的评估
To understand the approach in a complex setting, we applied the categorical algorithm to games from the Arcade Learning Environment (Bellemare et al., 2013, ALE;). While the ALE is deterministic, stochasticity does occur in a number of guises: 1) from state aliasing, 2) learning from a nonstationary policy, and 3) from approximation errors. We used five training games (Fig 3) and 52 testing games.
为了在复杂设定中理解这一方法,我们把分类算法应用到 Arcade Learning Environment(Bellemare et al., 2013, ALE;)中的游戏上。虽然 ALE 是确定性的,随机性仍会以若干面貌出现:1)来自状态混叠,2)从非平稳策略中学习,以及 3)来自近似误差。我们使用了五款训练游戏(图 3)和 52 款测试游戏。
For our study, we use the DQN architecture (Mnih et al., 2015), but output the atom probabilities instead of action-values, and chose from preliminary experiments over the training games. We call the resulting architecture Categorical DQN. We replace the squared loss by and train the network to minimize this loss.[^2] As in DQN, we use a simple -greedy policy over the expected action-values; we leave as future work the many ways in which an agent could select actions on the basis of the full distribution. The rest of our training regime matches Mnih et al.’s, including the use of a target network for .
在这项研究中,我们使用 DQN 的结构(Mnih et al., 2015),但输出的是原子概率 而不是动作价值,并在训练游戏上的初步实验后选择 。我们把得到的结构叫做分类 DQN。我们用 替换平方损失 ,并训练网络最小化这一损失。[^2] 与 DQN 一样,我们在期望动作价值上使用简单的 -贪心策略;智能体如何根据完整分布来选择动作的许多方式,我们留待未来工作。其余训练流程与 Mnih et al. 的做法一致,包括为 使用目标网络。
Figure 4 illustrates the typical value distributions we observed in our experiments. In this example, three actions (those including the button press) lead to the agent releasing its laser too early and eventually losing the game. The corresponding distributions reflect this: they assign a significant probability to 0 (the terminal value). The safe actions have similar distributions (left, which tracks the invaders’ movement, is slightly favoured). This example helps explain why our approach is so successful: the distributional update keeps separated the low-value, ‘‘losing’’ event from the high-value, ‘‘survival’’ event, rather than average them into one (unrealizable) expectation.[^3]
图 4 展示了我们在实验中观察到的典型价值分布。在这个例子里,三个动作(那些包含按键的动作)会让智能体过早放出激光,并最终输掉游戏。相应的分布反映了这一点:它们给 0(终止价值)分配了相当大的概率。安全动作的分布彼此相近(左侧那个跟踪入侵者移动的动作略被看好)。这个例子有助于解释为什么我们的方法如此成功:分布更新把低价值的“输掉”事件与高价值的“幸存”事件分开保持,而不是把它们平均成一个(无法实现的)期望。[^3]
One surprising fact is that the distributions are not concentrated on one or two values, in spite of the ALE’s determinism, but are often close to Gaussians. We believe this is due to our discretizing the diffusion process induced by .
一个令人惊讶的事实是:尽管 ALE 是确定性的,这些分布并没有集中在一两个取值上,而常常接近高斯分布。我们相信,这是由于我们对 所诱导的扩散过程做了离散化。
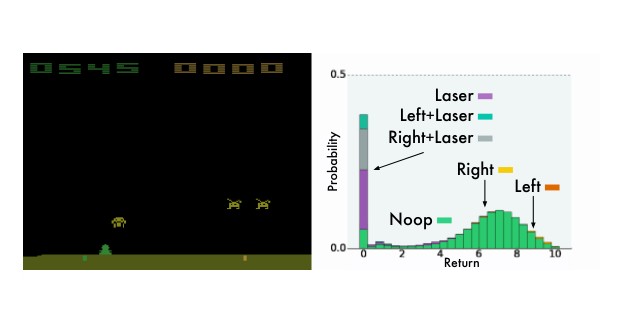
Figure 4: Learned value distribution during an episode of Space Invaders. Different actions are shaded different colours. Returns below 0 (which do not occur in Space Invaders) are not shown here as the agent assigns virtually no probability to them.
图 4:在一局太空侵略者中学到的价值分布。不同动作用不同颜色着色。低于 0 的回报(在太空侵略者中不会出现)这里没有画出,因为智能体几乎没有给它们分配任何概率。
5.1 Varying the Number of Atoms
5.1 改变原子个数
We began by studying our algorithm’s performance on the training games in relation to the number of atoms (Figure 3). For this experiment, we set . From the data, it is clear that using too few atoms can lead to poor behaviour, and that more always increases performance; this is not immediately obvious as we may have expected to saturate the network capacity. The difference in performance between the 51-atom version and DQN is particularly striking: the latter is outperformed in all five games, and in Seaquest we attain state-of-the-art performance. As an additional point of the comparison, the single-parameter Bernoulli algorithm performs better than DQN in 3 games out of 5, and is most notably more robust in Asterix.
我们首先结合原子个数,考察算法在训练游戏上的表现(图 3)。在这一实验中,我们设 。从数据可以清楚地看到,原子太少会导致较差的行为,而更多的原子总是能提升性能;这一点并不显而易见,因为我们本可能预期网络容量会先达到饱和。51 个原子的版本与 DQN 之间的性能差异尤其醒目:后者在全部五款游戏上都被超过,并且在 Seaquest 上我们达到了当时最好的成绩。作为额外的比较,单参数的伯努利算法在 5 款游戏中的 3 款上优于 DQN,并且在 Asterix 中明显更稳健。
One interesting outcome of this experiment was to find out that our method does pick up on stochasticity. Pong exhibits intrinsic randomness: the exact timing of the reward depends on internal registers and is truly unobservable. We see this clearly reflected in the agent’s prediction (Figure 5): over five consecutive frames, the value distribution shows two modes indicating the agent’s belief that it has yet to receive a reward. Interestingly, since the agent’s state does not include past rewards, it cannot even extinguish the prediction after receiving the reward, explaining the relative proportions of the modes.
这一实验的一个有意思的结果,是发现我们的方法确实能捕捉到随机性。Pong 具有内在随机性:奖励出现的精确时机取决于内部寄存器,并且真正不可观测。我们在智能体的预测中清楚地看到了这一点(图 5):在连续五帧里,价值分布呈现出两个峰,表明智能体相信自己尚未收到奖励。有意思的是,由于智能体的状态并不包含过去的奖励,它甚至无法在收到奖励后把这一预测熄灭,这也解释了两个峰的相对比例。
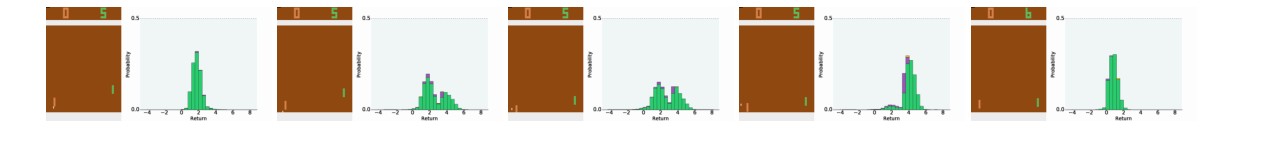
Figure 5: Intrinsic stochasticity in Pong.
图 5:Pong 中的内在随机性。
5.2 State-of-the-Art Results
5.2 当时最好的结果
The performance of the 51-atom agent (from here onwards, C51) on the training games, presented in the last section, is particularly remarkable given that it involved none of the other algorithmic ideas present in state-of-the-art agents. We next asked whether incorporating the most common hyperparameter choice, namely a smaller training , could lead to even better results. Specifically, we set (instead of ); furthermore, every 1 million frames, we evaluate our agent’s performance with .
上一节给出的 51 原子智能体(从此称为 C51)在训练游戏上的表现特别值得注意,因为它并没有用到当时最好智能体中的其他算法想法。我们接下来问:加入最常见的超参数选择,也就是更小的训练 ,能否带来更好的结果。具体来说,我们设 (而不是 );此外,每 100 万帧,我们用 评估智能体的表现。
We compare our algorithm to DQN (), Double DQN (van Hasselt et al., 2016), the Dueling architecture (Wang et al., 2016), and Prioritized Replay (Schaul et al., 2016), comparing the best evaluation score achieved during training. We see that C51 significantly outperforms these other algorithms (Figures 6 and 7). In fact, C51 surpasses the current state-of-the-art by a large margin in a number of games, most notably Seaquest. One particularly striking fact is the algorithm’s good performance on sparse reward games, for example Venture and Private Eye. This suggests that value distributions are better able to propagate rarely occurring events. Full results are provided in the appendix.
我们把算法与 DQN()、Double DQN(van Hasselt et al., 2016)、对决结构(Wang et al., 2016)以及优先回放(Schaul et al., 2016)相比较,比较的是训练期间达到的最好评估分数。可以看到,C51 显著超过了这些其他算法(图 6 和图 7)。事实上,C51 在不少游戏上以较大幅度超过了当时最好的成绩,尤其是 Seaquest。一个特别醒目的事实,是该算法在稀疏奖励游戏上的良好表现,例如 Venture 和 Private Eye。这表明价值分布更能传播很少出现的事件。完整结果见附录。
We also include in the appendix (Figure 12) a comparison, averaged over 3 seeds, showing the number of games in which C51’s training performance outperforms fully-trained DQN and human players. These results continue to show dramatic improvements, and are more representative of an agent’s average performance. Within 50 million frames, C51 has outperformed a fully trained DQN agent on 45 out of 57 games. This suggests that the full 200 million training frames, and its ensuing computational cost, are unnecessary for evaluating reinforcement learning algorithms within the ALE.
我们还在附录中(图 12)放入了一项对 3 个随机种子取平均的比较,给出 C51 的训练表现超过充分训练的 DQN 以及人类玩家的游戏数量。这些结果继续显示出巨大的提升,并且更能代表智能体的平均表现。在 5000 万帧之内,C51 已在 57 款游戏中的 45 款上超过了充分训练的 DQN 智能体。这表明,对在 ALE 内评估强化学习算法而言,完整的 2 亿训练帧及其随之而来的计算代价并不是必要的。
The most recent version of the ALE contains a stochastic execution mechanism designed to ward against trajectory overfitting.Specifically, on each frame the environment rejects the agent’s selected action with probability . Although DQN is mostly robust to stochastic execution, there are a few games in which its performance is reduced. On a score scale normalized with respect to the random and DQN agents, C51 obtains mean and median score improvements of and respectively, confirming the benefits of C51 beyond the deterministic setting.
ALE 的最新版本包含一种随机执行机制,用来防止对轨迹过拟合。具体来说,环境在每一帧以概率 拒绝智能体所选的动作。尽管 DQN 对随机执行大体是稳健的,仍有少数游戏中它的表现会下降。在相对随机智能体和 DQN 智能体做了分数标准化的尺度上,C51 分别获得了 和 的均值与中位数分数提升,从而在确定性设定之外也确认了 C51 的好处。
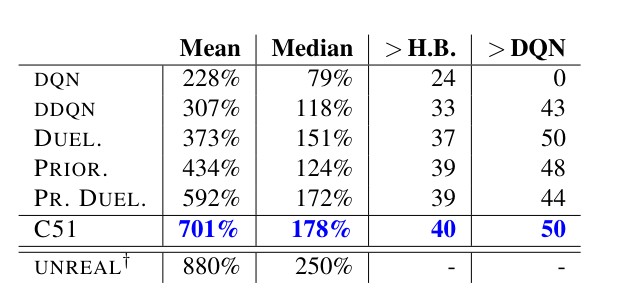
Figure 6: Mean and median scores across 57 Atari games, measured as percentages of human baseline (Nair et al., 2015, H.B.,).
图 6:57 款 Atari 游戏上的均值与中位数分数,以人类基线的百分比衡量(Nair et al., 2015, H.B.,)。
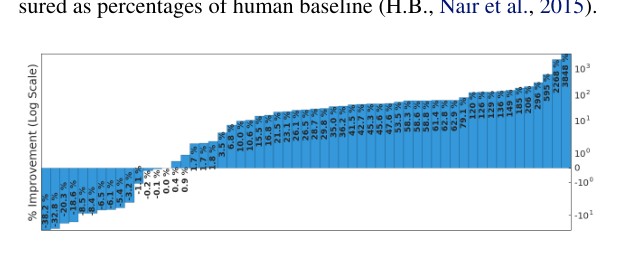
Figure 7: Percentage improvement, per-game, of C51 over Double DQN, computed using van Hasselt et al.’s method.
图 7:C51 相对 Double DQN 的逐游戏提升百分比,用 van Hasselt et al. 的方法计算。
6 Discussion
6 讨论
In this work we sought a more complete picture of reinforcement learning, one that involves value distributions. We found that learning value distributions is a powerful notion that allows us to surpass most gains previously made on Atari 2600, without further algorithmic adjustments.
在这项工作中,我们寻求一幅更完整的强化学习图景,一幅包含价值分布的图景。我们发现,学习价值分布是一种有力的想法,它让我们能够超过此前在 Atari 2600 上取得的大部分进展,而不需要进一步调整算法。
6.1 Why does learning a distribution matter?
6.1 为什么学习分布是要紧的?
It is surprising that, when we use a policy which aims to maximize expected return, we should see any difference in performance. The distinction we wish to make is that learning distributions matters in the presence of approximation. We now outline some possible reasons.
令人惊讶的是,当我们使用一个旨在最大化期望回报的策略时,竟然仍会看到性能上的差异。我们希望做出的区分是:在存在近似的情况下,学习分布是要紧的。下面我们勾勒一些可能的原因。
Reduced chattering. Our results from Section 3.4 highlighted a significant instability in the Bellman optimality operator. When combined with function approximation, this instability may prevent the policy from converging, what Gordon (1995) called chattering. We believe the gradient-based categorical algorithm is able to mitigate these effects by effectively averaging the different distributions, similar to conservative policy iteration (Kakade & Langford, 2002). While the chattering persists, it is integrated to the approximate solution.
减轻振荡。 我们在第 3.4 节的结果突出了贝尔曼最优性算子中的一种显著不稳定性。当与函数近似结合时,这种不稳定性可能阻止策略收敛,也就是 Gordon(1995)所说的振荡(chattering)。我们相信,基于梯度的分类算法能够通过有效地平均不同分布,来减轻这些效应,这与保守策略迭代类似(Kakade & Langford, 2002)。虽然振荡仍然存在,但它被整合进了近似解之中。
State aliasing. Even in a deterministic environment, state aliasing may result in effective stochasticity. McCallum (1995), for example, showed the importance of coupling representation learning with policy learning in partially observable domains. We saw an example of state aliasing in Pong, where the agent could not exactly predict the reward timing. Again, by explicitly modelling the resulting distribution we provide a more stable learning target.
状态混叠。 即便在确定性环境中,状态混叠也可能造成有效的随机性。例如,McCallum(1995)表明,在部分可观测域中,把表征学习与策略学习耦合起来是重要的。我们在 Pong 中看到了状态混叠的一个例子:智能体无法精确预测奖励出现的时机。同样,通过显式建模由此产生的分布,我们提供了一个更稳定的学习目标。
A richer set of predictions. A recurring theme in artificial intelligence is the idea of an agent learning from a multitude of predictions (Caruana 1997; Utgoff & Stracuzzi 2002; Sutton et al. 2011; Jaderberg et al. 2017). The distributional approach naturally provides us with a rich set of auxiliary predictions, namely: the probability that the return will take on a particular value. Unlike previously proposed approaches, however, the accuracy of these predictions is tightly coupled with the agent’s performance.
更丰富的一组预测。 人工智能中一个反复出现的主题,是智能体从大量预测中学习(Caruana 1997; Utgoff & Stracuzzi 2002; Sutton et al. 2011; Jaderberg et al. 2017)。分布方法自然地为我们提供了一组丰富的辅助预测,也就是:回报取某个特定值的概率。不过,与先前提出的方法不同,这些预测的准确性与智能体的表现紧密耦合。
Framework for inductive bias. The distributional perspective on reinforcement learning allows a more natural framework within which we can impose assumptions about the domain or the learning problem itself. In this work we used distributions with support bounded in . Treating this support as a hyperparameter allows us to change the optimization problem by treating all extremal returns (e.g. greater than ) as equivalent. Surprisingly, a similar value clipping in DQN significantly degrades performance in most games. To take another example: interpreting the discount factor as a proper probability, as some authors have argued, leads to a different algorithm.
归纳偏置的框架。 强化学习的分布视角提供了一个更自然的框架,我们可以在其中施加关于领域或学习问题本身的假定。在这项工作中,我们使用支撑被限制在 上的分布。把这一支撑当作超参数,使我们能够通过把所有极端回报(例如大于 的回报)视为等价,来改变优化问题。令人惊讶的是,在 DQN 中做类似的价值裁剪,会在大多数游戏上显著损害性能。再举一个例子:若像一些作者所主张的那样,把折扣因子 解释为真正的概率,则会得到另一种算法。
Well-behaved optimization. It is well-accepted that the KL divergence between categorical distributions is a reasonably easy loss to minimize. This may explain some of our empirical performance. Yet early experiments with alternative losses, such as KL divergence between continuous densities, were not fruitful, in part because the KL divergence is insensitive to the values of its outcomes. A closer minimization of the Wasserstein metric should yield even better results than what we presented here.
表现良好的优化。 人们普遍接受,分类分布之间的 KL 散度是一种相当容易最小化的损失。这或许可以解释我们经验表现中的一部分。然而,早期用替代损失所做的实验,例如连续密度之间的 KL 散度,并没有取得成效,部分原因是 KL 散度对其结果的取值不敏感。对 Wasserstein 度量做更接近的最小化,应当能得到比我们在这里给出的更好的结果。
In closing, we believe our results highlight the need to account for distribution in the design, theoretical or otherwise, of algorithms.
作为结束,我们相信我们的结果突出了这一点:在算法的设计中,无论是理论还是其他方面,都需要把分布考虑进去。
Acknowledgements
致谢
The authors acknowledge the important role played by their colleagues at DeepMind throughout the development of this work. Special thanks to Yee Whye Teh, Alex Graves, Joel Veness, Guillaume Desjardins, Tom Schaul, David Silver, Andre Barreto, Max Jaderberg, Mohammad Azar, Georg Ostrovski, Bernardo Avila Pires, Olivier Pietquin, Audrunas Gruslys, Tom Stepleton, Aaron van den Oord; and particularly Chris Maddison for his comprehensive review of an earlier draft. Thanks also to Marek Petrik for pointers to the relevant literature, and Mark Rowland for fine-tuning details in the final version.
作者感谢 DeepMind 的同事在这项工作发展全过程中所起的重要作用。特别感谢 Yee Whye Teh、Alex Graves、Joel Veness、Guillaume Desjardins、Tom Schaul、David Silver、Andre Barreto、Max Jaderberg、Mohammad Azar、Georg Ostrovski、Bernardo Avila Pires、Olivier Pietquin、Audrunas Gruslys、Tom Stepleton、Aaron van den Oord;尤其感谢 Chris Maddison 对较早草稿所做的全面审阅。也感谢 Marek Petrik 指出相关文献,以及 Mark Rowland 对最终版本中细节的打磨。
Erratum
勘误
The camera-ready copy of this paper incorrectly reported a mean score of 1010% for C51. The corrected figure stands at 701%, which remains higher than the other comparable baselines. The median score remains unchanged at 178%.
本文的 camera-ready 版本错误地报告了 C51 的均值分数为 1010%。更正后的数字为 701%,仍然高于其他可比较的基线。中位数分数保持不变,为 178%。
The error was due to evaluation episodes in one game (Atlantis) lasting over 30 minutes; in comparison, the other results presented here cap episodes at 30 minutes, as is standard. The previously reported score on Atlantis was 3.7 million; our 30-minute score is 841,075, which we believe is close to the achievable maximum in this time frame. Capping at 30 minutes brings our human-normalized score on Atlantis from 22824% to a mere (!) 5199%, unfortunately enough to noticeably affect the mean score, whose sensitivity to outliers is well-documented.
这一错误源于一款游戏(Atlantis)中的评估局持续超过 30 分钟;相比之下,这里给出的其他结果都按惯例把每局限制在 30 分钟。先前报告的 Atlantis 分数是 370 万;我们的 30 分钟分数是 841,075,我们相信这已接近在这一时限内可达到的最大值。把时限设为 30 分钟后,我们在 Atlantis 上相对人类的标准化分数从 22824% 降到了区区(!)5199%,但不幸的是,这已足以明显影响均值分数,而均值对异常值的敏感性是众所周知的。
References
参考文献
Azar et al. (2012) Azar, Mohammad Gheshlaghi, Munos, Rémi, and Kappen, Hilbert. On the sample complexity of reinforcement learning with a generative model. In Proceedings of the International Conference on Machine Learning , 2012.
Bellemare et al. (2013) Bellemare, Marc G, Naddaf, Yavar, Veness, Joel, and Bowling, Michael. The arcade learning environment: An evaluation platform for general agents. Journal of Artificial Intelligence Research , 47:253–279, 2013.
Bellemare et al. (2017) Bellemare, Marc G., Danihelka, Ivo, Dabney, Will, Mohamed, Shakir, Lakshminarayanan, Balaji, Hoyer, Stephan, and Munos, Rémi. The cramer distance as a solution to biased wasserstein gradients. arXiv , 2017.
Bellman (1957) Bellman, Richard E. Dynamic programming . Princeton University Press, Princeton, NJ, 1957.
Bertsekas & Tsitsiklis (1996) Bertsekas, Dimitri P. and Tsitsiklis, John N. Neuro-Dynamic Programming . Athena Scientific, 1996.
Bickel & Freedman (1981) Bickel, Peter J. and Freedman, David A. Some asymptotic theory for the bootstrap. The Annals of Statistics , pp. 1196–1217, 1981.
Billingsley (1995) Billingsley, Patrick. Probability and measure . John Wiley & Sons, 1995.
Caruana (1997) Caruana, Rich. Multitask learning. Machine Learning , 28(1):41–75, 1997.
Chung & Sobel (1987) Chung, Kun-Jen and Sobel, Matthew J. Discounted mdp’s: Distribution functions and exponential utility maximization. SIAM Journal on Control and Optimization , 25(1):49–62, 1987.
Dearden et al. (1998) Dearden, Richard, Friedman, Nir, and Russell, Stuart. Bayesian Q-learning. In Proceedings of the National Conference on Artificial Intelligence , 1998.
Engel et al. (2005) Engel, Yaakov, Mannor, Shie, and Meir, Ron. Reinforcement learning with gaussian processes. In Proceedings of the International Conference on Machine Learning , 2005.
Geist & Pietquin (2010) Geist, Matthieu and Pietquin, Olivier. Kalman temporal differences. Journal of Artificial Intelligence Research , 39:483–532, 2010.
Gordon (1995) Gordon, Geoffrey. Stable function approximation in dynamic programming. In Proceedings of the Twelfth International Conference on Machine Learning , 1995.
Harutyunyan et al. (2016) Harutyunyan, Anna, Bellemare, Marc G., Stepleton, Tom, and Munos, Rémi. Q( λ \lambda ) with off-policy corrections. In Proceedings of the Conference on Algorithmic Learning Theory , 2016.
Hoffman et al. (2009) Hoffman, Matthew D., de Freitas, Nando, Doucet, Arnaud, and Peters, Jan. An expectation maximization algorithm for continuous markov decision processes with arbitrary reward. In Proceedings of the International Conference on Artificial Intelligence and Statistics , 2009.
Jaderberg et al. (2017) Jaderberg, Max, Mnih, Volodymyr, Czarnecki, Wojciech Marian, Schaul, Tom, Leibo, Joel Z, Silver, David, and Kavukcuoglu, Koray. Reinforcement learning with unsupervised auxiliary tasks. Proceedings of the International Conference on Learning Representations , 2017.
Jaquette (1973) Jaquette, Stratton C. Markov decision processes with a new optimality criterion: Discrete time. The Annals of Statistics , 1(3):496–505, 1973.
Kakade & Langford (2002) Kakade, Sham and Langford, John. Approximately optimal approximate reinforcement learning. In Proceedings of the International Conference on Machine Learning , 2002.
Kingma & Ba (2015) Kingma, Diederik and Ba, Jimmy. Adam: A method for stochastic optimization. Proceedings of the International Conference on Learning Representations , 2015.
Lattimore & Hutter (2012) Lattimore, Tor and Hutter, Marcus. PAC bounds for discounted MDPs. In Proceedings of the Conference on Algorithmic Learning Theory , 2012.
Mannor & Tsitsiklis (2011) Mannor, Shie and Tsitsiklis, John N. Mean-variance optimization in markov decision processes. 2011.
McCallum (1995) McCallum, Andrew K. Reinforcement learning with selective perception and hidden state . PhD thesis, University of Rochester, 1995.
Mnih et al. (2015) Mnih, Volodymyr, Kavukcuoglu, Koray, Silver, David, Rusu, Andrei A, Veness, Joel, Bellemare, Marc G, Graves, Alex, Riedmiller, Martin, Fidjeland, Andreas K, Ostrovski, Georg, et al. Human-level control through deep reinforcement learning. Nature , 518(7540):529–533, 2015.
Morimura et al. (2010a) Morimura, Tetsuro, Hachiya, Hirotaka, Sugiyama, Masashi, Tanaka, Toshiyuki, and Kashima, Hisashi. Parametric return density estimation for reinforcement learning. In Proceedings of the Conference on Uncertainty in Artificial Intelligence , 2010a.
Morimura et al. (2010b) Morimura, Tetsuro, Sugiyama, Masashi, Kashima, Hisashi, Hachiya, Hirotaka, and Tanaka, Toshiyuki. Nonparametric return distribution approximation for reinforcement learning. In Proceedings of the 27th International Conference on Machine Learning (ICML-10) , pp. 799–806, 2010b.
Nair et al. (2015) Nair, Arun, Srinivasan, Praveen, Blackwell, Sam, Alcicek, Cagdas, Fearon, Rory, De Maria, Alessandro, Panneershelvam, Vedavyas, Suleyman, Mustafa, Beattie, Charles, and Petersen, Stig et al. Massively parallel methods for deep reinforcement learning. In ICML Workshop on Deep Learning , 2015.
Prashanth & Ghavamzadeh (2013) Prashanth, LA and Ghavamzadeh, Mohammad. Actor-critic algorithms for risk-sensitive mdps. In Advances in Neural Information Processing Systems , 2013.
Puterman (1994) Puterman, Martin L. Markov Decision Processes: Discrete stochastic dynamic programming . John Wiley & Sons, Inc., 1994.
Rösler (1992) Rösler, Uwe. A fixed point theorem for distributions. Stochastic Processes and their Applications , 42(2):195–214, 1992.
Schaul et al. (2016) Schaul, Tom, Quan, John, Antonoglou, Ioannis, and Silver, David. Prioritized experience replay. In Proceedings of the International Conference on Learning Representations , 2016.
Sobel (1982) Sobel, Matthew J. The variance of discounted markov decision processes. Journal of Applied Probability , 19(04):794–802, 1982.
Sutton & Barto (1998) Sutton, Richard S. and Barto, Andrew G. Reinforcement learning: An introduction . MIT Press, 1998.
Sutton et al. (2011) Sutton, R.S., Modayil, J., Delp, M., Degris, T., Pilarski, P.M., White, A., and Precup, D. Horde: A scalable real-time architecture for learning knowledge from unsupervised sensorimotor interaction. In Proceedings of the International Conference on Autonomous Agents and Multiagents Systems , 2011.
Tamar et al. (2016) Tamar, Aviv, Di Castro, Dotan, and Mannor, Shie. Learning the variance of the reward-to-go. Journal of Machine Learning Research , 17(13):1–36, 2016.
Tieleman & Hinton (2012) Tieleman, Tijmen and Hinton, Geoffrey. Lecture 6.5-rmsprop: Divide the gradient by a running average of its recent magnitude. COURSERA: Neural networks for machine learning , 4(2), 2012.
Toussaint & Storkey (2006) Toussaint, Marc and Storkey, Amos. Probabilistic inference for solving discrete and continuous state markov decision processes. In Proceedings of the International Conference on Machine Learning , 2006.
Tsitsiklis (2002) Tsitsiklis, John N. On the convergence of optimistic policy iteration. Journal of Machine Learning Research , 3:59–72, 2002.
Utgoff & Stracuzzi (2002) Utgoff, Paul E. and Stracuzzi, David J. Many-layered learning. Neural Computation , 14(10):2497–2529, 2002.
Van den Oord et al. (2016) Van den Oord, Aaron, Kalchbrenner, Nal, and Kavukcuoglu, Koray. Pixel recurrent neural networks. In Proceedings of the International Conference on Machine Learning , 2016.
van Hasselt et al. (2016) van Hasselt, Hado, Guez, Arthur, and Silver, David. Deep reinforcement learning with double Q-learning. In Proceedings of the AAAI Conference on Artificial Intelligence , 2016.
Veness et al. (2015) Veness, Joel, Bellemare, Marc G., Hutter, Marcus, Chua, Alvin, and Desjardins, Guillaume. Compress and control. In Proceedings of the AAAI Conference on Artificial Intelligence , 2015.
Wang et al. (2008) Wang, Tao, Lizotte, Daniel, Bowling, Michael, and Schuurmans, Dale. Dual representations for dynamic programming. Journal of Machine Learning Research , pp. 1–29, 2008.
Wang et al. (2016) Wang, Ziyu, Schaul, Tom, Hessel, Matteo, Hasselt, Hado van, Lanctot, Marc, and de Freitas, Nando. Dueling network architectures for deep reinforcement learning. In Proceedings of the International Conference on Machine Learning , 2016.
White (1988) White, D. J. Mean, variance, and probabilistic criteria in finite markov decision processes: a review. Journal of Optimization Theory and Applications , 56(1):1–29, 1988.
Appendix A Related Work
附录 A 相关工作
To the best of our knowledge, the work closest to ours are two papers (Morimura et al., 2010b; Morimura et al., 2010a) studying the distributional Bellman equation from the perspective of its cumulative distribution functions. The authors propose both parametric and nonparametric solutions to learn distributions for risk-sensitive reinforcement learning. They also provide some theoretical analysis for the policy evaluation setting, including a consistency result in the nonparametric case. By contrast, we also analyze the control setting, and emphasize the use of the distributional equations to improve approximate reinforcement learning.
据我们所知,与我们最接近的工作是两篇论文(Morimura et al., 2010b; Morimura et al., 2010a),它们从累积分布函数的角度研究分布贝尔曼方程。作者提出了参数化和非参数化的解法,用于为风险敏感强化学习学习分布。他们也为策略评估设定提供了一些理论分析,包括非参数情形下的一项一致性结果。相比之下,我们还分析了控制设定,并强调利用分布式方程来改进近似强化学习。
The variance of the return has been extensively studied in the risk-sensitive setting. Of note, Tamar et al. (2016) analyze the use of linear function approximation to learn this variance for policy evaluation, and Prashanth & Ghavamzadeh (2013) estimate the return variance in the design of a risk-sensitive actor-critic algorithm. Mannor & Tsitsiklis (2011) provides negative results regarding the computation of a variance-constrained solution to the optimal control problem.
回报的方差在风险敏感设定中已被广泛研究。值得注意的是,Tamar et al.(2016)分析了用线性函数近似在策略评估中学习这一方差,Prashanth & Ghavamzadeh(2013)则在设计风险敏感的演员-评论家算法时估计回报方差。Mannor & Tsitsiklis(2011)就计算带方差约束的最优控制问题给出了否定性结果。
The distributional formulation also arises when modelling uncertainty. Dearden et al. (1998) considered a Gaussian approximation to the value distribution, and modelled the uncertainty over the parameters of this approximation using a Normal-Gamma prior. Engel et al. (2005) leveraged the distributional Bellman equation to define a Gaussian process over the unknown value function. More recently, Geist & Pietquin (2010) proposed an alternative solution to the same problem based on unscented Kalman filters. We believe much of the analysis we provide here, which deals with the intrinsic randomness of the environment, can also be applied to modelling uncertainty.
当对不确定性建模时,也会出现分布表述。Dearden et al.(1998)考虑了对价值分布的高斯近似,并用 Normal-Gamma 先验对这一近似的参数不确定性建模。Engel et al.(2005)借助分布贝尔曼方程,在未知价值函数上定义了一个高斯过程。更近一些,Geist & Pietquin(2010)基于无迹卡尔曼滤波,为同一问题提出了另一种解法。我们相信,这里给出的、针对环境内在随机性的许多分析,也可以用于对不确定性建模。
Our work here is based on a number of foundational results, in particular concerning alternative optimality criteria. Early on, Jaquette (1973) showed that a moment optimality criterion, which imposes a total ordering on distributions, is achievable and defines a stationary optimal policy, echoing the second part of Theorem 1. Sobel (1982) is usually cited as the first reference to Bellman equations for the higher moments (but not the distribution) of the return. Chung & Sobel (1987) provides results concerning the convergence of the distributional Bellman operator in total variation distance. White (1988) studies “nonstandard MDP criteria” from the perspective of optimizing the state-action pair occupancy.
本文的工作建立在若干基础性结果之上,尤其是关于替代最优性准则的结果。较早时候,Jaquette(1973)表明,一种对分布施加全序的矩最优性准则是可达成的,并且定义了一个平稳最优策略,这与定理 1 的第二部分相呼应。Sobel(1982)通常被引为关于回报高阶矩(但不是分布)的贝尔曼方程的最早文献。Chung & Sobel(1987)给出了分布贝尔曼算子在全变差距离下收敛的有关结果。White(1988)从优化状态-动作对占有率的角度,研究了“非标准 MDP 准则”。
A number of probabilistic frameworks for reinforcement learning have been proposed in recent years. The planning as inference approach (Toussaint & Storkey, 2006; Hoffman et al., 2009) embeds the return into a graphical model, and applies probabilistic inference to determine the sequence of actions leading to maximal expected reward. Wang et al. (2008) considered the dual formulation of reinforcement learning, where one optimizes the stationary distribution subject to constraints given by the transition function (Puterman, 1994), in particular its relationship to linear approximation. Related to this dual is the Compress and Control algorithm Veness et al. (2015), which describes a value function by learning a return distribution using density models. One of the aims of this work was to address the question left open by their work of whether one could be design a practical distributional algorithm based on the Bellman equation, rather than Monte Carlo estimation.
近年来已有若干用于强化学习的概率框架被提出。把规划当作推理的方法(Toussaint & Storkey, 2006; Hoffman et al., 2009)把回报嵌入一个图模型,并应用概率推理来确定通向最大期望奖励的动作序列。Wang et al.(2008)考虑了强化学习的对偶表述,即在转移函数给出的约束下优化平稳分布(Puterman, 1994),尤其是它与线性近似的关系。与这一对偶相关的是 Compress and Control 算法(Veness et al., 2015),它通过用密度模型学习回报分布来描述价值函数。这项工作的目的之一,是回答他们留下的一个未决问题:能否设计一种基于贝尔曼方程、而不是蒙特卡洛估计的、实用的分布算法。
Appendix B Proofs
附录 B 证明
Lemma 1(Partition lemma).
Let be a set of random variables describing a partition of , i.e. and for any there is exactly one with . Let be two random variables. Then
引理 1(划分引理)。
设 是描述 的一个划分的一组随机变量,也就是 ,并且对任意 恰好有一个 满足 。设 是两个随机变量。则
Proof.
We will give the proof for , noting that the same applies to . Let and , respectively. First note that
证明。
我们将给出 时的证明,并指出同样的论证适用于 。分别设 以及 。首先注意到
Now, whenever . It follows that we can choose so that also whenever , without increasing the expected norm. Hence
现在,只要 ,就有 。由此可以选取 ,使得当 时也有 ,而不会增大期望范数。因此
Next, we claim that
接下来,我们断言
$$\displaystyle\inf_{U,V}\sum\nolimits_{i}\Pr{A_{i}=1}\expect\Big[\big|A_{i}U-A_{i}V\big|^{p},|,A_{i}=1\Big] \ \displaystyle\hskip 20.00003pt\leq\inf_{\begin{subarray}{c}Y_{1},Y_{2},\dots\
Z_{1},Z_{2},\dots\end{subarray}}\sum\nolimits_{i}\Pr{A_{i}=1}\expect\Big[|Y_{i}-Z_{i}\big|^{p},|,A_{i}=1\Big]. \tag{9}$$
Specifically, the left-hand side of the equation is an infimum over all r.v.’s whose cumulative distributions are and , respectively, while the right-hand side is an infimum over sequences of r.v’s and whose cumulative distributions are , respectively. To prove this upper bound, consider the c.d.f. of :
具体来说,方程左边是对累积分布分别为 和 的所有随机变量取下确界,而右边是对累积分布分别为 的随机变量序列 和 取下确界。为证明这一上界,考虑 的累积分布:
Hence the distribution is equivalent, in an almost sure sense, to one that first picks an element of the partition, then picks a value for conditional on the choice . On the other hand, the c.d.f. of is
因此,分布 在几乎必然的意义上,等价于先选取划分中的一个元素 ,再在选定 的条件下选取 的取值。另一方面, 的累积分布是
Thus the right-hand side infimum in (9) has the additional constraint that it must preserve the conditional c.d.fs, in particular when . Put another way, instead of having the freedom to completely reorder the mapping , we can only reorder it within each element of the partition. We now write
于是 (9) 右边的下确界有额外的约束:它必须保持条件累积分布,尤其是当 时。换一种说法,我们不再有完全重排映射 的自由,而只能在划分的每个元素内部重排。现在我们写
where (a) follows because is a partition. Using (9), this implies
其中 (a) 成立是因为 是一个划分。利用 (9),这蕴含
$$\displaystyle d^{p}{p}(U,V) \ \displaystyle\hskip-35.00005pt=\inf{U,V}\sum\nolimits_{i}\Pr{A_{i}=1}\expect\Big[\big|A_{i}U-A_{i}V\big|^{p},|,A_{i}=1\Big] \ \displaystyle\hskip-35.00005pt\leq\inf_{\begin{subarray}{c}Y_{1},Y_{2},\dots\
Z_{1},Z_{2},\dots\end{subarray}}\sum\nolimits_{i}\Pr{A_{i}=1}\expect\Big[\big|Y_{i}-Z_{i}\big|^{p},|,A_{i}=1\Big] \ \displaystyle\hskip-35.00005pt\overset{(b)}{=}\sum\nolimits_{i}\inf_{Y_{i},Z_{i}}\Pr{A_{i}=1}\expect\Big[\big|Y_{i}-Z_{i}\big|^{p},|,A_{i}=1\Big] \ \displaystyle\hskip-35.00005pt\overset{(c)}{=}\sum\nolimits_{i}d_{p}(A_{i}U,A_{i}V),$$
because in (b) the individual components of the sum are independently minimized; and (c) from (8). ∎
因为在 (b) 中,和式的各个分量被独立地最小化;而 (c) 来自 (8)。∎
Lemma 2.
is a metric over value distributions.
引理 2。
是价值分布上的一个度量。
Proof.
The only nontrivial property is the triangle inequality. For any value distribution , write
证明。
唯一非平凡的性质是三角不等式。对任意价值分布 ,写
where in (a) we used the triangle inequality for . ∎
其中在 (a) 中我们使用了 的三角不等式。∎
Lemma 3.
is a -contraction in .
引理 3。
在 下是一个 -压缩映射。
Proof.
Consider . By definition,
证明。
考虑 。根据定义,
By the properties of , we have
由 的性质,我们有
where the last line follows from the definition of (see (4)). Combining with (10) we obtain
其中最后一行由 的定义得出(见 (4))。与 (10) 结合,我们得到
Proposition 1(Sobel, 1982).
Consider two value distributions , and write to be the vector of variances of . Then
命题 1(Sobel, 1982)。
考虑两个价值分布 ,并把 写成 的方差组成的向量。则
Proof.
The first statement is standard, and its proof follows from , where the second denotes the usual operator over value functions. Now, by independence of and :
证明。
第一条陈述是标准的,其证明由 得出,这里第二个 表示通常作用于价值函数的算子。现在,由 与 的独立性:
And now
于是现在
Lemma 4.
Let . Then
引理 4。
设 。则
and in particular $\expect Z_{k}\to Q^{}$ exponentially quickly.*
并且特别地, 会指数快速地收敛到 $Q^{}$。*
Proof.
The proof follows by linearity of expectation. Write for the distributional operator and for the usual operator. Then
证明。
证明由期望的线性性得出。把 写成分布算子,把 写成通常的算子。则
Theorem 1(Convergence in the control setting).
Let with . Let be measurable and suppose that is finite. Then
定理 1(控制设定中的收敛性)。
设 ,且 。设 是可测的,并假定 是有限的。则
If is finite, then converges to uniformly. Furthermore, if there is a total ordering on $\Pi^{}Z^{}\in\mathcal{Z}^{}$,*
如果 是有限的,则 一致地收敛到 。此外,如果 $\Pi^{}\precZ^{}\in\mathcal{Z}^{}$,*
then has a unique fixed point $Z^{}\in\mathcal{Z}^{}$.
则 有唯一的不动点 $Z^{}\in\mathcal{Z}^{}$。
The gist of the proof of Theorem 1 consists in showing that for every state , there is a time after which the greedy policy w.r.t. is mostly optimal. To clearly expose the steps involved, we will first assume a unique (and therefore deterministic) optimal policy , and later return to the general case; we will denote the optimal action at by . For notational convenience, we will write and . Let and let . We first define the set of states whose values must be sufficiently close to at time :
定理 1 证明的要点在于表明:对每一个状态 ,都存在一个时刻 ,在此之后关于 的贪心策略大体上是最优的。为了把所涉及的步骤交代清楚,我们将先假定存在唯一(因而也是确定性的)最优策略 ,稍后再回到一般情形;我们把 处的最优动作记为 。为记号方便,我们写 以及 。设 ,并设 。我们首先定义状态集合 ,这些状态的价值在时刻 必须已经充分接近 :
Indeed, by Lemma 4, we know that after iterations
的确,由引理 4,我们知道在 次迭代之后
For , write . For any , we deduce that
对 ,写 。对任意 ,我们推出
It follows that if , then also for all : for these states, the greedy policy corresponds to the optimal policy .
由此可知,若 ,则对所有 也有 :对这些状态,贪心策略 与最优策略 相一致。
Lemma 5.
For each there exists a such that, for all , , and in particular $\argmax_{a}Q_{k}(x,a)=\pi^{}(x)$.*
引理 5。
对每个 ,都存在一个 ,使得对所有 ,都有 ,并且特别地 $\argmax_{a}Q_{k}(x,a)=\pi^{}(x)$。*
Proof.
Because is finite, the gap
证明。
因为 是有限的,间隙
is attained for some strictly positive . By definition, there exists a such that
对某个严格为正的 被达到。根据定义,存在一个 ,使得
and hence every must eventually be in . ∎
因此每一个 最终都必须进入 。∎
This lemma allows us to guarantee the existence of an iteration after which sufficiently many states are well-behaved, in the sense that the greedy policy at those states chooses the optimal action. We will call these states “solved”. We in fact require not only these states to be solved, but also most of their successors, and most of the successors of those, and so on. We formalize this notion as follows: fix some , let , and define for the set
这条引理使我们能够保证存在一次迭代 ,在此之后足够多的状态已经表现良好,也就是说,这些状态上的贪心策略会选择最优动作。我们将称这些状态为“已解决的”。实际上,我们不仅要求这些状态已解决,还要求它们的大多数后继、以及那些后继的大多数后继,以此类推,也都已解决。我们把这一概念形式化如下:固定某个 ,设 ,并对 定义集合
As the following lemma shows, any is eventually contained in the recursively-defined sets , for any .
如下面的引理所示,对任意 ,任何一个 最终都会被包含在递归定义的集合 中。
Lemma 6.
For any and any , there exists a such that for all , .
引理 6。
对任意 和任意 ,都存在一个 ,使得对所有 ,都有 。
Proof.
Fix and let us suppose that . By Lemma 5, this is true for . We infer that for any probability measure on , . In particular, for a given , this implies that
证明。
固定 ,并假定 。由引理 5,这对 成立。我们由此推断,对 上的任意概率测度 ,都有 。特别地,对给定的 ,这蕴含
Therefore, for any , there exists a time after which it is and remains a member of , the set of states for which . We conclude that also. The statement follows by induction. ∎
因此,对任意 ,都存在一个时刻,在此之后它进入并保持在 中,也就是满足 的状态集合。我们得出 同样成立。该陈述由归纳得出。∎
Proof of Theorem 1.
The proof is similar to policy iteration-type results, but requires more care in dealing with the metric and the possibly infinite state space. We will write , define similarly and with some overload of notation write . Finally, let and .
定理 1 的证明。
证明与策略迭代类结果相似,但在处理度量和可能无限的状态空间时需要更加小心。我们将写 ,对 做类似定义,并在稍稍滥用记号的情况下写 。最后,设 以及 。
Fix and . We begin by using Lemma 1 to separate the transition from into a solved term and an unsolved term:
固定 以及 。我们首先用引理 1,把从 出发的转移分成已解决项和未解决项:
where is the random successor from taking action , and we write to ease the notation. Similarly,
其中 是采取动作 后的随机后继,并且为简化记号我们写 。类似地,
Now
现在
where in we used Properties P1 and P2 of the Wasserstein metric, and in (b) we separate states for which from the rest using Lemma 1 ( form a partition of ). Let . From property P3 of the Wasserstein metric, we have
其中在 中我们使用了 Wasserstein 度量的性质 P1 和 P2,在 (b) 中我们用引理 1 把 的状态与其余状态分开( 构成 的一个划分)。设 。由 Wasserstein 度量的性质 P3,我们有
Recall that is the largest attainable . Since also by our choice of , we can upper bound the second term in (12) by . This yields
回想 是可达到的最大 。又因为由我们对 的选取有 ,我们可以把 (12) 中的第二项上界为 。这给出
By induction on , we conclude that for and some random state steps forward,
通过对 做归纳,我们得出:对 以及某个向前 步的随机状态 ,
Hence for any , , we can take , , and finally large enough to make . The proof then extends to by considering one additional application of .
因此,对任意 、,我们可以取足够大的 、,最后再取足够大的 ,使得 。证明随后通过对 再应用一次,扩展到 。
We now consider the more general case where there are multiple optimal policies. We expand the definition of as follows:
我们现在考虑存在多个最优策略的更一般情形。我们把 的定义扩展如下:
Because there are finitely many actions, Lemma 6 also holds for this new definition. As before, take , but now consider the sequence of greedy policies selected by successive applications of , and write
因为动作是有限多个,引理 6 对这一定义同样成立。和前面一样,取 ,但现在考虑由连续应用 选出的贪心策略序列 ,并写
such that
使得
Now denote by the set of nonstationary optimal policies. If we take any , we deduce that
现在把 记为非平稳最优策略的集合。如果我们取任意 ,我们推出
since corresponds to some optimal policy and is optimal along most of the trajectories from . In effect, is close to the value distribution of the nonstationary optimal policy . Now for this ,
因为 对应于某个最优策略 ,并且 沿着从 出发的大多数轨迹是最优的。实际上, 接近于非平稳最优策略 的价值分布。现在对这个 ,
using the same argument as before with the newly-defined . It follows that
这里用到了与前面相同的论证,以及新定义的 。由此可得
When is finite, there exists a fixed after which . The uniform convergence result then follows.
当 有限时,存在一个固定的 ,在此之后 。一致收敛的结果随之得出。
To prove the uniqueness of the fixed point when selects its actions according to the ordering , we note that for any optimal value distribution , its set of greedy policies is . Denote by the policy coming first in the ordering over . Then , which has a unique fixed point (Section 3.3). ∎
为证明当 按照序 选择动作时不动点 的唯一性,我们注意到:对任意最优价值分布 ,其贪心策略集合都是 。把 记为 上排序最靠前的策略。于是 ,它有唯一的不动点(第 3.3 节)。∎
Proposition 4.
That has a fixed point $Z^{}=\mathcal{T}Z^{}{Z_{k}}\mathcal{Z}^{}$.*
命题 4。
有一个不动点 $Z^{}=\mathcal{T}Z^{}{Z_{k}}\mathcal{Z}^{}$。*
We provide here a sketch of the result. Consider a single state with two actions, and (Figure 8). The first action yields a reward of , while the other either yields or with equal probability, and both actions are optimal. Now take and write for the received rewards. Consider a stochastic policy that takes action with probability . For , the return is
我们在这里给出这一结果的概要。考虑单个状态 和两个动作 与 (图 8)。第一个动作给出奖励 ,另一个动作则以相等的概率给出 或 ,并且两个动作都是最优的。现在取 ,并把收到的奖励写成 。考虑一个以概率 采取动作 的随机策略。当 时,回报是
For , on the other hand, the return is random and is given by the following fractional number (in binary):
另一方面,当 时,回报是随机的,并由下面这个(二进制)分数给出:
As a result, is uniformly distributed between and ! In fact, note that
结果是, 在 和 之间均匀分布!实际上,注意到
For some intermediary value of , we obtain a different probability of the different digits, but always putting some probability mass on all returns in .
对某个中间的 值,我们会得到不同数位上不同的概率,但总是会在 中的所有回报上放置一些概率质量。
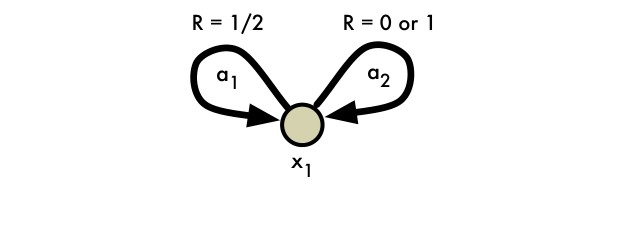
Figure 8: A simple example illustrating the effect of a nonstationary policy on the value distribution.
图 8:一个简单例子,说明非平稳策略对价值分布的影响。
Now suppose we follow the nonstationary policy that takes on the first step, then from there on. By inspection, the return will be uniformly distributed on the interval , which does not correspond to the return under any value of . But now we may imagine an operator which alternates between and depending on the exact value distribution it is applied to, which would in turn converge to a nonstationary optimal value distribution.
现在假定我们遵循如下非平稳策略:第一步采取 ,此后一直采取 。通过直接观察,回报将在区间 上均匀分布,这并不对应于任何一个 值下的回报。但现在我们可以设想一个算子 ,它根据被作用的价值分布的精确取值,在 和 之间交替,从而会收敛到一个非平稳的最优价值分布。
Lemma 7(Sample Wasserstein distance).
Let be a collection of random variables, a random index independent from , and consider the mixture random variable . For any random variable independent of ,
引理 7(样本 Wasserstein 距离)。
设 是一组随机变量, 是一个与 独立的随机指标,并考虑混合随机变量 。对任意与 独立的随机变量 ,
and in general the inequality is strict and
并且一般而言该不等式是严格的,而且
Proof.
We prove this using Lemma 1. Let . We write
证明。
我们用引理 1 来证明这一点。设 。我们写
\displaystyle d_{p}(P,Q) \\ \displaystyle=d_{p}(P_{I},Q) \\ \displaystyle=d_{p}\Big(\sum\nolimits_{i}A_{i}P_{i},\sum\nolimits_{i}A_{i}Q\Big) \\ \displaystyle\leq\sum\nolimits_{i}d_{p}(A_{i}P_{i},A_{i}Q) \\ \displaystyle\leq\sum\nolimits_{i}\Pr\{I=i\}d_{p}(P_{i},Q) \\ \displaystyle=\expect\nolimits_{I}d_{P}(P_{i},Q).
where in the penultimate line we used the independence of from and to appeal to property P3 of the Wasserstein metric.
其中在倒数第二行,我们利用 与 和 的独立性,援用了 Wasserstein 度量的性质 P3。
To show that the bound is in general strict, consider the mixture distribution depicted in Figure 9. We will simply consider the metric between this distribution and another distribution . The first distribution is
为表明这一界一般是严格的,考虑图 9 中画出的混合分布。我们将简单地考虑这一分布 与另一分布 之间的 度量。第一个分布是
$$P=\left{\begin{array}[]{ll}0&\text{w.p. }1/2\
1&\text{w.p. }1/2.\end{array}\right.$$
In this example, , , and . Now consider the distribution with the same support but that puts probability on :
在这个例子中,,,并且 。现在考虑支撑相同、但在 上放置概率 的分布:
$$Q=\left{\begin{array}[]{ll}0&\text{w.p. }p\
1&\text{w.p. }1-p.\end{array}\right.$$
The distance between and is
与 之间的距离是
This is for , and strictly less than for any other values of . On the other hand, the corresponding expected distance (after sampling an outcome or with equal probability) is
当 时,这就是 ;对其余任意 值,则严格小于 。另一方面,相应的期望距离(在以相等概率抽样结果 或 之后)是
\expect\nolimits_{I}d_{1}(P_{i},Q)=\tfrac{1}{2}p+\tfrac{1}{2}(1-p)=\tfrac{1}{2}.
Hence d_{1}(P,Q)<\expect\nolimits_{I}d_{1}(P_{i},Q) for . This shows that the bound is in general strict. By inspection, it is clear that the two gradients are different. ∎
因此当 时,d_{1}(P,Q)<\expect\nolimits_{I}d_{1}(P_{i},Q)。这表明这一界一般是严格的。通过直接观察可以清楚看出,两个梯度是不同的。∎
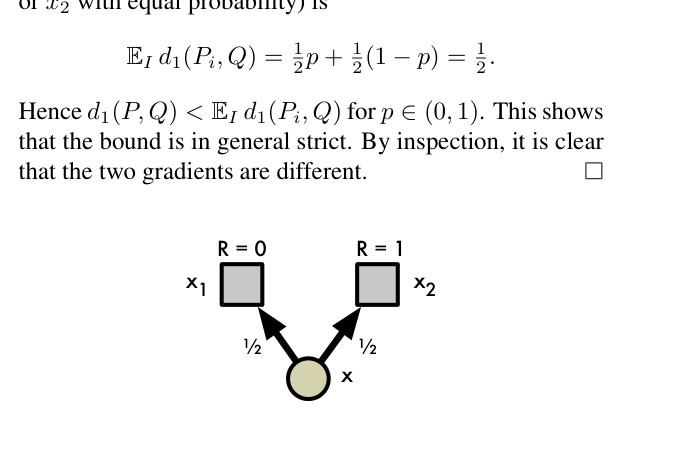
Figure 9: Example MDP in which the expected sample Wasserstein distance is greater than the Wasserstein distance.
图 9:一个示例 MDP,其中期望的样本 Wasserstein 距离大于 Wasserstein 距离。
Proposition 5.
Fix some next-state distribution and policy . Consider a parametric value distribution , and and define the Wasserstein loss
命题 5。
固定某个下一状态分布 和策略 。考虑参数化的价值分布 ,并定义 Wasserstein 损失
Let and and consider the sample loss
设 以及 ,并考虑样本损失
Its expectation is an upper bound on the loss :
它的期望是损失 的一个上界:
in general with strict inequality.
并且一般而言不等式是严格的。
The result follows directly from the previous lemma.
这一结果直接由前一条引理得出。
Appendix C Algorithmic Details
附录 C 算法细节
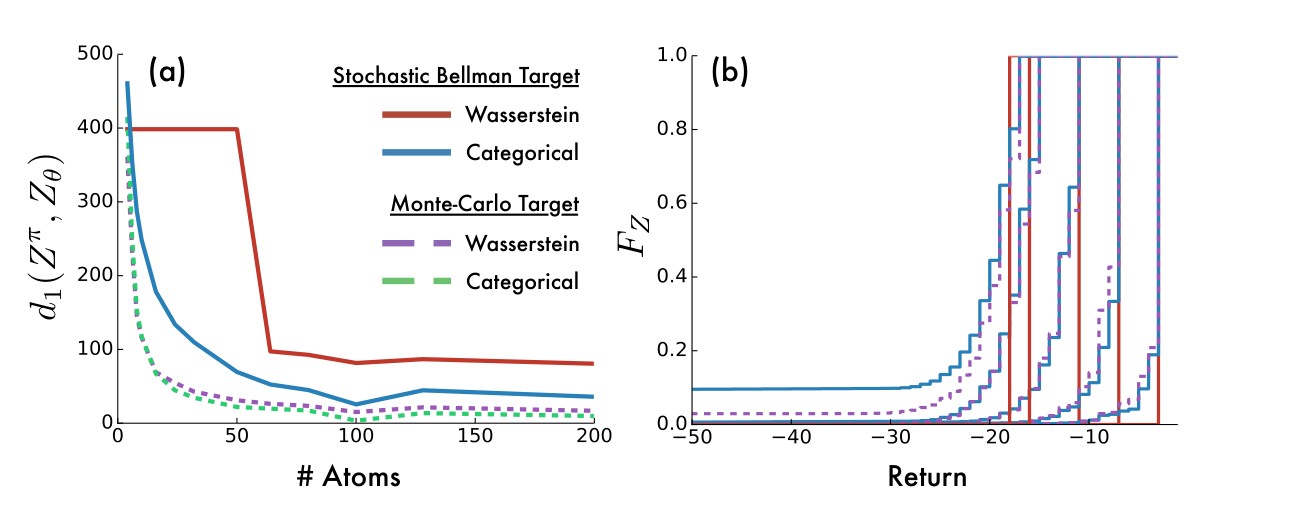
Figure 10: (a) Wasserstein distance between ground truth distribution and approximating distributions . Varying number of atoms in approximation, training target, and loss function. (b) Approximate cumulative distributions for five representative states in CliffWalk.
图 10:(a) 真实分布 与近似分布 之间的 Wasserstein 距离。变化的是近似中的原子数、训练目标以及损失函数。(b) CliffWalk 中五个代表性状态的近似累积分布。
While our training regime closely follows that of DQN (Mnih et al., 2015), we use Adam (Kingma & Ba, 2015) instead of RMSProp (Tieleman & Hinton, 2012) for gradient rescaling. We also performed some hyperparameter tuning for our final results. Specifically, we evaluated two hyperparameters over our five training games and choose the values that performed best. The hyperparameter values we considered were and , where is the minibatch size. We found and performed best. We used the same step-size value as DQN ().
虽然我们的训练安排紧密沿用 DQN(Mnih et al., 2015),但我们用 Adam(Kingma & Ba, 2015)而不是 RMSProp(Tieleman & Hinton, 2012)来做梯度缩放。我们也为最终结果做了一些超参数调优。具体来说,我们在五款训练游戏上评估了两个超参数,并选取表现最好的取值。我们考虑的超参数取值是 以及 ,其中 是小批量大小。我们发现 和 表现最好。我们使用了与 DQN 相同的步长()。
Pseudo-code for the categorical algorithm is given in Algorithm 1. We apply the Bellman update to each atom separately, and then project it into the two nearest atoms in the original support. Transitions to a terminal state are handled with .
分类算法的伪代码在算法 1 中给出。我们对每个原子分别应用贝尔曼更新,再把它投影到原先支撑中最近的两个原子上。转移到终止状态时用 处理。
Appendix D Comparison of Sampled Wasserstein Loss and Categorical Projection
附录 D 抽样 Wasserstein 损失与分类投影的比较
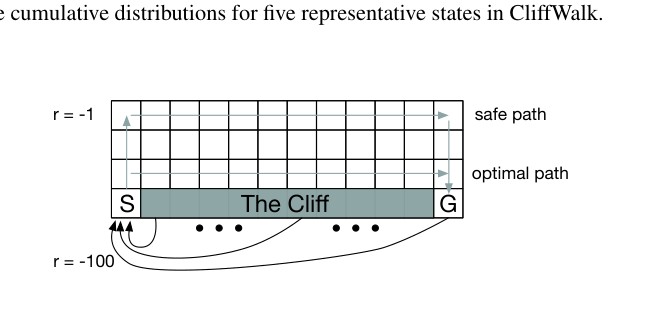
Figure 11: CliffWalk Environment (Sutton & Barto, 1998).
图 11:CliffWalk 环境(Sutton & Barto, 1998)。
Lemma 3 proves that for a fixed policy the distributional Bellman operator is a -contraction in , and therefore that will converge in distribution to the true distribution of returns . In this section, we empirically validate these results on the CliffWalk domain shown in Figure 11. The dynamics of the problem match those given by Sutton & Barto (1998). We also study the convergence of the distributional Bellman operator under the sampled Wasserstein loss and the categorical projection (Equation 7) while following a policy that tries to take the safe path but has a 10% chance of taking another action uniformly at random.
引理 3 证明,对固定策略 ,分布贝尔曼算子在 下是一个 -压缩映射,因此 会在分布上收敛到真实的回报分布 。在这一节中,我们在图 11 所示的 CliffWalk 域上对这些结果做经验验证。问题的动态与 Sutton & Barto(1998)给出的相同。我们还研究了分布贝尔曼算子在抽样 Wasserstein 损失和分类投影(方程 7)下的收敛,所遵循的策略试图走安全路径,但有 10% 的概率均匀随机地采取另一个动作。
We compute a ground-truth distribution of returns using Monte-Carlo (MC) rollouts from each state. We then perform two experiments, approximating the value distribution at each state with our discrete distributions.
我们从每个状态做 次蒙特卡洛(MC)展开,计算出真实的回报分布 。随后我们做两个实验,用我们的离散分布来近似每个状态上的价值分布。
In the first experiment, we perform supervised learning using either the Wasserstein loss or categorical projection (Equation 7) with cross-entropy loss. We use as the supervised target and perform sweeps over all states to ensure both approaches have converged. In the second experiment, we use the same loss functions, but the training target comes from the one-step distributional Bellman operator with sampled transitions. We use and .[^4] For the sample updates we perform 10 times as many sweeps over the state space. Fundamentally, these experiments investigate how well the two training regimes (minimizing the Wasserstein or categorical loss) minimize the Wasserstein metric under both ideal (supervised target) and practical (sampled one-step Bellman target) conditions.
在第一个实验中,我们分别用 Wasserstein 损失,或带交叉熵损失的分类投影(方程 7),做监督学习。我们以 作为监督目标,并对所有状态做 轮扫描,以确保两种方法都已收敛。在第二个实验中,我们使用同样的损失函数,但训练目标来自带抽样转移的一步分布贝尔曼算子。我们使用 和 。[^4] 对样本更新,我们对状态空间做十倍次数的扫描。从根本上说,这些实验考察两种训练安排(最小化 Wasserstein 损失或分类损失)在理想(监督目标)和实际(抽样的一步贝尔曼目标)条件下,能把 Wasserstein 度量最小化到什么程度。
In Figure 10a we show the final Wasserstein distance between the learned distributions and the ground-truth distribution as we vary the number of atoms. The graph shows that the categorical algorithm does indeed minimize the Wasserstein metric in both the supervised and sample Bellman setting. It also highlights that minimizing the Wasserstein loss with stochastic gradient descent is in general flawed, confirming the intuition given by Proposition 5. In repeat experiments the process converged to different values of , suggesting the presence of local minima (more prevalent with fewer atoms).
在图 10a 中,我们展示了在改变原子数时,学到的分布与真实分布之间的最终 Wasserstein 距离 。该图表明,分类算法在监督设定和抽样贝尔曼设定中,的确都在最小化 Wasserstein 度量。它也突出表明,用随机梯度下降来最小化 Wasserstein 损失一般是有缺陷的,这证实了命题 5 给出的直觉。在重复实验中,这一过程会收敛到不同的 取值,暗示存在局部极小值(在原子更少时更为常见)。
Figure 10 provides additional insight into why the sampled Wasserstein distance may perform poorly. Here, we see the cumulative densities for the approximations learned under these two losses for five different states along the safe path in CliffWalk. The Wasserstein has converged to a fixed-point distribution, but not one that captures the true (Monte Carlo) distribution very well. By comparison, the categorical algorithm captures the variance of the true distribution much more accurately.
图 10 为抽样 Wasserstein 距离可能表现不佳提供了进一步的洞察。在这里,我们看到在这两种损失下、对 CliffWalk 安全路径上五个不同状态所学到的近似累积密度。Wasserstein 已经收敛到一个不动点分布,但并不是一个能很好地捕捉真实(蒙特卡洛)分布的分布。相比之下,分类算法对真实分布的方差捕捉要准确得多。
Appendix E Supplemental Videos and Results
附录 E 补充视频与结果
In Figure 13 we provide links to supplemental videos showing the C51 agent during training on various Atari 2600 games. Figure 12 shows the relative performance of C51 over the course of training. Figure 14 provides a table of evaluation results, comparing C51 to other state-of-the-art agents. Figures 15–18 depict particularly interesting frames.
在图 13 中,我们提供了补充视频的链接,展示 C51 智能体在若干 Atari 2600 游戏上训练过程中的表现。图 12 展示了 C51 在训练过程中的相对表现。图 14 给出一张评估结果表,把 C51 与其他最先进的智能体做比较。图 15–18 画出了一些特别有意思的帧。
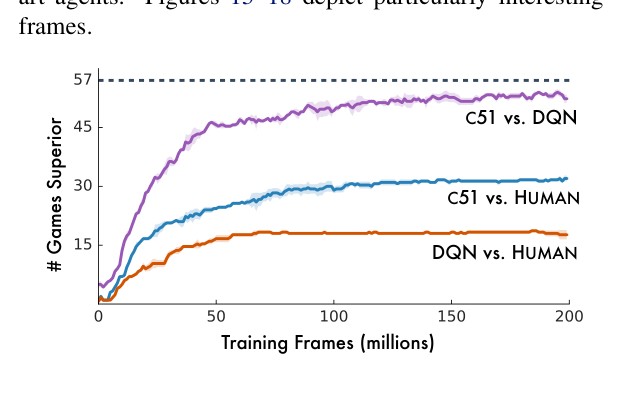
Figure 12: Number of Atari games where an agent’s training performance is greater than a baseline (fully trained DQN & human). Error bands give standard deviations, and averages are over number of games.
图 12:智能体训练表现超过基线(充分训练的 DQN 与人类)的 Atari 游戏数量。误差带给出标准差,平均值按游戏数量计算。
Figure 13: Supplemental videos of C51 during training.
图 13:C51 训练过程的补充视频。
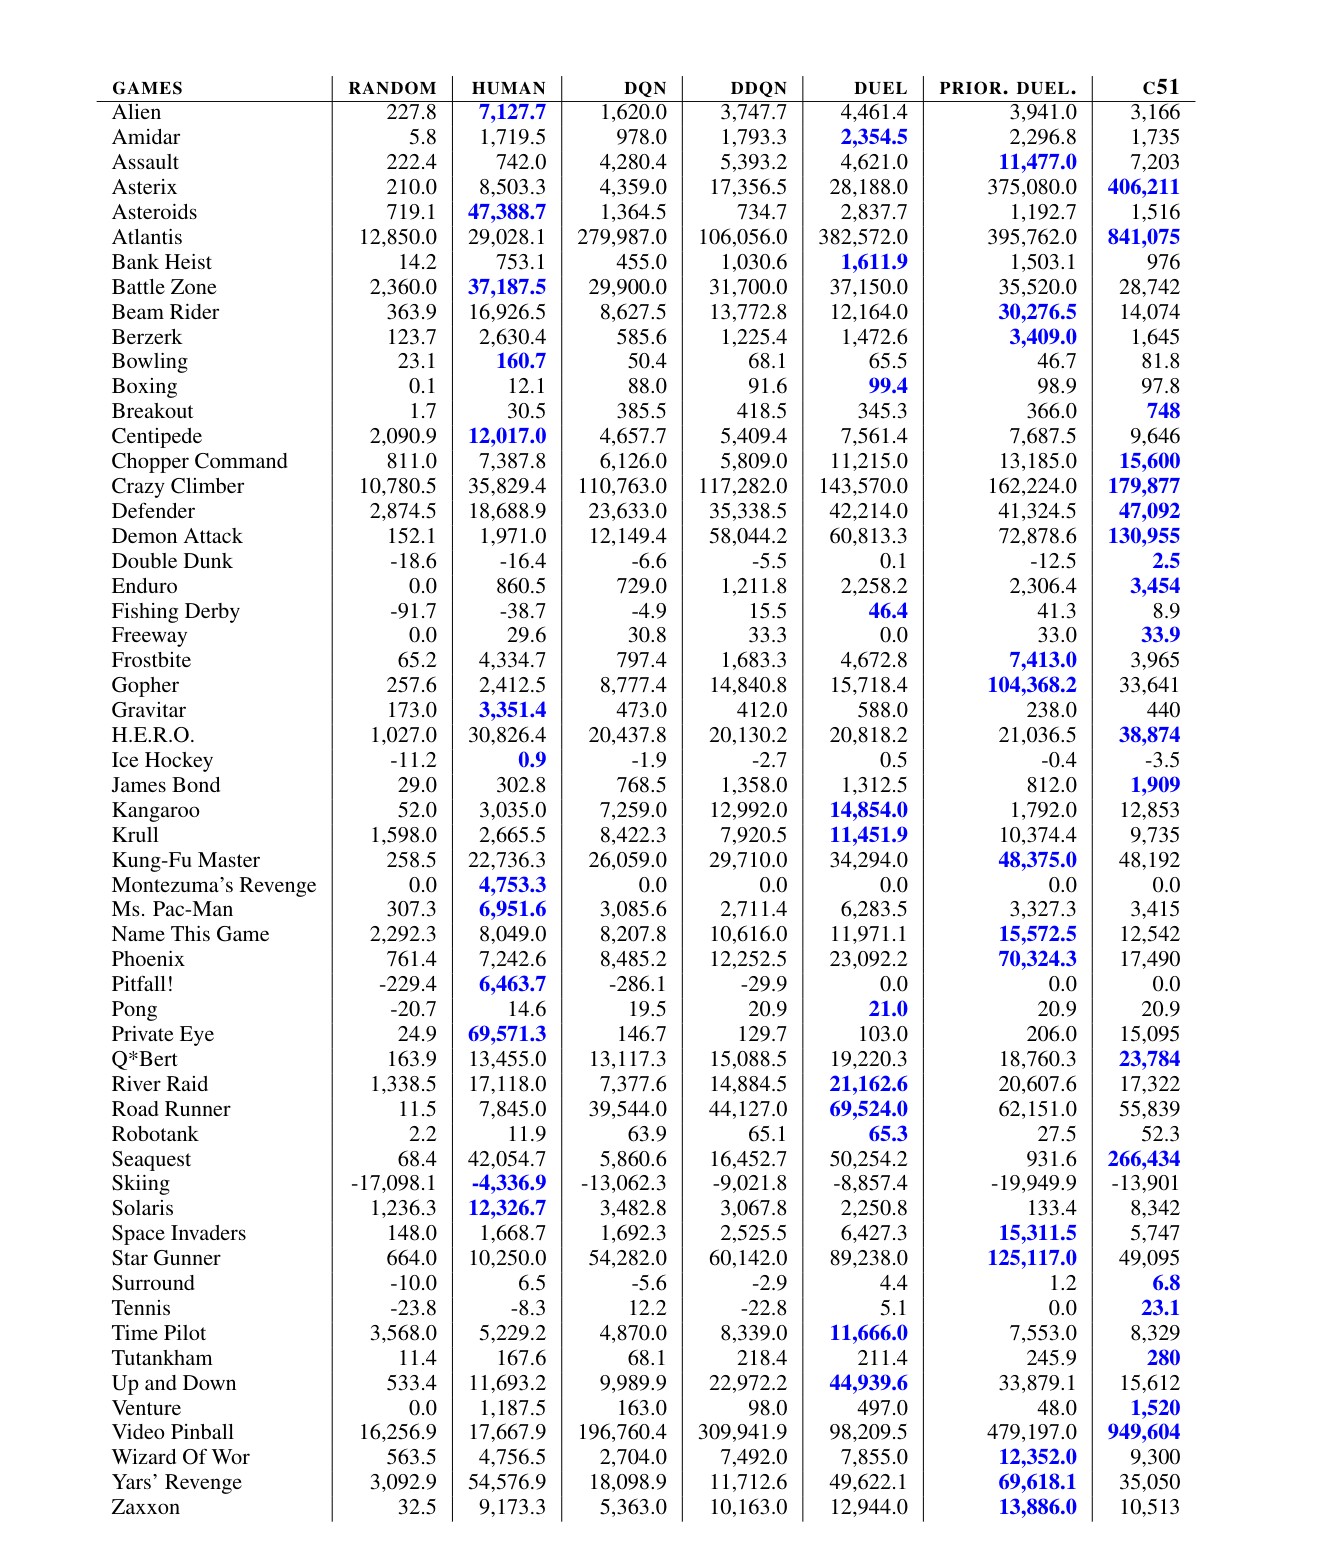
Figure 14: Raw scores across all games, starting with 30 no-op actions. Reference values from Wang et al. (2016).
图 14:全部游戏在以 30 步空操作起步时的原始分数。参考值来自 Wang et al.(2016)。
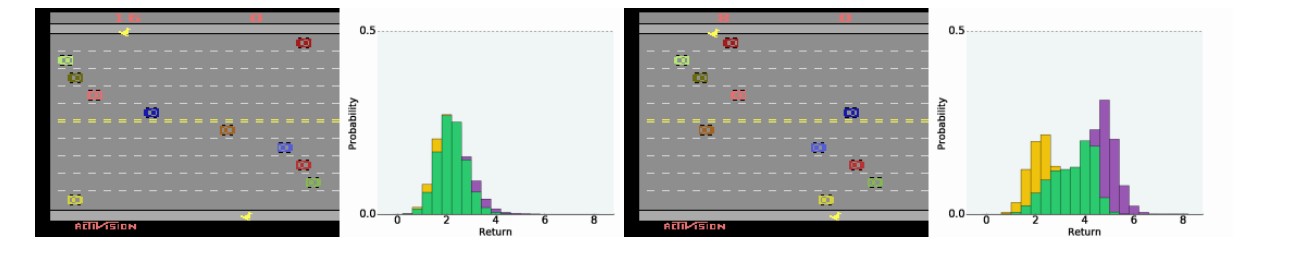
Figure 15: Freeway: Agent differentiates action-value distributions under pressure.
图 15:Freeway:智能体在压力下区分动作价值分布。
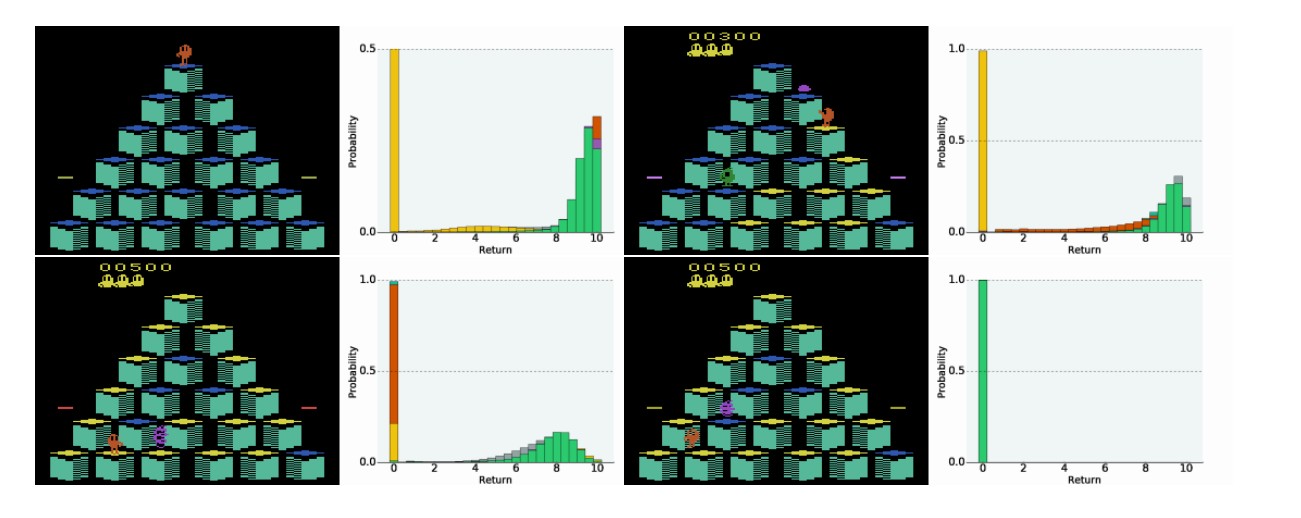
Figure 16: Q*Bert: Top, left and right: Predicting which actions are unrecoverably fatal. Bottom-Left: Value distribution shows steep consequences for wrong actions. Bottom-Right: The agent has made a huge mistake.
图 16:Q*Bert:上、左、右:预测哪些动作是不可挽回的致命动作。左下:价值分布显示出错误动作会带来陡峭的后果。右下:智能体已经铸成大错。
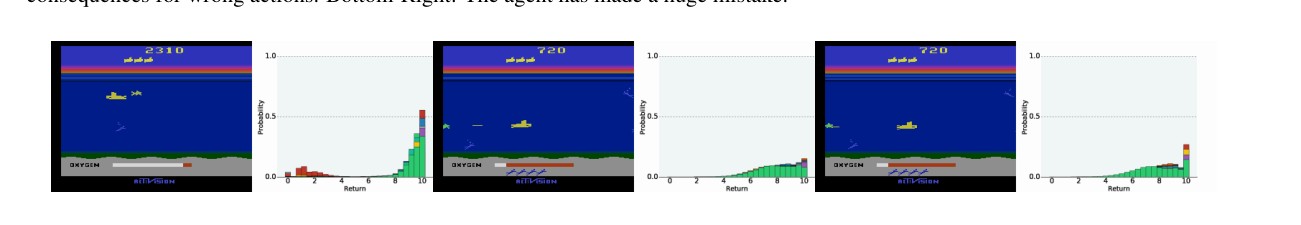
Figure 17: Seaquest: Left: Bimodal distribution. Middle: Might hit the fish. Right: Definitely going to hit the fish.
图 17:Seaquest:左:双峰分布。中:可能会撞到鱼。右:肯定会撞到鱼。
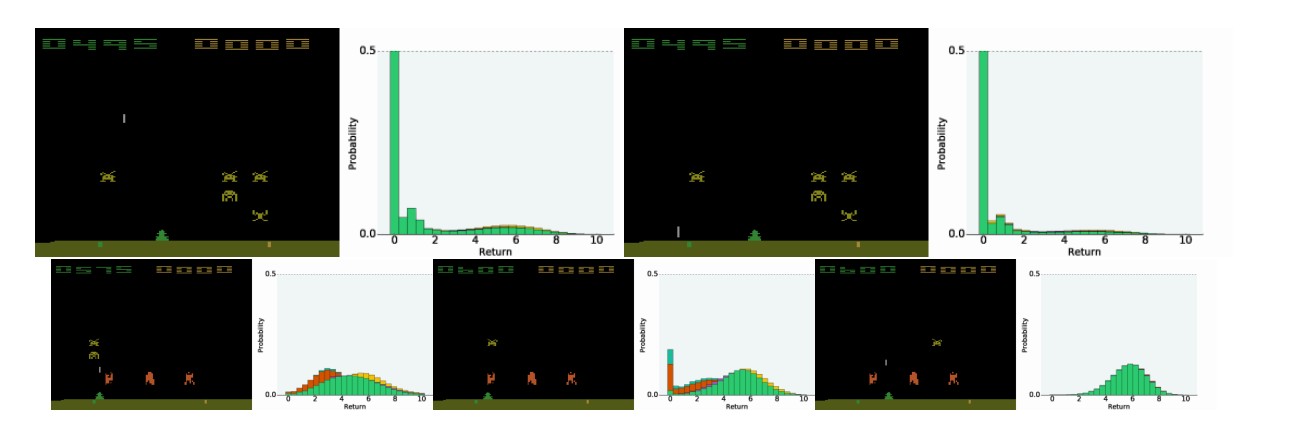
Figure 18: Space Invaders: Top-Left: Multi-modal distribution with high uncertainty. Top-Right: Subsequent frame, a more certain demise. Bottom-Left: Clear difference between actions. Bottom-Middle: Uncertain survival. Bottom-Right: Certain success.
图 18:太空侵略者:左上:带有高度不确定性的多峰分布。右上:随后一帧,更为确定的覆灭。左下:动作之间有清楚的差别。中下:生存不确定。右下:成功已确定。
Footnotes
脚注
† Equal contribution.
[^1] Algorithm 1 computes this projection in time linear in .
[^2] For , our TensorFlow implementation trains at roughly 75% of DQN’s speed.
[^3] Video: http://youtu.be/yFBwyPuO2Vg.
† The UNREAL results are not altogether comparable, as they were generated in the asynchronous setting with per-game hyperparameter tuning (Jaderberg et al., 2017).
[^4] Because there is a small probability of larger negative returns, some approximation error is unavoidable. However, this effect is relatively negligible in our experiments.
† 同等贡献。
[^1] 算法 1 用与 成线性的时间计算这一投影。
[^2] 对 ,我们的 TensorFlow 实现训练速度大约是 DQN 的 75%。
[^3] 视频:http://youtu.be/yFBwyPuO2Vg。
† UNREAL 的结果并不完全可比较,因为它们是在异步设定下、并对每款游戏单独调超参数得到的(Jaderberg et al., 2017)。
[^4] 因为存在较小概率出现更大幅度的负回报,一些近似误差不可避免。不过,这一影响在我们的实验中相对可以忽略。