Large Scale GAN Training for High Fidelity Natural Image Synthesis
Large Scale GAN Training for High Fidelity Natural Image Synthesis
Andrew Brock Thanks: Work done at DeepMind Thanks: Equal contribution Affiliation: Heriot-Watt University Email: ajb5@hw.ac.uk Jeff Donahue 2 2 footnotemark: 2 Affiliation: DeepMind Email: jeffdonahue@google.com Karen Simonyan 2 2 footnotemark: 2 Affiliation: DeepMind Email: simonyan@google.com
Abstract
Despite recent progress in generative image modeling, successfully generating high-resolution, diverse samples from complex datasets such as ImageNet remains an elusive goal. To this end, we train Generative Adversarial Networks at the largest scale yet attempted, and study the instabilities specific to such scale. We find that applying orthogonal regularization to the generator renders it amenable to a simple “truncation trick,” allowing fine control over the trade-off between sample fidelity and variety by reducing the variance of the Generator’s input. Our modifications lead to models which set the new state of the art in class-conditional image synthesis. When trained on ImageNet at 128128 resolution, our models (BigGANs) achieve an Inception Score (IS) of 166.5 and Fréchet Inception Distance (FID) of 7.4, improving over the previous best IS of 52.52 and FID of 18.65.
尽管生成式图像建模近年进步明显,在 ImageNet 这类复杂数据上稳定产出高分辨率、多样样本仍很难。我们把生成对抗网络训到迄今最大规模,并专门研究这一尺度特有的不稳定。发现对生成器加正交正则后,它能接受简单的「截断技巧」:压低生成器输入方差,即可精细权衡样本保真与多样性。这些改动把类别条件图像合成推到新的技术水平。在 ImageNet 128×128 上,我们的模型(BigGAN)Inception Score(IS)达 166.5、Fréchet Inception Distance(FID)为 7.4,优于此前最佳 IS 52.52 与 FID 18.65。
1 Introduction
Figure 1: Class-conditional samples generated by our model.
图 1:本模型生成的类别条件样本。
The state of generative image modeling has advanced dramatically in recent years, with Generative Adversarial Networks (GANs, Goodfellow et al. 2014) at the forefront of efforts to generate high-fidelity, diverse images with models learned directly from data. GAN training is dynamic, and sensitive to nearly every aspect of its setup (from optimization parameters to model architecture), but a torrent of research has yielded empirical and theoretical insights enabling stable training in a variety of settings. Despite this progress, the current state of the art in conditional ImageNet modeling (Zhang et al. 2018) achieves an Inception Score (Salimans et al. 2016) of 52.5, compared to 233 for real data.
近年来生成式图像建模进步显著,生成对抗网络(GAN,Goodfellow 等 2014)站在直接从数据学高保真、多样图像的前沿。GAN 训练动态,对优化参数到结构几乎处处敏感,但大量研究已给出经验与理论洞见,使多种设定下稳定训练成为可能。即便如此,当时条件 ImageNet 建模的最佳结果(Zhang 等 2018)Inception Score(Salimans 等 2016)仅 52.5,而真实数据约为 233。
In this work, we set out to close the gap in fidelity and variety between images generated by GANs and real-world images from the ImageNet dataset. We make the following three contributions towards this goal:
本文目标是缩小 GAN 生成图像与 ImageNet 真实图像在保真与多样性上的差距。我们朝这一目标给出三项贡献:
- • We demonstrate that GANs benefit dramatically from scaling, and train models with two to four times as many parameters and eight times the batch size compared to prior art. We introduce two simple, general architectural changes that improve scalability, and modify a regularization scheme to improve conditioning, demonstrably boosting performance.
- • 证明 GAN 从规模化中获益极大:相对此前工作,参数多二到四倍、批大小八倍。引入两项简单、通用的结构改动以提升可扩展性,并修改正则以改善条件数,显著抬升性能。
- • As a side effect of our modifications, our models become amenable to the “truncation trick,” a simple sampling technique that allows explicit, fine-grained control of the trade-off between sample variety and fidelity.
- • 这些改动的副作用是模型可用「截断技巧」——一种简单采样法,显式、精细地控制样本多样性与保真的权衡。
- • We discover instabilities specific to large scale GANs, and characterize them empirically. Leveraging insights from this analysis, we demonstrate that a combination of novel and existing techniques can reduce these instabilities, but complete training stability can only be achieved at a dramatic cost to performance.
- • 发现大规模 GAN 特有的不稳定,并经验刻画。据此说明新旧技术组合能减轻不稳定,但完全稳定往往要以大幅牺牲性能为代价。
Our modifications substantially improve class-conditional GANs. When trained on ImageNet at 128128 resolution, our models (BigGANs) improve the state-of-the-art Inception Score (IS) and Fréchet Inception Distance (FID) from 52.52 and 18.65 to 166.5 and 7.4 respectively. We also successfully train BigGANs on ImageNet at 256256 and 512512 resolution, and achieve IS and FID of 232.5 and 8.1 at 256256 and IS and FID of 241.5 and 11.5 at 512512. Finally, we train our models on an even larger dataset -- JFT-300M -- and demonstrate that our design choices transfer well from ImageNet. Code and weights for our pretrained generators are publicly available [^1].
上述改动大幅提升类别条件 GAN。ImageNet 128×128 上,BigGAN 将当时最佳 IS 与 FID 从 52.52、18.65 分别推到 166.5、7.4。我们也在 256×256 与 512×512 成功训练:256 上 IS/FID 为 232.5/8.1,512 上为 241.5/11.5。最后在更大的 JFT-300M 上训练,表明设计选择能从 ImageNet 迁移。预训练生成器代码与权重已公开[^1]。
2 Background
A Generative Adversarial Network (GAN) involves Generator (G) and Discriminator (D) networks whose purpose, respectively, is to map random noise to samples and discriminate real and generated samples. Formally, the GAN objective, in its original form (Goodfellow et al. 2014) involves finding a Nash equilibrium to the following two player min-max problem:
生成对抗网络含生成器(G)与判别器(D):前者把随机噪声映射成样本,后者区分真假。形式上,原始 GAN 目标(Goodfellow 等 2014)是求下列双人极小–极大问题的纳什均衡:
where is a latent variable drawn from distribution such as or . When applied to images, G and D are usually convolutional neural networks (Radford et al. 2016). Without auxiliary stabilization techniques, this training procedure is notoriously brittle, requiring finely-tuned hyperparameters and architectural choices to work at all.
其中 来自 ,如 或 。用于图像时,G 与 D 通常是卷积网络(Radford 等 2016)。若无额外稳定手段,该流程极脆,几乎要精细调参与结构才能跑通。
Much recent research has accordingly focused on modifications to the vanilla GAN procedure to impart stability, drawing on a growing body of empirical and theoretical insights (Nowozin et al. 2016; Sønderby et al. 2017; Fedus et al. 2018). One line of work is focused on changing the objective function (Arjovsky et al. 2017; Mao et al. 2016; Lim & Ye 2017; Bellemare et al. 2017; Salimans et al. 2018) to encourage convergence. Another line is focused on constraining D through gradient penalties (Gulrajani et al. 2017; Kodali et al. 2017; Mescheder et al. 2018) or normalization (Miyato et al. 2018), both to counteract the use of unbounded loss functions and ensure D provides gradients everywhere to G.
近期大量工作因此修改朴素 GAN 流程以增强稳定性,依托不断积累的经验与理论(Nowozin 等 2016;Sønderby 等 2017;Fedus 等 2018)。一派改目标函数以促进收敛(Arjovsky 等 2017;Mao 等 2016;Lim & Ye 2017;Bellemare 等 2017;Salimans 等 2018)。另一派用梯度惩罚(Gulrajani 等 2017;Kodali 等 2017;Mescheder 等 2018)或归一化(Miyato 等 2018)约束 D,既应对无界损失,又保证 D 处处给 G 提供梯度。
Of particular relevance to our work is Spectral Normalization (Miyato et al. 2018), which enforces Lipschitz continuity on D by normalizing its parameters with running estimates of their first singular values, inducing backwards dynamics that adaptively regularize the top singular direction. Relatedly Odena et al. 2018 analyze the condition number of the Jacobian of G and find that performance is dependent on G’s conditioning. Zhang et al. 2018 find that employing Spectral Normalization in G improves stability, allowing for fewer D steps per iteration. We extend on these analyses to gain further insight into the pathology of GAN training.
与本文尤其相关的是谱归一化(Miyato 等 2018):用参数最大奇异值的运行估计做归一,强制 D 满足 Lipschitz,并在反向中自适应正则主奇异方向。Odena 等 2018 分析 G 的雅可比条件数,发现性能依赖 G 的条件状况。Zhang 等 2018 发现在 G 上用谱归一也能稳住训练,从而减少每轮 D 步数。我们沿这些分析继续剖析 GAN 训练病理。
Other works focus on the choice of architecture, such as SA-GAN (Zhang et al. 2018) which adds the self-attention block from (Wang et al. 2018) to improve the ability of both G and D to model global structure. ProGAN (Karras et al. 2018) trains high-resolution GANs in the single-class setting by training a single model across a sequence of increasing resolutions.
另一些工作侧重结构:SA-GAN(Zhang 等 2018)引入 Wang 等 2018 的自注意力块,提升 G、D 建模全局结构的能力;ProGAN(Karras 等 2018)在单类设定下按分辨率递增训练同一模型,实现高分辨率 GAN。
In conditional GANs (Mirza & Osindero 2014) class information can be fed into the model in various ways. In (Odena et al. 2017) it is provided to G by concatenating a 1-hot class vector to the noise vector, and the objective is modified to encourage conditional samples to maximize the corresponding class probability predicted by an auxiliary classifier. de Vries et al. 2017 and Dumoulin et al. 2017 modify the way class conditioning is passed to G by supplying it with class-conditional gains and biases in BatchNorm (Ioffe & Szegedy 2015) layers. In Miyato & Koyama 2018, D is conditioned by using the cosine similarity between its features and a set of learned class embeddings as additional evidence for distinguishing real and generated samples, effectively encouraging generation of samples whose features match a learned class prototype.
条件 GAN(Mirza & Osindero 2014)有多种注入类别的方式。Odena 等 2017 把 one-hot 拼到噪声,并改目标使条件样本最大化辅助分类器对应类概率。de Vries 等 2017 与 Dumoulin 等 2017 用类别条件 BatchNorm(Ioffe & Szegedy 2015)的增益与偏置把类别送给 G。Miyato & Koyama 2018 用 D 特征与学得类嵌入的余弦相似度作额外证据,促使生成特征贴近学到的类原型。
Objectively evaluating implicit generative models is difficult (Theis et al. 2015). A variety of works have proposed heuristics for measuring the sample quality of models without tractable likelihoods (Salimans et al. 2016; Heusel et al. 2017; Bińkowski et al. 2018; Wu et al. 2017). Of these, the Inception Score (IS, Salimans et al. 2016) and Fréchet Inception Distance (FID, Heusel et al. 2017) have become popular despite their notable flaws (Barratt & Sharma 2018). We employ them as approximate measures of sample quality, and to enable comparison against previous work.
客观评价隐式生成模型很难(Theis 等 2015)。不少工作提出无似然时的样本质量启发式(Salimans 等 2016;Heusel 等 2017;Bińkowski 等 2018;Wu 等 2017)。其中 Inception Score(IS,Salimans 等 2016)与 Fréchet Inception Distance(FID,Heusel 等 2017)尽管有明显缺陷(Barratt & Sharma 2018),仍被广泛使用。我们用它们作近似质量指标,并与先前工作对照。
3 Scaling Up GANs
| Batch | Ch. | Param (M) | Shared | Skip- | Ortho. | Itr | FID | IS |
|---|---|---|---|---|---|---|---|---|
| 256 | 64 | 81.5 | SA-GAN Baseline | |||||
| 512 | 64 | 81.5 | ✗ | ✗ | ✗ | |||
| 1024 | 64 | 81.5 | ✗ | ✗ | ✗ | |||
| 2048 | 64 | 81.5 | ✗ | ✗ | ✗ | |||
| 2048 | 96 | 173.5 | ✗ | ✗ | ✗ | |||
| 2048 | 96 | 160.6 | ✓ | ✗ | ✗ | |||
| 2048 | 96 | 158.3 | ✓ | ✓ | ✗ | |||
| 2048 | 96 | 158.3 | ✓ | ✓ | ✓ | |||
| 2048 | 64 | 71.3 | ✓ | ✓ | ✓ |
Table 1: Fréchet Inception Distance (FID, lower is better) and Inception Score (IS, higher is better) for ablations of our proposed modifications. Batch is batch size, Param is total number of parameters, Ch. is the channel multiplier representing the number of units in each layer, Shared is using shared embeddings, Skip- is using skip connections from the latent to multiple layers, Ortho. is Orthogonal Regularization, and Itr indicates if the setting is stable to iterations, or it collapses at the given iteration. Other than rows 1-4, results are computed across 8 random initializations.
| Batch | Ch. | Param (M) | Shared | Skip- | Ortho. | Itr | FID | IS |
|---|---|---|---|---|---|---|---|---|
| 256 | 64 | 81.5 | SA-GAN Baseline | |||||
| 512 | 64 | 81.5 | ✗ | ✗ | ✗ | |||
| 1024 | 64 | 81.5 | ✗ | ✗ | ✗ | |||
| 2048 | 64 | 81.5 | ✗ | ✗ | ✗ | |||
| 2048 | 96 | 173.5 | ✗ | ✗ | ✗ | |||
| 2048 | 96 | 160.6 | ✓ | ✗ | ✗ | |||
| 2048 | 96 | 158.3 | ✓ | ✓ | ✗ | |||
| 2048 | 96 | 158.3 | ✓ | ✓ | ✓ | |||
| 2048 | 64 | 71.3 | ✓ | ✓ | ✓ |
表 1:所提改动消融的 FID(越低越好)与 IS(越高越好)。Batch 为批大小,Param 为总参数量,Ch. 为通道乘数,Shared 是否共享嵌入,Skip- 是否从潜变量到多层跳连,Ortho. 是否正交正则,Itr 表示是否稳定到 次迭代,或在给定迭代崩溃。除第 1–4 行外,结果跨 8 次随机初始化。
In this section, we explore methods for scaling up GAN training to reap the performance benefits of larger models and larger batches. As a baseline, we employ the SA-GAN architecture of Zhang et al. 2018, which uses the hinge loss (Lim & Ye 2017; Tran et al. 2017) GAN objective. We provide class information to G with class-conditional BatchNorm (Dumoulin et al. 2017; de Vries et al. 2017) and to D with projection (Miyato & Koyama 2018). The optimization settings follow Zhang et al. 2018 (notably employing Spectral Norm in G) with the modification that we halve the learning rates and take two D steps per G step. For evaluation, we employ moving averages of G’s weights following Karras et al. 2018; Mescheder et al. 2018; Yazıcı et al. 2018, with a decay of . We use Orthogonal Initialization (Saxe et al. 2014), whereas previous works used (Radford et al. 2016) or Xavier initialization (Glorot & Bengio 2010). Each model is trained on 128 to 512 cores of a Google TPUv3 Pod (Google 2018), and computes BatchNorm statistics in G across all devices, rather than per-device as is typical. We find progressive growing (Karras et al. 2018) unnecessary even for our 512512 models. Additional details are in Appendix C.
本节探索如何放大 GAN 训练,以吃到更大模型与更大批次的性能红利。基线采用 Zhang 等 2018 的 SA-GAN 结构,目标为 hinge 损失(Lim & Ye 2017;Tran 等 2017)。类别信息经类别条件 BatchNorm(Dumoulin 等 2017;de Vries 等 2017)送给 G,经投影(Miyato & Koyama 2018)送给 D。优化设定沿用 Zhang 等 2018(尤其在 G 上用谱归一),但学习率减半,且每步 G 对应两步 D。评估时对 G 权重做滑动平均(Karras 等 2018;Mescheder 等 2018;Yazıcı 等 2018),衰减 。初始化用正交初始化(Saxe 等 2014),而非此前的 或 Xavier。每个模型在 Google TPUv3 Pod 的 128–512 核上训练,G 的 BatchNorm 统计跨全部设备聚合,而非常见的按设备。即便对 512×512 模型,我们也发现无需渐进生长(Karras 等 2018)。更多细节见附录 C。
We begin by increasing the batch size for the baseline model, and immediately find tremendous benefits in doing so. Rows 1-4 of Table 1 show that simply increasing the batch size by a factor of 8 improves the state-of-the-art IS by 46%. We conjecture that this is a result of each batch covering more modes, providing better gradients for both networks. One notable side effect of this scaling is that our models reach better final performance in fewer iterations, but become unstable and undergo complete training collapse. We discuss the causes and ramifications of this in Section 4. For these experiments, we report scores from checkpoints saved just before collapse.
我们先放大基线批大小,立刻看到巨大收益。表 1 第 1–4 行显示:批大小放大 8 倍即可把当时最佳 IS 再抬约 46%。我们猜测是因为每批覆盖更多模态,给两个网络更好的梯度。副作用是模型用更少迭代就达到更好最终性能,但会失稳并彻底崩溃。第 4 节讨论原因与后果。这些实验报告崩溃前一刻检查点的分数。
We then increase the width (number of channels) in each layer by 50%, approximately doubling the number of parameters in both models. This leads to a further IS improvement of 21%, which we posit is due to the increased capacity of the model relative to the complexity of the dataset. Doubling the depth did not initially lead to improvement – we addressed this later in the BigGAN-deep model, which uses a different residual block structure.
随后把每层宽度(通道数)加 50%,两模型参数约翻倍,IS 再升约 21%。我们归因于相对数据集复杂度的容量提升。深度翻倍起初无收益——后来在 BigGAN-deep 里用不同残差块结构才解决。
We note that class embeddings used for the conditional BatchNorm layers in G contain a large number of weights. Instead of having a separate layer for each embedding (Miyato et al. 2018; Zhang et al. 2018), we opt to use a shared embedding, which is linearly projected to each layer’s gains and biases (Perez et al. 2018). This reduces computation and memory costs, and improves training speed (in number of iterations required to reach a given performance) by 37%. Next, we add direct skip connections (skip-) from the noise vector to multiple layers of G rather than just the initial layer. The intuition behind this design is to allow G to use the latent space to directly influence features at different resolutions and levels of hierarchy. In BigGAN, this is accomplished by splitting into one chunk per resolution, and concatenating each chunk to the conditional vector which gets projected to the BatchNorm gains and biases. In BigGAN-deep, we use an even simpler design, concatenating the entire with the conditional vector without splitting it into chunks. Previous works (Goodfellow et al. 2014; Denton et al. 2015) have considered variants of this concept; our implementation is a minor modification of this design. Skip- provides a modest performance improvement of around 4%, and improves training speed by a further 18%.
G 中条件 BatchNorm 的类别嵌入 权重很多。我们不用每层独立嵌入(Miyato 等 2018;Zhang 等 2018),而用共享嵌入再线性投影到各层增益与偏置(Perez 等 2018)。这降低算力与显存,并把达到给定性能所需迭代数缩短约 37%。接着加入从噪声 到 G 多层的直接跳连(skip-),而非只接到首层,好让潜空间直接调控不同分辨率与层级的特征。BigGAN 把 按分辨率切块,每块与条件向量 拼接后再投影到 BatchNorm 增益偏置;BigGAN-deep 更简单,整段 与条件向量拼接、不再分块。先前工作(Goodfellow 等 2014;Denton 等 2015)已有类似想法;我们的实现是小改。Skip- 大约再抬 4% 性能,并把训练速度再提约 18%。
3.1 Trading off variety and fidelity with the Truncation Trick
| (a) | (a) | (b) | (b) | ||||||
|---|---|---|---|---|---|---|---|---|---|
| (a) | |||||||||
| (b) |
| (a) |
| (b) |
Figure 2: (a) The effects of increasing truncation. From left to right, the threshold is set to 2, 1, 0.5, 0.04. (b) Saturation artifacts from applying truncation to a poorly conditioned model.
图 2:(a)加大截断的效果。从左到右阈值依次为 2、1、0.5、0.04。(b)对条件不佳的模型施加截断时的饱和伪影。
Unlike models which need to backpropagate through their latents, GANs can employ an arbitrary prior , yet the vast majority of previous works have chosen to draw from either or . We question the optimality of this choice and explore alternatives in Appendix E.
与需要沿潜变量反传的模型不同,GAN 可用任意先验 ,但绝大多数工作仍从 或 采样。我们质疑这一选择是否最优,并在附录 E 探索替代。
Remarkably, our best results come from using a different latent distribution for sampling than was used in training. Taking a model trained with and sampling from a truncated normal (where values which fall outside a range are resampled to fall inside that range) immediately provides a boost to IS and FID. We call this the Truncation Trick: truncating a vector by resampling the values with magnitude above a chosen threshold leads to improvement in individual sample quality at the cost of reduction in overall sample variety. Figure 2(a) demonstrates this: as the threshold is reduced, and elements of are truncated towards zero (the mode of the latent distribution), individual samples approach the mode of G’s output distribution. Related observations about this trade-off were made in (Marchesi 2016; Pieters & Wiering 2014).
有意思的是,最佳结果来自采样潜分布与训练时不同。模型用 训练,采样却用截断正态(越界值重采样回区间内),立刻抬升 IS 与 FID。我们称之为截断技巧:按阈值对幅值过大的 分量重采样,可抬单个样本质量、但牺牲整体多样性。图 2(a) 显示:阈值降低、 元素被压向零(潜分布众数)时,单样本逼近 G 输出分布的众数。Marchesi 2016、Pieters & Wiering 2014 有过相关观察。
This technique allows fine-grained, post-hoc selection of the trade-off between sample quality and variety for a given G. Notably, we can compute FID and IS for a range of thresholds, obtaining the variety-fidelity curve reminiscent of the precision-recall curve (Figure 17). As IS does not penalize lack of variety in class-conditional models, reducing the truncation threshold leads to a direct increase in IS (analogous to precision). FID penalizes lack of variety (analogous to recall) but also rewards precision, so we initially see a moderate improvement in FID, but as truncation approaches zero and variety diminishes, the FID sharply drops. The distribution shift caused by sampling with different latents than those seen in training is problematic for many models. Some of our larger models are not amenable to truncation, producing saturation artifacts (Figure 2(b)) when fed truncated noise. To counteract this, we seek to enforce amenability to truncation by conditioning G to be smooth, so that the full space of will map to good output samples. For this, we turn to Orthogonal Regularization (Brock et al. 2017), which directly enforces the orthogonality condition:
该技巧允许事后精细选择给定 G 的质量–多样性权衡。可对一系列阈值算 FID 与 IS,得到类似精确率–召回率的多样性–保真曲线(图 17)。类别条件设定下 IS 不惩罚多样性不足,降低截断阈值会直接抬 IS(类似精确率)。FID 既惩罚多样性不足(类似召回)也奖励精确,故起初 FID 中等改善;截断趋近零、多样性枯竭时 FID 急剧变差。采样潜变量与训练不同造成的分布偏移,对许多模型是问题:部分更大模型不耐受截断,喂截断噪声会出现饱和伪影(图 2(b))。为促使其可截断,我们希望 G 平滑,使整个 空间都映到好样本。于是用正交正则(Brock 等 2017)直接施加正交条件:
where is a weight matrix and a hyperparameter. This regularization is known to often be too limiting (Miyato et al. 2018), so we explore several variants designed to relax the constraint while still imparting the desired smoothness to our models. The version we find to work best removes the diagonal terms from the regularization, and aims to minimize the pairwise cosine similarity between filters but does not constrain their norm:
其中 为权重矩阵, 为超参。该正则常过严(Miyato 等 2018),我们试了几种放松版,仍希望保持平滑。效果最好的版本去掉对角项,最小化滤波器两两余弦相似、但不约束范数:
where denotes a matrix with all elements set to . We sweep values and select , finding this small added penalty sufficient to improve the likelihood that our models will be amenable to truncation. Across runs in Table 1, we observe that without Orthogonal Regularization, only 16% of models are amenable to truncation, compared to 60% when trained with Orthogonal Regularization.
其中 为全 1 矩阵。扫描 后取 ,这一小惩罚足以提高模型可截断概率。表 1 各次运行中,无正交正则时仅约 16% 可截断,有正交正则则约 60%。
3.2 Summary
We find that current GAN techniques are sufficient to enable scaling to large models and distributed, large-batch training. We find that we can dramatically improve the state of the art and train models up to 512512 resolution without need for explicit multiscale methods like Karras et al. 2018. Despite these improvements, our models undergo training collapse, necessitating early stopping in practice. In the next two sections we investigate why settings which were stable in previous works become unstable when applied at scale.
我们发现现有 GAN 技术已足以放大到大模型与分布式大批训练,可大幅刷新技术水平,并训到 512×512,而无需 Karras 等 2018 式显式多尺度方法。尽管有这些改进,模型仍会训练崩溃,实践上需早停。接下来两节分析:为何先前稳定的设定放到大尺度会失稳。
4 Analysis
| (a) G | (a) G | (b) D | (b) D | ||
|---|---|---|---|---|---|
| (a) G | |||||
| (b) D |
| (a) G |
| (b) D |
Figure 3: A typical plot of the first singular value in the layers of G (a) and D (b) before Spectral Normalization. Most layers in G have well-behaved spectra, but without constraints a small subset grow throughout training and explode at collapse. D’s spectra are noisier but otherwise better-behaved. Colors from red to violet indicate increasing depth.
图 3:谱归一前 G(a)与 D(b)各层第一奇异值 的典型曲线。G 多数层谱表现良好,但无约束时少数层会在训练中持续增长并在崩溃时爆炸。D 的谱更噪,但整体更规矩。颜色自红到紫表示深度加深。
4.1 Characterizing Instability: The Generator
Much previous work has investigated GAN stability from a variety of analytical angles and on toy problems, but the instabilities we observe occur for settings which are stable at small scale, necessitating direct analysis at large scale. We monitor a range of weight, gradient, and loss statistics during training, in search of a metric which might presage the onset of training collapse, similar to (Odena et al. 2018). We found the top three singular values of each weight matrix to be the most informative. They can be efficiently computed using the Alrnoldi iteration method (Golub & der Vorst 2000), which extends the power iteration method, used in Miyato et al. 2018, to estimation of additional singular vectors and values. A clear pattern emerges, as can be seen in Figure 3(a) and Appendix F: most G layers have well-behaved spectral norms, but some layers (typically the first layer in G, which is over-complete and not convolutional) are ill-behaved, with spectral norms that grow throughout training and explode at collapse.
既往大量工作从多种分析角度与玩具问题上研究 GAN 稳定性,但我们观察到的失稳出现在小尺度本该稳定的设定中,因此必须直接在大尺度分析。训练中我们监控权重、梯度与损失等多类统计量,寻找可预警崩溃的指标(类似 Odena 等 2018)。最有信息量的是各权重矩阵前三个奇异值 ,可用 Arnoldi 迭代(Golub & der Vorst 2000)高效估计——它把 Miyato 等 2018 所用的幂迭代扩展到更多奇异向量与奇异值。图 3(a) 与附录 F 呈现清晰模式:G 多数层谱范数表现良好,但少数层(通常是 G 首层——过完备且非卷积)行为差,谱范数训练中持续增长并在崩溃时爆炸。
To ascertain if this pathology is a cause of collapse or merely a symptom, we study the effects of imposing additional conditioning on G to explicitly counteract spectral explosion. First, we directly regularize the top singular values of each weight, either towards a fixed value or towards some ratio of the second singular value, (with the stop-gradient operation to prevent the regularization from increasing ). Alternatively, we employ a partial singular value decomposition to instead clamp . Given a weight , its first singular vectors and , and the value to which the will be clamped, our weights become:
为判断该病理是崩溃原因还是症状,我们在 G 上施加额外条件约束以显式对抗谱爆炸。先直接正则各权重最大奇异值 :要么拉向固定值 ,要么拉向第二奇异值的某比例 ( 为停止梯度,避免正则抬高 )。也可用部分奇异值分解钳制 。给定权重 、其第一对奇异向量 以及钳制目标 ,权重变为:
where is set to either or . We observe that both with and without Spectral Normalization these techniques have the effect of preventing the gradual increase and explosion of either or , but even though in some cases they mildly improve performance, no combination prevents training collapse. This evidence suggests that while conditioning G might improve stability, it is insufficient to ensure stability. We accordingly turn our attention to D.
其中 取 或 。无论是否用谱归一,这些手段都能阻止 或 逐步攀升与爆炸;有时轻微改善性能,但没有任何组合能阻止训练崩溃。这表明约束 G 或可改善稳定性,却不足以保证稳定。于是我们转向 D。
4.2 Characterizing Instability: The Discriminator
As with G, we analyze the spectra of D’s weights to gain insight into its behavior, then seek to stabilize training by imposing additional constraints. Figure 3(b) displays a typical plot of for D (with further plots in Appendix F). Unlike G, we see that the spectra are noisy, is well-behaved, and the singular values grow throughout training but only jump at collapse, instead of exploding.
与 G 一样,我们分析 D 权重的谱以理解其行为,再施加额外约束以求稳住训练。图 3(b) 给出 D 的 典型曲线(更多见附录 F)。与 G 不同,谱更噪, 表现良好,奇异值训练中增长但只在崩溃时跳变,而非爆炸。
The spikes in D’s spectra might suggest that it periodically receives very large gradients, but we observe that the Frobenius norms are smooth (Appendix F), suggesting that this effect is primarily concentrated on the top few singular directions. We posit that this noise is a result of optimization through the adversarial training process, where G periodically produces batches which strongly perturb D . If this spectral noise is causally related to instability, a natural counter is to employ gradient penalties, which explicitly regularize changes in D’s Jacobian. We explore the zero-centered gradient penalty from Mescheder et al. 2018:
D 谱上的尖峰或许暗示它周期性收到很大梯度,但 Frobenius 范数平滑(附录 F),说明效应主要集中在前几个奇异方向。我们猜想噪声来自对抗优化过程: G 周期性产出强烈扰动 D 的批次。若谱噪声与失稳有因果,自然对策是梯度惩罚,显式正则 D 雅可比变化。我们采用 Mescheder 等 2018 的 零中心梯度惩罚:
With the default suggested strength of 10, training becomes stable and improves the smoothness and boundedness of spectra in both G and D, but performance severely degrades, resulting in a 45% reduction in IS. Reducing the penalty partially alleviates this degradation, but results in increasingly ill-behaved spectra; even with the penalty strength reduced to (the lowest strength for which sudden collapse does not occur) the IS is reduced by 20%. Repeating this experiment with various strengths of Orthogonal Regularization, DropOut (Srivastava et al. 2014), and L2 (See Appendix I for details), reveals similar behaviors for these regularization strategies: with high enough penalties on D, training stability can be achieved, but at a substantial cost to performance.
取默认建议强度 时,训练变稳,G 与 D 的谱更平滑、有界,但性能严重下滑,IS 约降 45%。减弱惩罚可部分缓解下滑,但谱越来越差;即使降到 (仍能避免突然崩溃的最低强度),IS 仍降约 20%。对正交正则、DropOut(Srivastava 等 2014)与 L2 做不同强度重复实验(细节见附录 I)得到类似规律:对 D 惩罚够强可稳住训练,却要以大幅牺牲性能为代价。
We also observe that D’s loss approaches zero during training, but undergoes a sharp upward jump at collapse (Appendix F). One possible explanation for this behavior is that D is overfitting to the training set, memorizing training examples rather than learning some meaningful boundary between real and generated images. As a simple test for D’s memorization (related to Gulrajani et al. 2017), we evaluate uncollapsed discriminators on the ImageNet training and validation sets, and measure what percentage of samples are classified as real or generated. While the training accuracy is consistently above 98%, the validation accuracy falls in the range of 50-55%, no better than random guessing (regardless of regularization strategy). This confirms that D is indeed memorizing the training set; we deem this in line with D’s role, which is not explicitly to generalize, but to distill the training data and provide a useful learning signal for G. Additional experiments and discussion are provided in Appendix G.
我们还观察到 D 损失训练中趋近零,崩溃时却急剧上跳(附录 F)。一种解释是 D 过拟合训练集:在背训练样本,而非学习真伪之间有意义的边界。作为记忆测试(相关于 Gulrajani 等 2017),我们在未崩溃判别器上评估 ImageNet 训练与验证集,统计被判为真/假的比例。训练准确率始终高于 98%,验证准确率却落在 50–55%,不优于随机(与正则策略无关)。这证实 D 确实在记训练集;我们认为这符合 D 的角色——并不显式要求泛化,而是蒸馏训练数据、给 G 有用学习信号。更多实验与讨论见附录 G。
4.3 Summary
We find that stability does not come solely from G or D, but from their interaction through the adversarial training process. While the symptoms of their poor conditioning can be used to track and identify instability, ensuring reasonable conditioning proves necessary for training but insufficient to prevent eventual training collapse. It is possible to enforce stability by strongly constraining D, but doing so incurs a dramatic cost in performance. With current techniques, better final performance can be achieved by relaxing this conditioning and allowing collapse to occur at the later stages of training, by which time a model is sufficiently trained to achieve good results.
我们发现稳定性不只来自 G 或 D,而来自对抗训练中二者交互。其条件不良的症状可用于跟踪与识别失稳;保证合理条件对训练必要,却不足以阻止最终崩溃。可以靠强约束 D 强制稳定,但性能代价巨大。以现有技术,更好最终性能往往来自放松这一条件、允许训练后期崩溃——那时模型已训到足以出好结果。
5 Experiments
| (a) 128128 | (a) 128128 | (b) 256256 | (b) 256256 | (c) 512512 | (c) 512512 | (d) | (d) | ||||
|---|---|---|---|---|---|---|---|---|---|---|---|
| (a) 128128 | |||||||||||
| (b) 256256 | |||||||||||
| (c) 512512 | |||||||||||
| (d) |
| (a) 128128 |
| (b) 256256 |
| (c) 512512 |
| (d) |
Figure 4: Samples from our BigGAN model with truncation threshold 0.5 (a-c) and an example of class leakage in a partially trained model (d).
图 4:截断阈值 0.5 时 BigGAN 样本(a–c),以及部分训练模型中的类别泄漏示例(d)。
| Model | Res. | FID/IS | (min FID) / IS | FID / (valid IS) | FID / (max IS) |
|---|---|---|---|---|---|
| SN-GAN | 128 | N/A | N/A | N/A | |
| SA-GAN | 128 | N/A | N/A | N/A | |
| BigGAN | 128 | ||||
| BigGAN | 256 | ||||
| BigGAN | 512 | ||||
| BigGAN-deep | 128 | ||||
| BigGAN-deep | 256 | ||||
| BigGAN-deep | 512 |
Table 2: Evaluation of models at different resolutions. We report scores without truncation (Column 3), scores at the best FID (Column 4), scores at the IS of validation data (Column 5), and scores at the max IS (Column 6). Standard deviations are computed over at least three random initializations.
| Model | Res. | FID/IS | (min FID) / IS | FID / (valid IS) | FID / (max IS) |
|---|---|---|---|---|---|
| SN-GAN | 128 | N/A | N/A | N/A | |
| SA-GAN | 128 | N/A | N/A | N/A | |
| BigGAN | 128 | ||||
| BigGAN | 256 | ||||
| BigGAN | 512 | ||||
| BigGAN-deep | 128 | ||||
| BigGAN-deep | 256 | ||||
| BigGAN-deep | 512 |
表 2:不同分辨率模型评估。第 3 列为无截断分数,第 4 列为最佳 FID 处,第 5 列为验证集 IS 对齐处,第 6 列为最大 IS 处。标准差至少跨三次随机初始化。
5.1 Evaluation on ImageNet
We evaluate our models on ImageNet ILSVRC 2012 (Russakovsky et al. 2015) at 128128, 256256, and 512512 resolutions, employing the settings from Table 1, row 8. The samples generated by our models are presented in Figure 4, with additional samples in Appendix A, and online [^2]. We report IS and FID in Table 2. As our models are able to trade sample variety for quality, it is unclear how best to compare against prior art; we accordingly report values at three settings, with complete curves in Appendix D. First, we report the FID/IS values at the truncation setting which attains the best FID. Second, we report the FID at the truncation setting for which our model’s IS is the same as that attained by the real validation data, reasoning that this is a passable measure of maximum sample variety achieved while still achieving a good level of “objectness.” Third, we report FID at the maximum IS achieved by each model, to demonstrate how much variety must be traded off to maximize quality. In all three cases, our models outperform the previous state-of-the-art IS and FID scores achieved by Miyato et al. 2018 and Zhang et al. 2018.
我们在 ImageNet ILSVRC 2012(Russakovsky 等 2015)上以 128×128、256×256、512×512 评估,设定取自表 1 第 8 行。样本见图 4,更多见附录 A 与线上[^2]。IS 与 FID 见表 2。因模型可在多样性与质量间权衡,如何与先前工作公平对比并不显然;我们因此报告三组设定,完整曲线见附录 D。第一,取最佳 FID 对应截断下的 FID/IS;第二,取模型 IS 与真实验证集 IS 对齐时的 FID,作为在保持较好「物体感」下多样性上限的大致度量;第三,取各模型最大 IS 处的 FID,展示为抬质量需牺牲多少多样性。三种情形下,我们的模型均超过 Miyato 等 2018 与 Zhang 等 2018 此前最佳 IS 与 FID。
In addition to the BigGAN model introduced in the first version of the paper and used in the majority of experiments (unless otherwise stated), we also present a 4x deeper model (BigGAN-deep) which uses a different configuration of residual blocks. As can be seen from Table 2, BigGAN-deep substantially outperforms BigGAN across all resolutions and metrics. This confirms that our findings extend to other architectures, and that increased depth leads to improvement in sample quality. Both BigGAN and BigGAN-deep architectures are described in Appendix B.
除论文首版引入、多数实验默认的 BigGAN 外,我们还给出深度约 4 倍、残差块配置不同的 BigGAN-deep。表 2 显示它在所有分辨率与指标上显著优于 BigGAN,说明结论可推广到其他结构,且加深有助于样本质量。两种结构详见附录 B。
Our observation that D overfits to the training set, coupled with our model’s sample quality, raises the obvious question of whether or not G simply memorizes training points. To test this, we perform class-wise nearest neighbors analysis in pixel space and the feature space of pre-trained classifier networks (Appendix A). In addition, we present both interpolations between samples and class-wise interpolations (where is held constant) in Figures 8 and 9. Our model convincingly interpolates between disparate samples, and the nearest neighbors for its samples are visually distinct, suggesting that our model does not simply memorize training data.
既然观察到 D 过拟合训练集,而样本质量又高,自然要问 G 是否只是背训练点。我们按类在像素空间与预训练分类器特征空间做最近邻分析(附录 A),并在图 8、9 展示样本间插值与固定 的类间插值。模型能在差异很大的样本间令人信服地插值,最近邻在视觉上明显不同,说明并非简单背数据。
We note that some failure modes of our partially-trained models are distinct from those previously observed. Most previous failures involve local artifacts (Odena et al. 2016), images consisting of texture blobs instead of objects (Salimans et al. 2016), or the canonical mode collapse. We observe class leakage, where images from one class contain properties of another, as exemplified by Figure 4(d). We also find that many classes on ImageNet are more difficult than others for our model; our model is more successful at generating dogs (which make up a large portion of the dataset, and are mostly distinguished by their texture) than crowds (which comprise a small portion of the dataset and have more large-scale structure). Further discussion is available in Appendix A.
部分训练模型的一些失败模式也与既往不同。以往多见局部伪影(Odena 等 2016)、纹理团块而非物体(Salimans 等 2016)或经典模态崩塌。我们观察到类别泄漏:一类图像带上另一类属性,如图 4(d)。ImageNet 上各类难度也不均:狗类(占比大、多靠纹理区分)更容易,人群(占比小、依赖大尺度结构)更难。更多讨论见附录 A。
| Ch. | Param (M) | Shared | Skip- | Ortho. | FID | IS | (min FID) / IS | FID / (max IS) |
|---|---|---|---|---|---|---|---|---|
| 64 | 317.1 | ✗ | ✗ | ✗ | ||||
| 64 | 99.4 | ✓ | ✓ | ✓ | ||||
| 96 | 207.9 | ✓ | ✓ | ✓ | ||||
| 128 | 355.7 | ✓ | ✓ | ✓ |
Table 3: BigGAN results on JFT-300M at resolution. The FID and IS columns report these scores given by the JFT-300M-trained Inception v2 classifier with noise distributed as (non-truncated). The (min FID) / IS and FID / (max IS) columns report scores at the best FID and IS from a sweep across truncated noise distributions ranging from to . Images from the JFT-300M validation set have an IS of 50.88 and FID of 1.94.
| Ch. | Param (M) | Shared | Skip- | Ortho. | FID | IS | (min FID) / IS | FID / (max IS) |
|---|---|---|---|---|---|---|---|---|
| 64 | 317.1 | ✗ | ✗ | ✗ | ||||
| 64 | 99.4 | ✓ | ✓ | ✓ | ||||
| 96 | 207.9 | ✓ | ✓ | ✓ | ||||
| 128 | 355.7 | ✓ | ✓ | ✓ |
表 3:JFT-300M 上 256×256 的 BigGAN 结果。FID/IS 列为用该数据集训得的 Inception v2、噪声 (未截断)时的分数。(min FID)/IS 与 FID/(max IS) 为在 到 截断扫描中最佳 FID 与最佳 IS 处。JFT-300M 验证集 IS 50.88、FID 1.94。
5.2 Additional evaluation on JFT-300M
To confirm that our design choices are effective for even larger and more complex and diverse datasets, we also present results of our system on a subset of JFT-300M (Sun et al. 2017). The full JFT-300M dataset contains 300M real-world images labeled with 18K categories. Since the category distribution is heavily long-tailed, we subsample the dataset to keep only images with the 8.5K most common labels. The resulting dataset contains 292M images – two orders of magnitude larger than ImageNet. For images with multiple labels, we sample a single label randomly and independently whenever an image is sampled. To compute IS and FID for the GANs trained on this dataset, we use an Inception v2 classifier (Szegedy et al. 2016) trained on this dataset. Quantitative results are presented in Table 3. All models are trained with batch size 2048. We compare an ablated version of our model – comparable to SA-GAN (Zhang et al. 2018) but with the larger batch size – against a “full” BigGAN model that makes uses of all of the techniques applied to obtain the best results on ImageNet (shared embedding, skip-, and orthogonal regularization). Our results show that these techniques substantially improve performance even in the setting of this much larger dataset at the same model capacity (64 base channels). We further show that for a dataset of this scale, we see significant additional improvements from expanding the capacity of our models to 128 base channels, while for ImageNet GANs that additional capacity was not beneficial.
为确认设计在更大、更复杂、更多样的数据上仍有效,我们在 JFT-300M(Sun 等 2017)子集上报告结果。完整 JFT-300M 约 3 亿真实图像、1.8 万类;因长尾严重,我们只保留最常见的 8500 类标签图像,得到约 2.92 亿张——比 ImageNet 大约两个数量级。多标签图像每次采样时独立随机取一个标签。对该数据训得的 GAN,用同数据训的 Inception v2(Szegedy 等 2016)算 IS 与 FID。定量结果见表 3,批大小均为 2048。对照消融版(可比 SA-GAN(Zhang 等 2018)但批更大)与「完整」BigGAN(共享嵌入、skip-、正交正则等 ImageNet 上最佳技巧全开)。结果表明:同等容量(64 基通道)下这些技巧在更大数据上仍大幅提升;进一步扩到 128 基通道还有显著收益——而在 ImageNet GAN 上额外容量并无帮助。
In Figure 19 (Appendix D), we present truncation plots for models trained on this dataset. Unlike for ImageNet, where truncation limits of tend to produce the highest fidelity scores, IS is typically maximized for our JFT-300M models when the truncation value ranges from 0.5 to 1. We suspect that this is at least partially due to the intra-class variability of JFT-300M labels, as well as the relative complexity of the image distribution, which includes images with multiple objects at a variety of scales. Interestingly, unlike models trained on ImageNet, where training tends to collapse without heavy regularization (Section 4), the models trained on JFT-300M remain stable over many hundreds of thousands of iterations. This suggests that moving beyond ImageNet to larger datasets may partially alleviate GAN stability issues.
图 19(附录 D)给出该数据上的截断曲线。与 ImageNet 上 往往保真最高不同,JFT-300M 模型通常在 介于 0.5 与 1 时 IS 最大。我们怀疑部分原因是标签类内变异大,以及图像分布更复杂(多物体、多尺度)。有趣的是,ImageNet 上若不加重正则训练易崩溃(第 4 节),JFT-300M 上模型却可在数十万迭代间保持稳定,暗示走出 ImageNet、换更大数或可部分缓解 GAN 稳定性问题。
The improvement over the baseline GAN model that we achieve on this dataset without changes to the underlying models or training and regularization techniques (beyond expanded capacity) demonstrates that our findings extend from ImageNet to datasets with scale and complexity thus far unprecedented for generative models of images.
在不改底层模型与训练/正则技术(仅扩容量)的情况下相对基线 GAN 的提升,说明我们的发现可从 ImageNet 推广到迄今生成图像模型罕见的规模与复杂度。
6 Conclusion
We have demonstrated that Generative Adversarial Networks trained to model natural images of multiple categories highly benefit from scaling up, both in terms of fidelity and variety of the generated samples. As a result, our models set a new level of performance among ImageNet GAN models, improving on the state of the art by a large margin. We have also presented an analysis of the training behavior of large scale GANs, characterized their stability in terms of the singular values of their weights, and discussed the interplay between stability and performance.
我们证明:面向多类自然图像的生成对抗网络从放大中高度受益,生成样本的保真与多样性皆然。于是我们的模型在 ImageNet GAN 中树立新的性能水平,大幅超过此前最佳。我们也分析了大规模 GAN 的训练行为,用权重奇异值刻画稳定性,并讨论稳定性与性能的相互作用。
Acknowledgments
We would like to thank Kai Arulkumaran, Matthias Bauer, Peter Buchlovsky, Jeffrey Defauw, Sander Dieleman, Ian Goodfellow, Ariel Gordon, Karol Gregor, Dominik Grewe, Chris Jones, Jacob Menick, Augustus Odena, Suman Ravuri, Ali Razavi, Mihaela Rosca, and Jeff Stanway.
References
Abadi et al. (2016) Martín Abadi, Paul Barham, Jianmin Chen, Zhifeng Chen, Andy Davis, Jeffrey Dean, Matthieu Devin, Sanjay Ghemawat, Geoffrey Irving, Michael Isard, Manjunath Kudlur, Josh Levenberg, Rajat Monga, Sherry Moore, Derek Murray, Benoit Steiner, Paul Tucker, Vijay Vasudevan, Pete Warden, Martin Wicke, Yuan Yu, and Xiaoqiang Zheng. TensorFlow: A system for large-scale machine learning. In OSDI , 2016.
Arjovsky et al. (2017) Martin Arjovsky, Soumith Chintala, and Léon Bottou. Wasserstein generative adversarial networks. In ICML , 2017.
Barratt & Sharma (2018) Shane Barratt and Rishi Sharma. A note on the Inception Score. In arXiv preprint arXiv:1801.01973 , 2018.
Bellemare et al. (2017) Marc G. Bellemare, Ivo Danihelka, Will Dabney, Shakir Mohamed, Balaji Lakshminarayanan, Stephan Hoyer, and Rémi Munos. The Cramer distance as a solution to biased Wasserstein gradients. In arXiv preprint arXiv:1705.10743 , 2017.
Bińkowski et al. (2018) Mikolaj Bińkowski, Dougal J. Sutherland, Michael Arbel, and Arthur Gretton. Demystifying MMD GANs. In ICLR , 2018.
Brock et al. (2017) Andrew Brock, Theodore Lim, J.M. Ritchie, and Nick Weston. Neural photo editing with introspective adversarial networks. In ICLR , 2017.
Chen et al. (2016) Xi Chen, Yan Duan, Rein Houthooft, John Schulman, Ilya Sutskever, and Pieter Abbeel. Infogan: Interpretable representation learning by information maximizing generative adversarial nets. In NIPS , 2016.
de Vries et al. (2017) Harm de Vries, Florian Strub, Jérémie Mary, Hugo Larochelle, Olivier Pietquin, and Aaron Courville. Modulating early visual processing by language. In NIPS , 2017.
Denton et al. (2015) Emily Denton, Soumith Chintala, Arthur Szlam, and Rob Fergus. Deep generative image models using a laplacian pyramid of adversarial networks. In NIPS , 2015.
Dumoulin et al. (2017) Vincent Dumoulin, Jonathon Shlens, and Manjunath Kudlur. A learned representation for artistic style. In ICLR , 2017.
Fedus et al. (2018) William Fedus, Mihaela Rosca, Balaji Lakshminarayanan, Andrew M. Dai, Shakir Mohamed, and Ian Goodfellow. Many paths to equilibrium: GANs do not need to decrease a divergence at every step. In ICLR , 2018.
Glorot & Bengio (2010) Xavier Glorot and Yoshua Bengio. Understanding the difficulty of training deep feedforward neural networks. In AISTATS , 2010.
Golub & der Vorst (2000) Gene Golub and Henk Van der Vorst. Eigenvalue computation in the 20th century. Journal of Computational and Applied Mathematics , 123:35–65, 2000.
Goodfellow et al. (2014) Ian Goodfellow, Jean Pouget-Abadie, Mehdi Mirza, Bing Xu, David Warde-Farley, Sherjil Ozair, and Aaron Courville Yoshua Bengio. Generative adversarial nets. In NIPS , 2014.
Google (2018) Google. Cloud TPUs. https://cloud.google.com/tpu/ , 2018.
Gulrajani et al. (2017) Ishaan Gulrajani, Faruk Ahmed, Martín Arjovsky, Vincent Dumoulin, and Aaron C. Courville. Improved training of Wasserstein GANs. In NIPS , 2017.
He et al. (2016) Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. Deep residual learning for image recognition. In CVPR , 2016.
Heusel et al. (2017) Martin Heusel, Hubert Ramsauer, Thomas Unterthiner, Bernhard Nessler, Günter Klambauer, and Sepp Hochreiter. GANs trained by a two time-scale update rule converge to a local nash equilibrium. In NIPS , 2017.
Ioffe & Szegedy (2015) Sergey Ioffe and Christian Szegedy. Batch normalization: Accelerating deep network training by reducing internal covariate shift. In ICML , 2015.
Karras et al. (2018) Tero Karras, Timo Aila, Samuli Laine, and Jaakko Lehtinen. Progressive growing of GANs for improved quality, stability, and variation. In ICLR , 2018.
Kingma & Ba (2014) Diederik Kingma and Jimmy Ba. Adam: A method for stochastic optimization. In ICLR , 2014.
Kodali et al. (2017) Naveen Kodali, Jacob Abernethy, James Hays, and Zsolt Kira. On convergence and stability of GANs. In arXiv preprint arXiv:1705.07215 , 2017.
Krizhevsky & Hinton (2009) Alex Krizhevsky and Geoffrey Hinton. Learning multiple layers of features from tiny images. 2009.
Lim & Ye (2017) Jae Hyun Lim and Jong Chul Ye. Geometric GAN. In arXiv preprint arXiv:1705.02894 , 2017.
Mao et al. (2016) Xudong Mao, Qing Li, Haoran Xie, Raymond Y. K. Lau, and Zhen Wang. Least squares generative adversarial networks. In arXiv preprint arXiv:1611.04076 , 2016.
Marchesi (2016) Marco Marchesi. Megapixel size image creation using generative adversarial networks. In arXiv preprint arXiv:1706.00082 , 2016.
Mescheder et al. (2018) Lars Mescheder, Andreas Geiger, and Sebastian Nowozin. Which training methods for GANs do actually converge? In ICML , 2018.
Mirza & Osindero (2014) Mehdi Mirza and Simon Osindero. Conditional generative adversarial nets. In arXiv preprint arXiv:1411.1784 , 2014.
Miyato & Koyama (2018) Takeru Miyato and Masanori Koyama. cGANs with projection discriminator. In ICLR , 2018.
Miyato et al. (2018) Takeru Miyato, Toshiki Kataoka, Masanori Koyama, and Yuichi Yoshida. Spectral normalization for generative adversarial networks. In ICLR , 2018.
Nowozin et al. (2016) Sebastian Nowozin, Botond Cseke, and Ryota Tomioka. f-GAN: Training generative neural samplers using variational divergence minimization. In NIPS , 2016.
Odena et al. (2016) Augustus Odena, Vincent Dumoulin, and Chris Olah. Deconvolution and checkerboard artifacts. Distill , 2016.
Odena et al. (2017) Augustus Odena, Christopher Olah, and Jonathon Shlens. Conditional image synthesis with auxiliary classifier GANs. In ICML , 2017.
Odena et al. (2018) Augustus Odena, Jacob Buckman, Catherine Olsson, Tom B. Brown, Christopher Olah, Colin Raffel, and Ian Goodfellow. Is generator conditioning causally related to GAN performance? In ICML , 2018.
Perez et al. (2018) Ethan Perez, Florian Strub, Harm de Vries, Vincent Dumoulin, and Aaron Courville. FiLM: Visual reasoning with a general conditioning layer. In AAAI , 2018.
Pieters & Wiering (2014) Mathijs Pieters and Marco Wiering. Comparing generative adversarial network techniques for image creation and modificatio. In arXiv preprint arXiv:1803.09093 , 2014.
Radford et al. (2016) Alec Radford, Luke Metz, and Soumith Chintala. Unsupervised representation learning with deep convolutional generative adversarial networks. In ICLR , 2016.
Russakovsky et al. (2015) Olga Russakovsky, Jia Deng, Hao Su, Jonathan Krause, Sanjeev Satheesh, Sean Ma, Zhiheng Huang, Andrej Karpathy, Aditya Khosla, and Michael Bernstein. ImageNet large scale visual recognition challenge. IJCV , 115:211–252, 2015.
Salimans & Kingma (2016) Tim Salimans and Diederik Kingma. Weight normalization: A simple reparameterization to accelerate training of deep neural networks. In NIPS , 2016.
Salimans et al. (2016) Tim Salimans, Ian Goodfellow, Wojciech Zaremba, Vicki Cheung, Alec Radford, and Xi Chen. Improved techniques for training GANs. In NIPS , 2016.
Salimans et al. (2018) Tim Salimans, Han Zhang, Alec Radford, and Dimitris Metaxas. Improving GANs using optimal transport. In ICLR , 2018.
Saxe et al. (2014) Andrew Saxe, James McClelland, and Surya Ganguli. Exact solutions to the nonlinear dynamics of learning in deep linear neural networks. In ICLR , 2014.
Simonyan & Zisserman (2015) Karen Simonyan and Andrew Zisserman. Very deep convolutional networks for large-scale image recognition. In ICLR , 2015.
Sønderby et al. (2017) Casper Kaae Sønderby, Jose Caballero, Lucas Theis, Wenzhe Shi, and Ferenc Huszár. Amortised map inference for image super-resolution. In ICLR , 2017.
Srivastava et al. (2014) Nitish Srivastava, Geoffrey Hinton, Alex Krizhevsky, Ilya Sutskever, and Ruslan Salakhutdinov. Dropout: A simple way to prevent neural networks from overfitting. JMLR , 15:1929–1958, 2014.
Sun et al. (2017) Chen Sun, Abhinav Shrivastava, Saurabh Singh, and Abhinav Gupta. Revisiting unreasonable effectiveness of data in deep learning era. In ICCV , 2017.
Szegedy et al. (2016) Christian Szegedy, Vincent Vanhoucke, Sergey Ioffe, Jonathon Shlens, and Zbigniew Wojna. Rethinking the inception architecture for computer vision. In CVPR , 2016.
Theis et al. (2015) Lucas Theis, Aäron van den Oord, and Matthias Bethge. A note on the evaluation of generative models. In arXiv preprint arXiv:1511.01844 , 2015.
Tran et al. (2017) Dustin Tran, Rajesh Ranganath, and David M. Blei. Hierarchical implicit models and likelihood-free variational inference. In NIPS , 2017.
Wang et al. (2018) Xiaolong Wang, Ross B. Girshick, Abhinav Gupta, and Kaiming He. Non-local neural networks. In CVPR , 2018.
Wu et al. (2017) Yuhuai Wu, Yuri Burda, Ruslan Salakhutdinov, and Roger B. Grosse. On the quantitative analysis of decoder-based generative models. In ICLR , 2017.
Yazıcı et al. (2018) Yasin Yazıcı, Chuan-Sheng Foo, Stefan Winkler, Kim-Hui Yap, Georgios Piliouras, and Vijay Chandrasekhar. The unusual effectiveness of averaging in gan training. In arXiv preprint arXiv:1806.04498 , 2018.
Zhang et al. (2018) Han Zhang, Ian Goodfellow, Dimitris Metaxas, and Augustus Odena. Self-attention generative adversarial networks. In arXiv preprint arXiv:1805.08318 , 2018.
Appendix A Additional Samples, Interpolations, and Nearest Neighbors from ImageNet models
Figure 5: Samples generated by our BigGAN model at 256256 resolution.
图 5:BigGAN 在 256×256 分辨率生成的样本。
Figure 6: Samples generated by our BigGAN model at 512512 resolution.
图 6:BigGAN 在 512×512 分辨率生成的样本。
| (a) | (a) | (b) | (b) | ||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| (a) | |||||||||||||
| (b) |
| (a) |
| (b) |
Figure 7: Comparing easy classes (a) with difficult classes (b) at 512512. Classes such as dogs which are largely textural, and common in the dataset, are far easier to model than classes involving unaligned human faces or crowds. Such classes are more dynamic and structured, and often have details to which human observers are more sensitive. The difficulty of modeling global structure is further exacerbated when producing high-resolution images, even with non-local blocks.
图 7:在 512×512 上对比易类(a)与难类(b)。狗等偏纹理、且在数据集中常见的类远比未对齐人脸或人群更易建模。后者更动态、结构更强,且常含人类观察者更敏感的细节。建模全局结构与对齐人脸的难度在这些类别上尤为突出。

Figure 8: Interpolations between pairs.
图 8: 对之间的插值。

Figure 9: Interpolations between with held constant. Pose semantics are frequently maintained between endpoints (particularly in the final row). Row 2 demonstrates that grayscale is encoded in the joint space, rather than in .
图 9:固定 、在 之间插值。姿态语义常在端点间保持(尤其末行)。第 2 行说明灰度编码在联合 空间,而非仅在 。
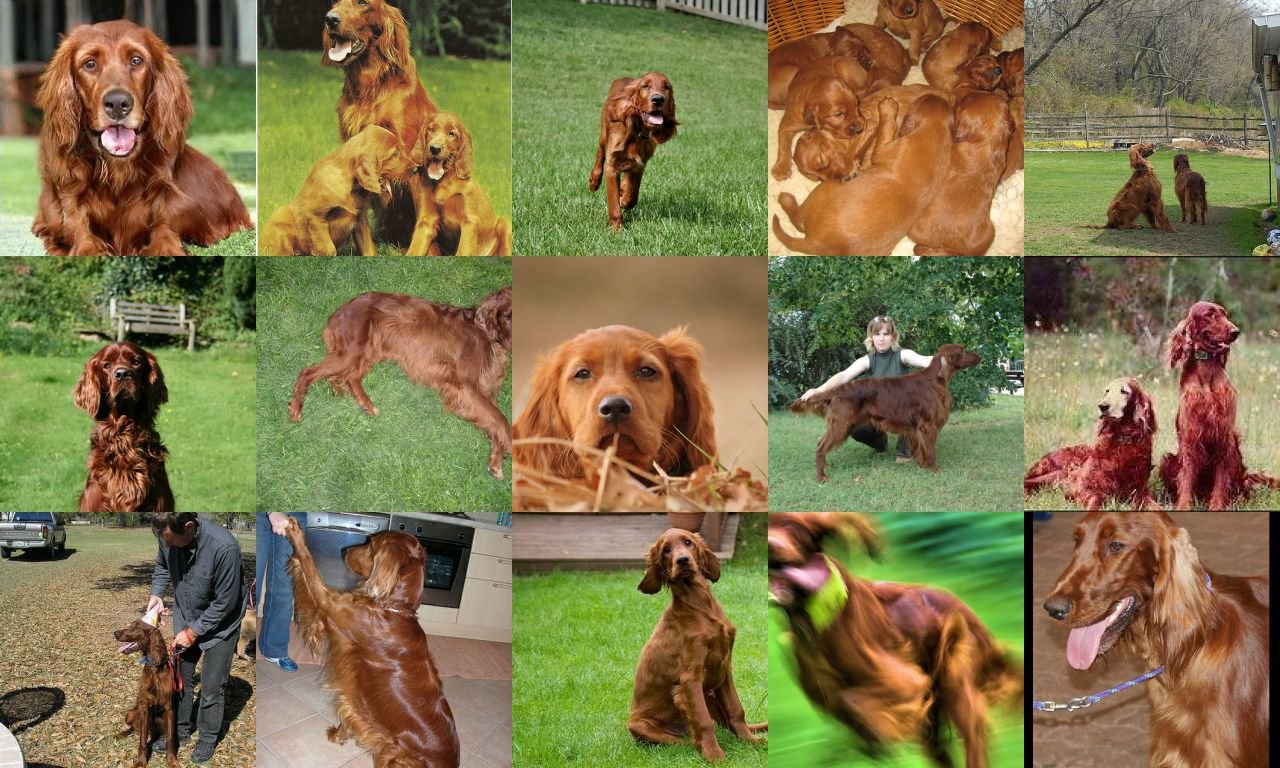
Figure 10: Nearest neighbors in VGG-16-fc7 (Simonyan & Zisserman 2015) feature space. The generated image is in the top left.
图 10:VGG-16-fc7(Simonyan & Zisserman 2015)特征空间最近邻。生成图在左上。
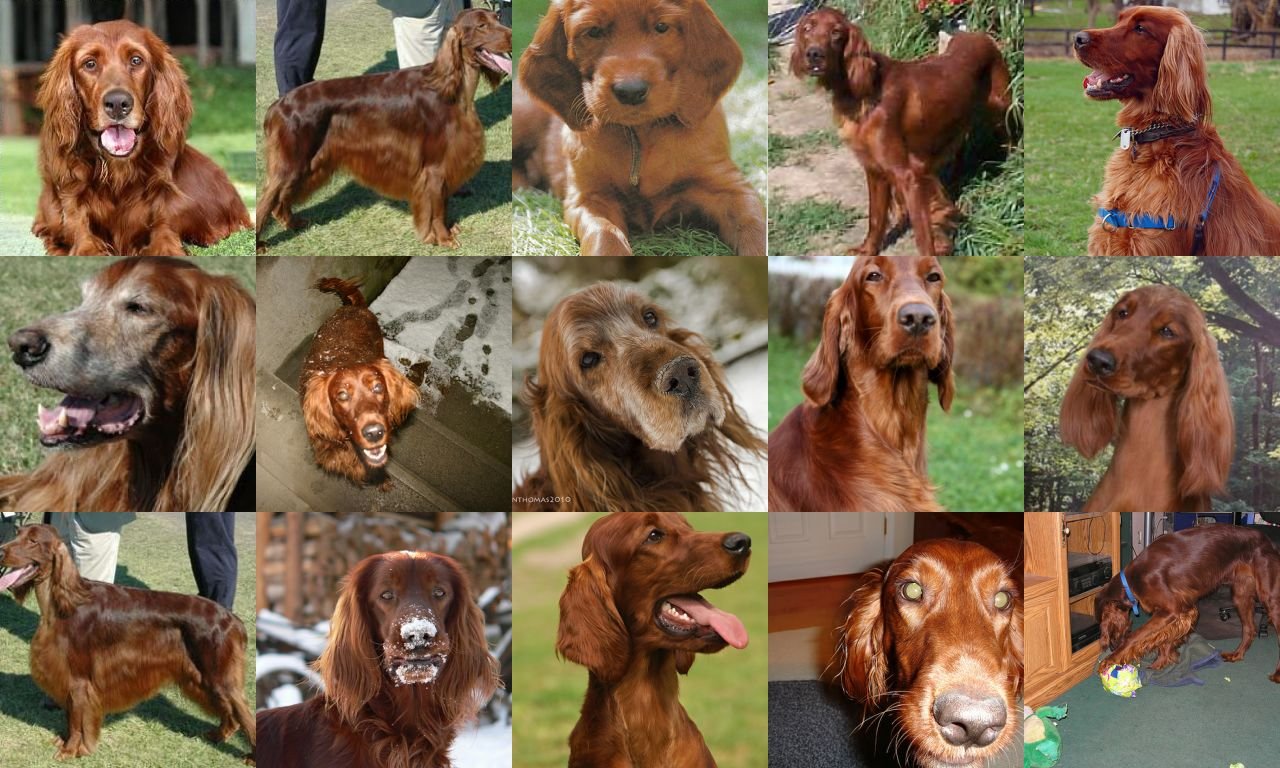
Figure 11: Nearest neighbors in ResNet-50-avgpool (He et al. 2016) feature space. The generated image is in the top left.
图 11:ResNet-50-avgpool(He 等 2016)特征空间最近邻。生成图在左上。
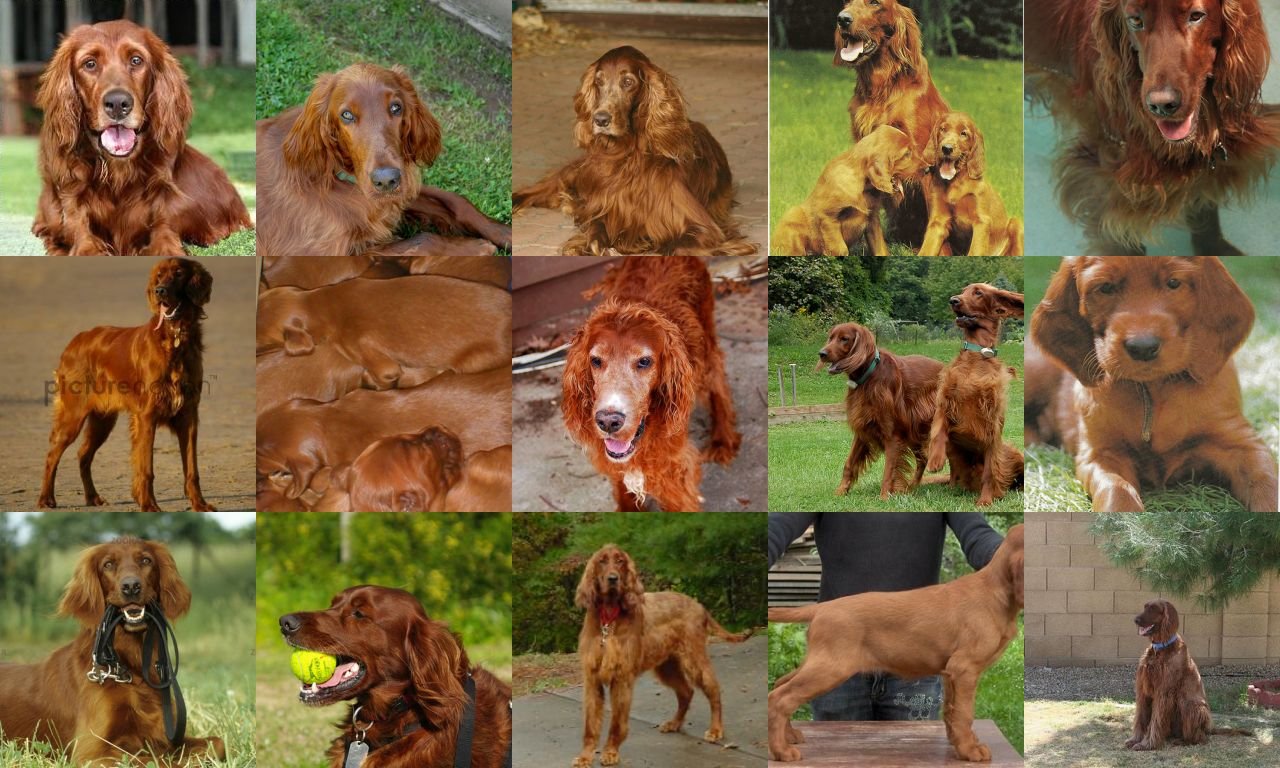
Figure 12: Nearest neighbors in pixel space. The generated image is in the top left.
图 12:像素空间最近邻。生成图在左上。
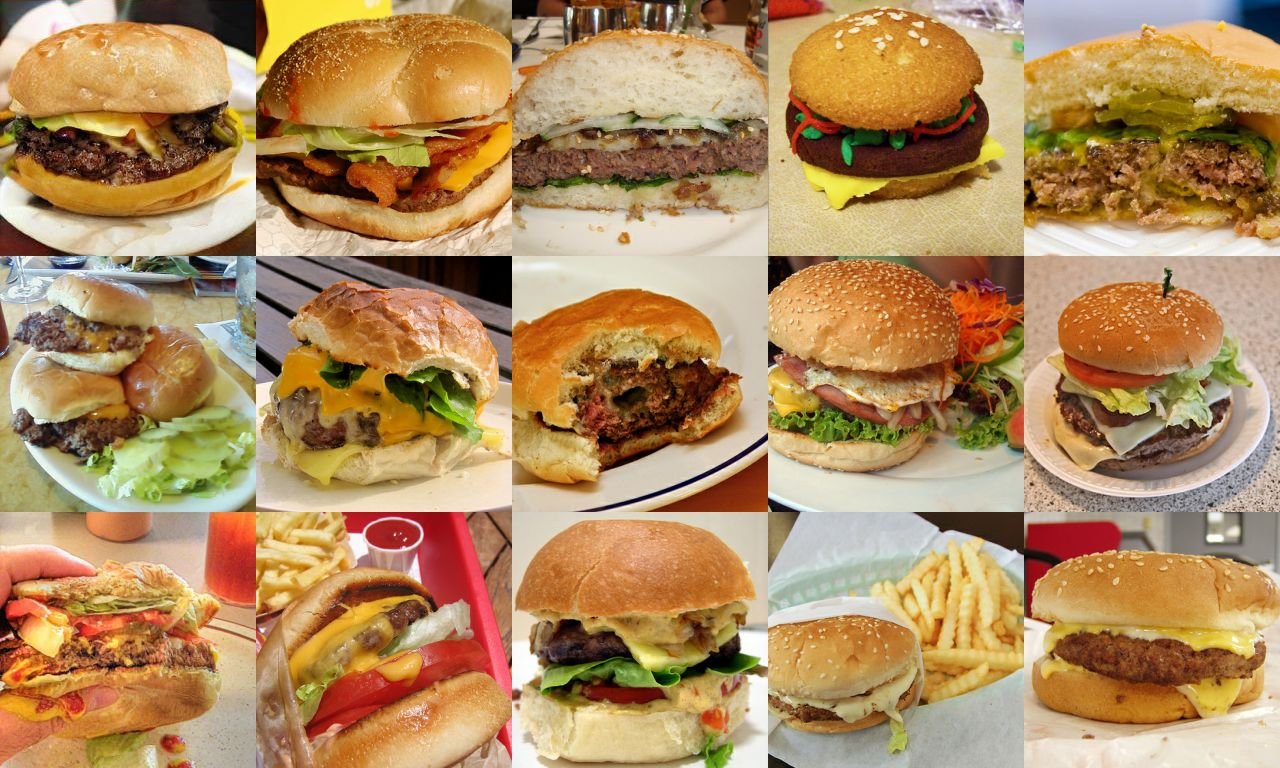
Figure 13: Nearest neighbors in VGG-16-fc7 (Simonyan & Zisserman 2015) feature space. The generated image is in the top left.
图 13:VGG-16-fc7(Simonyan & Zisserman 2015)特征空间最近邻。生成图在左上。
Figure 14: Nearest neighbors in ResNet-50-avgpool (He et al. 2016) feature space. The generated image is in the top left.
图 14:ResNet-50-avgpool(He 等 2016)特征空间最近邻。生成图在左上。
Appendix B Architectural details
In the BigGAN model (Figure 15), we use the ResNet (He et al. 2016) GAN architecture of (Zhang et al. 2018), which is identical to that used by (Miyato et al. 2018), but with the channel pattern in D modified so that the number of filters in the first convolutional layer of each block is equal to the number of output filters (rather than the number of input filters, as in Miyato et al. 2018; Gulrajani et al. 2017). We use a single shared class embedding in G, and skip connections for the latent vector (skip-). In particular, we employ hierarchical latent spaces, so that the latent vector is split along its channel dimension into chunks of equal size (-D in our case), and each chunk is concatenated to the shared class embedding and passed to a corresponding residual block as a conditioning vector. The conditioning of each block is linearly projected to produce per-sample gains and biases for the BatchNorm layers of the block. The bias projections are zero-centered, while the gain projections are centered at . Since the number of residual blocks depends on the image resolution, the full dimensionality of is 120 for , 140 for , and 160 for images.
BigGAN 模型(图 15)采用 Zhang 等 2018 的 ResNet(He 等 2016)GAN 结构,与 Miyato 等 2018 相同,但 D 中通道模式改为:每块首个卷积的滤波器数等于输出通道数(而非 Miyato 等 2018、Gulrajani 等 2017 的输入通道数)。G 用单一共享类嵌入,并对潜变量 做跳连(skip-)。具体采用分层潜空间:沿通道把 切成等长块(本文为 20 维),每块与共享类嵌入拼接后,作为条件向量送入对应残差块。各块条件再线性投影为该块 BatchNorm 的逐样本增益与偏置;偏置投影零中心,增益投影以 1 为中心。残差块数随分辨率变化,故 全维在 128×128 为 120、256×256 为 140、512×512 为 160。
The BigGAN-deep model (Figure 16) differs from BigGAN in several aspects. It uses a simpler variant of skip- conditioning: instead of first splitting into chunks, we concatenate the entire with the class embedding, and pass the resulting vector to each residual block through skip connections. BigGAN-deep is based on residual blocks with bottlenecks (He et al. 2016), which incorporate two additional convolutions: the first reduces the number of channels by a factor of before the more expensive convolutions; the second produces the required number of output channels. While BigGAN relies on convolutions in the skip connections whenever the number of channels needs to change, in BigGAN-deep we use a different strategy aimed at preserving identity throughout the skip connections. In G, where the number of channels needs to be reduced, we simply retain the first group of channels and drop the rest to produce the required number of channels. In D, where the number of channels should be increased, we pass the input channels unperturbed, and concatenate them with the remaining channels produced by a convolution. As far as the network configuration is concerned, the discriminator is an exact reflection of the generator. There are two blocks at each resolution (BigGAN uses one), and as a result BigGAN-deep is four times deeper than BigGAN. Despite their increased depth, the BigGAN-deep models have significantly fewer parameters mainly due to the bottleneck structure of their residual blocks. For example, the BigGAN-deep G and D have 50.4M and 34.6M parameters respectively, while the corresponding original BigGAN models have 70.4M and 88.0M parameters. All BigGAN-deep models use attention at resolution, channel width multiplier , and .
BigGAN-deep(图 16)在多方面不同于 BigGAN。skip- 更简单:不再先切 ,而是整段 与类嵌入拼接,经跳连送入每个残差块。它基于带瓶颈的残差块(He 等 2016),多两层 卷积:先把通道压到 1/4 再做更贵的 ,再投影到所需输出通道。BigGAN 在通道需变时于跳连用 ;BigGAN-deep 则力求跳连保持恒等——G 需减通道时保留前若干通道、丢掉其余;D 需增通道时原通道原样通过,再与 卷积产生的剩余通道拼接。网络配置上,判别器是生成器的精确镜像。每个分辨率两块(BigGAN 为一块),因而 BigGAN-deep 深度约四倍;尽管更深,因瓶颈结构参数反而显著更少。例如 128×128 的 BigGAN-deep G/D 分别约 50.4M/34.6M 参数,对应原版 BigGAN 约 70.4M/88.0M。所有 BigGAN-deep 在 64×64 用注意力,通道乘数 ,且 。
| (a) (b) (c) | (a) | (b) | (c) | |||
|---|---|---|---|---|---|---|
| (a) | ||||||
| (b) | ||||||
| (c) |
| (a) |
| (b) |
| (c) |
Figure 15: (a) A typical architectural layout for BigGAN’s G; details are in the following tables. (b) A Residual Block (ResBlock up) in BigGAN’s G. (c) A Residual Block (ResBlock down) in BigGAN’s D.
图 15:(a)BigGAN G 的典型结构布局,细节见表。(b)BigGAN G 中残差块(ResBlock up)。(c)BigGAN D 中残差块(ResBlock down)。
| (a) | (a) | |||
|---|---|---|---|---|
| (a) | ||||
| (b) (c) | (b) | (c) | ||
| (b) | ||||
| (c) |
| (a) |
| (b) |
| (c) |
Figure 16: (a) A typical architectural layout for BigGAN-deep’s G; details are in the following tables. (b) A Residual Block (ResBlock up) in BigGAN-deep’s G. (c) A Residual Block (ResBlock down) in BigGAN-deep’s D. A ResBlock (without up or down) in BigGAN-deep does not include the Upsample or Average Pooling layers, and has identity skip connections.
图 16:(a)BigGAN-deep G 的典型结构布局,细节见表。(b)BigGAN-deep G 中残差块(ResBlock up)。(c)BigGAN-deep D 中残差块(ResBlock down)。无 up/down 的 ResBlock 不含上采样或平均池化,跳连为恒等。
| Embed() |
| Linear |
| ResBlock up |
| ResBlock up |
| ResBlock up |
| ResBlock up |
| Non-Local Block () |
| ResBlock up |
| BN, ReLU, Conv |
| Tanh |
| RGB image |
|---|
| ResBlock down |
| Non-Local Block () |
| ResBlock down |
| ResBlock down |
| ResBlock down |
| ResBlock down |
| ResBlock |
| ReLU, Global sum pooling |
| Embed() + (linear 1) |
Table 4: BigGAN architecture for images. represents the channel width multiplier in each network from Table 1.
| Embed() |
| Linear |
| ResBlock up |
| ResBlock up |
| ResBlock up |
| ResBlock up |
| Non-Local Block () |
| ResBlock up |
| BN, ReLU, Conv |
| Tanh |
| RGB image |
|---|
| ResBlock down |
| Non-Local Block () |
| ResBlock down |
| ResBlock down |
| ResBlock down |
| ResBlock down |
| ResBlock |
| ReLU, Global sum pooling |
| Embed() + (linear 1) |
表 4:128×128 的 BigGAN 结构。 为表 1 中各网络的通道宽度乘数。
| Embed() |
| Linear |
| ResBlock up |
| ResBlock up |
| ResBlock up |
| ResBlock up |
| ResBlock up |
| Non-Local Block () |
| ResBlock up |
| BN, ReLU, Conv |
| Tanh |
| RGB image |
|---|
| ResBlock down |
| ResBlock down |
| Non-Local Block () |
| ResBlock down |
| ResBlock down |
| ResBlock down |
| ResBlock down |
| ResBlock |
| ReLU, Global sum pooling |
| Embed() + (linear 1) |
Table 5: BigGAN architecture for images. Relative to the architecture, we add an additional ResBlock in each network at 1616 resolution, and move the non-local block in G to resolution. Memory constraints prevent us from moving the non-local block in D.
| Embed() |
| Linear |
| ResBlock up |
| ResBlock up |
| ResBlock up |
| ResBlock up |
| ResBlock up |
| Non-Local Block () |
| ResBlock up |
| BN, ReLU, Conv |
| Tanh |
| RGB image |
|---|
| ResBlock down |
| ResBlock down |
| Non-Local Block () |
| ResBlock down |
| ResBlock down |
| ResBlock down |
| ResBlock down |
| ResBlock |
| ReLU, Global sum pooling |
| Embed() + (linear 1) |
表 5:256×256 的 BigGAN 结构。相对 128×128,各网络在 16×16 再加一块 ResBlock,并把 G 中非局部块移到 128×128。显存限制使我们无法移动 D 中的非局部块。
| Embed() |
| Linear |
| ResBlock up |
| ResBlock up |
| ResBlock up |
| ResBlock up |
| Non-Local Block () |
| ResBlock up |
| ResBlock up |
| ResBlock up |
| BN, ReLU, Conv |
| Tanh |
| RGB image |
|---|
| ResBlock down |
| ResBlock down |
| ResBlock down |
| Non-Local Block () |
| ResBlock down |
| ResBlock down |
| ResBlock down |
| ResBlock down |
| ResBlock |
| ReLU, Global sum pooling |
| Embed() + (linear 1) |
Table 6: BigGAN architecture for images. Relative to the architecture, we add an additional ResBlock at the resolution. Memory constraints force us to move the non-local block in both networks back to resolution as in the pixel setting.
| Embed() |
| Linear |
| ResBlock up |
| ResBlock up |
| ResBlock up |
| ResBlock up |
| Non-Local Block () |
| ResBlock up |
| ResBlock up |
| ResBlock up |
| BN, ReLU, Conv |
| Tanh |
| RGB image |
|---|
| ResBlock down |
| ResBlock down |
| ResBlock down |
| Non-Local Block () |
| ResBlock down |
| ResBlock down |
| ResBlock down |
| ResBlock down |
| ResBlock |
| ReLU, Global sum pooling |
| Embed() + (linear 1) |
表 6:512×512 的 BigGAN 结构。相对 256×256,在 512×512 再加一块 ResBlock。显存限制迫使两网络的非局部块回到 64×64,与 128×128 设定相同。
| Embed() |
| Linear |
| ResBlock |
| ResBlock up |
| ResBlock |
| ResBlock up |
| ResBlock |
| ResBlock up |
| ResBlock |
| ResBlock up |
| Non-Local Block () |
| ResBlock |
| ResBlock up |
| BN, ReLU, Conv |
| Tanh |
| RGB image |
|---|
| Conv |
| ResBlock down |
| ResBlock |
| Non-Local Block () |
| ResBlock down |
| ResBlock |
| ResBlock down |
| ResBlock |
| ResBlock down |
| ResBlock |
| ResBlock down |
| ResBlock |
| ReLU, Global sum pooling |
| Embed() + (linear 1) |
Table 7: BigGAN-deep architecture for images.
| Embed() |
| Linear |
| ResBlock |
| ResBlock up |
| ResBlock |
| ResBlock up |
| ResBlock |
| ResBlock up |
| ResBlock |
| ResBlock up |
| Non-Local Block () |
| ResBlock |
| ResBlock up |
| BN, ReLU, Conv |
| Tanh |
| RGB image |
|---|
| Conv |
| ResBlock down |
| ResBlock |
| Non-Local Block () |
| ResBlock down |
| ResBlock |
| ResBlock down |
| ResBlock |
| ResBlock down |
| ResBlock |
| ResBlock down |
| ResBlock |
| ReLU, Global sum pooling |
| Embed() + (linear 1) |
表 7:128×128 的 BigGAN-deep 结构。
| Embed() |
| Linear |
| ResBlock |
| ResBlock up |
| ResBlock |
| ResBlock up |
| ResBlock |
| ResBlock up |
| ResBlock |
| ResBlock up |
| Non-Local Block () |
| ResBlock |
| ResBlock up |
| ResBlock |
| ResBlock up |
| BN, ReLU, Conv |
| Tanh |
| RGB image |
|---|
| Conv |
| ResBlock down |
| ResBlock |
| ResBlock down |
| ResBlock |
| Non-Local Block () |
| ResBlock down |
| ResBlock |
| ResBlock down |
| ResBlock |
| ResBlock down |
| ResBlock |
| ResBlock down |
| ResBlock |
| ReLU, Global sum pooling |
| Embed() + (linear 1) |
Table 8: BigGAN-deep architecture for images.
| Embed() |
| Linear |
| ResBlock |
| ResBlock up |
| ResBlock |
| ResBlock up |
| ResBlock |
| ResBlock up |
| ResBlock |
| ResBlock up |
| Non-Local Block () |
| ResBlock |
| ResBlock up |
| ResBlock |
| ResBlock up |
| BN, ReLU, Conv |
| Tanh |
| RGB image |
|---|
| Conv |
| ResBlock down |
| ResBlock |
| ResBlock down |
| ResBlock |
| Non-Local Block () |
| ResBlock down |
| ResBlock |
| ResBlock down |
| ResBlock |
| ResBlock down |
| ResBlock |
| ResBlock down |
| ResBlock |
| ReLU, Global sum pooling |
| Embed() + (linear 1) |
表 8:256×256 的 BigGAN-deep 结构。
| Embed() |
| Linear |
| ResBlock |
| ResBlock up |
| ResBlock |
| ResBlock up |
| ResBlock |
| ResBlock up |
| ResBlock |
| ResBlock up |
| Non-Local Block () |
| ResBlock |
| ResBlock up |
| ResBlock |
| ResBlock up |
| ResBlock |
| ResBlock up |
| BN, ReLU, Conv |
| Tanh |
| RGB image |
|---|
| Conv |
| ResBlock down |
| ResBlock |
| ResBlock down |
| ResBlock |
| ResBlock down |
| ResBlock |
| Non-Local Block () |
| ResBlock down |
| ResBlock |
| ResBlock down |
| ResBlock |
| ResBlock down |
| ResBlock |
| ResBlock down |
| ResBlock |
| ReLU, Global sum pooling |
| Embed() + (linear 1) |
Table 9: BigGAN-deep architecture for images.
| Embed() |
| Linear |
| ResBlock |
| ResBlock up |
| ResBlock |
| ResBlock up |
| ResBlock |
| ResBlock up |
| ResBlock |
| ResBlock up |
| Non-Local Block () |
| ResBlock |
| ResBlock up |
| ResBlock |
| ResBlock up |
| ResBlock |
| ResBlock up |
| BN, ReLU, Conv |
| Tanh |
| RGB image |
|---|
| Conv |
| ResBlock down |
| ResBlock |
| ResBlock down |
| ResBlock |
| ResBlock down |
| ResBlock |
| Non-Local Block () |
| ResBlock down |
| ResBlock |
| ResBlock down |
| ResBlock |
| ResBlock down |
| ResBlock |
| ResBlock down |
| ResBlock |
| ReLU, Global sum pooling |
| Embed() + (linear 1) |
表 9:512×512 的 BigGAN-deep 结构。
Appendix C Experimental Details
Our basic setup follows SA-GAN (Zhang et al. 2018), and is implemented in TensorFlow (Abadi et al. 2016). We employ the architectures detailed in Appendix B, with non-local blocks inserted at a single stage in each network. Both G and D networks are initialized with Orthogonal Initialization (Saxe et al. 2014). We use Adam optimizer (Kingma & Ba 2014) with and and a constant learning rate. For BigGAN models at all resolutions, we use in D and in G. For BigGAN-deep, we use the learning rate of in D and in G for models, and in both D and G for and models. We experimented with the number of D steps per G step (varying it from to ) and found that two D steps per G step gave the best results.
基本设定沿用 SA-GAN(Zhang 等 2018),在 TensorFlow(Abadi 等 2016)实现。结构见附录 B,非局部块在每个网络插入单阶段。G 与 D 均用正交初始化(Saxe 等 2014)。优化器用 Adam(Kingma & Ba 2014),、,恒定学习率。各分辨率 BigGAN:D 用 ,G 用 。BigGAN-deep:128×128 时 D/、G/;256 与 512 时两网络均为 。我们试过每步 G 对应 1–6 步 D,发现两步 D 一步 G 最好。
We use an exponential moving average of the weights of G at sampling time, with a decay rate set to 0.9999. We employ cross-replica BatchNorm (Ioffe & Szegedy 2015) in G, where batch statistics are aggregated across all devices, rather than a single device as in standard implementations. Spectral Normalization (Miyato et al. 2018) is used in both G and D, following SA-GAN (Zhang et al. 2018). We train on a Google TPU v3 Pod, with the number of cores proportional to the resolution: 128 for 128128, 256 for 256256, and 512 for 512512. Training takes between 24 and 48 hours for most models. We increase from the default to in BatchNorm and Spectral Norm to mollify low-precision numerical issues. We preprocess data by cropping along the long edge and rescaling to a given resolution with area resampling.
采样时对 G 权重用指数滑动平均,衰减 0.9999。G 采用跨副本 BatchNorm(Ioffe & Szegedy 2015),在全部设备上聚合批统计,而非标准实现的单设备。G 与 D 均用谱归一(Miyato 等 2018),沿用 SA-GAN。在 Google TPU v3 Pod 上训练,核数随分辨率:128 对应 128×128,256 对应 256×256,512 对应 512×512。多数模型 24–48 小时。为缓和低精度数值问题,把 BatchNorm 与谱归一中的 从默认 提到 。数据预处理:沿长边裁剪,再以面积重采样到目标分辨率。
C.1 BatchNorm Statistics and Sampling
The default behavior with batch normalized classifier networks is to use a running average of the activation moments at test time. Previous works (Radford et al. 2016) have instead used batch statistics when sampling images. While this is not technically an invalid way to sample, it means that results are dependent on the test batch size (and how many devices it is split across), and further complicates reproducibility.
批归一分类网络默认在测试时用激活矩的运行平均。先前工作(Radford 等 2016)采样图像时反而用批统计。这在技术上并非无效,但结果依赖测试批大小(以及如何拆到多设备),也更难复现。
We find that this detail is extremely important, with changes in test batch size producing drastic changes in performance. This is further exacerbated when one uses exponential moving averages of G’s weights for sampling, as the BatchNorm running averages are computed with non-averaged weights and are poor estimates of the activation statistics for the averaged weights.
我们发现这一细节极为关键:测试批大小一变,性能可剧烈波动。对采样使用 G 权重指数滑动平均时更糟——BatchNorm 运行平均是用非平均权重算的,对平均权重激活统计是差估计。
To counteract both these issues, we employ “standing statistics,” where we compute activation statistics at sampling time by running the G through multiple forward passes (typically 100) each with different batches of random noise, and storing means and variances aggregated across all forward passes. Analogous to using running statistics, this results in G’s outputs becoming invariant to batch size and the number of devices, even when producing a single sample.
为同时应对这两点,我们采用「standing statistics」:采样时让 G 用不同随机噪声批次多次前向(通常 100 次),跨全部前向聚合均值与方差并存储。类似运行统计,这使 G 输出对批大小与设备数不变,即便只产单张样本。
C.2 CIFAR-10
We run our networks on CIFAR-10 (Krizhevsky & Hinton 2009) using the settings from Table 1, row 8, and achieve an IS of 9.22 and an FID of 14.73 without truncation.
我们用表 1 第 8 行设定在 CIFAR-10(Krizhevsky & Hinton 2009)上跑网络,无截断时 IS 9.22、FID 14.73。
C.3 Inception Scores of ImageNet Images
We compute the IS for both the training and validation sets of ImageNet. At 128128 the training data has an IS of 233, and the validation data has an IS of 166. At 256256 the training data has an IS of 377, and the validation data has an IS of 234. At 512512 the training data has an IS of 348, and the validation data has an IS of 241. The discrepancy between training and validation scores is due to the Inception classifier having been trained on the training data, resulting in high-confidence outputs that are preferred by the Inception Score.
我们计算 ImageNet 训练与验证集的 IS。128×128:训练 233、验证 166;256×256:训练 377、验证 234;512×512:训练 348、验证 241。训练与验证分数差异,是因为 Inception 分类器在训练数据上训过,输出更自信,而 IS 偏好这种高置信输出。
Appendix D Additional Plots
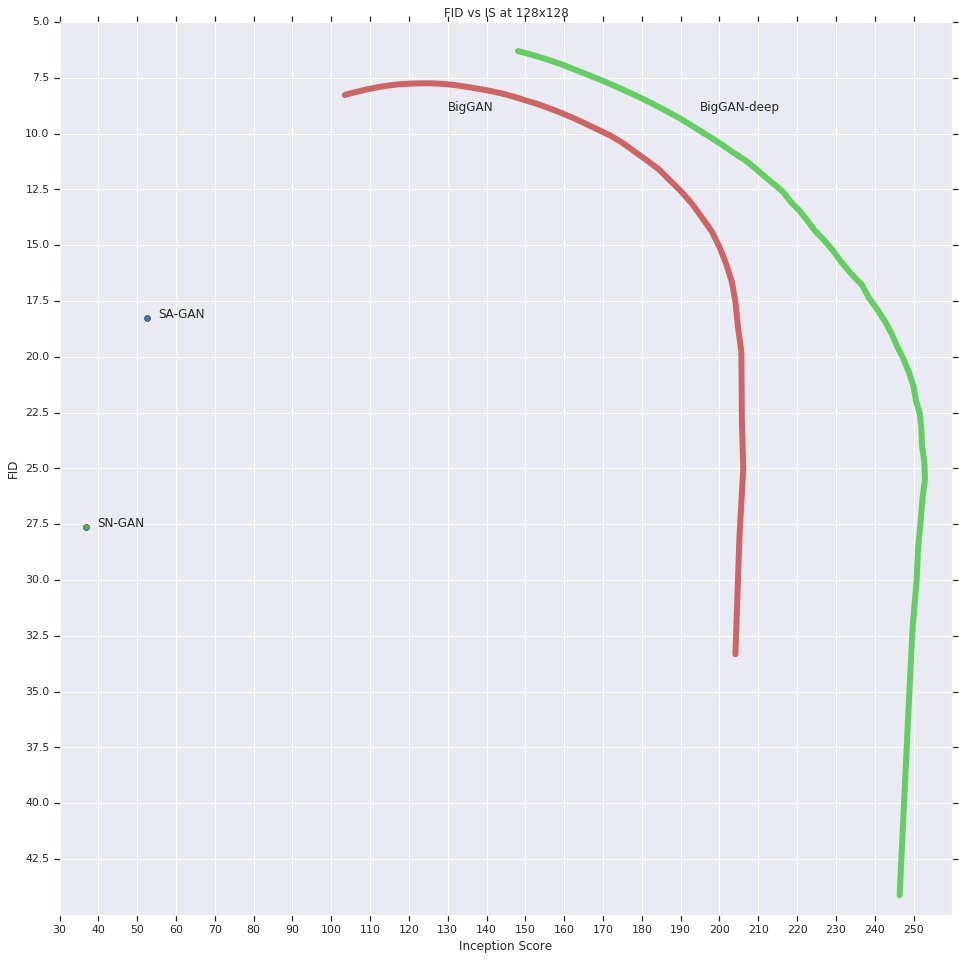
Figure 17: IS vs. FID at 128128. Scores are averaged across three random seeds.
图 17:128×128 上 IS 对 FID。分数跨三个随机种子平均。
Figure 18: IS vs. FID at 256 and 512 pixels. Scores are averaged across three random seeds for 256.
图 18:256 与 512 像素上 IS 对 FID。256 跨三个随机种子平均。
Figure 19: JFT-300M IS vs. FID at 256256. We show truncation values from to (top) and from to (bottom). Each curve corresponds to a row in Table 3. The curve labeled with baseline corresponds to the first row (with orthogonal regularization and other techniques disabled), while the rest correspond to rows 2-4 – the same architecture at different capacities (Ch).
图 19:JFT-300M 上 256×256 的 IS 对 FID。上图截断 到 ,下图 到 。每条曲线对应表 3 一行。标 baseline 的为第 1 行(关闭正交正则等技巧),其余对应第 2–4 行——同结构不同容量(Ch)。
Appendix E Choosing Latent Spaces
While most previous work has employed or as the prior for (the noise input to G), we are free to choose any latent distribution from which we can sample. We explore the choice of latents by considering an array of possible designs, described below. For each latent, we provide the intuition behind its design and briefly describe how it performs when used as a drop-in replacement for in an SA-GAN baseline. As the Truncation Trick proved more beneficial than switching to any of these latents, we do not perform a full ablation study, and employ for our main results to take full advantage of truncation. The two latents which we find to work best without truncation are Bernoulli and Censored Normal , both of which improve speed of training and lightly improve final performance, but are less amenable to truncation.
尽管既往多数工作用 或 作为 (G 的噪声输入)先验,我们可自由选择任何可采样的潜分布。下文给出一系列设计:每个潜空间说明设计直觉,并简述在 SA-GAN 基线中替换 的表现。因截断技巧收益大于切换这些潜空间,我们未做完整消融,主结果仍用 以充分发挥截断。无截断时表现最好的两种是 Bernoulli 与 Censored Normal ,二者加快训练并轻度抬最终性能,但对截断更不友好。
We also ablate the choice of latent space dimensonality (which by default is ), finding that we are able to successfully train with latent dimensions as low as , and that with we see a minimal drop in performance. While this is substantially smaller than many previous works, direct comparison to single-class networks (such as those in Karras et al. 2018, which employ a latent space on a highly constrained dataset with 30,000 images) is improper, as our networks have additional class information provided as input.
我们也消融潜空间维数(默认 ),发现可低至 仍成功训练, 时性能几乎不降。这远小于许多先前工作,但不宜直接与单类网络(如 Karras 等 2018 在约 3 万张高度约束数据上用 )对比,因为我们的网络还有类别信息输入。
Latents
- • . A standard choice of the latent space which we use in the main experiments.
- • 。主实验采用的标准潜空间。
- • . Another standard choice; we find that it performs similarly to .
- • 。另一标准选择;表现与 相近。
- • Bernoulli . A discrete latent might reflect our prior that underlying factors of variation in natural images are not continuous, but discrete (one feature is present, another is not). This latent outperforms (in terms of IS) by 8% and requires 60% fewer iterations.
- • Bernoulli 。离散潜变量可反映我们的先验:自然图像潜在变化因素未必连续,而是离散(某特征有或无)。相对 ,IS 约高 8%,迭代约少 60%。
- • , also called Censored Normal. This latent is designed to introduce sparsity in the latent space (reflecting our prior that certain latent features are sometimes present and sometimes not), but also allow those latents to vary continuously, expressing different degrees of intensity for latents which are active. This latent outperforms (in terms of IS) by 15-20% and tends to require fewer iterations.
- • ,亦称 Censored Normal。意在引入稀疏(反映某些潜特征时有时无),又允许激活者连续变化以表达强度。相对 ,IS 约高 15–20%,且往往迭代更少。
- • Bernoulli . This latent is designed to be discrete, but not sparse (as the network can learn to activate in response to negative inputs). This latent performs near-identically to .
- • Bernoulli 。离散但不稀疏(网络可对负输入激活)。表现与 几乎相同。
- • Independent Categorical in , with equal probability. This distribution is chosen to be discrete and have sparsity, but also to allow latents to take on both positive and negative values. This latent performs near-identically to .
- • 上独立等概率 Categorical。离散且稀疏,又允许正负取值。表现与 几乎相同。
- • multiplied by Bernoulli . This distribution is chosen to have continuous latent factors which are also sparse (with a peak at zero), similar to Censored Normal but not constrained to be positive. This latent performs near-identically to .
- • 乘 Bernoulli 。连续因子且稀疏(在零处峰值),类似 Censored Normal 但不强制非负。表现与 几乎相同。
- • Concatenating and Bernoulli , each taking half of the latent dimensions. This is inspired by Chen et al. 2016, and is chosen to allow some factors of variation to be discrete, while others are continuous. This latent outperforms by around 5%.
- • 拼接 与 Bernoulli ,各占一半潜维。受 Chen 等 2016 启发,允许部分因子离散、部分连续。相对 约高 5%。
- • Variance annealing: we sample from , where is allowed to vary over training. We compared a variety of piecewise schedules and found that starting with and annealing towards over the course of training mildly improved performance. The space of possible variance schedules is large, and we did not explore it in depth – we suspect that a more principled or better-tuned schedule could more strongly impact performance.
- • 方差退火:从 采样, 可随训练变化。比较多种分段日程后,发现从 退火到 轻度改善性能。可能的方差日程空间很大,我们未深入探索——更原则或更好调的日程或许影响更大。
- • Per-sample variable variance: , where independently for each sample in a batch, and are hyperparameters. This distribution was chosen to try and improve amenability to the Truncation Trick by feeding the network noise samples with non-constant variance. This did not appear to affect performance, but we did not explore it in depth. One might also consider scheduling , similar to variance annealing.
- • 逐样本可变方差:,其中批内每样本独立 , 为超参。意在通过非恒定方差噪声提升对截断技巧的耐受。似乎未影响性能,亦未深入。也可类似方差退火调度 。
Appendix F Monitored Training Statistics
| (a) G | (a) G | (b) G | (b) G | ||
|---|---|---|---|---|---|
| (a) G | |||||
| (b) G | |||||
| (c) G | (c) G | (d) G | (d) G | ||
| (c) G | |||||
| (d) G | |||||
| (e) D | (e) D | (f) D | (f) D | ||
| (e) D | |||||
| (f) D | |||||
| (g) D | (g) D | (h) D | (h) D | ||
| (g) D | |||||
| (h) D |
| (a) G |
| (b) G |
| (c) G |
| (d) G |
| (e) D |
| (f) D |
| (g) D |
| (h) D |
Figure 20: Training statistics for a typical model without special modifications. Collapse occurs after 200000 iterations.
图 20:无特殊改动的典型模型训练统计。约 200000 次迭代后崩溃。
| (a) | (a) | (b) | (b) | ||
|---|---|---|---|---|---|
| (a) | |||||
| (b) | |||||
| (c) | (c) | (d) | (d) | ||
| (c) | |||||
| (d) |
| (a) |
| (b) |
| (c) |
| (d) |
Figure 21: G training statistics with in G regularized towards 1. Collapse occurs after 125000 iterations.
图 21:G 训练统计,G 中 被正则向 1。约 125000 次迭代后崩溃。
| (a) | (a) | (b) | (b) | ||
|---|---|---|---|---|---|
| (a) | |||||
| (b) | |||||
| (c) | (c) | (d) | (d) | ||
| (c) | |||||
| (d) |
| (a) |
| (b) |
| (c) |
| (d) |
Figure 22: D training statistics with in G regularized towards 1. Collapse occurs after 125000 iterations.
图 22:D 训练统计,G 中 被正则向 1。约 125000 次迭代后崩溃。
| (a) | (a) | (b) | (b) | ||
|---|---|---|---|---|---|
| (a) | |||||
| (b) | |||||
| (c) | (c) | (d) | (d) | ||
| (c) | |||||
| (d) |
| (a) |
| (b) |
| (c) |
| (d) |
Figure 23: G training statistics with an R1 Gradient Penalty of strength 10 on D. This model does not collapse, but only reaches a maximum IS of 55.
图 23:G 训练统计,D 上 R1 梯度惩罚强度 10。模型不崩溃,但最高 IS 仅约 55。
| (a) | (a) | (b) | (b) | ||
|---|---|---|---|---|---|
| (a) | |||||
| (b) | |||||
| (c) | (c) | (d) | (d) | ||
| (c) | |||||
| (d) |
| (a) |
| (b) |
| (c) |
| (d) |
Figure 24: D training statistics with an R1 Gradient Penalty of strength 10 on D. This model does not collapse, but only reaches a maximum IS of 55.
图 24:D 训练统计,D 上 R1 梯度惩罚强度 10。模型不崩溃,但最高 IS 仅约 55。
| (a) | (a) | (b) | (b) | ||
|---|---|---|---|---|---|
| (a) | |||||
| (b) | |||||
| (c) | (c) | (d) | (d) | ||
| (c) | |||||
| (d) |
| (a) |
| (b) |
| (c) |
| (d) |
Figure 25: G training statistics with Dropout (keep probability 0.8) applied to the last feature layer of D. This model does not collapse, but only reaches a maximum IS of 70.
图 25:G 训练统计,对 D 末特征层施加 Dropout(保留概率 0.8)。模型不崩溃,但最高 IS 仅约 70。
| (a) | (a) | (b) | (b) | ||
|---|---|---|---|---|---|
| (a) | |||||
| (b) | |||||
| (c) | (c) | (d) | (d) | ||
| (c) | |||||
| (d) |
| (a) |
| (b) |
| (c) |
| (d) |
Figure 26: D training statistics with Dropout (keep probability 0.8) applied to the last feature layer of D. This model does not collapse, but only reaches a maximum IS of 70.
图 26:D 训练统计,对 D 末特征层施加 Dropout(保留概率 0.8)。模型不崩溃,但最高 IS 仅约 70。
| (a) G | | (a) G | (b) D | | (b) D |
|---|---|---|---|---|---|
| | | | | | |
| (a) G | | | | | |
| | | | | | |
| (b) D | | | | | |
| (c) losses | | (c) losses | (d) Variance of all gradient norms in G and D | | (d) Variance of all gradient norms in G and D |
| | | | | | |
| (c) losses | | | | | |
| | | | | | |
| (d) Variance of all gradient norms in G and D | | | | | |
| (a) G $\ |
| (b) D $\ |
| (c) losses |
| (d) Variance of all gradient norms in G and D |
Figure 27: Additional training statistics for a typical model without special modifications. Collapse occurs after 200000 iterations.
图 27:无特殊改动典型模型的额外训练统计。约 200000 次迭代后崩溃。
| (a) G | | (a) G | (b) D | | (b) D |
|---|---|---|---|---|---|
| | | | | | |
| (a) G | | | | | |
| | | | | | |
| (b) D | | | | | |
| (c) losses | | (c) losses | (d) Variance of all gradient norms in G and D | | (d) Variance of all gradient norms in G and D |
| | | | | | |
| (c) losses | | | | | |
| | | | | | |
| (d) Variance of all gradient norms in G and D | | | | | |
| (a) G $\ |
| (b) D $\ |
| (c) losses |
| (d) Variance of all gradient norms in G and D |
Figure 28: Additional training statistics with an R1 Gradient Penalty of strength 10 on D. This model does not collapse, but only reaches a maximum IS of 55.
图 28:D 上 R1 梯度惩罚强度 10 时的额外训练统计。模型不崩溃,但最高 IS 仅约 55。
Appendix G Additional Discussion: Stability and Collapse
In this section, we present and discuss additional investigations into the stability of our models, expanding upon the discussion in Section 4.
本节补充对模型稳定性的调查,扩展第 4 节讨论。
G.1 Intervening Before Collapse
The symptoms of collapse are sharp and sudden, with sample quality dropping from its peak to its lowest value over the course of a few hundred iterations. We can detect this collapse when the singular values in G explode, but while the (unnormalized) singular values grow throughout training, there is no consistent threshold at which collapse occurs. This raises the question of whether it is possible to prevent or delay collapse by taking a model checkpoint several thousand iterations before collapse, and continuing training with some hyperparameters modified (e.g., the learning rate).
崩溃症状尖锐突然:样本质量可在几百次迭代内从峰值跌到谷底。G 奇异值爆炸时可检测到崩溃,但(未归一)奇异值训练中持续增长,并无一致阈值。于是要问:能否在崩溃前数千迭代取检查点,改若干超参(如学习率)继续训,从而阻止或推迟崩溃?
We conducted a range of intervention experiments wherein we took checkpoints of a collapsed model ten or twenty thousand iterations before collapse, changed some aspect of the training setup, then observed whether collapse occurred, when it occurred relative to the original collapse, and the final performance attained at collapse.
我们做了一系列干预实验:取崩溃模型在崩溃前一万或两万迭代的检查点,改动训练设定某一方面,再观察是否崩溃、相对原崩溃推迟多久,以及崩溃时最终性能。
We found that increasing the learning rates (relative to their initial values) in either G or D, or both G and D, led to immediate collapse. This occurred even when doubling the learning rates from in D and in G, to in D and in G, a setting which is not normally unstable when used as the initial learning rates. We also tried changing the momentum terms (Adam’s and ), or resetting the momentum vectors to zero, but this tended to either make no difference or, when increasing the momentum, cause immediate collapse.
发现相对初值提高 G 或 D(或二者)的学习率会导致立即崩溃。即便把 D 从 、G 从 翻到 与 ——若作为初始学习率本不通常失稳——也会立刻崩溃。我们也试过改动量项(Adam 的 、)或把动量向量清零:要么几乎无效,要么在加大动量时立即崩溃。
We found that decreasing the learning rate in G, but keeping the learning rate in D unchanged could delay collapse (in some cases by over one hundred thousand iterations), but also crippled training—once the learning rate in G was decayed, performance either stayed constant or slowly decayed. Conversely, reducing the learning rate in D while keeping G’s learning rate led to immediate collapse. We hypothesize that this is because of the need for D to remain optimal throughout training—if its learning rate is reduced, it can no longer “keep up” with G, and training collapses. With this in mind, we also tried increasing the number of D steps per G step, but this either had no effect, or delayed collapse at the cost of crippling training (similar to decaying G’s learning rate).
发现降低 G 学习率、保持 D 不变可推迟崩溃(有时超过十万迭代),但也废掉训练——G 学习率衰减后,性能持平或缓慢下滑。反之,降 D、保持 G 则立即崩溃。我们猜测是因为全程需要 D 相对最优:学习率一降就跟不上 G,训练崩溃。据此我们也试过增加每步 G 对应的 D 步数:要么无效,要么以废掉训练为代价推迟崩溃(类似衰减 G 学习率)。
To further illuminate these dynamics, we construct two additional intervention experiments, one where we freeze G before collapse (by ceasing all parameter updates) and observe whether D remains stable, and the reverse, where we freeze D before collapse and observe whether G remains stable. We find that when G is frozen, D remains stable, and slowly reduces both components of its loss towards zero. However, when D is frozen, G immediately and dramatically collapses, maxing out D’s loss to values upwards of 300, compared to the normal range of 0 to 3.
为进一步照亮这些动态,我们再做两类干预:崩溃前冻结 G(停止全部参数更新)观察 D 是否仍稳;以及反过来冻结 D 观察 G。冻结 G 时 D 保持稳定,缓慢把两项损失压向零;冻结 D 时 G 立刻剧烈崩溃,把 D 损失顶到 300 以上,而正常范围约 0–3。
This leads to two conclusions: first, as has been noted in previous works (Miyato et al. 2018; Gulrajani et al. 2017; Zhang et al. 2018), D must remain optimal with respect to G both for stability and to provide useful gradient information. The consequence of G being allowed to win the game is a complete breakdown of the training process, regardless of G’s conditioning or optimization settings. Second, favoring D over G (either by training it with a larger learning rate, or for more steps) is insufficient to ensure stability even if D is well-conditioned. This suggests either that in practice, an optimal D is necessary but insufficient for training stability, or that some aspect of the system results in D not being trained towards optimality. With the latter possibility in mind, we take a closer look at the noise in D’s spectra in the following section.
由此得两点结论:其一,如既往工作所述(Miyato 等 2018;Gulrajani 等 2017;Zhang 等 2018),D 必须相对 G 保持最优,既为稳定,也为提供有用梯度;若允许 G「赢下比赛」,训练过程会彻底崩盘,与 G 的条件或优化设定无关。其二,偏袒 D(更大学习率或更多步数)即使 D 条件良好,也不足以保证稳定。这说明实践中最优 D 对稳定必要却不充分,或系统中某因素使 D 并未朝最优训练。带着后一可能,下一节更仔细看 D 谱中的噪声。
G.2 Spikes in the Discriminator’s Spectra
| (a) D | (a) D | (b) D | (b) D | ||
|---|---|---|---|---|---|
| (a) D | |||||
| (b) D |
| (a) D |
| (b) D |
Figure 29: A closeup of D’s spectra at a noise spike.
图 29:D 谱在噪声尖峰处的特写。
If some element of D’s training process results in undesirable dynamics, it follows that the behavior of D’s spectra may hold clues as to what that element is. The top three singular values of D differ from G’s in that they have a large noise component, tend to grow throughout training but only show a small response to collapse, and the ratio of the first two singular values tends to be centered around one, suggesting that the spectra of D have a slow decay. When viewed up close (Figure 29), the noise spikes resemble an impulse response: at each spike, the spectra jump upwards, then slowly decrease, with some oscillation.
若 D 训练中某要素导致不良动态,则其谱行为可能提供线索。D 前三个奇异值相对 G 噪声更大,训练中增长但对崩溃反应较小,且前两奇异值之比常以一为中心,暗示谱衰减缓慢。放大看(图 29),噪声尖峰像冲激响应:每次尖峰谱上跳,再缓慢下降并带振荡。
One possible explanation is that this behavior is a consequence of D memorizing the training data, as suggested by experiments in Section 4.2. As it approaches perfect memorization, it receives less and less signal from real data, as both the original GAN loss and the hinge loss provide zero gradients when D outputs a confident and correct prediction for a given example. If the gradient signal from real data attenuates to zero, this can result in D eventually becoming biased due to exclusively received gradients that encourage its outputs to be negative. If this bias passes a certain threshold, D will eventually misclassify a large number of real examples and receive a large gradient encouraging positive outputs, resulting in the observed impulse responses.
一种解释是这来自 D 记忆训练数据(第 4.2 节实验已提示)。接近完美记忆时,来自真实数据的信号越来越弱——原始 GAN 损失与 hinge 损失在 D 对某例自信且正确时梯度为零。若真实数据梯度衰减至零,D 可能因只收到鼓励输出为负的梯度而逐渐偏置;偏置过阈值后会大批误判真实样本,再收到鼓励输出为正的大梯度,形成观察到的冲激响应。
This argument suggests several fixes. First, one might consider an unbounded loss (such as the Wasserstein loss (Arjovsky et al. 2017)) which would not suffer this gradient attentuation. We found that even with gradient penalties and brief re-tuning of optimizer hyperparameters, our models did not stably train for more than a few thousand iterations with this loss. We instead explored changing the margin of the hinge loss as a partial compromise: for a given model and minibatch of data, increasing the margin will result in more examples falling within the margin, and thus contributing to the loss.[^3]. Training with a smaller margin (by a factor of 2) measurably reduces performance, but training with a larger margin (by up to a factor of 3) does not prevent collapse or reduce the noise in D’s spectra. Increasing the margin beyond 3 results in unstable training similar to using the Wasserstein loss. Finally, the memorization argument might suggest that using a smaller D or using dropout in D would improve training by reducing its capacity to memorize, but in practice this degrades training.
这一论证提示若干修补。其一可用无界损失(如 Wasserstein 损失,Arjovsky 等 2017)避免该梯度衰减。即便加梯度惩罚并短暂重调优化器超参,我们的模型用该损失也撑不过几千迭代。于是折中改 hinge 损失边界:对给定模型与小批,加大边界会使更多样本落入边界内并贡献损失[^3]。边界缩小到 1/2 会明显降性能;放大到 3 倍仍不能阻止崩溃或降低 D 谱噪声;超过 3 则像 Wasserstein 一样失稳。记忆论或许还暗示缩小 D 或在 D 用 dropout 以降低记忆容量,实践中却会损害训练。
Appendix H Negative Results
We explored a range of novel and existing techniques which ended up degrading or otherwise not affecting performance in our setting. We report them here; our evaluations for this section are not as thorough as those for the main architectural choices.
我们探索过一批新方法和已有技术,在本设定下最终损害性能或无明显影响。报告于此;本节评估不如主结构选择那么彻底。
Our intention in reporting these results is to save time for future work, and to give a more complete picture of our attempts to improve performance or stability. We note, however, that these results must be understood to be specific to the particular setup we used. A pitfall of reporting negative results is that one might report that a particular technique doesn’t work, when the reality is that this technique did not have the desired effect when applied in a particular way to a particular problem. Drawing overly general conclusions might close off potentially fruitful avenues of research.
报告这些结果意在为后续工作省时间,并更完整呈现我们为提升性能或稳定性所做的尝试。但须强调:结果绑定于我们所用的具体设定。报告阴性结果的风险是:可能宣称某技术「不行」,实际只是以特定方式用于特定问题时未达预期。过度概括可能关掉本可结果实的研究方向。
- • We found that doubling the depth (by inserting an additional Residual block after every up- or down-sampling block) hampered performance.
- • 发现把深度翻倍(在每个上/下采样块后插入额外残差块)会损害性能。
- • We experimented with sharing class embeddings between both G and D (as opposed to just within G). This is accomplished by replacing D’s class embedding with a projection from G’s embeddings, as is done in G’s BatchNorm layers. In our initial experiments this seemed to help and accelerate training, but we found this trick scaled poorly and was sensitive to optimization hyperparameters, particularly the choice of number of D steps per G step.
- • 试过在 G 与 D 之间共享类嵌入(而不只在 G 内共享):用从 G 嵌入的投影替换 D 的类嵌入,类似 G 的 BatchNorm 层。初期实验似有帮助并加速训练,但扩展性差,且对优化超参敏感,尤其是每步 G 对应多少步 D。
- • We tried replacing BatchNorm in G with WeightNorm (Salimans & Kingma 2016), but this crippled training. We also tried removing BatchNorm and only having Spectral Normalization, but this also crippled training.
- • 试过用 WeightNorm(Salimans & Kingma 2016)替换 G 中 BatchNorm,训练废掉;也试过去掉 BatchNorm 只留谱归一,同样废掉。
- • We tried adding BatchNorm to D (both class-conditional and unconditional) in addition to Spectral Normalization, but this crippled training.
- • 试过在 D 上于谱归一之外再加 BatchNorm(类别条件或无条件),训练废掉。
- • We tried varying the choice of location of the attention block in G and D (and inserting multiple attention blocks at different resolutions) but found that at 128128 there was no noticeable benefit to doing so, and compute and memory costs increased substantially. We found a benefit to moving the attention block up one stage when moving to 256256, which is in line with our expectations given the increased resolution.
- • 试过改变 G、D 注意力块位置(及在不同分辨率插入多块),在 128×128 无明显收益,算力与显存却大幅上升。升到 256×256 时把注意力上移一级有收益,与分辨率提高后的预期一致。
- • We tried using filter sizes of 5 or 7 instead of 3 in either G or D or both. We found that having a filter size of 5 in G only provided a small improvement over the baseline but came at an unjustifiable compute cost. All other settings degraded performance.
- • 试过在 G 或 D 或二者用 5 或 7 代替 3 的卷积核。仅 G 用 5 相对基线有小幅改善,但算力代价不合理;其余设定损害性能。
- • We tried varying the dilation for convolutional filters in both G and D at 128128, but found that even a small amount of dilation in either network degraded performance.
- • 在 128×128 上改变 G、D 卷积膨胀率,即使很小膨胀也损害性能。
- • We tried bilinear upsampling in G in place of nearest-neighbors upsampling, but this degraded performance.
- • 试过用双线性上采样替换 G 中最近邻上采样,损害性能。
- • In some of our models, we observed class-conditional mode collapse, where the model would only output one or two samples for a subset of classes but was still able to generate samples for all other classes. We noticed that the collapsed classes had embedings which had become very large relative to the other embeddings, and attempted to ameliorate this issue by applying weight decay to the shared embedding only. We found that small amounts of weight decay () instead degraded performance, and that only even smaller values () did not degrade performance, but these values were also too small to prevent the class vectors from exploding. Higher-resolution models appear to be more resilient to this problem, and none of our final models appear to suffer from this type of collapse.
- • 部分模型出现类别条件模态崩塌:对子集类只输出一两个样本,其他类仍可生成。崩塌类的嵌入相对其他嵌入变得很大;我们尝试只对共享嵌入加权重衰减。小量衰减()反而损害性能;更小()不损害性能,却也太小、挡不住类向量爆炸。更高分辨率模型对此更韧,我们最终模型似乎未受此类崩塌困扰。
- • We experimented with using MLPs instead of linear projections from G’s class embeddings to its BatchNorm gains and biases, but did not find any benefit to doing so. We also experimented with Spectrally Normalizing these MLPs, and with providing these (and the linear projections) with a bias at their output, but did not notice any benefit.
- • 试过用 MLP 代替从 G 类嵌入到 BatchNorm 增益/偏置的线性投影,未见收益;也对 MLP 做谱归一,并在其(及线性投影)输出加偏置,未见收益。
- • We tried gradient norm clipping (both the global variant typically used in recurrent networks, and a local version where the clipping value is determined on a per-parameter basis) but found this did not alleviate instability.
- • 试过梯度范数裁剪(循环网络常用的全局版,以及按参数确定裁剪值的局部版),未能缓解不稳定。
Appendix I Hyperparameters
We performed various hyperparameter sweeps in this work:
本文做了多种超参扫描:
- • We swept the Cartesian product of the learning rates for each network through [, , , , , , ], and initially found that the SA-GAN settings (G’s learning rate , D’s learning rate ) were optimal at lower batch sizes; we did not repeat this sweep at higher batch sizes but did try halving and doubling the learning rate, arriving at the halved settings used for our experiments.
- • 对两网络学习率在 [, , , , , , ] 上做笛卡尔积扫描;初期发现低批大小时 SA-GAN 设定(G 、D )最优;高批大小未重扫,但试过减半与加倍,最终采用实验中的减半设定。
- • We swept the R1 gradient penalty strength through [, , , , , , , , ]. We find that the strength of the penalty correlates negatively with performance, but that settings above impart training stability.
- • 对 R1 梯度惩罚强度扫描 [, , , , , , , , ]。惩罚强度与性能负相关,但高于 可带来训练稳定。
- • We swept the keep probabilities for DropOut in the final layer of D through [, , , , , ]. We find that DropOut has a similar stabilizing effect to R1 but also degrades performance.
- • 对 D 末层 DropOut 保留概率扫描 [, , , , , ]。DropOut 稳定效果类似 R1,同样损害性能。
- • We swept D’s Adam parameter through [, , , , ] and found it to have a light regularization effect similar to DropOut, but not to significantly improve results. Higher terms in either network crippled training.
- • 对 D 的 Adam 扫描 [, , , , ],有类似 DropOut 的轻度正则效果,但未显著提升结果。任一网络更高 都会废掉训练。
- • We swept the strength of the modified Orthogonal Regularization penalty in G through [, , , , , ], and selected .
- • 对 G 中修改版正交正则惩罚强度扫描 [, , , , , ],选定 。