Big Bird: Transformers for Longer Sequences
Big Bird: Transformers for Longer Sequences
Big Bird:面向更长序列的 Transformer
Manzil Zaheer Guru Guruganesh Avinava Dubey Affiliation: Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Affiliation: Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed Affiliation: Google Research Affiliation: {manzilz, gurug, avinavadubey}@google.com
Abstract
摘要
Transformers-based models, such as BERT, have been one of the most successful deep learning models for NLP. Unfortunately, one of their core limitations is the quadratic dependency (mainly in terms of memory) on the sequence length due to their full attention mechanism. To remedy this, we propose, BigBird, a sparse attention mechanism that reduces this quadratic dependency to linear. We show that BigBird is a universal approximator of sequence functions and is Turing complete, thereby preserving these properties of the quadratic, full attention model. Along the way, our theoretical analysis reveals some of the benefits of having global tokens (such as CLS), that attend to the entire sequence as part of the sparse attention mechanism. The proposed sparse attention can handle sequences of length up to 8x of what was previously possible using similar hardware. As a consequence of the capability to handle longer context, BigBird drastically improves performance on various NLP tasks such as question answering and summarization. We also propose novel applications to genomics data.
以 BERT 为代表的 Transformer 模型是 NLP 最成功的深度学习模型之一。其核心局限是全注意力对序列长度的二次依赖(主要体现在显存)。为此我们提出 BigBird:一种把二次依赖降为线性的稀疏注意力机制。我们证明 BigBird 是序列函数的通用逼近器且图灵完备,从而保留二次全注意力模型的这些性质。理论分析还揭示:在稀疏注意力中加入 个全局 token(如 CLS)并让其关注整段序列的若干好处。所提稀疏注意力在相近硬件上可处理此前约 8 倍长度的序列。因能建模更长上下文,BigBird 在问答与摘要等多项 NLP 任务上大幅提升表现。我们还提出面向基因组数据的新应用。
1 Introduction
1 引言
Models based on Transformers [91], such as BERT [22, 63], are wildly successful for a wide variety of Natural Language Processing (NLP) tasks and consequently are mainstay of modern NLP research. Their versatility and robustness are the primary drivers behind the wide-scale adoption of Transformers. The model is easily adapted for a diverse range of sequence based tasks – as a seq2seq model for translation [91], summarization [66], generation [15], etc. or as a standalone encoders for sentiment analysis [83], POS tagging [65], machine reading comprehension [93], etc. – and it is known to vastly outperform previous sequence models like LSTM [37]. The key innovation in Transformers is the introduction of a self-attention mechanism, which can be evaluated in parallel for each token of the input sequence, eliminating the sequential dependency in recurrent neural networks, like LSTM. This parallelism enables Transformers to leverage the full power of modern SIMD hardware accelerators like GPUs/TPUs, thereby facilitating training of NLP models on datasets of unprecedented size. This ability to train on large scale data has led to surfacing of models like BERT [22] and T5 [75], which pretrain transformers on large general purpose corpora and transfer the knowledge to down-stream task. The pretraining has led to significant improvement in low data regime downstream tasks [51] as well as tasks with sufficient data [101] and thus have been a major force behind the ubiquity of transformers in contemporary NLP.
以 Transformer [91] 为基础的模型,如 BERT [22, 63],在广泛 NLP 任务上极为成功,已成为现代 NLP 研究的主流。其通用性与稳健性是大规模采用的主要动力。模型易于适配多样的序列任务——作为翻译 [91]、摘要 [66]、生成 [15] 等的 seq2seq,或作为情感分析 [83]、词性标注 [65]、机器阅读理解 [93] 等的独立编码器——并显著优于 LSTM [37] 等既往序列模型。Transformer 的关键创新是自注意力:可对输入序列每个 token 并行计算,消除 LSTM 一类 RNN 的序列依赖。该并行性使 Transformer 能充分发挥 GPU/TPU 等现代 SIMD 加速器的能力,从而在前所未有规模的数据集上训练 NLP 模型。大规模训练催生了 BERT [22] 与 T5 [75] 等模型:在通用语料上预训练 Transformer,再把知识迁移到下游任务。预训练既提升低数据下游任务 [51],也提升数据充足的任务 [101],是 Transformer 在当代 NLP 中无处不在的重要原因。
The self-attention mechanism overcomes constraints of RNNs (namely the sequential nature of RNN) by allowing each token in the input sequence to attend independently to every other token in the sequence. This design choice has several interesting repercussions. In particular, the full self-attention have computational and memory requirement that is quadratic in the sequence length. We note that while the corpus can be large, the sequence length, which provides the context in many applications is very limited. Using commonly available current hardware and model sizes, this requirement translates to roughly being able to handle input sequences of length 512 tokens. This reduces its direct applicability to tasks that require larger context, like QA [60], document classification, etc.
自注意力克服 RNN 的序列性约束:输入序列中每个 token 可独立关注序列中每一个其他 token。这一设计选择带来若干后果。尤其是,全自注意力的计算与显存需求相对序列长度二次。我们注意到:语料可以很大,但许多应用提供上下文的序列长度非常有限。按常见硬件与模型规模,这大约只能处理 512 token 的输入。从而难以直接用于需要更长上下文的任务,如问答 [60]、文档分类等。
However, while we know that self-attention and Transformers are useful, our theoretical understanding is rudimentary. What aspects of the self-attention model are necessary for its performance? What can we say about the expressivity of Transformers and similar models? Apriori, it was not even clear from the design if the proposed self-attention mechanism was as effective as RNNs. For example, the self-attention does not even obey sequence order as it is permutation equivariant. This concern has been partially resolved, as Yun et al. 2019 showed that transformers are expressive enough to capture all continuous sequence to sequence functions with a compact domain. Meanwhile, Pérez et al. 2019 showed that the full transformer is Turing Complete (i.e. can simulate a full Turing machine). Two natural questions arise: Can we achieve the empirical benefits of a fully quadratic self-attention scheme using fewer inner-products? Do these sparse attention mechanisms preserve the expressivity and flexibility of the original network?
我们知道自注意力与 Transformer 有用,但理论理解仍粗糙。自注意力模型的哪些方面对其表现必要?Transformer 及类似模型的表达力如何?从设计上看,先验上甚至不清楚所提自注意力是否与 RNN 一样有效。例如,自注意力对置换等变,并不服从序列顺序。这一担忧已部分消解:Yun 等人 2019 表明 Transformer 足以刻画紧致定义域上所有连续序列到序列函数;Pérez 等人 2019 表明完整 Transformer 图灵完备(可模拟完整图灵机)。自然产生两个问题:能否用更少的内积获得全二次自注意力方案的经验收益?这些稀疏注意力机制是否保留原网络的表达力与灵活性?
In this paper, we address both the above questions and produce a sparse attention mechanism that improves performance on a multitude of tasks that require long contexts. We systematically develop BigBird, an attention mechanism whose complexity is linear in the number of tokens (Section 2). We take inspiration from graph sparsification methods and understand where the proof for expressiveness of Transformers breaks down when full-attention is relaxed to form the proposed attention pattern. This understanding helped us develop BigBird, which is theoretically as expressive and also empirically useful. In particular, our BigBird consists of three main part:
本文同时回答上述问题,并提出一种在众多需要长上下文的任务上提升表现的稀疏注意力机制。我们系统发展 BigBird:复杂度对 token 数线性的注意力机制(第 2 节)。我们从图稀疏化方法汲取灵感,并理解当全注意力放松为所提注意力模式时,Transformer 表达力证明在何处失效。这一理解帮助我们发展出理论上同样有表达力、经验上也有用的 BigBird。具体而言,BigBird 主要由三部分构成:
- • A set of global tokens attending on all parts of the sequence.
- • 一组 个全局 token,关注序列的所有部分。
- • All tokens attending to a set of local neighboring tokens.
- • 所有 token 关注一组 个局部邻域 token。
- • All tokens attending to a set of random tokens.
- • 所有 token 关注一组 个随机 token。
This leads to a high performing attention mechanism scaling to much longer sequence lengths (8x).
由此得到可扩展到更长序列长度(8 倍)的高性能注意力机制。
To summarize, our main contributions are:
总结一下,我们的主要贡献是:
- BigBird satisfies all the known theoretical properties of full transformer (Section 3). In particular, we show that adding extra tokens allows one to express all continuous sequence to sequence functions with only -inner products. Furthermore, we show that under standard assumptions regarding precision, BigBird is Turing complete.
- BigBird 满足全 Transformer 的全部已知理论性质(第 3 节)。特别地,我们证明加入额外 token 后,仅用 次内积即可表达所有连续序列到序列函数。进一步,在关于精度的标准假设下,BigBird 图灵完备。
- Empirically, we show that the extended context modelled by BigBird benefits variety of NLP tasks. We achieve state of the art results for question answering and document summarization on a number of different datasets. Summary of these results are presented in Section 4.
- 经验上,我们表明 BigBird 建模的扩展上下文有益于多种 NLP 任务。我们在若干不同数据集的问答与文档摘要上取得当时最优结果。结果摘要见第 4 节。
- Lastly, we introduce a novel application of attention based models where long contexts are beneficial: extracting contextual representations of genomics sequences like DNA. With longer masked LM pretraining, BigBird improves performance on downstream tasks such as promoter-region and chromatin profile prediction (Section 5).
- 最后,我们引入注意力模型在长上下文有益的新应用:提取 DNA 等基因组序列的上下文化表示。借助更长的掩码语言模型预训练,BigBird 提升启动子区域与染色质图谱预测等下游任务表现(第 5 节)。
1.1 Related Work
1.1 相关工作
There have been a number of interesting attempts, that were aimed at alleviating the quadratic dependency of Transformers, which can broadly categorized into two directions. First line of work embraces the length limitation and develops method around it. Simplest methods in this category just employ sliding window [93], but in general most work fits in the following general paradigm: using some other mechanism select a smaller subset of relevant contexts to feed in the transformer and optionally iterate, i.e. call transformer block multiple time with different contexts each time. Most prominently, SpanBERT [42], ORQA [54], REALM [34], RAG [57] have achieved strong performance for different tasks. However, it is worth noting that these methods often require significant engineering efforts (like back prop through large scale nearest neighbor search) and are hard to train.
缓解 Transformer 二次依赖已有许多有趣尝试,大致可分两个方向。第一类接受长度限制并在其周围发展方法。最简单的是只用滑动窗口 [93],但多数工作符合如下范式:用其他机制选出更小的相关上下文子集送入 Transformer,并可选地迭代——即用不同上下文多次调用 Transformer 块。最突出的是 SpanBERT [42]、ORQA [54]、REALM [34]、RAG [57] 在不同任务上取得强表现。不过这些方法往往需要显著工程投入(如对大规模近邻搜索反向传播),且难以训练。
Second line of work questions if full attention is essential and have tried to come up with approaches that do not require full attention, thereby reducing the memory and computation requirements. Prominently, Dai et al. 2019, Sukhbaatar et al. 2019, Rae et al. 2019 have proposed auto-regresive models that work well for left-to-right language modeling but suffer in tasks which require bidirectional context. Child et al. 2019 proposed a sparse model that reduces the complexity to , Kitaev et al. 2019 further reduced the complexity to by using LSH to compute nearest neighbors. Ye et al. 2019 proposed binary partitions of the data where as Qiu et al. 2019 reduced complexity by using block sparsity. Recently, Longformer [8] introduced a localized sliding window based mask with few global mask to reduce computation and extended BERT to longer sequence based tasks. Finally, our work is closely related to and built on the work of Extended Transformers Construction [4]. This work was designed to encode structure in text for transformers. The idea of global tokens was used extensively by them to achieve their goals. Our theoretical work can be seen as providing a justification for the success of these models as well. It is important to note that most of the aforementioned methods are heuristic based and empirically are not as versatile and robust as the original transformer, i.e. the same architecture do not attain SoTA on multiple standard benchmarks. (There is one exception of Longformer which we include in all our comparisons, see Section E.3 for a more detailed comparison). Moreover, these approximations do not come with theoretical guarantees.
第二类质疑全注意力是否必要,并尝试不需要全注意力的方法,从而降低显存与计算。突出地,Dai 等人 2019、Sukhbaatar 等人 2019、Rae 等人 2019 提出对从左到右语言建模效果好的自回归模型,但在需要双向上下文的任务上吃亏。Child 等人 2019 提出把复杂度降到 的稀疏模型;Kitaev 等人 2019 用 LSH 算近邻进一步降到 。Ye 等人 2019 提出数据的二分划分,Qiu 等人 2019 用块稀疏降低复杂度。近期 Longformer [8] 引入带少量全局掩码的局部滑动窗口掩码以降低计算,并把 BERT 扩展到更长序列任务。最后,我们的工作与 Extended Transformers Construction [4] 密切相关并建立其上。该工作旨在为 Transformer 编码文本结构,大量使用全局 token。我们的理论工作也可视为为这些模型的成功提供辩护。重要的是,上述方法多数基于启发式,经验上不如原始 Transformer 通用稳健,即同一架构难以在多个标准基准上同时达到 SoTA。(Longformer 是一个例外,我们在全部比较中纳入,更细比较见第 E.3 节。)而且这些近似没有理论保证。
(a) Random attention
(a) 随机注意力
2 BigBird Architecture
2 BigBird 架构
In this section, we describe the BigBird model using the generalised attention mechanism that is used in each layer of transformer operating on an input sequence . The generalized attention mechanism is described by a directed graph whose vertex set is . The set of arcs (directed edges) represent the set of inner products that the attention mechanism will consider. Let denote the out-neighbors set of node in , then the output vector of the generalized attention mechanism is defined as
本节描述 BigBird 模型,以及作用于输入序列 的 Transformer 每层所用的广义注意力机制。广义注意力由有向图 描述,其顶点集为 。弧(有向边)集合表示注意力将考虑的内积集合。记 为 中节点 的出邻域,则广义注意力的第 个输出向量定义为
where are query and key functions respectively, is a value function, is a scoring function (e.g. softmax or hardmax) and denotes the number of heads. Also note corresponds to the matrix formed by only stacking and not all the inputs. If is the complete digraph, we recover the full quadratic attention mechanism of Vaswani et al. 2017. To simplify our exposition, we will operate on the adjacency matrix of the graph even though the underlying graph maybe sparse. To elaborate, with if query attends to key and is zero otherwise. For example, when is the ones matrix (as in BERT), it leads to quadratic complexity, since all tokens attend on every other token. This view of self-attention as a fully connected graph allows us to exploit existing graph theory to help reduce its complexity. The problem of reducing the quadratic complexity of self-attention can now be seen as a graph sparsification problem. It is well-known that random graphs are expanders and can approximate complete graphs in a number of different contexts including in their spectral properties [80, 38]. We believe sparse random graph for attention mechanism should have two desiderata: small average path length between nodes and a notion of locality, each of which we discuss below.
其中 分别为查询与键函数, 为值函数, 为打分函数(如 softmax 或 hardmax), 为头数。注意 对应仅堆叠 而非全部输入形成的矩阵。若 为完全有向图,则恢复 Vaswani 等人 2017 的全二次注意力。为简化叙述,即使底层图稀疏,我们也在图 的邻接矩阵 上操作。具体地,,若查询 关注键 则 ,否则为 0。例如当 为全 1 矩阵(如 BERT)时复杂度二次,因为所有 token 互相关注。把自注意力看成全连接图,使我们能利用既有图论降低其复杂度。降低自注意力二次复杂度的问题于是可视为图稀疏化问题。众所周知,随机图是扩展器,可在多种语境——包括谱性质——上逼近完全图 [80, 38]。我们相信用于注意力的稀疏随机图应满足两点期望:节点间平均路径长度小,以及某种局部性;下文分别讨论。
Let us consider the simplest random graph construction, known as Erdős-Rényi model, where each edge is independently chosen with a fixed probability. In such a random graph with just edges, the shortest path between any two nodes is logarithmic in the number of nodes [17, 43]. As a consequence, such a random graph approximates the complete graph spectrally and its second eigenvalue (of the adjacency matrix) is quite far from the first eigenvalue [9, 10, 6]. This property leads to a rapid mixing time for random walks in the grpah, which informally suggests that information can flow fast between any pair of nodes. Thus, we propose a sparse attention where each query attends over random number of keys i.e. for randomly chosen keys (see Figure 1(a)).
考虑最简单的随机图构造——Erdős-Rényi 模型:每条边以固定概率独立选取。此类随机图仅需 条边时,任意两节点最短路径相对节点数成对数 [17, 43]。因此,此类随机图在谱上逼近完全图,邻接矩阵第二特征值远离第一特征值 [9, 10, 6]。该性质使图上随机游走混合迅速,非正式地说,信息可在任意节点对之间快速流动。于是我们提出稀疏注意力:每个查询关注 个随机键,即对随机选取的 个键令 (见图 1(a))。
The second viewpoint which inspired the creation of BigBird is that most contexts within NLP and computational biology have data which displays a great deal of locality of reference. In this phenomenon, a great deal of information about a token can be derived from its neighboring tokens. Most pertinently, Clark et al. 2019 investigated self-attention models in NLP tasks and concluded that that neighboring inner-products are extremely important. The concept of locality, proximity of tokens in linguistic structure, also forms the basis of various linguistic theories such as transformational-generative grammar. In the terminology of graph theory, clustering coefficient is a measure of locality of connectivity, and is high when the graph contains many cliques or near-cliques (subgraphs that are almost fully interconnected). Simple Erdős-Rényi random graphs do not have a high clustering coefficient [84], but a class of random graphs, known as small world graphs, exhibit high clustering coefficient [94]. A particular model introduced by Watts and Strogatz 1998 is of high relevance to us as it achieves a good balance between average shortest path and the notion of locality. The generative process of their model is as follows: Construct a regular ring lattice, a graph with nodes each connected to neighbors, /2 on each side.
启发 BigBird 的第二视角是:NLP 与计算生物学中的多数上下文数据表现出很强的引用局部性。在此现象中,关于某 token 的大量信息可从其邻域 token 导出。最切题的是,Clark 等人 2019 考察 NLP 任务中的自注意力模型,结论是邻域内积极为重要。局部性——语言结构中 token 的邻近——也构成转换生成语法等多种语言学理论的基础。在图论术语中,聚类系数度量连接的局部性;当图含许多团或近团(几乎全互连的子图)时聚类系数高。简单 Erdős-Rényi 随机图聚类系数不高 [84],但一类称为小世界图的随机图表现出高聚类系数 [94]。Watts 与 Strogatz 1998 引入的特定模型与我们高度相关:它在平均最短路径与局部性之间取得良好平衡。其生成过程如下:构造正则环格—— 个节点、每个连到 个邻居(每侧 /2)的图。
| Model | MLM | SQuAD | MNLI |
|---|---|---|---|
| BERT-base | 64.2 | 88.5 | 83.4 |
| Random (R) | 60.1 | 83.0 | 80.2 |
| Window (W) | 58.3 | 76.4 | 73.1 |
| R + W | 62.7 | 85.1 | 80.5 |
Table 1: Building block comparison @512
| Model | MLM | SQuAD | MNLI |
|---|---|---|---|
| BERT-base | 64.2 | 88.5 | 83.4 |
| Random (R) | 60.1 | 83.0 | 80.2 |
| Window (W) | 58.3 | 76.4 | 73.1 |
| R + W | 62.7 | 85.1 | 80.5 |
表 1:构件比较 @512
In other words we begin with a sliding window on the nodes. Then a random subset (%) of all connections is replaced with a random connection. The other (100 - )% local connections are retained. However, deleting such random edges might be inefficient on modern hardware, so we retain it, which will not affect its properties. In summary, to capture these local structures in the context, in BigBird, we define a sliding window attention, so that during self attention of width , query at location attends from to keys. In our notation, (see Figure 1(b)). As an initial sanity check, we performed basic experiments to test whether these intuitions are sufficient in getting performance close to BERT like models, while keeping attention linear in the number of tokens. We found that random blocks and local window were insufficient in capturing all the context necessary to compete with the performance of BERT.
换言之,我们从节点上的滑动窗口开始。然后把全部连接中随机的子集(%)替换为随机连接,其余(100 - )% 的局部连接保留。不过在现代硬件上删除这类随机边可能低效,因此我们保留它们,这不影响其性质。总之,为在上下文中捕获这些局部结构,BigBird 定义滑动窗口注意力:宽度为 的自注意力中,位置 的查询关注从 到 的键。按我们的记号,(见图 1(b))。作为初步健全性检查,我们做了基础实验,检验这些直觉是否足以在注意力对 token 数线性的前提下接近 BERT 类模型表现。我们发现随机块与局部窗口不足以捕获与 BERT 竞争所需的全部上下文。
The final piece of BigBird is inspired from our theoretical analysis (Section 3), which is critical for empirical performance. More specifically, our theory utilizes the importance of “global tokens” (tokens that attend to all tokens in the sequence and to whom all tokens attend to (see Figure 1(c)). These global tokens can be defined in two ways:
BigBird 的最后一块来自我们的理论分析(第 3 节),对经验表现至关重要。更具体地,理论利用了「全局 token」的重要性:它们关注序列中所有 token,且所有 token 也关注它们(见图 1(c))。全局 token 可用两种方式定义:
- • BigBird-itc: In internal transformer construction (itc), we make some existing tokens “global”, which attend over the entire sequence. Concretely, we choose a subset of indices (with ), such that and for all .
- • BigBird-itc:在内部 Transformer 构造(itc)中,我们把某些既有 token 设为「全局」,使其关注整段序列。具体地,选取指标子集 (),使得对所有 有 且 。
- • BigBird-etc: In extended transformer construction (etc), we include additional “global” tokens such as CLS. Concretely, we add global tokens that attend to all existing tokens. In our notation, this corresponds to creating a new matrix by adding rows to matrix , such that , and for all , and . This adds extra location to store context and as we will see in the experiments improves performance.
- • BigBird-etc:在扩展 Transformer 构造(etc)中,我们加入额外「全局」token,如 CLS。具体地,加入 个关注全部既有 token 的全局 token。按记号,这对应通过向矩阵 增加 行构造新矩阵 ,使得对所有 有 、,且 。这增加了存储上下文的额外位置,实验中也提升了表现。
The final attention mechanism for BigBird (Figure 1(d)) has all three of these properties: queries attend to random keys, each query attends to tokens to the left of its location and to the right of its location and they contain global tokens (The global tokens can be from existing tokens or extra added tokens). We provide implementation details in Appendix D.
BigBird 的最终注意力机制(图 1(d))具备这三性:查询关注 个随机键;每个查询关注其位置左侧 、右侧 的 token;并含 个全局 token(可来自既有 token 或额外加入)。实现细节见附录 D。
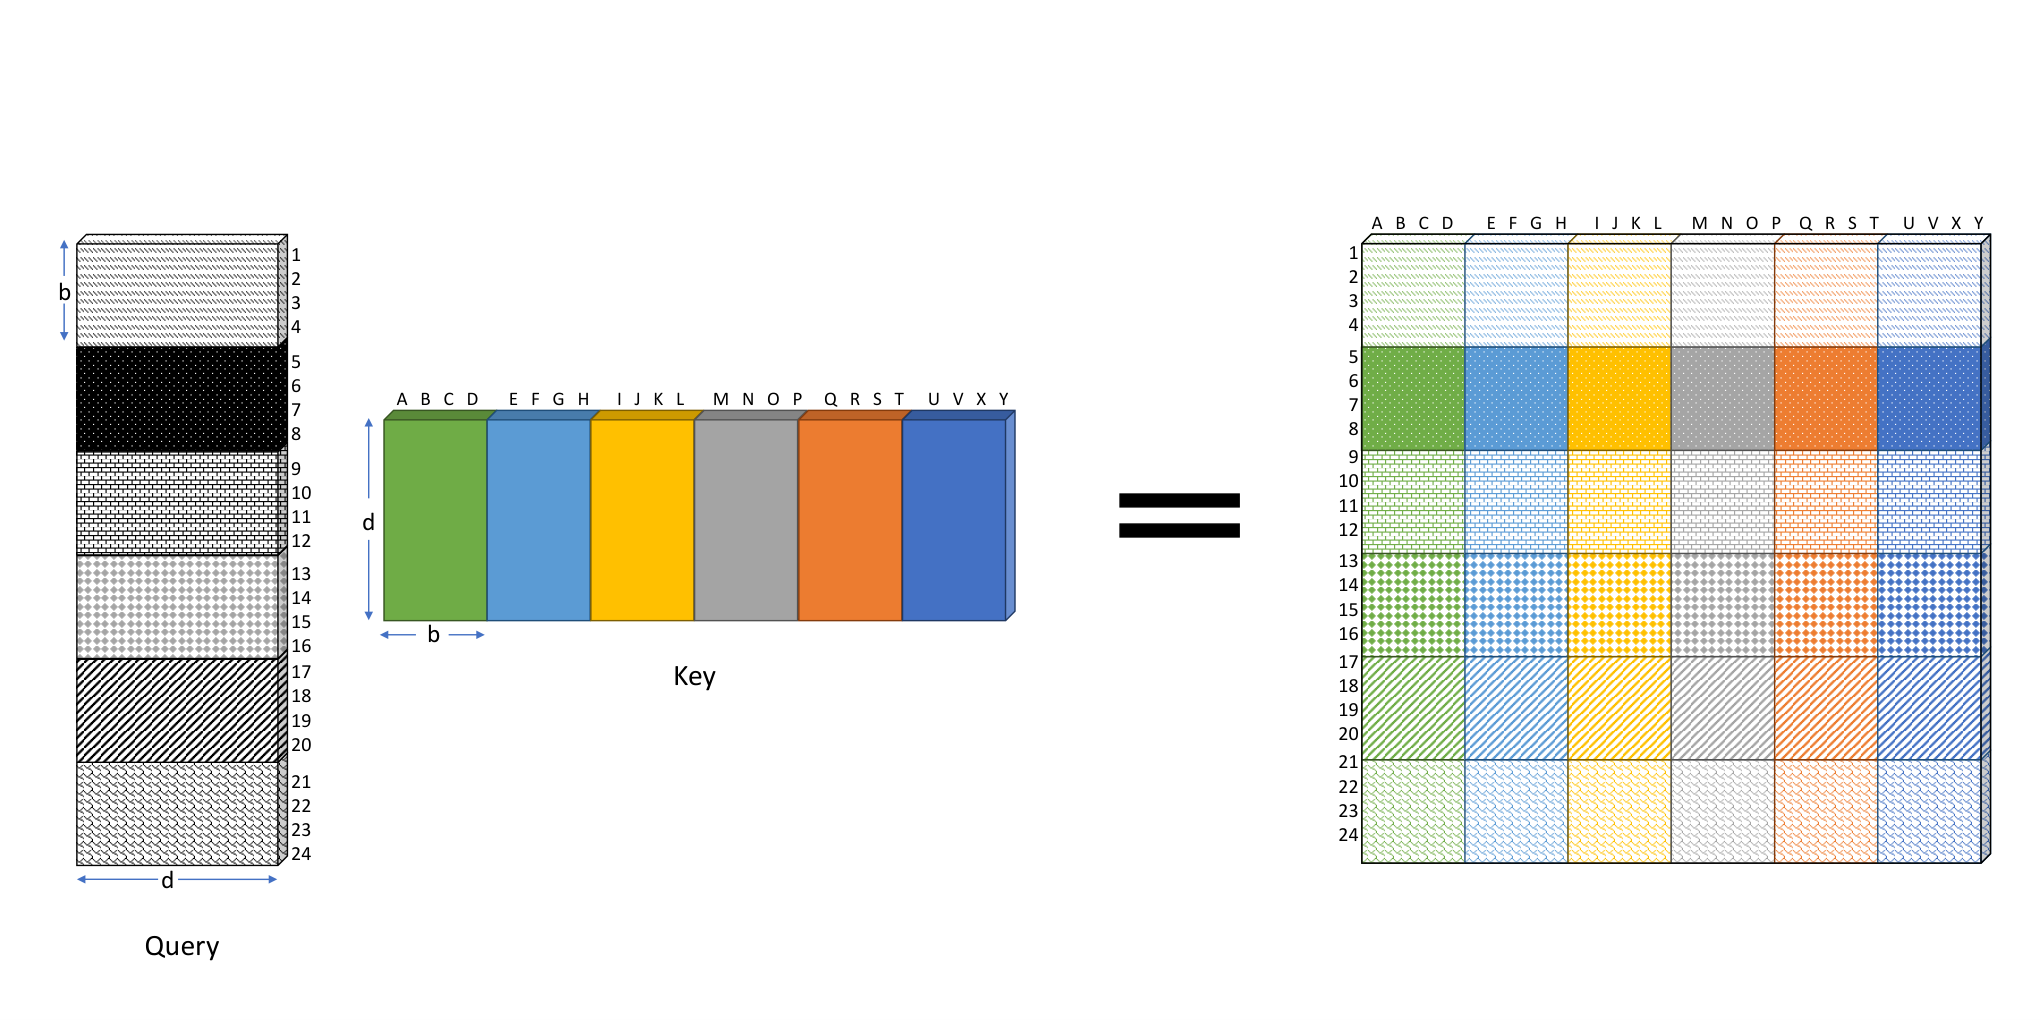
Figure 1: Building blocks of the attention mechanism used in BigBird. White color indicates absence of attention. (a) random attention with , (b) sliding window attention, (c) “ETC” combining global + sliding window, (d) BigBird’s full sparse attention.
图 1:BigBird 所用注意力机制的构件。白色表示无注意力。(a) 随机注意力();(b) 滑动窗口注意力;(c) 全局+滑动窗口组合的「ETC」结构;(d) BigBird 完整稀疏注意力。
3 Theoretical Results about Sparse Attention Mechanism
3 稀疏注意力机制的理论结果
In this section, we will show that that sparse attention mechanisms are as powerful and expressive as full-attention mechanisms in two respects. First, we show that when sparse attention mechanisms are used in a standalone encoder (such as BERT), they are Universal Approximators of sequence to sequence functions in the style of Yun et al. 2019. We note that this property was also explored theoretically in contemporary work Yun et al. 2020. Second, unlike [105], we further show that sparse encoder-decoder transformers are Turing Complete (assuming the same conditions defined in [72]). Complementing the above positive results, we also show that moving to a sparse-attention mechanism incurs a cost, i.e. there is no free lunch. In Section 3.4, we show lower bounds by exhibiting a natural task where any sufficiently sparse mechanism will require polynomially more layers.
本节将表明,稀疏注意力机制在两方面与全注意力机制同样强大且有表达力。第一,当稀疏注意力用于独立编码器(如 BERT)时,它们按 Yun 等人 2019 的风格是序列到序列函数的通用逼近器。我们注意到当代工作 Yun 等人 2020 也从理论上探讨了该性质。第二,与 [105] 不同,我们进一步证明稀疏编码器–解码器 Transformer 在 [72] 所定义的相同条件下图灵完备。补充上述正面结果的同时,我们也表明转向稀疏注意力有代价,即没有免费午餐。在第 3.4 节,我们展示自然任务上的下界:任何足够稀疏的机制都需要多项式更多层。
3.1 Notation
3.1 记号
The complete Transformer encoder stack is nothing but the repeated application of a single-layer encoder (with independent parameters). We denote class of such Transformer encoders stack, defined using generalized encoder (Section 2), by which consists of -heads with head size and is the hidden layer size of the output network, and the attention layer is defined by the directed graph .
完整 Transformer 编码器栈不过是(参数独立的)单层编码器的反复应用。我们用 表示由广义编码器(第 2 节)定义的此类 Transformer 编码器栈的类:含 个头、头大小 、 为输出网络隐层大小,注意力层由有向图 定义。
The key difference between our proposed attention mechanism to that of Vaswani et al. 2017, Yun et al. 2019 is that we add a special token at the beginning of each sequence and assign it a special vector. We will refer to this as . Therefore our graph will have vertex set . We will assume that this extra node and its respective vector will be dropped at the final output layer of transformer. To avoid cumbersome notation, we will still treat transformer as mapping sequences to . We will also allow the transformer to append position embeddings to matrix in the input layer.
我们所提注意力与 Vaswani 等人 2017、Yun 等人 2019 的关键差异是:在每段序列开头加入特殊 token 并赋以特殊向量,记为 。因此图 的顶点集为 。我们假定该额外节点及其向量在 Transformer 最终输出层被丢弃。为避免繁琐记号,仍把 Transformer 视为把序列 映到 。我们也允许 Transformer 在输入层把位置嵌入 拼到矩阵 。
Finally, we need to define the function class and distance measure for proving universal approximation property. Let denote the set of continuous functions which are continuous with respect to the topology defined by norm. Recall for any , the distance is .
最后,为证明通用逼近性质需定义函数类与距离。记 为连续函数 的集合,连续性相对 范数拓扑。对任意 , 距离为 。
3.2 Universal Approximators
3.2 通用逼近器
Definition 1.
The star-graph centered at is the graph defined on . The neighborhood of all vertices is for and .
定义 1。
以 0 为中心的星图 定义在 上。对 ,顶点 的邻域为 ,且 。
Our main theorem is that the sparse attention mechanism defined by any graph containing is a universal approximator:
我们的主定理是:任何包含 的图所定义的稀疏注意力机制都是通用逼近器:
Theorem 1.
Given and , for any , there exists a transformer with sparse-attention, such that where is any graph containing star graph .
定理 1。
给定 与 ,对任意 ,存在带稀疏注意力的 Transformer ,使得 ,其中 为任意包含星图 的图。
To prove the theorem, we will follow the standard proof structure outlined in [104].
为证明该定理,我们遵循 [104] 概述的标准证明结构。
Step 1: Approximate by piece-wise constant functions. Since is a continuous function with bounded domain , we will approximate it with a suitable piece-wise constant function. This is accomplished by a suitable partition of the region into a grid of granularity to get a discrete set . Therefore, we can assume that we are dealing with a function , where .
步骤 1:用分段常值函数逼近 。 因 是定义域有界 的连续函数,可用合适的分段常值函数逼近。做法是把区域 按粒度 划分网格,得到离散集 。于是可假定处理函数 ,且 。
Step 2: Approximate piece-wise constant functions by modified transformers. This is the key step of the proof where the self-attention mechanism is used to generate a contextual-mapping of the input. Informally, a contextual mapping is a unique code for the pair consisting of a matrix and a column. Its uniqueness allows the Feed forward layers to use each code to map it to a unique output column.
步骤 2:用修改后的 Transformer 逼近分段常值函数。 这是证明关键步:用自注意力机制生成输入的上下文映射。非正式地说,上下文映射是矩阵 与某一列之对的唯一编码。其唯一性使前馈层可用每个编码映到唯一输出列。
The main technical challenge is computing the contextual mapping using only sparse attention mechanism. This was done in [104] using a “selective” shift operator which shift up entries that are in a specific interval. Key to their proof was the fact that the shift, was exactly the range of the largest entry to the smallest entry.
主要技术挑战是仅用稀疏注意力计算上下文映射。[104] 用「选择性」移位算子完成:把落在特定区间的条目上移。其证明关键在于:移位恰好是从最大条目到最小条目的范围。
Creating a contextual mapping with a sparse attention mechanism is quite a challenge. In particular, because each query only attends to a few keys, it is not at all clear that sufficient information can be corralled to make a contextual embedding of the entire matrix. To get around this, we develop a sparse shift operator which shifts the entries of the matrices if they lie in a certain range. The exact amount of the shift is controlled by the directed sparse attention graphg . The second key ingredient is the use of additional global token. By carefully applying the operator to a set of chosen ranges, we will show that each column will contain a unique mapping of the full mapping. Therefore, we can augment the loss of inner-products in the self attention mechanism by using multiple layers and an auxiliary global token.
用稀疏注意力构造上下文映射相当困难。尤其是每个查询只关注少数键,远不清楚能否汇聚足够信息来做整个矩阵的上下文化嵌入。为此我们发展稀疏移位算子:若矩阵条目落在某范围则对其移位,精确位移量由有向稀疏注意力图 控制。第二关键成分是使用额外全局 token。通过对一组选定范围仔细施加该算子,我们将表明每列包含全映射的唯一映射。因此,可通过多层与辅助全局 token 弥补自注意力中内积的损失。
Step 3: Approximate modified transformers by original Transformers: The final step is to approximate the modified transformers by the original transformer which uses ReLU and softmax.
步骤 3:用原始 Transformer 逼近修改后的 Transformer:最后一步是用采用 ReLU 与 softmax 的原始 Transformer 逼近修改后的 Transformer。
We provide the full details in Appendix A.
完整细节见附录 A。
3.3 Turing Completeness
3.3 图灵完备性
Transformers are a very general class. In the original paper of Vaswani et al. 2017, they were used in both an encoder and a decoder. While the previous section outlined how powerful just the encoders were, another natural question is to ask what the additional power of both a decoder along with an encoder is? Pérez et al. 2019 showed that the full transformer based on a quadratic attention mechanism is Turing Complete. This result makes one unrealistic assumption, which is that the model works on arbitrary precision model. Of course, this is necessary as otherwise, Transformers are bounded finite state machines and cannot be Turing Complete.
Transformer 是非常一般的类。在 Vaswani 等人 2017 原文中,它们同时用于编码器与解码器。上一节概述了仅编码器有多强大;另一个自然问题是:解码器与编码器一起额外带来什么能力?Pérez 等人 2019 表明基于二次注意力的完整 Transformer 图灵完备。该结果做了一个不现实的假设:模型在任意精度模型上工作。当然这是必要的,否则 Transformer 是有界有限状态机,不可能图灵完备。
It is natural to ask if the full attention mechanism is necessary. Or can a sparse attention mechanism also be used to simulate any Turing Machine? We show that this is indeed the case: we can use a sparse encoder and sparse decoder to simulate any Turing Machine.
自然要问:全注意力是否必要?稀疏注意力是否也可用于模拟任意图灵机?我们表明确实如此:可用稀疏编码器与稀疏解码器模拟任意图灵机。
To use the sparse attention mechanism in the transformer architecture, we need to define a suitable modification where each token only reacts to previous tokens. Unlike the case for BERT, where the entire attention mechanism is applied once, in full transformers, the sparse attention mechanism at decoder side is used token by token. Secondly the work of Pérez et al. 2019, uses each token as a representation of the tape history and uses the full attention to move and retrieve the correct tape symbol. Most of the construction of Pérez et al. 2019 goes through for sparse attentions, except for their addressing scheme to point back in history (Lemma B.4 in [72]). We show how to simulate this using a sparse attention mechanism and defer the details to Appendix B.
要在 Transformer 架构中使用稀疏注意力,需定义合适修改,使每个 token 只对先前 token 反应。与 BERT 一次性施加整段注意力不同,在完整 Transformer 中,解码器侧稀疏注意力逐 token 使用。其次,Pérez 等人 2019 用每个 token 表示纸带历史,并用全注意力移动与检索正确纸带符号。Pérez 等人 2019 的构造大部分对稀疏注意力成立,除了其指向历史的寻址方案([72] 中引理 B.4)。我们说明如何用稀疏注意力模拟它,细节推迟到附录 B。
3.4 Limitations
3.4 局限
We demonstrate a natural task which can be solved by the full attention mechanism in -layers. However, under standard complexity theoretic assumptions, this problem requires -layers for any sparse attention layers with edges (not just BigBird). (Here hides poly-logarthmic factors). Consider the simple problem of finding the corresponding furthest vector for each vector in the given sequence of length . Formally,
我们展示一个全注意力机制可用 层解决的自然任务。但在标准复杂性假设下,对任意带 条边的稀疏注意力层(不仅是 BigBird),该问题需要 层。(此处 隐藏多项式对数因子。)考虑对给定长度 的向量序列,为每个向量找对应最远向量的简单问题。形式地,
Task 1. Given unit vectors , find where for a fixed , we define .
任务 1。 给定 个单位向量 ,求 ,其中对固定 ,定义 。
Finding vectors that are furthest apart boils down to minimize inner product search in case of unit vectors. For a full-attention mechanism with appropriate query and keys, this task is very easy as we can evaluate all pair-wise inner products.
找相距最远的向量在单位向量情形归结为最小化内积搜索。对带合适查询与键的全注意力机制,该任务很容易,因为可评估所有成对内积。
The impossibility for sparse-attention follows from hardness results stemming from Orthogonal Vector Conjecture(OVC) [1, 2, 7, 96]. The OVC is a widely used assumption in fine-grained complexity. Informally, it states that one cannot determine if the minimum inner product among boolean vectors is in subquadratic time. In Appendix C, we show a reduction using OVC to show that if a transformer for any sparse directed graph can evaluate the Task , it can solve the orthogonal vector problem.
稀疏注意力的不可能性来自正交向量猜想(OVC) [1, 2, 7, 96] 的困难性结果。OVC 是细粒度复杂性中广泛使用的假设。非正式地说,它断言无法在亚二次时间内判定 个布尔向量间最小内积是否为 0。在附录 C 中,我们用 OVC 做归约:若对任意稀疏有向图 ,Transformer 能评估任务 1,则它可解正交向量问题。
Proposition 1.
There exists a single layer full self-attention that can evaluate Task 1, i.e. $g(u_{1},...,u_{n})=[u_{1^{}},\dots,u_{n^{}}]D\tilde{O}(n)\tilde{\Omega}(n^{1-o(1)})$ layers.
命题 1。
存在单层全自注意力 可评估任务 1,即 $g(u_{1},...,u_{n})=[u_{1^{}},\dots,u_{n^{}}]\tilde{O}(n)D\tilde{\Omega}(n^{1-o(1)})$ 层。
We give a formal proof of this fact in Appendix C.
我们在附录 C 给出该事实的形式证明。
4 Experiments: Natural Language Processing
4 实验:自然语言处理
In this section our goal is to showcase benefits of modeling longer input sequence for NLP tasks, for which we select three representative tasks. We begin with basic masked language modeling (MLM; Devlin et al. 2018) to check if better contextual representations can be learnt by utilizing longer contiguous sequences. Next, we consider QA with supporting evidence, for which capability to handle longer sequence would allow us to retrieve more evidence using crude systems like TF-IDF/BM25. Finally, we tackle long document classification where discriminating information may not be located in first 512 tokens. Below we summarize the results for BigBird using sequence length 4096[^1], while we defer all other setup details including computational resources, batch size, step size, to Appendix E.
本节目标是展示为 NLP 任务建模更长输入序列的收益,为此选取三项代表性任务。先从基础掩码语言建模(MLM;Devlin 等人 2018)入手,检验利用更长连续序列能否学到更好的上下文化表示。接着考虑带支持证据的问答:处理更长序列的能力使我们能用 TF-IDF/BM25 等粗系统检索更多证据。最后做长文档分类,其中判别信息可能不在前 512 token。下文汇总 BigBird 使用序列长度 4096[^1] 的结果;包括计算资源、batch size、步数等设置细节推迟到附录 E。
Pretraining and MLM
We follow [22, 63] to create base and large versions of BigBird and pretrain it using MLM objective. This task involves predicting a random subset of tokens which have been masked out. We use four standard data-sets for pretraining (listed in Section E.1, Table 10), warm-starting from the public RoBERTa checkpoint[^2]. We compare performance in predicting the masked out tokens in terms of bits per character, following [8]. As seen in Section E.1, Table 10, both BigBird and Longformer perform better than limited length RoBERTa, with BigBird-etc performing the best. We note that we trained our models on a reasonable memory/chip with batch size of 32-64. Our memory efficiency is due to efficient blocking and sparsity structure of the sparse attention mechanism described in Section 2.
预训练与 MLM
我们遵循 [22, 63] 创建 base 与 large 版 BigBird,并用 MLM 目标预训练。该任务预测被掩码掉的随机 token 子集。我们用四个标准预训练数据集(列于第 E.1 节表 10),从公开 RoBERTa 检查点热启动[^2]。按 [8],以每字符比特数比较对被掩码 token 的预测表现。如第 E.1 节表 10 所示,BigBird 与 Longformer 均优于长度受限的 RoBERTa,其中 BigBird-etc 最好。注意我们在合理的每芯片 16GB 显存、batch size 32–64 上训练。显存效率来自第 2 节所述稀疏注意力的高效分块与稀疏结构。
| Model | HotpotQA | NaturalQ | TriviaQA | WikiHop | |||||||
|---|---|---|---|---|---|---|---|---|---|---|---|
| Ans | Sup | Joint | LA | SA | Full | MCQ | |||||
| RoBERTa | 73.5 | 83.4 | 63.5 | - | - | 74.3 | 72.4 | ||||
| Longformer | 74.3 | 84.4 | 64.4 | - | - | 75.2 | 75.0 | ||||
| BigBird-itc | 75.7 | 86.8 | 67.7 | 70.8 | 53.3 | 79.5 | 75.9 | ||||
| BigBird-etc | 75.5 | 87.1 | 67.8 | 73.9 | 54.9 | 78.7 | 75.9 |
Table 2: QA Dev results using Base size models. We report accuracy for WikiHop and F1 for HotpotQA, Natural Questions, and TriviaQA.
| Model | HotpotQA | NaturalQ | TriviaQA | WikiHop | |||||||
|---|---|---|---|---|---|---|---|---|---|---|---|
| Ans | Sup | Joint | LA | SA | Full | MCQ | |||||
| RoBERTa | 73.5 | 83.4 | 63.5 | - | - | 74.3 | 72.4 | ||||
| Longformer | 74.3 | 84.4 | 64.4 | - | - | 75.2 | 75.0 | ||||
| BigBird-itc | 75.7 | 86.8 | 67.7 | 70.8 | 53.3 | 79.5 | 75.9 | ||||
| BigBird-etc | 75.5 | 87.1 | 67.8 | 73.9 | 54.9 | 78.7 | 75.9 |
表 2:Base 规模模型的问答开发集结果。WikiHop 报准确率;HotpotQA、Natural Questions、TriviaQA 报 F1。
| Model | HotpotQA | NaturalQ | TriviaQA | WikiHop | |||||||
|---|---|---|---|---|---|---|---|---|---|---|---|
| Ans | Sup | Joint | LA | SA | Full | Verified | MCQ | ||||
| HGN [26] | 82.2 | 88.5 | 74.2 | - | - | - | - | - | |||
| GSAN | 81.6 | 88.7 | 73.9 | - | - | - | - | - | |||
| ReflectionNet [32] | - | - | - | 77.1 | 64.1 | - | - | - | |||
| RikiNet-v2 [61] | - | - | - | 76.1 | 61.3 | - | - | - | |||
| Fusion-in-Decoder [39] | - | - | - | - | - | 84.4 | 90.3 | - | |||
| SpanBERT [42] | - | - | - | - | - | 79.1 | 86.6 | - | |||
| MRC-GCN [87] | - | - | - | - | - | - | - | 78.3 | |||
| MultiHop [14] | - | - | - | - | - | - | - | 76.5 | |||
| Longformer [8] | 81.2 | 88.3 | 73.2 | - | - | 77.3 | 85.3 | 81.9 | |||
| BigBird-etc | 81.2 | 89.1 | 73.6 | 77.8 | 57.9 | 84.5 | 92.4 | 82.3 |
Table 3: Fine-tuning results on Test set for QA tasks. The Test results (F1 for HotpotQA, Natural Questions, TriviaQA, and Accuracy for WikiHop) have been picked from their respective leaderboard. For each task the top-3 leaders were picked not including BigBird-etc. For Natural Questions Long Answer (LA), TriviaQA, and WikiHop, BigBird-ETC is the new state-of-the-art. On HotpotQA we are third in the leaderboard by F1 and second by Exact Match (EM).
| Model | HotpotQA | | NaturalQ | | TriviaQA | | WikiHop |---|---|---|---|---|---|---|---|---|---|---|---|
| Ans | Sup | Joint | | LA | SA | | Full | Verified | | MCQ | HGN [26] | 82.2 | 88.5 | 74.2 | | - | - | | - | - | | - |
| GSAN | 81.6 | 88.7 | 73.9 | | - | - | | - | - | | - |
| ReflectionNet [32] | - | - | - | | 77.1 | 64.1 | | - | - | | - |
| RikiNet-v2 [61] | - | - | - | | 76.1 | 61.3 | | - | - | | - |
| Fusion-in-Decoder [39] | - | - | - | | - | - | | 84.4 | 90.3 | | - |
| SpanBERT [42] | - | - | - | | - | - | | 79.1 | 86.6 | | - |
| MRC-GCN [87] | - | - | - | | - | - | | - | - | | 78.3 |
| MultiHop [14] | - | - | - | | - | - | | - | - | | 76.5 |
| Longformer [8] | 81.2 | 88.3 | 73.2 | | - | - | | 77.3 | 85.3 | | 81.9 |
| BigBird-etc | 81.2 | 89.1 | 73.6 | | 77.8 | 57.9 | | 84.5 | 92.4 | | 82.3 |
表 3:问答任务测试集微调结果。测试结果取自各排行榜;每项取不含 BigBird-etc 的前三。Natural Questions 长答案、TriviaQA 与 WikiHop 上 BigBird-ETC 为新的当时最优;HotpotQA 按 F1 第三、按 EM 第二。
Question Answering (QA)
We considered following four challenging datasets:
问答(QA)
我们考虑以下四个具有挑战性的数据集:
- Natural Questions [52]: For the given question, find a short span of answer (SA) from the given evidences as well highlight the paragraph from the given evidences containing information about the correct answer (LA).
- Natural Questions [52]:给定问题,从给定证据中找出简短答案跨度(SA),并标出包含正确答案信息的证据段落(LA)。
- HotpotQA-distractor [100]: Similar to natural questions, it requires finding the answer (Ans) as well as the supporting facts (Sup) over different documents needed for multi-hop reasoning from the given evidences.
- HotpotQA-distractor [100]:类似 Natural Questions,需从给定证据中找出答案(Ans)以及多跳推理所需、分布在不同文档上的支持事实(Sup)。
- TriviaQA-wiki [41]: We need to provide an answer for the given question using provided Wikipedia evidence, however, the answer might not be present in the given evidence. On a smaller verified subset of question, the given evidence is guaranteed to contain the answer. Nevertheless, we model the answer as span selection problem in this case as well.
- TriviaQA-wiki [41]:利用所提供的维基证据回答给定问题;答案未必出现在证据中。在更小的verified问题子集上,证据保证包含答案。尽管如此,我们仍把答案建模为跨度选择问题。
- WikiHop [95]: Chose correct option from multiple-choice questions (MCQ), by aggregating information spread across multiple documents given in the evidences.
- WikiHop [95]:通过聚合证据中分布在多文档上的信息,从多项选择题(MCQ)中选出正确选项。
As these tasks are very competitive, multiple highly engineered systems have been designed specific each dataset confirming to respective output formats. For a fair comparison, we had to use some additional regularization for training BigBird, details of which are provided in Section E.2 along with exact architecture description. We experiment using the base sized model and select the best configuration on the development set for each dataset (as reported in Table 2). We can see that BigBird-etc, with expanded global tokens consistently outperforms all other models. Thus, we chose this configuration to train a large sized model to be used for evaluation on the hidden test set.
这些任务竞争激烈,已有多套高度工程化的系统分别针对各数据集与输出格式。为公平比较,训练 BigBird 时需使用一些额外正则,细节与精确架构描述见第 E.2 节。我们用 base 规模模型实验,并在各数据集开发集上选最佳配置(见表 2)。可见带扩展全局 token 的 BigBird-etc 持续优于所有其他模型。因此我们选该配置训练 large 规模模型,用于隐藏测试集评估。
In Table 3, we compare BigBird-etc model to top-3 entries from the leaderboard excluding BigBird. One can clearly see the importance of using longer context as both Longformer and BigBird outperform models with smaller contexts. Also, it is worth noting that BigBird submission is a single model, whereas the other top-3 entries for Natural Questions are ensembles, which might explain the slightly lower accuracy in exact answer phrase selection.
在表 3 中,我们把 BigBird-etc 与排行榜上除 BigBird 外的前三名比较。可清楚看到使用更长上下文的重要性:Longformer 与 BigBird 均超过较短上下文的模型。另需注意 BigBird 提交是单模型,而 Natural Questions 其他前三多为集成,这或许解释了精确答案短语选择上略低的准确率。
Classification
We experiment on datasets of different lengths and contents, specifically various document classification and GLUE tasks. Following BERT, we used one layer with cross entropy loss on top of the first [CLS] token. We see that gains of using BigBird are more significant when we have longer documents and fewer training examples. For instance, using base sized model, BigBird improves state-of-the-art for Arxiv dataset by about points. On Patents dataset, there is improvement over using simple BERT/RoBERTa, but given the large size of training data the improvement over SoTA (which is not BERT based) is not significant. Note that this performance gain is not seen for much smaller IMDb dataset. Along with experimental setup detail, we present detailed results in Section E.4 which show competitive performance.
分类
我们在不同长度与内容的数据集上实验,特别是多种文档分类与 GLUE 任务。遵循 BERT,在第一个 [CLS] token 上加一层交叉熵损失。我们发现:文档更长、训练样本更少时,使用 BigBird 的收益更显著。例如用 base 规模模型,BigBird 把 Arxiv 数据集的当时最优约提高 个百分点。在 Patents 上相对简单 BERT/RoBERTa 有提升,但因训练数据很大,相对(非 BERT 系的)SoTA 提升不显著。对小得多的 IMDb 则看不到该增益。连同实验设置细节,第 E.4 节给出详细结果,显示有竞争力的表现。
| Model | Arxiv | PubMed | BigPatent | |||||||
|---|---|---|---|---|---|---|---|---|---|---|
| R-1 | R-2 | R-L | R-1 | R-2 | R-L | R-1 | R-2 | R-L | ||
| Prior Art | SumBasic [68] | 29.47 | 6.95 | 26.30 | 37.15 | 11.36 | 33.43 | 27.44 | 7.08 | 23.66 |
| LexRank [25] | 33.85 | 10.73 | 28.99 | 39.19 | 13.89 | 34.59 | 35.57 | 10.47 | 29.03 | |
| LSA [97] | 29.91 | 7.42 | 25.67 | 33.89 | 9.93 | 29.70 | - | - | - | |
| Attn-Seq2Seq [85] | 29.30 | 6.00 | 25.56 | 31.55 | 8.52 | 27.38 | 28.74 | 7.87 | 24.66 | |
| Pntr-Gen-Seq2Seq [77] | 32.06 | 9.04 | 25.16 | 35.86 | 10.22 | 29.69 | 33.14 | 11.63 | 28.55 | |
| Long-Doc-Seq2Seq [20] | 35.80 | 11.05 | 31.80 | 38.93 | 15.37 | 35.21 | - | - | - | |
| Sent-CLF [81] | 34.01 | 8.71 | 30.41 | 45.01 | 19.91 | 41.16 | 36.20 | 10.99 | 31.83 | |
| Sent-PTR [81] | 42.32 | 15.63 | 38.06 | 43.30 | 17.92 | 39.47 | 34.21 | 10.78 | 30.07 | |
| Extr-Abst-TLM [81] | 41.62 | 14.69 | 38.03 | 42.13 | 16.27 | 39.21 | 38.65 | 12.31 | 34.09 | |
| Dancer [31] | 42.70 | 16.54 | 38.44 | 44.09 | 17.69 | 40.27 | - | - | - | |
| Base | Transformer | 28.52 | 6.70 | 25.58 | 31.71 | 8.32 | 29.42 | 39.66 | 20.94 | 31.20 |
| + RoBERTa [76] | 31.98 | 8.13 | 29.53 | 35.77 | 13.85 | 33.32 | 41.11 | 22.10 | 32.58 | |
| + Pegasus [107] | 34.81 | 10.16 | 30.14 | 39.98 | 15.15 | 35.89 | 43.55 | 20.43 | 31.80 | |
| BigBird-RoBERTa | 41.22 | 16.43 | 36.96 | 43.70 | 19.32 | 39.99 | 55.69 | 37.27 | 45.56 | |
| Large | Pegasus (Reported) [107] | 44.21 | 16.95 | 38.83 | 45.97 | 20.15 | 41.34 | 52.29 | 33.08 | 41.75 |
| Pegasus (Re-eval) | 43.85 | 16.83 | 39.17 | 44.53 | 19.30 | 40.70 | 52.25 | 33.04 | 41.80 | |
| BigBird-Pegasus | 46.63 | 19.02 | 41.77 | 46.32 | 20.65 | 42.33 | 60.64 | 42.46 | 50.01 |
Table 4: Summarization ROUGE score for long documents.
| Model | Arxiv | PubMed | BigPatent |---|---|---|---|---|---|---|---|---|---|---| R-1 | R-2 | R-L | R-1 | R-2 | R-L | R-1 | R-2 | R-L | Prior Art | SumBasic [68] | 29.47 | 6.95 | 26.30 | 37.15 | 11.36 | 33.43 | 27.44 | 7.08 | 23.66 | LexRank [25] | 33.85 | 10.73 | 28.99 | 39.19 | 13.89 | 34.59 | 35.57 | 10.47 | 29.03 | LSA [97] | 29.91 | 7.42 | 25.67 | 33.89 | 9.93 | 29.70 | - | - | - | Attn-Seq2Seq [85] | 29.30 | 6.00 | 25.56 | 31.55 | 8.52 | 27.38 | 28.74 | 7.87 | 24.66 | Pntr-Gen-Seq2Seq [77] | 32.06 | 9.04 | 25.16 | 35.86 | 10.22 | 29.69 | 33.14 | 11.63 | 28.55 | Long-Doc-Seq2Seq [20] | 35.80 | 11.05 | 31.80 | 38.93 | 15.37 | 35.21 | - | - | - | Sent-CLF [81] | 34.01 | 8.71 | 30.41 | 45.01 | 19.91 | 41.16 | 36.20 | 10.99 | 31.83 | Sent-PTR [81] | 42.32 | 15.63 | 38.06 | 43.30 | 17.92 | 39.47 | 34.21 | 10.78 | 30.07 | Extr-Abst-TLM [81] | 41.62 | 14.69 | 38.03 | 42.13 | 16.27 | 39.21 | 38.65 | 12.31 | 34.09 | Dancer [31] | 42.70 | 16.54 | 38.44 | 44.09 | 17.69 | 40.27 | - | - | - |
| Base | Transformer | 28.52 | 6.70 | 25.58 | 31.71 | 8.32 | 29.42 | 39.66 | 20.94 | 31.20 | + RoBERTa [76] | 31.98 | 8.13 | 29.53 | 35.77 | 13.85 | 33.32 | 41.11 | 22.10 | 32.58 | + Pegasus [107] | 34.81 | 10.16 | 30.14 | 39.98 | 15.15 | 35.89 | 43.55 | 20.43 | 31.80 | BigBird-RoBERTa | 41.22 | 16.43 | 36.96 | 43.70 | 19.32 | 39.99 | 55.69 | 37.27 | 45.56 |
| Large | Pegasus (Reported) [107] | 44.21 | 16.95 | 38.83 | 45.97 | 20.15 | 41.34 | 52.29 | 33.08 | 41.75 | Pegasus (Re-eval) | 43.85 | 16.83 | 39.17 | 44.53 | 19.30 | 40.70 | 52.25 | 33.04 | 41.80 | BigBird-Pegasus | 46.63 | 19.02 | 41.77 | 46.32 | 20.65 | 42.33 | 60.64 | 42.46 | 50.01 |
表 4:长文档摘要的 ROUGE 分数。
4.1 Encoder-Decoder Tasks
4.1 编码器–解码器任务
For an encoder-decoder setup, one can easily see that both suffer from quadratic complexity due to the full self attention. We focus on introducing the sparse attention mechanism of BigBird only at the encoder side. This is because, in practical generative applications, the length of output sequence is typically small as compared to the input. For example for text summarization, we see in realistic scenarios (c.f. Section E.5 Table 18) that the median output sequence length is where as the input sequence’s median length is . For such applications, it is more efficient to use sparse attention mechanism for the encoder and full self-attention for the decoder.
在编码器–解码器设定下,容易看到二者都因全自注意力而承受二次复杂度。我们聚焦仅在编码器侧引入 BigBird 稀疏注意力。因为在实际生成应用中,输出序列长度通常远小于输入。例如文本摘要,现实场景(参见第 E.5 节表 18)中输出序列长度中位数约 ,而输入中位数 。对此类应用,编码器用稀疏注意力、解码器用全自注意力更高效。
Summarization
Document summarization is a task of creating a short and accurate summary of a text document. We used three long document datasets for testing our model details of which are mention in Table 18. In this paper we focus on abstractive summarization of long documents where using a longer contextual encoder should improve performance. The reasons are two fold: First, the salient content can be evenly distributed in the long document, not just in first 512 tokens, and this is by design in the BigPatents dataset [78]. Second, longer documents exhibit a richer discourse structure and summaries are considerably more abstractive, thereby observing more context helps. As has been pointed out recently [76, 107], pretraining helps in generative tasks, we warm start from our general purpose MLM pretraining on base-sized models as well as utilizing state-of-the-art summarization specific pretraining from Pegasus [107] on large-sized models. The results of training BigBird sparse encoder along with full decoder on these long document datasets are presented in Table 4. We can clearly see modeling longer context brings significant improvement. Along with hyperparameters, we also present results on shorter but more widespread datasets in Section E.5, which show that using sparse attention does not hamper performance either.
摘要
文档摘要旨在生成短而准确的文本摘要。我们用三个长文档数据集测试模型,细节见表 18。本文聚焦长文档抽象摘要:更长上下文编码器应能提升表现,原因有二。其一,显著内容可均匀分布在长文档中,而非仅在前 512 token,这在 BigPatents 数据集 [78] 中是刻意设计。其二,更长文档展现更丰富的篇章结构,摘要也明显更抽象,因此观察更多上下文有帮助。如近期所指出 [76, 107],预训练有益于生成任务;我们从 base 规模的通用 MLM 预训练热启动,并在 large 规模上利用 Pegasus [107] 的摘要专用预训练。在这些长文档数据集上,用 BigBird 稀疏编码器配全解码器训练的结果见表 4。可清楚看到建模更长上下文带来显著提升。连同超参,第 E.5 节也给出更短但更常见数据集上的结果,表明使用稀疏注意力并不损害表现。
5 Experiments: Genomics
5 实验:基因组学
There has been a recent upsurge in using deep learning for genomics data [86, 106, 13], which has resulted in improved performance on several biologically-significant tasks such as promoter site prediction [71], methylation analysis [55], predicting functional effects of non-coding variant [109], etc. These approaches consume DNA sequence fragments as inputs, and therefore we believe longer input sequence handling capability of BigBird would be beneficial as many functional effects in DNA are highly non-local [12]. Furthermore, taking inspiration from NLP, we learn powerful contextual representations for DNA fragments utilizing abundant unlabeled data (e.g. human reference genome, Saccharomyces Genome Database) via MLM pretraining. Next, we showcase that our long input BigBird along with the proposed pretraining significantly improves performances in two downstream tasks. Detailed experimental setup for the two tasks are provided in Appendix F.
近期深度学习用于基因组数据显著升温 [86, 106, 13],并在启动子位点预测 [71]、甲基化分析 [55]、非编码变异功能效应预测 [109] 等多项生物学重要任务上提升表现。这些方法以 DNA 序列片段为输入,因此我们相信 BigBird 处理更长输入的能力会有益——DNA 中许多功能效应高度非局部 [12]。进一步,受 NLP 启发,我们利用充足的无标注数据(如人类参考基因组、酿酒酵母基因组数据库)经 MLM 预训练学习 DNA 片段的强上下文化表示。接下来展示:长输入 BigBird 配合所提预训练,在两项下游任务上显著提升表现。两项任务的详细实验设置见附录 F。
| Model | BPC |
|---|---|
| SRILM [58] | 1.57 |
| BERT (sqln. 512) | 1.23 |
| BigBird (sqln. 4096) | 1.12 |
Table 5: MLM BPC
| Model | BPC |
|---|---|
| SRILM [58] | 1.57 |
| BERT (sqln. 512) | 1.23 |
| BigBird (sqln. 4096) | 1.12 |
表 5:MLM 的 BPC
Pre-training and MLM
As explored in Liang 2012, instead of operating on base pairs, we propose to first segment DNA into tokens so as to further increase the context length (Appendix F, Figure 7). In particular, we build a byte-pair encoding [50] table for the DNA sequence of size 32K, with each token representing 8.78 base pairs on average. We learn contextual representation of these token on the human reference genome (GRCh37)[^3] using MLM objective. We then report the bits per character (BPC) on a held-out set in Table 5. We find that attention based contextual representation of DNA does improve BPC, which is further improved by using longer context.
预训练与 MLM
如 Liang 2012 所探索,我们建议先不在碱基对上直接操作,而是把 DNA 切成 token,以进一步增大上下文长度(附录 F,图 7)。具体地,为 DNA 序列构建大小 32K 的 byte-pair encoding [50] 表,每个 token 平均代表 8.78 个碱基对。我们在人类参考基因组(GRCh37)[^3] 上用 MLM 目标学习这些 token 的上下文化表示,并在表 5 报告留出集上的每字符比特数(BPC)。我们发现基于注意力的 DNA 上下文化表示确实改善 BPC,使用更长上下文可进一步改善。
| Model | F1 |
|---|---|
| CNNProm [90] | 69.7 |
| DeePromoter [71] | 95.6 |
| BigBird | 99.9 |
Table 6: Comparison.
| Model | F1 |
|---|---|
| CNNProm [90] | 69.7 |
| DeePromoter [71] | 95.6 |
| BigBird | 99.9 |
表 6:比较。
Promoter Region Prediction
Promoter is a DNA region typically located upstream of the gene, which is the site of transcription initiation. Multiple methods have been proposed to identify the promoter regions in a given DNA sequence [99, 59, 11, 98, 71], as it is an important first step in understanding gene regulation. The corresponding machine learning task is to classify a given DNA fragment as promoter or non-promoter sequence. We use the dataset compiled by Oubounyt et al. 2019 which was built from Eukaryotic Promoter Database (EPDnew) [24] [^4]. We finetuned the pretrained BigBird model from above, using the training data and report F1 on test dataset. We compare our results to the previously reported best method in Table 6. We see that BigBird achieve nearly perfect accuracy with a jump from the previous best reported accuracy.
启动子区域预测
启动子是通常位于基因上游的 DNA 区域,是转录起始位点。已有多种方法识别给定 DNA 序列中的启动子区域 [99, 59, 11, 98, 71],因为这是理解基因调控的重要第一步。对应机器学习任务是把给定 DNA 片段分类为启动子或非启动子序列。我们使用 Oubounyt 等人 2019 从真核启动子数据库(EPDnew) [24][^4] 构建的数据集。用上述预训练 BigBird 在训练数据上微调,并报告测试集 F1。与此前最佳方法比较见表 6。可见 BigBird 几乎达到完美准确率,相对此前最佳约提升 。
| Model | TF | HM | DHS |
|---|---|---|---|
| gkm-SVM [30] | 89.6 | - | - |
| DeepSea [109] | 95.8 | 85.6 | 92.3 |
| BigBird | 96.1 | 88.7 | 92.1 |
Table 7: Chromatin-Profile Prediction
| Model | TF | HM | DHS |
|---|---|---|---|
| gkm-SVM [30] | 89.6 | - | - |
| DeepSea [109] | 95.8 | 85.6 | 92.3 |
| BigBird | 96.1 | 88.7 | 92.1 |
表 7:染色质图谱预测
Chromatin-Profile Prediction
Non-coding regions of DNA do not code for proteins. Majority of diseases and other trait associated single-nucleotide polymorphism are correlated to non-coding genomic variations [109, 46]. Thus, understanding the functional effects of non-coding regions of DNA is a very important task. An important step in this process, as defined by Zhou and Troyanskaya 2015, is to predict large-scale chromatin-profiling from non-coding genomic sequence. To this effect, DeepSea [109], compiled 919 chromatin-profile of 2.4M non-coding variants from Encyclopedia of DNA Elements (ENCODE)[^5] and Roadmap Epigenomics projects[^6]. The corresponding ML task is to predict, for a given non-coding region of DNA, these 919 chromatin-profile including transcription factors (TF) binding profiles for different TFs, DNase I sensitivity (DHS) profiles and histone-mark (HM) profiles. We jointly learn 919 binary classifiers to predict these functional effects from sequence of DNA fragments. On held-out chromosomes, we compare AUC with the baselines in Table 7 and see that we significantly improve on performance on the harder task HM, which is known to have longer-range correlations [27] than others.
染色质图谱预测
DNA 非编码区不编码蛋白质。多数疾病及其他性状相关的单核苷酸多态性与非编码基因组变异相关 [109, 46]。因此理解 DNA 非编码区的功能效应非常重要。Zhou 与 Troyanskaya 2015 定义的重要一步是从非编码基因组序列预测大规模染色质图谱。为此 DeepSea [109] 从 DNA 元件百科全书(ENCODE)[^5] 与 Roadmap Epigenomics 项目[^6] 汇编了 2.4M 非编码变异的 919 项染色质图谱。对应 ML 任务是:给定 DNA 非编码区,预测这 919 项染色质图谱,包括 160 种不同 TF 的 个转录因子(TF)结合图谱、 个 DNase I 敏感性(DHS)图谱与 个组蛋白标记(HM)图谱。我们联合学习 919 个二分类器,从 DNA 片段序列预测这些功能效应。在留出染色体上与基线比较 AUC(表 7),可见我们在更难的 HM 任务上显著提升——已知 HM 具有比其他任务更长程的相关 [27]。
6 Conclusion
6 结论
We propose BigBird: a sparse attention mechanism that is linear in the number of tokens. BigBird satisfies a number of theoretical results: it is a universal approximator of sequence to sequence functions and is also Turing complete. Theoretically, we use the power of extra global tokens preserve the expressive powers of the model. We complement these results by showing that moving to sparse attention mechanism do incur a cost. Empirically, BigBird gives state-of-the-art performance on a number of NLP tasks such as question answering and long document classification. We further introduce attention based contextual language model for DNA and fine-tune it for down stream tasks such as promoter region prediction and predicting effects of non-coding variants.
我们提出 BigBird:对 token 数线性的稀疏注意力机制。BigBird 满足若干理论结果:它是序列到序列函数的通用逼近器,且图灵完备。理论上,我们利用额外全局 token 的力量保留模型表达力。我们补充表明:转向稀疏注意力确有代价。经验上,BigBird 在问答与长文档分类等多项 NLP 任务上给出当时最优表现。我们进一步为 DNA 引入基于注意力的上下文化语言模型,并微调用于启动子区域预测与非编码变异效应预测等下游任务。
References
参考文献
Big Bird: Transformers for Longer Sequences – Appendix
Abboud et al. [2014] A. Abboud, V. V. Williams, and O. Weimann. Consequences of faster alignment of sequences. In International Colloquium on Automata, Languages, and Programming , pages 39–51. Springer, 2014.
Abboud et al. [2015] A. Abboud, A. Backurs, and V. V. Williams. Tight hardness results for lcs and other sequence similarity measures. In 2015 IEEE 56th Annual Symposium on Foundations of Computer Science , pages 59–78. IEEE, 2015.
Abreu et al. [2019] J. Abreu, L. Fred, D. Macêdo, and C. Zanchettin. Hierarchical attentional hybrid neural networks for document classification. In International Conference on Artificial Neural Networks , pages 396–402. Springer, 2019.
Ainslie et al. [2020] J. Ainslie, S. Ontanon, C. Alberti, P. Pham, A. Ravula, and S. Sanghai. Etc: Encoding long and structured data in transformers. arXiv preprint arXiv:2004.08483 , 2020.
Alberti et al. [2019] C. Alberti, K. Lee, and M. Collins. A bert baseline for the natural questions. arXiv preprint arXiv:1901.08634 , 2019.
Alt et al. [2019] J. Alt, R. Ducatez, and A. Knowles. Extremal eigenvalues of critical erd \ \backslash h { { o } } sr \ \backslash ’enyi graphs. arXiv preprint arXiv:1905.03243 , 2019.
Backurs and Indyk [2015] A. Backurs and P. Indyk. Edit distance cannot be computed in strongly subquadratic time (unless seth is false). In Proceedings of the forty-seventh annual ACM symposium on Theory of computing , pages 51–58, 2015.
Beltagy et al. [2020] I. Beltagy, M. E. Peters, and A. Cohan. Longformer: The long-document transformer. arXiv preprint arXiv:2004.05150 , 2020.
Benaych-Georges et al. [2019] F. Benaych-Georges, C. Bordenave, A. Knowles, et al. Largest eigenvalues of sparse inhomogeneous erdős–rényi graphs. Annals of Probability , 47(3):1653–1676, 2019.
Benaych-Georges et al. [2020] F. Benaych-Georges, C. Bordenave, A. Knowles, et al. Spectral radii of sparse random matrices. In Annales de l’Institut Henri Poincaré, Probabilités et Statistiques , volume 56, pages 2141–2161. Institut Henri Poincaré, 2020.
Bharanikumar et al. [2018] R. Bharanikumar, K. A. R. Premkumar, and A. Palaniappan. Promoterpredict: sequence-based modelling of escherichia coli σ \sigma 70 promoter strength yields logarithmic dependence between promoter strength and sequence. PeerJ , 6:e5862, 2018.
Buldyrev et al. [1995] S. Buldyrev, A. Goldberger, S. Havlin, R. Mantegna, M. Matsa, C.-K. Peng, M. Simons, and H. Stanley. Long-range correlation properties of coding and noncoding dna sequences: Genbank analysis. Physical Review E , 51(5):5084, 1995.
Busia et al. [2019] A. Busia, G. E. Dahl, C. Fannjiang, D. H. Alexander, E. Dorfman, R. Poplin, C. Y. McLean, P.-C. Chang, and M. DePristo. A deep learning approach to pattern recognition for short dna sequences. BioRxiv , page 353474, 2019.
Chen et al. [2019a] J. Chen, S.-t. Lin, and G. Durrett. Multi-hop question answering via reasoning chains. arXiv preprint arXiv:1910.02610 , 2019a.
Chen et al. [2019b] Y.-C. Chen, Z. Gan, Y. Cheng, J. Liu, and J. Liu. Distilling the knowledge of bert for text generation. arXiv preprint arXiv:1911.03829 , 2019b.
Child et al. [2019] R. Child, S. Gray, A. Radford, and I. Sutskever. Generating long sequences with sparse transformers. arXiv preprint arXiv:1904.10509 , 2019.
Chung and Lu [2002] F. Chung and L. Lu. The average distances in random graphs with given expected degrees. Proceedings of the National Academy of Sciences , 99(25):15879–15882, 2002.
Clark and Gardner [2017] C. Clark and M. Gardner. Simple and effective multi-paragraph reading comprehension. arXiv preprint arXiv:1710.10723 , 2017.
Clark et al. [2019] K. Clark, U. Khandelwal, O. Levy, and C. D. Manning. What does bert look at? an analysis of bert’s attention. arXiv preprint arXiv:1906.04341 , 2019.
Cohan et al. [2018] A. Cohan, F. Dernoncourt, D. S. Kim, T. Bui, S. Kim, W. Chang, and N. Goharian. A discourse-aware attention model for abstractive summarization of long documents. arXiv preprint arXiv:1804.05685 , 2018.
Dai et al. [2019] Z. Dai, Z. Yang, Y. Yang, J. Carbonell, Q. V. Le, and R. Salakhutdinov. Transformer-xl: Attentive language models beyond a fixed-length context. arXiv:1901.02860 , 2019.
Devlin et al. [2018] J. Devlin, M.-W. Chang, K. Lee, and K. Toutanova. Bert: Pre-training of deep bidirectional transformers for language understanding. arXiv preprint arXiv:1810.04805 , 2018.
Dong et al. [2019] L. Dong, N. Yang, W. Wang, F. Wei, X. Liu, Y. Wang, J. Gao, M. Zhou, and H.-W. Hon. Unified language model pre-training for natural language understanding and generation. In Advances in Neural Information Processing Systems , pages 13042–13054, 2019.
Dreos et al. [2013] R. Dreos, G. Ambrosini, R. Cavin Périer, and P. Bucher. Epd and epdnew, high-quality promoter resources in the next-generation sequencing era. Nucleic acids research , 41(D1):D157–D164, 2013.
Erkan and Radev [2004] G. Erkan and D. R. Radev. Lexrank: Graph-based lexical centrality as salience in text summarization. Journal of artificial intelligence research , 22:457–479, 2004.
Fang et al. [2019] Y. Fang, S. Sun, Z. Gan, R. Pillai, S. Wang, and J. Liu. Hierarchical graph network for multi-hop question answering. arXiv preprint arXiv:1911.03631 , 2019.
Gates et al. [2017] L. A. Gates, C. E. Foulds, and B. W. O’Malley. Histone marks in the ‘driver’s seat’: functional roles in steering the transcription cycle. Trends in biochemical sciences , 42(12):977–989, 2017.
Gehring et al. [2017] J. Gehring, M. Auli, D. Grangier, D. Yarats, and Y. N. Dauphin. Convolutional sequence to sequence learning. In Proceedings of the 34th International Conference on Machine Learning-Volume 70 , pages 1243–1252. JMLR. org, 2017.
Gehrmann et al. [2018] S. Gehrmann, Y. Deng, and A. M. Rush. Bottom-up abstractive summarization. arXiv preprint arXiv:1808.10792 , 2018.
Ghandi et al. [2014] M. Ghandi, D. Lee, M. Mohammad-Noori, and M. A. Beer. Enhanced regulatory sequence prediction using gapped k-mer features. PLoS computational biology , 10(7), 2014.
Gidiotis and Tsoumakas [2020] A. Gidiotis and G. Tsoumakas. A divide-and-conquer approach to the summarization of academic articles. arXiv preprint arXiv:2004.06190 , 2020.
Gong [2020 (accessed June 3, 2020] M. Gong. ReflectionNet , 2020 (accessed June 3, 2020). URL https://www.microsoft.com/en-us/research/people/migon/ .
Gray et al. [2017] S. Gray, A. Radford, and D. P. Kingma. Gpu kernels for block-sparse weights. arXiv preprint arXiv:1711.09224 , 3, 2017.
Guu et al. [2020] K. Guu, K. Lee, Z. Tung, P. Pasupat, and M.-W. Chang. Realm: Retrieval-augmented language model pre-training. arXiv preprint arXiv:2002.08909 , 2020.
He et al. [2019] J. He, L. Wang, L. Liu, J. Feng, and H. Wu. Long document classification from local word glimpses via recurrent attention learning. IEEE Access , 7:40707–40718, 2019.
Hermann et al. [2015] K. M. Hermann, T. Kocisky, E. Grefenstette, L. Espeholt, W. Kay, M. Suleyman, and P. Blunsom. Teaching machines to read and comprehend. In Advances in neural information processing systems , pages 1693–1701, 2015.
Hochreiter and Schmidhuber [1997] S. Hochreiter and J. Schmidhuber. Long short-term memory. Neural computation , 9(8):1735–1780, 1997.
Hoory et al. [2006] S. Hoory, N. Linial, and A. Wigderson. Expander graphs and their applications. Bulletin of the American Mathematical Society , 43(4):439–561, 2006.
Izacard and Grave [2020] G. Izacard and E. Grave. Leveraging passage retrieval with generative models for open domain question answering. arXiv preprint arXiv:2007.01282 , 2020.
Jiang et al. [2019] Y. Jiang, J. Petrak, X. Song, K. Bontcheva, and D. Maynard. Team bertha von suttner at semeval-2019 task 4: Hyperpartisan news detection using elmo sentence representation convolutional network. In Proceedings of the 13th International Workshop on Semantic Evaluation , pages 840–844, 2019.
Joshi et al. [2017] M. Joshi, E. Choi, D. S. Weld, and L. Zettlemoyer. Triviaqa: A large scale distantly supervised challenge dataset for reading comprehension. In Proceedings of the 55th Annual Meeting of the Association for Computational Linguistics , Vancouver, Canada, July 2017. Association for Computational Linguistics.
Joshi et al. [2020] M. Joshi, D. Chen, Y. Liu, D. S. Weld, L. Zettlemoyer, and O. Levy. Spanbert: Improving pre-training by representing and predicting spans. Transactions of the Association for Computational Linguistics , 8:64–77, 2020.
Katzav et al. [2018] E. Katzav, O. Biham, and A. K. Hartmann. Distribution of shortest path lengths in subcritical erdős-rényi networks. Physical Review E , 98(1):012301, 2018.
Kent et al. [2002] W. J. Kent, C. W. Sugnet, T. S. Furey, K. M. Roskin, T. H. Pringle, A. M. Zahler, and D. Haussler. The human genome browser at ucsc. Genome research , 12(6):996–1006, 2002.
Khandelwal et al. [2019] U. Khandelwal, K. Clark, D. Jurafsky, and L. Kaiser. Sample efficient text summarization using a single pre-trained transformer. arXiv preprint arXiv:1905.08836 , 2019.
Khurana et al. [2016] E. Khurana, Y. Fu, D. Chakravarty, F. Demichelis, M. A. Rubin, and M. Gerstein. Role of non-coding sequence variants in cancer. Nature Reviews Genetics , 17(2):93, 2016.
Kiesel et al. [2019] J. Kiesel, M. Mestre, R. Shukla, E. Vincent, P. Adineh, D. Corney, B. Stein, and M. Potthast. Semeval-2019 task 4: Hyperpartisan news detection. In Proceedings of the 13th International Workshop on Semantic Evaluation , pages 829–839, 2019.
Kim et al. [2018] B. Kim, H. Kim, and G. Kim. Abstractive summarization of reddit posts with multi-level memory networks. arXiv preprint arXiv:1811.00783 , 2018.
Kitaev et al. [2019] N. Kitaev, L. Kaiser, and A. Levskaya. Reformer: The efficient transformer. In International Conference on Learning Representations , 2019.
Kudo and Richardson [2018] T. Kudo and J. Richardson. Sentencepiece: A simple and language independent subword tokenizer and detokenizer for neural text processing. arXiv preprint arXiv:1808.06226 , 2018.
Kumar et al. [2020] V. Kumar, A. Choudhary, and E. Cho. Data augmentation using pre-trained transformer models. arXiv preprint arXiv:2003.02245 , 2020.
Kwiatkowski et al. [2019] T. Kwiatkowski, J. Palomaki, O. Redfield, M. Collins, A. Parikh, C. Alberti, D. Epstein, I. Polosukhin, J. Devlin, K. Lee, et al. Natural questions: a benchmark for question answering research. Transactions of the Association for Computational Linguistics , 7:453–466, 2019.
Lee and Hsiang [2020] J.-S. Lee and J. Hsiang. Patent classification by fine-tuning bert language model. World Patent Information , 61:101965, 2020.
Lee et al. [2019] K. Lee, M.-W. Chang, and K. Toutanova. Latent retrieval for weakly supervised open domain question answering. arXiv preprint arXiv:1906.00300 , 2019.
Levy et al. [2020] J. J. Levy, A. J. Titus, C. L. Petersen, Y. Chen, L. A. Salas, and B. C. Christensen. Methylnet: an automated and modular deep learning approach for dna methylation analysis. BMC bioinformatics , 21(1):1–15, 2020.
Lewis et al. [2019] M. Lewis, Y. Liu, N. Goyal, M. Ghazvininejad, A. Mohamed, O. Levy, V. Stoyanov, and L. Zettlemoyer. Bart: Denoising sequence-to-sequence pre-training for natural language generation, translation, and comprehension. arXiv preprint arXiv:1910.13461 , 2019.
Lewis et al. [2020] P. Lewis, E. Perez, A. Piktus, F. Petroni, V. Karpukhin, N. Goyal, H. Küttler, M. Lewis, W.-t. Yih, T. Rocktäschel, et al. Retrieval-augmented generation for knowledge-intensive nlp tasks. arXiv preprint arXiv:2005.11401 , 2020.
Liang [2012] W. Liang. Segmenting dna sequence into words based on statistical language model. Nature Precedings , pages 1–1, 2012.
Lin et al. [2017] H. Lin, Z.-Y. Liang, H. Tang, and W. Chen. Identifying sigma70 promoters with novel pseudo nucleotide composition. IEEE/ACM transactions on computational biology and bioinformatics , 2017.
Lin et al. [2003] J. Lin, D. Quan, V. Sinha, K. Bakshi, D. Huynh, B. Katz, and D. R. Karger. What makes a good answer? the role of context in question answering. In Proceedings of the Ninth IFIP TC13 International Conference on Human-Computer Interaction (INTERACT 2003) , pages 25–32, 2003.
Liu et al. [2020] D. Liu, Y. Gong, J. Fu, Y. Yan, J. Chen, D. Jiang, J. Lv, and N. Duan. Rikinet: Reading wikipedia pages for natural question answering. arXiv preprint arXiv:2004.14560 , 2020.
Liu and Lapata [2019] Y. Liu and M. Lapata. Text summarization with pretrained encoders. arXiv preprint arXiv:1908.08345 , 2019.
Liu et al. [2019] Y. Liu, M. Ott, N. Goyal, J. Du, M. Joshi, D. Chen, O. Levy, M. Lewis, L. Zettlemoyer, and V. Stoyanov. Roberta: A robustly optimized bert pretraining approach. arXiv preprint arXiv:1907.11692 , 2019.
Maas et al. [2011] A. Maas, R. E. Daly, P. T. Pham, D. Huang, A. Y. Ng, and C. Potts. Learning word vectors for sentiment analysis. In Proceedings of the 49th annual meeting of the association for computational linguistics: Human language technologies , pages 142–150, 2011.
Martin et al. [2019] L. Martin, B. Muller, P. J. O. Suárez, Y. Dupont, L. Romary, É. V. de la Clergerie, D. Seddah, and B. Sagot. Camembert: a tasty french language model. arXiv preprint arXiv:1911.03894 , 2019.
Miller [2019] D. Miller. Leveraging bert for extractive text summarization on lectures. arXiv preprint arXiv:1906.04165 , 2019.
Narayan et al. [2018] S. Narayan, S. B. Cohen, and M. Lapata. Don’t give me the details, just the summary! topic-aware convolutional neural networks for extreme summarization. arXiv preprint arXiv:1808.08745 , 2018.
Nenkova and Vanderwende [2005] A. Nenkova and L. Vanderwende. The impact of frequency on summarization. Microsoft Research, Redmond, Washington, Tech. Rep. MSR-TR-2005 , 101, 2005.
Olson et al. [2019] M. L. Olson, L. Zhang, and C.-N. Yu. Adapting pretrained language models for long document classification. OpenReview , 2019.
Oord et al. [2018] A. v. d. Oord, Y. Li, and O. Vinyals. Representation learning with contrastive predictive coding. arXiv preprint arXiv:1807.03748 , 2018.
Oubounyt et al. [2019] M. Oubounyt, Z. Louadi, H. Tayara, and K. T. Chong. Deepromoter: Robust promoter predictor using deep learning. Frontiers in genetics , 10, 2019.
Pérez et al. [2019] J. Pérez, J. Marinković, and P. Barceló. On the turing completeness of modern neural network architectures. arXiv preprint arXiv:1901.03429 , 2019.
Qiu et al. [2019] J. Qiu, H. Ma, O. Levy, S. W.-t. Yih, S. Wang, and J. Tang. Blockwise self-attention for long document understanding. arXiv preprint arXiv:1911.02972 , 2019.
Rae et al. [2019] J. W. Rae, A. Potapenko, S. M. Jayakumar, and T. P. Lillicrap. Compressive transformers for long-range sequence modelling. arXiv preprint arXiv:1911.05507 , 2019.
Raffel et al. [2019] C. Raffel, N. Shazeer, A. Roberts, K. Lee, S. Narang, M. Matena, Y. Zhou, W. Li, and P. J. Liu. Exploring the limits of transfer learning with a unified text-to-text transformer. arXiv preprint arXiv:1910.10683 , 2019.
Rothe et al. [2019] S. Rothe, S. Narayan, and A. Severyn. Leveraging pre-trained checkpoints for sequence generation tasks. arXiv preprint arXiv:1907.12461 , 2019.
See et al. [2017] A. See, P. J. Liu, and C. D. Manning. Get to the point: Summarization with pointer-generator networks. arXiv preprint arXiv:1704.04368 , 2017.
Sharma et al. [2019] E. Sharma, C. Li, and L. Wang. Bigpatent: A large-scale dataset for abstractive and coherent summarization. arXiv preprint arXiv:1906.03741 , 2019.
Shaw et al. [2018] P. Shaw, J. Uszkoreit, and A. Vaswani. Self-attention with relative position representations. arXiv preprint arXiv:1803.02155 , 2018.
Spielman and Teng [2011] D. A. Spielman and S.-H. Teng. Spectral sparsification of graphs. SIAM Journal on Computing , 40(4):981–1025, 2011.
Subramanian et al. [2019] S. Subramanian, R. Li, J. Pilault, and C. Pal. On extractive and abstractive neural document summarization with transformer language models. arXiv preprint arXiv:1909.03186 , 2019.
Sukhbaatar et al. [2019] S. Sukhbaatar, E. Grave, P. Bojanowski, and A. Joulin. Adaptive attention span in transformers. arXiv preprint arXiv:1905.07799 , 2019.
Sun et al. [2019] C. Sun, L. Huang, and X. Qiu. Utilizing bert for aspect-based sentiment analysis via constructing auxiliary sentence. arXiv preprint arXiv:1903.09588 , 2019.
Sussman [2017 (accessed June 3, 2020] D. Sussman. Lecture Notes for Boston University MA 882 Spring 2017 , 2017 (accessed June 3, 2020). URL http://math.bu.edu/people/sussman/MA882_2017/2017-01-26-Lecture-2.html .
Sutskever et al. [2014] I. Sutskever, O. Vinyals, and Q. V. Le. Sequence to sequence learning with neural networks. In Advances in neural information processing systems , pages 3104–3112, 2014.
Tampuu et al. [2019] A. Tampuu, Z. Bzhalava, J. Dillner, and R. Vicente. Viraminer: Deep learning on raw dna sequences for identifying viral genomes in human samples. PloS one , 14(9), 2019.
Tang et al. [2020] Z. Tang, Y. Shen, X. Ma, W. Xu, J. Yu, and W. Lu. Multi-hop reading comprehension across documents with path-based graph convolutional network. arXiv:2006.06478 , 2020.
Thongtan and Phienthrakul [2019] T. Thongtan and T. Phienthrakul. Sentiment classification using document embeddings trained with cosine similarity. In Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics: Student Research Workshop , pages 407–414, 2019.
Trinh and Le [2018] T. H. Trinh and Q. V. Le. A simple method for commonsense reasoning. arXiv preprint arXiv:1806.02847 , 2018.
Umarov and Solovyev [2017] R. K. Umarov and V. V. Solovyev. Recognition of prokaryotic and eukaryotic promoters using convolutional deep learning neural networks. PloS one , 12(2), 2017.
Vaswani et al. [2017] A. Vaswani, N. Shazeer, N. Parmar, J. Uszkoreit, L. Jones, A. N. Gomez, Ł. Kaiser, and I. Polosukhin. Attention is all you need. In Advances in neural information processing systems , pages 5998–6008, 2017.
Wang et al. [2018] A. Wang, A. Singh, J. Michael, F. Hill, O. Levy, and S. R. Bowman. Glue: A multi-task benchmark and analysis platform for natural language understanding. arXiv preprint arXiv:1804.07461 , 2018.
Wang et al. [2019] Z. Wang, P. Ng, X. Ma, R. Nallapati, and B. Xiang. Multi-passage bert: A globally normalized bert model for open-domain question answering. arXiv preprint arXiv:1908.08167 , 2019.
Watts and Strogatz [1998] D. J. Watts and S. H. Strogatz. Collective dynamics of ‘small-world’networks. nature , 393(6684):440–442, 1998.
Welbl et al. [2018] J. Welbl, P. Stenetorp, and S. Riedel. Constructing datasets for multi-hop reading comprehension across documents. Transactions of the Association for Computational Linguistics , 6:287–302, 2018.
Williams [2005] R. Williams. A new algorithm for optimal 2-constraint satisfaction and its implications. Theoretical Computer Science , 348(2-3):357–365, 2005.
Wiseman et al. [2017] S. Wiseman, S. M. Shieber, and A. M. Rush. Challenges in data-to-document generation. arXiv preprint arXiv:1707.08052 , 2017.
Xiao et al. [2019] X. Xiao, Z.-C. Xu, W.-R. Qiu, P. Wang, H.-T. Ge, and K.-C. Chou. ipsw (2l)-pseknc: A two-layer predictor for identifying promoters and their strength by hybrid features via pseudo k-tuple nucleotide composition. Genomics , 111(6):1785–1793, 2019.
Yang et al. [2017] Y. Yang, R. Zhang, S. Singh, and J. Ma. Exploiting sequence-based features for predicting enhancer–promoter interactions. Bioinformatics , 33(14):i252–i260, 2017.
Yang et al. [2018] Z. Yang, P. Qi, S. Zhang, Y. Bengio, W. W. Cohen, R. Salakhutdinov, and C. D. Manning. Hotpotqa: A dataset for diverse, explainable multi-hop question answering. arXiv preprint arXiv:1809.09600 , 2018.
Yang et al. [2019] Z. Yang, Z. Dai, Y. Yang, J. Carbonell, R. R. Salakhutdinov, and Q. V. Le. Xlnet: Generalized autoregressive pretraining for language understanding. In Advances in neural information processing systems , pages 5754–5764, 2019.
Yao et al. [2019] Z. Yao, S. Cao, W. Xiao, C. Zhang, and L. Nie. Balanced sparsity for efficient dnn inference on gpu. In Proceedings of the AAAI Conference on Artificial Intelligence , volume 33, pages 5676–5683, 2019.
Ye et al. [2019] Z. Ye, Q. Guo, Q. Gan, X. Qiu, and Z. Zhang. Bp-transformer: Modelling long-range context via binary partitioning. arXiv preprint arXiv:1911.04070 , 2019.
Yun et al. [2019] C. Yun, S. Bhojanapalli, A. S. Rawat, S. J. Reddi, and S. Kumar. Are transformers universal approximators of sequence-to-sequence functions? arXiv preprint arXiv:1912.10077 , 2019.
Yun et al. [2020] C. Yun, Y.-W. Chang, S. Bhojanapalli, A. S. Rawat, S. J. Reddi, and S. Kumar. o ( n ) o(n) connections are expressive enough: Universal approximability of sparse transformers. In Advances in Neural Information Processing Systems , 2020.
Zhang et al. [2019a] H. Zhang, C.-L. Hung, M. Liu, X. Hu, and Y.-Y. Lin. Ncnet: Deep learning network models for predicting function of non-coding dna. Frontiers in genetics , 10, 2019a.
Zhang et al. [2019b] J. Zhang, Y. Zhao, M. Saleh, and P. J. Liu. Pegasus: Pre-training with extracted gap-sentences for abstractive summarization. arXiv preprint arXiv:1912.08777 , 2019b.
Zhang et al. [2015] X. Zhang, J. Zhao, and Y. LeCun. Character-level convolutional networks for text classification. In Advances in neural information processing systems , pages 649–657, 2015.
Zhou and Troyanskaya [2015] J. Zhou and O. G. Troyanskaya. Predicting effects of noncoding variants with deep learning–based sequence model. Nature methods , 12(10):931–934, 2015.
Zhu et al. [2015] Y. Zhu, R. Kiros, R. Zemel, R. Salakhutdinov, R. Urtasun, A. Torralba, and S. Fidler. Aligning books and movies: Towards story-like visual explanations by watching movies and reading books. In IEEE international conference on computer vision , pages 19–27, 2015.
Appendix A Universal Approximators
附录 A 通用逼近器
A.1 Notation
A.1 记号
We begin by setting up some notations following Pérez et al. 2019 to formally describe the complete architecture of Transformers. A single layer of Transformer encoder is a parametric function receiving a sequence of vectors in and returning a sequence of the same length. Each is a dimensional vector as well. We interchangeably treat the sequence as a matrix in . has two components:
我们先按 Pérez 等人 2019 的设定引入记号,以便形式化描述 Transformer 的完整架构。单层 Transformer 编码器是参数化函数 :接收 中向量序列 ,返回同长序列 ;每个 也是 维。我们把序列 与 中的矩阵互换使用。 有两个部件:
- An attention mechanism Attn that takes in the sequence and returns sequence of the same length and dimensionality; and
- 注意力机制 Attn:吃进序列 ,返回同长同维序列 ;以及
- A two layer fully connected network that takes in a vector in and returns a vector in .
- 两层全连接网络 :吃进 中向量,返回 中向量。
Then -th output vector of is computed as follows:
于是 的第 个输出向量按如下计算:
Now it remains to define Attn and which we do next.
接下来定义 Attn 与 。
As described in Section 2, an attention mechanism is parameterized by three functions: . In this paper, we assume that they are simply matrix products: , , and , where and . In reality a multi-headed attention is used, i.e. we have not only one, but -sets of Query/Key/Value weight matrices, . Thus, for a directed graph over , the output vector of the generalized attention mechanism would be
如第 2 节所述,注意力机制由三个函数参数化:。本文假定它们就是矩阵乘:,,,其中 且 。实际使用多头注意力,即有 组 Query/Key/Value 权矩阵 ()。因此,对 上的有向图 ,广义注意力机制的第 个输出向量为
where denote the out-neighbors set of node in . In other words, the set of arcs (directed edges) in represents the set of inner products that our attention mechanism will consider. Also recall that is a scoring function such as softmax or hardmax.
其中 表示 中节点 的出邻集。换言之, 中弧(有向边)集合就是注意力机制会考虑的内积集合。再提醒: 是 softmax 或 hardmax 一类打分函数。
Lastly, we define the output fully connected network as follows:
最后,输出全连接网络定义为:
Here , , , and are parameters of output network .
这里 ,,, 是输出网络 的参数。
Additional Notation We introduce a few pieces of additional notation that will be useful. Let . Therefore, . We use to denote the indicator variable; it is if the event occurs and otherwise.
补充记号 再引入几处后面会用到的记号。令 。于是 。用 表示示性变量:事件 发生时为 1,否则为 0。
A.2 Proof
A.2 证明
In this section, we will present the full proof of theorem 1. The proof will contain three parts. The first and the third part will largely follow standard techniques. The main innovation lies is in the second part.
本节给出定理 1 的完整证明。证明分三部分:第一、第三部分大体沿用标准技术;主要创新在第二部分。
A.2.1 Approximate by piece-wise constant functions
First, we consider a suitable partition of the region into a grid of granularity , which we denote by . We do this using Lemma 8 from Yun et al. 2019, which we restate for completeness:
A.2.1 用分段常函数逼近
首先把区域 按粒度 做成合适剖分,记为 。做法沿用 Yun 等人 2019 的引理 8,为完整起见重述如下:
Lemma 1(Lemma 8 [104]).
For any given and , there exists a such that there exists a piece-wise constant function with . Concretely, is defined as
引理 1(引理 8 [104])。
对任意给定 与 ,存在 以及分段常函数 ,使 。具体地, 定义为
Since transformers can learn a positional embedding , without any loss of generality, we can consider the translated function. In particular, define
由于 Transformer 可以学习位置嵌入 ,不失一般性可考虑平移后的函数。具体定义
$$E=\begin{bmatrix}0&0&0&\dots&0\
\delta^{-d}&\delta^{-d}&\delta^{-d}&\dots&\delta^{-d}\
\delta^{-2d}&\delta^{-2d}&\delta^{-2d}&\dots&\delta^{-2d}\
\vdots\
\delta^{-(n-1)d}&\delta^{-(n-1)d}&\delta^{-(n-1)d}&\dots&\delta^{-(n-1)d}\
\end{bmatrix}$$
We will try to approximate where is defined on the domain . To do so, we will apply a suitable modification of Lemma 1, which will consider the discretized grid
我们要逼近 ,其定义域为 。为此对引理 1 做合适改写,并考虑离散网格
Therefore, it suffices to approximate a function defined as
因此只需逼近函数 ,定义为
A.2.2 Contextual Mappings and Sparse Attention Mechanisms
Throughout this section, we will assume that we are given a function that has an extra global token at index and all vectors have an extra dimension appended to them. The latter assumption is without loss of generality as we can use the Feed-Forward Network to append sparse dimensions. In particular, we will associate where we write . Although our function is only defined for , we can amend the function in a natural way by making it ignore the first column. To avoid excessive clutter, we will assume that the function value is evaluated on the last columns.
A.2.2 上下文映射与稀疏注意力机制
本节始终假定函数在索引 0 处多一个全局 token,且所有向量多一维。后一假设不失一般性,因为可用前馈网络追加稀疏维。具体地,令 ,写作 。尽管函数只定义在 上,可通过忽略第一列自然延拓。为减少记号混乱,假定函数值在最后 列上求值。
The main idea in this section is the use of contextual mapping to enable Transformers to compute any discretized function. A contextual mapping is an unique encoding of each tuple where , and each column for all . We restate the definition adapted to our setting below
本节核心想法是用上下文映射,使 Transformer 能计算任意离散化函数。上下文映射是对每个元组 的唯一编码,其中 ,且对所有 ,。下面重述适配到本设定的定义。
Definition 2(Defn 3.1 [104]).
(Contextual Mapping) A contextual mapping is a function mapping if it satisfies the following:
定义 2(定义 3.1 [104])。
(上下文映射)函数 称为上下文映射,若满足:
- For any,contains distinct entries.
- 对任意,的各分量互异。
- For any twowith, all entries ofandare distinct.
- 对任意两个且,与的所有分量彼此互异。
The key technical novelty of the proof is computing a contextual mapping using only the sparse attention mechanism. We create a “selective shift” operator which only shifts entries of a vector that lie in a certain range. We will use this shift operator strategically to ensure that we attain a contextual mapping at the end of the process. The lemma below, which is based on parts of the proof of Lemma 6 of [104], states that we can implement a suitable “selective” shift operator using a sparse attention mechanism.
证明的关键技术新颖之处在于:只用稀疏注意力机制计算上下文映射。我们构造「选择性移位」算子,只移动落在某范围内的向量分量;再策略性地使用该算子,最终得到上下文映射。下述引理基于 [104] 引理 6 证明的部分内容,说明可用稀疏注意力实现合适的「选择性」移位算子。
Lemma 2.
Given a function and a vector and a sparse attention mechanism based on the directed graph , we can implement a selective shift operator that receives as input a matrix and outputs where
引理 2。
给定函数 、向量 以及基于有向图 的稀疏注意力机制,可实现选择性移位算子:输入矩阵 ,输出 ,其中
$$\psi_{u}(Z;b_{1},b_{2}){i}=\begin{cases}(\max{j\in N(i)}u^{T}Z_{j}-\min_{j\in N(i)}u^{T}Z_{j})e_{1}&\text{ if }b_{1}\leq u^{T}Z_{j}\leq b_{2}\
0&\text{ else. }\end{cases}$$
Note that denotes .
注意 表示 。
Proof.
Consider the function , which can be implemented by a sparse attention mechanism :
证明。
考虑可由稀疏注意力机制实现的函数:
This is because the Key, Query and Value functions are simply affine transformations of .
因为 Key、Query、Value 函数都只是 的仿射变换。
Given any graph , the above function will evaluate to the following:
对任意图 ,上述函数求值为:
$$\tilde{\psi}(Z;b){i}=\begin{cases}(\max{j\in N(i)}u^{T}Z_{j})e_{1}&\text{ if }u^{T}Z_{j}>b\
(\min_{j\in N(i)}u^{T}Z_{j})e_{1}&\text{ if }u^{T}Z_{j}<b\
\end{cases}$$
Therefore we can say that satisfies
因此可以说 满足
$$\psi(Z;b_{1},b_{2}){i}=\begin{cases}(\max{j\in N(i)}u^{T}Z_{j}-\min_{j\in N(i)}u^{T}Z_{j})e_{1}&\text{ if }b_{1}\leq u^{T}Z_{j}\leq b_{2}\
0&\text{ else }\end{cases}$$
∎
The following lemma, which is the heart of the proof, uses the above selective shift operators to construct contextual mappings.
下述引理是证明的核心:用上述选择性移位算子构造上下文映射。
Lemma 3.
There exists a function and a unique vector , such that for all satisfies the property that is a contextual mapping of . Furthermore, using a composition of sparse attention layers as long as contains the star graph.
引理 3。
存在函数 与唯一向量 ,使得对所有 , 满足 是 的上下文映射。进一步,只要 含星图,则 ,可由稀疏注意力层复合得到。
Proof.
Define and let . We will assume that , by assuming that all the columns are appended by .
证明。
定义 ,并令 。假定所有列 末尾追加 0,从而 。
To successfully encode the entire context in each token, we will interleave the shift operator to target the original columns and to target the global column . After a column is targeted, its inner product with will encode the entire context of the first columns. Next, we will shift the global token to take this context into account. This can be subsequently used by the remaining columns.
为在每个 token 中成功编码完整上下文,我们交替对原始列 与全局列 做移位。列 被对准后,它与 的内积将编码前 列的全部上下文;再移位全局 token 以吸收该上下文,供后续列使用。
For , we will use to denote the innerproducts at the beginning. For after the column has changed for and we will use to denote after the phase. We need to distinguish the global token further as it’s inner product will change in each phase. Initially, given , the following are true:
对 ,用 记初始内积 。对 ,用 记第 列改变后的内积;用 记第 阶段后 。全局 token 的内积每阶段都会变,需要单独区分。初始时,给定 ,有:
Note that all ordered in distinct buckets .
注意所有 落在互异桶中:。
We do this in phases indexed from . Each phase consists of two distinct parts: The low shift operation: These operation will be of the form
我们按 分阶段进行。每阶段有两部分:低移位操作: 形式为
for values . The range is chosen so that only will be in the range and no other is in the range. This will shift exactly the column so that the new inner product is substantially larger than . Furthermore, no other column of will be affected. The high shift operation: These operation will be of the form
其中 。该范围只含 ,不含其他 ()。于是恰好移位第 列 ,使新内积 远大于 ,且 的其他列不受影响。高移位操作: 形式为
for values . The range is chosen to only affect the column (corresponding to the global token) and no other column. In particular, this will shift the global token by a further . Let denote the value of at the end of high operation.
其中 。区间 只影响列 (全局 token),不影响其他列;具体地,把全局 token 再移位 。令 表示第 次高操作结束时 的值。
Each phase interleaves a shift operation to column and updates the global token. After each phase, the updated column will contain a unique token encoding the values of all the . After the high update, will contain information about the first tokens.
每阶段交错:对列 做移位,再更新全局 token。每阶段结束后,更新后的第 列 含编码 全部值的唯一 token;高更新后, 含前 个 token 的信息。
Finally, we define the following constants for all .
最后,对所有 定义如下常数。
After each phases, we will maintain the following invariants:
每经过 个阶段,我们维持如下不变量:
- for all .
- 对所有 ,。
- The order of the inner products after phase is
- 第 阶段后内积次序为
Base case
The case , is trivial as we simply set , .
基础情形
平凡:直接取 ,。
The first nontrivial case is .
第一个非平凡情形是 。
Inductive Step
First, in the low shift operation is performed in the range Due to the invariant, we know that there exists only one column that is affected by this shift. In particular, for column , we will have . The minimum is . Thus the update will be . Observe that for small enough , . Hence the total ordering, after this operation is
归纳步骤
首先在区间 上做低移位。由不变量,只有列 受影响。对列 ,有 ,最小为 。于是更新为 。对足够小的 ,。故该操作后的全序为
Now when we operate a higher selective shift operator in the range . Since only global token’s innerproduct is in this range, it will be the only column affected by the shift operator. The global token operates over the entire range, we know from Equation 2 that, and . The new value . Expanding and simplifying we get,
接着在区间 上做更高的选择性移位。因只有全局 token 的内积 落在该区间,只有该列受影响。全局 token 覆盖全范围,由式 (2) 知 ,。新值 。展开并化简得
Since we know that and each , we can substitute this to get Equation UP and we can get an lower-bound Equation LP by using .
已知 且每个 ,代入可得式 UP;再用 可得下界式 LP。
By construction, we know that . For sufficiently small , observe that all are essentially the dominant term and all the lower order terms do not matter. As a result it is immediate to see that that and hence we can see that the invariant 2 is also satisfied. Since only column and the global token are affected, we can see that invariant 3 is also satisfied.
由构造知 。对足够小的 , 本质上都由主导项 决定,低阶项无关紧要。于是立即有 ,不变量 2 成立。又因只有列 与全局 token 受影响,不变量 3 亦成立。
After iterations, contains a unique encoding for any . To ensure that all tokens are distinct, we will add an additional layer for all . This ensures that for all , each entry of and are distinct. ∎
经 次迭代后, 对任意 含唯一编码。为确保所有 token 互异,再加一层 (对所有 )。这保证对所有 , 与 的每个分量都互异。∎
The previous lemma shows that we can compute a contextual mapping using only sparse transforms. We now use the following lemma to show that we can use a contextual mapping and feed-forward layers to accurately map to the desired output of the function .
上一引理表明只用稀疏变换即可计算上下文映射。下面用下一引理说明:可用上下文映射与前馈层精确映射到函数 的期望输出。
Lemma 4(Lemma 7 [104]).
Let be the function in Lemma 3, we can construct a function composed of feed-forward layers (with hidden dimension ) with activations in such that is defined as , where for all ,
引理 4(引理 7 [104])。
令 为引理 3 中的函数,可构造 ,由 个前馈层(隐维 、激活属于 )组成,定义为 ,其中对所有 ,
A.2.3 Approximating modified Transformers by Transformers
The previous section assumed we used Transformers that used hardmax operator and activations functions belonging to the set . This is without loss of generality as following lemma shows.
A.2.3 用 Transformer 逼近改性 Transformer
上一节假定使用 hardmax 算子 以及属于集合 的激活。这不失一般性,如下述引理所示。
Lemma 5(Lemma 9 [104]).
For each and , such that
引理 5(引理 9 [104])。
对每个 与 ,存在 使
Combining the above lemma with the Lemma 3, we get our main result:
把上述引理与引理 3 合在一起,得到主结果:
Theorem 2.
Let and , there exists a transformer network which achieves a ratio of where is the sparse graph.
定理 2。
设 且 ,存在 Transformer 网络 ,在稀疏图 上达到 。
Since the sparsity graph associated with BigBird contains a star network, we know that it can express any continuous function from a compact domain.
由于 BigBird 对应的稀疏图含星形网络,可知它能表达紧致定义域上的任意连续函数。
Contemporary work on Universal Approximability of Sparse Transformers
We would like to note that, contemporary work done by Yun et al. 2020, also parallelly explored the ability of sparse transformers with linear connections to capture sequence-to-sequence functions on the compact domain.
关于稀疏 Transformer 通用逼近性的同期工作
顺带指出:Yun 等人 2020 的同期工作也并行探讨了带线性连接的稀疏 Transformer 在紧致定义域上刻画序列到序列函数的能力。
Appendix B Turing Completeness
附录 B 图灵完备性
In this section, we will extend our results to the setting of Pérez et al. 2019. Our exposition will largely use their proof structure but we will make a few changes. We repeat some of the lemmas with the amendments to make the exposition self-contained.
本节把结果推广到 Pérez 等人 2019 的设定。叙述大体沿用他们的证明结构,但会做若干改动。我们重述部分引理并写明修正,以使论证自洽。
B.1 Notation
B.1 记号
Transformer Decoder
We need both an encoder and a decoder in the transformer for simulating a Turing machine. We utilize the same notation used in Section A.1 for encoders. The decoder is similar to an encoder but with additional attention to an external pair of key-value vectors , which usually come from the encoder stack. A single layer of Transformer decoder is a parametric function receiving a sequence of vectors in plus the external and returning a sequence of vectors of the same length. Each is a dimensional vector as well. has three components, one more than :
Transformer 解码器
要模拟图灵机,Transformer 需要编码器与解码器。编码器记号与第 A.1 节相同。解码器类似编码器,但额外对一对外部键–值向量 (通常来自编码器栈)做注意力。单层 Transformer 解码器是参数化函数 :接收 中向量序列 与外部 ,返回同长向量序列 ;每个 亦为 维。 有三个部件,比 多一个:
- An attention mechanism Attn that takes in the sequence and returns sequence of the same length and dimensionality;
- 注意力机制 Attn:吃进序列 ,返回同长同维序列 ;
- A cross-attention mechanism CrossAttn that takes in the sequence plus the external and returns sequence , with each ; and
- 交叉注意力机制 CrossAttn:吃进序列 与外部 ,返回序列 ,每个 ;以及
- A two layer fully connected network that takes in a vector in and returns a vector in .
- 两层全连接网络 :吃进 中向量,返回 中向量。
Then -th output vector of is computed as follows:
于是 的第 个输出向量按如下计算:
and are as defined in Section A.1 and it remains to define CrossAttn. The output vector of multi-head cross-attention attention is given by
与 如第 A.1 节所定义,剩下定义 CrossAttn。多头交叉注意力的第 个输出向量为
where , , for all heads.
其中对所有 个头,,。
Turning Machine
We will use the same setup of Turning Machine that was used by Pérez et al. 2019 (see section B.4). Given a Turing Machine , we use the following notation
图灵机
我们采用与 Pérez 等人 2019 相同的图灵机设定(见其 B.4 节)。给定图灵机 ,使用如下记号
Vector representations
For a symbol , denotes its one-hot vector representation in . All the transformer intermediate vectors used in our simulations have dimension . Note that we use five extra dimension as compared to Pérez et al. 2019. We follow the convention used in Pérez et al. 2019 and write a a vector arranged in four groups of values as follows
向量表示
对符号 , 表示其在 中的 one-hot 向量。模拟所用全部 Transformer 中间向量维数为 。注意比 Pérez 等人 2019 多了五维。我们沿用他们的约定,把向量 写成四组值如下
$$\begin{array}[]{rcllr}{\bm{v}}&=&[&{\bm{q}}{1},{\bm{s}}{1},x_{1},\
&&&{\bm{q}}{2},{\bm{s}}{2},x_{2},x_{3},x_{4},x_{5},x_{6},\
&&&{\bm{s}}{3},x{7},{\bm{s}}{4},\
&&&x{8},x_{9},x_{10},x_{11},x_{12},x_{13},x_{14},x_{15},x_{16}&]\end{array}$$
where , , and .
其中 ,,。
B.2 Details of the Simulation
B.2 模拟细节
In this section, we give more details on the architecture of the encoder and decoder needed to implement our simulation strategy.
本节更细致地给出实现模拟策略所需的编码器与解码器架构。
Figure 2: Mapping between transformer step and original Turing machine step.
图 2:Transformer 步与原图灵机步之间的对应。
High Level Overview:
Given the Turing machine , we will show that a transformer with an appropriate encoder and decoder can simulate each step of ’s execution. Our simulation strategy will mostly follow Pérez et al. 2019, except we will use a sparse attention mechanism. The main idea is to maintain the current Turing machine state and symbol under the head as part of the decoder sequence for all time step so that we can always simulate the corresponding Turing machine transition . The key difference will rise in Lemma B.4 of Pérez et al. 2019, where full attention is used to select the appropriate symbol from tape history in one step. To accomplish the same task with sparse attention, we will exploit the associative property of max and break down the symbol selection over multiple steps. Thus, unlike Pérez et al. 2019 one decoding step of our sparse transformer does not correspond to one step of the Turing machine . In particular, we will have two type of steps: compute step corresponding to update of ’s state and intermediate steps corresponding to aggregating the max (which in turn is used for symbol selection). Let denote the step of and denote the step of being simulated at step of the decoder. At each decoding step we want to maintain the current Turing machine state and symbol under the in . For roughly intermediate steps the state will remain the same, while we aggregate information about relevant past output symbols through sparse attention. To maintain the same state for intermediate steps, we introduce an extra switching layer (Section B.2.3). Finally, at the next compute step we will make the transition to new state , new head movement , and new output symbol to be written. Thereby we are able to completely simulate the given Turing machine . As a result, we can prove the following main theorem:
高层概览:
给定图灵机 ,我们将证明带合适编码器与解码器的 Transformer 能模拟 执行的每一步。模拟策略大体沿用 Pérez 等人 2019,但改用稀疏注意力。核心想法是:在所有时间步 ,把当前图灵机状态 与磁头下符号 维持在解码器序列 中,以便始终能模拟转移 。关键差别出现在 Pérez 等人 2019 的引理 B.4:那里用全注意力一步从纸带历史选出合适符号。为用稀疏注意力完成同样任务,我们利用 max 的结合律,把符号选择拆到多步。因此,与 Pérez 等人 2019 不同,我们的稀疏 Transformer 的一步解码并不对应 的一步。具体有两类步:对应更新 状态的计算步,以及对应聚合 max(进而用于符号选择)的中间步。令 为 的步, 为解码器第 步所模拟的 步。每一步解码都要在 中维持当前状态 与磁头下符号 。大约 个中间步内状态不变,同时通过稀疏注意力聚合相关历史输出符号。为在中间步保持同一状态,我们引入额外切换层(第 B.2.3 节)。最后在下一计算步转移到新状态 、新磁头移动 与待写新输出符号 。由此完整模拟给定图灵机 。于是可证如下主定理:
Theorem 3.
There exists a sparse attention mechanism using inner products such that the resulting class of Transformer Networks using this sparse attention mechanism is Turing Complete.
定理 3。
存在仅用 个内积的稀疏注意力机制,使采用该机制的 Transformer 网络类是图灵完备的。
Encoder
As [72], we use the same trivial single layer encoder where resulting contains position embedding and contains one-hot symbol representation.
编码器
与 [72] 一样,我们使用平凡的单层编码器:所得 含位置嵌入, 含 one-hot 符号表示。
Sparse Self-Attention mechanism for Decoder
In this section, we will consider a particular instance of the sparse graph at decoder. We define its edges to be given by the following relations: ,
解码器的稀疏自注意力机制
本节考虑解码器上稀疏图 的一个具体实例。定义其边由如下关系给出:对所有 ,,
This graph can be seen as a special case of BigBird where first type of edges are realizations of random and second type of edges correspond to locality. Also note that this graph satisfies the left-to-right constraint of decoder, i.e. no node attends to a node in the future.
该图可看作 BigBird 的特例:第一类边是随机边的实现,第二类边对应局部性。同时注意该图满足解码器的从左到右约束,即任何节点都不关注未来节点。
Embeddings and positional encodings
Our construction needs a different positional encoding for decoder:
嵌入与位置编码
我们的构造需要解码器使用不同的位置编码 :
$$\begin{array}[]{rcllr}\operatorname{pos}_{\operatorname{Dec}}(i)&=&[&0,\ldots,0,\
&&&0,\ldots,0,\
&&&0,\ldots,0,\
&&&1,g(i)+1,\frac{1}{g(i)+1},\frac{1}{(g(i)+1)^{2}},h(i),0,0,0,0&]\end{array}$$
where and . Note that reduces to a binary indicator variable .
其中 ,。注意 化为二值示性变量 。
Induction Setup
We next show how to construct the decoder layers to produce the sequence of outputs , where is given by:
归纳设定
下面说明如何构造解码器各层以产生输出序列 ,其中 为:
$$\begin{array}[]{rcllr}{{\bm{y}}}{i}&=&[&\llbracket\ q^{g(i)}\ \rrbracket,\llbracket\ s^{g(i)}\ \rrbracket,c^{g(i)},\
&&&0,\ldots,0,\
&&&{\bm{0}}{s},0,\llbracket\ w^{(i)}\ \rrbracket,\
&&&0,0,0,0,0,u_{1}^{(i)},u_{2}^{(i)},u_{3}^{(i)},u_{4}^{(i)}&]\end{array}$$
That is, at step of our sparse decoder , it will contain the information about the state of the turing machine at time , the symbol under the head of at time , and the current location of head of at time . We also have a placeholder symbol and placeholder scalars , whose role will be clear from our construction.
也就是说,在稀疏解码器第 步, 含时刻 时图灵机 的状态、磁头下符号以及磁头当前位置。另有占位符号 与占位标量 ,其作用将在构造中说明。
We consider as the starting vector for the decoder the vector
我们取解码器起始向量为
$$\begin{array}[]{rcllr}{{\bm{y}}}{1}&=&[&\llbracket\ q{\text{init}}\ \rrbracket,\llbracket\ #\ \rrbracket,0,\
&&&0,\ldots,0,\
&&&0,\ldots,0,\
&&&0,\ldots,0&]\end{array}$$
We assume that the start head is at , the initial state is , and as we initialize from clean tape. We show the correctness of our construction by an inductive argument: we describe the architecture piece by piece and at the same time will show for every , our architecture constructs from the previous vectors .
假定起始磁头在 ,初始状态 ,且因从空白纸带初始化有 。用归纳论证构造的正确性:逐块描述架构,同时证明对每个 ,架构能由前向量 构造 。
Thus, assume that satisfy the properties stated above. Since we are using positional encodings, the actual input for the first layer of the decoder is the sequence
于是假定 满足上述性质。由于使用位置编码,解码器第一层的实际输入序列为
We denote by the vector plus its positional encoding. Thus we have that
用 记 加上其位置编码。于是对所有 有
$$\begin{array}[]{rcllr}\overline{{\bm{y}}}{i}&=&[&\llbracket\ q^{g(i)}\ \rrbracket,\llbracket\ s^{g(i)}\ \rrbracket,c^{g(i)},\
&&&0,\ldots,0,\
&&&{\bm{0}}{s},0,\llbracket\ w^{(i)}\ \rrbracket,\
&&&1,g(i)+1,\frac{1}{g(i)+1},\frac{1}{(g(i)+1)^{2}},h(i),u_{1}^{(i)},u_{2}^{(i)},u_{3}^{(i)},u_{4}^{(i)}&]\end{array}$$
B.2.1 Layer 1: Simulate Transition Function
In this layer, we use the cross-attention between encoder and decoder to access the input string and a feed-forward network to simulate the transition function of . The first self attention in Equation 5 is not used in this layer and we just produce the identity. This identity function is achieved by setting all queries, keys, values to be 0 everywhere plus the residual connection. Thus, we have .
B.2.1 第 1 层:模拟转移函数
本层用编码器与解码器之间的交叉注意力访问输入串,并用前馈网络模拟 的转移函数。式 (5) 中的第一次自注意力在本层不用,只产生恒等映射;做法是把所有 query、key、value 处处置 0,再加残差连接。于是 。
Since is of the form , we know by Lemma B.1 of Pérez et al. 2019 that if we use to attend over the encoder we obtain
由于 形如 ,由 Pérez 等人 2019 引理 B.1,用 对编码器做注意力可得
$$\begin{array}[]{rcllr}\textsc{CrossAttn}({\bm{p}}^{1}{i},{\bm{K}}^{\textbf{e}},{\bm{V}}^{\textbf{e}})&=&[&0,\ldots,0,\
&&&0,\ldots,0,\
&&&\llbracket\ \alpha^{g(i)+1}\ \rrbracket,\beta^{g(i)+1},{\bm{0}}{s},\
&&&0,\ldots,0&]\end{array}$$
where and are as defined in Eq. (21) of [72]. Thus in Equation 4 we finally produce the vector given by
其中 、 如 [72] 式 (21) 所定义。于是在式 (4) 中最终得到向量 :
$$\begin{array}[]{rcllr}{\bm{a}}^{1}{i}&=&&\textsc{CrossAttn}({\bm{p}}^{1}{i},{\bm{K}}^{\textbf{e}},{\bm{V}}^{\textbf{e}})+{\bm{p}}^{1}{i}\
&=&[&\llbracket\ q^{g(i)}\ \rrbracket,\llbracket\ s^{g(i)}\ \rrbracket,c^{g(i)},\
&&&0,\ldots,0,\
&&&\llbracket\ \alpha^{g(i)+1}\ \rrbracket,\beta^{g(i)+1},\llbracket\ w^{(i)}\ \rrbracket,\
&&&1,g(i)+1,\frac{1}{g(i)+1},\frac{1}{(g(i)+1)^{2}},h(i),u{1}^{(i)},u_{2}^{(i)},u_{3}^{(i)},u_{4}^{(i)}&]\end{array} \tag{7}$$
As the final piece of the first decoder layer we use a function (Equation 3) that satisfies the following lemma.
作为第一解码层的最后一块,我们使用满足下述引理的函数 (式 3)。
Lemma 6(Lemma B.2 [72]).
There exists a two-layer feed-forward network such that with input vector (Equation 7) produces as output
引理 6(引理 B.2 [72])。
存在两层前馈网络 ,以向量 (式 7)为输入时输出
$$\begin{array}[]{rcllr}O_{1}({\bm{a}}^{1}_{i})&=&[&0,\ldots,0,\
&&&\llbracket\ q^{g(i)+1}\ \rrbracket,\llbracket\ v^{g(i)}\ \rrbracket,m^{g(i)},0,0,0,0\
&&&0,\ldots,0,\
&&&0,\ldots,0&]\end{array}$$
That is, function simulates transition to construct , , and besides some other linear transformations.
也就是说,函数 模拟转移 ,构造 、 与 ,外加若干线性变换。
Thus, finally the output of the first decoder layer is
于是第一解码层的最终输出为
$$\begin{array}[]{rcllr}{\bm{z}}^{1}{i}=O{1}({\bm{a}}^{1}{i})+{\bm{a}}^{1}{i}&=&[&\llbracket\ q^{g(i)}\ \rrbracket,\llbracket\ s^{g(i)}\ \rrbracket,c^{g(i)},\
&&&\llbracket\ q^{g(i)+1}\ \rrbracket,\llbracket\ v^{g(i)}\ \rrbracket,m^{g(i)},0,0,0,0,\
&&&\llbracket\ \alpha^{g(i)+1}\ \rrbracket,\beta^{g(i)+1},\llbracket\ w^{(i)}\ \rrbracket,\
&&&1,g(i)+1,\frac{1}{g(i)+1},\frac{1}{(g(i)+1)^{2}},h(i),u_{1}^{(i)},u_{2}^{(i)},u_{3}^{(i)},u_{4}^{(i)}&]\end{array}$$
B.2.2 Layer 2: Finding Head Node
In this layer, we only use the feed-forward network to evaluate the next location of the head. The self-attention and cross-attention are set to be the identity function, so . Recall that is the cell to which is pointing to at time , and that it satisfies the following recursion , which can be expanded to see that that . Its not difficult to see that a two layer network with non-linearity can compute and from , , and using the relation . At the end of layer 2, we obtain
B.2.2 第 2 层:寻找磁头节点
本层只用前馈网络计算磁头下一位置。自注意力与交叉注意力设为恒等,故 。回忆 是时刻 时 指向的单元,满足递归 ,展开即 。不难看出,带非线性的两层网络可由 、 与 ,利用关系 算出 与 。第 2 层结束时得到
$$\begin{array}[]{rcllr}{\bm{z}}^{2}{i}\ =\ O{2}({\bm{a}}^{2}{i})+{\bm{a}}^{2}{i}&=&[&\llbracket\ q^{g(i)}\ \rrbracket,\llbracket\ s^{g(i)}\ \rrbracket,c^{g(i)},\
&&&\llbracket\ q^{g(i)+1}\ \rrbracket,\llbracket\ v^{g(i)}\ \rrbracket,c^{g(i)+1},\frac{1}{g(i)+1},\frac{1}{(g(i)+1)^{2}},\frac{c^{g(i)+1}}{g(i)+1},\frac{c^{g(i)}}{g(i)+1},\
&&&\llbracket\ \alpha^{g(i)+1}\ \rrbracket,\beta^{g(i)+1},\llbracket\ w^{(i)}\ \rrbracket,\
&&&1,g(i)+1,\frac{1}{g(i)+1},\frac{1}{(g(i)+1)^{2}},h(i),u_{1}^{(i)},u_{2}^{(i)},u_{3}^{(i)},u_{4}^{(i)}&]\end{array}$$
B.2.3 Layer 3: Distinguishing Node Type
This is an additional layer (not present in the work of [72]), where we propagate computations in our sparse graph. In particular, we will use this layer to “compute” or accumulate state in intermediate nodes. We make this clear below. The self-attention and cross-attention are all set to be the identity function, so . In this layer, we only use the dense attention layers to select the newly computed states or to continue with previous states. Using idea similar to Lemma B.6 of [72], we can construct a dense network such that
B.2.3 第 3 层:区分节点类型
这是额外一层([72] 中没有),用于在稀疏图上传播计算。具体地,用它在中间节点上「计算」或累积状态。下文说清。自注意力与交叉注意力均设为恒等,故 。本层只用稠密注意力层在新计算状态与继续沿用旧状态之间选择。借用类似 [72] 引理 B.6 的想法,可构造稠密网络使
$$O([{\bm{x}},{\bm{y}},{\bm{z}},b]))=\begin{cases}[{\bm{0}},{\bm{0}},{\bm{0}},0]&\text{if }b=1,\
[{\bm{0}},{\bm{z}}-{\bm{y}},-{\bm{z}},0]&\text{if }b=0.\end{cases}$$
The negatives are generated to offset results from skip connection. We utilize such network to switch Turing machine state and position embedding for intermediate steps to the values received from previous time step and do nothing for compute nodes. We use as the flipping bit . Thus, at end of layer 3, we obtain
负号用于抵消跳跃连接的结果。我们用这样的网络:对中间步,把图灵机状态与位置嵌入切到上一时刻收到的值;对计算节点则不动。用 作为翻转位 。于是第 3 层结束时得到
$$\begin{array}[]{rcllr}{\bm{z}}^{3}{i}\ =\ O{3}({\bm{a}}^{3}{i})+{\bm{a}}^{3}{i}&=&[&0,\ldots,0,\
&&&\llbracket\ \hat{q}^{(i)}\ \rrbracket,\llbracket\ \hat{v}^{(i)}\ \rrbracket,\hat{c}^{(i)},\frac{1}{g(i)+1},\frac{1}{(g(i)+1)^{2}},\frac{c^{g(i)+1}}{g(i)+1},\hat{u}{4}^{(i)},\
&&&\llbracket\ \hat{\alpha}^{(i)}\ \rrbracket,\hat{\beta}^{(i)},{\bm{0}}{s},\
&&&1,\hat{u}{1}^{(i)},\hat{u}{2}^{(i)},\hat{u}_{3}^{(i)},h(i),0,0,0,0&]\end{array}$$
where we used for selecting old states. In particular,
其中用 选择旧状态。具体地,
- • We copy the input state and head position as is for intermediate nodes. We do not need to transition to next Turing machine states in these nodes.
- • 对中间节点,原样复制输入状态与磁头位置。这些节点上不需要转移到下一图灵机状态。
| , | , | . |
|---|
| , | , | 。 |
|---|
- • To preserve the symbol under the head for intermediate nodes, we copy the previous symbol to location and set , as the symbol at location will be copied as the symbol under head for next transformer step by the final transformation layer if . Thus, we correctly preserve the previous symbol under head as Turing machine does not transition these nodes. For compute nodes, things happen as usual.
- • 为在中间节点保留磁头下符号,把上一符号复制到 位置并设 ,因为若 ,最终变换层会把 位置的符号复制为下一步 Transformer 的磁头下符号。于是在图灵机不转移的这些节点上,正确保留了上一磁头下符号。对计算节点则照常进行。
| , | . |
|---|
| , | 。 |
|---|
- • Finally for the intermediate nodes, we copy the position embedding corresponding to current best symbol , which is stored in . For compute node, we let the position embedding correspond to current Turing machine step.
- • 最后,对中间节点,复制对应当前最佳符号 的位置嵌入(存在 中)。对计算节点,令位置嵌入对应当前图灵机步。
| , | , | |
|---|---|---|
| , | . |
| , | , | |
|---|---|---|
| , | 。 |
For further simplification note that if else when . With this fact, we can conclude that and . Thus, we can write,
为进一步化简,注意:若 则 ,若 则 。由此得 、。于是可写
$$\begin{array}[]{rcllr}{\bm{z}}^{3}{i}&=&[&0,\ldots,0,\
&&&\llbracket\ {q}^{g(i+1)}\ \rrbracket,\llbracket\ \hat{v}^{(i)}\ \rrbracket,{c}^{g(i+1)},\frac{1}{g(i)+1},\frac{1}{(g(i)+1)^{2}},\frac{c^{g(i)+1}}{g(i)+1},\hat{u}{4}^{(i)},\
&&&\llbracket\ \hat{\alpha}^{(i)}\ \rrbracket,\hat{\beta}^{(i)},{\bm{0}}{s},\
&&&1,\hat{u}{1}^{(i)},\hat{u}{2}^{(i)},\hat{u}{3}^{(i)},h(i),0,0,0,0&]\end{array}$$
B.2.4 Layer 4: Finding next symbol on tape
To find the symbol on tape under next head position , we try to find what was written last at the location . To facilitate this, following [72], we define to be the last time (previous to ) in which was pointing to position , or it is if this is the first time that is pointing to . Recall is the Turing machine step counter, which is different from sparse transformer step . [72] could utilize full attention mechanism to find at one go, but we have to do it over multiple steps owing to our sparse attention mechanism.
B.2.4 第 4 层:寻找纸带上下一符号
为找到下一磁头位置 下的纸带符号,我们试图找出位置 上最后一次写入的内容。为此,沿用 [72],定义 为(早于 的) 上一次指向位置 的时刻;若这是第一次指向 ,则取 。注意 是图灵机步计数,不同于稀疏 Transformer 步 。[72] 可用全注意力一次找到 ,而我们因稀疏注意力必须分多步完成。
We use similar query, key, value functions as used for full attention by [72] :
我们使用与 [72] 全注意力类似的 query、key、value 函数,对所有 :
$$\begin{array}[]{rcllr}Q_{4}({\bm{z}}^{3}_{i})&=&[&0,\ldots,0\
&&&0,\ldots,0,\
&&&0,\ldots,0,\
&&&0,\frac{c^{g(i)+1}}{g(i)+1},\frac{1}{g(i)+1},\frac{1}{3(g(i)+1)^{2}},0,0,0,0,0&]\
\end{array}$$
$$\begin{array}[]{rcllr}K_{4}({\bm{z}}^{3}{i})&=&[&0,\ldots,0\
&&&0,\ldots,0,\
&&&0,\ldots,0,\
&&&0,\hat{u}{2}^{(i)},\hat{u}{4}^{(i)},\hat{u}{3}^{(i)},0,0,0,0,0&]\
V_{4}({\bm{z}}^{3}{i})&=&[&0,\ldots,0,\
&&&0,\ldots,0,\
&&&{\bm{0}}{s},0,\llbracket\ \hat{v}^{(i)}\ \rrbracket,\
&&&0,0,0,0,0,\hat{u}{1}^{(i)},\hat{u}{2}^{(i)},\hat{u}{3}^{(i)},\hat{u}{4}^{(i)}&]\end{array}$$
It is clear that the three functions are linear transformations and thus they can be defined by feed-forward networks. Notice that the query vector is always formed using current time step position embedding, whereas key and value vectors are formed using copied over entries for intermediate nodes and using current entries only for compute node.
显然这三个函数都是线性变换,因而可由前馈网络定义。注意:query 向量总由当前时间步的位置嵌入构成;而 key 与 value 在中间节点上用复制过来的条目,在计算节点上才用当前条目。
Pérez et al. 2019 find the desired as using full attention, where
Pérez 等人 2019 用全注意力把期望的 找成 ,其中
Note the minimization is only over Turing machine steps, i.e. over compute nodes in our case. We show below that we can estimates by parts using sparse attention mechanism. The main idea is just to notice that minimization problem can be expressed as by the associativity property.
注意最小化只对图灵机步(即我们的计算节点)进行。下面说明可用稀疏注意力分段估计 。核心只是注意到最小化问题 可由结合律写成 。
By definition of our graph , at every intermediate node of the form , i.e. where , and , we will attend over node and best till now copied from . The node is never an intermediate node as for all and in fact corresponds to Turing machine’s step . This will help us select the key and value corresponding to min between node and . In other words, at node of the form we would have evaluated and corresponding value selected:
按图 的定义,在每个形如 (即 )的中间节点 上, 且 ,我们会关注节点 以及从 复制来的「迄今最佳」。节点 从不是中间节点,因为对所有 有 ,它实际对应图灵机的第 步。这将帮助我们选出最小化问题对应的 key 与 value。
and similarly for ’s. So after going through all the intermediate nodes, finally at the next compute node, i.e. when , we will obtain the minimum value over all of . This implies at a compute node will be able to recover and its corresponding value as shown in Lemma B.4 of [72]. Then we have that is given by
对各个 同理。因此走完所有中间节点后,在下一计算节点(即 )上将得到对全部 的最小值。这意味着在计算节点上能如 [72] 引理 B.4 所示恢复 及其对应值。于是 为
$$\begin{array}[]{rcllr}{\bm{p}}^{4}{i}&=&&\textsc{Attn}{D}({\bm{Z}}{i}^{3})+{\bm{z}}^{3}{i}\
&=&[&0,\ldots,0,\
&&&\llbracket\ q^{g(i+1)}\ \rrbracket,\llbracket\ \hat{v}^{(i)}\ \rrbracket,c^{g(i+1)},0,\frac{c^{g(i)+1}}{g(i)+1},\hat{u}{4}^{(i)},\
&&&\llbracket\ \hat{\alpha}^{(i)}\ \rrbracket,\hat{\beta}^{(i)},\llbracket\ w^{(i+1)}\ \rrbracket,\
&&&1,\hat{u}{1}^{(i)},\hat{u}{2}^{(i)},\hat{u}{3}^{(i)},h(i),{u}{1}^{(i+1)},{u}{2}^{(i+1)},{u}{3}^{(i+1)},{u}{4}^{(i+1)}&]\end{array} \tag{8}$$
The cross-attention and feed-forward network are set to be identity, so .
交叉注意力与前馈网络设为恒等,故 。
B.2.5 Final transformation
We finish our construction by using the final transformation function from the corresponding lemma from Pérez et al. 2019, with a slight modification.
B.2.5 最终变换
最后用 Pérez 等人 2019 对应引理中的最终变换函数 结束构造,并做一处小修改。
Lemma 7(Lemma B.5 [72]).
There exists a function defined by a feed-forward network such that
引理 7(引理 B.5 [72])。
存在由前馈网络定义的函数 ,使得
$$\begin{array}[]{rcllr}F({\bm{z}}^{4}{r})&=&[&\llbracket\ q^{g(r+1)}\ \rrbracket,\llbracket\ s^{g(r+1))}\ \rrbracket,c^{g(r+1)},\
&&&0,\ldots,0,\
&&&{\bm{0}}{s},0,\llbracket\ w^{(r+1)}\ \rrbracket,\
&&&0,0,0,0,0,{u}{1}^{(r+1)},{u}{2}^{(r+1)},{u}{3}^{(r+1)},{u}{4}^{(r+1)}]\
&=&&{\bm{y}}_{r+1}\end{array}$$
The modification is to let to pass through. This yields the desired input to transformer at next time step for both intermediate and compute node, thereby concluding our induction.
修改是让 直接通过。这为中间节点与计算节点都给出下一步 Transformer 的期望输入,从而完成归纳。
Appendix C Limitations
附录 C 局限
Finally, we show that sparse attention mechanisms can not universally replace dense attention mechanisms, i.e. there is no free lunch. We demonstrate a natural task which can be solved by the full attention mechanism in -layers. However, under standard complexity theoretic assumptions, we show that this problem will require -layers for any sparse attention layers with edges (not just BigBird). (We use the standard notation to hide the dependence on poly-logarithmic factors. )
最后,我们表明稀疏注意力机制不能普遍替代稠密注意力,即没有免费午餐。我们展示一个全注意力可用 层解决的自然任务;但在标准复杂性假设下,对任意带 条边的稀疏注意力层(不仅是 BigBird),该问题需要 层。(我们用标准记号 隐藏对多项式对数因子的依赖。)
We consider the simple problem of finding the furthest vector for each vector in the given sequence of length and dimension . The assumption on the dimension is mild , as in many situations the dimension is actually comparable to the number of .
考虑在长度 、维度 的给定序列中,为每个向量找最远向量的简单问题。对维度的假设是温和的,因为许多情形下维度 实际上与 可比。
Task 1.
Given unit vectors , each in where , compute $f(u_{1},\dots,u_{n})\to(u_{1^{}},\dots,u_{n^{}})j\in[n]j^{}=\argmax_{k}|u_{k}-u_{j}|_{2}^{2}$.*
任务 1。
给定 个单位向量 ,每个在 中且 ,计算 $f(u_{1},\dots,u_{n})\to(u_{1^{}},\dots,u_{n^{}})j\in[n]j^{}=\argmax_{k}|u_{k}-u_{j}|_{2}^{2}$。*
Finding vectors that are furthest apart boils down to minimizing inner product search in case of unit vectors. For a full-attention mechanism with appropriate query and keys, this task is very easy as we can evaluate all pair-wise inner products.
找相距最远的向量在单位向量情形归结为最小化内积搜索。对带合适查询与键的全注意力,该任务很容易,因为可评估所有成对内积。
The impossibility for sparse-attention follows from hardness results stemming from Orthogonal Vector Conjecture (OVC) [2, 1, 96, 7], which is a widely used assumption in fine-grained complexity. Informally, it states that one cannot determine if the minimum inner product among Boolean vectors is in subquadratic time.
稀疏注意力的不可能性来自正交向量猜想(OVC)[2, 1, 96, 7] 的困难性结果;OVC 是细粒度复杂性中广泛使用的假设。非正式地说,它断言无法在亚二次时间内判定 个布尔向量间最小内积是否为 0。
Conjecture 1(Orthogonal Vectors Conjecture).
For every , there is a such that given Boolean vectors in dimension, cannot determine if there is a pair of orthogonal vectors in time on instances with .
猜想 1(正交向量猜想)。
对每个 ,存在 ,使得给定 维的 个布尔向量,在 的实例上无法在 时间内判定是否存在一对正交向量。
Using 1, we show a reduction to show that a transformer for any sparse directed graph which completes Task must require a superlinear number of layers.
利用 1,我们做归约表明:对任意稀疏有向图 ,完成任务 1 的 Transformer 必须需要超线性层数。
Proposition 2.
There exists a single layer full-attention network that can evaluate Task 1, i.e. $g(u_{1},...,u_{n})=[u_{1^{}},\dots,u_{n^{}}]\mathcal{T}_{D}^{H=O(d),m=O(d),q=O(d)}D\tilde{O}(n)\tilde{\Omega}(n^{1-o(1)})$ layers.
命题 2。
存在单层全注意力网络 可评估任务 1,即 $g(u_{1},...,u_{n})=[u_{1^{}},\dots,u_{n^{}}]\mathcal{T}_{D}^{H=O(d),m=O(d),q=O(d)}D\tilde{O}(n)\tilde{\Omega}(n^{1-o(1)})$ 层。
Proof.
We will break this proof into two parts:
证明。
我们将证明拆成两部分:
Part 1: The full attention mechanism can solve the problem in layer
We begin by providing an explicit construction of a single layer full self-attention that can evaluate Task 1.
第 1 部分:全注意力机制可用 层求解该问题
我们先给出可评估任务 1 的单层全自注意力显式构造。
Step 1 We embed each in the input into as follows:
步骤 1 把输入中每个 嵌入到 如下:
Step 2 Construct query, key, value functions as follows:
步骤 2 构造查询、键、值函数如下:
Then . Then,
则 。于是,
Step 3 Let , then the output as desired.
步骤 3 令 ,则输出 ,即所欲。
To complete the argument, observe that it now only takes inner products to check if there is a pair of orthogonal vectors as we need only compare .
为完成论证,观察现在只需 次内积即可检查是否存在正交向量对,因为只需比较 。
Part 2: Every Sparse Attention Mechanism will need layers
We prove by contradiction that it is impossible to solve Task 1 by any sparse-attention graph with edges.
第 2 部分:每个稀疏注意力机制都需要 层
我们用反证法证明:任何 、图 带 条边的稀疏注意力都不可能求解任务 1。
Suppose we can solve Task 1 using a network that has layers. Recall that all the computation we do in one layer is:
假定可用有 层的网络 求解任务 1。回忆一层中的全部计算为:
where is defined in eq. AT.
其中 由式 AT 定义。
Thus, total computation per layer is and consequently for the whole network consisting of layers.
因此每层总计算为 ,从而由 层组成的整网为 。
We can use the result of Task 1 to solve the orthogonal vector (OV) problem (defined in 1) in linear time. So in total, we will be able to solve any instance of OV in time.
我们可用任务 1 的结果在线性时间内解正交向量(OV)问题(定义于 1)。因此总共能在 时间内解任意 OV 实例。
Now if for any and , then it appears that we are able to solve OV in which contradicts 1. Therefore, we need at least layers. ∎
若对任意 有 且 ,则似乎能在 内解 OV,与 1 矛盾。因此至少需要 层。∎
Appendix D Implementation details
附录 D 实现细节
We optimize the code for modern hardware. Hardware accelerators like GPUs and TPUs truly shine on coalesced memory operations which load blocks of contiguous bytes at once. Thus, its not very efficient to have small sporadic look-ups caused by a sliding window or random element queries. We alleviate this by “blockifying” the lookups.
我们针对现代硬件优化代码。GPU 与 TPU 等硬件加速器真正擅长合并内存操作——一次加载连续字节块。因此,由滑动窗口或随机元素查询引起的零星小查找并不高效。我们通过把查找「分块化」来缓解。
(a) Random Attention
(a) 随机注意力
GPU/TPU and Sparsity
Ideally, if the adjacency matrix described in Section 2 is sparse, one would hope this would be sufficient to speed up the implementation. Unfortunately, it is well known [33, 102], that such sparse multiplications cannot be efficiently implemented in GPUs. GPUs have thousands of cores performing operations in parallel. Thus, we cannot efficiently perform the sparse matrix multiplication mentioned in section Section 2.
GPU/TPU 与稀疏性
理想情况下,若第 2 节所述邻接矩阵 稀疏,人们会希望这足以加速实现。不幸的是,众所周知 [33, 102],此类稀疏乘法无法在 GPU 上高效实现。GPU 有数千核并行运算,因此无法高效执行第 2 节提到的稀疏矩阵乘法。
As a result we propose to first blockify the attention pattern i.e. we pack sets of query and keys together and then define attention on these blocks. It is easier to explain this process using the example shown in Figure 3. Suppose, there are query and key vectors to attend to. Using a block size of , we split the query matrix into blocks and similarly the key matrix into blocks. Then the three different building components of BigBird are defined on the block matrix. In particular the three different components are:
于是我们建议先把注意力模式分块化,即把成组的查询与键打包,再在这些块上定义注意力。用图 3 所示例子更易说明。假定有 个查询与 个键向量要关注。用块大小 ,把查询矩阵分成 块,键矩阵同样分成 块。然后在块矩阵上定义 BigBird 的三个构件。具体地,三个不同组件为:
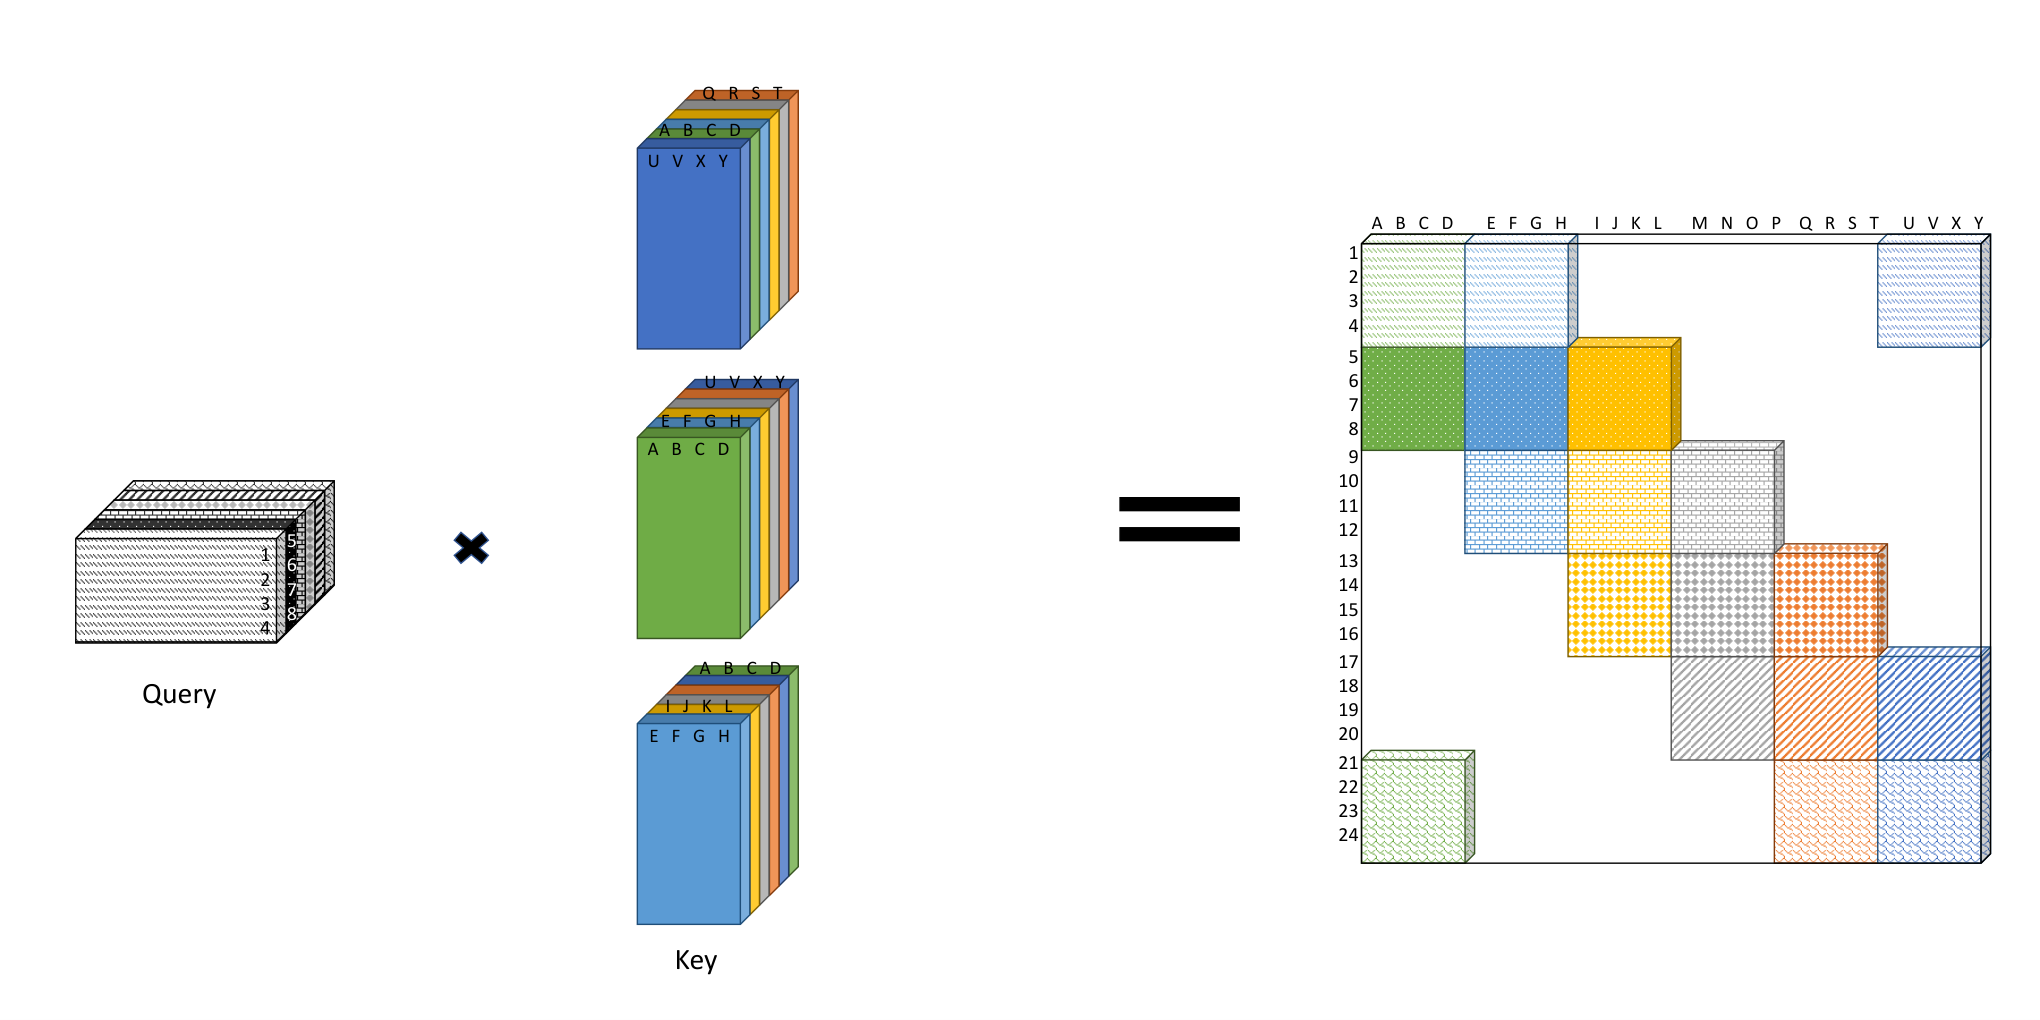
Figure 3: Building blocks of the block-attention mechanism used in BigBird with block size . The attention matrix is split into blocks; panels show random, window, and global block-sparse patterns.
图 3:BigBird 所用块注意力机制的构件(块大小 )。注意力矩阵按块划分;各子图对应随机、窗口与全局等块稀疏模式。
- Random attention: Each query block attends to random key blocks. In Figure 3(a), with block size . This implies that each query block of size randomly attends to a key block of size .
- 随机注意力:每个查询块关注 个随机键块。在图 3(a) 中,、块大小 。这意味着每个大小为 的查询块随机关注一个大小为 的键块。
- Window local attention: While creating the block, we ensure that the number of query blocks and the number of key blocks are the same. This helps us in defining the block window attention. Every query block with index attends to key block with index to , including key block . In Figure 3(b), with block size . It means that each query block (size queries) attends to key block .
- 窗口局部注意力:创建块时保证查询块数与键块数相同,以便定义块窗口注意力。索引为 的每个查询块关注索引从 到 的键块(含键块 )。在图 3(b) 中,、块大小 。意味着每个查询块 ( 个查询)关注键块 。
- Global attention: Global attention remains the same as defined in Section 2, but we compute it in terms of blocks. In Figure 3(c), with block size . For BigBird-itc this implies that one query and key block, attend to everyone.
- 全局注意力:全局注意力与第 2 节定义相同,但按块计算。在图 3(c) 中,、块大小 。对 BigBird-itc,这意味着一个查询块与一个键块关注所有人。
The resulting overall attention matrix is shown in Figure 3(d). Unfortunately, simply trying to compute this attention score as multiplying arbitrary pairs of query and key vectors would require use of gather operation, which is inefficient. Upon closer examination of window and global attention, we observe that we can compute these attention scores without using a gather operation.
所得整体注意力矩阵见图 3(d)。不幸的是,若简单把任意查询–键向量对相乘来算注意力分数,需要 gather 操作,效率低。仔细考察窗口与全局注意力后,我们观察到可不使用 gather 计算这些注意力分数。
(a) Full all pair attention can be obtained by direct matrix multiplication between the query and key matrix. Groupings just shown for guidance.
(a) 完整成对注意力可由查询与键矩阵直接矩阵乘得到。分组仅为示意。
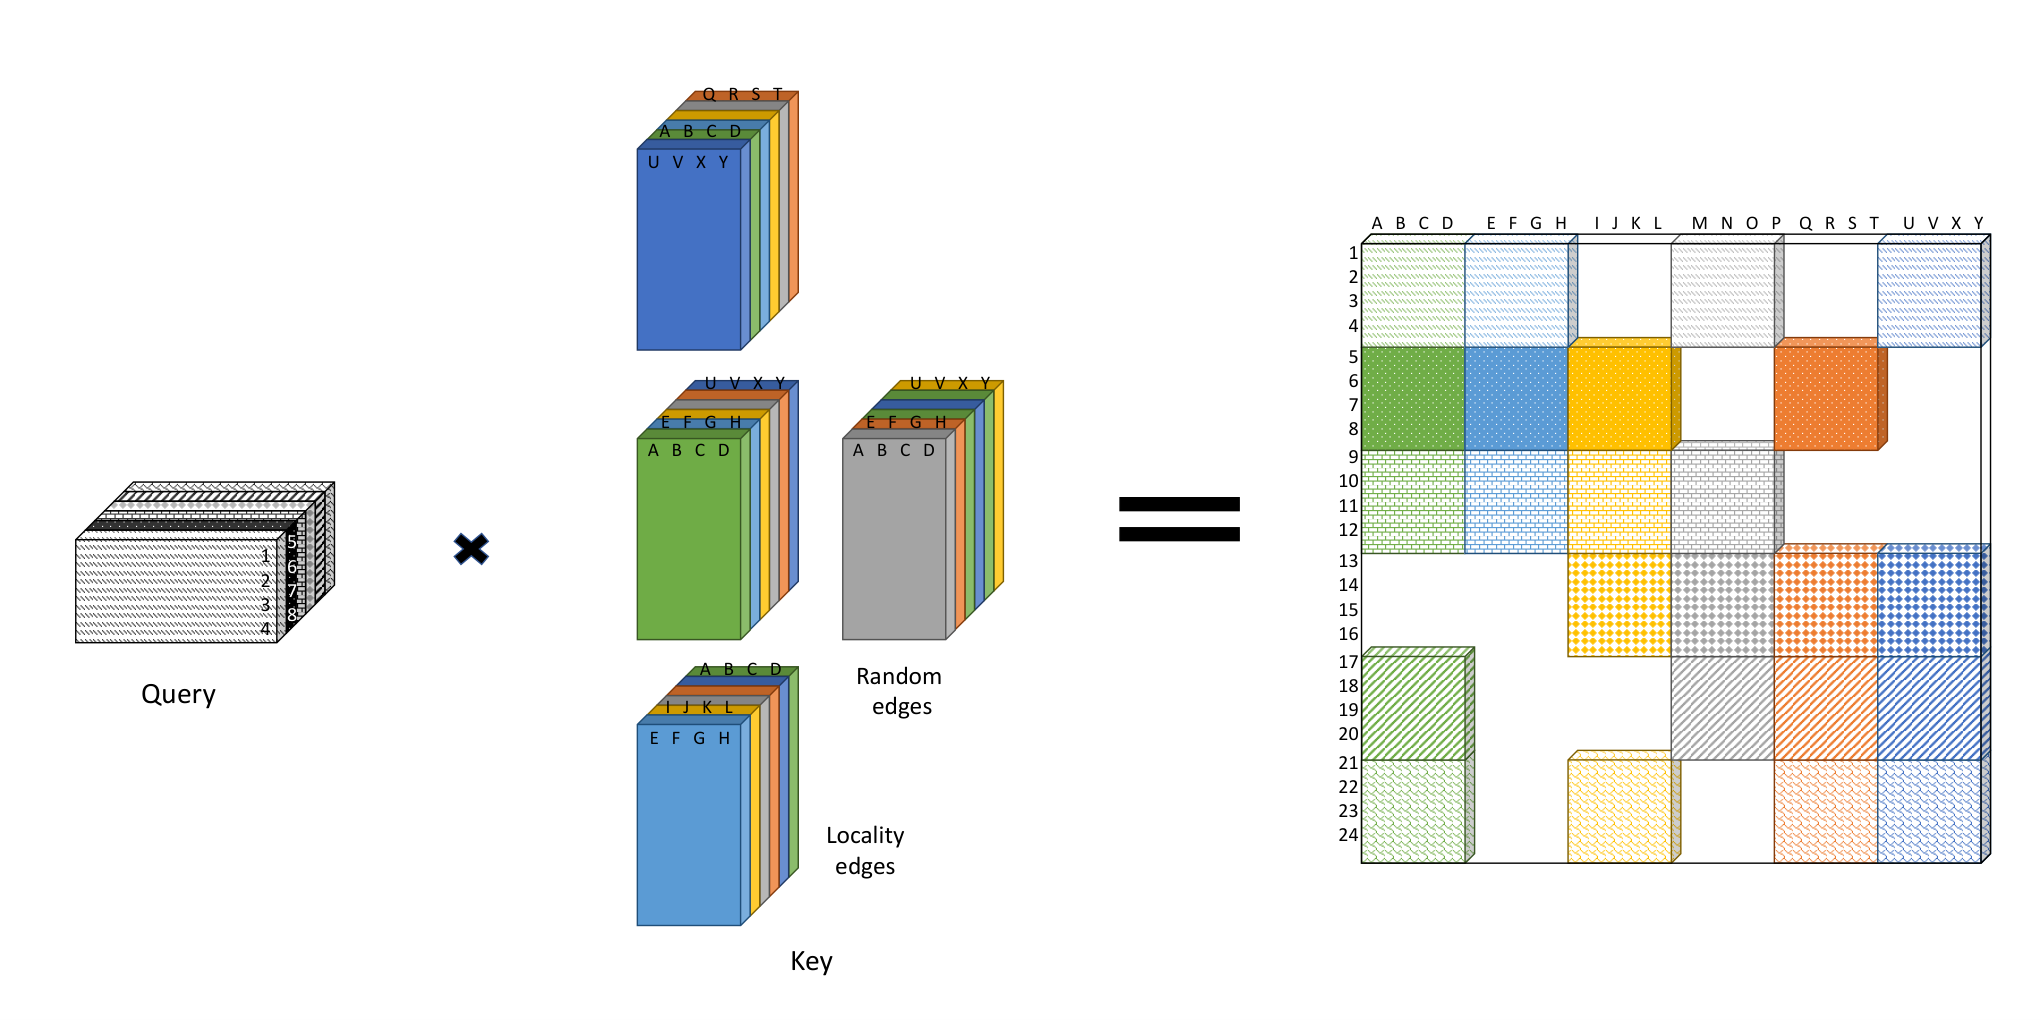
Figure 4: Idea behind fast sparse attention computation in BigBird.
图 4:BigBird 快速稀疏注意力计算的思路示意。
Recall, full dense attention scores can be calculated by simple matrix product of query and key matrix with a cost of , as illustrated in Figure 4(a). Now note that if we blockify the query and key matrix and multiply, then with only cost we will obtain the block diagonal portion of the attention score, as depicted in Figure 4(b). To elaborate this lets assume that are the query and key matrix corresponding to tokens such that and . We reshape query matrix, , and key matrix, , along the sequence length to obtain tensors and respectively. Now we multiply the two tensors as
回忆:全稠密注意力分数可由查询与键矩阵简单矩阵乘以 代价算出,如图 4(a)。若把查询与键矩阵分块再相乘,则仅以 代价得到注意力分数的块对角部分,如图 4(b)。展开来说,设 为对应 个 token 的查询与键矩阵,满足 、。沿序列长度把 的查询矩阵 与键矩阵 重塑,分别得到 张量 与 。再把两张量相乘为
The resulting tensor of size can be reshaped to correspond to the block diagonal portion of the full attention pattern. Now to extend the attention from block diagonal to a window, i.e. where query block with index attends to key block with index to , we make copies of the reshaped key tensor . We “roll” each copy of key-block tensor incrementally along the first axis of length as illustrated in Figure 5. Multiplying these rolled key-block tensors with the query-block tensor would yield the desired window attention scores (Figure 4(c)). Likewise the global component, we can always include the first blocks from key tensor corresponding to the global tokens. Finally, for the random attention, which is very small ( for all of our experiments), we resort to using gather ops (Figure 4(d)). Also note by design, each query block attends to exactly random blocks.
所得大小为 的 张量可重塑以对应全注意力模式的块对角部分。要把注意力从块对角扩展到窗口——即索引 的查询块关注索引从 到 的键块——我们对重塑后的键张量 做 份拷贝。如图 5 所示,沿长度 的第一轴把每份键块张量增量「滚动」。把这 个滚动键块张量与查询块张量相乘,即得所需窗口注意力分数(图 4(c))。同样对全局分量,我们总可纳入对应全局 token 的键张量前 块。最后,对随机注意力(我们全部实验中很小,),诉诸 gather 操作(图 4(d))。另按设计,每个查询块恰好关注 个随机块。
Thus, the result of all the three components is basically a compact dense tensor of size as shown in Figure 6. Computing the final attention score then just boils down to a dense tensor multiplication, at which TPU/GPU are very efficient. Specifically, we need to multiply (size: ) and (size: ) with a cost of to yield the desired attention score tensor of size , which can be reshaped to obtain all the attention scores according to the BigBird pattern.
于是,三个组件的结果本质上是大小为 的紧凑稠密张量 ,如图 6。计算最终注意力分数于是归结为稠密张量乘法,TPU/GPU 对此极为高效。具体地,需以 代价把 (大小:)与 (大小:)相乘,得到大小为 的所需注意力分数张量,再重塑即可得到按 BigBird 模式的全部注意力分数。
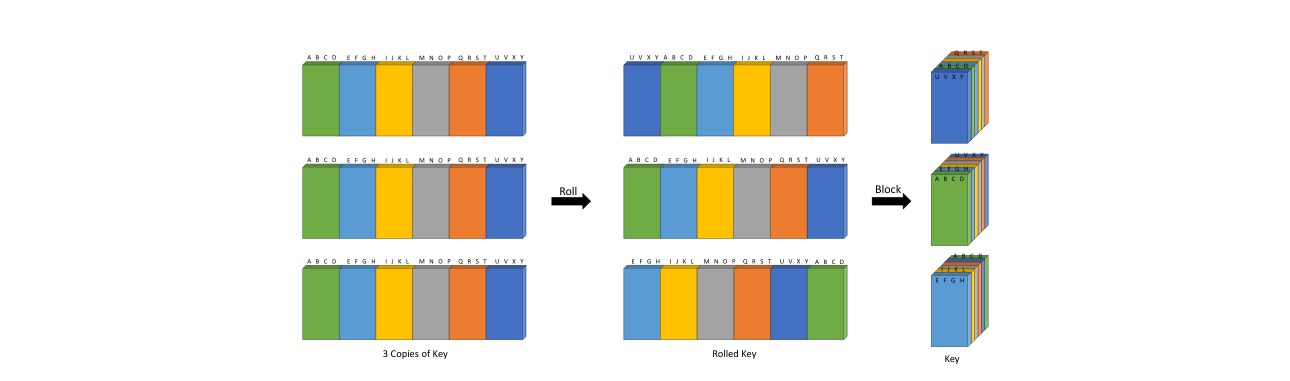
Figure 5: Construction of rolled key-block tensor. Make copies of the key matrix. Index the copies as . Roll copy by blocks. Positive roll means circular shift entries left and likewise for negative roll corresponds to right shift. Finally, reshape by grouping the blocks along a new axis to obtain the key-blocked tensor. For illustration purpose is chosen.
图 5:滚动键块张量的构造。对键矩阵做 份拷贝。把拷贝索引为 。把第 份拷贝滚动 个块。正滚动表示循环左移条目,负滚动对应右移。最后沿新轴把块分组重塑,得到键分块张量。为说明取 。
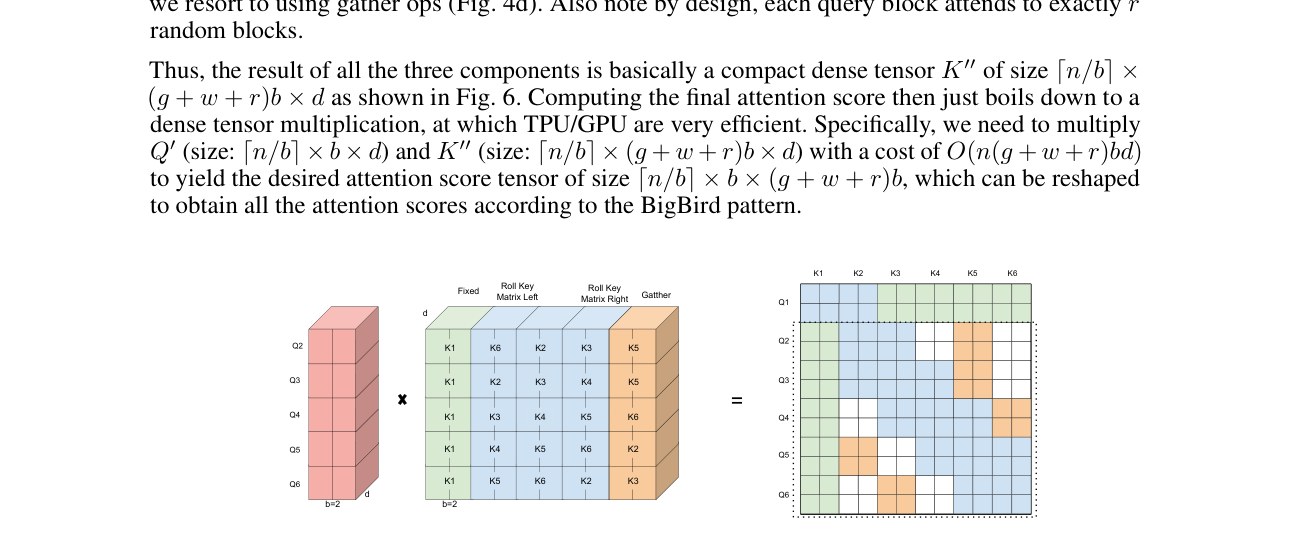
Figure 6: Overview of BigBird attention computation. Structured block sparsity helps in compactly packing our operations of sparse attention, thereby making our method efficient on GPU/TPU. On the left, we depict the transformed dense query and key tensors. The query tensor is obtained by simply blocking and reshaping while the final key tensor by concatenating three transformations: The first green columns, corresponding to global attention, is fixed. The middle blue columns correspond to window local attention and can be obtained by appropriately rolling as illustrated in Figure 5. For the final orange columns, corresponding to random attentions, we need to use computationally inefficient gather operation. Dense multiplication between the query and key tensors efficiently calculates the sparse attention pattern (except the first row-block, which is computed by direct multiplication), using the ideas illustrated in Figure 4. The resultant matrix on the right is same as that shown in Figure 3(d).
图 6:BigBird 注意力计算总览。结构化块稀疏有助于紧凑打包稀疏注意力运算,从而使我们的方法在 GPU/TPU 上高效。左侧描绘变换后的稠密查询与键张量。查询张量由简单分块与重塑得到;最终键张量由三种变换拼接:对应全局注意力的首组绿色列固定;中间蓝色列对应窗口局部注意力,可按图 5 适当滚动得到;对应随机注意力的末组橙色列需用计算上低效的 gather。查询与键张量的稠密乘法高效算出稀疏注意力模式(除第一行块由直接乘法计算外),思路见图 4。右侧所得矩阵与图 3(d) 相同。
Appendix E NLP experiments details
附录 E NLP 实验细节
E.1 MLM Pretraining
E.1 MLM 预训练
We use four publicly available datasets Books [110], CC-News [34], Stories [89] and Wikipedia to pretrain BigBird. We borrow the sentencepiece vocabulary as RoBERTa (which is in turn borrowed from GPT2). We split any document longer than into multiple documents and we join documents that were much smaller than . Following the original BERT training, we mask of tokens in these four datasets, and train to predict the mask. We warm start from RoBERTa’s checkpoint. We train two different models: BigBird-itc-base and BigBird-etc-base. The hyper-parameters for these two models are given in Table 8. In all experiments we use a learning rate warmup over the first 10,000 steps, and linear decay of the learning rate.
我们用四个公开数据集 Books [110]、CC-News [34]、Stories [89] 与 Wikipedia 预训练 BigBird。词表沿用 RoBERTa 的 sentencepiece(其本身借自 GPT2)。长度超过 的文档拆成多份,远短于 的文档则拼接。沿用原 BERT 的掩码语言模型设定做预训练;批大小、学习率与步数等细节见表。
Similar to the norm, we trained a large version of model as well, which has 24 layers with 16 heads and hidden dimension of 1024. Following the observation from RoBERTa, we pretrain on a larger batch size of 2048 for this size. For BigBird-itc the block length was kept same as base size, but for BigBird-etc the block length was almost doubled to 169. All the remaining parameters were the same.
与惯例类似,我们也训练了大模型:24 层、16 头、隐维 1024。沿用 RoBERTa 的观察,该规模用更大的批大小 2048 预训练。BigBird-itc 的块长与 base 相同;BigBird-etc 的块长几乎加倍到 168。
| Parameter | BigBird-itc | BigBird-etc | ||
|---|---|---|---|---|
| Block length, | 84 | |||
| of global token, | ||||
| Window length, | ||||
| of random token, | ||||
| Max. sequence length | ||||
| of heads | ||||
| of hidden layers | ||||
| Hidden layer size | ||||
| Batch size | ||||
| Loss | MLM | MLM | ||
| Activation layer | gelu | gelu | ||
| Dropout prob | ||||
| Attention dropout prob | ||||
| Optimizer | Adam | Adam | ||
| Learning rate | ||||
| Compute resources | TPUv3 | TPUv3 |
Table 8: Hyperparameters for the two BigBird base models for MLM.
| 参数 | BigBird-itc | BigBird-etc | ||
|---|---|---|---|---|
| 块长 | 84 | |||
| 全局 token 数 | ||||
| 窗口长 | ||||
| 随机 token 数 | ||||
| 最大序列长 | ||||
| 头数 | ||||
| of hidden layers | ||||
| Hidden layer size | ||||
| 批大小 | ||||
| Loss | MLM | MLM | ||
| Activation layer | gelu | gelu | ||
| Dropout prob | ||||
| 注意力 Dropout prob | ||||
| Optimizer | Adam | Adam | ||
| Learning rate | ||||
| Compute resources | TPUv3 | TPUv3 |
Table 8: Hyperparameters for the two BigBird base models for MLM.
| Dataset | tokens | Avg. doc len. |
|---|---|---|
| Books [110] | B | K |
| CC-News [34] | B | |
| Stories [89] | B | K |
| Wikipedia | B |
| Model | Base | Large |
|---|---|---|
| RoBERTa (sqln: 512) | 1.846 | 1.496 |
| Longformer (sqln: 4096) | 1.705 | 1.358 |
| BigBird-itc (sqln: 4096) | 1.678 | 1.456 |
| BigBird-etc (sqln: 4096) | 1.611 | 1.274 |
Table 9: Dataset used for pre training.
| 数据集 | token 数 | 平均文档长 |
|---|---|---|
| Books [110] | B | K |
| CC-News [34] | B | |
| Stories [89] | B | K |
| Wikipedia | B |
| 模型 | Base | Large |
|---|---|---|
| RoBERTa (sqln: 512) | 1.846 | 1.496 |
| Longformer (sqln: 4096) | 1.705 | 1.358 |
| BigBird-itc (sqln: 4096) | 1.678 | 1.456 |
| BigBird-etc (sqln: 4096) | 1.611 | 1.274 |
Table 9: 数据集 used for pre training.
| Instances | Instance Length | |||||
|---|---|---|---|---|---|---|
| Dataset | Training | Dev | Median | Max | ||
| HotpotQA-distractor [100] | ||||||
| Natural Questions [52] | ||||||
| TriviaQA [41] | 4900 | 32755 | ||||
| WikiHop [95] |
Table 11: Question Answering Datasets
| 样本数 | 样本长度 | |||||
|---|---|---|---|---|---|---|
| 数据集 | 训练 | 开发 | 中位 | 最大 | ||
| HotpotQA-distractor [100] | ||||||
| Natural Questions [52] | ||||||
| TriviaQA [41] | 4900 | 32755 | ||||
| WikiHop [95] |
Table 11: Question Answering 数据集s
| Parameter | HotpotQA | NaturalQ | TriviaQA | WikiHop | ||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Global token location | itc | etc | itc | etc | itc | etc | itc | etc | ||||
| of global token, | ||||||||||||
| Window length, | ||||||||||||
| of random token, | ||||||||||||
| Max. sequence length | ||||||||||||
| of heads | ||||||||||||
| of hidden layers | ||||||||||||
| Hidden layer size | ||||||||||||
| Batch size | ||||||||||||
| Loss | cross-entropy | cross-entropy | cross-entropy | cross-entropy | ||||||||
| golden spans | golden spans | noisy spans [18] | ans choices | |||||||||
| Compute resources | TPUv3 | TPUv3 | TPUv3 | TPUv3 |
Table 12: Hyperparameters of base BigBird model used for Question Answering i.e. the numbers reported in Table 2
| 参数 | | HotpotQA | | NaturalQ | | TriviaQA | | WikiHop |---|---|---|---|---|---|---|---|---|---|---|---|---|
| 全局 token 位置 | | itc | etc | | itc | etc | | itc | etc | | itc | etc |
| 全局 token 数 | | | | | | | | | | | | |
| 窗口长 | | | | | | | | | | | | |
| 随机 token 数 | | | | | | | | | | | | |
| Max. sequence length | | | | | | | | | | | | |
| of heads | | | | | | | | | | | | |
| of hidden layers | | | | | | | | | | | | |
| Hidden layer size | | | | | | | | | | | | |
| 批大小 | | | | | | | | | | | | |
| Loss | | cross-entropy | | cross-entropy | | cross-entropy | | cross-entropy | golden spans | | golden spans | | noisy spans [18] | | ans choices | Compute resources | | TPUv3 | | TPUv3 | | TPUv3 | | TPUv3 |
Table 12: Hyperparameters of base BigBird model used for Question Answering i.e. the numbers reported in Table 2
| Parameter | HotpotQA | NaturalQ | TriviaQA | WikiHop | ||||
|---|---|---|---|---|---|---|---|---|
| Global token location | etc | etc | etc | etc | ||||
| of global token, | ||||||||
| Window length, | ||||||||
| of random token, | ||||||||
| Max. sequence length | ||||||||
| of heads | ||||||||
| of hidden layers | ||||||||
| Hidden layer size | ||||||||
| Batch size | ||||||||
| Loss | cross-entropy | cross-entropy | cross-entropy | cross-entropy | ||||
| Num epochs | ||||||||
| Optimizer | Adam | Adam | Adam | LAMB | ||||
| Learning rate | ||||||||
| Compute resources | TPUv3 | TPUv3 | TPUv3 | TPUv3 |
Table 13: Hyperparameters of large BigBird model for Question Answering submitted for test i.e. the numbers reported in Table 3
| 参数 | | HotpotQA | | NaturalQ | | TriviaQA | | WikiHop |
| 全局 token 位置 | | etc | | etc | | etc | | etc |
| 全局 token 数 | | | | | | | | |
| 窗口长 | | | | | | | | |
| 随机 token 数 | | | | | | | | |
| Max. sequence length | | | | | | | | |
| of heads | | | | | | | | |
| of hidden layers | | | | | | | | |
| Hidden layer size | | | | | | | | |
| 批大小 | | | | | | | | |
| Loss | | cross-entropy | | cross-entropy | | cross-entropy | | cross-entropy |
| 轮数 | | | | | | | | |
| Optimizer | | Adam | | Adam | | Adam | | LAMB |
| 学习率 | | | | | | | | |
| Compute resources | | TPUv3 | | TPUv3 | | TPUv3 | | TPUv3 |
Table 13: Hyperparameters of large BigBird model for Question Answering submitted for test i.e. the numbers reported in Table 3
E.2 Question Answering
E.2 问答
The detailed statistics of the four datasets used are given in Table 11. All the hyperparameters for BigBird, used for creating Table 2 are shown in Table 12 and those submitted to get Table 3 are shown in Table 13. We use two types of regularization in training:
四个数据集的详细统计见表 11。用于得到表 2 的 BigBird 超参见表 12,用于得到表 3 的见表 13。训练中使用两类正则:
- • We used a variant of contrastive predictive coding [70] as a dual encoder model.
- • 使用对比预测编码 [70] 的一种变体作为双编码器模型。
- • We use position embedding for itc and relative position encoding [79] for etc.
- • itc 用位置嵌入,etc 用相对位置编码 [79]。
Next, we will mention the dataset/task specific part of the model.
下面说明各数据集/任务特有的模型部分。
HotpotQA
The data consists of each question with multiple evidence paragraphs. We filtered 16 QA where the answer was not in the given evidences. For BigBird-itc, we use first global tokens. For BigBird-etc, we have one global token for each question token, one for each evidence paragraph, and one for each sentence within the paragraph, for a maximum of global token. We use a dense layer on the output corresponding to global token of the evidence paragraph to predict whether its a supporting fact with a threshold over the output logits. The answer type (yes/no/span) is predicted with a single dense layer from the global CLS token. For span based answers, the spans are predicted with dense layers on the sequence with the distance between start and end positions to be no more than 30 words. The spans are ranked by sum of start and end logits.
HotpotQA
数据由每个问题配多段证据段落组成。我们过滤掉 16 条答案不在给定证据中的问答。对 BigBird-itc,使用前 个全局 token。对 BigBird-etc,为每个问题 token、每个证据段落以及段内每个句子各设一个全局 token。其余超参见表 12/13。答案跨度用标准起止分类头预测。
Natural Questions
Here also the data consists of question with supporting evidence, but in form of a single, potentially long, document and not multiple paragraphs. We largely follow the setup of [5]. For documents, that are longer than 4096, a sliding window approach is used with stride of 2048. We use CLS token at the beginning, followed by the question followed by a separator token followed by the document as input. For BigBird-itc, we make the first tokens as global. For BigBird-etc, we make a global token for CLS, question, and one token for each of the paragraphs. We train four predictors at the final layer to predict long answer start, long answer end, short answer start and short answer end respectively. Instead of independently predicting the start and end of answers we first predict the start and then predict the best end location beyond the start. For short answer, we limit the distance between start and end positions to be no more than 38 words. The answer type (null, yes, no, short, long) is predicted from CLS token output embedding. When the logit for a yes/no answer is higher than the logits for short, long or null answer, we replace the short answer with a corresponding yes/no text.
Natural Questions
此处数据同样是问题加支持证据,但证据是单篇可能很长的文档而非多段。大体沿用 [5] 的设定。对长于 4096 的文档,用步长 2048 的滑动窗口。开头用 CLS,后接问题与文档。分别预测长答案与短答案跨度;相关超参见表。
TriviaQA
The data consists of question-answer pairs with Wikipedia articles as the “noisy” supporting evidence. We call them noisy because the given Wikipedia articles may or may not contain the answer. Moreover, the answer entities is not annotated to appropriate span in the article, rather all occurrences found using fuzzy string matching are listed. We use CLS token at the beginning, followed by the question followed by a separator token followed by the document as input. For BigBird-itc, we make the first tokens as global. For BigBird-etc, we make a global token for CLS, question, and one token for each sentence up to a maximum of 320 global tokens. Given the noisy nature of answer span, we follow Clark and Gardner 2017 for training. We use a dense layer on the sequence to predict the answer span for each article independently, with the distance between start and end positions to be no more than 16 words. For each article the span with maximum start logit + end logit is chosen. Then we normalize over all the documents associated with that question.
TriviaQA
数据由问答对与作为「嘈杂」支持证据的维基文章组成。称之为嘈杂,是因为给定文章未必含答案;且答案实体未标注到合适跨度,而是用模糊字符串匹配找到的所有出现都被当作正跨度。我们沿用常见设定做跨度抽取,并对长文滑动窗口。
WikiHop
For each question in WikiHop, we are given upto candidates, and supporting paragraphs. In our BigBird-itc model, following Beltagy et al. 2020, we concatenate the answer and the question with special tokens, [q] Question [/q] [ans] Ans1 [/ans] [ans] AnsN [/ans] along with the context. As the start of the text, always contains questions followed by answers, we make the first token attend globally. In BigBird-etc model, we do not need to insert special [ans], [/ans] etc. as we design global tokens appropriately. Along with global tokens for question, we have one per candidate answer up to a maximum of 430. Further, we linked answer tokens to their mentions using relative position label. Lastly, we use a dense layer that takes in the output vector corresponding to a candidate answer, and predicts a score for the current candidate to be the correct answer. We apply this dense layer to each candidate independently and the candidate with the best score is picked as our final answer.
WikiHop
WikiHop 每个问题最多给 个候选项与 段支持段落。在 BigBird-itc 中,沿用 Beltagy 等人 2020:用特殊 token 把答案与问题拼成 [q] Question [/q] [ans] Ans1 [/ans] [ans] AnsN [/ans],再接上下文。文本开头始终放全局 token。模型在候选上做分类。
It is worthwhile to note that explicitly designed attention connection in etc works slightly better, the random connection based itc is pretty competative.
值得注意:etc 中显式设计的注意力连接略好,但基于随机连接的 itc 也相当有竞争力。
E.3 Relationship to Contemporary Work
E.3 与同期工作的关系
Longformer
Child et al. 2019 introduced localized sliding window to reduce computation. A more recent version, which includes localized sliding windows and global tokens was introduced independently by Longofrmer[8]. Although BigBird contains additional random tokens, there are also differences in the way global and local tokens are realized. In particular even when there is no random token, as used to get SoTA in question answering, there are two key differences between Longformer and BigBird-etc (see [4]):
Longformer
Child 等人 2019 引入局部滑动窗口以降低计算。更近的、同时包含局部滑动窗口与全局 token 的版本由 Longformer [8] 独立提出。尽管 BigBird 还含额外随机 token,全局与局部 token 的实现方式也有差别。
- We use global-local attention with relative position encodings enables it to better handle structured inputs
- 我们用带相对位置编码的全局–局部注意力,以便更好处理结构化输入
- Unlike Longformer, we train the global tokens using CPC loss and learn their use during finetuning.
- 与 Longformer 不同,我们用 CPC 损失训练全局 token,并在微调时学习其用法。
E.4 Classification
E.4 分类
We try two types of classification task.
我们尝试两类分类任务。
| Parameter | IMDb | Arxiv | Patents | Hyperpartisan | Yelp-5 | |
|---|---|---|---|---|---|---|
| Batch size | 64 | 64 | 64 | 32 | 32 | |
| Learning rate | ||||||
| Num epochs | 40 | 10 | 3 | 15 | 2 | |
| TPUv3 slice | ||||||
| of heads | 12 | 16 | ||||
| of hidden layers | 12 | 24 | ||||
| Hidden layer size | 768 | |||||
| Block length, | 64 | |||||
| Global token location | itc | |||||
| of global token, | ||||||
| Window length, | ||||||
| of random token, | ||||||
| Max. sequence length | 4096 | |||||
| Vocab size | ||||||
| Activation layer | gelu | |||||
| Dropout prob | 0.1 | |||||
| Attention dropout prob | 0.1 | |||||
| Loss | cross-entropy | |||||
| Optimizer | Adam |
Table 14: Hyperparameters for document classification.
| 参数 | | IMDb | Arxiv | Patents | Hyperpartisan | Yelp-5 |
| 批大小 | | 64 | 64 | 64 | 32 | 32 |
| 学习率 | | | | | | |
| 轮数 | | 40 | 10 | 3 | 15 | 2 |
| TPUv3 切片 | | | | | | |
| of heads | | 12 | 16 | of hidden layers | | 12 | 24 | Hidden layer size | | 768 | | Block length, | | 64 | Global token location | | itc | of global token, | | | Window length, | | | of random token, | | | Max. sequence length | | 4096 | Vocab size | | | Activation layer | | gelu | Dropout prob | | 0.1 | Attention dropout prob | | 0.1 | Loss | | cross-entropy | Optimizer | | Adam |
Table 14: Hyperparameters for document classification.
| Model | IMDb [64] | Yelp-5 [108] | Arxiv [35] | Patents [53] | Hyperpartisan [47] |
|---|---|---|---|---|---|
| # Examples | 25000 | 650000 | 30043 | 1890093 | 645 |
| # Classes | 2 | 5 | 11 | 663 | 2 |
| Excess fraction | 0.14 | 0.04 | 1.00 | 0.90 | 0.53 |
| SoTA | [88] 97.4 | [3] 73.28 | [69] 87.96 | [69] 69.01 | [40] 90.6 |
| RoBERTa | 71.75 | 87.42 | 67.07 | ||
| BigBird | 72.16 | 92.31 | 69.30 |
Table 15: Classification results. We report the F1 micro-averaged score for all datasets. Experiments on smaller IMDb and Hyperpartisan datasets are repeated 5 times and the average performance is presented along with standard deviation.
| 模型 | IMDb [64] | Yelp-5 [108] | Arxiv [35] | Patents [53] | Hyperpartisan [47] |
|---|---|---|---|---|---|
| # 样本数 | 25000 | 650000 | 30043 | 1890093 | 645 |
| # 类别数 | 2 | 5 | 11 | 663 | 2 |
| 超长比例 | 0.14 | 0.04 | 1.00 | 0.90 | 0.53 |
| SoTA | [88] 97.4 | [3] 73.28 | [69] 87.96 | [69] 69.01 | [40] 90.6 |
| RoBERTa | 71.75 | 87.42 | 67.07 | ||
| BigBird | 72.16 | 92.31 | 69.30 |
Table 15: Classification results. We report the F1 micro-averaged score for all datasets. Experiments on smaller IMDb and Hyperpartisan datasets are repeated 5 times and the average performance is presented along with standard deviation.
| System | MNLI-(m/mm) | QQP | QNLI | SST-2 | CoLA | STS-B | MRPC | RTE |
|---|---|---|---|---|---|---|---|---|
| 392k | 363k | 108k | 67k | 8.5k | 5.7k | 3.5k | 2.5k | |
| BERT | 84.6/83.4 | 71.2 | 90.5 | 93.5 | 52.1 | 85.8 | 88.9 | 66.4 |
| XLNet | 86.8/- | 91.4 | 91.7 | 94.7 | 60.2 | 89.5 | 88.2 | 74.0 |
| RoBERTa | 87.6/- | 91.9 | 92.8 | 94.8 | 63.6 | 91.2 | 90.2 | 78.7 |
| BigBird | 87.5/87.3 | 88.6 | 92.2 | 94.6 | 58.5 | 87.8 | 91.5 | 75.0 |
Table 16: GLUE Dev results on base sized models. Number of training examples is reported below each task. MCC score is reported for CoLA, F1 score is reported for MRPC, Spearman correlation is reported for STS-B, and accuracy scores are reported for the other tasks.
| 系统 | MNLI-(m/mm) | QQP | QNLI | SST-2 | CoLA | STS-B | MRPC | RTE |
|---|---|---|---|---|---|---|---|---|
| 392k | 363k | 108k | 67k | 8.5k | 5.7k | 3.5k | 2.5k | |
| BERT | 84.6/83.4 | 71.2 | 90.5 | 93.5 | 52.1 | 85.8 | 88.9 | 66.4 |
| XLNet | 86.8/- | 91.4 | 91.7 | 94.7 | 60.2 | 89.5 | 88.2 | 74.0 |
| RoBERTa | 87.6/- | 91.9 | 92.8 | 94.8 | 63.6 | 91.2 | 90.2 | 78.7 |
| BigBird | 87.5/87.3 | 88.6 | 92.2 | 94.6 | 58.5 | 87.8 | 91.5 | 75.0 |
Table 16: GLUE Dev results on base sized models. Number of training examples is reported below each task. MCC score is reported for CoLA, F1 score is reported for MRPC, Spearman correlation is reported for STS-B, and accuracy scores are reported for the other tasks.
Document classification
We experiment on datasets of different lengths and contents, as listed in Table 15. In particular, we look at sentiment analysis (IMDb [64] and Yelp-5 [108]) task and topic assignment (Arxiv [35], Patents [53], and Hyperpartisan [47]) task. Following BERT, we used one layer with cross entropy loss on top of the first [CLS] token from the BigBird encoder consuming 4096 tokens. We report the results of document classification experiments in Table 15. We compare against state-of-the-art (SoTA) methods for each dataset and plain RoBERTa model with 512 tokens truncation. In all experiments we use a learning rate warmup over the first 10% steps, and linear decay of the learning rate and detail list of remaining hyperparameters are provided in Table 14. For better quantitative evaluation, we compute the fraction of the dataset that exceeds 512 tokens, i.e. the length at which the document are often truncated. We see that gains of using BigBird are more significant when we have longer documents and fewer training examples. For instance, using base sized model, BigBird improves state-of-the-art for Arxiv dataset by about points. On Patents dataset, there is improvement over using simple BERT/RoBERTa, but given the large size of training data the improvement over SoTA (which is not BERT based) is not significant. Note that this performance gain is not seen for much smaller IMDb dataset. Along with experimental setup detail, we present detailed results in Section E.4 which show competitive performance.
文档分类
我们在长度与内容各异的数据集上实验,见表 15。具体包括情感分析(IMDb [64]、Yelp-5 [108])与主题划分(Arxiv [35]、Patents [53]、Hyperpartisan [47])。沿用 BERT,在第一个 [CLS] token 上接一层交叉熵损失。对超长文档做截断或滑动。结果表明:在超长比例高的数据集上,长上下文带来更大收益。
GLUE
The General Language Understanding Evaluation (GLUE) benchmark [92], test language models on 8 different natural language understanding tasks. We used the same training parameters as mentioned in https://github.com/pytorch/fairseq/blob/master/examples/roberta/README.glue.md. Our model parameters are ( we used the BigBird-itc base model pretrained on MLM task). We compare the performance of BigBird to BERT, XLNet [101] and RoBERTa in Table 16. We find that even on task that have a much smaller context, our performance is competitive to full attention models.
GLUE
通用语言理解评估(GLUE)基准 [92] 在 8 个自然语言理解任务上测试语言模型。训练参数与 https://github.com/pytorch/fairseq/blob/master/examples/roberta/README.glue.md 相同。我们的模型参数为 。结果表明:即便为长序列设计,BigBird 在短序列 GLUE 任务上仍与 RoBERTa 竞争力相当。
E.5 Summarization
E.5 摘要
As discussed in Section 4.1, given the small length of output sequence, we used sparse BigBird attention only for encoder, while keeping the full attention for decoder. The number of hidden layers, number of heads, and hidden dimension is same for encoder and decoder. The hyperparameters are detailed in Table 17. We summarize our result in Table 20. In all experiments, we use a learning rate warmup over the first 10,000 steps, and square root decay of the learning rate.
如第 4.1 节所述,因输出序列较短,我们只在编码器使用稀疏 BigBird 注意力,解码器保持全注意力。编码器与解码器的隐层层数、头数与隐维相同。超详见表 17。结果汇总于表 20。
| Parameter | Base: BigBird-RoBERTa | Large: BigBird-Pegasus | ||
|---|---|---|---|---|
| Block length, | ||||
| Global token location | itc | itc | ||
| of global token, | ||||
| Window length, | ||||
| of random token, | ||||
| Max. encoder sequence length | BBC-XSUM: .1024 | 1024 | ||
| CNN/DM: .2048 | 2048 | |||
| Others: .3072 | 3072 | |||
| Max. decoder sequence length | BBC-XSUM: 10.64 | 64 | ||
| CNN/DM: 1.128 | 128 | |||
| Others: 1.256 | 256 | |||
| Beam size | 5 | 5 | ||
| Length penalty | BBC-XSUM: 100.7 | 0.7 | ||
| Others: 100.8 | 0.8 | |||
| of heads | ||||
| of hidden layers | ||||
| Hidden layer size | ||||
| Batch size | ||||
| Loss | teacher forced | teacher forced | ||
| cross-entropy | cross-entropy | |||
| Activation layer | gelu | gelu | ||
| Dropout prob | ||||
| Attention dropout prob | ||||
| Optimizer | Adam | Adafactor | ||
| Learning rate | ||||
| Compute resources | TPUv3 | TPUv3 |
Table 17: Encoder hyperparameters for Summarization. We use full attention in decoder
| 参数 | Base: BigBird-RoBERTa | Large: BigBird-Pegasus | ||
|---|---|---|---|---|
| 块长 | ||||
| 全局 token 位置 | itc | itc | ||
| 全局 token 数 | ||||
| 窗口长 | ||||
| 随机 token 数 | ||||
| Max. encoder sequence length | BBC-XSUM: .1024 | 1024 | ||
| CNN/DM: .2048 | 2048 | |||
| Others: .3072 | 3072 | |||
| Max. decoder sequence length | BBC-XSUM: 10.64 | 64 | ||
| CNN/DM: 1.128 | 128 | |||
| Others: 1.256 | 256 | |||
| 束宽 | 5 | 5 | ||
| 长度惩罚 | BBC-XSUM: 100.7 | 0.7 | ||
| Others: 100.8 | 0.8 | |||
| of heads | ||||
| of hidden layers | ||||
| Hidden layer size | ||||
| 批大小 | ||||
| Loss | teacher forced | teacher forced | ||
| cross-entropy | cross-entropy | |||
| Activation layer | gelu | gelu | ||
| Dropout prob | ||||
| Attention dropout prob | ||||
| Optimizer | Adam | Adafactor | ||
| 学习率 | ||||
| Compute resources | TPUv3 | TPUv3 |
Table 17: Encoder hyperparameters for Summarization. We use full attention in decoder
| Instances | Input Length | Output Length | ||||||||
|---|---|---|---|---|---|---|---|---|---|---|
| Dataset | Training | Dev | Test | Median | 90%-ile | Median | 90%-ile | |||
| Arxiv [20] | 203037 | 6436 | 6440 | 6151 | 14405 | 171 | 352 | |||
| PubMed [20] | 119924 | 6633 | 6658 | 2715 | 6101 | 212 | 318 | |||
| BigPatent [78] | 1207222 | 67068 | 67072 | 3082 | 7693 | 123 | 197 |
Table 18: Statistics of datasets used for summarization.
| 样本数 | 输入长度 | 输出长度 | ||||||||
|---|---|---|---|---|---|---|---|---|---|---|
| 数据集 | 训练 | 开发 | 测试 | 中位 | 90 分位 | 中位 | 90 分位 | |||
| Arxiv [20] | 203037 | 6436 | 6440 | 6151 | 14405 | 171 | 352 | |||
| PubMed [20] | 119924 | 6633 | 6658 | 2715 | 6101 | 212 | 318 | |||
| BigPatent [78] | 1207222 | 67068 | 67072 | 3082 | 7693 | 123 | 197 |
Table 18: Statistics of datasets used for summarization.
Following success of several recent works [76, 63], we warm start our encoder-decoder BigBird transformer model with pretrained weights and the weights between encoder and decoder are shared. In particular, the query/key/value matrix of self-attention and all the feedforward layers are shared between encoder and decoder. The only variable that is initialized randomly is the encoder-decoder attention. For base sized model, we utilize our MLM pretrained model on 4096 sequence length from Section E.1, which is in turn initialized using the public RoBERTa checkpoint. For the large size model, we lift weight from the state-of-the-art Pegasus model [107], which is pretrained using an objective designed for summarization task.
沿用若干近期工作 [76, 63] 的成功经验,我们用预训练权重热启动编码器–解码器 BigBird Transformer,并在编码器与解码器之间共享权重。具体地,自注意力的 query/key/value 矩阵与全部前馈层在编码器与解码器间共享。唯一独立的变量是交叉注意力参数。
To check if sparse attention causes significant degradation as compared to full attention, we further experiment on two shorter but popular datasets, where full attention can be used without significantly truncating the document. The statistics of these two datasets are in Table 19. We see that our performance is competitive, which shows that sparse attention can achieve similar performance to a full attention models.
为检查稀疏注意力相对全注意力是否显著变差,我们还在两个较短但流行的数据集上实验——那里用全注意力不必大幅截断文档。两数据集统计见表 19。可见性能有竞争力,说明稀疏化并未带来明显损失。
| Instances | Input Length | Output Length | ||||||||
|---|---|---|---|---|---|---|---|---|---|---|
| Dataset | Training | Dev | Test | Median | 90%-ile | Median | 90%-ile | |||
| BBC XSum [67] | 204044 | 11332 | 11334 | 359 | 920 | 25 | 32 | |||
| CNN/DailyMail [36] | 287113 | 13368 | 11490 | 777 | 1439 | 59 | 93 |
Table 19: Shorter summarization dataset statistics.
| 样本数 | 输入长度 | 输出长度 | ||||||||
|---|---|---|---|---|---|---|---|---|---|---|
| 数据集 | 训练 | 开发 | 测试 | 中位 | 90 分位 | 中位 | 90 分位 | |||
| BBC XSum [67] | 204044 | 11332 | 11334 | 359 | 920 | 25 | 32 | |||
| CNN/DailyMail [36] | 287113 | 13368 | 11490 | 777 | 1439 | 59 | 93 |
Table 19: Shorter summarization dataset statistics.
| Model | BBC XSum | CNN/DailyMail | |||||||
|---|---|---|---|---|---|---|---|---|---|
| R-1 | R-2 | R-L | R1 | R2 | R-L | ||||
| Prior Art | Lead | ||||||||
| PtGen [77] | |||||||||
| ConvS2S [28] | |||||||||
| MMN [48] | |||||||||
| Bottom-Up [29] | |||||||||
| TransLM [45] | |||||||||
| UniLM [23] | |||||||||
| Extr-Abst-BERT [62] | 38.81 | 16.50 | 31.27 | 42.13 | 19.60 | 39.18 | |||
| BART [56] | 45.14 | 22.27 | 37.25 | 44.16 | 21.28 | 40.90 | |||
| Base | Transformer [91] | 29.61 | 9.47 | 23.17 | 34.89 | 13.13 | 32.12 | ||
| + RoBERTa [76] | 39.92 | 17.33 | 32.63 | 39.44 | 18.69 | 36.80 | |||
| + Pegasus [107] | 39.79 | 16.58 | 31.70 | 41.79 | 18.81 | 38.93 | |||
| BigBird-RoBERTa | 39.52 | 17.22 | 32.30 | 39.25 | 18.46 | 36.61 | |||
| Large | Pegasus (Reported) [107] | 47.60 | 24.83 | 39.64 | 44.16 | 21.56 | 41.30 | ||
| Pegasus (Re-eval) | 47.37 | 24.31 | 39.23 | 44.15 | 21.56 | 41.05 | |||
| BigBird-Pegasus | 47.12 | 24.05 | 38.80 | 43.84 | 21.11 | 40.74 |
Table 20: Summarization ROUGE score for shorter documents.
| 模型 | | BBC XSum | | CNN/DailyMail |---|---|---|---|---|---|---|---|---|---| R-1 | R-2 | R-L | | R1 | R2 | R-L | 先前工作 | Lead | | | | | | | | |
| PtGen [77] | | | | | | | | | ConvS2S [28] | | | | | | | | | MMN [48] | | | | | | | | | Bottom-Up [29] | | | | | | | | | TransLM [45] | | | | | | | | | UniLM [23] | | | | | | | | | Extr-Abst-BERT [62] | | 38.81 | 16.50 | 31.27 | | 42.13 | 19.60 | 39.18 | BART [56] | | 45.14 | 22.27 | 37.25 | | 44.16 | 21.28 | 40.90 | Base | Transformer [91] | | 29.61 | 9.47 | 23.17 | | 34.89 | 13.13 | 32.12 |
| + RoBERTa [76] | | 39.92 | 17.33 | 32.63 | | 39.44 | 18.69 | 36.80 | + Pegasus [107] | | 39.79 | 16.58 | 31.70 | | 41.79 | 18.81 | 38.93 | BigBird-RoBERTa | | 39.52 | 17.22 | 32.30 | | 39.25 | 18.46 | 36.61 | Large | Pegasus (Reported) [107] | | 47.60 | 24.83 | 39.64 | | 44.16 | 21.56 | 41.30 |
| Pegasus (Re-eval) | | 47.37 | 24.31 | 39.23 | | 44.15 | 21.56 | 41.05 | BigBird-Pegasus | | 47.12 | 24.05 | 38.80 | | 43.84 | 21.11 | 40.74 | |
Table 20: Summarization ROUGE score for shorter documents.
Appendix F Genomics experiments details
附录 F 基因组实验细节
In this section we provide details of the experimental setup for BigBird on genomics data.
本节给出 BigBird 在基因组数据上的实验设定细节。
F.1 Pretraining
F.1 预训练
We try to keep the experimental setup as close to a typical NLP pipeline. In this regard, we take human reference GRCh37[^7] and convert it into documents . Each document is a sequence of sentences, where each sentence is a sequence of fragments of DNA. We construct the documents as follows:
我们尽量让实验设定贴近典型 NLP 流水线。为此,取人类参考基因组 GRCh37,并转换成文档集合 。每个文档 是句子序列,每个句子又是 DNA 片段序列。文档构造如下:
- Start with empty document set .
- 从空文档集 开始。
- For each chromosome , repeat the following procedure 10 times. (a) Pick uniformly at random a starting point between base pairs 0 and 5000 from the 5’ end. (b) Repeat until i. Pick uniformly at random a number between 50 and 100 to denote number of sentences per document. ii. Constructs a document containing sentences using consecutive base pairs (bps). The length of each sentence is chosen uniformly at random between 500-1000. Thus the resulting document has - bps. iii. iv.
- 对每条染色体 ,重复下列过程 10 次。(a) 在距 5′ 端 0 到 5000 碱基对之间均匀随机取起点 。(b) 重复直到 :i. 均匀随机取 作为每文档句子数;ii. 构造含 个句子的文档 ,每个句子长度在 500–1000 bp 间随机;iii. 将 加入 ,并令 前进相应长度。
By this procedure we end-up with approximately documents.
按此过程最终得到约 篇文档。
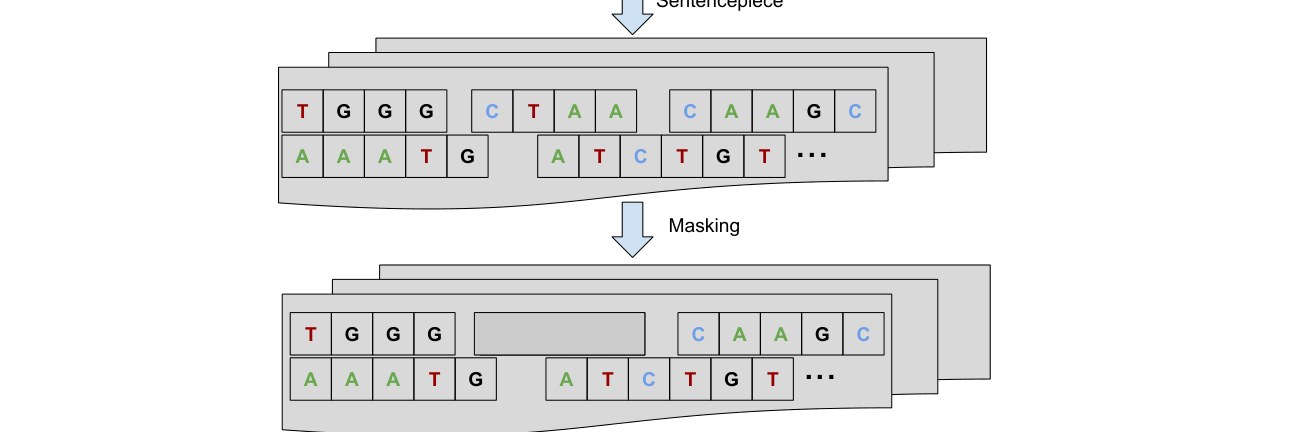
Figure 7: Visual description of how the masked language modeling data was generated from raw DNA dataset. The raw DNA sequences of GRCh37, where split at random positions to create documents with 50-100 sentences where each sentence was 500-1000 base pairs (bps). Thus each document had a continuous strand of 25000-100,000 bps of DNA. This process was repeated 10 times to create 10 sets of document for each chromosome of GRCH37. The resulting set of documents was then passed through Sentencepiece that created tokens of average 8bp. For pretraining we used masked language model and masked of the tokens and trained on predicting the masked tokens.
图 7:由原始 DNA 数据生成掩码语言模型数据的示意。GRCh37 原始 DNA 序列在随机位置切开,做成含 50–100 句、每句 500–1000 碱基对(bp)的文档,因而每篇文档是连续 25000–100000 bp 的 DNA 链。该过程重复以覆盖基因组。
Next we run sentencepiece [50] tokenization on the resulting documents. In particular, using 5 characters as the building blocks (four for bases - A, T, C, G and one for missing symbol N), we construct a byte pair encoding table of size 32k, with each token representing 8.78 base pairs on average.
接着对所得文档跑 sentencepiece [50] 分词。具体地,以 5 个字符为构建块(四种碱基 A、T、C、G 与缺失符号 N),构造大小 32k 的 BPE 表,每个 token 平均代表 8.78 个碱基对。
Using the above constructed documents, we construct a dataset for two pretraining tasks following Devlin et al. 2018:
用上述文档,按 Devlin 等人 2018 构造两个预训练任务的数据集:
- • Masked Language Model (MLM): In order to train a deep bidirectional representation, BERT training introduces the MLM task, where we simply mask out 15% of the input tokens at random, and then predict those masked tokens. We can simply replace such masked out of the tokens with a [MASK] placeholder, but it leads to a distribution mis-match for downstream tasks which will not have such placeholders. To mitigate with this issue, out of the 15% of the tokens selected for masking: – 80% of the tokens are actually replaced with the token [MASK]. – 10% of the time tokens are replaced with a random token. – 10% of the time tokens are left unchanged, but are still predicted at output. We run this entire sequence through the BigBird transformer encoder and then predict corresponding to the masked positions, based on the context provided by the other non-masked tokens in the sequence.
- • 掩码语言模型(MLM): 为训练深层双向表示,BERT 训练引入 MLM:随机掩掉 15% 输入 token 再预测它们。可直接用 [MASK] 占位替换,但这会造成微调时分布不匹配;因此沿用 BERT:80% 换成 [MASK],10% 换成随机 token,10% 保持不变。
- • Next Sentence Prediction (NSP): In order to understand relationship between two sequences, BERT training introduces the NSP task, where we predict if a given pair of sequences are contiguous or not. During training the model gets as input pairs of sequences separated by [SEP] token along with a [CLS] token at the start. Overall the input pattern is: [CLS] sequence A [SEP] sequence B [SEP]. For 50% of the time the second sequence comes from true sequence after the first one. Remaining 50% of the time it is a a random sequence from the full dataset. The model is then required to predict this relationship using the output corresponding to the [CLS] token, which is fed into a simple binary classification layer.
- • 下一句预测(NSP): 为理解两序列关系,BERT 训练引入 NSP:预测给定序列对是否相邻。训练时输入由 [SEP] 分隔的序列对,开头加 [CLS]。整体输入打包方式与 NLP 设定一致。
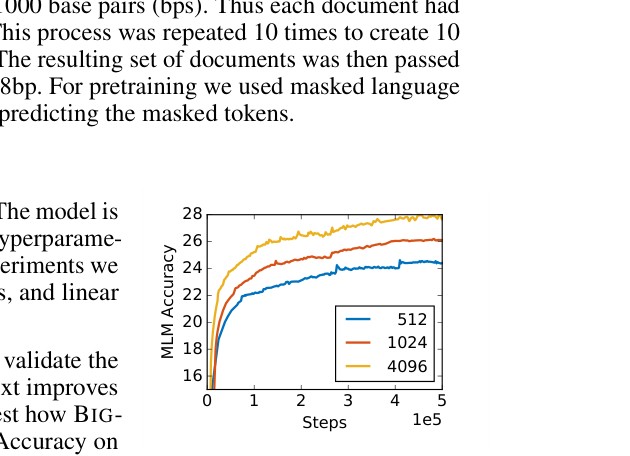
Figure 8: BigBird accuracy with context length.
图 8:BigBird 准确率随上下文长度变化。
The sequence of steps is visually elaborated in Figure 9. The model is trained with both MLM and NSP together. Training hyperparameter is provided in second columns of Table 21. In all experiments we use a learning rate warmup over the first 10,000 steps, and linear decay of the learning rate.
步骤序列见图 9 的示意。模型同时用 MLM 与 NSP 训练。训练超参见表 21 第二列。所有实验在前 10,000 步做学习率预热,之后线性衰减。
We additionally performed a simple ablation study to validate the hypothesis, that similar to NLP, having a larger context improves performance. We use MLM task described above to test how BigBird performed with sequences of different length. Accuracy on MLM task with increasing sequence length is shown in Figure 8. Not only longer context improves final accuracy, it also leads to faster learning, as we have now more opportunities for masking.
我们还做了一个简单消融,验证「与 NLP 类似,更大上下文能提升表现」的假设。用上述 MLM 任务测试 BigBird 在不同序列长度上的表现。随序列长度增加的 MLM 准确率见图 8:更长上下文不仅提升准确率,也表明基因组建模同样受益于长程依赖。
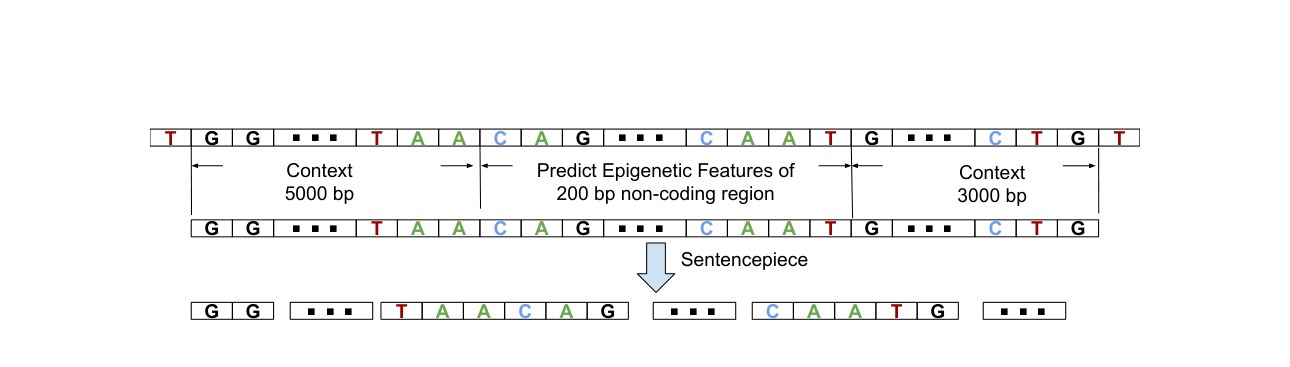
Figure 9: Visual description of the DNA segment from which we predict the chromatin profile for a given non-coding region of the raw DNA sequences of GRCh37. We take 8000 bps of DNA before and after the given non-coding region as context. The complete fragment of DNA including the context on both side, is then tokenized to form our input sequence of tokens. The task is to predict 919 chromatin profile including transcription factors (TF) binding profiles for different TFs, DNase I sensitivity (DHS) profiles and histone-mark (HM) profiles
图 9:由 GRCh37 原始 DNA 预测给定非编码区域染色质谱时所用 DNA 片段的示意。我们在给定非编码区域前后各取 8000 bp 作为上下文。含两侧上下文的完整 DNA 片段再分词,形成输入序列。
F.2 Promoter Region Prediction
F.2 启动子区域预测
The promoter region plays an important role in transcription initiation and thus its recognition is an important area of interest in the field of bioinformatics. Following Oubounyt et al. 2019, we use datasets from Eukaryotic Promoter Database (EPDnew) [24], which contains 29,597 promoter region in the human genome. Around the transcription start site (TSS), we extract a sequence of 8000 bp (-5000 +3000 bp) from the human reference genome GRCh37. Since EPDnew uses newer GRCh38, we convert to GRCh37 coordinates using LiftOver [44].
启动子区域在转录起始中起重要作用,其识别是生物信息学的重要议题。沿用 Oubounyt 等人 2019,我们使用真核启动子数据库(EPDnew)[24] 的数据,其中含人类基因组中 29,597 个启动子区域。在转录起始位点周围截取固定窗口作为正例。
Following Oubounyt et al. 2019 for each promoter region example, a negative example (non-promoter sequences) with the same size of the positive one is constructed as follow: The positive sequence is divided into 20 subsequences. Then, 12 subsequences are picked randomly and substituted randomly. The remaining 8 subsequences are conserved. This process is illustrated in Figure 1 of [71]. Applying this process to the positive set results in new non-promoter sequences with conserved parts from promoter sequences (the unchanged subsequences, 8 subsequences out of 20). These parameters enable generating a negative set that has 32 and 40% of its sequences containing conserved portions of promoter sequences.
沿用 Oubounyt 等人 2019:对每个启动子正例,构造等长负例(非启动子序列)如下:把正序列分成 20 个子序列;随机挑 12 段做随机替换,其余 8 段保留。该过程保证负例与正例局部统计相近但破坏启动子结构。
We prefix and append each example with [CLS] and [SEP] token respectively. The output corresponding to the [CLS] token from BigBird transformer encoder is fed to a simple binary classification layer. We fine-tune the pretrained BigBird from Section F.1 using hyper-parameters described in Table 21. We note that high performance is not surprising due to the overlap in the nature of negative example generation and MLM pretraining.
每个样本前后分别加 [CLS] 与 [SEP]。BigBird Transformer 编码器在 [CLS] 上的输出送入简单二分类层。用第 F.1 节预训练的 BigBird,按表 21 超参微调。高性能并不令人意外,因为任务相对容易且上下文充足。
F.3 Chromatin-Profile Prediction
F.3 染色质谱预测
The first step of sequence-based algorithmic framework for predicting non-coding effects is to build a model to predict, large scale chromatic profile [109].
基于序列预测非编码效应的算法框架,第一步往往是建立预测大规模染色质谱的模型 [109]。
| Parameter | Pretraining | Promoter Region | Chromatin-Profile | |||
|---|---|---|---|---|---|---|
| Block length, | ||||||
| Global token location | itc | itc | itc | |||
| of global token, | ||||||
| Window length, | ||||||
| of random token, | ||||||
| Max. Sequence Length | ||||||
| of heads | ||||||
| of hidden layers | ||||||
| Hidden layer size | ||||||
| Batch Size | ||||||
| Vocab Size | ||||||
| Loss | MLM+NSP | BCE | 919 x +ve upweighted | |||
| BCE | ||||||
| Dropout prob | ||||||
| Optimizer | Adam | Adam | Adam | |||
| Learning rate | ||||||
| of steps | 711 | 500000 | ||||
| Compute Resources | TPUv3 | TPUv3 | TPUv3 |
Table 21: Table of hyperparameters for Computational biology.
表 21:基因组实验超参。预训练 / 启动子区域 / 染色质谱三列设定接近:块长 ,全局 token 取 itc 且 ,窗口 ,随机 token ,最大序列长按任务分别为 4096、约 1k、约 1k;学习率、批大小、轮数、预热步与权重衰减见表原文各列。
In this paper, we use the dataset provided in Zhou and Troyanskaya 2015[^8], to train BigBird to predict the chromatic profile.
本文使用 Zhou 与 Troyanskaya 2015 提供的数据集,训练 BigBird 预测染色质谱。
Each training sample consists of a 8,000-bp sequence from the human GRCh37 reference genome centered on each 200-bp bin and is paired with a label vector for 919 chromatin features. As before, we prefix and append each example with [CLS] and [SEP] token respectively. The output corresponding to the [CLS] token from BigBird transformer encoder is fed to a linear layer with 919 heads. Thus we jointly predict the 919 independent binary classification problems. We fine-tune the pretrained BigBird from Section F.1 using hyper-parameters described in Table 21. As the data is highly imbalanced data (way more negative examples than positive examples), we upweighted loss function for positive examples by factor of 8.
每个训练样本是人类 GRCh37 参考基因组上以每个 200-bp bin 为中心的 8,000-bp 序列,并配有 919 个染色质特征的标签向量。同样在样本前后加 [CLS] 与 [SEP]。BigBird 编码器在 [CLS] 上的输出送入多标签分类头。
We used training and testing split provided by Zhou and Troyanskaya 2015 using chromosomes and strictly non-overlapping. Chromosome 8 and 9 were excluded from training to test chromatin feature prediction performances, and the rest of the autosomes were used for training and validation. 4,000 samples on chromosome 7 spanning the genomic coordinates 30,508,751–35,296,850 were used as the validation set.
训练/测试划分沿用 Zhou 与 Troyanskaya 2015:按染色体且严格不重叠。8、9 号染色体排除出训练以测试染色质特征预测;其余常染色体用于训练与验证。7 号染色体上跨越指定基因组坐标的 4,000 个样本用作额外检查。
As the predicted probability for each sequence in DeepSea Zhou and Troyanskaya 2015 was computed as the ensemble average of the probability predictions for the forward and complementary sequence pairs, we also predict using an ensemble of two BigBird model trained independently.
由于 DeepSea(Zhou 与 Troyanskaya 2015)对每条序列的预测概率取正链与互补链概率的集成平均,我们也用两个独立训练的 BigBird 做集成预测。