BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
BERT:用于语言理解的深度双向Transformer预训练
Jacob Devlin Ming-Wei Chang Kenton Lee Kristina Toutanova Google AI Language {jacobdevlin,mingweichang,kentonl,kristout}@google.com
arXiv:1810.04805v2 [cs.CL] 24 May 2019
arXiv:1810.04805v2 [cs.CL] 2019年5月24日
Abstract
摘要
We introduce a new language representation model called BERT, which stands for Bidirectional Encoder Representations from Transformers. Unlike recent language representation models (Peters et al., 2018a; Radford et al., 2018), BERT is designed to pretrain deep bidirectional representations from unlabeled text by jointly conditioning on both left and right context in all layers. As a result, the pre-trained BERT model can be finetuned with just one additional output layer to create state-of-the-art models for a wide range of tasks, such as question answering and language inference, without substantial taskspecific architecture modifications.
我们提出了一种新的语言表示模型,称为BERT,即来自Transformer的双向编码器表示(Bidirectional Encoder Representations from Transformers)。与最近的语言表示模型(Peters et al., 2018a; Radford et al., 2018)不同,BERT旨在通过在所有层中同时联合左侧和右侧上下文,从未标记文本中预训练深度双向表示。因此,预训练的BERT模型只需添加一个额外的输出层进行微调,即可为广泛的任务(如问答和语言推理)创建最先进的模型,而无需进行大量的任务特定架构修改。
BERT is conceptually simple and empirically powerful. It obtains new state-of-the-art results on eleven natural language processing tasks, including pushing the GLUE score to 80.5% (7.7% point absolute improvement), MultiNLI accuracy to 86.7% (4.6% absolute improvement), SQuAD v1.1 question answering Test F1 to 93.2 (1.5 point absolute improvement) and SQuAD v2.0 Test F1 to 83.1 (5.1 point absolute improvement).
BERT在概念上简单,在经验上强大。它在十一项自然语言处理任务上取得了新的最先进结果,包括将GLUE分数提高到80.5%(绝对提升7.7个百分点),MultiNLI准确率提高到86.7%(绝对提升4.6个百分点),SQuAD v1.1问答测试F1提高到93.2(绝对提升1.5分),以及SQuAD v2.0测试F1提高到83.1(绝对提升5.1分)。
1 Introduction
1 引言
Language model pre-training has been shown to be effective for improving many natural language processing tasks (Dai and Le, 2015; Peters et al., 2018a; Radford et al., 2018; Howard and Ruder, 2018). These include sentence-level tasks such as natural language inference (Bowman et al., 2015; Williams et al., 2018) and paraphrasing (Dolan and Brockett, 2005), which aim to predict the relationships between sentences by analyzing them holistically, as well as token-level tasks such as named entity recognition and question answering, where models are required to produce fine-grained output at the token level (Tjong Kim Sang and De Meulder, 2003; Rajpurkar et al., 2016).
语言模型预训练已被证明能有效改善许多自然语言处理任务(Dai and Le, 2015; Peters et al., 2018a; Radford et al., 2018; Howard and Ruder, 2018)。这些任务包括句子级任务,如自然语言推理(Bowman et al., 2015; Williams et al., 2018)和释义(Dolan and Brockett, 2005),旨在通过整体分析句子来预测句子之间的关系;以及词元级任务,如命名实体识别和问答,其中模型需要在词元级别产生细粒度输出(Tjong Kim Sang and De Meulder, 2003; Rajpurkar et al., 2016)。
There are two existing strategies for applying pre-trained language representations to downstream tasks: feature-based and fine-tuning. The feature-based approach, such as ELMo (Peters et al., 2018a), uses task-specific architectures that include the pre-trained representations as additional features. The fine-tuning approach, such as the Generative Pre-trained Transformer (OpenAI GPT) (Radford et al., 2018), introduces minimal task-specific parameters, and is trained on the downstream tasks by simply fine-tuning all pretrained parameters. The two approaches share the same objective function during pre-training, where they use unidirectional language models to learn general language representations.
将预训练语言表示应用于下游任务有两种现有策略:基于特征的和微调。基于特征的方法,如ELMo(Peters et al., 2018a),使用包含预训练表示作为附加特征的任务特定架构。微调方法,如生成式预训练Transformer(OpenAI GPT)(Radford et al., 2018),引入最少的任务特定参数,并通过简单地微调所有预训练参数在下游任务上进行训练。这两种方法在预训练期间共享相同的目标函数,它们使用单向语言模型来学习通用语言表示。
We argue that current techniques restrict the power of the pre-trained representations, especially for the fine-tuning approaches. The major limitation is that standard language models are unidirectional, and this limits the choice of architectures that can be used during pre-training. For example, in OpenAI GPT, the authors use a left-toright architecture, where every token can only attend to previous tokens in the self-attention layers of the Transformer (Vaswani et al., 2017). Such restrictions are sub-optimal for sentence-level tasks, and could be very harmful when applying finetuning based approaches to token-level tasks such as question answering, where it is crucial to incorporate context from both directions.
我们认为当前技术限制了预训练表示的能力,尤其是对于微调方法。主要限制是标准语言模型是单向的,这限制了预训练期间可使用的架构选择。例如,在OpenAI GPT中,作者使用从左到右的架构,其中每个词元在Transformer的自注意力层中只能关注先前的词元(Vaswani et al., 2017)。这种限制对于句子级任务是次优的,并且在将基于微调的方法应用于词元级任务(如问答)时可能非常有害,因为在这些任务中,结合来自两个方向的上下文至关重要。
In this paper, we improve the fine-tuning based approaches by proposing BERT: Bidirectional Encoder Representations from Transformers. BERT alleviates the previously mentioned unidirectionality constraint by using a “masked language model” (MLM) pre-training objective, inspired by the Cloze task (Taylor, 1953). The masked language model randomly masks some of the tokens from the input, and the objective is to predict the original vocabulary id of the masked word based only on its context. Unlike left-to-right language model pre-training, the MLM objective enables the representation to fuse the left and the right context, which allows us to pretrain a deep bidirectional Transformer. In addition to the masked language model, we also use a “next sentence prediction” task that jointly pretrains text-pair representations. The contributions of our paper are as follows:
在本文中,我们通过提出BERT:来自变换器的双向编码器表示,改进了基于微调的方法。BERT通过使用受完形填空任务(Taylor, 1953)启发的“掩码语言模型”(MLM)预训练目标,缓解了之前提到的单向性约束。掩码语言模型随机掩盖输入中的一些词元,目标是仅基于其上下文预测被掩盖单词的原始词汇表ID。与从左到右的语言模型预训练不同,MLM目标使表示能够融合左右上下文,这使我们能够预训练深度双向变换器。除了掩码语言模型,我们还使用“下一句预测”任务来联合预训练文本对表示。我们论文的贡献如下:
- We demonstrate the importance of bidirectional pre-training for language representations. Unlike Radford et al. (2018), which uses unidirectional language models for pre-training, BERT uses masked language models to enable pre-trained deep bidirectional representations. This is also in contrast to Peters et al. (2018a), which uses a shallow concatenation of independently trained left-to-right and right-to-left LMs.
- We show that pre-trained representations reduce the need for many heavily-engineered task-specific architectures. BERT is the first fine-tuning based representation model that achieves state-of-the-art performance on a large suite of sentence-level and token-level tasks, outperforming many task-specific architectures.
- BERT advances the state of the art for eleven NLP tasks. The code and pre-trained models are available at https://github.com/google-research/bert.
- 我们证明了双向预训练对语言表示的重要性。与 Radford et al. (2018) 使用单向语言模型进行预训练不同,BERT 使用掩码语言模型来实现预训练深度双向表示。这与 Peters et al. (2018a) 也形成对比,后者使用独立训练的从左到右和从右到左语言模型的浅层拼接。
- 我们表明,预训练表示减少了对许多重度工程化任务特定架构的需求。BERT 是第一个基于微调的表示模型,在大规模句子级和词元级任务上取得了最先进的性能,超越了许多任务特定架构。
- BERT 推进了十一项 NLP 任务的最先进水平。代码和预训练模型可在 https://github.com/google-research/bert 获取。
2 Related Work
2 相关工作
There is a long history of pre-training general language representations, and we briefly review the most widely-used approaches in this section.
预训练通用语言表示有着悠久的历史,我们在本节中简要回顾最广泛使用的方法。
2.1 Unsupervised Feature-based Approaches
2.1 无监督基于特征的方法
Learning widely applicable representations of words has been an active area of research for decades, including non-neural (Brown et al., 1992; Ando and Zhang, 2005; Blitzer et al., 2006) and neural (Mikolov et al., 2013; Pennington et al., 2014) methods. Pre-trained word embeddings are an integral part of modern NLP systems, offering significant improvements over embeddings learned from scratch (Turian et al., 2010). To pre-train word embedding vectors, left-to-right language modeling objectives have been used (Mnih and Hinton, 2009), as well as objectives to discriminate correct from incorrect words in left and right context (Mikolov et al., 2013).
数十年来,学习广泛适用的词表示一直是一个活跃的研究领域,包括非神经方法(Brown et al., 1992; Ando and Zhang, 2005; Blitzer et al., 2006)和神经方法(Mikolov et al., 2013; Pennington et al., 2014)。预训练词嵌入是现代 NLP 系统的重要组成部分,相比从头学习的嵌入能带来显著改进(Turian et al., 2010)。为了预训练词嵌入向量,人们使用了从左到右的语言建模目标(Mnih and Hinton, 2009),以及区分左右上下文中正确与不正确词语的目标(Mikolov et al., 2013)。
These approaches have been generalized to coarser granularities, such as sentence embeddings (Kiros et al., 2015; Logeswaran and Lee, 2018) or paragraph embeddings (Le and Mikolov, 2014). To train sentence representations, prior work has used objectives to rank candidate next sentences (Jernite et al., 2017; Logeswaran and Lee, 2018), left-to-right generation of next sentence words given a representation of the previous sentence (Kiros et al., 2015), or denoising auto-encoder derived objectives (Hill et al., 2016).
这些方法已被推广到更粗的粒度,例如句子嵌入(Kiros et al., 2015; Logeswaran and Lee, 2018)或段落嵌入(Le and Mikolov, 2014)。为了训练句子表示,先前工作使用了对候选下一句进行排序的目标(Jernite et al., 2017; Logeswaran and Lee, 2018),在给定上一句表示的情况下从左到右生成下一句词语(Kiros et al., 2015),或使用去噪自编码器衍生的目标(Hill et al., 2016)。
ELMo and its predecessor (Peters et al., 2017, 2018a) generalize traditional word embedding research along a different dimension. They extract context-sensitive features from a left-to-right and a right-to-left language model. The contextual representation of each token is the concatenation of the left-to-right and right-to-left representations. When integrating contextual word embeddings with existing task-specific architectures, ELMo advances the state of the art for several major NLP benchmarks (Peters et al., 2018a) including question answering (Rajpurkar et al., 2016), sentiment analysis (Socher et al., 2013), and named entity recognition (Tjong Kim Sang and De Meulder, 2003). Melamud et al. (2016) proposed learning contextual representations through a task to predict a single word from both left and right context using LSTMs. Similar to ELMo, their model is feature-based and not deeply bidirectional. Fedus et al. (2018) shows that the cloze task can be used to improve the robustness of text generation models.
ELMo 及其前身(Peters et al., 2017, 2018a)沿不同维度推广了传统词嵌入研究。它们从左到右和从右到左的语言模型中提取上下文相关特征。每个词元的上下文表示是从左到右和从右到左表示的拼接。当将上下文词嵌入与现有任务特定架构结合时,ELMo 在多个主要 NLP 基准上推进了最先进水平(Peters et al., 2018a),包括问答(Rajpurkar et al., 2016)、情感分析(Socher et al., 2013)和命名实体识别(Tjong Kim Sang and De Meulder, 2003)。Melamud et al. (2016) 提出通过一项使用 LSTM 从左右上下文预测单个词的任务来学习上下文表示。与 ELMo 类似,他们的模型是基于特征的,并非深度双向。Fedus et al. (2018) 表明完形填空任务可用于提高文本生成模型的鲁棒性。
2.2 Unsupervised Fine-tuning Approaches
2.2 无监督微调方法
As with the feature-based approaches, the first works in this direction only pre-trained word embedding parameters from unlabeled text (Collobert and Weston, 2008).
与基于特征的方法一样,该方向最初的工作仅从未标注文本中预训练词嵌入参数(Collobert and Weston, 2008)。
More recently, sentence or document encoders which produce contextual token representations have been pre-trained from unlabeled text and fine-tuned for a supervised downstream task (Dai and Le, 2015; Howard and Ruder, 2018; Radford et al., 2018). The advantage of these approaches is that few parameters need to be learned from scratch. At least partly due to this advantage, OpenAI GPT (Radford et al., 2018) achieved previously state-of-the-art results on many sentence-level tasks from the GLUE benchmark (Wang et al., 2018a). Left-to-right language modeling and auto-encoder objectives have been used for pre-training such models (Howard and Ruder, 2018; Radford et al., 2018; Dai and Le, 2015).
最近,能够产生上下文词元表示的句子或文档编码器已从未标注文本中预训练,并针对有监督的下游任务进行微调(Dai 和 Le,2015;Howard 和 Ruder,2018;Radford 等,2018)。这些方法的优势在于只需从头学习少量参数。至少部分由于这一优势,OpenAI GPT(Radford 等,2018)在 GLUE 基准(Wang 等,2018a)的许多句子级任务上取得了当时最先进的结果。从左到右的语言建模和自编码器目标已被用于预训练此类模型(Howard 和 Ruder,2018;Radford 等,2018;Dai 和 Le,2015)。
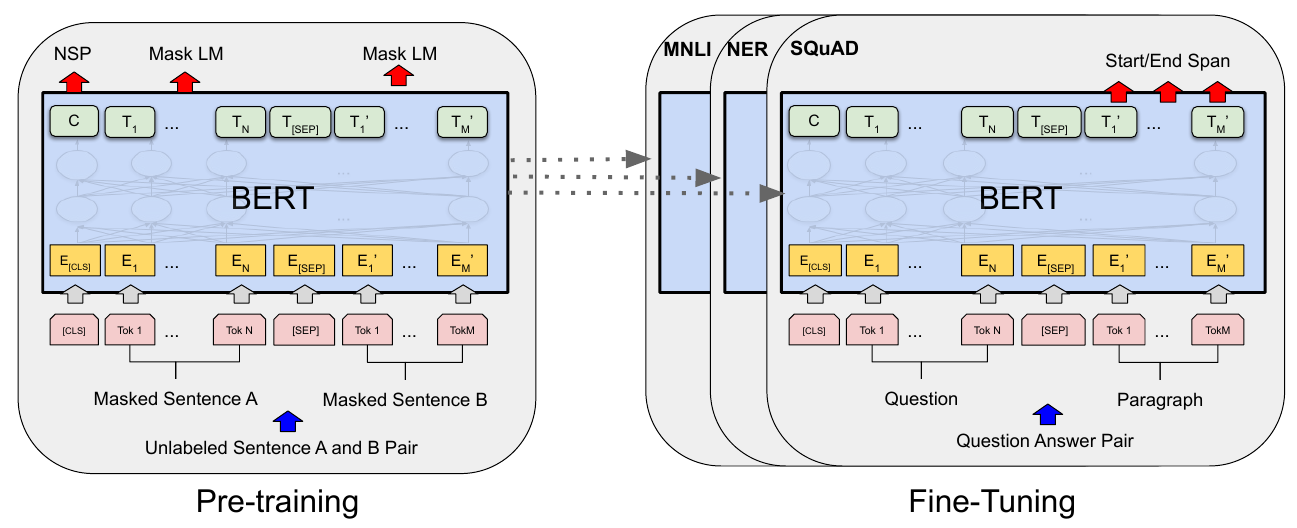
Figure 1: Overall pre-training and fine-tuning procedures for BERT. Apart from output layers, the same architectures are used in both pre-training and fine-tuning. The same pre-trained model parameters are used to initialize models for different down-stream tasks. During fine-tuning, all parameters are fine-tuned. [CLS] is a special symbol added in front of every input example, and [SEP] is a special separator token (e.g. separating questions/answers).
图1:BERT的整体预训练和微调流程。除了输出层之外,预训练和微调使用相同的架构。相同的预训练模型参数用于初始化不同下游任务的模型。在微调期间,所有参数都会被微调。[CLS]是添加在每个输入示例前面的特殊符号,[SEP]是特殊的分隔符词元(例如分隔问题/答案)。
图内标注:左侧为预训练,右侧为微调;NSP 为下一句预测,Mask LM 为掩码语言模型。输入包括掩码句子 A、B 或问题与段落;Start/End Span 表示答案片段的起止位置。
2.3 Transfer Learning from Supervised Data
2.3 从监督数据中进行迁移学习
There has also been work showing effective transfer from supervised tasks with large datasets, such as natural language inference (Conneau et al., 2017) and machine translation (McCann et al., 2017). Computer vision research has also demonstrated the importance of transfer learning from large pre-trained models, where an effective recipe is to fine-tune models pre-trained with ImageNet (Deng et al., 2009; Yosinski et al., 2014).
也有工作表明,从具有大型数据集的监督任务(如自然语言推理(Conneau等人,2017)和机器翻译(McCann等人,2017))中进行有效迁移是可行的。计算机视觉研究也证明了从大型预训练模型中进行迁移学习的重要性,其中一种有效的方法是微调使用ImageNet预训练的模型(Deng等人,2009;Yosinski等人,2014)。
3 BERT
We introduce BERT and its detailed implementation in this section. There are two steps in our framework: pre-training and fine-tuning. During pre-training, the model is trained on unlabeled data over different pre-training tasks. For fine-tuning, the BERT model is first initialized with the pre-trained parameters, and all of the parameters are fine-tuned using labeled data from the downstream tasks. Each downstream task has separate fine-tuned models, even though they are initialized with the same pre-trained parameters. The question-answering example in Figure 1 will serve as a running example for this section.
我们在本节中介绍BERT及其详细实现。我们的框架包含两个步骤:预训练和微调。在预训练期间,模型在不同的预训练任务上使用无标签数据进行训练。对于微调,BERT模型首先使用预训练参数进行初始化,然后使用来自下游任务的带标签数据对所有参数进行微调。每个下游任务都有单独的微调模型,即使它们使用相同的预训练参数进行初始化。图1中的问答示例将作为本节的贯穿示例。
A distinctive feature of BERT is its unified architecture across different tasks. There is minimal difference between the pre-trained architecture and the final downstream architecture.
BERT的一个显著特征是其在不同任务中具有统一的架构。预训练架构与最终下游架构之间的差异很小。
Model Architecture BERT’s model architecture is a multi-layer bidirectional Transformer encoder based on the original implementation described in Vaswani et al. (2017) and released in the tensor2tensor library.1 Because the use of Transformers has become common and our implementation is almost identical to the original, we will omit an exhaustive background description of the model architecture and refer readers to Vaswani et al. (2017) as well as excellent guides such as “The Annotated Transformer.”2
模型架构 BERT的模型架构是一个多层双向Transformer编码器,基于Vaswani等人(2017)中描述的原始实现,并在tensor2tensor库中发布。1 由于Transformer的使用已经变得普遍,并且我们的实现与原始实现几乎相同,我们将省略对模型架构的详尽背景描述,并请读者参考Vaswani等人(2017)以及诸如“The Annotated Transformer”之类的优秀指南。2
In this work, we denote the number of layers (i.e., Transformer blocks) as L, the hidden size as H, and the number of self-attention heads as A.3 We primarily report results on two model sizes: BERTBASE (L=12, H=768, A=12, Total Parameters=110M) and BERTLARGE (L=24, H=1024, A=16, Total Parameters=340M).
在这项工作中,我们将层数(即Transformer块)表示为L,隐藏层大小表示为H,自注意力头数表示为A。3 我们主要报告两种模型尺寸的结果:BERTBASE(L=12,H=768,A=12,总参数=110M)和BERTLARGE(L=24,H=1024,A=16,总参数=340M)。
BERTBASE was chosen to have the same model size as OpenAI GPT for comparison purposes. Critically, however, the BERT Transformer uses bidirectional self-attention, while the GPT Transformer uses constrained self-attention where every token can only attend to context to its left.4
选择BERTBASE是为了与OpenAI GPT具有相同的模型大小以便进行比较。然而,关键的是,BERT Transformer使用双向自注意力,而GPT Transformer使用受限的自注意力,其中每个词元只能关注其左侧的上下文。4
3 In all cases we set the feed-forward/filter size to be 4H, i.e., 3072 for the H = 768 and 4096 for the H = 1024.
3 在所有情况下,我们将前馈/滤波器大小设置为4H,即对于H = 768为3072,对于H = 1024为4096。
4 We note that in the literature the bidirectional Transformer is often referred to as a “Transformer encoder” while the left-context-only version is referred to as a “Transformer decoder” since it can be used for text generation.
4 我们注意到,在文献中,双向Transformer通常被称为“Transformer编码器”,而仅使用左侧上下文的版本被称为“Transformer解码器”,因为它可以用于文本生成。
Input/Output Representations
输入/输出表示
To make BERT handle a variety of down-stream tasks, our input representation is able to unambiguously represent both a single sentence and a pair of sentences (e.g., h Question, Answer i) in one token sequence. Throughout this work, a “sentence” can be an arbitrary span of contiguous text, rather than an actual linguistic sentence. A “sequence” refers to the input token sequence to BERT, which may be a single sentence or two sentences packed together.
为了使BERT能够处理各种下游任务,我们的输入表示能够在一个词元序列中明确地表示单个句子和句子对(例如,〈问题,答案〉)。在本文中,“句子”可以是任意连续文本的片段,而不一定是实际的语言学句子。“序列”指的是输入到BERT的词元序列,它可以是单个句子或两个句子打包在一起。
We use WordPiece embeddings (Wu et al., 2016) with a 30,000 token vocabulary. The first token of every sequence is always a special classification token ([CLS]). The final hidden state corresponding to this token is used as the aggregate sequence representation for classification tasks. Sentence pairs are packed together into a single sequence. We differentiate the sentences in two ways. First, we separate them with a special token ([SEP]). Second, we add a learned embedding to every token indicating whether it belongs to sentence A or sentence B. As shown in Figure 1, we denote input embedding as E, the final hidden vector of the special [CLS] token as , and the final hidden vector for the ith input token as .
我们使用WordPiece嵌入(Wu等人,2016),词汇量为30,000个词元。每个序列的第一个词元始终是特殊的分类词元([CLS])。与该词元对应的最终隐藏状态被用作分类任务的聚合序列表示。句子对被打包成一个单一序列。我们通过两种方式区分句子。首先,我们用特殊词元([SEP])将它们分隔开。其次,我们为每个词元添加一个学习到的嵌入,指示它属于句子A还是句子B。如图1所示,我们将输入嵌入表示为E,特殊[CLS]词元的最终隐藏向量表示为,第i个输入词元的最终隐藏向量表示为。
For a given token, its input representation is constructed by summing the corresponding token, segment, and position embeddings. A visualization of this construction can be seen in Figure 2.
对于给定的词元,其输入表示是通过将相应的词元嵌入、段嵌入和位置嵌入相加来构建的。这种构建的可视化如图2所示。
3.1 Pre-training BERT
3.1 预训练BERT
Unlike Peters et al. (2018a) and Radford et al. (2018), we do not use traditional left-to-right or right-to-left language models to pre-train BERT. Instead, we pre-train BERT using two unsupervised tasks, described in this section. This step is presented in the left part of Figure 1.
与Peters等人(2018a)和Radford等人(2018)不同,我们不使用传统的从左到右或从右到左的语言模型来预训练BERT。相反,我们使用本节描述的两个无监督任务来预训练BERT。这一步如图1左侧所示。
Task #1: Masked LM Intuitively, it is reasonable to believe that a deep bidirectional model is strictly more powerful than either a left-to-right model or the shallow concatenation of a left-to-right and a right-to-left model. Unfortunately, standard conditional language models can only be trained left-to-right or right-to-left, since bidirectional conditioning would allow each word to indirectly “see itself”, and the model could trivially predict the target word in a multi-layered context.
任务#1:掩码语言模型 直观上,有理由相信深度双向模型严格强于从左到右模型或从左到右和从右到左模型的浅层拼接。不幸的是,标准条件语言模型只能从左到右或从右到左进行训练,因为双向条件化会使每个词间接地“看到自己”,模型可以在多层上下文中轻易地预测目标词。
In order to train a deep bidirectional representation, we simply mask some percentage of the input tokens at random, and then predict those masked tokens. We refer to this procedure as a “masked LM” (MLM), although it is often referred to as a Cloze task in the literature (Taylor, 1953). In this case, the final hidden vectors corresponding to the mask tokens are fed into an output softmax over the vocabulary, as in a standard LM. In all of our experiments, we mask 15% of all WordPiece tokens in each sequence at random. In contrast to denoising auto-encoders (Vincent et al., 2008), we only predict the masked words rather than reconstructing the entire input.
为了训练深度双向表示,我们简单地随机掩盖一定比例的输入词元,然后预测这些被掩盖的词元。我们将此过程称为“掩码语言模型”(MLM),尽管在文献中它通常被称为完形填空任务(Taylor,1953)。在这种情况下,与掩码词元对应的最终隐藏向量被输入到词汇表上的输出softmax中,就像标准语言模型一样。在我们所有的实验中,我们随机掩盖每个序列中15%的WordPiece词元。与去噪自编码器(Vincent等人,2008)不同,我们只预测被掩盖的词,而不是重建整个输入。
Although this allows us to obtain a bidirectional pre-trained model, a downside is that we are creating a mismatch between pre-training and fine-tuning, since the [MASK] token does not appear during fine-tuning. To mitigate this, we do not always replace “masked” words with the actual [MASK] token. The training data generator chooses 15% of the token positions at random for prediction. If the i-th token is chosen, we replace the i-th token with (1) the [MASK] token 80% of the time (2) a random token 10% of the time (3) the unchanged i-th token 10% of the time. Then, Ti will be used to predict the original token with cross entropy loss. We compare variations of this procedure in Appendix C.2.
尽管这使我们能够获得双向预训练模型,但一个缺点是我们在预训练和微调之间造成了不匹配,因为[MASK]词元在微调期间不会出现。为了缓解这个问题,我们并不总是用实际的[MASK]词元替换“被掩盖”的词。训练数据生成器随机选择15%的词元位置进行预测。如果第i个词元被选中,我们将第i个词元替换为(1)80%的时间使用[MASK]词元(2)10%的时间使用随机词元(3)10%的时间使用不变的第i个词元。然后,Ti将被用于通过交叉熵损失预测原始词元。我们在附录C.2中比较了此过程的变体。
Task #2: Next Sentence Prediction (NSP) Many important downstream tasks such as Question Answering (QA) and Natural Language Inference (NLI) are based on understanding the relationship between two sentences, which is not directly captured by language modeling. In order to train a model that understands sentence relationships, we pre-train for a binarized next sentence prediction task that can be trivially generated from any monolingual corpus. Specifically, when choosing the sentences A and B for each pretraining example, 50% of the time B is the actual next sentence that follows A (labeled as IsNext), and 50% of the time it is a random sentence from the corpus (labeled as NotNext). As we show in Figure 1, C is used for next sentence prediction (NSP).5 Despite its simplicity, we demonstrate in Section 5.1 that pre-training towards this task is very beneficial to both QA and NLI. 6
任务#2:下一句预测(NSP) 许多重要的下游任务,如问答(QA)和自然语言推理(NLI),都基于理解两个句子之间的关系,而语言建模并不能直接捕捉这种关系。为了训练一个理解句子关系的模型,我们预训练一个二值化的下一句预测任务,该任务可以从任何单语语料库中轻松生成。具体来说,在为每个预训练示例选择句子A和B时,50%的时间B是A之后的实际下一句(标记为IsNext),50%的时间是语料库中的随机句子(标记为NotNext)。如图1所示,C用于下一句预测(NSP)。5 尽管其简单,我们在第5.1节中证明,针对此任务的预训练对QA和NLI都非常有益。6
5 The final model achieves 97%-98% accuracy on NSP.
5 最终模型在NSP上达到97%-98%的准确率。
6 The vector C is not a meaningful sentence representation without fine-tuning, since it was trained with NSP.
6 向量C在没有微调的情况下不是有意义的句子表示,因为它是在NSP上训练的。
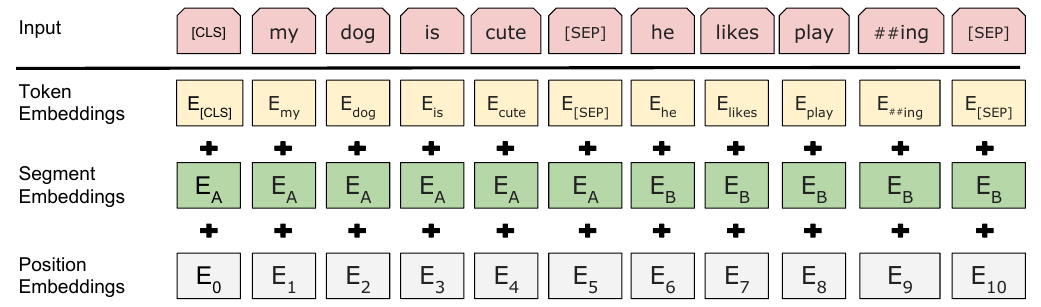
Figure 2: BERT input representation. The input embeddings are the sum of the token embeddings, the segmentation embeddings and the position embeddings.
图2:BERT输入表示。输入嵌入是词元嵌入、分段嵌入和位置嵌入的总和。
图内标注:输入嵌入由词元嵌入、句段嵌入和位置嵌入相加得到。图中保留英文分词示例及特殊词元。
The NSP task is closely related to representation-learning objectives used in Jernite et al. (2017) and Logeswaran and Lee (2018). However, in prior work, only sentence embeddings are transferred to down-stream tasks, where BERT transfers all parameters to initialize end-task model parameters.
NSP任务与Jernite等人(2017)和Logeswaran与Lee(2018)中使用的表示学习目标密切相关。然而,在先前的工作中,只有句子嵌入被转移到下游任务,而BERT转移所有参数来初始化最终任务模型参数。
Pre-training data The pre-training procedure largely follows the existing literature on language model pre-training. For the pre-training corpus we use the BooksCorpus (800M words) (Zhu et al., 2015) and English Wikipedia (2,500M words). For Wikipedia we extract only the text passages and ignore lists, tables, and headers. It is critical to use a document-level corpus rather than a shuffled sentence-level corpus such as the Billion Word Benchmark (Chelba et al., 2013) in order to extract long contiguous sequences.
预训练数据 预训练过程在很大程度上遵循了语言模型预训练的现有文献。对于预训练语料库,我们使用BooksCorpus(8亿词)(Zhu等人,2015)和英文维基百科(25亿词)。对于维基百科,我们仅提取文本段落,忽略列表、表格和标题。为了提取长的连续序列,使用文档级语料库而不是像十亿词基准(Chelba等人,2013)这样的打乱句子级语料库至关重要。
3.2 Fine-tuning BERT
3.2 微调BERT
Fine-tuning is straightforward since the self-attention mechanism in the Transformer allows BERT to model many downstream tasks—whether they involve single text or text pairs—by swapping out the appropriate inputs and outputs. For applications involving text pairs, a common pattern is to independently encode text pairs before applying bidirectional cross attention, such as Parikh et al. (2016); Seo et al. (2017). BERT instead uses the self-attention mechanism to unify these two stages, as encoding a concatenated text pair with self-attention effectively includes bidirectional cross attention between two sentences.
微调是直接的,因为Transformer中的自注意力机制允许BERT通过替换适当的输入和输出来建模许多下游任务——无论它们涉及单个文本还是文本对。对于涉及文本对的应用,一种常见模式是在应用双向交叉注意力之前独立编码文本对,例如Parikh等人(2016);Seo等人(2017)。BERT则使用自注意力机制来统一这两个阶段,因为用自注意力编码拼接的文本对有效地包含了两个句子之间的双向交叉注意力。
For each task, we simply plug in the task-specific inputs and outputs into BERT and fine-tune all the parameters end-to-end. At the input, sentence A and sentence B from pre-training are analogous to (1) sentence pairs in paraphrasing, (2) hypothesis-premise pairs in entailment, (3) question-passage pairs in question answering, and (4) a degenerate text-∅ pair in text classification or sequence tagging. At the output, the token representations are fed into an output layer for token-level tasks, such as sequence tagging or question answering, and the [CLS] representation is fed into an output layer for classification, such as entailment or sentiment analysis.
对于每个任务,我们只需将任务特定的输入和输出插入BERT,并端到端地微调所有参数。在输入端,预训练中的句子A和句子B类似于(1)释义中的句子对,(2)蕴含中的假设-前提对,(3)问答中的问题-段落对,以及(4)文本分类或序列标注中的退化文本-∅对。在输出端,词元表示被馈送到输出层用于词元级任务,如序列标注或问答,而[CLS]表示被馈送到输出层用于分类,如蕴含或情感分析。
Compared to pre-training, fine-tuning is relatively inexpensive. All of the results in the paper can be replicated in at most 1 hour on a single Cloud TPU, or a few hours on a GPU, starting from the exact same pre-trained model.7 We describe the task-specific details in the corresponding subsections of Section 4. More details can be found in Appendix A.5.
与预训练相比,微调相对便宜。从完全相同的预训练模型开始,本文中的所有结果最多可以在单个Cloud TPU上1小时内复现,或在GPU上几小时内复现。7 我们在第4节的相应小节中描述了任务特定的细节。更多细节可以在附录A.5中找到。
4 Experiments
4 实验
In this section, we present BERT fine-tuning results on 11 NLP tasks.
在本节中,我们展示了BERT在11个NLP任务上的微调结果。
4.1 GLUE
The General Language Understanding Evaluation (GLUE) benchmark (Wang et al., 2018a) is a collection of diverse natural language understanding tasks. Detailed descriptions of GLUE datasets are included in Appendix B.1.
通用语言理解评估(GLUE)基准(Wang等人,2018a)是各种自然语言理解任务的集合。GLUE数据集的详细描述包含在附录B.1中。
To fine-tune on GLUE, we represent the input sequence (for single sentence or sentence pairs) as described in Section 3, and use the final hidden vector corresponding to the first input token ([CLS]) as the aggregate representation. The only new parameters introduced during fine-tuning are classification layer weights , where K is the number of labels. We compute a standard classification loss with C and W, i.e., .
为了在GLUE上进行微调,我们按照第3节所述表示输入序列(对于单个句子或句子对),并使用与第一个输入词元([CLS])对应的最终隐藏向量作为聚合表示。微调期间引入的唯一新参数是分类层权重,其中K是标签的数量。我们使用C和W计算标准分类损失,即。
7 For example, the BERT SQuAD model can be trained in around 30 minutes on a single Cloud TPU to achieve a Dev F1 score of 91.0%.
7 例如,BERT SQuAD模型可以在单个Cloud TPU上约30分钟内训练,以达到91.0%的开发F1分数。
8 See (10) in https://gluebenchmark.com/faq.
8 参见https://gluebenchmark.com/faq中的(10)。
| System | MNLI-(m/mm) · 392k | QQP · 363k | QNLI · 108k | SST-2 · 67k | CoLA · 8.5k | STS-B · 5.7k | MRPC · 3.5k | RTE · 2.5k | Average |
|---|---|---|---|---|---|---|---|---|---|
| Pre-OpenAI SOTA | 80.6/80.1 | 66.1 | 82.3 | 93.2 | 35.0 | 81.0 | 86.0 | 61.7 | 74.0 |
| BiLSTM+ELMo+Attn | 76.4/76.1 | 64.8 | 79.8 | 90.4 | 36.0 | 73.3 | 84.9 | 56.8 | 71.0 |
| OpenAI GPT | 82.1/81.4 | 70.3 | 87.4 | 91.3 | 45.4 | 80.0 | 82.3 | 56.0 | 75.1 |
| BERT_BASE | 84.6/83.4 | 71.2 | 90.5 | 93.5 | 52.1 | 85.8 | 88.9 | 66.4 | 79.6 |
| BERT_LARGE | 86.7/85.9 | 72.1 | 92.7 | 94.9 | 60.5 | 86.5 | 89.3 | 70.1 | 82.1 |
| 系统 | MNLI-(m/mm) · 392k | QQP · 363k | QNLI · 108k | SST-2 · 67k | CoLA · 8.5k | STS-B · 5.7k | MRPC · 3.5k | RTE · 2.5k | 平均 |
|---|---|---|---|---|---|---|---|---|---|
| Pre-OpenAI SOTA | 80.6/80.1 | 66.1 | 82.3 | 93.2 | 35.0 | 81.0 | 86.0 | 61.7 | 74.0 |
| BiLSTM+ELMo+Attn | 76.4/76.1 | 64.8 | 79.8 | 90.4 | 36.0 | 73.3 | 84.9 | 56.8 | 71.0 |
| OpenAI GPT | 82.1/81.4 | 70.3 | 87.4 | 91.3 | 45.4 | 80.0 | 82.3 | 56.0 | 75.1 |
| BERT_BASE | 84.6/83.4 | 71.2 | 90.5 | 93.5 | 52.1 | 85.8 | 88.9 | 66.4 | 79.6 |
| BERT_LARGE | 86.7/85.9 | 72.1 | 92.7 | 94.9 | 60.5 | 86.5 | 89.3 | 70.1 | 82.1 |
Table 1: GLUE Test results, scored by the evaluation server (https://gluebenchmark.com/leaderboard). The number below each task denotes the number of training examples. The “Average” column is slightly different than the official GLUE score, since we exclude the problematic WNLI set.8 BERT and OpenAI GPT are single-model, single task. F1 scores are reported for QQP and MRPC, Spearman correlations are reported for STS-B, and accuracy scores are reported for the other tasks. We exclude entries that use BERT as one of their components.
表1:GLUE测试结果,由评估服务器评分(https://gluebenchmark.com/leaderboard)。每个任务下方的数字表示训练样本数。“平均”列与官方GLUE分数略有不同,因为我们排除了有问题的WNLI集。8 BERT和OpenAI GPT均为单模型、单任务。QQP和MRPC报告F1分数,STS-B报告Spearman相关系数,其他任务报告准确率分数。我们排除了使用BERT作为其组成部分之一的条目。
We use a batch size of 32 and fine-tune for 3 epochs over the data for all GLUE tasks. For each task, we selected the best fine-tuning learning rate (among 5e-5, 4e-5, 3e-5, and 2e-5) on the Dev set. Additionally, for BERTLARGE we found that fine-tuning was sometimes unstable on small datasets, so we ran several random restarts and selected the best model on the Dev set. With random restarts, we use the same pre-trained checkpoint but perform different fine-tuning data shuffling and classifier layer initialization.9
我们使用批量大小为32,对所有GLUE任务的数据进行3个epoch的微调。对于每个任务,我们在开发集上选择了最佳的微调学习率(在5e-5、4e-5、3e-5和2e-5之间)。此外,对于BERTLARGE,我们发现微调在小数据集上有时不稳定,因此我们进行了多次随机重启,并在开发集上选择了最佳模型。在随机重启时,我们使用相同的预训练检查点,但执行不同的微调数据打乱和分类器层初始化。9
Results are presented in Table 1. Both BERTBASE and BERTLARGE outperform all systems on all tasks by a substantial margin, obtaining 4.5% and 7.0% respective average accuracy improvement over the prior state of the art. Note that BERTBASE and OpenAI GPT are nearly identical in terms of model architecture apart from the attention masking. For the largest and most widely reported GLUE task, MNLI, BERT obtains a 4.6% absolute accuracy improvement. On the official GLUE leaderboard10, BERTLARGE obtains a score of 80.5, compared to OpenAI GPT, which obtains 72.8 as of the date of writing.
结果如表1所示。BERTBASE和BERTLARGE在所有任务上均大幅优于所有系统,相对于先前的最先进水平,平均准确率分别提高了4.5%和7.0%。请注意,BERTBASE和OpenAI GPT在模型架构上除注意力掩码外几乎相同。对于最大且最广泛报告的GLUE任务MNLI,BERT获得了4.6%的绝对准确率提升。在官方GLUE排行榜10上,BERTLARGE获得了80.5分,而OpenAI GPT在撰写本文时获得了72.8分。
We find that BERTLARGE significantly outperforms BERTBASE across all tasks, especially those with very little training data. The effect of model size is explored more thoroughly in Section 5.2.
我们发现BERTLARGE在所有任务上均显著优于BERTBASE,尤其是在训练数据非常少的任务上。模型大小的影响将在第5.2节中更详细地探讨。
4.2 SQuAD v1.1
The Stanford Question Answering Dataset (SQuAD v1.1) is a collection of 100k crowdsourced question/answer pairs (Rajpurkar et al., 2016). Given a question and a passage from Wikipedia containing the answer, the task is to predict the answer text span in the passage.
斯坦福问答数据集(SQuAD v1.1)是一个包含10万个众包问答对的集合(Rajpurkar et al., 2016)。给定一个问题和一段包含答案的维基百科段落,任务是预测段落中的答案文本跨度。
As shown in Figure 1, in the question answering task, we represent the input question and passage as a single packed sequence, with the question using the A embedding and the passage using the B embedding. We only introduce a start vector and an end vector during fine-tuning. The probability of word i being the start of the answer span is computed as a dot product between Ti and S followed by a softmax over all of the words in the paragraph: . The analogous formula is used for the end of the answer span. The score of a candidate span from position i to position j is defined as , and the maximum scoring span where is used as a prediction. The training objective is the sum of the log-likelihoods of the correct start and end positions. We fine-tune for 3 epochs with a learning rate of 5e-5 and a batch size of 32.
如图1所示,在问答任务中,我们将输入的问题和段落表示为一个单一的打包序列,问题使用A嵌入,段落使用B嵌入。在微调期间,我们仅引入起始向量和结束向量。单词i作为答案跨度起始位置的概率通过Ti与S的点积,然后对段落中所有单词进行softmax计算:。类似的公式用于答案跨度的结束位置。从位置i到位置j的候选跨度得分定义为,并且使用时得分最高的跨度作为预测。训练目标是正确起始和结束位置的对数似然之和。我们以5e-5的学习率和32的批量大小微调3个epoch。
Table 2 shows top leaderboard entries as well as results from top published systems (Seo et al., 2017; Clark and Gardner, 2018; Peters et al., 2018a; Hu et al., 2018). The top results from the SQuAD leaderboard do not have up-to-date public system descriptions available,11 and are allowed to use any public data when training their systems. We therefore use modest data augmentation in our system by first fine-tuning on TriviaQA (Joshi et al., 2017) befor fine-tuning on SQuAD.
表2显示了排行榜前列条目以及顶级已发表系统的结果(Seo et al., 2017; Clark and Gardner, 2018; Peters et al., 2018a; Hu et al., 2018)。SQuAD排行榜上的顶级结果没有最新的公开系统描述11,并且允许在训练系统时使用任何公开数据。因此,我们在系统中使用了适度的数据增强,首先在TriviaQA(Joshi et al., 2017)上进行微调,然后在SQuAD上进行微调。
Our best performing system outperforms the top leaderboard system by +1.5 F1 in ensembling and +1.3 F1 as a single system. In fact, our single BERT model outperforms the top ensemble system in terms of F1 score. Without TriviaQA finetuning data, we only lose 0.1-0.4 F1, still outperforming all existing systems by a wide margin.12
我们表现最佳的系统在集成学习中比排行榜榜首系统高出+1.5 F1,作为单一系统则高出+1.3 F1。事实上,我们的单一BERT模型在F1分数上就超过了顶级集成系统。如果没有TriviaQA微调数据,我们仅损失0.1-0.4 F1,仍然以较大优势超越所有现有系统。12
9 The GLUE data set distribution does not include the Test labels, and we only made a single GLUE evaluation server submission for each of BERTBASE and BERTLARGE.
9 GLUE 发布的数据不包含测试集标签;对于 BERT_BASE 和 BERT_LARGE,我们分别只向 GLUE 评估服务器提交过一次结果。
11 QANet is described in Yu et al. (2018), but the system has improved substantially after publication.
11 QANet在Yu et al. (2018)中有描述,但该系统在发表后已大幅改进。
| System | Dev EM | Dev F1 | Test EM | Test F1 |
|---|---|---|---|---|
| Top Leaderboard Systems (Dec 10th, 2018) | ||||
| Human | - | - | 82.3 | 91.2 |
| #1 Ensemble - nlnet | - | - | 86.0 | 91.7 |
| #2 Ensemble - QANet | - | - | 84.5 | 90.5 |
| Published | ||||
| BiDAF+ELMo (Single) | - | 85.6 | - | 85.8 |
| R.M. Reader (Ensemble) | 81.2 | 87.9 | 82.3 | 88.5 |
| Ours | ||||
| BERT_BASE (Single) | 80.8 | 88.5 | - | - |
| BERT_LARGE (Single) | 84.1 | 90.9 | - | - |
| BERT_LARGE (Ensemble) | 85.8 | 91.8 | - | - |
| BERT_LARGE (Sgl.+TriviaQA) | 84.2 | 91.1 | 85.1 | 91.8 |
| BERT_LARGE (Ens.+TriviaQA) | 86.2 | 92.2 | 87.4 | 93.2 |
| 系统 | 开发集 EM | 开发集 F1 | 测试集 EM | 测试集 F1 |
|---|---|---|---|---|
| 排行榜领先系统(2018年12月10日) | ||||
| 人类 | - | - | 82.3 | 91.2 |
| #1 Ensemble - nlnet | - | - | 86.0 | 91.7 |
| #2 Ensemble - QANet | - | - | 84.5 | 90.5 |
| 已发表系统 | ||||
| BiDAF+ELMo (Single) | - | 85.6 | - | 85.8 |
| R.M. Reader (Ensemble) | 81.2 | 87.9 | 82.3 | 88.5 |
| 本文系统 | ||||
| BERT_BASE(单模型) | 80.8 | 88.5 | - | - |
| BERT_LARGE(单模型) | 84.1 | 90.9 | - | - |
| BERT_LARGE(集成) | 85.8 | 91.8 | - | - |
| BERT_LARGE(单模型+TriviaQA) | 84.2 | 91.1 | 85.1 | 91.8 |
| BERT_LARGE(集成+TriviaQA) | 86.2 | 92.2 | 87.4 | 93.2 |
Table 2: SQuAD 1.1 results. The BERT ensemble is 7x systems which use different pre-training checkpoints and fine-tuning seeds.
表2:SQuAD 1.1结果。BERT集成是7个系统,它们使用不同的预训练检查点和微调种子。
| System | Dev EM | Dev F1 | Test EM | Test F1 |
|---|---|---|---|---|
| Top Leaderboard Systems (Dec 10th, 2018) | ||||
| Human | 86.3 | 89.0 | 86.9 | 89.5 |
| #1 Single - MIR-MRC (F-Net) | - | - | 74.8 | 78.0 |
| #2 Single - nlnet | - | - | 74.2 | 77.1 |
| Published | ||||
| unet (Ensemble) | - | - | 71.4 | 74.9 |
| SLQA+ (Single) | - | - | 71.4 | 74.4 |
| Ours | ||||
| BERT_LARGE (Single) | 78.7 | 81.9 | 80.0 | 83.1 |
| 系统 | 开发集 EM | 开发集 F1 | 测试集 EM | 测试集 F1 |
|---|---|---|---|---|
| 排行榜领先系统(2018年12月10日) | ||||
| 人类 | 86.3 | 89.0 | 86.9 | 89.5 |
| #1 Single - MIR-MRC (F-Net) | - | - | 74.8 | 78.0 |
| #2 Single - nlnet | - | - | 74.2 | 77.1 |
| 已发表系统 | ||||
| unet (Ensemble) | - | - | 71.4 | 74.9 |
| SLQA+ (Single) | - | - | 71.4 | 74.4 |
| 本文系统 | ||||
| BERT_LARGE(单模型) | 78.7 | 81.9 | 80.0 | 83.1 |
Table 3: SQuAD 2.0 results. We exclude entries that use BERT as one of their components.
表3:SQuAD 2.0结果。我们排除了使用BERT作为其组件之一的条目。
4.3 SQuAD v2.0
The SQuAD 2.0 task extends the SQuAD 1.1 problem definition by allowing for the possibility that no short answer exists in the provided paragraph, making the problem more realistic.
SQuAD 2.0任务扩展了SQuAD 1.1的问题定义,允许提供的段落中可能不存在简短答案,使问题更加现实。
We use a simple approach to extend the SQuAD v1.1 BERT model for this task. We treat questions that do not have an answer as having an answer span with start and end at the [CLS] token. The probability space for the start and end answer span positions is extended to include the position of the [CLS] token. For prediction, we compare the score of the no-answer span: to the score of the best non-null span . We predict a non-null answer when , where the threshold τ is selected on the dev set to maximize F1. We did not use TriviaQA data for this model. We fine-tuned for 2 epochs with a learning rate of 5e-5 and a batch size of 48.
我们使用一种简单的方法来扩展SQuAD v1.1 BERT模型以完成此任务。我们将没有答案的问题视为答案跨度以[CLS]词元为起点和终点。起始和结束答案跨度位置的概率空间被扩展以包含[CLS]词元的位置。对于预测,我们将无答案跨度的得分: 与最佳非空跨度的得分 进行比较。当 时,我们预测一个非空答案,其中阈值τ在开发集上选择以最大化F1。我们没有为该模型使用TriviaQA数据。我们进行了2个周期的微调,学习率为5e-5,批量大小为48。
12 The TriviaQA data we used consists of paragraphs from TriviaQA-Wiki formed of the first 400 tokens in documents, that contain at least one of the provided possible answers.
12 我们使用的TriviaQA数据由TriviaQA-Wiki中的段落组成,这些段落由文档中的前400个词元构成,且至少包含一个提供的可能答案。
| System | Dev | Test |
|---|---|---|
| ESIM+GloVe | 51.9 | 52.7 |
| ESIM+ELMo | 59.1 | 59.2 |
| OpenAI GPT | - | 78.0 |
| BERT_BASE | 81.6 | - |
| BERT_LARGE | 86.6 | 86.3 |
| Human (expert)† | - | 85.0 |
| Human (5 annotations)† | - | 88.0 |
| 系统 | 开发集 | 测试集 |
|---|---|---|
| ESIM+GloVe | 51.9 | 52.7 |
| ESIM+ELMo | 59.1 | 59.2 |
| OpenAI GPT | - | 78.0 |
| BERT_BASE | 81.6 | - |
| BERT_LARGE | 86.6 | 86.3 |
| 人类(专家)† | - | 85.0 |
| 人类(5次标注)† | - | 88.0 |
Table 4: SWAG Dev and Test accuracies. † Human performance is measured with 100 samples, as reported in the SWAG paper.
表4:SWAG开发集和测试集准确率。† 人类表现使用100个样本测量,如SWAG论文中所报告。
The results compared to prior leaderboard entries and top published work (Sun et al., 2018; Wang et al., 2018b) are shown in Table 3, excluding systems that use BERT as one of their components. We observe a +5.1 F1 improvement over the previous best system.
与先前排行榜条目和顶级已发表工作(Sun et al., 2018; Wang et al., 2018b)相比的结果显示在表3中,排除了使用BERT作为其组件之一的系统。我们观察到比先前最佳系统提高了+5.1 F1。
4.4 SWAG
The Situations With Adversarial Generations (SWAG) dataset contains 113k sentence-pair completion examples that evaluate grounded commonsense inference (Zellers et al., 2018). Given a sentence, the task is to choose the most plausible continuation among four choices.
对抗生成情境(SWAG)数据集包含113k个句子对补全示例,用于评估基于常识的推理(Zellers et al., 2018)。给定一个句子,任务是在四个选项中选择最合理的续写。
When fine-tuning on the SWAG dataset, we construct four input sequences, each containing the concatenation of the given sentence (sentence A) and a possible continuation (sentence B). The only task-specific parameters introduced is a vector whose dot product with the [CLS] token representation C denotes a score for each choice which is normalized with a softmax layer.
在SWAG数据集上微调时,我们构建四个输入序列,每个序列包含给定句子(句子A)和一个可能续写(句子B)的拼接。引入的唯一任务特定参数是一个向量,它与[CLS]词元表示C的点积表示每个选项的分数,该分数通过softmax层进行归一化。
We fine-tune the model for 3 epochs with a learning rate of 2e-5 and a batch size of 16. Results are presented in Table 4. BERTLARGE outperforms the authors’ baseline ESIM+ELMo system by +27.1% and OpenAI GPT by 8.3%.
我们以2e-5的学习率和16的批量大小微调模型3个周期。结果呈现在表4中。BERTLARGE比作者的基线ESIM+ELMo系统高出+27.1%,比OpenAI GPT高出8.3%。
5 Ablation Studies
5 消融研究
In this section, we perform ablation experiments over a number of facets of BERT in order to better understand their relative importance. Additional ablation studies can be found in Appendix C.
在本节中,我们对BERT的多个方面进行消融实验,以更好地理解它们的相对重要性。更多的消融研究可以在附录C中找到。
| Tasks | MNLI-m (Acc) | QNLI (Acc) | MRPC (Acc) | SST-2 (Acc) | SQuAD (F1) |
|---|---|---|---|---|---|
| BERT_BASE | 84.4 | 88.4 | 86.7 | 92.7 | 88.5 |
| No NSP | 83.9 | 84.9 | 86.5 | 92.6 | 87.9 |
| LTR & No NSP | 82.1 | 84.3 | 77.5 | 92.1 | 77.8 |
| + BiLSTM | 82.1 | 84.1 | 75.7 | 91.6 | 84.9 |
| 任务 | MNLI-m(准确率) | QNLI(准确率) | MRPC(准确率) | SST-2(准确率) | SQuAD(F1) |
|---|---|---|---|---|---|
| BERT_BASE | 84.4 | 88.4 | 86.7 | 92.7 | 88.5 |
| No NSP | 83.9 | 84.9 | 86.5 | 92.6 | 87.9 |
| LTR & No NSP | 82.1 | 84.3 | 77.5 | 92.1 | 77.8 |
| + BiLSTM | 82.1 | 84.1 | 75.7 | 91.6 | 84.9 |
Table 5: Ablation over the pre-training tasks using the BERTBASE architecture. “No NSP” is trained without the next sentence prediction task. “LTR & No NSP” is trained as a left-to-right LM without the next sentence prediction, like OpenAI GPT. “+ BiLSTM” adds a randomly initialized BiLSTM on top of the “LTR + No NSP” model during fine-tuning.
表 5:使用 BERTBASE 架构对预训练任务进行消融实验。“无 NSP”表示训练时不使用下一句预测任务。“LTR 且无 NSP”表示像 OpenAI GPT 一样,以从左到右的语言模型进行训练,且不使用下一句预测。“+ BiLSTM”表示在微调期间,在“LTR + 无 NSP”模型之上添加一个随机初始化的 BiLSTM。
5.1 Effect of Pre-training Tasks
5.1 预训练任务的影响
We demonstrate the importance of the deep bidirectionality of BERT by evaluating two pretraining objectives using exactly the same pretraining data, fine-tuning scheme, and hyperparameters as BERTBASE :
我们通过使用与 BERTBASE 完全相同的预训练数据、微调方案和超参数来评估两个预训练目标,从而证明 BERT 深度双向性的重要性:
No NSP: A bidirectional model which is trained using the “masked LM” (MLM) but without the “next sentence prediction” (NSP) task.
无 NSP:一个双向模型,使用“掩码语言模型”(MLM)进行训练,但不使用“下一句预测”(NSP)任务。
LTR & No NSP: A left-context-only model which is trained using a standard Left-to-Right (LTR) LM, rather than an MLM. The left-only constraint was also applied at fine-tuning, because removing it introduced a pre-train/fine-tune mismatch that degraded downstream performance. Additionally, this model was pre-trained without the NSP task. This is directly comparable to OpenAI GPT, but using our larger training dataset, our input representation, and our fine-tuning scheme.
LTR 且无 NSP:一个仅使用左上下文的模型,使用标准的从左到右(LTR)语言模型进行训练,而不是 MLM。在微调时也应用了仅左约束,因为移除该约束会导致预训练/微调不匹配,从而降低下游性能。此外,该模型在预训练时没有使用 NSP 任务。这与 OpenAI GPT 直接可比,但使用了我们更大的训练数据集、我们的输入表示和我们的微调方案。
We first examine the impact brought by the NSP task. In Table 5, we show that removing NSP hurts performance significantly on QNLI, MNLI, and SQuAD 1.1. Next, we evaluate the impact of training bidirectional representations by comparing “No NSP” to “LTR & No NSP”. The LTR model performs worse than the MLM model on all tasks, with large drops on MRPC and SQuAD.
我们首先考察 NSP 任务带来的影响。在表 5 中,我们表明移除 NSP 会显著损害 QNLI、MNLI 和 SQuAD 1.1 上的性能。接下来,我们通过比较“无 NSP”和“LTR 且无 NSP”来评估训练双向表示的影响。LTR 模型在所有任务上的表现都比 MLM 模型差,在 MRPC 和 SQuAD 上有大幅下降。
For SQuAD it is intuitively clear that a LTR model will perform poorly at token predictions, since the token-level hidden states have no rightside context. In order to make a good faith attempt at strengthening the LTR system, we added a randomly initialized BiLSTM on top. This does significantly improve results on SQuAD, but the results are still far worse than those of the pretrained bidirectional models. The BiLSTM hurts performance on the GLUE tasks.
对于 SQuAD,直观上很明显,LTR 模型在词元预测方面表现不佳,因为词元级别的隐藏状态没有右侧上下文。为了真诚地尝试加强 LTR 系统,我们在其上添加了一个随机初始化的 BiLSTM。这确实显著改善了 SQuAD 上的结果,但结果仍然远差于预训练的双向模型。BiLSTM 损害了 GLUE 任务上的性能。
We recognize that it would also be possible to train separate LTR and RTL models and represent each token as the concatenation of the two models, as ELMo does. However: (a) this is twice as expensive as a single bidirectional model; (b) this is non-intuitive for tasks like QA, since the RTL model would not be able to condition the answer on the question; (c) this it is strictly less powerful than a deep bidirectional model, since it can use both left and right context at every layer.
我们认识到,也可以像 ELMo 那样分别训练 LTR 和 RTL 模型,并将每个词元表示为两个模型的拼接。然而:(a) 这比单个双向模型昂贵一倍;(b) 对于 QA 等任务来说,这是不直观的,因为 RTL 模型无法根据问题来条件化答案;(c) 这严格弱于深度双向模型,因为深度双向模型可以在每一层同时使用左右上下文。
5.2 Effect of Model Size
5.2 模型大小的影响
In this section, we explore the effect of model size on fine-tuning task accuracy. We trained a number of BERT models with a differing number of layers, hidden units, and attention heads, while otherwise using the same hyperparameters and training procedure as described previously.
在本节中,我们探讨模型大小对微调任务准确率的影响。我们训练了多个具有不同层数、隐藏单元数和注意力头数的 BERT 模型,除此之外使用与前述相同的超参数和训练过程。
Results on selected GLUE tasks are shown in Table 6. In this table, we report the average Dev Set accuracy from 5 random restarts of fine-tuning. We can see that larger models lead to a strict accuracy improvement across all four datasets, even for MRPC which only has 3,600 labeled training examples, and is substantially different from the pre-training tasks. It is also perhaps surprising that we are able to achieve such significant improvements on top of models which are already quite large relative to the existing literature. For example, the largest Transformer explored in Vaswani et al. (2017) is (L=6, H=1024, A=16) with 100M parameters for the encoder, and the largest Transformer we have found in the literature is (L=64, H=512, A=2) with 235M parameters (Al-Rfou et al., 2018). By contrast, BERTBASE contains 110M parameters and BERTLARGE contains 340M parameters.
所选 GLUE 任务的结果如表 6 所示。在该表中,我们报告了微调 5 次随机重启的平均开发集准确率。我们可以看到,更大的模型在所有四个数据集上都带来了严格的准确率提升,即使对于只有 3,600 个带标签训练样本且与预训练任务有很大不同的 MRPC 也是如此。也许令人惊讶的是,我们能够在相对于现有文献已经相当大的模型之上取得如此显著的改进。例如,Vaswani et al. (2017) 中探索的最大 Transformer 是 (L=6, H=1024, A=16),编码器有 100M 参数,而我们在文献中发现的最大 Transformer 是 (L=64, H=512, A=2),有 235M 参数 (Al-Rfou et al., 2018)。相比之下,BERTBASE 包含 110M 参数,BERTLARGE 包含 340M 参数。
It has long been known that increasing the model size will lead to continual improvements on large-scale tasks such as machine translation and language modeling, which is demonstrated by the LM perplexity of held-out training data shown in Table 6. However, we believe that this is the first work to demonstrate convincingly that scaling to extreme model sizes also leads to large improvements on very small scale tasks, provided that the model has been sufficiently pre-trained. Peters et al. (2018b) presented mixed results on the downstream task impact of increasing the pre-trained bi-LM size from two to four layers and Melamud et al. (2016) mentioned in passing that increasing hidden dimension size from 200 to 600 helped, but increasing further to 1,000 did not bring further improvements. Both of these prior works used a feature-based approach — we hypothesize that when the model is fine-tuned directly on the downstream tasks and uses only a very small number of randomly initialized additional parameters, the task-specific models can benefit from the larger, more expressive pre-trained representations even when downstream task data is very small.
长期以来,人们已经知道,增大模型规模会在大规模任务(如机器翻译和语言建模)上带来持续改进,表6中展示的留出训练数据的语言模型困惑度证明了这一点。然而,我们相信,这是第一项令人信服地证明,只要模型经过充分的预训练,扩展到极端模型规模也能在非常小规模的任务上带来巨大改进的工作。Peters等人(2018b)在将预训练双向语言模型从两层增加到四层时,对下游任务的影响给出了混合结果;Melamud等人(2016)顺带提到,将隐藏维度从200增加到600有帮助,但进一步增加到1000并没有带来更多改进。这两项先前的工作都使用了基于特征的方法——我们假设,当模型直接在下游任务上进行微调,并且只使用极少量的随机初始化附加参数时,即使下游任务数据非常少,任务特定模型也能从更大、更具表达力的预训练表示中受益。
| #L | #H | #A | LM (ppl) | MNLI-m | MRPC | SST-2 |
|---|---|---|---|---|---|---|
| 3 | 768 | 12 | 5.84 | 77.9 | 79.8 | 88.4 |
| 6 | 768 | 3 | 5.24 | 80.6 | 82.2 | 90.7 |
| 6 | 768 | 12 | 4.68 | 81.9 | 84.8 | 91.3 |
| 12 | 768 | 12 | 3.99 | 84.4 | 86.7 | 92.9 |
| 12 | 1024 | 16 | 3.54 | 85.7 | 86.9 | 93.3 |
| 24 | 1024 | 16 | 3.23 | 86.6 | 87.8 | 93.7 |
| 层数 L | 隐藏维度 H | 注意力头数 A | 语言模型困惑度 | MNLI-m 准确率 | MRPC 准确率 | SST-2 准确率 |
|---|---|---|---|---|---|---|
| 3 | 768 | 12 | 5.84 | 77.9 | 79.8 | 88.4 |
| 6 | 768 | 3 | 5.24 | 80.6 | 82.2 | 90.7 |
| 6 | 768 | 12 | 4.68 | 81.9 | 84.8 | 91.3 |
| 12 | 768 | 12 | 3.99 | 84.4 | 86.7 | 92.9 |
| 12 | 1024 | 16 | 3.54 | 85.7 | 86.9 | 93.3 |
| 24 | 1024 | 16 | 3.23 | 86.6 | 87.8 | 93.7 |
Table 6: Ablation over BERT model size. #L = the number of layers; #H = hidden size; #A = number of attention heads. “LM (ppl)” is the masked LM perplexity of held-out training data.
表6:BERT模型大小的消融实验。#L = 层数;#H = 隐藏层大小;#A = 注意力头数。“LM (ppl)”是留出训练数据的掩码语言模型困惑度。
5.3 Feature-based Approach with BERT
5.3 基于特征的方法与BERT
All of the BERT results presented so far have used the fine-tuning approach, where a simple classification layer is added to the pre-trained model, and all parameters are jointly fine-tuned on a downstream task. However, the feature-based approach, where fixed features are extracted from the pre-trained model, has certain advantages. First, not all tasks can be easily represented by a Transformer encoder architecture, and therefore require a task-specific model architecture to be added. Second, there are major computational benefits to pre-compute an expensive representation of the training data once and then run many experiments with cheaper models on top of this representation.
到目前为止,所有展示的BERT结果都使用了微调方法,即在预训练模型上添加一个简单的分类层,并在下游任务上联合微调所有参数。然而,基于特征的方法,即从预训练模型中提取固定特征,具有某些优势。首先,并非所有任务都能轻易用Transformer编码器架构表示,因此需要添加任务特定的模型架构。其次,预先计算一次训练数据的昂贵表示,然后在此表示之上用更便宜的模型运行许多实验,具有重大的计算优势。
In this section, we compare the two approaches by applying BERT to the CoNLL-2003 Named Entity Recognition (NER) task (Tjong Kim Sang and De Meulder, 2003). In the input to BERT, we use a case-preserving WordPiece model, and we include the maximal document context provided by the data. Following standard practice, we formulate this as a tagging task but do not use a CRF layer in the output. We use the representation of the first sub-token as the input to the token-level classifier over the NER label set.
在本节中,我们通过将BERT应用于CoNLL-2003命名实体识别(NER)任务(Tjong Kim Sang和De Meulder,2003)来比较这两种方法。在BERT的输入中,我们使用保留大小写的WordPiece模型,并包含数据提供的最大文档上下文。按照标准做法,我们将其表述为标注任务,但在输出中不使用CRF层。我们使用第一个子词元的表示作为NER标签集上词元级分类器的输入。
To ablate the fine-tuning approach, we apply the feature-based approach by extracting the activations from one or more layers without fine-tuning any parameters of BERT. These contextual embeddings are used as input to a randomly initialized two-layer 768-dimensional BiLSTM before the classification layer.
为了消融微调方法,我们应用基于特征的方法,从一个或多个层中提取激活值,而不微调BERT的任何参数。这些上下文嵌入被用作随机初始化的两层768维BiLSTM的输入,然后进入分类层。
Results are presented in Table 7. BERTLARGE performs competitively with state-of-the-art methods. The best performing method concatenates the token representations from the top four hidden layers of the pre-trained Transformer, which is only 0.3 F1 behind fine-tuning the entire model. This demonstrates that BERT is effective for both fine-tuning and feature-based approaches.
结果见表7。BERTLARGE与最先进的方法相比具有竞争力。表现最佳的方法将预训练Transformer顶部四个隐藏层的词元表示拼接起来,仅比微调整个模型低0.3 F1。这表明BERT对微调和基于特征的方法都有效。
| System | Dev F1 | Test F1 |
|---|---|---|
| ELMo (Peters et al., 2018a) | 95.7 | 92.2 |
| CVT (Clark et al., 2018) | - | 92.6 |
| CSE (Akbik et al., 2018) | - | 93.1 |
| Fine-tuning approach | ||
| BERT_LARGE | 96.6 | 92.8 |
| BERT_BASE | 96.4 | 92.4 |
| Feature-based approach (BERT_BASE) | ||
| Embeddings | 91.0 | - |
| Second-to-Last Hidden | 95.6 | - |
| Last Hidden | 94.9 | - |
| Weighted Sum Last Four Hidden | 95.9 | - |
| Concat Last Four Hidden | 96.1 | - |
| Weighted Sum All 12 Layers | 95.5 | - |
| 系统 | 开发集 F1 | 测试集 F1 |
|---|---|---|
| ELMo (Peters et al., 2018a) | 95.7 | 92.2 |
| CVT (Clark et al., 2018) | - | 92.6 |
| CSE (Akbik et al., 2018) | - | 93.1 |
| 微调方法 | ||
| BERT_LARGE | 96.6 | 92.8 |
| BERT_BASE | 96.4 | 92.4 |
| 基于特征的方法(BERT_BASE) | ||
| 嵌入 | 91.0 | - |
| 倒数第二隐藏层 | 95.6 | - |
| 最后一隐藏层 | 94.9 | - |
| 最后四隐藏层加权和 | 95.9 | - |
| 最后四隐藏层拼接 | 96.1 | - |
| 全部12层加权和 | 95.5 | - |
Table 7: CoNLL-2003 Named Entity Recognition results. Hyperparameters were selected using the Dev set. The reported Dev and Test scores are averaged over 5 random restarts using those hyperparameters.
表7:CoNLL-2003命名实体识别结果。超参数使用开发集选择。报告的开发集和测试集分数是在这些超参数下5次随机重启的平均值。
6 Conclusion
6 结论
Recent empirical improvements due to transfer learning with language models have demonstrated that rich, unsupervised pre-training is an integral part of many language understanding systems. In particular, these results enable even low-resource tasks to benefit from deep unidirectional architectures. Our major contribution is further generalizing these findings to deep bidirectional architectures, allowing the same pre-trained model to successfully tackle a broad set of NLP tasks.
最近由于语言模型的迁移学习带来的实证改进表明,丰富的无监督预训练是许多语言理解系统不可或缺的一部分。特别是,这些结果使低资源任务也能从深度单向架构中受益。我们的主要贡献是将这些发现进一步推广到深度双向架构,使同一个预训练模型能够成功处理广泛的NLP任务。
References
参考文献
Alan Akbik, Duncan Blythe, and Roland Vollgraf. 2018. Contextual string embeddings for sequence labeling. In Proceedings of the 27th International Conference on Computational Linguistics, pages 1638–1649.
Alan Akbik、Duncan Blythe 和 Roland Vollgraf。2018 年。用于序列标注的上下文字符串嵌入。载于《第 27 届国际计算语言学会议论文集》,第 1638–1649 页。
Rami Al-Rfou, Dokook Choe, Noah Constant, Mandy Guo, and Llion Jones. 2018. Character-level language modeling with deeper self-attention. arXiv preprint arXiv:1808.04444.
Rami Al-Rfou、Dokook Choe、Noah Constant、Mandy Guo 和 Llion Jones。2018 年。使用更深层自注意力的字符级语言建模。arXiv 预印本 arXiv:1808.04444。
Rie Kubota Ando and Tong Zhang. 2005. A framework for learning predictive structures from multiple tasks and unlabeled data. Journal of Machine Learning Research, 6(Nov):1817–1853.
Rie Kubota Ando 和 Tong Zhang。2005 年。一种从多任务和未标注数据中学习预测结构的框架。《机器学习研究杂志》,6(11 月):1817–1853。
Luisa Bentivogli, Bernardo Magnini, Ido Dagan, Hoa Trang Dang, and Danilo Giampiccolo. 2009. The fifth PASCAL recognizing textual entailment challenge. In TAC. NIST.
Luisa Bentivogli、Bernardo Magnini、Ido Dagan、Hoa Trang Dang 和 Danilo Giampiccolo。2009 年。第五届 PASCAL 文本蕴含识别挑战赛。载于 TAC。NIST。
John Blitzer, Ryan McDonald, and Fernando Pereira. 2006. Domain adaptation with structural correspondence learning. In Proceedings of the 2006 conference on empirical methods in natural language processing, pages 120–128. Association for Computational Linguistics.
John Blitzer、Ryan McDonald 和 Fernando Pereira。2006 年。基于结构对应学习的领域自适应。载于《2006 年自然语言处理经验方法会议论文集》,第 120–128 页。计算语言学协会。
Samuel R. Bowman, Gabor Angeli, Christopher Potts, and Christopher D. Manning. 2015. A large annotated corpus for learning natural language inference. In EMNLP. Association for Computational Linguistics.
Samuel R. Bowman、Gabor Angeli、Christopher Potts 和 Christopher D. Manning。2015 年。用于学习自然语言推理的大型标注语料库。载于 EMNLP。计算语言学协会。
Peter F Brown, Peter V Desouza, Robert L Mercer, Vincent J Della Pietra, and Jenifer C Lai. 1992. Class-based n-gram models of natural language. Computational linguistics, 18(4):467–479.
Peter F Brown、Peter V Desouza、Robert L Mercer、Vincent J Della Pietra 和 Jenifer C Lai。1992 年。基于类的自然语言 n-gram 模型。《计算语言学》,18(4):467–479。
Daniel Cer, Mona Diab, Eneko Agirre, Inigo Lopez-Gazpio, and Lucia Specia. 2017. Semeval-2017 task 1: Semantic textual similarity multilingual and crosslingual focused evaluation. In Proceedings of the 11th International Workshop on Semantic Evaluation (SemEval-2017), pages 1–14, Vancouver, Canada. Association for Computational Linguistics.
Daniel Cer、Mona Diab、Eneko Agirre、Inigo Lopez-Gazpio 和 Lucia Specia。2017 年。SemEval-2017 任务 1:语义文本相似度的多语言和跨语言重点评估。载于《第 11 届语义评估国际研讨会论文集(SemEval-2017)》,第 1–14 页,加拿大温哥华。计算语言学协会。
Ciprian Chelba, Tomas Mikolov, Mike Schuster, Qi Ge, Thorsten Brants, Phillipp Koehn, and Tony Robinson. 2013. One billion word benchmark for measuring progress in statistical language modeling. arXiv preprint arXiv:1312.3005.
Ciprian Chelba、Tomas Mikolov、Mike Schuster、Qi Ge、Thorsten Brants、Phillipp Koehn 和 Tony Robinson。2013 年。用于衡量统计语言建模进展的十亿词基准。arXiv 预印本 arXiv:1312.3005。
Z. Chen, H. Zhang, X. Zhang, and L. Zhao. 2018. Quora question pairs.
Z. Chen、H. Zhang、X. Zhang 和 L. Zhao。2018 年。Quora 问题对。
Christopher Clark and Matt Gardner. 2018. Simple and effective multi-paragraph reading comprehension. In ACL.
Christopher Clark 和 Matt Gardner。2018 年。简单有效的多段落阅读理解。载于 ACL。
Kevin Clark, Minh-Thang Luong, Christopher D Manning, and Quoc Le. 2018. Semi-supervised sequence modeling with cross-view training. In Proceedings of the 2018 Conference on Empirical Methods in Natural Language Processing, pages 1914–1925.
Kevin Clark、Minh-Thang Luong、Christopher D Manning 和 Quoc Le。2018 年。基于跨视图训练的半监督序列建模。载于《2018 年自然语言处理经验方法会议论文集》,第 1914–1925 页。
Ronan Collobert and Jason Weston. 2008. A unified architecture for natural language processing: Deep neural networks with multitask learning. In Proceedings of the 25th international conference on Machine learning, pages 160–167. ACM.
Ronan Collobert 和 Jason Weston。2008 年。自然语言处理的统一架构:具有多任务学习的深度神经网络。载于《第 25 届国际机器学习会议论文集》,第 160–167 页。ACM。
Alexis Conneau, Douwe Kiela, Holger Schwenk, Loïc Barrault, and Antoine Bordes. 2017. Supervised learning of universal sentence representations from natural language inference data. In Proceedings of the 2017 Conference on Empirical Methods in Natural Language Processing, pages 670–680, Copenhagen, Denmark. Association for Computational Linguistics.
Alexis Conneau、Douwe Kiela、Holger Schwenk、Loïc Barrault 和 Antoine Bordes。2017 年。从自然语言推理数据中监督学习通用句子表示。载于《2017 年自然语言处理经验方法会议论文集》,第 670–680 页,丹麦哥本哈根。计算语言学协会。
Andrew M Dai and Quoc V Le. 2015. Semi-supervised sequence learning. In Advances in neural information processing systems, pages 3079–3087.
Andrew M Dai 和 Quoc V Le。2015 年。半监督序列学习。载于《神经信息处理系统进展》,第 3079–3087 页。
J. Deng, W. Dong, R. Socher, L.-J. Li, K. Li, and L. Fei-Fei. 2009. ImageNet: A Large-Scale Hierarchical Image Database. In CVPR09.
J. Deng、W. Dong、R. Socher、L.-J. Li、K. Li 和 L. Fei-Fei。2009 年。ImageNet:一个大规模分层图像数据库。载于 CVPR09。
William B Dolan and Chris Brockett. 2005. Automatically constructing a corpus of sentential paraphrases. In Proceedings of the Third International Workshop on Paraphrasing (IWP2005).
William B Dolan 和 Chris Brockett。2005 年。自动构建句子释义语料库。载于《第三届国际释义研讨会论文集(IWP2005)》。
William Fedus, Ian Goodfellow, and Andrew M Dai. 2018. Maskgan: Better text generation via filling in the . arXiv preprint arXiv:1801.07736.
William Fedus、Ian Goodfellow 和 Andrew M Dai。2018 年。MaskGAN:通过填充空白实现更好的文本生成。arXiv 预印本 arXiv:1801.07736。
Dan Hendrycks and Kevin Gimpel. 2016. Bridging nonlinearities and stochastic regularizers with gaussian error linear units. CoRR, abs/1606.08415.
Dan Hendrycks 和 Kevin Gimpel。2016 年。用高斯误差线性单元桥接非线性与随机正则化器。CoRR,abs/1606.08415。
Felix Hill, Kyunghyun Cho, and Anna Korhonen. 2016. Learning distributed representations of sentences from unlabelled data. In Proceedings of the 2016 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies. Association for Computational Linguistics.
Felix Hill、Kyunghyun Cho 和 Anna Korhonen。2016 年。从未标注数据中学习句子的分布式表示。载于《2016 年计算语言学协会北美分会会议论文集:人类语言技术》。计算语言学协会。
Jeremy Howard and Sebastian Ruder. 2018. Universal language model fine-tuning for text classification. In ACL. Association for Computational Linguistics.
Jeremy Howard 和 Sebastian Ruder。2018 年。用于文本分类的通用语言模型微调。载于 ACL。计算语言学协会。
Minghao Hu, Yuxing Peng, Zhen Huang, Xipeng Qiu, Furu Wei, and Ming Zhou. 2018. Reinforced mnemonic reader for machine reading comprehension. In IJCAI.
Minghao Hu、Yuxing Peng、Zhen Huang、Xipeng Qiu、Furu Wei 和 Ming Zhou。2018 年。用于机器阅读理解的强化记忆阅读器。载于 IJCAI。
Yacine Jernite, Samuel R. Bowman, and David Sontag. 2017. Discourse-based objectives for fast unsupervised sentence representation learning. CoRR, abs/1705.00557.
Yacine Jernite、Samuel R. Bowman 和 David Sontag。2017 年。基于篇章的目标用于快速无监督句子表示学习。CoRR,abs/1705.00557。
Mandar Joshi, Eunsol Choi, Daniel S Weld, and Luke Zettlemoyer. 2017. Triviaqa: A large scale distantly supervised challenge dataset for reading comprehension. In ACL.
Mandar Joshi, Eunsol Choi, Daniel S Weld 和 Luke Zettlemoyer。2017 年。Triviaqa:一个用于阅读理解的大规模远程监督挑战数据集。收录于 ACL。
Ryan Kiros, Yukun Zhu, Ruslan R Salakhutdinov, Richard Zemel, Raquel Urtasun, Antonio Torralba, and Sanja Fidler. 2015. Skip-thought vectors. In Advances in neural information processing systems, pages 3294–3302.
Ryan Kiros, Yukun Zhu, Ruslan R Salakhutdinov, Richard Zemel, Raquel Urtasun, Antonio Torralba 和 Sanja Fidler。2015 年。Skip-thought 向量。收录于《神经信息处理系统进展》,第 3294–3302 页。
Quoc Le and Tomas Mikolov. 2014. Distributed representations of sentences and documents. In International Conference on Machine Learning, pages 1188–1196.
Quoc Le 和 Tomas Mikolov。2014 年。句子和文档的分布式表示。收录于国际机器学习会议,第 1188–1196 页。
Hector J Levesque, Ernest Davis, and Leora Morgenstern. 2011. The winograd schema challenge. In Aaai spring symposium: Logical formalizations of commonsense reasoning, volume 46, page 47.
Hector J Levesque, Ernest Davis 和 Leora Morgenstern。2011 年。Winograd 模式挑战。收录于 AAAI 春季研讨会:常识推理的逻辑形式化,第 46 卷,第 47 页。
Lajanugen Logeswaran and Honglak Lee. 2018. An efficient framework for learning sentence representations. In International Conference on Learning Representations.
Lajanugen Logeswaran 和 Honglak Lee。2018 年。一种学习句子表示的高效框架。收录于国际学习表征会议。
Bryan McCann, James Bradbury, Caiming Xiong, and Richard Socher. 2017. Learned in translation: Contextualized word vectors. In NIPS.
Bryan McCann, James Bradbury, Caiming Xiong 和 Richard Socher。2017 年。在翻译中学习:上下文词向量。收录于 NIPS。
Oren Melamud, Jacob Goldberger, and Ido Dagan. 2016. context2vec: Learning generic context embedding with bidirectional LSTM. In CoNLL.
Oren Melamud, Jacob Goldberger 和 Ido Dagan。2016 年。context2vec:使用双向 LSTM 学习通用上下文嵌入。收录于 CoNLL。
Tomas Mikolov, Ilya Sutskever, Kai Chen, Greg S Corrado, and Jeff Dean. 2013. Distributed representations of words and phrases and their compositionality. In Advances in Neural Information Processing Systems 26, pages 3111–3119. Curran Associates, Inc.
Tomas Mikolov, Ilya Sutskever, Kai Chen, Greg S Corrado 和 Jeff Dean。2013 年。词和短语的分布式表示及其组合性。收录于《神经信息处理系统进展 26》,第 3111–3119 页。Curran Associates, Inc.
Andriy Mnih and Geoffrey E Hinton. 2009. A scalable hierarchical distributed language model. In D. Koller, D. Schuurmans, Y. Bengio, and L. Bottou, editors, Advances in Neural Information Processing Systems 21, pages 1081–1088. Curran Associates, Inc.
Andriy Mnih 和 Geoffrey E Hinton。2009 年。一种可扩展的分层分布式语言模型。收录于 D. Koller, D. Schuurmans, Y. Bengio 和 L. Bottou 编,《神经信息处理系统进展 21》,第 1081–1088 页。Curran Associates, Inc.
Ankur P Parikh, Oscar Täckström, Dipanjan Das, and Jakob Uszkoreit. 2016. A decomposable attention model for natural language inference. In EMNLP.
Ankur P Parikh, Oscar Täckström, Dipanjan Das 和 Jakob Uszkoreit。2016 年。一种用于自然语言推理的可分解注意力模型。收录于 EMNLP。
Jeffrey Pennington, Richard Socher, and Christopher D. Manning. 2014. Glove: Global vectors for word representation. In Empirical Methods in Natural Language Processing (EMNLP), pages 1532–1543.
Jeffrey Pennington, Richard Socher 和 Christopher D. Manning。2014 年。Glove:用于词表示的全局向量。收录于自然语言处理经验方法会议 (EMNLP),第 1532–1543 页。
Matthew Peters, Waleed Ammar, Chandra Bhagavatula, and Russell Power. 2017. Semi-supervised sequence tagging with bidirectional language models. In ACL.
Matthew Peters, Waleed Ammar, Chandra Bhagavatula 和 Russell Power。2017 年。使用双向语言模型的半监督序列标注。收录于 ACL。
Matthew Peters, Mark Neumann, Mohit Iyyer, Matt Gardner, Christopher Clark, Kenton Lee, and Luke Zettlemoyer. 2018a. Deep contextualized word representations. In NAACL.
Matthew Peters, Mark Neumann, Mohit Iyyer, Matt Gardner, Christopher Clark, Kenton Lee 和 Luke Zettlemoyer。2018a。深度上下文词表示。收录于 NAACL。
Matthew Peters, Mark Neumann, Luke Zettlemoyer, and Wen-tau Yih. 2018b. Dissecting contextual word embeddings: Architecture and representation. In Proceedings of the 2018 Conference on Empirical Methods in Natural Language Processing, pages 1499–1509.
Matthew Peters, Mark Neumann, Luke Zettlemoyer 和 Wen-tau Yih。2018b。剖析上下文词嵌入:架构与表示。收录于 2018 年自然语言处理经验方法会议论文集,第 1499–1509 页。
Alec Radford, Karthik Narasimhan, Tim Salimans, and Ilya Sutskever. 2018. Improving language understanding with unsupervised learning. Technical report, OpenAI.
Alec Radford, Karthik Narasimhan, Tim Salimans 和 Ilya Sutskever。2018 年。通过无监督学习提升语言理解能力。技术报告,OpenAI。
Pranav Rajpurkar, Jian Zhang, Konstantin Lopyrev, and Percy Liang. 2016. Squad: 100,000+ questions for machine comprehension of text. In Proceedings of the 2016 Conference on Empirical Methods in Natural Language Processing, pages 2383–2392.
Pranav Rajpurkar, Jian Zhang, Konstantin Lopyrev 和 Percy Liang。2016 年。Squad:用于文本机器理解的 100,000+ 个问题。收录于 2016 年自然语言处理经验方法会议论文集,第 2383–2392 页。
Minjoon Seo, Aniruddha Kembhavi, Ali Farhadi, and Hannaneh Hajishirzi. 2017. Bidirectional attention flow for machine comprehension. In ICLR.
Minjoon Seo, Aniruddha Kembhavi, Ali Farhadi 和 Hannaneh Hajishirzi。2017 年。用于机器理解的双向注意力流。收录于 ICLR。
Richard Socher, Alex Perelygin, Jean Wu, Jason Chuang, Christopher D Manning, Andrew Ng, and Christopher Potts. 2013. Recursive deep models for semantic compositionality over a sentiment treebank. In Proceedings of the 2013 conference on empirical methods in natural language processing, pages 1631–1642.
Richard Socher, Alex Perelygin, Jean Wu, Jason Chuang, Christopher D Manning, Andrew Ng 和 Christopher Potts。2013 年。基于情感树库的语义组合性递归深度模型。收录于 2013 年自然语言处理经验方法会议论文集,第 1631–1642 页。
Fu Sun, Linyang Li, Xipeng Qiu, and Yang Liu. 2018. U-net: Machine reading comprehension with unanswerable questions. arXiv preprint arXiv:1810.06638.
Fu Sun, Linyang Li, Xipeng Qiu 和 Yang Liu。2018 年。U-net:具有不可回答问题的机器阅读理解。arXiv 预印本 arXiv:1810.06638。
Wilson L Taylor. 1953. Cloze procedure: A new tool for measuring readability. Journalism Bulletin, 30(4):415–433.
Wilson L Taylor。1953 年。完形填空程序:一种衡量可读性的新工具。《新闻学公报》,30(4):415–433。
Erik F Tjong Kim Sang and Fien De Meulder. 2003. Introduction to the conll-2003 shared task: Language-independent named entity recognition. In CoNLL.
Erik F Tjong Kim Sang 和 Fien De Meulder。2003 年。CoNLL-2003 共享任务介绍:语言无关的命名实体识别。收录于 CoNLL。
Joseph Turian, Lev Ratinov, and Yoshua Bengio. 2010. Word representations: A simple and general method for semi-supervised learning. In Proceedings of the 48th Annual Meeting of the Association for Computational Linguistics, ACL '10, pages 384–394.
Joseph Turian, Lev Ratinov 和 Yoshua Bengio。2010 年。词表示:一种简单通用的半监督学习方法。收录于计算语言学协会第 48 届年会论文集,ACL '10,第 384–394 页。
Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Lukasz Kaiser, and Illia Polosukhin. 2017. Attention is all you need. In Advances in Neural Information Processing Systems, pages 6000–6010.
Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Lukasz Kaiser 和 Illia Polosukhin。2017 年。注意力就是你所需要的一切。收录于《神经信息处理系统进展》,第 6000–6010 页。
Pascal Vincent, Hugo Larochelle, Yoshua Bengio, and Pierre-Antoine Manzagol. 2008. Extracting and composing robust features with denoising autoencoders. In Proceedings of the 25th international conference on Machine learning, pages 1096–1103. ACM.
Pascal Vincent, Hugo Larochelle, Yoshua Bengio 和 Pierre-Antoine Manzagol。2008 年。使用去噪自动编码器提取和组合鲁棒特征。收录于第 25 届国际机器学习会议论文集,第 1096–1103 页。ACM。
Alex Wang, Amanpreet Singh, Julian Michael, Felix Hill, Omer Levy, and Samuel Bowman. 2018a. Glue: A multi-task benchmark and analysis platform for natural language understanding. In Proceedings of the 2018 EMNLP Workshop BlackboxNLP: Analyzing and Interpreting Neural Networks for NLP, pages 353–355.
Alex Wang、Amanpreet Singh、Julian Michael、Felix Hill、Omer Levy 和 Samuel Bowman。2018a。Glue:自然语言理解的多任务基准与分析平台。载于《2018年EMNLP研讨会BlackboxNLP:分析与解释自然语言处理中的神经网络》论文集,第353–355页。
Wei Wang, Ming Yan, and Chen Wu. 2018b. Multi-granularity hierarchical attention fusion networks for reading comprehension and question answering. In Proceedings of the 56th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers). Association for Computational Linguistics.
Wei Wang, Ming Yan, and Chen Wu. 2018b. 用于阅读理解和问答的多粒度层次注意力融合网络。见第56届计算语言学协会年会论文集(第1卷:长论文)。计算语言学协会。
Alex Warstadt, Amanpreet Singh, and Samuel R Bowman. 2018. Neural network acceptability judgments. arXiv preprint arXiv:1805.12471.
Alex Warstadt, Amanpreet Singh, and Samuel R Bowman. 2018. 神经网络可接受性判断。arXiv预印本arXiv:1805.12471。
Adina Williams, Nikita Nangia, and Samuel R Bowman. 2018. A broad-coverage challenge corpus for sentence understanding through inference. In NAACL.
Adina Williams, Nikita Nangia, and Samuel R Bowman. 2018. 一个通过推理进行句子理解的广覆盖挑战语料库。见NAACL。
Yonghui Wu, Mike Schuster, Zhifeng Chen, Quoc V Le, Mohammad Norouzi, Wolfgang Macherey, Maxim Krikun, Yuan Cao, Qin Gao, Klaus Macherey, et al. 2016. Google's neural machine translation system: Bridging the gap between human and machine translation. arXiv preprint arXiv:1609.08144.
Yonghui Wu, Mike Schuster, Zhifeng Chen, Quoc V Le, Mohammad Norouzi, Wolfgang Macherey, Maxim Krikun, Yuan Cao, Qin Gao, Klaus Macherey, et al. 2016. 谷歌神经机器翻译系统:弥合人工翻译与机器翻译之间的差距。arXiv预印本arXiv:1609.08144。
Jason Yosinski, Jeff Clune, Yoshua Bengio, and Hod Lipson. 2014. How transferable are features in deep neural networks? In Advances in neural information processing systems, pages 3320–3328.
Jason Yosinski, Jeff Clune, Yoshua Bengio, and Hod Lipson. 2014. 深度神经网络中的特征可迁移性如何?见神经信息处理系统进展,第3320–3328页。
Adams Wei Yu, David Dohan, Minh-Thang Luong, Rui Zhao, Kai Chen, Mohammad Norouzi, and Quoc V Le. 2018. QANet: Combining local convolution with global self-attention for reading comprehension. In ICLR.
Adams Wei Yu, David Dohan, Minh-Thang Luong, Rui Zhao, Kai Chen, Mohammad Norouzi, and Quoc V Le. 2018. QANet:结合局部卷积与全局自注意力进行阅读理解。见ICLR。
Rowan Zellers, Yonatan Bisk, Roy Schwartz, and Yejin Choi. 2018. Swag: A large-scale adversarial dataset for grounded commonsense inference. In Proceedings of the 2018 Conference on Empirical Methods in Natural Language Processing (EMNLP).
Rowan Zellers, Yonatan Bisk, Roy Schwartz, and Yejin Choi. 2018. Swag:一个用于有根据常识推理的大规模对抗数据集。见2018年自然语言处理经验方法会议论文集(EMNLP)。
Yukun Zhu, Ryan Kiros, Rich Zemel, Ruslan Salakhutdinov, Raquel Urtasun, Antonio Torralba, and Sanja Fidler. 2015. Aligning books and movies: Towards story-like visual explanations by watching movies and reading books. In Proceedings of the IEEE international conference on computer vision, pages 19–27.
Yukun Zhu, Ryan Kiros, Rich Zemel, Ruslan Salakhutdinov, Raquel Urtasun, Antonio Torralba, and Sanja Fidler. 2015. 对齐书籍与电影:通过观看电影和阅读书籍实现故事般的视觉解释。见IEEE国际计算机视觉会议论文集,第19–27页。
Appendix for "BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding"
附录:“BERT:用于语言理解的深度双向Transformer预训练”
We organize the appendix into three sections:
我们将附录组织为三个部分:
• Additional implementation details for BERT are presented in Appendix A;
• BERT的额外实现细节在附录A中呈现;
• Additional details for our experiments are presented in Appendix B; and
• 我们实验的更多细节在附录B中呈现;并且
• Additional ablation studies are presented in Appendix C.
• 额外的消融研究在附录C中呈现。
We present additional ablation studies for BERT including: – Effect of Number of Training Steps; and – Ablation for Different Masking Procedures.
我们呈现了BERT的额外消融研究,包括:– 训练步数的影响;以及 – 不同掩码程序的消融。
A Additional Details for BERT
A BERT的额外细节
A.1 Illustration of the Pre-training Tasks
A.1 预训练任务示例
We provide examples of the pre-training tasks in the following.
我们在下面提供预训练任务的示例。
Masked LM and the Masking Procedure Assuming the unlabeled sentence is my dog is hairy, and during the random masking procedure we chose the 4-th token (which corresponding to hairy), our masking procedure can be further illustrated by
掩码语言模型与掩码程序 假设未标注句子为 my dog is hairy,并且在随机掩码过程中我们选择了第4个词元(对应 hairy),我们的掩码程序可以进一步通过以下方式说明
• 80% of the time: Replace the word with the [MASK] token, e.g., my dog is hairy → my dog is [MASK]
• 80%的时间:用[MASK]词元替换该词,例如,my dog is hairy → my dog is [MASK]
• 10% of the time: Replace the word with a random word, e.g., my dog is hairy → my dog is apple
• 10%的时间:用一个随机词替换该词,例如,my dog is hairy → my dog is apple
• 10% of the time: Keep the word unchanged, e.g., my dog is hairy → my dog is hairy. The purpose of this is to bias the representation towards the actual observed word.
• 10%的时间:保持该词不变,例如,my dog is hairy → my dog is hairy。这样做的目的是使表示偏向实际观察到的词。
The advantage of this procedure is that the Transformer encoder does not know which words it will be asked to predict or which have been replaced by random words, so it is forced to keep a distributional contextual representation of every input token. Additionally, because random replacement only occurs for 1.5% of all tokens (i.e., 10% of 15%), this does not seem to harm the model's language understanding capability. In Section C.2, we evaluate the impact this procedure.
该程序的优点是Transformer编码器不知道它将被要求预测哪些词或哪些词已被随机词替换,因此它被迫保持每个输入词元的分布式上下文表示。此外,由于随机替换仅发生在所有词元的1.5%(即15%的10%),这似乎不会损害模型的语言理解能力。在C.2节中,我们评估了该程序的影响。
Compared to standard langauge model training, the masked LM only make predictions on 15% of tokens in each batch, which suggests that more pre-training steps may be required for the model to converge. In Section C.1 we demonstrate that MLM does converge marginally slower than a left-to-right model (which predicts every token), but the empirical improvements of the MLM model far outweigh the increased training cost.
与标准语言模型训练相比,掩码语言模型仅对每批中15%的词元进行预测,这表明模型可能需要更多的预训练步骤才能收敛。在C.1节中,我们证明了MLM的收敛速度确实比从左到右的模型(预测每个词元)略慢,但MLM模型的经验改进远远超过了增加的训练成本。
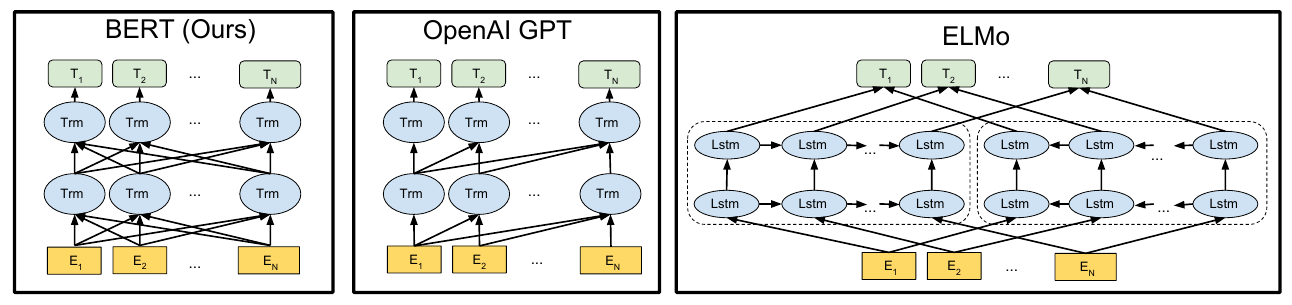
Figure 3: Differences in pre-training model architectures. BERT uses a bidirectional Transformer. OpenAI GPT uses a left-to-right Transformer. ELMo uses the concatenation of independently trained left-to-right and right-to-left LSTMs to generate features for downstream tasks. Among the three, only BERT representations are jointly conditioned on both left and right context in all layers. In addition to the architecture differences, BERT and OpenAI GPT are fine-tuning approaches, while ELMo is a feature-based approach.
图3:预训练模型架构的差异。BERT使用双向Transformer。OpenAI GPT使用从左到右的Transformer。ELMo使用独立训练的从左到右和从右到左LSTM的拼接来为下游任务生成特征。在这三者中,只有BERT的表示在所有层中都同时以左右上下文为条件。除了架构差异外,BERT和OpenAI GPT是微调方法,而ELMo是基于特征的方法。
图内标注:左为 BERT,中为 OpenAI GPT,右为 ELMo;Trm 表示 Transformer 层,Lstm 表示 LSTM 层,E 和 T 分别标记输入与输出表示。
Next Sentence Prediction
下一句预测
The next sentence prediction task can be illustrated in the following examples.
下一句预测任务可以通过以下示例来说明。
Input = [CLS] the man went to [MASK] store [SEP] he bought a gallon [MASK] milk [SEP]
Label = IsNext
输入 = [CLS] the man went to [MASK] store [SEP] he bought a gallon [MASK] milk [SEP]
标签 = IsNext
Input = [CLS] the man [MASK] to the store [SEP] penguin [MASK] are flight ##less birds [SEP]
Label = NotNext
输入 = [CLS] the man [MASK] to the store [SEP] penguin [MASK] are flight ##less birds [SEP]
标签 = NotNext
A.2 Pre-training Procedure
A.2 预训练过程
To generate each training input sequence, we sample two spans of text from the corpus, which we refer to as “sentences” even though they are typically much longer than single sentences (but can be shorter also). The first sentence receives the A embedding and the second receives the B embedding. 50% of the time B is the actual next sentence that follows A and 50% of the time it is a random sentence, which is done for the “next sentence prediction” task. They are sampled such that the combined length is ≤ 512 tokens. The LM masking is applied after WordPiece tokenization with a uniform masking rate of 15%, and no special consideration given to partial word pieces.
为了生成每个训练输入序列,我们从语料库中采样两段文本,我们称之为“句子”,尽管它们通常比单个句子长得多(但也可能更短)。第一个句子接收A嵌入,第二个句子接收B嵌入。50%的情况下B是A之后的实际下一句,50%的情况下是随机句子,这是为了“下一句预测”任务。它们的采样使得组合长度≤512个词元。LM掩码在WordPiece分词后应用,统一掩码率为15%,对部分词片没有特殊考虑。
We train with batch size of 256 sequences (256 sequences * 512 tokens = 128,000 tokens/batch) for 1,000,000 steps, which is approximately 40 epochs over the 3.3 billion word corpus. We use Adam with learning rate of 1e-4, β1 = 0.9, β2 = 0.999, L2 weight decay of 0.01, learning rate warmup over the first 10,000 steps, and linear decay of the learning rate. We use a dropout probability of 0.1 on all layers. We use a gelu activation (Hendrycks and Gimpel, 2016) rather than the standard relu, following OpenAI GPT. The training loss is the sum of the mean masked LM likelihood and the mean next sentence prediction likelihood.
我们以256个序列的批量大小(256个序列 * 512个词元 = 128,000个词元/批)训练1,000,000步,这大约是在33亿词语料库上的40个周期。我们使用Adam,学习率为1e-4,β1 = 0.9,β2 = 0.999,L2权重衰减为0.01,在前10,000步进行学习率预热,然后线性衰减学习率。我们在所有层上使用0.1的dropout概率。我们使用gelu激活函数(Hendrycks and Gimpel, 2016),而不是标准的relu,遵循OpenAI GPT。训练损失是平均掩码LM似然和平均下一句预测似然之和。
Training of BERTBASE was performed on 4 Cloud TPUs in Pod configuration (16 TPU chips total).13 Training of BERTLARGE was performed on 16 Cloud TPUs (64 TPU chips total). Each pre-training took 4 days to complete.
BERTBASE的训练在4个Cloud TPU上以Pod配置进行(总共16个TPU芯片)。13 BERTLARGE的训练在16个Cloud TPU上进行(总共64个TPU芯片)。每次预训练耗时4天完成。
Longer sequences are disproportionately expensive because attention is quadratic to the sequence length. To speed up pretraing in our experiments, we pre-train the model with sequence length of 128 for 90% of the steps. Then, we train the rest 10% of the steps of sequence of 512 to learn the positional embeddings.
较长的序列成本不成比例地高,因为注意力与序列长度呈二次关系。为了在实验中加速预训练,我们在90%的步骤中使用序列长度128预训练模型。然后,在剩余10%的步骤中使用序列长度512进行训练,以学习位置嵌入。
A.3 Fine-tuning Procedure
A.3 微调过程
For fine-tuning, most model hyperparameters are the same as in pre-training, with the exception of the batch size, learning rate, and number of training epochs. The dropout probability was always kept at 0.1. The optimal hyperparameter values are task-specific, but we found the following range of possible values to work well across all tasks:
对于微调,大多数模型超参数与预训练相同,除了批量大小、学习率和训练周期数。dropout概率始终保持在0.1。最优超参数值因任务而异,但我们发现以下可能值范围在所有任务中都表现良好:
• Batch size: 16, 32
• 批量大小:16, 32
• Learning rate (Adam): 5e-5, 3e-5, 2e-5
• Number of epochs: 2, 3, 4
We also observed that large data sets (e.g., 100k+ labeled training examples) were far less sensitive to hyperparameter choice than small data sets. Fine-tuning is typically very fast, so it is reasonable to simply run an exhaustive search over the above parameters and choose the model that performs best on the development set.
• 学习率(Adam):5e-5、3e-5、2e-5
• 训练轮数:2、3、4
我们还观察到,大数据集(例如,10万+标注训练样本)对超参数选择的敏感度远低于小数据集。微调通常非常快,因此合理的方法是直接对上述参数进行穷举搜索,并选择在开发集上表现最佳的模型。
A.4 Comparison of BERT, ELMo, and OpenAI GPT
A.4 BERT、ELMo 与 OpenAI GPT 的比较
Here we studies the differences in recent popular representation learning models including ELMo, OpenAI GPT and BERT. The comparisons between the model architectures are shown visually in Figure 3. Note that in addition to the architecture differences, BERT and OpenAI GPT are fine-tuning approaches, while ELMo is a feature-based approach.
这里我们研究近期流行的表示学习模型(包括 ELMo、OpenAI GPT 和 BERT)之间的差异。模型架构之间的比较如图 3 所示。请注意,除了架构差异之外,BERT 和 OpenAI GPT 是微调方法,而 ELMo 是基于特征的方法。
The most comparable existing pre-training method to BERT is OpenAI GPT, which trains a left-to-right Transformer LM on a large text corpus. In fact, many of the design decisions in BERT were intentionally made to make it as close to GPT as possible so that the two methods could be minimally compared. The core argument of this work is that the bi-directionality and the two pre-training tasks presented in Section 3.1 account for the majority of the empirical improvements, but we do note that there are several other differences between how BERT and GPT were trained:
与 BERT 最具可比性的现有预训练方法是 OpenAI GPT,它在大型文本语料库上训练从左到右的 Transformer 语言模型。事实上,BERT 中的许多设计决策都是有意为之,使其尽可能接近 GPT,以便对两种方法进行最小化比较。本工作的核心论点是,第 3.1 节中提出的双向性和两个预训练任务解释了大部分经验改进,但我们确实注意到 BERT 和 GPT 的训练方式还有其他几个差异:
• GPT is trained on the BooksCorpus (800M words); BERT is trained on the BooksCorpus (800M words) and Wikipedia (2,500M words).
• GPT uses a sentence separator ([SEP]) and classifier token ([CLS]) which are only introduced at fine-tuning time; BERT learns [SEP], [CLS] and sentence A/B embeddings during pre-training.
• GPT was trained for 1M steps with a batch size of 32,000 words; BERT was trained for 1M steps with a batch size of 128,000 words.
• GPT used the same learning rate of 5e-5 for all fine-tuning experiments; BERT chooses a task-specific fine-tuning learning rate which performs the best on the development set.
• GPT 在 BooksCorpus(8 亿词)上训练;BERT 在 BooksCorpus(8 亿词)和 Wikipedia(25 亿词)上训练。
• GPT 使用句子分隔符([SEP])和分类器标记([CLS]),它们仅在微调时引入;BERT 在预训练期间学习 [SEP]、[CLS] 和句子 A/B 嵌入。
• GPT 训练了 100 万步,批量大小为 32,000 词;BERT 训练了 100 万步,批量大小为 128,000 词。
• GPT 在所有微调实验中使用相同的学习率 5e-5;BERT 选择在开发集上表现最佳的任务特定微调学习率。
To isolate the effect of these differences, we perform ablation experiments in Section 5.1 which demonstrate that the majority of the improvements are in fact coming from the two pre-training tasks and the bidirectionality they enable.
为了分离这些差异的影响,我们在第 5.1 节中进行了消融实验,结果表明大部分改进实际上来自两个预训练任务及其所实现的双向性。
A.5 Illustrations of Fine-tuning on Different Tasks
A.5 不同任务上微调的图示
The illustration of fine-tuning BERT on different tasks can be seen in Figure 4. Our task-specific models are formed by incorporating BERT with one additional output layer, so a minimal number of parameters need to be learned from scratch. Among the tasks, (a) and (b) are sequence-level tasks while (c) and (d) are token-level tasks. In the figure, E represents the input embedding, Ti represents the contextual representation of token i, [CLS] is the special symbol for classification output, and [SEP] is the special symbol to separate non-consecutive token sequences.
在不同任务上微调 BERT 的图示见图 4。我们的任务特定模型通过将 BERT 与一个额外的输出层结合而成,因此只需从头学习极少量的参数。在这些任务中,(a) 和 (b) 是序列级任务,而 (c) 和 (d) 是词元级任务。在图中,E 表示输入嵌入,Ti 表示词元 i 的上下文表示,[CLS] 是用于分类输出的特殊符号,[SEP] 是用于分隔非连续词元序列的特殊符号。
B Detailed Experimental Setup
B 详细实验设置
B.1 Detailed Descriptions for the GLUE Benchmark Experiments.
B.1 GLUE 基准实验的详细描述。
Our GLUE results in Table1 are obtained from https://gluebenchmark.com/leaderboard and https://blog.openai.com/language-unsupervised. The GLUE benchmark includes the following datasets, the descriptions of which were originally summarized in Wang et al. (2018a):
我们在表 1 中的 GLUE 结果来自 https://gluebenchmark.com/leaderboard 和 https://blog.openai.com/language-unsupervised。GLUE 基准包括以下数据集,其描述最初由 Wang 等人(2018a)总结:
MNLI Multi-Genre Natural Language Inference is a large-scale, crowdsourced entailment classification task (Williams et al., 2018). Given a pair of sentences, the goal is to predict whether the second sentence is an entailment, contradiction, or neutral with respect to the first one.
MNLI 多类型自然语言推理是一个大规模、众包的蕴含分类任务(Williams 等人,2018)。给定一对句子,目标是预测第二个句子相对于第一个句子是蕴含、矛盾还是中立。
QQP Quora Question Pairs is a binary classification task where the goal is to determine if two questions asked on Quora are semantically equivalent (Chen et al., 2018).
QQP Quora 问题对是一个二元分类任务,目标是确定在 Quora 上提出的两个问题在语义上是否等价(Chen 等人,2018)。
QNLI Question Natural Language Inference is a version of the Stanford Question Answering Dataset (Rajpurkar et al., 2016) which has been converted to a binary classification task (Wang et al., 2018a). The positive examples are (question, sentence) pairs which do contain the correct answer, and the negative examples are (question, sentence) from the same paragraph which do not contain the answer.
QNLI 问题自然语言推理是斯坦福问答数据集(Rajpurkar 等人,2016)的一个版本,已被转换为二元分类任务(Wang 等人,2018a)。正例是确实包含正确答案的(问题,句子)对,负例是来自同一段落但不包含答案的(问题,句子)。
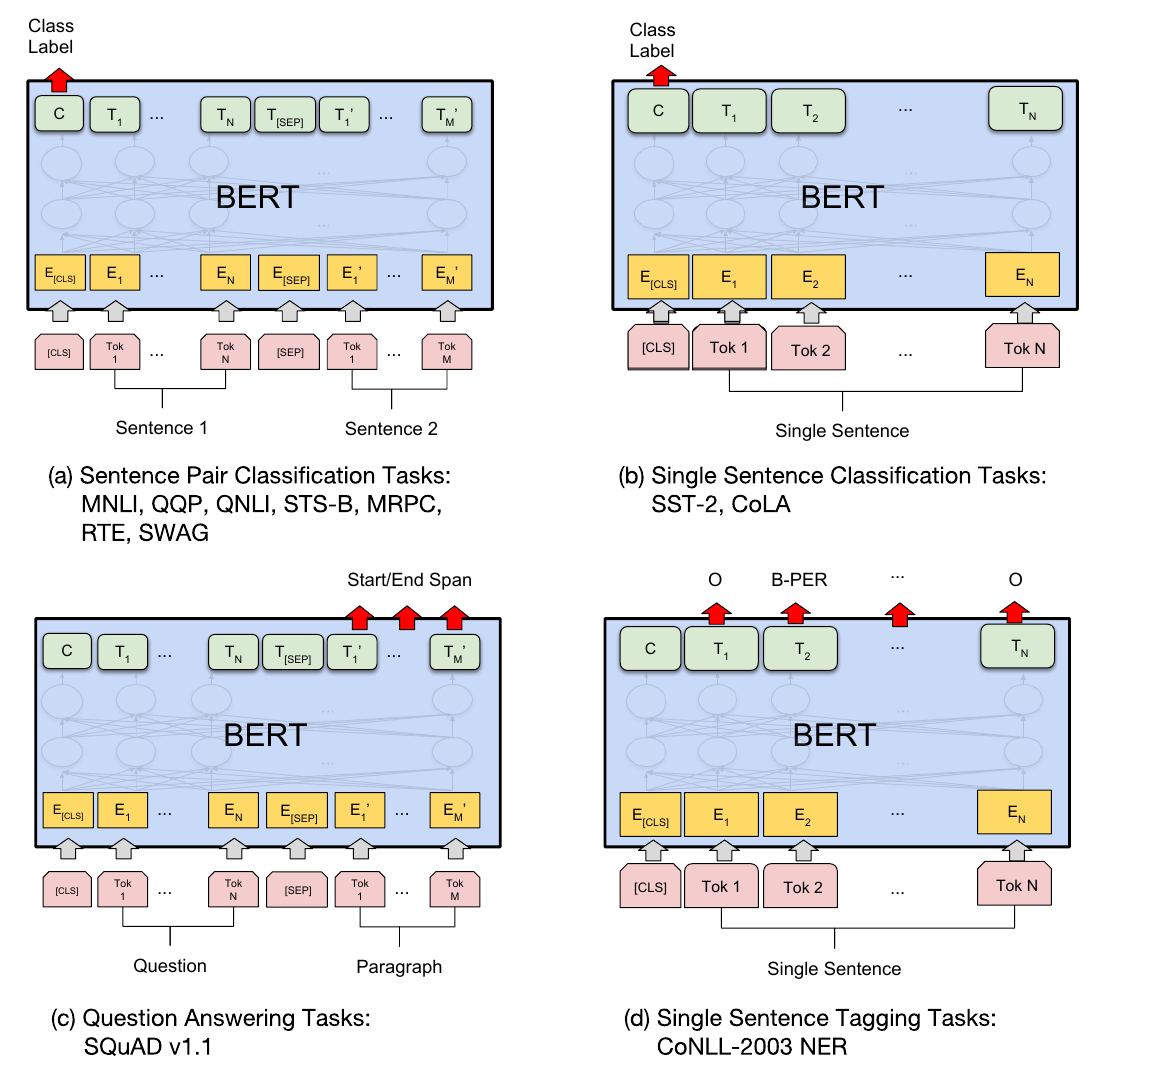
Figure 4: Illustrations of Fine-tuning BERT on Different Tasks.
图4:在不同任务上微调BERT的示意图。
图内标注:(a) 句子对分类;(b) 单句分类;(c) 问答;(d) 单句序列标注。Class Label 为类别标签,Start/End Span 为答案起止位置,Question 为问题,Paragraph 为段落,Single Sentence 为单句。
SST-2 The Stanford Sentiment Treebank is a binary single-sentence classification task consisting of sentences extracted from movie reviews with human annotations of their sentiment (Socher et al., 2013).
SST-2 斯坦福情感树库是一个二元单句分类任务,包含从电影评论中提取的句子,并带有人工标注的情感(Socher 等人,2013)。
CoLA The Corpus of Linguistic Acceptability is a binary single-sentence classification task, where the goal is to predict whether an English sentence is linguistically “acceptable” or not (Warstadt et al., 2018).
CoLA 语言可接受性语料库是一个二元单句分类任务,其目标是预测一个英语句子在语言上是否“可接受”(Warstadt 等人,2018)。
STS-B The Semantic Textual Similarity Benchmark is a collection of sentence pairs drawn from news headlines and other sources (Cer et al., 2017). They were annotated with a score from 1 to 5 denoting how similar the two sentences are in terms of semantic meaning.
STS-B 语义文本相似度基准是一个句子对集合,取自新闻标题和其他来源(Cer 等人,2017)。它们被标注了从1到5的分数,表示两个句子在语义意义上的相似程度。
MRPC Microsoft Research Paraphrase Corpus consists of sentence pairs automatically extracted from online news sources, with human annotations for whether the sentences in the pair are semantically equivalent (Dolan and Brockett, 2005).
MRPC 微软研究院释义语料库包含从在线新闻来源自动提取的句子对,并带有人工标注,说明句子对中的句子在语义上是否等价(Dolan 和 Brockett,2005)。
RTE Recognizing Textual Entailment is a binary entailment task similar to MNLI, but with much less training data (Bentivogli et al., 2009).14
RTE 识别文本蕴含是一个二元蕴含任务,类似于MNLI,但训练数据少得多(Bentivogli 等人,2009)。14
WNLI Winograd NLI is a small natural language inference dataset (Levesque et al., 2011). The GLUE webpage notes that there are issues with the construction of this dataset, 15 and every trained system that’s been submitted to GLUE has performed worse than the 65.1 baseline accuracy of predicting the majority class. We therefore exclude this set to be fair to OpenAI GPT. For our GLUE submission, we always predicted the majority class.
WNLI Winograd NLI 是一个小型自然语言推理数据集(Levesque 等,2011)。GLUE 网页指出该数据集的构建存在问题,15 并且所有提交给 GLUE 的已训练系统表现都差于预测多数类的 65.1 基线准确率。因此,为了公平对待 OpenAI GPT,我们排除了这个数据集。对于我们的 GLUE 提交,我们始终预测多数类。
14 Note that we only report single-task fine-tuning results in this paper. A multitask fine-tuning approach could potentially push the performance even further. For example, we did observe substantial improvements on RTE from multitask training with MNLI.
14 请注意,本文仅报告单任务微调结果。多任务微调方法可能会进一步提升性能。例如,我们确实观察到通过使用 MNLI 进行多任务训练,RTE 的性能有显著提升。
C Additional Ablation Studies
C 附加消融研究
C.1 Effect of Number of Training Steps
C.1 训练步数的影响
Figure 5 presents MNLI Dev accuracy after finetuning from a checkpoint that has been pre-trained for k steps. This allows us to answer the following questions:
图5展示了从已预训练k步的检查点进行微调后的MNLI开发集准确率。这使我们能够回答以下问题:
- Question: Does BERT really need such a large amount of pre-training (128,000 words/batch * 1,000,000 steps) to achieve high fine-tuning accuracy? Answer: Yes, BERTBASE achieves almost 1.0% additional accuracy on MNLI when trained on 1M steps compared to 500k steps.
- 问题:BERT真的需要如此大量的预训练(128,000词/批次 * 1,000,000步)才能达到高微调准确率吗?回答:是的,与500k步相比,BERTBASE在1M步训练后在MNLI上获得了几乎1.0%的额外准确率。
- Question: Does MLM pre-training converge slower than LTR pre-training, since only 15% of words are predicted in each batch rather than every word? Answer: The MLM model does converge slightly slower than the LTR model. However, in terms of absolute accuracy the MLM model begins to outperform the LTR model almost immediately.
- 问题:由于每个批次中只有15%的词被预测,而不是每个词,MLM预训练是否比LTR预训练收敛更慢?回答:MLM模型确实比LTR模型收敛稍慢。然而,就绝对准确率而言,MLM模型几乎立即开始优于LTR模型。
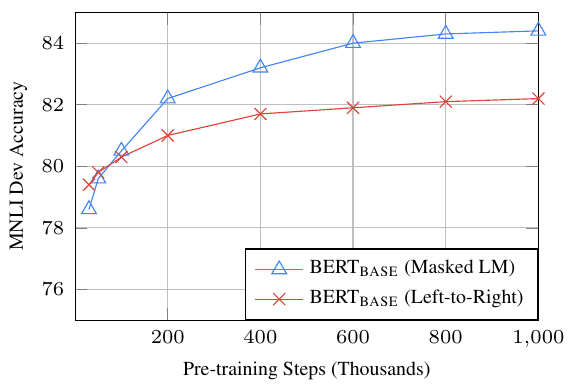
Figure 5: Ablation over number of training steps. This shows the MNLI accuracy after fine-tuning, starting from model parameters that have been pre-trained for k steps. The x-axis is the value of k.
图5:训练步数的消融。这显示了从已预训练k步的模型参数开始微调后的MNLI准确率。x轴是k的值。
图内标注:横轴为预训练步数(千步),纵轴为 MNLI 开发集准确率。蓝线为掩码语言模型,红线为从左到右的语言模型。
C.2 Ablation for Different Masking Procedures
C.2 不同掩码策略的消融
In Section 3.1, we mention that BERT uses a mixed strategy for masking the target tokens when pre-training with the masked language model (MLM) objective. The following is an ablation study to evaluate the effect of different masking strategies.
在第3.1节中,我们提到BERT在使用掩码语言模型(MLM)目标进行预训练时,采用混合策略来掩码目标词元。以下是一项消融研究,用于评估不同掩码策略的效果。
Note that the purpose of the masking strategies is to reduce the mismatch between pre-training and fine-tuning, as the [MASK] symbol never appears during the fine-tuning stage. We report the Dev results for both MNLI and NER. For NER, we report both fine-tuning and feature-based approaches, as we expect the mismatch will be amplified for the feature-based approach as the model will not have the chance to adjust the representations.
请注意,掩码策略的目的是减少预训练和微调之间的不匹配,因为[MASK]符号在微调阶段从未出现。我们报告了MNLI和NER的开发集结果。对于NER,我们报告了微调和基于特征的方法,因为我们预计对于基于特征的方法,这种不匹配会被放大,因为模型将没有机会调整表示。
| MASK | SAME | RND | MNLI Fine-tune | NER Fine-tune | NER Feature-based |
|---|---|---|---|---|---|
| 80% | 10% | 10% | 84.2 | 95.4 | 94.9 |
| 100% | 0% | 0% | 84.3 | 94.9 | 94.0 |
| 80% | 0% | 20% | 84.1 | 95.2 | 94.6 |
| 80% | 20% | 0% | 84.4 | 95.2 | 94.7 |
| 0% | 20% | 80% | 83.7 | 94.8 | 94.6 |
| 0% | 0% | 100% | 83.6 | 94.9 | 94.6 |
| 掩码替换 | 保持原样 | 随机替换 | MNLI 微调 | NER 微调 | NER 基于特征 |
|---|---|---|---|---|---|
| 80% | 10% | 10% | 84.2 | 95.4 | 94.9 |
| 100% | 0% | 0% | 84.3 | 94.9 | 94.0 |
| 80% | 0% | 20% | 84.1 | 95.2 | 94.6 |
| 80% | 20% | 0% | 84.4 | 95.2 | 94.7 |
| 0% | 20% | 80% | 83.7 | 94.8 | 94.6 |
| 0% | 0% | 100% | 83.6 | 94.9 | 94.6 |
Table 8: Ablation over different masking strategies.
表8:不同掩码策略的消融。
The results are presented in Table 8. In the table, MASK means that we replace the target token with the [MASK] symbol for MLM; SAME means that we keep the target token as is; RND means that we replace the target token with another random token.
结果呈现在表8中。在表中,MASK表示我们用[MASK]符号替换目标词元以进行MLM;SAME表示我们保持目标词元不变;RND表示我们用另一个随机词元替换目标词元。
The numbers in the left part of the table represent the probabilities of the specific strategies used during MLM pre-training (BERT uses 80%, 10%, 10%). The right part of the paper represents the Dev set results. For the feature-based approach, we concatenate the last 4 layers of BERT as the features, which was shown to be the best approach in Section 5.3.
表格左侧的数字表示MLM预训练期间使用的特定策略的概率(BERT使用80%、10%、10%)。表格的右侧部分表示开发集结果。对于基于特征的方法,我们将BERT的最后4层连接起来作为特征,这在第5.3节中被证明是最好的方法。
From the table it can be seen that fine-tuning is surprisingly robust to different masking strategies. However, as expected, using only the MASK strategy was problematic when applying the feature-based approach to NER. Interestingly, using only the RND strategy performs much worse than our strategy as well.
从表中可以看出,微调对不同掩码策略出奇地稳健。然而,正如预期的那样,在将基于特征的方法应用于NER时,仅使用MASK策略是有问题的。有趣的是,仅使用RND策略的表现也比我们的策略差得多。