Batch Normalization: Accelerating Deep Network Training by Reducing Internal Covariate Shift
Batch Normalization: Accelerating Deep Network Training by Reducing Internal Covariate Shift
批归一化:通过减少内部协变量偏移加速深度网络训练(Batch Normalization: Accelerating Deep Network Training by Reducing Internal Covariate Shift)
Sergey Ioffe Affiliation: Google Inc., sioffe@google.com Christian Szegedy Affiliation: Google Inc., szegedy@google.com
Sergey Ioffe
所属机构:Google Inc.,sioffe@google.com
Christian Szegedy
所属机构:Google Inc.,szegedy@google.com
Abstract
摘要
Training Deep Neural Networks is complicated by the fact that the distribution of each layer’s inputs changes during training, as the parameters of the previous layers change. This slows down the training by requiring lower learning rates and careful parameter initialization, and makes it notoriously hard to train models with saturating nonlinearities. We refer to this phenomenon as internal covariate shift, and address the problem by normalizing layer inputs. Our method draws its strength from making normalization a part of the model architecture and performing the normalization for each training mini-batch. Batch Normalization allows us to use much higher learning rates and be less careful about initialization. It also acts as a regularizer, in some cases eliminating the need for Dropout. Applied to a state-of-the-art image classification model, Batch Normalization achieves the same accuracy with 14 times fewer training steps, and beats the original model by a significant margin. Using an ensemble of batch-normalized networks, we improve upon the best published result on ImageNet classification: reaching 4.9% top-5 validation error (and 4.8% test error), exceeding the accuracy of human raters.
训练深度神经网络时,每一层输入的分布会随前层参数更新而变化,这使训练变得复杂:需要更小的学习率、更谨慎的参数初始化,带饱和非线性的模型也极难训练。我们把这一现象称为内部协变量偏移(Internal Covariate Shift),并通过归一化层输入来应对。我们的方法利用 mini-batch 上的均值与方差做归一化,并回传归一化所需的梯度。批归一化(批归一化)使更大的学习率可用、对初始化更不敏感,还充当正则、在部分情形下减少对 Dropout 的依赖。应用到目前最强的 ImageNet 分类网络上,批归一化用少得多的训练步数达到同等精度,并显著超过原模型。用一组批归一化网络做集成,在 ImageNet 分类挑战的验证集上把 top-5 错误率降到了 4.8%,超过了人类标注者给出的估计。
1 Introduction
1 引言
Deep learning has dramatically advanced the state of the art in vision, speech, and many other areas. Stochastic gradient descent (SGD) has proved to be an effective way of training deep networks, and SGD variants such as momentum Sutskever et al. 2013 and Adagrad Duchi et al. 2011 have been used to achieve state of the art performance. SGD optimizes the parameters of the network, so as to minimize the loss
深度学习极大地提升了视觉、语音和许多其他领域的技术水平。 随机梯度下降 (SGD) 已被证明是训练深度网络的有效方法,而 SGD 变体如动量 Sutskever 等人。 2013 年和 Adagrad Duchi 等人。 2011 年已用于实现最先进的性能。 SGD优化网络的参数,从而使损失最小化
where is the training data set. With SGD, the training proceeds in steps, and at each step we consider a mini-batch of size . The mini-batch is used to approximate the gradient of the loss function with respect to the parameters, by computing
其中是训练数据集。 使用 SGD,训练分步骤进行,并且在每一步我们都会考虑大小为的小批量。 小批量用于近似损失函数相对于参数的梯度,通过计算
Using mini-batches of examples, as opposed to one example at a time, is helpful in several ways. First, the gradient of the loss over a mini-batch is an estimate of the gradient over the training set, whose quality improves as the batch size increases. Second, computation over a batch can be much more efficient than computations for individual examples, due to the parallelism afforded by the modern computing platforms.
使用小批量示例(而不是一次使用一个示例)在很多方面都有帮助。 首先,小批量损失的梯度是训练集梯度的估计,其质量随着批量大小的增加而提高。 其次,由于现代计算平台提供的并行性,批量计算比单个示例的计算要高效得多。
While stochastic gradient is simple and effective, it requires careful tuning of the model hyper-parameters, specifically the learning rate used in optimization, as well as the initial values for the model parameters. The training is complicated by the fact that the inputs to each layer are affected by the parameters of all preceding layers – so that small changes to the network parameters amplify as the network becomes deeper.
虽然随机梯度简单有效,但它需要仔细调整模型超参数,特别是优化中使用的学习率以及模型参数的初始值。 由于每一层的输入都受到前面所有层的参数的影响,因此训练变得很复杂——因此,随着网络变得更深,网络参数的微小变化会放大。
The change in the distributions of layers’ inputs presents a problem because the layers need to continuously adapt to the new distribution. When the input distribution to a learning system changes, it is said to experience covariate shift Shimodaira 2000. This is typically handled via domain adaptation Jiang 2008. However, the notion of covariate shift can be extended beyond the learning system as a whole, to apply to its parts, such as a sub-network or a layer. Consider a network computing
层输入分布的变化会带来一个问题,因为层需要不断适应新的分布。 当学习系统的输入分布发生变化时,据说会经历协变量偏移 Shimodaira 2000。这通常通过域适应 Jiang 2008 来处理。但是,协变量偏移的概念可以扩展到整个学习系统之外,以应用于其各个部分,例如子网络或层。 考虑网络计算
where and are arbitrary transformations, and the parameters are to be learned so as to minimize the loss . Learning can be viewed as if the inputs are fed into the sub-network
其中和是任意变换,并且需要学习参数以便最小化损失。 学习可以被视为输入被馈送到子网络中
For example, a gradient descent step
例如,梯度下降步骤
(for batch size and learning rate ) is exactly equivalent to that for a stand-alone network with input . Therefore, the input distribution properties that make training more efficient – such as having the same distribution between the training and test data – apply to training the sub-network as well. As such it is advantageous for the distribution of to remain fixed over time. Then, does not have to readjust to compensate for the change in the distribution of .
(对于批量大小和学习率)与输入的独立网络完全相同。 因此,使训练更加高效的输入分布属性(例如训练数据和测试数据之间具有相同的分布)也适用于训练子网络。 因此,随着时间的推移, 的分布保持固定是有利的。 那么,不必重新调整来补偿分布的变化。
Fixed distribution of inputs to a sub-network would have positive consequences for the layers outside the sub-network, as well. Consider a layer with a sigmoid activation function where is the layer input, the weight matrix and bias vector are the layer parameters to be learned, and . As increases, tends to zero. This means that for all dimensions of except those with small absolute values, the gradient flowing down to will vanish and the model will train slowly. However, since is affected by and the parameters of all the layers below, changes to those parameters during training will likely move many dimensions of into the saturated regime of the nonlinearity and slow down the convergence. This effect is amplified as the network depth increases. In practice, the saturation problem and the resulting vanishing gradients are usually addressed by using Rectified Linear Units Nair & Hinton 2010 , careful initialization Bengio & Glorot 2010; Saxe et al. 2013, and small learning rates. If, however, we could ensure that the distribution of nonlinearity inputs remains more stable as the network trains, then the optimizer would be less likely to get stuck in the saturated regime, and the training would accelerate.
子网络输入的固定分布也会对子网络“外部”的层产生积极的影响。 考虑具有 sigmoid 激活函数的层,其中是层输入,权重矩阵和偏差向量是要学习的层参数, 。 随着的增加, 趋于零。 这意味着对于的所有维度(绝对值较小的维度除外),流向的梯度将消失,模型将训练缓慢。 然而,由于受到和下面所有层的参数的影响,因此在训练期间对这些参数的更改可能会使的许多维度进入非线性的饱和状态并减慢收敛速度。 随着网络深度的增加,这种效应会被放大。 在实践中,饱和问题和由此产生的梯度消失通常通过使用修正线性单元 Nair & Hinton 2010、仔细初始化 Bengio & Glorot 2010 来解决; 萨克斯等人。 2013 年,学习率较小。 然而,如果我们能够确保非线性输入的分布在网络训练时保持更加稳定,那么优化器就不太可能陷入饱和状态,并且训练将会加速。
We refer to the change in the distributions of internal nodes of a deep network, in the course of training, as Internal Covariate Shift. Eliminating it offers a promise of faster training. We propose a new mechanism, which we call Batch Normalization, that takes a step towards reducing internal covariate shift, and in doing so dramatically accelerates the training of deep neural nets. It accomplishes this via a normalization step that fixes the means and variances of layer inputs. Batch Normalization also has a beneficial effect on the gradient flow through the network, by reducing the dependence of gradients on the scale of the parameters or of their initial values. This allows us to use much higher learning rates without the risk of divergence. Furthermore, batch normalization regularizes the model and reduces the need for Dropout Srivastava et al. 2014. Finally, Batch Normalization makes it possible to use saturating nonlinearities by preventing the network from getting stuck in the saturated modes.
我们把深度网络训练过程中内部节点分布的变化称为内部协变量偏移(Internal Covariate Shift)。消除它有望加快训练。我们提出一种机制:对层输入做归一化,并把该步骤嵌入网络本身,在每次参数更新时执行。为了保证归一化对网络无损,我们让网络学习恢复各激活所需的恒等变换;由此,网络可以撤销归一化,若它是最优选择。同样,归一化也保证模型的表达能力不受损。
In Sec. 4.2, we apply Batch Normalization to the best-performing ImageNet classification network, and show that we can match its performance using only 7% of the training steps, and can further exceed its accuracy by a substantial margin. Using an ensemble of such networks trained with Batch Normalization, we achieve the top-5 error rate that improves upon the best known results on ImageNet classification.
在秒。 4.2 中,我们将 批归一化(批归一化) 应用于性能最佳的 ImageNet 分类网络,并表明我们仅使用 7% 的训练步骤就可以匹配其性能,并且可以进一步大幅超过其准确性。 使用通过批量归一化训练的此类网络的集合,我们实现了前 5 名错误率,该错误率改进了 ImageNet 分类的最佳已知结果。
2 Towards Reducing Internal Covariate Shift
2 迈向减少内部协变量偏移
We define Internal Covariate Shift as the change in the distribution of network activations due to the change in network parameters during training. To improve the training, we seek to reduce the internal covariate shift. By fixing the distribution of the layer inputs as the training progresses, we expect to improve the training speed. It has been long known LeCun et al. 1998b; Wiesler & Ney 2011 that the network training converges faster if its inputs are whitened – i.e., linearly transformed to have zero means and unit variances, and decorrelated. As each layer observes the inputs produced by the layers below, it would be advantageous to achieve the same whitening of the inputs of each layer. By whitening the inputs to each layer, we would take a step towards achieving the fixed distributions of inputs that would remove the ill effects of the internal covariate shift.
我们将“内部协变量偏移”定义为由于训练期间网络参数的变化而导致的网络激活分布的变化。 为了改进训练,我们寻求减少内部协变量偏移。 通过随着训练的进行固定层输入的分布,我们期望提高训练速度。 LeCun 等人早已为人所知。 1998b; Wiesler & Ney 2011 指出,如果输入被白化,即线性变换为均值和单位方差为零,并且去相关,则网络训练收敛得更快。 由于每一层都会观察下面各层产生的输入,因此对每一层的输入实现相同的白化将是有利的。 通过白化每一层的输入,我们将朝着实现输入的固定分布迈出一步,从而消除内部协变量偏移的不良影响。
We could consider whitening activations at every training step or at some interval, either by modifying the network directly or by changing the parameters of the optimization algorithm to depend on the network activation values Wiesler et al. 2014; Raiko et al. 2012; Povey et al. 2014; Desjardins & Kavukcuoglu. However, if these modifications are interspersed with the optimization steps, then the gradient descent step may attempt to update the parameters in a way that requires the normalization to be updated, which reduces the effect of the gradient step. For example, consider a layer with the input that adds the learned bias , and normalizes the result by subtracting the mean of the activation computed over the training data: where , is the set of values of over the training set, and . If a gradient descent step ignores the dependence of on , then it will update , where . Then . Thus, the combination of the update to and subsequent change in normalization led to no change in the output of the layer nor, consequently, the loss. As the training continues, will grow indefinitely while the loss remains fixed. This problem can get worse if the normalization not only centers but also scales the activations. We have observed this empirically in initial experiments, where the model blows up when the normalization parameters are computed outside the gradient descent step.
我们可以考虑在每个训练步骤或在某个时间间隔进行白化激活,方法是直接修改网络或更改优化算法的参数以取决于网络激活值 Wiesler 等人。 2014年; 莱科等人 2012年; 波维等人。 2014年; Desjardins 和 Kavukcuoglu。 然而,如果这些修改散布在优化步骤中,那么梯度下降步骤可能会尝试以需要更新归一化的方式来更新参数,这会降低梯度步骤的效果。 例如,考虑一个具有输入的层,该层添加了学习偏差,并通过减去训练数据上计算的激活平均值来标准化结果:其中, 是训练集上和的值集。 如果梯度下降步骤忽略对的依赖性,那么它将更新,其中。 然后是。 因此,对的更新和随后的归一化更改相结合不会导致该层的输出发生变化,也不会导致损失。 随着训练的继续, 将无限增长,而损失保持不变。 如果标准化不仅中心化而且还缩放激活,这个问题可能会变得更糟。 我们在最初的实验中凭经验观察到了这一点,当在梯度下降步骤之外计算归一化参数时,模型就会崩溃。
The issue with the above approach is that the gradient descent optimization does not take into account the fact that the normalization takes place. To address this issue, we would like to ensure that, for any parameter values, the network always produces activations with the desired distribution. Doing so would allow the gradient of the loss with respect to the model parameters to account for the normalization, and for its dependence on the model parameters . Let again be a layer input, treated as a vector, and be the set of these inputs over the training data set. The normalization can then be written as a transformation
上述方法的问题在于梯度下降优化没有考虑到归一化发生的事实。 为了解决这个问题,我们希望确保对于任何参数值,网络始终产生具有所需分布的激活。 这样做将使损失相对于模型参数的梯度能够解释归一化及其对模型参数的依赖性。 再次让为层输入,被视为向量, 为训练数据集上这些输入的集合。 然后标准化可以写成一个变换
which depends not only on the given training example but on all examples – each of which depends on if is generated by another layer. For backpropagation, we would need to compute the Jacobians
这不仅取决于给定的训练示例 ,还取决于所有示例– 如果由另一层生成,则每个示例都取决于 。 对于反向传播,我们需要计算雅可比行列式
ignoring the latter term would lead to the explosion described above. Within this framework, whitening the layer inputs is expensive, as it requires computing the covariance matrix and its inverse square root, to produce the whitened activations , as well as the derivatives of these transforms for backpropagation. This motivates us to seek an alternative that performs input normalization in a way that is differentiable and does not require the analysis of the entire training set after every parameter update.
忽略后一项将导致上述爆炸。 在此框架内,白化层输入的成本很高,因为它需要计算协方差矩阵及其反平方根,以生成白化激活以及这些变换的导数以进行反向传播。 这促使我们寻求一种替代方案,以可微分的方式执行输入标准化,并且不需要在每次参数更新后分析整个训练集。
Some of the previous approaches (e.g. Lyu & Simoncelli 2008) use statistics computed over a single training example, or, in the case of image networks, over different feature maps at a given location. However, this changes the representation ability of a network by discarding the absolute scale of activations. We want to a preserve the information in the network, by normalizing the activations in a training example relative to the statistics of the entire training data.
之前的一些方法(例如 Lyu & Simoncelli 2008)使用在单个训练示例上计算的统计数据,或者在ImageNet络的情况下,在给定位置的不同特征图上计算的统计数据。 然而,这通过丢弃激活的绝对规模来改变网络的表示能力。 我们希望通过相对于整个训练数据的统计数据标准化训练示例中的激活来保留网络中的信息。
3 Normalization via Mini-Batch Statistics
3 用 Mini-Batch 统计做归一化
Since the full whitening of each layer’s inputs is costly and not everywhere differentiable, we make two necessary simplifications. The first is that instead of whitening the features in layer inputs and outputs jointly, we will normalize each scalar feature independently, by making it have the mean of zero and the variance of 1. For a layer with -dimensional input , we will normalize each dimension
由于每层输入的完全白化成本高昂且并非处处可微,因此我们进行了两项必要的简化。 第一个是,我们不是联合白化层输入和输出中的特征,而是独立地标准化每个标量特征,使其均值为零,方差为1。对于具有维输入的层,我们将标准化每个维度
where the expectation and variance are computed over the training data set. As shown in LeCun et al. 1998b, such normalization speeds up convergence, even when the features are not decorrelated.
其中期望和方差是在训练数据集上计算的。 如 LeCun 等人所示。 1998b,这种归一化加速了收敛速度,即使特征没有解相关。
Note that simply normalizing each input of a layer may change what the layer can represent. For instance, normalizing the inputs of a sigmoid would constrain them to the linear regime of the nonlinearity. To address this, we make sure that the transformation inserted in the network can represent the identity transform. To accomplish this, we introduce, for each activation , a pair of parameters , which scale and shift the normalized value:
请注意,简单地规范化层的每个输入可能会改变该层可以表示的内容。 例如,标准化 sigmoid 的输入会将它们限制为非线性的线性状态。 为了解决这个问题,我们确保插入网络中的变换可以代表恒等变换。 为了实现这一点,我们为每个激活引入一对参数,用于缩放和移动归一化值:
These parameters are learned along with the original model parameters, and restore the representation power of the network. Indeed, by setting and , we could recover the original activations, if that were the optimal thing to do.
这些参数与原始模型参数一起学习,并恢复网络的表示能力。 事实上,通过设置和,我们可以恢复原始激活,如果这是最佳做法的话。
In the batch setting where each training step is based on the entire training set, we would use the whole set to normalize activations. However, this is impractical when using stochastic optimization. Therefore, we make the second simplification: since we use mini-batches in stochastic gradient training, each mini-batch produces estimates of the mean and variance of each activation. This way, the statistics used for normalization can fully participate in the gradient backpropagation. Note that the use of mini-batches is enabled by computation of per-dimension variances rather than joint covariances; in the joint case, regularization would be required since the mini-batch size is likely to be smaller than the number of activations being whitened, resulting in singular covariance matrices.
在批处理设置中,每个训练步骤都基于整个训练集,我们将使用整个训练集来标准化激活。 然而,当使用随机优化时,这是不切实际的。 因此,我们进行第二次简化:由于我们在随机梯度训练中使用小批量,每个小批量都会生成每个激活的均值和方差的估计。 这样,用于归一化的统计量就可以充分参与梯度反向传播。 请注意,小批量的使用是通过计算每维方差而不是联合协方差来实现的; 在联合情况下,需要进行正则化,因为小批量大小可能小于白化激活的数量,从而导致奇异协方差矩阵。
Consider a mini-batch of size . Since the normalization is applied to each activation independently, let us focus on a particular activation and omit for clarity. We have values of this activation in the mini-batch,
考虑大小为的小批量。 由于归一化独立应用于每个激活,因此为了清楚起见,让我们关注特定的激活并省略 。 我们在小批量中拥有此激活的值,
Let the normalized values be , and their linear transformations be . We refer to the transform
令归一化值为,其线性变换为。 我们参考变换
as the Batch Normalizing Transform. We present the BN Transform in Algorithm 1. In the algorithm, is a constant added to the mini-batch variance for numerical stability.
称之为批归一化变换(Batch Normalizing Transform)。算法 1 给出 BN 变换。算法中 是为数值稳定加到 mini-batch 方差上的常数。
| Values of over a mini-batch: ; |
|---|
| Parameters to be learned: , |
0: Values of over a mini-batch: ; Parameters to be learned: ,
0: // mini-batch mean // mini-batch variance // normalize // scale and shift
Algorithm 1 Batch Normalizing Transform, applied to activation over a mini-batch.
| 小批量中的值:; |
|---|
| 需要学习的参数:, |
0: 小批量中的值: ; 需要学习的参数:,
0: // 小批量均值 // 小批量方差 // 标准化 // 缩放和移位
算法 1 批量归一化变换,应用于小批量激活 。
The BN transform can be added to a network to manipulate any activation. In the notation , we indicate that the parameters and are to be learned, but it should be noted that the BN transform does not independently process the activation in each training example. Rather, depends both on the training example and the other examples in the mini-batch. The scaled and shifted values are passed to other network layers. The normalized activations are internal to our transformation, but their presence is crucial. The distributions of values of any has the expected value of and the variance of , as long as the elements of each mini-batch are sampled from the same distribution, and if we neglect . This can be seen by observing that and , and taking expectations. Each normalized activation can be viewed as an input to a sub-network composed of the linear transform , followed by the other processing done by the original network. These sub-network inputs all have fixed means and variances, and although the joint distribution of these normalized can change over the course of training, we expect that the introduction of normalized inputs accelerates the training of the sub-network and, consequently, the network as a whole.
BN 变换可以添加到网络中以操纵任何激活。 在符号中,我们表明要学习参数和 ,但应该注意的是,BN 变换不会独立处理每个训练示例中的激活。 相反, 取决于训练示例和小批量中的其他示例。 缩放和移位的值被传递到其他网络层。 标准化激活是我们转换的内部因素,但它们的存在至关重要。 只要每个小批量的元素是从相同的分布中采样的,并且如果我们忽略,任何的值的分布都具有的期望值和的方差。 这可以通过观察和并获取期望来看出。 每个归一化激活都可以被视为由线性变换组成的子网络的输入,然后由原始网络完成其他处理。 这些子网络输入都具有固定的均值和方差,尽管这些归一化的联合分布可能会在训练过程中发生变化,但我们预计归一化输入的引入会加速子网络的训练,从而加速整个网络的训练。
During training we need to backpropagate the gradient of loss through this transformation, as well as compute the gradients with respect to the parameters of the BN transform. We use chain rule, as follows (before simplification):
在训练过程中,我们需要通过这个变换反向传播损失的梯度,并计算相对于 BN 变换参数的梯度。 我们使用链式法则,如下(简化之前):
Thus, BN transform is a differentiable transformation that introduces normalized activations into the network. This ensures that as the model is training, layers can continue learning on input distributions that exhibit less internal covariate shift, thus accelerating the training. Furthermore, the learned affine transform applied to these normalized activations allows the BN transform to represent the identity transformation and preserves the network capacity.
因此,BN 变换是可微的,它向网络引入归一化后的激活。这保证训练时各层可以在内部协变量偏移更小的输入分布上继续学习,从而加速训练。此外,作用在这些归一化激活上的可学习仿射变换,使网络仍能表示恒等变换。
3.1 Training and Inference with Batch-Normalized Networks
3.1 训练与推理批归一化网络
To Batch-Normalize a network, we specify a subset of activations and insert the BN transform for each of them, according to Alg. 1. Any layer that previously received as the input, now receives . A model employing Batch Normalization can be trained using batch gradient descent, or Stochastic Gradient Descent with a mini-batch size , or with any of its variants such as Adagrad Duchi et al. 2011. The normalization of activations that depends on the mini-batch allows efficient training, but is neither necessary nor desirable during inference; we want the output to depend only on the input, deterministically. For this, once the network has been trained, we use the normalization
为了“批量归一化”网络,我们指定激活子集,并根据 Alg 为每个激活子集插入 BN 变换。 1. 之前接收作为输入的任何层现在接收。 采用批量归一化的模型可以使用批量梯度下降或小批量大小的随机梯度下降或其任何变体(例如 Adagrad Duchi 等人)进行训练。 2011.依赖于小批量的激活标准化可以实现高效的训练,但在推理过程中既不必要也不可取; 我们希望输出确定性地仅依赖于输入。 为此,一旦网络经过训练,我们就使用归一化
using the population, rather than mini-batch, statistics. Neglecting , these normalized activations have the same mean 0 and variance 1 as during training. We use the unbiased variance estimate , where the expectation is over training mini-batches of size and are their sample variances. Using moving averages instead, we can track the accuracy of a model as it trains. Since the means and variances are fixed during inference, the normalization is simply a linear transform applied to each activation. It may further be composed with the scaling by and shift by , to yield a single linear transform that replaces . Algorithm 2 summarizes the procedure for training batch-normalized networks.
使用总体统计而不是小批量统计。 忽略,这些归一化激活与训练期间具有相同的均值 0 和方差 1。 我们使用无偏方差估计,其中期望超过训练小批量的大小和是它们的样本方差。 使用移动平均值,我们可以跟踪模型训练时的准确性。 由于均值和方差在推理过程中是固定的,因此归一化只是应用于每个激活的线性变换。 它可以进一步由的缩放和的移位组成,以产生替代的单个线性变换。 算法 2 总结了训练批量归一化网络的过程。
| Network N with trainable parameters ; |
|---|
| subset of activations |
| // Inference BN network with frozen |
|---|
| // parameters |
0: Network N with trainable parameters ; subset of activations
0: Batch-normalized network for inference,
1: // Training BN network
2: for do
3: Add transformation to (Alg. 1)
4: Modify each layer in with input to take instead
5: end for
6: Train to optimize the parameters
7: // Inference BN network with frozen // parameters
8: for do
9: // For clarity, , etc.
10: Process multiple training mini-batches , each of size , and average over them:
11: In , replace the transform with
12: end for
Algorithm 2 Training a Batch-Normalized Network
| 具有可训练参数的网络 N; |
|---|
| 激活子集 |
| // 冻结的推理 BN 网络 |
|---|
| // parameters |
0: 具有可训练参数的网络 N ; 激活子集
0: 用于推理的批量归一化网络,
1: //训练BN网络
2: 对于做
3: 将转换添加到 (算法 1)
4: 使用输入修改中的每一层以采用代替
5: 结束****用于
6: 训练来优化参数
7: // 具有冻结 // 参数的推理 BN 网络
8: 对于做
9: // 为了清楚起见, 等。
10: 处理多个训练小批量,每个大小为,并对它们求平均值:
11: 在中,将变换替换为
12: 结束****为了
算法 2 训练批量归一化网络
3.2 Batch-Normalized Convolutional Networks
3.2 批归一化的卷积网络
Batch Normalization can be applied to any set of activations in the network. Here, we focus on transforms that consist of an affine transformation followed by an element-wise nonlinearity:
批量归一化可以应用于网络中的任何激活集。 在这里,我们关注由仿射变换和逐元素非线性组成的变换:
where and are learned parameters of the model, and is the nonlinearity such as sigmoid or ReLU. This formulation covers both fully-connected and convolutional layers. We add the BN transform immediately before the nonlinearity, by normalizing . We could have also normalized the layer inputs , but since is likely the output of another nonlinearity, the shape of its distribution is likely to change during training, and constraining its first and second moments would not eliminate the covariate shift. In contrast, is more likely to have a symmetric, non-sparse distribution, that is “more Gaussian” Hyvärinen & Oja 2000; normalizing it is likely to produce activations with a stable distribution.
其中和是模型的学习参数, 是非线性,例如 sigmoid 或 ReLU。 该公式涵盖了全连接层和卷积层。 我们通过归一化在非线性之前添加 BN 变换。 我们还可以对层输入进行归一化,但由于可能是另一个非线性的输出,因此其分布的形状在训练期间可能会发生变化,并且约束其一阶矩和二阶矩不会消除协变量偏移。 相比之下, 更有可能具有对称、非稀疏分布,即“更多高斯分布”Hyvärinen & Oja 2000; 对其进行标准化可能会产生具有稳定分布的激活。
Note that, since we normalize , the bias can be ignored since its effect will be canceled by the subsequent mean subtraction (the role of the bias is subsumed by in Alg. 1). Thus, is replaced with
请注意,由于我们对进行了归一化,因此可以忽略偏差 ,因为其影响将被随后的均值减法所抵消(偏差的作用被包含在算法 1 中的中)。 因此, 被替换为
where the BN transform is applied independently to each dimension of , with a separate pair of learned parameters , per dimension.
其中 BN 变换独立应用于的每个维度,每个维度都有一对单独的学习参数、。
For convolutional layers, we additionally want the normalization to obey the convolutional property – so that different elements of the same feature map, at different locations, are normalized in the same way. To achieve this, we jointly normalize all the activations in a mini-batch, over all locations. In Alg. 1, we let be the set of all values in a feature map across both the elements of a mini-batch and spatial locations – so for a mini-batch of size and feature maps of size , we use the effective mini-batch of size . We learn a pair of parameters and per feature map, rather than per activation. Alg. 2 is modified similarly, so that during inference the BN transform applies the same linear transformation to each activation in a given feature map.
对于卷积层,我们还希望标准化遵循卷积属性——以便同一特征图的不同元素在不同位置以相同的方式标准化。 为了实现这一目标,我们在所有位置联合标准化小批量中的所有激活。 在阿尔格. 1,我们让是跨小批量元素和空间位置的特征图中所有值的集合 - 因此对于大小为的小批量和大小为的特征图,我们使用大小为的有效小批量。 我们为每个特征图(而不是每个激活)学习一对参数和 。 藻类。 对 2 进行类似修改,以便在推理过程中 BN 变换对给定特征图中的每个激活应用相同的线性变换。
3.3 Batch Normalization enables higher learning rates
3.3 批归一化支持更高学习率
In traditional deep networks, too-high learning rate may result in the gradients that explode or vanish, as well as getting stuck in poor local minima. Batch Normalization helps address these issues. By normalizing activations throughout the network, it prevents small changes to the parameters from amplifying into larger and suboptimal changes in activations in gradients; for instance, it prevents the training from getting stuck in the saturated regimes of nonlinearities.
在传统的深度网络中,过高的学习率可能会导致梯度爆炸或消失,以及陷入不良的局部最小值。 批量归一化有助于解决这些问题。 通过标准化整个网络的激活,它可以防止参数的微小变化放大为梯度激活中较大的和次优的变化; 例如,它可以防止训练陷入非线性饱和状态。
Batch Normalization also makes training more resilient to the parameter scale. Normally, large learning rates may increase the scale of layer parameters, which then amplify the gradient during backpropagation and lead to the model explosion. However, with Batch Normalization, backpropagation through a layer is unaffected by the scale of its parameters. Indeed, for a scalar ,
批量归一化还使训练对参数规模更具弹性。 通常,大的学习率可能会增加层参数的规模,从而放大反向传播期间的梯度并导致模型爆炸。 然而,通过批量归一化,通过层的反向传播不受其参数规模的影响。 事实上,对于标量,
and we can show that
我们可以证明
The scale does not affect the layer Jacobian nor, consequently, the gradient propagation. Moreover, larger weights lead to smaller gradients, and Batch Normalization will stabilize the parameter growth.
比例不影响雅可比行列式,因此也不影响梯度传播。 此外,较大的权重会导致较小的梯度,而批量归一化将稳定参数增长。
We further conjecture that Batch Normalization may lead the layer Jacobians to have singular values close to 1, which is known to be beneficial for training Saxe et al. 2013. Consider two consecutive layers with normalized inputs, and the transformation between these normalized vectors: . If we assume that and are Gaussian and uncorrelated, and that is a linear transformation for the given model parameters, then both and have unit covariances, and . Thus, , and so all singular values of are equal to 1, which preserves the gradient magnitudes during backpropagation. In reality, the transformation is not linear, and the normalized values are not guaranteed to be Gaussian nor independent, but we nevertheless expect Batch Normalization to help make gradient propagation better behaved. The precise effect of Batch Normalization on gradient propagation remains an area of further study.
我们进一步推测批量归一化可能会导致雅可比行列式的奇异值接近 1,这对于训练 Saxe 等人来说是有益的。 2013. 考虑具有归一化输入的两个连续层,以及这些归一化向量之间的转换:。 如果我们假设和是高斯分布且不相关,并且是给定模型参数的线性变换,则和都具有单位协方差,并且。 因此,,以及的所有奇异值都等于 1,这在反向传播期间保留了梯度大小。 实际上,变换不是线性的,并且归一化值不能保证是高斯分布或独立的,但我们仍然期望批量归一化有助于使梯度传播表现更好。 批量归一化对梯度传播的精确影响仍然是进一步研究的领域。
3.4 Batch Normalization regularizes the model
3.4 批归一化正则化模型
When training with Batch Normalization, a training example is seen in conjunction with other examples in the mini-batch, and the training network no longer producing deterministic values for a given training example. In our experiments, we found this effect to be advantageous to the generalization of the network. Whereas Dropout Srivastava et al. 2014 is typically used to reduce overfitting, in a batch-normalized network we found that it can be either removed or reduced in strength.
当使用批量归一化进行训练时,训练示例与小批量中的其他示例一起出现,并且训练网络不再为给定的训练示例生成确定性值。 在我们的实验中,我们发现这种效应有利于网络的泛化。 而 Dropout Srivastava 等人。 2014 通常用于减少过度拟合,在批量归一化网络中,我们发现它可以被删除或降低强度。
4 Experiments
4 实验
4.1 Activations over time
4.1 激活随时间的演变
To verify the effects of internal covariate shift on training, and the ability of Batch Normalization to combat it, we considered the problem of predicting the digit class on the MNIST dataset LeCun et al. 1998a. We used a very simple network, with a 28x28 binary image as input, and 3 fully-connected hidden layers with 100 activations each. Each hidden layer computes with sigmoid nonlinearity, and the weights initialized to small random Gaussian values. The last hidden layer is followed by a fully-connected layer with 10 activations (one per class) and cross-entropy loss. We trained the network for 50000 steps, with 60 examples per mini-batch. We added Batch Normalization to each hidden layer of the network, as in Sec. 3.1. We were interested in the comparison between the baseline and batch-normalized networks, rather than achieving the state of the art performance on MNIST (which the described architecture does not).
为了验证内部协变量偏移对训练的影响以及批量归一化对抗它的能力,我们考虑了在 MNIST 数据集 LeCun 等人上预测数字类别的问题。 1998a. 我们使用了一个非常简单的网络,以 28x28 的二值图像作为输入,以及 3 个全连接的隐藏层,每个隐藏层有 100 次激活。 每个隐藏层使用 sigmoid 非线性计算 ,权重初始化为小的随机高斯值。 最后一个隐藏层后面是一个全连接层,具有 10 个激活(每个类一个)和交叉熵损失。 我们对网络进行了 50000 个步骤的训练,每个小批量有 60 个示例。 我们将批量归一化添加到网络的每个隐藏层,如第 2 节中所示。 3.1. 我们感兴趣的是基线网络和批量归一化网络之间的比较,而不是在 MNIST 上实现最先进的性能(所描述的架构没有做到这一点)。
| (a) | (b) Without BN | (c) With BN |
Figure 1: (a) The test accuracy of the MNIST network trained with and without Batch Normalization, vs. the number of training steps. Batch Normalization helps the network train faster and achieve higher accuracy. (b, c) The evolution of input distributions to a typical sigmoid, over the course of training, shown as th percentiles. Batch Normalization makes the distribution more stable and reduces the internal covariate shift.
| (a) | (b) 没有国阵 | (c) 与国阵 |
图 1:(a) 使用和不使用批量归一化训练的 MNIST 网络的测试准确性与训练步骤数的关系。 批量归一化有助于网络更快地训练并实现更高的准确性。 (b, c) 在训练过程中,输入分布向典型 sigmoid 的演变,显示为th 百分位数。 批量归一化使分布更加稳定并减少内部协变量偏移。
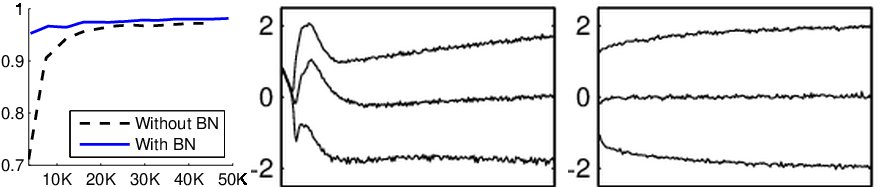
Figure 1(a) shows the fraction of correct predictions by the two networks on held-out test data, as training progresses. The batch-normalized network enjoys the higher test accuracy. To investigate why, we studied inputs to the sigmoid, in the original network N and batch-normalized network (Alg. 2) over the course of training. In Fig. 1(b,c) we show, for one typical activation from the last hidden layer of each network, how its distribution evolves. The distributions in the original network change significantly over time, both in their mean and the variance, which complicates the training of the subsequent layers. In contrast, the distributions in the batch-normalized network are much more stable as training progresses, which aids the training.
图 1(a) 显示了随着训练的进行,两个网络对保留测试数据的正确预测的比例。 批量归一化网络具有更高的测试精度。 为了探究原因,我们在训练过程中研究了原始网络 N 和批量归一化网络 (算法 2)中 sigmoid 的输入。 在图 1(b,c) 中,我们展示了每个网络最后一个隐藏层的一个典型激活,其分布如何演变。 原始网络中的分布随着时间的推移,其均值和方差都会发生显着变化,这使得后续层的训练变得复杂。 相比之下,随着训练的进行,批量归一化网络中的分布更加稳定,这有助于训练。
4.2 ImageNet classification
4.2 ImageNet 分类
We applied Batch Normalization to a new variant of the Inception network Szegedy et al. 2014, trained on the ImageNet classification task Russakovsky et al. 2014. The network has a large number of convolutional and pooling layers, with a softmax layer to predict the image class, out of 1000 possibilities. Convolutional layers use ReLU as the nonlinearity. The main difference to the network described in Szegedy et al. 2014 is that the convolutional layers are replaced by two consecutive layers of convolutions with up to filters. The network contains parameters, and, other than the top softmax layer, has no fully-connected layers. More details are given in the Appendix. We refer to this model as Inception in the rest of the text. The model was trained using a version of Stochastic Gradient Descent with momentum Sutskever et al. 2013, using the mini-batch size of 32. The training was performed using a large-scale, distributed architecture (similar to Dean et al. 2012). All networks are evaluated as training progresses by computing the validation accuracy , i.e. the probability of predicting the correct label out of 1000 possibilities, on a held-out set, using a single crop per image.
我们将批量归一化应用于 Inception 网络的新变体 Szegedy 等人。 2014 年,接受了 ImageNet 分类任务 Russakovsky 等人的训练。 2014年。该网络有大量的卷积层和池化层,并有一个softmax层来预测图像类别,有1000种可能性。 卷积层使用 ReLU 作为非线性。 与 Szegedy 等人描述的网络的主要区别 2014 年, 卷积层被两个连续的卷积层以及最多滤波器所取代。 该网络包含参数,并且除了顶层 softmax 层之外,没有全连接层。 附录中给出了更多详细信息。 在本文的其余部分中,我们将此模型称为 Inception。 该模型使用带有动量的随机梯度下降版本进行训练 Sutskever 等人。 2013 年,使用小批量大小 32。训练是使用大规模分布式架构进行的(类似于 Dean 等人,2012 年)。 随着训练的进展,所有网络都通过计算验证精度进行评估,即在保留集上,使用每个图像的单个裁剪,从 1000 种可能性中预测正确标签的概率。
| Model | Steps to 72.2% | Max accuracy |
|---|---|---|
| Inception | 72.2% | |
| BN-Baseline | 72.7% | |
| BN-x5 | 73.0% | |
| BN-x30 | 74.8% | |
| BN-x5-Sigmoid | 69.8% |
Figure 2: Single crop validation accuracy of Inception and its batch-normalized variants, vs. the number of training steps.
| 模型 | 达到 72.2% 的步数 |
| --- | --- |
| Inception | |
| BN-Baseline | |
| BN-x5 | |
| BN-x30 | |
| BN-x5-Sigmoid |
图 2:Inception 及其批归一化变体在 ImageNet 验证集上的单裁准确率。
In our experiments, we evaluated several modifications of Inception with Batch Normalization. In all cases, Batch Normalization was applied to the input of each nonlinearity, in a convolutional way, as described in section 3.2, while keeping the rest of the architecture constant.
在我们的实验中,我们评估了批标准化对 Inception 的几种修改。 在所有情况下,批量归一化都以卷积方式应用于每个非线性的输入,如第 3.2 节所述,同时保持架构的其余部分不变。
4.2.1 Accelerating BN Networks
Simply adding Batch Normalization to a network does not take full advantage of our method. To do so, we further changed the network and its training parameters, as follows:
4.2.1 加速BN网络
简单地将批量归一化添加到网络中并不能充分利用我们的方法。 为此,我们进一步更改了网络及其训练参数,如下:
Increase learning rate. In a batch-normalized model, we have been able to achieve a training speedup from higher learning rates, with no ill side effects (Sec. 3.3).
*提高学习率。*在批量归一化模型中,我们已经能够通过更高的学习率实现训练加速,并且没有不良副作用(第 3.3 节)。
Remove Dropout. As described in Sec. 3.4, Batch Normalization fulfills some of the same goals as Dropout. Removing Dropout from Modified BN-Inception speeds up training, without increasing overfitting.
删除 Dropout。 如第 2 节所述。 3.4、批归一化(批归一化) 实现了一些与 Dropout 相同的目标。 从 Modified BN-Inception 中删除 Dropout 可加快训练速度,而不会增加过度拟合。
Reduce the weight regularization. While in Inception an loss on the model parameters controls overfitting, in Modified BN-Inception the weight of this loss is reduced by a factor of 5. We find that this improves the accuracy on the held-out validation data.
*减少权重正则化。*虽然在 Inception 中模型参数上的损失控制了过度拟合,但在 Modified BN-Inception 中,该损失的权重减少了 5 倍。我们发现这提高了保留验证数据的准确性。
Accelerate the learning rate decay. In training Inception, learning rate was decayed exponentially. Because our network trains faster than Inception, we lower the learning rate 6 times faster.
*加速学习率衰减。*在训练Inception时,学习率呈指数衰减。 因为我们的网络训练速度比 Inception 快,所以我们将学习率降低了 6 倍。
Remove Local Response Normalization While Inception and other networks Srivastava et al. 2014 benefit from it, we found that with Batch Normalization it is not necessary.
删除本地响应标准化 而 Inception 和其他网络 Srivastava 等人。 2014年受益于此,我们发现使用批归一化(批归一化)就没有必要了。
Shuffle training examples more thoroughly. We enabled within-shard shuffling of the training data, which prevents the same examples from always appearing in a mini-batch together. This led to about 1% improvements in the validation accuracy, which is consistent with the view of Batch Normalization as a regularizer (Sec. 3.4): the randomization inherent in our method should be most beneficial when it affects an example differently each time it is seen.
*更彻底地洗牌训练示例。*我们启用了训练数据的分片内洗牌,这可以防止相同的示例始终一起出现在小批量中。 这导致验证准确性提高了约 1%,这与批量归一化作为正则化器的观点一致(第 3.4 节):当我们的方法中固有的随机化每次对示例产生不同的影响时,它应该是最有益的。
Reduce the photometric distortions. Because batch-normalized networks train faster and observe each training example fewer times, we let the trainer focus on more “real” images by distorting them less.
*减少光度失真。*因为批量归一化网络训练速度更快,并且观察每个训练示例的次数更少,所以我们让训练者通过减少扭曲来专注于更“真实”的图像。
4.2.2 Single-Network Classification
We evaluated the following networks, all trained on the LSVRC2012 training data, and tested on the validation data:
4.2.2 单网络分类
我们评估了以下网络,所有网络均在 LSVRC2012 训练数据上进行训练,并在验证数据上进行测试:
Inception: the network described at the beginning of Section 4.2, trained with the initial learning rate of 0.0015.
Inception:4.2 节开头描述的网络,以 0.0015 的初始学习率进行训练。
BN-Baseline: Same as Inception with Batch Normalization before each nonlinearity.
BN-Baseline:与每个非线性之前进行批量归一化的 Inception 相同。
BN-x5: Inception with Batch Normalization and the modifications in Sec. 4.2.1. The initial learning rate was increased by a factor of 5, to 0.0075. The same learning rate increase with original Inception caused the model parameters to reach machine infinity.
BN-x5:批量归一化的初始以及第 2 节中的修改。 4.2.1. 初始学习率增加了 5 倍,达到 0.0075。 与原始 Inception 相同的学习率增加导致模型参数达到机器无穷大。
BN-x30: Like BN-x5, but with the initial learning rate 0.045 (30 times that of Inception).
BN-x30:与BN-x5类似,但初始学习率为0.045(Inception的30倍)。
BN-x5-Sigmoid: Like BN-x5, but with sigmoid nonlinearity instead of ReLU. We also attempted to train the original Inception with sigmoid, but the model remained at the accuracy equivalent to chance.
BN-x5-Sigmoid:与 BN-x5 类似,但具有 sigmoid 非线性而不是 ReLU。 我们还尝试用 sigmoid 训练原始的 Inception,但模型的准确度仍然与机会相当。
In Figure 3, we show the validation accuracy of the networks, as a function of the number of training steps. Inception reached the accuracy of 72.2% after training steps. The Figure 3 shows, for each network, the number of training steps required to reach the same 72.2% accuracy, as well as the maximum validation accuracy reached by the network and the number of steps to reach it.
在图 3 中,我们显示了网络的验证准确性,作为训练步骤数的函数。 经过训练步骤后,Inception 的准确率达到了 72.2%。 图 3 显示了每个网络达到相同 72.2% 准确度所需的训练步骤数,以及网络达到的最大验证准确度和达到该准确度的步骤数。
By only using Batch Normalization (BN-Baseline), we match the accuracy of Inception in less than half the number of training steps. By applying the modifications in Sec. 4.2.1, we significantly increase the training speed of the network. BN-x5 needs 14 times fewer steps than Inception to reach the 72.2% accuracy. Interestingly, increasing the learning rate further (BN-x30) causes the model to train somewhat slower initially, but allows it to reach a higher final accuracy. It reaches 74.8% after steps, i.e. 5 times fewer steps than required by Inception to reach 72.2%.
仅使用批归一化(BN-Baseline),我们就能在不到一半的训练步数内达到 Inception 的精度。再应用 4.2.1 节的修改后,网络训练速度显著提高。BN-x5 达到 72.2% 精度所需步数约为 Inception 的 1/14。有趣的是,把学习率再提高(BN-x30)并未带来同等的进一步加速,但最终精度更高。
We also verified that the reduction in internal covariate shift allows deep networks with Batch Normalization to be trained when sigmoid is used as the nonlinearity, despite the well-known difficulty of training such networks. Indeed, BN-x5-Sigmoid achieves the accuracy of 69.8%. Without Batch Normalization, Inception with sigmoid never achieves better than accuracy.
我们还验证了,当使用 sigmoid 作为非线性时,内部协变量偏移的减少允许训练具有批量归一化的深度网络,尽管训练此类网络存在众所周知的困难。 事实上,BN-x5-Sigmoid 的准确率达到了 69.8%。 如果没有批量归一化,使用 sigmoid 的 Inception 永远不会达到比更好的精度。
4.2.3 Ensemble Classification
| Model | Resolution | Crops | Models | Top-1 error | Top-5 error |
|---|---|---|---|---|---|
| GoogLeNet ensemble | 224 | 144 | 7 | - | 6.67% |
| Deep Image low-res | 256 | - | 1 | - | 7.96% |
| Deep Image high-res | 512 | - | 1 | 24.88 | 7.42% |
| Deep Image ensemble | variable | - | - | - | 5.98% |
| BN-Inception single crop | 224 | 1 | 1 | 25.2% | 7.82% |
| BN-Inception multicrop | 224 | 144 | 1 | 21.99% | 5.82% |
| BN-Inception ensemble | 224 | 144 | 6 | 20.1% | 4.9%* |
Figure 4: *Batch-Normalized Inception comparison with previous state of the art on the provided validation set comprising 50000 images. BN-Inception ensemble has reached 4.82% top-5 error on the 100000 images of the test set of the ImageNet as reported by the test server.
| 模型 | 分辨率 | 裁剪数 | 模型数 | Top-1 错误 | Top-5 错误 |
|---|---|---|---|---|---|
| GoogLeNet 集成 | 224 | 144 | 7 | - | 6.67% |
| Deep Image 低分辨率 | 256 | - | 1 | - | 7.96% |
| Deep Image 高分辨率 | 512 | - | 1 | 24.88 | 7.42% |
| Deep Image 集成 | 可变 | - | - | - | 5.98% |
| BN-Inception 集成 | 224 | 144 | 6 | 20.1 | 4.9% |
表:ImageNet 分类结果对照(摘录)。
The current reported best results on the ImageNet Large Scale Visual Recognition Competition are reached by the Deep Image ensemble of traditional models Wu et al. 2015 and the ensemble model of He et al. 2015. The latter reports the top-5 error of 4.94%, as evaluated by the ILSVRC server. Here we report a top-5 validation error of 4.9%, and test error of 4.82% (according to the ILSVRC server). This improves upon the previous best result, and exceeds the estimated accuracy of human raters according to Russakovsky et al. 2014.
目前在 ImageNet 大规模视觉识别竞赛中报告的最佳成绩是由传统模型 Wu 等人的深度图像集成获得的。 2015 和 He 等人的集成模型。 2015 年。根据 ILSVRC 服务器的评估,后者报告 top-5 错误为 4.94%。 在这里,我们报告的 top-5 验证错误为 4.9%,测试错误为 4.82%(根据 ILSVRC 服务器)。 根据 Russakovsky 等人的说法,这改进了之前的最佳结果,并超过了人类评估者的估计准确性。 2014年。
For our ensemble, we used 6 networks. Each was based on BN-x30, modified via some of the following: increased initial weights in the convolutional layers; using Dropout (with the Dropout probability of 5% or 10%, vs. 40% for the original Inception); and using non-convolutional, per-activation Batch Normalization with last hidden layers of the model. Each network achieved its maximum accuracy after about training steps. The ensemble prediction was based on the arithmetic average of class probabilities predicted by the constituent networks. The details of ensemble and multicrop inference are similar to Szegedy et al. 2014.
对于我们的集成,我们使用了 6 个网络。 每个都基于 BN-x30,并通过以下一些修改:增加了卷积层中的初始权重; 使用 Dropout(Dropout 概率为 5% 或 10%,而原始 Inception 的 Dropout 概率为 40%); 并对模型的最后隐藏层使用非卷积、每次激活批量归一化。 每个网络在大约训练步骤后达到了最大准确度。 整体预测基于组成网络预测的类别概率的算术平均值。 集成和多作物推理的细节与 Szegedy 等人类似。 2014年。
We demonstrate in Fig. 4 that batch normalization allows us to set new state-of-the-art by a healthy margin on the ImageNet classification challenge benchmarks.
我们在图 4 中证明,批量归一化使我们能够在 ImageNet 分类挑战基准上以良好的裕度设定新的最先进技术。
5 Conclusion
5 结论
We have presented a novel mechanism for dramatically accelerating the training of deep networks. It is based on the premise that covariate shift, which is known to complicate the training of machine learning systems, also applies to sub-networks and layers, and removing it from internal activations of the network may aid in training. Our proposed method draws its power from normalizing activations, and from incorporating this normalization in the network architecture itself. This ensures that the normalization is appropriately handled by any optimization method that is being used to train the network. To enable stochastic optimization methods commonly used in deep network training, we perform the normalization for each mini-batch, and backpropagate the gradients through the normalization parameters. Batch Normalization adds only two extra parameters per activation, and in doing so preserves the representation ability of the network. We presented an algorithm for constructing, training, and performing inference with batch-normalized networks. The resulting networks can be trained with saturating nonlinearities, are more tolerant to increased training rates, and often do not require Dropout for regularization.
我们提出了一种显着加速深度网络训练的新颖机制。 它基于这样一个前提:协变量偏移(已知会使机器学习系统的训练变得复杂)也适用于子网络和层,并且将其从网络的内部激活中删除可能有助于训练。 我们提出的方法从标准化激活中汲取力量,并将这种标准化纳入网络架构本身。 这确保了用于训练网络的任何优化方法都能正确处理归一化。 为了启用深度网络训练中常用的随机优化方法,我们对每个小批量进行归一化,并通过归一化参数反向传播梯度。 批量归一化每次激活仅添加两个额外参数,这样做保留了网络的表示能力。 我们提出了一种使用批量归一化网络构建、训练和执行推理的算法。 由此产生的网络可以用饱和非线性进行训练,更能容忍增加的训练率,并且通常不需要 Dropout 进行正则化。
Merely adding Batch Normalization to a state-of-the-art image classification model yields a substantial speedup in training. By further increasing the learning rates, removing Dropout, and applying other modifications afforded by Batch Normalization, we reach the previous state of the art with only a small fraction of training steps – and then beat the state of the art in single-network image classification. Furthermore, by combining multiple models trained with Batch Normalization, we perform better than the best known system on ImageNet, by a significant margin.
仅仅将批量归一化添加到最先进的图像分类模型中就可以显着提高训练速度。 通过进一步提高学习率、消除 Dropout 以及应用批归一化提供的其他修改,我们仅用一小部分训练步骤就达到了之前的最先进水平,然后在单网络图像分类中击败了最先进技术。 此外,通过结合使用 批归一化(批归一化) 训练的多个模型,我们的表现比 ImageNet 上最知名的系统要好很多。
Interestingly, our method bears similarity to the standardization layer of Gülçehre & Bengio 2013, though the two methods stem from very different goals, and perform different tasks. The goal of Batch Normalization is to achieve a stable distribution of activation values throughout training, and in our experiments we apply it before the nonlinearity since that is where matching the first and second moments is more likely to result in a stable distribution. On the contrary, Gülçehre & Bengio 2013 apply the standardization layer to the output of the nonlinearity, which results in sparser activations. In our large-scale image classification experiments, we have not observed the nonlinearity inputs to be sparse, neither with nor without Batch Normalization. Other notable differentiating characteristics of Batch Normalization include the learned scale and shift that allow the BN transform to represent identity (the standardization layer did not require this since it was followed by the learned linear transform that, conceptually, absorbs the necessary scale and shift), handling of convolutional layers, deterministic inference that does not depend on the mini-batch, and batch-normalizing each convolutional layer in the network.
有趣的是,我们的方法与 Gülçehre & Bengio 2013 的标准化层相似,尽管这两种方法源于非常不同的目标,并执行不同的任务。 批量归一化的目标是在整个训练过程中实现激活值的稳定分布,在我们的实验中,我们在非线性之前应用它,因为这是匹配一阶矩和二阶矩更有可能产生稳定分布的地方。 相反,Gülçehre & Bengio 2013 将标准化层应用于非线性的“输出”,从而导致激活更加稀疏。 在我们的大规模图像分类实验中,无论是否使用批量归一化,我们都没有观察到非线性输入稀疏。 批量归一化的其他显着差异化特征包括允许 BN 变换表示身份的学习尺度和移位(标准化层不需要这一点,因为它后面是学习的线性变换,从概念上讲,吸收了必要的尺度和移位)、卷积层的处理、不依赖于小批量的确定性推理,以及对网络中的每个卷积层进行批量归一化。
In this work, we have not explored the full range of possibilities that Batch Normalization potentially enables. Our future work includes applications of our method to Recurrent Neural Networks Pascanu et al. 2013, where the internal covariate shift and the vanishing or exploding gradients may be especially severe, and which would allow us to more thoroughly test the hypothesis that normalization improves gradient propagation (Sec. 3.3). We plan to investigate whether Batch Normalization can help with domain adaptation, in its traditional sense – i.e. whether the normalization performed by the network would allow it to more easily generalize to new data distributions, perhaps with just a recomputation of the population means and variances (Alg. 2). Finally, we believe that further theoretical analysis of the algorithm would allow still more improvements and applications.
在这项工作中,我们尚未探索批归一化可能实现的全部可能性。 我们未来的工作包括将我们的方法应用于循环神经网络 Pascanu 等人。 2013 年,内部协变量偏移和梯度消失或爆炸可能特别严重,这将使我们能够更彻底地检验归一化改善梯度传播的假设(第 3.3 节)。 我们计划研究批量归一化是否有助于传统意义上的领域适应,即网络执行的归一化是否可以使其更轻松地推广到新的数据分布,也许只需重新计算总体均值和方差(算法 2)。 最后,我们相信对该算法的进一步理论分析将带来更多的改进和应用。
References
参考文献
Bengio & Glorot (2010) Bengio, Yoshua and Glorot, Xavier. Understanding the difficulty of training deep feedforward neural networks. In Proceedings of AISTATS 2010 , volume 9, pp. 249–256, May 2010.
Dean et al. (2012) Dean, Jeffrey, Corrado, Greg S., Monga, Rajat, Chen, Kai, Devin, Matthieu, Le, Quoc V., Mao, Mark Z., Ranzato, Marc’Aurelio, Senior, Andrew, Tucker, Paul, Yang, Ke, and Ng, Andrew Y. Large scale distributed deep networks. In NIPS , 2012.
(3) Desjardins, Guillaume and Kavukcuoglu, Koray. Natural neural networks. (unpublished).
Duchi et al. (2011) Duchi, John, Hazan, Elad, and Singer, Yoram. Adaptive subgradient methods for online learning and stochastic optimization. J. Mach. Learn. Res. , 12:2121–2159, July 2011. ISSN 1532-4435.
Gülçehre & Bengio (2013) Gülçehre, Çaglar and Bengio, Yoshua. Knowledge matters: Importance of prior information for optimization. CoRR , abs/1301.4083, 2013.
He et al. (2015) He, K., Zhang, X., Ren, S., and Sun, J. Delving Deep into Rectifiers: Surpassing Human-Level Performance on ImageNet Classification. ArXiv e-prints , February 2015.
Hyvärinen & Oja (2000) Hyvärinen, A. and Oja, E. Independent component analysis: Algorithms and applications. Neural Netw. , 13(4-5):411–430, May 2000.
Jiang (2008) Jiang, Jing. A literature survey on domain adaptation of statistical classifiers, 2008.
LeCun et al. (1998a) LeCun, Y., Bottou, L., Bengio, Y., and Haffner, P. Gradient-based learning applied to document recognition. Proceedings of the IEEE , 86(11):2278–2324, November 1998a.
LeCun et al. (1998b) LeCun, Y., Bottou, L., Orr, G., and Muller, K. Efficient backprop. In Orr, G. and K., Muller (eds.), Neural Networks: Tricks of the trade . Springer, 1998b.
Lyu & Simoncelli (2008) Lyu, S and Simoncelli, E P. Nonlinear image representation using divisive normalization. In Proc. Computer Vision and Pattern Recognition , pp. 1–8. IEEE Computer Society, Jun 23-28 2008. doi: 10.1109/CVPR.2008.4587821 .
Nair & Hinton (2010) Nair, Vinod and Hinton, Geoffrey E. Rectified linear units improve restricted boltzmann machines. In ICML , pp. 807–814. Omnipress, 2010.
Pascanu et al. (2013) Pascanu, Razvan, Mikolov, Tomas, and Bengio, Yoshua. On the difficulty of training recurrent neural networks. In Proceedings of the 30th International Conference on Machine Learning, ICML 2013, Atlanta, GA, USA, 16-21 June 2013 , pp. 1310–1318, 2013.
Povey et al. (2014) Povey, Daniel, Zhang, Xiaohui, and Khudanpur, Sanjeev. Parallel training of deep neural networks with natural gradient and parameter averaging. CoRR , abs/1410.7455, 2014.
Raiko et al. (2012) Raiko, Tapani, Valpola, Harri, and LeCun, Yann. Deep learning made easier by linear transformations in perceptrons. In International Conference on Artificial Intelligence and Statistics (AISTATS) , pp. 924–932, 2012.
Russakovsky et al. (2014) Russakovsky, Olga, Deng, Jia, Su, Hao, Krause, Jonathan, Satheesh, Sanjeev, Ma, Sean, Huang, Zhiheng, Karpathy, Andrej, Khosla, Aditya, Bernstein, Michael, Berg, Alexander C., and Fei-Fei, Li. ImageNet Large Scale Visual Recognition Challenge, 2014.
Saxe et al. (2013) Saxe, Andrew M., McClelland, James L., and Ganguli, Surya. Exact solutions to the nonlinear dynamics of learning in deep linear neural networks. CoRR , abs/1312.6120, 2013.
Shimodaira (2000) Shimodaira, Hidetoshi. Improving predictive inference under covariate shift by weighting the log-likelihood function. Journal of Statistical Planning and Inference , 90(2):227–244, October 2000.
Srivastava et al. (2014) Srivastava, Nitish, Hinton, Geoffrey, Krizhevsky, Alex, Sutskever, Ilya, and Salakhutdinov, Ruslan. Dropout: A simple way to prevent neural networks from overfitting. J. Mach. Learn. Res. , 15(1):1929–1958, January 2014.
Sutskever et al. (2013) Sutskever, Ilya, Martens, James, Dahl, George E., and Hinton, Geoffrey E. On the importance of initialization and momentum in deep learning. In ICML (3) , volume 28 of JMLR Proceedings , pp. 1139–1147. JMLR.org, 2013.
Szegedy et al. (2014) Szegedy, Christian, Liu, Wei, Jia, Yangqing, Sermanet, Pierre, Reed, Scott, Anguelov, Dragomir, Erhan, Dumitru, Vanhoucke, Vincent, and Rabinovich, Andrew. Going deeper with convolutions. CoRR , abs/1409.4842, 2014.
Wiesler & Ney (2011) Wiesler, Simon and Ney, Hermann. A convergence analysis of log-linear training. In Shawe-Taylor, J., Zemel, R.S., Bartlett, P., Pereira, F.C.N., and Weinberger, K.Q. (eds.), Advances in Neural Information Processing Systems 24 , pp. 657–665, Granada, Spain, December 2011.
Wiesler et al. (2014) Wiesler, Simon, Richard, Alexander, Schlüter, Ralf, and Ney, Hermann. Mean-normalized stochastic gradient for large-scale deep learning. In IEEE International Conference on Acoustics, Speech, and Signal Processing , pp. 180–184, Florence, Italy, May 2014.
Wu et al. (2015) Wu, Ren, Yan, Shengen, Shan, Yi, Dang, Qingqing, and Sun, Gang. Deep image: Scaling up image recognition, 2015.
Appendix
附录
Variant of the Inception Model Used
所用 Inception 模型的变体
| type | patch size/ stride | output size | depth | reduce | double reduce | double | Pool +proj | ||
|---|---|---|---|---|---|---|---|---|---|
| convolution* | 1 | ||||||||
| max pool | 0 | ||||||||
| convolution | 1 | 64 | 192 | ||||||
| max pool | 0 | ||||||||
| inception (3a) | 3 | 64 | 64 | 64 | 64 | 96 | avg + 32 | ||
| inception (3b) | 3 | 64 | 64 | 96 | 64 | 96 | avg + 64 | ||
| inception (3c) | stride 2 | 3 | 0 | 128 | 160 | 64 | 96 | max + pass through | |
| inception (4a) | 3 | 224 | 64 | 96 | 96 | 128 | avg + 128 | ||
| inception (4b) | 3 | 192 | 96 | 128 | 96 | 128 | avg + 128 | ||
| inception (4c) | 3 | 160 | 128 | 160 | 128 | 160 | avg + 128 | ||
| inception (4d) | 3 | 96 | 128 | 192 | 160 | 192 | avg + 128 | ||
| inception (4e) | stride 2 | 3 | 0 | 128 | 192 | 192 | 256 | max + pass through | |
| inception (5a) | 3 | 352 | 192 | 320 | 160 | 224 | avg + 128 | ||
| inception (5b) | 3 | 352 | 192 | 320 | 192 | 224 | max + 128 | ||
| avg pool | 0 |
Figure 5: Inception architecture
| 类型 | 补丁大小/ 步幅 | 输出 尺寸 | 深度 | 减少 | 双 减少 | 双 | 池+项目 | ||
|---|---|---|---|---|---|---|---|---|---|
| 卷积* | 1 | ||||||||
| 最大池 | 0 | ||||||||
| 卷积 | 1 | 64 | 192 | ||||||
| 最大池 | 0 | ||||||||
| 起始(3a) | 3 | 64 | 64 | 64 | 64 | 96 | 平均+32 | ||
| 起始 (3b) | 3 | 64 | 64 | 96 | 64 | 96 | 平均+64 | ||
| 起始 (3c) | 步幅 2 | 3 | 0 | 128 | 160 | 64 | 96 | 最大+通过 | |
| 起始 (4a) | 3 | 224 | 64 | 96 | 96 | 128 | 平均+128 | ||
| 起始 (4b) | 3 | 192 | 96 | 128 | 96 | 128 | 平均+128 | ||
| 起始 (4c) | 3 | 160 | 128 | 160 | 128 | 160 | 平均+128 | ||
| 起始(4天) | 3 | 96 | 128 | 192 | 160 | 192 | 平均+128 | ||
| 起始 (4e) | 步幅 2 | 3 | 0 | 128 | 192 | 192 | 256 | 最大+通过 | |
| 起始(5a) | 3 | 352 | 192 | 320 | 160 | 224 | 平均+128 | ||
| 起始 (5b) | 3 | 352 | 192 | 320 | 192 | 224 | max + 128 | ||
| 平均池 | 0 |
图 5:Inception 架构
Figure 5 documents the changes that were performed compared to the architecture with respect to the GoogleNet archictecture. For the interpretation of this table, please consult Szegedy et al. 2014. The notable architecture changes compared to the GoogLeNet model include:
图 5 记录了与 GoogleNet 架构相比所执行的更改。 有关此表的解释,请咨询 Szegedy 等人。 2014 年。与 GoogLeNet 模型相比,显着的架构变化包括:
- • The 55 convolutional layers are replaced by two consecutive 33 convolutional layers. This increases the maximum depth of the network by 9 weight layers. Also it increases the number of parameters by 25% and the computational cost is increased by about 30%.
- • The number 2828 inception modules is increased from 2 to 3.
- • Inside the modules, sometimes average, sometimes maximum-pooling is employed. This is indicated in the entries corresponding to the pooling layers of the table.
- • There are no across the board pooling layers between any two Inception modules, but stride-2 convolution/pooling layers are employed before the filter concatenation in the modules 3c, 4e.
- • 5 个 5 卷积层被两个连续的33 卷积层替代。 这将网络的最大深度增加了 9 个权重层。 同时参数数量增加了25%,计算成本增加了约30%。
- • 2828 inception 模块的数量从 2 个增加到 3 个。
- • 在模块内部,有时采用平均池化,有时采用最大池化。 这在与表的池化层相对应的条目中指示。
- • 任何两个Inception 模块之间没有全面的池化层,但在模块3c、4e 中的过滤器串联之前采用了stride-2 卷积/池化层。
Our model employed separable convolution with depth multiplier on the first convolutional layer. This reduces the computational cost while increasing the memory consumption at training time.
我们的模型在第一个卷积层上采用了带有深度乘数的可分离卷积。 这降低了计算成本,同时增加了训练时的内存消耗。