Auto-Encoding Variational Bayes | AGIDaily
AGI Daily
资讯日报词条论文人物新创
返回论文列表
摘要1 引言2 方法2.1 问题设定2.2 变分下界2.3 SGVB 估计器与 AEVB 算法2.4 重参数化技巧3 示例:变分自编码器4 相关工作5 实验似然下界边际似然高维数据的可视化6 结论7 未来工作参考文献附录 A 可视化附录 B $-D{KL}(q{\boldsymbol{\phi}}(\mathbf{z})||p{\boldsymbol{\theta}}(\mathbf{z}))$ 的高斯情形解析解附录 C 作为概率编码器与解码器的 MLPC.1 Bernoulli MLP 作解码器C.2 高斯 MLP 作编码器或解码器附录 D 边际似然估计器附录 E 蒙特卡洛 EM附录 F 完全变分贝叶斯F.1 示例
返回论文列表
目录

Auto-Encoding Variational Bayes

收录于 ICLR 2014;arXiv:1312.6114被引 17,804 次
打开论文来源

Auto-Encoding Variational Bayes

自编码变分贝叶斯(Auto-Encoding Variational Bayes)

Diederik P. Kingma Affiliation:  Machine Learning Group Affiliation:  Universiteit van Amsterdam Email:  dpkingma@gmail.com    Max Welling Affiliation:  Machine Learning Group Affiliation:  Universiteit van Amsterdam Email:  welling.max@gmail.com

Diederik P. Kingma(隶属:Machine Learning Group,Universiteit van Amsterdam,邮箱:dpkingma@gmail.com)、Max Welling(隶属:Machine Learning Group,Universiteit van Amsterdam,邮箱:welling.max@gmail.com)

Abstract

摘要

How can we perform efficient inference and learning in directed probabilistic models, in the presence of continuous latent variables with intractable posterior distributions, and large datasets? We introduce a stochastic variational inference and learning algorithm that scales to large datasets and, under some mild differentiability conditions, even works in the intractable case. Our contributions are two-fold. First, we show that a reparameterization of the variational lower bound yields a lower bound estimator that can be straightforwardly optimized using standard stochastic gradient methods. Second, we show that for i.i.d. datasets with continuous latent variables per datapoint, posterior inference can be made especially efficient by fitting an approximate inference model (also called a recognition model) to the intractable posterior using the proposed lower bound estimator. Theoretical advantages are reflected in experimental results.

在存在连续隐变量、后验分布不可积以及大规模数据集的情况下,我们如何在有向概率模型中进行高效的推断与学习?我们提出一种随机变分推断与学习算法,该算法可扩展到大数据集,并且在一些温和的可微条件下,即便在不可积情形下也能工作。贡献有两点。第一,我们证明对变分下界做重参数化,可以得到一个可用标准随机梯度方法直接优化的下界估计器。第二,我们证明:对于每个数据点带有连续隐变量的 i.i.d. 数据集,用所提出的下界估计器去拟合一个逼近不可积后验的近似推断模型(也称识别模型),可以使后验推断特别高效。理论优势在实验结果中得到体现。

1 Introduction

1 引言

How can we perform efficient approximate inference and learning with directed probabilistic models whose continuous latent variables and/or parameters have intractable posterior distributions? The variational Bayesian (VB) approach involves the optimization of an approximation to the intractable posterior. Unfortunately, the common mean-field approach requires analytical solutions of expectations w.r.t. the approximate posterior, which are also intractable in the general case. We show how a reparameterization of the variational lower bound yields a simple differentiable unbiased estimator of the lower bound; this SGVB (Stochastic Gradient Variational Bayes) estimator can be used for efficient approximate posterior inference in almost any model with continuous latent variables and/or parameters, and is straightforward to optimize using standard stochastic gradient ascent techniques.

我们如何对连续隐变量和/或参数具有不可积后验分布的有向概率模型,进行高效的近似推断与学习?变分贝叶斯(VB)方法通过对不可积后验的近似进行优化。遗憾的是,常见的平均场方法需要就可近似后验解析地求出期望,这在一般情形下同样不可积。我们证明:对变分下界做重参数化,可以得到下界的一个简单、可微且无偏的估计器;该 SGVB(Stochastic Gradient Variational Bayes,随机梯度变分贝叶斯)估计器可用于几乎任何带连续隐变量和/或参数的模型中的高效近似后验推断,并可用标准随机梯度上升技术直接优化。

For the case of an i.i.d. dataset and continuous latent variables per datapoint, we propose the Auto-Encoding VB (AEVB) algorithm. In the AEVB algorithm we make inference and learning especially efficient by using the SGVB estimator to optimize a recognition model that allows us to perform very efficient approximate posterior inference using simple ancestral sampling, which in turn allows us to efficiently learn the model parameters, without the need of expensive iterative inference schemes (such as MCMC) per datapoint. The learned approximate posterior inference model can also be used for a host of tasks such as recognition, denoising, representation and visualization purposes. When a neural network is used for the recognition model, we arrive at the variational auto-encoder.

针对 i.i.d. 数据集且每个数据点带有连续隐变量的情形,我们提出自编码变分贝叶斯(Auto-Encoding VB,AEVB)算法。在 AEVB 中,我们用 SGVB 估计器优化识别模型,使推断与学习特别高效:该识别模型允许用简单的祖先采样做非常高效的近似后验推断,从而高效学习模型参数,而无需对每个数据点做昂贵的迭代推断(如 MCMC)。学到的近似后验推断模型还可用于识别、去噪、表示与可视化等任务。当识别模型采用神经网络时,我们就得到了变分自编码器。

2 Method

2 方法

The strategy in this section can be used to derive a lower bound estimator (a stochastic objective function) for a variety of directed graphical models with continuous latent variables. We will restrict ourselves here to the common case where we have an i.i.d. dataset with latent variables per datapoint, and where we like to perform maximum likelihood (ML) or maximum a posteriori (MAP) inference on the (global) parameters, and variational inference on the latent variables. It is, for example, straightforward to extend this scenario to the case where we also perform variational inference on the global parameters; that algorithm is put in the appendix, but experiments with that case are left to future work. Note that our method can be applied to online, non-stationary settings, e.g. streaming data, but here we assume a fixed dataset for simplicity.

本节的策略可用于为一类带连续隐变量的有向图模型推导下界估计器(随机目标函数)。我们在此限于常见情形:拥有每个数据点带隐变量的 i.i.d. 数据集,希望对(全局)参数做最大似然(ML)或最大后验(MAP)推断,并对隐变量做变分推断。例如,将其扩展到对全局参数也做变分推断是直接的;该算法放在附录中,相关实验留给未来工作。注意我们的方法可用于在线、非平稳设定(例如流式数据),但为简单起见这里假设数据集固定。
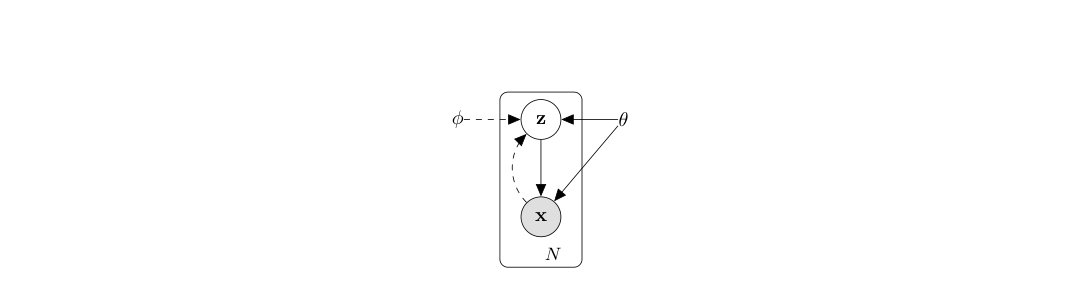
Figure 1

Figure 1: The type of directed graphical model under consideration. Solid lines denote the generative model pθ(z)pθ(x∣z)p_{\boldsymbol{\theta}}(\mathbf{z})p_{\boldsymbol{\theta}}(\mathbf{x}|\mathbf{z})pθ​(z)pθ​(x∣z), dashed lines denote the variational approximation qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x) to the intractable posterior pθ(z∣x)p_{\boldsymbol{\theta}}(\mathbf{z}|\mathbf{x})pθ​(z∣x). The variational parameters ϕ\boldsymbol{\phi}ϕ are learned jointly with the generative model parameters θ\boldsymbol{\theta}θ.

图 1:所考虑的有向图模型类型。实线表示生成模型 pθ(z)pθ(x∣z)p_{\boldsymbol{\theta}}(\mathbf{z})p_{\boldsymbol{\theta}}(\mathbf{x}|\mathbf{z})pθ​(z)pθ​(x∣z),虚线表示对不可积后验 pθ(z∣x)p_{\boldsymbol{\theta}}(\mathbf{z}|\mathbf{x})pθ​(z∣x) 的变分近似 qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x)。变分参数 ϕ\boldsymbol{\phi}ϕ 与生成模型参数 θ\boldsymbol{\theta}θ 联合学习。

2.1 Problem scenario

2.1 问题设定

Let us consider some dataset X={x(i)}i=1N\mathbf{X}=\{\mathbf{x}^{(i)}\}_{i=1}^{N}X={x(i)}i=1N​ consisting of NNN i.i.d. samples of some continuous or discrete variable x\mathbf{x}x. We assume that the data are generated by some random process, involving an unobserved continuous random variable z\mathbf{z}z. The process consists of two steps: (1) a value z(i)\mathbf{z}^{(i)}z(i) is generated from some prior distribution pθ∗(z)p_{\boldsymbol{\theta}^{*}}(\mathbf{z})pθ∗​(z); (2) a value x(i)\mathbf{x}^{(i)}x(i) is generated from some conditional distribution pθ∗(x∣z)p_{\boldsymbol{\theta}^{*}}(\mathbf{x}|\mathbf{z})pθ∗​(x∣z). We assume that the prior pθ∗(z)p_{\boldsymbol{\theta}^{*}}(\mathbf{z})pθ∗​(z) and likelihood pθ∗(x∣z)p_{\boldsymbol{\theta}^{*}}(\mathbf{x}|\mathbf{z})pθ∗​(x∣z) come from parametric families of distributions pθ(z)p_{\boldsymbol{\theta}}(\mathbf{z})pθ​(z) and pθ(x∣z)p_{\boldsymbol{\theta}}(\mathbf{x}|\mathbf{z})pθ​(x∣z), and that their PDFs are differentiable almost everywhere w.r.t. both θ\boldsymbol{\theta}θ and z\mathbf{z}z. Unfortunately, a lot of this process is hidden from our view: the true parameters θ∗\boldsymbol{\theta}^{*}θ∗ as well as the values of the latent variables z(i)\mathbf{z}^{(i)}z(i) are unknown to us.

考虑由连续或离散变量 x\mathbf{x}x 的 NNN 个 i.i.d. 样本组成的数据集 X={x(i)}i=1N\mathbf{X}=\{\mathbf{x}^{(i)}\}_{i=1}^{N}X={x(i)}i=1N​。我们假定数据由某个涉及未观测连续随机变量 z\mathbf{z}z 的随机过程生成。该过程分两步:(1) 从某先验分布 pθ∗(z)p_{\boldsymbol{\theta}^{*}}(\mathbf{z})pθ∗​(z) 生成值 z(i)\mathbf{z}^{(i)}z(i);(2) 从某条件分布 pθ∗(x∣z)p_{\boldsymbol{\theta}^{*}}(\mathbf{x}|\mathbf{z})pθ∗​(x∣z) 生成值 x(i)\mathbf{x}^{(i)}x(i)。我们假定先验 pθ∗(z)p_{\boldsymbol{\theta}^{*}}(\mathbf{z})pθ∗​(z) 与似然 pθ∗(x∣z)p_{\boldsymbol{\theta}^{*}}(\mathbf{x}|\mathbf{z})pθ∗​(x∣z) 来自参数族 pθ(z)p_{\boldsymbol{\theta}}(\mathbf{z})pθ​(z) 与 pθ(x∣z)p_{\boldsymbol{\theta}}(\mathbf{x}|\mathbf{z})pθ​(x∣z),且其概率密度函数几乎处处对 θ\boldsymbol{\theta}θ 与 z\mathbf{z}z 可微。遗憾的是,这一过程有许多对我们隐藏:真实参数 θ∗\boldsymbol{\theta}^{*}θ∗ 以及隐变量取值 z(i)\mathbf{z}^{(i)}z(i) 均未知。

Very importantly, we do not make the common simplifying assumptions about the marginal or posterior probabilities. Conversely, we are here interested in a general algorithm that even works efficiently in the case of:

非常重要的是,我们并不对边际或后验概率做常见的简化假设。相反,我们关心一种即便在下列情形下仍能高效工作的通用算法:

  1. Intractability: the case where the integral of the marginal likelihood pθ(x)=∫pθ(z)pθ(x∣z) dzp_{\boldsymbol{\theta}}(\mathbf{x})=\int p_{\boldsymbol{\theta}}(\mathbf{z})p_{\boldsymbol{\theta}}(\mathbf{x}|\mathbf{z})\,d\mathbf{z}pθ​(x)=∫pθ​(z)pθ​(x∣z)dz is intractable (so we cannot evaluate or differentiate the marginal likelihood), where the true posterior density pθ(z∣x)=pθ(x∣z)pθ(z)/pθ(x)p_{\boldsymbol{\theta}}(\mathbf{z}|\mathbf{x})=p_{\boldsymbol{\theta}}(\mathbf{x}|\mathbf{z})p_{\boldsymbol{\theta}}(\mathbf{z})/p_{\boldsymbol{\theta}}(\mathbf{x})pθ​(z∣x)=pθ​(x∣z)pθ​(z)/pθ​(x) is intractable (so the EM algorithm cannot be used), and where the required integrals for any reasonable mean-field VB algorithm are also intractable. These intractabilities are quite common and appear in cases of moderately complicated likelihood functions pθ(x∣z)p_{\boldsymbol{\theta}}(\mathbf{x}|\mathbf{z})pθ​(x∣z), e.g. a neural network with a nonlinear hidden layer.
  2. A large dataset: we have so much data that batch optimization is too costly; we would like to make parameter updates using small minibatches or even single datapoints. Sampling-based solutions, e.g. Monte Carlo EM, would in general be too slow, since it involves a typically expensive sampling loop per datapoint.
  1. 不可积性:边际似然 pθ(x)=∫pθ(z)pθ(x∣z) dzp_{\boldsymbol{\theta}}(\mathbf{x})=\int p_{\boldsymbol{\theta}}(\mathbf{z})p_{\boldsymbol{\theta}}(\mathbf{x}|\mathbf{z})\,d\mathbf{z}pθ​(x)=∫pθ​(z)pθ​(x∣z)dz 的积分不可积(因而无法评估或微分边际似然),真实后验密度 pθ(z∣x)=pθ(x∣z)pθ(z)/pθ(x)p_{\boldsymbol{\theta}}(\mathbf{z}|\mathbf{x})=p_{\boldsymbol{\theta}}(\mathbf{x}|\mathbf{z})p_{\boldsymbol{\theta}}(\mathbf{z})/p_{\boldsymbol{\theta}}(\mathbf{x})pθ​(z∣x)=pθ​(x∣z)pθ​(z)/pθ​(x) 不可积(因而无法使用 EM 算法),且任何合理平均场 VB 算法所需的积分也不可积。这类不可积性相当常见,出现在似然函数 pθ(x∣z)p_{\boldsymbol{\theta}}(\mathbf{x}|\mathbf{z})pθ​(x∣z) 适度复杂时,例如带非线性隐层的神经网络。
  2. 大规模数据集:数据量大会使批量优化代价过高;我们希望用小批量甚至单个数据点做参数更新。基于采样的方案(如蒙特卡洛 EM)通常过慢,因为每个数据点都涉及通常很昂贵的采样循环。

We are interested in, and propose a solution to, three related problems in the above scenario:

我们关心并针对上述情形提出对三个相关问题的解:

  1. Efficient approximate ML or MAP estimation for the parameters θ\boldsymbol{\theta}θ. The parameters can be of interest themselves, e.g. if we are analyzing some natural process. They also allow us to mimic the hidden random process and generate artificial data that resembles the real data.
  2. Efficient approximate posterior inference of the latent variable z\mathbf{z}z given an observed value x\mathbf{x}x for a choice of parameters θ\boldsymbol{\theta}θ. This is useful for coding or data representation tasks.
  3. Efficient approximate marginal inference of the variable x\mathbf{x}x. This allows us to perform all kinds of inference tasks where a prior over x\mathbf{x}x is required. Common applications in computer vision include image denoising, inpainting and super-resolution.
  1. 对参数 θ\boldsymbol{\theta}θ 的高效近似 ML 或 MAP 估计。参数本身可能有兴趣,例如我们在分析某个自然过程时;它们也允许我们模仿隐藏的随机过程并生成与真实数据相似的人工数据。
  2. 在选定参数 θ\boldsymbol{\theta}θ 时,给定观测 x\mathbf{x}x 对隐变量 z\mathbf{z}z 的高效近似后验推断。这对编码或数据表示任务有用。
  3. 对变量 x\mathbf{x}x 的高效近似边际推断。这使我们能完成各类需要 x\mathbf{x}x 上先验的推断任务。计算机视觉中的常见应用包括图像去噪、补全与超分辨率。

For the purpose of solving the above problems, let us introduce a recognition model qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x): an approximation to the intractable true posterior pθ(z∣x)p_{\boldsymbol{\theta}}(\mathbf{z}|\mathbf{x})pθ​(z∣x). Note that in contrast with the approximate posterior in mean-field variational inference, it is not necessarily factorial and its parameters ϕ\boldsymbol{\phi}ϕ are not computed from some closed-form expectation. Instead, we’ll introduce a method for learning the recognition model parameters ϕ\boldsymbol{\phi}ϕ jointly with the generative model parameters θ\boldsymbol{\theta}θ.

为解决上述问题,引入识别模型 qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x):对不可积真实后验 pθ(z∣x)p_{\boldsymbol{\theta}}(\mathbf{z}|\mathbf{x})pθ​(z∣x) 的近似。注意与平均场变分推断中的近似后验不同,它不必是因子化的,其参数 ϕ\boldsymbol{\phi}ϕ 也不是由某个闭式期望算出。相反,我们将引入一种把识别模型参数 ϕ\boldsymbol{\phi}ϕ 与生成模型参数 θ\boldsymbol{\theta}θ 联合学习的方法。

From a coding theory perspective, the unobserved variables z\mathbf{z}z have an interpretation as a latent representation or code. In this paper we will therefore also refer to the recognition model qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x) as a probabilistic encoder, since given a datapoint x\mathbf{x}x it produces a distribution (e.g. a Gaussian) over the possible values of the code z\mathbf{z}z from which the datapoint x\mathbf{x}x could have been generated. In a similar vein we will refer to pθ(x∣z)p_{\boldsymbol{\theta}}(\mathbf{x}|\mathbf{z})pθ​(x∣z) as a probabilistic decoder, since given a code z\mathbf{z}z it produces a distribution over the possible corresponding values of x\mathbf{x}x.

从编码理论角度看,未观测变量 z\mathbf{z}z 可解释为潜在表示或码。因此本文也把识别模型 qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x) 称为概率编码器:给定数据点 x\mathbf{x}x,它在可能生成该点的码 z\mathbf{z}z 上产出一个分布(例如高斯)。同理,我们把 pθ(x∣z)p_{\boldsymbol{\theta}}(\mathbf{x}|\mathbf{z})pθ​(x∣z) 称为概率解码器:给定码 z\mathbf{z}z,它在可能对应的 x\mathbf{x}x 值上产出一个分布。

2.2 The variational bound

2.2 变分下界

The marginal likelihood is composed of a sum over the marginal likelihoods of individual datapoints log⁡pθ(x(1),⋯ ,x(N))=∑i=1Nlog⁡pθ(x(i))\log p_{\boldsymbol{\theta}}(\mathbf{x}^{(1)},\cdots,\mathbf{x}^{(N)})=\sum_{i=1}^{N}\log p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)})logpθ​(x(1),⋯,x(N))=∑i=1N​logpθ​(x(i)), which can each be rewritten as:

边际似然由各数据点边际似然之和构成 log⁡pθ(x(1),⋯ ,x(N))=∑i=1Nlog⁡pθ(x(i))\log p_{\boldsymbol{\theta}}(\mathbf{x}^{(1)},\cdots,\mathbf{x}^{(N)})=\sum_{i=1}^{N}\log p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)})logpθ​(x(1),⋯,x(N))=∑i=1N​logpθ​(x(i)),每一个可改写为:

log⁡pθ(x(i))=DKL(qϕ(z∣x(i))∣∣pθ(z∣x(i)))+L(θ,ϕ;x(i))(1)\displaystyle\log p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)})=D_{KL}(q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x}^{(i)})||p_{\boldsymbol{\theta}}(\mathbf{z}|\mathbf{x}^{(i)}))+\mathcal{L}(\boldsymbol{\theta},\boldsymbol{\phi};\mathbf{x}^{(i)}) \tag{1}logpθ​(x(i))=DKL​(qϕ​(z∣x(i))∣∣pθ​(z∣x(i)))+L(θ,ϕ;x(i))(1)

The first RHS term is the KL divergence of the approximate from the true posterior. Since this KL-divergence is non-negative, the second RHS term L(θ,ϕ;x(i))\mathcal{L}(\boldsymbol{\theta},\boldsymbol{\phi};\mathbf{x}^{(i)})L(θ,ϕ;x(i)) is called the (variational) lower bound on the marginal likelihood of datapoint iii, and can be written as:

右边第一项是近似后验相对真实后验的 KL 散度。由于该 KL 散度非负,右边第二项 L(θ,ϕ;x(i))\mathcal{L}(\boldsymbol{\theta},\boldsymbol{\phi};\mathbf{x}^{(i)})L(θ,ϕ;x(i)) 称为数据点 iii 边际似然的(变分)下界,并可写成:

log⁡pθ(x(i))≥L(θ,ϕ;x(i))=Eqϕ(z∣x)[−log⁡qϕ(z∣x)+log⁡pθ(x,z)](2)\displaystyle\log p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)})\geq\mathcal{L}(\boldsymbol{\theta},\boldsymbol{\phi};\mathbf{x}^{(i)}) \\ \displaystyle=\mathbb{E}_{q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})}\left[-\log q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})+\log p_{\boldsymbol{\theta}}(\mathbf{x},\mathbf{z})\right] \tag{2}logpθ​(x(i))≥L(θ,ϕ;x(i))=Eqϕ​(z∣x)​[−logqϕ​(z∣x)+logpθ​(x,z)](2)

which can also be written as:

也可写成:

L(θ,ϕ;x(i))=−DKL(qϕ(z∣x(i))∣∣pθ(z))+Eqϕ(z∣x(i))[log⁡pθ(x(i)∣z)](3)\displaystyle\mathcal{L}(\boldsymbol{\theta},\boldsymbol{\phi};\mathbf{x}^{(i)})=-D_{KL}(q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x}^{(i)})||p_{\boldsymbol{\theta}}(\mathbf{z}))+\mathbb{E}_{q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x}^{(i)})}\left[\log p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)}|\mathbf{z})\right] \tag{3}L(θ,ϕ;x(i))=−DKL​(qϕ​(z∣x(i))∣∣pθ​(z))+Eqϕ​(z∣x(i))​[logpθ​(x(i)∣z)](3)

We want to differentiate and optimize the lower bound L(θ,ϕ;x(i))\mathcal{L}(\boldsymbol{\theta},\boldsymbol{\phi};\mathbf{x}^{(i)})L(θ,ϕ;x(i)) w.r.t. both the variational parameters ϕ\boldsymbol{\phi}ϕ and generative parameters θ\boldsymbol{\theta}θ. However, the gradient of the lower bound w.r.t. ϕ\boldsymbol{\phi}ϕ is a bit problematic. The usual (naïve) Monte Carlo gradient estimator for this type of problem is: ∇ϕEqϕ(z)[f(z)]=Eqϕ(z)[f(z)∇qϕ(z)log⁡qϕ(z)]≃1L∑l=1Lf(z)∇qϕ(z(l))log⁡qϕ(z(l))\nabla_{\boldsymbol{\phi}}\mathbb{E}_{q_{\boldsymbol{\phi}}(\mathbf{z})}\left[f(\mathbf{z})\right]=\mathbb{E}_{q_{\boldsymbol{\phi}}(\mathbf{z})}\left[f(\mathbf{z})\nabla_{q_{\boldsymbol{\phi}}(\mathbf{z})}\log q_{\boldsymbol{\phi}}(\mathbf{z})\right]\simeq\frac{1}{L}\sum_{l=1}^{L}f(\mathbf{z})\nabla_{q_{\boldsymbol{\phi}}(\mathbf{z}^{(l)})}\log q_{\boldsymbol{\phi}}(\mathbf{z}^{(l)})∇ϕ​Eqϕ​(z)​[f(z)]=Eqϕ​(z)​[f(z)∇qϕ​(z)​logqϕ​(z)]≃L1​∑l=1L​f(z)∇qϕ​(z(l))​logqϕ​(z(l)) where z(l)∼qϕ(z∣x(i))\mathbf{z}^{(l)}\sim q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x}^{(i)})z(l)∼qϕ​(z∣x(i)). This gradient estimator exhibits exhibits very high variance (see e.g.  [BJP12]) and is impractical for our purposes.

我们希望就可分参数 ϕ\boldsymbol{\phi}ϕ 与生成参数 θ\boldsymbol{\theta}θ 微分并优化下界 L(θ,ϕ;x(i))\mathcal{L}(\boldsymbol{\theta},\boldsymbol{\phi};\mathbf{x}^{(i)})L(θ,ϕ;x(i))。然而下界对 ϕ\boldsymbol{\phi}ϕ 的梯度有些棘手。这类问题常用的(朴素)蒙特卡洛梯度估计器为:∇ϕEqϕ(z)[f(z)]=Eqϕ(z)[f(z)∇qϕ(z)log⁡qϕ(z)]≃1L∑l=1Lf(z)∇qϕ(z(l))log⁡qϕ(z(l))\nabla_{\boldsymbol{\phi}}\mathbb{E}_{q_{\boldsymbol{\phi}}(\mathbf{z})}\left[f(\mathbf{z})\right]=\mathbb{E}_{q_{\boldsymbol{\phi}}(\mathbf{z})}\left[f(\mathbf{z})\nabla_{q_{\boldsymbol{\phi}}(\mathbf{z})}\log q_{\boldsymbol{\phi}}(\mathbf{z})\right]\simeq\frac{1}{L}\sum_{l=1}^{L}f(\mathbf{z})\nabla_{q_{\boldsymbol{\phi}}(\mathbf{z}^{(l)})}\log q_{\boldsymbol{\phi}}(\mathbf{z}^{(l)})∇ϕ​Eqϕ​(z)​[f(z)]=Eqϕ​(z)​[f(z)∇qϕ​(z)​logqϕ​(z)]≃L1​∑l=1L​f(z)∇qϕ​(z(l))​logqϕ​(z(l)),其中 z(l)∼qϕ(z∣x(i))\mathbf{z}^{(l)}\sim q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x}^{(i)})z(l)∼qϕ​(z∣x(i))。该梯度估计器方差极高(见例如 [BJP12]),对我们的目的不实用。

2.3 The SGVB estimator and AEVB algorithm

2.3 SGVB 估计器与 AEVB 算法

In this section we introduce a practical estimator of the lower bound and its derivatives w.r.t. the parameters. We assume an approximate posterior in the form qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x), but please note that the technique can be applied to the case qϕ(z)q_{\boldsymbol{\phi}}(\mathbf{z})qϕ​(z), i.e. where we do not condition on x\mathbf{x}x, as well. The fully variational Bayesian method for inferring a posterior over the parameters is given in the appendix.

本节引入下界及其对参数导数的实用估计器。我们假定近似后验形式为 qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x),但请注意该技术同样适用于 qϕ(z)q_{\boldsymbol{\phi}}(\mathbf{z})qϕ​(z),即不条件于 x\mathbf{x}x 的情形。对参数做后验推断的完全变分贝叶斯方法见附录。

Under certain mild conditions outlined in section 2.4 for a chosen approximate posterior qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x) we can reparameterize the random variable z~∼qϕ(z∣x)\widetilde{\mathbf{z}}\sim q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})z∼qϕ​(z∣x) using a differentiable transformation gϕ(ϵ,x)g_{\boldsymbol{\phi}}(\boldsymbol{\epsilon},\mathbf{x})gϕ​(ϵ,x) of an (auxiliary) noise variable ϵ\boldsymbol{\epsilon}ϵ:

在第 2.4 节对所选近似后验 qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x) 给出的某些温和条件下,我们可以用辅助噪声变量 ϵ\boldsymbol{\epsilon}ϵ 的可微变换 gϕ(ϵ,x)g_{\boldsymbol{\phi}}(\boldsymbol{\epsilon},\mathbf{x})gϕ​(ϵ,x) 重参数化随机变量 z~∼qϕ(z∣x)\widetilde{\mathbf{z}}\sim q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})z∼qϕ​(z∣x):

z~=gϕ(ϵ,x)with ϵ∼p(ϵ)(4)\displaystyle\widetilde{\mathbf{z}}=g_{\boldsymbol{\phi}}(\boldsymbol{\epsilon},\mathbf{x})\text{\quad with \quad}\boldsymbol{\epsilon}\sim p(\boldsymbol{\epsilon}) \tag{4}z=gϕ​(ϵ,x)with ϵ∼p(ϵ)(4)

See section 2.4 for general strategies for chosing such an approriate distribution p(ϵ)p(\boldsymbol{\epsilon})p(ϵ) and function gϕ(ϵ,x)g_{\boldsymbol{\phi}}(\boldsymbol{\epsilon},\mathbf{x})gϕ​(ϵ,x). We can now form Monte Carlo estimates of expectations of some function f(z)f(\mathbf{z})f(z) w.r.t. qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x) as follows:

选择合适分布 p(ϵ)p(\boldsymbol{\epsilon})p(ϵ) 与函数 gϕ(ϵ,x)g_{\boldsymbol{\phi}}(\boldsymbol{\epsilon},\mathbf{x})gϕ​(ϵ,x) 的一般策略见第 2.4 节。现在可以把某函数 f(z)f(\mathbf{z})f(z) 关于 qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x) 的期望的蒙特卡洛估计写成:

Eqϕ(z∣x(i))[f(z)]=Ep(ϵ)[f(gϕ(ϵ,x(i)))]≃1L∑l=1Lf(gϕ(ϵ(l),x(i)))where ϵ(l)∼p(ϵ)(5)\displaystyle\mathbb{E}_{q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x}^{(i)})}\left[f(\mathbf{z})\right]=\mathbb{E}_{p(\boldsymbol{\epsilon})}\left[f(g_{\boldsymbol{\phi}}(\boldsymbol{\epsilon},\mathbf{x}^{(i)}))\right] \\ \displaystyle\simeq\frac{1}{L}\sum_{l=1}^{L}{f(g_{\boldsymbol{\phi}}(\boldsymbol{\epsilon}^{(l)},\mathbf{x}^{(i)}))}\text{\quad where \quad}\boldsymbol{\epsilon}^{(l)}\sim p(\boldsymbol{\epsilon}) \tag{5}Eqϕ​(z∣x(i))​[f(z)]=Ep(ϵ)​[f(gϕ​(ϵ,x(i)))]≃L1​l=1∑L​f(gϕ​(ϵ(l),x(i)))where ϵ(l)∼p(ϵ)(5)

We apply this technique to the variational lower bound (eq. (2)), yielding our generic Stochastic Gradient Variational Bayes (SGVB) estimator L~A(θ,ϕ;x(i))≃L(θ,ϕ;x(i))\widetilde{\mathcal{L}}^{A}(\boldsymbol{\theta},\boldsymbol{\phi};\mathbf{x}^{(i)})\simeq\mathcal{L}(\boldsymbol{\theta},\boldsymbol{\phi};\mathbf{x}^{(i)})LA(θ,ϕ;x(i))≃L(θ,ϕ;x(i)):

我们将该技术用于变分下界(式 (2)),得到通用的随机梯度变分贝叶斯(SGVB)估计器 L~A(θ,ϕ;x(i))≃L(θ,ϕ;x(i))\widetilde{\mathcal{L}}^{A}(\boldsymbol{\theta},\boldsymbol{\phi};\mathbf{x}^{(i)})\simeq\mathcal{L}(\boldsymbol{\theta},\boldsymbol{\phi};\mathbf{x}^{(i)})LA(θ,ϕ;x(i))≃L(θ,ϕ;x(i)):

L~A(θ,ϕ;x(i))=1L∑l=1Llog⁡pθ(x(i),z(i,l))−log⁡qϕ(z(i,l)∣x(i))where z(i,l)=gϕ(ϵ(i,l),x(i))and ϵ(l)∼p(ϵ)(6)\displaystyle\widetilde{\mathcal{L}}^{A}(\boldsymbol{\theta},\boldsymbol{\phi};\mathbf{x}^{(i)}) \\ \displaystyle=\frac{1}{L}\sum_{l=1}^{L}\log p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)},\mathbf{z}^{(i,l)})-\log q_{\boldsymbol{\phi}}(\mathbf{z}^{(i,l)}|\mathbf{x}^{(i)}) \\ \displaystyle\text{where \quad}\mathbf{z}^{(i,l)} \\ \displaystyle=g_{\boldsymbol{\phi}}(\boldsymbol{\epsilon}^{(i,l)},\mathbf{x}^{(i)})\text{\quad and \quad}\boldsymbol{\epsilon}^{(l)}\sim p(\boldsymbol{\epsilon}) \tag{6}LA(θ,ϕ;x(i))=L1​l=1∑L​logpθ​(x(i),z(i,l))−logqϕ​(z(i,l)∣x(i))where z(i,l)=gϕ​(ϵ(i,l),x(i))and ϵ(l)∼p(ϵ)(6)

Often, the KL-divergence DKL(qϕ(z∣x(i))∣∣pθ(z))D_{KL}(q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x}^{(i)})||p_{\boldsymbol{\theta}}(\mathbf{z}))DKL​(qϕ​(z∣x(i))∣∣pθ​(z)) of eq. (3) can be integrated analytically (see appendix B), such that only the expected reconstruction error Eqϕ(z∣x(i))[log⁡pθ(x(i)∣z)]\mathbb{E}_{q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x}^{(i)})}\left[\log p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)}|\mathbf{z})\right]Eqϕ​(z∣x(i))​[logpθ​(x(i)∣z)] requires estimation by sampling. The KL-divergence term can then be interpreted as regularizing ϕ\boldsymbol{\phi}ϕ, encouraging the approximate posterior to be close to the prior pθ(z)p_{\boldsymbol{\theta}}(\mathbf{z})pθ​(z). This yields a second version of the SGVB estimator L~B(θ,ϕ;x(i))≃L(θ,ϕ;x(i))\widetilde{\mathcal{L}}^{B}(\boldsymbol{\theta},\boldsymbol{\phi};\mathbf{x}^{(i)})\simeq\mathcal{L}(\boldsymbol{\theta},\boldsymbol{\phi};\mathbf{x}^{(i)})LB(θ,ϕ;x(i))≃L(θ,ϕ;x(i)), corresponding to eq. (3), which typically has less variance than the generic estimator:

常常地,式 (3) 中的 KL 散度 DKL(qϕ(z∣x(i))∣∣pθ(z))D_{KL}(q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x}^{(i)})||p_{\boldsymbol{\theta}}(\mathbf{z}))DKL​(qϕ​(z∣x(i))∣∣pθ​(z)) 可以解析积分(见附录 B),因而只需用采样估计期望重构误差 Eqϕ(z∣x(i))[log⁡pθ(x(i)∣z)]\mathbb{E}_{q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x}^{(i)})}\left[\log p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)}|\mathbf{z})\right]Eqϕ​(z∣x(i))​[logpθ​(x(i)∣z)]。此时 KL 项可解释为对 ϕ\boldsymbol{\phi}ϕ 的正则,鼓励近似后验靠近先验 pθ(z)p_{\boldsymbol{\theta}}(\mathbf{z})pθ​(z)。由此得到对应式 (3) 的第二版 SGVB 估计器 L~B(θ,ϕ;x(i))≃L(θ,ϕ;x(i))\widetilde{\mathcal{L}}^{B}(\boldsymbol{\theta},\boldsymbol{\phi};\mathbf{x}^{(i)})\simeq\mathcal{L}(\boldsymbol{\theta},\boldsymbol{\phi};\mathbf{x}^{(i)})LB(θ,ϕ;x(i))≃L(θ,ϕ;x(i)),通常比通用估计器方差更低:

L~B(θ,ϕ;x(i))=−DKL(qϕ(z∣x(i))∣∣pθ(z))+1L∑l=1L(log⁡pθ(x(i)∣z(i,l)))where z(i,l)=gϕ(ϵ(i,l),x(i))and ϵ(l)∼p(ϵ)(7)\displaystyle\widetilde{\mathcal{L}}^{B}(\boldsymbol{\theta},\boldsymbol{\phi};\mathbf{x}^{(i)}) \\ \displaystyle=-D_{KL}(q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x}^{(i)})||p_{\boldsymbol{\theta}}(\mathbf{z}))+\frac{1}{L}\sum_{l=1}^{L}(\log p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)}|\mathbf{z}^{(i,l)})) \\ \displaystyle\text{where \quad}\mathbf{z}^{(i,l)} \\ \displaystyle=g_{\boldsymbol{\phi}}(\boldsymbol{\epsilon}^{(i,l)},\mathbf{x}^{(i)})\text{\quad and \quad}\boldsymbol{\epsilon}^{(l)}\sim p(\boldsymbol{\epsilon}) \tag{7}LB(θ,ϕ;x(i))=−DKL​(qϕ​(z∣x(i))∣∣pθ​(z))+L1​l=1∑L​(logpθ​(x(i)∣z(i,l)))where z(i,l)=gϕ​(ϵ(i,l),x(i))and ϵ(l)∼p(ϵ)(7)

Given multiple datapoints from a dataset X\mathbf{X}X with NNN datapoints, we can construct an estimator of the marginal likelihood lower bound of the full dataset, based on minibatches:

给定来自含 NNN 个数据点的数据集 X\mathbf{X}X 的多个数据点,我们可以基于小批量构造全数据集边际似然下界的估计器:

L(θ,ϕ;X)≃L~M(θ,ϕ;XM)=NM∑i=1ML~(θ,ϕ;x(i))(8)\displaystyle\mathcal{L}(\boldsymbol{\theta},\boldsymbol{\phi};\mathbf{X})\simeq\widetilde{\mathcal{L}}^{M}(\boldsymbol{\theta},\boldsymbol{\phi};\mathbf{X}^{M})=\frac{N}{M}\sum_{i=1}^{M}\widetilde{\mathcal{L}}(\boldsymbol{\theta},\boldsymbol{\phi};\mathbf{x}^{(i)}) \tag{8}L(θ,ϕ;X)≃LM(θ,ϕ;XM)=MN​i=1∑M​L(θ,ϕ;x(i))(8)

where the minibatch XM={x(i)}i=1M\mathbf{X}^{M}=\{\mathbf{x}^{(i)}\}_{i=1}^{M}XM={x(i)}i=1M​ is a randomly drawn sample of MMM datapoints from the full dataset X\mathbf{X}X with NNN datapoints. In our experiments we found that the number of samples LLL per datapoint can be set to 111 as long as the minibatch size MMM was large enough, e.g. M=100M=100M=100. Derivatives ∇θ,ϕL~(θ;XM)\nabla_{\boldsymbol{\theta},\boldsymbol{\phi}}\widetilde{\mathcal{L}}(\boldsymbol{\theta};\mathbf{X}^{M})∇θ,ϕ​L(θ;XM) can be taken, and the resulting gradients can be used in conjunction with stochastic optimization methods such as SGD or Adagrad [DHS10]. See algorithm 1 for a basic approach to compute the stochastic gradients.

其中小批量 XM={x(i)}i=1M\mathbf{X}^{M}=\{\mathbf{x}^{(i)}\}_{i=1}^{M}XM={x(i)}i=1M​ 是从全数据集 X\mathbf{X}X(含 NNN 个点)中随机抽取的 MMM 个数据点。实验中我们发现,只要小批量大小 MMM 足够大(例如 M=100M=100M=100),每个数据点的样本数 LLL 可设为 111。可以求导数 ∇θ,ϕL~(θ;XM)\nabla_{\boldsymbol{\theta},\boldsymbol{\phi}}\widetilde{\mathcal{L}}(\boldsymbol{\theta};\mathbf{X}^{M})∇θ,ϕ​L(θ;XM),并与 SGD 或 Adagrad [DHS10] 等随机优化方法联用。计算随机梯度的基本做法见算法 1。

A connection with auto-encoders becomes clear when looking at the objective function given at eq. (7). The first term is (the KL divergence of the approximate posterior from the prior) acts as a regularizer, while the second term is a an expected negative reconstruction error. The function gϕ(.)g_{\boldsymbol{\phi}}(.)gϕ​(.) is chosen such that it maps a datapoint x(i)\mathbf{x}^{(i)}x(i) and a random noise vector ϵ(l)\boldsymbol{\epsilon}^{(l)}ϵ(l) to a sample from the approximate posterior for that datapoint: z(i,l)=gϕ(ϵ(l),x(i))\mathbf{z}^{(i,l)}=g_{\boldsymbol{\phi}}(\boldsymbol{\epsilon}^{(l)},\mathbf{x}^{(i)})z(i,l)=gϕ​(ϵ(l),x(i)) where z(i,l)∼qϕ(z∣x(i))\mathbf{z}^{(i,l)}\sim q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x}^{(i)})z(i,l)∼qϕ​(z∣x(i)). Subsequently, the sample z(i,l)\mathbf{z}^{(i,l)}z(i,l) is then input to function log⁡pθ(x(i)∣z(i,l))\log p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)}|\mathbf{z}^{(i,l)})logpθ​(x(i)∣z(i,l)), which equals the probability density (or mass) of datapoint x(i)\mathbf{x}^{(i)}x(i) under the generative model, given z(i,l)\mathbf{z}^{(i,l)}z(i,l). This term is a negative reconstruction error in auto-encoder parlance.

观察式 (7) 的目标函数,与自动编码器的联系就清楚了。第一项(近似后验相对先验的 KL 散度)起正则作用,第二项是期望负重构误差。函数 gϕ(.)g_{\boldsymbol{\phi}}(.)gϕ​(.) 被选成把数据点 x(i)\mathbf{x}^{(i)}x(i) 与随机噪声向量 ϵ(l)\boldsymbol{\epsilon}^{(l)}ϵ(l) 映射为该点近似后验的一个样本:z(i,l)=gϕ(ϵ(l),x(i))\mathbf{z}^{(i,l)}=g_{\boldsymbol{\phi}}(\boldsymbol{\epsilon}^{(l)},\mathbf{x}^{(i)})z(i,l)=gϕ​(ϵ(l),x(i)),其中 z(i,l)∼qϕ(z∣x(i))\mathbf{z}^{(i,l)}\sim q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x}^{(i)})z(i,l)∼qϕ​(z∣x(i))。随后样本 z(i,l)\mathbf{z}^{(i,l)}z(i,l) 被送入 log⁡pθ(x(i)∣z(i,l))\log p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)}|\mathbf{z}^{(i,l)})logpθ​(x(i)∣z(i,l)),即在给定 z(i,l)\mathbf{z}^{(i,l)}z(i,l) 时数据点在生成模型下的概率密度(或质量)。用自动编码器的说法,这一项就是负重构误差。

θ,ϕ←\boldsymbol{\theta},\boldsymbol{\phi}\leftarrowθ,ϕ← Initialize parameters
repeat
XM←\mathbf{X}^{M}\leftarrowXM← Random minibatch of MMM datapoints (drawn from full dataset)
ϵ←\boldsymbol{\epsilon}\leftarrowϵ← Random samples from noise distribution p(ϵ)p(\boldsymbol{\epsilon})p(ϵ)
g←∇θ,ϕL~M(θ,ϕ;XM,ϵ)\mathbf{g}\leftarrow\nabla_{\boldsymbol{\theta},\boldsymbol{\phi}}\widetilde{\mathcal{L}}^{M}(\boldsymbol{\theta},\boldsymbol{\phi};\mathbf{X}^{M},\boldsymbol{\epsilon})g←∇θ,ϕ​LM(θ,ϕ;XM,ϵ) (Gradients of minibatch estimator (8))
θ,ϕ←\boldsymbol{\theta},\boldsymbol{\phi}\leftarrowθ,ϕ← Update parameters using gradients g\mathbf{g}g (e.g. SGD or Adagrad [DHS10])
until convergence of parameters (θ,ϕ)(\boldsymbol{\theta},\boldsymbol{\phi})(θ,ϕ)
return θ,ϕ\boldsymbol{\theta},\boldsymbol{\phi}θ,ϕ

Algorithm 1 Minibatch version of the Auto-Encoding VB (AEVB) algorithm. Either of the two SGVB estimators in section 2.3 can be used. We use settings M=100M=100M=100 and L=1L=1L=1 in experiments.

θ,ϕ←\boldsymbol{\theta},\boldsymbol{\phi}\leftarrowθ,ϕ← 初始化参数
repeat
XM←\mathbf{X}^{M}\leftarrowXM← 随机小批量,含 MMM 个数据点(从全数据集抽取)
ϵ←\boldsymbol{\epsilon}\leftarrowϵ← 从噪声分布 p(ϵ)p(\boldsymbol{\epsilon})p(ϵ) 随机采样
g←∇θ,ϕL~M(θ,ϕ;XM,ϵ)\mathbf{g}\leftarrow\nabla_{\boldsymbol{\theta},\boldsymbol{\phi}}\widetilde{\mathcal{L}}^{M}(\boldsymbol{\theta},\boldsymbol{\phi};\mathbf{X}^{M},\boldsymbol{\epsilon})g←∇θ,ϕ​LM(θ,ϕ;XM,ϵ)(小批量估计器 (8) 的梯度)
θ,ϕ←\boldsymbol{\theta},\boldsymbol{\phi}\leftarrowθ,ϕ← 用梯度 g\mathbf{g}g 更新参数(例如 SGD 或 Adagrad [DHS10])
until 参数 (θ,ϕ)(\boldsymbol{\theta},\boldsymbol{\phi})(θ,ϕ) 收敛
return θ,ϕ\boldsymbol{\theta},\boldsymbol{\phi}θ,ϕ

算法 1 自编码变分贝叶斯(AEVB)算法的小批量版本。可使用第 2.3 节两个 SGVB 估计器中的任一个。实验中我们使用 M=100M=100M=100、L=1L=1L=1。

2.4 The reparameterization trick

2.4 重参数化技巧

In order to solve our problem we invoked an alternative method for generating samples from qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x). The essential parameterization trick is quite simple. Let z\mathbf{z}z be a continuous random variable, and z∼qϕ(z∣x)\mathbf{z}\sim q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})z∼qϕ​(z∣x) be some conditional distribution. It is then often possible to express the random variable z\mathbf{z}z as a deterministic variable z=gϕ(ϵ,x)\mathbf{z}=g_{\boldsymbol{\phi}}(\boldsymbol{\epsilon},\mathbf{x})z=gϕ​(ϵ,x), where ϵ\boldsymbol{\epsilon}ϵ is an auxiliary variable with independent marginal p(ϵ)p(\boldsymbol{\epsilon})p(ϵ), and gϕ(.)g_{\boldsymbol{\phi}}(.)gϕ​(.) is some vector-valued function parameterized by ϕ\boldsymbol{\phi}ϕ.

为解决问题,我们采用了从 qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x) 生成样本的另一种方法。本质的参数化技巧相当简单。设 z\mathbf{z}z 为连续随机变量,且 z∼qϕ(z∣x)\mathbf{z}\sim q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})z∼qϕ​(z∣x) 为某条件分布。则常常可以把随机变量 z\mathbf{z}z 表达为确定性变量 z=gϕ(ϵ,x)\mathbf{z}=g_{\boldsymbol{\phi}}(\boldsymbol{\epsilon},\mathbf{x})z=gϕ​(ϵ,x),其中 ϵ\boldsymbol{\epsilon}ϵ 是具有独立边际 p(ϵ)p(\boldsymbol{\epsilon})p(ϵ) 的辅助变量,gϕ(.)g_{\boldsymbol{\phi}}(.)gϕ​(.) 是由 ϕ\boldsymbol{\phi}ϕ 参数化的某个向量值函数。

This reparameterization is useful for our case since it can be used to rewrite an expectation w.r.t qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x) such that the Monte Carlo estimate of the expectation is differentiable w.r.t. ϕ\boldsymbol{\phi}ϕ. A proof is as follows. Given the deterministic mapping z=gϕ(ϵ,x)\mathbf{z}=g_{\boldsymbol{\phi}}(\boldsymbol{\epsilon},\mathbf{x})z=gϕ​(ϵ,x) we know that qϕ(z∣x)∏idzi=p(ϵ)∏idϵiq_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})\prod_{i}dz_{i}=p(\boldsymbol{\epsilon})\prod_{i}d\epsilon_{i}qϕ​(z∣x)∏i​dzi​=p(ϵ)∏i​dϵi​. Therefore[^1], ∫qϕ(z∣x)f(z) dz=∫p(ϵ)f(z) dϵ=∫p(ϵ)f(gϕ(ϵ,x)) dϵ\int q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})f(\mathbf{z})\,d\mathbf{z}=\int p(\boldsymbol{\epsilon})f(\mathbf{z})\,d\boldsymbol{\epsilon}=\int p(\boldsymbol{\epsilon})f(g_{\boldsymbol{\phi}}(\boldsymbol{\epsilon},\mathbf{x}))\,d\boldsymbol{\epsilon}∫qϕ​(z∣x)f(z)dz=∫p(ϵ)f(z)dϵ=∫p(ϵ)f(gϕ​(ϵ,x))dϵ. It follows that a differentiable estimator can be constructed: ∫qϕ(z∣x)f(z) dz≃1L∑l=1Lf(gϕ(x,ϵ(l)))\int q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})f(\mathbf{z})\,d\mathbf{z}\simeq\frac{1}{L}\sum_{l=1}^{L}f(g_{\boldsymbol{\phi}}(\mathbf{x},\boldsymbol{\epsilon}^{(l)}))∫qϕ​(z∣x)f(z)dz≃L1​∑l=1L​f(gϕ​(x,ϵ(l))) where ϵ(l)∼p(ϵ)\boldsymbol{\epsilon}^{(l)}\sim p(\boldsymbol{\epsilon})ϵ(l)∼p(ϵ). In section 2.3 we applied this trick to obtain a differentiable estimator of the variational lower bound.

这种重参数化对我们有用,因为它可以把关于 qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x) 的期望改写,使得期望的蒙特卡洛估计对 ϕ\boldsymbol{\phi}ϕ 可微。证明如下。给定确定性映射 z=gϕ(ϵ,x)\mathbf{z}=g_{\boldsymbol{\phi}}(\boldsymbol{\epsilon},\mathbf{x})z=gϕ​(ϵ,x),有 qϕ(z∣x)∏idzi=p(ϵ)∏idϵiq_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})\prod_{i}dz_{i}=p(\boldsymbol{\epsilon})\prod_{i}d\epsilon_{i}qϕ​(z∣x)∏i​dzi​=p(ϵ)∏i​dϵi​。因此[^1],∫qϕ(z∣x)f(z) dz=∫p(ϵ)f(z) dϵ=∫p(ϵ)f(gϕ(ϵ,x)) dϵ\int q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})f(\mathbf{z})\,d\mathbf{z}=\int p(\boldsymbol{\epsilon})f(\mathbf{z})\,d\boldsymbol{\epsilon}=\int p(\boldsymbol{\epsilon})f(g_{\boldsymbol{\phi}}(\boldsymbol{\epsilon},\mathbf{x}))\,d\boldsymbol{\epsilon}∫qϕ​(z∣x)f(z)dz=∫p(ϵ)f(z)dϵ=∫p(ϵ)f(gϕ​(ϵ,x))dϵ。于是可构造可微估计器:∫qϕ(z∣x)f(z) dz≃1L∑l=1Lf(gϕ(x,ϵ(l)))\int q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})f(\mathbf{z})\,d\mathbf{z}\simeq\frac{1}{L}\sum_{l=1}^{L}f(g_{\boldsymbol{\phi}}(\mathbf{x},\boldsymbol{\epsilon}^{(l)}))∫qϕ​(z∣x)f(z)dz≃L1​∑l=1L​f(gϕ​(x,ϵ(l))),其中 ϵ(l)∼p(ϵ)\boldsymbol{\epsilon}^{(l)}\sim p(\boldsymbol{\epsilon})ϵ(l)∼p(ϵ)。第 2.3 节正是用该技巧得到了变分下界的可微估计器。

Take, for example, the univariate Gaussian case: let z∼p(z∣x)=N(μ,σ2)z\sim p(z|x)=\mathcal{N}(\mu,\sigma^{2})z∼p(z∣x)=N(μ,σ2). In this case, a valid reparameterization is z=μ+σϵz=\mu+\sigma\epsilonz=μ+σϵ, where ϵ\epsilonϵ is an auxiliary noise variable ϵ∼N(0,1)\epsilon\sim\mathcal{N}(0,1)ϵ∼N(0,1). Therefore, EN(z;μ,σ2)[f(z)]=EN(ϵ;0,1)[f(μ+σϵ)]≃1L∑l=1Lf(μ+σϵ(l))\mathbb{E}_{\mathcal{N}(z;\mu,\sigma^{2})}\left[f(z)\right]=\mathbb{E}_{\mathcal{N}(\epsilon;0,1)}\left[f(\mu+\sigma\epsilon)\right]\simeq\frac{1}{L}\sum_{l=1}^{L}f(\mu+\sigma\epsilon^{(l)})EN(z;μ,σ2)​[f(z)]=EN(ϵ;0,1)​[f(μ+σϵ)]≃L1​∑l=1L​f(μ+σϵ(l)) where ϵ(l)∼N(0,1)\epsilon^{(l)}\sim\mathcal{N}(0,1)ϵ(l)∼N(0,1).

以一元高斯为例:设 z∼p(z∣x)=N(μ,σ2)z\sim p(z|x)=\mathcal{N}(\mu,\sigma^{2})z∼p(z∣x)=N(μ,σ2)。此时有效重参数化为 z=μ+σϵz=\mu+\sigma\epsilonz=μ+σϵ,其中 ϵ\epsilonϵ 为辅助噪声变量 ϵ∼N(0,1)\epsilon\sim\mathcal{N}(0,1)ϵ∼N(0,1)。因此 EN(z;μ,σ2)[f(z)]=EN(ϵ;0,1)[f(μ+σϵ)]≃1L∑l=1Lf(μ+σϵ(l))\mathbb{E}_{\mathcal{N}(z;\mu,\sigma^{2})}\left[f(z)\right]=\mathbb{E}_{\mathcal{N}(\epsilon;0,1)}\left[f(\mu+\sigma\epsilon)\right]\simeq\frac{1}{L}\sum_{l=1}^{L}f(\mu+\sigma\epsilon^{(l)})EN(z;μ,σ2)​[f(z)]=EN(ϵ;0,1)​[f(μ+σϵ)]≃L1​∑l=1L​f(μ+σϵ(l)),其中 ϵ(l)∼N(0,1)\epsilon^{(l)}\sim\mathcal{N}(0,1)ϵ(l)∼N(0,1)。

For which qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x) can we choose such a differentiable transformation gϕ(.)g_{\boldsymbol{\phi}}(.)gϕ​(.) and auxiliary variable ϵ∼p(ϵ)\boldsymbol{\epsilon}\sim p(\boldsymbol{\epsilon})ϵ∼p(ϵ)? Three basic approaches are:

对哪些 qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x) 我们可以选择这样的可微变换 gϕ(.)g_{\boldsymbol{\phi}}(.)gϕ​(.) 与辅助变量 ϵ∼p(ϵ)\boldsymbol{\epsilon}\sim p(\boldsymbol{\epsilon})ϵ∼p(ϵ)?三种基本途径是:

  1. Tractable inverse CDF. In this case, let ϵ∼U(0,I)\boldsymbol{\epsilon}\sim\mathcal{U}(\mathbf{0},\mathbf{I})ϵ∼U(0,I), and let gϕ(ϵ,x)g_{\boldsymbol{\phi}}(\boldsymbol{\epsilon},\mathbf{x})gϕ​(ϵ,x) be the inverse CDF of qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x). Examples: Exponential, Cauchy, Logistic, Rayleigh, Pareto, Weibull, Reciprocal, Gompertz, Gumbel and Erlang distributions.
  2. Analogous to the Gaussian example, for any ”location-scale” family of distributions we can choose the standard distribution (with location=0\text{location}=0location=0, scale=1\text{scale}=1scale=1) as the auxiliary variable ϵ\boldsymbol{\epsilon}ϵ, and let g(.)=location+scale⋅ϵg(.)=\text{location}+\text{scale}\cdot\boldsymbol{\epsilon}g(.)=location+scale⋅ϵ. Examples: Laplace, Elliptical, Student’s t, Logistic, Uniform, Triangular and Gaussian distributions.
  3. Composition: It is often possible to express random variables as different transformations of auxiliary variables. Examples: Log-Normal (exponentiation of normally distributed variable), Gamma (a sum over exponentially distributed variables), Dirichlet (weighted sum of Gamma variates), Beta, Chi-Squared, and F distributions.
  1. 可处理的逆 CDF。此时令 ϵ∼U(0,I)\boldsymbol{\epsilon}\sim\mathcal{U}(\mathbf{0},\mathbf{I})ϵ∼U(0,I),并令 gϕ(ϵ,x)g_{\boldsymbol{\phi}}(\boldsymbol{\epsilon},\mathbf{x})gϕ​(ϵ,x) 为 qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x) 的逆 CDF。例子:指数、Cauchy、Logistic、Rayleigh、Pareto、Weibull、倒数、Gompertz、Gumbel 与 Erlang 分布。
  2. 类似于高斯例子,对任何“位置-尺度”族,可选标准分布(location=0,scale=1)作为辅助变量 ϵ\boldsymbol{\epsilon}ϵ,并令 g(.)=location+scale⋅ϵg(.)=\mathrm{location}+\mathrm{scale}\cdot\boldsymbol{\epsilon}g(.)=location+scale⋅ϵ。例子:Laplace、椭圆、Student t、Logistic、均匀、三角与高斯分布。
  3. 复合:常常可以把随机变量表达为辅助变量的不同变换。例子:对数正态(正态变量的指数)、Gamma(指数变量之和)、Dirichlet(Gamma 变量的加权和)、Beta、卡方与 F 分布。

When all three approaches fail, good approximations to the inverse CDF exist requiring computations with time complexity comparable to the PDF (see e.g.  [Dev86] for some methods).

当三种途径都失败时,存在与 PDF 时间复杂度相当的良好逆 CDF 近似(例如见 [Dev86] 中的一些方法)。

3 Example: Variational Auto-Encoder

3 示例:变分自编码器

In this section we’ll give an example where we use a neural network for the probabilistic encoder qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x) (the approximation to the posterior of the generative model pθ(x,z)p_{\boldsymbol{\theta}}(\mathbf{x},\mathbf{z})pθ​(x,z)) and where the parameters ϕ\boldsymbol{\phi}ϕ and θ\boldsymbol{\theta}θ are optimized jointly with the AEVB algorithm.

本节给出一个例子:用神经网络作为概率编码器 qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x)(对生成模型 pθ(x,z)p_{\boldsymbol{\theta}}(\mathbf{x},\mathbf{z})pθ​(x,z) 后验的近似),并用 AEVB 算法联合优化参数 ϕ\boldsymbol{\phi}ϕ 与 θ\boldsymbol{\theta}θ。

Let the prior over the latent variables be the centered isotropic multivariate Gaussian pθ(z)=N(z;0,I)p_{\boldsymbol{\theta}}(\mathbf{z})=\mathcal{N}(\mathbf{z};\mathbf{0},\mathbf{I})pθ​(z)=N(z;0,I). Note that in this case, the prior lacks parameters. We let pθ(x∣z)p_{\boldsymbol{\theta}}(\mathbf{x}|\mathbf{z})pθ​(x∣z) be a multivariate Gaussian (in case of real-valued data) or Bernoulli (in case of binary data) whose distribution parameters are computed from z\mathbf{z}z with a MLP (a fully-connected neural network with a single hidden layer, see appendix C). Note the true posterior pθ(z∣x)p_{\boldsymbol{\theta}}(\mathbf{z}|\mathbf{x})pθ​(z∣x) is in this case intractable. While there is much freedom in the form qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x), we’ll assume the true (but intractable) posterior takes on a approximate Gaussian form with an approximately diagonal covariance. In this case, we can let the variational approximate posterior be a multivariate Gaussian with a diagonal covariance structure[^2]:

设隐变量先验为中心各向同性多元高斯 pθ(z)=N(z;0,I)p_{\boldsymbol{\theta}}(\mathbf{z})=\mathcal{N}(\mathbf{z};\mathbf{0},\mathbf{I})pθ​(z)=N(z;0,I)。注意此时先验没有参数。令 pθ(x∣z)p_{\boldsymbol{\theta}}(\mathbf{x}|\mathbf{z})pθ​(x∣z) 为多元高斯(实值数据)或 Bernoulli(二值数据),其分布参数由 MLP(带单个隐层的全连接神经网络,见附录 C)从 z\mathbf{z}z 算出。注意此时真实后验 pθ(z∣x)p_{\boldsymbol{\theta}}(\mathbf{z}|\mathbf{x})pθ​(z∣x) 不可积。尽管 qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x) 形式很自由,我们假定真实(但不可积)后验近似呈对角协方差的高斯形式。此时可令变分近似后验为具有对角协方差结构的多元高斯[^2]:

log⁡qϕ(z∣x(i))=log⁡N(z;μ(i),σ2(i)I)(9)\displaystyle\log q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x}^{(i)}) \\ \displaystyle=\log\mathcal{N}(\mathbf{z};\boldsymbol{\mu}^{(i)},\boldsymbol{\sigma}^{2(i)}\mathbf{I}) \tag{9}logqϕ​(z∣x(i))=logN(z;μ(i),σ2(i)I)(9)

where the mean and s.d. of the approximate posterior, μ(i)\boldsymbol{\mu}^{(i)}μ(i) and σ(i)\boldsymbol{\sigma}^{(i)}σ(i), are outputs of the encoding MLP, i.e. nonlinear functions of datapoint x(i)\mathbf{x}^{(i)}x(i) and the variational parameters ϕ\boldsymbol{\phi}ϕ (see appendix C).

其中近似后验的均值与标准差 μ(i)\boldsymbol{\mu}^{(i)}μ(i) 与 σ(i)\boldsymbol{\sigma}^{(i)}σ(i) 是编码 MLP 的输出,即数据点 x(i)\mathbf{x}^{(i)}x(i) 与变分参数 ϕ\boldsymbol{\phi}ϕ 的非线性函数(见附录 C)。

As explained in section 2.4, we sample from the posterior z(i,l)∼qϕ(z∣x(i))\mathbf{z}^{(i,l)}\sim q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x}^{(i)})z(i,l)∼qϕ​(z∣x(i)) using z(i,l)=gϕ(x(i),ϵ(l))=μ(i)+σ(i)⊙ϵ(l)\mathbf{z}^{(i,l)}=g_{\boldsymbol{\phi}}(\mathbf{x}^{(i)},\boldsymbol{\epsilon}^{(l)})=\boldsymbol{\mu}^{(i)}+\boldsymbol{\sigma}^{(i)}\odot\boldsymbol{\epsilon}^{(l)}z(i,l)=gϕ​(x(i),ϵ(l))=μ(i)+σ(i)⊙ϵ(l) where ϵ(l)∼N(0,I)\boldsymbol{\epsilon}^{(l)}\sim\mathcal{N}(\mathbf{0},\mathbf{I})ϵ(l)∼N(0,I). With ⊙\odot⊙ we signify an element-wise product. In this model both pθ(z)p_{\boldsymbol{\theta}}(\mathbf{z})pθ​(z) (the prior) and qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x) are Gaussian; in this case, we can use the estimator of eq. (7) where the KL divergence can be computed and differentiated without estimation (see appendix B). The resulting estimator for this model and datapoint x(i)\mathbf{x}^{(i)}x(i) is:

如第 2.4 节所释,我们用 z(i,l)=gϕ(x(i),ϵ(l))=μ(i)+σ(i)⊙ϵ(l)\mathbf{z}^{(i,l)}=g_{\boldsymbol{\phi}}(\mathbf{x}^{(i)},\boldsymbol{\epsilon}^{(l)})=\boldsymbol{\mu}^{(i)}+\boldsymbol{\sigma}^{(i)}\odot\boldsymbol{\epsilon}^{(l)}z(i,l)=gϕ​(x(i),ϵ(l))=μ(i)+σ(i)⊙ϵ(l)(其中 ϵ(l)∼N(0,I)\boldsymbol{\epsilon}^{(l)}\sim\mathcal{N}(\mathbf{0},\mathbf{I})ϵ(l)∼N(0,I))从后验 z(i,l)∼qϕ(z∣x(i))\mathbf{z}^{(i,l)}\sim q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x}^{(i)})z(i,l)∼qϕ​(z∣x(i)) 采样。⊙\odot⊙ 表示逐元素乘积。该模型中 pθ(z)p_{\boldsymbol{\theta}}(\mathbf{z})pθ​(z)(先验)与 qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x) 均为高斯;此时可用式 (7) 的估计器,KL 散度无需估计即可计算并微分(见附录 B)。对该模型与数据点 x(i)\mathbf{x}^{(i)}x(i),所得估计器为:

L(θ,ϕ;x(i))≃12∑j=1J(1+log⁡((σj(i))2)−(μj(i))2−(σj(i))2)+1L∑l=1Llog⁡pθ(x(i)∣z(i,l))wherez(i,l)=μ(i)+σ(i)⊙ϵ(l)and ϵ(l)∼N(0,I)(10)\displaystyle\mathcal{L}(\boldsymbol{\theta},\boldsymbol{\phi};\mathbf{x}^{(i)}) \\ \displaystyle\simeq\frac{1}{2}\sum_{j=1}^{J}\left(1+\log((\sigma_{j}^{(i)})^{2})-(\mu_{j}^{(i)})^{2}-(\sigma_{j}^{(i)})^{2}\right)+\frac{1}{L}\sum_{l=1}^{L}\log p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)}|\mathbf{z}^{(i,l)}) \\ \displaystyle\text{where\quad}\mathbf{z}^{(i,l)} \\ \displaystyle=\boldsymbol{\mu}^{(i)}+\boldsymbol{\sigma}^{(i)}\odot\boldsymbol{\epsilon}^{(l)}\text{\quad and \quad}\boldsymbol{\epsilon}^{(l)}\sim\mathcal{N}(0,\mathbf{I}) \tag{10}L(θ,ϕ;x(i))≃21​j=1∑J​(1+log((σj(i)​)2)−(μj(i)​)2−(σj(i)​)2)+L1​l=1∑L​logpθ​(x(i)∣z(i,l))wherez(i,l)=μ(i)+σ(i)⊙ϵ(l)and ϵ(l)∼N(0,I)(10)

As explained above and in appendix C, the decoding term log⁡pθ(x(i)∣z(i,l))\log p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)}|\mathbf{z}^{(i,l)})logpθ​(x(i)∣z(i,l)) is a Bernoulli or Gaussian MLP, depending on the type of data we are modelling.

如上所述及附录 C,解码项 log⁡pθ(x(i)∣z(i,l))\log p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)}|\mathbf{z}^{(i,l)})logpθ​(x(i)∣z(i,l)) 是 Bernoulli 或高斯 MLP,取决于所建模数据类型。

4 Related work

4 相关工作

The wake-sleep algorithm [HDFN95] is, to the best of our knowledge, the only other on-line learning method in the literature that is applicable to the same general class of continuous latent variable models. Like our method, the wake-sleep algorithm employs a recognition model that approximates the true posterior. A drawback of the wake-sleep algorithm is that it requires a concurrent optimization of two objective functions, which together do not correspond to optimization of (a bound of) the marginal likelihood. An advantage of wake-sleep is that it also applies to models with discrete latent variables. Wake-Sleep has the same computational complexity as AEVB per datapoint.

据我们所知,wake-sleep 算法 [HDFN95] 是文献中唯一另一种适用于同一大类连续隐变量模型的在线学习方法。与我们的方法一样,wake-sleep 使用逼近真实后验的识别模型。其缺点是需要同时优化两个目标函数,它们合在一起并不对应于(边际似然下界的)优化。其优点是也适用于离散隐变量模型。wake-sleep 与 AEVB 每个数据点的计算复杂度相同。

Stochastic variational inference [HBWP13] has recently received increasing interest. Recently, [BJP12] introduced a control variate schemes to reduce the high variance of the naïve gradient estimator discussed in section 2.1, and applied to exponential family approximations of the posterior. In [RGB13] some general methods, i.e. a control variate scheme, were introduced for reducing the variance of the original gradient estimator. In [SK13], a similar reparameterization as in this paper was used in an efficient version of a stochastic variational inference algorithm for learning the natural parameters of exponential-family approximating distributions.

随机变分推断 [HBWP13] 近来受到越来越多关注。[BJP12] 引入控制变量方案以降低第 2.1 节讨论的朴素梯度估计器的高方差,并应用于后验的指数族近似。[RGB13] 引入了一些降低原始梯度估计器方差的一般方法(即控制变量方案)。[SK13] 在学习指数族近似分布自然参数的高效随机变分推断算法中,使用了与本文类似的重参数化。

The AEVB algorithm exposes a connection between directed probabilistic models (trained with a variational objective) and auto-encoders. A connection between linear auto-encoders and a certain class of generative linear-Gaussian models has long been known. In  [Row98] it was shown that PCA corresponds to the maximum-likelihood (ML) solution of a special case of the linear-Gaussian model with a prior p(z)=N(0,I)p(\mathbf{z})=\mathcal{N}(0,\mathbf{I})p(z)=N(0,I) and a conditional distribution p(x∣z)=N(x;Wz,ϵI)p(\mathbf{x}|\mathbf{z})=\mathcal{N}(\mathbf{x};\mathbf{W}\mathbf{z},\epsilon\mathbf{I})p(x∣z)=N(x;Wz,ϵI), specifically the case with infinitesimally small ϵ\epsilonϵ.

AEVB 算法揭示了(用变分目标训练的)有向概率模型与自动编码器之间的联系。线性自动编码器与某类生成线性-高斯模型之间的联系早已为人所知。[Row98] 证明 PCA 对应于带先验 p(z)=N(0,I)p(\mathbf{z})=\mathcal{N}(0,\mathbf{I})p(z)=N(0,I) 与条件分布 p(x∣z)=N(x;Wz,ϵI)p(\mathbf{x}|\mathbf{z})=\mathcal{N}(\mathbf{x};\mathbf{W}\mathbf{z},\epsilon\mathbf{I})p(x∣z)=N(x;Wz,ϵI) 的线性-高斯模型特例(具体是 ϵ\epsilonϵ 无穷小)的最大似然解。

In relevant recent work on autoencoders [VLL+10] it was shown that the training criterion of unregularized autoencoders corresponds to maximization of a lower bound (see the infomax principle [Lin89]) of the mutual information between input XXX and latent representation ZZZ. Maximizing (w.r.t. parameters) of the mutual information is equivalent to maximizing the conditional entropy, which is lower bounded by the expected loglikelihood of the data under the autoencoding model [VLL+10], i.e. the negative reconstrution error. However, it is well known that this reconstruction criterion is in itself not sufficient for learning useful representations [BCV13]. Regularization techniques have been proposed to make autoencoders learn useful representations, such as denoising, contractive and sparse autoencoder variants  [BCV13]. The SGVB objective contains a regularization term dictated by the variational bound (e.g. eq. (10)), lacking the usual nuisance regularization hyperparameter required to learn useful representations. Related are also encoder-decoder architectures such as the predictive sparse decomposition (PSD) [KRL08], from which we drew some inspiration. Also relevant are the recently introduced Generative Stochastic Networks [BTL13] where noisy auto-encoders learn the transition operator of a Markov chain that samples from the data distribution. In [SL10] a recognition model was employed for efficient learning with Deep Boltzmann Machines. These methods are targeted at either unnormalized models (i.e. undirected models like Boltzmann machines) or limited to sparse coding models, in contrast to our proposed algorithm for learning a general class of directed probabilistic models.

在自动编码器的相关近期工作中,[VLL+10] 证明无正则自动编码器的训练准则对应于输入 XXX 与潜在表示 ZZZ 互信息下界的最大化(见信息最大化原理 [Lin89])。最大化(对参数)互信息等价于最大化条件熵,而条件熵又被自动编码模型下数据的期望对数似然下界,即负重构误差 [VLL+10]。然而众所周知,仅靠重构准则不足以学到有用表示 [BCV13]。已有去噪、收缩与稀疏等自动编码器变体等正则技术使自动编码器学习有用表示 [BCV13]。SGVB 目标包含由变分下界规定的正则项(例如式 (10)),无需学习有用表示时常有的讨厌正则超参数。相关的还有预测稀疏分解(PSD)[KRL08] 这类编码器-解码器架构,我们从中获得了一些启发。同样相关的是近来提出的生成随机网络 [BTL13],其中带噪自动编码器学习从数据分布采样的马尔可夫链转移算子。[SL10] 使用识别模型对深度玻尔兹曼机做高效学习。这些方法要么针对未归一化模型(即玻尔兹曼机这类无向模型),要么限于稀疏编码模型,而我们提出的是学习一般有向概率模型类的算法。

The recently proposed DARN method  [GMW13], also learns a directed probabilistic model using an auto-encoding structure, however their method applies to binary latent variables. Even more recently,  [RMW14] also make the connection between auto-encoders, directed proabilistic models and stochastic variational inference using the reparameterization trick we describe in this paper. Their work was developed independently of ours and provides an additional perspective on AEVB.

近来提出的 DARN 方法 [GMW13] 也用自动编码结构学习有向概率模型,但其方法适用于二值隐变量。更近地,[RMW14] 也建立了自动编码器、有向概率模型与使用本文重参数化技巧的随机变分推断之间的联系。他们的工作与我们独立发展,为 AEVB 提供了额外视角。
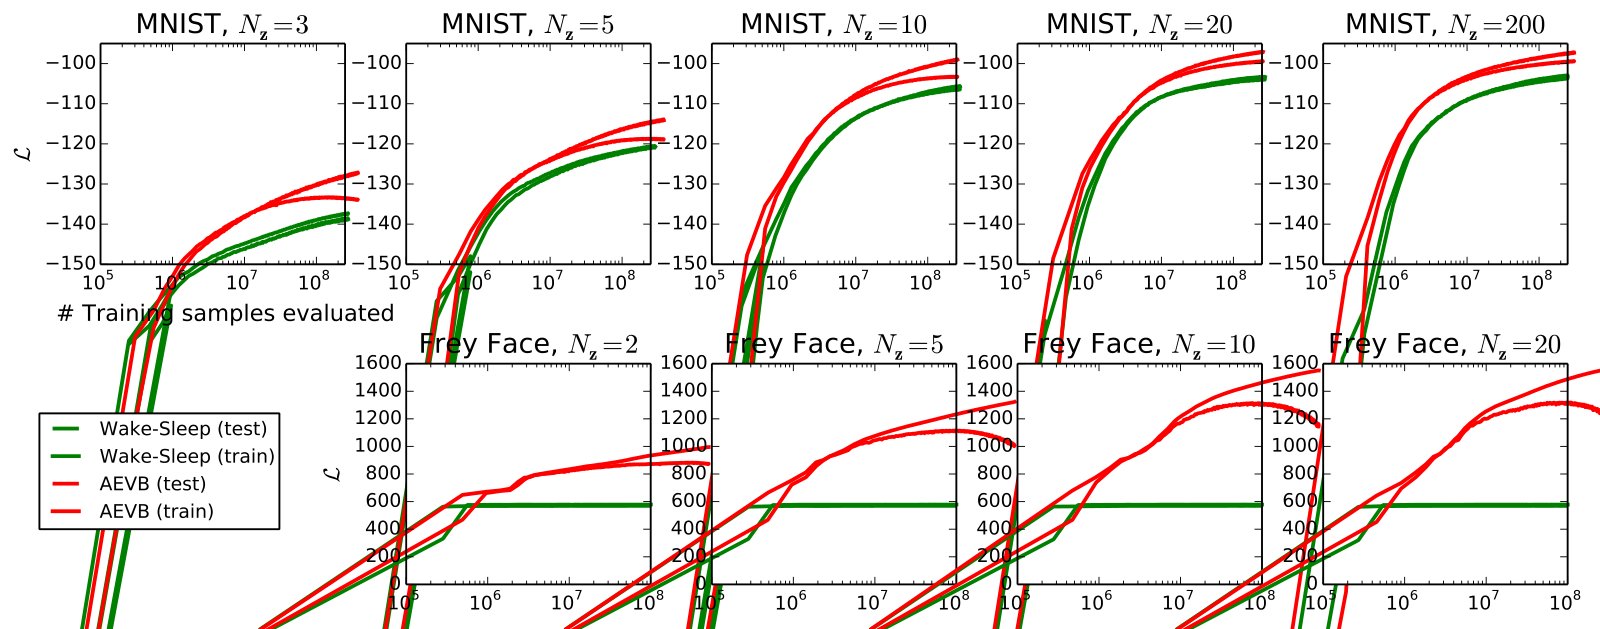
Figure 2

Figure 2: Comparison of our AEVB method to the wake-sleep algorithm, in terms of optimizing the lower bound, for different dimensionality of latent space (NzN_{\mathbf{z}}Nz​). Our method converged considerably faster and reached a better solution in all experiments. Interestingly enough, more latent variables does not result in more overfitting, which is explained by the regularizing effect of the lower bound. Vertical axis: the estimated average variational lower bound per datapoint. The estimator variance was small (<1<1<1) and omitted. Horizontal axis: amount of training points evaluated. Computation took around 20-40 minutes per million training samples with a Intel Xeon CPU running at an effective 40 GFLOPS.

图 2:就可分下界优化,在不同隐空间维数(NzN_{\mathbf{z}}Nz​)下比较我们的 AEVB 方法与 wake-sleep 算法。所有实验中我们的方法收敛明显更快并达到更好解。有趣的是,更多隐变量并未导致更多过拟合,这可由下界的正则效应解释。纵轴:每个数据点估计的平均变分下界。估计器方差很小(<1<1<1)故省略。横轴:已评估的训练点数。在有效约 40 GFLOPS 的 Intel Xeon CPU 上,每百万训练样本计算约需 20–40 分钟。

5 Experiments

5 实验

We trained generative models of images from the MNIST and Frey Face datasets[^3] and compared learning algorithms in terms of the variational lower bound, and the estimated marginal likelihood.

我们在 MNIST 与 Frey Face 数据集[^3] 上训练图像生成模型,并就可分下界与估计的边际似然比较学习算法。

The generative model (encoder) and variational approximation (decoder) from section 3 were used, where the described encoder and decoder have an equal number of hidden units. Since the Frey Face data are continuous, we used a decoder with Gaussian outputs, identical to the encoder, except that the means were constrained to the interval (0,1)(0,1)(0,1) using a sigmoidal activation function at the decoder output. Note that with hidden units we refer to the hidden layer of the neural networks of the encoder and decoder.

使用第 3 节的生成模型(解码器)与变分近似(编码器),其中所述编码器与解码器具有相同数量的隐单元。由于 Frey Face 数据是连续的,我们使用带高斯输出的解码器,与编码器相同,只是均值通过解码器输出端的 sigmoid 激活约束在区间 (0,1)(0,1)(0,1)。注意这里的隐单元指编码器与解码器神经网络的隐层。

Parameters are updated using stochastic gradient ascent where gradients are computed by differentiating the lower bound estimator ∇θ,ϕL(θ,ϕ;X)\nabla_{\boldsymbol{\theta},\boldsymbol{\phi}}\mathcal{L}(\boldsymbol{\theta},\boldsymbol{\phi};\mathbf{X})∇θ,ϕ​L(θ,ϕ;X) (see algorithm  1), plus a small weight decay term corresponding to a prior p(θ)=N(0,I)p(\boldsymbol{\theta})=\mathcal{N}(0,\mathbf{I})p(θ)=N(0,I). Optimization of this objective is equivalent to approximate MAP estimation, where the likelihood gradient is approximated by the gradient of the lower bound.

参数用随机梯度上升更新,梯度通过对下界估计器微分得到 ∇θ,ϕL(θ,ϕ;X)\nabla_{\boldsymbol{\theta},\boldsymbol{\phi}}\mathcal{L}(\boldsymbol{\theta},\boldsymbol{\phi};\mathbf{X})∇θ,ϕ​L(θ,ϕ;X)(见算法 1),外加对应先验 p(θ)=N(0,I)p(\boldsymbol{\theta})=\mathcal{N}(0,\mathbf{I})p(θ)=N(0,I) 的小权重衰减项。优化该目标等价于近似 MAP 估计,其中似然梯度由下界梯度近似。

We compared performance of AEVB to the wake-sleep algorithm [HDFN95]. We employed the same encoder (also called recognition model) for the wake-sleep algorithm and the variational auto-encoder. All parameters, both variational and generative, were initialized by random sampling from N(0,0.01)\mathcal{N}(0,0.01)N(0,0.01), and were jointly stochastically optimized using the MAP criterion. Stepsizes were adapted with Adagrad [DHS10]; the Adagrad global stepsize parameters were chosen from {0.01, 0.02, 0.1} based on performance on the training set in the first few iterations. Minibatches of size M=100M=100M=100 were used, with L=1L=1L=1 samples per datapoint.

我们将 AEVB 的表现与 wake-sleep 算法 [HDFN95] 比较。wake-sleep 与变分自编码器使用相同的编码器(也称识别模型)。所有参数(变分与生成)均从 N(0,0.01)\mathcal{N}(0,0.01)N(0,0.01) 随机初始化,并用 MAP 准则联合随机优化。步长用 Adagrad [DHS10] 自适应;Adagrad 全局步长参数从 {0.01,0.02,0.1}\{0.01, 0.02, 0.1\}{0.01,0.02,0.1} 中按前几次迭代在训练集上的表现选取。使用大小 M=100M=100M=100 的小批量。

Likelihood lower bound

似然下界

We trained generative models (decoders) and corresponding encoders (a.k.a. recognition models) having 500500500 hidden units in case of MNIST, and 200200200 hidden units in case of the Frey Face dataset (to prevent overfitting, since it is a considerably smaller dataset). The chosen number of hidden units is based on prior literature on auto-encoders, and the relative performance of different algorithms was not very sensitive to these choices. Figure 2 shows the results when comparing the lower bounds. Interestingly, superfluous latent variables did not result in overfitting, which is explained by the regularizing nature of the variational bound.

我们训练生成模型(解码器)与对应编码器(即识别模型),MNIST 用 500 个隐单元,Frey Face 用 200 个隐单元(防止过拟合,因其数据集小得多)。隐单元数基于自动编码器的先前文献选取,不同算法的相对表现对这些选择不太敏感。图 2 给出下界比较结果。有趣的是,多余的隐变量并未导致过拟合。
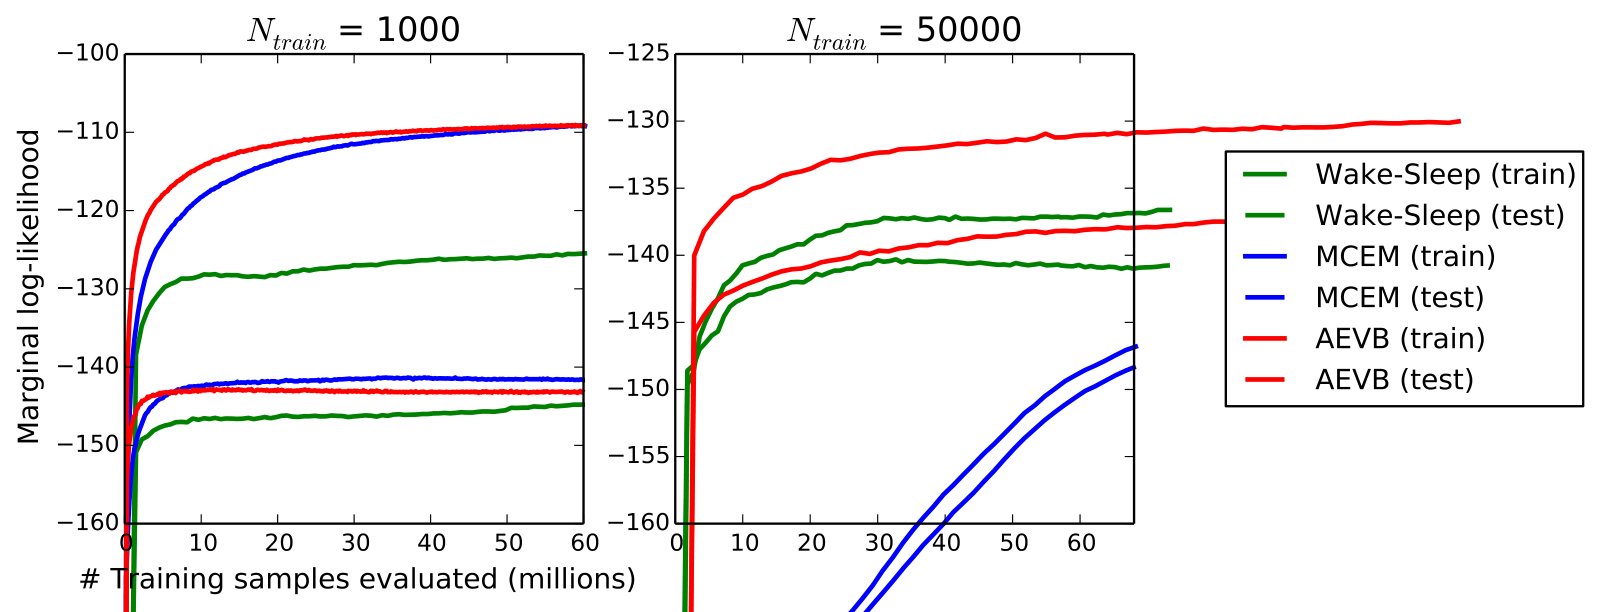
Figure 3

Figure 3: Comparison of AEVB to the wake-sleep algorithm and Monte Carlo EM, in terms of the estimated marginal likelihood, for a different number of training points. Monte Carlo EM is not an on-line algorithm, and (unlike AEVB and the wake-sleep method) can’t be applied efficiently for the full MNIST dataset.

图 3:就可估计边际似然,在不同训练点数下比较 AEVB、wake-sleep 与蒙特卡洛 EM。蒙特卡洛 EM 不是在线算法,(与 AEVB 和 wake-sleep 不同)不能高效应用于完整 MNIST 数据集。

Marginal likelihood

边际似然

For very low-dimensional latent space it is possible to estimate the marginal likelihood of the learned generative models using an MCMC estimator. More information about the marginal likelihood estimator is available in the appendix. For the encoder and decoder we again used neural networks, this time with 100 hidden units, and 3 latent variables; for higher dimensional latent space the estimates became unreliable. Again, the MNIST dataset was used. The AEVB and Wake-Sleep methods were compared to Monte Carlo EM (MCEM) with a Hybrid Monte Carlo (HMC) [DKPR87] sampler; details are in the appendix. We compared the convergence speed for the three algorithms, for a small and large training set size. Results are in figure 3.

对很低维的隐空间,可以用 MCMC 估计器估计所学生成模型的边际似然。关于边际似然估计器的更多信息见附录。编码器与解码器再次使用神经网络,此次 100 个隐单元、3 个隐变量;更高维隐空间时估计变得不可靠。仍使用 MNIST。将 AEVB 与 wake-sleep 与带 Hybrid Monte Carlo(HMC)[DKPR87] 采样器的蒙特卡洛 EM(MCEM)比较。

Visualisation of high-dimensional data

高维数据的可视化

If we choose a low-dimensional latent space (e.g. 2D), we can use the learned encoders (recognition model) to project high-dimensional data to a low-dimensional manifold. See appendix A for visualisations of the 2D latent manifolds for the MNIST and Frey Face datasets.

若选择低维隐空间(例如 2 维),可用学到的编码器(识别模型)把高维数据投影到低维流形。MNIST 与 Frey Face 数据集的二维隐流形可视化见附录 A。

6 Conclusion

6 结论

We have introduced a novel estimator of the variational lower bound, Stochastic Gradient VB (SGVB), for efficient approximate inference with continuous latent variables. The proposed estimator can be straightforwardly differentiated and optimized using standard stochastic gradient methods. For the case of i.i.d. datasets and continuous latent variables per datapoint we introduce an efficient algorithm for efficient inference and learning, Auto-Encoding VB (AEVB), that learns an approximate inference model using the SGVB estimator. The theoretical advantages are reflected in experimental results.

我们引入了变分下界的新估计器——随机梯度变分贝叶斯(SGVB),用于带连续隐变量的高效近似推断。该估计器可直接微分,并用标准随机梯度方法优化。针对 i.i.d. 数据集且每个数据点带连续隐变量的情形,我们引入高效推断与学习算法——自编码变分贝叶斯(AEVB),它用 SGVB 估计器学习近似推断模型。理论优势在实验结果中得到体现。

7 Future work

7 未来工作

Since the SGVB estimator and the AEVB algorithm can be applied to almost any inference and learning problem with continuous latent variables, there are plenty of future directions: (i) learning hierarchical generative architectures with deep neural networks (e.g. convolutional networks) used for the encoders and decoders, trained jointly with AEVB; (ii) time-series models (i.e. dynamic Bayesian networks); (iii) application of SGVB to the global parameters; (iv) supervised models with latent variables, useful for learning complicated noise distributions.

由于 SGVB 估计器与 AEVB 算法几乎可用于任何带连续隐变量的推断与学习问题,未来方向很多:(i) 用深度神经网络(例如卷积网络)作编码器与解码器,并用 AEVB 联合训练的层次生成架构;(ii) 时间序列模型(即动态贝叶斯网络);(iii) 将 SGVB 应用于全局参数;(iv) 带隐变量的监督模型,有助于学习复杂噪声分布。

References

参考文献

(a) Learned Frey Face manifold

(a) 学到的 Frey Face 流形

(a) 2-D latent space

(a) 二维隐空间

[BCV13] Yoshua Bengio, Aaron Courville, and Pascal Vincent. Representation learning: A review and new perspectives. 2013.

[BJP12] David M Blei, Michael I Jordan, and John W Paisley. Variational Bayesian inference with Stochastic Search. In Proceedings of the 29th International Conference on Machine Learning (ICML-12) , pages 1367–1374, 2012.

[BTL13] Yoshua Bengio and Éric Thibodeau-Laufer. Deep generative stochastic networks trainable by backprop. arXiv preprint arXiv:1306.1091 , 2013.

[Dev86] Luc Devroye. Sample-based non-uniform random variate generation. In Proceedings of the 18th conference on Winter simulation , pages 260–265. ACM, 1986.

[DHS10] John Duchi, Elad Hazan, and Yoram Singer. Adaptive subgradient methods for online learning and stochastic optimization. Journal of Machine Learning Research , 12:2121–2159, 2010.

[DKPR87] Simon Duane, Anthony D Kennedy, Brian J Pendleton, and Duncan Roweth. Hybrid monte carlo. Physics letters B , 195(2):216–222, 1987.

[GMW13] Karol Gregor, Andriy Mnih, and Daan Wierstra. Deep autoregressive networks. arXiv preprint arXiv:1310.8499 , 2013.

[HBWP13] Matthew D Hoffman, David M Blei, Chong Wang, and John Paisley. Stochastic variational inference. The Journal of Machine Learning Research , 14(1):1303–1347, 2013.

[HDFN95] Geoffrey E Hinton, Peter Dayan, Brendan J Frey, and Radford M Neal. The” wake-sleep” algorithm for unsupervised neural networks. SCIENCE , pages 1158–1158, 1995.

[KRL08] Koray Kavukcuoglu, Marc’Aurelio Ranzato, and Yann LeCun. Fast inference in sparse coding algorithms with applications to object recognition. Technical Report CBLL-TR-2008-12-01, Computational and Biological Learning Lab, Courant Institute, NYU, 2008.

[Lin89] Ralph Linsker. An application of the principle of maximum information preservation to linear systems . Morgan Kaufmann Publishers Inc., 1989.

[RGB13] Rajesh Ranganath, Sean Gerrish, and David M Blei. Black Box Variational Inference. arXiv preprint arXiv:1401.0118 , 2013.

[RMW14] Danilo Jimenez Rezende, Shakir Mohamed, and Daan Wierstra. Stochastic back-propagation and variational inference in deep latent gaussian models. arXiv preprint arXiv:1401.4082 , 2014.

[Row98] Sam Roweis. EM algorithms for PCA and SPCA. Advances in neural information processing systems , pages 626–632, 1998.

[SK13] Tim Salimans and David A Knowles. Fixed-form variational posterior approximation through stochastic linear regression. Bayesian Analysis , 8(4), 2013.

[SL10] Ruslan Salakhutdinov and Hugo Larochelle. Efficient learning of deep boltzmann machines. In International Conference on Artificial Intelligence and Statistics , pages 693–700, 2010.

[VLL + 10] Pascal Vincent, Hugo Larochelle, Isabelle Lajoie, Yoshua Bengio, and Pierre-Antoine Manzagol. Stacked denoising autoencoders: Learning useful representations in a deep network with a local denoising criterion. The Journal of Machine Learning Research , 9999:3371–3408, 2010.

Appendix A Visualisations

附录 A 可视化

See figures 4 and 5 for visualisations of latent space and corresponding observed space of models learned with SGVB.

用 SGVB 所学模型的隐空间与对应观测空间可视化见图 4 与图 5。

Appendix B Solution of −DKL(qϕ(z)∣∣pθ(z))-D_{KL}(q_{\boldsymbol{\phi}}(\mathbf{z})||p_{\boldsymbol{\theta}}(\mathbf{z}))−DKL​(qϕ​(z)∣∣pθ​(z)), Gaussian case

附录 B −DKL(qϕ(z)∣∣pθ(z))-D_{KL}(q_{\boldsymbol{\phi}}(\mathbf{z})||p_{\boldsymbol{\theta}}(\mathbf{z}))−DKL​(qϕ​(z)∣∣pθ​(z)) 的高斯情形解析解

The variational lower bound (the objective to be maximized) contains a KL term that can often be integrated analytically. Here we give the solution when both the prior pθ(z)=N(0,I)p_{\boldsymbol{\theta}}(\mathbf{z})=\mathcal{N}(0,\mathbf{I})pθ​(z)=N(0,I) and the posterior approximation qϕ(z∣x(i))q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x}^{(i)})qϕ​(z∣x(i)) are Gaussian. Let JJJ be the dimensionality of z\mathbf{z}z. Let μ\boldsymbol{\mu}μ and σ\boldsymbol{\sigma}σ denote the variational mean and s.d. evaluated at datapoint iii, and let μj\mu_{j}μj​ and σj\sigma_{j}σj​ simply denote the jjj-th element of these vectors. Then:

变分下界(待最大化的目标)包含一个常常可解析积分的 KL 项。这里给出先验 pθ(z)=N(0,I)p_{\boldsymbol{\theta}}(\mathbf{z})=\mathcal{N}(0,\mathbf{I})pθ​(z)=N(0,I) 与后验近似 qϕ(z∣x(i))q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x}^{(i)})qϕ​(z∣x(i)) 均为高斯时的解。设 JJJ 为 z\mathbf{z}z 的维数。令 μ\boldsymbol{\mu}μ 与 σ\boldsymbol{\sigma}σ 表示在数据点 iii 处评估的变分均值与标准差,并令 μj\mu_{j}μj​ 与 σj\sigma_{j}σj​ 表示这些向量的第 jjj 个元素。则:

∫qθ(z)log⁡p(z) dz=∫N(z;μ,σ2)log⁡N(z;0,I) dz=−J2log⁡(2π)−12∑j=1J(μj2+σj2)\displaystyle\int q_{\boldsymbol{\theta}}(\mathbf{z})\log p(\mathbf{z})\,d\mathbf{z} \\ \displaystyle=\int\mathcal{N}(\mathbf{z};\boldsymbol{\mu},\boldsymbol{\sigma}^{2})\log\mathcal{N}(\mathbf{z};\mathbf{0},\mathbf{I})\,d\mathbf{z} \\ \displaystyle=-\frac{J}{2}\log(2\pi)-\frac{1}{2}\sum_{j=1}^{J}(\mu_{j}^{2}+\sigma_{j}^{2})∫qθ​(z)logp(z)dz=∫N(z;μ,σ2)logN(z;0,I)dz=−2J​log(2π)−21​j=1∑J​(μj2​+σj2​)

And:

并且:

∫qθ(z)log⁡qθ(z) dz=∫N(z;μ,σ2)log⁡N(z;μ,σ2) dz=−J2log⁡(2π)−12∑j=1J(1+log⁡σj2)\displaystyle\int q_{\boldsymbol{\theta}}(\mathbf{z})\log q_{\boldsymbol{\theta}}(\mathbf{z})\,d\mathbf{z} \\ \displaystyle=\int\mathcal{N}(\mathbf{z};\boldsymbol{\mu},\boldsymbol{\sigma}^{2})\log\mathcal{N}(\mathbf{z};\boldsymbol{\mu},\boldsymbol{\sigma}^{2})\,d\mathbf{z} \\ \displaystyle=-\frac{J}{2}\log(2\pi)-\frac{1}{2}\sum_{j=1}^{J}(1+\log\sigma^{2}_{j})∫qθ​(z)logqθ​(z)dz=∫N(z;μ,σ2)logN(z;μ,σ2)dz=−2J​log(2π)−21​j=1∑J​(1+logσj2​)

Therefore:

因此:

−DKL((qϕ(z)∣∣pθ(z))=∫qθ(z)(log⁡pθ(z)−log⁡qθ(z)) dz=12∑j=1J(1+log⁡((σj)2)−(μj)2−(σj)2)\displaystyle-D_{KL}((q_{\boldsymbol{\phi}}(\mathbf{z})||p_{\boldsymbol{\theta}}(\mathbf{z})) \\ \displaystyle=\int q_{\boldsymbol{\theta}}(\mathbf{z})\left(\log p_{\boldsymbol{\theta}}(\mathbf{z})-\log q_{\boldsymbol{\theta}}(\mathbf{z})\right)\,d\mathbf{z} \\ \displaystyle=\frac{1}{2}\sum_{j=1}^{J}\left(1+\log((\sigma_{j})^{2})-(\mu_{j})^{2}-(\sigma_{j})^{2}\right)−DKL​((qϕ​(z)∣∣pθ​(z))=∫qθ​(z)(logpθ​(z)−logqθ​(z))dz=21​j=1∑J​(1+log((σj​)2)−(μj​)2−(σj​)2)

When using a recognition model qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x) then μ\boldsymbol{\mu}μ and s.d. σ\boldsymbol{\sigma}σ are simply functions of x\mathbf{x}x and the variational parameters ϕ\boldsymbol{\phi}ϕ, as exemplified in the text.

当使用识别模型 qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x) 时,μ\boldsymbol{\mu}μ 与标准差 σ\boldsymbol{\sigma}σ 只是 x\mathbf{x}x 与变分参数 ϕ\boldsymbol{\phi}ϕ 的函数,如正文示例。

Appendix C MLP’s as probabilistic encoders and decoders

附录 C 作为概率编码器与解码器的 MLP

In variational auto-encoders, neural networks are used as probabilistic encoders and decoders. There are many possible choices of encoders and decoders, depending on the type of data and model. In our example we used relatively simple neural networks, namely multi-layered perceptrons (MLPs). For the encoder we used a MLP with Gaussian output, while for the decoder we used MLPs with either Gaussian or Bernoulli outputs, depending on the type of data.

在变分自编码器中,神经网络被用作概率编码器与解码器。视数据类型与模型而定,编码器与解码器有许多可能选择。我们的例子使用相对简单的神经网络,即多层感知机(MLP)。编码器使用带高斯输出的 MLP,解码器视数据类型使用带高斯或 Bernoulli 输出的 MLP。

C.1 Bernoulli MLP as decoder

C.1 Bernoulli MLP 作解码器

In this case let pθ(x∣z)p_{\boldsymbol{\theta}}(\mathbf{x}|\mathbf{z})pθ​(x∣z) be a multivariate Bernoulli whose probabilities are computed from z\mathbf{z}z with a fully-connected neural network with a single hidden layer:

此时令 pθ(x∣z)p_{\boldsymbol{\theta}}(\mathbf{x}|\mathbf{z})pθ​(x∣z) 为多元 Bernoulli,其概率由带单个隐层的全连接神经网络从 z\mathbf{z}z 计算:

log⁡p(x∣z)=∑i=1Dxilog⁡yi+(1−xi)⋅log⁡(1−yi)where   y=fσ(W2tanh⁡(W1z+b1)+b2)(11)\displaystyle\log p(\mathbf{x}|\mathbf{z}) \\ \displaystyle=\sum_{i=1}^{D}x_{i}\log y_{i}+(1-x_{i})\cdot\log(1-y_{i}) \\ \displaystyle\text{where\,\,\,}\mathbf{y} \\ \displaystyle=f_{\sigma}(\mathbf{W}_{2}\tanh(\mathbf{W}_{1}\mathbf{z}+\mathbf{b}_{1})+\mathbf{b}_{2}) \tag{11}logp(x∣z)=i=1∑D​xi​logyi​+(1−xi​)⋅log(1−yi​)wherey=fσ​(W2​tanh(W1​z+b1​)+b2​)(11)

where fσ(.)f_{\sigma}(.)fσ​(.) is the elementwise sigmoid activation function, and where θ={W1,W2,b1,b2}\boldsymbol{\theta}=\{\mathbf{W}_{1},\mathbf{W}_{2},\mathbf{b}_{1},\mathbf{b}_{2}\}θ={W1​,W2​,b1​,b2​} are the weights and biases of the MLP.

其中 fσ(.)f_{\sigma}(.)fσ​(.) 为逐元素 sigmoid 激活函数,θ={W1,W2,b1,b2}\boldsymbol{\theta}=\{\mathbf{W}_{1},\mathbf{W}_{2},\mathbf{b}_{1},\mathbf{b}_{2}\}θ={W1​,W2​,b1​,b2​} 为 MLP 的权重与偏置。

C.2 Gaussian MLP as encoder or decoder

C.2 高斯 MLP 作编码器或解码器

In this case let encoder or decoder be a multivariate Gaussian with a diagonal covariance structure:

此时令编码器或解码器为具有对角协方差结构的多元高斯:

log⁡p(x∣z)=log⁡N(x;μ,σ2I)where   μ=W4h+b4log⁡σ2=W5h+b5h=tanh⁡(W3z+b3)(12)\displaystyle\log p(\mathbf{x}|\mathbf{z}) \\ \displaystyle=\log\mathcal{N}(\mathbf{x};\boldsymbol{\mu},\boldsymbol{\sigma}^{2}\mathbf{I}) \\ \displaystyle\text{where\,\,\,}\boldsymbol{\mu} \\ \displaystyle=\mathbf{W}_{4}\mathbf{h}+\mathbf{b}_{4} \\ \displaystyle\log\boldsymbol{\sigma}^{2} \\ \displaystyle=\mathbf{W}_{5}\mathbf{h}+\mathbf{b}_{5} \\ \displaystyle\mathbf{h} \\ \displaystyle=\tanh(\mathbf{W}_{3}\mathbf{z}+\mathbf{b}_{3}) \tag{12}logp(x∣z)=logN(x;μ,σ2I)whereμ=W4​h+b4​logσ2=W5​h+b5​h=tanh(W3​z+b3​)(12)

where {W3,W4,W5,b3,b4,b5}\{\mathbf{W}_{3},\mathbf{W}_{4},\mathbf{W}_{5},\mathbf{b}_{3},\mathbf{b}_{4},\mathbf{b}_{5}\}{W3​,W4​,W5​,b3​,b4​,b5​} are the weights and biases of the MLP and part of θ\boldsymbol{\theta}θ when used as decoder. Note that when this network is used as an encoder qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x), then z\mathbf{z}z and x\mathbf{x}x are swapped, and the weights and biases are variational parameters ϕ\boldsymbol{\phi}ϕ.

其中 {W3,W4,W5,b3,b4,b5}\{\mathbf{W}_{3},\mathbf{W}_{4},\mathbf{W}_{5},\mathbf{b}_{3},\mathbf{b}_{4},\mathbf{b}_{5}\}{W3​,W4​,W5​,b3​,b4​,b5​} 为 MLP 的权重与偏置,用作解码器时属于 θ\boldsymbol{\theta}θ。注意当该网络用作编码器 qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x) 时,z\mathbf{z}z 与 x\mathbf{x}x 对调,权重与偏置为变分参数 ϕ\boldsymbol{\phi}ϕ。

Appendix D Marginal likelihood estimator

附录 D 边际似然估计器

We derived the following marginal likelihood estimator that produces good estimates of the marginal likelihood as long as the dimensionality of the sampled space is low (less then 5 dimensions), and sufficient samples are taken. Let pθ(x,z)=pθ(z)pθ(x∣z)p_{\boldsymbol{\theta}}(\mathbf{x},\mathbf{z})=p_{\boldsymbol{\theta}}(\mathbf{z})p_{\boldsymbol{\theta}}(\mathbf{x}|\mathbf{z})pθ​(x,z)=pθ​(z)pθ​(x∣z) be the generative model we are sampling from, and for a given datapoint x(i)\mathbf{x}^{(i)}x(i) we would like to estimate the marginal likelihood pθ(x(i))p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)})pθ​(x(i)).

我们推导了如下边际似然估计器:只要采样空间维数较低(小于 5 维)且样本足够,就能给出良好的边际似然估计。设 pθ(x,z)=pθ(z)pθ(x∣z)p_{\boldsymbol{\theta}}(\mathbf{x},\mathbf{z})=p_{\boldsymbol{\theta}}(\mathbf{z})p_{\boldsymbol{\theta}}(\mathbf{x}|\mathbf{z})pθ​(x,z)=pθ​(z)pθ​(x∣z) 为所采样的生成模型,对给定数据点 x(i)\mathbf{x}^{(i)}x(i) 我们希望估计边际似然 pθ(x(i))p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)})pθ​(x(i))。

The estimation process consists of three stages:

估计过程分三步:

  1. Sample LLL values {z(l)}\{\mathbf{z}^{(l)}\}{z(l)} from the posterior using gradient-based MCMC, e.g. Hybrid Monte Carlo, using ∇zlog⁡pθ(z∣x)=∇zlog⁡pθ(z)+∇zlog⁡pθ(x∣z)\nabla_{\mathbf{z}}\log p_{\boldsymbol{\theta}}(\mathbf{z}|\mathbf{x})=\nabla_{\mathbf{z}}\log p_{\boldsymbol{\theta}}(\mathbf{z})+\nabla_{\mathbf{z}}\log p_{\boldsymbol{\theta}}(\mathbf{x}|\mathbf{z})∇z​logpθ​(z∣x)=∇z​logpθ​(z)+∇z​logpθ​(x∣z).
  2. Fit a density estimator q(z)q(\mathbf{z})q(z) to these samples {z(l)}\{\mathbf{z}^{(l)}\}{z(l)}.
  3. Again, sample LLL new values from the posterior. Plug these samples, as well as the fitted q(z)q(\mathbf{z})q(z), into the following estimator: pθ(x(i))≃(1L∑l=1Lq(z(l))pθ(z)pθ(x(i)∣z(l)))−1where z(l)∼pθ(z∣x(i))\displaystyle p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)})\simeq\left(\frac{1}{L}\sum_{l=1}^{L}\frac{q(\mathbf{z}^{(l)})}{p_{\boldsymbol{\theta}}(\mathbf{z})p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)}|\mathbf{z}^{(l)})}\right)^{-1}\text{\quad where \quad}\mathbf{z}^{(l)}\sim p_{\boldsymbol{\theta}}(\mathbf{z}|\mathbf{x}^{(i)})pθ​(x(i))≃(L1​l=1∑L​pθ​(z)pθ​(x(i)∣z(l))q(z(l))​)−1where z(l)∼pθ​(z∣x(i))
  1. 用基于梯度的 MCMC(例如 Hybrid Monte Carlo),借助 ∇zlog⁡pθ(z∣x)=∇zlog⁡pθ(z)+∇zlog⁡pθ(x∣z)\nabla_{\mathbf{z}}\log p_{\boldsymbol{\theta}}(\mathbf{z}|\mathbf{x})=\nabla_{\mathbf{z}}\log p_{\boldsymbol{\theta}}(\mathbf{z})+\nabla_{\mathbf{z}}\log p_{\boldsymbol{\theta}}(\mathbf{x}|\mathbf{z})∇z​logpθ​(z∣x)=∇z​logpθ​(z)+∇z​logpθ​(x∣z),从后验采样 LLL 个值 {z(l)}\{\mathbf{z}^{(l)}\}{z(l)}。
  2. 对这些样本 {z(l)}\{\mathbf{z}^{(l)}\}{z(l)} 拟合密度估计器 q(z)q(\mathbf{z})q(z)。
  3. 再次从后验采样 LLL 个新值。将这些样本以及拟合的 q(z)q(\mathbf{z})q(z) 代入如下估计器:pθ(x(i))≃(1L∑l=1Lq(z(l))pθ(z)pθ(x(i)∣z(l)))−1\displaystyle p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)})\simeq\left(\frac{1}{L}\sum_{l=1}^{L}\frac{q(\mathbf{z}^{(l)})}{p_{\boldsymbol{\theta}}(\mathbf{z})p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)}|\mathbf{z}^{(l)})}\right)^{-1}pθ​(x(i))≃(L1​l=1∑L​pθ​(z)pθ​(x(i)∣z(l))q(z(l))​)−1,其中 z(l)∼pθ(z∣x(i))\mathbf{z}^{(l)}\sim p_{\boldsymbol{\theta}}(\mathbf{z}|\mathbf{x}^{(i)})z(l)∼pθ​(z∣x(i))

Derivation of the estimator:

估计器的推导:

1pθ(x(i))=∫q(z) dzpθ(x(i))=∫q(z)pθ(x(i),z)pθ(x(i),z) dzpθ(x(i))=∫pθ(x(i),z)pθ(x(i))q(z)pθ(x(i),z) dz=∫pθ(z∣x(i))q(z)pθ(x(i),z) dz≃1L∑l=1Lq(z(l))pθ(z)pθ(x(i)∣z(l))where z(l)∼pθ(z∣x(i))\displaystyle\frac{1}{p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)})} \\ \displaystyle=\frac{\int q(\mathbf{z})\,d\mathbf{z}}{p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)})}=\frac{\int q(\mathbf{z})\frac{p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)},\mathbf{z})}{p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)},\mathbf{z})}\,d\mathbf{z}}{p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)})} \\ \displaystyle=\int\frac{p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)},\mathbf{z})}{p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)})}\frac{q(\mathbf{z})}{p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)},\mathbf{z})}\,d\mathbf{z} \\ \displaystyle=\int p_{\boldsymbol{\theta}}(\mathbf{z}|\mathbf{x}^{(i)})\frac{q(\mathbf{z})}{p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)},\mathbf{z})}\,d\mathbf{z} \\ \displaystyle\simeq\frac{1}{L}\sum_{l=1}^{L}\frac{q(\mathbf{z}^{(l)})}{p_{\boldsymbol{\theta}}(\mathbf{z})p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)}|\mathbf{z}^{(l)})}\text{\quad where \quad}\mathbf{z}^{(l)}\sim p_{\boldsymbol{\theta}}(\mathbf{z}|\mathbf{x}^{(i)})pθ​(x(i))1​=pθ​(x(i))∫q(z)dz​=pθ​(x(i))∫q(z)pθ​(x(i),z)pθ​(x(i),z)​dz​=∫pθ​(x(i))pθ​(x(i),z)​pθ​(x(i),z)q(z)​dz=∫pθ​(z∣x(i))pθ​(x(i),z)q(z)​dz≃L1​l=1∑L​pθ​(z)pθ​(x(i)∣z(l))q(z(l))​where z(l)∼pθ​(z∣x(i))

Appendix E Monte Carlo EM

附录 E 蒙特卡洛 EM

The Monte Carlo EM algorithm does not employ an encoder, instead it samples from the posterior of the latent variables using gradients of the posterior computed with ∇zlog⁡pθ(z∣x)=∇zlog⁡pθ(z)+∇zlog⁡pθ(x∣z)\nabla_{\mathbf{z}}\log p_{\boldsymbol{\theta}}(\mathbf{z}|\mathbf{x})=\nabla_{\mathbf{z}}\log p_{\boldsymbol{\theta}}(\mathbf{z})+\nabla_{\mathbf{z}}\log p_{\boldsymbol{\theta}}(\mathbf{x}|\mathbf{z})∇z​logpθ​(z∣x)=∇z​logpθ​(z)+∇z​logpθ​(x∣z). The Monte Carlo EM procedure consists of 10 HMC leapfrog steps with an automatically tuned stepsize such that the acceptance rate was 90%, followed by 5 weight updates steps using the acquired sample. For all algorithms the parameters were updated using the Adagrad stepsizes (with accompanying annealing schedule).

蒙特卡洛 EM 算法不使用编码器,而是用后验梯度 ∇zlog⁡pθ(z∣x)=∇zlog⁡pθ(z)+∇zlog⁡pθ(x∣z)\nabla_{\mathbf{z}}\log p_{\boldsymbol{\theta}}(\mathbf{z}|\mathbf{x})=\nabla_{\mathbf{z}}\log p_{\boldsymbol{\theta}}(\mathbf{z})+\nabla_{\mathbf{z}}\log p_{\boldsymbol{\theta}}(\mathbf{x}|\mathbf{z})∇z​logpθ​(z∣x)=∇z​logpθ​(z)+∇z​logpθ​(x∣z) 从隐变量后验采样。蒙特卡洛 EM 流程包括:10 步 HMC leapfrog(自动调节步长使接受率约 90%),随后用所得样本做 5 次权重更新。所有算法均用 Adagrad 步长(配合退火日程)更新参数。

The marginal likelihood was estimated with the first 1000 datapoints from the train and test sets, for each datapoint sampling 50 values from the posterior of the latent variables using Hybrid Monte Carlo with 4 leapfrog steps.

边际似然用训练集与测试集各自前 1000 个数据点估计,每个点用带 4 步 leapfrog 的 Hybrid Monte Carlo 从隐变量后验采样 50 个值。

Appendix F Full VB

附录 F 完全变分贝叶斯

As written in the paper, it is possible to perform variational inference on both the parameters θ\boldsymbol{\theta}θ and the latent variables z\mathbf{z}z, as opposed to just the latent variables as we did in the paper. Here, we’ll derive our estimator for that case.

如正文所述,可以对参数 θ\boldsymbol{\theta}θ 与隐变量 z\mathbf{z}z 同时做变分推断,而不只像正文那样只对隐变量做。这里我们推导该情形下的估计器。

Let pα(θ)p_{\boldsymbol{\alpha}}(\boldsymbol{\theta})pα​(θ) be some hyperprior for the parameters introduced above, parameterized by α\boldsymbol{\alpha}α. The marginal likelihood can be written as:

设 pα(θ)p_{\boldsymbol{\alpha}}(\boldsymbol{\theta})pα​(θ) 为上述参数的某超先验,由 α\boldsymbol{\alpha}α 参数化。边际似然可写成:

log⁡pα(X)=DKL(qϕ(θ)∣∣pα(θ∣X))+L(ϕ;X)(13)\displaystyle\log p_{\boldsymbol{\alpha}}(\mathbf{X})=D_{KL}(q_{\boldsymbol{\phi}}(\boldsymbol{\theta})||p_{\boldsymbol{\alpha}}(\boldsymbol{\theta}|\mathbf{X}))+\mathcal{L}(\boldsymbol{\phi};\mathbf{X}) \tag{13}logpα​(X)=DKL​(qϕ​(θ)∣∣pα​(θ∣X))+L(ϕ;X)(13)

where the first RHS term denotes a KL divergence of the approximate from the true posterior, and where L(ϕ;X)\mathcal{L}(\boldsymbol{\phi};\mathbf{X})L(ϕ;X) denotes the variational lower bound to the marginal likelihood:

其中右边第一项表示近似后验相对真实后验的 KL 散度,L(ϕ;X)\mathcal{L}(\boldsymbol{\phi};\mathbf{X})L(ϕ;X) 表示边际似然的变分下界:

L(ϕ;X)=∫qϕ(θ)(log⁡pθ(X)+log⁡pα(θ)−log⁡qϕ(θ)) dθ(14)\displaystyle\mathcal{L}(\boldsymbol{\phi};\mathbf{X})=\int q_{\boldsymbol{\phi}}(\boldsymbol{\theta})\left(\log p_{\boldsymbol{\theta}}(\mathbf{X})+\log p_{\boldsymbol{\alpha}}(\boldsymbol{\theta})-\log q_{\boldsymbol{\phi}}(\boldsymbol{\theta})\right)\,d\boldsymbol{\theta} \tag{14}L(ϕ;X)=∫qϕ​(θ)(logpθ​(X)+logpα​(θ)−logqϕ​(θ))dθ(14)

Note that this is a lower bound since the KL divergence is non-negative; the bound equals the true marginal when the approximate and true posteriors match exactly. The term log⁡pθ(X)\log p_{\boldsymbol{\theta}}(\mathbf{X})logpθ​(X) is composed of a sum over the marginal likelihoods of individual datapoints log⁡pθ(X)=∑i=1Nlog⁡pθ(x(i))\log p_{\boldsymbol{\theta}}(\mathbf{X})=\sum_{i=1}^{N}\log p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)})logpθ​(X)=∑i=1N​logpθ​(x(i)), which can each be rewritten as:

注意这是下界,因为 KL 散度非负;当近似后验与真实后验完全吻合时,下界等于真实边际。项 log⁡pθ(X)\log p_{\boldsymbol{\theta}}(\mathbf{X})logpθ​(X) 由各数据点边际似然之和构成 log⁡pθ(X)=∑i=1Nlog⁡pθ(x(i))\log p_{\boldsymbol{\theta}}(\mathbf{X})=\sum_{i=1}^{N}\log p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)})logpθ​(X)=∑i=1N​logpθ​(x(i)),每一个可改写为:

log⁡pθ(x(i))=DKL(qϕ(z∣x(i))∣∣pθ(z∣x(i)))+L(θ,ϕ;x(i))(15)\displaystyle\log p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)})=D_{KL}(q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x}^{(i)})||p_{\boldsymbol{\theta}}(\mathbf{z}|\mathbf{x}^{(i)}))+\mathcal{L}(\boldsymbol{\theta},\boldsymbol{\phi};\mathbf{x}^{(i)}) \tag{15}logpθ​(x(i))=DKL​(qϕ​(z∣x(i))∣∣pθ​(z∣x(i)))+L(θ,ϕ;x(i))(15)

where again the first RHS term is the KL divergence of the approximate from the true posterior, and L(θ,ϕ;x)\mathcal{L}(\boldsymbol{\theta},\boldsymbol{\phi};\mathbf{x})L(θ,ϕ;x) is the variational lower bound of the marginal likelihood of datapoint iii:

其中右边第一项同样是近似后验相对真实后验的 KL 散度,L(θ,ϕ;x)\mathcal{L}(\boldsymbol{\theta},\boldsymbol{\phi};\mathbf{x})L(θ,ϕ;x) 是数据点 iii 边际似然的变分下界:

L(θ,ϕ;x(i))=∫qϕ(z∣x)(log⁡pθ(x(i)∣z)+log⁡pθ(z)−log⁡qϕ(z∣x)) dz(16)\displaystyle\mathcal{L}(\boldsymbol{\theta},\boldsymbol{\phi};\mathbf{x}^{(i)}) \\ \displaystyle=\int q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})\left(\log p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)}|\mathbf{z})+\log p_{\boldsymbol{\theta}}(\mathbf{z})-\log q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})\right)\,d\mathbf{z} \tag{16}L(θ,ϕ;x(i))=∫qϕ​(z∣x)(logpθ​(x(i)∣z)+logpθ​(z)−logqϕ​(z∣x))dz(16)

The expectations on the RHS of eqs  (14) and (16) can obviously be written as a sum of three separate expectations, of which the second and third component can sometimes be analytically solved, e.g. when both pθ(x)p_{\boldsymbol{\theta}}(\mathbf{x})pθ​(x) and qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x) are Gaussian. For generality we will here assume that each of these expectations is intractable.

式 (14) 与 (16) 右边的期望显然可写成三个单独期望之和,其中第二、三项有时可解析求解,例如当 pθ(x)p_{\boldsymbol{\theta}}(\mathbf{x})pθ​(x) 与 qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x) 均为高斯时。为一般性,这里假定这些期望都不可积。

Under certain mild conditions outlined in section (see paper) for chosen approximate posteriors qϕ(θ)q_{\boldsymbol{\phi}}(\boldsymbol{\theta})qϕ​(θ) and qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x) we can reparameterize conditional samples z~∼qϕ(z∣x)\widetilde{\mathbf{z}}\sim q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})z∼qϕ​(z∣x) as

在正文给出的某些温和条件下,对所选近似后验 qϕ(θ)q_{\boldsymbol{\phi}}(\boldsymbol{\theta})qϕ​(θ) 与 qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x),可以把条件样本 z~∼qϕ(z∣x)\widetilde{\mathbf{z}}\sim q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})z∼qϕ​(z∣x) 重参数化为

z~=gϕ(ϵ,x)with ϵ∼p(ϵ)(17)\displaystyle\widetilde{\mathbf{z}}=g_{\boldsymbol{\phi}}(\boldsymbol{\epsilon},\mathbf{x})\text{\quad with \quad}\boldsymbol{\epsilon}\sim p(\boldsymbol{\epsilon}) \tag{17}z=gϕ​(ϵ,x)with ϵ∼p(ϵ)(17)

where we choose a prior p(ϵ)p(\boldsymbol{\epsilon})p(ϵ) and a function gϕ(ϵ,x)g_{\boldsymbol{\phi}}(\boldsymbol{\epsilon},\mathbf{x})gϕ​(ϵ,x) such that the following holds:

其中我们选择先验 p(ϵ)p(\boldsymbol{\epsilon})p(ϵ) 与函数 gϕ(ϵ,x)g_{\boldsymbol{\phi}}(\boldsymbol{\epsilon},\mathbf{x})gϕ​(ϵ,x) 使得下式成立:

L(θ,ϕ;x(i))=∫qϕ(z∣x)(log⁡pθ(x(i)∣z)+log⁡pθ(z)−log⁡qϕ(z∣x)) dz=∫p(ϵ)(log⁡pθ(x(i)∣z)+log⁡pθ(z)−log⁡qϕ(z∣x))∣z=gϕ(ϵ,x(i)) dϵ(18)\displaystyle\mathcal{L}(\boldsymbol{\theta},\boldsymbol{\phi};\mathbf{x}^{(i)}) \\ \displaystyle=\int q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})\left(\log p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)}|\mathbf{z})+\log p_{\boldsymbol{\theta}}(\mathbf{z})-\log q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})\right)\,d\mathbf{z} \\ \displaystyle=\int p(\boldsymbol{\epsilon})\left(\log p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)}|\mathbf{z})+\log p_{\boldsymbol{\theta}}(\mathbf{z})-\log q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})\right)\bigg|_{\mathbf{z}=g_{\boldsymbol{\phi}}(\boldsymbol{\epsilon},\mathbf{x}^{(i)})}\,d\boldsymbol{\epsilon} \tag{18}L(θ,ϕ;x(i))=∫qϕ​(z∣x)(logpθ​(x(i)∣z)+logpθ​(z)−logqϕ​(z∣x))dz=∫p(ϵ)(logpθ​(x(i)∣z)+logpθ​(z)−logqϕ​(z∣x))​z=gϕ​(ϵ,x(i))​dϵ(18)

The same can be done for the approximate posterior qϕ(θ)q_{\boldsymbol{\phi}}(\boldsymbol{\theta})qϕ​(θ):

对近似后验 qϕ(θ)q_{\boldsymbol{\phi}}(\boldsymbol{\theta})qϕ​(θ) 可同样处理:

θ~=hϕ(ζ)with ζ∼p(ζ)(19)\displaystyle\widetilde{\boldsymbol{\theta}}=h_{\boldsymbol{\phi}}(\boldsymbol{\zeta})\text{\quad with \quad}\boldsymbol{\zeta}\sim p(\boldsymbol{\zeta}) \tag{19}θ=hϕ​(ζ)with ζ∼p(ζ)(19)

where we, similarly as above, choose a prior p(ζ)p(\boldsymbol{\zeta})p(ζ) and a function hϕ(ζ)h_{\boldsymbol{\phi}}(\boldsymbol{\zeta})hϕ​(ζ) such that the following holds:

其中类似地,我们选择先验 p(ζ)p(\boldsymbol{\zeta})p(ζ) 与函数 hϕ(ζ)h_{\boldsymbol{\phi}}(\boldsymbol{\zeta})hϕ​(ζ) 使得下式成立:

L(ϕ;X)=∫qϕ(θ)(log⁡pθ(X)+log⁡pα(θ)−log⁡qϕ(θ)) dθ=∫p(ζ)(log⁡pθ(X)+log⁡pα(θ)−log⁡qϕ(θ))∣θ=hϕ(ζ) dζ(20)\displaystyle\mathcal{L}(\boldsymbol{\phi};\mathbf{X}) \\ \displaystyle=\int q_{\boldsymbol{\phi}}(\boldsymbol{\theta})\left(\log p_{\boldsymbol{\theta}}(\mathbf{X})+\log p_{\boldsymbol{\alpha}}(\boldsymbol{\theta})-\log q_{\boldsymbol{\phi}}(\boldsymbol{\theta})\right)\,d\boldsymbol{\theta} \\ \displaystyle=\int p(\boldsymbol{\zeta})\left(\log p_{\boldsymbol{\theta}}(\mathbf{X})+\log p_{\boldsymbol{\alpha}}(\boldsymbol{\theta})-\log q_{\boldsymbol{\phi}}(\boldsymbol{\theta})\right)\bigg|_{\boldsymbol{\theta}=h_{\boldsymbol{\phi}}(\boldsymbol{\zeta})}\,d\boldsymbol{\zeta} \tag{20}L(ϕ;X)=∫qϕ​(θ)(logpθ​(X)+logpα​(θ)−logqϕ​(θ))dθ=∫p(ζ)(logpθ​(X)+logpα​(θ)−logqϕ​(θ))​θ=hϕ​(ζ)​dζ(20)

For notational conciseness we introduce a shorthand notation fϕ(x,z,θ)f_{\boldsymbol{\phi}}(\mathbf{x},\mathbf{z},\boldsymbol{\theta})fϕ​(x,z,θ):

为记号简洁,引入简写 fϕ(x,z,θ)f_{\boldsymbol{\phi}}(\mathbf{x},\mathbf{z},\boldsymbol{\theta})fϕ​(x,z,θ):

fϕ(x,z,θ)=N⋅(log⁡pθ(x∣z)+log⁡pθ(z)−log⁡qϕ(z∣x))+log⁡pα(θ)−log⁡qϕ(θ)(21)\displaystyle f_{\boldsymbol{\phi}}(\mathbf{x},\mathbf{z},\boldsymbol{\theta})=N\cdot(\log p_{\boldsymbol{\theta}}(\mathbf{x}|\mathbf{z})+\log p_{\boldsymbol{\theta}}(\mathbf{z})-\log q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x}))+\log p_{\boldsymbol{\alpha}}(\boldsymbol{\theta})-\log q_{\boldsymbol{\phi}}(\boldsymbol{\theta}) \tag{21}fϕ​(x,z,θ)=N⋅(logpθ​(x∣z)+logpθ​(z)−logqϕ​(z∣x))+logpα​(θ)−logqϕ​(θ)(21)

Using equations  (20) and  (18), the Monte Carlo estimate of the variational lower bound, given datapoint x(i)\mathbf{x}^{(i)}x(i), is:

利用式 (20) 与 (18),给定数据点 x(i)\mathbf{x}^{(i)}x(i) 时变分下界的蒙特卡洛估计为:

L(ϕ;X)≃1L∑l=1Lfϕ(x(l),gϕ(ϵ(l),x(l)),hϕ(ζ(l)))(22)\displaystyle\mathcal{L}(\boldsymbol{\phi};\mathbf{X}) \\ \displaystyle\simeq\frac{1}{L}\sum_{l=1}^{L}f_{\boldsymbol{\phi}}(\mathbf{x}^{(l)},g_{\boldsymbol{\phi}}(\boldsymbol{\epsilon}^{(l)},\mathbf{x}^{(l)}),h_{\boldsymbol{\phi}}(\zeta^{(l)})) \tag{22}L(ϕ;X)≃L1​l=1∑L​fϕ​(x(l),gϕ​(ϵ(l),x(l)),hϕ​(ζ(l)))(22)

where ϵ(l)∼p(ϵ)\boldsymbol{\epsilon}^{(l)}\sim p(\boldsymbol{\epsilon})ϵ(l)∼p(ϵ) and ζ(l)∼p(ζ)\zeta^{(l)}\sim p(\boldsymbol{\zeta})ζ(l)∼p(ζ). The estimator only depends on samples from p(ϵ)p(\boldsymbol{\epsilon})p(ϵ) and p(ζ)p(\boldsymbol{\zeta})p(ζ) which are obviously not influenced by ϕ\boldsymbol{\phi}ϕ, therefore the estimator can be differentiated w.r.t. ϕ\boldsymbol{\phi}ϕ. The resulting stochastic gradients can be used in conjunction with stochastic optimization methods such as SGD or Adagrad [DHS10]. See algorithm 1 for a basic approach to computing stochastic gradients.

其中 ϵ(l)∼p(ϵ)\boldsymbol{\epsilon}^{(l)}\sim p(\boldsymbol{\epsilon})ϵ(l)∼p(ϵ),ζ(l)∼p(ζ)\zeta^{(l)}\sim p(\boldsymbol{\zeta})ζ(l)∼p(ζ)。估计器只依赖于来自 p(ϵ)p(\boldsymbol{\epsilon})p(ϵ) 与 p(ζ)p(\boldsymbol{\zeta})p(ζ) 的样本,它们显然不受 ϕ\boldsymbol{\phi}ϕ 影响,因此估计器可对 ϕ\boldsymbol{\phi}ϕ 微分。所得随机梯度可与 SGD 或 Adagrad [DHS10] 等随机优化方法联用。计算随机梯度的基本做法见算法 1。

ϕ\boldsymbol{\phi}ϕ (Current value of variational parameters)
g←0\mathbf{g}\leftarrow 0g←0
for lll is 111 to LLL do
x←\mathbf{x}\leftarrowx← Random draw from dataset X\mathbf{X}X
ϵ←\boldsymbol{\epsilon}\leftarrowϵ← Random draw from prior p(ϵ)p(\boldsymbol{\epsilon})p(ϵ)
ζ←\boldsymbol{\zeta}\leftarrowζ← Random draw from prior p(ζ)p(\boldsymbol{\zeta})p(ζ)
g←g+1L∇ϕfϕ(x,gϕ(ϵ,x),hϕ(ζ))\mathbf{g}\leftarrow\mathbf{g}+\frac{1}{L}\nabla_{\boldsymbol{\phi}}f_{\boldsymbol{\phi}}(\mathbf{x},g_{\boldsymbol{\phi}}(\boldsymbol{\epsilon},\mathbf{x}),h_{\boldsymbol{\phi}}(\boldsymbol{\zeta}))g←g+L1​∇ϕ​fϕ​(x,gϕ​(ϵ,x),hϕ​(ζ))
end for
return g\mathbf{g}g

Algorithm 2 Pseudocode for computing a stochastic gradient using our estimator. See text for meaning of the functions fϕf_{\boldsymbol{\phi}}fϕ​, gϕg_{\boldsymbol{\phi}}gϕ​ and hϕh_{\boldsymbol{\phi}}hϕ​.

ϕ\boldsymbol{\phi}ϕ(变分参数当前值)
g←0\mathbf{g}\leftarrow 0g←0
for lll 从 1 到 LLL do
x←\mathbf{x}\leftarrowx← 从数据集 X\mathbf{X}X 随机抽取
ϵ←\boldsymbol{\epsilon}\leftarrowϵ← 从先验 p(ϵ)p(\boldsymbol{\epsilon})p(ϵ) 随机抽取
ζ←\boldsymbol{\zeta}\leftarrowζ← 从先验 p(ζ)p(\boldsymbol{\zeta})p(ζ) 随机抽取
g←g+1L∇ϕfϕ(x,gϕ(ϵ,x),hϕ(ζ))\mathbf{g}\leftarrow\mathbf{g}+\frac{1}{L}\nabla_{\boldsymbol{\phi}}f_{\boldsymbol{\phi}}(\mathbf{x},g_{\boldsymbol{\phi}}(\boldsymbol{\epsilon},\mathbf{x}),h_{\boldsymbol{\phi}}(\boldsymbol{\zeta}))g←g+L1​∇ϕ​fϕ​(x,gϕ​(ϵ,x),hϕ​(ζ))
end for
return g\mathbf{g}g

算法 2 用我们的估计器计算随机梯度的伪代码。函数 fϕf_{\boldsymbol{\phi}}fϕ​、gϕg_{\boldsymbol{\phi}}gϕ​ 与 hϕh_{\boldsymbol{\phi}}hϕ​ 的含义见正文。

F.1 Example

F.1 示例

Let the prior over the parameters and latent variables be the centered isotropic Gaussian pα(θ)=N(z;0,I)p_{\boldsymbol{\alpha}}(\boldsymbol{\theta})=\mathcal{N}(\mathbf{z};\mathbf{0},\mathbf{I})pα​(θ)=N(z;0,I) and pθ(z)=N(z;0,I)p_{\boldsymbol{\theta}}(\mathbf{z})=\mathcal{N}(\mathbf{z};\mathbf{0},\mathbf{I})pθ​(z)=N(z;0,I). Note that in this case, the prior lacks parameters. Let’s also assume that the true posteriors are approximatily Gaussian with an approximately diagonal covariance. In this case, we can let the variational approximate posteriors be multivariate Gaussians with a diagonal covariance structure:

设参数与隐变量的先验为中心各向同性高斯 pα(θ)=N(z;0,I)p_{\boldsymbol{\alpha}}(\boldsymbol{\theta})=\mathcal{N}(\mathbf{z};\mathbf{0},\mathbf{I})pα​(θ)=N(z;0,I) 与 pθ(z)=N(z;0,I)p_{\boldsymbol{\theta}}(\mathbf{z})=\mathcal{N}(\mathbf{z};\mathbf{0},\mathbf{I})pθ​(z)=N(z;0,I)。注意此时先验没有参数。再假定真实后验近似为对角协方差的高斯。此时可令变分近似后验为具有对角协方差结构的多元高斯:

log⁡qϕ(θ)=log⁡N(θ;μθ,σθ2I)log⁡qϕ(z∣x)=log⁡N(z;μz,σz2I)(23)\displaystyle\log q_{\boldsymbol{\phi}}(\boldsymbol{\theta}) \\ \displaystyle=\log\mathcal{N}(\boldsymbol{\theta};\boldsymbol{\mu}_{\boldsymbol{\theta}},\boldsymbol{\sigma}_{\boldsymbol{\theta}}^{2}\mathbf{I}) \\ \displaystyle\log q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x}) \\ \displaystyle=\log\mathcal{N}(\mathbf{z};\boldsymbol{\mu}_{\mathbf{z}},\boldsymbol{\sigma}_{\mathbf{z}}^{2}\mathbf{I}) \tag{23}logqϕ​(θ)=logN(θ;μθ​,σθ2​I)logqϕ​(z∣x)=logN(z;μz​,σz2​I)(23)

where μz\boldsymbol{\mu}_{\mathbf{z}}μz​ and σz\boldsymbol{\sigma}_{\mathbf{z}}σz​ are yet unspecified functions of x\mathbf{x}x. Since they are Gaussian, we can parameterize the variational approximate posteriors:

其中 μz\boldsymbol{\mu}_{\mathbf{z}}μz​ 与 σz\boldsymbol{\sigma}_{\mathbf{z}}σz​ 是尚待指定的 x\mathbf{x}x 的函数。由于它们是高斯,我们可以参数化变分近似后验:

qϕ(θ)as θ~=μθ+σθ⊙ζwhere ζ∼N(0,I)qϕ(z∣x)as z~=μz+σz⊙ϵwhere ϵ∼N(0,I)\displaystyle q_{\boldsymbol{\phi}}(\boldsymbol{\theta}) \\ \displaystyle\text{\quad as \quad}\widetilde{\boldsymbol{\theta}}=\boldsymbol{\mu}_{\boldsymbol{\theta}}+\boldsymbol{\sigma}_{\boldsymbol{\theta}}\odot\boldsymbol{\zeta} \\ \displaystyle\text{\quad where \quad}\boldsymbol{\zeta}\sim\mathcal{N}(\mathbf{0},\mathbf{I}) \\ \displaystyle q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x}) \\ \displaystyle\text{\quad as \quad}\widetilde{\mathbf{z}}=\boldsymbol{\mu}_{\mathbf{z}}+\boldsymbol{\sigma}_{\mathbf{z}}\odot\boldsymbol{\epsilon} \\ \displaystyle\text{\quad where \quad}\boldsymbol{\epsilon}\sim\mathcal{N}(\mathbf{0},\mathbf{I})qϕ​(θ)as θ=μθ​+σθ​⊙ζwhere ζ∼N(0,I)qϕ​(z∣x)as z=μz​+σz​⊙ϵwhere ϵ∼N(0,I)

With ⊙\odot⊙ we signify an element-wise product. These can be plugged into the lower bound defined above (eqs (21) and (22)).

⊙\odot⊙ 表示逐元素乘积。这些可代入上面定义的下界(式 (21) 与 (22))。

In this case it is possible to construct an alternative estimator with a lower variance, since in this model pα(θ)p_{\boldsymbol{\alpha}}(\boldsymbol{\theta})pα​(θ), pθ(z)p_{\boldsymbol{\theta}}(\mathbf{z})pθ​(z), qϕ(θ)q_{\boldsymbol{\phi}}(\boldsymbol{\theta})qϕ​(θ) and qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x) are Gaussian, and therefore four terms of fϕf_{\boldsymbol{\phi}}fϕ​ can be solved analytically. The resulting estimator is:

此时可以构造方差更低的替代估计器,因为该模型中 pα(θ)p_{\boldsymbol{\alpha}}(\boldsymbol{\theta})pα​(θ)、pθ(z)p_{\boldsymbol{\theta}}(\mathbf{z})pθ​(z)、qϕ(θ)q_{\boldsymbol{\phi}}(\boldsymbol{\theta})qϕ​(θ) 与 qϕ(z∣x)q_{\boldsymbol{\phi}}(\mathbf{z}|\mathbf{x})qϕ​(z∣x) 均为高斯,因而 fϕf_{\boldsymbol{\phi}}fϕ​ 的四项可解析求解。所得估计器为:

L(ϕ;X)≃1L∑l=1LN⋅(12∑j=1J(1+log⁡((σz,j(l))2)−(μz,j(l))2−(σz,j(l))2)+log⁡pθ(x(i)z(i)))+12∑j=1J(1+log⁡((σθ,j(l))2)−(μθ,j(l))2−(σθ,j(l))2)(24)\displaystyle\mathcal{L}(\boldsymbol{\phi};\mathbf{X}) \\ \displaystyle\simeq\frac{1}{L}\sum_{l=1}^{L}N\cdot\left(\frac{1}{2}\sum_{j=1}^{J}\left(1+\log((\sigma_{\mathbf{z},j}^{(l)})^{2})-(\mu_{\mathbf{z},j}^{(l)})^{2}-(\sigma_{\mathbf{z},j}^{(l)})^{2}\right)+\log p_{\boldsymbol{\theta}}(\mathbf{x}^{(i)}\mathbf{z}^{(i)})\right) \\ \displaystyle+\frac{1}{2}\sum_{j=1}^{J}\left(1+\log((\sigma_{\boldsymbol{\theta},j}^{(l)})^{2})-(\mu_{\boldsymbol{\theta},j}^{(l)})^{2}-(\sigma_{\boldsymbol{\theta},j}^{(l)})^{2}\right) \tag{24}L(ϕ;X)≃L1​l=1∑L​N⋅(21​j=1∑J​(1+log((σz,j(l)​)2)−(μz,j(l)​)2−(σz,j(l)​)2)+logpθ​(x(i)z(i)))+21​j=1∑J​(1+log((σθ,j(l)​)2)−(μθ,j(l)​)2−(σθ,j(l)​)2)(24)

μj(i)\mu_{j}^{(i)}μj(i)​ and σj(i)\sigma_{j}^{(i)}σj(i)​ simply denote the jjj-th element of vectors μ(i)\boldsymbol{\mu}^{(i)}μ(i) and σ(i)\boldsymbol{\sigma}^{(i)}σ(i).

μj(i)\mu_{j}^{(i)}μj(i)​ 与 σj(i)\sigma_{j}^{(i)}σj(i)​ 分别表示向量 μ(i)\boldsymbol{\mu}^{(i)}μ(i) 与 σ(i)\boldsymbol{\sigma}^{(i)}σ(i) 的第 jjj 个元素。