Mastering Chess and Shogi by Self-Play with a General Reinforcement Learning Algorithm
Mastering Chess and Shogi by Self-Play with a General Reinforcement Learning Algorithm
通过自我对弈与通用强化学习算法掌握国际象棋和将棋
David Silver Thomas Hubert Julian Schrittwieser Ioannis Antonoglou Matthew Lai Affiliation: DeepMind, 6 Pancras Square, London N1C 4AG. Arthur Guez Affiliation: DeepMind, 6 Pancras Square, London N1C 4AG. Marc Lanctot Affiliation: DeepMind, 6 Pancras Square, London N1C 4AG. Affiliation: DeepMind, 6 Pancras Square, London N1C 4AG. Laurent Sifre Dharshan Kumaran Affiliation: DeepMind, 6 Pancras Square, London N1C 4AG. Thore Graepel Affiliation: DeepMind, 6 Pancras Square, London N1C 4AG. Affiliation: DeepMind, 6 Pancras Square, London N1C 4AG. Timothy Lillicrap Karen Simonyan Affiliation: DeepMind, 6 Pancras Square, London N1C 4AG. Demis Hassabis Affiliation: DeepMind, 6 Pancras Square, London N1C 4AG. Affiliation: DeepMind, 6 Pancras Square, London N1C 4AG.
Abstract
摘要
The game of chess is the most widely-studied domain in the history of artificial intelligence. The strongest programs are based on a combination of sophisticated search techniques, domain-specific adaptations, and handcrafted evaluation functions that have been refined by human experts over several decades. In contrast, the AlphaGo Zero program recently achieved superhuman performance in the game of Go, by tabula rasa reinforcement learning from games of self-play. In this paper, we generalise this approach into a single AlphaZero algorithm that can achieve, tabula rasa, superhuman performance in many challenging domains. Starting from random play, and given no domain knowledge except the game rules, AlphaZero achieved within 24 hours a superhuman level of play in the games of chess and shogi (Japanese chess) as well as Go, and convincingly defeated a world-champion program in each case.
国际象棋是人工智能历史上被研究得最充分的领域。最强的程序依赖精密的搜索技术、针对该领域的改写,以及人类专家历经数十年打磨的手工评估函数。与此相对,AlphaGo Zero 最近在围棋上达到了超人类水平,方法是从自我对弈中做 tabula rasa(从零开始)的强化学习。本文将这一思路推广为单一的 AlphaZero 算法,使它能在许多困难的领域里同样从零达到超人类水平。从随机走子出发,除游戏规则外不给任何领域知识,AlphaZero 在 24 小时内就把国际象棋、将棋(日本将棋)以及围棋都练到了超人类水平,并在每种游戏中都明显击败了当时的世界冠军程序。
The study of computer chess is as old as computer science itself. Babbage, Turing, Shannon, and von Neumann devised hardware, algorithms and theory to analyse and play the game of chess. Chess subsequently became the grand challenge task for a generation of artificial intelligence researchers, culminating in high-performance computer chess programs that perform at superhuman level [9, 13]. However, these systems are highly tuned to their domain, and cannot be generalised to other problems without significant human effort.
电脑象棋的研究几乎与计算机科学本身一样久。Babbage、Turing、Shannon 和 von Neumann 都曾设计硬件、算法和理论,用来分析和对弈国际象棋。此后,象棋成了一代人工智能研究者的“重大挑战”,最终出现了达到超人类水平的高性能电脑象棋程序 [9, 13]。不过这些系统高度贴合本领域,若要推广到其他问题上,仍需投入大量人工。
A long-standing ambition of artificial intelligence has been to create programs that can instead learn for themselves from first principles [26]. Recently, the AlphaGo Zero algorithm achieved superhuman performance in the game of Go, by representing Go knowledge using deep convolutional neural networks [22, 28], trained solely by reinforcement learning from games of self-play [29]. In this paper, we apply a similar but fully generic algorithm, which we call AlphaZero, to the games of chess and shogi as well as Go, without any additional domain knowledge except the rules of the game, demonstrating that a general-purpose reinforcement learning algorithm can achieve, tabula rasa, superhuman performance across many challenging domains.
人工智能的一个长期目标,是让程序能够从第一性原理出发自己学习 [26]。最近,AlphaGo Zero 算法在围棋上达到了超人类水平:它用深度卷积神经网络来表示围棋知识 [22, 28],训练信号完全来自自我对弈的强化学习 [29]。本文将一个相近、但完全通用的算法——我们称之为 AlphaZero——应用到国际象棋、将棋以及围棋上,除规则外不再加入任何领域知识,以表明一套通用的强化学习算法能够 tabula rasa 地在多个困难领域达到超人类水平。
A landmark for artificial intelligence was achieved in 1997 when Deep Blue defeated the human world champion [9]. Computer chess programs continued to progress steadily beyond human level in the following two decades. These programs evaluate positions using features handcrafted by human grandmasters and carefully tuned weights, combined with a high-performance alpha-beta search that expands a vast search tree using a large number of clever heuristics and domain-specific adaptations. In the Methods we describe these augmentations, focusing on the 2016 Top Chess Engine Championship (TCEC) world-champion Stockfish [25]; other strong chess programs, including Deep Blue, use very similar architectures [9, 21].
1997 年,Deep Blue 击败人类世界冠军,成为人工智能的一个里程碑 [9]。此后二十年,电脑象棋程序继续稳步超越人类水平。这些程序用人类特级大师手工设计的特征、再仔细调过的权重来评估局面,并配以高性能的 alpha-beta 搜索:它靠大量巧妙的启发式和领域特有的改写,把搜索树扩得很大。我们在“方法”一节描述这些增强,重点放在 2016 年顶级象棋引擎锦标赛(TCEC)世界冠军 Stockfish [25];包括 Deep Blue 在内的其他强程序,架构也非常接近 [9, 21]。
Shogi is a significantly harder game, in terms of computational complexity, than chess [2, 14]: it is played on a larger board, and any captured opponent piece changes sides and may subsequently be dropped anywhere on the board. The strongest shogi programs, such as Computer Shogi Association (CSA) world-champion Elmo, have only recently defeated human champions [5]. These programs use a similar algorithm to computer chess programs, again based on a highly optimised alpha-beta search engine with many domain-specific adaptations.
就计算复杂度而言,将棋明显难于国际象棋 [2, 14]:棋盘更大,而且吃掉的对方棋子会易手,随后可以打到棋盘上的任意位置。最强的将棋程序,例如计算机将棋协会(CSA)世界冠军 Elmo,直到不久前才击败人类冠军 [5]。这些程序采用与电脑象棋类似的算法,同样建立在高度优化的 alpha-beta 搜索引擎之上,并辅以大量领域特有的改写。
Go is well suited to the neural network architecture used in AlphaGo because the rules of the game are translationally invariant (matching the weight sharing structure of convolutional networks), are defined in terms of liberties corresponding to the adjacencies between points on the board (matching the local structure of convolutional networks), and are rotationally and reflectionally symmetric (allowing for data augmentation and ensembling). Furthermore, the action space is simple (a stone may be placed at each possible location), and the game outcomes are restricted to binary wins or losses, both of which may help neural network training.
围棋很适合 AlphaGo 所用的神经网络结构:规则具有平移不变性(与卷积网络的权值共享一致),用与棋盘邻接相对应的“气”来定义(与卷积的局部结构一致),并且对旋转和反射对称(便于数据增强和集成)。此外,动作空间简单(每个交叉点都可以落子),对局结果也限于胜或负,这两点都可能有利于神经网络训练。
Chess and shogi are, arguably, less innately suited to AlphaGo’s neural network architectures. The rules are position-dependent (e.g. pawns may move two steps forward from the second rank and promote on the eighth rank) and asymmetric (e.g. pawns only move forward, and castling is different on kingside and queenside). The rules include long-range interactions (e.g. the queen may traverse the board in one move, or checkmate the king from the far side of the board). The action space for chess includes all legal destinations for all of the players’ pieces on the board; shogi also allows captured pieces to be placed back on the board. Both chess and shogi may result in draws in addition to wins and losses; indeed it is believed that the optimal solution to chess is a draw [30, 20, 17].
相形之下,国际象棋和将棋可以说并不那么天然适合 AlphaGo 的网络结构。规则与位置有关(例如兵可以从第二横排一次走两格,并在第八横排升变),而且不对称(兵只能向前走,短易位和长易位也不同)。规则里还有长程交互(后可以一步走遍棋盘,也可以从远处将死王)。象棋的动作空间包含己方所有棋子的全部合法落点;将棋还允许把吃到的棋子打回棋盘。两种游戏除了胜负之外都可能和棋;事实上,一般认为象棋的最优解是和棋 [30, 20, 17]。
The AlphaZero algorithm is a more generic version of the AlphaGo Zero algorithm that was first introduced in the context of Go [29]. It replaces the handcrafted knowledge and domain-specific augmentations used in traditional game-playing programs with deep neural networks and a tabula rasa reinforcement learning algorithm.
AlphaZero 算法是 AlphaGo Zero 算法的更通用版本,后者最初是在围棋语境下提出的 [29]。它用深度神经网络和 tabula rasa 强化学习,取代了传统对弈程序里的手工知识和领域特有增强。
Instead of a handcrafted evaluation function and move ordering heuristics, AlphaZero utilises a deep neural network with parameters . This neural network takes the board position as an input and outputs a vector of move probabilities with components for each action , and a scalar value estimating the expected outcome from position , . AlphaZero learns these move probabilities and value estimates entirely from self-play; these are then used to guide its search.
不再使用手工评估函数和着法排序启发式,AlphaZero 采用带参数 的深度神经网络 。网络以棋盘局面 为输入,输出着法概率向量 ,其分量 对应每个动作 ,以及一个标量价值 ,用来估计从局面 出发的期望结果 ,即 。这些着法概率和价值估计完全从自我对弈中学得,再用来引导搜索。
Instead of an alpha-beta search with domain-specific enhancements, AlphaZero uses a general-purpose Monte-Carlo tree search (MCTS) algorithm. Each search consists of a series of simulated games of self-play that traverse a tree from root to leaf. Each simulation proceeds by selecting in each state a move with low visit count, high move probability and high value (averaged over the leaf states of simulations that selected from ) according to the current neural network . The search returns a vector representing a probability distribution over moves, either proportionally or greedily with respect to the visit counts at the root state.
不再使用带领域特有增强的 alpha-beta 搜索,AlphaZero 采用通用的蒙特卡洛树搜索(MCTS)。每次搜索由一系列从根节点 走到叶子的自我对弈模拟构成。在每个状态 ,模拟会根据当前网络 ,选择访问次数较低、着法概率较高、价值较高(对该从 选出 的那些模拟,取其叶子状态的平均)的着法 。搜索返回一个表示着法概率分布的向量 ,可以按根节点的访问次数成比例采样,也可以对其贪心取值。
The parameters of the deep neural network in AlphaZero are trained by self-play reinforcement learning, starting from randomly initialised parameters . Games are played by selecting moves for both players by MCTS, . At the end of the game, the terminal position is scored according to the rules of the game to compute the game outcome : for a loss, for a draw, and for a win. The neural network parameters are updated so as to minimise the error between the predicted outcome and the game outcome , and to maximise the similarity of the policy vector to the search probabilities . Specifically, the parameters are adjusted by gradient descent on a loss function that sums over mean-squared error and cross-entropy losses respectively,
AlphaZero 中深度网络的参数 通过自我对弈强化学习来训练,从随机初始化的 起步。对局中双方都用 MCTS 来选着,。对局结束时,按规则给终局 计分,得到结果 :负为 ,和为 ,胜为 。更新参数 ,使预测结果 与对局结果 的误差尽量小,并使策略向量 尽量接近搜索概率 。具体地,用梯度下降最小化损失函数 ,它分别把均方误差和交叉熵损失加在一起,
where is a parameter controlling the level of weight regularisation. The updated parameters are used in subsequent games of self-play.
其中 控制 权值正则的强度。更新后的参数用于后续的自我对弈。
The AlphaZero algorithm described in this paper differs from the original AlphaGo Zero algorithm in several respects.
本文描述的 AlphaZero 算法与最初的 AlphaGo Zero 算法有几处不同。
AlphaGo Zero estimates and optimises the probability of winning, assuming binary win/loss outcomes. AlphaZero instead estimates and optimises the expected outcome, taking account of draws or potentially other outcomes.
AlphaGo Zero 估计并优化的是获胜概率,并假定结果只有胜或负。AlphaZero 则估计并优化期望结果,从而把和棋或其他可能的结局也考虑进去。
The rules of Go are invariant to rotation and reflection. This fact was exploited in AlphaGo and AlphaGo Zero in two ways. First, training data was augmented by generating 8 symmetries for each position. Second, during MCTS, board positions were transformed using a randomly selected rotation or reflection before being evaluated by the neural network, so that the Monte-Carlo evaluation is averaged over different biases. The rules of chess and shogi are asymmetric, and in general symmetries cannot be assumed. AlphaZero does not augment the training data and does not transform the board position during MCTS.
围棋规则对旋转和反射不变。AlphaGo 和 AlphaGo Zero 从两方面利用了这一点。第一,训练数据会为每个局面生成 8 种对称。第二,在 MCTS 中,把棋盘先随机旋转或反射再送入网络评估,使蒙特卡洛评估能对各种偏差取平均。国际象棋和将棋的规则并不对称,一般不能假定存在这类对称。AlphaZero 既不增强训练数据,也不在 MCTS 中变换棋盘。
In AlphaGo Zero, self-play games were generated by the best player from all previous iterations. After each iteration of training, the performance of the new player was measured against the best player; if it won by a margin of then it replaced the best player and self-play games were subsequently generated by this new player. In contrast, AlphaZero simply maintains a single neural network that is updated continually, rather than waiting for an iteration to complete. Self-play games are generated by using the latest parameters for this neural network, omitting the evaluation step and the selection of best player.
在 AlphaGo Zero 里,自我对弈由截至当时所有迭代中的最佳棋手来生成。每次训练迭代结束后,用新棋手对阵最佳棋手;若胜率超过 ,就替换最佳棋手,之后的自我对弈改由这个新棋手生成。相比之下,AlphaZero 只维护一个持续更新的神经网络,不必等一次迭代结束。自我对弈直接使用该网络的最新参数,省去了评估步骤和最佳棋手的筛选。
AlphaGo Zero tuned the hyper-parameter of its search by Bayesian optimisation. In AlphaZero we reuse the same hyper-parameters for all games without game-specific tuning. The sole exception is the noise that is added to the prior policy to ensure exploration [29]; this is scaled in proportion to the typical number of legal moves for that game type.
AlphaGo Zero 用贝叶斯优化来调节搜索超参数。在 AlphaZero 中,我们对所有游戏复用同一组超参数,不做针对游戏的微调。唯一的例外是为了保证探索而加到先验策略上的噪声 [29];它按该游戏典型合法着法数成比例缩放。
Like AlphaGo Zero, the board state is encoded by spatial planes based only on the basic rules for each game. The actions are encoded by either spatial planes or a flat vector, again based only on the basic rules for each game (see Methods).
与 AlphaGo Zero 一样,棋盘状态只用基于各游戏基本规则的空间平面来编码。动作则用空间平面或扁平向量编码,同样只依据各游戏的基本规则(见“方法”)。
We applied the AlphaZero algorithm to chess, shogi, and also Go. Unless otherwise specified, the same algorithm settings, network architecture, and hyper-parameters were used for all three games. We trained a separate instance of AlphaZero for each game. Training proceeded for 700,000 steps (mini-batches of size 4,096) starting from randomly initialised parameters, using 5,000 first-generation TPUs [15] to generate self-play games and 64 second-generation TPUs to train the neural networks.[^1] Further details of the training procedure are provided in the Methods.
[^1]: The original AlphaGo Zero paper used GPUs to train the neural networks.
我们将 AlphaZero 算法应用到国际象棋、将棋,以及围棋。除非另有说明,三种游戏使用相同的算法设置、网络结构和超参数。每种游戏单独训练一个 AlphaZero 实例。训练进行 700,000 步(小批量大小为 4,096),参数从随机初始化开始,用 5,000 块第一代 TPU [15] 生成自我对弈,用 64 块第二代 TPU 训练神经网络。[^1] 训练流程的更多细节见“方法”。
[^1]: 最初的 AlphaGo Zero 论文用 GPU 来训练神经网络。
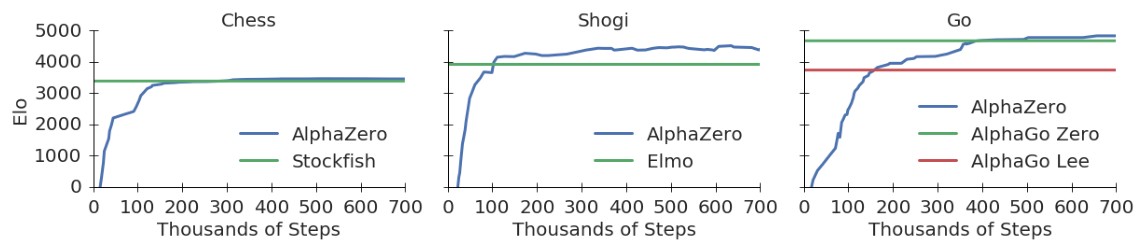
Figure 1: Training AlphaZero for 700,000 steps. Elo ratings were computed from evaluation games between different players when given one second per move. a Performance of AlphaZero in chess, compared to 2016 TCEC world-champion program Stockfish. b Performance of AlphaZero in shogi, compared to 2017 CSA world-champion program Elmo. c Performance of AlphaZero in Go, compared to AlphaGo Lee and AlphaGo Zero (20 block / 3 day) [29].
图 1:将 AlphaZero 训练 700,000 步。Elo 等级分由不同棋手在每步思考 1 秒的评估对局中计算。a AlphaZero 在国际象棋上的表现,对照 2016 年 TCEC 世界冠军程序 Stockfish。b AlphaZero 在将棋上的表现,对照 2017 年 CSA 世界冠军程序 Elmo。c AlphaZero 在围棋上的表现,对照 AlphaGo Lee 以及 AlphaGo Zero(20 个残差块 / 训练 3 天)[29]。
Figure 1 shows the performance of AlphaZero during self-play reinforcement learning, as a function of training steps, on an Elo scale [10]. In chess, AlphaZero outperformed Stockfish after just 4 hours (300k steps); in shogi, AlphaZero outperformed Elmo after less than 2 hours (110k steps); and in Go, AlphaZero outperformed AlphaGo Lee [29] after 8 hours (165k steps).[^2]
[^2]: AlphaGo Master and AlphaGo Zero were ultimately trained for 100 times this length of time; we do not reproduce that effort here.
图 1 给出了 AlphaZero 在自我对弈强化学习过程中的表现,横轴是训练步数,纵轴是 Elo 等级分 [10]。在国际象棋上,AlphaZero 只用 4 小时(30 万步)就超过了 Stockfish;在将棋上,不到 2 小时(11 万步)就超过了 Elmo;在围棋上,8 小时(16.5 万步)就超过了 AlphaGo Lee [29]。[^2]
[^2]: AlphaGo Master 和 AlphaGo Zero 最终的训练时长是这里的 100 倍;我们没有在此重复那一规模的训练。
We evaluated the fully trained instances of AlphaZero against Stockfish, Elmo and the previous version of AlphaGo Zero (trained for 3 days) in chess, shogi and Go respectively, playing 100 game matches at tournament time controls of one minute per move. AlphaZero and the previous AlphaGo Zero used a single machine with 4 TPUs. Stockfish and Elmo played at their strongest skill level using 64 threads and a hash size of 1GB. AlphaZero convincingly defeated all opponents, losing zero games to Stockfish and eight games to Elmo (see Supplementary Material for several example games), as well as defeating the previous version of AlphaGo Zero (see Table 1).
我们将训练完成的 AlphaZero 分别在国际象棋、将棋和围棋上,与 Stockfish、Elmo 以及此前版本的 AlphaGo Zero(训练 3 天)对阵,各下 100 局,时限为每步 1 分钟。AlphaZero 和此前的 AlphaGo Zero 使用单机 4 块 TPU。Stockfish 和 Elmo 以最强级别运行,使用 64 个线程、1GB 哈希表。AlphaZero 明显击败了所有对手:对 Stockfish 一局未负,对 Elmo 只负 8 局(若干示例对局见补充材料),同时也击败了此前版本的 AlphaGo Zero(见表 1)。
| Game | White | Black | Win | Draw | Loss |
|---|---|---|---|---|---|
| Chess | AlphaZero | Stockfish | 25 | 25 | 0 |
| Stockfish | AlphaZero | 3 | 47 | 0 | |
| Shogi | AlphaZero | Elmo | 43 | 2 | 5 |
| Elmo | AlphaZero | 47 | 0 | 3 | |
| Go | AlphaZero | AG0 3-day | 31 | – | 19 |
| AG0 3-day | AlphaZero | 29 | – | 21 |
Table 1: Tournament evaluation of AlphaZero in chess, shogi, and Go, as games won, drawn or lost from AlphaZero’s perspective, in 100 game matches against Stockfish, Elmo, and the previously published AlphaGo Zero after 3 days of training. Each program was given 1 minute of thinking time per move.
| 游戏 | 白方 | 黑方 | 胜 | 和 | 负 |
|---|---|---|---|---|---|
| 国际象棋 | AlphaZero | Stockfish | 25 | 25 | 0 |
| Stockfish | AlphaZero | 3 | 47 | 0 | |
| 将棋 | AlphaZero | Elmo | 43 | 2 | 5 |
| Elmo | AlphaZero | 47 | 0 | 3 | |
| 围棋 | AlphaZero | AG0 3-day | 31 | – | 19 |
| AG0 3-day | AlphaZero | 29 | – | 21 |
表 1:AlphaZero 在国际象棋、将棋和围棋上的循环赛评估,以 AlphaZero 的视角统计胜、和、负;各与 Stockfish、Elmo 以及此前发表的、训练 3 天的 AlphaGo Zero 进行 100 局对抗。每个程序每步有 1 分钟思考时间。
We also analysed the relative performance of AlphaZero’s MCTS search compared to the state-of-the-art alpha-beta search engines used by Stockfish and Elmo. AlphaZero searches just 80 thousand positions per second in chess and 40 thousand in shogi, compared to 70 million for Stockfish and 35 million for Elmo. AlphaZero compensates for the lower number of evaluations by using its deep neural network to focus much more selectively on the most promising variations – arguably a more “human-like” approach to search, as originally proposed by Shannon [27]. Figure 2 shows the scalability of each player with respect to thinking time, measured on an Elo scale, relative to Stockfish or Elmo with 40ms thinking time. AlphaZero’s MCTS scaled more effectively with thinking time than either Stockfish or Elmo, calling into question the widely held belief [4, 11] that alpha-beta search is inherently superior in these domains.[^3]
[^3]: The prevalence of draws in high-level chess tends to compress the Elo scale, compared to shogi or Go.
我们还分析了 AlphaZero 的 MCTS 搜索,相对于 Stockfish 和 Elmo 所用的最先进 alpha-beta 搜索引擎的表现。AlphaZero 在国际象棋上每秒只搜索 8 万个局面,在将棋上是 4 万个,而 Stockfish 是 7,000 万,Elmo 是 3,500 万。评估次数更少,AlphaZero 靠深度神经网络把搜索更有选择地集中到最有希望的变化上——这可以说更接近 Shannon 最初提出的“像人一样”的搜索方式 [27]。图 2 给出各棋手随思考时间变化的可扩展性,用 Elo 量表衡量,并以思考时间为 40 毫秒的 Stockfish 或 Elmo 为参照。AlphaZero 的 MCTS 随思考时间的扩展,比 Stockfish 或 Elmo 都更有效,这使人们开始怀疑那种认为 alpha-beta 搜索在这些领域天生更优的流行看法 [4, 11]。[^3]
[^3]: 高水平国际象棋中和棋很多,往往会压缩 Elo 量表,将棋和围棋则没有这个问题那么突出。
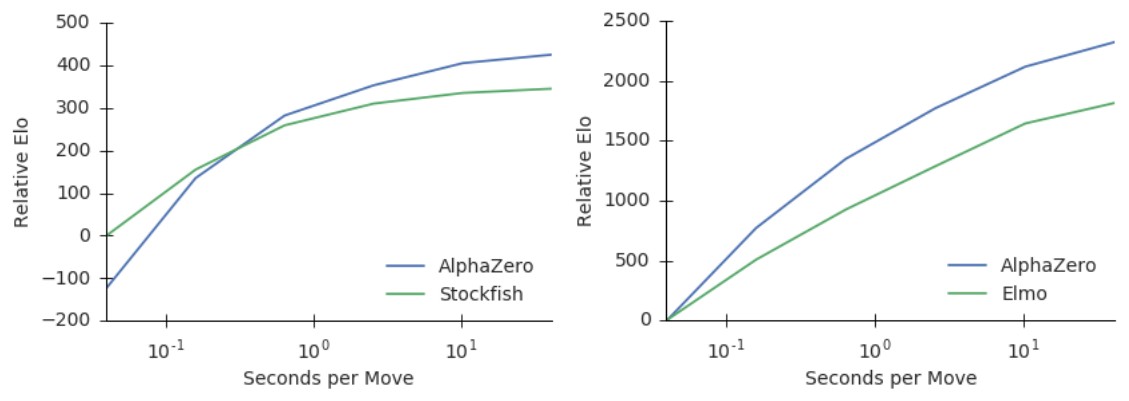
Figure 2: Scalability of AlphaZero with thinking time, measured on an Elo scale. a Performance of AlphaZero and Stockfish in chess, plotted against thinking time per move. b Performance of AlphaZero and Elmo in shogi, plotted against thinking time per move.
图 2:AlphaZero 随思考时间变化的可扩展性,以 Elo 量表衡量。a AlphaZero 与 Stockfish 在国际象棋上的表现,横轴为每步思考时间。b AlphaZero 与 Elmo 在将棋上的表现,横轴为每步思考时间。
Finally, we analysed the chess knowledge discovered by AlphaZero. Table 2 analyses the most common human openings (those played more than 100,000 times in an online database of human chess games [1]). Each of these openings is independently discovered and played frequently by AlphaZero during self-play training. When starting from each human opening, AlphaZero convincingly defeated Stockfish, suggesting that it has indeed mastered a wide spectrum of chess play.
最后,我们分析了 AlphaZero 发现的国际象棋知识。表 2 分析了最常见的人类开局(在一个在线人类对局库中出现超过 10 万次的那些 [1])。这些开局都由 AlphaZero 在自我对弈训练中独立发现,并且经常被走出。从每一种人类开局出发,AlphaZero 都明显击败了 Stockfish,说明它确实掌握了相当宽的下棋谱系。
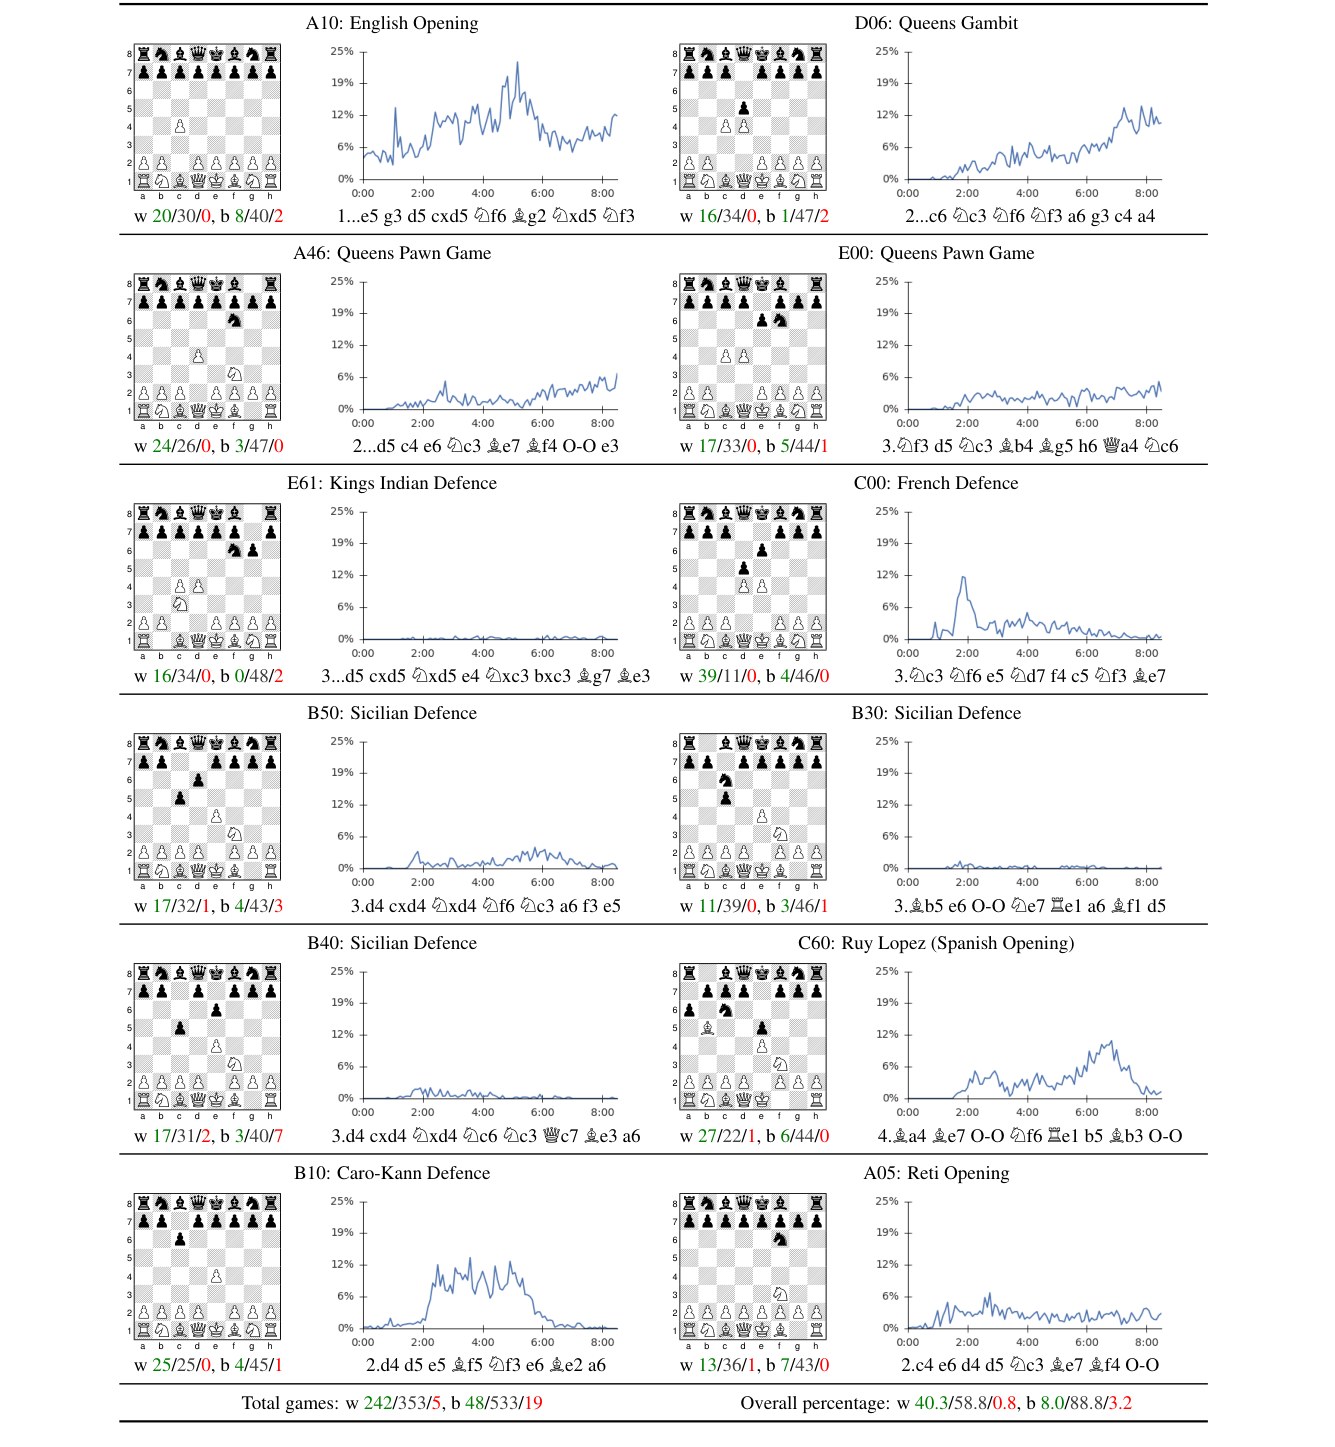
Table 2: Analysis of the 12 most popular human openings (played more than 100,000 times in an online database [1]). Each opening is labelled by its ECO code and common name. The plot shows the proportion of self-play training games in which AlphaZero played each opening, against training time. We also report the win/draw/loss results of 100 game AlphaZero vs. Stockfish matches starting from each opening, as either white (w) or black (b), from AlphaZero’s perspective. Finally, the principal variation (PV) of AlphaZero is provided from each opening.
表 2:对 12 种最常见人类开局的分析(在一个在线棋库中出现超过 10 万次 [1])。每种开局用 ECO 编号和通用名称标注。图中给出自我对弈训练里 AlphaZero 走出该开局的比例随训练时间的变化。我们还报告从该开局出发、AlphaZero 对 Stockfish 各 100 局的胜/和/负结果,执白记为 w、执黑记为 b,均从 AlphaZero 的视角统计。最后给出 AlphaZero 在各开局上的主要变化(PV)。
The game of chess represented the pinnacle of AI research over several decades. State-of-the-art programs are based on powerful engines that search many millions of positions, leveraging handcrafted domain expertise and sophisticated domain adaptations. AlphaZero is a generic reinforcement learning algorithm – originally devised for the game of Go – that achieved superior results within a few hours, searching a thousand times fewer positions, given no domain knowledge except the rules of chess. Furthermore, the same algorithm was applied without modification to the more challenging game of shogi, again outperforming the state of the art within a few hours.
几十年来,国际象棋一直被看作人工智能研究的巅峰。最先进的程序依靠强大的引擎搜索数以百万计的局面,并借助手工领域专长和精巧的领域改写。AlphaZero 则是一套通用的强化学习算法——最初是为围棋设计的——它在几小时内就取得了更优的结果,搜索的局面数少了约一千倍,除象棋规则外不使用其他领域知识。同一套算法不加修改地用到更难的将棋上,同样在几小时内超过了当时的最先进水平。
References
参考文献
[1] Online chess games database, 365chess, 2017. URL: https://www.365chess.com/ .
[2] Victor Allis. Searching for Solutions in Games and Artificial Intelligence . PhD thesis, University of Limburg, Netherlands, 1994.
[3] Thomas Anthony, Zheng Tian, and David Barber. Thinking fast and slow with deep learning and tree search. In Advances in Neural Information Processing Systems 30: Annual Conference on Neural Information Processing Systems 2017, 4-9 December 2017, Long Beach, CA, USA , pages 5366–5376, 2017.
[4] Oleg Arenz. Monte Carlo chess. Master’s thesis, Technische Universitat Darmstadt, 2012.
[5] Computer Shogi Association. Results of the 27th world computer shogi championship. http://www2.computer-shogi.org/wcsc27/index_e.html . Retrieved November 29th, 2017.
[6] J. Baxter, A. Tridgell, and L. Weaver. Learning to play chess using temporal differences. Machine Learning , 40(3):243–263, 2000.
[7] Donald F. Beal and Martin C. Smith. Temporal difference learning for heuristic search and game playing. Inf. Sci. , 122(1):3–21, 2000.
[8] Donald F. Beal and Martin C. Smith. Temporal difference learning applied to game playing and the results of application to shogi. Theoretical Computer Science , 252(1–2):105–119, 2001.
[9] M. Campbell, A. J. Hoane, and F. Hsu. Deep Blue. Artificial Intelligence , 134:57–83, 2002.
[10] R. Coulom. Whole-history rating: A Bayesian rating system for players of time-varying strength. In International Conference on Computers and Games , pages 113–124, 2008.
[11] Omid E David, Nathan S Netanyahu, and Lior Wolf. Deepchess: End-to-end deep neural network for automatic learning in chess. In International Conference on Artificial Neural Networks , pages 88–96. Springer, 2016.
[12] Kunihito Hoki and Tomoyuki Kaneko. Large-scale optimization for evaluation functions with minimax search. Journal of Artificial Intelligence Research (JAIR) , 49:527–568, 2014.
[13] Feng-hsiung Hsu. Behind Deep Blue: Building the Computer that Defeated the World Chess Champion . Princeton University Press, 2002.
[14] Hiroyuki Iida, Makoto Sakuta, and Jeff Rollason. Computer shogi. Artificial Intelligence , 134:121–144, 2002.
[15] Norman P. Jouppi, Cliff Young, Nishant Patil, et al. In-datacenter performance analysis of a tensor processing unit. In Proceedings of the 44th Annual International Symposium on Computer Architecture , ISCA ’17, pages 1–12. ACM, 2017.
[16] Tomoyuki Kaneko and Kunihito Hoki. Analysis of evaluation-function learning by comparison of sibling nodes. In Advances in Computer Games - 13th International Conference, ACG 2011, Tilburg, The Netherlands, November 20-22, 2011, Revised Selected Papers , pages 158–169, 2011.
[17] John Knudsen. Essential Chess Quotations . iUniverse, 2000.
[18] D. E. Knuth and R. W Moore. An analysis of alpha–beta pruning. Artificial Intelligence , 6(4):293––326, 1975.
[19] Matthew Lai. Giraffe: Using deep reinforcement learning to play chess. Master’s thesis, Imperial College London, 2015.
[20] Emanuel Lasker. Common Sense in Chess . Dover Publications, 1965.
[21] David N. L. Levy and Monty Newborn. How Computers Play Chess . Ishi Press, 2009.
[22] Chris J. Maddison, Aja Huang, Ilya Sutskever, and David Silver. Move evaluation in Go using deep convolutional neural networks. In International Conference on Learning Representations , 2015.
[23] Tony Marsland. Computer chess methods. In S. Shapiro, editor, Encyclopedia of Artificial Intelligence . John Wiley & sons, New York, 1987.
[24] Raghuram Ramanujan, Ashish Sabharwal, and Bart Selman. Understanding sampling style adversarial search methods. In Proceedings of the 26th Conference on Uncertainty in Artificial Intelligence (UAI) , 2010.
[25] Tord Romstad, Marco Costalba, Joona Kiiski, et al. Stockfish: A strong open source chess engine. https://stockfishchess.org/ . Retrieved November 29th, 2017.
[26] A. L. Samuel. Some studies in machine learning using the game of checkers II - recent progress. IBM Journal of Research and Development , 11(6):601–617, 1967.
[27] Claude E Shannon. Xxii. programming a computer for playing chess. The London, Edinburgh, and Dublin Philosophical Magazine and Journal of Science , 41(314):256–275, 1950.
[28] David Silver, Aja Huang, Chris J. Maddison, Arthur Guez, Laurent Sifre, George van den Driessche, Julian Schrittwieser, Ioannis Antonoglou, Veda Panneershelvam, Marc Lanctot, Sander Dieleman, Dominik Grewe, John Nham, Nal Kalchbrenner, Ilya Sutskever, Timothy Lillicrap, Madeleine Leach, Koray Kavukcuoglu, Thore Graepel, and Demis Hassabis. Mastering the game of Go with deep neural networks and tree search. Nature , 529(7587):484–489, January 2016.
[29] David Silver, Julian Schrittwieser, Karen Simonyan, Ioannis Antonoglou, Aja Huang, Arthur Guez, Thomas Hubert, Lucas Baker, Matthew Lai, Adrian Bolton, Yutian Chen, Timothy Lillicrap, Fan Hui, Laurent Sifre, George van den Driessche, Thore Graepel, and Demis Hassabis. Mastering the game of go without human knowledge. Nature , 550:354–359, 2017.
[30] Wilhelm Steinitz. The Modern Chess Instructor . Edition Olms AG, 1990.
[31] Sebastian Thrun. Learning to play the game of chess. In Advances in neural information processing systems , pages 1069–1076, 1995.
[32] J. Veness, D. Silver, A. Blair, and W. Uther. Bootstrapping from game tree search. In Advances in Neural Information Processing Systems , pages 1937–1945, 2009.
Methods
方法
Anatomy of a Computer Chess Program
电脑象棋程序的结构
In this section we describe the components of a typical computer chess program, focusing specifically on Stockfish[25], an open source program that won the 2016 TCEC computer chess championship. For an overview of standard methods, see [23].
本节描述典型电脑象棋程序的组成部分,重点放在 Stockfish [25],这是一个赢得 2016 年 TCEC 电脑象棋冠军的开源程序。关于标准方法的综述,见 [23]。
Each position is described by a sparse vector of handcrafted features , including midgame/endgame-specific material point values, material imbalance tables, piece-square tables, mobility and trapped pieces, pawn structure, king safety, outposts, bishop pair, and other miscellaneous evaluation patterns. Each feature is assigned, by a combination of manual and automatic tuning, a corresponding weight and the position is evaluated by a linear combination . However, this raw evaluation is only considered accurate for positions that are “quiet”, with no unresolved captures or checks. A domain-specialised quiescence search is used to resolve ongoing tactical situations before the evaluation function is applied.
每个局面 由一个稀疏的手工特征向量 描述,包括中局/残局各自的子力分、子力不平衡表、棋子-格子表、活动性与被困棋子、兵形、王的安全、前哨、双象,以及其他杂项评估模式。每个特征 通过人工与自动调参相结合,被赋予相应权重 ,局面由线性组合 来评估。不过,这种原始评估只对“安静”的局面——没有尚未解决的吃子或将军——才被认为准确。程序会先用专门的 静态搜索(quiescence search)把正在进行的战术清算完,再调用评估函数。
The final evaluation of a position is computed by a minimax search that evaluates each leaf using a quiescence search. Alpha-beta pruning is used to safely cut any branch that is provably dominated by another variation. Additional cuts are achieved using aspiration windows and principal variation search. Other pruning strategies include null move pruning (which assumes a pass move should be worse than any variation, in positions that are unlikely to be in zugzwang, as determined by simple heuristics), futility pruning (which assumes knowledge of the maximum possible change in evaluation), and other domain-dependent pruning rules (which assume knowledge of the value of captured pieces).
局面 的最终评估由极小极大搜索计算,每个叶子再用静态搜索来评估。alpha-beta 剪枝用来安全地砍掉那些已被另一变化支配的分支。另外还用渴望窗口和主要变化搜索来增加剪枝。其他剪枝策略包括空着剪枝(在不太可能处于 zugzwang(逼着)的局面中,假定虚着应差于任何实际变化,是否逼着用简单启发式判断)、无效着剪枝(假定已知评估可能的最大变化),以及其他依赖领域知识的剪枝规则(假定已知被吃子的价值)。
The search is focused on promising variations both by extending the search depth of promising variations, and by reducing the search depth of unpromising variations based on heuristics like history, static-exchange evaluation (SEE), and moving piece type. Extensions are based on domain-independent rules that identify singular moves with no sensible alternative, and domain-dependent rules, such as extending check moves. Reductions, such as late move reductions, are based heavily on domain knowledge.
搜索既会加深有希望的变化,也会根据历史、静态交换评估(SEE)和走动棋子种类等启发式,缩短没有希望的变化的深度,从而把计算集中到更有前途的变化上。延伸基于与领域无关的规则(识别没有合理替代的单一着法),以及与领域有关的规则(例如将军延伸)。像迟着缩减这类缩减,则大量依赖领域知识。
The efficiency of alpha-beta search depends critically upon the order in which moves are considered. Moves are therefore ordered by iterative deepening (using a shallower search to order moves for a deeper search). In addition, a combination of domain-independent move ordering heuristics, such as killer heuristic, history heuristic, counter-move heuristic, and also domain-dependent knowledge based on captures (SEE) and potential captures (MVV/LVA).
alpha-beta 搜索的效率在很大程度上取决于着法被考虑的顺序。因此会用迭代加深来排序(用较浅的搜索为更深的搜索排好着法)。此外还结合与领域无关的着法排序启发式,如杀手启发式、历史启发式、反击启发式,以及基于吃子(SEE)和潜在吃子(MVV/LVA)的领域知识。
A transposition table facilitates the reuse of values and move orders when the same position is reached by multiple paths. A carefully tuned opening book is used to select moves at the start of the game. An endgame tablebase, precalculated by exhaustive retrograde analysis of endgame positions, provides the optimal move in all positions with six and sometimes seven pieces or less.
置换表便于在同一局面经由多条路径到达时,复用已有的分值和着法顺序。开局用精心调过的开局书来选着。残局库则通过对残局局面做穷尽的逆推分析预先算好,在棋子数不超过六枚、有时是七枚的所有局面中给出最优着法。
Other strong chess programs, and also earlier programs such as Deep Blue, have used very similar architectures [23, 9] including the majority of the components described above, although important details vary considerably.
其他强象棋程序,以及更早的 Deep Blue 一类程序,都使用了非常相似的架构 [23, 9],包含上面描述的大部分组件,不过重要细节往往差别很大。
None of the techniques described in this section are used by AlphaZero. It is likely that some of these techniques could further improve the performance of AlphaZero; however, we have focused on a pure self-play reinforcement learning approach and leave these extensions for future research.
本节描述的技术,AlphaZero 一概没有使用。其中一些很可能还能进一步提高 AlphaZero 的表现;不过我们把重点放在纯粹的自我对弈强化学习上,这些扩展留待将来的研究。
Prior Work on Computer Chess and Shogi
电脑国际象棋与将棋的先前工作
In this section we discuss some notable prior work on reinforcement learning in computer chess.
本节讨论电脑象棋中若干值得注意的强化学习先前工作。
NeuroChess [31] evaluated positions by a neural network that used 175 handcrafted input features. It was trained by temporal-difference learning to predict the final game outcome, and also the expected features after two moves. NeuroChess won 13% of games against GnuChess using a fixed depth 2 search.
NeuroChess [31] 用一个以 175 个手工输入特征为输入的神经网络来评估局面。它用时序差分学习来预测对局的最终结果,以及两步之后的期望特征。NeuroChess 在固定深度为 2 的搜索下,对 GnuChess 的胜率为 13%。
Beal and Smith applied temporal-difference learning to estimate the piece values in chess [7] and shogi [8], starting from random values and learning solely by self-play.
Beal 和 Smith 把时序差分学习用于估计国际象棋 [7] 和将棋 [8] 中的棋子价值,从随机取值出发,只靠自我对弈来学习。
KnightCap [6] evaluated positions by a neural network that used an attack-table based on knowledge of which squares are attacked or defended by which pieces. It was trained by a variant of temporal-difference learning, known as TD(leaf), that updates the leaf value of the principal variation of an alpha-beta search. KnightCap achieved human master level after training against a strong computer opponent with hand-initialised piece-value weights.
KnightCap [6] 用一个基于攻击表的神经网络来评估局面,攻击表编码了哪些格子被哪些棋子攻击或保护。它用一种称为 TD(leaf) 的时序差分变体来训练,更新的是 alpha-beta 搜索主要变化的叶子价值。在与一个强电脑对手对阵、并以手工初始化的子力权重起步之后,KnightCap 达到了人类大师水平。
Meep [32] evaluated positions by a linear evaluation function based on handcrafted features. It was trained by another variant of temporal-difference learning, known as TreeStrap, that updated all nodes of an alpha-beta search. Meep defeated human international master players in 13 out of 15 games, after training by self-play with randomly initialised weights.
Meep [32] 用基于手工特征的线性评估函数来评估局面。它用另一种称为 TreeStrap 的时序差分变体来训练,会更新 alpha-beta 搜索中的所有节点。在以随机初始化的权重做自我对弈训练之后,Meep 在 15 局中赢下了 13 局对人类国际大师的比赛。
Kaneko and Hoki [16] trained the weights of a shogi evaluation function comprising a million features, by learning to select expert human moves during alpha-beta serach. They also performed a large-scale optimization based on minimax search regulated by expert game logs [12]; this formed part of the Bonanza engine that won the 2013 World Computer Shogi Championship.
Kaneko 和 Hoki [16] 训练了一个包含百万级特征的将棋评估函数的权重,学习目标是在 alpha-beta 搜索中选出人类专家的着法。他们还基于受专家对局记录约束的极小极大搜索,做了大规模优化 [12];这构成了赢得 2013 年世界电脑将棋锦标赛的 Bonanza 引擎的一部分。
Giraffe [19] evaluated positions by a neural network that included mobility maps and attack and defend maps describing the lowest valued attacker and defender of each square. It was trained by self-play using TD(leaf), also reaching a standard of play comparable to international masters.
Giraffe [19] 用包含活动性图以及攻防图(描述每个格子价值最低的攻击者和防御者)的神经网络来评估局面。它用 TD(leaf) 做自我对弈训练,同样达到了与国际大师相当的水平。
DeepChess [11] trained a neural network to performed pair-wise evaluations of positions. It was trained by supervised learning from a database of human expert games that was pre-filtered to avoid capture moves and drawn games. DeepChess reached a strong grandmaster level of play.
DeepChess [11] 训练神经网络对局面做成对比较。训练是在一个人类专家对局库上做监督学习,并预先过滤掉吃子着法和和棋对局。DeepChess 达到了很强的特级大师水平。
All of these programs combined their learned evaluation functions with an alpha-beta search enhanced by a variety of extensions.
上述程序都把学得的评估函数,与经过各种扩展增强的 alpha-beta 搜索结合在一起。
An approach based on training dual policy and value networks using AlphaZero-like policy iteration was successfully applied to improve on the state-of-the-art in Hex [3].
一种用类似 AlphaZero 的策略迭代来训练双头策略网络和价值网络的方法,被成功用来提升 Hex 的最先进水平 [3]。
MCTS and Alpha-Beta Search
MCTS 与 Alpha-Beta 搜索
For at least four decades the strongest computer chess programs have used alpha-beta search [23, 18]. AlphaZero uses a markedly different approach that averages over the position evaluations within a subtree, rather than computing the minimax evaluation of that subtree. However, chess programs using traditional MCTS were much weaker than alpha-beta search programs, [24, 4]; while alpha-beta programs based on neural networks have previously been unable to compete with faster, handcrafted evaluation functions.
至少四十年来,最强的电脑象棋程序一直使用 alpha-beta 搜索 [23, 18]。AlphaZero 采用明显不同的做法:对子树中的局面评估取平均,而不是计算该子树的极小极大评估。不过,使用传统 MCTS 的象棋程序远弱于 alpha-beta 程序 [24, 4];而基于神经网络的 alpha-beta 程序,此前也竞争不过更快的手工评估函数。
AlphaZero evaluates positions using non-linear function approximation based on a deep neural network, rather than the linear function approximation used in typical chess programs. This provides a much more powerful representation, but may also introduce spurious approximation errors. MCTS averages over these approximation errors, which therefore tend to cancel out when evaluating a large subtree. In contrast, alpha-beta search computes an explicit minimax, which propagates the biggest approximation errors to the root of the subtree. Using MCTS may allow AlphaZero to effectively combine its neural network representations with a powerful, domain-independent search.
AlphaZero 用基于深度神经网络的非线性函数逼近来评估局面,而不是典型象棋程序所用的线性函数逼近。这提供了强得多的表示,但也可能引入虚假的逼近误差。MCTS 对这些逼近误差取平均,因此在评估一棵较大的子树时,误差往往会相互抵消。相比之下,alpha-beta 搜索计算的是显式的极小极大,会把最大的逼近误差传播到子树的根。使用 MCTS,或许能让 AlphaZero 有效地把它的神经网络表示与一种强大、且不依赖领域的搜索结合起来。
Domain Knowledge
领域知识
- The input features describing the position, and the output features describing the move, are structured as a set of planes; i.e. the neural network architecture is matched to the grid-structure of the board.
- 描述局面的输入特征和描述着法的输出特征被组织成一组平面,也就是说,神经网络结构与棋盘的网格结构相匹配。
- AlphaZero is provided with perfect knowledge of the game rules. These are used during MCTS, to simulate the positions resulting from a sequence of moves, to determine game termination, and to score any simulations that reach a terminal state.
- AlphaZero 被提供了游戏规则的完备知识。这些规则在 MCTS 中用来模拟一串着法之后的局面,判定对局是否终止,并对到达终局的模拟计分。
- Knowledge of the rules is also used to encode the input planes (i.e. castling, repetition, no-progress) and output planes (how pieces move, promotions, and piece drops in shogi).
- 规则知识也用于编码输入平面(即易位、重复、无进展)和输出平面(棋子如何走动、升变,以及将棋中的打入)。
- The typical number of legal moves is used to scale the exploration noise (see below).
- 典型合法着法数用来缩放探索噪声(见下文)。
- Chess and shogi games exceeding a maximum number of steps (determined by typical game length) were terminated and assigned a drawn outcome; Go games were terminated and scored with Tromp-Taylor rules, similarly to previous work [29].
- 国际象棋和将棋的对局若超过一个由典型对局长度决定的最大步数,就终止并判和;围棋对局按 Tromp-Taylor 规则终止并计分,做法与先前工作相同 [29]。
AlphaZero did not use any form of domain knowledge beyond the points listed above.
除上面列出的几点之外,AlphaZero 没有使用任何其他形式的领域知识。
Representation
表示
In this section we describe the representation of the board inputs, and the representation of the action outputs, used by the neural network in AlphaZero. Other representations could have been used; in our experiments the training algorithm worked robustly for many reasonable choices.
本节描述 AlphaZero 神经网络所用的棋盘输入表示,以及动作输出表示。也可以采用其他表示;在我们的实验中,对许多合理的选择,训练算法都表现稳健。
The input to the neural network is an image stack that represents state using a concatenation of sets of planes of size . Each set of planes represents the board position at a time-step , and is set to zero for time-steps less than 1. The board is oriented to the perspective of the current player. The feature planes are composed of binary feature planes indicating the presence of the player’s pieces, with one plane for each piece type, and a second set of planes indicating the presence of the opponent’s pieces. For shogi there are additional planes indicating the number of captured prisoners of each type. There are an additional constant-valued input planes denoting the player’s colour, the total move count, and the state of special rules: the legality of castling in chess (kingside or queenside); the repetition count for that position (3 repetitions is an automatic draw in chess; 4 in shogi); and the number of moves without progress in chess (50 moves without progress is an automatic draw). Input features are summarised in Table S1.
神经网络的输入是一个 的图像堆叠,用 组大小为 的 个平面拼接起来表示状态。每一组平面表示时刻 的棋盘局面,对小于 1 的时刻则置零。棋盘按当前行棋方的视角摆放。这 个特征平面由二值平面组成:一组表示己方各类棋子是否在场,每类棋子一个平面;另一组表示对方棋子是否在场。将棋还有额外平面,表示各类被俘棋子(持驹)的数量。另外还有 个取常值的输入平面,用来表示行棋方颜色、总步数,以及特殊规则的状态:国际象棋中易位是否合法(短易位或长易位);该局面的重复次数(象棋三次重复自动判和,将棋为四次);以及象棋中无进展的步数(50 步无进展自动判和)。输入特征汇总于表 S1。
| Go | Chess | Shogi | |||
|---|---|---|---|---|---|
| Feature | Planes | Feature | Planes | Feature | Planes |
| P1 stone | 1 | P1 piece | 6 | P1 piece | 14 |
| P2 stone | 1 | P2 piece | 6 | P2 piece | 14 |
| Repetitions | 2 | Repetitions | 3 | ||
| P1 prisoner count | 7 | ||||
| P2 prisoner count | 7 | ||||
| Colour | 1 | Colour | 1 | Colour | 1 |
| Total move count | 1 | Total move count | 1 | ||
| P1 castling | 2 | ||||
| P2 castling | 2 | ||||
| No-progress count | 1 | ||||
| Total | 17 | Total | 119 | Total | 362 |
Table S1: Input features used by AlphaZero in Go, Chess and Shogi respectively. The first set of features are repeated for each position in a -step history. Counts are represented by a single real-valued input; other input features are represented by a one-hot encoding using the specified number of binary input planes. The current player is denoted by P1 and the opponent by P2.
| 围棋 | 国际象棋 | 将棋 | |||
|---|---|---|---|---|---|
| 围棋特征 | 平面数 | 象棋特征 | 平面数 | 将棋特征 | 平面数 |
| P1 棋子 | 1 | P1 棋子 | 6 | P1 棋子 | 14 |
| P2 棋子 | 1 | P2 棋子 | 6 | P2 棋子 | 14 |
| 重复 | 2 | 重复 | 3 | ||
| P1 持驹计数 | 7 | ||||
| P2 持驹计数 | 7 | ||||
| 颜色(围棋) | 1 | 颜色(象棋) | 1 | 颜色(将棋) | 1 |
| 总步数 | 1 | 总步数 | 1 | ||
| P1 易位 | 2 | ||||
| P2 易位 | 2 | ||||
| 无进展计数 | 1 | ||||
| 合计 | 17 | 合计 | 119 | 合计 | 362 |
表 S1:AlphaZero 分别在围棋、国际象棋和将棋中使用的输入特征。第一组特征对 步历史中的每个局面重复一次。计数用单个实值输入表示;其他输入特征用指定数量的二值平面做 one-hot 编码。当前行棋方记为 P1,对方记为 P2。
| Chess | Shogi | ||
|---|---|---|---|
| Feature | Planes | Feature | Planes |
| Queen moves | 56 | Queen moves | 64 |
| Knight moves | 8 | Knight moves | 2 |
| Underpromotions | 9 | Promoting queen moves | 64 |
| Promoting knight moves | 2 | ||
| Drop | 7 | ||
| Total | 73 | Total | 139 |
Table S2: Action representation used by AlphaZero in Chess and Shogi respectively. The policy is represented by a stack of planes encoding a probability distribution over legal moves; planes correspond to the entries in the table.
| 国际象棋 | 将棋 | ||
|---|---|---|---|
| 特征 | 平面数 | 特征 | 平面数 |
| 后的走法 | 56 | 后的走法 | 64 |
| 马的走法 | 8 | 马的走法 | 2 |
| 低升变 | 9 | 升变的后走法 | 64 |
| 升变的马走法 | 2 | ||
| 打入 | 7 | ||
| 合计 | 73 | 合计 | 139 |
表 S2:AlphaZero 分别在国际象棋和将棋中使用的动作表示。策略用一组平面的堆叠来表示合法着法上的概率分布;各平面与表中的条目相对应。
A move in chess may be described in two parts: selecting the piece to move, and then selecting among the legal moves for that piece. We represent the policy by a stack of planes encoding a probability distribution over 4,672 possible moves. Each of the positions identifies the square from which to “pick up” a piece. The first 56 planes encode possible ‘queen moves’ for any piece: a number of squares in which the piece will be moved, along one of eight relative compass directions . The next 8 planes encode possible knight moves for that piece. The final 9 planes encode possible underpromotions for pawn moves or captures in two possible diagonals, to knight, bishop or rook respectively. Other pawn moves or captures from the seventh rank are promoted to a queen.
国际象棋中的一步可以分成两部分:先选择要走动的棋子,再在该棋子的合法走法中选择。我们将策略 表示成 的平面堆叠,编码 4,672 种可能着法上的概率分布。每个 位置标明从哪一格“拿起”棋子。前 56 个平面编码任意棋子可能的“后式走法”:沿八个相对罗盘方向 之一走动若干格 。接下来 8 个平面编码该棋子可能的马步。最后 9 个平面编码兵的走子或沿两条对角斜线吃子时,升变为马、象或车的低升变。从第七横排出发的其他兵步或吃子则升变为后。
The policy in shogi is represented by a stack of planes similarly encoding a probability distribution over 11,259 possible moves. The first 64 planes encode ‘queen moves’ and the next 2 moves encode knight moves. An additional planes encode promoting queen moves and promoting knight moves respectively. The last 7 planes encode a captured piece dropped back into the board at that location.
将棋的策略用 的平面堆叠类似地编码 11,259 种可能着法上的概率分布。前 64 个平面编码“后式走法”,接下来 2 个平面编码马步。另外 个平面分别编码升变的后式走法和升变的马步。最后 7 个平面编码在该位置打入一枚被俘棋子。
The policy in Go is represented identically to AlphaGo Zero [29], using a flat distribution over moves representing possible stone placements and the pass move. We also tried using a flat distribution over moves for chess and shogi; the final result was almost identical although training was slightly slower.
围棋的策略表示与 AlphaGo Zero [29] 相同,用 种着法上的扁平分布,分别对应可能的落子和停着。我们也试过对国际象棋和将棋使用扁平的着法分布;最终结果几乎一样,只是训练稍慢一些。
The action representations are summarised in Table S2. Illegal moves are masked out by setting their probabilities to zero, and re-normalising the probabilities for remaining moves.
动作表示汇总于表 S2。不合法的着法通过把概率置零来屏蔽,再对剩余着法的概率重新归一化。
Configuration
配置
During training, each MCTS used 800 simulations. The number of games, positions, and thinking time varied per game due largely to different board sizes and game lengths, and are shown in Table S3. The learning rate was set to 0.2 for each game, and was dropped three times (to 0.02, 0.002 and 0.0002 respectively) during the course of training. Moves are selected in proportion to the root visit count. Dirichlet noise was added to the prior probabilities in the root node; this was scaled in inverse proportion to the approximate number of legal moves in a typical position, to a value of for chess, shogi and Go respectively. Unless otherwise specified, the training and search algorithm and parameters are identical to AlphaGo Zero [29].
训练时,每次 MCTS 使用 800 次模拟。对局数、局面数和思考时间因棋盘大小和对局长度不同而有差异,列于表 S3。三种游戏的学习率都设为 0.2,并在训练过程中三次下降(分别降到 0.02、0.002 和 0.0002)。着法按根节点访问次数成比例选择。在根节点的先验概率上加入 Dirichlet 噪声 ;它按典型局面中合法着法的近似数目成反比缩放,对国际象棋、将棋和围棋分别取 。除非另有说明,训练与搜索的算法和参数都与 AlphaGo Zero [29] 相同。
During evaluation, AlphaZero selects moves greedily with respect to the root visit count. Each MCTS was executed on a single machine with 4 TPUs.
评估时,AlphaZero 对根节点访问次数做贪心选择。每次 MCTS 在单机 4 块 TPU 上执行。
| Chess | Shogi | Go | |
|---|---|---|---|
| Mini-batches | 700k | 700k | 700k |
| Training Time | 9h | 12h | 34h |
| Training Games | 44 million | 24 million | 21 million |
| Thinking Time | 800 sims | 800 sims | 800 sims |
| 40 ms | 80 ms | 200 ms |
Table S3: Selected statistics of AlphaZero training in Chess, Shogi and Go.
| 国际象棋 | 将棋 | 围棋 | |
|---|---|---|---|
| 小批量 | 700k | 700k | 700k |
| 训练时间 | 9 小时 | 12 小时 | 34 小时 |
| 训练对局 | 4400 万 | 2400 万 | 2100 万 |
| 思考时间 | 800 次模拟 | 800 次模拟 | 800 次模拟 |
| 40 毫秒 | 80 毫秒 | 200 毫秒 |
表 S3:AlphaZero 在国际象棋、将棋和围棋上的部分训练统计。
Evaluation
评估
To evaluate performance in chess, we used Stockfish version 8 (official Linux release) as a baseline program, using 64 CPU threads and a hash size of 1GB.
评估国际象棋表现时,我们以 Stockfish 第 8 版(官方 Linux 发布)为基线程序,使用 64 个 CPU 线程和 1GB 哈希表。
To evaluate performance in shogi, we used Elmo version WCSC27 in combination with YaneuraOu 2017 Early KPPT 4.73 64AVX2 with 64 CPU threads and a hash size of 1GB with the usi option of EnteringKingRule set to NoEnteringKing.
评估将棋表现时,我们使用 Elmo 的 WCSC27 版本,搭配 YaneuraOu 2017 Early KPPT 4.73 64AVX2,使用 64 个 CPU 线程和 1GB 哈希表,并将 usi 选项 EnteringKingRule 设为 NoEnteringKing。
We evaluated the relative strength of AlphaZero (Figure 1) by measuring the Elo rating of each player. We estimate the probability that player will defeat player by a logistic function , and estimate the ratings by Bayesian logistic regression, computed by the BayesElo program [10] using the standard constant . Elo ratings were computed from the results of a 1 second per move tournament between iterations of AlphaZero during training, and also a baseline player: either Stockfish, Elmo or AlphaGo Lee respectively. The Elo rating of the baseline players was anchored to publicly available values [29].
我们通过测量每位棋手的 Elo 等级分,来评估 AlphaZero 的相对实力(图 1)。我们用 logistic 函数 来估计棋手 击败棋手 的概率,并用贝叶斯 logistic 回归估计等级分 ,由 BayesElo 程序 [10] 计算,采用标准常数 。Elo 等级分来自训练过程中 AlphaZero 各迭代之间、每步 1 秒的循环赛结果,再各加一个基线棋手:分别为 Stockfish、Elmo 或 AlphaGo Lee。基线棋手的 Elo 锚定到已公开的数值 [29]。
We also measured the head-to-head performance of AlphaZero against each baseline player. Settings were chosen to correspond with computer chess tournament conditions: each player was allowed 1 minute per move, resignation was enabled for all players (-900 centipawns for 10 consecutive moves for Stockfish and Elmo, 5% winrate for AlphaZero). Pondering was disabled for all players.
我们还测量了 AlphaZero 与各基线棋手的直接对局表现。设置对应电脑象棋比赛条件:每步限时 1 分钟,所有棋手都允许认输(Stockfish 和 Elmo 为连续 10 步落后 900 厘兵,AlphaZero 为胜率 5%)。所有棋手都关闭了后台思考(pondering)。
| Program | Chess | Shogi | Go |
|---|---|---|---|
| AlphaZero | 80k | 40k | 16k |
| Stockfish | 70,000k | ||
| Elmo | 35,000k |
Table S4: Evaluation speed (positions/second) of AlphaZero, Stockfish, and Elmo in chess, shogi and Go.
| 程序 | 国际象棋 | 将棋 | 围棋 |
|---|---|---|---|
| AlphaZero | 80k | 40k | 16k |
| Stockfish | 70,000k | ||
| Elmo | 35,000k |
表 S4:AlphaZero、Stockfish 和 Elmo 在国际象棋、将棋和围棋上的评估速度(局面/秒)。
Example games
对局实例
In this section we include 10 example games played by AlphaZero against Stockfish during the 100 game match using 1 minute per move.
本节收录 AlphaZero 在每步 1 分钟、100 局对抗中对阵 Stockfish 的 10 局示例。
| White: Stockfish Black: AlphaZero |
|---|
| 1. e4 e5 2. Nf3 Nc6 3. Bb5 Nf6 4. d3 Bc5 5. Bxc6 dxc6 6. 0-0 Nd7 7. Nbd2 0-0 8. Qe1 f6 9. Nc4 Rf7 10. a4 Bf8 11. Kh1 Nc5 12. a5 Ne6 13. Ncxe5 fxe5 14. Nxe5 Rf6 15. Ng4 Rf7 16. Ne5 Re7 17. a6 c5 18. f4 Qe8 19. axb7 Bxb7 20. Qa5 Nd4 21. Qc3 Re6 22. Be3 Rb6 23. Nc4 Rb4 24. b3 a5 25. Rxa5 Rxa5 26. Nxa5 Ba6 27. Bxd4 Rxd4 28. Nc4 Rd8 29. g3 h6 30. Qa5 Bc8 31. Qxc7 Bh3 32. Rg1 Rd7 33. Qe5 Qxe5 34. Nxe5 Ra7 35. Nc4 g5 36. Rc1 Bg7 37. Ne5 Ra8 38. Nf3 Bb2 39. Rb1 Bc3 40. Ng1 Bd7 41. Ne2 Bd2 42. Rd1 Be3 43. Kg2 Bg4 44. Re1 Bd2 45. Rf1 Ra2 46. h3 Bxe2 47. Rf2 Bxf4 48. Rxe2 Be5 49. Rf2 Kg7 50. g4 Bd4 51. Re2 Kf6 52. e5+ Bxe5 53. Kf3 Ra1 54. Rf2 Re1 55. Kg2+ Bf4 56. c3 Rc1 57. d4 Rxc3 58. dxc5 Rxc5 59. b4 Rc3 60. h4 Ke5 61. hxg5 hxg5 62. Re2+ Kf6 63. Kf2 Be5 64. Ra2 Rc4 65. Ra6+ Ke7 66. Ra5 Ke6 67. Ra6+ Bd6 0-1 |
| White: Stockfish Black: AlphaZero |
| 1. e4 e5 2. Nf3 Nc6 3. Bb5 Nf6 4. d3 Bc5 5. Bxc6 dxc6 6. 0-0 Nd7 7. c3 0-0 8. d4 Bd6 9. Bg5 Qe8 10. Re1 f6 11. Bh4 Qf7 12. Nbd2 a5 13. Bg3 Re8 14. Qc2 Nf8 15. c4 c5 16. d5 b6 17. Nh4 g6 18. Nhf3 Bd7 19. Rad1 Re7 20. h3 Qg7 21. Qc3 Rae8 22. a3 h6 23. Bh4 Rf7 24. Bg3 Rfe7 25. Bh4 Rf7 26. Bg3 a4 27. Kh1 Rfe7 28. Bh4 Rf7 29. Bg3 Rfe7 30. Bh4 g5 31. Bg3 Ng6 32. Nf1 Rf7 33. Ne3 Ne7 34. Qd3 h5 35. h4 Nc8 36. Re2 g4 37. Nd2 Qh7 38. Kg1 Bf8 39. Nb1 Nd6 40. Nc3 Bh6 41. Rf1 Ra8 42. Kh2 Kf8 43. Kg1 Qg6 44. f4 gxf3 45. Rxf3 Bxe3+ 46. Rfxe3 Ke7 47. Be1 Qh7 48. Rg3 Rg7 49. Rxg7+ Qxg7 50. Re3 Rg8 51. Rg3 Qh8 52. Nb1 Rxg3 53. Bxg3 Qh6 54. Nd2 Bg4 55. Kh2 Kd7 56. b3 axb3 57. Nxb3 Qg6 58. Nd2 Bd1 59. Nf3 Ba4 60. Nd2 Ke7 61. Bf2 Qg4 62. Qf3 Bd1 63. Qxg4 Bxg4 64. a4 Nb7 65. Nb1 Na5 66. Be3 Nxc4 67. Bc1 Bd7 68. Nc3 c6 69. Kg1 cxd5 70. exd5 Bf5 71. Kf2 Nd6 72. Be3 Ne4+ 73. Nxe4 Bxe4 74. a5 bxa5 75. Bxc5+ Kd7 76. d6 Bf5 77. Ba3 Kc6 78. Ke1 Kd5 79. Kd2 Ke4 80. Bb2 Kf4 81. Bc1 Kg3 82. Ke2 a4 83. Kf1 Kxh4 84. Kf2 Kg4 85. Ba3 Bd7 86. Bc1 Kf5 87. Ke3 Ke6 0-1 |
| White: AlphaZero Black: Stockfish |
| 1. Nf3 Nf6 2. c4 b6 3. d4 e6 4. g3 Ba6 5. Qc2 c5 6. d5 exd5 7. cxd5 Bb7 8. Bg2 Nxd5 9. 0-0 Nc6 10. Rd1 Be7 11. Qf5 Nf6 12. e4 g6 13. Qf4 0-0 14. e5 Nh5 15. Qg4 Re8 16. Nc3 Qb8 17. Nd5 Bf8 18. Bf4 Qc8 19. h3 Ne7 20. Ne3 Bc6 21. Rd6 Ng7 22. Rf6 Qb7 23. Bh6 Nd5 24. Nxd5 Bxd5 25. Rd1 Ne6 26. Bxf8 Rxf8 27. Qh4 Bc6 28. Qh6 Rae8 29. Rd6 Bxf3 30. Bxf3 Qa6 31. h4 Qa5 32. Rd1 c4 33. Rd5 Qe1+ 34. Kg2 c3 35. bxc3 Qxc3 36. h5 Re7 37. Bd1 Qe1 38. Bb3 Rd8 39. Rf3 Qe4 40. Qd2 Qg4 41. Bd1 Qe4 42. h6 Nc7 43. Rd6 Ne6 44. Bb3 Qxe5 45. Rd5 Qh8 46. Qb4 Nc5 47. Rxc5 bxc5 48. Qh4 Rde8 49. Rf6 Rf8 50. Qf4 a5 51. g4 d5 52. Bxd5 Rd7 53. Bc4 a4 54. g5 a3 55. Qf3 Rc7 56. Qxa3 Qxf6 57. gxf6 Rfc8 58. Qd3 Rf8 59. Qd6 Rfc8 60. a4 1-0 |
| White: AlphaZero Black: Stockfish |
| 1. d4 e6 2. Nc3 Nf6 3. e4 d5 4. e5 Nfd7 5. f4 c5 6. Nf3 Nc6 7. Be3 Be7 8. Qd2 a6 9. Bd3 c4 10. Be2 b5 11. a3 Rb8 12. 0-0 0-0 13. f5 a5 14. fxe6 fxe6 15. Bd1 b4 16. axb4 axb4 17. Ne2 c3 18. bxc3 Nb6 19. Qe1 Nc4 20. Bc1 bxc3 21. Qxc3 Qb6 22. Kh1 Nb2 23. Nf4 Nxd1 24. Rxd1 Bd7 25. h4 Ra8 26. Bd2 Rfb8 27. h5 Rxa1 28. Rxa1 Qb2 29. Qxb2 Rxb2 30. c3 Rb3 31. Ra8+ Rb8 32. Ra2 Rb3 33. g4 Ra3 34. Rb2 Kf7 35. Kg2 Bc8 36. Rb6 Ra6 37. Rb1 Ke8 38. Kg3 h6 39. Ng6 Ra3 40. Rb6 Bd7 41. g5 hxg5 42. Kg4 Bd8 43. Rb2 Bc8 44. Nxg5 Ra1 45. Nf3 Ra3 46. Be1 Ba5 47. Rf2 Ra1 48. Bd2 Bd8 49. Rh2 Ne7 50. Bg5 Nf5 51. Bxd8 Kxd8 52. Rb2 Rc1 53. Ngh4 Nxh4 54. Nxh4 Bd7 55. Rb8+ Bc8 56. Ng2 Rxc3 57. Nf4 Rc1 58. Ra8 Kd7 59. Kf3 Rc3+ 60. Kf2 Ke7 61. Kg2 Kf7 62. Ng6 Ke8 63. Ra1 Rc7 64. Kh3 Rf7 65. Kg4 Kd8 66. Nf4 Bd7 67. Ra7 Kc8 68. Kg3 Re7 69. Nd3 Kb8 70. Ra6 Bc8 71. Rb6+ Kc7 72. Rd6 Kb8 73. Nc5 g6 74. h6 Rh7 75. Nxe6 Rxh6 76. Nf4 Rh1 77. Nxd5 Rh3+ 78. Kf4 Rh4+ 79. Ke3 Rh3+ 80. Kd2 Bf5 81. Ne7 Rh2+ 82. Ke3 Bh3 83. Nxg6 Rh1 84. Nf4 Bg4 85. Rf6 Kc7 86. Nd3 Bd7 87. d5 Bb5 88. Nf4 Ba4 89. Kd4 Be8 90. Rf8 Rd1+ 91. Kc5 Rc1+ 92. Kb4 Rb1+ 93. Kc3 Bb5 94. Kd4 Ba6 95. Rf7+ 1-0 |
| White: AlphaZero Black: Stockfish |
| 1. d4 Nf6 2. c4 e6 3. Nf3 b6 4. g3 Bb7 5. Bg2 Be7 6. 0-0 0-0 7. d5 exd5 8. Nh4 c6 9. cxd5 Nxd5 10. Nf5 Nc7 11. e4 Bf6 12. Nd6 Ba6 13. Re1 Ne8 14. e5 Nxd6 15. exf6 Qxf6 16. Nc3 Nb7 17. Ne4 Qg6 18. h4 h6 19. h5 Qh7 20. Qg4 Kh8 21. Bg5 f5 22. Qf4 Nc5 23. Be7 Nd3 24. Qd6 Nxe1 25. Rxe1 fxe4 26. Bxe4 Rf5 27. Bh4 Bc4 28. g4 Rd5 29. Bxd5 Bxd5 30. Re8+ Bg8 31. Bg3 c5 32. Qd5 d6 33. Qxa8 Nd7 34. Qe4 Nf6 35. Qxh7+ Kxh7 36. Re7 Nxg4 37. Rxa7 Nf6 38. Bxd6 Be6 39. Be5 Nd7 40. Bc3 g6 41. Bd2 gxh5 42. a3 Kg6 43. Bf4 Kf5 44. Bc7 h4 45. Ra8 h5 46. Rh8 Kg6 47. Rd8 Kf7 48. f3 Bf5 49. Bh2 h3 50. Rh8 Kg6 51. Re8 Kf7 52. Re1 Be6 53. Bc7 b5 54. Kh2 Kf6 55. Re3 Ke7 56. Re4 Kf7 57. Bd6 Kf6 58. Kg3 Kf7 59. Kf2 Bf5 60. Re1 Kg6 61. Kg1 c4 62. Kh2 h4 63. Be7 Nb6 64. Bxh4 Na4 65. Re2 Nc5 66. Re5 Nb3 67. Rd5 Be6 68. Rd6 Kf5 69. Be1 Ke5 70. Rb6 Bd7 71. Kg3 Nc1 72. Rh6 Kd5 73. Bc3 Bf5 74. Rh5 Ke6 75. Kf2 Nd3+ 76. Kg1 Nf4 77. Rh6+ Ke7 78. Kh2 Nd5 79. Kg3 Be6 80. Rh5 Ke8 81. Re5 Kf7 82. Bd2 Ne7 83. Bb4 Nd5 84. Bc3 Ke7 85. Bd2 Kf6 86. f4 Ne7 87. Rxb5 Nf5+ 88. Kh2 Ke7 89. Ra5 Nh4 90. Bb4+ Kf7 91. Rh5 Nf3+ 92. Kg3 Kg6 93. Rh8 Nd4 94. Bc3 Nf5+ 95. Kxh3 Bd7 96. Kh2 Kf7 97. Rb8 Ke6 98. Kg1 Bc6 99. Rb6 Kd5 100. Kf2 Bd7 101. Ke1 Ke4 102. Bd2 Kd5 103. Rf6 Nd6 104. Rh6 Nf5 105. Rh8 Ke4 106. Rh7 Bc8 107. Rc7 Ba6 108. Rc6 Bb5 109. Rc5 Bd7 110. Rxc4+ Kd5 111. Rc7 Kd6 112. Rc3 Ke6 113. Rc5 Nd4 114. Be3 Nf5 115. Bf2 Nd6 116. Rc3 Ne4 117. Rd3 1-0 |
| White: AlphaZero Black: Stockfish |
| 1. d4 Nf6 2. Nf3 e6 3. c4 b6 4. g3 Be7 5. Bg2 Bb7 6. 0-0 0-0 7. d5 exd5 8. Nh4 c6 9. cxd5 Nxd5 10. Nf5 Nc7 11. e4 Bf6 12. Nd6 Ba6 13. Re1 Ne8 14. e5 Nxd6 15. exf6 Qxf6 16. Nc3 Bc4 17. h4 h6 18. b3 Qxc3 19. Bf4 Nb7 20. bxc4 Qf6 21. Be4 Na6 22. Be5 Qe6 23. Bd3 f6 24. Bd4 Qf7 25. Qg4 Rfd8 26. Re3 Nac5 27. Bg6 Qf8 28. Rd1 Rab8 29. Kg2 Ne6 30. Bc3 Nbc5 31. Rde1 Na4 32. Bd2 Kh8 33. f4 Qd6 34. Bc1 Nd4 35. Re7 f5 36. Bxf5 Nxf5 37. Qxf5 Rf8 38. Rxd7 Rxf5 39. Rxd6 Rf7 40. g4 Kg8 41. g5 hxg5 42. hxg5 Nc5 43. Kf3 Nb7 44. Rdd1 Na5 45. Re4 c5 46. Bb2 Nc6 47. g6 Rc7 48. Kg4 Nd4 49. Rd2 Rf8 50. Bxd4 cxd4 51. Rdxd4 Rfc8 52. Kg5 Rf8 53. Rd2 Rc6 54. Rd5 Rc7 55. f5 Rb7 56. a3 Rc7 57. a4 a6 58. Red4 Rcc8 59. Re5 Rc7 60. a5 Rc5 61. Rxc5 bxc5 62. Rd6 Ra8 63. Re6 Kf8 64. Rc6 Ke7 65. Kf4 Kd7 66. Rxc5 Rh8 67. Rd5+ Ke7 68. Re5+ Kd7 69. Re6 Rh4+ 70. Kg5 1-0 |
| White: AlphaZero Black: Stockfish |
| 1. d4 Nf6 2. c4 e6 3. Nf3 b6 4. g3 Bb7 5. Bg2 Bb4+ 6. Bd2 Bxd2+ 7. Qxd2 d5 8. 0-0 0-0 9. cxd5 exd5 10. Nc3 Nbd7 11. b4 c6 12. Qb2 a5 13. b5 c5 14. Rac1 Qe7 15. Na4 Rab8 16. Rfd1 c4 17. Ne5 Qe6 18. f4 Rfd8 19. Qd2 Nf8 20. Nc3 Ng6 21. Rf1 Qd6 22. a4 Rbc8 23. e3 Ne7 24. g4 Ne8 25. f5 f6 26. Nf3 Qd7 27. Qf2 Nd6 28. Nd2 Rf8 29. Qg3 Rcd8 30. Rf4 Nf7 31. Rf2 Rfe8 32. h3 Qd6 33. Nf1 Qa3 34. Rcc2 h5 35. Qc7 Qd6 36. Qxd6 Rxd6 37. Ng3 h4 38. Nh5 Ng5 39. Rf1 Kh7 40. Nf4 Rdd8 41. Kh2 Rd7 42. Bh1 Rd6 43. Ng2 g6 44. Nxh4 gxf5 45. gxf5 Rh8 46. Nf3 Kg7 47. Nxg5 fxg5 48. Rg2 Kf6 49. Rg3 Re8 50. Bf3 Rdd8 51. Be2 Rf8 52. Bg4 Nc8 53. Bf3 Rfe8 54. h4 Rh8 55. h5 Rhe8 56. Bg2 Ne7 57. h6 Rh8 58. Rh3 Rh7 59. Kg1 Ba8 60. Nd1 g4 61. Rh5 g3 62. Nc3 Ng8 63. Ne2 Rxh6 64. Nxg3 Rxh5 65. Nxh5+ Kf7 66. Kf2 Nf6 67. Nxf6 Kxf6 68. Rh1 c3 69. Rc1 Rh8 70. Rxc3 Kxf5 71. Rc7 Kf6 72. Bf3 Rg8 73. Rh7 Rg6 74. Bd1 Rg8 75. Rh6+ Ke7 76. Rxb6 Kd7 77. Rf6 Ke7 78. Rh6 Rg7 79. Rh8 Bb7 80. Rh5 Kd6 81. Rh3 Rf7+ 82. Ke1 Bc8 83. Rh6+ Kc7 84. Rc6+ Kb8 85. Rd6 Bb7 86. b6 Ba6 87. Rxd5 Rf6 88. Rxa5 Rxb6 89. Kd2 Bb7 90. Rb5 Rf6 91. Bb3 Kc7 92. Re5 Ba6 93. Kc3 Rf1 94. Bc2 Rh1 95. a5 Kd6 96. e4 Bf1 97. Rf5 Bg2 98. Rf4 Rc1 99. Kb2 Rh1 100. a6 1-0 |
| White: AlphaZero Black: Stockfish |
| 1. d4 Nf6 2. c4 e6 3. Nf3 b6 4. g3 Bb7 5. Bg2 Bb4+ 6. Bd2 Be7 7. Nc3 c6 8. e4 d5 9. e5 Ne4 10. 0-0 Ba6 11. b3 Nxc3 12. Bxc3 dxc4 13. b4 b5 14. Nd2 0-0 15. Ne4 Bb7 16. Qg4 Nd7 17. Nc5 Nxc5 18. dxc5 a5 19. a3 axb4 20. axb4 Rxa1 21. Rxa1 Qd3 22. Rc1 Ra8 23. h4 Qd8 24. Be4 Qc8 25. Kg2 Qc7 26. Qh5 g6 27. Qg4 Bf8 28. h5 Rd8 29. Qh4 Qe7 30. Qf6 Qe8 31. Rh1 Rd7 32. hxg6 fxg6 33. Qh4 Qe7 34. Qg4 Rd8 35. Bb2 Qf7 36. Bc1 c3 37. Be3 Be7 38. Qe2 Bf8 39. Qc2 Bg7 40. Qxc3 Qd7 41. Rc1 Qc7 42. Bg5 Rf8 43. f4 h6 44. Bf6 Bxf6 45. exf6 Qf7 46. Ra1 Qxf6 47. Qxf6 Rxf6 48. Ra7 Rf7 49. Bxg6 Rd7 50. Kf2 Kf8 51. g4 Bc8 52. Ra8 Rc7 53. Ke3 h5 54. gxh5 Kg7 55. Ra2 Re7 56. Be4 e5 57. Bxc6 exf4+ 58. Kxf4 Rf7+ 59. Ke5 Rf5+ 60. Kd6 Rxh5 61. Rg2+ Kf6 62. Kc7 Bf5 63. Kb6 Rh4 64. Ka5 Bg4 65. Bxb5 Ke7 66. Rg3 Bc8 67. Re3+ Kf7 68. Be2 1-0 |
| White: AlphaZero, Black: Stockfish |
| 1. d4 e6 2. e4 d5 3. Nc3 Nf6 4. e5 Nfd7 5. f4 c5 6. Nf3 cxd4 7. Nb5 Bb4+ 8. Bd2 Bc5 9. b4 Be7 10. Nbxd4 Nc6 11. c3 a5 12. b5 Nxd4 13. cxd4 Nb6 14. a4 Nc4 15. Bd3 Nxd2 16. Kxd2 Bd7 17. Ke3 b6 18. g4 h5 19. Qg1 hxg4 20. Qxg4 Bf8 21. h4 Qe7 22. Rhc1 g6 23. Rc2 Kd8 24. Rac1 Qe8 25. Rc7 Rc8 26. Rxc8+ Bxc8 27. Rc6 Bb7 28. Rc2 Kd7 29. Ng5 Be7 30. Bxg6 Bxg5 31. Qxg5 fxg6 32. f5 Rg8 33. Qh6 Qf7 34. f6 Kd8 35. Kd2 Kd7 36. Rc1 Kd8 37. Qe3 Qf8 38. Qc3 Qb4 39. Qxb4 axb4 40. Rg1 b3 41. Kc3 Bc8 42. Kxb3 Bd7 43. Kb4 Be8 44. Ra1 Kc7 45. a5 Bd7 46. axb6+ Kxb6 47. Ra6+ Kb7 48. Kc5 Rd8 49. Ra2 Rc8+ 50. Kd6 Be8 51. Ke7 g5 52. hxg5 1-0 |
| White: AlphaZero, Black: Stockfish |
| 1. Nf3 Nf6 2. d4 e6 3. c4 b6 4. g3 Bb7 5. Bg2 Be7 6. 0-0 0-0 7. d5 exd5 8. Nh4 c6 9. cxd5 Nxd5 10. Nf5 Nc7 11. e4 d5 12. exd5 Nxd5 13. Nc3 Nxc3 14. Qg4 g6 15. Nh6+ Kg7 16. bxc3 Bc8 17. Qf4 Qd6 18. Qa4 g5 19. Re1 Kxh6 20. h4 f6 21. Be3 Bf5 22. Rad1 Qa3 23. Qc4 b5 24. hxg5+ fxg5 25. Qh4+ Kg6 26. Qh1 Kg7 27. Be4 Bg6 28. Bxg6 hxg6 29. Qh3 Bf6 30. Kg2 Qxa2 31. Rh1 Qg8 32. c4 Re8 33. Bd4 Bxd4 34. Rxd4 Rd8 35. Rxd8 Qxd8 36. Qe6 Nd7 37. Rd1 Nc5 38. Rxd8 Nxe6 39. Rxa8 Kf6 40. cxb5 cxb5 41. Kf3 Nd4+ 42. Ke4 Nc6 43. Rc8 Ne7 44. Rb8 Nf5 45. g4 Nh6 46. f3 Nf7 47. Ra8 Nd6+ 48. Kd5 Nc4 49. Rxa7 Ne3+ 50. Ke4 Nc4 51. Ra6+ Kg7 52. Rc6 Kf7 53. Rc5 Ke6 54. Rxg5 Kf6 55. Rc5 g5 56. Kd4 1-0 |
| 白方:Stockfish 黑方:AlphaZero |
|---|
| 1. e4 e5 2. Nf3 Nc6 3. Bb5 Nf6 4. d3 Bc5 5. Bxc6 dxc6 6. 0-0 Nd7 7. Nbd2 0-0 8. Qe1 f6 9. Nc4 Rf7 10. a4 Bf8 11. Kh1 Nc5 12. a5 Ne6 13. Ncxe5 fxe5 14. Nxe5 Rf6 15. Ng4 Rf7 16. Ne5 Re7 17. a6 c5 18. f4 Qe8 19. axb7 Bxb7 20. Qa5 Nd4 21. Qc3 Re6 22. Be3 Rb6 23. Nc4 Rb4 24. b3 a5 25. Rxa5 Rxa5 26. Nxa5 Ba6 27. Bxd4 Rxd4 28. Nc4 Rd8 29. g3 h6 30. Qa5 Bc8 31. Qxc7 Bh3 32. Rg1 Rd7 33. Qe5 Qxe5 34. Nxe5 Ra7 35. Nc4 g5 36. Rc1 Bg7 37. Ne5 Ra8 38. Nf3 Bb2 39. Rb1 Bc3 40. Ng1 Bd7 41. Ne2 Bd2 42. Rd1 Be3 43. Kg2 Bg4 44. Re1 Bd2 45. Rf1 Ra2 46. h3 Bxe2 47. Rf2 Bxf4 48. Rxe2 Be5 49. Rf2 Kg7 50. g4 Bd4 51. Re2 Kf6 52. e5+ Bxe5 53. Kf3 Ra1 54. Rf2 Re1 55. Kg2+ Bf4 56. c3 Rc1 57. d4 Rxc3 58. dxc5 Rxc5 59. b4 Rc3 60. h4 Ke5 61. hxg5 hxg5 62. Re2+ Kf6 63. Kf2 Be5 64. Ra2 Rc4 65. Ra6+ Ke7 66. Ra5 Ke6 67. Ra6+ Bd6 0-1 |
| 白方:Stockfish 黑方:AlphaZero |
| 1. e4 e5 2. Nf3 Nc6 3. Bb5 Nf6 4. d3 Bc5 5. Bxc6 dxc6 6. 0-0 Nd7 7. c3 0-0 8. d4 Bd6 9. Bg5 Qe8 10. Re1 f6 11. Bh4 Qf7 12. Nbd2 a5 13. Bg3 Re8 14. Qc2 Nf8 15. c4 c5 16. d5 b6 17. Nh4 g6 18. Nhf3 Bd7 19. Rad1 Re7 20. h3 Qg7 21. Qc3 Rae8 22. a3 h6 23. Bh4 Rf7 24. Bg3 Rfe7 25. Bh4 Rf7 26. Bg3 a4 27. Kh1 Rfe7 28. Bh4 Rf7 29. Bg3 Rfe7 30. Bh4 g5 31. Bg3 Ng6 32. Nf1 Rf7 33. Ne3 Ne7 34. Qd3 h5 35. h4 Nc8 36. Re2 g4 37. Nd2 Qh7 38. Kg1 Bf8 39. Nb1 Nd6 40. Nc3 Bh6 41. Rf1 Ra8 42. Kh2 Kf8 43. Kg1 Qg6 44. f4 gxf3 45. Rxf3 Bxe3+ 46. Rfxe3 Ke7 47. Be1 Qh7 48. Rg3 Rg7 49. Rxg7+ Qxg7 50. Re3 Rg8 51. Rg3 Qh8 52. Nb1 Rxg3 53. Bxg3 Qh6 54. Nd2 Bg4 55. Kh2 Kd7 56. b3 axb3 57. Nxb3 Qg6 58. Nd2 Bd1 59. Nf3 Ba4 60. Nd2 Ke7 61. Bf2 Qg4 62. Qf3 Bd1 63. Qxg4 Bxg4 64. a4 Nb7 65. Nb1 Na5 66. Be3 Nxc4 67. Bc1 Bd7 68. Nc3 c6 69. Kg1 cxd5 70. exd5 Bf5 71. Kf2 Nd6 72. Be3 Ne4+ 73. Nxe4 Bxe4 74. a5 bxa5 75. Bxc5+ Kd7 76. d6 Bf5 77. Ba3 Kc6 78. Ke1 Kd5 79. Kd2 Ke4 80. Bb2 Kf4 81. Bc1 Kg3 82. Ke2 a4 83. Kf1 Kxh4 84. Kf2 Kg4 85. Ba3 Bd7 86. Bc1 Kf5 87. Ke3 Ke6 0-1 |
| 白方:AlphaZero 黑方:Stockfish |
| 1. Nf3 Nf6 2. c4 b6 3. d4 e6 4. g3 Ba6 5. Qc2 c5 6. d5 exd5 7. cxd5 Bb7 8. Bg2 Nxd5 9. 0-0 Nc6 10. Rd1 Be7 11. Qf5 Nf6 12. e4 g6 13. Qf4 0-0 14. e5 Nh5 15. Qg4 Re8 16. Nc3 Qb8 17. Nd5 Bf8 18. Bf4 Qc8 19. h3 Ne7 20. Ne3 Bc6 21. Rd6 Ng7 22. Rf6 Qb7 23. Bh6 Nd5 24. Nxd5 Bxd5 25. Rd1 Ne6 26. Bxf8 Rxf8 27. Qh4 Bc6 28. Qh6 Rae8 29. Rd6 Bxf3 30. Bxf3 Qa6 31. h4 Qa5 32. Rd1 c4 33. Rd5 Qe1+ 34. Kg2 c3 35. bxc3 Qxc3 36. h5 Re7 37. Bd1 Qe1 38. Bb3 Rd8 39. Rf3 Qe4 40. Qd2 Qg4 41. Bd1 Qe4 42. h6 Nc7 43. Rd6 Ne6 44. Bb3 Qxe5 45. Rd5 Qh8 46. Qb4 Nc5 47. Rxc5 bxc5 48. Qh4 Rde8 49. Rf6 Rf8 50. Qf4 a5 51. g4 d5 52. Bxd5 Rd7 53. Bc4 a4 54. g5 a3 55. Qf3 Rc7 56. Qxa3 Qxf6 57. gxf6 Rfc8 58. Qd3 Rf8 59. Qd6 Rfc8 60. a4 1-0 |
| 白方:AlphaZero 黑方:Stockfish |
| 1. d4 e6 2. Nc3 Nf6 3. e4 d5 4. e5 Nfd7 5. f4 c5 6. Nf3 Nc6 7. Be3 Be7 8. Qd2 a6 9. Bd3 c4 10. Be2 b5 11. a3 Rb8 12. 0-0 0-0 13. f5 a5 14. fxe6 fxe6 15. Bd1 b4 16. axb4 axb4 17. Ne2 c3 18. bxc3 Nb6 19. Qe1 Nc4 20. Bc1 bxc3 21. Qxc3 Qb6 22. Kh1 Nb2 23. Nf4 Nxd1 24. Rxd1 Bd7 25. h4 Ra8 26. Bd2 Rfb8 27. h5 Rxa1 28. Rxa1 Qb2 29. Qxb2 Rxb2 30. c3 Rb3 31. Ra8+ Rb8 32. Ra2 Rb3 33. g4 Ra3 34. Rb2 Kf7 35. Kg2 Bc8 36. Rb6 Ra6 37. Rb1 Ke8 38. Kg3 h6 39. Ng6 Ra3 40. Rb6 Bd7 41. g5 hxg5 42. Kg4 Bd8 43. Rb2 Bc8 44. Nxg5 Ra1 45. Nf3 Ra3 46. Be1 Ba5 47. Rf2 Ra1 48. Bd2 Bd8 49. Rh2 Ne7 50. Bg5 Nf5 51. Bxd8 Kxd8 52. Rb2 Rc1 53. Ngh4 Nxh4 54. Nxh4 Bd7 55. Rb8+ Bc8 56. Ng2 Rxc3 57. Nf4 Rc1 58. Ra8 Kd7 59. Kf3 Rc3+ 60. Kf2 Ke7 61. Kg2 Kf7 62. Ng6 Ke8 63. Ra1 Rc7 64. Kh3 Rf7 65. Kg4 Kd8 66. Nf4 Bd7 67. Ra7 Kc8 68. Kg3 Re7 69. Nd3 Kb8 70. Ra6 Bc8 71. Rb6+ Kc7 72. Rd6 Kb8 73. Nc5 g6 74. h6 Rh7 75. Nxe6 Rxh6 76. Nf4 Rh1 77. Nxd5 Rh3+ 78. Kf4 Rh4+ 79. Ke3 Rh3+ 80. Kd2 Bf5 81. Ne7 Rh2+ 82. Ke3 Bh3 83. Nxg6 Rh1 84. Nf4 Bg4 85. Rf6 Kc7 86. Nd3 Bd7 87. d5 Bb5 88. Nf4 Ba4 89. Kd4 Be8 90. Rf8 Rd1+ 91. Kc5 Rc1+ 92. Kb4 Rb1+ 93. Kc3 Bb5 94. Kd4 Ba6 95. Rf7+ 1-0 |
| 白方:AlphaZero 黑方:Stockfish |
| 1. d4 Nf6 2. c4 e6 3. Nf3 b6 4. g3 Bb7 5. Bg2 Be7 6. 0-0 0-0 7. d5 exd5 8. Nh4 c6 9. cxd5 Nxd5 10. Nf5 Nc7 11. e4 Bf6 12. Nd6 Ba6 13. Re1 Ne8 14. e5 Nxd6 15. exf6 Qxf6 16. Nc3 Nb7 17. Ne4 Qg6 18. h4 h6 19. h5 Qh7 20. Qg4 Kh8 21. Bg5 f5 22. Qf4 Nc5 23. Be7 Nd3 24. Qd6 Nxe1 25. Rxe1 fxe4 26. Bxe4 Rf5 27. Bh4 Bc4 28. g4 Rd5 29. Bxd5 Bxd5 30. Re8+ Bg8 31. Bg3 c5 32. Qd5 d6 33. Qxa8 Nd7 34. Qe4 Nf6 35. Qxh7+ Kxh7 36. Re7 Nxg4 37. Rxa7 Nf6 38. Bxd6 Be6 39. Be5 Nd7 40. Bc3 g6 41. Bd2 gxh5 42. a3 Kg6 43. Bf4 Kf5 44. Bc7 h4 45. Ra8 h5 46. Rh8 Kg6 47. Rd8 Kf7 48. f3 Bf5 49. Bh2 h3 50. Rh8 Kg6 51. Re8 Kf7 52. Re1 Be6 53. Bc7 b5 54. Kh2 Kf6 55. Re3 Ke7 56. Re4 Kf7 57. Bd6 Kf6 58. Kg3 Kf7 59. Kf2 Bf5 60. Re1 Kg6 61. Kg1 c4 62. Kh2 h4 63. Be7 Nb6 64. Bxh4 Na4 65. Re2 Nc5 66. Re5 Nb3 67. Rd5 Be6 68. Rd6 Kf5 69. Be1 Ke5 70. Rb6 Bd7 71. Kg3 Nc1 72. Rh6 Kd5 73. Bc3 Bf5 74. Rh5 Ke6 75. Kf2 Nd3+ 76. Kg1 Nf4 77. Rh6+ Ke7 78. Kh2 Nd5 79. Kg3 Be6 80. Rh5 Ke8 81. Re5 Kf7 82. Bd2 Ne7 83. Bb4 Nd5 84. Bc3 Ke7 85. Bd2 Kf6 86. f4 Ne7 87. Rxb5 Nf5+ 88. Kh2 Ke7 89. Ra5 Nh4 90. Bb4+ Kf7 91. Rh5 Nf3+ 92. Kg3 Kg6 93. Rh8 Nd4 94. Bc3 Nf5+ 95. Kxh3 Bd7 96. Kh2 Kf7 97. Rb8 Ke6 98. Kg1 Bc6 99. Rb6 Kd5 100. Kf2 Bd7 101. Ke1 Ke4 102. Bd2 Kd5 103. Rf6 Nd6 104. Rh6 Nf5 105. Rh8 Ke4 106. Rh7 Bc8 107. Rc7 Ba6 108. Rc6 Bb5 109. Rc5 Bd7 110. Rxc4+ Kd5 111. Rc7 Kd6 112. Rc3 Ke6 113. Rc5 Nd4 114. Be3 Nf5 115. Bf2 Nd6 116. Rc3 Ne4 117. Rd3 1-0 |
| 白方:AlphaZero 黑方:Stockfish |
| 1. d4 Nf6 2. Nf3 e6 3. c4 b6 4. g3 Be7 5. Bg2 Bb7 6. 0-0 0-0 7. d5 exd5 8. Nh4 c6 9. cxd5 Nxd5 10. Nf5 Nc7 11. e4 Bf6 12. Nd6 Ba6 13. Re1 Ne8 14. e5 Nxd6 15. exf6 Qxf6 16. Nc3 Bc4 17. h4 h6 18. b3 Qxc3 19. Bf4 Nb7 20. bxc4 Qf6 21. Be4 Na6 22. Be5 Qe6 23. Bd3 f6 24. Bd4 Qf7 25. Qg4 Rfd8 26. Re3 Nac5 27. Bg6 Qf8 28. Rd1 Rab8 29. Kg2 Ne6 30. Bc3 Nbc5 31. Rde1 Na4 32. Bd2 Kh8 33. f4 Qd6 34. Bc1 Nd4 35. Re7 f5 36. Bxf5 Nxf5 37. Qxf5 Rf8 38. Rxd7 Rxf5 39. Rxd6 Rf7 40. g4 Kg8 41. g5 hxg5 42. hxg5 Nc5 43. Kf3 Nb7 44. Rdd1 Na5 45. Re4 c5 46. Bb2 Nc6 47. g6 Rc7 48. Kg4 Nd4 49. Rd2 Rf8 50. Bxd4 cxd4 51. Rdxd4 Rfc8 52. Kg5 Rf8 53. Rd2 Rc6 54. Rd5 Rc7 55. f5 Rb7 56. a3 Rc7 57. a4 a6 58. Red4 Rcc8 59. Re5 Rc7 60. a5 Rc5 61. Rxc5 bxc5 62. Rd6 Ra8 63. Re6 Kf8 64. Rc6 Ke7 65. Kf4 Kd7 66. Rxc5 Rh8 67. Rd5+ Ke7 68. Re5+ Kd7 69. Re6 Rh4+ 70. Kg5 1-0 |
| 白方:AlphaZero 黑方:Stockfish |
| 1. d4 Nf6 2. c4 e6 3. Nf3 b6 4. g3 Bb7 5. Bg2 Bb4+ 6. Bd2 Bxd2+ 7. Qxd2 d5 8. 0-0 0-0 9. cxd5 exd5 10. Nc3 Nbd7 11. b4 c6 12. Qb2 a5 13. b5 c5 14. Rac1 Qe7 15. Na4 Rab8 16. Rfd1 c4 17. Ne5 Qe6 18. f4 Rfd8 19. Qd2 Nf8 20. Nc3 Ng6 21. Rf1 Qd6 22. a4 Rbc8 23. e3 Ne7 24. g4 Ne8 25. f5 f6 26. Nf3 Qd7 27. Qf2 Nd6 28. Nd2 Rf8 29. Qg3 Rcd8 30. Rf4 Nf7 31. Rf2 Rfe8 32. h3 Qd6 33. Nf1 Qa3 34. Rcc2 h5 35. Qc7 Qd6 36. Qxd6 Rxd6 37. Ng3 h4 38. Nh5 Ng5 39. Rf1 Kh7 40. Nf4 Rdd8 41. Kh2 Rd7 42. Bh1 Rd6 43. Ng2 g6 44. Nxh4 gxf5 45. gxf5 Rh8 46. Nf3 Kg7 47. Nxg5 fxg5 48. Rg2 Kf6 49. Rg3 Re8 50. Bf3 Rdd8 51. Be2 Rf8 52. Bg4 Nc8 53. Bf3 Rfe8 54. h4 Rh8 55. h5 Rhe8 56. Bg2 Ne7 57. h6 Rh8 58. Rh3 Rh7 59. Kg1 Ba8 60. Nd1 g4 61. Rh5 g3 62. Nc3 Ng8 63. Ne2 Rxh6 64. Nxg3 Rxh5 65. Nxh5+ Kf7 66. Kf2 Nf6 67. Nxf6 Kxf6 68. Rh1 c3 69. Rc1 Rh8 70. Rxc3 Kxf5 71. Rc7 Kf6 72. Bf3 Rg8 73. Rh7 Rg6 74. Bd1 Rg8 75. Rh6+ Ke7 76. Rxb6 Kd7 77. Rf6 Ke7 78. Rh6 Rg7 79. Rh8 Bb7 80. Rh5 Kd6 81. Rh3 Rf7+ 82. Ke1 Bc8 83. Rh6+ Kc7 84. Rc6+ Kb8 85. Rd6 Bb7 86. b6 Ba6 87. Rxd5 Rf6 88. Rxa5 Rxb6 89. Kd2 Bb7 90. Rb5 Rf6 91. Bb3 Kc7 92. Re5 Ba6 93. Kc3 Rf1 94. Bc2 Rh1 95. a5 Kd6 96. e4 Bf1 97. Rf5 Bg2 98. Rf4 Rc1 99. Kb2 Rh1 100. a6 1-0 |
| 白方:AlphaZero 黑方:Stockfish |
| 1. d4 Nf6 2. c4 e6 3. Nf3 b6 4. g3 Bb7 5. Bg2 Bb4+ 6. Bd2 Be7 7. Nc3 c6 8. e4 d5 9. e5 Ne4 10. 0-0 Ba6 11. b3 Nxc3 12. Bxc3 dxc4 13. b4 b5 14. Nd2 0-0 15. Ne4 Bb7 16. Qg4 Nd7 17. Nc5 Nxc5 18. dxc5 a5 19. a3 axb4 20. axb4 Rxa1 21. Rxa1 Qd3 22. Rc1 Ra8 23. h4 Qd8 24. Be4 Qc8 25. Kg2 Qc7 26. Qh5 g6 27. Qg4 Bf8 28. h5 Rd8 29. Qh4 Qe7 30. Qf6 Qe8 31. Rh1 Rd7 32. hxg6 fxg6 33. Qh4 Qe7 34. Qg4 Rd8 35. Bb2 Qf7 36. Bc1 c3 37. Be3 Be7 38. Qe2 Bf8 39. Qc2 Bg7 40. Qxc3 Qd7 41. Rc1 Qc7 42. Bg5 Rf8 43. f4 h6 44. Bf6 Bxf6 45. exf6 Qf7 46. Ra1 Qxf6 47. Qxf6 Rxf6 48. Ra7 Rf7 49. Bxg6 Rd7 50. Kf2 Kf8 51. g4 Bc8 52. Ra8 Rc7 53. Ke3 h5 54. gxh5 Kg7 55. Ra2 Re7 56. Be4 e5 57. Bxc6 exf4+ 58. Kxf4 Rf7+ 59. Ke5 Rf5+ 60. Kd6 Rxh5 61. Rg2+ Kf6 62. Kc7 Bf5 63. Kb6 Rh4 64. Ka5 Bg4 65. Bxb5 Ke7 66. Rg3 Bc8 67. Re3+ Kf7 68. Be2 1-0 |
| 白方:AlphaZero,黑方:Stockfish |
| 1. d4 e6 2. e4 d5 3. Nc3 Nf6 4. e5 Nfd7 5. f4 c5 6. Nf3 cxd4 7. Nb5 Bb4+ 8. Bd2 Bc5 9. b4 Be7 10. Nbxd4 Nc6 11. c3 a5 12. b5 Nxd4 13. cxd4 Nb6 14. a4 Nc4 15. Bd3 Nxd2 16. Kxd2 Bd7 17. Ke3 b6 18. g4 h5 19. Qg1 hxg4 20. Qxg4 Bf8 21. h4 Qe7 22. Rhc1 g6 23. Rc2 Kd8 24. Rac1 Qe8 25. Rc7 Rc8 26. Rxc8+ Bxc8 27. Rc6 Bb7 28. Rc2 Kd7 29. Ng5 Be7 30. Bxg6 Bxg5 31. Qxg5 fxg6 32. f5 Rg8 33. Qh6 Qf7 34. f6 Kd8 35. Kd2 Kd7 36. Rc1 Kd8 37. Qe3 Qf8 38. Qc3 Qb4 39. Qxb4 axb4 40. Rg1 b3 41. Kc3 Bc8 42. Kxb3 Bd7 43. Kb4 Be8 44. Ra1 Kc7 45. a5 Bd7 46. axb6+ Kxb6 47. Ra6+ Kb7 48. Kc5 Rd8 49. Ra2 Rc8+ 50. Kd6 Be8 51. Ke7 g5 52. hxg5 1-0 |
| 白方:AlphaZero,黑方:Stockfish |
| 1. Nf3 Nf6 2. d4 e6 3. c4 b6 4. g3 Bb7 5. Bg2 Be7 6. 0-0 0-0 7. d5 exd5 8. Nh4 c6 9. cxd5 Nxd5 10. Nf5 Nc7 11. e4 d5 12. exd5 Nxd5 13. Nc3 Nxc3 14. Qg4 g6 15. Nh6+ Kg7 16. bxc3 Bc8 17. Qf4 Qd6 18. Qa4 g5 19. Re1 Kxh6 20. h4 f6 21. Be3 Bf5 22. Rad1 Qa3 23. Qc4 b5 24. hxg5+ fxg5 25. Qh4+ Kg6 26. Qh1 Kg7 27. Be4 Bg6 28. Bxg6 hxg6 29. Qh3 Bf6 30. Kg2 Qxa2 31. Rh1 Qg8 32. c4 Re8 33. Bd4 Bxd4 34. Rxd4 Rd8 35. Rxd8 Qxd8 36. Qe6 Nd7 37. Rd1 Nc5 38. Rxd8 Nxe6 39. Rxa8 Kf6 40. cxb5 cxb5 41. Kf3 Nd4+ 42. Ke4 Nc6 43. Rc8 Ne7 44. Rb8 Nf5 45. g4 Nh6 46. f3 Nf7 47. Ra8 Nd6+ 48. Kd5 Nc4 49. Rxa7 Ne3+ 50. Ke4 Nc4 51. Ra6+ Kg7 52. Rc6 Kf7 53. Rc5 Ke6 54. Rxg5 Kf6 55. Rc5 g5 56. Kd4 1-0 |