AlphaEdit: Null-Space Constrained Knowledge Editing for Language Models
AlphaEdit: Null-Space Constrained Knowledge Editing for Language Models
AlphaEdit:零空间约束的语言模型知识编辑
Junfeng Fang Thanks: Equal contribution. Corresponding author: {xiangwang1223, xiangnanhe}@gmail.com . Affiliation: University of Science and Technology of China, National University of Singapore fangjf1997@gmail.com, jianghc@mail.ustc.edu.cn Houcheng Jiang Kun Wang Yunshan Ma Affiliation: University of Science and Technology of China, National University of Singapore fangjf1997@gmail.com, jianghc@mail.ustc.edu.cn Jie Shi Affiliation: University of Science and Technology of China, National University of Singapore fangjf1997@gmail.com, jianghc@mail.ustc.edu.cn Xiang Wang Xiangnan He Tat-Seng Chua Affiliation: University of Science and Technology of China, National University of Singapore fangjf1997@gmail.com, jianghc@mail.ustc.edu.cn
Abstract
摘要
Large language models (LLMs) often exhibit hallucinations, producing incorrect or outdated knowledge. Hence, model editing methods have emerged to enable targeted knowledge updates. To achieve this, a prevailing paradigm is the locating-then-editing approach, which first locates influential parameters and then edits them by introducing a perturbation. While effective, current studies have demonstrated that this perturbation inevitably disrupt the originally preserved knowledge within LLMs, especially in sequential editing scenarios. To address this, we introduce AlphaEdit, a novel solution that projects perturbation onto the null space of the preserved knowledge before applying it to the parameters. We theoretically prove that this projection ensures the output of post-edited LLMs remains unchanged when queried about the preserved knowledge, thereby mitigating the issue of disruption. Extensive experiments on various LLMs, including LLaMA3, GPT2-XL, and GPT-J, show that AlphaEdit boosts the performance of most locating-then-editing methods by an average of with a single line of additional code for projection solely. Our code is available at: https://github.com/jianghoucheng/AlphaEdit.
大语言模型(LLM)常出现幻觉,输出错误或过时的知识。因此,模型编辑方法应运而生,用于对知识做定向更新。主流范式是「先定位再编辑」:先找到有影响力的参数,再通过引入扰动完成编辑。尽管有效,现有研究已表明,这类扰动不可避免地会破坏 LLM 中原本应保留的知识,在序列编辑场景下尤为严重。为此,我们提出 AlphaEdit:在把扰动作用到参数之前,先将其投影到保留知识的零空间上。我们从理论上证明,这一投影保证编辑后的 LLM 在被问及保留知识时输出保持不变,从而缓解破坏问题。在 LLaMA3、GPT2-XL、GPT-J 等多种 LLM 上的大量实验表明,AlphaEdit 仅需额外一行投影代码,就能把多数「先定位再编辑」方法的性能平均提升 。代码见:https://github.com/jianghoucheng/AlphaEdit。
1 Introduction
1 引言
Large language models (LLMs) have demonstrated the capability to store extensive knowledge during pre-training and recall it during inference (Brown et al. 2020; Petroni et al. 2019; Roberts et al. 2020; Liu et al. 2024). Despite this, they frequently exhibit hallucinations, producing incorrect or outdated information (Cao et al. 2021; Mitchell et al. 2022a). While fine-tuning with updated knowledge offers a straightforward solution, it is often prohibitively time-consuming (Mitchell et al. 2022b). In sight of this, model editing methods have emerged, enabling updating the target knowledge while preserving other knowledge (Yao et al. 2023; Gupta et al. 2024). Broadly, model editing approaches fall into two categories: (1) parameter-modifying methods, which directly adjust a small subset of parameters (Meng et al. 2023; Jiang et al. 2025), and (2) parameter-preserving methods that integrate additional modules without altering the original parameters (Huang et al. 2023; Yu et al. 2024; Hartvigsen et al. 2023; Zheng et al. 2023).
大语言模型(LLM)在预训练阶段已展现出存储大量知识、并在推理时调用的能力(Brown et al. 2020;Petroni et al. 2019;Roberts et al. 2020;Liu et al. 2024)。尽管如此,它们仍频繁出现幻觉,产出错误或过时信息(Cao et al. 2021;Mitchell et al. 2022a)。用更新后的知识做微调是直观方案,但往往耗时过长(Mitchell et al. 2022b)。鉴于此,模型编辑方法兴起:在更新目标知识的同时尽量保留其他知识(Yao et al. 2023;Gupta et al. 2024)。广义上,模型编辑分为两类:(1)改参方法,直接调整一小部分参数(Meng et al. 2023;Jiang et al. 2025);(2)保参方法,在不改原参数的前提下接入额外模块(Huang et al. 2023;Yu et al. 2024;Hartvigsen et al. 2023;Zheng et al. 2023)。
In this paper, we aim to explore the parameter-modifying methods for model editing. Concretely, current parameter-modifying methods typically follow the locate-then-edit paradigm (Meng et al. 2022). The basic idea is to first locate influential parameters through causal tracing, and then edit them by introducing a perturbation (Li et al. 2024b). The common objective for solving is to minimize the output error on the to-be-updated knowledge, denoted as . Additionally, the output error on the to-be-preserved knowledge, , is typically incorporated into the objective function, acting as a constraint to ensure the model’s accuracy on the preserved knowledge.
本文聚焦改参类模型编辑。具体而言,当前改参方法多遵循「先定位再编辑」范式(Meng et al. 2022):先用因果追踪定位有影响力的参数 ,再引入扰动 完成编辑(Li et al. 2024b)。求解 的常见目标是最小化待更新知识上的输出误差 ;同时,待保留知识上的输出误差 通常也会写进目标函数,作为约束以保证模型在保留知识上的正确性。
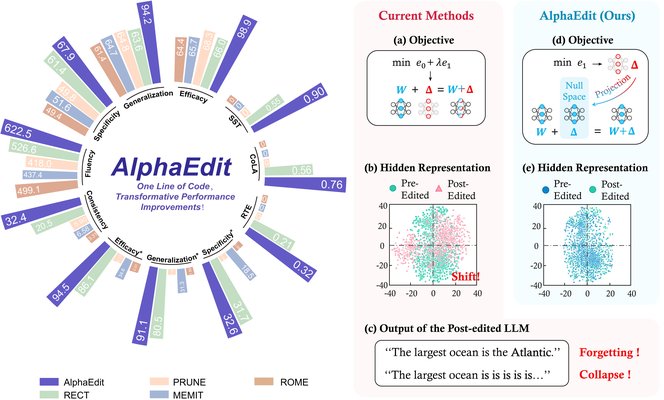
Figure 1: Comparison between the current methods and AlphaEdit. (a) and (d) exhibit the objectives, where is the coefficient to keep balance between and in the objective; (b) and (e) show the distributions of hidden representations after dimensionality reduction within the pre-edited and post-edited LLaMA3, respectively; (c) depicts the output of the post-edited LLaMA3. Best viewed in color.
图 1:现有方法与 AlphaEdit 的对比。(a)(d) 展示目标函数, 用于在目标中平衡 与 ;(b)(e) 展示编辑前、后 LLaMA3 隐表示降维后的分布;(c) 展示编辑后 LLaMA3 的输出。建议彩色阅读。
Despite their success, the current paradigm faces a critical limitation: it struggles to maintain a balance between knowledge-update error and knowledge-preservation error . Specifically, to prioritize the success of update, prior studies focus more on minimizing by assigning a larger weight, while taking insufficient control over . This could make the LLMs after editing (*i.e.,*the post-edited LLMs) overfit to the updated knowledge. This overfitting would introduce a distribution shift of the hidden representations within LLMs. Figure 2 (b) showcases this shift, where the hidden representations in the post-edited LLaMA-3 (8B) (Meta 2024) diverge from their distribution in the original LLM (*i.e.,*the pre-edited LLM). Worse still, in sequential editing scenarios (Gupta & Anumanchipalli 2024) where the LLM undergoes multiple sequential edits, the accumulation of overfitting gradually erodes the model’s ability to preserve knowledge and generate coherent sentences, eventually leading to model forgetting and model collapse, as depicted in Figure 2 (c).
尽管取得成功,当前范式仍有关键局限:难以在知识更新误差 与知识保留误差 之间维持平衡。具体来说,为优先保证更新成功,既有工作往往给 更大权重,对 控制不足。这会使编辑后的 LLM(即 post-edited LLM)过拟合到更新知识。过拟合会带来 LLM 内部隐表示的分布偏移。图 2 (b) 展示了这一偏移:编辑后 LLaMA-3(8B)(Meta 2024)的隐表示相对原始 LLM(即编辑前 LLM)发生偏离。更糟的是,在序列编辑场景(Gupta & Anumanchipalli 2024)——模型经历多次连续编辑——过拟合的累积会逐渐侵蚀保留知识与连贯造句的能力,最终导致模型遗忘与崩溃,如图 2 (c) 所示。
To address these flaws, we instead remove from the current objective, allowing the model to focus solely on minimizing without trade-offs. To avoid overfitting to the to-be-updated knowledge, we project the solution of this new objective onto the null space (Wang et al. 2021) of the preserved knowledge before applying it to the model parameters, as shown in Figure 2 (d). By leveraging the mathematical properties of matrix projection and null space, our new objective ensures that the distribution of hidden representations within LLMs remains invariant post-edited, as shown in Figure 2 (e). This invariance enables the post-edited LLMs to reduce while keeping close to zero, thereby alleviating the issues of model forgetting and model collapse. A detailed theoretical proof is provided in Section 3. In a nutshell, we term the method as AlphaEdit, a simple yet effective editing approach with a null-space constraint for LLMs.
为解决上述缺陷,我们从当前目标中去掉 ,让模型只专注最小化 、不再做权衡。为避免过拟合待更新知识,我们在把该新目标的解应用到模型参数之前,先将其投影到保留知识的零空间(Wang et al. 2021)上,如图 2 (d)。借助矩阵投影与零空间的数学性质,新目标保证编辑后 LLM 内部隐表示分布保持不变,如图 2 (e)。这种不变性使编辑后模型在压低 的同时把 维持在接近零,从而缓解遗忘与崩溃。详细理论证明见第 3 节。简言之,我们称该方法为 AlphaEdit:一种带零空间约束、简单却有效的 LLM 编辑方法。
To validate the effectiveness of our method, we conducted extensive experiments on multiple representative LLMs, such as GPT-2 XL (Radford et al. 2019) and LLaMA-3 (8B). The results show that, compared to the best-performing baseline methods, AlphaEdit can achieve over a 36.7% performance improvement on average by adding just one line of code to the conventional model editing method, MEMIT (Meng et al. 2023), as illustrated in Figure 2. Furthermore, we empirically verified that this simple optimization can be easily integrated into most existing model editing methods (Ma et al. 2024; Gu et al. 2024), functioning as a plug-and-play enhancement that significantly boosts their performance. This highlights AlphaEdit’s crucial role in efficient knowledge updates for LLMs, enabling broader applications and future advancements in the field.
为验证有效性,我们在 GPT-2 XL(Radford et al. 2019)、LLaMA-3(8B)等代表性 LLM 上做了大量实验。结果显示,相对表现最好的基线,AlphaEdit 仅在传统模型编辑方法 MEMIT(Meng et al. 2023)上额外加一行代码,平均就能带来超过 的性能提升,如图 2。我们还实证验证:这一简单优化可轻松接入多数现有模型编辑方法(Ma et al. 2024;Gu et al. 2024),作为即插即用增强显著抬升其表现。这凸显了 AlphaEdit 对 LLM 高效知识更新 的关键作用,有助于更广应用与后续进展。
2 Preliminary
2 预备知识
2.1 Autoregressive Language Model
2.1 自回归语言模型
An autoregressive large language model (LLM) predicts the next token in a sequence based on the preceding tokens. Specifically, the hidden state of at layer within the model, denoted as , can be calculated as:
自回归大语言模型(LLM)根据前文预测序列中的下一个 token 。具体地,模型第 层中 的隐状态记为 ,可按下式计算:
where and represent the outputs of the attention block and the feed-forward network (FFN) layer, respectively; and are the weight matrices of the FFN layers; is the non-linear activation function, and denotes the layer normalization. Following Meng et al. 2022, we express the attention and FFN modules in parallel here.
其中 与 分别表示注意力块与前馈网络(FFN)层的输出; 与 为 FFN 层的权重矩阵; 为非线性激活, 表示层归一化。遵循 Meng et al. 2022,此处将注意力与 FFN 写成并联形式。
It is worth noting that within FFN layers is often interpreted as a linear associative memory, functioning as key-value storage for information retrieval (Geva et al. 2021). Specifically, if the knowledge stored in LLMs is formalized as — representing subject , relation , and object (e.g., , , ) — associates a set of input keys encoding with corresponding values encoding . That is,
值得注意的是,FFN 层中的 常被解读为线性联想记忆,充当信息检索的键值存储(Geva et al. 2021)。具体地,若将 LLM 中存储的知识形式化为 ——分别表示主语 、关系 与宾语 (例如 ,,)——则 把编码 的一组输入键 与编码 的对应值 关联起来。即:
This interpretation has inspired most model editing methods to modify the FFN layers for knowledge updates (Hase et al. 2023; Li et al. 2024a; Hu et al. 2024). For simplicity, we use to refer to in the following sections.
这一解读启发了多数模型编辑方法去修改 FFN 层以更新知识(Hase et al. 2023;Li et al. 2024a;Hu et al. 2024)。为简洁起见,后文用 指代 。
2.2 Model Editing in LLMs
2.2 LLM 中的模型编辑
Model editing aims to update knowledge stored in LLMs through a single edit or multiple edits (i.e., sequential editing). Each edit modifies the model parameters by adding a perturbation in locate-then-edit paradigm. Specifically, suppose each edit needs to update pieces of knowledge in the form of . The perturbed is expected to associate new - pairs, where and encode and of the new knowledge, respectively. Let , where and represent the dimensions of the FFN’s intermediate and output layers. Then, we can stack these keys and values into matrices following:
模型编辑旨在通过单次或多次编辑(即序列编辑)更新 LLM 中存储的知识。在「先定位再编辑」范式下,每次编辑通过对模型参数 加扰动 来完成。具体地,设每次编辑需更新 条形如 的知识。扰动后的 期望关联 对新的 -,其中 、 分别编码新知识的 与 。令 ,其中 、 分别为 FFN 中间层与输出层维度。可将这些键与值按如下方式堆叠成矩阵:
where the subscripts of and represent the index of the to-be-updated knowledge. Based on these, the objective can be expressed as:
其中 、 的下标表示待更新知识的索引。据此,目标可写为:
where denotes the sum of the squared elements in the matrix.
其中 表示矩阵元素平方和。
Additionally, let and represent the matrices formed by stacking the and of the preserved knowledge. Current methods (Meng et al. 2023; Gu et al. 2024) typically incorporate the error involving and to preserve it, as follows:
此外,令 、 表示由保留知识的 、 堆叠而成的矩阵。当前方法(Meng et al. 2023;Gu et al. 2024)通常把涉及 、 的误差纳入目标以保留这些知识,如下:
Since and encode the preserved knowledge in LLMs, we have (cf. Eqn. 2). Thus, by applying the normal equation (Lang 2012), if the closed-form solution of Eqn. 5 exists, it can be written as:
由于 、 编码 LLM 中的保留知识,有 (参见式 2)。于是,由正规方程(Lang 2012),若式 5 存在闭式解,则可写为:
Although is difficult to obtain directly since we hardly have access to the LLM’s full extent of knowledge, it can be estimated using abundant text input (Meng et al. 2023). In practical applications, triplets from Wikipedia are typically randomly selected to encode (Meng et al. 2023), making a high-dimensional matrix with columns (i.e., ). See Appendix B.1 for detailed implementation steps.
尽管 难以直接获得——我们几乎无法访问 LLM 的全部知识——但可用大量文本输入估计(Meng et al. 2023)。实践中通常从 Wikipedia 随机选取 条 三元组编码 (Meng et al. 2023),使 成为有 列的高维矩阵(即 )。详细实现见附录 B.1。
3 Method
3 方法
In this section, we first introduce the concept of the null space and its relationship to model editing (Section 3.1). Based on this, we present the method for projecting a given perturbation onto the null space of the matrix , which encodes the persevered knowledge (Section 3.2). Following that, a new editing objective that incorporates the aforementioned projection method is introduced in Section 3.3.
本节先介绍零空间概念及其与模型编辑的关系(第 3.1 节)。据此给出如何将给定扰动 投影到编码保留知识的矩阵 的零空间(第 3.2 节)。随后在第 3.3 节引入融入上述投影的新编辑目标。
3.1 Null Space
3.1 零空间
Null space is at the core of our work. Here we first introduce the definition of the left null space (hereafter referred to simply as null space). Specifically, given two matrices and , is in the null space of if and only if . See Adam-NSCL (Wang et al. 2021) for more details.
零空间是本文核心。这里先给出左零空间的定义(后文简称为零空间)。具体地,给定矩阵 、,当且仅当 时,称 落在 的零空间中。更多细节见 Adam-NSCL(Wang et al. 2021)。
In the context of model editing, if the perturbation is projected into the null space of (i.e., , where denotes the projected perturbation), adding it to the parameters results in:
在模型编辑语境下,若将扰动 投影到 的零空间(即 ,其中 为投影后的扰动),再加到参数 上,则有:
This implies that the projected will not disrupt the key-value associations of the preserved knowledge (i.e., ), ensuring that the storage of the preserved knowledge remains intact.
这意味着:投影后的 不会破坏保留知识的键值关联(即 ),从而保证保留知识的存储完好。
Therefore, in this work, before adding perturbation to the model parameters , we project it onto the null space of to protect the preserved knowledge. This protection allows us to remove the first term — the term focusing on protecting the preserved knowledge — from the objective in Eqn. 5.
因此,本文在把扰动 加到模型参数 之前,先将其投影到 的零空间以保护保留知识。这一保护使我们得以从式 5 的目标中去掉第一项——专注于保护保留知识的那一项。
3.2 Null Space Projecting
3.2 零空间投影
In Section 3.1, we briefly explained why should be projected into the null space of . In this part, we focus on how to implement this projection.
第 3.1 节简要说明了为何要把 投影到 的零空间。本小节聚焦如何实现该投影。
As introduced at the end of Section 2.2, the matrix has a high dimensionality with columns. Hence, directly projecting the given perturbation onto the null space of presents significant computational and storage challenges. In sight of this, we adopt the null space of the non-central covariance matrix as a substitute to reduce computational complexity, as is typically much smaller than . This matrix’s null space is equal to that of (please see Appendix B.2 for detailed proof).
如第 2.2 节末所述,矩阵 列数高达 。因此直接把给定扰动 投影到 的零空间会带来显著的计算与存储负担。有鉴于此,我们改用非中心协方差矩阵 的零空间作为替代以降低复杂度,因为 通常远小于 。该矩阵与 的零空间相同(详细证明见附录 B.2)。
Following the existing methods for conducting null space projection (Wang et al. 2021), we first apply a Singular Value Decomposition (SVD) to :
遵循既有零空间投影做法(Wang et al. 2021),我们先对 做奇异值分解(SVD):
where each column in is an eigenvector of . Then, we remove the eigenvectors in that correspond to non-zero eigenvalues[^1], and define the remaining submatrix as . Based on this, the projection matrix can be defined as follows:
其中 的每一列是 的特征向量。随后去掉 中对应非零特征值的特征向量[^1],将其余子矩阵记为 。据此,投影矩阵 可定义为:
This projection matrix can map the column vectors of into the null space of , as it satisfies the condition . The detailed derivation is exhibited in Appendix B.3.
该投影矩阵可将 的列向量映射到 的零空间,因为它满足 。详细推导见附录 B.3。
Since and share the same null space, we can derive . Hence, we have:
由于 与 共享同一零空间,可得 。于是:
This shows the projection matrix ensures that the model edits occur without interference with the preserved knowledge in LLMs.
这表明投影矩阵 保证模型编辑不会干扰 LLM 中的保留知识。
3.3 Null-Space Constrained Model Editing
3.3 零空间约束的模型编辑
Section 3.2 has provided how to apply projection to ensure that preserved knowledge is not disrupted. Here, we introduce how to leverage this projection to optimize the current model editing objective.
第 3.2 节给出了如何用投影保证保留知识不被破坏。这里介绍如何借助该投影优化当前模型编辑目标。
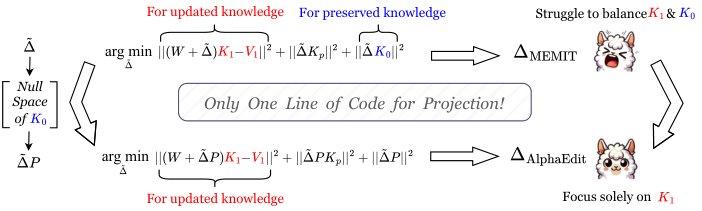
Figure 3: Comparison between the paradigms of AlphaEdit and current method. Best viewed in color.
图 3:AlphaEdit 与现有方法范式的对比。建议彩色阅读。
Starting with the single-edit objective in Eqn. 5, the optimization follows three steps: (1) Replace with the projected perturbation , ensuring that the perturbation would not disrupt the preserved knowledge; (2) Remove the first term involving , as Step (1) has already protected the preserved knowledge from being disrupted; (3) Add a regularization term to guarantee stable convergence. With these optimizations, Eqn. 5 becomes:
从式 5 的单次编辑目标出发,优化分三步:(1) 用投影扰动 替换 ,确保扰动不破坏保留知识;(2) 去掉涉及 的第一项,因为步骤 (1) 已保护保留知识;(3) 加入正则项 以保证稳定收敛。经此优化,式 5 变为:
where and denote the key and value matrices of to-be-updated knowledge defined in Eqn. 3.
其中 、 表示式 3 中定义的待更新知识的键、值矩阵。
In sequential editing tasks, during the current edit, we also need to add a term to the objective (cf. Eqn. 11) to prevent the perturbation from disrupting the updated knowledge in previous edits. Let and present the key and value matrices of the previously updated knowledge, analogous to the earlier definitions of and . This term should minimize to protect the association. Since the related knowledge has been updated in previous edits, we have . Hence, this term can be simplified to , and adding it to Eqn. 11 gives the new objective:
在序列编辑任务中,当前编辑还需在目标中加入一项(参见式 11),防止扰动破坏此前各次编辑已更新的知识。令 、 表示此前已更新知识的键、值矩阵,定义方式类比 、。该项应最小化 以保护关联。由于相关知识已在先前编辑中更新,有 。故该项可简化为 ,将其加入式 11 得到新目标:
To facilitate expression, we define the residual vector of the current edit as . Based on this, Eqn. 12 can be solved using the normal equation (Lang 2012):
为便于表述,将当前编辑的残差向量定义为 。据此,可用正规方程(Lang 2012)求解式 12:
Solving Eqn. 13 yields the final perturbation which will be added to the model parameters :
求解式 13 得到最终扰动 ,将其加到模型参数 :
The detailed derivation process and the invertibility of the term within the brackets are provided in Appendices B.4 and B.5 respectively. This solution could not only store the to-be-updated knowledge in the current edit, but also ensure that both the preserved knowledge and the previously updated knowledge remain unaffected. Furthermore, for better comparison, we also present the commonly used solution in existing methods like MEMIT (Meng et al. 2023) as follows[^2]:
详细推导过程及括号内项的可逆性分别见附录 B.4 与 B.5。解 不仅能在当前编辑中存入待更新知识,还能保证保留知识与此前已更新知识均不受影响。为便于对比,我们也给出 MEMIT(Meng et al. 2023)等现有方法常用的解[^2]:
By comparing Eqn. 14 and 15, it is evident that our approach requires only a minor modification to the standard solution by incorporating the projection matrix . This makes our method easily integrable into existing model editing algorithms. Figure 3 summarizes this modification from the perspective of convergence objectives. We emphasize that by adding just a single line of code for this modification, the performance of most editing methods could be significantly enhanced, as shown in Figure 2. More detailed experimental results are exhibited in Section 4.
对比式 14 与 15 可见,我们的方法只需在标准解上乘入投影矩阵 ,改动很小,因而易于接入现有模型编辑算法。图 3 从收敛目标角度概括了这一修改。我们强调:仅额外加一行代码完成该修改,多数编辑方法的性能就能显著提升,如图 2。更详细实验结果见第 4 节。
Furthermore, since the projection matrix is entirely independent of the to-be-updated knowledge, it only needs to be computed once and can then be directly applied to any downstream editing tasks. Consequently, AlphaEdit introduces negligible additional time consumption compared to baselines, making it both efficient and effective.
此外,由于投影矩阵 完全独立于待更新知识,只需计算一次即可直接用于任意下游编辑任务。因此相对基线,AlphaEdit 引入的额外时间开销可忽略,兼具高效与有效。
4 Experiment
4 实验
In this section, we conduct experiments to address the following research questions:
本节通过实验回答以下研究问题:
- • RQ1: How does AlphaEdit perform on sequential editing tasks compared to baseline methods? Can it mitigate the issues of model forgetting and model collapse exhibited in Figure 2?
- • RQ2: How does AlphaEdit-edited LLM perform on general ability evaluations? Does the post-edited LLM successfully retain its inherent capabilities?
- • RQ3: Can AlphaEdit effectively prevent the model from overfitting to updated knowledge? Specifically, can the post-edited LLM avoid shifts in the distribution of hidden representations?
- • RQ4: Can the performance of baseline methods be significantly improved with a single line of code in AlphaEdit (i.e., the code for projection)?
- • RQ1: 相对基线,AlphaEdit 在序列编辑任务上表现如何?能否缓解图 2 所示的模型遗忘与崩溃?
- • RQ2: 经 AlphaEdit 编辑后的 LLM 在通用能力评测上表现如何?编辑后模型是否成功保留固有能力?
- • RQ3: AlphaEdit 能否有效防止模型过拟合更新知识?具体地,编辑后 LLM 能否避免隐表示分布发生偏移?
- • RQ4: 仅加入 AlphaEdit 中一行投影代码,基线方法的性能能否显著提升?
| Method | Model | Counterfact | ZsRE | ||||||
|---|---|---|---|---|---|---|---|---|---|
| Eff. | Gen. | Spe. | Flu. | Consis. | Eff. | Gen. | Spe. | ||
| Pre-edited | LLaMA3 | 7.850.26 | 10.580.26 | 89.480.18 | 635.230.11 | 24.140.08 | 36.990.30 | 36.340.30 | 31.890.22 |
| FT | 83.330.37 | 67.790.40 | 46.630.37 | 233.720.22 | 8.770.05 | 30.480.26 | 30.220.32 | 15.490.17 | |
| MEND | 63.240.31 | 61.170.36 | 45.370.38 | 372.160.80 | 4.210.05 | 0.910.05 | 1.090.05 | 0.530.02 | |
| InstructEdit | 66.580.24 | 64.180.35 | 47.140.37 | 443.850.78 | 7.280.04 | 1.580.04 | 1.360.08 | 1.010.05 | |
| ROME | 64.400.41 | 61.420.42 | 49.440.38 | 449.060.26 | 3.310.02 | 2.010.07 | 1.800.07 | 0.690.03 | |
| MEMIT | 65.650.47 | 64.650.42 | 51.560.38 | 437.431.67 | 6.580.11 | 34.620.36 | 31.280.34 | 18.490.19 | |
| PRUNE | 68.250.46 | 64.750.41 | 49.820.36 | 418.031.52 | 5.900.10 | 24.770.27 | 23.870.27 | 20.690.23 | |
| RECT | 66.050.47 | 63.620.43 | 61.410.37 | 526.620.44 | 20.540.09 | 86.050.23 | 80.540.27 | 31.670.22 | |
| AlphaEdit | 98.900.10 | 94.220.19 | 67.880.29 | 622.490.16 | 32.400.11 | 94.470.13 | 91.130.19 | 32.550.22 | |
| Pre-edited | GPT-J | 16.220.31 | 18.560.45 | 83.110.13 | 621.810.67 | 29.740.51 | 26.32037 | 25.790.25 | 27.420.53 |
| FT | 92.150.27 | 72.380.38 | 43.350.37 | 297.920.77 | 6.650.10 | 72.370.29 | 68.910.32 | 19.660.23 | |
| MEND | 46.150.50 | 46.220.51 | 53.900.48 | 242.410.41 | 3.940.03 | 0.710.04 | 0.710.04 | 0.520.03 | |
| InstructEdit | 50.620.58 | 51.730.42 | 56.280.50 | 245.890.44 | 4.210.04 | 0.920.07 | 0.880.03 | 0.650.06 | |
| ROME | 57.500.48 | 54.200.40 | 52.050.31 | 589.420.08 | 3.220.02 | 56.420.42 | 54.650.42 | 9.860.16 | |
| MEMIT | 98.550.11 | 95.500.16 | 63.640.31 | 546.280.88 | 34.890.15 | 94.910.16 | 90.220.23 | 30.390.27 | |
| PRUNE | 86.150.34 | 86.850.29 | 53.870.35 | 427.140.53 | 14.780.11 | 0.150.02 | 0.150.02 | 0.000.00 | |
| RECT | 98.800.10 | 86.580.28 | 72.220.28 | 617.310.19 | 41.390.12 | 96.380.14 | 91.210.21 | 27.790.26 | |
| AlphaEdit | 99.750.08 | 96.380.23 | 75.480.21 | 618.500.17 | 42.080.15 | 99.790.14 | 96.000.22 | 28.290.25 | |
| Pre-edited | GPT2-XL | 22.230.73 | 24.340.62 | 78.530.33 | 626.640.31 | 31.880.20 | 22.190.24 | 31.300.27 | 24.150.32 |
| FT | 63.550.48 | 42.200.41 | 57.060.30 | 519.350.27 | 10.560.05 | 37.110.39 | 33.300.37 | 10.360.17 | |
| MEND | 50.800.50 | 50.800.48 | 49.200.51 | 407.210.08 | 1.010.00 | 0.000.00 | 0.000.00 | 0.000.00 | |
| InstructEdit | 55.320.58 | 53.630.42 | 53.250.62 | 412.570.15 | 1.080.03 | 3.540.03 | 4.250.02 | 3.230.04 | |
| ROME | 54.600.48 | 51.180.40 | 52.680.33 | 366.131.40 | 0.720.02 | 47.500.43 | 43.560.42 | 14.270.19 | |
| MEMIT | 94.700.22 | 85.820.28 | 60.500.32 | 477.260.54 | 22.720.15 | 79.170.32 | 71.440.36 | 26.420.25 | |
| PRUNE | 82.050.38 | 78.550.34 | 53.020.35 | 530.470.39 | 15.930.11 | 21.620.30 | 19.270.28 | 13.190.18 | |
| RECT | 92.150.26 | 81.150.33 | 65.130.31 | 480.830.62 | 21.050.16 | 81.020.31 | 73.080.35 | 24.850.25 | |
| AlphaEdit | 99.500.24 | 93.950.34 | 66.390.31 | 597.880.18 | 39.380.15 | 94.810.30 | 86.110.29 | 25.880.21 |
Table 1: Comparison of AlphaEdit with existing methods on the sequential model editing task. Eff., Gen., Spe., Flu. and Consis. denote Efficacy, Generalization, Specificity, Fluency and Consistency, respectively. The best results are highlighted in bold, while the second-best results are underlined.
| 方法 | 模型 | Counterfact | ZsRE | ||||||
|---|---|---|---|---|---|---|---|---|---|
| Eff. | Gen. | Spe. | Flu. | Consis. | Eff. | Gen. | Spe. | ||
| Pre-edited | LLaMA3 | 7.850.26 | 10.580.26 | 89.480.18 | 635.230.11 | 24.140.08 | 36.990.30 | 36.340.30 | 31.890.22 |
| FT | 83.330.37 | 67.790.40 | 46.630.37 | 233.720.22 | 8.770.05 | 30.480.26 | 30.220.32 | 15.490.17 | |
| MEND | 63.240.31 | 61.170.36 | 45.370.38 | 372.160.80 | 4.210.05 | 0.910.05 | 1.090.05 | 0.530.02 | |
| InstructEdit | 66.580.24 | 64.180.35 | 47.140.37 | 443.850.78 | 7.280.04 | 1.580.04 | 1.360.08 | 1.010.05 | |
| ROME | 64.400.41 | 61.420.42 | 49.440.38 | 449.060.26 | 3.310.02 | 2.010.07 | 1.800.07 | 0.690.03 | |
| MEMIT | 65.650.47 | 64.650.42 | 51.560.38 | 437.431.67 | 6.580.11 | 34.620.36 | 31.280.34 | 18.490.19 | |
| PRUNE | 68.250.46 | 64.750.41 | 49.820.36 | 418.031.52 | 5.900.10 | 24.770.27 | 23.870.27 | 20.690.23 | |
| RECT | 66.050.47 | 63.620.43 | 61.410.37 | 526.620.44 | 20.540.09 | 86.050.23 | 80.540.27 | 31.670.22 | |
| AlphaEdit | 98.900.10 | 94.220.19 | 67.880.29 | 622.490.16 | 32.400.11 | 94.470.13 | 91.130.19 | 32.550.22 | |
| Pre-edited | GPT-J | 16.220.31 | 18.560.45 | 83.110.13 | 621.810.67 | 29.740.51 | 26.32037 | 25.790.25 | 27.420.53 |
| FT | 92.150.27 | 72.380.38 | 43.350.37 | 297.920.77 | 6.650.10 | 72.370.29 | 68.910.32 | 19.660.23 | |
| MEND | 46.150.50 | 46.220.51 | 53.900.48 | 242.410.41 | 3.940.03 | 0.710.04 | 0.710.04 | 0.520.03 | |
| InstructEdit | 50.620.58 | 51.730.42 | 56.280.50 | 245.890.44 | 4.210.04 | 0.920.07 | 0.880.03 | 0.650.06 | |
| ROME | 57.500.48 | 54.200.40 | 52.050.31 | 589.420.08 | 3.220.02 | 56.420.42 | 54.650.42 | 9.860.16 | |
| MEMIT | 98.550.11 | 95.500.16 | 63.640.31 | 546.280.88 | 34.890.15 | 94.910.16 | 90.220.23 | 30.390.27 | |
| PRUNE | 86.150.34 | 86.850.29 | 53.870.35 | 427.140.53 | 14.780.11 | 0.150.02 | 0.150.02 | 0.000.00 | |
| RECT | 98.800.10 | 86.580.28 | 72.220.28 | 617.310.19 | 41.390.12 | 96.380.14 | 91.210.21 | 27.790.26 | |
| AlphaEdit | 99.750.08 | 96.380.23 | 75.480.21 | 618.500.17 | 42.080.15 | 99.790.14 | 96.000.22 | 28.290.25 | |
| Pre-edited | GPT2-XL | 22.230.73 | 24.340.62 | 78.530.33 | 626.640.31 | 31.880.20 | 22.190.24 | 31.300.27 | 24.150.32 |
| FT | 63.550.48 | 42.200.41 | 57.060.30 | 519.350.27 | 10.560.05 | 37.110.39 | 33.300.37 | 10.360.17 | |
| MEND | 50.800.50 | 50.800.48 | 49.200.51 | 407.210.08 | 1.010.00 | 0.000.00 | 0.000.00 | 0.000.00 | |
| InstructEdit | 55.320.58 | 53.630.42 | 53.250.62 | 412.570.15 | 1.080.03 | 3.540.03 | 4.250.02 | 3.230.04 | |
| ROME | 54.600.48 | 51.180.40 | 52.680.33 | 366.131.40 | 0.720.02 | 47.500.43 | 43.560.42 | 14.270.19 | |
| MEMIT | 94.700.22 | 85.820.28 | 60.500.32 | 477.260.54 | 22.720.15 | 79.170.32 | 71.440.36 | 26.420.25 | |
| PRUNE | 82.050.38 | 78.550.34 | 53.020.35 | 530.470.39 | 15.930.11 | 21.620.30 | 19.270.28 | 13.190.18 | |
| RECT | 92.150.26 | 81.150.33 | 65.130.31 | 480.830.62 | 21.050.16 | 81.020.31 | 73.080.35 | 24.850.25 | |
| AlphaEdit | 99.500.24 | 93.950.34 | 66.390.31 | 597.880.18 | 39.380.15 | 94.810.30 | 86.110.29 | 25.880.21 |
表 1:序列模型编辑任务上 AlphaEdit 与现有方法的对比。Eff.、Gen.、Spe.、Flu.、Consis. 分别表示 Efficacy、Generalization、Specificity、Fluency、Consistency。最优加粗,次优下划线。
4.1 Experimental Setup
4.1 实验设置
We begin by briefly outlining the evaluation metrics, datasets, and baseline methods. For more detailed descriptions of the experimental settings, please refer to Appendix A.
我们先简要概述评价指标、数据集与基线方法。更细致的实验设定见附录 A。
Base LLMs & Baseline Methods. Our experiments are conducted on three LLMs: GPT2-XL (1.5B), GPT-J (6B), and LLaMA3 (8B). We compare our method against several model editing baselines, including Fine-Tuning (FT) (Zhu et al. 2020), MEND (Mitchell et al. 2022a), InstructEdit (Zhang et al. 2024b), ROME (Meng et al. 2022), MEMIT (Meng et al. 2023), PRUNE (Ma et al. 2024), and RECT (Gu et al. 2024). Furthermore, to further validate the generalizability of AlphaEdit, we include three memory-based editing methods (i.e., SERAC (Mitchell et al. 2022b), GRACE (Hartvigsen et al. 2023) and MELO (Yu et al. 2024)) as baselines in Appendix C.5, along with two additional base LLMs: Gemma (Mesnard et al. 2024) and phi-1.5 (Li et al. 2023) in Appendix C.6.
基座 LLM 与基线方法。 实验在三个 LLM 上进行:GPT2-XL(1.5B)、GPT-J(6B)与 LLaMA3(8B)。对比基线包括 Fine-Tuning(FT)(Zhu et al. 2020)、MEND(Mitchell et al. 2022a)、InstructEdit(Zhang et al. 2024b)、ROME(Meng et al. 2022)、MEMIT(Meng et al. 2023)、PRUNE(Ma et al. 2024)与 RECT(Gu et al. 2024)。为进一步验证 AlphaEdit 的泛化性,附录 C.5 另纳入三种基于记忆的编辑方法(即 SERAC(Mitchell et al. 2022b)、GRACE(Hartvigsen et al. 2023)与 MELO(Yu et al. 2024))作基线,附录 C.6 再补充两个基座 LLM:Gemma(Mesnard et al. 2024)与 phi-1.5(Li et al. 2023)。
Datasets & Evaluation Metrics. We evaluate AlphaEdit using two widely adopted benchmarks: the Counterfact dataset (Meng et al. 2022) and the ZsRE dataset (Levy et al. 2017). In line with prior works (Meng et al. 2022), we employ Efficacy (efficiency success), Generalization (paraphrase success), Specificity (neighborhood success), Fluency (generation entropy), and Consistency (reference score) as evaluation metrics. In addition, for comprehensive evaluation, Appendix C.7 presents experiments conducted on three additional datasets: LongformEvaluation (Rosati et al. 2024), MQUAKE (Zhong et al. 2023), and KnowEdit (Zhang et al. 2024d). We encourage interested readers to refer to Appendix C.7 for further details.
数据集与评价指标。 我们在两个广泛使用的基准上评估 AlphaEdit:Counterfact(Meng et al. 2022)与 ZsRE(Levy et al. 2017)。与既有工作(Meng et al. 2022)一致,采用 Efficacy(编辑成功率)、Generalization(改写成功率)、Specificity(邻域成功率)、Fluency(生成熵)与 Consistency(参考分数)作为指标。为更全面评估,附录 C.7 还在 LongformEvaluation(Rosati et al. 2024)、MQUAKE(Zhong et al. 2023)与 KnowEdit(Zhang et al. 2024d)三个额外数据集上报告实验。感兴趣的读者可参阅附录 C.7。
4.2 Performance on Knowledge Update and Preservation (RQ1)
4.2 知识更新与保留表现(RQ1)
To evaluate the performance of different editing methods in terms of knowledge update and retention, we conducted sequential editing on three base LLMs using AlphaEdit and the baseline methods. Table 1 presents the results under a commonly used configuration for the sequential editing task, where 2,000 samples are randomly drawn from the dataset for updates, with 100 samples per edit (i.e., a batch size of 100). For additional experimental results, such as case studies of model outputs after editing, please refer to Appendix C. Based on Table 1, we can draw the following observations:
为评估不同编辑方法在知识更新与保留上的表现,我们在三个基座 LLM 上用 AlphaEdit 与各基线做序列编辑。表 1 给出序列编辑任务常用配置下的结果:从数据集随机抽取 2,000 条样本做更新,每次编辑 100 条(即 batch size 为 100)。更多结果——如编辑后模型输出的案例——见附录 C。基于表 1,我们有如下观察:
- • Obs 1: AlphaEdit achieves superior performance across nearly all metrics and base models. Specifically, in terms of Efficacy and Generalization metrics, AlphaEdit provides an average improvement of 12.54% and 16.78%, respectively, over the best baseline. On LLaMA3, these performance boosts are even more remarkable (i.e., and ). These gains arise from AlphaEdit’s ability to mitigate the trade-off between updating and preserving knowledge.
- • Obs 2: AlphaEdit enhances text generation fluency and coherence. In addition to editing capabilities, AlphaEdit also exhibits substantial improvements in Fluency and Coherence. For instance, on GPT2-XL, AlphaEdit achieves an improvement over the strongest baseline, demonstrating that it can preserve both the knowledge and the ability to generate fluent text.
- • 观察 1:AlphaEdit 在几乎所有指标与基座模型上均取得更优表现。 具体地,在 Efficacy 与 Generalization 上,AlphaEdit 相对最强基线平均分别提升 与 ;在 LLaMA3 上提升更为显著(即 与 )。这些收益来自 AlphaEdit 缓解了更新与保留知识之间的权衡。
- • 观察 2:AlphaEdit 提升文本生成的流畅性与连贯性。 除编辑能力外,AlphaEdit 在 Fluency 与 Coherence 上也有可观提升。例如在 GPT2-XL 上,相对最强基线提升 ,表明它既能保留知识,也能维持流畅造句能力。
4.3 General Capability Tests (RQ2)
4.3 通用能力测试(RQ2)
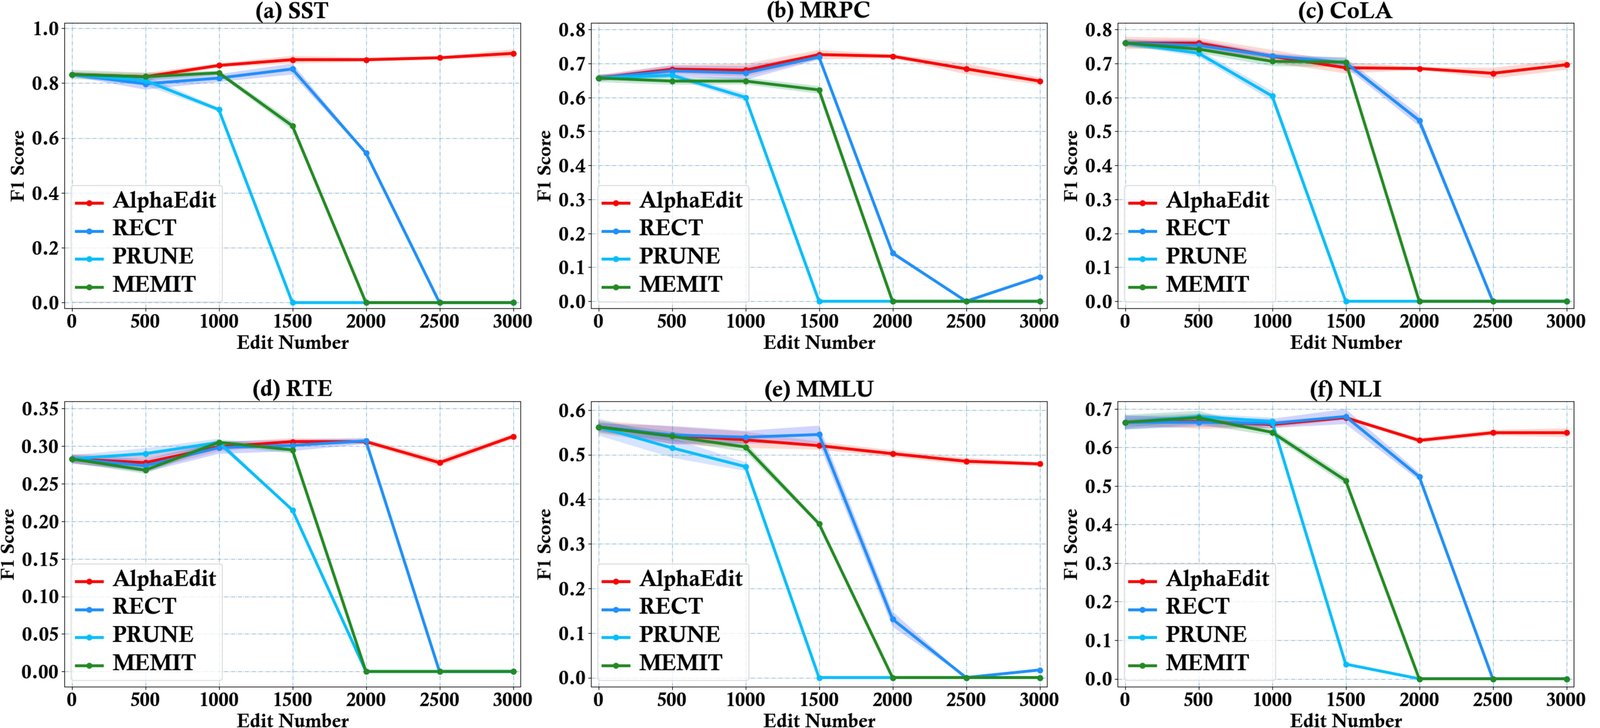
Figure 4: F1 scores of the post-edited LLaMA3 (8B) on six tasks (i.e., SST, MRPC, CoLA, RTE, MMLU and NLI) used for general capability testing. Best viewed in color.
图 4:编辑后 LLaMA3(8B)在通用能力测试六项任务(即 SST、MRPC、CoLA、RTE、MMLU 与 NLI)上的 F1。建议彩色阅读。
To further evaluate the intrinsic knowledge of post-edited LLMs, we perform General Capability Tests using six natural language tasks from the General Language Understanding Evaluation (GLUE) benchmark (Wang et al. 2019). Specifically, the evaluation tasks include:
为进一步评估编辑后 LLM 的内在知识,我们用 General Language Understanding Evaluation(GLUE)基准(Wang et al. 2019)中的六项自然语言任务做通用能力测试。具体任务包括:
- SST (The Stanford Sentiment Treebank) (Socher et al. 2013) is a single-sentence classification task involving sentences from movie reviews and their corresponding human-annotated sentiment labels. The task requires classifying the sentiment into two categories.
- MRPC (Microsoft Research Paraphrase Corpus) (Dolan & Brockett 2005) is a well-known benchmark for text matching and semantic similarity assessment. In the MRPC task, the objective is to determine whether a given pair of sentences is semantically equivalent.
- MMLU (Massive Multi-task Language Understanding) (Hendrycks et al. 2021) is a comprehensive evaluation designed to measure the multi-task accuracy of text models. This assessment focuses on evaluating models under zero-shot and few-shot settings.
- RTE (Recognizing Textual Entailment) (Bentivogli et al. 2009) involves natural language inference that determines if a premise sentence logically entails a hypothesis sentence.
- CoLA (Corpus of Linguistic Acceptability) (Warstadt et al. 2019) is a single-sentence classification task, where sentences are annotated as either grammatically acceptable or unacceptable.
- NLI (Natural Language Inference) (Williams et al. 2018) focuses on natural language understanding, requiring the model to infer the logical relationship between pairs of sentences.
- SST(Stanford Sentiment Treebank)(Socher et al. 2013)是单句分类任务,数据来自影评句子及其人工标注情感标签,需将情感分为两类。
- MRPC(Microsoft Research Paraphrase Corpus)(Dolan & Brockett 2005)是文本匹配与语义相似度评估的知名基准,目标是判断给定句对是否语义等价。
- MMLU(Massive Multi-task Language Understanding)(Hendrycks et al. 2021)旨在衡量文本模型的多任务准确率,侧重零样本与少样本设定。
- RTE(Recognizing Textual Entailment)(Bentivogli et al. 2009)属于自然语言推理,判断前提句是否在逻辑上蕴含假设句。
- CoLA(Corpus of Linguistic Acceptability)(Warstadt et al. 2019)是单句分类任务,句子被标注为语法可接受或不可接受。
- NLI(Natural Language Inference)(Williams et al. 2018)聚焦自然语言理解,要求模型推断句对之间的逻辑关系。
Figure 4 illustrates the performance as the number of edited samples increases across six tasks. More results are provided in Appendix C.2. Based on Figure 4, we have the following observations:
图 4 展示随编辑样本数增加、六项任务上的表现变化。更多结果见附录 C.2。基于图 4,我们有如下观察:
- • Obs 3: AlphaEdit sustains the general capability of post-edited LLMs even after extensive editing. Specifically, AlphaEdit maintains the original model performance across all metrics, even after editing 3,000 samples, demonstrating that the null-space projection not only safeguards the preserved knowledge but also protects the general capability learned from this knowledge’s corpus.
- • Obs 4: LLMs edited with baseline methods experience significant degradation of general capability after editing 2,000 samples. Specifically, in this case, all metrics are rapidly approaching zero, confirming our theoretical analysis that the common objective are inherently flawed and fail to balance knowledge update and preservation.
- • 观察 3:即便经历大量编辑,AlphaEdit 仍能维持编辑后 LLM 的通用能力。 具体地,即便编辑 3,000 条样本,AlphaEdit 在所有指标上仍保持接近原始模型的表现,说明零空间投影不仅保护保留知识,也保护了从这些知识语料中学到的通用能力。
- • 观察 4:用基线方法编辑的 LLM,在编辑约 2,000 条样本后通用能力显著退化。 此时各项指标迅速趋近于零,印证了我们的理论分析:常见目标本身有缺陷,难以平衡知识更新与保留。
4.4 Hidden Representations Analysis (RQ3)
4.4 隐表示分析(RQ3)
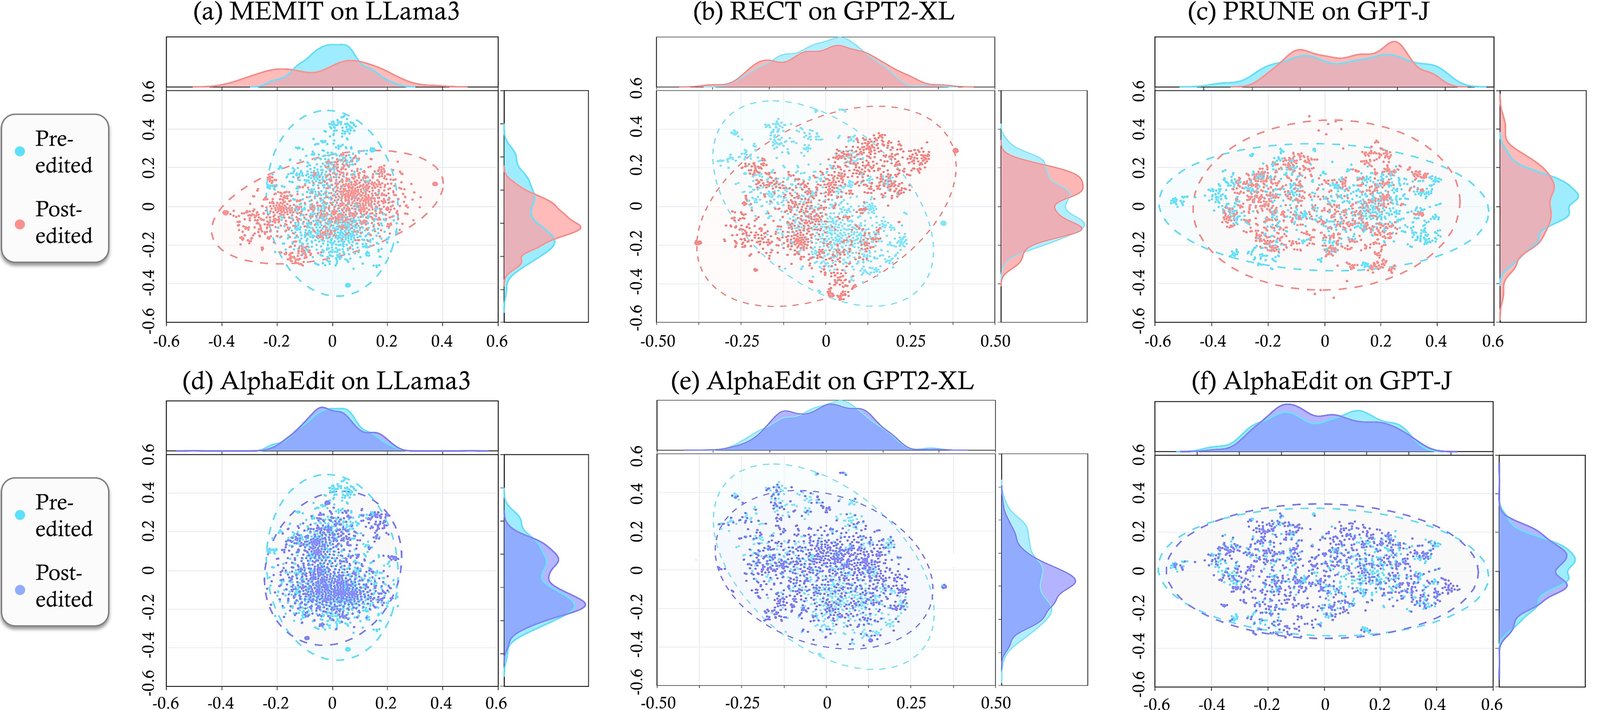
Figure 5: The distribution of hidden representations of pre-edited and post-edited LLMs after dimensionality reduction. The top and right curve graphs display the marginal distributions for two reduced dimensions, where AlphaEdit consistently exhibits minimal shift. Best viewed in color.
图 5:编辑前、后 LLM 隐表示降维后的分布。上方与右侧曲线为两个降维维度上的边缘分布;AlphaEdit 始终呈现最小偏移。建议彩色阅读。
As discussed in previous sections, current editing methods often cause post-edited LLMs to overfit to the updated knowledge, leading to a shift in the distribution of hidden representations. Hence, here we aim to empirically verify that AlphaEdit can prevent overfitting and avoid this distributional shift. To validate it, we conducted the following steps: (1) We randomly select 1,000 factual prompts and extract the hidden representations within pre-edited LLMs. (2) Subsequently, we performed 2,000 sequential edits on the LLMs and recomputed these hidden representation. (3) Finally, we used t-SNE (Van der Maaten & Hinton 2008) to visualize the hidden representation before and after editing. Figure 5 exhibits them and their marginal distribution curves. Furthermore, we quantify the deviation of scatter point distributions and the differences of marginal distribution curves in Figure 5, and the results are provided in Appendix C.3. According to Figure 5 we can find that:
如前所述,当前编辑方法常使编辑后 LLM 过拟合更新知识,导致隐表示分布偏移。因此,这里实证检验 AlphaEdit 能否防止过拟合并避免该分布偏移。步骤如下:(1) 随机选取 1,000 条事实提示,提取编辑前 LLM 的隐表示;(2) 对 LLM 做 2,000 次序列编辑并重新计算这些隐表示;(3) 用 t-SNE(Van der Maaten & Hinton 2008)可视化编辑前后的隐表示。图 5 展示散点及其边缘分布曲线。我们还量化了图 5 中散点分布偏差与边缘分布曲线差异,结果见附录 C.3。根据图 5 可见:
- • Obs 5: AlphaEdit maintains consistency in hidden representations after editing. Specifically, the hidden representations within LLMs edited using AlphaEdit remain consistent with the original distribution across all three base models. This stability indicates that AlphaEdit effectively mitigates overfitting, in turn explaining its superior knowledge preservation and generalization capabilities.
- • Obs 6: There is a significant shift in the distribution of hidden representations within baseline-edited LLMs. In some cases (*e.g.,*RECT-edited LLaMA3), the trend of the distribution before and after editing is even completely reversed. This discrepancy becomes more pronounced as sequential editing progresses, further underscoring the importance of projection-based optimization.
- • 观察 5:AlphaEdit 使编辑后隐表示保持一致。 具体地,经 AlphaEdit 编辑的 LLM,其隐表示在三个基座模型上均与原始分布一致。这一稳定性表明 AlphaEdit 有效缓解过拟合,也解释了其更强的知识保留与泛化能力。
- • 观察 6:基线编辑后的 LLM 隐表示分布出现显著偏移。 某些情形(例如经 RECT 编辑的 LLaMA3)编辑前后分布趋势甚至完全反转。随序列编辑推进,这种差异更明显,进一步凸显基于投影的优化之必要。
4.5 Performance Improvements of Baseline Methods (RQ4)
4.5 基线方法的性能提升(RQ4)
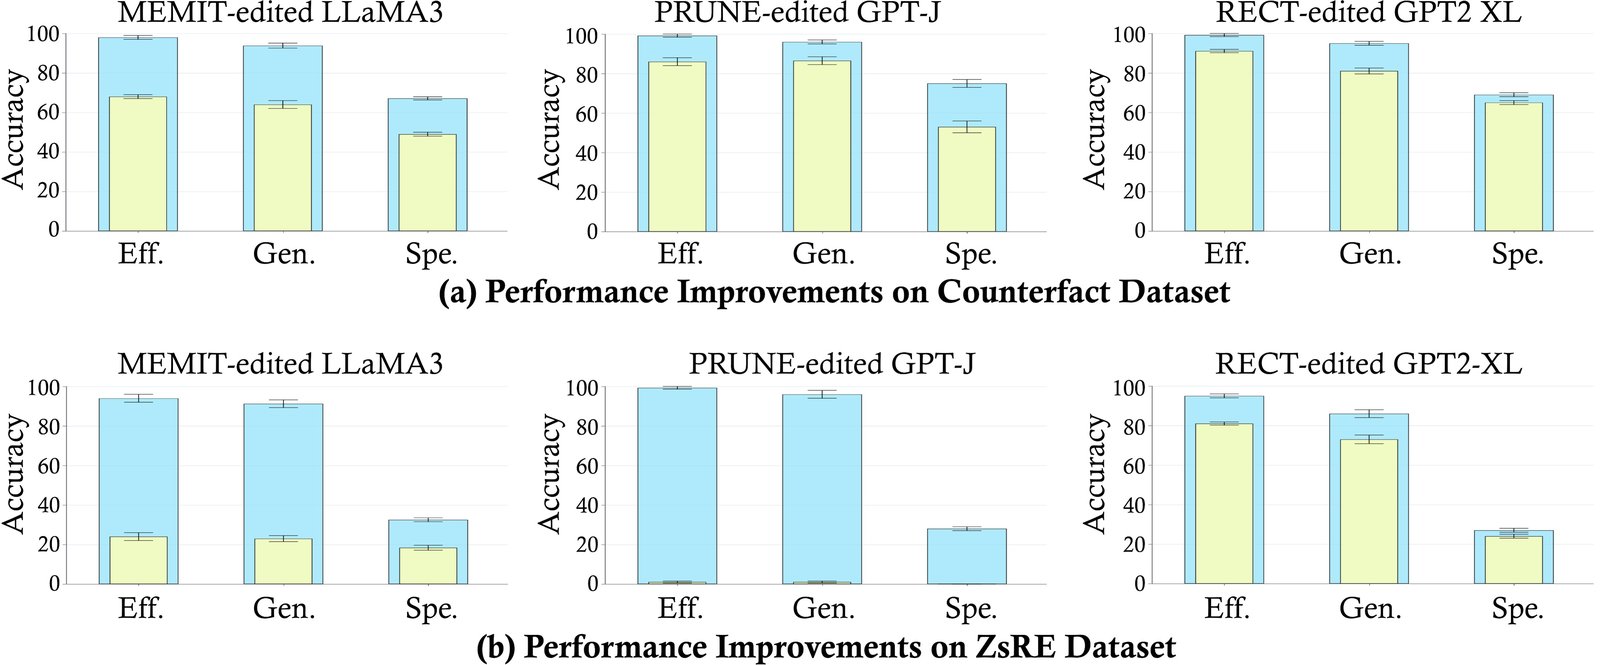
Figure 6: Performance improvements of baseline editing methods (i.e., MEMIT, PRUNE and RECT) after adding a single line of code from AlphaEdit (i.e., the code used for matrix projection). The yellow bars represent the original performance of each baseline, while the blue bars represent the performance after the addition. Best viewed in color.
图 6:基线编辑方法(即 MEMIT、PRUNE 与 RECT)在加入 AlphaEdit 的一行投影代码后的性能提升。黄条为各基线原始表现,蓝条为加入后表现。建议彩色阅读。
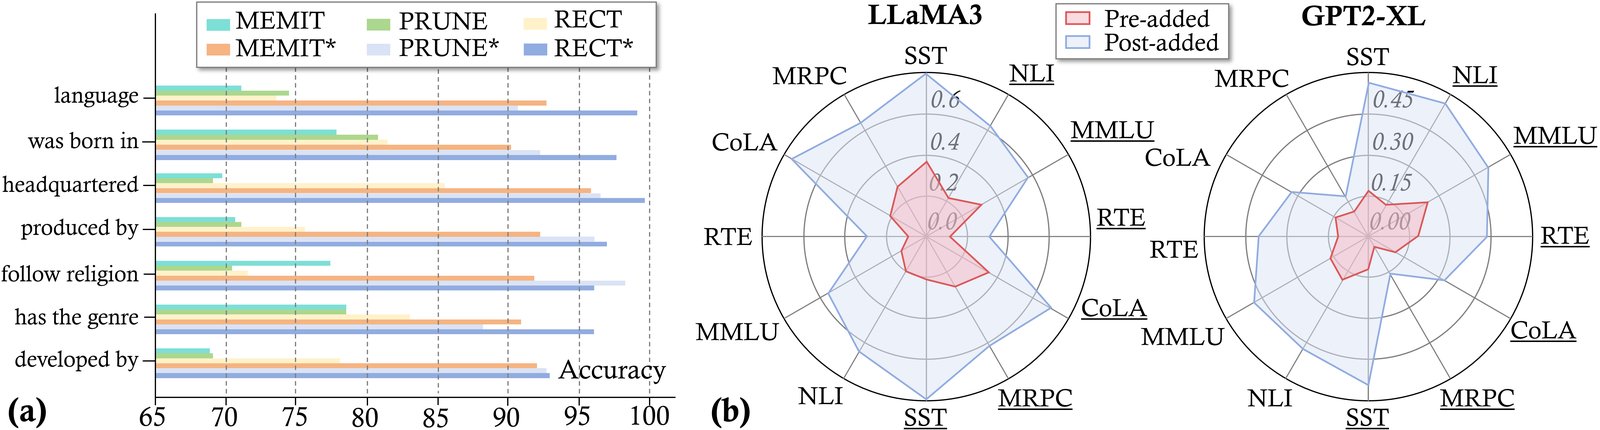
Figure 7: Performance comparison before and after adding the projection code in AlphaEdit to the baselines. (a) Performance of editing methods on samples involving specific semantics, where asterisk denotes the versions added the projection; the vertical and horizontal axis represent the categories of knowledge and the accuracy of LLM responses involving this knowledge, respectively. (b) Comparison of general capabilities for PRUNE and RECT before and after adding the projection, where the underlined method represents the results of RECT. Best viewed in color.
图 7:向基线加入 AlphaEdit 投影代码前后的性能对比。(a) 在涉及特定语义的样本上的编辑表现,星号表示加入投影后的版本;纵轴与横轴分别表示知识类别与涉及该类知识的 LLM 回答准确率。(b) PRUNE 与 RECT 加入投影前后的通用能力对比,下划线方法表示 RECT 的结果。建议彩色阅读。
We conclude by evaluating whether integrating AlphaEdit’s projection strategy can comprehensively enhance current editing methods. To achieve this, we add one line of code from AlphaEdit (the code for projection) to baselines and measure their performance before and after the addition. Following previous works (Meng et al. 2023), we analyze (1) the average performance across all editing samples, (2) the performance on editing samples involving specific semantics and (3) the general capability of post-edited LLMs. Results are shown in Figure 6, 7 (a), and 7 (b), respectively. Note that in Figure 7 (a), the y-axis represents the knowledge belonging to different semantic categories. For instance, the labeled “language” indicates the knowledge instances related to language. Detailed experimental settings can be found in Appendix C.4. The results show that:
最后评估:接入 AlphaEdit 的投影策略能否全面增强现有编辑方法。我们向各基线加入 AlphaEdit 的一行投影代码,并度量加入前后的表现。遵循既有工作(Meng et al. 2023),分析 (1) 全部编辑样本上的平均表现、(2) 涉及特定语义的编辑样本上的表现,以及 (3) 编辑后 LLM 的通用能力。结果分别见图 6、图 7 (a) 与图 7 (b)。注意图 7 (a) 的纵轴表示不同语义类别的知识;例如标注「language」表示与语言相关的知识实例。详细实验设定见附录 C.4。结果表明:
- • Obs 7: AlphaEdit seamlessly integrates with other model editing methods, significantly boosting their overall performance. The optimized baselines show an average improvement of on editing capability and on general capability, underscoring the substantial potential and broad applicability of the null-space projection in enhancing model editing methods.
- • 观察 7:AlphaEdit 可无缝接入其他模型编辑方法,显著提升其整体表现。 优化后的基线在编辑能力上平均提升 ,在通用能力上平均提升 ,凸显零空间投影在增强模型编辑方法上的巨大潜力与广泛适用性。
5 Related Work
5 相关工作
Parameter-modifying Model Editing. This approach typically employs meta-learning or locating-then-editing strategies (Zhang et al. 2024d) to conduct editing. Meta-learning, as implemented by KE (Cao et al. 2021) and MEND (Mitchell et al. 2022a), involves adapting model parameters through a hypernetwork. InstructEdit (Zhang et al. 2024b) extends MEND by designing instructions for training on different tasks. Locate-then-edit strategies, exemplified by ROME (Meng et al. 2022) and MEMIT (Meng et al. 2023), prioritize pinpointing the knowledge’s storage location before making targeted edits. GLAME (Zhang et al. 2024a) enhances ROME by leveraging knowledge graphs to facilitate the editing of related knowledge. Recent work has introduced AnyEdit (Jiang et al. 2025), a recursive approach designed to modify knowledge of arbitrary length and format stored within LLMs.
改参类模型编辑。 该类方法通常采用元学习或「先定位再编辑」策略(Zhang et al. 2024d)。元学习方面,KE(Cao et al. 2021)与 MEND(Mitchell et al. 2022a)通过超网络适配模型参数;InstructEdit(Zhang et al. 2024b)在 MEND 基础上为不同任务设计指令以训练。定位-编辑策略以 ROME(Meng et al. 2022)与 MEMIT(Meng et al. 2023)为代表,先定位知识存储位置再做针对性编辑;GLAME(Zhang et al. 2024a)借助知识图谱增强 ROME,便于编辑相关知识。近期工作提出 AnyEdit(Jiang et al. 2025),用递归方式修改 LLM 中任意长度与格式的知识。
Parameter-preserving Model Editing. This line utilizes additional modules to store to-be-updated knowledge. These modules may include codebooks, neurons, or auxiliary models, as seen in methods like SERAC (Mitchell et al. 2022b), T-Patcher (Huang et al. 2023), GRACE (Hartvigsen et al. 2023), and MELO (Yu et al. 2024). Additionally, MemPrompt (Madaan et al. 2022) and IKE (Zheng et al. 2023) achieve editing by incorporating to-be-updated knowledge into input prompts. More recently, WISE (Wang et al. 2025) innovates prior module designs by introducing dual memory and conflict-free knowledge sharding, overcoming trade-off between reliability and generalization.
保参类模型编辑。 该类方法用额外模块存储待更新知识。模块可以是码本、神经元或辅助模型,如 SERAC(Mitchell et al. 2022b)、T-Patcher(Huang et al. 2023)、GRACE(Hartvigsen et al. 2023)与 MELO(Yu et al. 2024)。此外,MemPrompt(Madaan et al. 2022)与 IKE(Zheng et al. 2023)通过把待更新知识写入输入提示实现编辑。更近的 WISE(Wang et al. 2025)引入双记忆与无冲突知识分片,改进先前模块设计,缓解可靠性与泛化之间的权衡。
Evaluating Knowledge Editing. Recent work has introduced diverse benchmarks to assess the efficacy of model editing. For instance, KnowEdit (Zhang et al. 2024d) provides a unified datasets by collecting different types of knowledge tailored for knowledge insertion, modification, and erasure tasks; LEME (Rosati et al. 2024), CKnowEdit (Fang et al. 2025), and MQuAKE (Zhong et al. 2023) shift attention to long-form, multi-lingual, and multi-hop knowledge, respectively. These benchmarks collectively push for more comprehensive evaluations.
知识编辑评测。 近期工作提出多种基准以评估模型编辑效果。例如 KnowEdit(Zhang et al. 2024d)汇集不同类型知识,统一覆盖插入、修改与擦除任务;LEME(Rosati et al. 2024)、CKnowEdit(Fang et al. 2025)与 MQuAKE(Zhong et al. 2023)分别转向长文、多语与多跳知识。这些基准共同推动更全面的评估。
6 Limitations & Future Discussion
6 局限与展望
While AlphaEdit demonstrates the capability to edit knowledge with minimal performance degradation, we also recognize its limitations. Concretely, its applicability to multi-modal LLMs (OpenAI et al. 2024) and large reasoning models (Liu et al. 2024) remains unexplored. Hence, future research could focus on extending AlphaEdit to a broader range of base LLMs. Furthermore, the superior performance of null-space projection in balancing knowledge updates and preservation suggests its potential for broader applications. Especially, it could enhance specific LLM capabilities — such as safety, mathematics, or biochemistry — without degrading other abilities. These avenues present exciting opportunities to improve both the applicability and scalability of our method.
尽管 AlphaEdit 能在尽量少损伤性能的前提下编辑知识,我们也认识到其局限。具体地,它在多模态 LLM(OpenAI et al. 2024)与大型推理模型(Liu et al. 2024)上的适用性尚未探索。因此,未来可将 AlphaEdit 扩展到更广范围的基座 LLM。此外,零空间投影 在平衡知识更新与保留上的优异表现,暗示其有更广应用潜力。尤其是,它或许能在不削弱其他能力的前提下增强 LLM 的特定能力——如安全、数学或生物化学。 这些方向为提升方法适用性与可扩展性提供了令人兴奋的机会。
7 Conclusion
7 结论
In this work, we introduced AlphaEdit, a novel model editing method to address a critical challenge in current approaches — the trade-off between knowledge update and preservation — with only a single line of code. Specifically, AlphaEdit minimizes disruption to the preserved knowledge by projecting parameter perturbations onto the null space of its key matrices, allowing the model to focus solely on knowledge update. Extensive experiments on multiple base LLMs, including LLaMA3, GPT-2 XL, and GPT-J, demonstrate that AlphaEdit significantly enhances the performance of existing model editing methods, delivering an average improvement of in editing capabilities.
本文提出 AlphaEdit:一种新型模型编辑方法,仅用一行代码应对当前方法的关键挑战——知识更新与保留之间的权衡。具体地,AlphaEdit 将参数扰动投影到保留知识键矩阵的零空间上,以最小化对保留知识的破坏,使模型可专注于知识更新。在 LLaMA3、GPT-2 XL、GPT-J 等多个基座 LLM 上的大量实验表明,AlphaEdit 显著增强现有模型编辑方法,编辑能力平均提升 。
Ethics Statement
伦理声明
Our AlphaEdit method significantly enhances the performance of sequential model editing, making it invaluable for updating and managing knowledge in real-world applications. While the ability to directly modify stored knowledge introduces potential risks, such as the introduction of false or harmful information, we strongly urge researchers to implement strict validation and oversight to ensure the ethical use of these techniques. Nevertheless, the original goal of model editing is positive, aiming to facilitate efficient updates of large models in the future. Therefore, we encourage researchers to leverage this technology responsibly and with care.
我们的 AlphaEdit 方法显著提升序列模型编辑表现,对现实应用中的知识更新与管理很有价值。直接修改存储知识的能力也带来潜在风险,例如引入虚假或有害信息;我们强烈呼吁研究者实施严格验证与监督,确保这些技术被合乎伦理地使用。不过,模型编辑的初衷是正面的:便于未来高效更新大模型。因此,我们鼓励研究者负责任、审慎地使用该技术。
Reproducibility
可复现性
To ensure the reproducibility of our findings, detailed implementation instructions for AlphaEdit can be found in Appendix A. Additionally, the source code is publicly available at the following URL: https://github.com/jianghoucheng/AlphaEdit. These measures are intended to facilitate the verification and replication of our results by other researchers in the field.
为保证发现可复现,AlphaEdit 的详细实现说明见附录 A。源代码公开于:https://github.com/jianghoucheng/AlphaEdit。这些措施旨在方便领域内其他研究者核验与复现我们的结果。
Acknowledgement
致谢
This research is supported by the National Science and Technology Major Project (2023ZD0121102), the National Natural Science Foundation of China (92270114), and the National Natural Science Foundation of China (U24B20180). We also thank the EasyEdit platform for their support (https://github.com/zjunlp/EasyEdit).
本研究得到国家科技重大专项(2023ZD0121102)、国家自然科学基金(92270114)与国家自然科学基金(U24B20180)支持。亦感谢 EasyEdit 平台的支持(https://github.com/zjunlp/EasyEdit)。
References
参考文献
Bentivogli et al. (2009) Luisa Bentivogli, Bernardo Magnini, Ido Dagan, Hoa Trang Dang, and Danilo Giampiccolo. The fifth PASCAL recognizing textual entailment challenge. In TAC . NIST, 2009.
Brown et al. (2020) Tom B. Brown, Benjamin Mann, Nick Ryder, Melanie Subbiah, Jared Kaplan, Prafulla Dhariwal, Arvind Neelakantan, Pranav Shyam, Girish Sastry, Amanda Askell, Sandhini Agarwal, Ariel Herbert-Voss, Gretchen Krueger, Tom Henighan, Rewon Child, Aditya Ramesh, Daniel M. Ziegler, Jeffrey Wu, Clemens Winter, Christopher Hesse, Mark Chen, Eric Sigler, Mateusz Litwin, Scott Gray, Benjamin Chess, Jack Clark, Christopher Berner, Sam McCandlish, Alec Radford, Ilya Sutskever, and Dario Amodei. Language models are few-shot learners. In NeurIPS , 2020.
Cao et al. (2021) Nicola De Cao, Wilker Aziz, and Ivan Titov. Editing factual knowledge in language models. In EMNLP (1) , pp. 6491–6506. Association for Computational Linguistics, 2021.
Dolan & Brockett (2005) William B. Dolan and Chris Brockett. Automatically constructing a corpus of sentential paraphrases. In IWP@IJCNLP . Asian Federation of Natural Language Processing, 2005.
Fang et al. (2025) Jizhan Fang, Tianhe Lu, Yunzhi Yao, Ziyan Jiang, Xin Xu, Ningyu Zhang, and Huajun Chen. Cknowedit: A new chinese knowledge editing dataset for linguistics, facts, and logic error correction in llms, 2025. URL https://arxiv.org/abs/2409.05806 .
Geva et al. (2021) Mor Geva, Roei Schuster, Jonathan Berant, and Omer Levy. Transformer feed-forward layers are key-value memories. In EMNLP (1) , pp. 5484–5495. Association for Computational Linguistics, 2021.
Gu et al. (2024) Jia-Chen Gu, Hao-Xiang Xu, Jun-Yu Ma, Pan Lu, Zhen-Hua Ling, Kai-Wei Chang, and Nanyun Peng. Model editing harms general abilities of large language models: Regularization to the rescue, 2024. URL https://arxiv.org/abs/2401.04700 .
Gupta & Anumanchipalli (2024) Akshat Gupta and Gopala Anumanchipalli. Rebuilding ROME : Resolving model collapse during sequential model editing. CoRR , abs/2403.07175, 2024.
Gupta et al. (2024) Akshat Gupta, Anurag Rao, and Gopala Anumanchipalli. Model editing at scale leads to gradual and catastrophic forgetting. CoRR , abs/2401.07453, 2024.
Hartvigsen et al. (2023) Tom Hartvigsen, Swami Sankaranarayanan, Hamid Palangi, Yoon Kim, and Marzyeh Ghassemi. Aging with GRACE: lifelong model editing with discrete key-value adaptors. In NeurIPS , 2023.
Hase et al. (2023) Peter Hase, Mohit Bansal, Been Kim, and Asma Ghandeharioun. Does localization inform editing? surprising differences in causality-based localization vs. knowledge editing in language models. Advances in Neural Information Processing Systems , 36:17643–17668, 2023.
Hendrycks et al. (2021) Dan Hendrycks, Collin Burns, Steven Basart, Andy Zou, Mantas Mazeika, Dawn Song, and Jacob Steinhardt. Measuring massive multitask language understanding. In ICLR . OpenReview.net, 2021.
Hu et al. (2024) Chenhui Hu, Pengfei Cao, Yubo Chen, Kang Liu, and Jun Zhao. Wilke: Wise-layer knowledge editor for lifelong knowledge editing. CoRR , abs/2402.10987, 2024.
Huang et al. (2023) Zeyu Huang, Yikang Shen, Xiaofeng Zhang, Jie Zhou, Wenge Rong, and Zhang Xiong. Transformer-patcher: One mistake worth one neuron. In ICLR . OpenReview.net, 2023.
Jiang et al. (2024) Houcheng Jiang, Junfeng Fang, Tianyu Zhang, An Zhang, Ruipeng Wang, Tao Liang, and Xiang Wang. Neuron-level sequential editing for large language models. arXiv preprint arXiv:2410.04045 , 2024.
Jiang et al. (2025) Houcheng Jiang, Junfeng Fang, Ningyu Zhang, Guojun Ma, Mingyang Wan, Xiang Wang, Xiangnan He, and Tat-seng Chua. Anyedit: Edit any knowledge encoded in language models. arXiv preprint arXiv:2502.05628 , 2025.
Lang (2012) Serge Lang. Introduction to linear algebra . Springer Science & Business Media, 2012.
Levy et al. (2017) Omer Levy, Minjoon Seo, Eunsol Choi, and Luke Zettlemoyer. Zero-shot relation extraction via reading comprehension. In CoNLL , pp. 333–342. Association for Computational Linguistics, 2017.
Li et al. (2024a) Shuaiyi Li, Yang Deng, Deng Cai, Hongyuan Lu, Liang Chen, and Wai Lam. Consecutive model editing with batch alongside hook layers. CoRR , abs/2403.05330, 2024a.
Li et al. (2024b) Xiaopeng Li, Shasha Li, Shezheng Song, Jing Yang, Jun Ma, and Jie Yu. PMET: precise model editing in a transformer. In AAAI , pp. 18564–18572. AAAI Press, 2024b.
Li et al. (2023) Yuanzhi Li, Sébastien Bubeck, Ronen Eldan, Allie Del Giorno, Suriya Gunasekar, and Yin Tat Lee. Textbooks are all you need II: phi-1.5 technical report. CoRR , abs/2309.05463, 2023.
Li et al. (2025) Zherui Li, Houcheng Jiang, Hao Chen, Baolong Bi, Zhenhong Zhou, Fei Sun, Junfeng Fang, and Xiang Wang. Reinforced lifelong editing for language models. arXiv preprint arXiv:2502.05759 , 2025.
Liu et al. (2024) Aixin Liu, Bei Feng, Bing Xue, Bingxuan Wang, Bochao Wu, Chengda Lu, Chenggang Zhao, Chengqi Deng, Chenyu Zhang, Chong Ruan, et al. Deepseek-v3 technical report. arXiv preprint arXiv:2412.19437 , 2024.
Ma et al. (2024) Jun-Yu Ma, Hong Wang, Hao-Xiang Xu, Zhen-Hua Ling, and Jia-Chen Gu. Perturbation-restrained sequential model editing. CoRR , abs/2405.16821, 2024.
Madaan et al. (2022) Aman Madaan, Niket Tandon, Peter Clark, and Yiming Yang. Memory-assisted prompt editing to improve GPT-3 after deployment. CoRR , abs/2201.06009, 2022.
Meng et al. (2022) Kevin Meng, David Bau, Alex Andonian, and Yonatan Belinkov. Locating and editing factual associations in GPT. In NeurIPS , 2022.
Meng et al. (2023) Kevin Meng, Arnab Sen Sharma, Alex J. Andonian, Yonatan Belinkov, and David Bau. Mass-editing memory in a transformer. In ICLR . OpenReview.net, 2023.
Mesnard et al. (2024) Thomas Mesnard, Cassidy Hardin, Robert Dadashi, Surya Bhupatiraju, Shreya Pathak, Laurent Sifre, Morgane Rivière, Mihir Sanjay Kale, Juliette Love, Pouya Tafti, Léonard Hussenot, Aakanksha Chowdhery, Adam Roberts, Aditya Barua, Alex Botev, Alex Castro-Ros, Ambrose Slone, Amélie Héliou, Andrea Tacchetti, Anna Bulanova, Antonia Paterson, Beth Tsai, Bobak Shahriari, Charline Le Lan, Christopher A. Choquette-Choo, Clément Crepy, Daniel Cer, Daphne Ippolito, David Reid, Elena Buchatskaya, Eric Ni, Eric Noland, Geng Yan, George Tucker, George-Cristian Muraru, Grigory Rozhdestvenskiy, Henryk Michalewski, Ian Tenney, Ivan Grishchenko, Jacob Austin, James Keeling, Jane Labanowski, Jean-Baptiste Lespiau, Jeff Stanway, Jenny Brennan, Jeremy Chen, Johan Ferret, Justin Chiu, and et al. Gemma: Open models based on gemini research and technology. CoRR , abs/2403.08295, 2024.
Meta (2024) Meta. Llama 3, 2024. URL https://llama.meta.com/llama3/ . Large language model release.
Mitchell et al. (2022a) Eric Mitchell, Charles Lin, Antoine Bosselut, Chelsea Finn, and Christopher D. Manning. Fast model editing at scale. In ICLR . OpenReview.net, 2022a.
Mitchell et al. (2022b) Eric Mitchell, Charles Lin, Antoine Bosselut, Christopher D. Manning, and Chelsea Finn. Memory-based model editing at scale. In ICML , volume 162 of Proceedings of Machine Learning Research , pp. 15817–15831. PMLR, 2022b.
OpenAI et al. (2024) OpenAI, Josh Achiam, Steven Adler, Sandhini Agarwal, Lama Ahmad, Ilge Akkaya, Florencia Leoni Aleman, Diogo Almeida, Janko Altenschmidt, Sam Altman, Shyamal Anadkat, Red Avila, Igor Babuschkin, Suchir Balaji, Valerie Balcom, Paul Baltescu, Haiming Bao, Mohammad Bavarian, Jeff Belgum, Irwan Bello, Jake Berdine, Gabriel Bernadett-Shapiro, Christopher Berner, Lenny Bogdonoff, Oleg Boiko, Madelaine Boyd, Anna-Luisa Brakman, Greg Brockman, Tim Brooks, Miles Brundage, Kevin Button, Trevor Cai, Rosie Campbell, Andrew Cann, Brittany Carey, Chelsea Carlson, Rory Carmichael, Brooke Chan, Che Chang, Fotis Chantzis, Derek Chen, Sully Chen, Ruby Chen, Jason Chen, Mark Chen, Ben Chess, Chester Cho, Casey Chu, Hyung Won Chung, Dave Cummings, Jeremiah Currier, Yunxing Dai, Cory Decareaux, Thomas Degry, Noah Deutsch, Damien Deville, Arka Dhar, David Dohan, Steve Dowling, Sheila Dunning, Adrien Ecoffet, Atty Eleti, Tyna Eloundou, David Farhi, Liam Fedus, Niko Felix, Simón Posada Fishman, Juston Forte, Isabella Fulford, Leo Gao, Elie Georges, Christian Gibson, Vik Goel, Tarun Gogineni, Gabriel Goh, Rapha Gontijo-Lopes, Jonathan Gordon, Morgan Grafstein, Scott Gray, Ryan Greene, Joshua Gross, Shixiang Shane Gu, Yufei Guo, Chris Hallacy, Jesse Han, Jeff Harris, Yuchen He, Mike Heaton, Johannes Heidecke, Chris Hesse, Alan Hickey, Wade Hickey, Peter Hoeschele, Brandon Houghton, Kenny Hsu, Shengli Hu, Xin Hu, Joost Huizinga, Shantanu Jain, Shawn Jain, Joanne Jang, Angela Jiang, Roger Jiang, Haozhun Jin, Denny Jin, Shino Jomoto, Billie Jonn, Heewoo Jun, Tomer Kaftan, Łukasz Kaiser, Ali Kamali, Ingmar Kanitscheider, Nitish Shirish Keskar, Tabarak Khan, Logan Kilpatrick, Jong Wook Kim, Christina Kim, Yongjik Kim, Jan Hendrik Kirchner, Jamie Kiros, Matt Knight, Daniel Kokotajlo, Łukasz Kondraciuk, Andrew Kondrich, Aris Konstantinidis, Kyle Kosic, Gretchen Krueger, Vishal Kuo, Michael Lampe, Ikai Lan, Teddy Lee, Jan Leike, Jade Leung, Daniel Levy, Chak Ming Li, Rachel Lim, Molly Lin, Stephanie Lin, Mateusz Litwin, Theresa Lopez, Ryan Lowe, Patricia Lue, Anna Makanju, Kim Malfacini, Sam Manning, Todor Markov, Yaniv Markovski, Bianca Martin, Katie Mayer, Andrew Mayne, Bob McGrew, Scott Mayer McKinney, Christine McLeavey, Paul McMillan, Jake McNeil, David Medina, Aalok Mehta, Jacob Menick, Luke Metz, Andrey Mishchenko, Pamela Mishkin, Vinnie Monaco, Evan Morikawa, Daniel Mossing, Tong Mu, Mira Murati, Oleg Murk, David Mély, Ashvin Nair, Reiichiro Nakano, Rajeev Nayak, Arvind Neelakantan, Richard Ngo, Hyeonwoo Noh, Long Ouyang, Cullen O’Keefe, Jakub Pachocki, Alex Paino, Joe Palermo, Ashley Pantuliano, Giambattista Parascandolo, Joel Parish, Emy Parparita, Alex Passos, Mikhail Pavlov, Andrew Peng, Adam Perelman, Filipe de Avila Belbute Peres, Michael Petrov, Henrique Ponde de Oliveira Pinto, Michael, Pokorny, Michelle Pokrass, Vitchyr H. Pong, Tolly Powell, Alethea Power, Boris Power, Elizabeth Proehl, Raul Puri, Alec Radford, Jack Rae, Aditya Ramesh, Cameron Raymond, Francis Real, Kendra Rimbach, Carl Ross, Bob Rotsted, Henri Roussez, Nick Ryder, Mario Saltarelli, Ted Sanders, Shibani Santurkar, Girish Sastry, Heather Schmidt, David Schnurr, John Schulman, Daniel Selsam, Kyla Sheppard, Toki Sherbakov, Jessica Shieh, Sarah Shoker, Pranav Shyam, Szymon Sidor, Eric Sigler, Maddie Simens, Jordan Sitkin, Katarina Slama, Ian Sohl, Benjamin Sokolowsky, Yang Song, Natalie Staudacher, Felipe Petroski Such, Natalie Summers, Ilya Sutskever, Jie Tang, Nikolas Tezak, Madeleine B. Thompson, Phil Tillet, Amin Tootoonchian, Elizabeth Tseng, Preston Tuggle, Nick Turley, Jerry Tworek, Juan Felipe Cerón Uribe, Andrea Vallone, Arun Vijayvergiya, Chelsea Voss, Carroll Wainwright, Justin Jay Wang, Alvin Wang, Ben Wang, Jonathan Ward, Jason Wei, CJ Weinmann, Akila Welihinda, Peter Welinder, Jiayi Weng, Lilian Weng, Matt Wiethoff, Dave Willner, Clemens Winter, Samuel Wolrich, Hannah Wong, Lauren Workman, Sherwin Wu, Jeff Wu, Michael Wu, Kai Xiao, Tao Xu, Sarah Yoo, Kevin Yu, Qiming Yuan, Wojciech Zaremba, Rowan Zellers, Chong Zhang, Marvin Zhang, Shengjia Zhao, Tianhao Zheng, Juntang Zhuang, William Zhuk, and Barret Zoph. Gpt-4 technical report, 2024. URL https://arxiv.org/abs/2303.08774 .
Petroni et al. (2019) Fabio Petroni, Tim Rocktäschel, Sebastian Riedel, Patrick S. H. Lewis, Anton Bakhtin, Yuxiang Wu, and Alexander H. Miller. Language models as knowledge bases? In EMNLP/IJCNLP (1) , pp. 2463–2473. Association for Computational Linguistics, 2019.
Radford et al. (2019) Alec Radford, Jeffrey Wu, Rewon Child, David Luan, Dario Amodei, Ilya Sutskever, et al. Language models are unsupervised multitask learners. OpenAI blog , 1(8):9, 2019.
Roberts et al. (2020) Adam Roberts, Colin Raffel, and Noam Shazeer. How much knowledge can you pack into the parameters of a language model? In EMNLP (1) , pp. 5418–5426. Association for Computational Linguistics, 2020.
Rosati et al. (2024) Domenic Rosati, Robie Gonzales, Jinkun Chen, Xuemin Yu, Yahya Kayani, Frank Rudzicz, and Hassan Sajjad. Long-form evaluation of model editing. In NAACL-HLT , pp. 3749–3780. Association for Computational Linguistics, 2024.
Socher et al. (2013) Richard Socher, Alex Perelygin, Jean Wu, Jason Chuang, Christopher D. Manning, Andrew Y. Ng, and Christopher Potts. Recursive deep models for semantic compositionality over a sentiment treebank. In EMNLP , pp. 1631–1642. ACL, 2013.
Van der Maaten & Hinton (2008) Laurens Van der Maaten and Geoffrey Hinton. Visualizing data using t-sne. Journal of machine learning research , 9(11), 2008.
Wang et al. (2019) Alex Wang, Amanpreet Singh, Julian Michael, Felix Hill, Omer Levy, and Samuel R. Bowman. GLUE: A multi-task benchmark and analysis platform for natural language understanding. In ICLR (Poster) . OpenReview.net, 2019.
Wang et al. (2025) Peng Wang, Zexi Li, Ningyu Zhang, Ziwen Xu, Yunzhi Yao, Yong Jiang, Pengjun Xie, Fei Huang, and Huajun Chen. Wise: Rethinking the knowledge memory for lifelong model editing of large language models. Advances in Neural Information Processing Systems , 37:53764–53797, 2025.
Wang et al. (2021) Shipeng Wang, Xiaorong Li, Jian Sun, and Zongben Xu. Training networks in null space of feature covariance for continual learning. In CVPR , pp. 184–193. Computer Vision Foundation / IEEE, 2021.
Wang et al. (2024) Song Wang, Yaochen Zhu, Haochen Liu, Zaiyi Zheng, Chen Chen, and Jundong Li. Knowledge editing for large language models: A survey. ACM Computing Surveys , 57(3):1–37, 2024.
Warstadt et al. (2019) Alex Warstadt, Amanpreet Singh, and Samuel R. Bowman. Neural network acceptability judgments. Trans. Assoc. Comput. Linguistics , 7:625–641, 2019.
Williams et al. (2018) Adina Williams, Nikita Nangia, and Samuel R. Bowman. A broad-coverage challenge corpus for sentence understanding through inference. In NAACL-HLT , pp. 1112–1122. Association for Computational Linguistics, 2018.
Wolf et al. (2019) Thomas Wolf, Lysandre Debut, Victor Sanh, Julien Chaumond, Clement Delangue, Anthony Moi, Pierric Cistac, Tim Rault, Rémi Louf, Morgan Funtowicz, and Jamie Brew. Huggingface’s transformers: State-of-the-art natural language processing. CoRR , abs/1910.03771, 2019.
Yang et al. (2024a) Wanli Yang, Fei Sun, Xinyu Ma, Xun Liu, Dawei Yin, and Xueqi Cheng. The butterfly effect of model editing: Few edits can trigger large language models collapse. In ACL (Findings) , pp. 5419–5437. Association for Computational Linguistics, 2024a.
Yang et al. (2024b) Wanli Yang, Fei Sun, Jiajun Tan, Xinyu Ma, Du Su, Dawei Yin, and Huawei Shen. The fall of ROME: understanding the collapse of llms in model editing. In EMNLP (Findings) , pp. 4079–4087. Association for Computational Linguistics, 2024b.
Yao et al. (2023) Yunzhi Yao, Peng Wang, Bozhong Tian, Siyuan Cheng, Zhoubo Li, Shumin Deng, Huajun Chen, and Ningyu Zhang. Editing large language models: Problems, methods, and opportunities. In EMNLP , pp. 10222–10240. Association for Computational Linguistics, 2023.
Yu et al. (2024) Lang Yu, Qin Chen, Jie Zhou, and Liang He. MELO: enhancing model editing with neuron-indexed dynamic lora. In AAAI , pp. 19449–19457. AAAI Press, 2024.
Zhang et al. (2024a) Mengqi Zhang, Xiaotian Ye, Qiang Liu, Pengjie Ren, Shu Wu, and Zhumin Chen. Knowledge graph enhanced large language model editing. CoRR , abs/2402.13593, 2024a.
Zhang et al. (2024b) Ningyu Zhang, Bozhong Tian, Siyuan Cheng, Xiaozhuan Liang, Yi Hu, Kouying Xue, Yanjie Gou, Xi Chen, and Huajun Chen. Instructedit: Instruction-based knowledge editing for large language models. In IJCAI , pp. 6633–6641. ijcai.org, 2024b.
Zhang et al. (2024c) Ningyu Zhang, Zekun Xi, Yujie Luo, Peng Wang, Bozhong Tian, Yunzhi Yao, Jintian Zhang, Shumin Deng, Mengshu Sun, Lei Liang, et al. Oneedit: A neural-symbolic collaboratively knowledge editing system. arXiv preprint arXiv:2409.07497 , 2024c.
Zhang et al. (2024d) Ningyu Zhang, Yunzhi Yao, Bozhong Tian, Peng Wang, Shumin Deng, Mengru Wang, Zekun Xi, Shengyu Mao, Jintian Zhang, Yuansheng Ni, Siyuan Cheng, Ziwen Xu, Xin Xu, Jia-Chen Gu, Yong Jiang, Pengjun Xie, Fei Huang, Lei Liang, Zhiqiang Zhang, Xiaowei Zhu, Jun Zhou, and Huajun Chen. A comprehensive study of knowledge editing for large language models. CoRR , abs/2401.01286, 2024d.
Zheng et al. (2023) Ce Zheng, Lei Li, Qingxiu Dong, Yuxuan Fan, Zhiyong Wu, Jingjing Xu, and Baobao Chang. Can we edit factual knowledge by in-context learning? CoRR , abs/2305.12740, 2023.
Zhong et al. (2023) Zexuan Zhong, Zhengxuan Wu, Christopher D. Manning, Christopher Potts, and Danqi Chen. Mquake: Assessing knowledge editing in language models via multi-hop questions. In EMNLP , pp. 15686–15702. Association for Computational Linguistics, 2023.
Zhu et al. (2020) Chen Zhu, Ankit Singh Rawat, Manzil Zaheer, Srinadh Bhojanapalli, Daliang Li, Felix X. Yu, and Sanjiv Kumar. Modifying memories in transformer models. CoRR , abs/2012.00363, 2020.
Appendix A Experimental Setup
附录 A 实验设置
In this section, we provide a detailed description of the experimental configuration, including a comprehensive explanation of the evaluation metrics, an introduction to the datasets, and a discussion of the baselines.
本节详细描述实验配置,包括评价指标的全面说明、数据集介绍以及基线讨论。
A.1 Datasets
A.1 数据集
Here, we provide a detailed introduction to the datasets used in this paper:
这里详细介绍本文使用的数据集:
- • Counterfact (Meng et al. 2022) is a more challenging dataset that contrasts counterfactual with factual statements, initially scoring lower for Counterfact. It constructs out-of-scope data by replacing the subject entity with approximate entities sharing the same predicate. The Counterfact dataset has similar metrics to ZsRE for evaluating efficacy, generalization, and specificity. Additionally, Counterfact includes multiple generation prompts with the same meaning as the original prompt to test the quality of generated text, specifically focusing on fluency and consistency.
- • ZsRE (Levy et al. 2017) is a question answering (QA) dataset that uses questions generated through back-translation as equivalent neighbors. Following previous work, natural questions are used as out-of-scope data to evaluate locality. Each sample in ZsRE includes a subject string and answers as the editing targets to assess editing success, along with the rephrased question for generalization evaluation and the locality question for evaluating specificity.
- • KnowEdit (Zhang et al. 2024d) introduces a comprehensive benchmark aimed at systematically evaluating knowledge editing methods, categorizing them into approaches that rely on external knowledge, intrinsic knowledge updates, or merging new knowledge into the model. The benchmark not only measures the impact of editing on specific domains but also emphasizes preserving the model’s overall performance across tasks, offering a unified framework for evaluating editing efficiency and impact. In our paper, we employ the wiki_recent and wikibio within KnowEdit to conduct our experiments.
- • LEME (Long-form Evaluation of Model Editing) (Rosati et al. 2024) extends the evaluation paradigm by focusing on long-form generative outputs, revealing unique challenges such as factual drift, internal consistency, and lexical cohesion. This protocol highlights that short-form metrics fail to correlate with long-form generative outcomes, shedding light on previously unexplored dimensions of editing.
- • MQuAKE (Zhong et al. 2023) addresses a critical gap in current evaluations by introducing multi-hop reasoning questions to test the ripple effects of factual updates. Unlike single-fact recall benchmarks, MQUAKE measures the consistency of entailed beliefs after editing, uncovering limitations in existing methods when handling complex relational dependencies.
- • Counterfact(Meng et al. 2022)是更具挑战性的数据集,将反事实陈述与事实陈述对照,Counterfact 初始得分较低。它通过用共享同一谓词的近似实体替换主语实体来构造范围外数据。Counterfact 在评估效力、泛化与特异性上的指标与 ZsRE 类似;此外还包含多个与原提示同义的生成提示,用于测试生成文本质量,尤其关注流畅性与一致性。
- • ZsRE(Levy et al. 2017)是问答(QA)数据集,用回译生成的问题作为等价邻居。遵循既有工作,用自然语言问题作为范围外数据评估局部性。ZsRE 每条样本含主语字符串与作为编辑目标的答案以评估编辑成功,另有改写问题评估泛化、局部性问题评估特异性。
- • KnowEdit(Zhang et al. 2024d)提出系统性评估知识编辑方法的综合基准,将方法分为依赖外部知识、内在知识更新或将新知识并入模型等类别。基准不仅度量编辑对特定领域的影响,也强调跨任务保持整体表现,为评估编辑效率与影响提供统一框架。本文采用 KnowEdit 中的 wiki_recent 与 wikibio 开展实验。
- • LEME(Long-form Evaluation of Model Editing)(Rosati et al. 2024)将评估范式扩展到长文生成输出,揭示事实漂移、内部一致性与词汇衔接等独特挑战。该协议表明短文指标与长文生成结果相关性不足,照亮此前未充分探索的编辑维度。
- • MQuAKE(Zhong et al. 2023)通过引入多跳推理问题检验事实更新的涟漪效应,填补当前评估的关键空白。不同于单事实回忆基准,MQuAKE 度量编辑后蕴含信念的一致性,揭示现有方法在处理复杂关系依赖时的局限。
A.2 Metrics
A.2 评价指标
Now we introduce the evaluation metrics used for ZsRE and Counterfact datasets, respectively.
下面分别介绍 ZsRE 与 Counterfact 所用的评价指标。
A.2.1 ZsRE Metrics
Following the previous work (Mitchell et al. 2022a; Meng et al. 2022; Meng et al. 2023), this section defines each ZsRE metric given a LLM , a knowledge fact prompt , an edited target output , and the model’s original output :
A.2.1 ZsRE 指标
遵循既有工作(Mitchell et al. 2022a;Meng et al. 2022;Meng et al. 2023),给定 LLM 、知识事实提示 、编辑目标输出 以及模型原始输出 ,本节定义各项 ZsRE 指标:
- • Efficacy: Efficacy is calculated as the average top-1 accuracy on the edit samples: (16)
- • Generalization: Generalization measures the model’s performance on equivalent prompt of , such as rephrased statements . This is evaluated by the average top-1 accuracy on these : (17)
- • Specificity: Specificity ensures that the editing does not affect samples unrelated to the edit cases . This is evaluated by the top-1 accuracy of predictions that remain unchanged: (18)
- • Efficacy:在编辑样本上的平均 top-1 准确率: (16)
- • Generalization:度量模型在 的等价提示(如改写陈述 )上的表现,以这些 上的平均 top-1 准确率评估: (17)
- • Specificity:确保编辑不影响与编辑案例无关的样本 ,以预测保持不变的 top-1 准确率评估: (18)
A.2.2 Counterfact Metrics
Following previous work (Meng et al. 2022; Meng et al. 2023), this section defines each Counterfact metric given a LLM , a knowledge fact prompt , an edited target output , and the model’s original output :
A.2.2 Counterfact 指标
遵循既有工作(Meng et al. 2022;Meng et al. 2023),给定 LLM 、知识事实提示 、编辑目标输出 以及模型原始输出 ,本节定义各项 Counterfact 指标:
- • Efficacy (efficacy success): The proportion of cases where is more probable than with the prompt: (19)
- • Generalization (paraphrase success): The proportion of cases where is more probable than in rephrased statements : (20)
- • Specificity (neighborhood success): The proportion of neighborhood prompts , which are prompts about distinct but semantically related subjects, where the model assigns a higher probability to the correct fact: (21)
- • Fluency (generation entropy): Measure for excessive repetition in model outputs. It uses the entropy of n-gram distributions: (22) where is the n-gram frequency distribution.
- • Consistency (reference score): The consistency of the model’s outputs is evaluated by giving the model a subject and computing the cosine similarity between the TF-IDF vectors of the model-generated text and a reference Wikipedia text about .
- • Efficacy(编辑成功):在 提示下 比 更可能的样本比例: (19)
- • Generalization(改写成功):在改写陈述 中 比 更可能的样本比例: (20)
- • Specificity(邻域成功):在关于不同但语义相关主语的邻域提示 上,模型给正确事实更高概率的比例: (21)
- • Fluency(生成熵):度量模型输出中的过度重复,使用 n-gram 分布熵: (22) 其中 为 n-gram 频率分布。
- • Consistency(参考分数):给模型 一个主语 ,计算模型生成文本与关于 的维基百科参考文本的 TF-IDF 向量余弦相似度,以此评估输出一致性。
A.3 Implementation Details
A.3 实现细节
Our implementation of AlphaEdit with GPT-2 XL and GPT-J follows the configurations outlined in MEMIT (Meng et al. 2023). Specifically,
我们对 GPT-2 XL 与 GPT-J 的 AlphaEdit 实现遵循 MEMIT(Meng et al. 2023)所述配置。具体地:
- • For the GPT-2 XL model, we target critical layers for editing, with the hyperparameter set to 20,000. During the computation of hidden representations of the critical layer, we perform 20 optimization steps with a learning rate of 0.5.
- • For the GPT-J model, we target critical layers for editing, with the hyperparameter set to 15,000. During the computation of hidden representations of the critical layer, we perform 25 optimization steps, also with a learning rate of 0.5.
- • For Llama3 (8B) model, we target critical layers for editing. The hyperparameter is set to 15,000. During the process of computing hidden representations of the critical layer, we perform 25 steps with a learning rate of 0.1.
- • 对 GPT-2 XL,编辑目标关键层为 ,超参数 设为 。计算关键层隐表示时做 20 步优化,学习率 0.5。
- • 对 GPT-J,编辑目标关键层为 ,超参数 设为 。计算关键层隐表示时做 25 步优化,学习率同为 0.5。
- • 对 Llama3(8B),编辑目标关键层为 ,超参数 设为 。计算关键层隐表示时做 25 步,学习率 0.1。
All experiments are conducted on a single A40 (48GB) GPU. The LLMs are loaded using HuggingFace Transformers (Wolf et al. 2019).
全部实验在单块 A40(48GB)GPU 上进行。LLM 通过 HuggingFace Transformers(Wolf et al. 2019)加载。
A.4 Baselines
A.4 基线
Here we introduce the five baseline models employed in this study. For the hyperparameter settings of the baseline methods, except the settings mentioned in Appendix A.3, we used the original code provided in the respective papers for reproduction. It is important to note that, since the code for PRUNE is not publicly available, we implemented the method based on the description in the original paper. Specifically, in our implementation, the threshold for retaining eigenvalues in PRUNE was set to .
这里介绍本研究采用的基线模型。除附录 A.3 所述设定外,基线方法的超参数均使用各自论文提供的原始代码复现。 需注意:由于 PRUNE 代码未公开,我们按原文描述自行实现;实现中保留特征值的阈值设为 。
- • MEND is a method for efficiently editing large pre-trained models using a single input-output pair. MEND utilizes small auxiliary networks to make fast, localized changes to the model without full retraining. By applying a low-rank decomposition to the gradient from standard fine-tuning, MEND enables efficient and tractable parameter adjustments. This approach allows for post-hoc edits in large models while avoiding the overfitting common in traditional fine-tuning methods.
- • InstructEdit enables the learning of a well-formed Editor by designing corresponding instructions for training on different tasks. InstructEdit applies meta-learning editing methods based on MEND to train the editor with a variety of meticulously curated instructions, and through this approach, InstructEdit can endow the Editor with the capacity for multi-task editing, thus saving a significant amount of human and computational resources.
- • ROME is a method for updating specific factual associations in LLMs. By identifying key neuron activations in middle-layer feed-forward modules that influence factual predictions, ROME modifies feed-forward weights to edit these associations directly. ROME demonstrates that mid-layer feed-forward modules play a crucial role in storing and recalling factual knowledge, making direct model manipulation a viable editing technique.
- • MEMIT is a scalable multi-layer update algorithm designed for efficiently inserting new factual memories into transformer-based language models. Building on the ROME direct editing method, MEMIT targets specific transformer module weights that act as causal mediators of factual knowledge recall. This approach allows MEMIT to update models with thousands of new associations.
- • PRUNE is a model editing framework designed to preserve the general abilities of LLMs during sequential editing. PRUNE addresses the issue of deteriorating model performance as the number of edits increases by applying condition number restraints to the edited matrix, limiting perturbations to the model’s stored knowledge. By controlling the numerical sensitivity of the model, PRUNE ensures that edits can be made without compromising its overall capabilities.
- • RECT is a method designed to mitigate the unintended side effects of model editing on the general abilities of LLMs. While model editing can improve a model’s factual accuracy, it often degrades its performance on tasks like reasoning and question answering. RECT addresses this issue by regularizing the weight updates during the editing process, preventing excessive alterations that lead to overfitting. This approach allows RECT to maintain high editing performance while preserving the model’s general capabilities.
- • SERAC (Mitchell et al. 2022b) introduces Semi-Parametric Editing with a Retrieval-Augmented Counterfactual Model, addressing limitations of traditional editors in defining edit scope and handling sequential updates. It stores edits in explicit memory and reasons over them to adjust model behavior as needed. SERAC outperforms existing methods on three challenging tasks—question answering, fact-checking, and dialogue generation.
- • MELO (Yu et al. 2024) proposes Neuron-Indexed Dynamic LoRA, a plug-in method that dynamically activates LoRA blocks to edit model behavior efficiently. Adaptable across multiple LLM backbones, it achieves state-of-the-art performance on tasks like document classification, question answering, and hallucination correction, with minimal computational cost and trainable parameters.
- • GRACE (Hartvigsen et al. 2023) introduces a lifelong model editing framework that uses a local codebook in the latent space to handle thousands of sequential edits without degrading model performance. It makes targeted fixes while preserving generalization, demonstrating superior results on T5, BERT, and GPT for retaining and generalizing edits.
- • MEND 是用单个输入-输出对高效编辑大型预训练模型的方法。MEND 利用小型辅助网络对模型做快速、局部化修改,无需完整重训。通过对标准微调梯度做低秩分解,MEND 使参数调整高效且可处理,可在大型模型上做事后编辑,同时避免传统微调常见的过拟合。
- • InstructEdit 通过为不同任务设计相应指令来学习良好成型的编辑器。它在 MEND 基础上用精心设计的多种指令训练编辑器,从而赋予多任务编辑能力,显著节省人力与算力。
- • ROME 用于更新 LLM 中特定事实关联。通过识别影响事实预测的中层前馈模块中的关键神经元激活,ROME 直接修改前馈权重以编辑这些关联,表明中层前馈模块在存储与回忆事实知识中起关键作用,使直接操控模型成为可行编辑技术。
- • MEMIT 是可扩展的多层更新算法,用于向基于 Transformer 的语言模型高效插入新事实记忆。在 ROME 直接编辑方法之上,MEMIT 瞄准充当事实知识回忆因果中介的特定 Transformer 模块权重,从而可一次更新成千上万条新关联。
- • PRUNE 是在序列编辑中保护 LLM 通用能力的模型编辑框架。随着编辑次数增加模型表现恶化;PRUNE 通过对编辑矩阵施加条件数约束、限制对已存知识的扰动来应对。通过控制数值敏感性,PRUNE 保证编辑不牺牲整体能力。
- • RECT 旨在缓解模型编辑对 LLM 通用能力的非预期副作用。编辑可提升事实准确性,却常损害推理与问答等任务表现;RECT 在编辑过程中正则化权重更新,防止导致过拟合的过度改动,从而在保持高编辑表现的同时保留通用能力。
- • SERAC(Mitchell et al. 2022b)提出检索增强反事实模型的半参数编辑,应对传统编辑器在界定编辑范围与处理序列更新上的局限。它把编辑存在显式记忆中,并据此推理以按需调整模型行为,在问答、事实核查与对话生成三项挑战任务上优于既有方法。
- • MELO(Yu et al. 2024)提出神经元索引的动态 LoRA,作为插件动态激活 LoRA 块以高效编辑模型行为。可适配多种 LLM 骨干,在文档分类、问答与幻觉纠正等任务上以极少算力与可训练参数达到先进表现。
- • GRACE(Hartvigsen et al. 2023)提出终身模型编辑框架,在潜空间使用局部码本处理数千次序列编辑而不损害模型表现。它做针对性修复并保留泛化,在 T5、BERT 与 GPT 上对保留与泛化编辑展现更优结果。
Appendix B Implementation Details of Current Model Editing & Related Proofs
附录 B 现有模型编辑实现细节及相关证明
Here, we provide the implementation details of the current model editing methods along with the proof process related to it and the concept of the null space (Wang et al. 2021).
这里给出当前模型编辑方法的实现细节,以及与之相关的证明过程和零空间概念(Wang et al. 2021)。
B.1 Model Editing
B.1 模型编辑
Model editing aims to refine a pre-trained model through one or multiple edits, while each edit replaces with the new knowledge (Yang et al. 2024b; Li et al. 2025). Then, model is expected to recall the updated object given a natural language prompt , such as “The President of the United States is” (Zhang et al. 2024c).
模型编辑旨在通过一次或多次编辑精炼预训练模型,每次编辑将 替换为新知识 (Yang et al. 2024b;Li et al. 2025)。随后,给定自然语言提示 (例如「The President of the United States is」)(Zhang et al. 2024c),模型应回忆更新后的宾语 。
To achieve this, locating-and-editing methods are proposed for effectively model editing (Wang et al. 2024; Yang et al. 2024a). These methods typically adhere to the following steps (Jiang et al. 2024):
为实现这一目标,定位-编辑方法被提出用于有效模型编辑(Wang et al. 2024;Yang et al. 2024a)。这些方法通常遵循以下步骤(Jiang et al. 2024):
Step 1: Locating Influential Layers. The first step is to identify the specific FFN layers to edit using causal tracing (Meng et al. 2022). This method involves injecting Gaussian noise into the hidden states, and then incrementally restoring them to original values. By analyzing the degree to which the original output recovers, the influential layers can be pinpointed as the targets for editing.
步骤 1:定位有影响力的层。 第一步用因果追踪(Meng et al. 2022)识别要编辑的具体 FFN 层。方法是向隐状态注入高斯噪声,再逐步恢复到原始值;通过分析原始输出的恢复程度,可定位有影响力的层作为编辑目标。
Step 2: Acquiring the Excepted Output. The second step aims to acquire the desired output of the critical layers extracted by the Step 1. Concretely, following the aforementioned key-value theory, the key , which encodes , is processed through the output weights to produce the original value encoding . Formally:
步骤 2:获取期望输出。 第二步旨在获取步骤 1 抽出的关键层的期望输出。具体地,按前述键值理论,编码 的键 经输出权重 处理,得到编码 的原始值 。形式化地:
To achieve knowledge editing, is expected to be replaced with a new value encoding . To this end, current methods typically use gradient descent on , maximizing the probability that the model outputs the word associated with (Meng et al. 2023). The optimization objective is as follows:
为实现知识编辑,期望用编码 的新值 替换 。为此,当前方法通常对 做梯度下降,最大化模型输出与 相关词的概率(Meng et al. 2023)。优化目标如下:
where represents the original model with updated to .
其中 表示将 更新为 后的原始模型。
Step 3: Updating . This step aims to update the parameters . It includes a factual set containing new associations, while preserving the set containing original associations. Specifically,
步骤 3:更新 。 本步旨在更新参数 。它包含含 条新关联的事实集合 ,同时保留含 条原始关联的集合 。具体地:
$$\begin{gathered}{\bm{K}}{0}=\left[{\bm{k}}{1}\left|{\bm{k}}{2}\right|\ldots\mid{\bm{k}}{n}\right],\quad{\bm{V}}{0}=\left[{\bm{v}}{1}\left|{\bm{v}}{2}\right|\ldots\mid{\bm{v}}{n}\right],\
{\bm{K}}{1}=\left[{\bm{k}}{n+1}\left|{\bm{k}}{n+2}\right|\ldots\mid{\bm{k}}{n+u}\right],\quad{\bm{V}}{1}=\left[{\bm{v}}^{\ast}{n+1}\left|{\bm{v}}^{\ast}{n+2}\right|\ldots\mid{\bm{v}}^{\ast}{n+u}\right],\end{gathered} \tag{25}$$
where vectors and defined in Eqn. 23 and their subscripts represent the index of the knowledge. Based on these, the objective can be defined as:
其中式 23 定义的向量 、 及其下标表示知识索引。据此,目标可定义为:
By applying the normal equation (Lang 2012), its closed-form solution can be derived:
应用正规方程(Lang 2012),可导出闭式解:
Additionally, current methods often modify parameters across multiple layers to achieve more effective editing. For more details, please refer to Meng et al. 2023.
此外,当前方法常跨多层修改参数以获得更有效的编辑。更多细节见 Meng et al. 2023。
B.2 Proof for the Shared Null Space of and
B.2 与 共享零空间的证明
Theorem: Let be a matrix. Then and share the same left null space.
定理: 设 为 矩阵。则 与 共享同一左零空间。
Proof: Define the left null space of a matrix as the set of all vectors such that . We need to show that if is in the left null space of , then is also in the left null space of , and vice versa.
证明: 将矩阵 的左零空间定义为所有满足 的向量 的集合。需证明:若 属于 的左零空间,则 也属于 的左零空间,反之亦然。
- Inclusion :
- 包含关系 :
- • Suppose is in the left null space of , i.e., .
- • It follows that .
- • Therefore, is in the left null space of .
- • 设 属于 的左零空间,即 。
- • 于是 。
- • 因此 属于 的左零空间。
- Inclusion :
- 包含关系 :
- • Suppose is in the left null space of , i.e., .
- • Expanding this expression gives .
- • Since is non-negative (as any vector multiplied by its transpose results in a non-negative scalar), must be a zero vector for their product to be zero.
- • Hence, is also in the left null space of .
- • 设 属于 的左零空间,即 。
- • 展开得 。
- • 由于 非负(任意向量乘以其转置得非负标量),要使乘积为零, 必须为零向量。
- • 故 也属于 的左零空间。
From these arguments, we establish that both and share the same left null space. That is, belongs to the left null space of if and only if belongs to the left null space of . This equality of left null spaces illustrates the structural symmetry and dependency between and its self-product .
由上述论证, 与 共享同一左零空间。亦即: 属于 的左零空间,当且仅当它属于 的左零空间。左零空间的相等性说明了 与其自乘积 之间的结构对称与依赖。
B.3 Proof for Equation
B.3 方程 的证明
The SVD of provides us the eigenvectors and eigenvalues . Based on this, we can express and as and correspondingly , where all zero eigenvalues are contained in , and consists of the eigenvectors corresponding to .
的 SVD 给出特征向量 与特征值 。据此可将 、 写成 ,相应地 ,其中所有零特征值落在 中, 由对应 的特征向量组成。
Since is an orthogonal matrix, it follows that:
由于 是正交矩阵,有:
This implies that the column space of spans the null space of . Accordingly, the projection matrix onto the null space of can be defined as:
这意味着 的列空间张成 的零空间。据此,到 零空间的投影矩阵可定义为:
Based on the Eqn. 28 and 29, we can derive that:
基于式 28 与 29,可推导:
which confirms that projects onto the null space of .
这确认了 将 投影到 的零空间。
B.4 Derivation of AlphaEdit Perturbation
B.4 AlphaEdit 扰动的推导
Given the orthogonal projection matrix with , it satisfies and . We aim to minimize the objective:
给定正交投影矩阵 ,且 ,它满足 与 。我们旨在最小化目标:
where . Setting the matrix derivative to zero yields:
其中 。令矩阵导数 为零,得到:
Simplifying via Projection Properties: Factorize and utilize , :
借助投影性质化简: 因式分解 ,并利用 、:
Closed-Form Solution: Left-multiplying by the inverse of the bracketed term gives:
闭式解: 左乘括号内项的逆,得到:
where the solution is constrained to the column space of via .
其中解通过 被约束在 的列空间内。
B.5 Invertibility of
B.5 的可逆性
To prove the invertibility of the matrix , note that and are symmetric and positive semidefinite matrices, and is a projection matrix which is also symmetric and positive semidefinite. Since projects onto a subspace, the matrices and are positive semidefinite.
为证明矩阵 可逆,注意 与 为对称半正定矩阵, 为投影矩阵,亦对称半正定。由于 投影到某子空间,矩阵 与 半正定。
Adding the term , where , to these positive semidefinite matrices makes the entire matrix positive definite. This is because the addition of increases each eigenvalue by , ensuring that all eigenvalues are positive, thereby making the matrix invertible. Thus, the matrix () is invertible.
对这些半正定矩阵加上 ()使整个矩阵正定。因为加上 会使每个特征值增加 ,保证全部特征值为正,从而矩阵可逆。因此矩阵 可逆。
Appendix C More Experimental Results
附录 C 更多实验结果
C.1 Case Study
C.1 案例分析
We selected several editing samples from the Counterfact and ZsRE datasets as case studies to analyze the generation after sequential editing. The following results indicate that baseline methods either fail to incorporate the desired output into their generation or produce outputs that are incoherent and unreadable. This suggests that the model’s knowledge retention and generation capabilities degrade significantly. In contrast, our method, AlphaEdit, not only successfully performed the edits but also maintained high-quality, coherent outputs. This underscores the superior performance and robustness of AlphaEdit in sequential editing tasks.
我们从 Counterfact 与 ZsRE 数据集中选取若干编辑样本作案例分析,考察序列编辑后的生成。下列结果表明:基线方法要么未能把期望输出纳入生成,要么产出不连贯、不可读的文本,说明模型的知识保留与生成能力显著退化。相比之下,我们的方法 AlphaEdit 不仅成功完成编辑,还维持了高质量、连贯的输出。这凸显了 AlphaEdit 在序列编辑任务上的更优表现与稳健性。
C.2 General Capability Tests
C.2 通用能力测试
C.1.3 Case 3
Here, we present the results of general capability tests for LLMs edited by various methods when the number of edits per batch is reduced by half. The results are shown in Figure 8. Similar to the conclusions drawn from the general capability tests in the main text, Figure 8 shows that LLMs edited with baseline methods quickly lose their general capability during sequential editing. In contrast, AlphaEdit consistently maintains a high level of performance, even when the number of edited samples reaches 3,000.
C.1.3 案例 3
这里给出每批编辑次数减半时、经各方法编辑的 LLM 的通用能力测试结果,见图 8。与正文通用能力测试结论类似,图 8 显示:经基线方法编辑的 LLM 在序列编辑过程中很快丧失通用能力;而 AlphaEdit 即便在编辑样本数达到 3,000 时仍持续保持高水平表现。
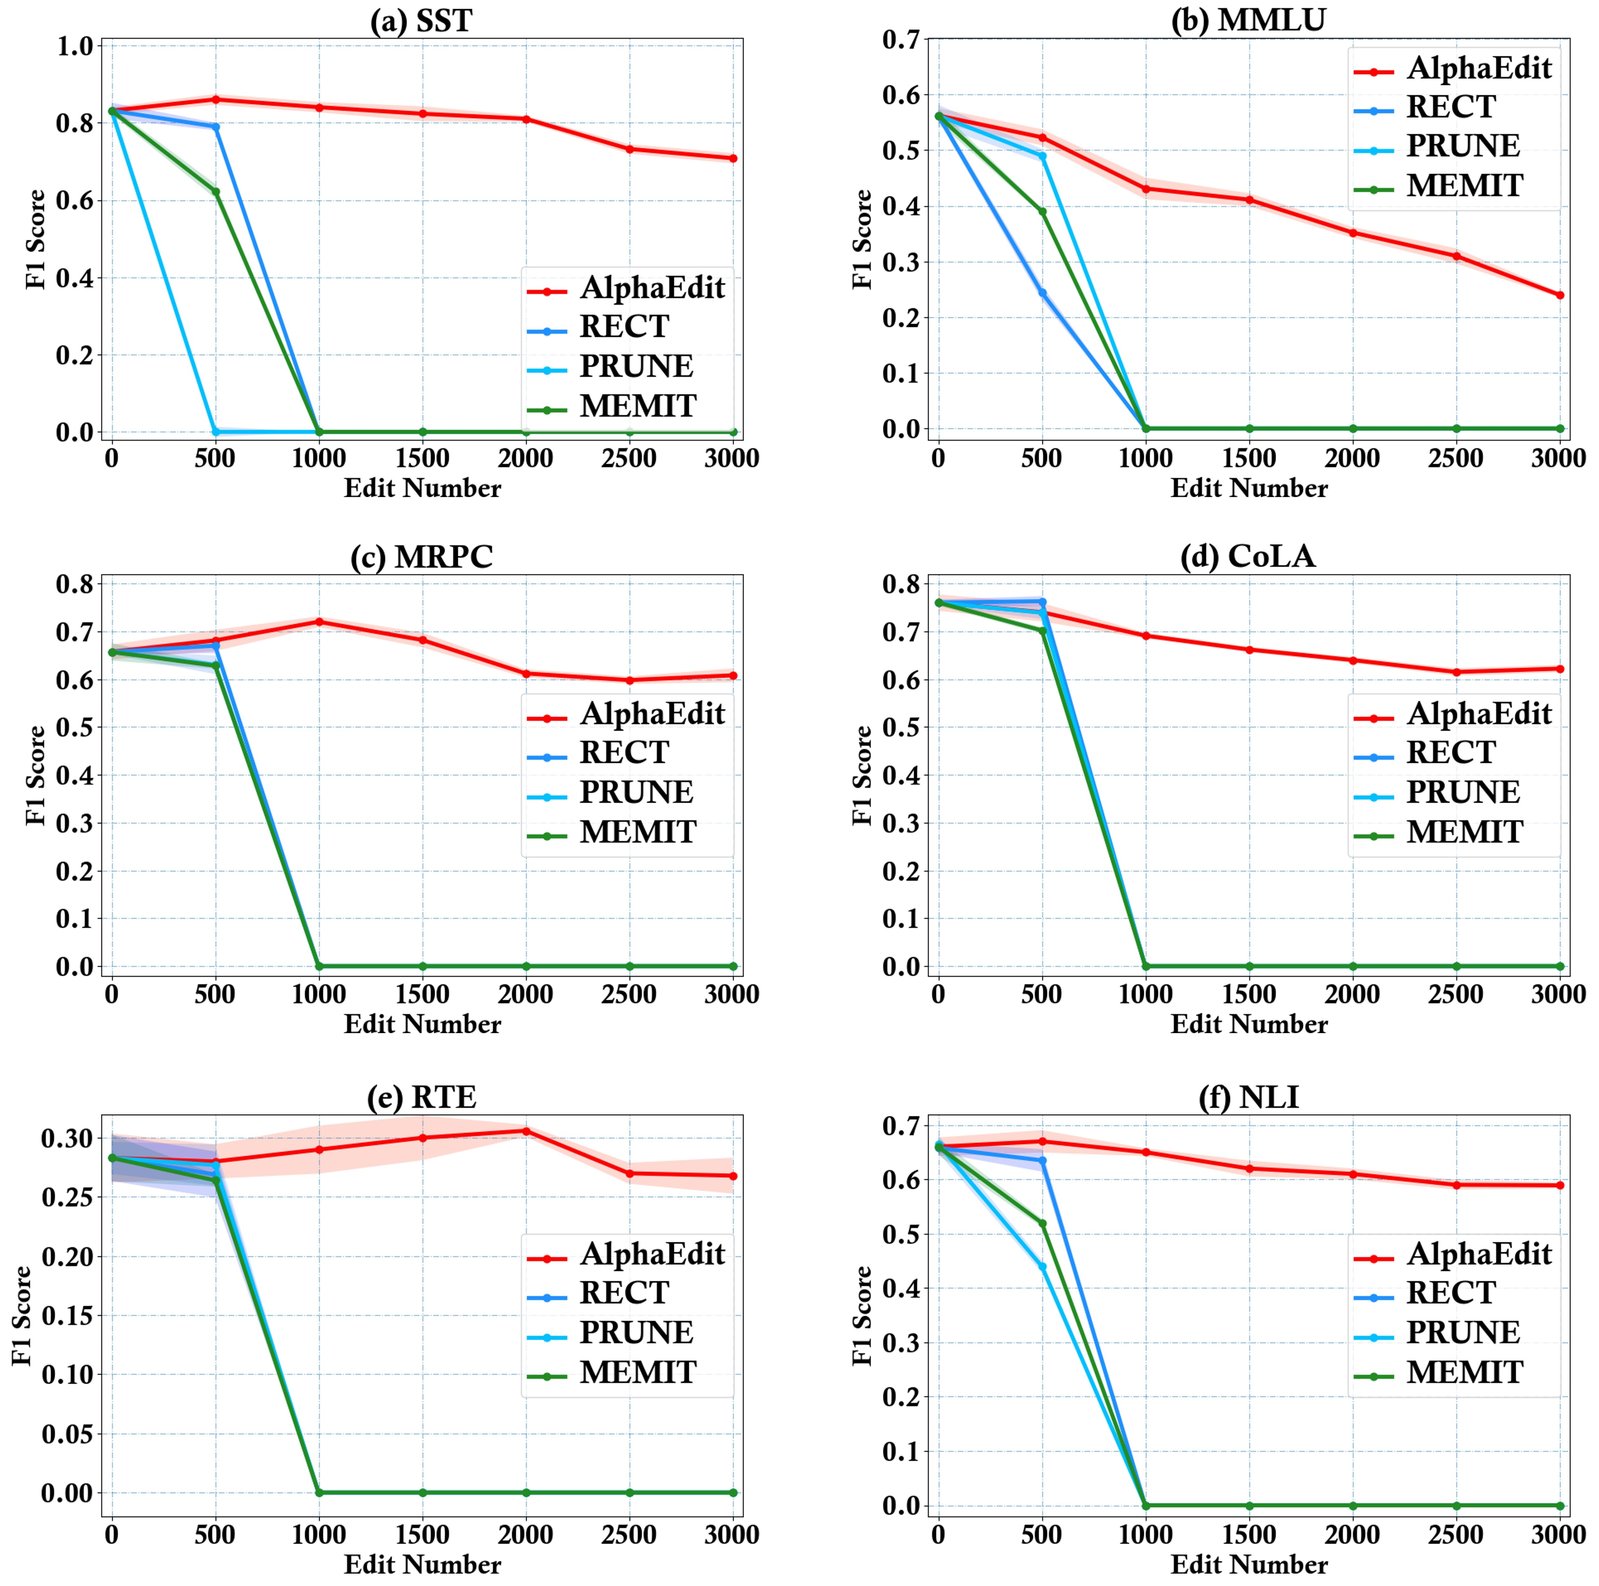
Figure 8: F1 scores of the post-edited model on six tasks (i.e., SST, MRPC, CoLA, RTE, MMLU and NLI) used for general capability testing. Best viewed in color.
图 8:编辑后模型在通用能力测试六项任务(即 SST、MRPC、CoLA、RTE、MMLU 与 NLI)上的 F1。建议彩色阅读。
C.3 Quantification of Distribution Shift
C.3 分布偏移的量化
Here, we present the quantitative results of hidden representation shifts before and after editing. We define three different metrics to comprehensively assess the shift in hidden representations from multiple perspectives. Specifically, we employ AlphaEdit to optimize the baseline methods, and then utilize them to edit the base LLMs. The results are shown in Figure 9.
这里给出编辑前后隐表示偏移的量化结果。我们定义三项不同指标,从多角度综合评估隐表示偏移。具体地,用 AlphaEdit 优化各基线方法,再用它们编辑基座 LLM。结果见图 9。
In more detail, in Figure 9, we first calculate the overlap between the marginal distribution curves before and after editing, with the overlap across two dimensions defined as metrics and . Next, we introduced the Hausdorff distance, labeled as , to measure the distance between the edited and original distributions. Finally, we calculated the probability that post-edit data points in the confidence interval of the pre-edit distribution, defining this metric as .
更细致地,在图 9 中我们先计算编辑前后边缘分布曲线的重叠,将两维上的重叠分别定义为指标 与 。接着引入 Hausdorff 距离,记为 ,度量编辑后分布与原始分布之间的距离。最后计算编辑后数据点落在编辑前分布置信区间内的概率,将该指标定义为 。
Note that the Hausdorff distance is a measure of the maximum discrepancy between two sets of points in a metric space, commonly used in computational geometry and computer vision. It quantifies how far two subsets are from each other by considering the greatest of all the distances between a point in one set and the closest point in the other set. This makes it particularly useful for comparing shapes, contours, or point clouds. For two sets and in a metric space, the Hausdorff distance is defined as:
注意:Hausdorff 距离度量度量空间中两集合点之间的最大差异,常用于计算几何与计算机视觉。它通过考虑一集合中一点到另一集合最近点的所有距离中的最大者,量化两子集相距多远,因而特别适合比较形状、轮廓或点云。对度量空间中两集合 、,Hausdorff 距离 定义为:
where:
其中:
- • is the distance between points and (often the Euclidean distance);
- • represents the distance from point in set to the nearest point in set ;
- • is the supremum (*i.e.,*maximum) of all such minimum distances from to , and similarly for points in to .
- • 为点 与 之间的距离(常为欧氏距离);
- • 表示集合 中点 到集合 最近点的距离;
- • 为从 到 所有这些最小距离的上确界(即最大值),从 到 同理。
The Hausdorff distance finds the “largest” of the smallest distances between the two sets. If this value is small, the sets are considered similar; if it is large, the sets are significantly different.
Hausdorff 距离取两集合间「最小距离」中的「最大」者。若该值小,则认为集合相似;若大,则集合显著不同。
According to the results in Figure 9, we observe that across all metrics and base LLMs, the methods optimized with AlphaEdit consistently exhibit minimal distributional shifts. This further supports the qualitative analysis presented in the main text, demonstrating that AlphaEdit effectively prevents post-edited LLMs from overfitting hidden representations to the updated knowledge, thereby preserving the original knowledge.
根据图 9,我们观察到:在所有指标与基座 LLM 上,经 AlphaEdit 优化的方法始终呈现最小的分布偏移。这进一步支持正文中的定性分析,表明 AlphaEdit 有效防止编辑后 LLM 将隐表示过拟合到更新知识,从而保留原始知识。
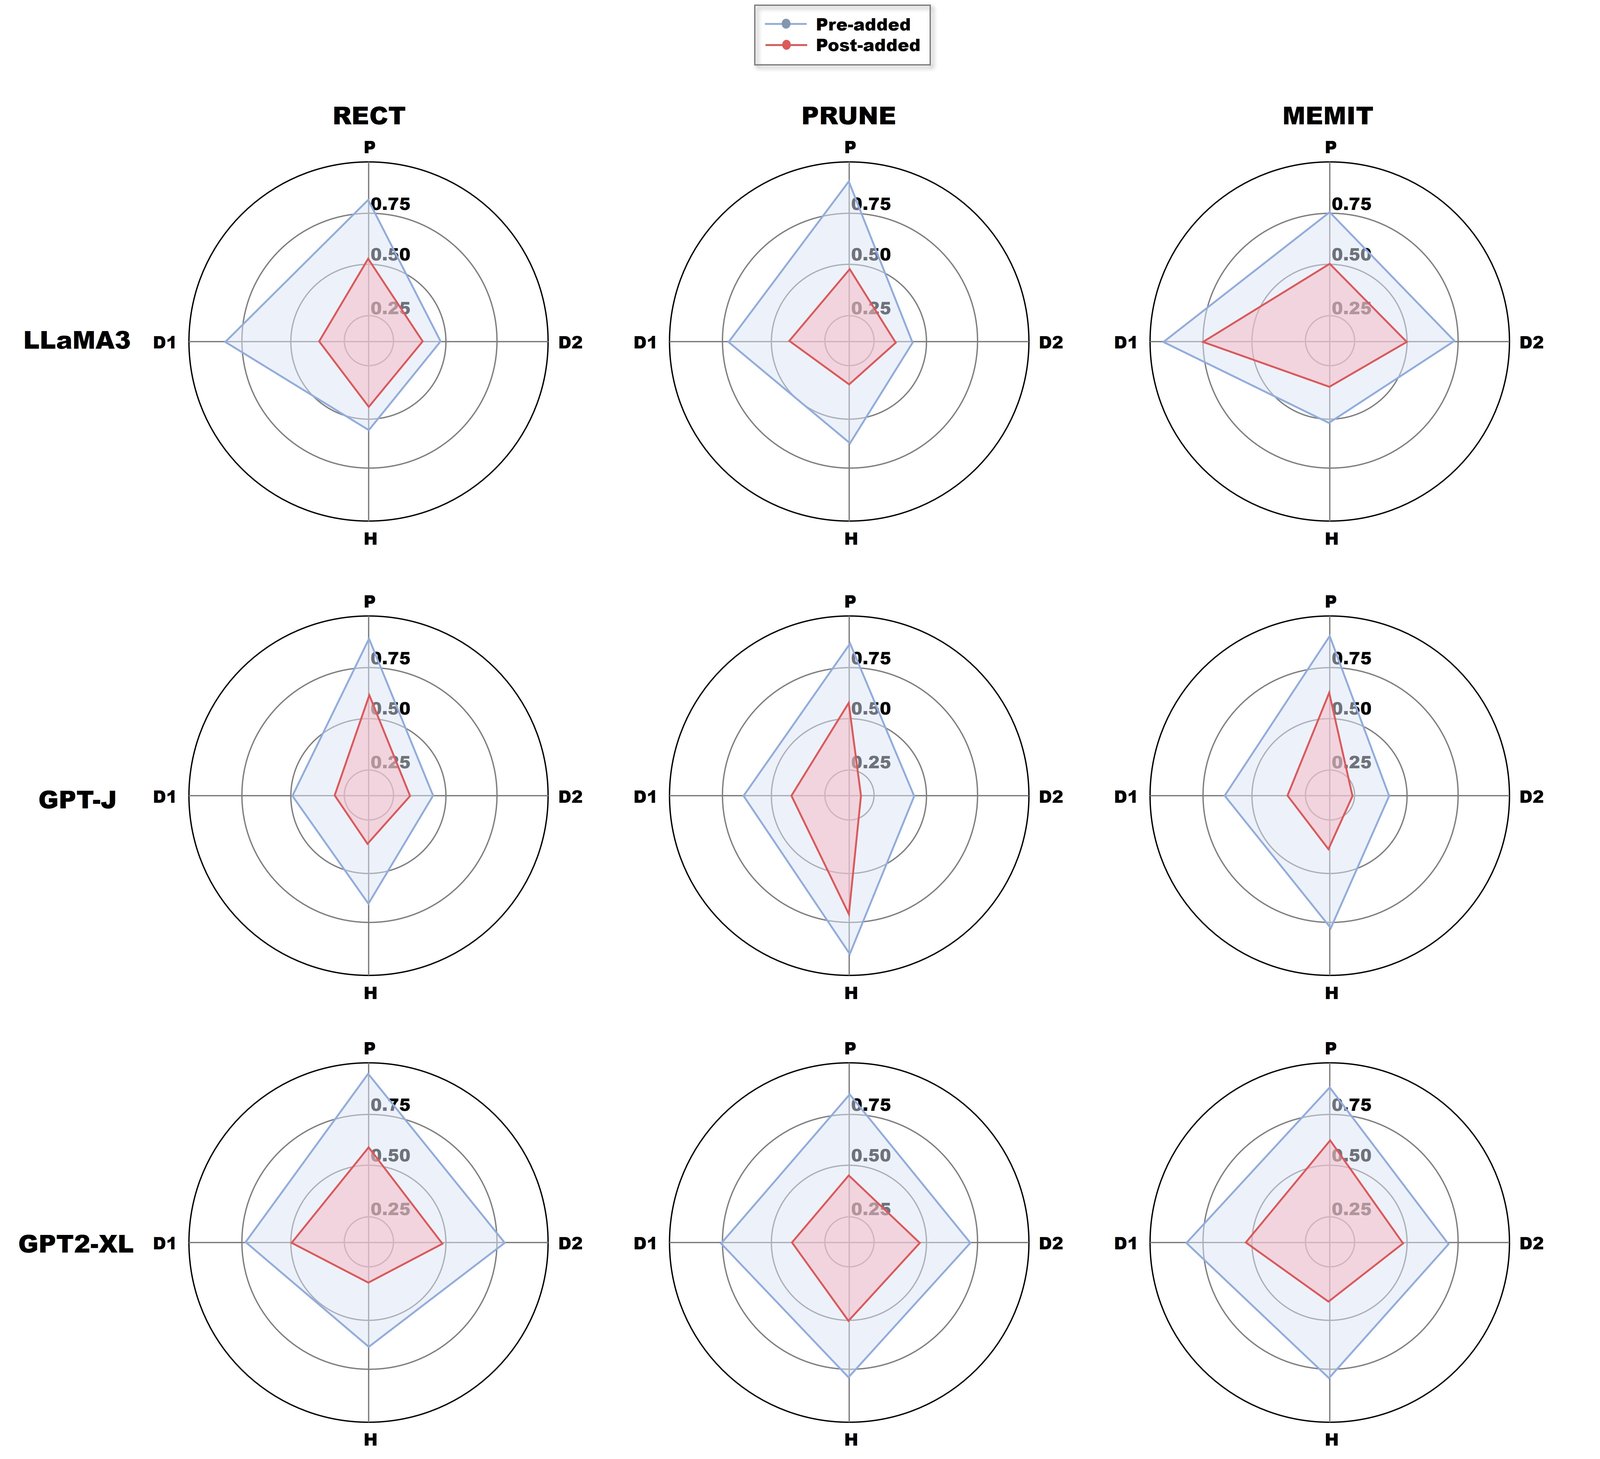
Figure 9: The quantitative results of hidden representation shifts before and after editing. Best viewed in color.
图 9:编辑前后隐表示偏移的量化结果。建议彩色阅读。
C.4 Editing Facts involving Various Semantics
C.4 涉及不同语义的事实编辑
To gain a deeper understanding of the performance when editing facts involving different semantics, following MEMIT (Meng et al. 2023), we selected several semantics from the Counterfact dataset, each containing at least 300 examples, and evaluated the performance of each baseline methods on these examples (which were evenly distributed across the sequential editing batches). Some of the results are shown in Figure 7 in the main text, with more comprehensive results displayed in Figure 10. In these figures, the horizontal axis represents Accuracy, defined as the average of Efficacy and Generalization across the 300 examples. For instance, the bar labeled "language," with a height of 98, indicates that out of 1,000 knowledge instances related to language (e.g., "The primary language in the United States is English," or "The official language of France is French"), AlphaEdit successfully edited 98% of them. This metric provides a fine-grained assessment of AlphaEdit’s effectiveness across various knowledge domains. The results in Figure 10 show that methods incorporating the projection code from AlphaEdit achieve better accuracy across all semantics. It also indicates that some semantics are more challenging to edit than others. However, even in these more difficult cases, baseline methods enhanced with AlphaEdit’s projection code still achieve over 90% accuracy.
为更深入理解编辑涉及不同语义的事实时的表现,遵循 MEMIT(Meng et al. 2023),我们从 Counterfact 中选取若干语义,每类至少含 300 条样本,并在这些样本上评估各基线(样本均匀分布在各序列编辑批次中)。部分结果见正文图 7,更全面结果见图 10。图中横轴为 Accuracy,定义为 300 条样本上 Efficacy 与 Generalization 的平均。例如标注「language」、高度为 98 的柱表示:在 1,000 条与语言相关的知识实例中(例如「The primary language in the United States is English」或「The official language of France is French」),AlphaEdit 成功编辑了 98%。该指标提供对 AlphaEdit 跨知识领域有效性的细粒度评估。图 10 显示:加入 AlphaEdit 投影代码的方法在所有语义上准确率更高;也表明某些语义比其他更难编辑。但即便在这些更难情形下,经 AlphaEdit 投影增强的基线仍能达到超过 90% 的准确率。
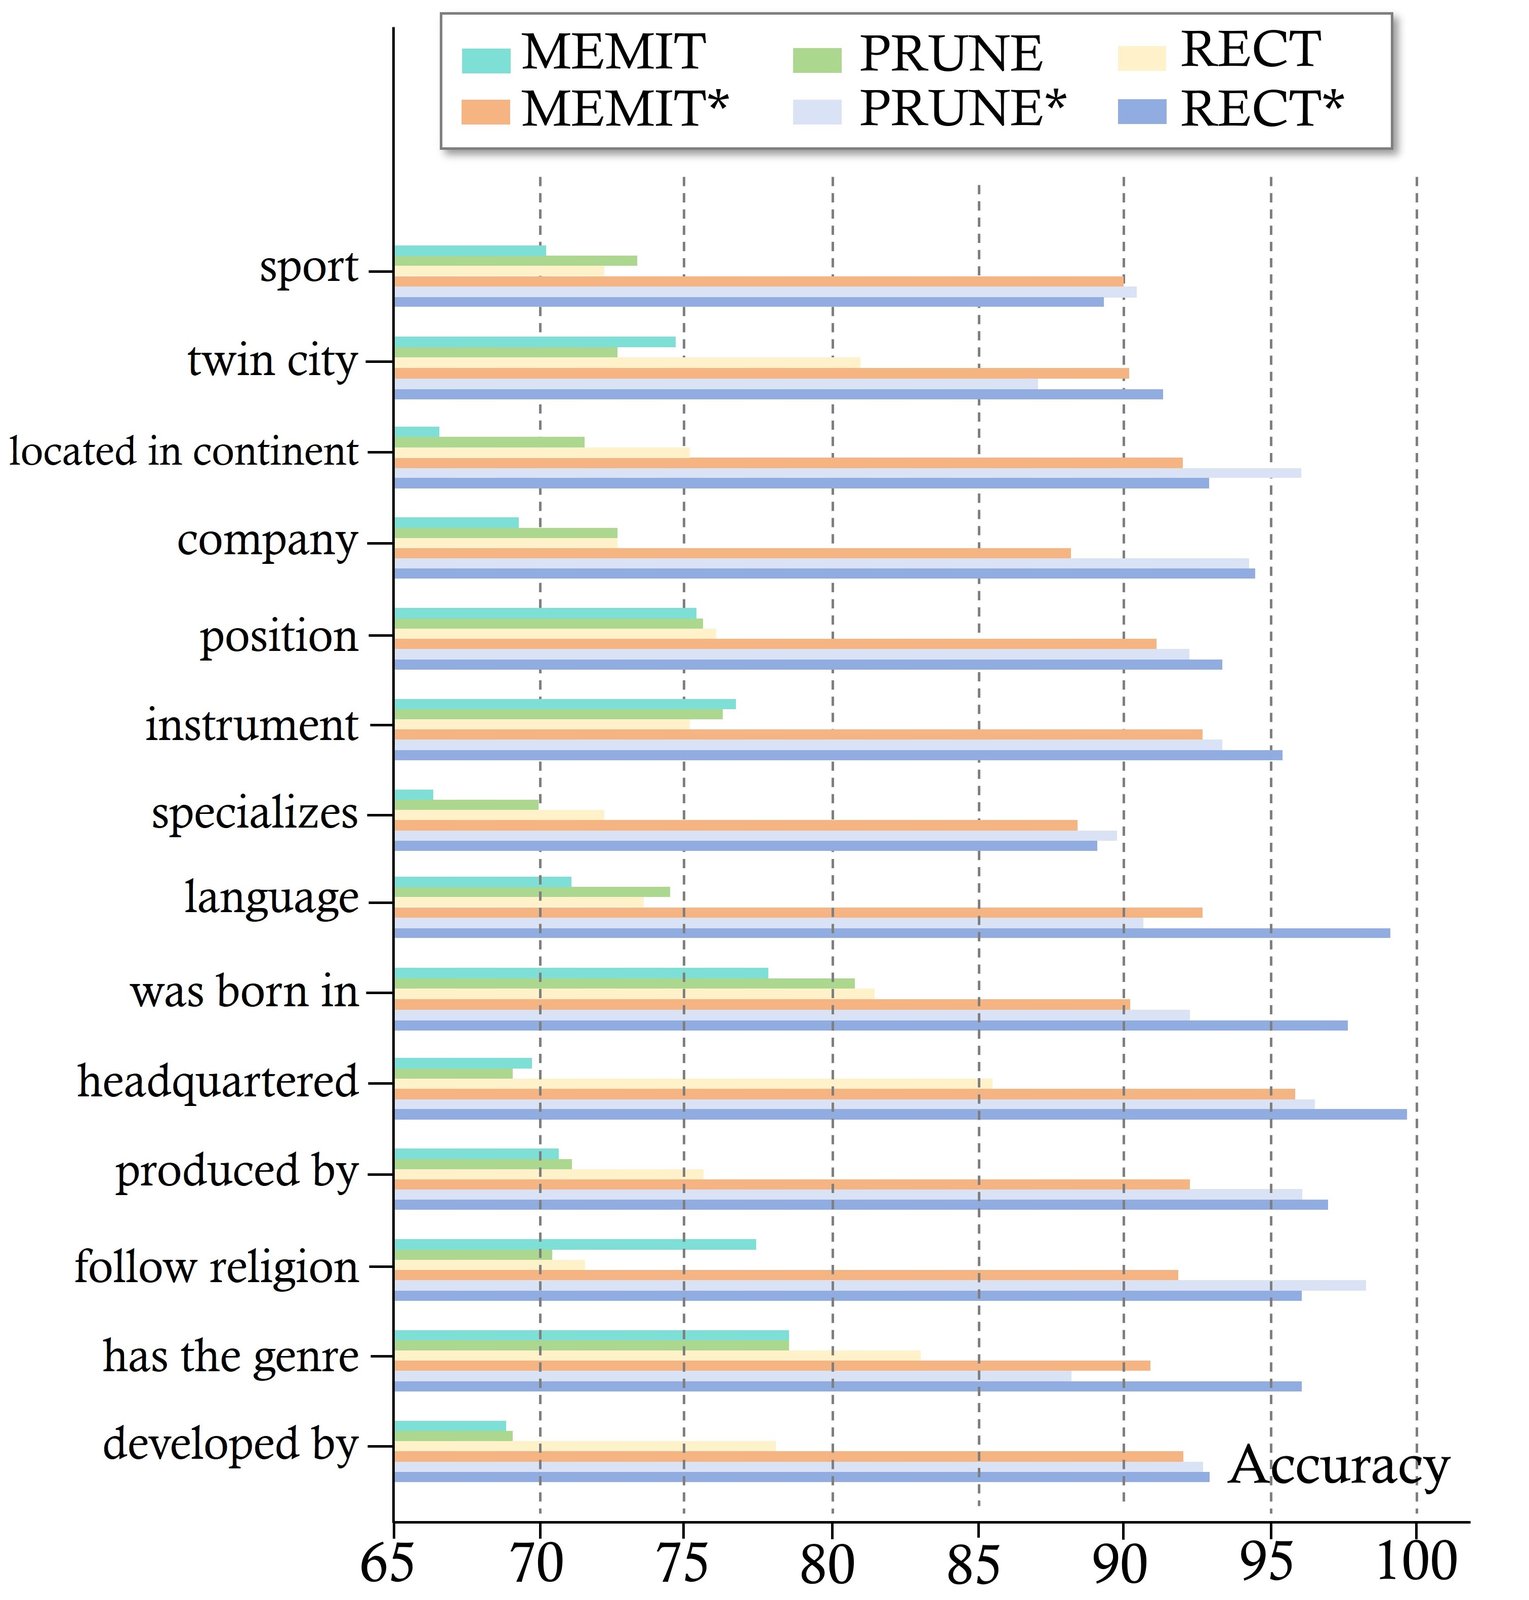
Figure 10: Performance of editing methods on samples involving specific semantics, where asterisk denotes the versions added the projection. Best viewed in color.
图 10:编辑方法在涉及特定语义样本上的表现,星号表示加入投影后的版本。建议彩色阅读。
C.5 Comparison between AlphaEdit and Memory-based Editing Methods
C.5 AlphaEdit 与基于记忆的编辑方法对比
Although our AlphaEdit mainly focuses on the parameter-modifying editing method, we also hope to explore the advantages of our method compared with some mainstream memory-based editing methods. Specifically, we select SERAC (Mitchell et al. 2022b), GRACE (Hartvigsen et al. 2023), and MELO (Yu et al. 2024) as the representative baselines of the memory-based editing methods. The results are shown in Table 2. According to Table 2 we can summarize that:
尽管 AlphaEdit 主要聚焦改参类编辑方法,我们也希望探索其相对若干主流基于记忆的编辑方法的优势。具体选取 SERAC(Mitchell et al. 2022b)、GRACE(Hartvigsen et al. 2023)与 MELO(Yu et al. 2024)作为基于记忆方法的代表基线。结果见表 2。根据表 2 可总结:
- • Across all models and tasks, AlphaEdit consistently achieves the highest scores in efficacy (Eff.) and generalization (Gen.). This indicates that AlphaEdit is highly effective at correctly applying the desired edits while maintaining robust generalization to the other knowledge. For example, on GPT-J under the Counterfact dataset, AlphaEdit achieves an efficacy of 99.75, significantly outperforming memory-based methods like SERAC and MELO.
- • While AlphaEdit generally achieves competitive scores in specificity (Spe.) and fluency (Flu.), it does not always surpass the memory-based methods. However, we believe this trade-off is reasonable and acceptable because memory-based methods inherently rely on consuming storage space to better preserve existing knowledge.
- • 在所有模型与任务上,AlphaEdit 在效力(Eff.)与泛化(Gen.)上始终取得最高分。这表明 AlphaEdit 能高效正确应用期望编辑,同时对其他知识保持稳健泛化。例如在 GPT-J、Counterfact 上,AlphaEdit 效力达 99.75,显著优于 SERAC、MELO 等基于记忆的方法。
- • 尽管 AlphaEdit 在特异性(Spe.)与流畅性(Flu.)上通常具有竞争力,但不总能超过基于记忆的方法。我们认为这一权衡合理且可接受,因为基于记忆的方法本质上依赖消耗存储空间来更好地保留已有知识。
| Method | Model | Counterfact | ZsRE | ||||||
|---|---|---|---|---|---|---|---|---|---|
| Eff. | Gen. | Spe. | Flu. | Consis. | Eff. | Gen. | Spe. | ||
| Pre-edited | LLaMA3 | 7.850.26 | 10.580.26 | 89.480.18 | 635.230.11 | 24.140.08 | 36.990.30 | 36.340.30 | 31.890.22 |
| SERAC | 71.210.56 | 61.050.39 | 66.900.21 | 615.720.34 | 20.770.13 | 67.750.24 | 33.960.35 | 22.170.15 | |
| GRACE | 96.720.13 | 50.140.01 | 72.230.21 | 620.430.63 | 23.790.23 | 93.580.31 | 1.030.06 | 31.860.12 | |
| MELO | 65.290.13 | 58.580.32 | 63.360.37 | 608.980.82 | 22.180.04 | 25.180.14 | 24.140.23 | 30.360.75 | |
| AlphaEdit | 98.900.10 | 94.220.19 | 67.880.29 | 622.490.16 | 32.400.11 | 94.470.13 | 91.130.19 | 32.550.22 | |
| Pre-edited | GPT-J | 16.220.31 | 18.560.45 | 83.110.13 | 621.810.67 | 29.740.51 | 26.32037 | 25.790.25 | 27.420.53 |
| SERAC | 82.280.26 | 58.310.34 | 68.980.32 | 615.920.72 | 28.650.17 | 92.370.29 | 38.210.32 | 25.170.25 | |
| GRACE | 96.500.24 | 50.100.01 | 74.420.43 | 620.560.79 | 31.550.25 | 96.540.21 | 0.400.02 | 24.780.21 | |
| MELO | 78.290.24 | 60.520.32 | 66.800.52 | 610.820.44 | 24.310.24 | 82.240.07 | 32.880.03 | 26.650.06 | |
| AlphaEdit | 99.750.08 | 96.380.23 | 75.480.21 | 618.500.17 | 42.080.15 | 99.790.14 | 96.000.22 | 28.290.25 | |
| Pre-edited | GPT2-XL | 22.230.73 | 24.340.62 | 78.530.33 | 626.640.31 | 31.880.20 | 22.190.24 | 31.300.27 | 24.150.32 |
| SERAC | 72.250.15 | 58.180.23 | 64.060.37 | 595.350.35 | 27.350.12 | 92.170.67 | 36.570.72 | 20.670.22 | |
| GRACE | 98.880.28 | 50.050.01 | 72.070.24 | 620.210.49 | 28.530.15 | 94.330.37 | 1.590.03 | 27.630.43 | |
| MELO | 72.620.58 | 53.630.42 | 63.250.62 | 588.570.65 | 23.580.33 | 93.540.03 | 45.250.02 | 23.450.24 | |
| AlphaEdit | 99.500.24 | 93.950.34 | 66.390.31 | 597.880.18 | 39.380.15 | 94.810.30 | 86.110.29 | 25.880.21 |
Table 2: Comparison of AlphaEdit with existing methods on the sequential model editing task. Eff., Gen., Spe., Flu. and Consis. denote Efficacy, Generalization, Specificity, Fluency and Consistency, respectively. The best results are highlighted in bold, while the second-best results are underlined.
| 方法 | 模型 | Counterfact | ZsRE | ||||||
|---|---|---|---|---|---|---|---|---|---|
| Eff. | Gen. | Spe. | Flu. | Consis. | Eff. | Gen. | Spe. | ||
| Pre-edited | LLaMA3 | 7.850.26 | 10.580.26 | 89.480.18 | 635.230.11 | 24.140.08 | 36.990.30 | 36.340.30 | 31.890.22 |
| SERAC | 71.210.56 | 61.050.39 | 66.900.21 | 615.720.34 | 20.770.13 | 67.750.24 | 33.960.35 | 22.170.15 | |
| GRACE | 96.720.13 | 50.140.01 | 72.230.21 | 620.430.63 | 23.790.23 | 93.580.31 | 1.030.06 | 31.860.12 | |
| MELO | 65.290.13 | 58.580.32 | 63.360.37 | 608.980.82 | 22.180.04 | 25.180.14 | 24.140.23 | 30.360.75 | |
| AlphaEdit | 98.900.10 | 94.220.19 | 67.880.29 | 622.490.16 | 32.400.11 | 94.470.13 | 91.130.19 | 32.550.22 | |
| Pre-edited | GPT-J | 16.220.31 | 18.560.45 | 83.110.13 | 621.810.67 | 29.740.51 | 26.32037 | 25.790.25 | 27.420.53 |
| SERAC | 82.280.26 | 58.310.34 | 68.980.32 | 615.920.72 | 28.650.17 | 92.370.29 | 38.210.32 | 25.170.25 | |
| GRACE | 96.500.24 | 50.100.01 | 74.420.43 | 620.560.79 | 31.550.25 | 96.540.21 | 0.400.02 | 24.780.21 | |
| MELO | 78.290.24 | 60.520.32 | 66.800.52 | 610.820.44 | 24.310.24 | 82.240.07 | 32.880.03 | 26.650.06 | |
| AlphaEdit | 99.750.08 | 96.380.23 | 75.480.21 | 618.500.17 | 42.080.15 | 99.790.14 | 96.000.22 | 28.290.25 | |
| Pre-edited | GPT2-XL | 22.230.73 | 24.340.62 | 78.530.33 | 626.640.31 | 31.880.20 | 22.190.24 | 31.300.27 | 24.150.32 |
| SERAC | 72.250.15 | 58.180.23 | 64.060.37 | 595.350.35 | 27.350.12 | 92.170.67 | 36.570.72 | 20.670.22 | |
| GRACE | 98.880.28 | 50.050.01 | 72.070.24 | 620.210.49 | 28.530.15 | 94.330.37 | 1.590.03 | 27.630.43 | |
| MELO | 72.620.58 | 53.630.42 | 63.250.62 | 588.570.65 | 23.580.33 | 93.540.03 | 45.250.02 | 23.450.24 | |
| AlphaEdit | 99.500.24 | 93.950.34 | 66.390.31 | 597.880.18 | 39.380.15 | 94.810.30 | 86.110.29 | 25.880.21 |
表 2:序列模型编辑任务上 AlphaEdit 与现有方法的对比。Eff.、Gen.、Spe.、Flu.、Consis. 分别表示 Efficacy、Generalization、Specificity、Fluency、Consistency。最优加粗,次优下划线。
C.6 Evaluation on Additional Base LLMs: Gemma and phi-1.5
C.6 在额外基座 LLM 上的评估:Gemma 与 phi-1.5
To enhance evaluation diversity, we extended experiments to two additional base LLMs, Gemma (Mesnard et al. 2024) and phi-1.5 (Li et al. 2023). We summarize the results in Table 3. These results demonstrate that AlphaEdit consistently outperforms MEMIT and RECT across key metrics on both the Counterfact and ZsRE datasets. Notably, on Gemma, AlphaEdit achieves the highest fluency (398.96) and consistency (32.91), reflecting its ability to maintain coherence and accuracy. Similarly, on phi-1.5, AlphaEdit excels in efficacy (70.79) and fluency (399.47), showcasing its adaptability to smaller, efficient models. These findings confirm AlphaEdit’s robustness across diverse LLM architectures and its capability to deliver high-quality edits while preserving model integrity.
为增强评估多样性,我们将实验扩展到另外两个基座 LLM:Gemma(Mesnard et al. 2024)与 phi-1.5(Li et al. 2023)。结果汇总于表 3。这些结果表明:在 Counterfact 与 ZsRE 的关键指标上,AlphaEdit 持续优于 MEMIT 与 RECT。尤其在 Gemma 上,AlphaEdit 取得最高流畅性(398.96)与一致性(32.91),反映其维持连贯与准确的能力;在 phi-1.5 上,AlphaEdit 在效力(70.79)与流畅性(399.47)上表现突出,展现对更小、更高效模型的适应性。这些发现确认了 AlphaEdit 跨多样 LLM 架构的稳健性,以及在保留模型完整性的同时交付高质量编辑的能力。
| Method | Model | Counterfact | ZsRE | ||||||
|---|---|---|---|---|---|---|---|---|---|
| Eff. | Gen. | Spe. | Flu. | Consis. | Eff. | Gen. | Spe. | ||
| MEMIT | Gemma | 64.680.21 | 60.360.30 | 46.730.62 | 373.941.12 | 22.140.31 | 64.380.26 | 66.120.46 | 24.520.38 |
| RECT | 65.170.19 | 57.480.64 | 52.540.54 | 388.770.44 | 23.370.39 | 67.180.50 | 64.120.47 | 20.020.47 | |
| AlphaEdit | 75.210.09 | 67.830.63 | 52.630.49 | 398.960.39 | 32.910.35 | 75.910.42 | 68.120.67 | 23.500.56 | |
| MEMIT | phi-1.5 | 55.710.63 | 56.580.78 | 35.410.99 | 368.571.26 | 19.790.31 | 54.410.78 | 52.470.89 | 20.980.58 |
| RECT | 58.190.73 | 58.920.76 | 38.460.92 | 362.941.44 | 19.880.37 | 55.150.72 | 53.640.83 | 18.580.65 | |
| AlphaEdit | 70.790.56 | 65.120.88 | 48.960.96 | 399.470.67 | 25.980.48 | 70.020.85 | 63.190.72 | 20.690.73 |
Table 3: Comparison of AlphaEdit with existing methods on the sequential model editing task. Eff., Gen., Spe., Flu. and Consis. denote Efficacy, Generalization, Specificity, Fluency and Consistency, respectively. The best results are highlighted in bold, while the second-best results are underlined.
| 方法 | 模型 | Counterfact | ZsRE | ||||||
|---|---|---|---|---|---|---|---|---|---|
| Eff. | Gen. | Spe. | Flu. | Consis. | Eff. | Gen. | Spe. | ||
| MEMIT | Gemma | 64.680.21 | 60.360.30 | 46.730.62 | 373.941.12 | 22.140.31 | 64.380.26 | 66.120.46 | 24.520.38 |
| RECT | 65.170.19 | 57.480.64 | 52.540.54 | 388.770.44 | 23.370.39 | 67.180.50 | 64.120.47 | 20.020.47 | |
| AlphaEdit | 75.210.09 | 67.830.63 | 52.630.49 | 398.960.39 | 32.910.35 | 75.910.42 | 68.120.67 | 23.500.56 | |
| MEMIT | phi-1.5 | 55.710.63 | 56.580.78 | 35.410.99 | 368.571.26 | 19.790.31 | 54.410.78 | 52.470.89 | 20.980.58 |
| RECT | 58.190.73 | 58.920.76 | 38.460.92 | 362.941.44 | 19.880.37 | 55.150.72 | 53.640.83 | 18.580.65 | |
| AlphaEdit | 70.790.56 | 65.120.88 | 48.960.96 | 399.470.67 | 25.980.48 | 70.020.85 | 63.190.72 | 20.690.73 |
表 3:序列模型编辑任务上 AlphaEdit 与现有方法的对比。Eff.、Gen.、Spe.、Flu.、Consis. 分别表示 Efficacy、Generalization、Specificity、Fluency、Consistency。最优加粗,次优下划线。
C.7 Evaluation on Expanding Benchmark: KnowEdit, LEME and MQUAKE
C.7 在扩展基准上的评估:KnowEdit、LEME 与 MQUAKE
In this part, we selected two datasets from the KnowEdit (Zhang et al. 2024d) benchmark, namely wiki_recent and wikibio, for testing. During our experiments, we noticed that some samples within these datasets exhibit abnormally high norms in the hidden states when processed by the LLaMA3-8B-instruct model. These elevated norms are often accompanied by disproportionately large target value norms, which, if forcibly edited, could compromise the model’s stability. To mitigate this issue, we implemented an automatic filtering mechanism to exclude samples with excessively high hidden state norms during the continuous editing process. Experimental results are presented in Table 4.
本部分从 KnowEdit(Zhang et al. 2024d)基准中选取 wiki_recent 与 wikibio 两个数据集进行测试。实验中我们发现:部分样本经 LLaMA3-8B-instruct 处理后,隐状态范数异常偏高;这些偏高范数常伴随目标值范数不成比例地放大,若强行编辑可能损害模型稳定性。为缓解该问题,我们在连续编辑过程中实现自动过滤机制,排除隐状态范数过高的样本。实验结果见表 4。
Additionally, we extended our evaluations to two critical datasets, LEME (Rosati et al. 2024) and MQUAKE (Zhong et al. 2023), to test AlphaEdit’s performance in more challenging scenarios. LEME focuses on long-form generative tasks, emphasizing consistency, factual correctness, and lexical cohesion. MQUAKE, on the other hand, evaluates the ripple effects of factual updates using multi-hop reasoning questions. Results for these two datasets are summarized in Table 5.
此外,我们将评估扩展到两个关键数据集 LEME(Rosati et al. 2024)与 MQUAKE(Zhong et al. 2023),以在更具挑战的场景下测试 AlphaEdit。LEME 聚焦长文生成任务,强调一致性、事实正确性与词汇衔接;MQUAKE 则用多跳推理问题评估事实更新的涟漪效应。两数据集结果汇总于表 5。
According to Table 4 and 5 we can find that:
根据表 4 与表 5,可以发现:
- • AlphaEdit demonstrates a remarkable ability to achieve high editing success rates across all evaluated datasets. For instance, on the wiki_recent dataset, AlphaEdit achieves an impressive 96.10% editing success, which is significantly higher than the second-best method, RECT (82.47%). A similar trend is observed on wikibio, where AlphaEdit reaches 95.34%, outperforming RECT by a substantial margin.
- • AlphaEdit demonstrates the best performance in both Multi-hop and Multi-hop (CoT) tasks, with scores of 9.14 and 9.75 respectively, significantly surpassing competing methods. This showcases its strong capability in handling complex reasoning tasks and ensuring logical consistency across interdependent facts.
- • On LEME, AlphaEdit excels in all three metrics, showcasing its ability to generate accurate long-form outputs. Its consistently high performance across GPT-J and GPT2-XL reinforces its reliability in executing precise edits while maintaining the structural coherence and integrity of the generated text.
- • AlphaEdit 在所有评估数据集上均展现出很高的编辑成功率。例如在 wiki_recent 上,AlphaEdit 达到 96.10% 的编辑成功,显著高于次优方法 RECT(82.47%);在 wikibio 上同样达到 95.34%,大幅领先 RECT。
- • AlphaEdit 在 Multi-hop 与 Multi-hop(CoT)任务上表现最佳,分数分别为 9.14 与 9.75,显著超过竞争方法。这展示其处理复杂推理任务、并在相互依赖事实间保证逻辑一致性的能力。
- • 在 LEME 上,AlphaEdit 三项指标均领先,展现生成准确长文输出的能力;其在 GPT-J 与 GPT2-XL 上持续的高表现,强化了它在执行精确编辑的同时维持生成文本结构连贯与完整性的可靠性。
| Method | wiki_recent | wikibio | |||||
|---|---|---|---|---|---|---|---|
| Edit Succ. | Portability | Locality | Fluency | Edit Succ. | Locality | Fluency | |
| MEMIT | 56.250.28 | 42.730.27 | 41.020.20 | 513.353.47 | 63.730.40 | 64.270.41 | 582.383.34 |
| RECT | 82.470.53 | 51.280.25 | 48.840.24 | 568.623.71 | 91.480.48 | 72.830.44 | 612.044.29 |
| AlphaEdit | 96.100.47 | 57.300.38 | 54.760.30 | 594.523.91 | 95.340.46 | 75.340.50 | 618.354.22 |
Table 4: Performance comparison of alphaEdit on wiki_Recent and wikibio datasets across key metrics including Edit Success, Portability, Locality, and Fluency. Results are averaged with standard deviations. The best results are highlighted in bold.
| 方法 | wiki_recent | wikibio | |||||
|---|---|---|---|---|---|---|---|
| Edit Succ. | Portability | Locality | Fluency | Edit Succ. | Locality | Fluency | |
| MEMIT | 56.250.28 | 42.730.27 | 41.020.20 | 513.353.47 | 63.730.40 | 64.270.41 | 582.383.34 |
| RECT | 82.470.53 | 51.280.25 | 48.840.24 | 568.623.71 | 91.480.48 | 72.830.44 | 612.044.29 |
| AlphaEdit | 96.100.47 | 57.300.38 | 54.760.30 | 594.523.91 | 95.340.46 | 75.340.50 | 618.354.22 |
表 4:AlphaEdit 在 wiki_recent 与 wikibio 数据集上跨 Edit Success、Portability、Locality、Fluency 等关键指标的性能对比。结果为均值±标准差。最优加粗。
| Model | Method | MQuAKE | LEME | |||
|---|---|---|---|---|---|---|
| Multi-hop | Multi-hop(CoT) | Edit | Factual | Internal | ||
| MEMIT | 3.350.07 | 6.130.12 | 2.110.18 | 2.020.17 | 3.840.29 | |
| GPT-J | RECT | 3.770.04 | 7.610.20 | 2.240.20 | 2.620.19 | 4.070.31 |
| AlphaEdit | 5.030.16 | 9.140.21 | 3.340.26 | 3.800.28 | 5.420.41 | |
| MEMIT | 3.140.08 | 6.250.11 | 1.920.22 | 2.310.20 | 3.850.34 | |
| GPT2-XL | RECT | 3.720.06 | 7.480.24 | 2.120.26 | 2.600.21 | 4.130.29 |
| AlphaEdit | 5.000.23 | 9.250.27 | 3.280.36 | 3.070.33 | 5.760.49 |
Table 5: Performance of AlphaEdit on MQuAKE and LEME datasets for multi-Hop reasoning and long-form editing. Metrics include Multi-hop Reasoning, Chain-of-Thought (CoT) Multi-hop Reasoning, Edit Consistency, Factual Consistency, and Internal Consistency. The best results are highlighted in bold.
| 模型 | 方法 | MQuAKE | LEME | |||
|---|---|---|---|---|---|---|
| Multi-hop | Multi-hop(CoT) | Edit | Factual | Internal | ||
| MEMIT | 3.350.07 | 6.130.12 | 2.110.18 | 2.020.17 | 3.840.29 | |
| GPT-J | RECT | 3.770.04 | 7.610.20 | 2.240.20 | 2.620.19 | 4.070.31 |
| AlphaEdit | 5.030.16 | 9.140.21 | 3.340.26 | 3.800.28 | 5.420.41 | |
| MEMIT | 3.140.08 | 6.250.11 | 1.920.22 | 2.310.20 | 3.850.34 | |
| GPT2-XL | RECT | 3.720.06 | 7.480.24 | 2.120.26 | 2.600.21 | 4.130.29 |
| AlphaEdit | 5.000.23 | 9.250.27 | 3.280.36 | 3.070.33 | 5.760.49 |
表 5:AlphaEdit 在 MQuAKE 与 LEME 上的多跳推理与长文编辑表现。指标包括 Multi-hop Reasoning、Chain-of-Thought(CoT)Multi-hop Reasoning、Edit Consistency、Factual Consistency 与 Internal Consistency。最优加粗。
C.8 Impact of Dataset Size on AlphaEdit’s Performance
C.8 数据集规模对 AlphaEdit 表现的影响
To explore the relationship between dataset size for calculating and AlphaEdit’s performance, we conduct additional experiments to evaluate the robustness of the model under reduced dataset conditions. Specifically, we progressively reduce the size of the dataset used to compute to proportions of its original size. The goal is to analyze the impact of dataset size on three key metrics: Efficacy, Generalization, and Specificity. All the results are summarized in Table 6. To further illustrate trend changes, we select the results for LLaMA3 and visualized them using line charts, as presented in Figure 11. According to Figure 11 we can find that:
为探索用于计算 的数据集规模与 AlphaEdit 表现的关系,我们做额外实验,在缩减数据集条件下评估模型稳健性。具体地,将用于计算 的数据集规模逐步降至原规模的 。目标是分析数据集规模对三项关键指标——Efficacy、Generalization、Specificity——的影响。全部结果汇总于表 6。为进一步展示趋势变化,我们选取 LLaMA3 的结果并用折线图可视化,见图 11。根据图 11 可以发现:
- • As the dataset size decreased, both Efficacy and Generalization demonstrate notable stability. Even at only 10% of the original dataset size, the drop in these metrics is negligible (less than 5%), suggesting that AlphaEdit effectively generalizes to unseen data and remains efficient even with reduced data availability.
- • In contrast, the Specificity metric experience a significant decline as the dataset size is reduced. When the dataset size is limited to just 10% of its original volume, Specificity drop by 11.76%, indicating that the model’s ability to store neighborhood knowledge heavily relies on the availability of a sufficiently large dataset.
- • 随数据集规模减小,Efficacy 与 Generalization 展现出显著稳定性。即便仅用原规模的 10%,这两项指标的下降也可忽略(小于 5%),表明 AlphaEdit 能有效泛化到未见数据,并在数据可用性降低时仍保持高效。
- • 相比之下,Specificity 随数据集规模减小而显著下降。当规模仅剩原体积的 10% 时,Specificity 下降 11.76%,表明模型存储邻域知识的能力高度依赖足够大的数据集。
| Model | Ratio | Counterfact | ZsRE | ||||
|---|---|---|---|---|---|---|---|
| Eff. | Gen. | Spe. | Eff. | Gen. | Spe. | ||
| LLaMA3 | 1.0 | 98.901.21 | 94.220.89 | 67.881.34 | 94.470.97 | 91.131.02 | 32.551.78 |
| 0.9 | 98.320.92 | 93.871.56 | 66.231.18 | 94.121.44 | 91.761.02 | 31.891.23 | |
| 0.8 | 96.751.35 | 92.450.78 | 66.450.99 | 94.121.23 | 90.951.42 | 30.671.09 | |
| 0.7 | 95.660.76 | 93.110.98 | 64.891.41 | 93.871.11 | 90.450.97 | 29.340.84 | |
| 0.6 | 96.120.86 | 91.341.23 | 63.340.94 | 93.871.36 | 91.121.11 | 29.341.25 | |
| 0.5 | 97.931.23 | 94.011.09 | 63.510.97 | 92.960.89 | 91.671.03 | 28.561.34 | |
| 0.4 | 95.880.78 | 92.671.11 | 61.781.09 | 92.981.09 | 91.761.28 | 28.560.99 | |
| 0.3 | 96.981.67 | 93.220.99 | 58.561.08 | 93.121.43 | 89.121.23 | 27.561.67 | |
| 0.2 | 97.450.97 | 91.891.22 | 56.890.89 | 93.010.84 | 89.991.09 | 26.341.34 | |
| 0.1 | 95.211.03 | 90.121.45 | 56.121.22 | 92.011.02 | 89.971.28 | 25.891.47 | |
| GPT2-XL | 1.0 | 99.500.98 | 93.951.13 | 66.390.89 | 94.811.56 | 86.111.24 | 25.881.42 |
| 0.9 | 97.821.43 | 92.780.87 | 65.240.92 | 93.671.05 | 85.731.12 | 25.051.32 | |
| 0.8 | 98.471.12 | 92.541.32 | 64.890.76 | 93.210.99 | 85.480.78 | 23.981.24 | |
| 0.7 | 96.231.09 | 93.211.24 | 64.450.98 | 94.051.09 | 85.740.89 | 23.671.11 | |
| 0.6 | 99.120.87 | 91.331.07 | 64.450.93 | 94.310.99 | 84.851.45 | 23.450.98 | |
| 0.5 | 95.680.92 | 90.891.34 | 61.760.76 | 94.740.87 | 85.921.23 | 22.780.76 | |
| 0.4 | 97.541.45 | 91.761.23 | 60.231.09 | 93.520.98 | 84.450.88 | 22.341.01 | |
| 0.3 | 99.011.09 | 90.321.11 | 58.920.92 | 93.011.34 | 83.780.99 | 22.671.21 | |
| 0.2 | 95.890.78 | 91.031.03 | 58.141.23 | 93.041.09 | 85.070.95 | 22.451.15 | |
| 0.1 | 96.351.02 | 91.031.32 | 58.141.14 | 93.041.22 | 85.071.43 | 21.111.12 | |
| GPT-J | 1.0 | 99.751.15 | 96.381.45 | 75.481.25 | 99.791.28 | 96.001.67 | 28.291.32 |
| 0.9 | 99.431.09 | 96.141.08 | 74.751.11 | 97.631.03 | 96.110.98 | 27.121.43 | |
| 0.8 | 98.340.76 | 96.031.12 | 75.210.89 | 97.650.87 | 96.011.32 | 25.890.89 | |
| 0.7 | 98.211.23 | 95.111.56 | 73.581.01 | 98.781.15 | 95.340.94 | 25.091.09 | |
| 0.6 | 98.941.17 | 95.331.12 | 73.891.21 | 99.051.09 | 95.450.84 | 24.871.45 | |
| 0.5 | 98.461.21 | 94.891.09 | 70.881.05 | 98.941.04 | 95.121.28 | 23.780.97 | |
| 0.4 | 97.740.88 | 94.761.04 | 69.891.18 | 98.311.23 | 94.911.09 | 23.671.22 | |
| 0.3 | 96.741.32 | 94.340.95 | 67.950.84 | 97.580.98 | 94.231.15 | 22.781.12 | |
| 0.2 | 96.941.09 | 94.731.24 | 68.040.92 | 97.340.97 | 94.121.02 | 23.451.09 | |
| 0.1 | 97.020.89 | 94.730.98 | 68.041.09 | 97.581.21 | 94.230.89 | 23.671.32 |
Table 6: Performance of AlphaEdit across various ratio of dataset size on the sequential model editing task. Eff., Gen. and Spe. denote Efficacy, Generalization and Specificity, respectively.
| 模型 | 比例 | Counterfact | ZsRE | ||||
|---|---|---|---|---|---|---|---|
| Eff. | Gen. | Spe. | Eff. | Gen. | Spe. | ||
| LLaMA3 | 1.0 | 98.901.21 | 94.220.89 | 67.881.34 | 94.470.97 | 91.131.02 | 32.551.78 |
| 0.9 | 98.320.92 | 93.871.56 | 66.231.18 | 94.121.44 | 91.761.02 | 31.891.23 | |
| 0.8 | 96.751.35 | 92.450.78 | 66.450.99 | 94.121.23 | 90.951.42 | 30.671.09 | |
| 0.7 | 95.660.76 | 93.110.98 | 64.891.41 | 93.871.11 | 90.450.97 | 29.340.84 | |
| 0.6 | 96.120.86 | 91.341.23 | 63.340.94 | 93.871.36 | 91.121.11 | 29.341.25 | |
| 0.5 | 97.931.23 | 94.011.09 | 63.510.97 | 92.960.89 | 91.671.03 | 28.561.34 | |
| 0.4 | 95.880.78 | 92.671.11 | 61.781.09 | 92.981.09 | 91.761.28 | 28.560.99 | |
| 0.3 | 96.981.67 | 93.220.99 | 58.561.08 | 93.121.43 | 89.121.23 | 27.561.67 | |
| 0.2 | 97.450.97 | 91.891.22 | 56.890.89 | 93.010.84 | 89.991.09 | 26.341.34 | |
| 0.1 | 95.211.03 | 90.121.45 | 56.121.22 | 92.011.02 | 89.971.28 | 25.891.47 | |
| GPT2-XL | 1.0 | 99.500.98 | 93.951.13 | 66.390.89 | 94.811.56 | 86.111.24 | 25.881.42 |
| 0.9 | 97.821.43 | 92.780.87 | 65.240.92 | 93.671.05 | 85.731.12 | 25.051.32 | |
| 0.8 | 98.471.12 | 92.541.32 | 64.890.76 | 93.210.99 | 85.480.78 | 23.981.24 | |
| 0.7 | 96.231.09 | 93.211.24 | 64.450.98 | 94.051.09 | 85.740.89 | 23.671.11 | |
| 0.6 | 99.120.87 | 91.331.07 | 64.450.93 | 94.310.99 | 84.851.45 | 23.450.98 | |
| 0.5 | 95.680.92 | 90.891.34 | 61.760.76 | 94.740.87 | 85.921.23 | 22.780.76 | |
| 0.4 | 97.541.45 | 91.761.23 | 60.231.09 | 93.520.98 | 84.450.88 | 22.341.01 | |
| 0.3 | 99.011.09 | 90.321.11 | 58.920.92 | 93.011.34 | 83.780.99 | 22.671.21 | |
| 0.2 | 95.890.78 | 91.031.03 | 58.141.23 | 93.041.09 | 85.070.95 | 22.451.15 | |
| 0.1 | 96.351.02 | 91.031.32 | 58.141.14 | 93.041.22 | 85.071.43 | 21.111.12 | |
| GPT-J | 1.0 | 99.751.15 | 96.381.45 | 75.481.25 | 99.791.28 | 96.001.67 | 28.291.32 |
| 0.9 | 99.431.09 | 96.141.08 | 74.751.11 | 97.631.03 | 96.110.98 | 27.121.43 | |
| 0.8 | 98.340.76 | 96.031.12 | 75.210.89 | 97.650.87 | 96.011.32 | 25.890.89 | |
| 0.7 | 98.211.23 | 95.111.56 | 73.581.01 | 98.781.15 | 95.340.94 | 25.091.09 | |
| 0.6 | 98.941.17 | 95.331.12 | 73.891.21 | 99.051.09 | 95.450.84 | 24.871.45 | |
| 0.5 | 98.461.21 | 94.891.09 | 70.881.05 | 98.941.04 | 95.121.28 | 23.780.97 | |
| 0.4 | 97.740.88 | 94.761.04 | 69.891.18 | 98.311.23 | 94.911.09 | 23.671.22 | |
| 0.3 | 96.741.32 | 94.340.95 | 67.950.84 | 97.580.98 | 94.231.15 | 22.781.12 | |
| 0.2 | 96.941.09 | 94.731.24 | 68.040.92 | 97.340.97 | 94.121.02 | 23.451.09 | |
| 0.1 | 97.020.89 | 94.730.98 | 68.041.09 | 97.581.21 | 94.230.89 | 23.671.32 |
表 6:不同数据集规模比例下 AlphaEdit 在序列模型编辑任务上的表现。Eff.、Gen.、Spe. 分别表示 Efficacy、Generalization、Specificity。
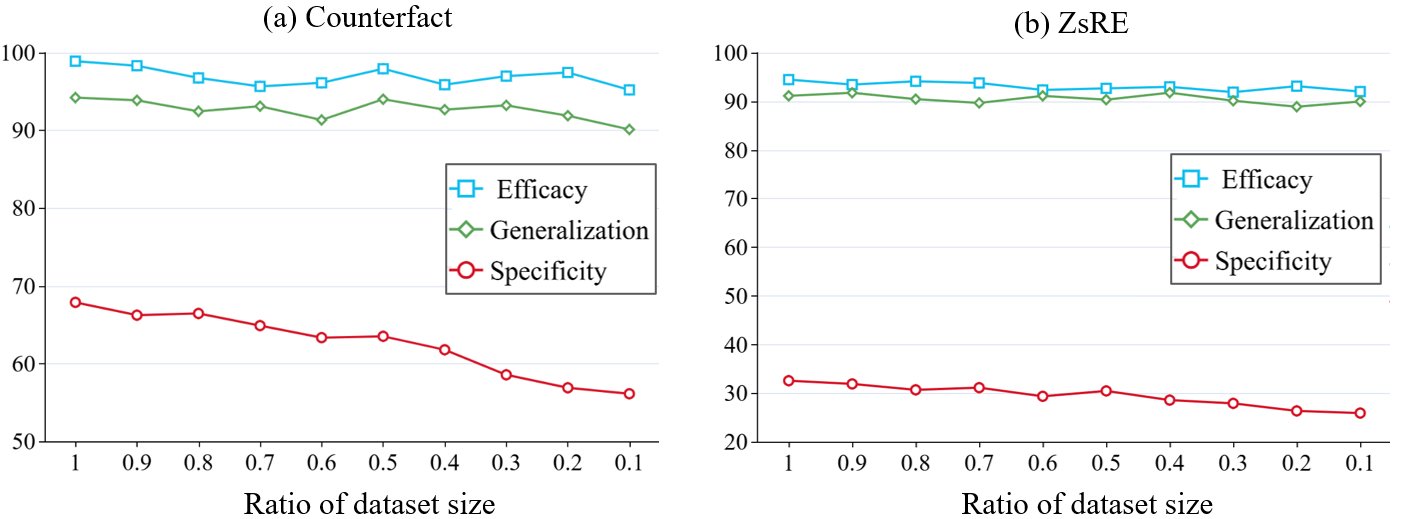
Figure 11: Performance of AlphaEdit across various ratio of dataset size on the sequential model editing task. Best viewed in color.
图 11:不同数据集规模比例下 AlphaEdit 在序列模型编辑任务上的表现。建议彩色阅读。
| Method | Counterfact | ZsRE | ||||
|---|---|---|---|---|---|---|
| LLaMA3 | GPT-J | GPT2-XL | LLaMA3 | GPT-J | GPT2-XL | |
| MEMIT | 222.51s | 334.74s | 474.14s | 231.32s | 344.21s | 488.37s |
| AlphaEdit | 223.24s | 334.93s | 476.79s | 231.40s | 345.52s | 490.25s |
Table 7: Times per batch (100 edits) for MEMIT and AlphaEdit evaluated on Counterfact and ZsRE dataset across various base LLMs.
| 方法 | Counterfact | ZsRE | ||||
|---|---|---|---|---|---|---|
| LLaMA3 | GPT-J | GPT2-XL | LLaMA3 | GPT-J | GPT2-XL | |
| MEMIT | 222.51s | 334.74s | 474.14s | 231.32s | 344.21s | 488.37s |
| AlphaEdit | 223.24s | 334.93s | 476.79s | 231.40s | 345.52s | 490.25s |
表 7:MEMIT 与 AlphaEdit 在 Counterfact、ZsRE 及多种基座 LLM 上每批(100 次编辑)耗时。
C.9 Runtime Evaluation of AlphaEdit
C.9 AlphaEdit 的运行时评估
The computational complexity of the null-space projection in AlphaEdit depends solely on the dimension of the hidden dimension within the base LLM. Specifically, calculating the null-space projection matrix only requires operations on , which are independent of the number of layers, model size, or the knowledge base size.
AlphaEdit 中零空间投影的计算复杂度仅取决于基座 LLM 的隐维度 。具体地,计算零空间投影矩阵只需对 做运算,与层数、模型规模或知识库规模无关。
To empirically validate the scalability of our method, we measured the average runtime for performing 100 edits with AlphaEdit and MEMIT on three LLMs with different model sizes and knowledge bases: LLaMA3, GPT-J, and GPT2-XL. The results are summarized in Table 7.
为实证验证方法的可扩展性,我们在三个不同模型规模与知识库的 LLM——LLaMA3、GPT-J 与 GPT2-XL——上测量 AlphaEdit 与 MEMIT 执行 100 次编辑的平均运行时。结果汇总于表 7。
From these results, it is evident that AlphaEdit does not incur additional runtime overhead compared to MEMIT, even as the model size or knowledge base grows. This supports our claim that the null-space projection method is highly scalable and practical for large-scale model editing tasks.
从这些结果可见:即便模型规模或知识库增大,AlphaEdit 相对 MEMIT 也不引入额外运行时开销。这支持我们的主张:零空间投影方法高度可扩展,适用于大规模模型编辑任务。
Appendix D Visualizing the Counterfact and ZSRE Datasets Through Examples
附录 D 通过示例可视化 Counterfact 与 ZSRE 数据集
To help readers unfamiliar with model editing tasks better understand the Counterfact and ZSRE datasets, we provide two examples from them in Figure 12 and 13. These examples illustrate the types of modifications and factual updates applied to the models during the editing process.
为帮助不熟悉模型编辑任务的读者更好理解 Counterfact 与 ZSRE 数据集,我们在图 12 与图 13 中各给出一个示例。这些示例说明编辑过程中对模型施加的修改与事实更新类型。
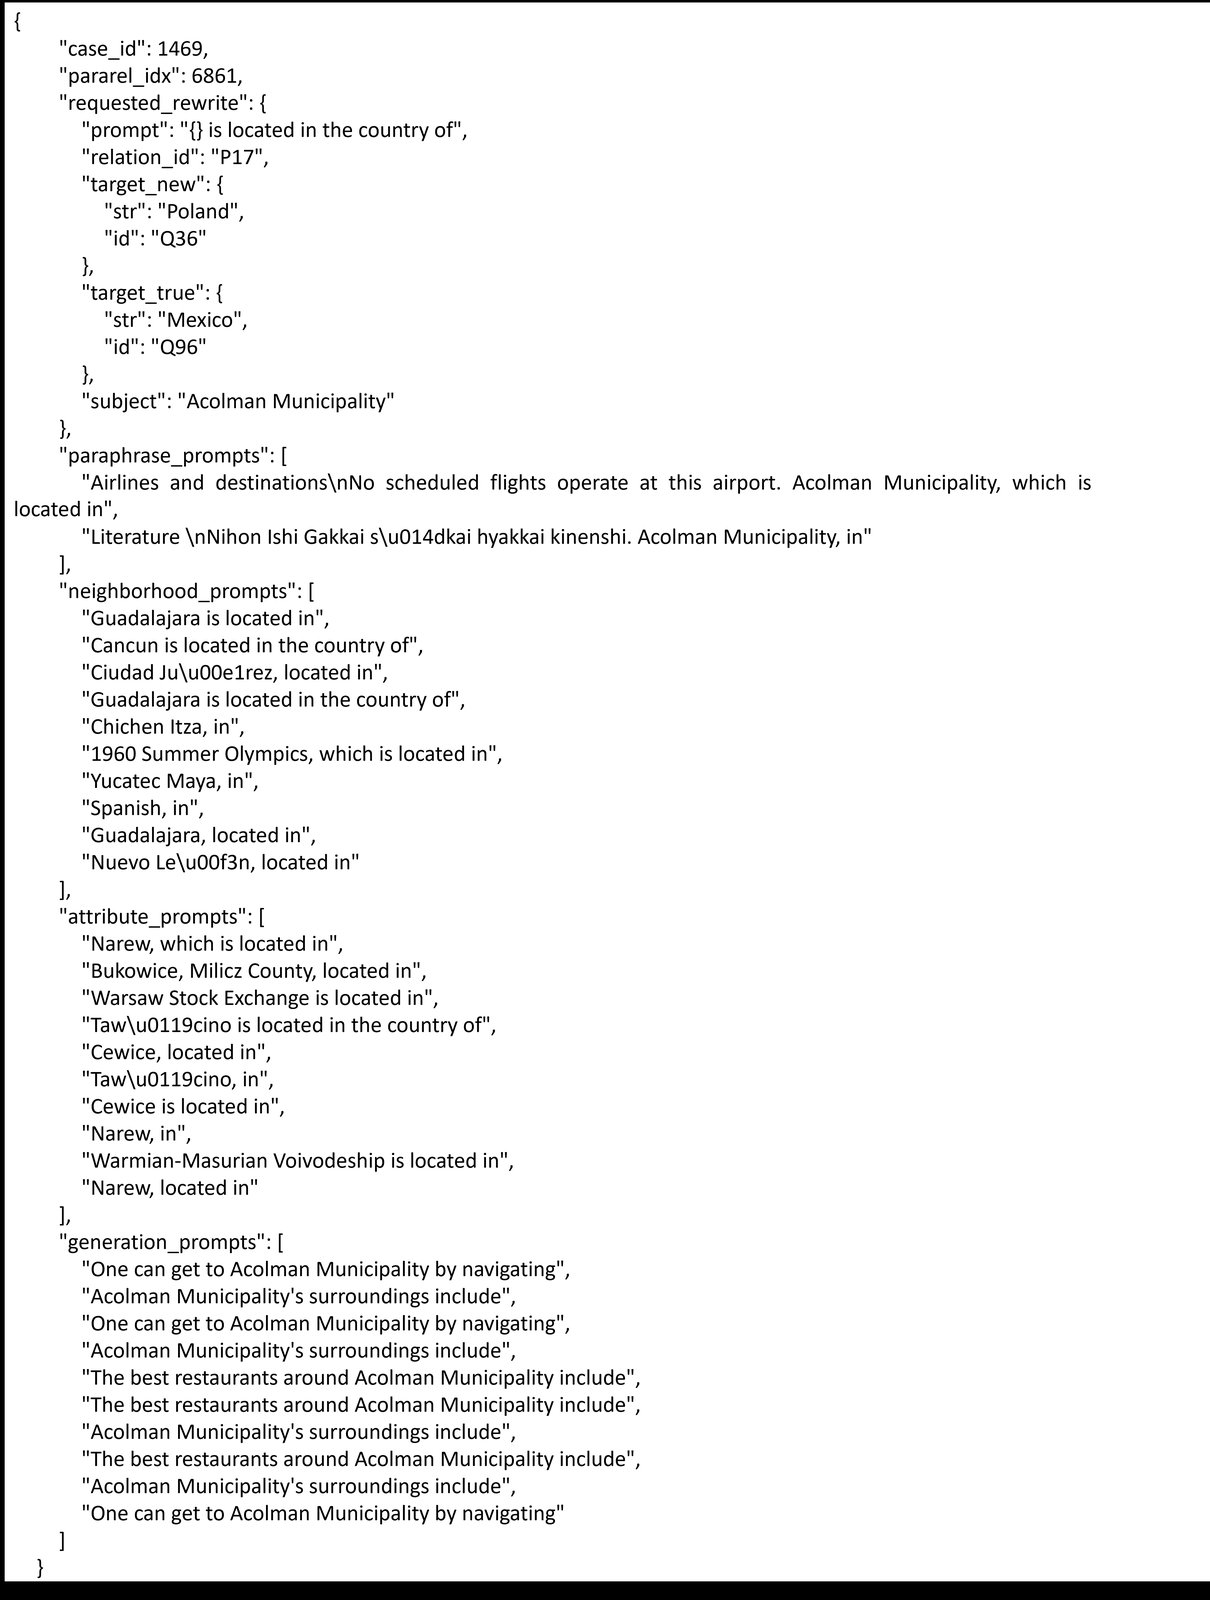
Figure 12: A Sample of the Counterfact dataset.
图 12:Counterfact 数据集的一条样本。
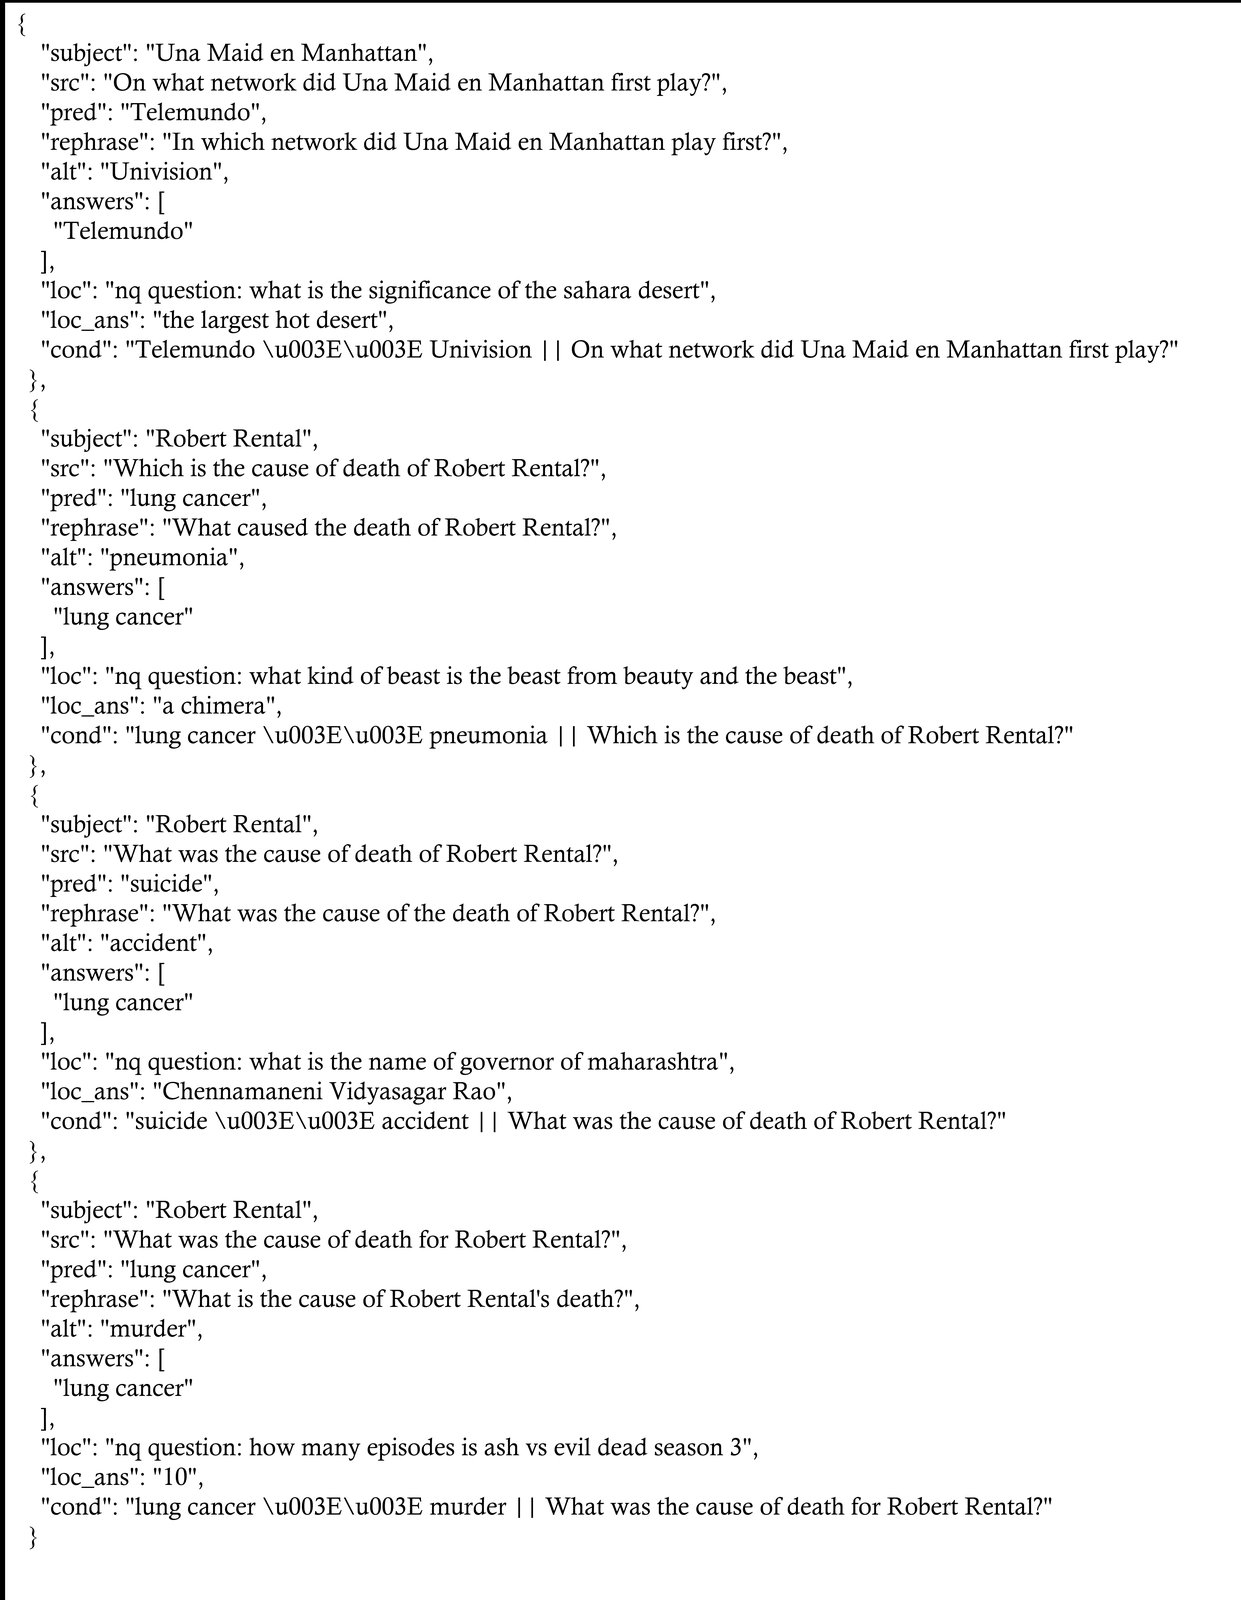
Figure 13: A Samples of the ZsRE dataset.
图 13:ZsRE 数据集的若干样本。