Decoupled Weight Decay Regularization
Decoupled Weight Decay Regularization
解耦的权重衰减正则化
Ilya Loshchilov & Frank Hutter Affiliation: University of Freiburg Affiliation: Freiburg, Germany, Email: {ilya,fh}@cs.uni-freiburg.de
Abstract
摘要
L2 regularization and weight decay regularization are equivalent for standard stochastic gradient descent (when rescaled by the learning rate), but as we demonstrate this is not the case for adaptive gradient algorithms, such as Adam. While common implementations of these algorithms employ L2 regularization (often calling it “weight decay” in what may be misleading due to the inequivalence we expose), we propose a simple modification to recover the original formulation of weight decay regularization by decoupling the weight decay from the optimization steps taken w.r.t. the loss function. We provide empirical evidence that our proposed modification (i) decouples the optimal choice of weight decay factor from the setting of the learning rate for both standard SGD and Adam and (ii) substantially improves Adam’s generalization performance, allowing it to compete with SGD with momentum on image classification datasets (on which it was previously typically outperformed by the latter). Our proposed decoupled weight decay has already been adopted by many researchers, and the community has implemented it in TensorFlow and PyTorch; the complete source code for our experiments is available at https://github.com/loshchil/AdamW-and-SGDW
对标准随机梯度下降而言,L2 正则化与权重衰减正则化是等价的(只需按学习率重新缩放),但我们会说明:对 Adam 这类自适应梯度算法,二者并不等价。这些算法的常见实现采用的是 L2 正则化(还常常把它叫成“权重衰减”,鉴于我们揭示的不等价,这一叫法可能造成误导)。我们提出一个简单修改:把权重衰减从针对损失函数的优化步骤中解耦出来,从而恢复权重衰减正则化的原始形式。实验证据表明,这一修改(i)对标准 SGD 和 Adam 都能把最优权重衰减系数的选择与学习率设置解开;(ii)显著改善 Adam 的泛化,使其能在图像分类数据集上与带动量的 SGD 竞争(过去在这些数据上通常是后者更好)。我们提出的解耦权重衰减已被许多研究者采用,社区也已在 TensorFlow 和 PyTorch 中实现;完整实验源代码见 https://github.com/loshchil/AdamW-and-SGDW
1 Introduction
1 引言
Adaptive gradient methods, such as AdaGrad (Duchi et al. 2011), RMSProp (Tieleman & Hinton 2012), Adam (Kingma & Ba 2014) and most recently AMSGrad (Reddi et al. 2018) have become a default method of choice for training feed-forward and recurrent neural networks (Xu et al. 2015; Radford et al. 2015). Nevertheless, state-of-the-art results for popular image classification datasets, such as CIFAR-10 and CIFAR-100 Krizhevsky 2009, are still obtained by applying SGD with momentum (Gastaldi 2017; Cubuk et al. 2018). Furthermore, Wilson et al. 2017 suggested that adaptive gradient methods do not generalize as well as SGD with momentum when tested on a diverse set of deep learning tasks, such as image classification, character-level language modeling and constituency parsing. Different hypotheses about the origins of this worse generalization have been investigated, such as the presence of sharp local minima (Keskar et al. 2016; Dinh et al. 2017) and inherent problems of adaptive gradient methods (Wilson et al. 2017). In this paper, we investigate whether it is better to use L2 regularization or weight decay regularization to train deep neural networks with SGD and Adam. We show that a major factor of the poor generalization of the most popular adaptive gradient method, Adam, is due to the fact that L2 regularization is not nearly as effective for it as for SGD. Specifically, our analysis of Adam leads to the following observations:
自适应梯度方法,如 AdaGrad(Duchi 等,2011)、RMSProp(Tieleman 与 Hinton,2012)、Adam(Kingma 与 Ba,2014)以及最近的 AMSGrad(Reddi 等,2018),已成为训练前馈和循环神经网络的默认选择(Xu 等,2015;Radford 等,2015)。尽管如此,CIFAR-10 和 CIFAR-100(Krizhevsky,2009)等流行图像分类数据集上的当时最优结果,仍是由带动量的 SGD 得到的(Gastaldi,2017;Cubuk 等,2018)。此外,Wilson 等(2017)指出,在图像分类、字符级语言建模和成分句法分析等多样化深度学习任务上,自适应梯度方法的泛化不如带动量的 SGD。关于这种更差泛化从何而来,已有不同假说,例如尖锐局部极小值的存在(Keskar 等,2016;Dinh 等,2017)以及自适应梯度方法本身的问题(Wilson 等,2017)。本文考察的是:用 SGD 和 Adam 训练深度网络时,用 L2 正则化更好,还是用权重衰减正则化更好。我们表明,最流行的自适应梯度方法 Adam 泛化较差的一个主要因素是:L2 正则化对它远不如对 SGD 有效。具体来说,我们对 Adam 的分析得到以下几点:
L2 regularization and weight decay are not identical. The two techniques can be made equivalent for SGD by a reparameterization of the weight decay factor based on the learning rate; however, as is often overlooked, this is not the case for Adam. In particular, when combined with adaptive gradients, L2 regularization leads to weights with large historic parameter and/or gradient amplitudes being regularized less than they would be when using weight decay.
L2 正则化与权重衰减并不相同。 对 SGD,可以通过按学习率重新参数化权重衰减系数,使二者等价;但这一点常被忽视:对 Adam 并不成立。特别是与自适应梯度结合时,L2 正则化会让历史上参数幅度和/或梯度幅度较大的权重,受到的正则化弱于使用权重衰减时。
L2 regularization is not effective in Adam. One possible explanation why Adam and other adaptive gradient methods might be outperformed by SGD with momentum is that common deep learning libraries only implement L2 regularization, not the original weight decay. Therefore, on tasks/datasets where the use of L2 regularization is beneficial for SGD (e.g., on many popular image classification datasets), Adam leads to worse results than SGD with momentum (for which L2 regularization behaves as expected).
L2 正则化在 Adam 中并不有效。 Adam 和其他自适应梯度方法会被带动量的 SGD 超过,一种可能解释是:常见深度学习库只实现了 L2 正则化,而不是原始的权重衰减。因此,在 L2 正则化对 SGD 有益的任务/数据集上(例如许多流行的图像分类数据集),Adam 的结果会差于带动量的 SGD(对后者,L2 正则化的行为符合预期)。
Weight decay is equally effective in both SGD and Adam. For SGD, it is equivalent to L2 regularization, while for Adam it is not.
权重衰减对 SGD 和 Adam 同样有效。 对 SGD,它与 L2 正则化等价;对 Adam,则不然。
Optimal weight decay depends on the total number of batch passes/weight updates. Our empirical analysis of SGD and Adam suggests that the larger the runtime/number of batch passes to be performed, the smaller the optimal weight decay.
最优权重衰减取决于批次数/权重更新的总数。 我们对 SGD 和 Adam 的经验分析表明:运行时间/批次数越多,最优权重衰减就越小。
Adam can substantially benefit from a scheduled learning rate multiplier. The fact that Adam is an adaptive gradient algorithm and as such adapts the learning rate for each parameter does not rule out the possibility to substantially improve its performance by using a global learning rate multiplier, scheduled, e.g., by cosine annealing.
Adam 能从带调度的学习率乘数中显著受益。 Adam 是自适应梯度算法,会为每个参数调整学习率,但这并不排除用全局学习率乘数(例如按余弦退火调度)大幅改善其表现的可能。
The main contribution of this paper is to improve regularization in Adam by decoupling the weight decay from the gradient-based update. In a comprehensive analysis, we show that Adam generalizes substantially better with decoupled weight decay than with L2 regularization, achieving 15% relative improvement in test error (see Figures 2 and 3); this holds true for various image recognition datasets (CIFAR-10 and ImageNet32x32), training budgets (ranging from 100 to 1800 epochs), and learning rate schedules (fixed, drop-step, and cosine annealing; see Figure 1). We also demonstrate that our decoupled weight decay renders the optimal settings of the learning rate and the weight decay factor much more independent, thereby easing hyperparameter optimization (see Figure 2).
本文的主要贡献是通过把权重衰减从基于梯度的更新中解耦出来,改善 Adam 的正则化。在全面分析中,我们表明:带解耦权重衰减的 Adam 比带 L2 正则化的 Adam 泛化明显更好,测试误差有约 15% 的相对改善(见图 2 和图 3);这一结论对多种图像识别数据集(CIFAR-10 和 ImageNet32x32)、训练预算(从 100 到 1800 个周期)以及学习率调度(固定、阶梯下降和余弦退火;见图 1)都成立。我们还表明,解耦权重衰减使学习率和权重衰减系数的最优设置更加独立,从而减轻超参数优化的负担(见图 2)。
The main motivation of this paper is to improve Adam to make it competitive w.r.t. SGD with momentum even for those problems where it did not use to be competitive. We hope that as a result, practitioners do not need to switch between Adam and SGD anymore, which in turn should reduce the common issue of selecting dataset/task-specific training algorithms and their hyperparameters.
本文的主要动机是改进 Adam,使其即便在过去并不占优的问题上,也能与带动量的 SGD 竞争。我们希望这样一来,实践者不必再在 Adam 与 SGD 之间切换,从而减少按数据集/任务挑选训练算法及其超参数这一常见问题。
2 Decoupling the Weight Decay from the Gradient-based Update
2 把权重衰减从基于梯度的更新中解耦
In the weight decay described by Hanson & Pratt 1988, the weights decay exponentially as
在 Hanson 与 Pratt(1988)描述的权重衰减中,权重 按指数衰减:
where defines the rate of the weight decay per step and is the -th batch gradient to be multiplied by a learning rate . For standard SGD, it is equivalent to standard L2 regularization:
其中 定义每步的权重衰减率, 是第 个批次的梯度,再乘以学习率 。对标准 SGD,这与标准 L2 正则化等价:
Proposition 1(Weight decay = L2 reg for standard SGD).
Standard SGD with base learning rate executes the same steps on batch loss functions with weight decay (defined in Equation 1) as it executes without weight decay on , with .
命题 1(对标准 SGD,权重衰减 = L2 正则化)。
带基础学习率 的标准 SGD,在带权重衰减 的批次损失函数 上执行的步骤(定义见式 1),与它在不带权重衰减、但使用 (其中 )上执行的步骤相同。
The proofs of this well-known fact, as well as our other propositions, are given in Appendix A.
这一熟知事实以及我们其他命题的证明,见附录 A。
Due to this equivalence, L2 regularization is very frequently referred to as weight decay, including in popular deep learning libraries. However, as we will demonstrate later in this section, this equivalence does not hold for adaptive gradient methods. One fact that is often overlooked already for the simple case of SGD is that in order for the equivalence to hold, the L2 regularizer has to be set to , i.e., if there is an overall best weight decay value , the best value of is tightly coupled with the learning rate . In order to decouple the effects of these two hyperparameters, we advocate to decouple the weight decay step as proposed by Hanson & Pratt 1988 (Equation 1).
由于这种等价,L2 正则化常常被直接称为权重衰减,流行的深度学习库也是如此。然而,我们稍后会说明,这种等价对自适应梯度方法并不成立。即便对简单的 SGD,也常被忽视的一点是:要使等价成立,L2 正则系数 必须设为 ,也就是说,如果存在一个总体上最好的权重衰减值 ,那么最好的 与学习率 是紧密耦合的。为了解开这两个超参数的效果,我们主张按 Hanson 与 Pratt(1988)的提议(式 1)把权重衰减步骤解耦出来。
1: given initial learning rate , momentum factor , weight decay/L2 regularization factor
2: initialize time step , parameter vector , first moment vector , schedule multiplier
3: repeat
4:
5: select batch and return the corresponding gradient
6:
7: can be fixed, decay, be used for warm restarts
8:
9:
10: until stopping criterion is met
11: return optimized parameters
Algorithm 1 SGD with L2 regularization and SGD with decoupled weight decay (SGDW), both with momentum
1: 给定 初始学习率 ,动量因子 ,权重衰减/L2 正则化系数
2: 初始化 时间步 ,参数向量 ,一阶矩向量 ,调度乘数
3: 重复
4:
5: 选取批次并返回对应梯度
6:
7: 可以固定、衰减,也可用于热重启
8:
9:
10: 直到 满足停止条件
11: 返回 优化后的参数
算法 1 带 L2 正则化的 SGD,以及带解耦权重衰减的 SGD(SGDW),二者都带动量
1: given
2: initialize time step , parameter vector , first moment vector , second moment vector , schedule multiplier
3: repeat
4:
5: select batch and return the corresponding gradient
6:
7: here and below all operations are element-wise
8:
9: is taken to the power of
10: is taken to the power of
11: can be fixed, decay, or also be used for warm restarts
12: \bm{\theta}_{t}\leftarrow\bm{\theta}_{t-1}-\eta_{t}\left(\alpha\hat{\textit{{m}}}_{t}/(\sqrt{\hat{\textit{{v}}}_{t}}+\epsilon)\hbox{\pagecolor{SpringGreen}\displaystyle+\lambda\bm{\theta}{t-1}}\right)
13: until stopping criterion is met
14: return optimized parameters $\bm{\theta}{t}$
Algorithm 2 Adam with L2 regularization and Adam with decoupled weight decay (AdamW)
1: 给定
2: 初始化 时间步 ,参数向量 ,一阶矩向量 ,二阶矩向量 ,调度乘数
3: 重复
4:
5: 选取批次并返回对应梯度
6:
7: 此处及以下运算均为逐元素
8:
9: 取 次方
10: 取 次方
11: 可以固定、衰减,也可用于热重启
12: \bm{\theta}_{t}\leftarrow\bm{\theta}_{t-1}-\eta_{t}\left(\alpha\hat{\textit{{m}}}_{t}/(\sqrt{\hat{\textit{{v}}}_{t}}+\epsilon)\hbox{\pagecolor{SpringGreen}\displaystyle+\lambda\bm{\theta}{t-1}}\right)
13: 直到 满足停止条件
14: 返回 优化后的参数 $\bm{\theta}{t}$
算法 2 带 L2 正则化的 Adam,以及带解耦权重衰减的 Adam(AdamW)
Looking first at the case of SGD, we propose to decay the weights simultaneously with the update of based on gradient information in Line 9 of Algorithm 1. This yields our proposed variant of SGD with momentum using decoupled weight decay (SGDW). This simple modification explicitly decouples and (although some problem-dependent implicit coupling may of course remain as for any two hyperparameters). In order to account for a possible scheduling of both and , we introduce a scaling factor delivered by a user-defined procedure .
先看 SGD 的情形:我们提议在算法 1 第 9 行根据梯度信息更新 的同时衰减权重。这就得到我们提出的、带解耦权重衰减的带动量 SGD 变体(SGDW)。这一简单修改显式地把 与 解开(当然,与任何两个超参数一样,仍可能残留一些与问题相关的隐式耦合)。为了兼顾 和 可能的调度,我们引入由用户定义过程 给出的缩放因子 。
Now, let’s turn to adaptive gradient algorithms like the popular optimizer Adam Kingma & Ba 2014, which scale gradients by their historic magnitudes. Intuitively, when Adam is run on a loss function plus L2 regularization, weights that tend to have large gradients in do not get regularized as much as they would with decoupled weight decay, since the gradient of the regularizer gets scaled along with the gradient of . This leads to an inequivalence of L2 and decoupled weight decay regularization for adaptive gradient algorithms:
现在转向 Adam(Kingma 与 Ba,2014)这类按历史幅度缩放梯度的自适应梯度算法。直观上,当 Adam 跑在损失函数 加上 L2 正则化时,在 中往往具有大梯度的权重,受到的正则化会弱于解耦权重衰减,因为正则项的梯度会和 的梯度一起被缩放。于是对自适应梯度算法,L2 与解耦权重衰减正则化不再等价:
Proposition 2(Weight decay L2 reg for adaptive gradients).
Let denote an optimizer that has iterates when run on batch loss function without weight decay, and when run on with weight decay, respectively, with (where ). Then, for there exists no L2 coefficient such that running on batch loss without weight decay is equivalent to running on with decay .
命题 2(对自适应梯度,权重衰减 L2 正则化)。
设 表示这样一种优化器:在不带权重衰减的批次损失 上,迭代为 ;在带权重衰减的 上,迭代为 ,其中 ()。那么对 而言,不存在 L2 系数 ,使得在不带权重衰减的批次损失 上运行 ,等价于在带衰减 的 上运行 。
We decouple weight decay and loss-based gradient updates in Adam as shown in line 12 of Algorithm 2; this gives rise to our variant of Adam with decoupled weight decay (AdamW).
我们按算法 2 第 12 行把权重衰减与基于损失的梯度更新在 Adam 中解耦;这就得到带解耦权重衰减的 Adam 变体(AdamW)。
Having shown that L2 regularization and weight decay regularization differ for adaptive gradient algorithms raises the question of how they differ and how to interpret their effects. Their equivalence for standard SGD remains very helpful for intuition: both mechanisms push weights closer to zero, at the same rate. However, for adaptive gradient algorithms they differ: with L2 regularization, the sums of the gradient of the loss function and the gradient of the regularizer (i.e., the L2 norm of the weights) are adapted, whereas with decoupled weight decay, only the gradients of the loss function are adapted (with the weight decay step separated from the adaptive gradient mechanism). With L2 regularization both types of gradients are normalized by their typical (summed) magnitudes, and therefore weights with large typical gradient magnitude are regularized by a smaller relative amount than other weights. In contrast, decoupled weight decay regularizes all weights with the same rate , effectively regularizing weights with large more than standard L2 regularization does. We demonstrate this formally for a simple special case of adaptive gradient algorithm with a fixed preconditioner:
既然已经表明对自适应梯度算法,L2 正则化与权重衰减正则化不同,接下来的问题是:它们如何不同,又该如何理解各自的效果。二者在标准 SGD 上的等价关系仍然有助于建立直觉:两种机制都以相同速率把权重推向零。但对自适应梯度算法,它们不一样:使用 L2 正则化时,损失函数梯度与正则项梯度(也就是权重的 L2 范数)之和会被自适应缩放;使用解耦权重衰减时,只有损失函数的梯度被自适应缩放(权重衰减步骤与自适应梯度机制分开)。使用 L2 正则化时,两类梯度都会按各自典型(累加)幅度归一化,因此典型梯度幅度 较大的权重 相对其他权重被正则化得更少。相反,解耦权重衰减对所有权重使用同一速率 ,从而对 较大的权重 的正则化比标准 L2 正则化更强。我们对带固定预条件子的自适应梯度算法这一简单特例给出形式说明:
Proposition 3(Weight decay = scale-adjusted reg for adaptive gradient algorithm with fixed preconditioner).
Let denote an algorithm with the same characteristics as in Proposition 2, and using a fixed preconditioner matrix (with for all ). Then, with base learning rate executes the same steps on batch loss functions with weight decay as it executes without weight decay on the scale-adjusted regularized batch loss
命题 3(对带固定预条件子的自适应梯度算法,权重衰减 = 按尺度调整的 正则化)。
设 表示与命题 2 具有相同特征的算法,并使用固定预条件矩阵 (对所有 有 )。那么,带基础学习率 的 在带权重衰减 的批次损失 上执行的步骤,与它在不带权重衰减、但使用按下式按尺度调整后的正则化批次损失上执行的步骤相同
where and denote element-wise multiplication and square root, respectively, and .
其中 与 分别表示逐元素乘法和开方,且 。
We note that this proposition does not directly apply to practical adaptive gradient algorithms, since these change the preconditioner matrix at every step. Nevertheless, it can still provide intuition about the equivalent loss function being optimized in each step: parameters with a large inverse preconditioner (which in practice would be caused by historically large gradients in dimension ) are regularized relatively more than they would be with L2 regularization; specifically, the regularization is proportional to .
我们指出,这一命题并不直接适用于实际的自适应梯度算法,因为它们每一步都会改变预条件矩阵。尽管如此,它仍能提供关于每一步所优化的等价损失函数的直觉:逆预条件 较大的参数 (实践中这通常来自第 维历史上较大的梯度)会比使用 L2 正则化时受到相对更强的正则化;具体来说,正则化强度与 成正比。
3 Justification of Decoupled Weight Decay via a View of Adaptive Gradient Methods as Bayesian Filtering
3 从把自适应梯度方法视为贝叶斯滤波的角度为解耦权重衰减辩护
We now discuss a justification of decoupled weight decay in the framework of Bayesian filtering for a unified theory of adaptive gradient algorithms due to Aitchison 2018. After we posted a preliminary version of our current paper on arXiv, Aitchison noted that his theory “gives us a theoretical framework in which we can understand the superiority of this weight decay over regularization, because it is weight decay, rather than regularization that emerges through the straightforward application of Bayesian filtering.”(Aitchison 2018). While full credit for this theory goes to Aitchison, we summarize it here to shed some light on why weight decay may be favored over regularization.
我们接下来在 Aitchison(2018)提出的、用以统一解释自适应梯度算法的贝叶斯滤波框架里,讨论解耦权重衰减的理由。我们在 arXiv 上发布本文初稿之后,Aitchison 指出他的理论“为我们提供了一个理论框架来理解这种权重衰减优于 正则化的原因,因为通过直接应用贝叶斯滤波得到的是权重衰减,而不是 正则化。”(Aitchison,2018)。该理论的全部功劳归于 Aitchison,我们在此只做概述,以便说明为何权重衰减可能比 正则化更受青睐。
Aitchison 2018 views stochastic optimization of parameters as a Bayesian filtering problem with the goal of inferring a distribution over the optimal values of each of the parameters given the current values of the other parameters at time step . When the other parameters do not change this is an optimization problem, but when they do change it becomes one of “tracking” the optimizer using Bayesian filtering as follows. One is given a probability distribution of the optimizer at time step that takes into account the data from the first mini batches, a state transition prior reflecting a (small) data-independent change in this distribution from one step to the next, and a likelihood derived from the mini batch at step . The posterior distribution of the optimizer at time step can then be computed (as usual in Bayesian filtering) by marginalizing over to obtain the one-step ahead predictions and then applying Bayes’ rule to incorporate the likelihood . Aitchison 2018 assumes a Gaussian state transition distribution and an approximate conjugate likelihood , leading to the following closed-form update of the filtering distribution’s mean:
Aitchison(2018)把 个参数 的随机优化看成贝叶斯滤波问题,目标是在给定其余参数在时间步 的当前值 时,推断每个参数 最优值的分布。当其余参数不变时,这是优化问题;当它们变化时,就变成用贝叶斯滤波“跟踪”优化器,做法如下。给定考虑了前 个小批次数据 的时间步 优化器概率分布 ,反映该分布从一步到下一步发生(较小的)与数据无关变化的状态转移先验 ,以及由第 步小批次导出的似然 。时间步 的后验 便可按贝叶斯滤波的通常方式计算:先对 边缘化得到一步预测 ,再用贝叶斯法则纳入似然 。Aitchison(2018)假设高斯状态转移分布 以及近似共轭的似然 ,从而得到滤波分布均值的如下闭式更新:
where is the gradient of the log likelihood of the mini batch at time . This result implies a preconditioner of the gradients that is given by the posterior uncertainty of the filtering distribution: updates are larger for parameters we are more uncertain about and smaller for parameters we are more certain about. Aitchison 2018 goes on to show that popular adaptive gradient methods, such as Adam and RMSprop, as well as Kronecker-factorized methods are special cases of this framework.
其中 是时间 小批次对数似然的梯度。这一结果意味着梯度的预条件子由滤波分布的后验不确定性 给出:我们对之更不确定的参数更新更大,对之更确定的参数更新更小。Aitchison(2018)接着表明,Adam 和 RMSprop 等流行自适应梯度方法,以及 Kronecker 分解方法,都是该框架的特例。
Decoupled weight decay very naturally fits into this unified framework as part of the state-transition distribution: Aitchison 2018 assumes a slow change of the optimizer according to the following Gaussian:
解耦权重衰减非常自然地作为状态转移分布的一部分进入这一统一框架:Aitchison(2018)假设优化器按如下高斯缓慢变化:
where is the covariance of Gaussian perturbations of the weights, and is a regularizer to avoid values growing unboundedly over time. When instantiated as , this regularizer plays exactly the role of decoupled weight decay as described in Equation 1, since this leads to multiplying the current mean estimate by at each step. Notably, this regularization is also directly applied to the prior and does not depend on the uncertainty in each of the parameters (which would be required for regularization).
其中 是权重高斯扰动的协方差, 是避免数值随时间无限增长的正则项。当取 时,正则项 恰好扮演式 1 中描述的解耦权重衰减的角色,因为这会在每一步把当前均值估计 乘以 。值得注意的是,这一正则化也直接作用于先验,并不依赖于各个参数的不确定性(而 正则化会要求这一点)。
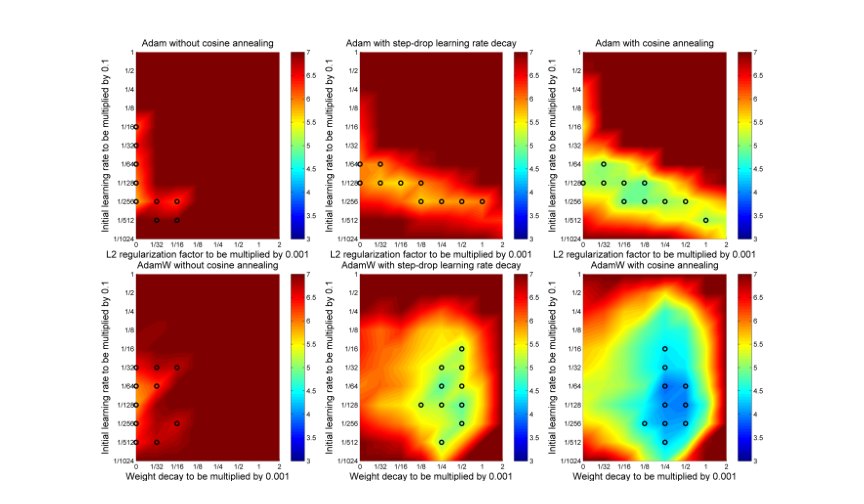
Figure 1: Adam performs better with decoupled weight decay (bottom row, AdamW) than with regularization (top row, Adam). We show the final test error of a 26 2x64d ResNet on CIFAR-10 after 100 epochs of training with fixed learning rate (left column), step-drop learning rate (with drops at epoch indexes 30, 60 and 80, middle column) and cosine annealing (right column). AdamW leads to a more separable hyperparameter search space, especially when a learning rate schedule, such as step-drop and cosine annealing is applied. Cosine annealing yields clearly superior results.
图 1:Adam 使用解耦权重衰减(底行,AdamW)比使用 正则化(顶行,Adam)表现更好。我们展示 26 层 2x64d ResNet 在 CIFAR-10 上训练 100 个周期后的最终测试误差,分别使用固定学习率(左列)、阶梯下降学习率(在第 30、60 和 80 个周期下降,中列)以及余弦退火(右列)。AdamW 使超参数搜索空间更易分离,尤其是在使用阶梯下降和余弦退火这类学习率调度时。余弦退火给出明显更好的结果。
4 Experimental Validation
4 实验验证
We now evaluate the performance of decoupled weight decay under various training budgets and learning rate schedules. Our experimental setup follows that of Gastaldi 2017, who proposed, in addition to L2 regularization, to apply the new Shake-Shake regularization to a 3-branch residual DNN that allowed to achieve new state-of-the-art results of 2.86% on the CIFAR-10 dataset (Krizhevsky 2009). We used the same model/source code based on fb.resnet.torch [^1]. We always used a batch size of 128 and applied the regular data augmentation procedure for the CIFAR datasets. The base networks are a 26 2x64d ResNet (i.e. the network has a depth of 26, 2 residual branches and the first residual block has a width of 64) and a 26 2x96d ResNet with 11.6M and 25.6M parameters, respectively. For a detailed description of the network and the Shake-Shake method, we refer the interested reader to Gastaldi 2017. We also perform experiments on the ImageNet32x32 dataset (Chrabaszcz et al. 2017), a downsampled version of the original ImageNet dataset with 1.2 million 3232 pixels images.
我们现在在多种训练预算和学习率调度下评估解耦权重衰减的表现。实验设置沿用 Gastaldi(2017):他在 L2 正则化之外,还对三分支残差深度网络使用新的 Shake-Shake 正则化,在 CIFAR-10 数据集(Krizhevsky,2009)上取得了当时最优的 2.86%。我们使用基于 fb.resnet.torch 的同一模型/源代码[^1]。批次大小始终为 128,并采用 CIFAR 数据集常规的数据增强。基础网络是 26 层 2x64d ResNet(即深度为 26、2 条残差分支、第一个残差块宽度为 64)以及 26 层 2x96d ResNet,参数量分别为 1160 万和 2560 万。关于网络和 Shake-Shake 方法的详细描述,请参阅 Gastaldi(2017)。我们还在 ImageNet32x32 数据集(Chrabaszcz 等,2017)上做了实验,这是原始 ImageNet 的下采样版本,包含 120 万张 像素图像。
4.1 Evaluating Decoupled Weight Decay With Different Learning Rate Schedules
4.1 在不同学习率调度下评估解耦权重衰减
In our first experiment, we compare Adam with regularization to Adam with decoupled weight decay (AdamW), using three different learning rate schedules: a fixed learning rate, a drop-step schedule, and a cosine annealing schedule (Loshchilov & Hutter 2016). Since Adam already adapts its parameterwise learning rates it is not as common to use a learning rate multiplier schedule with it as it is with SGD, but as our results show such schedules can substantially improve Adam’s performance, and we advocate not to overlook their use for adaptive gradient algorithms.
第一个实验中,我们把带 正则化的 Adam 与带解耦权重衰减的 Adam(AdamW)比较,使用三种学习率调度:固定学习率、阶梯下降调度,以及余弦退火调度(Loshchilov 与 Hutter,2016)。由于 Adam 已经在逐参数地适应学习率,给它再加全局学习率乘数调度不像对 SGD 那么常见;但我们的结果表明,这类调度能显著改善 Adam 的表现,我们也主张不要忽视它们在自适应梯度算法中的使用。
For each learning rate schedule and weight decay variant, we trained a 2x64d ResNet for 100 epochs, using different settings of the initial learning rate and the weight decay factor . Figure 1 shows that decoupled weight decay outperforms regularization for all learning rate schedules, with larger differences for better learning rate schedules. We also note that decoupled weight decay leads to a more separable hyperparameter search space, especially when a learning rate schedule, such as step-drop and cosine annealing is applied. The figure also shows that cosine annealing clearly outperforms the other learning rate schedules; we thus used cosine annealing for the remainder of the experiments.
对每种学习率调度和权重衰减变体,我们训练 2x64d ResNet 共 100 个周期,并尝试不同的初始学习率 和权重衰减系数 。图 1 表明,解耦权重衰减在所有学习率调度上都优于 正则化,而且更好的学习率调度对应更大的差距。我们还注意到,解耦权重衰减使超参数搜索空间更易分离,尤其是在使用阶梯下降和余弦退火这类调度时。图中也显示余弦退火明显优于其他学习率调度;因此后续实验都使用余弦退火。
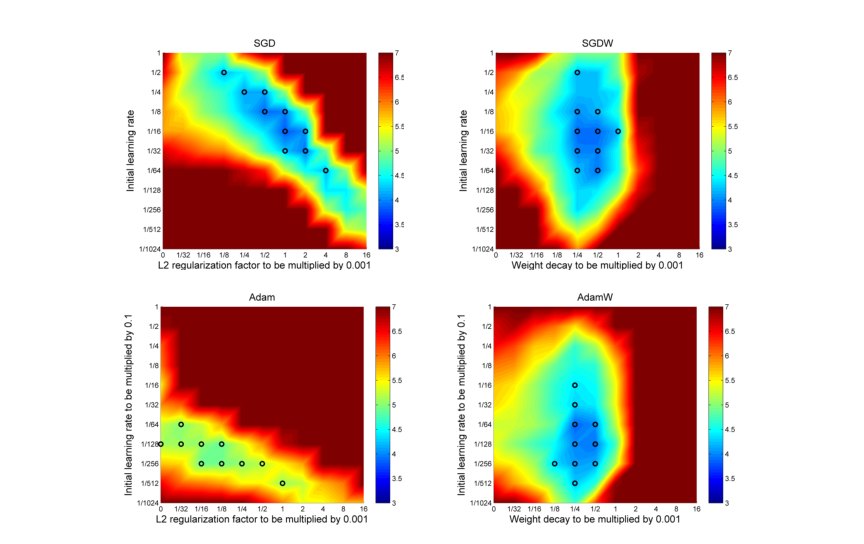
Figure 2: The Top-1 test error of a 26 2x64d ResNet on CIFAR-10 measured after 100 epochs. The proposed SGDW and AdamW (right column) have a more separable hyperparameter space.
图 2:26 层 2x64d ResNet 在 CIFAR-10 上训练 100 个周期后的 Top-1 测试误差。提出的 SGDW 和 AdamW(右列)具有更易分离的超参数空间。
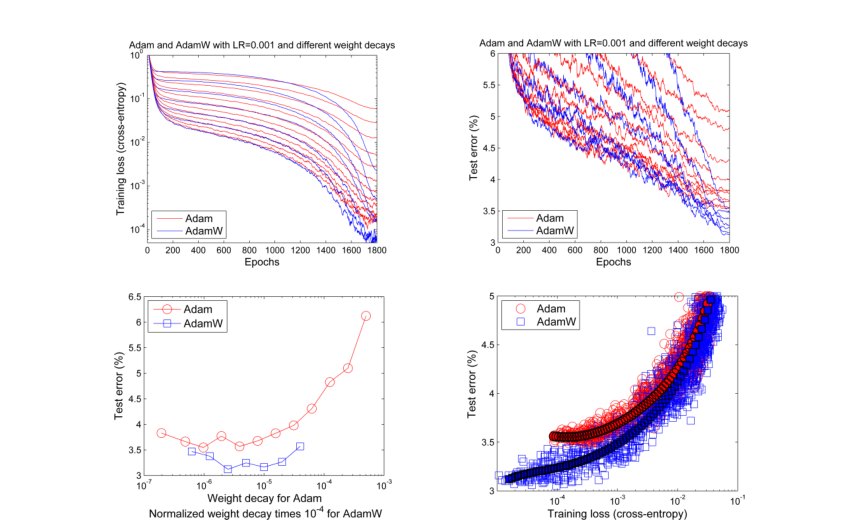
Figure 3: Learning curves (top row) and generalization results (bottom row) obtained by a 26 2x96d ResNet trained with Adam and AdamW on CIFAR-10. See text for details. SuppFigure 4 in the Appendix shows the same qualitative results for ImageNet32x32.
图 3:用 Adam 和 AdamW 在 CIFAR-10 上训练 26 层 2x96d ResNet 得到的学习曲线(顶行)和泛化结果(底行)。细节见正文。附录中的补充图 4 给出了 ImageNet32x32 上相同的定性结果。
4.2 Decoupling the Weight Decay and Initial Learning Rate Parameters
4.2 把权重衰减与初始学习率参数解耦
In order to verify our hypothesis about the coupling of and , in Figure 2 we compare the performance of L2 regularization vs. decoupled weight decay in SGD (SGD vs. SGDW, top row) and in Adam (Adam vs. AdamW, bottom row). In SGD (Figure 2, top left), L2 regularization is not decoupled from the learning rate (the common way as described in Algorithm 1), and the figure clearly shows that the basin of best hyperparameter settings (depicted by color and top-10 hyperparameter settings by black circles) is not aligned with the x-axis or y-axis but lies on the diagonal. This suggests that the two hyperparameters are interdependent and need to be changed simultaneously, while only changing one of them might substantially worsen results. Consider, e.g., the setting at the top left black circle (, ); only changing either or by itself would worsen results, while changing both of them could still yield clear improvements. We note that this coupling of initial learning rate and L2 regularization factor might have contributed to SGD’s reputation of being very sensitive to its hyperparameter settings.
为了验证我们关于 与 耦合的假说,图 2 比较了 L2 正则化与解耦权重衰减在 SGD(SGD 对 SGDW,顶行)和 Adam(Adam 对 AdamW,底行)中的表现。在 SGD 中(图 2,左上),L2 正则化没有与学习率解耦(即算法 1 所描述的常见做法),图中清楚地显示最优超参数盆地(用颜色表示,前 10 组超参数用黑圈标出)并不沿 轴或 轴对齐,而是落在对角线上。这说明这两个超参数相互依赖,需要同时改动;只改其中一个可能会显著变差。例如考虑左上黑圈的设置(,):只改 或只改 都会变差,而同时改两者仍可能带来明显改善。我们指出,初始学习率与 L2 正则化系数的这种耦合,可能部分造就了 SGD 对超参数设置非常敏感的名声。
In contrast, the results for SGD with decoupled weight decay (SGDW) in Figure 2 (top right) show that weight decay and initial learning rate are decoupled. The proposed approach renders the two hyperparameters more separable: even if the learning rate is not well tuned yet (e.g., consider the value of 1/1024 in Figure 2, top right), leaving it fixed and only optimizing the weight decay factor would yield a good value (of 1/4*0.001). This is not the case for SGD with L2 regularization (see Figure 2, top left).
相反,图 2(右上)中带解耦权重衰减的 SGD(SGDW)结果显示,权重衰减与初始学习率已经解开。提出的方法使这两个超参数更可分离:即便学习率尚未调好(例如图 2 右上中取 ),把它固定、只优化权重衰减系数也能得到一个不错的值()。带 L2 正则化的 SGD 并非如此(见图 2 左上)。
The results for Adam with L2 regularization are given in Figure 2 (bottom left). Adam’s best hyperparameter settings performed clearly worse than SGD’s best ones (compare Figure 2, top left). While both methods used L2 regularization, Adam did not benefit from it at all: its best results obtained for non-zero L2 regularization factors were comparable to the best ones obtained without the L2 regularization, i.e., when . Similarly to the original SGD, the shape of the hyperparameter landscape suggests that the two hyperparameters are coupled.
带 L2 正则化的 Adam 结果见图 2(左下)。Adam 的最佳超参数设置明显差于 SGD 的最佳设置(比较图 2 左上)。尽管两种方法都用了 L2 正则化,Adam 完全没有从中受益:非零 L2 系数得到的最好结果,与完全不用 L2 正则化(即 )时的最好结果相当。与原始 SGD 类似,超参数景观的形状表明这两个超参数是耦合的。
In contrast, the results for our new variant of Adam with decoupled weight decay (AdamW) in Figure 2 (bottom right) show that AdamW largely decouples weight decay and learning rate. The results for the best hyperparameter settings were substantially better than the best ones of Adam with L2 regularization and rivaled those of SGD and SGDW.
相反,图 2(右下)中我们提出的带解耦权重衰减的 Adam 新变体(AdamW)表明,AdamW 在很大程度上把权重衰减与学习率解开了。最佳超参数设置的结果明显好于带 L2 正则化的 Adam 的最佳结果,并足以与 SGD 和 SGDW 竞争。
In summary, the results in Figure 2 support our hypothesis that the weight decay and learning rate hyperparameters can be decoupled, and that this in turn simplifies the problem of hyperparameter tuning in SGD and improves Adam’s performance to be competitive w.r.t. SGD with momentum.
总之,图 2 的结果支持我们的假说:权重衰减与学习率这两个超参数可以解开;这反过来简化了 SGD 的超参数调节,也使 Adam 的表现能够与带动量的 SGD 竞争。
4.3 Better Generalization of AdamW
4.3 AdamW 更好的泛化
While the previous experiment suggested that the basin of optimal hyperparameters of AdamW is broader and deeper than the one of Adam, we next investigated the results for much longer runs of 1800 epochs to compare the generalization capabilities of AdamW and Adam.
上一实验表明 AdamW 的最优超参数盆地比 Adam 更宽也更深。接下来我们考察长得多的 1800 个周期的运行,以比较 AdamW 与 Adam 的泛化能力。
We fixed the initial learning rate to 0.001 which represents both the default learning rate for Adam and the one which showed reasonably good results in our experiments. Figure 3 shows the results for 12 settings of the L2 regularization of Adam and 7 settings of the normalized weight decay of AdamW (the normalized weight decay represents a rescaling formally defined in Appendix B.1; it amounts to a multiplicative factor which depends on the number of batch passes). Interestingly, while the dynamics of the learning curves of Adam and AdamW often coincided for the first half of the training run, AdamW often led to lower training loss and test errors (see Figure 3 top left and top right, respectively). Importantly, the use of L2 weight decay in Adam did not yield as good results as decoupled weight decay in AdamW (see also Figure 3, bottom left). Next, we investigated whether AdamW’s better results were only due to better convergence or due to better generalization. The results in Figure 3 (bottom right) for the best settings of Adam and AdamW suggest that AdamW did not only yield better training loss but also yielded better generalization performance for similar training loss values. The results on ImageNet32x32 (see SuppFigure 4 in the Appendix) yield the same conclusion of substantially improved generalization performance.
我们把初始学习率固定为 0.001,这既是 Adam 的默认学习率,也是在我们实验中表现相当不错的取值。图 3 给出了 Adam 的 12 组 L2 正则化设置,以及 AdamW 的 7 组归一化权重衰减设置(归一化权重衰减是附录 B.1 中形式定义的一种重缩放,相当于一个依赖于批次数的乘法因子)。有意思的是,尽管 Adam 与 AdamW 的学习曲线动态在训练前半段常常重合,AdamW 往往能得到更低的训练损失和测试误差(分别见图 3 左上和右上)。重要的是,Adam 中使用 L2 权重衰减得到的结果,不如 AdamW 中的解耦权重衰减(也见图 3 左下)。接下来我们考察 AdamW 更好的结果仅仅来自更好的收敛,还是来自更好的泛化。图 3(右下)中 Adam 与 AdamW 最佳设置的结果表明,AdamW 不仅训练损失更好,在相近的训练损失取值下泛化也更好。ImageNet32x32 上的结果(见附录补充图 4)得出同样的结论:泛化有实质改善。
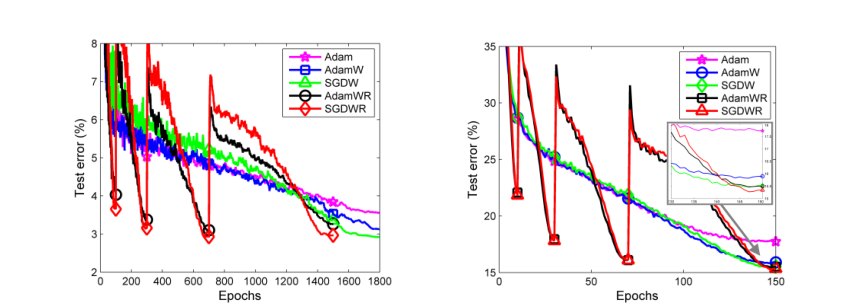
Figure 4: Top-1 test error on CIFAR-10 (left) and Top-5 test error on ImageNet32x32 (right). For a better resolution and with training loss curves, see SuppFigure 5 and SuppFigure 6 in the supplementary material.
图 4:CIFAR-10 上的 Top-1 测试误差(左)和 ImageNet32x32 上的 Top-5 测试误差(右)。更高分辨率并带训练损失曲线的版本,见补充材料中的补充图 5 和补充图 6。
4.4 AdamWR with Warm Restarts for Better Anytime Performance
4.4 带热重启的 AdamWR 以获得更好的任意时刻表现
In order to improve the anytime performance of SGDW and AdamW we extended them with the warm restarts we introduced in Loshchilov & Hutter 2016, to obtain SGDWR and AdamWR, respectively (see Section B.2 in the Appendix). As Figure 4 shows, AdamWR greatly sped up AdamW on CIFAR-10 and ImageNet32x32, up to a factor of 10 (see the results at the first restart). For the default learning rate of 0.001, AdamW achieved 15% relative improvement in test error compared to Adam both on CIFAR-10 (also see SuppFigure 5) and ImageNet32x32 (also see SuppFigure 6).
为了改善 SGDW 和 AdamW 的任意时刻表现,我们把在 Loshchilov 与 Hutter(2016)中引入的热重启扩展到二者上,分别得到 SGDWR 和 AdamWR(见附录 B.2 节)。如图 4 所示,AdamWR 在 CIFAR-10 和 ImageNet32x32 上大幅加快了 AdamW,最高可达约 10 倍(见第一次重启时的结果)。对默认学习率 0.001,AdamW 相对 Adam 在 CIFAR-10(也见补充图 5)和 ImageNet32x32(也见补充图 6)上都取得了约 15% 的测试误差相对改善。
AdamWR achieved the same improved results but with a much better anytime performance. These improvements closed most of the gap between Adam and SGDWR on CIFAR-10 and yielded comparable performance on ImageNet32x32.
AdamWR 达到了同样改善的最终结果,但任意时刻表现好得多。 这些改善弥合了 CIFAR-10 上 Adam 与 SGDWR 之间的大部分差距,并在 ImageNet32x32 上达到相当的表现。
4.5 Use of AdamW on other datasets and architectures
4.5 AdamW 在其他数据集和架构上的使用
Several other research groups have already successfully applied AdamW in citable works. For example, Wang et al. 2018 used AdamW to train a novel architecture for face detection on the standard WIDER FACE dataset (Yang et al. 2016), obtaining almost 10x faster predictions than the previous state of the art algorithms while achieving comparable performance. Völker et al. 2018 employed AdamW with cosine annealing to train convolutional neural networks to classify and characterize error-related brain signals measured from intracranial electroencephalography (EEG) recordings. While their paper does not provide a comparison to Adam, they kindly provided us with a direct comparison of the two on their best-performing problem-specific network architecture Deep4Net and a variant of ResNet. AdamW with the same hyperparameter setting as Adam yielded higher test set accuracy on Deep4Net (73.68% versus 71.37%) and statistically significantly higher test set accuracy on ResNet (72.04% versus 61.34%). Radford et al. 2018 employed AdamW to train Transformer (Vaswani et al. 2017) architectures to obtain new state-of-the-art results on a wide range of benchmarks for natural language understanding. Zhang et al. 2018 compared L2 regularization vs. weight decay for SGD, Adam and the Kronecker-Factored Approximate Curvature (K-FAC) optimizer (Martens & Grosse 2015) on the CIFAR datasets with ResNet and VGG architectures, reporting that decoupled weight decay consistently outperformed L2 regularization in cases where they differ.
已有多个研究组在可引用的工作中成功使用了 AdamW。例如,Wang 等(2018)用 AdamW 在标准 WIDER FACE 数据集(Yang 等,2016)上训练一种新的人脸检测架构,预测速度比此前的最优算法快近 10 倍,同时表现相当。Völker 等(2018)用带余弦退火的 AdamW 训练卷积神经网络,对颅内脑电图(EEG)记录中的错误相关脑信号进行分类和刻画。他们的论文没有提供与 Adam 的比较,但他们向我们提供了二者在其表现最好的专用网络架构 Deep4Net 以及一种 ResNet 变体上的直接比较。使用与 Adam 相同超参数的 AdamW,在 Deep4Net 上测试集准确率更高(73.68% 对 71.37%),在 ResNet 上测试集准确率有统计显著提高(72.04% 对 61.34%)。Radford 等(2018)用 AdamW 训练 Transformer(Vaswani 等,2017)架构,在一系列自然语言理解基准上取得了当时最优结果。Zhang 等(2018)在 CIFAR 数据集上用 ResNet 和 VGG 架构,比较了 SGD、Adam 以及 Kronecker 分解近似曲率(K-FAC)优化器(Martens 与 Grosse,2015)的 L2 正则化与权重衰减,报告称在二者不同的情形下,解耦权重衰减始终优于 L2 正则化。
5 Conclusion and Future Work
5 结论与未来工作
Following suggestions that adaptive gradient methods such as Adam might lead to worse generalization than SGD with momentum (Wilson et al. 2017), we identified and exposed the inequivalence of L2 regularization and weight decay for Adam. We empirically showed that our version of Adam with decoupled weight decay yields substantially better generalization performance than the common implementation of Adam with L2 regularization. We also proposed to use warm restarts for Adam to improve its anytime performance.
在有人提出 Adam 等自适应梯度方法的泛化可能差于带动量的 SGD(Wilson 等,2017)之后,我们识别并揭示了 Adam 中 L2 正则化与权重衰减的不等价。我们用实验表明,带解耦权重衰减的 Adam 版本,比常见的带 L2 正则化的 Adam 实现有明显更好的泛化。我们还提议给 Adam 加上热重启,以改善其任意时刻表现。
Our results obtained on image classification datasets must be verified on a wider range of tasks, especially ones where the use of regularization is expected to be important. It would be interesting to integrate our findings on weight decay into other methods which attempt to improve Adam, e.g, normalized direction-preserving Adam (Zhang et al. 2017). While we focused our experimental analysis on Adam, we believe that similar results also hold for other adaptive gradient methods, such as AdaGrad (Duchi et al. 2011) and AMSGrad (Reddi et al. 2018).
我们在图像分类数据集上得到的结果,必须在更广的任务上加以验证,尤其是那些可以预期正则化会很重要的任务。把关于权重衰减的发现整合进其他试图改进 Adam 的方法中会很有意思,例如保持方向的归一化 Adam(Zhang 等,2017)。虽然实验分析集中在 Adam 上,我们相信类似结论也适用于其他自适应梯度方法,如 AdaGrad(Duchi 等,2011)和 AMSGrad(Reddi 等,2018)。
6 Acknowledgments
6 致谢
We thank Patryk Chrabaszcz for help with running experiments with ImageNet32x32; Matthias Feurer and Robin Schirrmeister for providing valuable feedback on this paper in several iterations; and Martin Völker, Robin Schirrmeister, and Tonio Ball for providing us with a comparison of AdamW and Adam on their EEG data. We also thank the following members of the deep learning community for implementing decoupled weight decay in various deep learning libraries:
我们感谢 Patryk Chrabaszcz 帮助运行 ImageNet32x32 实验;感谢 Matthias Feurer 和 Robin Schirrmeister 多次为本文提供宝贵反馈;感谢 Martin Völker、Robin Schirrmeister 和 Tonio Ball 向我们提供 AdamW 与 Adam 在其脑电数据上的比较。我们也感谢深度学习社区的下列成员在各种深度学习库中实现了解耦权重衰减:
- • Jingwei Zhang, Lei Tai, Robin Schirrmeister, and Kashif Rasul for their implementations in PyTorch (see https://github.com/pytorch/pytorch/pull/4429)
- • Jingwei Zhang、Lei Tai、Robin Schirrmeister 和 Kashif Rasul 在 PyTorch 中的实现(见 https://github.com/pytorch/pytorch/pull/4429)
- • Phil Jund for his implementation in TensorFlow described at https://www.tensorflow.org/api_docs/python/tf/contrib/opt/DecoupledWeightDecayExtension
- • Phil Jund 在 TensorFlow 中的实现,见 https://www.tensorflow.org/api_docs/python/tf/contrib/opt/DecoupledWeightDecayExtension
- • Sylvain Gugger, Anand Saha, Jeremy Howard and other members of fast.ai for their implementation available at https://github.com/sgugger/Adam-experiments
- • Sylvain Gugger、Anand Saha、Jeremy Howard 以及 fast.ai 的其他成员,实现见 https://github.com/sgugger/Adam-experiments
- • Guillaume Lambard for his implementation in Keras available at https://github.com/GLambard/AdamW_Keras
- • Guillaume Lambard 在 Keras 中的实现,见 https://github.com/GLambard/AdamW_Keras
- • Yagami Lin for his implementation in Caffe available at https://github.com/Yagami123/Caffe-AdamW-AdamWR
- • Yagami Lin 在 Caffe 中的实现,见 https://github.com/Yagami123/Caffe-AdamW-AdamWR
This work was supported by the European Research Council (ERC) under the European Union’s Horizon 2020 research and innovation programme under grant no. 716721, by the German Research Foundation (DFG) under the BrainLinksBrainTools Cluster of Excellence (grant number EXC 1086) and through grant no. INST 37/935-1 FUGG, and by the German state of Baden-Württemberg through bwHPC.
本工作得到欧洲研究理事会(ERC)在欧盟 Horizon 2020 研究与创新计划下的资助(编号 716721),德国研究基金会(DFG)BrainLinksBrainTools 卓越集群(编号 EXC 1086)以及编号 INST 37/935-1 FUGG 的资助,并得到德国巴登–符腾堡州 bwHPC 的支持。
References
参考文献
Appendix
附录
Aitchison (2018) Laurence Aitchison. A unified theory of adaptive stochastic gradient descent as Bayesian filtering. arXiv:1507.02030 , 2018.
Chrabaszcz et al. (2017) Patryk Chrabaszcz, Ilya Loshchilov, and Frank Hutter. A downsampled variant of ImageNet as an alternative to the CIFAR datasets. arXiv:1707.08819 , 2017.
Cubuk et al. (2018) Ekin D Cubuk, Barret Zoph, Dandelion Mane, Vijay Vasudevan, and Quoc V Le. Autoaugment: Learning augmentation policies from data. arXiv preprint arXiv:1805.09501 , 2018.
Dinh et al. (2017) Laurent Dinh, Razvan Pascanu, Samy Bengio, and Yoshua Bengio. Sharp minima can generalize for deep nets. arXiv:1703.04933 , 2017.
Duchi et al. (2011) John Duchi, Elad Hazan, and Yoram Singer. Adaptive subgradient methods for online learning and stochastic optimization. The Journal of Machine Learning Research , 12:2121–2159, 2011.
Gastaldi (2017) Xavier Gastaldi. Shake-Shake regularization. arXiv preprint arXiv:1705.07485 , 2017.
Hanson & Pratt (1988) Stephen José Hanson and Lorien Y Pratt. Comparing biases for minimal network construction with back-propagation. In Proceedings of the 1st International Conference on Neural Information Processing Systems , pp. 177–185, 1988.
Huang et al. (2017) Gao Huang, Yixuan Li, Geoff Pleiss, Zhuang Liu, John E Hopcroft, and Kilian Q Weinberger. Snapshot ensembles: Train 1, get m for free. arXiv:1704.00109 , 2017.
Keskar et al. (2016) Nitish Shirish Keskar, Dheevatsa Mudigere, Jorge Nocedal, Mikhail Smelyanskiy, and Ping Tak Peter Tang. On large-batch training for deep learning: Generalization gap and sharp minima. arXiv:1609.04836 , 2016.
Kingma & Ba (2014) Diederik Kingma and Jimmy Ba. Adam: A method for stochastic optimization. arXiv:1412.6980 , 2014.
Krizhevsky (2009) Alex Krizhevsky. Learning multiple layers of features from tiny images. 2009.
Li et al. (2017) Hao Li, Zheng Xu, Gavin Taylor, and Tom Goldstein. Visualizing the loss landscape of neural nets. arXiv preprint arXiv:1712.09913 , 2017.
Loshchilov & Hutter (2016) Ilya Loshchilov and Frank Hutter. SGDR: stochastic gradient descent with warm restarts. arXiv:1608.03983 , 2016.
Martens & Grosse (2015) James Martens and Roger Grosse. Optimizing neural networks with kronecker-factored approximate curvature. In International conference on machine learning , pp. 2408–2417, 2015.
Radford et al. (2015) Alec Radford, Luke Metz, and Soumith Chintala. Unsupervised representation learning with deep convolutional generative adversarial networks. arXiv:1511.06434 , 2015.
Radford et al. (2018) Alec Radford, Karthik Narasimhan, Tim Salimans, and Ilya Sutskever. Improving language understanding by generative pre-training. URL https://s3-us-west-2. amazonaws. com/openai-assets/research-covers/language-unsupervised/language_ understanding_paper. pdf , 2018.
Reddi et al. (2018) Sashank J. Reddi, Satyen Kale, and Sanjiv Kumar. On the convergence of adam and beyond. International Conference on Learning Representations , 2018.
Smith (2016) Leslie N Smith. Cyclical learning rates for training neural networks. arXiv:1506.01186v3 , 2016.
Tieleman & Hinton (2012) Tijmen Tieleman and Geoffrey Hinton. Lecture 6.5-rmsprop: Divide the gradient by a running average of its recent magnitude. COURSERA: Neural networks for machine learning , 4(2):26–31, 2012.
Vaswani et al. (2017) Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Łukasz Kaiser, and Illia Polosukhin. Attention is all you need. In Advances in Neural Information Processing Systems , pp. 5998–6008, 2017.
Völker et al. (2018) Martin Völker, Jiří Hammer, Robin T Schirrmeister, Joos Behncke, Lukas DJ Fiederer, Andreas Schulze-Bonhage, Petr Marusič, Wolfram Burgard, and Tonio Ball. Intracranial error detection via deep learning. arXiv preprint arXiv:1805.01667 , 2018.
Wang et al. (2018) Jianfeng Wang, Ye Yuan, Gang Yu, and Sun Jian. Sface: An efficient network for face detection in large scale variations. arXiv preprint arXiv:1804.06559 , 2018.
Wilson et al. (2017) Ashia C Wilson, Rebecca Roelofs, Mitchell Stern, Nathan Srebro, and Benjamin Recht. The marginal value of adaptive gradient methods in machine learning. arXiv:1705.08292 , 2017.
Xu et al. (2015) Kelvin Xu, Jimmy Ba, Ryan Kiros, Kyunghyun Cho, Aaron Courville, Ruslan Salakhudinov, Rich Zemel, and Yoshua Bengio. Show, attend and tell: Neural image caption generation with visual attention. In International Conference on Machine Learning , pp. 2048–2057, 2015.
Yang et al. (2016) Shuo Yang, Ping Luo, Chen-Change Loy, and Xiaoou Tang. Wider face: A face detection benchmark. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition , pp. 5525–5533, 2016.
Zhang et al. (2018) Guodong Zhang, Chaoqi Wang, Bowen Xu, and Roger Grosse. Three mechanisms of weight decay regularization. arXiv preprint arXiv:1810.12281 , 2018.
Zhang et al. (2017) Zijun Zhang, Lin Ma, Zongpeng Li, and Chuan Wu. Normalized direction-preserving adam. arXiv:1709.04546 , 2017.
Zoph et al. (2017) Barret Zoph, Vijay Vasudevan, Jonathon Shlens, and Quoc V. Le. Learning transferable architectures for scalable image recognition. In arXiv:1707.07012 [cs.CV] , 2017.
Appendix A Formal Analysis of Weight Decay vs L2 Regularization
附录 A 权重衰减与 L2 正则化的形式分析
Proof of Proposition 1The proof for this well-known fact is straight-forward. SGD without weight decay has the following iterates on :
命题 1 的证明 这一熟知事实的证明是直接的。不带权重衰减的 SGD 在 上的迭代为:
SGD with weight decay has the following iterates on :
带权重衰减的 SGD 在 上的迭代为:
These iterates are identical since . ∎
由于 ,这些迭代是相同的。∎
Proof of Proposition 2Similarly to the proof of Proposition 1, the iterates of without weight decay on and with weight decay on are, respectively:
命题 2 的证明 与命题 1 的证明类似, 在不带权重衰减的 上的迭代,以及 在带权重衰减 的 上的迭代分别是:
The equality of these iterates for all would imply . This can only hold for all if , with , which is not the case for . Therefore, no L2 regularizer exists that makes the iterates equivalent. ∎
若这些迭代对所有 都相等,则意味着 。这要对所有 成立,只能有 ,其中 ,而对 并非如此。因此,不存在使这些迭代等价的 L2 正则项 。∎
Proof of Proposition 3 without weight decay has the following iterates on :
命题 3 的证明 不带权重衰减的 在 上的迭代为:
where the division by s is element-wise. with weight decay has the following iterates on :
其中除以 s 是逐元素的。带权重衰减的 在 上的迭代为:
These iterates are identical since . ∎
由于 ,这些迭代是相同的。∎
Appendix B Additional Practical Improvements of Adam
附录 B Adam 的其他实用改进
Having discussed decoupled weight decay for improving Adam’s generalization, in this section we introduce two additional components to improve Adam’s performance in practice.
在讨论了用解耦权重衰减改善 Adam 泛化之后,本节再引入两个在实践中改善 Adam 表现的组件。
B.1 Normalized Weight Decay
B.1 归一化权重衰减
Our preliminary experiments showed that different weight decay factors are optimal for different computational budgets (defined in terms of the number of batch passes). Relatedly, Li et al. 2017 demonstrated that a smaller batch size (for the same total number of epochs) leads to the shrinking effect of weight decay being more pronounced. Here, we propose to reduce this dependence by normalizing the values of weight decay. Specifically, we replace the hyperparameter by a new (more robust) normalized weight decay hyperparameter , and use this to set as , where is the batch size, is the total number of training points and is the total number of epochs.[^2] Thus, can be interpreted as the weight decay used if only one batch pass is allowed. We emphasize that our choice of normalization is merely one possibility informed by few experiments; a more lasting conclusion we draw is that using some normalization can substantially improve results.
我们的初步实验表明,不同计算预算(以批次数衡量)对应不同的最优权重衰减系数。与此相关,Li 等(2017)表明更小的批次大小(总周期数相同)会让权重衰减的收缩效果更明显。这里我们提议通过归一化权重衰减的取值来减弱这种依赖。具体来说,我们用一个新的(更稳健的)归一化权重衰减超参数 替换超参数 ,并据此设定 ,其中 是批次大小, 是训练样本总数, 是总周期数。[^2] 因此, 可以理解为只允许一次批次遍历时所用的权重衰减。我们强调,这一归一化选择只是由少量实验得到的一种可能;我们得出的更持久结论是:使用某种归一化能显著改善结果。
B.2 Adam with Cosine Annealing and Warm Restarts
B.2 带余弦退火和热重启的 Adam
We now apply cosine annealing and warm restarts to Adam, following our recent work (Loshchilov & Hutter 2016). There, we proposed Stochastic Gradient Descent with Warm Restarts (SGDR) to improve the anytime performance of SGD by quickly cooling down the learning rate according to a cosine schedule and periodically increasing it. SGDR has been successfully adopted to lead to new state-of-the-art results for popular image classification benchmarks (Huang et al. 2017; Gastaldi 2017; Zoph et al. 2017), and we therefore already tried extending it to Adam shortly after proposing it. However, while our initial version of Adam with warm restarts had better anytime performance than Adam, it was not competitive with SGD with warm restarts, precisely because L2 regularization was not working as well as in SGD. Now, having fixed this issue by means of the original weight decay regularization (Section 2) and also having introduced normalized weight decay (Section B.1), our original work on cosine annealing and warm restarts directly carries over to Adam.
我们现在按近期工作(Loshchilov 与 Hutter,2016)把余弦退火和热重启用到 Adam 上。当时我们提出带热重启的随机梯度下降(SGDR),按余弦调度迅速降低学习率并周期性地升高,以改善 SGD 的任意时刻表现。SGDR 已被成功采用,并在流行的图像分类基准上带来当时最优结果(Huang 等,2017;Gastaldi,2017;Zoph 等,2017),因此我们在提出它之后不久就尝试把它扩展到 Adam。然而,我们最初带热重启的 Adam 版本虽然任意时刻表现好于 Adam,却无法与带热重启的 SGD 竞争,正是因为 L2 正则化不像在 SGD 中那样有效。现在,我们用原始的权重衰减正则化(第 2 节)解决了这一问题,并引入了归一化权重衰减(B.1 节),原先关于余弦退火和热重启的工作就可以直接搬到 Adam 上。
In the interest of keeping the presentation self-contained, we briefly describe how SGDR schedules the change of the effective learning rate in order to accelerate the training of DNNs. Here, we decouple the initial learning rate and its multiplier used to obtain the actual learning rate at iteration (see, e.g., line 8 in Algorithm 1). In SGDR, we simulate a new warm-started run/restart of SGD once epochs are performed, where is the index of the run. Importantly, the restarts are not performed from scratch but emulated by increasing while the old value of is used as an initial solution. The amount by which is increased controls to which extent the previously acquired information (e.g., momentum) is used. Within the -th run, the value of decays according to a cosine annealing (Loshchilov & Hutter 2016) learning rate for each batch as follows:
为了叙述自洽,我们简要说明 SGDR 如何调度有效学习率的变化,以加速深度网络训练。这里我们把初始学习率 与在迭代 得到实际学习率所用的乘数 分开(例如见算法 1 第 8 行)。在 SGDR 中,每当完成 个周期( 是该轮运行的序号),我们就模拟一次新的、热启动的 SGD 运行/重启。重要的是,重启并不是从头开始,而是在沿用旧的 作为初始解的同时提高 来模拟。 升高多少,控制着先前获得的信息(例如动量)被使用到什么程度。在第 轮运行内, 对每个批次按余弦退火(Loshchilov 与 Hutter,2016)学习率衰减如下:
where and are ranges for the multiplier and accounts for how many epochs have been performed since the last restart. is updated at each batch iteration and is thus not constrained to integer values. Adjusting (e.g., decreasing) and at every -th restart (see also Smith 2016) could potentially improve performance, but we do not consider that option here because it would involve additional hyperparameters. For and , one can simplify Eq. (14) to
其中 和 是乘数的取值范围, 记录自上次重启以来已经完成多少个周期。 在每个批次迭代 更新,因此不必取整数值。在每一次第 次重启时调整(例如减小) 和 (也见 Smith,2016)有可能改善表现,但我们这里不考虑这一选项,因为它会引入额外超参数。当 且 时,可以把式 (14) 简化为
In order to achieve good anytime performance, one can start with an initially small (e.g., from 1% to 10% of the expected total budget) and multiply it by a factor of (e.g., ) at every restart. The -th restart is triggered when by setting to 0. An example setting of the schedule multiplier is given in C.
为了获得良好的任意时刻表现,可以从一个最初较小的 开始(例如预期总预算的 1% 到 10%),并在每次重启时把它乘以因子 (例如 )。当 时触发第 次重启,并把 置为 0。调度乘数的一个示例设置见附录 C。
Our proposed AdamWR algorithm represents AdamW (see Algorithm 2) with following Eq. (15) and computed at each iteration using normalized weight decay described in Section B.1. We note that normalized weight decay allowed us to use a constant parameter setting across short and long runs performed within AdamWR and SGDWR (SGDW with warm restarts).
我们提出的 AdamWR 算法就是 AdamW(见算法 2),其中 按式 (15) 变化,且每一步用 B.1 节描述的归一化权重衰减计算 。我们指出,归一化权重衰减使我们能在 AdamWR 和 SGDWR(带热重启的 SGDW)内部的短运行和长运行中使用同一组参数设置。
Appendix C An Example Setting of the Schedule Multiplier
附录 C 调度乘数的一个示例设置
An example schedule of the schedule multiplier is given in SuppFigure 1 for and . After the initial 100 epochs the learning rate will reach 0 because . Then, since , we restart by resetting , causing the multiplier to be reset to 1 due to Eq. (15). This multiplier will then decrease again from 1 to 0, but now over the course of 200 epochs because . Solutions obtained right before the restarts, when (e.g., at epoch indexes 100, 300, 700 and 1500 as shown in SuppFigure 1) are recommended by the optimizer as the solutions, with more recent solutions prioritized.
补充图 1 给出了 、 时调度乘数 的一个示例。最初 100 个周期之后学习率会达到 0,因为 。然后,由于 ,我们通过把 重置为 0 来重启,从而使乘数 因式 (15) 被重置为 1。该乘数随后会再次从 1 降到 0,但这次跨越 200 个周期,因为 。重启前、 时得到的解(例如补充图 1 中第 100、300、700 和 1500 个周期)被优化器推荐为解,并且更近期的解优先。
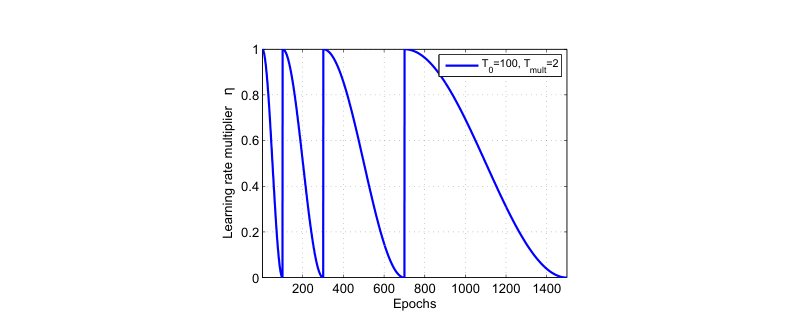
SuppFigure 1: An example schedule of the learning rate multiplier as a function of epoch index. The first run is scheduled to converge at epoch , then the budget for the next run is doubled as , etc.
补充图 1:学习率乘数随周期序号变化的一个示例调度。第一轮运行计划在第 个周期收敛,然后下一轮预算翻倍为 ,依此类推。
Appendix D Additional Results
附录 D 补充结果
We investigated whether the use of much longer runs (1800 epochs) of “standard Adam” (Adam with L2 regularization and a fixed learning rate) makes the use of cosine annealing unnecessary. SuppFigure 2 shows the results of standard Adam for a 4 by 4 logarithmic grid of hyperparameter settings (the coarseness of the grid is due to the high computational expense of runs for 1800 epochs). Even after taking the low resolution of the grid into account, the results appear to be at best comparable to the ones obtained with AdamW with 18 times less epochs and a smaller network (see SuppFigure 3, top row, middle). These results are not very surprising given Figure 1 in the main paper (which demonstrates both the improvements possible by using some learning rate schedule, such as cosine annealing, and the effectiveness of decoupled weight decay).
我们考察了把“标准 Adam”(带 L2 正则化和固定学习率的 Adam)跑长得多(1800 个周期)是否使余弦退火变得不必要。补充图 2 给出了标准 Adam 在 对数网格超参数设置上的结果(网格较粗,是因为 1800 个周期的运行计算开销很大)。即便考虑到网格分辨率较低,这些结果看起来最多也只是与用少 18 倍周期、更小网络的 AdamW 所得结果相当(见补充图 3,顶行中间)。鉴于正文中的图 1(它同时展示了使用余弦退火这类学习率调度可能带来的改善,以及解耦权重衰减的效果),这些结果并不令人意外。
Our experimental results with Adam and SGD suggest that the total runtime in terms of the number of epochs affect the basin of optimal hyperparameters (see SuppFigure 3). More specifically, the greater the total number of epochs the smaller the values of the weight decay should be. SuppFigure 4 shows that our remedy for this problem, the normalized weight decay defined in Eq. (15), simplifies hyperparameter selection because the optimal values observed for short runs are similar to the ones for much longer runs. We used our initial experiments on CIFAR-10 to suggest the square root normalization we proposed in Eq. (15) and double-checked that this is not a coincidence on the ImageNet32x32 dataset (Chrabaszcz et al. 2017), a downsampled version of the original ImageNet dataset with 1.2 million 3232 pixels images, where an epoch is 24 times longer than on CIFAR-10. This experiment also supported the square root scaling: the best values of the normalized weight decay observed on CIFAR-10 represented nearly optimal values for ImageNet32x32 (see SuppFigure 3). In contrast, had we used the same raw weight decay values for ImageNet32x32 as for CIFAR-10 and for the same number of epochs, without the proposed normalization, would have been roughly 5 times too large for ImageNet32x32, leading to much worse performance. The optimal normalized weight decay values were also very similar (e.g., and ) across SGDW and AdamW. These results clearly show that normalizing weight decay can substantially improve performance; while square root scaling performed very well in our experiments we emphasize that these experiments were not very comprehensive and that even better scaling rules are likely to exist.
我们用 Adam 和 SGD 得到的实验结果表明,以周期数衡量的总运行时间会影响最优超参数盆地(见补充图 3)。更具体地说,总周期数越大,权重衰减的取值就应该越小。补充图 4 表明,我们对这一问题的补救——式 (15) 定义的归一化权重衰减——简化了超参数选择,因为短运行上观察到的最优值与长得多的运行相近。我们用 CIFAR-10 上的初步实验提出式 (15) 中的平方根归一化,并在 ImageNet32x32 数据集(Chrabaszcz 等,2017)上复核这并非巧合;该数据集是原始 ImageNet 的下采样版本,包含 120 万张 像素图像,一个周期比 CIFAR-10 长 24 倍。这一实验也支持平方根缩放:在 CIFAR-10 上观察到的最佳归一化权重衰减值,对 ImageNet32x32 也接近最优(见补充图 3)。相反,如果我们在相同周期数下对 ImageNet32x32 使用与 CIFAR-10 相同的原始权重衰减值 ,而不做所提议的归一化, 对 ImageNet32x32 大约会偏大 5 倍,从而导致差得多的表现。最优归一化权重衰减值在 SGDW 与 AdamW 之间也非常接近(例如 和 )。这些结果清楚表明,归一化权重衰减能显著改善表现;虽然平方根缩放在我们的实验中表现很好,我们强调这些实验并不十分全面,很可能存在更好的缩放规则。
SuppFigure 4 is the equivalent of Figure 3 in the main paper, but for ImageNet32x32 instead of for CIFAR-10. The qualitative results are identical: weight decay leads to better training loss (cross-entropy) than L2 regularization, and to an even greater improvement of test error.
补充图 4 相当于正文中的图 3,只是把 CIFAR-10 换成了 ImageNet32x32。定性结果相同:权重衰减比 L2 正则化给出更好的训练损失(交叉熵),对测试误差的改善则更大。
SuppFigure 5 and SuppFigure 6 are the equivalents of Figure 4 in the main paper but supplemented with training loss curves in its bottom row. The results show that Adam and its variants with decoupled weight decay converge faster (in terms of training loss) on CIFAR-10 than the corresponding SGD variants (the difference for ImageNet32x32 is small). As is discussed in the main paper, when the same values of training loss are considered, AdamW demonstrates better values of test error than Adam. Interestingly, SuppFigure 5 and SuppFigure 6 show that the restart variants AdamWR and SGDWR also demonstrate better generalization than AdamW and SGDW, respectively.
补充图 5 和补充图 6 相当于正文中的图 4,但在底行补充了训练损失曲线。结果表明,Adam 及其带解耦权重衰减的变体在 CIFAR-10 上比相应的 SGD 变体收敛更快(就训练损失而言;在 ImageNet32x32 上差别较小)。正如正文所讨论的,在考虑相同训练损失取值时,AdamW 的测试误差好于 Adam。有意思的是,补充图 5 和补充图 6 还表明,重启变体 AdamWR 和 SGDWR 的泛化也分别好于 AdamW 和 SGDW。
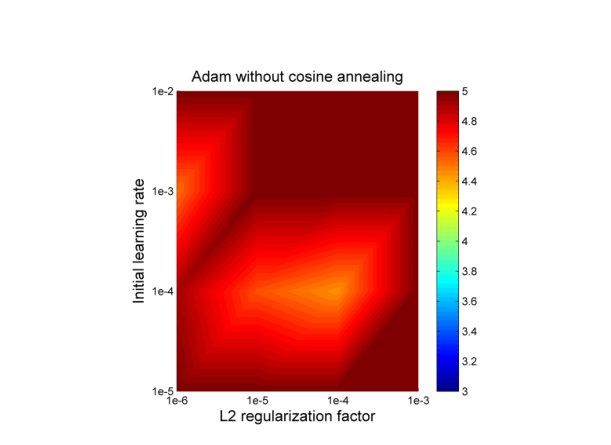
SuppFigure 2: Performance of “standard Adam”: Adam with L2 regularization and a fixed learning rate. We show the final test error of a 26 2x96d ResNet on CIFAR-10 after 1800 epochs of the original Adam for different settings of learning rate and weight decay used for L2 regularization.
补充图 2:“标准 Adam”的表现,即带 L2 正则化和固定学习率的 Adam。我们展示 26 层 2x96d ResNet 在 CIFAR-10 上用原始 Adam 训练 1800 个周期后的最终测试误差,对应不同的学习率以及用于 L2 正则化的权重衰减设置。
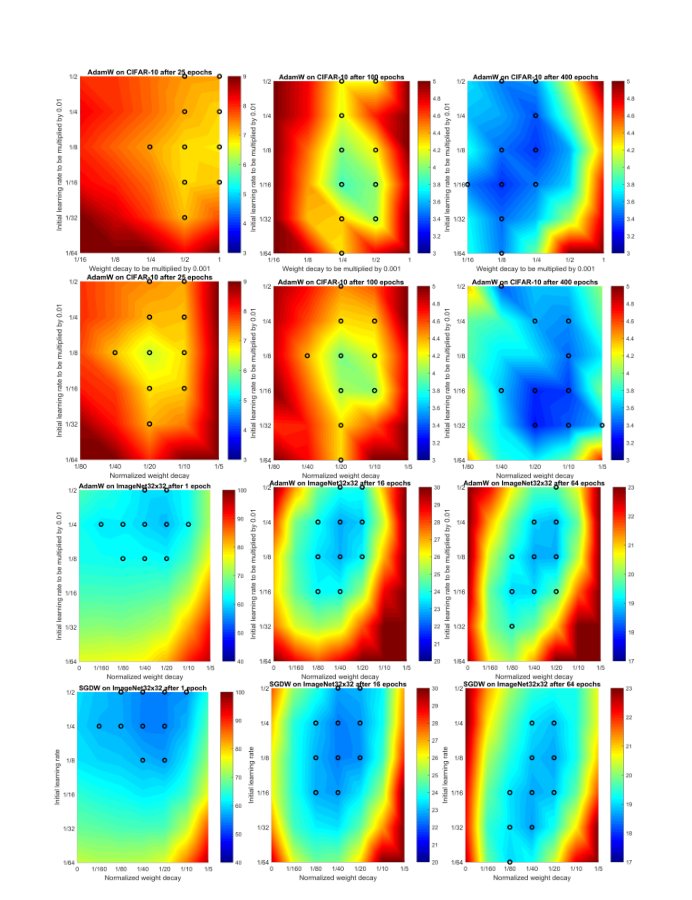
SuppFigure 3: Effect of normalized weight decay. We show the final test Top-1 error on CIFAR-10 (first two rows for AdamW without and with normalized weight decay) and Top-5 error on ImageNet32x32 (last two rows for AdamW and SGDW, both with normalized weight decay) of a 26 2x64d ResNet after different numbers of epochs (see columns). While the optimal settings of the raw weight decay change significantly for different runtime budgets (see the first row), the values of the normalized weight decay remain very similar for different budgets (see the second row) and different datasets (here, CIFAR-10 and ImageNet32x32), and even across AdamW and SGDW.
补充图 3:归一化权重衰减的效果。我们展示 26 层 2x64d ResNet 在不同周期数(见各列)后,在 CIFAR-10 上的最终 Top-1 测试误差(前两行分别是不带和带归一化权重衰减的 AdamW)以及在 ImageNet32x32 上的 Top-5 误差(后两行是都带归一化权重衰减的 AdamW 和 SGDW)。虽然原始权重衰减的最优设置随运行预算显著变化(见第一行),归一化权重衰减的取值在不同预算(见第二行)和不同数据集(这里是 CIFAR-10 与 ImageNet32x32)上非常接近,甚至在 AdamW 与 SGDW 之间也是如此。
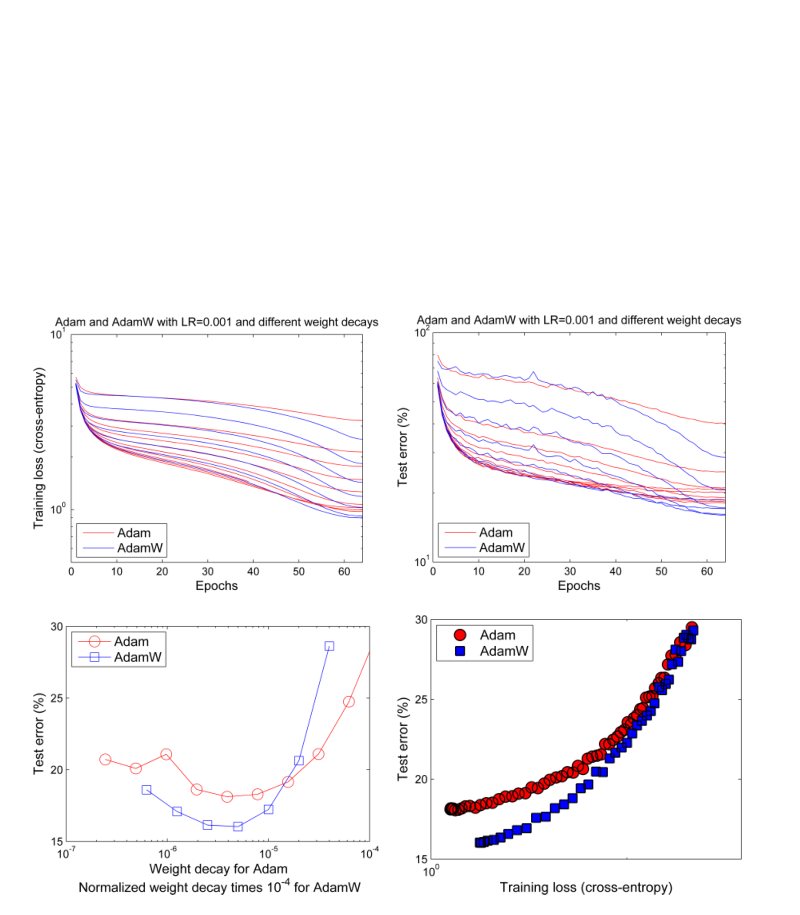
SuppFigure 4: Learning curves (top row) and generalization results (Top-5 errors in bottom row) obtained by a 26 2x96d ResNet trained with Adam and AdamW on ImageNet32x32.
补充图 4:用 Adam 和 AdamW 在 ImageNet32x32 上训练 26 层 2x96d ResNet 得到的学习曲线(顶行)和泛化结果(底行的 Top-5 误差)。
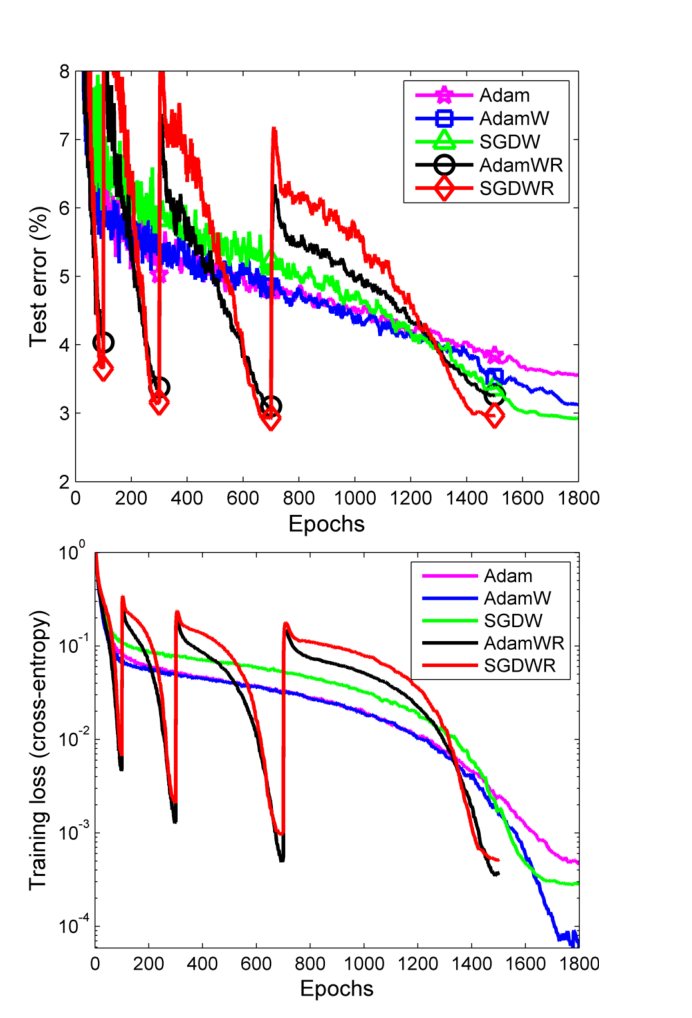
SuppFigure 5: Test error curves (top row) and training loss curves (bottom row) for CIFAR-10.
补充图 5:CIFAR-10 上的测试误差曲线(顶行)和训练损失曲线(底行)。
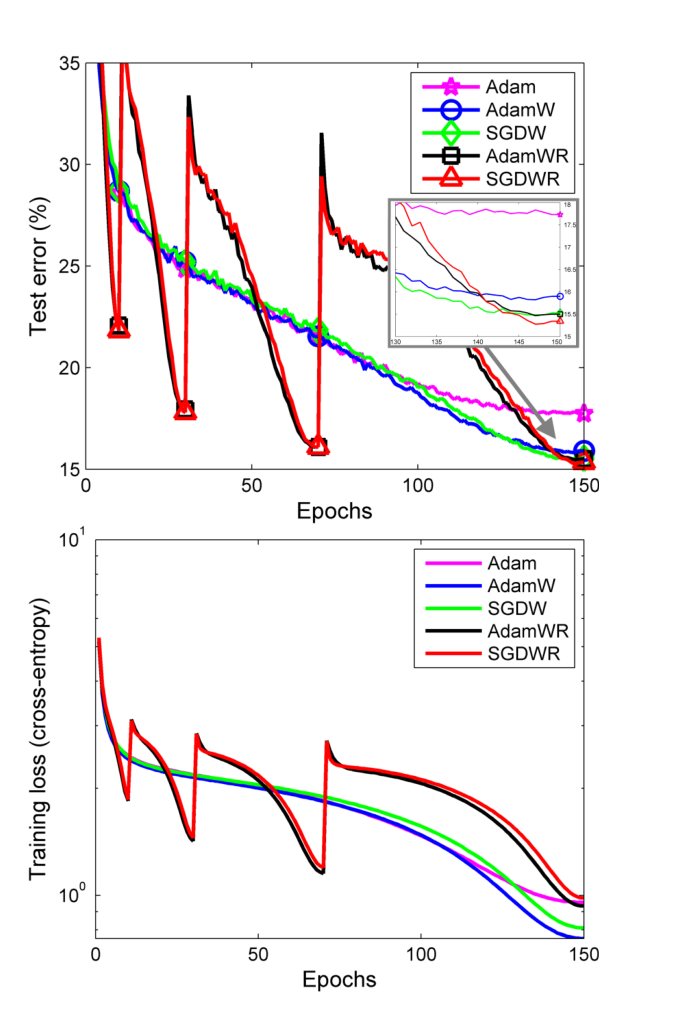
SuppFigure 6: Test error curves (top row) and training loss curves (bottom row) for ImageNet32x32.
补充图 6:ImageNet32x32 上的测试误差曲线(顶行)和训练损失曲线(底行)。